



Commit ·
65e4624
0
Parent(s):
Duplicate from deepseek-ai/DeepSeek-V4.1-Flash
Browse filesCo-authored-by: Xingkai Yu <GeeeekExplorer@users.noreply.huggingface.co>
This view is limited to 50 files because it contains too many changes. See raw diff
- .gitattributes +38 -0
- DeepSeek_V41_Tech_Report.pdf +3 -0
- LICENSE +21 -0
- README.md +197 -0
- assets/dsv41_agentic_performance.png +3 -0
- assets/dsv41_kv_cache.png +3 -0
- config.json +170 -0
- encoding/README.md +305 -0
- encoding/encoding.py +979 -0
- encoding/test_encoding.py +558 -0
- encoding/tests/test_input_1.json +82 -0
- encoding/tests/test_input_2.json +24 -0
- encoding/tests/test_input_3.json +93 -0
- encoding/tests/test_input_4.json +28 -0
- encoding/tests/test_input_5.json +39 -0
- encoding/tests/test_output_1.txt +38 -0
- encoding/tests/test_output_2.txt +1 -0
- encoding/tests/test_output_3.txt +35 -0
- encoding/tests/test_output_4.txt +2 -0
- encoding/tests/test_output_5.txt +11 -0
- evaluation/README.md +103 -0
- evaluation/dsh-minimal.patch +711 -0
- inference/README.md +71 -0
- inference/config.json +66 -0
- inference/convert.py +205 -0
- inference/engram.py +184 -0
- inference/examples/example.txt +7 -0
- inference/examples/example_harmony.json +96 -0
- inference/examples/images/carrots.jpeg +3 -0
- inference/examples/images/corn.jpeg +0 -0
- inference/generate.py +218 -0
- inference/image_processor.py +173 -0
- inference/kernel.py +591 -0
- inference/model.py +1309 -0
- inference/requirements.txt +9 -0
- inference/run.sh +54 -0
- inference/vision.py +119 -0
- model-00001-of-00048.safetensors +3 -0
- model-00002-of-00048.safetensors +3 -0
- model-00003-of-00048.safetensors +3 -0
- model-00004-of-00048.safetensors +3 -0
- model-00005-of-00048.safetensors +3 -0
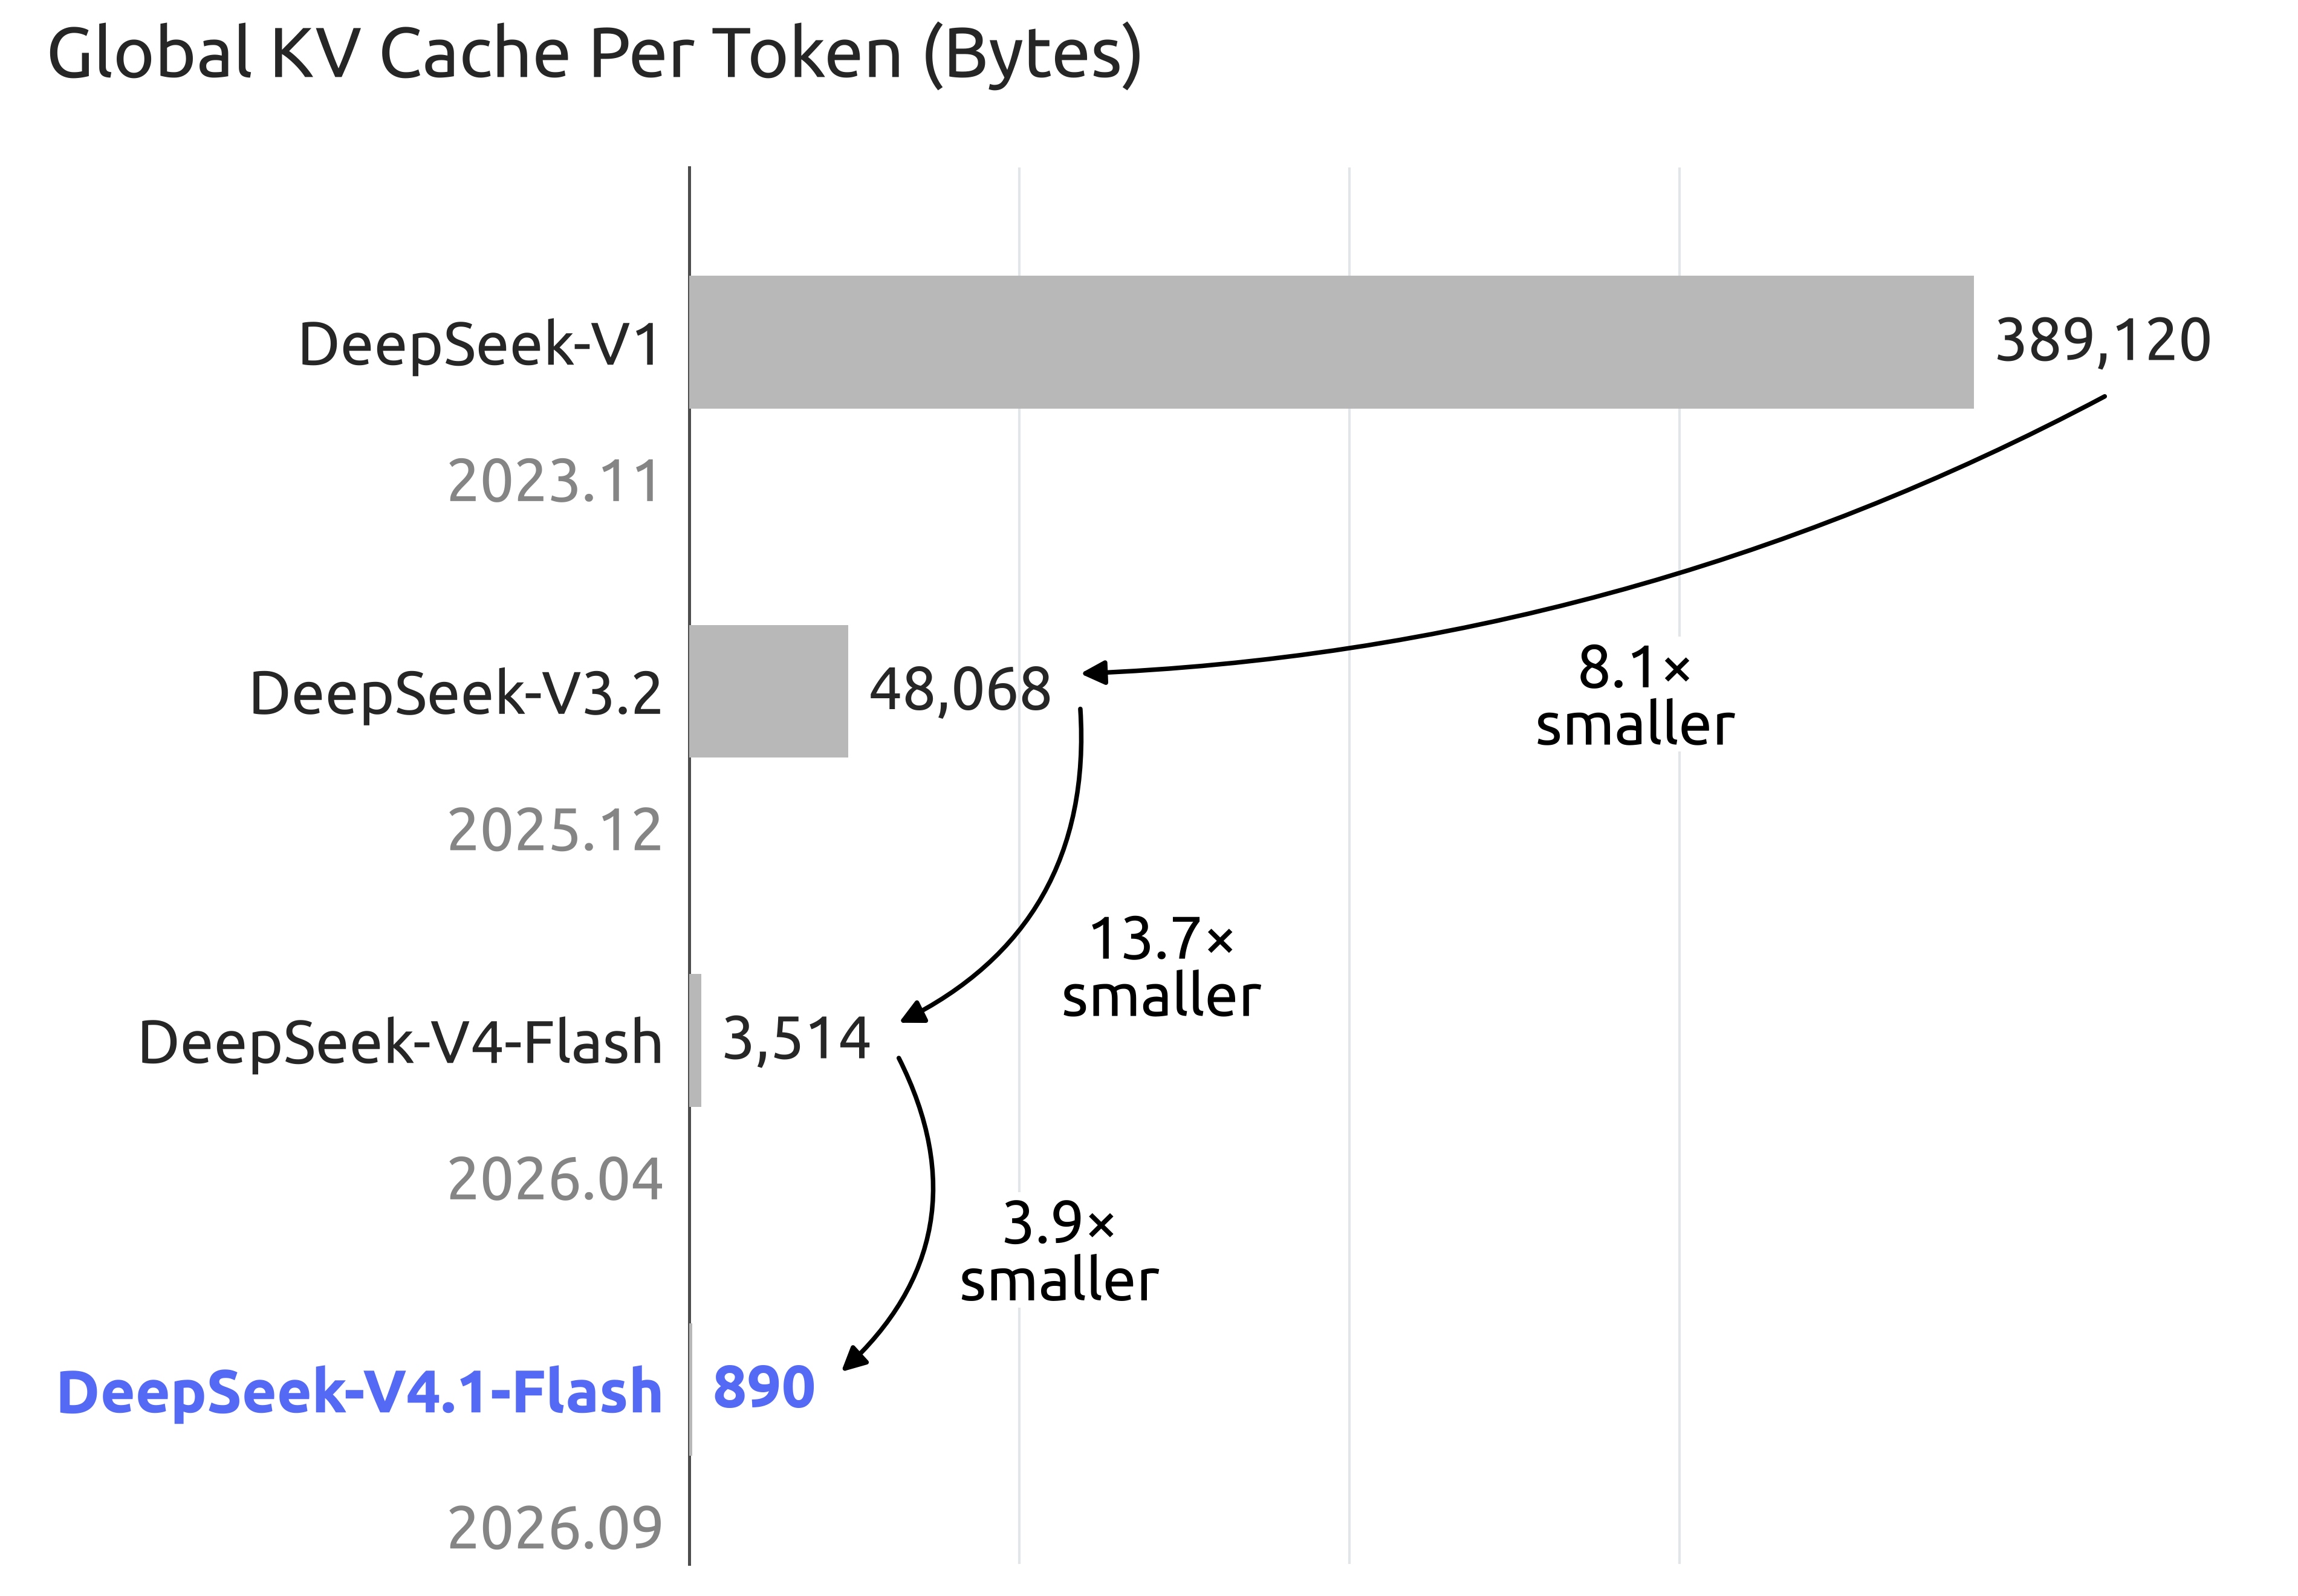
- model-00006-of-00048.safetensors +3 -0
- model-00007-of-00048.safetensors +3 -0
- model-00008-of-00048.safetensors +3 -0
- model-00009-of-00048.safetensors +3 -0
- model-00010-of-00048.safetensors +3 -0
- model-00011-of-00048.safetensors +3 -0
- model-00012-of-00048.safetensors +3 -0
- model-00013-of-00048.safetensors +3 -0
.gitattributes
ADDED
|
@@ -0,0 +1,38 @@
|
|
|
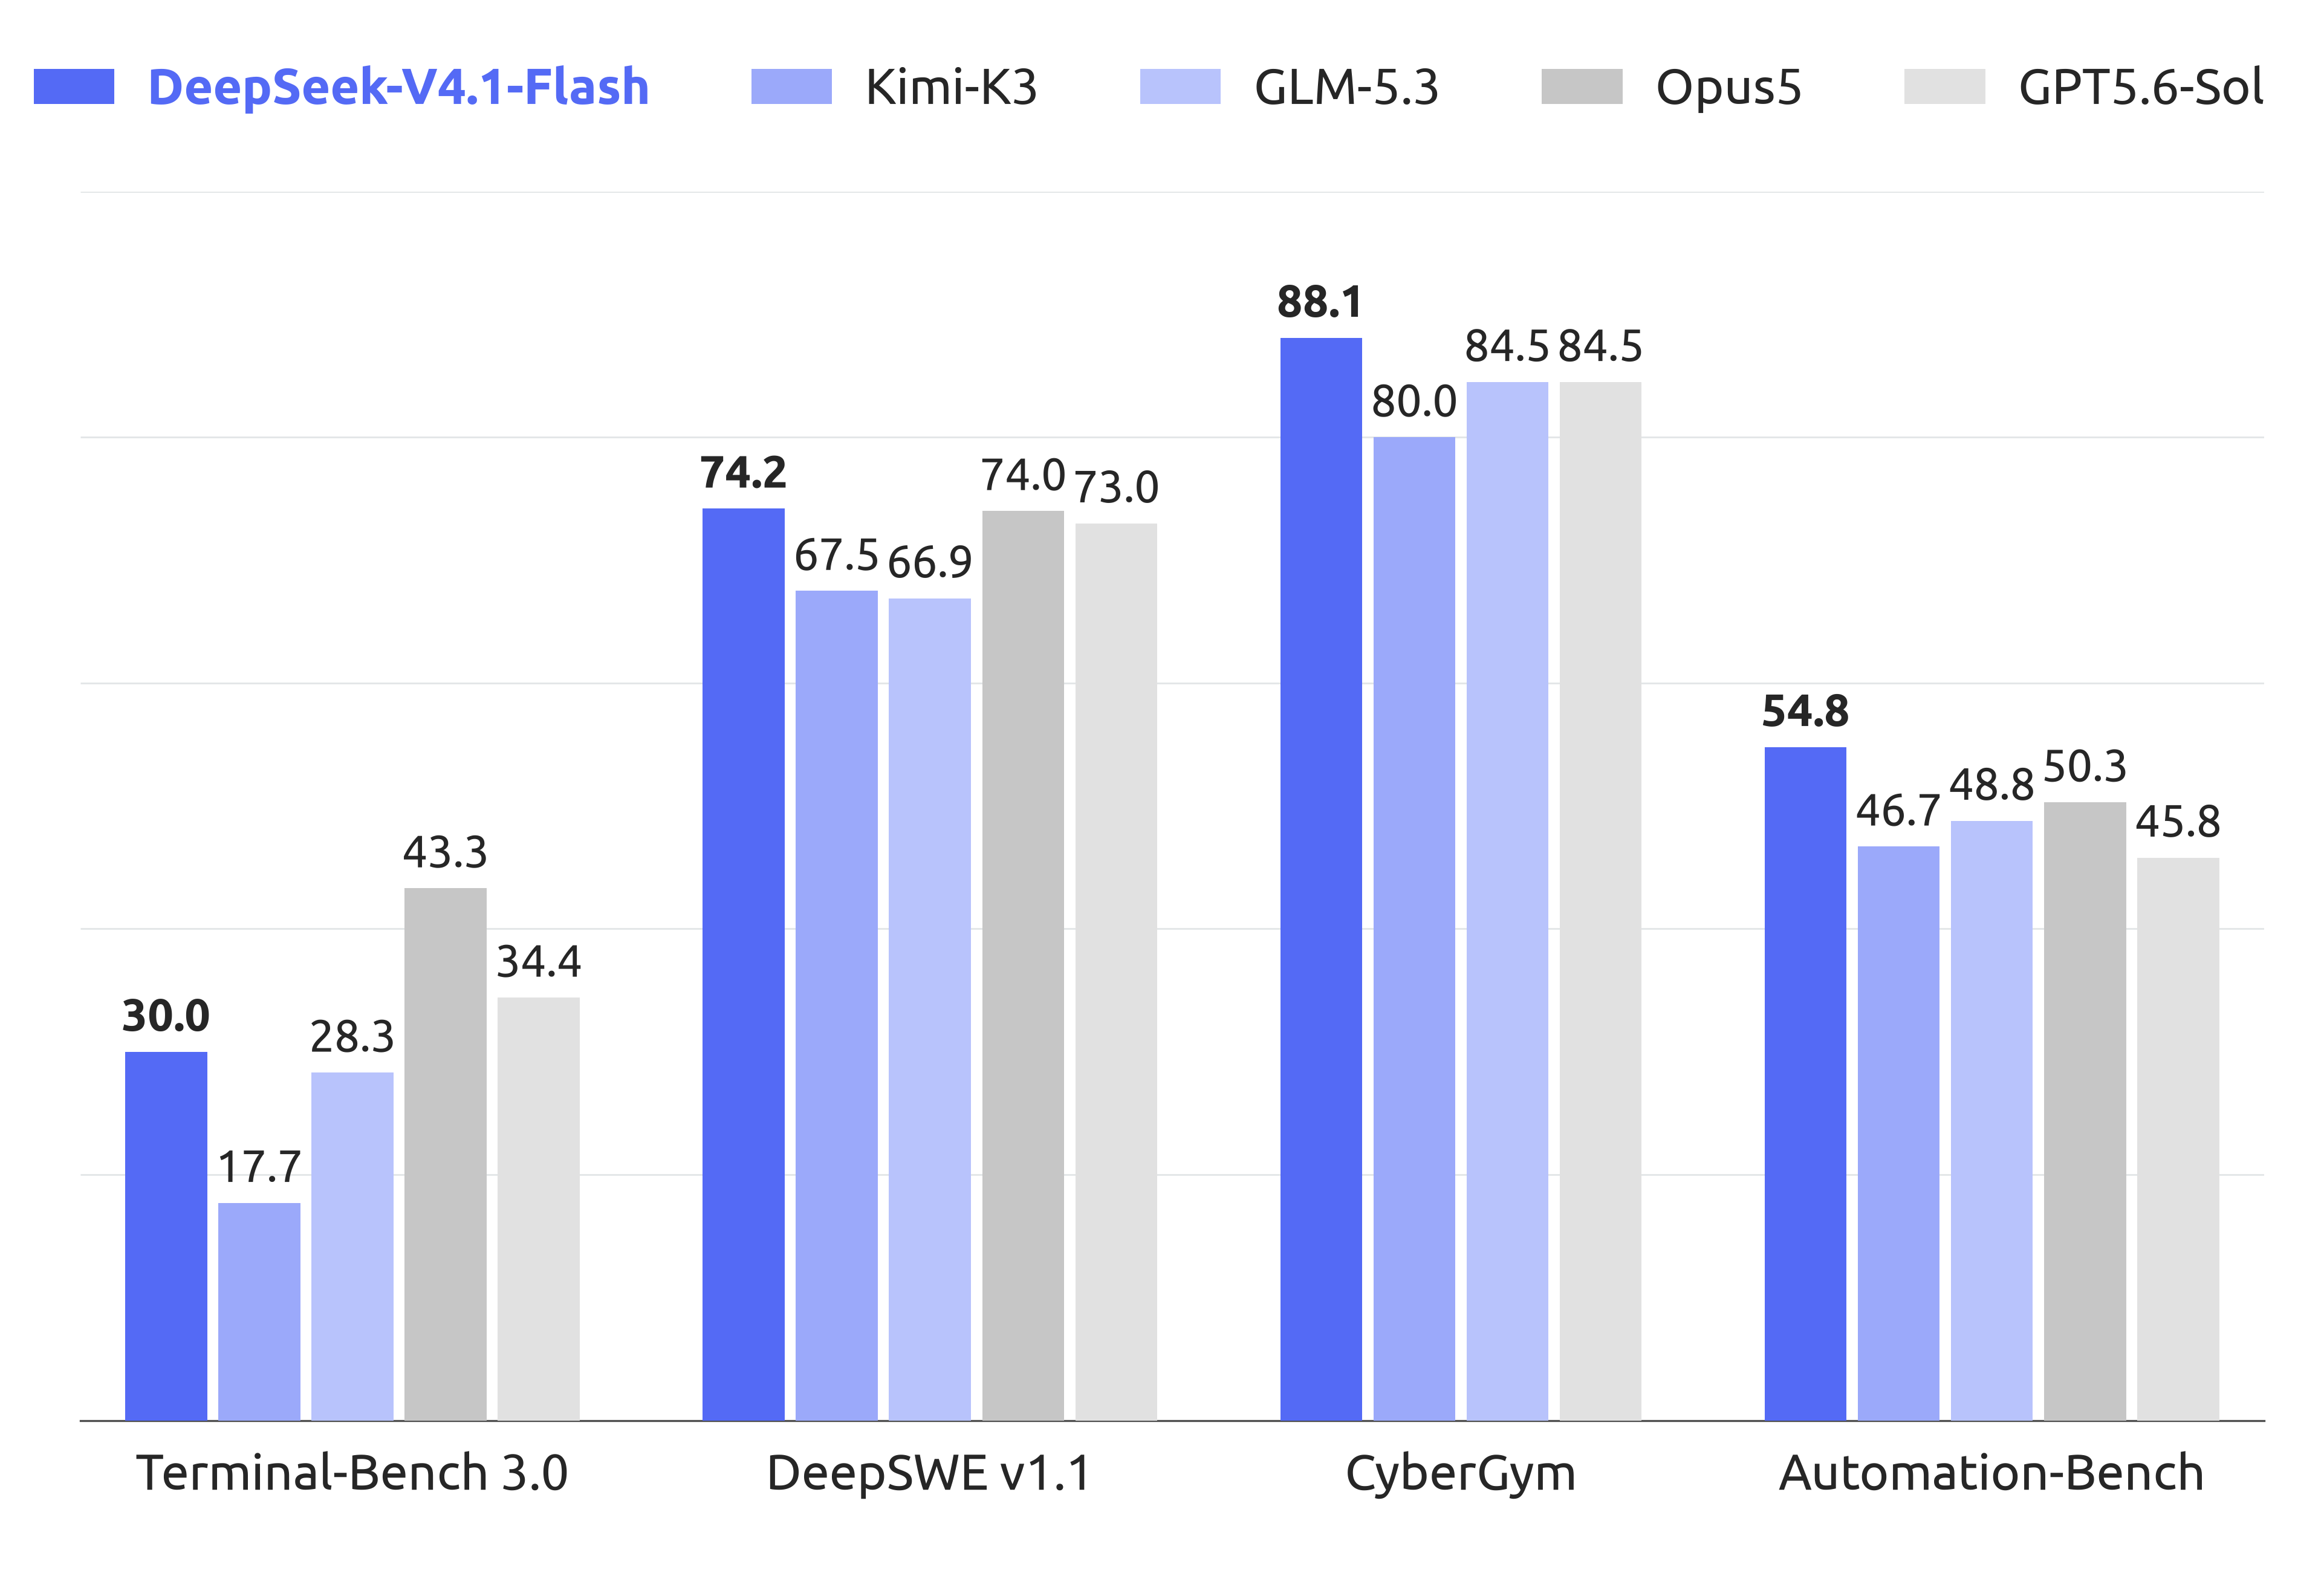
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
*.7z filter=lfs diff=lfs merge=lfs -text
|
| 2 |
+
*.arrow filter=lfs diff=lfs merge=lfs -text
|
| 3 |
+
*.bin filter=lfs diff=lfs merge=lfs -text
|
| 4 |
+
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
| 5 |
+
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
| 6 |
+
*.ftz filter=lfs diff=lfs merge=lfs -text
|
| 7 |
+
*.gz filter=lfs diff=lfs merge=lfs -text
|
| 8 |
+
*.h5 filter=lfs diff=lfs merge=lfs -text
|
| 9 |
+
*.joblib filter=lfs diff=lfs merge=lfs -text
|
| 10 |
+
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
| 11 |
+
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
| 12 |
+
*.model filter=lfs diff=lfs merge=lfs -text
|
| 13 |
+
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
| 14 |
+
*.npy filter=lfs diff=lfs merge=lfs -text
|
| 15 |
+
*.npz filter=lfs diff=lfs merge=lfs -text
|
| 16 |
+
*.onnx filter=lfs diff=lfs merge=lfs -text
|
| 17 |
+
*.ot filter=lfs diff=lfs merge=lfs -text
|
| 18 |
+
*.parquet filter=lfs diff=lfs merge=lfs -text
|
| 19 |
+
*.pb filter=lfs diff=lfs merge=lfs -text
|
| 20 |
+
*.pickle filter=lfs diff=lfs merge=lfs -text
|
| 21 |
+
*.pkl filter=lfs diff=lfs merge=lfs -text
|
| 22 |
+
*.pt filter=lfs diff=lfs merge=lfs -text
|
| 23 |
+
*.pth filter=lfs diff=lfs merge=lfs -text
|
| 24 |
+
*.rar filter=lfs diff=lfs merge=lfs -text
|
| 25 |
+
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
| 26 |
+
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
| 27 |
+
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
| 28 |
+
*.tar filter=lfs diff=lfs merge=lfs -text
|
| 29 |
+
*.tflite filter=lfs diff=lfs merge=lfs -text
|
| 30 |
+
*.tgz filter=lfs diff=lfs merge=lfs -text
|
| 31 |
+
*.wasm filter=lfs diff=lfs merge=lfs -text
|
| 32 |
+
*.xz filter=lfs diff=lfs merge=lfs -text
|
| 33 |
+
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
+
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
+
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
inference/examples/images/carrots.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 37 |
+
DeepSeek_V41_Tech_Report.pdf filter=lfs diff=lfs merge=lfs -text
|
| 38 |
+
*.png filter=lfs diff=lfs merge=lfs -text
|
DeepSeek_V41_Tech_Report.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:ba68e2e40408125ae6d2f63a9a241b61c73910691c74ec1a2a7023c851eac08d
|
| 3 |
+
size 1809802
|
LICENSE
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
MIT License
|
| 2 |
+
|
| 3 |
+
Copyright (c) 2023 DeepSeek
|
| 4 |
+
|
| 5 |
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
| 6 |
+
of this software and associated documentation files (the "Software"), to deal
|
| 7 |
+
in the Software without restriction, including without limitation the rights
|
| 8 |
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
| 9 |
+
copies of the Software, and to permit persons to whom the Software is
|
| 10 |
+
furnished to do so, subject to the following conditions:
|
| 11 |
+
|
| 12 |
+
The above copyright notice and this permission notice shall be included in all
|
| 13 |
+
copies or substantial portions of the Software.
|
| 14 |
+
|
| 15 |
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
| 16 |
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
| 17 |
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
| 18 |
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
| 19 |
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
| 20 |
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
| 21 |
+
SOFTWARE.
|
README.md
ADDED
|
@@ -0,0 +1,197 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: mit
|
| 3 |
+
library_name: transformers
|
| 4 |
+
pipeline_tag: image-text-to-text
|
| 5 |
+
---
|
| 6 |
+
|
| 7 |
+
# DeepSeek-V4.1-Flash: Pushing the Limits of KV Cache Compression
|
| 8 |
+
|
| 9 |
+
<!-- markdownlint-disable first-line-h1 -->
|
| 10 |
+
<!-- markdownlint-disable html -->
|
| 11 |
+
<!-- markdownlint-disable no-duplicate-header -->
|
| 12 |
+
|
| 13 |
+
<div align="center">
|
| 14 |
+
<img src="https://github.com/deepseek-ai/DeepSeek-V2/blob/main/figures/logo.svg?raw=true" width="60%" alt="DeepSeek-V4.1" />
|
| 15 |
+
</div>
|
| 16 |
+
<hr>
|
| 17 |
+
<div align="center" style="line-height: 1;">
|
| 18 |
+
<a href="https://www.deepseek.com/" target="_blank" style="margin: 2px;">
|
| 19 |
+
<img alt="Homepage" src="https://github.com/deepseek-ai/DeepSeek-V2/blob/main/figures/badge.svg?raw=true" style="display: inline-block; vertical-align: middle;"/>
|
| 20 |
+
</a>
|
| 21 |
+
<a href="https://chat.deepseek.com/" target="_blank" style="margin: 2px;">
|
| 22 |
+
<img alt="Chat" src="https://img.shields.io/badge/🤖%20Chat-DeepSeek%20V4.1-536af5?color=536af5&logoColor=white" style="display: inline-block; vertical-align: middle;"/>
|
| 23 |
+
</a>
|
| 24 |
+
</div>
|
| 25 |
+
<div align="center" style="line-height: 1;">
|
| 26 |
+
<a href="https://huggingface.co/deepseek-ai" target="_blank" style="margin: 2px;">
|
| 27 |
+
<img alt="Hugging Face" src="https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-DeepSeek%20AI-ffc107?color=ffc107&logoColor=white" style="display: inline-block; vertical-align: middle;"/>
|
| 28 |
+
</a>
|
| 29 |
+
<a href="https://twitter.com/deepseek_ai" target="_blank" style="margin: 2px;">
|
| 30 |
+
<img alt="Twitter Follow" src="https://img.shields.io/badge/Twitter-deepseek_ai-white?logo=x&logoColor=white" style="display: inline-block; vertical-align: middle;"/>
|
| 31 |
+
</a>
|
| 32 |
+
</div>
|
| 33 |
+
<div align="center" style="line-height: 1;">
|
| 34 |
+
<a href="LICENSE" style="margin: 2px;">
|
| 35 |
+
<img alt="License" src="https://img.shields.io/badge/License-MIT-f5de53?&color=f5de53" style="display: inline-block; vertical-align: middle;"/>
|
| 36 |
+
</a>
|
| 37 |
+
</div>
|
| 38 |
+
|
| 39 |
+
<p align="center">
|
| 40 |
+
<a href="https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash/blob/main/DeepSeek_V41_Tech_Report.pdf"><b>Technical Report</b> 👁️</a>
|
| 41 |
+
</p>
|
| 42 |
+
|
| 43 |
+
## Introduction
|
| 44 |
+
|
| 45 |
+
We introduce **DeepSeek-V4.1-Flash**, a multimodal Mixture-of-Experts (MoE) model with 552B backbone parameters and support for contexts of up to one million tokens. The model natively processes images and text, and generates text autoregressively.
|
| 46 |
+
|
| 47 |
+
**Architecture.** DeepSeek-V4.1-Flash adopts a **Causal Encoder-Decoder (CED)** architecture: a 40-layer Transformer organized as a 20-layer causal encoder followed by a 20-layer decoder. With CED, the decoder's global KV cache is projected from the final encoder hidden states rather than derived from each decoder layer's own hidden states. This allows the model to activate only **8B parameters per token during prefill** and **16B during decode**, substantially improving cost efficiency for input-heavy agentic workloads. **SWA Bounded Replay** reconstructs missing SWA KV states by replaying only the most recent *n*_win tokens, avoiding the need to persist SWA KV to SSD and reducing the persistent KV cache footprint to roughly **1/8** of that of DeepSeek-V4-Flash.
|
| 48 |
+
|
| 49 |
+
**Compressed Sparse Attention 2 (CSA2).** DeepSeek-V4.1-Flash uses CSA2, which assigns each attention layer one of three static modes — **Full**, **Reindex**, or **Reuse** — to share main KV and indexer K across layers and reuse Top-K sparse-attention indices. In the decoder, a **Hierarchical Sparse Indexer** further restricts later indexing layers to a candidate pool constructed by the first Full Mode layer, bounding deeper indexer cost independently of context length. Combined with **FP4 main KV caching** (E2M1 format, one E4M3 scale per 16 channels), these designs reduce the global KV cache footprint to **890 bytes per token** — roughly **1/4** of DeepSeek-V4-Flash.
|
| 50 |
+
|
| 51 |
+
**Additional architectural components** include Single-Pass mHC (revised residual-stream mixing with an efficient Mega-mHC kernel), Engram conditional memory (196B parameters, sparsely accessed via token-based lookup), and DSpark speculative decoding (semi-autoregressive draft generation with confidence-scheduled verification). The model uses 1 shared expert and 384 routed experts per MoE layer, activating 6 routed experts per token.
|
| 52 |
+
|
| 53 |
+
**Multimodal architecture.** A vision encoder (DeepSeek-ViT, trained from scratch with 2D-RoPE and 3×3 pixel-unshuffle downsampling) and a two-layer MLP projector convert images into visual embeddings, processed jointly with text embeddings from the start of language-model pre-training.
|
| 54 |
+
|
| 55 |
+
**Pre-training.** DeepSeek-V4.1-Flash is trained from scratch on a multimodal corpus comprising **45T tokens**, with sparse attention trained at a sequence length of 64K and context extended to 1M tokens at 34T tokens.
|
| 56 |
+
|
| 57 |
+
**Post-training.** The post-training recipe follows the standard SFT → RL → on-policy distillation (OPD) paradigm without algorithmic modifications. All substantive changes lie instead in the data pipeline: large-scale automated synthesis of agent tasks and environments with progressive scaling of data, tasks, and rollouts. The model supports a **continuously controllable reasoning effort** setting (integer 1–100) that trades inference cost for accuracy.
|
| 58 |
+
|
| 59 |
+
<div align="center">
|
| 60 |
+
<img src="assets/dsv41_agentic_performance.png" width="48%" alt="DeepSeek-V4.1-Flash agentic benchmark performance" style="display: inline-block; margin: 0 1%;" />
|
| 61 |
+
<img src="assets/dsv41_kv_cache.png" width="48%" alt="Global KV cache size per token across DeepSeek generations" style="display: inline-block; margin: 0 1%;" />
|
| 62 |
+
</div>
|
| 63 |
+
|
| 64 |
+
*Figure 1. (a) Performance of DeepSeek-V4.1-Flash and counterparts on agentic benchmarks. (b) Global KV cache size per token (bytes) across generations of DeepSeek models. DeepSeek-V4.1-Flash achieves approximately 4-fold and 437-fold reductions relative to DeepSeek-V4-Flash and DeepSeek-V1, respectively.*
|
| 65 |
+
|
| 66 |
+
## Evaluation Results
|
| 67 |
+
|
| 68 |
+
### Base Model
|
| 69 |
+
|
| 70 |
+
All base models are evaluated in our internal framework under the same evaluation settings. Scores within 0.3 of each other are considered equivalent.
|
| 71 |
+
|
| 72 |
+
<div align="center">
|
| 73 |
+
|
| 74 |
+
| Benchmark (Metric) | # Shots | DeepSeek-V4-Flash-Base | DeepSeek-V4-Pro-Base | DeepSeek-V4.1-Flash-Base |
|
| 75 |
+
| :--- | :---: | :---: | :---: | :---: |
|
| 76 |
+
| Architecture | — | MoE | MoE | MoE |
|
| 77 |
+
| # Backbone Params | — | 284B | 1.6T | 552B |
|
| 78 |
+
| # Activated Params | — | 13B | 49B | 8B / 16B |
|
| 79 |
+
| **World Knowledge** | | | | |
|
| 80 |
+
| AGIEval (EM) | 3–5-shot | 83.9 | **84.4** | 83.4 |
|
| 81 |
+
| MMLU-Pro (EM) | 5-shot | 68.3 | 73.5 | **74.1** |
|
| 82 |
+
| C-Eval (EM) | 5-shot | 92.1 | **93.1** | 92.1 |
|
| 83 |
+
| MultiLoKo (LLM-Judge) | 5-shot | 42.6 | **50.9** | 45.5 |
|
| 84 |
+
| SimpleQA-Verified (EM) | 25-shot | 30.1 | **55.2** | 42.3 |
|
| 85 |
+
| SuperGPQA (EM) | 5-shot | 46.5 | **53.9** | 53.1 |
|
| 86 |
+
| **Language & Reasoning** | | | | |
|
| 87 |
+
| BBH (EM) | 3-shot | 86.9 | **87.5** | 86.1 |
|
| 88 |
+
| BBEH (EM) | 1-shot | 25.4 | **29.8** | 27.2 |
|
| 89 |
+
| DROP (F1) | 1-shot | **88.6** | **88.7** | 87.9 |
|
| 90 |
+
| HellaSwag (EM) | 0-shot | 85.7 | **88.0** | 87.2 |
|
| 91 |
+
| **Code & Math** | | | | |
|
| 92 |
+
| BigCodeBench (Pass@1) | 3-shot | 56.8 | 59.2 | **60.6** |
|
| 93 |
+
| HumanEval (Pass@1) | 0-shot | 69.5 | 76.8 | **79.4** |
|
| 94 |
+
| GSM8K (EM) | 8-shot | 90.8 | 92.6 | **93.0** |
|
| 95 |
+
| MATH (EM) | 4-shot | 57.4 | **64.5** | 61.1 |
|
| 96 |
+
| MGSM (EM) | 8-shot | **85.7** | 84.4 | 80.2 |
|
| 97 |
+
| **Long Context** | | | | |
|
| 98 |
+
| LongBench-V2 (EM) | 1-shot | 44.7 | **51.5** | 45.2 |
|
| 99 |
+
| **Multimodal** | | | | |
|
| 100 |
+
| MMMU-Pro (EM) | 4-shot | — | — | 56.5 |
|
| 101 |
+
| CVBench (EM) | 4-shot | — | — | 77.9 |
|
| 102 |
+
| DocVQA (LLM-Judge) | 4-shot | — | — | 95.6 |
|
| 103 |
+
| RefCOCO-avg (Acc@0.5) | 0-shot | — | — | 86.0 |
|
| 104 |
+
|
| 105 |
+
</div>
|
| 106 |
+
|
| 107 |
+
### Instruct Model
|
| 108 |
+
|
| 109 |
+
DeepSeek-V4.1-Flash supports a continuously controllable reasoning effort from 1 to 100. All instruct results below use the maximum effort setting (`reasoning_effort=100`). Evaluations use `temperature=1.0, top_p=0.95`.
|
| 110 |
+
|
| 111 |
+
For code agent benchmarks (Terminal-Bench 2.1/3.0/4.0, DeepSWE v1.1, NL2Repo-Bench, ProgramBench), the model is evaluated with the Minimal mode of DeepSeek Harness and a 1M-token context window. To align with official setup requirements, the mini-SWE harness is used for DeepSWE v1.1, and the Claude Code harness for SEC-Bench Pro. Visual agent benchmarks (Chartography, BabyVision, ZeroBench) use the Claude Code harness with a 512k-token context window. Agent's Last Exam and AutomationBench use their official scaffolds. All agentic evaluations use `temperature=1.0, top_p=0.95`.
|
| 112 |
+
|
| 113 |
+
#### Comparison with frontier models (Max reasoning effort)
|
| 114 |
+
|
| 115 |
+
<div align="center">
|
| 116 |
+
|
| 117 |
+
| Benchmark (Metric) | Opus-5.0 | GPT-5.6 Sol | K3 | GLM-5.3 | DS-V4-Pro | DS-V4-Flash | DS-V4.1-Flash |
|
| 118 |
+
| :--- | :---: | :---: | :---: | :---: | :---: | :---: | :---: |
|
| 119 |
+
| **Reasoning** | | | | | | | |
|
| 120 |
+
| GPQA Diamond (Pass@1) | 93.4 | **94.1** | 92.9 | 88.1 | 92.4 | 89.9 | 90.9 |
|
| 121 |
+
| HLE (Pass@1) | **56.3** | 44.5 | 43.5 | 42.0† | 42.7† | 37.8† | 36.8 (39.1†) |
|
| 122 |
+
| Codeforces (Rating) | — | — | — | — | 3348 | 3289 | **3471** |
|
| 123 |
+
| MathArena Apex (Pass@1) | — | — | **65.6** | — | 65.3 | 58.6 | **65.6** |
|
| 124 |
+
| **Agentic** | | | | | | | |
|
| 125 |
+
| Terminal-Bench 2.1 (Pass@1) | 89.1 | 88.8 | 88.3 | 88.2 | 87.9 | 82.7 | **90.6** |
|
| 126 |
+
| Terminal-Bench 3.0 (Pass@1) | **43.3** | 34.4 | 17.7 | 28.3 | 11.8 | 7.6 | 30.0 |
|
| 127 |
+
| Terminal-Bench 4.0 (Pass@1) | **51.8** | 39.9 | 12.6 | 37.9 | 12.4 | 7.0 | 31.2 |
|
| 128 |
+
| DeepSWE v1.1 (Resolved) | 74.0 | 73.0 | 67.5 | 66.9 | 62.7 | 54.4 | **74.2** |
|
| 129 |
+
| ProgramBench (Almost@1) | **37.0** | 23.0 | 17.5 | 19.0 | 15.5 | — | 20.3 |
|
| 130 |
+
| NL2Repo-Bench (Score) | **75.3** | 56.8 | 58.0 | 58.0 | 61.5 | 54.2 | 64.0 |
|
| 131 |
+
| CyberGym (Pass@1) | — | 84.5 | 80.0 | 84.5 | 83.3 | 76.7 | **88.1** |
|
| 132 |
+
| SEC-Bench Pro (Pass@1) | — | **74.3** | — | — | 56.4 | 30.9 | 62.8 |
|
| 133 |
+
| ExploitGym (Pass@1) | 22.1 | **33.7** | — | 15.0 | 5.4 | 1.8 | 15.3 |
|
| 134 |
+
| HLE w/ tools (Pass@1) | 63.6 | — | 59.8 | 62.5 | 60.0 | 51.5 | **63.9** |
|
| 135 |
+
| AutomationBench (Pass@1) | 50.3 | 45.8 | 46.7 | 48.8 | 43.2 | 37.7 | **54.8** |
|
| 136 |
+
| Agent's Last Exam (Pass@1) | 28.6 | 26.7 | 27.6 | 28.5 | 25.7 | 25.2 | **31.8** |
|
| 137 |
+
| Chartography w/ tools (Pass@1) | **84.0** | 79.9 | 68.1 | — | — | — | 78.9 |
|
| 138 |
+
| BabyVision w/ tools (Pass@1) | **94.1** | 88.9 | 85.7 | — | — | — | 89.6 |
|
| 139 |
+
| ZeroBench-main w/ tools (Pass@5) | 52.0 | **53.0** | 41.0 | — | — | — | 49.0 |
|
| 140 |
+
|
| 141 |
+
</div>
|
| 142 |
+
|
| 143 |
+
*† Text-only subset of HLE.*
|
| 144 |
+
|
| 145 |
+
#### Performance across agent scaffolds (DeepSWE v1.1 and Terminal-Bench 2.1, Max reasoning effort)
|
| 146 |
+
|
| 147 |
+
All scaffolds use N=8 samples per task on DeepSWE v1.1 and N=3 on Terminal-Bench 2.1, with Linux containers, `temperature=1.0`, `top_p=0.95`, a 1M-token context limit, and max_steps=500 per agent. Terminal-Bench 2.1 is evaluated without network access.
|
| 148 |
+
|
| 149 |
+
<div align="center">
|
| 150 |
+
|
| 151 |
+
| Benchmark (Metric) | Claude Code | Codex | OpenCode | Pi | mini-SWE | DSH Minimal | DSH Standard | DSH PTC |
|
| 152 |
+
| :--- | :---: | :---: | :---: | :---: | :---: | :---: | :---: | :---: |
|
| 153 |
+
| DeepSWE v1.1 (Resolved) | 69.8 | 65.6 | 65.5 | 66.2 | 74.2 | 72.6 | 70.5 | 67.6 |
|
| 154 |
+
| Terminal-Bench 2.1 (Pass@1) | 88.0 | 84.1 | 85.0 | 86.1 | 90.3 | 90.6 | 85.8 | 85.8 |
|
| 155 |
+
|
| 156 |
+
</div>
|
| 157 |
+
|
| 158 |
+
## Prompt Encoding
|
| 159 |
+
|
| 160 |
+
This release does not include a Jinja-format chat template. The [`encoding`](encoding/README.md) folder contains a self-contained Python reference implementation (`encoding.py`) with test cases for multi-turn conversations, tool calling, thinking mode, numeric reasoning effort, mid-conversation system messages, and interleaved image content.
|
| 161 |
+
|
| 162 |
+
For production use, we additionally release [deepseek-recipe](https://github.com/deepseek-ai/deepseek-recipe), a set of Rust libraries with Python bindings that provides the same prompt format as a maintained, protocol-aware toolkit. It converts Messages, Chat Completions, and Responses API requests into the Conversation format, encodes them into DeepSeek V4 and V4.1 prompts or token IDs, and parses model output back into complete or streamed responses — covering thinking, tool calls, images, and generation settings. Model inference, tool execution, and HTTP transport are left to the caller.
|
| 163 |
+
|
| 164 |
+
## Minimal Inference
|
| 165 |
+
|
| 166 |
+
Please refer to the [`inference`](inference/README.md) folder for instructions on weight conversion and running inference locally.
|
| 167 |
+
|
| 168 |
+
**Recommended sampling parameters:**
|
| 169 |
+
|
| 170 |
+
| Parameter | Value |
|
| 171 |
+
| :--- | :--- |
|
| 172 |
+
| `temperature` | 1.0 |
|
| 173 |
+
| `top_p` | 0.95 or 1.0 |
|
| 174 |
+
| `context_window` | 1M tokens |
|
| 175 |
+
| `max_tokens` | ≥ 256K |
|
| 176 |
+
|
| 177 |
+
## Reproducing DeepSWE Benchmark Results
|
| 178 |
+
|
| 179 |
+
The [`evaluation`](evaluation/README.md) folder contains step-by-step instructions for reproducing the DeepSWE v1.1 benchmark results, covering both the `dsh-minimal` agent and the official `mini-swe-agent`. The patch required to integrate `dsh-minimal` with [Pier](https://github.com/datacurve-ai/pier) is also included there.
|
| 180 |
+
|
| 181 |
+
## License
|
| 182 |
+
|
| 183 |
+
This repository and the model weights are licensed under the [MIT License](LICENSE).
|
| 184 |
+
|
| 185 |
+
## Citation
|
| 186 |
+
|
| 187 |
+
```bibtex
|
| 188 |
+
@misc{deepseekai2026deepseekv41flash,
|
| 189 |
+
title={DeepSeek-V4.1-Flash: Pushing the Limits of KV Cache Compression},
|
| 190 |
+
author={DeepSeek-AI},
|
| 191 |
+
year={2026},
|
| 192 |
+
}
|
| 193 |
+
```
|
| 194 |
+
|
| 195 |
+
## Contact
|
| 196 |
+
|
| 197 |
+
If you have any questions, please raise an issue or contact us at [service@deepseek.com](mailto:service@deepseek.com).
|
assets/dsv41_agentic_performance.png
ADDED
|
Git LFS Details
|
assets/dsv41_kv_cache.png
ADDED
|
Git LFS Details
|
config.json
ADDED
|
@@ -0,0 +1,170 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"architectures": [
|
| 3 |
+
"DeepseekV41ForCausalLM"
|
| 4 |
+
],
|
| 5 |
+
"model_type": "deepseek_v41",
|
| 6 |
+
"dtype": "bfloat16",
|
| 7 |
+
"transformers_version": "5.6.0",
|
| 8 |
+
"bos_token_id": 0,
|
| 9 |
+
"eos_token_id": 1,
|
| 10 |
+
"pad_token_id": 2,
|
| 11 |
+
"image_token_id": 129264,
|
| 12 |
+
"quantization_config": {
|
| 13 |
+
"quant_method": "fp8",
|
| 14 |
+
"activation_scheme": "dynamic",
|
| 15 |
+
"weight_block_size": [
|
| 16 |
+
32,
|
| 17 |
+
32
|
| 18 |
+
],
|
| 19 |
+
"scale_fmt": "ue8m0",
|
| 20 |
+
"expert_dtype": "fp4"
|
| 21 |
+
},
|
| 22 |
+
"text_config": {
|
| 23 |
+
"model_type": "deepseek_v41_text",
|
| 24 |
+
"vocab_size": 129280,
|
| 25 |
+
"hidden_size": 5120,
|
| 26 |
+
"moe_intermediate_size": 2304,
|
| 27 |
+
"num_hidden_layers": 40,
|
| 28 |
+
"num_attention_heads": 64,
|
| 29 |
+
"num_key_value_heads": 1,
|
| 30 |
+
"head_dim": 512,
|
| 31 |
+
"qk_rope_head_dim": 64,
|
| 32 |
+
"q_lora_rank": 1280,
|
| 33 |
+
"o_lora_rank": 1024,
|
| 34 |
+
"o_groups": 8,
|
| 35 |
+
"hidden_act": "silu",
|
| 36 |
+
"swiglu_limit": 10.0,
|
| 37 |
+
"rms_norm_eps": 1e-20,
|
| 38 |
+
"attention_bias": false,
|
| 39 |
+
"attention_dropout": 0.0,
|
| 40 |
+
"initializer_range": 0.02,
|
| 41 |
+
"use_cache": true,
|
| 42 |
+
"tie_word_embeddings": false,
|
| 43 |
+
"max_position_embeddings": 1048576,
|
| 44 |
+
"rope_theta": 10000,
|
| 45 |
+
"rope_scaling": {
|
| 46 |
+
"rope_type": "yarn",
|
| 47 |
+
"factor": 16,
|
| 48 |
+
"beta_fast": 32,
|
| 49 |
+
"beta_slow": 1,
|
| 50 |
+
"original_max_position_embeddings": 65536
|
| 51 |
+
},
|
| 52 |
+
"n_routed_experts": 384,
|
| 53 |
+
"n_shared_experts": 1,
|
| 54 |
+
"num_experts_per_tok": 6,
|
| 55 |
+
"scoring_func": "sqrtsoftplus",
|
| 56 |
+
"topk_method": "noaux_tc",
|
| 57 |
+
"norm_topk_prob": true,
|
| 58 |
+
"routed_scaling_factor": 1.5,
|
| 59 |
+
"sliding_window": 128,
|
| 60 |
+
"compress_ratios": [
|
| 61 |
+
0,
|
| 62 |
+
0,
|
| 63 |
+
2,
|
| 64 |
+
2,
|
| 65 |
+
2,
|
| 66 |
+
2,
|
| 67 |
+
2,
|
| 68 |
+
2,
|
| 69 |
+
2,
|
| 70 |
+
2,
|
| 71 |
+
2,
|
| 72 |
+
2,
|
| 73 |
+
2,
|
| 74 |
+
2,
|
| 75 |
+
2,
|
| 76 |
+
2,
|
| 77 |
+
2,
|
| 78 |
+
2,
|
| 79 |
+
2,
|
| 80 |
+
2,
|
| 81 |
+
1,
|
| 82 |
+
1,
|
| 83 |
+
1,
|
| 84 |
+
1,
|
| 85 |
+
1,
|
| 86 |
+
1,
|
| 87 |
+
1,
|
| 88 |
+
1,
|
| 89 |
+
1,
|
| 90 |
+
1,
|
| 91 |
+
1,
|
| 92 |
+
1,
|
| 93 |
+
1,
|
| 94 |
+
1,
|
| 95 |
+
1,
|
| 96 |
+
1,
|
| 97 |
+
1,
|
| 98 |
+
1,
|
| 99 |
+
1,
|
| 100 |
+
1,
|
| 101 |
+
0,
|
| 102 |
+
0,
|
| 103 |
+
0
|
| 104 |
+
],
|
| 105 |
+
"compress_rope_theta": 160000,
|
| 106 |
+
"kv_source_layer_ids": [
|
| 107 |
+
2,
|
| 108 |
+
8,
|
| 109 |
+
14,
|
| 110 |
+
20
|
| 111 |
+
],
|
| 112 |
+
"index_source_layer_ids": [
|
| 113 |
+
2,
|
| 114 |
+
8,
|
| 115 |
+
14,
|
| 116 |
+
20,
|
| 117 |
+
24,
|
| 118 |
+
28,
|
| 119 |
+
32,
|
| 120 |
+
36
|
| 121 |
+
],
|
| 122 |
+
"index_n_heads": 32,
|
| 123 |
+
"index_head_dim": 128,
|
| 124 |
+
"index_topk": 512,
|
| 125 |
+
"candidate_source_layer_id": 20,
|
| 126 |
+
"candidate_topk_blocks": 2048,
|
| 127 |
+
"candidate_block_size": 8,
|
| 128 |
+
"hc_mult": 4,
|
| 129 |
+
"hc_sinkhorn_iters": 20,
|
| 130 |
+
"hc_eps": 1e-06,
|
| 131 |
+
"engram_layer_ids": [
|
| 132 |
+
1,
|
| 133 |
+
14
|
| 134 |
+
],
|
| 135 |
+
"engram_num_embeddings": [
|
| 136 |
+
384006168,
|
| 137 |
+
384016682
|
| 138 |
+
],
|
| 139 |
+
"engram_max_ngram_size": 4,
|
| 140 |
+
"engram_vocab_size": 16000000,
|
| 141 |
+
"engram_n_heads": 8,
|
| 142 |
+
"engram_head_dim": 256,
|
| 143 |
+
"engram_pad_token_id": 2,
|
| 144 |
+
"engram_compressed_vocab_size": 99092,
|
| 145 |
+
"num_nextn_predict_layers": 3,
|
| 146 |
+
"dspark_block_size": 5,
|
| 147 |
+
"dspark_noise_token_id": 128799,
|
| 148 |
+
"dspark_target_layer_ids": [
|
| 149 |
+
37,
|
| 150 |
+
38,
|
| 151 |
+
39
|
| 152 |
+
],
|
| 153 |
+
"dspark_markov_rank": 256,
|
| 154 |
+
"dspark_n_routed_experts": 128,
|
| 155 |
+
"dspark_num_experts_per_tok": 3
|
| 156 |
+
},
|
| 157 |
+
"vision_config": {
|
| 158 |
+
"model_type": "deepseek_v41_vision",
|
| 159 |
+
"num_hidden_layers": 32,
|
| 160 |
+
"hidden_size": 1024,
|
| 161 |
+
"num_attention_heads": 16,
|
| 162 |
+
"intermediate_size": 2816,
|
| 163 |
+
"patch_size": 14,
|
| 164 |
+
"rope_theta": 10000,
|
| 165 |
+
"downsample_ratio": 3,
|
| 166 |
+
"max_image_tokens": 1024,
|
| 167 |
+
"min_pixels": 295936,
|
| 168 |
+
"max_wh_ratio": null
|
| 169 |
+
}
|
| 170 |
+
}
|
encoding/README.md
ADDED
|
@@ -0,0 +1,305 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# DeepSeek-V4.1 text and vision encoding
|
| 2 |
+
|
| 3 |
+
`encoding.py` is the standalone prompt-format reference for DeepSeek-V4.1. It
|
| 4 |
+
supports multi-turn conversations, tool calls, thinking modes, numeric reasoning
|
| 5 |
+
effort, mid-conversation system messages, and interleaved image content blocks,
|
| 6 |
+
without importing the inference implementation.
|
| 7 |
+
|
| 8 |
+
## V4.1 changes relative to V4
|
| 9 |
+
|
| 10 |
+
Three prompt-format changes distinguish V4.1 from V4:
|
| 11 |
+
|
| 12 |
+
1. **DSML tag names use a leading space.** Tool calls are wrapped in
|
| 13 |
+
`<|DSML| calls>` blocks with `<|DSML| invoke>` / `<|DSML| parameter>` tags
|
| 14 |
+
(note the space before `calls`, `invoke`, and `parameter`). The V4 format used
|
| 15 |
+
`<|DSML|tool_calls>` without a space.
|
| 16 |
+
|
| 17 |
+
2. **Reasoning effort is a numeric budget (1–100).** The effort prefix is
|
| 18 |
+
rendered as `Reasoning Effort: {budget} (range 1-100, ...)` rather than the
|
| 19 |
+
verbose natural-language descriptions used in V4. String aliases map as
|
| 20 |
+
follows: `"low"` → 50, `"high"` → 75, `"max"` → 100. The
|
| 21 |
+
default is `"high"` (75). The effort prefix is only rendered in
|
| 22 |
+
`thinking_mode="thinking"` and only at the beginning of the conversation
|
| 23 |
+
(index 0).
|
| 24 |
+
|
| 25 |
+
3. **Mid-conversation system messages** are supported via the `<|System|>` token.
|
| 26 |
+
A mid-conversation system message behaves like a user message for the purpose
|
| 27 |
+
of appending the assistant generation header.
|
| 28 |
+
|
| 29 |
+
## Quick start
|
| 30 |
+
|
| 31 |
+
```python
|
| 32 |
+
from encoding import encode_messages, parse_message_from_completion_text
|
| 33 |
+
|
| 34 |
+
# Text-only conversation
|
| 35 |
+
messages = [
|
| 36 |
+
{"role": "system", "content": "You are a helpful assistant."},
|
| 37 |
+
{"role": "user", "content": "What is 2+2?"},
|
| 38 |
+
]
|
| 39 |
+
prompt, media = encode_messages(
|
| 40 |
+
messages,
|
| 41 |
+
thinking_mode="thinking",
|
| 42 |
+
reasoning_effort=75, # integer 1–100, or "low"/"high"/"max"
|
| 43 |
+
return_multi_modal_data=True,
|
| 44 |
+
)
|
| 45 |
+
# prompt:
|
| 46 |
+
# '<|begin▁of▁sentence|><|System|>Reasoning Effort: 75 (range 1-100, the higher the
|
| 47 |
+
# value, the more thorough the reasoning)\n\nYou are a helpful assistant.
|
| 48 |
+
# <|User|>What is 2+2?<|Assistant|><think>'
|
| 49 |
+
|
| 50 |
+
# Parse model output back to a structured message
|
| 51 |
+
completion = "Simple arithmetic.</think>2 + 2 = 4.<|end▁of▁sentence|>"
|
| 52 |
+
parsed = parse_message_from_completion_text(completion, thinking_mode="thinking")
|
| 53 |
+
# => {"role": "assistant", "reasoning_content": "Simple arithmetic.",
|
| 54 |
+
# "content": "2 + 2 = 4.", "tool_calls": []}
|
| 55 |
+
```
|
| 56 |
+
|
| 57 |
+
> **Note:** `parse_message_from_completion_text` is designed to handle
|
| 58 |
+
> well-formatted model output only. It does not attempt to correct or recover
|
| 59 |
+
> from malformed output that the model might occasionally generate. For
|
| 60 |
+
> production use, additional error handling is recommended.
|
| 61 |
+
|
| 62 |
+
## OpenAI-style messages
|
| 63 |
+
|
| 64 |
+
```python
|
| 65 |
+
from encoding import encode_messages
|
| 66 |
+
|
| 67 |
+
messages = [{
|
| 68 |
+
"role": "user",
|
| 69 |
+
"content": [
|
| 70 |
+
{"type": "text", "text": "第一张图"},
|
| 71 |
+
{
|
| 72 |
+
"type": "image_url",
|
| 73 |
+
"image_url": {"url": "examples/images/image_1.jpeg"},
|
| 74 |
+
},
|
| 75 |
+
{"type": "text", "text": "有什么内容?"},
|
| 76 |
+
],
|
| 77 |
+
}]
|
| 78 |
+
|
| 79 |
+
prompt, media = encode_messages(
|
| 80 |
+
messages,
|
| 81 |
+
thinking_mode="chat",
|
| 82 |
+
return_multi_modal_data=True,
|
| 83 |
+
)
|
| 84 |
+
# prompt:
|
| 85 |
+
# '<|begin▁of▁sentence|><|User|>第一张图\n\n<|deepseek_image|>\n\n有什么内容?<|Assistant|></think>'
|
| 86 |
+
# media["images"] contains the image records in prompt order
|
| 87 |
+
```
|
| 88 |
+
|
| 89 |
+
Images are represented in the prompt by `<|deepseek_image|>`. `media["images"]`
|
| 90 |
+
contains the corresponding image records in exactly the same order they appear in
|
| 91 |
+
the prompt. Pixel loading and expansion into model image tokens are handled by
|
| 92 |
+
`inference/image_processor.py`.
|
| 93 |
+
|
| 94 |
+
## Compact TXT notation
|
| 95 |
+
|
| 96 |
+
`parse_tagged_text()` converts a compact prompt such as
|
| 97 |
+
|
| 98 |
+
```text
|
| 99 |
+
第一张图<image>examples/images/image_1.jpeg</image>有什么内容?
|
| 100 |
+
```
|
| 101 |
+
|
| 102 |
+
into the same standard content blocks. It is an input convenience layer, not a
|
| 103 |
+
second encoding implementation.
|
| 104 |
+
|
| 105 |
+
## Message format
|
| 106 |
+
|
| 107 |
+
### Special tokens
|
| 108 |
+
|
| 109 |
+
| Token | Purpose |
|
| 110 |
+
| :--- | :--- |
|
| 111 |
+
| `<|begin▁of▁sentence|>` | Beginning of sequence (BOS) |
|
| 112 |
+
| `<|end▁of▁sentence|>` | End of assistant turn (EOS) |
|
| 113 |
+
| `<|User|>` | User turn prefix |
|
| 114 |
+
| `<|Assistant|>` | Assistant turn prefix |
|
| 115 |
+
| `<|System|>` | Mid-conversation system message prefix |
|
| 116 |
+
| `<|latest_reminder|>` | Latest reminder (date, locale, etc.) |
|
| 117 |
+
| `<think>` / `</think>` | Reasoning block delimiters |
|
| 118 |
+
| `|DSML|` | DSML markup token |
|
| 119 |
+
| `<|deepseek_image|>` | Image placeholder in the prompt string |
|
| 120 |
+
|
| 121 |
+
### Roles
|
| 122 |
+
|
| 123 |
+
The encoding supports the following message roles: `system`, `user`, `assistant`,
|
| 124 |
+
`tool`, and `latest_reminder`.
|
| 125 |
+
|
| 126 |
+
A `tool` message is not rendered directly: `merge_tool_messages()` converts it
|
| 127 |
+
into a `<tool_result>` block inside the preceding user message. When multiple
|
| 128 |
+
tool results are present, they are sorted by the order of the corresponding
|
| 129 |
+
`tool_calls` in the preceding assistant message.
|
| 130 |
+
|
| 131 |
+
### Basic chat
|
| 132 |
+
|
| 133 |
+
A simple multi-turn conversation is encoded as:
|
| 134 |
+
|
| 135 |
+
```
|
| 136 |
+
<|begin▁of▁sentence|>{system_prompt}
|
| 137 |
+
<|User|>{user_message}<|Assistant|></think>{response}<|end▁of▁sentence|>
|
| 138 |
+
<|User|>{user_message_2}<|Assistant|></think>{response_2}<|end▁of▁sentence|>
|
| 139 |
+
```
|
| 140 |
+
|
| 141 |
+
- The BOS token is prepended at the very beginning of the conversation.
|
| 142 |
+
- In **chat mode** (`thinking_mode="chat"`), `</think>` is placed right after
|
| 143 |
+
`<|Assistant|>` to immediately close the thinking block, so the model generates
|
| 144 |
+
content directly.
|
| 145 |
+
|
| 146 |
+
### Thinking mode
|
| 147 |
+
|
| 148 |
+
In **thinking mode** (`thinking_mode="thinking"`), the model produces explicit
|
| 149 |
+
reasoning inside `<think>...</think>` blocks before responding.
|
| 150 |
+
|
| 151 |
+
```
|
| 152 |
+
<|begin▁of▁sentence|><|System|>{reasoning_effort_prefix}{system_prompt}
|
| 153 |
+
<|User|>{message}<|Assistant|><think>{reasoning}</think>{response}<|end▁of▁sentence|>
|
| 154 |
+
```
|
| 155 |
+
|
| 156 |
+
The reasoning effort prefix is injected once, before the system message, as a
|
| 157 |
+
`<|System|>` block:
|
| 158 |
+
|
| 159 |
+
```
|
| 160 |
+
<|System|>Reasoning Effort: {budget} (range 1-100, the higher the value, the more thorough the reasoning)
|
| 161 |
+
```
|
| 162 |
+
|
| 163 |
+
The `drop_thinking` parameter (default `True`) controls whether reasoning from
|
| 164 |
+
earlier turns is preserved:
|
| 165 |
+
|
| 166 |
+
- **Without tools**: reasoning content from assistant turns **before** the last
|
| 167 |
+
user message is stripped. Only the final assistant turn retains its
|
| 168 |
+
`<think>...</think>` block.
|
| 169 |
+
- **With tools**: `drop_thinking` is automatically disabled. All turns retain
|
| 170 |
+
their reasoning, because tool-calling conversations require full context for
|
| 171 |
+
the model to track multi-step reasoning across tool calls.
|
| 172 |
+
|
| 173 |
+
### Tool calling (DSML format)
|
| 174 |
+
|
| 175 |
+
Tools are defined on the `system` message via the `tools` field
|
| 176 |
+
(OpenAI-compatible format). When tools are present, the following schema block is
|
| 177 |
+
injected into the system prompt:
|
| 178 |
+
|
| 179 |
+
```
|
| 180 |
+
## Tools
|
| 181 |
+
|
| 182 |
+
You have access to a set of tools to help answer the user's question. You can invoke tools by writing a "<|DSML| calls>" block like the following:
|
| 183 |
+
|
| 184 |
+
<|DSML| calls>
|
| 185 |
+
<|DSML| invoke name="$TOOL_NAME">
|
| 186 |
+
<|DSML| parameter name="$PARAMETER_NAME" string="true|false">$PARAMETER_VALUE</|DSML| parameter>
|
| 187 |
+
...
|
| 188 |
+
</|DSML| invoke>
|
| 189 |
+
<|DSML| invoke name="$TOOL_NAME2">
|
| 190 |
+
...
|
| 191 |
+
</|DSML| invoke>
|
| 192 |
+
</|DSML| calls>
|
| 193 |
+
|
| 194 |
+
String parameters should be specified as is and set `string="true"`. For all other types (numbers, booleans, arrays, objects), pass the value in JSON format and set `string="false"`.
|
| 195 |
+
|
| 196 |
+
If thinking_mode is enabled (triggered by <think>), you MUST output your complete reasoning inside <think>...</think> BEFORE any tool calls or final response.
|
| 197 |
+
|
| 198 |
+
Otherwise, output directly after </think> with tool calls or final response.
|
| 199 |
+
|
| 200 |
+
### Available Tool Schemas
|
| 201 |
+
|
| 202 |
+
{tool_definitions_json}
|
| 203 |
+
|
| 204 |
+
You MUST strictly follow the above defined tool name and parameter schemas to invoke tool calls.
|
| 205 |
+
```
|
| 206 |
+
|
| 207 |
+
An actual tool call in the assistant turn looks like:
|
| 208 |
+
|
| 209 |
+
```xml
|
| 210 |
+
|
| 211 |
+
<|DSML| calls>
|
| 212 |
+
<|DSML| invoke name="function_name">
|
| 213 |
+
<|DSML| parameter name="param" string="true">string_value</|DSML| parameter>
|
| 214 |
+
<|DSML| parameter name="count" string="false">5</|DSML| parameter>
|
| 215 |
+
</|DSML| invoke>
|
| 216 |
+
</|DSML| calls><|end▁of▁sentence|>
|
| 217 |
+
```
|
| 218 |
+
|
| 219 |
+
- `string="true"`: the parameter value is a raw string.
|
| 220 |
+
- `string="false"`: the parameter value is JSON (number, boolean, array, object).
|
| 221 |
+
|
| 222 |
+
Tool execution results are wrapped in `<tool_result>` tags within user messages:
|
| 223 |
+
|
| 224 |
+
```
|
| 225 |
+
<|User|><tool_result>{result_json}</tool_result><|Assistant|><think>...
|
| 226 |
+
```
|
| 227 |
+
|
| 228 |
+
### Tool namespaces
|
| 229 |
+
|
| 230 |
+
Tool definitions may include a `namespace` alongside `function`, either as a
|
| 231 |
+
string or as an object with `name` and an optional `description`:
|
| 232 |
+
|
| 233 |
+
```python
|
| 234 |
+
tool = {
|
| 235 |
+
"type": "function",
|
| 236 |
+
"namespace": {"name": "search", "description": "Search tools."},
|
| 237 |
+
"function": {
|
| 238 |
+
"name": "lookup",
|
| 239 |
+
"description": "Look up a value",
|
| 240 |
+
"parameters": {"type": "object", "properties": {"query": {"type": "string"}}},
|
| 241 |
+
},
|
| 242 |
+
}
|
| 243 |
+
tool_call = {
|
| 244 |
+
"type": "function",
|
| 245 |
+
"namespace": "search",
|
| 246 |
+
"function": {"name": "lookup", "arguments": '{"query": "value"}'},
|
| 247 |
+
}
|
| 248 |
+
```
|
| 249 |
+
|
| 250 |
+
The tool schema and DSML invocation both use `search::lookup`. The namespace
|
| 251 |
+
description is prepended to the tool description, separated by a newline.
|
| 252 |
+
The parser returns `function.name="lookup"` and `namespace="search"` on the
|
| 253 |
+
tool call, so its output can be passed back to `encode_messages()` directly.
|
| 254 |
+
|
| 255 |
+
Input also accepts `namespace` inside `function`, or a qualified function name
|
| 256 |
+
such as `search::lookup`. A qualified name must agree with any explicit
|
| 257 |
+
namespace; `::` separates exactly one namespace from the tool name. Tools
|
| 258 |
+
without a namespace retain their original names and output format.
|
| 259 |
+
|
| 260 |
+
### Reasoning effort
|
| 261 |
+
|
| 262 |
+
Pass `reasoning_effort` as an integer in `[1, 100]` or as one of `"low"` (50),
|
| 263 |
+
`"high"` (75), or `"max"` (100). The default is `"high"` (75).
|
| 264 |
+
The setting only affects `thinking_mode="thinking"` and is only rendered at the
|
| 265 |
+
start of the conversation (index 0). Intermediate values may be used to elicit
|
| 266 |
+
interpolated reasoning behavior.
|
| 267 |
+
|
| 268 |
+
### Quick instruction special tokens
|
| 269 |
+
|
| 270 |
+
Quick instruction tokens are used for auxiliary classification and generation
|
| 271 |
+
tasks. They are appended to messages via the `"task"` field to trigger
|
| 272 |
+
specialized model behavior for a single-token or short-form output.
|
| 273 |
+
|
| 274 |
+
| Special Token | Description | Format |
|
| 275 |
+
|:---|:---|:---|
|
| 276 |
+
| `<|action|>` | Determines whether the user prompt requires a web search or can be answered directly. | `...<|User|>{prompt}<|Assistant|><think><|action|>` |
|
| 277 |
+
| `<|title|>` | Generates a concise conversation title after the first assistant response. | `...<|Assistant|>{response}<|end▁of▁sentence|><|title|>` |
|
| 278 |
+
| `<|query|>` | Generates search queries for the user prompt. | `...<|User|>{prompt}<|query|>` |
|
| 279 |
+
| `<|authority|>` | Classifies the user prompt's demand for source authoritativeness. | `...<|User|>{prompt}<|authority|>` |
|
| 280 |
+
| `<|domain|>` | Identifies the domain of the user prompt. | `...<|User|>{prompt}<|domain|>` |
|
| 281 |
+
| `<|read_url|>` | Determines whether each URL in the user prompt should be fetched and read. | `...<|User|>{prompt}<|read_url|>` |
|
| 282 |
+
|
| 283 |
+
Usage in message format:
|
| 284 |
+
|
| 285 |
+
- **`action`** on a user message: the `<|action|>` token is placed after the
|
| 286 |
+
assistant prefix and thinking token, triggering a routing decision (e.g.,
|
| 287 |
+
"Search" or "Answer").
|
| 288 |
+
- **Other tasks** (`query`, `authority`, `domain`, `read_url`) on a user message:
|
| 289 |
+
the task token is appended directly after the user content.
|
| 290 |
+
- **`title`** on an assistant message: the `<|title|>` token is appended after
|
| 291 |
+
the assistant's EOS. The next assistant message provides the generated title.
|
| 292 |
+
|
| 293 |
+
## Tests
|
| 294 |
+
|
| 295 |
+
From this directory:
|
| 296 |
+
|
| 297 |
+
```bash
|
| 298 |
+
python -m pytest -q test_encoding.py
|
| 299 |
+
```
|
| 300 |
+
|
| 301 |
+
Test cases are stored as paired JSON input / TXT expected-output files under
|
| 302 |
+
`tests/`. The tests cover multi-turn conversations, tool calling, thinking mode,
|
| 303 |
+
numeric reasoning effort, mid-conversation system messages, and multimodal image
|
| 304 |
+
ordering. They include a check that the TXT and JSON examples encode to the same
|
| 305 |
+
prompt and preserve the same image ordering.
|
encoding/encoding.py
ADDED
|
@@ -0,0 +1,979 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""
|
| 2 |
+
DeepSeek-V4.1 Text and Vision Encoding
|
| 3 |
+
|
| 4 |
+
A fully self-contained implementation for encoding/decoding DeepSeek-V4.1 chat
|
| 5 |
+
messages with tool calling, thinking mode, quick instruction tasks, and image
|
| 6 |
+
content blocks. No dependency on encoding_dsv4.
|
| 7 |
+
|
| 8 |
+
V4.1 changes relative to V4:
|
| 9 |
+
|
| 10 |
+
1. DSML tag names: tool calls are wrapped in "<|DSML| calls>" blocks with
|
| 11 |
+
"<|DSML| invoke>" / "<|DSML| parameter>" tags (leading-space tag names).
|
| 12 |
+
2. Numeric reasoning effort: "Reasoning Effort: {budget} (range 1-100, ...)".
|
| 13 |
+
Accepts an int in [1, 100] or one of "low"/"high"/"max"
|
| 14 |
+
(mapped to 50/75/100). Defaults to "high". Only rendered in thinking mode.
|
| 15 |
+
3. Mid-conversation system messages are supported via the "<|System|>" token.
|
| 16 |
+
A mid-conversation system message behaves like a user message for the purpose
|
| 17 |
+
of appending the assistant generation header.
|
| 18 |
+
"""
|
| 19 |
+
|
| 20 |
+
from typing import Any, Dict, List, Union, Optional, Tuple
|
| 21 |
+
import copy
|
| 22 |
+
import json
|
| 23 |
+
import re
|
| 24 |
+
|
| 25 |
+
# ============================================================
|
| 26 |
+
# Special Tokens
|
| 27 |
+
# ============================================================
|
| 28 |
+
|
| 29 |
+
bos_token: str = "<|begin▁of▁sentence|>"
|
| 30 |
+
eos_token: str = "<|end▁of▁sentence|>"
|
| 31 |
+
thinking_start_token: str = "<think>"
|
| 32 |
+
thinking_end_token: str = "</think>"
|
| 33 |
+
dsml_token: str = "|DSML|"
|
| 34 |
+
|
| 35 |
+
USER_SP_TOKEN = "<|User|>"
|
| 36 |
+
ASSISTANT_SP_TOKEN = "<|Assistant|>"
|
| 37 |
+
LATEST_REMINDER_SP_TOKEN = "<|latest_reminder|>"
|
| 38 |
+
|
| 39 |
+
IMAGE_PLACEHOLDER = "<|deepseek_image|>"
|
| 40 |
+
IMAGE_TAG_PATTERN = re.compile(r"<image>(.*?)</image>", re.DOTALL)
|
| 41 |
+
|
| 42 |
+
# Task special tokens for internal classification tasks
|
| 43 |
+
DS_TASK_SP_TOKENS = {
|
| 44 |
+
"action": "<|action|>",
|
| 45 |
+
"query": "<|query|>",
|
| 46 |
+
"authority": "<|authority|>",
|
| 47 |
+
"domain": "<|domain|>",
|
| 48 |
+
"title": "<|title|>",
|
| 49 |
+
"read_url": "<|read_url|>",
|
| 50 |
+
}
|
| 51 |
+
VALID_TASKS = set(DS_TASK_SP_TOKENS.keys())
|
| 52 |
+
|
| 53 |
+
# ============================================================
|
| 54 |
+
# Templates
|
| 55 |
+
# ============================================================
|
| 56 |
+
|
| 57 |
+
system_msg_template: str = "{content}"
|
| 58 |
+
user_msg_template: str = "{content}"
|
| 59 |
+
latest_reminder_msg_template: str = "{content}"
|
| 60 |
+
assistant_msg_template: str = "{reasoning}{content}{tool_calls}" + eos_token
|
| 61 |
+
assistant_msg_wo_eos_template: str = "{reasoning}{content}{tool_calls}"
|
| 62 |
+
thinking_template: str = "{reasoning_content}"
|
| 63 |
+
|
| 64 |
+
response_format_template: str = (
|
| 65 |
+
"## Response Format:\n\nYou MUST strictly adhere to the following schema to reply:\n{schema}"
|
| 66 |
+
)
|
| 67 |
+
|
| 68 |
+
tool_output_template: str = (
|
| 69 |
+
"<tool_result>{content}</tool_result>"
|
| 70 |
+
)
|
| 71 |
+
|
| 72 |
+
# ============================================================
|
| 73 |
+
# Utility Functions
|
| 74 |
+
# ============================================================
|
| 75 |
+
|
| 76 |
+
def to_json(value: Any) -> str:
|
| 77 |
+
"""Serialize a value to JSON string."""
|
| 78 |
+
try:
|
| 79 |
+
return json.dumps(value, ensure_ascii=False)
|
| 80 |
+
except:
|
| 81 |
+
return json.dumps(value, ensure_ascii=True)
|
| 82 |
+
|
| 83 |
+
|
| 84 |
+
def tools_from_openai_format(tools):
|
| 85 |
+
"""Extract function definitions with namespace-qualified names."""
|
| 86 |
+
functions = []
|
| 87 |
+
for tool in tools:
|
| 88 |
+
function = dict(tool["function"])
|
| 89 |
+
if tool.get("namespace") is not None:
|
| 90 |
+
function["namespace"] = tool["namespace"]
|
| 91 |
+
function["name"] = _tool_name_for_encoding(function)
|
| 92 |
+
namespace = function.pop("namespace", None)
|
| 93 |
+
if isinstance(namespace, dict) and namespace.get("description"):
|
| 94 |
+
function["description"] = (
|
| 95 |
+
namespace["description"] + "\n" + (function.get("description") or "")
|
| 96 |
+
)
|
| 97 |
+
functions.append(function)
|
| 98 |
+
return functions
|
| 99 |
+
|
| 100 |
+
|
| 101 |
+
def _split_tool_name(name: str, namespace: Optional[str] = None) -> Tuple[Optional[str], str]:
|
| 102 |
+
"""Split a qualified name and validate any explicit namespace."""
|
| 103 |
+
prefix, separator, bare_name = name.partition("::")
|
| 104 |
+
if separator:
|
| 105 |
+
assert namespace in (None, prefix), (
|
| 106 |
+
f"Conflicting tool namespaces: {namespace} != {prefix}"
|
| 107 |
+
)
|
| 108 |
+
namespace, name = prefix, bare_name
|
| 109 |
+
assert "::" not in name, f"Tool name must not contain '::': {name}"
|
| 110 |
+
assert namespace is None or "::" not in namespace, (
|
| 111 |
+
f"Tool namespace must not contain '::': {namespace}"
|
| 112 |
+
)
|
| 113 |
+
return namespace, name
|
| 114 |
+
|
| 115 |
+
|
| 116 |
+
def _tool_name_for_encoding(tool: Dict[str, Any]) -> str:
|
| 117 |
+
namespace = tool.get("namespace")
|
| 118 |
+
if isinstance(namespace, dict):
|
| 119 |
+
namespace = namespace["name"]
|
| 120 |
+
namespace, name = _split_tool_name(tool["name"], namespace)
|
| 121 |
+
return name if namespace is None else f"{namespace}::{name}"
|
| 122 |
+
|
| 123 |
+
|
| 124 |
+
def tool_calls_from_openai_format(tool_calls):
|
| 125 |
+
"""Convert OpenAI-format tool calls to internal format."""
|
| 126 |
+
calls = []
|
| 127 |
+
for tool_call in tool_calls:
|
| 128 |
+
function = tool_call["function"]
|
| 129 |
+
namespace, name = _split_tool_name(
|
| 130 |
+
function["name"], tool_call.get("namespace") or function.get("namespace")
|
| 131 |
+
)
|
| 132 |
+
call = {"name": name, "arguments": function["arguments"]}
|
| 133 |
+
if namespace is not None:
|
| 134 |
+
call["namespace"] = namespace
|
| 135 |
+
calls.append(call)
|
| 136 |
+
return calls
|
| 137 |
+
|
| 138 |
+
|
| 139 |
+
def tool_calls_to_openai_format(tool_calls):
|
| 140 |
+
"""Convert internal tool calls to OpenAI format."""
|
| 141 |
+
calls = []
|
| 142 |
+
for tool_call in tool_calls:
|
| 143 |
+
call = {
|
| 144 |
+
"type": "function",
|
| 145 |
+
"function": {
|
| 146 |
+
"name": tool_call["name"],
|
| 147 |
+
"arguments": tool_call["arguments"],
|
| 148 |
+
}
|
| 149 |
+
}
|
| 150 |
+
if tool_call.get("namespace") is not None:
|
| 151 |
+
call["namespace"] = tool_call["namespace"]
|
| 152 |
+
calls.append(call)
|
| 153 |
+
return calls
|
| 154 |
+
|
| 155 |
+
|
| 156 |
+
def decode_dsml_to_arguments(tool_name: str, tool_args: Dict[str, Tuple[str, str]]) -> Dict[str, str]:
|
| 157 |
+
"""
|
| 158 |
+
Decode DSML parameters back to a tool call dict.
|
| 159 |
+
|
| 160 |
+
Args:
|
| 161 |
+
tool_name: Name of the tool.
|
| 162 |
+
tool_args: Dict mapping param_name -> (value, is_string_flag).
|
| 163 |
+
|
| 164 |
+
Returns:
|
| 165 |
+
Dict with "name", "arguments" (JSON string), and optional "namespace".
|
| 166 |
+
"""
|
| 167 |
+
def _decode_value(key: str, value: str, string: str):
|
| 168 |
+
if string == "true":
|
| 169 |
+
value = to_json(value)
|
| 170 |
+
return f"{to_json(key)}: {value}"
|
| 171 |
+
|
| 172 |
+
tool_args_json = "{" + ", ".join([_decode_value(k, v, string=is_str) for k, (v, is_str) in tool_args.items()]) + "}"
|
| 173 |
+
namespace, name = _split_tool_name(tool_name)
|
| 174 |
+
tool_call = dict(name=name, arguments=tool_args_json)
|
| 175 |
+
if namespace is not None:
|
| 176 |
+
tool_call["namespace"] = namespace
|
| 177 |
+
return tool_call
|
| 178 |
+
|
| 179 |
+
|
| 180 |
+
# ============================================================
|
| 181 |
+
# Preprocessing
|
| 182 |
+
# ============================================================
|
| 183 |
+
|
| 184 |
+
def merge_tool_messages(messages: List[Dict[str, Any]]) -> List[Dict[str, Any]]:
|
| 185 |
+
"""
|
| 186 |
+
Merge tool messages into the preceding user message using content_blocks format.
|
| 187 |
+
|
| 188 |
+
DeepSeek-V4.1 does not have a standalone "tool" role; instead, tool results
|
| 189 |
+
are encoded as <tool_result> blocks within user messages.
|
| 190 |
+
"""
|
| 191 |
+
merged: List[Dict[str, Any]] = []
|
| 192 |
+
|
| 193 |
+
for msg in messages:
|
| 194 |
+
msg = copy.deepcopy(msg)
|
| 195 |
+
role = msg.get("role")
|
| 196 |
+
|
| 197 |
+
if role == "tool":
|
| 198 |
+
# Convert tool message to a user message with tool_result block
|
| 199 |
+
tool_block = {
|
| 200 |
+
"type": "tool_result",
|
| 201 |
+
"tool_use_id": msg.get("tool_call_id", ""),
|
| 202 |
+
"content": msg.get("content", ""),
|
| 203 |
+
}
|
| 204 |
+
# Merge into previous message if it's already a user (merged tool)
|
| 205 |
+
if merged and merged[-1].get("role") == "user" and "content_blocks" in merged[-1]:
|
| 206 |
+
merged[-1]["content_blocks"].append(tool_block)
|
| 207 |
+
else:
|
| 208 |
+
merged.append({
|
| 209 |
+
"role": "user",
|
| 210 |
+
"content_blocks": [tool_block],
|
| 211 |
+
})
|
| 212 |
+
elif role == "user":
|
| 213 |
+
content_blocks = msg.get("content_blocks")
|
| 214 |
+
if content_blocks is None:
|
| 215 |
+
content_blocks = [{"type": "text", "text": msg.get("content", "")}]
|
| 216 |
+
if merged and merged[-1].get("role") == "user" and "content_blocks" in merged[-1] and merged[-1].get("task") is None:
|
| 217 |
+
merged[-1]["content_blocks"].extend(content_blocks)
|
| 218 |
+
else:
|
| 219 |
+
# Preserve structured content and all message-level metadata.
|
| 220 |
+
new_msg = msg
|
| 221 |
+
new_msg["content_blocks"] = content_blocks
|
| 222 |
+
merged.append(new_msg)
|
| 223 |
+
else:
|
| 224 |
+
merged.append(msg)
|
| 225 |
+
|
| 226 |
+
return merged
|
| 227 |
+
|
| 228 |
+
|
| 229 |
+
def sort_tool_results_by_call_order(messages: List[Dict[str, Any]]) -> List[Dict[str, Any]]:
|
| 230 |
+
"""
|
| 231 |
+
Sort tool_result blocks within user messages by the order of tool_calls
|
| 232 |
+
in the preceding assistant message.
|
| 233 |
+
"""
|
| 234 |
+
last_tool_call_order: Dict[str, int] = {}
|
| 235 |
+
|
| 236 |
+
for msg in messages:
|
| 237 |
+
role = msg.get("role")
|
| 238 |
+
if role == "assistant" and msg.get("tool_calls"):
|
| 239 |
+
last_tool_call_order = {}
|
| 240 |
+
for idx, tc in enumerate(msg["tool_calls"]):
|
| 241 |
+
tc_id = tc.get("id") or tc.get("function", {}).get("id", "")
|
| 242 |
+
if tc_id:
|
| 243 |
+
last_tool_call_order[tc_id] = idx
|
| 244 |
+
|
| 245 |
+
elif role == "user" and msg.get("content_blocks"):
|
| 246 |
+
tool_blocks = [b for b in msg["content_blocks"] if b.get("type") == "tool_result"]
|
| 247 |
+
if len(tool_blocks) > 1 and last_tool_call_order:
|
| 248 |
+
sorted_blocks = sorted(
|
| 249 |
+
tool_blocks,
|
| 250 |
+
key=lambda b: last_tool_call_order.get(b.get("tool_use_id", ""), 0)
|
| 251 |
+
)
|
| 252 |
+
sorted_idx = 0
|
| 253 |
+
new_blocks = []
|
| 254 |
+
for block in msg["content_blocks"]:
|
| 255 |
+
if block.get("type") == "tool_result":
|
| 256 |
+
new_blocks.append(sorted_blocks[sorted_idx])
|
| 257 |
+
sorted_idx += 1
|
| 258 |
+
else:
|
| 259 |
+
new_blocks.append(block)
|
| 260 |
+
msg["content_blocks"] = new_blocks
|
| 261 |
+
|
| 262 |
+
return messages
|
| 263 |
+
|
| 264 |
+
|
| 265 |
+
# ============================================================
|
| 266 |
+
# Vision Message Preprocessing
|
| 267 |
+
# ============================================================
|
| 268 |
+
|
| 269 |
+
def parse_tagged_text(text: str) -> Union[str, List[Dict[str, Any]]]:
|
| 270 |
+
"""Convert ``<image>path</image>`` text into standard content blocks."""
|
| 271 |
+
matches = list(IMAGE_TAG_PATTERN.finditer(text))
|
| 272 |
+
remaining = IMAGE_TAG_PATTERN.sub("", text)
|
| 273 |
+
if "<image>" in remaining or "</image>" in remaining:
|
| 274 |
+
raise ValueError("Malformed <image>path</image> tag")
|
| 275 |
+
if not matches:
|
| 276 |
+
return text
|
| 277 |
+
|
| 278 |
+
blocks: List[Dict[str, Any]] = []
|
| 279 |
+
cursor = 0
|
| 280 |
+
for match in matches:
|
| 281 |
+
if match.start() > cursor:
|
| 282 |
+
blocks.append({"type": "text", "text": text[cursor:match.start()]})
|
| 283 |
+
path = match.group(1)
|
| 284 |
+
if not path:
|
| 285 |
+
raise ValueError("Image path must not be empty")
|
| 286 |
+
blocks.append({
|
| 287 |
+
"type": "image_url",
|
| 288 |
+
"image_url": {"url": path},
|
| 289 |
+
})
|
| 290 |
+
cursor = match.end()
|
| 291 |
+
if cursor < len(text):
|
| 292 |
+
blocks.append({"type": "text", "text": text[cursor:]})
|
| 293 |
+
return blocks
|
| 294 |
+
|
| 295 |
+
|
| 296 |
+
def _is_image_block(block: Dict[str, Any]) -> bool:
|
| 297 |
+
"""Return whether a content block is an OpenAI/Anthropic/internal image."""
|
| 298 |
+
return isinstance(block, dict) and block.get("type") in ("image", "image_url")
|
| 299 |
+
|
| 300 |
+
|
| 301 |
+
def _extract_image(block: Dict[str, Any]) -> Dict[str, Any]:
|
| 302 |
+
"""Normalize a supported image block into an internal image record."""
|
| 303 |
+
record: Dict[str, Any] = {"type": "image"}
|
| 304 |
+
if block.get("type") == "image_url":
|
| 305 |
+
image_url = block.get("image_url")
|
| 306 |
+
if isinstance(image_url, str):
|
| 307 |
+
record["url"] = image_url
|
| 308 |
+
else:
|
| 309 |
+
record["url"] = (image_url or {}).get("url", "")
|
| 310 |
+
else:
|
| 311 |
+
for key in ("source", "url", "data"):
|
| 312 |
+
if key in block:
|
| 313 |
+
record[key] = block[key]
|
| 314 |
+
if not any(record.get(key) for key in ("source", "url", "data")):
|
| 315 |
+
raise ValueError("Image block does not contain a valid source")
|
| 316 |
+
return record
|
| 317 |
+
|
| 318 |
+
|
| 319 |
+
def _process_image_blocks(
|
| 320 |
+
blocks: List[Any], image_placeholder: str = IMAGE_PLACEHOLDER
|
| 321 |
+
) -> Tuple[List[Any], List[Dict[str, Any]]]:
|
| 322 |
+
"""Replace image blocks and collect their records in one ordered traversal."""
|
| 323 |
+
new_blocks: List[Any] = []
|
| 324 |
+
images: List[Dict[str, Any]] = []
|
| 325 |
+
for block in blocks:
|
| 326 |
+
if not isinstance(block, dict):
|
| 327 |
+
new_blocks.append(block)
|
| 328 |
+
continue
|
| 329 |
+
if _is_image_block(block):
|
| 330 |
+
new_blocks.append({"type": "text", "text": image_placeholder})
|
| 331 |
+
images.append(_extract_image(block))
|
| 332 |
+
elif block.get("type") == "tool_result" and isinstance(block.get("content"), list):
|
| 333 |
+
block = copy.copy(block)
|
| 334 |
+
block["content"], nested_images = _process_image_blocks(
|
| 335 |
+
block["content"], image_placeholder)
|
| 336 |
+
new_blocks.append(block)
|
| 337 |
+
images.extend(nested_images)
|
| 338 |
+
elif block.get("type") == "text":
|
| 339 |
+
text = block.get("text") or ""
|
| 340 |
+
if IMAGE_PLACEHOLDER in text:
|
| 341 |
+
raise ValueError(
|
| 342 |
+
f"Text block contains image placeholder '{IMAGE_PLACEHOLDER}': "
|
| 343 |
+
f"'{text[:100]}'. Images should be separate content blocks."
|
| 344 |
+
)
|
| 345 |
+
new_blocks.append(block)
|
| 346 |
+
else:
|
| 347 |
+
new_blocks.append(block)
|
| 348 |
+
return new_blocks, images
|
| 349 |
+
|
| 350 |
+
|
| 351 |
+
def _validate_no_image_sp_tokens(msg: Dict[str, Any]) -> None:
|
| 352 |
+
"""Reject user-supplied image placeholder tokens in textual fields."""
|
| 353 |
+
content = msg.get("content")
|
| 354 |
+
if isinstance(content, str) and IMAGE_PLACEHOLDER in content:
|
| 355 |
+
raise ValueError(
|
| 356 |
+
f"Message content contains image special token '{IMAGE_PLACEHOLDER}'. "
|
| 357 |
+
"Images should be provided as image content blocks."
|
| 358 |
+
)
|
| 359 |
+
reasoning_content = msg.get("reasoning_content")
|
| 360 |
+
if isinstance(reasoning_content, str) and IMAGE_PLACEHOLDER in reasoning_content:
|
| 361 |
+
raise ValueError(
|
| 362 |
+
f"reasoning_content contains image special token '{IMAGE_PLACEHOLDER}'"
|
| 363 |
+
)
|
| 364 |
+
|
| 365 |
+
|
| 366 |
+
def process_image_messages(
|
| 367 |
+
messages: List[Dict[str, Any]],
|
| 368 |
+
) -> Tuple[List[Dict[str, Any]], List[Dict[str, Any]]]:
|
| 369 |
+
"""Normalize image blocks and return their records in prompt order."""
|
| 370 |
+
processed: List[Dict[str, Any]] = []
|
| 371 |
+
images: List[Dict[str, Any]] = []
|
| 372 |
+
for msg in messages:
|
| 373 |
+
msg = copy.deepcopy(msg)
|
| 374 |
+
_validate_no_image_sp_tokens(msg)
|
| 375 |
+
|
| 376 |
+
if isinstance(msg.get("content"), list) and "content_blocks" not in msg:
|
| 377 |
+
msg["content_blocks"] = msg.pop("content")
|
| 378 |
+
|
| 379 |
+
if msg.get("content_blocks"):
|
| 380 |
+
msg["content_blocks"], message_images = _process_image_blocks(
|
| 381 |
+
msg["content_blocks"])
|
| 382 |
+
images.extend(message_images)
|
| 383 |
+
if not isinstance(msg.get("content"), str):
|
| 384 |
+
texts = [
|
| 385 |
+
block.get("text", "")
|
| 386 |
+
for block in msg["content_blocks"]
|
| 387 |
+
if isinstance(block, dict) and block.get("type") == "text"
|
| 388 |
+
]
|
| 389 |
+
msg["content"] = "\n\n".join(texts)
|
| 390 |
+
|
| 391 |
+
processed.append(msg)
|
| 392 |
+
return processed, images
|
| 393 |
+
|
| 394 |
+
|
| 395 |
+
def _read_until_stop(index: int, text: str, stop: List[str]) -> Tuple[int, str, Optional[str]]:
|
| 396 |
+
"""
|
| 397 |
+
Read text from index until one of the stop strings is found.
|
| 398 |
+
|
| 399 |
+
Returns:
|
| 400 |
+
Tuple of (new_index, content_before_stop, matched_stop_string_or_None).
|
| 401 |
+
"""
|
| 402 |
+
min_pos = len(text)
|
| 403 |
+
matched_stop = None
|
| 404 |
+
|
| 405 |
+
for s in stop:
|
| 406 |
+
pos = text.find(s, index)
|
| 407 |
+
if pos != -1 and pos < min_pos:
|
| 408 |
+
min_pos = pos
|
| 409 |
+
matched_stop = s
|
| 410 |
+
|
| 411 |
+
if matched_stop:
|
| 412 |
+
content = text[index:min_pos]
|
| 413 |
+
return min_pos + len(matched_stop), content, matched_stop
|
| 414 |
+
else:
|
| 415 |
+
content = text[index:]
|
| 416 |
+
return len(text), content, None
|
| 417 |
+
|
| 418 |
+
# ============================================================
|
| 419 |
+
# V4.1 Special Tokens and DSML Tag Names
|
| 420 |
+
# ============================================================
|
| 421 |
+
|
| 422 |
+
SYSTEM_SP_TOKEN = "<|System|>"
|
| 423 |
+
|
| 424 |
+
tool_calls_block_name: str = " calls"
|
| 425 |
+
tool_call_tag_name: str = " invoke"
|
| 426 |
+
tool_parameter_tag_name: str = " parameter"
|
| 427 |
+
|
| 428 |
+
tool_call_template: str = (
|
| 429 |
+
"<{dsml_token}{tool_call_tag_name} name=\"{name}\">\n{arguments}\n</{dsml_token}{tool_call_tag_name}>"
|
| 430 |
+
)
|
| 431 |
+
tool_calls_template = (
|
| 432 |
+
"<{dsml_token}{tc_block_name}>\n{tool_calls}\n</{dsml_token}{tc_block_name}>"
|
| 433 |
+
)
|
| 434 |
+
|
| 435 |
+
# ============================================================
|
| 436 |
+
# Reasoning Effort (numeric budget)
|
| 437 |
+
# ============================================================
|
| 438 |
+
|
| 439 |
+
REASONING_EFFORT_TEMPLATE = (
|
| 440 |
+
"Reasoning Effort: {budget} "
|
| 441 |
+
"(range 1-100, the higher the value, the more thorough the reasoning)\n\n"
|
| 442 |
+
)
|
| 443 |
+
|
| 444 |
+
REASONING_EFFORT_MAPPINGS: Dict[str, int] = {
|
| 445 |
+
"low": 50,
|
| 446 |
+
"high": 75,
|
| 447 |
+
"max": 100,
|
| 448 |
+
}
|
| 449 |
+
DEFAULT_REASONING_EFFORT = "high"
|
| 450 |
+
|
| 451 |
+
|
| 452 |
+
def render_reasoning_effort(
|
| 453 |
+
index: int,
|
| 454 |
+
thinking_mode: str,
|
| 455 |
+
effort: Union[str, int, None],
|
| 456 |
+
) -> str:
|
| 457 |
+
"""Render the V4.1 numeric reasoning effort prefix (thinking mode, index 0 only)."""
|
| 458 |
+
if effort is None:
|
| 459 |
+
effort = DEFAULT_REASONING_EFFORT
|
| 460 |
+
assert (
|
| 461 |
+
type(effort) is int and 1 <= effort <= 100
|
| 462 |
+
) or effort in REASONING_EFFORT_MAPPINGS, (
|
| 463 |
+
"Invalid reasoning effort for deepseek_v41: "
|
| 464 |
+
f"{effort}, should be int within [1,100] or {list(REASONING_EFFORT_MAPPINGS)}"
|
| 465 |
+
)
|
| 466 |
+
if type(effort) is str:
|
| 467 |
+
effort = REASONING_EFFORT_MAPPINGS[effort]
|
| 468 |
+
if index == 0 and thinking_mode == "thinking":
|
| 469 |
+
return REASONING_EFFORT_TEMPLATE.format(budget=effort)
|
| 470 |
+
return ""
|
| 471 |
+
|
| 472 |
+
|
| 473 |
+
# ============================================================
|
| 474 |
+
# Tools rendering
|
| 475 |
+
# ============================================================
|
| 476 |
+
|
| 477 |
+
TOOLS_TEMPLATE = """## Tools
|
| 478 |
+
|
| 479 |
+
You have access to a set of tools to help answer the user's question. You can invoke tools by writing a "<{dsml_token}{tc_block_name}>" block like the following:
|
| 480 |
+
|
| 481 |
+
<{dsml_token}{tc_block_name}>
|
| 482 |
+
<{dsml_token}{tool_call_tag_name} name="$TOOL_NAME">
|
| 483 |
+
<{dsml_token}{tool_parameter_tag_name} name="$PARAMETER_NAME" string="true|false">$PARAMETER_VALUE</{dsml_token}{tool_parameter_tag_name}>
|
| 484 |
+
...
|
| 485 |
+
</{dsml_token}{tool_call_tag_name}>
|
| 486 |
+
<{dsml_token}{tool_call_tag_name} name="$TOOL_NAME2">
|
| 487 |
+
...
|
| 488 |
+
</{dsml_token}{tool_call_tag_name}>
|
| 489 |
+
</{dsml_token}{tc_block_name}>
|
| 490 |
+
|
| 491 |
+
String parameters should be specified as is and set `string="true"`. For all other types (numbers, booleans, arrays, objects), pass the value in JSON format and set `string="false"`.
|
| 492 |
+
|
| 493 |
+
If thinking_mode is enabled (triggered by {thinking_start_token}), you MUST output your complete reasoning inside {thinking_start_token}...{thinking_end_token} BEFORE any tool calls or final response.
|
| 494 |
+
|
| 495 |
+
Otherwise, output directly after {thinking_end_token} with tool calls or final response.
|
| 496 |
+
|
| 497 |
+
### Available Tool Schemas
|
| 498 |
+
|
| 499 |
+
{tool_schemas}
|
| 500 |
+
|
| 501 |
+
You MUST strictly follow the above defined tool name and parameter schemas to invoke tool calls.
|
| 502 |
+
"""
|
| 503 |
+
|
| 504 |
+
|
| 505 |
+
def render_tools(tools: List[Dict[str, Union[str, Dict[str, Any]]]]) -> str:
|
| 506 |
+
"""Render tool schemas into the V4.1 system prompt format."""
|
| 507 |
+
tools_json = [to_json(t) for t in tools]
|
| 508 |
+
|
| 509 |
+
return TOOLS_TEMPLATE.format(
|
| 510 |
+
tool_schemas="\n".join(tools_json),
|
| 511 |
+
dsml_token=dsml_token,
|
| 512 |
+
tc_block_name=tool_calls_block_name,
|
| 513 |
+
tool_call_tag_name=tool_call_tag_name,
|
| 514 |
+
tool_parameter_tag_name=tool_parameter_tag_name,
|
| 515 |
+
thinking_start_token=thinking_start_token,
|
| 516 |
+
thinking_end_token=thinking_end_token,
|
| 517 |
+
)
|
| 518 |
+
|
| 519 |
+
|
| 520 |
+
def encode_arguments_to_dsml(tool_call: Dict[str, Any]) -> str:
|
| 521 |
+
"""Encode tool call arguments into V4.1 DSML parameter format."""
|
| 522 |
+
p_dsml_template = (
|
| 523 |
+
'<{dsml_token}{tool_parameter_tag_name} name="{key}" string="{is_str}">'
|
| 524 |
+
'{value}</{dsml_token}{tool_parameter_tag_name}>'
|
| 525 |
+
)
|
| 526 |
+
P_dsml_strs = []
|
| 527 |
+
|
| 528 |
+
arguments = tool_call["arguments"]
|
| 529 |
+
if not isinstance(arguments, dict):
|
| 530 |
+
# Tolerate JSON strings, including double-encoded ones.
|
| 531 |
+
for _ in range(2):
|
| 532 |
+
if isinstance(arguments, str):
|
| 533 |
+
try:
|
| 534 |
+
arguments = json.loads(arguments)
|
| 535 |
+
except Exception:
|
| 536 |
+
break
|
| 537 |
+
else:
|
| 538 |
+
break
|
| 539 |
+
if not isinstance(arguments, dict):
|
| 540 |
+
arguments = {"arguments": tool_call["arguments"]}
|
| 541 |
+
|
| 542 |
+
for k, v in arguments.items():
|
| 543 |
+
P_dsml_strs.append(p_dsml_template.format(
|
| 544 |
+
dsml_token=dsml_token,
|
| 545 |
+
tool_parameter_tag_name=tool_parameter_tag_name,
|
| 546 |
+
key=k,
|
| 547 |
+
is_str="true" if isinstance(v, str) else "false",
|
| 548 |
+
value=v if isinstance(v, str) else to_json(v),
|
| 549 |
+
))
|
| 550 |
+
|
| 551 |
+
return "\n".join(P_dsml_strs)
|
| 552 |
+
|
| 553 |
+
|
| 554 |
+
# ============================================================
|
| 555 |
+
# Message Rendering
|
| 556 |
+
# ============================================================
|
| 557 |
+
|
| 558 |
+
def find_last_user_index(messages: List[Dict[str, Any]]) -> int:
|
| 559 |
+
"""
|
| 560 |
+
Find the index of the last user message.
|
| 561 |
+
|
| 562 |
+
V4.1 supports mid-conversation system messages, which count as user
|
| 563 |
+
messages for the purposes of the assistant generation header.
|
| 564 |
+
"""
|
| 565 |
+
last_user_index = -1
|
| 566 |
+
for idx in range(len(messages) - 1, -1, -1):
|
| 567 |
+
role = messages[idx].get("role")
|
| 568 |
+
if role == "user" or (role == "system" and idx > 0):
|
| 569 |
+
last_user_index = idx
|
| 570 |
+
break
|
| 571 |
+
return last_user_index
|
| 572 |
+
|
| 573 |
+
|
| 574 |
+
def render_message(
|
| 575 |
+
index: int,
|
| 576 |
+
messages: List[Dict[str, Any]],
|
| 577 |
+
thinking_mode: str,
|
| 578 |
+
drop_thinking: bool = True,
|
| 579 |
+
reasoning_effort: Union[str, int, None] = None,
|
| 580 |
+
) -> str:
|
| 581 |
+
"""
|
| 582 |
+
Render a single message at the given index into its V4.1 encoded string form.
|
| 583 |
+
"""
|
| 584 |
+
assert 0 <= index < len(messages)
|
| 585 |
+
assert thinking_mode in ["chat", "thinking"], f"Invalid thinking_mode `{thinking_mode}`"
|
| 586 |
+
|
| 587 |
+
msg = messages[index]
|
| 588 |
+
last_user_idx = find_last_user_index(messages)
|
| 589 |
+
|
| 590 |
+
role = msg.get("role")
|
| 591 |
+
content = msg.get("content")
|
| 592 |
+
tools = msg.get("tools")
|
| 593 |
+
response_format = msg.get("response_format")
|
| 594 |
+
tool_calls = msg.get("tool_calls")
|
| 595 |
+
reasoning_content = msg.get("reasoning_content")
|
| 596 |
+
wo_eos = msg.get("wo_eos", False)
|
| 597 |
+
|
| 598 |
+
if tools:
|
| 599 |
+
tools = tools_from_openai_format(tools)
|
| 600 |
+
if tool_calls:
|
| 601 |
+
tool_calls = tool_calls_from_openai_format(tool_calls)
|
| 602 |
+
|
| 603 |
+
# Reasoning effort prefix (thinking mode, index 0 only)
|
| 604 |
+
reasoning_effort_prompt = render_reasoning_effort(index, thinking_mode, reasoning_effort)
|
| 605 |
+
# System token leads the conversation when there is a reasoning effort prompt
|
| 606 |
+
# or the first message is a system message.
|
| 607 |
+
prompt = SYSTEM_SP_TOKEN if index == 0 and (reasoning_effort_prompt or role == "system") else ""
|
| 608 |
+
prompt += reasoning_effort_prompt
|
| 609 |
+
|
| 610 |
+
if role == "system":
|
| 611 |
+
if index > 0:
|
| 612 |
+
# Mid-conversation system message
|
| 613 |
+
prompt += SYSTEM_SP_TOKEN
|
| 614 |
+
prompt += system_msg_template.format(content=content or "")
|
| 615 |
+
if tools:
|
| 616 |
+
prompt += "\n\n" + render_tools(tools)
|
| 617 |
+
if response_format:
|
| 618 |
+
prompt += "\n\n" + response_format_template.format(schema=to_json(response_format))
|
| 619 |
+
|
| 620 |
+
elif role == "user":
|
| 621 |
+
prompt += USER_SP_TOKEN
|
| 622 |
+
|
| 623 |
+
# Handle content blocks (tool results mixed with text)
|
| 624 |
+
content_blocks = msg.get("content_blocks")
|
| 625 |
+
if content_blocks:
|
| 626 |
+
parts = []
|
| 627 |
+
for block in content_blocks:
|
| 628 |
+
block_type = block.get("type")
|
| 629 |
+
if block_type == "text":
|
| 630 |
+
parts.append(block.get("text", ""))
|
| 631 |
+
elif block_type == "tool_result":
|
| 632 |
+
tool_content = block.get("content", "")
|
| 633 |
+
if isinstance(tool_content, list):
|
| 634 |
+
text_parts = []
|
| 635 |
+
for b in tool_content:
|
| 636 |
+
if b.get("type") == "text":
|
| 637 |
+
text_parts.append(b.get("text", ""))
|
| 638 |
+
else:
|
| 639 |
+
text_parts.append(f"[Unsupported {b.get('type')}]")
|
| 640 |
+
tool_content = "\n\n".join(text_parts)
|
| 641 |
+
parts.append(tool_output_template.format(content=tool_content))
|
| 642 |
+
else:
|
| 643 |
+
parts.append(f"[Unsupported {block_type}]")
|
| 644 |
+
prompt += "\n\n".join(parts)
|
| 645 |
+
else:
|
| 646 |
+
prompt += content or ""
|
| 647 |
+
|
| 648 |
+
elif role == "latest_reminder":
|
| 649 |
+
prompt += LATEST_REMINDER_SP_TOKEN + latest_reminder_msg_template.format(content=content)
|
| 650 |
+
|
| 651 |
+
elif role == "tool":
|
| 652 |
+
raise NotImplementedError("deepseek_v41 merges tool messages into user; please preprocess with merge_tool_messages()")
|
| 653 |
+
|
| 654 |
+
elif role == "assistant":
|
| 655 |
+
thinking_part = ""
|
| 656 |
+
tc_content = ""
|
| 657 |
+
|
| 658 |
+
if tool_calls:
|
| 659 |
+
tc_list = [
|
| 660 |
+
tool_call_template.format(
|
| 661 |
+
dsml_token=dsml_token,
|
| 662 |
+
tool_call_tag_name=tool_call_tag_name,
|
| 663 |
+
name=_tool_name_for_encoding(tc),
|
| 664 |
+
arguments=encode_arguments_to_dsml(tc)
|
| 665 |
+
)
|
| 666 |
+
for tc in tool_calls
|
| 667 |
+
]
|
| 668 |
+
tc_content += '\n\n' + tool_calls_template.format(
|
| 669 |
+
dsml_token=dsml_token,
|
| 670 |
+
tool_calls="\n".join(tc_list),
|
| 671 |
+
tc_block_name=tool_calls_block_name,
|
| 672 |
+
)
|
| 673 |
+
|
| 674 |
+
summary_content = content or ""
|
| 675 |
+
rc = reasoning_content or ""
|
| 676 |
+
|
| 677 |
+
# Check if previous message has a task - if so, this is a task output (no thinking)
|
| 678 |
+
prev_has_task = index - 1 >= 0 and messages[index - 1].get("task") is not None
|
| 679 |
+
|
| 680 |
+
if thinking_mode == "thinking" and not prev_has_task:
|
| 681 |
+
if not drop_thinking or index > last_user_idx:
|
| 682 |
+
thinking_part = thinking_template.format(reasoning_content=rc) + thinking_end_token
|
| 683 |
+
else:
|
| 684 |
+
thinking_part = ""
|
| 685 |
+
|
| 686 |
+
if wo_eos:
|
| 687 |
+
prompt += assistant_msg_wo_eos_template.format(
|
| 688 |
+
reasoning=thinking_part,
|
| 689 |
+
content=summary_content,
|
| 690 |
+
tool_calls=tc_content,
|
| 691 |
+
)
|
| 692 |
+
else:
|
| 693 |
+
prompt += assistant_msg_template.format(
|
| 694 |
+
reasoning=thinking_part,
|
| 695 |
+
content=summary_content,
|
| 696 |
+
tool_calls=tc_content,
|
| 697 |
+
)
|
| 698 |
+
else:
|
| 699 |
+
raise NotImplementedError(f"Unknown role: {role}")
|
| 700 |
+
|
| 701 |
+
# Append transition tokens based on what follows
|
| 702 |
+
if index + 1 < len(messages) and messages[index + 1].get("role") not in ["assistant", "latest_reminder"]:
|
| 703 |
+
return prompt
|
| 704 |
+
|
| 705 |
+
task = messages[index].get("task")
|
| 706 |
+
if task is not None:
|
| 707 |
+
# Task special token for internal classification tasks
|
| 708 |
+
assert task in VALID_TASKS, f"Invalid task: '{task}'. Valid tasks are: {list(VALID_TASKS)}"
|
| 709 |
+
task_sp_token = DS_TASK_SP_TOKENS[task]
|
| 710 |
+
|
| 711 |
+
if task != "action":
|
| 712 |
+
# Non-action tasks: append task sp token directly after the message
|
| 713 |
+
prompt += task_sp_token
|
| 714 |
+
else:
|
| 715 |
+
# Action task: append Assistant + thinking token + action sp token
|
| 716 |
+
prompt += ASSISTANT_SP_TOKEN
|
| 717 |
+
prompt += thinking_end_token if thinking_mode != "thinking" else thinking_start_token
|
| 718 |
+
prompt += task_sp_token
|
| 719 |
+
|
| 720 |
+
elif role == "user" or (role == "system" and index > 0):
|
| 721 |
+
# Normal generation: append Assistant + thinking token
|
| 722 |
+
# (mid-conversation system messages also trigger the assistant header)
|
| 723 |
+
prompt += ASSISTANT_SP_TOKEN
|
| 724 |
+
if not drop_thinking and thinking_mode == "thinking":
|
| 725 |
+
prompt += thinking_start_token
|
| 726 |
+
elif drop_thinking and thinking_mode == "thinking" and index >= last_user_idx:
|
| 727 |
+
prompt += thinking_start_token
|
| 728 |
+
else:
|
| 729 |
+
prompt += thinking_end_token
|
| 730 |
+
|
| 731 |
+
return prompt
|
| 732 |
+
|
| 733 |
+
|
| 734 |
+
# ============================================================
|
| 735 |
+
# Main Encoding Function
|
| 736 |
+
# ============================================================
|
| 737 |
+
|
| 738 |
+
def _drop_thinking_messages(messages: List[Dict[str, Any]]) -> List[Dict[str, Any]]:
|
| 739 |
+
"""
|
| 740 |
+
Drop reasoning_content and non-essential messages before the last user message.
|
| 741 |
+
Same as V4, but uses the V4.1 last-user definition (mid systems count).
|
| 742 |
+
"""
|
| 743 |
+
last_user_idx = find_last_user_index(messages)
|
| 744 |
+
result = []
|
| 745 |
+
keep_roles = {"user", "system", "tool", "latest_reminder", "direct_search_results"}
|
| 746 |
+
|
| 747 |
+
for idx, msg in enumerate(messages):
|
| 748 |
+
role = msg.get("role")
|
| 749 |
+
if role in keep_roles or idx >= last_user_idx:
|
| 750 |
+
result.append(msg)
|
| 751 |
+
elif role == "assistant":
|
| 752 |
+
msg = copy.copy(msg)
|
| 753 |
+
msg.pop("reasoning_content", None)
|
| 754 |
+
result.append(msg)
|
| 755 |
+
|
| 756 |
+
return result
|
| 757 |
+
|
| 758 |
+
|
| 759 |
+
def _encode_messages_text(
|
| 760 |
+
messages: List[Dict[str, Any]],
|
| 761 |
+
thinking_mode: str,
|
| 762 |
+
context: Optional[List[Dict[str, Any]]] = None,
|
| 763 |
+
drop_thinking: bool = True,
|
| 764 |
+
add_default_bos_token: bool = True,
|
| 765 |
+
reasoning_effort: Union[str, int, None] = None,
|
| 766 |
+
) -> str:
|
| 767 |
+
"""Encode preprocessed (text-only) messages into the V4.1 prompt format."""
|
| 768 |
+
context = context if context else []
|
| 769 |
+
|
| 770 |
+
# Preprocess: merge tool messages and sort tool results
|
| 771 |
+
messages = merge_tool_messages(messages)
|
| 772 |
+
messages = sort_tool_results_by_call_order(context + messages)[len(context):]
|
| 773 |
+
if context:
|
| 774 |
+
context = merge_tool_messages(context)
|
| 775 |
+
context = sort_tool_results_by_call_order(context)
|
| 776 |
+
|
| 777 |
+
full_messages = context + messages
|
| 778 |
+
|
| 779 |
+
prompt = bos_token if add_default_bos_token and len(context) == 0 else ""
|
| 780 |
+
|
| 781 |
+
# Resolve drop_thinking: if any message has tools defined, don't drop thinking
|
| 782 |
+
effective_drop_thinking = drop_thinking
|
| 783 |
+
if any(m.get("tools") for m in full_messages):
|
| 784 |
+
effective_drop_thinking = False
|
| 785 |
+
|
| 786 |
+
if thinking_mode == "thinking" and effective_drop_thinking:
|
| 787 |
+
full_messages = _drop_thinking_messages(full_messages)
|
| 788 |
+
num_to_render = len(full_messages) - len(_drop_thinking_messages(context))
|
| 789 |
+
context_len = len(full_messages) - num_to_render
|
| 790 |
+
else:
|
| 791 |
+
num_to_render = len(messages)
|
| 792 |
+
context_len = len(context)
|
| 793 |
+
|
| 794 |
+
for idx in range(num_to_render):
|
| 795 |
+
prompt += render_message(
|
| 796 |
+
idx + context_len,
|
| 797 |
+
full_messages,
|
| 798 |
+
thinking_mode=thinking_mode,
|
| 799 |
+
drop_thinking=effective_drop_thinking,
|
| 800 |
+
reasoning_effort=reasoning_effort,
|
| 801 |
+
)
|
| 802 |
+
|
| 803 |
+
return prompt
|
| 804 |
+
|
| 805 |
+
|
| 806 |
+
def encode_messages(
|
| 807 |
+
messages: List[Dict[str, Any]],
|
| 808 |
+
thinking_mode: str,
|
| 809 |
+
context: Optional[List[Dict[str, Any]]] = None,
|
| 810 |
+
drop_thinking: bool = True,
|
| 811 |
+
add_default_bos_token: bool = True,
|
| 812 |
+
reasoning_effort: Union[str, int, None] = None,
|
| 813 |
+
return_multi_modal_data: bool = False,
|
| 814 |
+
) -> Any:
|
| 815 |
+
"""Encode text or multimodal messages into the DeepSeek-V4.1 prompt format.
|
| 816 |
+
|
| 817 |
+
Text-only calls return the prompt string. When return_multi_modal_data is
|
| 818 |
+
true, the result is ``(prompt, media_data)``.
|
| 819 |
+
"""
|
| 820 |
+
context = context or []
|
| 821 |
+
processed_context, _ = process_image_messages(context) if context else ([], [])
|
| 822 |
+
processed_messages, images = process_image_messages(messages)
|
| 823 |
+
prompt = _encode_messages_text(
|
| 824 |
+
processed_messages,
|
| 825 |
+
thinking_mode=thinking_mode,
|
| 826 |
+
context=processed_context if processed_context else None,
|
| 827 |
+
drop_thinking=drop_thinking,
|
| 828 |
+
add_default_bos_token=add_default_bos_token,
|
| 829 |
+
reasoning_effort=reasoning_effort,
|
| 830 |
+
)
|
| 831 |
+
if return_multi_modal_data:
|
| 832 |
+
return prompt, {"images": images}
|
| 833 |
+
return prompt
|
| 834 |
+
|
| 835 |
+
|
| 836 |
+
def load_cases(input_file: str) -> List[Dict[str, Any]]:
|
| 837 |
+
"""Load one or more OpenAI-format conversation cases from JSON."""
|
| 838 |
+
with open(input_file) as file:
|
| 839 |
+
data = json.load(file)
|
| 840 |
+
if isinstance(data, dict):
|
| 841 |
+
data = [data]
|
| 842 |
+
elif data and isinstance(data[0], dict) and "role" in data[0]:
|
| 843 |
+
data = [{"messages": data}]
|
| 844 |
+
|
| 845 |
+
cases = []
|
| 846 |
+
for case in data:
|
| 847 |
+
messages = copy.deepcopy(case["messages"])
|
| 848 |
+
if "tools" in case:
|
| 849 |
+
if not messages:
|
| 850 |
+
raise ValueError("A case with tools must contain at least one message")
|
| 851 |
+
messages[0]["tools"] = case["tools"]
|
| 852 |
+
cases.append({
|
| 853 |
+
"messages": messages,
|
| 854 |
+
"context": case.get("context"),
|
| 855 |
+
"thinking_mode": case.get("thinking_mode"),
|
| 856 |
+
"reasoning_effort": case.get("reasoning_effort"),
|
| 857 |
+
})
|
| 858 |
+
return cases
|
| 859 |
+
|
| 860 |
+
|
| 861 |
+
def encode_case(
|
| 862 |
+
case: Dict[str, Any], thinking_mode: str
|
| 863 |
+
) -> Tuple[str, List[Dict[str, Any]]]:
|
| 864 |
+
"""Encode one JSON case and return its current-turn image records."""
|
| 865 |
+
prompt, media_data = encode_messages(
|
| 866 |
+
case["messages"],
|
| 867 |
+
thinking_mode=case.get("thinking_mode") or thinking_mode,
|
| 868 |
+
context=case.get("context"),
|
| 869 |
+
reasoning_effort=case.get("reasoning_effort"),
|
| 870 |
+
return_multi_modal_data=True,
|
| 871 |
+
)
|
| 872 |
+
return prompt, media_data["images"]
|
| 873 |
+
|
| 874 |
+
|
| 875 |
+
# ============================================================
|
| 876 |
+
# Parsing (Decoding model output)
|
| 877 |
+
# ============================================================
|
| 878 |
+
|
| 879 |
+
def parse_tool_calls(index: int, text: str) -> Tuple[int, Optional[str], List[Dict[str, str]]]:
|
| 880 |
+
"""
|
| 881 |
+
Parse V4.1 DSML tool calls from text starting at the given index.
|
| 882 |
+
|
| 883 |
+
Returns:
|
| 884 |
+
Tuple of (new_index, last_stop_token, list_of_tool_call_dicts).
|
| 885 |
+
"""
|
| 886 |
+
tool_calls: List[Dict[str, Any]] = []
|
| 887 |
+
stop_token = None
|
| 888 |
+
tool_calls_end_token = f"</{dsml_token}{tool_calls_block_name}>"
|
| 889 |
+
tool_call_start_token = f"<{dsml_token}{tool_call_tag_name}"
|
| 890 |
+
tool_call_end_token = f"</{dsml_token}{tool_call_tag_name}"
|
| 891 |
+
tool_parameter_start_token = f"<{dsml_token}{tool_parameter_tag_name}"
|
| 892 |
+
tool_parameter_end_token = f"/{dsml_token}{tool_parameter_tag_name}"
|
| 893 |
+
|
| 894 |
+
while index < len(text):
|
| 895 |
+
index, _, stop_token = _read_until_stop(index, text, [tool_call_start_token, tool_calls_end_token])
|
| 896 |
+
if _ != ">\n":
|
| 897 |
+
raise ValueError(f"Tool call format error: expected '>\\n' but got '{_}'")
|
| 898 |
+
|
| 899 |
+
if stop_token == tool_calls_end_token:
|
| 900 |
+
break
|
| 901 |
+
|
| 902 |
+
if stop_token is None:
|
| 903 |
+
raise ValueError("Missing special token in tool calls")
|
| 904 |
+
|
| 905 |
+
index, tool_name_content, stop_token = _read_until_stop(index, text, [tool_parameter_start_token, tool_call_end_token])
|
| 906 |
+
|
| 907 |
+
p_tool_name = re.findall(r'^\s*name="(.*?)">\n$', tool_name_content, flags=re.DOTALL)
|
| 908 |
+
if len(p_tool_name) != 1:
|
| 909 |
+
raise ValueError(f"Tool name format error: '{tool_name_content}'")
|
| 910 |
+
tool_name = p_tool_name[0]
|
| 911 |
+
|
| 912 |
+
tool_args: Dict[str, Tuple[str, str]] = {}
|
| 913 |
+
while stop_token == tool_parameter_start_token:
|
| 914 |
+
index, param_content, stop_token = _read_until_stop(index, text, [tool_parameter_end_token])
|
| 915 |
+
|
| 916 |
+
param_kv = re.findall(r'^ name="(.*?)" string="(true|false)">(.*?)<$', param_content, flags=re.DOTALL)
|
| 917 |
+
if len(param_kv) != 1:
|
| 918 |
+
raise ValueError(f"Parameter format error: '{param_content}'")
|
| 919 |
+
param_name, string, param_value = param_kv[0]
|
| 920 |
+
|
| 921 |
+
if param_name in tool_args:
|
| 922 |
+
raise ValueError(f"Duplicate parameter name: '{param_name}'")
|
| 923 |
+
tool_args[param_name] = (param_value, string)
|
| 924 |
+
|
| 925 |
+
index, content, stop_token = _read_until_stop(index, text, [tool_parameter_start_token, tool_call_end_token])
|
| 926 |
+
if content != ">\n":
|
| 927 |
+
raise ValueError(f"Parameter format error: expected '>\\n' but got '{content}'")
|
| 928 |
+
|
| 929 |
+
tool_call = decode_dsml_to_arguments(tool_name=tool_name, tool_args=tool_args)
|
| 930 |
+
tool_calls.append(tool_call)
|
| 931 |
+
|
| 932 |
+
return index, stop_token, tool_calls
|
| 933 |
+
|
| 934 |
+
|
| 935 |
+
def parse_message_from_completion_text(text: str, thinking_mode: str) -> Dict[str, Any]:
|
| 936 |
+
"""
|
| 937 |
+
Parse a model completion text into a structured assistant message (V4.1 format).
|
| 938 |
+
|
| 939 |
+
Returns:
|
| 940 |
+
Dict with keys: "role", "content", "reasoning_content", "tool_calls".
|
| 941 |
+
tool_calls are in OpenAI format.
|
| 942 |
+
"""
|
| 943 |
+
summary_content, reasoning_content, tool_calls = "", "", []
|
| 944 |
+
index, stop_token = 0, None
|
| 945 |
+
tool_calls_start_token = f"\n\n<{dsml_token}{tool_calls_block_name}"
|
| 946 |
+
|
| 947 |
+
is_thinking = thinking_mode == "thinking"
|
| 948 |
+
is_tool_calling = False
|
| 949 |
+
|
| 950 |
+
if is_thinking:
|
| 951 |
+
index, content_delta, stop_token = _read_until_stop(index, text, [thinking_end_token, tool_calls_start_token])
|
| 952 |
+
reasoning_content = content_delta
|
| 953 |
+
assert stop_token == thinking_end_token, "Invalid thinking format: missing </think>"
|
| 954 |
+
|
| 955 |
+
index, content_delta, stop_token = _read_until_stop(index, text, [eos_token, tool_calls_start_token])
|
| 956 |
+
summary_content = content_delta
|
| 957 |
+
if stop_token == tool_calls_start_token:
|
| 958 |
+
is_tool_calling = True
|
| 959 |
+
else:
|
| 960 |
+
assert stop_token == eos_token, "Invalid format: missing EOS token"
|
| 961 |
+
|
| 962 |
+
if is_tool_calling:
|
| 963 |
+
index, stop_token, tool_calls = parse_tool_calls(index, text)
|
| 964 |
+
|
| 965 |
+
index, tool_ends_text, stop_token = _read_until_stop(index, text, [eos_token])
|
| 966 |
+
assert not tool_ends_text, "Unexpected content after tool calls"
|
| 967 |
+
|
| 968 |
+
assert len(text) == index and stop_token in [eos_token, None], "Unexpected content at end"
|
| 969 |
+
|
| 970 |
+
for sp_token in [bos_token, eos_token, thinking_start_token, thinking_end_token, dsml_token]:
|
| 971 |
+
assert sp_token not in summary_content and sp_token not in reasoning_content, \
|
| 972 |
+
f"Unexpected special token '{sp_token}' in content"
|
| 973 |
+
|
| 974 |
+
return {
|
| 975 |
+
"role": "assistant",
|
| 976 |
+
"content": summary_content,
|
| 977 |
+
"reasoning_content": reasoning_content,
|
| 978 |
+
"tool_calls": tool_calls_to_openai_format(tool_calls)
|
| 979 |
+
}
|
encoding/test_encoding.py
ADDED
|
@@ -0,0 +1,558 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""
|
| 2 |
+
Tests for encoding.py (DeepSeek-V4.1 encoding).
|
| 3 |
+
|
| 4 |
+
Adapted from dsv41-master/deepseek_harmony/tests/test_deepseek_v41.py for the
|
| 5 |
+
self-contained dict-based API in this repo.
|
| 6 |
+
"""
|
| 7 |
+
|
| 8 |
+
import copy
|
| 9 |
+
import json
|
| 10 |
+
from pathlib import Path
|
| 11 |
+
from typing import Any
|
| 12 |
+
|
| 13 |
+
import pytest
|
| 14 |
+
|
| 15 |
+
import encoding as enc
|
| 16 |
+
from encoding import (
|
| 17 |
+
IMAGE_PLACEHOLDER,
|
| 18 |
+
SYSTEM_SP_TOKEN,
|
| 19 |
+
encode_messages,
|
| 20 |
+
parse_message_from_completion_text,
|
| 21 |
+
render_message,
|
| 22 |
+
merge_tool_messages,
|
| 23 |
+
)
|
| 24 |
+
|
| 25 |
+
|
| 26 |
+
REASONING_EFFORT_TEMPLATE = (
|
| 27 |
+
SYSTEM_SP_TOKEN + "Reasoning Effort: {budget} "
|
| 28 |
+
"(range 1-100, the higher the value, the more thorough the reasoning)\n\n"
|
| 29 |
+
)
|
| 30 |
+
|
| 31 |
+
V41_TOOL_CALL_OUTPUT = (
|
| 32 |
+
' reason </think>summary\n\n'
|
| 33 |
+
'<|DSML| calls>\n'
|
| 34 |
+
'<|DSML| invoke name="lookup">\n'
|
| 35 |
+
'<|DSML| parameter name="query" string="true">value'
|
| 36 |
+
'</|DSML| parameter>\n'
|
| 37 |
+
'<|DSML| parameter name="limit" string="false">2'
|
| 38 |
+
'</|DSML| parameter>\n'
|
| 39 |
+
'</|DSML| invoke>\n'
|
| 40 |
+
'</|DSML| calls><|end▁of▁sentence|>'
|
| 41 |
+
)
|
| 42 |
+
|
| 43 |
+
|
| 44 |
+
def make_tool() -> dict:
|
| 45 |
+
return {
|
| 46 |
+
"type": "function",
|
| 47 |
+
"function": {
|
| 48 |
+
"name": "lookup",
|
| 49 |
+
"description": "Look up a value",
|
| 50 |
+
"parameters": {
|
| 51 |
+
"type": "object",
|
| 52 |
+
"properties": {
|
| 53 |
+
"query": {"type": "string"},
|
| 54 |
+
"limit": {"type": "integer"},
|
| 55 |
+
},
|
| 56 |
+
},
|
| 57 |
+
},
|
| 58 |
+
}
|
| 59 |
+
|
| 60 |
+
|
| 61 |
+
def make_tool_call_messages() -> list:
|
| 62 |
+
return [
|
| 63 |
+
{"role": "user", "content": "question"},
|
| 64 |
+
{
|
| 65 |
+
"role": "assistant",
|
| 66 |
+
"reasoning_content": " reason ",
|
| 67 |
+
"content": "summary",
|
| 68 |
+
"tool_calls": [
|
| 69 |
+
{
|
| 70 |
+
"type": "function",
|
| 71 |
+
"function": {
|
| 72 |
+
"name": "lookup",
|
| 73 |
+
"arguments": '{"query":"value","limit":2}',
|
| 74 |
+
},
|
| 75 |
+
}
|
| 76 |
+
],
|
| 77 |
+
},
|
| 78 |
+
]
|
| 79 |
+
|
| 80 |
+
|
| 81 |
+
# ============================================================
|
| 82 |
+
# Vision
|
| 83 |
+
# ============================================================
|
| 84 |
+
|
| 85 |
+
def test_v41_renders_images() -> None:
|
| 86 |
+
prompt, media = encode_messages(
|
| 87 |
+
[
|
| 88 |
+
{
|
| 89 |
+
"role": "user",
|
| 90 |
+
"content": [
|
| 91 |
+
{"type": "text", "text": "inspect"},
|
| 92 |
+
{"type": "image_url", "image_url": {"url": "/unused/image.png"}},
|
| 93 |
+
],
|
| 94 |
+
}
|
| 95 |
+
],
|
| 96 |
+
thinking_mode="chat",
|
| 97 |
+
return_multi_modal_data=True,
|
| 98 |
+
)
|
| 99 |
+
|
| 100 |
+
assert prompt == (
|
| 101 |
+
'<|begin▁of▁sentence|><|User|>inspect\n\n'
|
| 102 |
+
f'{IMAGE_PLACEHOLDER}<|Assistant|></think>'
|
| 103 |
+
)
|
| 104 |
+
assert media == {"images": [{"type": "image", "url": "/unused/image.png"}]}
|
| 105 |
+
|
| 106 |
+
|
| 107 |
+
def test_v41_rejects_image_placeholder_in_text() -> None:
|
| 108 |
+
with pytest.raises(ValueError):
|
| 109 |
+
encode_messages(
|
| 110 |
+
[{"role": "user", "content": f"hi {IMAGE_PLACEHOLDER}"}],
|
| 111 |
+
thinking_mode="chat",
|
| 112 |
+
)
|
| 113 |
+
|
| 114 |
+
|
| 115 |
+
# ============================================================
|
| 116 |
+
# Reasoning Effort
|
| 117 |
+
# ============================================================
|
| 118 |
+
|
| 119 |
+
@pytest.mark.parametrize(
|
| 120 |
+
("effort", "budget"),
|
| 121 |
+
[
|
| 122 |
+
(None, 75),
|
| 123 |
+
("low", 50),
|
| 124 |
+
("high", 75),
|
| 125 |
+
("max", 100),
|
| 126 |
+
(1, 1),
|
| 127 |
+
(42, 42),
|
| 128 |
+
(100, 100),
|
| 129 |
+
],
|
| 130 |
+
)
|
| 131 |
+
def test_v41_maps_reasoning_effort_to_1_100_budget(
|
| 132 |
+
effort: Any,
|
| 133 |
+
budget: int,
|
| 134 |
+
) -> None:
|
| 135 |
+
prompt = encode_messages(
|
| 136 |
+
[{"role": "user", "content": "question"}],
|
| 137 |
+
thinking_mode="thinking",
|
| 138 |
+
reasoning_effort=effort,
|
| 139 |
+
)
|
| 140 |
+
|
| 141 |
+
assert prompt == (
|
| 142 |
+
'<|begin▁of▁sentence|>'
|
| 143 |
+
f'{REASONING_EFFORT_TEMPLATE.format(budget=budget)}'
|
| 144 |
+
'<|User|>question<|Assistant|><think>'
|
| 145 |
+
)
|
| 146 |
+
|
| 147 |
+
|
| 148 |
+
def test_v41_only_adds_reasoning_effort_to_first_thinking_message() -> None:
|
| 149 |
+
messages = [
|
| 150 |
+
{"role": "system", "content": "system"},
|
| 151 |
+
{"role": "user", "content": "question"},
|
| 152 |
+
]
|
| 153 |
+
|
| 154 |
+
later_message = render_message(
|
| 155 |
+
1, messages, thinking_mode="thinking", reasoning_effort=100
|
| 156 |
+
)
|
| 157 |
+
chat_message = render_message(
|
| 158 |
+
0, messages, thinking_mode="chat", reasoning_effort=100
|
| 159 |
+
)
|
| 160 |
+
|
| 161 |
+
assert "Reasoning Effort:" not in later_message
|
| 162 |
+
assert "Reasoning Effort:" not in chat_message
|
| 163 |
+
|
| 164 |
+
|
| 165 |
+
def test_v41_chat_mode_has_no_reasoning_effort_or_system_token() -> None:
|
| 166 |
+
prompt = encode_messages(
|
| 167 |
+
[{"role": "user", "content": "hello"}],
|
| 168 |
+
thinking_mode="chat",
|
| 169 |
+
reasoning_effort="max",
|
| 170 |
+
)
|
| 171 |
+
assert prompt == '<|begin▁of▁sentence|><|User|>hello<|Assistant|></think>'
|
| 172 |
+
|
| 173 |
+
|
| 174 |
+
@pytest.mark.parametrize("effort", [-1, 0, 101, "medium"])
|
| 175 |
+
def test_v41_rejects_out_of_range_or_unknown_reasoning_effort(
|
| 176 |
+
effort: Any,
|
| 177 |
+
) -> None:
|
| 178 |
+
with pytest.raises(AssertionError, match=r"int within \[1,100\]"):
|
| 179 |
+
encode_messages(
|
| 180 |
+
[{"role": "user", "content": "question"}],
|
| 181 |
+
thinking_mode="thinking",
|
| 182 |
+
reasoning_effort=effort,
|
| 183 |
+
)
|
| 184 |
+
|
| 185 |
+
|
| 186 |
+
@pytest.mark.parametrize("effort", [True, False, 1.5])
|
| 187 |
+
def test_v41_rejects_non_string_non_integer_effort_types(effort: Any) -> None:
|
| 188 |
+
# bool is not `type(...) is int`; float is invalid too
|
| 189 |
+
with pytest.raises(AssertionError):
|
| 190 |
+
encode_messages(
|
| 191 |
+
[{"role": "user", "content": "question"}],
|
| 192 |
+
thinking_mode="thinking",
|
| 193 |
+
reasoning_effort=effort,
|
| 194 |
+
)
|
| 195 |
+
|
| 196 |
+
|
| 197 |
+
# ============================================================
|
| 198 |
+
# System token
|
| 199 |
+
# ============================================================
|
| 200 |
+
|
| 201 |
+
def test_v41_leading_system_message_uses_system_token() -> None:
|
| 202 |
+
prompt = encode_messages(
|
| 203 |
+
[
|
| 204 |
+
{"role": "system", "content": "You are a helpful assistant."},
|
| 205 |
+
{"role": "user", "content": "hello"},
|
| 206 |
+
],
|
| 207 |
+
thinking_mode="chat",
|
| 208 |
+
)
|
| 209 |
+
assert prompt == (
|
| 210 |
+
'<|begin▁of▁sentence|><|System|>You are a helpful assistant.'
|
| 211 |
+
'<|User|>hello<|Assistant|></think>'
|
| 212 |
+
)
|
| 213 |
+
|
| 214 |
+
|
| 215 |
+
def test_v41_mid_conversation_system_message() -> None:
|
| 216 |
+
prompt = encode_messages(
|
| 217 |
+
[
|
| 218 |
+
{"role": "system", "content": "sys"},
|
| 219 |
+
{"role": "user", "content": "q1"},
|
| 220 |
+
{"role": "assistant", "content": "a1", "reasoning_content": "r1"},
|
| 221 |
+
{"role": "system", "content": "mid sys"},
|
| 222 |
+
],
|
| 223 |
+
thinking_mode="thinking",
|
| 224 |
+
reasoning_effort=88,
|
| 225 |
+
)
|
| 226 |
+
# Mid-conversation system gets its own <|System|> token and triggers
|
| 227 |
+
# the assistant generation header afterwards.
|
| 228 |
+
assert prompt == (
|
| 229 |
+
'<|begin▁of▁sentence|>'
|
| 230 |
+
f'{REASONING_EFFORT_TEMPLATE.format(budget=88)}'
|
| 231 |
+
'sys<|User|>q1<|Assistant|></think>a1<|end▁of▁sentence|>'
|
| 232 |
+
'<|System|>mid sys<|Assistant|><think>'
|
| 233 |
+
)
|
| 234 |
+
|
| 235 |
+
|
| 236 |
+
# ============================================================
|
| 237 |
+
# DSML tool tags
|
| 238 |
+
# ============================================================
|
| 239 |
+
|
| 240 |
+
def test_v41_tool_instructions_use_spaced_dsml_tags_in_chat_mode() -> None:
|
| 241 |
+
prompt = encode_messages(
|
| 242 |
+
[
|
| 243 |
+
{"role": "system", "content": "system", "tools": [make_tool()]},
|
| 244 |
+
{"role": "user", "content": "question"},
|
| 245 |
+
],
|
| 246 |
+
thinking_mode="chat",
|
| 247 |
+
)
|
| 248 |
+
|
| 249 |
+
assert (
|
| 250 |
+
'<|DSML| calls>\n'
|
| 251 |
+
'<|DSML| invoke name="$TOOL_NAME">\n'
|
| 252 |
+
'<|DSML| parameter name="$PARAMETER_NAME" '
|
| 253 |
+
'string="true|false">$PARAMETER_VALUE</|DSML| parameter>\n'
|
| 254 |
+
'...\n'
|
| 255 |
+
'</|DSML| invoke>'
|
| 256 |
+
) in prompt
|
| 257 |
+
assert '<|DSML|tool_calls>' not in prompt
|
| 258 |
+
assert '<|DSML|invoke' not in prompt
|
| 259 |
+
assert '<|DSML|parameter' not in prompt
|
| 260 |
+
|
| 261 |
+
|
| 262 |
+
def test_v41_renders_spaced_dsml_with_v4_assistant_semantics() -> None:
|
| 263 |
+
messages = make_tool_call_messages()
|
| 264 |
+
|
| 265 |
+
prompt = render_message(1, messages, thinking_mode="thinking")
|
| 266 |
+
|
| 267 |
+
assert prompt == V41_TOOL_CALL_OUTPUT
|
| 268 |
+
|
| 269 |
+
|
| 270 |
+
def test_v41_parses_spaced_dsml_roundtrip() -> None:
|
| 271 |
+
messages = make_tool_call_messages()
|
| 272 |
+
|
| 273 |
+
parsed = parse_message_from_completion_text(
|
| 274 |
+
V41_TOOL_CALL_OUTPUT, thinking_mode="thinking"
|
| 275 |
+
)
|
| 276 |
+
|
| 277 |
+
assert parsed["role"] == "assistant"
|
| 278 |
+
assert parsed["reasoning_content"] == " reason "
|
| 279 |
+
assert parsed["content"] == "summary"
|
| 280 |
+
assert parsed["tool_calls"]
|
| 281 |
+
assert parsed["tool_calls"][0]["function"]["name"] == "lookup"
|
| 282 |
+
assert json.loads(parsed["tool_calls"][0]["function"]["arguments"]) == {
|
| 283 |
+
"query": "value",
|
| 284 |
+
"limit": 2,
|
| 285 |
+
}
|
| 286 |
+
|
| 287 |
+
# Re-encoding the parsed message reproduces the original completion text
|
| 288 |
+
assert encode_messages(
|
| 289 |
+
[parsed],
|
| 290 |
+
thinking_mode="thinking",
|
| 291 |
+
context=messages[:1],
|
| 292 |
+
) == V41_TOOL_CALL_OUTPUT
|
| 293 |
+
|
| 294 |
+
|
| 295 |
+
def test_v41_parse_rejects_unspaced_v4_dsml() -> None:
|
| 296 |
+
v4_output = V41_TOOL_CALL_OUTPUT.replace("|DSML| calls", "|DSML|tool_calls") \
|
| 297 |
+
.replace("|DSML| invoke", "|DSML|invoke") \
|
| 298 |
+
.replace("|DSML| parameter", "|DSML|parameter")
|
| 299 |
+
with pytest.raises(AssertionError):
|
| 300 |
+
parse_message_from_completion_text(v4_output, thinking_mode="thinking")
|
| 301 |
+
|
| 302 |
+
|
| 303 |
+
# ============================================================
|
| 304 |
+
# Tool namespaces
|
| 305 |
+
# ============================================================
|
| 306 |
+
|
| 307 |
+
@pytest.mark.parametrize("location", ["tool", "function"])
|
| 308 |
+
@pytest.mark.parametrize("namespace", ["search", {"name": "search", "description": "Search tools."}])
|
| 309 |
+
def test_v41_renders_namespaced_tool_schemas(location: str, namespace: Any) -> None:
|
| 310 |
+
tool = make_tool()
|
| 311 |
+
target = tool if location == "tool" else tool["function"]
|
| 312 |
+
target["namespace"] = namespace
|
| 313 |
+
original = copy.deepcopy(tool)
|
| 314 |
+
|
| 315 |
+
prompt = encode_messages(
|
| 316 |
+
[{"role": "system", "content": "system", "tools": [tool]}],
|
| 317 |
+
thinking_mode="chat",
|
| 318 |
+
)
|
| 319 |
+
|
| 320 |
+
schema = dict(make_tool()["function"], name="search::lookup")
|
| 321 |
+
if isinstance(namespace, dict):
|
| 322 |
+
schema["description"] = "Search tools.\nLook up a value"
|
| 323 |
+
assert json.dumps(schema) in prompt
|
| 324 |
+
assert '"namespace":' not in prompt
|
| 325 |
+
assert tool == original
|
| 326 |
+
|
| 327 |
+
|
| 328 |
+
@pytest.mark.parametrize("thinking_mode", ["chat", "thinking"])
|
| 329 |
+
@pytest.mark.parametrize("location", ["tool", "function", "qualified_name"])
|
| 330 |
+
def test_v41_namespaced_tool_calls_roundtrip(thinking_mode: str, location: str) -> None:
|
| 331 |
+
messages = make_tool_call_messages()
|
| 332 |
+
call = messages[1]["tool_calls"][0]
|
| 333 |
+
if location == "qualified_name":
|
| 334 |
+
call["function"]["name"] = "search::lookup"
|
| 335 |
+
else:
|
| 336 |
+
target = call if location == "tool" else call["function"]
|
| 337 |
+
target["namespace"] = "search"
|
| 338 |
+
original = copy.deepcopy(messages)
|
| 339 |
+
|
| 340 |
+
expected = V41_TOOL_CALL_OUTPUT.replace('name="lookup"', 'name="search::lookup"')
|
| 341 |
+
if thinking_mode == "chat":
|
| 342 |
+
expected = expected.split("</think>", 1)[1]
|
| 343 |
+
assert render_message(1, messages, thinking_mode=thinking_mode) == expected
|
| 344 |
+
|
| 345 |
+
parsed = parse_message_from_completion_text(expected, thinking_mode=thinking_mode)
|
| 346 |
+
assert parsed["tool_calls"] == [{
|
| 347 |
+
"type": "function",
|
| 348 |
+
"namespace": "search",
|
| 349 |
+
"function": {
|
| 350 |
+
"name": "lookup",
|
| 351 |
+
"arguments": '{"query": "value", "limit": 2}',
|
| 352 |
+
},
|
| 353 |
+
}]
|
| 354 |
+
assert encode_messages(
|
| 355 |
+
[parsed], thinking_mode=thinking_mode, context=messages[:1]
|
| 356 |
+
) == expected
|
| 357 |
+
assert messages == original
|
| 358 |
+
|
| 359 |
+
|
| 360 |
+
def test_v41_keeps_same_named_tools_in_separate_namespaces() -> None:
|
| 361 |
+
tools, calls = [], []
|
| 362 |
+
for namespace in (None, "search", "files"):
|
| 363 |
+
tool = make_tool()
|
| 364 |
+
call = {
|
| 365 |
+
"type": "function",
|
| 366 |
+
"function": {"name": "lookup", "arguments": '{"query":"value"}'},
|
| 367 |
+
}
|
| 368 |
+
if namespace is not None:
|
| 369 |
+
tool["namespace"] = {"name": namespace}
|
| 370 |
+
call["namespace"] = namespace
|
| 371 |
+
tools.append(tool)
|
| 372 |
+
calls.append(call)
|
| 373 |
+
|
| 374 |
+
messages = [
|
| 375 |
+
{"role": "system", "content": "system", "tools": tools},
|
| 376 |
+
{"role": "user", "content": "question"},
|
| 377 |
+
{"role": "assistant", "content": "summary", "tool_calls": calls},
|
| 378 |
+
]
|
| 379 |
+
prompt = encode_messages(messages, thinking_mode="chat")
|
| 380 |
+
for name in ("lookup", "search::lookup", "files::lookup"):
|
| 381 |
+
assert f'"name": "{name}"' in prompt
|
| 382 |
+
assert f'<|DSML| invoke name="{name}">' in prompt
|
| 383 |
+
|
| 384 |
+
completion = render_message(2, messages, thinking_mode="chat")
|
| 385 |
+
parsed = parse_message_from_completion_text(completion, thinking_mode="chat")
|
| 386 |
+
assert "namespace" not in parsed["tool_calls"][0]
|
| 387 |
+
assert [call.get("namespace") for call in parsed["tool_calls"]] == [None, "search", "files"]
|
| 388 |
+
assert all(call["function"]["name"] == "lookup" for call in parsed["tool_calls"])
|
| 389 |
+
|
| 390 |
+
|
| 391 |
+
def test_v41_does_not_duplicate_a_qualified_namespace() -> None:
|
| 392 |
+
tool = make_tool()
|
| 393 |
+
tool["function"]["name"] = "search::lookup"
|
| 394 |
+
tool["namespace"] = {"name": "search", "description": "Search tools."}
|
| 395 |
+
schema = enc.tools_from_openai_format([tool])[0]
|
| 396 |
+
assert schema["name"] == "search::lookup"
|
| 397 |
+
assert schema["description"] == "Search tools.\nLook up a value"
|
| 398 |
+
|
| 399 |
+
messages = make_tool_call_messages()
|
| 400 |
+
call = messages[1]["tool_calls"][0]
|
| 401 |
+
call["function"]["name"] = "search::lookup"
|
| 402 |
+
call["namespace"] = "search"
|
| 403 |
+
assert render_message(1, messages, thinking_mode="thinking") == (
|
| 404 |
+
V41_TOOL_CALL_OUTPUT.replace('name="lookup"', 'name="search::lookup"')
|
| 405 |
+
)
|
| 406 |
+
|
| 407 |
+
|
| 408 |
+
@pytest.mark.parametrize(
|
| 409 |
+
("name", "namespace", "error"),
|
| 410 |
+
[
|
| 411 |
+
("search::lookup", "files", "Conflicting tool namespaces"),
|
| 412 |
+
("search::nested::lookup", None, "Tool name must not contain"),
|
| 413 |
+
("lookup", "search::nested", "Tool namespace must not contain"),
|
| 414 |
+
],
|
| 415 |
+
)
|
| 416 |
+
def test_v41_rejects_ambiguous_tool_namespaces(name: str, namespace: Any, error: str) -> None:
|
| 417 |
+
tool = make_tool()
|
| 418 |
+
tool["function"]["name"] = name
|
| 419 |
+
tool["namespace"] = namespace
|
| 420 |
+
with pytest.raises(AssertionError, match=error):
|
| 421 |
+
enc.tools_from_openai_format([tool])
|
| 422 |
+
|
| 423 |
+
messages = make_tool_call_messages()
|
| 424 |
+
call = messages[1]["tool_calls"][0]
|
| 425 |
+
call["function"]["name"] = name
|
| 426 |
+
call["namespace"] = namespace
|
| 427 |
+
with pytest.raises(AssertionError, match=error):
|
| 428 |
+
render_message(1, messages, thinking_mode="thinking")
|
| 429 |
+
|
| 430 |
+
|
| 431 |
+
# ============================================================
|
| 432 |
+
# Multi-turn flow
|
| 433 |
+
# ============================================================
|
| 434 |
+
|
| 435 |
+
def test_v41_drop_thinking_without_tools() -> None:
|
| 436 |
+
prompt = encode_messages(
|
| 437 |
+
[
|
| 438 |
+
{"role": "user", "content": "q1"},
|
| 439 |
+
{"role": "assistant", "content": "a1", "reasoning_content": "r1"},
|
| 440 |
+
{"role": "user", "content": "q2"},
|
| 441 |
+
],
|
| 442 |
+
thinking_mode="thinking",
|
| 443 |
+
drop_thinking=True,
|
| 444 |
+
)
|
| 445 |
+
# Earlier turn reasoning dropped, </think> form; new turn opens <think>
|
| 446 |
+
assert '<|User|>q1<|Assistant|></think>a1<|end▁of▁sentence|>' in prompt
|
| 447 |
+
assert 'r1' not in prompt
|
| 448 |
+
assert prompt.endswith('<|User|>q2<|Assistant|><think>')
|
| 449 |
+
|
| 450 |
+
|
| 451 |
+
# ============================================================
|
| 452 |
+
# Preprocessing
|
| 453 |
+
# ============================================================
|
| 454 |
+
|
| 455 |
+
def test_merge_tool_messages_creates_tool_result_blocks() -> None:
|
| 456 |
+
merged = merge_tool_messages([
|
| 457 |
+
{"role": "assistant", "content": "", "tool_calls": []},
|
| 458 |
+
{"role": "tool", "tool_call_id": "a", "content": "r1"},
|
| 459 |
+
{"role": "tool", "tool_call_id": "b", "content": "r2"},
|
| 460 |
+
])
|
| 461 |
+
assert len(merged) == 2
|
| 462 |
+
assert merged[1]["role"] == "user"
|
| 463 |
+
assert [b["type"] for b in merged[1]["content_blocks"]] == ["tool_result", "tool_result"]
|
| 464 |
+
|
| 465 |
+
|
| 466 |
+
def test_v41_task_sp_token() -> None:
|
| 467 |
+
prompt = encode_messages(
|
| 468 |
+
[{"role": "user", "content": "classify me", "task": "query"}],
|
| 469 |
+
thinking_mode="chat",
|
| 470 |
+
)
|
| 471 |
+
assert prompt.endswith("classify me<|query|>")
|
| 472 |
+
assert "<|Assistant|>" not in prompt
|
| 473 |
+
|
| 474 |
+
|
| 475 |
+
# ============================================================
|
| 476 |
+
# Golden fixtures from encoding/tests
|
| 477 |
+
# ============================================================
|
| 478 |
+
|
| 479 |
+
ENCODING_DIR = Path(__file__).resolve().parent
|
| 480 |
+
ENCODING_FIXTURES_DIR = ENCODING_DIR / "tests"
|
| 481 |
+
INFERENCE_EXAMPLES_DIR = ENCODING_DIR.parent / "inference" / "examples"
|
| 482 |
+
|
| 483 |
+
FIXTURE_CASE_IDS = sorted(
|
| 484 |
+
int(p.stem.split("_")[-1])
|
| 485 |
+
for p in ENCODING_FIXTURES_DIR.glob("test_input_*.json")
|
| 486 |
+
)
|
| 487 |
+
|
| 488 |
+
|
| 489 |
+
@pytest.mark.parametrize("case_id", FIXTURE_CASE_IDS)
|
| 490 |
+
def test_examples_encoding_golden_outputs(case_id: int) -> None:
|
| 491 |
+
"""Each tests/encoding input must encode to its checked-in golden output."""
|
| 492 |
+
input_file = ENCODING_FIXTURES_DIR / f"test_input_{case_id}.json"
|
| 493 |
+
output_file = ENCODING_FIXTURES_DIR / f"test_output_{case_id}.txt"
|
| 494 |
+
assert output_file.exists(), f"missing golden output: {output_file.name} (run tests/encoding/regen_outputs.py)"
|
| 495 |
+
|
| 496 |
+
case = enc.load_cases(str(input_file))[0]
|
| 497 |
+
prompt, _ = enc.encode_case(case, thinking_mode="chat")
|
| 498 |
+
|
| 499 |
+
assert prompt == output_file.read_text(), (
|
| 500 |
+
f"{output_file.name} is stale; regenerate with tests/encoding/regen_outputs.py"
|
| 501 |
+
)
|
| 502 |
+
|
| 503 |
+
|
| 504 |
+
def test_examples_v41_output_uses_v41_format_markers() -> None:
|
| 505 |
+
"""Sanity-check the V4.1 goldens actually exercise V4.1-specific format."""
|
| 506 |
+
# case 1: tool calls with spaced DSML tags
|
| 507 |
+
out1 = (ENCODING_FIXTURES_DIR / "test_output_1.txt").read_text()
|
| 508 |
+
assert '<|DSML| calls>' in out1 and '<|DSML| invoke name="get_weather">' in out1
|
| 509 |
+
assert '<|DSML|tool_calls>' not in out1
|
| 510 |
+
|
| 511 |
+
# case 5: numeric reasoning effort behind the system token
|
| 512 |
+
out5 = (ENCODING_FIXTURES_DIR / "test_output_5.txt").read_text()
|
| 513 |
+
assert out5.startswith(
|
| 514 |
+
'<|begin▁of▁sentence|>' + REASONING_EFFORT_TEMPLATE.format(budget=100)
|
| 515 |
+
)
|
| 516 |
+
assert out5.count(IMAGE_PLACEHOLDER) == 2
|
| 517 |
+
|
| 518 |
+
|
| 519 |
+
def test_examples_vl_txt_and_json_encode_identically() -> None:
|
| 520 |
+
"""The TXT (last block of example.txt) and JSON vision examples must encode identically."""
|
| 521 |
+
txt = (INFERENCE_EXAMPLES_DIR / "example.txt").read_text().rstrip("\n").split("\n\n")[-1]
|
| 522 |
+
messages = [{"role": "user", "content": enc.parse_tagged_text(txt)}]
|
| 523 |
+
p1, m1 = encode_messages(messages, thinking_mode="chat", return_multi_modal_data=True)
|
| 524 |
+
|
| 525 |
+
case = enc.load_cases(str(INFERENCE_EXAMPLES_DIR / "example_harmony.json"))[0]
|
| 526 |
+
p2, m2 = enc.encode_case(case, thinking_mode="chat")
|
| 527 |
+
|
| 528 |
+
assert p1 == p2
|
| 529 |
+
assert m1["images"] == m2
|
| 530 |
+
assert len(m2) == 2
|
| 531 |
+
|
| 532 |
+
|
| 533 |
+
def test_examples_harmony_cases_encode() -> None:
|
| 534 |
+
"""All example_harmony.json cases encode without error."""
|
| 535 |
+
cases = enc.load_cases(str(INFERENCE_EXAMPLES_DIR / "example_harmony.json"))
|
| 536 |
+
assert len(cases) == 4
|
| 537 |
+
|
| 538 |
+
# case 1 (vision) is covered by test_examples_vl_txt_and_json_encode_identically
|
| 539 |
+
|
| 540 |
+
# cases are pure OpenAI format: mode/effort are passed at call time
|
| 541 |
+
prompt = encode_messages(
|
| 542 |
+
cases[1]["messages"], thinking_mode="thinking", reasoning_effort=75
|
| 543 |
+
)
|
| 544 |
+
assert REASONING_EFFORT_TEMPLATE.format(budget=75) in prompt
|
| 545 |
+
|
| 546 |
+
# case 3: tools with spaced DSML tags
|
| 547 |
+
prompt, _ = enc.encode_case(cases[2], thinking_mode="chat")
|
| 548 |
+
assert '<|DSML| calls>' in prompt
|
| 549 |
+
|
| 550 |
+
# case 4: mid-conversation system message triggers assistant header
|
| 551 |
+
prompt, _ = enc.encode_case(cases[3], thinking_mode="chat")
|
| 552 |
+
assert '<|System|>Mid-conversation instruction update' in prompt
|
| 553 |
+
assert prompt.endswith('<|Assistant|></think>')
|
| 554 |
+
|
| 555 |
+
|
| 556 |
+
if __name__ == "__main__":
|
| 557 |
+
import sys
|
| 558 |
+
sys.exit(pytest.main([__file__, "-v"]))
|
encoding/tests/test_input_1.json
ADDED
|
@@ -0,0 +1,82 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"thinking_mode": "thinking",
|
| 3 |
+
"tools": [
|
| 4 |
+
{
|
| 5 |
+
"type": "function",
|
| 6 |
+
"function": {
|
| 7 |
+
"name": "get_weather",
|
| 8 |
+
"description": "Get the weather for a specific location",
|
| 9 |
+
"parameters": {
|
| 10 |
+
"type": "object",
|
| 11 |
+
"properties": {
|
| 12 |
+
"location": {
|
| 13 |
+
"type": "string",
|
| 14 |
+
"description": "The city name"
|
| 15 |
+
},
|
| 16 |
+
"unit": {
|
| 17 |
+
"type": "string",
|
| 18 |
+
"enum": ["celsius", "fahrenheit"],
|
| 19 |
+
"description": "Temperature unit"
|
| 20 |
+
}
|
| 21 |
+
},
|
| 22 |
+
"required": ["location"]
|
| 23 |
+
}
|
| 24 |
+
}
|
| 25 |
+
},
|
| 26 |
+
{
|
| 27 |
+
"type": "function",
|
| 28 |
+
"function": {
|
| 29 |
+
"name": "search",
|
| 30 |
+
"description": "Search the web for information",
|
| 31 |
+
"parameters": {
|
| 32 |
+
"type": "object",
|
| 33 |
+
"properties": {
|
| 34 |
+
"query": {
|
| 35 |
+
"type": "string",
|
| 36 |
+
"description": "Search query"
|
| 37 |
+
},
|
| 38 |
+
"num_results": {
|
| 39 |
+
"type": "integer",
|
| 40 |
+
"description": "Number of results to return"
|
| 41 |
+
}
|
| 42 |
+
},
|
| 43 |
+
"required": ["query"]
|
| 44 |
+
}
|
| 45 |
+
}
|
| 46 |
+
}
|
| 47 |
+
],
|
| 48 |
+
"messages": [
|
| 49 |
+
{
|
| 50 |
+
"role": "system",
|
| 51 |
+
"content": "You are a helpful assistant."
|
| 52 |
+
},
|
| 53 |
+
{
|
| 54 |
+
"role": "user",
|
| 55 |
+
"content": "What's the weather like in Beijing?"
|
| 56 |
+
},
|
| 57 |
+
{
|
| 58 |
+
"role": "assistant",
|
| 59 |
+
"reasoning_content": "The user wants the weather in Beijing. I should call get_weather.",
|
| 60 |
+
"content": "",
|
| 61 |
+
"tool_calls": [
|
| 62 |
+
{
|
| 63 |
+
"type": "function",
|
| 64 |
+
"function": {
|
| 65 |
+
"name": "get_weather",
|
| 66 |
+
"arguments": "{\"location\": \"Beijing\", \"unit\": \"celsius\"}"
|
| 67 |
+
}
|
| 68 |
+
}
|
| 69 |
+
]
|
| 70 |
+
},
|
| 71 |
+
{
|
| 72 |
+
"role": "tool",
|
| 73 |
+
"tool_call_id": "call_0",
|
| 74 |
+
"content": "{\"temperature\": 22, \"condition\": \"sunny\", \"humidity\": 45}"
|
| 75 |
+
},
|
| 76 |
+
{
|
| 77 |
+
"role": "assistant",
|
| 78 |
+
"reasoning_content": "Got the weather data. Let me format a nice response.",
|
| 79 |
+
"content": "The weather in Beijing is currently sunny with a temperature of 22\u00b0C and 45% humidity."
|
| 80 |
+
}
|
| 81 |
+
]
|
| 82 |
+
}
|
encoding/tests/test_input_2.json
ADDED
|
@@ -0,0 +1,24 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
[
|
| 2 |
+
{
|
| 3 |
+
"role": "system",
|
| 4 |
+
"content": "You are a helpful assistant."
|
| 5 |
+
},
|
| 6 |
+
{
|
| 7 |
+
"role": "user",
|
| 8 |
+
"content": "Hello"
|
| 9 |
+
},
|
| 10 |
+
{
|
| 11 |
+
"role": "assistant",
|
| 12 |
+
"reasoning_content": "The user said hello, I should greet back.",
|
| 13 |
+
"content": "Hi there! How can I help you?"
|
| 14 |
+
},
|
| 15 |
+
{
|
| 16 |
+
"role": "user",
|
| 17 |
+
"content": "What is the capital of France?"
|
| 18 |
+
},
|
| 19 |
+
{
|
| 20 |
+
"role": "assistant",
|
| 21 |
+
"reasoning_content": "The user asks about the capital of France. It is Paris.",
|
| 22 |
+
"content": "The capital of France is Paris."
|
| 23 |
+
}
|
| 24 |
+
]
|
encoding/tests/test_input_3.json
ADDED
|
@@ -0,0 +1,93 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
[
|
| 2 |
+
{
|
| 3 |
+
"role": "system",
|
| 4 |
+
"content": "该助手为DeepSeek,由深度求索公司创造。"
|
| 5 |
+
},
|
| 6 |
+
{
|
| 7 |
+
"role": "latest_reminder",
|
| 8 |
+
"content": "2026-02-21,星期六,广州,App,中文"
|
| 9 |
+
},
|
| 10 |
+
{
|
| 11 |
+
"role": "system",
|
| 12 |
+
"content": "CITATION FORMAT: 【{cursor_id}†L{start_line_id}(-L{end_line_id})?】",
|
| 13 |
+
"tools": [
|
| 14 |
+
{
|
| 15 |
+
"type": "function",
|
| 16 |
+
"function": {
|
| 17 |
+
"name": "search",
|
| 18 |
+
"description": "Web search. Split multiple queries with '||'.",
|
| 19 |
+
"parameters": {
|
| 20 |
+
"type": "object",
|
| 21 |
+
"properties": {
|
| 22 |
+
"queries": {
|
| 23 |
+
"type": "string",
|
| 24 |
+
"description": "query1||query2"
|
| 25 |
+
}
|
| 26 |
+
},
|
| 27 |
+
"required": ["queries"],
|
| 28 |
+
"additionalProperties": false
|
| 29 |
+
}
|
| 30 |
+
}
|
| 31 |
+
},
|
| 32 |
+
{
|
| 33 |
+
"type": "function",
|
| 34 |
+
"function": {
|
| 35 |
+
"name": "open",
|
| 36 |
+
"description": "Batch open IDs (format 【{id}†...】) or URLs.",
|
| 37 |
+
"parameters": {
|
| 38 |
+
"type": "object",
|
| 39 |
+
"properties": {
|
| 40 |
+
"open_list": {
|
| 41 |
+
"type": "array",
|
| 42 |
+
"items": {
|
| 43 |
+
"type": "object",
|
| 44 |
+
"properties": {
|
| 45 |
+
"id": {
|
| 46 |
+
"description": "ID or URL",
|
| 47 |
+
"anyOf": [{"type": "integer"}, {"type": "string"}],
|
| 48 |
+
"default": -1
|
| 49 |
+
},
|
| 50 |
+
"loc": {"type": "integer", "description": "Start line", "default": -1},
|
| 51 |
+
"num_lines": {"type": "integer", "description": "", "default": -1}
|
| 52 |
+
},
|
| 53 |
+
"additionalProperties": false
|
| 54 |
+
},
|
| 55 |
+
"description": ""
|
| 56 |
+
}
|
| 57 |
+
},
|
| 58 |
+
"required": ["open_list"],
|
| 59 |
+
"additionalProperties": false
|
| 60 |
+
}
|
| 61 |
+
}
|
| 62 |
+
}
|
| 63 |
+
]
|
| 64 |
+
},
|
| 65 |
+
{
|
| 66 |
+
"role": "user",
|
| 67 |
+
"content": "小柴胡冲剂和布洛芬能一起吃吗?"
|
| 68 |
+
},
|
| 69 |
+
{
|
| 70 |
+
"role": "assistant",
|
| 71 |
+
"content": "",
|
| 72 |
+
"reasoning_content": "用户想知道小柴胡冲剂和布洛芬能否一起服用。",
|
| 73 |
+
"tool_calls": [
|
| 74 |
+
{
|
| 75 |
+
"type": "function",
|
| 76 |
+
"function": {
|
| 77 |
+
"name": "search",
|
| 78 |
+
"arguments": "{\"queries\": \"小柴胡冲剂 布洛芬 相互作用 一起吃\"}"
|
| 79 |
+
}
|
| 80 |
+
}
|
| 81 |
+
]
|
| 82 |
+
},
|
| 83 |
+
{
|
| 84 |
+
"role": "tool",
|
| 85 |
+
"content": "[0]"
|
| 86 |
+
},
|
| 87 |
+
{
|
| 88 |
+
"role": "assistant",
|
| 89 |
+
"content": "请及时就医。",
|
| 90 |
+
"reasoning_content": "现在开始组织回答。",
|
| 91 |
+
"tool_calls": []
|
| 92 |
+
}
|
| 93 |
+
]
|
encoding/tests/test_input_4.json
ADDED
|
@@ -0,0 +1,28 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
[
|
| 2 |
+
{
|
| 3 |
+
"role": "system",
|
| 4 |
+
"content": "该助手为DeepSeek-V3,由深度求索公司创造。\n今天是2025年10月17日,星期五。"
|
| 5 |
+
},
|
| 6 |
+
{
|
| 7 |
+
"role": "latest_reminder",
|
| 8 |
+
"content": "2024-11-15,上海市,App,中文"
|
| 9 |
+
},
|
| 10 |
+
{
|
| 11 |
+
"role": "user",
|
| 12 |
+
"content": "热海大滚锅是世界著名温泉吗"
|
| 13 |
+
},
|
| 14 |
+
{
|
| 15 |
+
"role": "assistant",
|
| 16 |
+
"content": "热海大滚锅在中国乃至全球的地热奇观中占有重要地位,但“世界著名”的称号更侧重于它作为独特的地质现象和旅游景点。",
|
| 17 |
+
"mask": 1
|
| 18 |
+
},
|
| 19 |
+
{
|
| 20 |
+
"role": "user",
|
| 21 |
+
"content": "世界著名温泉有哪些",
|
| 22 |
+
"task": "action"
|
| 23 |
+
},
|
| 24 |
+
{
|
| 25 |
+
"role": "assistant",
|
| 26 |
+
"content": "Search"
|
| 27 |
+
}
|
| 28 |
+
]
|
encoding/tests/test_input_5.json
ADDED
|
@@ -0,0 +1,39 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"thinking_mode": "thinking",
|
| 3 |
+
"reasoning_effort": "max",
|
| 4 |
+
"messages": [
|
| 5 |
+
{
|
| 6 |
+
"role": "system",
|
| 7 |
+
"content": "You are a helpful vision assistant."
|
| 8 |
+
},
|
| 9 |
+
{
|
| 10 |
+
"role": "user",
|
| 11 |
+
"content": [
|
| 12 |
+
{
|
| 13 |
+
"type": "text",
|
| 14 |
+
"text": "请按“第一张、第二张”的顺序回答:第一张图"
|
| 15 |
+
},
|
| 16 |
+
{
|
| 17 |
+
"type": "image_url",
|
| 18 |
+
"image_url": {
|
| 19 |
+
"url": "examples/images/carrots.jpeg"
|
| 20 |
+
}
|
| 21 |
+
},
|
| 22 |
+
{
|
| 23 |
+
"type": "text",
|
| 24 |
+
"text": "和第二张图"
|
| 25 |
+
},
|
| 26 |
+
{
|
| 27 |
+
"type": "image_url",
|
| 28 |
+
"image_url": {
|
| 29 |
+
"url": "examples/images/corn.jpeg"
|
| 30 |
+
}
|
| 31 |
+
},
|
| 32 |
+
{
|
| 33 |
+
"type": "text",
|
| 34 |
+
"text": "中分别是什么食材?它们通常食用的部位分别是什么?"
|
| 35 |
+
}
|
| 36 |
+
]
|
| 37 |
+
}
|
| 38 |
+
]
|
| 39 |
+
}
|
encoding/tests/test_output_1.txt
ADDED
|
@@ -0,0 +1,38 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<|begin▁of▁sentence|><|System|>Reasoning Effort: 75 (range 1-100, the higher the value, the more thorough the reasoning)
|
| 2 |
+
|
| 3 |
+
You are a helpful assistant.
|
| 4 |
+
|
| 5 |
+
## Tools
|
| 6 |
+
|
| 7 |
+
You have access to a set of tools to help answer the user's question. You can invoke tools by writing a "<|DSML| calls>" block like the following:
|
| 8 |
+
|
| 9 |
+
<|DSML| calls>
|
| 10 |
+
<|DSML| invoke name="$TOOL_NAME">
|
| 11 |
+
<|DSML| parameter name="$PARAMETER_NAME" string="true|false">$PARAMETER_VALUE</|DSML| parameter>
|
| 12 |
+
...
|
| 13 |
+
</|DSML| invoke>
|
| 14 |
+
<|DSML| invoke name="$TOOL_NAME2">
|
| 15 |
+
...
|
| 16 |
+
</|DSML| invoke>
|
| 17 |
+
</|DSML| calls>
|
| 18 |
+
|
| 19 |
+
String parameters should be specified as is and set `string="true"`. For all other types (numbers, booleans, arrays, objects), pass the value in JSON format and set `string="false"`.
|
| 20 |
+
|
| 21 |
+
If thinking_mode is enabled (triggered by <think>), you MUST output your complete reasoning inside <think>...</think> BEFORE any tool calls or final response.
|
| 22 |
+
|
| 23 |
+
Otherwise, output directly after </think> with tool calls or final response.
|
| 24 |
+
|
| 25 |
+
### Available Tool Schemas
|
| 26 |
+
|
| 27 |
+
{"name": "get_weather", "description": "Get the weather for a specific location", "parameters": {"type": "object", "properties": {"location": {"type": "string", "description": "The city name"}, "unit": {"type": "string", "enum": ["celsius", "fahrenheit"], "description": "Temperature unit"}}, "required": ["location"]}}
|
| 28 |
+
{"name": "search", "description": "Search the web for information", "parameters": {"type": "object", "properties": {"query": {"type": "string", "description": "Search query"}, "num_results": {"type": "integer", "description": "Number of results to return"}}, "required": ["query"]}}
|
| 29 |
+
|
| 30 |
+
You MUST strictly follow the above defined tool name and parameter schemas to invoke tool calls.
|
| 31 |
+
<|User|>What's the weather like in Beijing?<|Assistant|><think>The user wants the weather in Beijing. I should call get_weather.</think>
|
| 32 |
+
|
| 33 |
+
<|DSML| calls>
|
| 34 |
+
<|DSML| invoke name="get_weather">
|
| 35 |
+
<|DSML| parameter name="location" string="true">Beijing</|DSML| parameter>
|
| 36 |
+
<|DSML| parameter name="unit" string="true">celsius</|DSML| parameter>
|
| 37 |
+
</|DSML| invoke>
|
| 38 |
+
</|DSML| calls><|end▁of▁sentence|><|User|><tool_result>{"temperature": 22, "condition": "sunny", "humidity": 45}</tool_result><|Assistant|><think>Got the weather data. Let me format a nice response.</think>The weather in Beijing is currently sunny with a temperature of 22°C and 45% humidity.<|end▁of▁sentence|>
|
encoding/tests/test_output_2.txt
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
<|begin▁of▁sentence|><|System|>You are a helpful assistant.<|User|>Hello<|Assistant|></think>Hi there! How can I help you?<|end▁of▁sentence|><|User|>What is the capital of France?<|Assistant|></think>The capital of France is Paris.<|end▁of▁sentence|>
|
encoding/tests/test_output_3.txt
ADDED
|
@@ -0,0 +1,35 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<|begin▁of▁sentence|><|System|>该助手为DeepSeek,由深度求索公司创造。<|latest_reminder|>2026-02-21,星期六,广州,App,中文<|System|>CITATION FORMAT: 【{cursor_id}†L{start_line_id}(-L{end_line_id})?】
|
| 2 |
+
|
| 3 |
+
## Tools
|
| 4 |
+
|
| 5 |
+
You have access to a set of tools to help answer the user's question. You can invoke tools by writing a "<|DSML| calls>" block like the following:
|
| 6 |
+
|
| 7 |
+
<|DSML| calls>
|
| 8 |
+
<|DSML| invoke name="$TOOL_NAME">
|
| 9 |
+
<|DSML| parameter name="$PARAMETER_NAME" string="true|false">$PARAMETER_VALUE</|DSML| parameter>
|
| 10 |
+
...
|
| 11 |
+
</|DSML| invoke>
|
| 12 |
+
<|DSML| invoke name="$TOOL_NAME2">
|
| 13 |
+
...
|
| 14 |
+
</|DSML| invoke>
|
| 15 |
+
</|DSML| calls>
|
| 16 |
+
|
| 17 |
+
String parameters should be specified as is and set `string="true"`. For all other types (numbers, booleans, arrays, objects), pass the value in JSON format and set `string="false"`.
|
| 18 |
+
|
| 19 |
+
If thinking_mode is enabled (triggered by <think>), you MUST output your complete reasoning inside <think>...</think> BEFORE any tool calls or final response.
|
| 20 |
+
|
| 21 |
+
Otherwise, output directly after </think> with tool calls or final response.
|
| 22 |
+
|
| 23 |
+
### Available Tool Schemas
|
| 24 |
+
|
| 25 |
+
{"name": "search", "description": "Web search. Split multiple queries with '||'.", "parameters": {"type": "object", "properties": {"queries": {"type": "string", "description": "query1||query2"}}, "required": ["queries"], "additionalProperties": false}}
|
| 26 |
+
{"name": "open", "description": "Batch open IDs (format 【{id}†...】) or URLs.", "parameters": {"type": "object", "properties": {"open_list": {"type": "array", "items": {"type": "object", "properties": {"id": {"description": "ID or URL", "anyOf": [{"type": "integer"}, {"type": "string"}], "default": -1}, "loc": {"type": "integer", "description": "Start line", "default": -1}, "num_lines": {"type": "integer", "description": "", "default": -1}}, "additionalProperties": false}, "description": ""}}, "required": ["open_list"], "additionalProperties": false}}
|
| 27 |
+
|
| 28 |
+
You MUST strictly follow the above defined tool name and parameter schemas to invoke tool calls.
|
| 29 |
+
<|User|>小柴胡冲剂和布洛芬能一起吃吗?<|Assistant|></think>
|
| 30 |
+
|
| 31 |
+
<|DSML| calls>
|
| 32 |
+
<|DSML| invoke name="search">
|
| 33 |
+
<|DSML| parameter name="queries" string="true">小柴胡冲剂 布洛芬 相互作用 一起吃</|DSML| parameter>
|
| 34 |
+
</|DSML| invoke>
|
| 35 |
+
</|DSML| calls><|end▁of▁sentence|><|User|><tool_result>[0]</tool_result><|Assistant|></think>请及时就医。<|end▁of▁sentence|>
|
encoding/tests/test_output_4.txt
ADDED
|
@@ -0,0 +1,2 @@
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<|begin▁of▁sentence|><|System|>该助手为DeepSeek-V3,由深度求索公司创造。
|
| 2 |
+
今天是2025年10月17日,星期五。<|latest_reminder|>2024-11-15,上海市,App,中文<|User|>热海大滚锅是世界著名温泉吗<|Assistant|></think>热海大滚锅在中国乃至全球的地热奇观中占有重要地位,但“世界著名”的称号更侧重于它作为独特的地质现象和旅游景点。<|end▁of▁sentence|><|User|>世界著名温泉有哪些<|Assistant|></think><|action|>Search<|end▁of▁sentence|>
|
encoding/tests/test_output_5.txt
ADDED
|
@@ -0,0 +1,11 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<|begin▁of▁sentence|><|System|>Reasoning Effort: 100 (range 1-100, the higher the value, the more thorough the reasoning)
|
| 2 |
+
|
| 3 |
+
You are a helpful vision assistant.<|User|>请按“第一张、第二张”的顺序回答:第一张图
|
| 4 |
+
|
| 5 |
+
<|deepseek_image|>
|
| 6 |
+
|
| 7 |
+
和第二张图
|
| 8 |
+
|
| 9 |
+
<|deepseek_image|>
|
| 10 |
+
|
| 11 |
+
中分别是什么食材?它们通常食用的部位分别是什么?<|Assistant|><think>
|
evaluation/README.md
ADDED
|
@@ -0,0 +1,103 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Running DeepSWE with `dsh-minimal` and `mini-swe-agent`
|
| 2 |
+
|
| 3 |
+
## 1. Prerequisites
|
| 4 |
+
|
| 5 |
+
- Docker, running and able to pull images
|
| 6 |
+
- Python 3.12+ and [uv](https://docs.astral.sh/uv/)
|
| 7 |
+
- An endpoint and key for any DeepSeek-API-compatible service (the DeepSeek official API is used as the example below)
|
| 8 |
+
|
| 9 |
+
```sh
|
| 10 |
+
export DEEPSEEK_API_KEY=sk-your-key-here
|
| 11 |
+
export DEEPSEEK_BASE_URL=https://api.deepseek.com
|
| 12 |
+
```
|
| 13 |
+
|
| 14 |
+
## 2. Get Pier and DeepSWE
|
| 15 |
+
|
| 16 |
+
```sh
|
| 17 |
+
git clone https://github.com/datacurve-ai/pier.git
|
| 18 |
+
git -C pier checkout 0c802fc067a425345b24d1c69411aa98acf61a1d
|
| 19 |
+
|
| 20 |
+
git clone https://github.com/datacurve-ai/deep-swe.git
|
| 21 |
+
git -C deep-swe checkout 0b9fabbb63b9104d678fe965e1632f2dd9eaa2ea
|
| 22 |
+
```
|
| 23 |
+
|
| 24 |
+
## 3. Patch and install Pier
|
| 25 |
+
|
| 26 |
+
`dsh-minimal.patch` ships next to this document. Treat it as a **reference patch** and adapt it to your own setup.
|
| 27 |
+
|
| 28 |
+
```sh
|
| 29 |
+
cd pier
|
| 30 |
+
git apply /path/to/dsh-minimal.patch
|
| 31 |
+
uv sync
|
| 32 |
+
```
|
| 33 |
+
|
| 34 |
+
What the patch changes:
|
| 35 |
+
|
| 36 |
+
- **Adds the `dsh-minimal` agent**, which drives the Harness SDK and folds its event stream into a Pier ATIF trajectory. The SDK artifact is never installed into the image: step 4's `--mounts-json` bind-mounts it read-only into the sandbox, so no trial installs anything.
|
| 37 |
+
- **Appends a runtime-constraints section to the task instruction for both agents**: work in `/app`, leave `/tests` alone, no network or package mirror.
|
| 38 |
+
- **Passes test-runner concurrency caps into the container**: Docker's `--cpus` is only a quota, so `nproc` inside the container reports the host's core count and test runners size their worker pools from that rather than from the container's share.
|
| 39 |
+
- **Enables IPv6 loopback in the container**: Docker disables it by default, so suites that bind `::1` are skipped and scored as failures.
|
| 40 |
+
- **Makes `--mounts-json` additive instead of replacing the default mounts**, keeping the `/logs` binds that carry agent logs and collected patches.
|
| 41 |
+
|
| 42 |
+
## 4. Run the suite
|
| 43 |
+
|
| 44 |
+
Both agents take the same task set, concurrency, and `--no-delete` (which keeps the task images cached between trials). Repeat each run with a different `--job-name` and average the results.
|
| 45 |
+
|
| 46 |
+
Each trial's container takes the 2 CPUs and 8 GB its task declares, so size `-n` against the host's cores and memory.
|
| 47 |
+
|
| 48 |
+
### `mini-swe-agent`
|
| 49 |
+
|
| 50 |
+
Pier installs it into each task image at trial time, so no host-side preparation is needed.
|
| 51 |
+
|
| 52 |
+
```sh
|
| 53 |
+
uv run pier run \
|
| 54 |
+
-p ../deep-swe/tasks \
|
| 55 |
+
--agent mini-swe-agent \
|
| 56 |
+
--model deepseek/deepseek-flash \
|
| 57 |
+
--ak reasoning_effort=max \
|
| 58 |
+
--ak cost_limit=0 \
|
| 59 |
+
--ae DEEPSEEK_API_KEY="$DEEPSEEK_API_KEY" \
|
| 60 |
+
--ae DEEPSEEK_BASE_URL="$DEEPSEEK_BASE_URL" \
|
| 61 |
+
-n 32 --no-delete -r 2 --job-name deepswe-mini-run1 -y
|
| 62 |
+
```
|
| 63 |
+
|
| 64 |
+
- `--model` takes a litellm-style `provider/model` string.
|
| 65 |
+
|
| 66 |
+
### `dsh-minimal`
|
| 67 |
+
|
| 68 |
+
Install the Harness SDK artifact once on the host, then bind-mount it read-only into every container.
|
| 69 |
+
|
| 70 |
+
```sh
|
| 71 |
+
mkdir -p ~/dsh-minimal && cd ~/dsh-minimal
|
| 72 |
+
uv pip install --target dsh-dist \
|
| 73 |
+
--python-version 3.12 --python-platform x86_64-manylinux_2_28 \
|
| 74 |
+
'deepseek-harness-sdk==0.1.5.*'
|
| 75 |
+
```
|
| 76 |
+
|
| 77 |
+
```sh
|
| 78 |
+
uv run pier run \
|
| 79 |
+
-p ../deep-swe/tasks \
|
| 80 |
+
--agent dsh-minimal \
|
| 81 |
+
--model deepseek-flash \
|
| 82 |
+
--ak reasoning_effort=max \
|
| 83 |
+
--ae DEEPSEEK_API_KEY="$DEEPSEEK_API_KEY" \
|
| 84 |
+
--ae DEEPSEEK_BASE_URL="$DEEPSEEK_BASE_URL" \
|
| 85 |
+
--mounts-json '[{"type":"bind","source":"'"$HOME"'/dsh-minimal/dsh-dist","target":"/opt/dsh-minimal","read_only":true}]' \
|
| 86 |
+
-n 32 --no-delete --job-name deepswe-dsh-run1 -y
|
| 87 |
+
```
|
| 88 |
+
|
| 89 |
+
- In `--mounts-json`, `source` is the absolute path of the `dsh-dist` directory above; `target` is always `/opt/dsh-minimal`.
|
| 90 |
+
|
| 91 |
+
## 5. Read the results
|
| 92 |
+
|
| 93 |
+
```
|
| 94 |
+
jobs/<job-name>/
|
| 95 |
+
result.json pass rate and token totals
|
| 96 |
+
<task>__<id>/
|
| 97 |
+
result.json reward, fail-to-pass / pass-to-pass counts, tokens
|
| 98 |
+
agent/trajectory.json full ATIF trajectory (dsh-minimal)
|
| 99 |
+
agent/mini-swe-agent.trajectory.json mini-swe-agent trajectory
|
| 100 |
+
verifier/ reward.json and test output
|
| 101 |
+
```
|
| 102 |
+
|
| 103 |
+
Browse a job with `uv run pier view jobs/<job-name>`.
|
evaluation/dsh-minimal.patch
ADDED
|
@@ -0,0 +1,711 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
diff --git a/src/pier/agents/factory.py b/src/pier/agents/factory.py
|
| 2 |
+
index 665fadd..503a45d 100644
|
| 3 |
+
--- a/src/pier/agents/factory.py
|
| 4 |
+
+++ b/src/pier/agents/factory.py
|
| 5 |
+
@@ -6,6 +6,7 @@ from pier.agents.installed.antigravity_sdk import AntigravitySDK
|
| 6 |
+
from pier.agents.installed.claude_code import ClaudeCode
|
| 7 |
+
from pier.agents.installed.codex import Codex
|
| 8 |
+
from pier.agents.installed.cursor_cli import CursorCli
|
| 9 |
+
+from pier.agents.installed.dsh_minimal import DshMinimal
|
| 10 |
+
from pier.agents.installed.gemini_cli import GeminiCli
|
| 11 |
+
from pier.agents.installed.mini_swe_agent import MiniSweAgent
|
| 12 |
+
from pier.agents.installed.opencode import OpenCode
|
| 13 |
+
@@ -24,6 +25,7 @@ class AgentFactory:
|
| 14 |
+
ClaudeCode,
|
| 15 |
+
Codex,
|
| 16 |
+
CursorCli,
|
| 17 |
+
+ DshMinimal,
|
| 18 |
+
GeminiCli,
|
| 19 |
+
MiniSweAgent,
|
| 20 |
+
OpenCode,
|
| 21 |
+
diff --git a/src/pier/agents/installed/base.py b/src/pier/agents/installed/base.py
|
| 22 |
+
index 16f6a84..1fd1050 100644
|
| 23 |
+
--- a/src/pier/agents/installed/base.py
|
| 24 |
+
+++ b/src/pier/agents/installed/base.py
|
| 25 |
+
@@ -15,6 +15,18 @@ from pier.utils.env import parse_bool_env_value
|
| 26 |
+
from pier.utils.templating import render_prompt_template
|
| 27 |
+
|
| 28 |
+
|
| 29 |
+
+RUNTIME_CONSTRAINTS = (
|
| 30 |
+
+ "\n## Runtime constraints\n"
|
| 31 |
+
+ "- Work in `/app`; do not modify files under `/tests`.\n"
|
| 32 |
+
+ "- No network or mirror access; use only dependencies already in the image.\n"
|
| 33 |
+
+)
|
| 34 |
+
+
|
| 35 |
+
+
|
| 36 |
+
+def with_runtime_constraints(instruction: str) -> str:
|
| 37 |
+
+ """Append the sandbox constraints to a task instruction."""
|
| 38 |
+
+ return instruction.rstrip("\n") + "\n" + RUNTIME_CONSTRAINTS
|
| 39 |
+
+
|
| 40 |
+
+
|
| 41 |
+
class NonZeroAgentExitCodeError(RuntimeError):
|
| 42 |
+
"""Raised when the agent process exits with a non-zero exit code."""
|
| 43 |
+
|
| 44 |
+
@@ -394,12 +406,14 @@ class BaseInstalledAgent(BaseAgent, ABC):
|
| 45 |
+
return instruction
|
| 46 |
+
|
| 47 |
+
@abstractmethod
|
| 48 |
+
- def install_spec(self) -> AgentInstallSpec:
|
| 49 |
+
- """Declarative install steps executed at setup and inlined into Dockerfile builds."""
|
| 50 |
+
+ def install_spec(self) -> AgentInstallSpec | None:
|
| 51 |
+
+ """Declarative install steps executed at setup and inlined into Dockerfile
|
| 52 |
+
+ builds, or ``None`` for an agent already present in the environment."""
|
| 53 |
+
|
| 54 |
+
async def install(self, environment: BaseEnvironment) -> None:
|
| 55 |
+
"""Run each step from :meth:`install_spec` with matching privilege."""
|
| 56 |
+
- for step in self.install_spec().steps:
|
| 57 |
+
+ spec = self.install_spec()
|
| 58 |
+
+ for step in spec.steps if spec is not None else ():
|
| 59 |
+
if step.user == "root":
|
| 60 |
+
await self.exec_as_root(environment, command=step.run, env=step.env)
|
| 61 |
+
else:
|
| 62 |
+
diff --git a/src/pier/agents/installed/dsh_minimal.py b/src/pier/agents/installed/dsh_minimal.py
|
| 63 |
+
new file mode 100644
|
| 64 |
+
index 0000000..c84a1b1
|
| 65 |
+
--- /dev/null
|
| 66 |
+
+++ b/src/pier/agents/installed/dsh_minimal.py
|
| 67 |
+
@@ -0,0 +1,131 @@
|
| 68 |
+
+import shlex
|
| 69 |
+
+from pathlib import Path
|
| 70 |
+
+from typing import Any, override
|
| 71 |
+
+
|
| 72 |
+
+from pier.agents.installed.base import (
|
| 73 |
+
+ BaseInstalledAgent,
|
| 74 |
+
+ with_prompt_template,
|
| 75 |
+
+ with_runtime_constraints,
|
| 76 |
+
+)
|
| 77 |
+
+from pier.agents.network import allowlist_from_urls
|
| 78 |
+
+from pier.environments.base import BaseEnvironment
|
| 79 |
+
+from pier.models.agent.context import AgentContext
|
| 80 |
+
+from pier.models.agent.name import AgentName
|
| 81 |
+
+from pier.models.agent.network import NetworkAllowlist
|
| 82 |
+
+from pier.models.trajectories import Trajectory
|
| 83 |
+
+from pier.utils.trajectory_metrics import populate_context_from_final_metrics
|
| 84 |
+
+
|
| 85 |
+
+DIST = "/opt/dsh-minimal"
|
| 86 |
+
+DEFAULT_MODEL = "deepseek-flash"
|
| 87 |
+
+DEFAULT_BASE_URL = "https://api.deepseek.com"
|
| 88 |
+
+REASONING_EFFORTS = ("low", "high", "max")
|
| 89 |
+
+
|
| 90 |
+
+
|
| 91 |
+
+class DshMinimal(BaseInstalledAgent):
|
| 92 |
+
+ """DeepSeek Harness `sdk-minimal` profile driven through its Python SDK.
|
| 93 |
+
+
|
| 94 |
+
+ The SDK and its bundled runtime executable come from a `pip install --target`
|
| 95 |
+
+ tree bind-mounted read-only at ``DIST``, so no trial installs anything.
|
| 96 |
+
+ """
|
| 97 |
+
+
|
| 98 |
+
+ SUPPORTS_ATIF = True
|
| 99 |
+
+ _TRAJECTORY = "trajectory.json"
|
| 100 |
+
+ # The distribution mount is read-only, so the runner lands beside it.
|
| 101 |
+
+ _RUNNER = "/tmp/dsh-minimal-runner.py"
|
| 102 |
+
+
|
| 103 |
+
+ def __init__(
|
| 104 |
+
+ self, *args: Any, reasoning_effort: str = "max", **kwargs: Any
|
| 105 |
+
+ ) -> None:
|
| 106 |
+
+ if reasoning_effort not in REASONING_EFFORTS:
|
| 107 |
+
+ raise ValueError(
|
| 108 |
+
+ f"reasoning_effort must be one of {REASONING_EFFORTS}, "
|
| 109 |
+
+ f"got {reasoning_effort!r}"
|
| 110 |
+
+ )
|
| 111 |
+
+ self._reasoning_effort = reasoning_effort
|
| 112 |
+
+ kwargs["model_name"] = kwargs.get("model_name") or DEFAULT_MODEL
|
| 113 |
+
+ super().__init__(*args, **kwargs)
|
| 114 |
+
+
|
| 115 |
+
+ @staticmethod
|
| 116 |
+
+ @override
|
| 117 |
+
+ def name() -> str:
|
| 118 |
+
+ return AgentName.DSH_MINIMAL.value
|
| 119 |
+
+
|
| 120 |
+
+ @override
|
| 121 |
+
+ def install_spec(self) -> None:
|
| 122 |
+
+ """The distribution is bind-mounted, so no image layer is needed."""
|
| 123 |
+
+ return None
|
| 124 |
+
+
|
| 125 |
+
+ @override
|
| 126 |
+
+ def get_version_command(self) -> str:
|
| 127 |
+
+ return f"sed -n 's/^Version: //p' {DIST}/deepseek_harness_sdk-*.dist-info/METADATA"
|
| 128 |
+
+
|
| 129 |
+
+ @override
|
| 130 |
+
+ async def setup(self, environment: BaseEnvironment) -> None:
|
| 131 |
+
+ await super().setup(environment)
|
| 132 |
+
+ runner = Path(__file__).with_name("dsh_minimal_runner.py")
|
| 133 |
+
+ await environment.upload_file(runner, self._RUNNER)
|
| 134 |
+
+ await self.exec_as_root(environment, f"chmod a+r {self._RUNNER}")
|
| 135 |
+
+
|
| 136 |
+
+ def _base_url(self) -> str:
|
| 137 |
+
+ return self._get_env("DEEPSEEK_BASE_URL") or DEFAULT_BASE_URL
|
| 138 |
+
+
|
| 139 |
+
+ @override
|
| 140 |
+
+ def network_allowlist(self) -> NetworkAllowlist:
|
| 141 |
+
+ return allowlist_from_urls([self._base_url()])
|
| 142 |
+
+
|
| 143 |
+
+ @override
|
| 144 |
+
+ def populate_context_post_run(self, context: AgentContext) -> None:
|
| 145 |
+
+ path = self.logs_dir / self._TRAJECTORY
|
| 146 |
+
+ if not path.exists():
|
| 147 |
+
+ self.logger.debug("No dsh-minimal trajectory found at %s", path)
|
| 148 |
+
+ return
|
| 149 |
+
+ try:
|
| 150 |
+
+ trajectory = Trajectory.model_validate_json(path.read_text())
|
| 151 |
+
+ except (OSError, ValueError):
|
| 152 |
+
+ self.logger.exception("Failed to parse dsh-minimal trajectory")
|
| 153 |
+
+ return
|
| 154 |
+
+ if trajectory.final_metrics is not None:
|
| 155 |
+
+ populate_context_from_final_metrics(context, trajectory.final_metrics)
|
| 156 |
+
+ context.n_agent_steps = sum(step.source == "agent" for step in trajectory.steps)
|
| 157 |
+
+
|
| 158 |
+
+ @override
|
| 159 |
+
+ @with_prompt_template
|
| 160 |
+
+ async def run(
|
| 161 |
+
+ self,
|
| 162 |
+
+ instruction: str,
|
| 163 |
+
+ environment: BaseEnvironment,
|
| 164 |
+
+ context: AgentContext,
|
| 165 |
+
+ ) -> None:
|
| 166 |
+
+ api_key = self._get_env("DEEPSEEK_API_KEY")
|
| 167 |
+
+ if not api_key:
|
| 168 |
+
+ raise ValueError("DEEPSEEK_API_KEY environment variable must be set")
|
| 169 |
+
+
|
| 170 |
+
+ instruction = with_runtime_constraints(instruction)
|
| 171 |
+
+ agent_dir = environment.env_paths.agent_dir.as_posix()
|
| 172 |
+
+ env = self.build_process_env(
|
| 173 |
+
+ {
|
| 174 |
+
+ "DEEPSEEK_API_KEY": api_key,
|
| 175 |
+
+ "DEEPSEEK_BASE_URL": self._base_url(),
|
| 176 |
+
+ # The Node runtime reaches the model only through Pier's egress
|
| 177 |
+
+ # proxy, and its fetch ignores the proxy variables without this.
|
| 178 |
+
+ "NODE_USE_ENV_PROXY": "1",
|
| 179 |
+
+ "PYTHONPATH": DIST,
|
| 180 |
+
+ "DSH_MODEL": self._parsed_model_name,
|
| 181 |
+
+ "DSH_REASONING_EFFORT": self._reasoning_effort,
|
| 182 |
+
+ # Required, and kept off the /logs bind mount: it materializes many
|
| 183 |
+
+ # files the host cannot read anyway. `trajectory.json` is the record.
|
| 184 |
+
+ "DSH_HOME": "/tmp/dsh-home",
|
| 185 |
+
+ "SESSION_ID": environment.session_id,
|
| 186 |
+
+ }
|
| 187 |
+
+ )
|
| 188 |
+
+
|
| 189 |
+
+ await self.exec_as_agent(
|
| 190 |
+
+ environment,
|
| 191 |
+
+ command=(
|
| 192 |
+
+ f"python3 {self._RUNNER} "
|
| 193 |
+
+ f"--instruction {shlex.quote(instruction)} "
|
| 194 |
+
+ f"--trajectory-path {agent_dir}/{self._TRAJECTORY} "
|
| 195 |
+
+ f"2>&1 </dev/null | stdbuf -oL tee {agent_dir}/dsh-minimal.txt"
|
| 196 |
+
+ ),
|
| 197 |
+
+ env=env,
|
| 198 |
+
+ )
|
| 199 |
+
diff --git a/src/pier/agents/installed/dsh_minimal_runner.py b/src/pier/agents/installed/dsh_minimal_runner.py
|
| 200 |
+
new file mode 100644
|
| 201 |
+
index 0000000..8b69d7d
|
| 202 |
+
--- /dev/null
|
| 203 |
+
+++ b/src/pier/agents/installed/dsh_minimal_runner.py
|
| 204 |
+
@@ -0,0 +1,307 @@
|
| 205 |
+
+"""Run the DeepSeek Harness `sdk-minimal` profile and persist its stream as ATIF v1.7."""
|
| 206 |
+
+
|
| 207 |
+
+from __future__ import annotations
|
| 208 |
+
+
|
| 209 |
+
+import argparse
|
| 210 |
+
+import json
|
| 211 |
+
+import os
|
| 212 |
+
+import sys
|
| 213 |
+
+import traceback
|
| 214 |
+
+from datetime import datetime, timezone
|
| 215 |
+
+from importlib.metadata import PackageNotFoundError, version
|
| 216 |
+
+from pathlib import Path
|
| 217 |
+
+from typing import Any
|
| 218 |
+
+
|
| 219 |
+
+from deepseek_harness import DeepSeekHarness
|
| 220 |
+
+from deepseek_harness.models import Notification
|
| 221 |
+
+
|
| 222 |
+
+PROVIDER = "deepseek-official"
|
| 223 |
+
+
|
| 224 |
+
+
|
| 225 |
+
+def _iso(epoch_ms: Any) -> str | None:
|
| 226 |
+
+ if not isinstance(epoch_ms, (int, float)):
|
| 227 |
+
+ return None
|
| 228 |
+
+ return datetime.fromtimestamp(epoch_ms / 1000, tz=timezone.utc).isoformat()
|
| 229 |
+
+
|
| 230 |
+
+
|
| 231 |
+
+def _text(blocks: Any, kind: str) -> str:
|
| 232 |
+
+ if not isinstance(blocks, list):
|
| 233 |
+
+ return ""
|
| 234 |
+
+ return "".join(
|
| 235 |
+
+ str(block.get("text") or "")
|
| 236 |
+
+ for block in blocks
|
| 237 |
+
+ if isinstance(block, dict) and block.get("type") == kind
|
| 238 |
+
+ )
|
| 239 |
+
+
|
| 240 |
+
+
|
| 241 |
+
+def _flatten(blocks: Any) -> str:
|
| 242 |
+
+ if isinstance(blocks, str):
|
| 243 |
+
+ return blocks
|
| 244 |
+
+ if not isinstance(blocks, list):
|
| 245 |
+
+ return json.dumps(blocks, ensure_ascii=False)
|
| 246 |
+
+ return "".join(
|
| 247 |
+
+ str(block.get("text") or "")
|
| 248 |
+
+ if isinstance(block, dict) and block.get("type") == "text"
|
| 249 |
+
+ else json.dumps(block, ensure_ascii=False)
|
| 250 |
+
+ for block in blocks
|
| 251 |
+
+ )
|
| 252 |
+
+
|
| 253 |
+
+
|
| 254 |
+
+def _arguments(raw: Any) -> dict[str, Any]:
|
| 255 |
+
+ """ATIF wants an object; the wire carries the model's raw argument string."""
|
| 256 |
+
+ if isinstance(raw, dict):
|
| 257 |
+
+ return raw
|
| 258 |
+
+ if isinstance(raw, str):
|
| 259 |
+
+ try:
|
| 260 |
+
+ parsed = json.loads(raw)
|
| 261 |
+
+ except json.JSONDecodeError:
|
| 262 |
+
+ return {"_unparsed_arguments": raw}
|
| 263 |
+
+ return parsed if isinstance(parsed, dict) else {"_arguments": parsed}
|
| 264 |
+
+ return {}
|
| 265 |
+
+
|
| 266 |
+
+
|
| 267 |
+
+def _metrics(usage: dict[str, Any]) -> dict[str, Any]:
|
| 268 |
+
+ """The adapter reports disjoint counts, so the cache legs rejoin prompt tokens."""
|
| 269 |
+
+ cache_read = usage.get("cacheReadTokens") or 0
|
| 270 |
+
+ cache_write = usage.get("cacheWriteTokens") or 0
|
| 271 |
+
+ metrics = {
|
| 272 |
+
+ "prompt_tokens": (usage.get("inputTokens") or 0) + cache_read + cache_write,
|
| 273 |
+
+ "completion_tokens": usage.get("outputTokens") or 0,
|
| 274 |
+
+ "cached_tokens": cache_read,
|
| 275 |
+
+ }
|
| 276 |
+
+ if usage.get("reasoningTokens") is not None:
|
| 277 |
+
+ metrics["extra"] = {"reasoning_tokens": usage["reasoningTokens"]}
|
| 278 |
+
+ return metrics
|
| 279 |
+
+
|
| 280 |
+
+
|
| 281 |
+
+class Collector:
|
| 282 |
+
+ """Fold root-session events into one ATIF step per model call."""
|
| 283 |
+
+
|
| 284 |
+
+ def __init__(self, instruction: str, model: str, effort: str, session: str) -> None:
|
| 285 |
+
+ self.model = model
|
| 286 |
+
+ self.effort = effort
|
| 287 |
+
+ self.session = session
|
| 288 |
+
+ self.steps: list[dict[str, Any]] = [
|
| 289 |
+
+ {
|
| 290 |
+
+ "step_id": 1,
|
| 291 |
+
+ "timestamp": datetime.now(tz=timezone.utc).isoformat(),
|
| 292 |
+
+ "source": "user",
|
| 293 |
+
+ "message": instruction,
|
| 294 |
+
+ }
|
| 295 |
+
+ ]
|
| 296 |
+
+ # (turn, step) identifies one model call; callId maps a later `tool/result`
|
| 297 |
+
+ # back to the step that issued it, which is never the step it arrives in.
|
| 298 |
+
+ self._by_call: dict[tuple[int, int], dict[str, Any]] = {}
|
| 299 |
+
+ self._by_call_id: dict[str, dict[str, Any]] = {}
|
| 300 |
+
+ self.turn_end_reasons: list[dict[str, Any]] = []
|
| 301 |
+
+ self.llm_retries = 0
|
| 302 |
+
+
|
| 303 |
+
+ def _step(self, turn: Any, step: Any, timestamp: str | None) -> dict[str, Any]:
|
| 304 |
+
+ key = (int(turn or 0), int(step or 0))
|
| 305 |
+
+ if key not in self._by_call:
|
| 306 |
+
+ created = {
|
| 307 |
+
+ "step_id": len(self.steps) + 1,
|
| 308 |
+
+ "timestamp": timestamp,
|
| 309 |
+
+ "source": "agent",
|
| 310 |
+
+ "message": "",
|
| 311 |
+
+ "model_name": self.model,
|
| 312 |
+
+ "reasoning_effort": self.effort,
|
| 313 |
+
+ "llm_call_count": 1,
|
| 314 |
+
+ }
|
| 315 |
+
+ self.steps.append(created)
|
| 316 |
+
+ self._by_call[key] = created
|
| 317 |
+
+ return self._by_call[key]
|
| 318 |
+
+
|
| 319 |
+
+ def _tool_call(self, step: dict[str, Any], call_id: Any, name: Any, raw: Any) -> None:
|
| 320 |
+
+ if not isinstance(call_id, str) or not call_id:
|
| 321 |
+
+ return
|
| 322 |
+
+ calls = step.setdefault("tool_calls", [])
|
| 323 |
+
+ entry = {
|
| 324 |
+
+ "tool_call_id": call_id,
|
| 325 |
+
+ "function_name": str(name),
|
| 326 |
+
+ "arguments": _arguments(raw),
|
| 327 |
+
+ }
|
| 328 |
+
+ for index, existing in enumerate(calls):
|
| 329 |
+
+ if existing["tool_call_id"] == call_id:
|
| 330 |
+
+ calls[index] = entry
|
| 331 |
+
+ break
|
| 332 |
+
+ else:
|
| 333 |
+
+ calls.append(entry)
|
| 334 |
+
+ self._by_call_id[call_id] = step
|
| 335 |
+
+
|
| 336 |
+
+ def record(self, event: dict[str, Any]) -> None:
|
| 337 |
+
+ kind = event.get("type")
|
| 338 |
+
+ data = event.get("data") if isinstance(event.get("data"), dict) else {}
|
| 339 |
+
+ timestamp = _iso(event.get("time"))
|
| 340 |
+
+
|
| 341 |
+
+ if kind == "assistant/message":
|
| 342 |
+
+ step = self._step(data.get("turn"), data.get("step"), timestamp)
|
| 343 |
+
+ message = data.get("message") if isinstance(data.get("message"), dict) else {}
|
| 344 |
+
+ content = message.get("content")
|
| 345 |
+
+ step["message"] = _text(content, "text")
|
| 346 |
+
+ if reasoning := _text(content, "reasoning"):
|
| 347 |
+
+ step["reasoning_content"] = reasoning
|
| 348 |
+
+ source = message.get("source")
|
| 349 |
+
+ if isinstance(source, dict) and isinstance(source.get("model"), str):
|
| 350 |
+
+ step["model_name"] = source["model"]
|
| 351 |
+
+ if isinstance(data.get("usage"), dict):
|
| 352 |
+
+ step["metrics"] = _metrics(data["usage"])
|
| 353 |
+
+ if data.get("interrupted"):
|
| 354 |
+
+ step.setdefault("extra", {})["interrupted"] = True
|
| 355 |
+
+ for block in content if isinstance(content, list) else []:
|
| 356 |
+
+ if isinstance(block, dict) and block.get("type") == "tool-call":
|
| 357 |
+
+ self._tool_call(
|
| 358 |
+
+ step, block.get("id"), block.get("name"), block.get("arguments")
|
| 359 |
+
+ )
|
| 360 |
+
+ elif kind == "tool/call":
|
| 361 |
+
+ step = self._step(data.get("turn"), data.get("step"), timestamp)
|
| 362 |
+
+ self._tool_call(
|
| 363 |
+
+ step, data.get("callId"), data.get("name"), data.get("arguments")
|
| 364 |
+
+ )
|
| 365 |
+
+ elif kind == "tool/result":
|
| 366 |
+
+ self._result(data)
|
| 367 |
+
+ elif kind == "turn/end":
|
| 368 |
+
+ reason = data.get("reason")
|
| 369 |
+
+ self.turn_end_reasons.append(reason if isinstance(reason, dict) else {})
|
| 370 |
+
+ elif kind == "llm/retry":
|
| 371 |
+
+ self.llm_retries += 1
|
| 372 |
+
+
|
| 373 |
+
+ def _result(self, data: dict[str, Any]) -> None:
|
| 374 |
+
+ message = data.get("message") if isinstance(data.get("message"), dict) else {}
|
| 375 |
+
+ for block in message.get("content") or []:
|
| 376 |
+
+ if not isinstance(block, dict) or block.get("type") != "tool-result":
|
| 377 |
+
+ continue
|
| 378 |
+
+ step = self._by_call_id.get(block.get("toolCallId"))
|
| 379 |
+
+ if step is None:
|
| 380 |
+
+ continue
|
| 381 |
+
+ entry: dict[str, Any] = {
|
| 382 |
+
+ "source_call_id": block["toolCallId"],
|
| 383 |
+
+ "content": _flatten(block.get("content")),
|
| 384 |
+
+ }
|
| 385 |
+
+ if block.get("isError"):
|
| 386 |
+
+ entry["extra"] = {"is_error": True, "error": data.get("error")}
|
| 387 |
+
+ results = step.setdefault("observation", {"results": []})["results"]
|
| 388 |
+
+ for index, existing in enumerate(results):
|
| 389 |
+
+ if existing["source_call_id"] == entry["source_call_id"]:
|
| 390 |
+
+ results[index] = entry
|
| 391 |
+
+ break
|
| 392 |
+
+ else:
|
| 393 |
+
+ results.append(entry)
|
| 394 |
+
+
|
| 395 |
+
+ def trajectory(self, finish_reason: str | None, failure: str | None) -> dict[str, Any]:
|
| 396 |
+
+ prompt = completion = cached = peak = 0
|
| 397 |
+
+ for step in self.steps:
|
| 398 |
+
+ metrics = step.get("metrics")
|
| 399 |
+
+ if not isinstance(metrics, dict):
|
| 400 |
+
+ continue
|
| 401 |
+
+ prompt += metrics["prompt_tokens"]
|
| 402 |
+
+ completion += metrics["completion_tokens"]
|
| 403 |
+
+ cached += metrics["cached_tokens"]
|
| 404 |
+
+ peak = max(peak, metrics["prompt_tokens"])
|
| 405 |
+
+ extra = {
|
| 406 |
+
+ "finish_reason": finish_reason,
|
| 407 |
+
+ "turn_end_reasons": self.turn_end_reasons,
|
| 408 |
+
+ "llm_retry_count": self.llm_retries,
|
| 409 |
+
+ }
|
| 410 |
+
+ if failure is not None:
|
| 411 |
+
+ extra["failure"] = failure
|
| 412 |
+
+ return {
|
| 413 |
+
+ "schema_version": "ATIF-v1.7",
|
| 414 |
+
+ "session_id": self.session,
|
| 415 |
+
+ "agent": {"name": "dsh-minimal", "version": _version(), "model_name": self.model},
|
| 416 |
+
+ "steps": self.steps,
|
| 417 |
+
+ "final_metrics": {
|
| 418 |
+
+ "total_prompt_tokens": prompt,
|
| 419 |
+
+ "total_completion_tokens": completion,
|
| 420 |
+
+ "total_cached_tokens": cached,
|
| 421 |
+
+ "total_steps": len(self.steps),
|
| 422 |
+
+ # The sdk-minimal profile has no compaction, so no summary step
|
| 423 |
+
+ # can replace a transcript prefix.
|
| 424 |
+
+ "extra": {"peak_context_tokens": peak, "summarization_count": 0},
|
| 425 |
+
+ },
|
| 426 |
+
+ "extra": extra,
|
| 427 |
+
+ }
|
| 428 |
+
+
|
| 429 |
+
+
|
| 430 |
+
+def _version() -> str:
|
| 431 |
+
+ try:
|
| 432 |
+
+ return version("deepseek-harness-sdk")
|
| 433 |
+
+ except PackageNotFoundError:
|
| 434 |
+
+ return "unknown"
|
| 435 |
+
+
|
| 436 |
+
+
|
| 437 |
+
+def _write(path: Path, value: Any) -> None:
|
| 438 |
+
+ path.parent.mkdir(parents=True, exist_ok=True)
|
| 439 |
+
+ temporary = path.with_suffix(f"{path.suffix}.tmp")
|
| 440 |
+
+ temporary.write_text(json.dumps(value, indent=2, ensure_ascii=False) + "\n")
|
| 441 |
+
+ temporary.replace(path)
|
| 442 |
+
+
|
| 443 |
+
+
|
| 444 |
+
+def main() -> None:
|
| 445 |
+
+ parser = argparse.ArgumentParser()
|
| 446 |
+
+ parser.add_argument("--instruction", required=True)
|
| 447 |
+
+ parser.add_argument("--trajectory-path", required=True)
|
| 448 |
+
+ args = parser.parse_args()
|
| 449 |
+
+
|
| 450 |
+
+ # Task images can leave the agent user on a 077 umask; the session log and
|
| 451 |
+
+ # trajectory have to stay readable to the host user that collects /logs.
|
| 452 |
+
+ os.umask(0o022)
|
| 453 |
+
+
|
| 454 |
+
+ model = os.environ["DSH_MODEL"]
|
| 455 |
+
+ effort = os.environ.get("DSH_REASONING_EFFORT", "max")
|
| 456 |
+
+ session = os.environ.get("SESSION_ID") or "pier-session"
|
| 457 |
+
+ path = Path(args.trajectory_path)
|
| 458 |
+
+ collector = Collector(args.instruction, model, effort, session)
|
| 459 |
+
+ state: dict[str, Any] = {"finish_reason": None, "failure": None}
|
| 460 |
+
+
|
| 461 |
+
+ def checkpoint() -> None:
|
| 462 |
+
+ _write(path, collector.trajectory(state["finish_reason"], state["failure"]))
|
| 463 |
+
+
|
| 464 |
+
+ def on_notification(notification: Notification) -> None:
|
| 465 |
+
+ payload = notification.payload
|
| 466 |
+
+ event = payload.get("event") if isinstance(payload, dict) else None
|
| 467 |
+
+ if (
|
| 468 |
+
+ notification.method != "session.event"
|
| 469 |
+
+ or not isinstance(event, dict)
|
| 470 |
+
+ # Token deltas repeat what their `assistant/message` already carries.
|
| 471 |
+
+ or event.get("type") == "assistant/chunk"
|
| 472 |
+
+ or payload.get("sessionId") != session
|
| 473 |
+
+ ):
|
| 474 |
+
+ return
|
| 475 |
+
+ collector.record(event)
|
| 476 |
+
+ checkpoint()
|
| 477 |
+
+
|
| 478 |
+
+ checkpoint()
|
| 479 |
+
+ print(f"dsh-minimal: model={model} effort={effort} session={session}")
|
| 480 |
+
+ try:
|
| 481 |
+
+ with DeepSeekHarness(
|
| 482 |
+
+ profile="sdk-minimal",
|
| 483 |
+
+ provider=PROVIDER,
|
| 484 |
+
+ model=model,
|
| 485 |
+
+ reasoning_effort=effort,
|
| 486 |
+
+ cwd=os.getcwd(),
|
| 487 |
+
+ dsh_home=os.environ["DSH_HOME"],
|
| 488 |
+
+ ) as harness:
|
| 489 |
+
+ result = harness.run(
|
| 490 |
+
+ args.instruction, session_id=session, on_notification=on_notification
|
| 491 |
+
+ )
|
| 492 |
+
+ state["finish_reason"] = result.finish_reason
|
| 493 |
+
+ print(f"dsh-minimal: finish_reason={result.finish_reason}")
|
| 494 |
+
+ print(f"dsh-minimal: final_response={result.final_response}")
|
| 495 |
+
+ except Exception as error: # noqa: BLE001 - the trajectory must survive any failure
|
| 496 |
+
+ state["failure"] = f"{type(error).__name__}: {error}"
|
| 497 |
+
+ traceback.print_exc()
|
| 498 |
+
+ finally:
|
| 499 |
+
+ checkpoint()
|
| 500 |
+
+
|
| 501 |
+
+ # `max-tokens` is a bounded model outcome the verifier can still grade; anything
|
| 502 |
+
+ # else non-terminal means the harness never produced a usable turn.
|
| 503 |
+
+ if state["failure"] is not None or state["finish_reason"] not in (
|
| 504 |
+
+ "completed",
|
| 505 |
+
+ "max-tokens",
|
| 506 |
+
+ ):
|
| 507 |
+
+ sys.exit(1)
|
| 508 |
+
+
|
| 509 |
+
+
|
| 510 |
+
+if __name__ == "__main__":
|
| 511 |
+
+ main()
|
| 512 |
+
diff --git a/src/pier/agents/installed/mini_swe_agent.py b/src/pier/agents/installed/mini_swe_agent.py
|
| 513 |
+
index 75d25b6..d283f66 100644
|
| 514 |
+
--- a/src/pier/agents/installed/mini_swe_agent.py
|
| 515 |
+
+++ b/src/pier/agents/installed/mini_swe_agent.py
|
| 516 |
+
@@ -11,6 +11,7 @@ from pier.agents.installed.base import (
|
| 517 |
+
BaseInstalledAgent,
|
| 518 |
+
CliFlag,
|
| 519 |
+
with_prompt_template,
|
| 520 |
+
+ with_runtime_constraints,
|
| 521 |
+
)
|
| 522 |
+
from pier.agents.network import allowlist_from_urls, collect_url_values
|
| 523 |
+
from pier.agents.utils import get_api_key_var_names_from_model_name
|
| 524 |
+
@@ -821,7 +822,7 @@ mini-swe-agent --help
|
| 525 |
+
async def run(
|
| 526 |
+
self, instruction: str, environment: BaseEnvironment, context: AgentContext
|
| 527 |
+
) -> None:
|
| 528 |
+
- augmented_instruction = instruction
|
| 529 |
+
+ augmented_instruction = with_runtime_constraints(instruction)
|
| 530 |
+
if self.mcp_servers:
|
| 531 |
+
mcp_info = "\n\nMCP Servers:\nThe following MCP servers are available for this task.\n"
|
| 532 |
+
for s in self.mcp_servers:
|
| 533 |
+
diff --git a/src/pier/environments/docker/__init__.py b/src/pier/environments/docker/__init__.py
|
| 534 |
+
index 4bb8f11..04a8c6e 100644
|
| 535 |
+
--- a/src/pier/environments/docker/__init__.py
|
| 536 |
+
+++ b/src/pier/environments/docker/__init__.py
|
| 537 |
+
@@ -25,6 +25,9 @@ def write_resources_compose_file(
|
| 538 |
+
*,
|
| 539 |
+
cpu_request: int | None = None,
|
| 540 |
+
cpu_limit: int | None = None,
|
| 541 |
+
+ environment: dict[str, str] | None = None,
|
| 542 |
+
+ sysctls: dict[str, str] | None = None,
|
| 543 |
+
+ volumes: list[str] | None = None,
|
| 544 |
+
memory_request_mb: int | None = None,
|
| 545 |
+
memory_limit_mb: int | None = None,
|
| 546 |
+
) -> Path:
|
| 547 |
+
@@ -46,7 +49,13 @@ def write_resources_compose_file(
|
| 548 |
+
if reservations:
|
| 549 |
+
resources["reservations"] = reservations
|
| 550 |
+
|
| 551 |
+
- main = {"deploy": {"resources": resources}} if resources else {}
|
| 552 |
+
+ main: dict[str, object] = {"deploy": {"resources": resources}} if resources else {}
|
| 553 |
+
+ if environment:
|
| 554 |
+
+ main["environment"] = dict(environment)
|
| 555 |
+
+ if sysctls:
|
| 556 |
+
+ main["sysctls"] = dict(sysctls)
|
| 557 |
+
+ if volumes:
|
| 558 |
+
+ main["volumes"] = list(volumes)
|
| 559 |
+
compose = {"services": {"main": main}}
|
| 560 |
+
path.parent.mkdir(parents=True, exist_ok=True)
|
| 561 |
+
path.write_text(json.dumps(compose, indent=2))
|
| 562 |
+
diff --git a/src/pier/environments/docker/docker.py b/src/pier/environments/docker/docker.py
|
| 563 |
+
index 2ed4e92..bc671be 100644
|
| 564 |
+
--- a/src/pier/environments/docker/docker.py
|
| 565 |
+
+++ b/src/pier/environments/docker/docker.py
|
| 566 |
+
@@ -31,6 +31,11 @@ from pier.environments.docker import (
|
| 567 |
+
write_mounts_compose_file,
|
| 568 |
+
write_resources_compose_file,
|
| 569 |
+
)
|
| 570 |
+
+from pier.environments.docker.parallelism import (
|
| 571 |
+
+ CPU_CLAMP_PATH,
|
| 572 |
+
+ cpu_clamp_source,
|
| 573 |
+
+ parallelism_env,
|
| 574 |
+
+)
|
| 575 |
+
from pier.models.environment_type import EnvironmentType
|
| 576 |
+
from pier.models.task.config import EnvironmentConfig, TaskOS
|
| 577 |
+
from pier.models.trial.config import ResourceMode, ServiceVolumeConfig
|
| 578 |
+
@@ -102,6 +107,11 @@ class DockerEnvironment(BaseEnvironment):
|
| 579 |
+
|
| 580 |
+
_DOCKER_COMPOSE_WINDOWS_KEEPALIVE_PATH = COMPOSE_WINDOWS_KEEPALIVE_PATH
|
| 581 |
+
|
| 582 |
+
+ # Docker leaves IPv6 off in the container netns, so loopback has no ::1 and
|
| 583 |
+
+ # suites that bind it skip where a real Linux host passes. These environments
|
| 584 |
+
+ # always get their own netns, which is what net.* sysctls require.
|
| 585 |
+
+ _LINUX_SYSCTLS = {"net.ipv6.conf.all.disable_ipv6": "0"}
|
| 586 |
+
+
|
| 587 |
+
# Class-level lock per image name to prevent parallel builds of the same image.
|
| 588 |
+
_image_build_locks: dict[str, asyncio.Lock] = {}
|
| 589 |
+
|
| 590 |
+
@@ -160,6 +170,7 @@ class DockerEnvironment(BaseEnvironment):
|
| 591 |
+
task_env_config: EnvironmentConfig,
|
| 592 |
+
keep_containers: bool = False,
|
| 593 |
+
mounts_json: list[ServiceVolumeConfig] | None = None,
|
| 594 |
+
+ mounts_override: list[ServiceVolumeConfig] | None = None,
|
| 595 |
+
*args,
|
| 596 |
+
**kwargs,
|
| 597 |
+
):
|
| 598 |
+
@@ -193,8 +204,13 @@ class DockerEnvironment(BaseEnvironment):
|
| 599 |
+
self._windows_container_name: str | None = None
|
| 600 |
+
self._platform = UnixOps(self)
|
| 601 |
+
|
| 602 |
+
+ # Configured mounts are additive so the default /logs binds survive and
|
| 603 |
+
+ # agent logs and artifacts stay host-visible. A separate verifier
|
| 604 |
+
+ # environment must not share those directories, so it overrides the set.
|
| 605 |
+
self._mounts_json = (
|
| 606 |
+
- mounts_json if mounts_json is not None else self._default_log_mounts()
|
| 607 |
+
+ [*self._default_log_mounts(), *(mounts_json or [])]
|
| 608 |
+
+ if mounts_override is None
|
| 609 |
+
+ else mounts_override
|
| 610 |
+
)
|
| 611 |
+
self._mounts_compose_path: Path | None = None
|
| 612 |
+
self._resources_compose_temp_dir: tempfile.TemporaryDirectory | None = None
|
| 613 |
+
@@ -427,12 +443,16 @@ class DockerEnvironment(BaseEnvironment):
|
| 614 |
+
Path(self._resources_compose_temp_dir.name)
|
| 615 |
+
/ f"{self.session_id}-{RESOURCES_COMPOSE_NAME}"
|
| 616 |
+
)
|
| 617 |
+
+ cpu_limit = self._resource_limit_value("cpu", auto_mode=ResourceMode.LIMIT)
|
| 618 |
+
return write_resources_compose_file(
|
| 619 |
+
path,
|
| 620 |
+
+ environment=parallelism_env(cpu_limit),
|
| 621 |
+
+ volumes=self._write_cpu_clamp(path.parent, cpu_limit),
|
| 622 |
+
+ sysctls=None if self._is_windows_container else self._LINUX_SYSCTLS,
|
| 623 |
+
cpu_request=self._resource_request_value(
|
| 624 |
+
"cpu", auto_mode=ResourceMode.LIMIT
|
| 625 |
+
),
|
| 626 |
+
- cpu_limit=self._resource_limit_value("cpu", auto_mode=ResourceMode.LIMIT),
|
| 627 |
+
+ cpu_limit=cpu_limit,
|
| 628 |
+
memory_request_mb=self._resource_request_value(
|
| 629 |
+
"memory", auto_mode=ResourceMode.LIMIT
|
| 630 |
+
),
|
| 631 |
+
@@ -441,6 +461,15 @@ class DockerEnvironment(BaseEnvironment):
|
| 632 |
+
),
|
| 633 |
+
)
|
| 634 |
+
|
| 635 |
+
+ def _write_cpu_clamp(self, directory: Path, cpu_limit: int | None) -> list[str]:
|
| 636 |
+
+ """Mount the preload that `parallelism_env` points NODE_OPTIONS at."""
|
| 637 |
+
+ if not cpu_limit or self._is_windows_container:
|
| 638 |
+
+ return []
|
| 639 |
+
+ source = directory / "pier-node-cpu-clamp.js"
|
| 640 |
+
+ source.write_text(cpu_clamp_source(cpu_limit))
|
| 641 |
+
+ source.chmod(0o644)
|
| 642 |
+
+ return [f"{source}:{CPU_CLAMP_PATH}:ro"]
|
| 643 |
+
+
|
| 644 |
+
def _cleanup_resources_compose_file(self) -> None:
|
| 645 |
+
if self._resources_compose_temp_dir is None:
|
| 646 |
+
return
|
| 647 |
+
diff --git a/src/pier/environments/docker/parallelism.py b/src/pier/environments/docker/parallelism.py
|
| 648 |
+
new file mode 100644
|
| 649 |
+
index 0000000..b21ae7c
|
| 650 |
+
--- /dev/null
|
| 651 |
+
+++ b/src/pier/environments/docker/parallelism.py
|
| 652 |
+
@@ -0,0 +1,34 @@
|
| 653 |
+
+"""Tell test runners how many CPUs the container actually gets.
|
| 654 |
+
+
|
| 655 |
+
+Docker's ``--cpus`` is a bandwidth quota, so ``nproc`` still reports every host
|
| 656 |
+
+core and runner worker pools oversubscribe the container.
|
| 657 |
+
+"""
|
| 658 |
+
+
|
| 659 |
+
+from __future__ import annotations
|
| 660 |
+
+
|
| 661 |
+
+CPU_CLAMP_PATH = "/opt/pier-node-cpu-clamp.js"
|
| 662 |
+
+
|
| 663 |
+
+
|
| 664 |
+
+def cpu_clamp_source(cpus: int) -> str:
|
| 665 |
+
+ """A ``node --require`` preload; the Node runners take no cap from the environment."""
|
| 666 |
+
+ return (
|
| 667 |
+
+ "const os = require('node:os')\n"
|
| 668 |
+
+ f"const limit = {cpus}\n"
|
| 669 |
+
+ "const cpus = os.cpus\n"
|
| 670 |
+
+ "os.cpus = () => cpus.call(os).slice(0, limit)\n"
|
| 671 |
+
+ "os.availableParallelism = () => limit\n"
|
| 672 |
+
+ )
|
| 673 |
+
+
|
| 674 |
+
+
|
| 675 |
+
+def parallelism_env(cpus: int | None) -> dict[str, str]:
|
| 676 |
+
+ """Worker-count caps for the test runners, derived from the CPU limit."""
|
| 677 |
+
+ if not cpus or cpus < 1:
|
| 678 |
+
+ return {}
|
| 679 |
+
+ n = str(cpus)
|
| 680 |
+
+ return {
|
| 681 |
+
+ "GOMAXPROCS": n,
|
| 682 |
+
+ "CARGO_BUILD_JOBS": n,
|
| 683 |
+
+ "NEXTEST_TEST_THREADS": n,
|
| 684 |
+
+ "PYTEST_XDIST_AUTO_NUM_WORKERS": n,
|
| 685 |
+
+ "NODE_OPTIONS": f"--require {CPU_CLAMP_PATH}",
|
| 686 |
+
+ }
|
| 687 |
+
diff --git a/src/pier/models/agent/name.py b/src/pier/models/agent/name.py
|
| 688 |
+
index d84516a..41ac147 100644
|
| 689 |
+
--- a/src/pier/models/agent/name.py
|
| 690 |
+
+++ b/src/pier/models/agent/name.py
|
| 691 |
+
@@ -8,6 +8,7 @@ class AgentName(str, Enum):
|
| 692 |
+
ANTIGRAVITY_SDK = "antigravity-sdk"
|
| 693 |
+
CODEX = "codex"
|
| 694 |
+
CURSOR_CLI = "cursor-cli"
|
| 695 |
+
+ DSH_MINIMAL = "dsh-minimal"
|
| 696 |
+
GEMINI_CLI = "gemini-cli"
|
| 697 |
+
MINI_SWE_AGENT = "mini-swe-agent"
|
| 698 |
+
SWE_AGENT = "swe-agent"
|
| 699 |
+
diff --git a/src/pier/trial/trial.py b/src/pier/trial/trial.py
|
| 700 |
+
index fd5d4a2..126f0fa 100644
|
| 701 |
+
--- a/src/pier/trial/trial.py
|
| 702 |
+
+++ b/src/pier/trial/trial.py
|
| 703 |
+
@@ -402,7 +402,7 @@ class Trial:
|
| 704 |
+
trial_paths=self._trial_paths,
|
| 705 |
+
task_env_config=env_config,
|
| 706 |
+
logger=self._logger,
|
| 707 |
+
- mounts_json=self._verifier_env_mounts(env_config),
|
| 708 |
+
+ mounts_override=self._verifier_env_mounts(env_config),
|
| 709 |
+
agent_install_spec=None,
|
| 710 |
+
network_allowlist=None,
|
| 711 |
+
default_user=(
|
inference/README.md
ADDED
|
@@ -0,0 +1,71 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Minimal inference
|
| 2 |
+
|
| 3 |
+
A readable reference implementation rather than a production serving engine. The
|
| 4 |
+
model code covers the vision encoder and aligner, sliding-window plus compressed
|
| 5 |
+
sparse attention with its two-level indexer, engram n-gram lookups, MoE,
|
| 6 |
+
Hyper-Connections, and the DSpark forward path. Generation itself is plain
|
| 7 |
+
autoregressive sampling.
|
| 8 |
+
|
| 9 |
+
## Install
|
| 10 |
+
|
| 11 |
+
```bash
|
| 12 |
+
python -m pip install -r requirements.txt
|
| 13 |
+
```
|
| 14 |
+
|
| 15 |
+
## Convert Hugging Face weights
|
| 16 |
+
|
| 17 |
+
The runtime uses one converted checkpoint file per tensor-parallel rank. From
|
| 18 |
+
this directory:
|
| 19 |
+
|
| 20 |
+
```bash
|
| 21 |
+
export HF_CKPT_PATH=/path/to/DeepSeek-V4.1-Flash-HF
|
| 22 |
+
export SAVE_PATH=/path/to/DeepSeek-V4.1-Flash-TP8
|
| 23 |
+
export MP=8
|
| 24 |
+
|
| 25 |
+
python convert.py \
|
| 26 |
+
--hf-ckpt-path "${HF_CKPT_PATH}" \
|
| 27 |
+
--save-path "${SAVE_PATH}" \
|
| 28 |
+
--model-parallel "${MP}" \
|
| 29 |
+
--expert-dtype fp4 \
|
| 30 |
+
--tokenizer-path "${HF_CKPT_PATH}"
|
| 31 |
+
```
|
| 32 |
+
|
| 33 |
+
Expert counts are inferred from the weight names, so they do not need to be
|
| 34 |
+
passed. `--tokenizer-path` points at whichever directory holds `tokenizer.json`
|
| 35 |
+
and `tokenizer_config.json`; they are copied into the converted checkpoint.
|
| 36 |
+
|
| 37 |
+
## Run the equivalent TXT and JSON examples
|
| 38 |
+
|
| 39 |
+
```bash
|
| 40 |
+
export CKPT_PATH=/path/to/DeepSeek-V4.1-Flash-TP8
|
| 41 |
+
export MP=8
|
| 42 |
+
|
| 43 |
+
INPUT_FILE=examples/example.txt ./run.sh
|
| 44 |
+
INPUT_FILE=examples/example_harmony.json ./run.sh
|
| 45 |
+
```
|
| 46 |
+
|
| 47 |
+
The two files express the same interleaved two-image prompt, so they produce
|
| 48 |
+
identical encoded prompts and input token IDs.
|
| 49 |
+
|
| 50 |
+
For interactive chat:
|
| 51 |
+
|
| 52 |
+
```bash
|
| 53 |
+
torchrun --nproc-per-node "${MP}" generate.py \
|
| 54 |
+
--ckpt-path "${CKPT_PATH}" \
|
| 55 |
+
--config config.json \
|
| 56 |
+
--interactive \
|
| 57 |
+
--temperature 0.6
|
| 58 |
+
```
|
| 59 |
+
|
| 60 |
+
For multi-node execution, pass the usual `torchrun --nnodes`, `--node-rank`,
|
| 61 |
+
`--master-addr`, and `--master-port` arguments before `generate.py`.
|
| 62 |
+
|
| 63 |
+
## Self-test
|
| 64 |
+
|
| 65 |
+
`model.py` builds a small model from the `ModelArgs` defaults and runs a prefill
|
| 66 |
+
plus 22 decode steps, exercising the real dense-fp8 / MoE-fp4 kernels. Weights
|
| 67 |
+
are uninitialized, so it checks shapes and kernel plumbing, not numerics:
|
| 68 |
+
|
| 69 |
+
```bash
|
| 70 |
+
python model.py
|
| 71 |
+
```
|
inference/config.json
ADDED
|
@@ -0,0 +1,66 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"vocab_size": 129280,
|
| 3 |
+
"dim": 5120,
|
| 4 |
+
"moe_inter_dim": 2304,
|
| 5 |
+
"n_layers": 40,
|
| 6 |
+
"n_mtp_layers": 3,
|
| 7 |
+
"dspark_block_size": 5,
|
| 8 |
+
"dspark_noise_token_id": 128799,
|
| 9 |
+
"dspark_target_layer_ids": [37, 38, 39],
|
| 10 |
+
"dspark_markov_rank": 256,
|
| 11 |
+
"dspark_n_routed_experts": 128,
|
| 12 |
+
"dspark_n_activated_experts": 3,
|
| 13 |
+
"n_heads": 64,
|
| 14 |
+
"n_routed_experts": 384,
|
| 15 |
+
"n_shared_experts": 1,
|
| 16 |
+
"n_activated_experts": 6,
|
| 17 |
+
"score_func": "sqrtsoftplus",
|
| 18 |
+
"route_scale": 1.5,
|
| 19 |
+
"swiglu_limit": 10.0,
|
| 20 |
+
"q_lora_rank": 1280,
|
| 21 |
+
"head_dim": 512,
|
| 22 |
+
"rope_head_dim": 64,
|
| 23 |
+
"norm_eps": 1e-20,
|
| 24 |
+
"o_groups": 8,
|
| 25 |
+
"o_lora_rank": 1024,
|
| 26 |
+
"window_size": 128,
|
| 27 |
+
"kv_source_layers": [2, 8, 14, 20],
|
| 28 |
+
"index_source_layers": [2, 8, 14, 20, 24, 28, 32, 36],
|
| 29 |
+
"original_seq_len": 65536,
|
| 30 |
+
"rope_theta": 10000,
|
| 31 |
+
"rope_factor": 16,
|
| 32 |
+
"beta_fast": 32,
|
| 33 |
+
"beta_slow": 1,
|
| 34 |
+
"index_n_heads": 32,
|
| 35 |
+
"index_head_dim": 128,
|
| 36 |
+
"index_topk": 512,
|
| 37 |
+
"candidate_source_layer": 20,
|
| 38 |
+
"candidate_topk_blocks": 2048,
|
| 39 |
+
"candidate_block_size": 8,
|
| 40 |
+
"hc_mult": 4,
|
| 41 |
+
"hc_sinkhorn_iters": 20,
|
| 42 |
+
"hc_eps": 1e-06,
|
| 43 |
+
"engram_layer_ids": [1, 14],
|
| 44 |
+
"engram_vocab_size": 16000000,
|
| 45 |
+
"engram_num_embeddings": [384006168, 384016682],
|
| 46 |
+
"engram_max_ngram_size": 4,
|
| 47 |
+
"engram_pad_id": 2,
|
| 48 |
+
"engram_compressed_vocab_size": 99092,
|
| 49 |
+
"dtype": "fp8",
|
| 50 |
+
"expert_dtype": "fp4",
|
| 51 |
+
"compress_rope_theta": 160000,
|
| 52 |
+
"compress_ratios": [0, 0, 2, 2, 2, 2, 2, 2, 2, 2, 2, 2, 2, 2, 2, 2, 2, 2, 2, 2, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 0, 0, 0],
|
| 53 |
+
"vision_n_layers": 32,
|
| 54 |
+
"vision_dim": 1024,
|
| 55 |
+
"vision_n_heads": 16,
|
| 56 |
+
"vision_inter_dim": 2816,
|
| 57 |
+
"vision_patch_size": 14,
|
| 58 |
+
"vision_downsample_ratio": 3,
|
| 59 |
+
"vision_max_n_token": 1024,
|
| 60 |
+
"vision_min_pixels": 295936,
|
| 61 |
+
"vision_max_wh_ratio": null,
|
| 62 |
+
"image_token_id": 129264,
|
| 63 |
+
"engram_n_heads": 8,
|
| 64 |
+
"engram_head_dim": 256,
|
| 65 |
+
"vision_rope_theta": 10000
|
| 66 |
+
}
|
inference/convert.py
ADDED
|
@@ -0,0 +1,205 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
import json
|
| 2 |
+
import os
|
| 3 |
+
import re
|
| 4 |
+
import shutil
|
| 5 |
+
from argparse import ArgumentParser
|
| 6 |
+
from glob import glob
|
| 7 |
+
from tqdm import tqdm, trange
|
| 8 |
+
|
| 9 |
+
import torch
|
| 10 |
+
from safetensors.torch import safe_open, save_file
|
| 11 |
+
|
| 12 |
+
|
| 13 |
+
FP4_TABLE = torch.tensor(
|
| 14 |
+
[0.0, 0.5, 1.0, 1.5, 2.0, 3.0, 4.0, 6.0, 0.0, -0.5, -1.0, -1.5, -2.0, -3.0, -4.0, -6.0], dtype=torch.float32
|
| 15 |
+
)
|
| 16 |
+
|
| 17 |
+
|
| 18 |
+
def cast_e2m1fn_to_e4m3fn(x: torch.Tensor, scale: torch.Tensor) -> tuple[torch.Tensor, torch.Tensor]:
|
| 19 |
+
"""
|
| 20 |
+
Casts a tensor from e2m1fn to e4m3fn losslessly.
|
| 21 |
+
"""
|
| 22 |
+
assert x.dtype == torch.int8
|
| 23 |
+
assert x.ndim == 2
|
| 24 |
+
out_dim, in_dim = x.size()
|
| 25 |
+
in_dim *= 2
|
| 26 |
+
fp8_block_size = 32
|
| 27 |
+
fp4_block_size = 32
|
| 28 |
+
assert in_dim % fp8_block_size == 0 and out_dim % fp8_block_size == 0
|
| 29 |
+
assert scale.size(0) == out_dim and scale.size(1) == in_dim // fp4_block_size
|
| 30 |
+
|
| 31 |
+
x = x.view(torch.uint8)
|
| 32 |
+
low = x & 0x0F
|
| 33 |
+
high = (x >> 4) & 0x0F
|
| 34 |
+
x = torch.stack([FP4_TABLE[low.long()], FP4_TABLE[high.long()]], dim=-1).flatten(2)
|
| 35 |
+
|
| 36 |
+
# max_fp4 (6.0) * MAX_OFFSET must fit in e4m3fn (max 448)
|
| 37 |
+
# 6.0 * 2^6 = 384 < 448; 6.0 * 2^7 = 768 > 448; so MAX_OFFSET_BITS = 6
|
| 38 |
+
MAX_OFFSET_BITS = 6
|
| 39 |
+
|
| 40 |
+
bOut = out_dim // fp8_block_size
|
| 41 |
+
bIn = in_dim // fp8_block_size
|
| 42 |
+
# bOut, bIn, fp8_block_size, fp8_block_size
|
| 43 |
+
x = x.view(bOut, fp8_block_size, bIn, fp8_block_size).transpose(1, 2)
|
| 44 |
+
# bOut, bIn, fp8_block_size * (fp8_block_size // fp4_block_size)
|
| 45 |
+
scale = scale.float().view(bOut, fp8_block_size, bIn, -1).transpose(1, 2).flatten(2)
|
| 46 |
+
## bOut, bIn, 1
|
| 47 |
+
scale_max_offset_bits = scale.amax(dim=-1, keepdim=True) / (2**MAX_OFFSET_BITS)
|
| 48 |
+
# bOut, bIn, fp8_block_size * (fp8_block_size // fp4_block_size)
|
| 49 |
+
offset = scale / scale_max_offset_bits
|
| 50 |
+
# bOut, bIn, fp8_block_size, fp8_block_size
|
| 51 |
+
offset = offset.unflatten(-1, (fp8_block_size, -1)).repeat_interleave(fp4_block_size, dim=-1)
|
| 52 |
+
x = (x * offset).transpose(1, 2).reshape(out_dim, in_dim)
|
| 53 |
+
return x.to(torch.float8_e4m3fn), scale_max_offset_bits.squeeze(-1).to(torch.float8_e8m0fnu)
|
| 54 |
+
|
| 55 |
+
|
| 56 |
+
mapping = {
|
| 57 |
+
"embed": ("embed", 0),
|
| 58 |
+
"wq_b": ("wq_b", 0),
|
| 59 |
+
"wo_a": ("wo_a", 0),
|
| 60 |
+
"wo_b": ("wo_b", 1),
|
| 61 |
+
"head": ("head", 0),
|
| 62 |
+
"attn_sink": ("attn_sink", 0),
|
| 63 |
+
"weights_proj": ("weights_proj", 0),
|
| 64 |
+
}
|
| 65 |
+
|
| 66 |
+
|
| 67 |
+
def infer_num_experts(names) -> tuple[int, int]:
|
| 68 |
+
"""Number of routed experts in the backbone and in the MTP layers, from the weight names."""
|
| 69 |
+
counts = [0, 0]
|
| 70 |
+
for name in names:
|
| 71 |
+
name = name.removeprefix("model.")
|
| 72 |
+
match = re.search(r"(?:mlp|ffn)\.experts\.(\d+)\.", name)
|
| 73 |
+
if match:
|
| 74 |
+
is_mtp = name.startswith("mtp.")
|
| 75 |
+
counts[is_mtp] = max(counts[is_mtp], int(match.group(1)) + 1)
|
| 76 |
+
assert counts[0], "no routed experts found in the checkpoint"
|
| 77 |
+
return counts[0], counts[1] or counts[0]
|
| 78 |
+
|
| 79 |
+
|
| 80 |
+
def main(hf_ckpt_path, save_path, mp, expert_dtype, tokenizer_path=None):
|
| 81 |
+
"""Shard an exported HuggingFace checkpoint into `mp` files for this inference stack."""
|
| 82 |
+
torch.set_num_threads(8)
|
| 83 |
+
state_dicts = [{} for _ in range(mp)]
|
| 84 |
+
os.makedirs(save_path, exist_ok=True)
|
| 85 |
+
|
| 86 |
+
index_path = os.path.join(hf_ckpt_path, "model.safetensors.index.json")
|
| 87 |
+
expected_names = set(json.load(open(index_path))["weight_map"]) if os.path.exists(index_path) else None
|
| 88 |
+
seen_names = set()
|
| 89 |
+
|
| 90 |
+
all_names = expected_names
|
| 91 |
+
if all_names is None:
|
| 92 |
+
all_names = set()
|
| 93 |
+
for file_path in glob(os.path.join(hf_ckpt_path, "*.safetensors")):
|
| 94 |
+
with safe_open(file_path, framework="pt", device="cpu") as f:
|
| 95 |
+
all_names.update(f.keys())
|
| 96 |
+
n_experts, mtp_n_experts = infer_num_experts(all_names)
|
| 97 |
+
assert n_experts % mp == 0 and mtp_n_experts % mp == 0, (n_experts, mtp_n_experts, mp)
|
| 98 |
+
print(f"{n_experts=} {mtp_n_experts=}")
|
| 99 |
+
|
| 100 |
+
for file_path in tqdm(glob(os.path.join(hf_ckpt_path, "*.safetensors"))):
|
| 101 |
+
with safe_open(file_path, framework="pt", device="cpu") as f:
|
| 102 |
+
for source_name in f.keys():
|
| 103 |
+
seen_names.add(source_name)
|
| 104 |
+
name = source_name
|
| 105 |
+
if name.startswith("model."):
|
| 106 |
+
name = name[len("model.") :]
|
| 107 |
+
param: torch.Tensor = f.get_tensor(source_name)
|
| 108 |
+
# an MTP layer ties its token embedding and output head to the backbone's
|
| 109 |
+
if name.startswith("mtp.") and name.split(".", 2)[-1] in ("embed.weight", "head.weight"):
|
| 110 |
+
continue
|
| 111 |
+
name = name.replace("self_attn", "attn")
|
| 112 |
+
if not name.startswith("vision."):
|
| 113 |
+
name = name.replace("mlp", "ffn")
|
| 114 |
+
name = name.replace("weight_scale_inv", "scale")
|
| 115 |
+
name = name.replace("e_score_correction_bias", "bias")
|
| 116 |
+
if any(
|
| 117 |
+
x in name for x in ["hc", "attn_sink", "tie2eid", "tid2eid", "ape", "image_"]
|
| 118 |
+
): # without .weight
|
| 119 |
+
key = name.split(".")[-1]
|
| 120 |
+
else:
|
| 121 |
+
key = name.split(".")[-2]
|
| 122 |
+
if key in mapping:
|
| 123 |
+
new_key, dim = mapping[key]
|
| 124 |
+
else:
|
| 125 |
+
new_key, dim = key, None
|
| 126 |
+
name = name.replace(key, new_key)
|
| 127 |
+
for i in range(mp):
|
| 128 |
+
new_param = param
|
| 129 |
+
if "experts" in name and "shared_experts" not in name:
|
| 130 |
+
current_n_experts = mtp_n_experts if name.startswith("mtp.") else n_experts
|
| 131 |
+
n_local_experts = current_n_experts // mp
|
| 132 |
+
idx = int(name.split(".")[-3])
|
| 133 |
+
if idx < i * n_local_experts or idx >= (i + 1) * n_local_experts:
|
| 134 |
+
continue
|
| 135 |
+
elif ".engram.embed." in name:
|
| 136 |
+
shard_size = (param.size(0) + mp - 1) // mp
|
| 137 |
+
new_param = param[i * shard_size : (i + 1) * shard_size].contiguous()
|
| 138 |
+
if new_param.size(0) < shard_size:
|
| 139 |
+
pad_value = 1 if name.endswith(".scale") else 0
|
| 140 |
+
padding = param.new_full((shard_size - new_param.size(0), param.size(1)), pad_value)
|
| 141 |
+
new_param = torch.cat([new_param, padding])
|
| 142 |
+
elif dim is not None:
|
| 143 |
+
assert param.size(dim) % mp == 0, f"Dimension {dim} must be divisible by {mp}"
|
| 144 |
+
shard_size = param.size(dim) // mp
|
| 145 |
+
new_param = param.narrow(dim, i * shard_size, shard_size).contiguous()
|
| 146 |
+
state_dicts[i][name] = new_param
|
| 147 |
+
|
| 148 |
+
if expected_names is not None:
|
| 149 |
+
assert seen_names == expected_names, (
|
| 150 |
+
f"checkpoint shards incomplete: {len(expected_names - seen_names)} tensors missing, "
|
| 151 |
+
f"{len(seen_names - expected_names)} unexpected (source may be mid-upload)"
|
| 152 |
+
)
|
| 153 |
+
|
| 154 |
+
for i in trange(mp):
|
| 155 |
+
names = list(state_dicts[i].keys())
|
| 156 |
+
for name in names:
|
| 157 |
+
if name.endswith("wo_a.weight"):
|
| 158 |
+
weight = state_dicts[i][name]
|
| 159 |
+
scale = state_dicts[i].pop(name.replace("weight", "scale"))
|
| 160 |
+
assert weight.size(0) % scale.size(0) == 0
|
| 161 |
+
assert weight.size(1) % scale.size(1) == 0
|
| 162 |
+
out_block_size = weight.size(0) // scale.size(0)
|
| 163 |
+
in_block_size = weight.size(1) // scale.size(1)
|
| 164 |
+
assert (out_block_size, in_block_size) in ((32, 32), (128, 128)), (
|
| 165 |
+
name,
|
| 166 |
+
weight.shape,
|
| 167 |
+
scale.shape,
|
| 168 |
+
)
|
| 169 |
+
weight = (
|
| 170 |
+
weight.unflatten(0, (-1, out_block_size)).unflatten(-1, (-1, in_block_size)).float()
|
| 171 |
+
* scale[:, None, :, None].float()
|
| 172 |
+
)
|
| 173 |
+
state_dicts[i][name] = weight.flatten(2, 3).flatten(0, 1).bfloat16()
|
| 174 |
+
elif "experts" in name and state_dicts[i][name].dtype == torch.int8:
|
| 175 |
+
if expert_dtype == "fp8":
|
| 176 |
+
scale_name = name.replace("weight", "scale")
|
| 177 |
+
weight = state_dicts[i].pop(name)
|
| 178 |
+
scale = state_dicts[i].pop(scale_name)
|
| 179 |
+
state_dicts[i][name], state_dicts[i][scale_name] = cast_e2m1fn_to_e4m3fn(weight, scale)
|
| 180 |
+
else:
|
| 181 |
+
state_dicts[i][name] = state_dicts[i][name].view(torch.float4_e2m1fn_x2)
|
| 182 |
+
save_file(state_dicts[i], os.path.join(save_path, f"model{i}-mp{mp}.safetensors"))
|
| 183 |
+
|
| 184 |
+
tokenizer_path = tokenizer_path or hf_ckpt_path
|
| 185 |
+
for file in ["tokenizer.json", "tokenizer_config.json"]:
|
| 186 |
+
old_file_path = os.path.join(tokenizer_path, file)
|
| 187 |
+
new_file_path = os.path.join(save_path, file)
|
| 188 |
+
if os.path.exists(old_file_path):
|
| 189 |
+
shutil.copyfile(old_file_path, new_file_path)
|
| 190 |
+
|
| 191 |
+
|
| 192 |
+
if __name__ == "__main__":
|
| 193 |
+
parser = ArgumentParser()
|
| 194 |
+
parser.add_argument("--hf-ckpt-path", type=str, required=True)
|
| 195 |
+
parser.add_argument("--save-path", type=str, required=True)
|
| 196 |
+
parser.add_argument("--model-parallel", type=int, required=True)
|
| 197 |
+
parser.add_argument("--expert-dtype", type=str, choices=["fp8", "fp4"], default=None)
|
| 198 |
+
parser.add_argument(
|
| 199 |
+
"--tokenizer-path",
|
| 200 |
+
type=str,
|
| 201 |
+
default=None,
|
| 202 |
+
help="Optional tokenizer directory when the HF checkpoint does not contain tokenizer files",
|
| 203 |
+
)
|
| 204 |
+
args = parser.parse_args()
|
| 205 |
+
main(args.hf_ckpt_path, args.save_path, args.model_parallel, args.expert_dtype, args.tokenizer_path)
|
inference/engram.py
ADDED
|
@@ -0,0 +1,184 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
from dataclasses import dataclass
|
| 2 |
+
|
| 3 |
+
import numpy as np
|
| 4 |
+
import torch
|
| 5 |
+
from sympy import isprime
|
| 6 |
+
from torch import nn
|
| 7 |
+
|
| 8 |
+
|
| 9 |
+
def find_next_prime(start: int, seen_primes: set[int]) -> int:
|
| 10 |
+
"""The smallest prime above `start` that has not been handed out yet."""
|
| 11 |
+
candidate = start + 1
|
| 12 |
+
while not isprime(candidate) or candidate in seen_primes:
|
| 13 |
+
candidate += 1
|
| 14 |
+
return candidate
|
| 15 |
+
|
| 16 |
+
|
| 17 |
+
def build_compressed_token_map(tokenizer) -> tuple[list[int], int]:
|
| 18 |
+
"""Map every token id onto a smaller id space where tokens that normalize alike collapse together.
|
| 19 |
+
|
| 20 |
+
N-grams are hashed over these compressed ids, so " The", "the" and "THE" all hash the same way.
|
| 21 |
+
Returns the lookup plus the size of the compressed vocab -- and that size matters beyond bounds
|
| 22 |
+
checking, because every hash multiplier is derived from it.
|
| 23 |
+
"""
|
| 24 |
+
from tokenizers import Regex, normalizers
|
| 25 |
+
|
| 26 |
+
# a private-use char, so a token that is exactly one space survives Strip() instead of
|
| 27 |
+
# collapsing to the empty string and merging with unrelated tokens
|
| 28 |
+
sentinel = "\ue000"
|
| 29 |
+
normalizer = normalizers.Sequence(
|
| 30 |
+
[
|
| 31 |
+
normalizers.NFKC(),
|
| 32 |
+
normalizers.NFD(),
|
| 33 |
+
normalizers.StripAccents(),
|
| 34 |
+
normalizers.Lowercase(),
|
| 35 |
+
normalizers.Replace(Regex(r"[ \t\r\n]+"), " "),
|
| 36 |
+
normalizers.Replace(Regex(r"^ $"), sentinel),
|
| 37 |
+
normalizers.Strip(),
|
| 38 |
+
normalizers.Replace(sentinel, " "),
|
| 39 |
+
]
|
| 40 |
+
)
|
| 41 |
+
|
| 42 |
+
# the raw Rust tokenizer, matching what training decodes with (no clean_up_tokenization_spaces)
|
| 43 |
+
backend = tokenizer.backend_tokenizer
|
| 44 |
+
key_to_new: dict[str, int] = {}
|
| 45 |
+
lookup = [0] * len(tokenizer)
|
| 46 |
+
for token_id in range(len(tokenizer)):
|
| 47 |
+
text = backend.decode([token_id], skip_special_tokens=False)
|
| 48 |
+
if "\ufffd" in text:
|
| 49 |
+
# a partial UTF-8 byte token: nothing to normalize, so key it by its raw form
|
| 50 |
+
key = backend.id_to_token(token_id)
|
| 51 |
+
else:
|
| 52 |
+
normalized = normalizer.normalize_str(text)
|
| 53 |
+
key = normalized if normalized else text
|
| 54 |
+
|
| 55 |
+
new_id = key_to_new.get(key)
|
| 56 |
+
if new_id is None:
|
| 57 |
+
new_id = len(key_to_new)
|
| 58 |
+
key_to_new[key] = new_id
|
| 59 |
+
lookup[token_id] = new_id
|
| 60 |
+
|
| 61 |
+
return lookup, len(key_to_new)
|
| 62 |
+
|
| 63 |
+
|
| 64 |
+
def compute_hash_multipliers(
|
| 65 |
+
layer_ids: tuple[int, ...], max_ngram_size: int, tokenizer_vocab_size: int
|
| 66 |
+
) -> torch.Tensor:
|
| 67 |
+
"""One multiplier per (layer, lookback), from a per-layer RNG so layers hash differently.
|
| 68 |
+
|
| 69 |
+
Kept odd, and bounded so that `token_id * multiplier` cannot overflow int64.
|
| 70 |
+
"""
|
| 71 |
+
max_long = np.iinfo(np.int64).max
|
| 72 |
+
multiplier_bound = max(1, (max_long // tokenizer_vocab_size) // 2)
|
| 73 |
+
rows = []
|
| 74 |
+
for layer_id in layer_ids:
|
| 75 |
+
generator = np.random.default_rng(10007 * layer_id)
|
| 76 |
+
values = generator.integers(
|
| 77 |
+
low=0,
|
| 78 |
+
high=multiplier_bound,
|
| 79 |
+
size=(max_ngram_size,),
|
| 80 |
+
dtype=np.int64,
|
| 81 |
+
)
|
| 82 |
+
rows.append(torch.tensor(values * 2 + 1))
|
| 83 |
+
return torch.stack(rows)
|
| 84 |
+
|
| 85 |
+
|
| 86 |
+
@dataclass(frozen=True)
|
| 87 |
+
class EngramLayout:
|
| 88 |
+
"""Bucket layout of the n-gram hash tables.
|
| 89 |
+
|
| 90 |
+
A position is hashed as `max_ngram_size - 1` n-grams (2-gram .. max_ngram_size-gram), each split
|
| 91 |
+
over `n_heads` heads. Every (n-gram size, head) pair owns its own prime-sized bucket range in the
|
| 92 |
+
layer's table; the primes are drawn in order and never reused, which keeps the ranges disjoint.
|
| 93 |
+
"""
|
| 94 |
+
|
| 95 |
+
max_ngram_size: int
|
| 96 |
+
layer_ids: tuple[int, ...]
|
| 97 |
+
num_embeddings: tuple[int, ...] # table rows, per engram layer
|
| 98 |
+
primes: tuple[tuple[tuple[int, ...], ...], ...] # [layer][n-gram size][head] bucket modulus
|
| 99 |
+
n_heads: int
|
| 100 |
+
head_dim: int
|
| 101 |
+
|
| 102 |
+
@classmethod
|
| 103 |
+
def from_args(cls, args) -> "EngramLayout | None":
|
| 104 |
+
layer_ids = tuple(args.engram_layer_ids)
|
| 105 |
+
if not layer_ids:
|
| 106 |
+
return None
|
| 107 |
+
max_ngram_size, n_heads = args.engram_max_ngram_size, args.engram_n_heads
|
| 108 |
+
primes, seen = [], set()
|
| 109 |
+
for _ in layer_ids:
|
| 110 |
+
per_ngram = []
|
| 111 |
+
for _ in range(max_ngram_size - 1):
|
| 112 |
+
sizes, current = [], args.engram_vocab_size - 1
|
| 113 |
+
for _ in range(n_heads):
|
| 114 |
+
current = find_next_prime(current, seen)
|
| 115 |
+
seen.add(current)
|
| 116 |
+
sizes.append(current)
|
| 117 |
+
per_ngram.append(tuple(sizes))
|
| 118 |
+
primes.append(tuple(per_ngram))
|
| 119 |
+
return cls(
|
| 120 |
+
max_ngram_size=max_ngram_size,
|
| 121 |
+
layer_ids=layer_ids,
|
| 122 |
+
num_embeddings=tuple(args.engram_num_embeddings),
|
| 123 |
+
primes=tuple(primes),
|
| 124 |
+
n_heads=n_heads,
|
| 125 |
+
head_dim=args.engram_head_dim,
|
| 126 |
+
)
|
| 127 |
+
|
| 128 |
+
|
| 129 |
+
class NgramHashState(nn.Module):
|
| 130 |
+
"""Maps each position to the hash ids of the n-grams ending there.
|
| 131 |
+
|
| 132 |
+
Ids go through the compressed table, then each position is hashed with the `max_ngram_size - 1`
|
| 133 |
+
tokens before it. Look-back stops at the start of the sequence and at any dead token (an image
|
| 134 |
+
span, cached as DEAD), so an n-gram never spans one. The cache carries all of this across the
|
| 135 |
+
prefill/decode split.
|
| 136 |
+
"""
|
| 137 |
+
|
| 138 |
+
DEAD = -1
|
| 139 |
+
|
| 140 |
+
def __init__(self, args, layout: EngramLayout, tokenizer):
|
| 141 |
+
super().__init__()
|
| 142 |
+
self.layout = layout
|
| 143 |
+
# every hash multiplier derives from the compressed vocab size, so a mismatch there would
|
| 144 |
+
# silently rehash the whole table
|
| 145 |
+
token_map, vocab_size = build_compressed_token_map(tokenizer)
|
| 146 |
+
assert vocab_size == args.engram_compressed_vocab_size, (vocab_size, args.engram_compressed_vocab_size)
|
| 147 |
+
self.pad_id = token_map[args.engram_pad_id]
|
| 148 |
+
flat = [[p for per_ngram in layer for p in per_ngram] for layer in layout.primes]
|
| 149 |
+
offsets = [np.cumsum([0, *sizes[:-1]]) for sizes in flat]
|
| 150 |
+
multipliers = compute_hash_multipliers(layout.layer_ids, layout.max_ngram_size, vocab_size)
|
| 151 |
+
self.register_buffer("primes", torch.tensor(layout.primes), persistent=False)
|
| 152 |
+
self.register_buffer("offsets", torch.tensor(np.array(offsets)), persistent=False)
|
| 153 |
+
self.register_buffer("multipliers", multipliers, persistent=False)
|
| 154 |
+
self.register_buffer("token_map", torch.tensor(token_map), persistent=False)
|
| 155 |
+
self.register_buffer(
|
| 156 |
+
"cache", torch.empty(args.max_batch_size, args.max_seq_len, dtype=torch.int64), persistent=False
|
| 157 |
+
)
|
| 158 |
+
|
| 159 |
+
@torch.inference_mode()
|
| 160 |
+
def forward(self, input_ids: torch.Tensor, start_pos: int, token_mask: torch.Tensor | None = None) -> torch.Tensor:
|
| 161 |
+
"""token_mask: [B, L], False for tokens that take no part in an n-gram (image spans).
|
| 162 |
+
Returns the hash ids, shaped [B, L, n_engram_layers, n_hash_cols]."""
|
| 163 |
+
batch, seqlen = input_ids.shape
|
| 164 |
+
compressed = self.token_map[input_ids]
|
| 165 |
+
if token_mask is not None:
|
| 166 |
+
compressed = torch.where(token_mask, compressed, self.DEAD)
|
| 167 |
+
self.cache[:batch, start_pos : start_pos + seqlen] = compressed
|
| 168 |
+
|
| 169 |
+
positions = torch.arange(start_pos, start_pos + seqlen, device=input_ids.device).expand(batch, seqlen)
|
| 170 |
+
tokens, blocked = [], torch.zeros_like(positions, dtype=torch.bool)
|
| 171 |
+
for shift in range(self.layout.max_ngram_size):
|
| 172 |
+
source = self.cache[:batch].gather(1, (positions - shift).clamp_min(0))
|
| 173 |
+
blocked = blocked | (positions < shift) | (source == self.DEAD)
|
| 174 |
+
tokens.append(torch.where(blocked, self.pad_id, source))
|
| 175 |
+
tokens = torch.stack(tokens, dim=-1) # [B, L, max_ngram_size]
|
| 176 |
+
|
| 177 |
+
# XOR the multiplied ids together one lookback at a time, so the running value after step i
|
| 178 |
+
# is the hash of the (i+1)-gram; each lands in its own prime-sized bucket range
|
| 179 |
+
products = tokens.unsqueeze(2) * self.multipliers # [B, L, n_engram_layers, max_ngram_size]
|
| 180 |
+
rolling, hashes = products[..., 0], []
|
| 181 |
+
for i in range(1, self.layout.max_ngram_size):
|
| 182 |
+
rolling = torch.bitwise_xor(rolling, products[..., i])
|
| 183 |
+
hashes.append(rolling.unsqueeze(-1) % self.primes[:, i - 1])
|
| 184 |
+
return torch.cat(hashes, dim=-1) + self.offsets
|
inference/examples/example.txt
ADDED
|
@@ -0,0 +1,7 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
中国的首都是哪里?
|
| 2 |
+
|
| 3 |
+
列出100以内的所有素数。
|
| 4 |
+
|
| 5 |
+
DeepSeek是做什么的公司?
|
| 6 |
+
|
| 7 |
+
请按“第一张、第二张”的顺序回答:第一张图<image>examples/images/carrots.jpeg</image>和第二张图<image>examples/images/corn.jpeg</image>中分别是什么食材?它们通常食用的部位分别是什么?
|
inference/examples/example_harmony.json
ADDED
|
@@ -0,0 +1,96 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
[
|
| 2 |
+
{
|
| 3 |
+
"messages": [
|
| 4 |
+
{
|
| 5 |
+
"role": "user",
|
| 6 |
+
"content": [
|
| 7 |
+
{
|
| 8 |
+
"type": "text",
|
| 9 |
+
"text": "请按“第一张、第二张”的顺序回答:第一张图"
|
| 10 |
+
},
|
| 11 |
+
{
|
| 12 |
+
"type": "image_url",
|
| 13 |
+
"image_url": {
|
| 14 |
+
"url": "examples/images/carrots.jpeg"
|
| 15 |
+
}
|
| 16 |
+
},
|
| 17 |
+
{
|
| 18 |
+
"type": "text",
|
| 19 |
+
"text": "和第二张图"
|
| 20 |
+
},
|
| 21 |
+
{
|
| 22 |
+
"type": "image_url",
|
| 23 |
+
"image_url": {
|
| 24 |
+
"url": "examples/images/corn.jpeg"
|
| 25 |
+
}
|
| 26 |
+
},
|
| 27 |
+
{
|
| 28 |
+
"type": "text",
|
| 29 |
+
"text": "中分别是什么食材?它们通常食用的部位分别是什么?"
|
| 30 |
+
}
|
| 31 |
+
]
|
| 32 |
+
}
|
| 33 |
+
]
|
| 34 |
+
},
|
| 35 |
+
{
|
| 36 |
+
"messages": [
|
| 37 |
+
{
|
| 38 |
+
"role": "system",
|
| 39 |
+
"content": "You are a helpful assistant."
|
| 40 |
+
},
|
| 41 |
+
{
|
| 42 |
+
"role": "user",
|
| 43 |
+
"content": "中国的首都是哪里?"
|
| 44 |
+
}
|
| 45 |
+
]
|
| 46 |
+
},
|
| 47 |
+
{
|
| 48 |
+
"tools": [
|
| 49 |
+
{
|
| 50 |
+
"type": "function",
|
| 51 |
+
"function": {
|
| 52 |
+
"name": "get_weather",
|
| 53 |
+
"description": "Get the weather for a specific location",
|
| 54 |
+
"parameters": {
|
| 55 |
+
"type": "object",
|
| 56 |
+
"properties": {
|
| 57 |
+
"location": {"type": "string", "description": "The city name"},
|
| 58 |
+
"unit": {"type": "string", "enum": ["celsius", "fahrenheit"]}
|
| 59 |
+
},
|
| 60 |
+
"required": ["location"]
|
| 61 |
+
}
|
| 62 |
+
}
|
| 63 |
+
}
|
| 64 |
+
],
|
| 65 |
+
"messages": [
|
| 66 |
+
{
|
| 67 |
+
"role": "system",
|
| 68 |
+
"content": "You are a helpful assistant."
|
| 69 |
+
},
|
| 70 |
+
{
|
| 71 |
+
"role": "user",
|
| 72 |
+
"content": "What's the weather like in Beijing?"
|
| 73 |
+
}
|
| 74 |
+
]
|
| 75 |
+
},
|
| 76 |
+
{
|
| 77 |
+
"messages": [
|
| 78 |
+
{
|
| 79 |
+
"role": "system",
|
| 80 |
+
"content": "You are a helpful assistant."
|
| 81 |
+
},
|
| 82 |
+
{
|
| 83 |
+
"role": "user",
|
| 84 |
+
"content": "Hello"
|
| 85 |
+
},
|
| 86 |
+
{
|
| 87 |
+
"role": "assistant",
|
| 88 |
+
"content": "Hi there! How can I help you?"
|
| 89 |
+
},
|
| 90 |
+
{
|
| 91 |
+
"role": "system",
|
| 92 |
+
"content": "Mid-conversation instruction update: reply in Chinese only. (deepseek_v41 only)"
|
| 93 |
+
}
|
| 94 |
+
]
|
| 95 |
+
}
|
| 96 |
+
]
|
inference/examples/images/carrots.jpeg
ADDED
|
Git LFS Details
|
inference/examples/images/corn.jpeg
ADDED
|
inference/generate.py
ADDED
|
@@ -0,0 +1,218 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
import os
|
| 2 |
+
import json
|
| 3 |
+
import sys
|
| 4 |
+
from argparse import ArgumentParser
|
| 5 |
+
from typing import List
|
| 6 |
+
|
| 7 |
+
import torch
|
| 8 |
+
import torch.distributed as dist
|
| 9 |
+
from transformers import AutoTokenizer
|
| 10 |
+
from safetensors.torch import load_model
|
| 11 |
+
|
| 12 |
+
from model import Transformer, ModelArgs
|
| 13 |
+
|
| 14 |
+
current_dir = os.path.dirname(os.path.abspath(__file__))
|
| 15 |
+
sys.path.insert(0, os.path.abspath(os.path.join(current_dir, "../encoding")))
|
| 16 |
+
|
| 17 |
+
from encoding import (
|
| 18 |
+
encode_case,
|
| 19 |
+
encode_messages,
|
| 20 |
+
load_cases,
|
| 21 |
+
parse_message_from_completion_text,
|
| 22 |
+
parse_tagged_text,
|
| 23 |
+
to_json,
|
| 24 |
+
)
|
| 25 |
+
from image_processor import TEXT, prepare_vl_inputs
|
| 26 |
+
|
| 27 |
+
|
| 28 |
+
@torch.inference_mode()
|
| 29 |
+
def generate(
|
| 30 |
+
model: Transformer,
|
| 31 |
+
prompt_tokens: List[List[int]],
|
| 32 |
+
max_new_tokens: int,
|
| 33 |
+
eos_id: int,
|
| 34 |
+
prompt_token_types: List[List[int]] | None = None,
|
| 35 |
+
images=None,
|
| 36 |
+
) -> List[List[int]]:
|
| 37 |
+
"""Batch generation with right-padded prompts.
|
| 38 |
+
|
| 39 |
+
The first forward pass processes [:min_prompt_len] tokens (prefill phase).
|
| 40 |
+
Subsequent passes generate one token at a time (decode phase). For positions
|
| 41 |
+
still within a prompt, the ground-truth token overrides the model's prediction.
|
| 42 |
+
|
| 43 |
+
`prompt_token_types` and `images` come from image_processor.prepare_vl_inputs. Image spans are
|
| 44 |
+
only visible to the prefill pass, so they must end before the shortest prompt does.
|
| 45 |
+
"""
|
| 46 |
+
prompt_lens = [len(t) for t in prompt_tokens]
|
| 47 |
+
assert max(prompt_lens) <= model.max_seq_len, (
|
| 48 |
+
f"Prompt length exceeds model maximum sequence length (max_seq_len={model.max_seq_len})"
|
| 49 |
+
)
|
| 50 |
+
total_len = min(model.max_seq_len, max_new_tokens + max(prompt_lens))
|
| 51 |
+
tokens = torch.full((len(prompt_tokens), total_len), -1, dtype=torch.long)
|
| 52 |
+
for i, t in enumerate(prompt_tokens):
|
| 53 |
+
tokens[i, : len(t)] = torch.tensor(t, dtype=torch.long)
|
| 54 |
+
|
| 55 |
+
token_types = None
|
| 56 |
+
if images is not None:
|
| 57 |
+
token_types = torch.full((len(prompt_tokens), total_len), TEXT, dtype=torch.long)
|
| 58 |
+
for i, types in enumerate(prompt_token_types):
|
| 59 |
+
token_types[i, : len(types)] = torch.tensor(types, dtype=torch.long)
|
| 60 |
+
for sample in images:
|
| 61 |
+
for img in sample or ():
|
| 62 |
+
assert img.start + img.types.numel() <= min(prompt_lens), "image spans must fit in the prefill chunk"
|
| 63 |
+
|
| 64 |
+
prev_pos = 0
|
| 65 |
+
finished = torch.tensor([False] * len(prompt_tokens))
|
| 66 |
+
prompt_mask = tokens != -1
|
| 67 |
+
for cur_pos in range(min(prompt_lens), total_len):
|
| 68 |
+
with_images = images is not None and prev_pos == 0
|
| 69 |
+
next_token = model.forward(
|
| 70 |
+
tokens[:, prev_pos:cur_pos],
|
| 71 |
+
prev_pos,
|
| 72 |
+
images=images if with_images else None,
|
| 73 |
+
token_types=token_types[:, prev_pos:cur_pos] if with_images else None,
|
| 74 |
+
)[0]
|
| 75 |
+
next_token = torch.where(prompt_mask[:, cur_pos], tokens[:, cur_pos], next_token)
|
| 76 |
+
tokens[:, cur_pos] = next_token
|
| 77 |
+
finished |= torch.logical_and(~prompt_mask[:, cur_pos], next_token == eos_id)
|
| 78 |
+
prev_pos = cur_pos
|
| 79 |
+
if finished.all():
|
| 80 |
+
break
|
| 81 |
+
completion_tokens = []
|
| 82 |
+
for i, toks in enumerate(tokens.tolist()):
|
| 83 |
+
toks = toks[prompt_lens[i] : prompt_lens[i] + max_new_tokens]
|
| 84 |
+
if eos_id in toks:
|
| 85 |
+
toks = toks[: toks.index(eos_id)]
|
| 86 |
+
completion_tokens.append(toks)
|
| 87 |
+
return completion_tokens
|
| 88 |
+
|
| 89 |
+
|
| 90 |
+
def prepare_case(case, thinking_mode, tokenizer, args):
|
| 91 |
+
"""Encode one message case and expand any image placeholders."""
|
| 92 |
+
if case.get("context"):
|
| 93 |
+
raise ValueError("Standalone inference does not support context without a prefilled KV cache")
|
| 94 |
+
prompt, image_records = encode_case(case, thinking_mode)
|
| 95 |
+
tokens, token_types, images = prepare_vl_inputs(prompt, image_records, tokenizer, args)
|
| 96 |
+
return prompt, tokens, token_types, images
|
| 97 |
+
|
| 98 |
+
|
| 99 |
+
def main(
|
| 100 |
+
ckpt_path: str,
|
| 101 |
+
config: str,
|
| 102 |
+
input_file: str = "",
|
| 103 |
+
interactive: bool = True,
|
| 104 |
+
max_new_tokens: int = 100,
|
| 105 |
+
temperature: float = 1.0,
|
| 106 |
+
thinking_mode: str = "chat",
|
| 107 |
+
) -> None:
|
| 108 |
+
world_size = int(os.getenv("WORLD_SIZE", "1"))
|
| 109 |
+
rank = int(os.getenv("RANK", "0"))
|
| 110 |
+
local_rank = int(os.getenv("LOCAL_RANK", "0"))
|
| 111 |
+
if world_size > 1:
|
| 112 |
+
dist.init_process_group("nccl")
|
| 113 |
+
global print
|
| 114 |
+
if rank != 0:
|
| 115 |
+
print = lambda *_, **__: None
|
| 116 |
+
torch.cuda.set_device(local_rank)
|
| 117 |
+
torch.cuda.memory._set_allocator_settings("expandable_segments:True")
|
| 118 |
+
torch.set_default_dtype(torch.bfloat16)
|
| 119 |
+
torch.set_num_threads(8)
|
| 120 |
+
torch.manual_seed(33377335)
|
| 121 |
+
with open(config) as f:
|
| 122 |
+
args = ModelArgs(**json.load(f))
|
| 123 |
+
args.temperature = temperature
|
| 124 |
+
if interactive:
|
| 125 |
+
args.max_batch_size = 1
|
| 126 |
+
args.max_seq_len = 64 * 1024
|
| 127 |
+
print(args)
|
| 128 |
+
tokenizer = AutoTokenizer.from_pretrained(ckpt_path)
|
| 129 |
+
print("build model")
|
| 130 |
+
with torch.device("cuda"):
|
| 131 |
+
model = Transformer(args, tokenizer)
|
| 132 |
+
print("load model")
|
| 133 |
+
load_model(model, os.path.join(ckpt_path, f"model{rank}-mp{world_size}.safetensors"))
|
| 134 |
+
torch.set_default_device("cuda")
|
| 135 |
+
print("I'm DeepSeek 👋")
|
| 136 |
+
|
| 137 |
+
if interactive:
|
| 138 |
+
messages = []
|
| 139 |
+
while True:
|
| 140 |
+
if world_size == 1:
|
| 141 |
+
prompt = input(">>> ")
|
| 142 |
+
elif rank == 0:
|
| 143 |
+
prompt = input(">>> ")
|
| 144 |
+
objects = [prompt]
|
| 145 |
+
dist.broadcast_object_list(objects, 0)
|
| 146 |
+
else:
|
| 147 |
+
objects = [None]
|
| 148 |
+
dist.broadcast_object_list(objects, 0)
|
| 149 |
+
prompt = objects[0]
|
| 150 |
+
if prompt == "/exit":
|
| 151 |
+
break
|
| 152 |
+
elif prompt == "/clear":
|
| 153 |
+
messages.clear()
|
| 154 |
+
continue
|
| 155 |
+
messages.append({"role": "user", "content": prompt})
|
| 156 |
+
prompt_tokens = tokenizer.encode(encode_messages(messages, thinking_mode=thinking_mode))
|
| 157 |
+
completion_tokens = generate(model, [prompt_tokens], max_new_tokens, tokenizer.eos_token_id)
|
| 158 |
+
completion = tokenizer.decode(completion_tokens[0])
|
| 159 |
+
print(completion)
|
| 160 |
+
messages.append(parse_message_from_completion_text(completion, thinking_mode=thinking_mode))
|
| 161 |
+
else:
|
| 162 |
+
if input_file.endswith(".json"):
|
| 163 |
+
# Harmony input: a JSON file with one or more OpenAI-format cases
|
| 164 |
+
# ({"messages": [...], "tools": [...]} or a bare message list).
|
| 165 |
+
cases = load_cases(input_file)
|
| 166 |
+
raw_prompts = [to_json(case["messages"]) for case in cases]
|
| 167 |
+
else:
|
| 168 |
+
# Plain-text input: blank-line-separated prompts, optionally with
|
| 169 |
+
# <image>path</image> tags.
|
| 170 |
+
with open(input_file) as f:
|
| 171 |
+
raw_prompts = f.read().rstrip("\n").split("\n\n")
|
| 172 |
+
cases = [{"messages": [{"role": "user", "content": parse_tagged_text(prompt)}]} for prompt in raw_prompts]
|
| 173 |
+
|
| 174 |
+
prompt_tokens, prompt_token_types, images = [], [], []
|
| 175 |
+
for case in cases:
|
| 176 |
+
_, tokens, token_types, image_inputs = prepare_case(case, thinking_mode, tokenizer, args)
|
| 177 |
+
prompt_tokens.append(tokens)
|
| 178 |
+
prompt_token_types.append(token_types)
|
| 179 |
+
images.append(image_inputs)
|
| 180 |
+
|
| 181 |
+
if any(images):
|
| 182 |
+
# image spans must be prefilled in one chunk, so VL prompts are generated one at a time
|
| 183 |
+
completion_tokens = [
|
| 184 |
+
generate(model, [tok], max_new_tokens, tokenizer.eos_token_id, [types], [image])[0]
|
| 185 |
+
for tok, types, image in zip(prompt_tokens, prompt_token_types, images)
|
| 186 |
+
]
|
| 187 |
+
else:
|
| 188 |
+
completion_tokens = generate(model, prompt_tokens, max_new_tokens, tokenizer.eos_token_id)
|
| 189 |
+
completions = tokenizer.batch_decode(completion_tokens)
|
| 190 |
+
for raw_prompt, completion in zip(raw_prompts, completions):
|
| 191 |
+
print("Prompt:", raw_prompt)
|
| 192 |
+
print("Completion:", completion)
|
| 193 |
+
print()
|
| 194 |
+
|
| 195 |
+
if world_size > 1:
|
| 196 |
+
dist.destroy_process_group()
|
| 197 |
+
|
| 198 |
+
|
| 199 |
+
if __name__ == "__main__":
|
| 200 |
+
parser = ArgumentParser()
|
| 201 |
+
parser.add_argument("--ckpt-path", type=str, required=True)
|
| 202 |
+
parser.add_argument("--config", type=str, required=True)
|
| 203 |
+
parser.add_argument("--input-file", type=str, default="")
|
| 204 |
+
parser.add_argument("--interactive", action="store_true")
|
| 205 |
+
parser.add_argument("--max-new-tokens", type=int, default=200)
|
| 206 |
+
parser.add_argument("--temperature", type=float, default=1.0)
|
| 207 |
+
parser.add_argument("--thinking-mode", type=str, default="chat", choices=["chat", "thinking"])
|
| 208 |
+
args = parser.parse_args()
|
| 209 |
+
assert args.input_file or args.interactive, "Either input-file or interactive mode must be specified"
|
| 210 |
+
main(
|
| 211 |
+
args.ckpt_path,
|
| 212 |
+
args.config,
|
| 213 |
+
args.input_file,
|
| 214 |
+
args.interactive,
|
| 215 |
+
args.max_new_tokens,
|
| 216 |
+
args.temperature,
|
| 217 |
+
args.thinking_mode,
|
| 218 |
+
)
|
inference/image_processor.py
ADDED
|
@@ -0,0 +1,173 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Image preprocessing.
|
| 2 |
+
|
| 3 |
+
An image becomes a `n_vit_h x n_vit_w` patch grid for the ViT and a `n_llm_h x n_llm_w` token grid
|
| 4 |
+
after the 3x3 aligner downsample, which the LLM sees as
|
| 5 |
+
|
| 6 |
+
[IMAGE_START] + ([IMAGE] * n_llm_w + [IMAGE_NEW_LINE]) * n_llm_h + [IMAGE_END]
|
| 7 |
+
|
| 8 |
+
Every one of those positions carries `image_token_id` in `input_ids`; only the token type tells them
|
| 9 |
+
apart. The IMAGE slots are filled with aligner rows in reading order.
|
| 10 |
+
"""
|
| 11 |
+
|
| 12 |
+
import base64
|
| 13 |
+
import io
|
| 14 |
+
import math
|
| 15 |
+
from dataclasses import dataclass
|
| 16 |
+
from urllib.request import urlopen
|
| 17 |
+
|
| 18 |
+
import numpy as np
|
| 19 |
+
import torch
|
| 20 |
+
from PIL import Image, ImageOps
|
| 21 |
+
|
| 22 |
+
TEXT = -1
|
| 23 |
+
IMAGE_START, IMAGE, IMAGE_NEW_LINE, IMAGE_END = range(4)
|
| 24 |
+
|
| 25 |
+
|
| 26 |
+
@dataclass
|
| 27 |
+
class ImageInput:
|
| 28 |
+
start: int
|
| 29 |
+
patches: torch.Tensor
|
| 30 |
+
n_vit_h: int
|
| 31 |
+
n_vit_w: int
|
| 32 |
+
types: torch.Tensor
|
| 33 |
+
|
| 34 |
+
|
| 35 |
+
def num_image_tokens(n_llm_h: int, n_llm_w: int) -> int:
|
| 36 |
+
return n_llm_h * (n_llm_w + 1) + 2
|
| 37 |
+
|
| 38 |
+
|
| 39 |
+
def llm_grid(best_height: int, best_width: int, patch_size: int, downsample_ratio: int):
|
| 40 |
+
"""Token grid the aligner produces from a patch grid of this pixel size."""
|
| 41 |
+
return math.ceil((best_height // patch_size) / downsample_ratio), math.ceil(
|
| 42 |
+
(best_width // patch_size) / downsample_ratio
|
| 43 |
+
)
|
| 44 |
+
|
| 45 |
+
|
| 46 |
+
def solve_resize_ratio(height, width, patch_size, downsample_ratio, max_n_token):
|
| 47 |
+
"""Largest aspect-preserving pixel size whose token grid still fits in max_n_token."""
|
| 48 |
+
r = height / width
|
| 49 |
+
max_w_float = math.sqrt((max_n_token - 2) / r + 0.25) - 0.5
|
| 50 |
+
max_h_float = max_w_float * r
|
| 51 |
+
cell = patch_size * downsample_ratio
|
| 52 |
+
if max_w_float < 1.0: # very tall: collapse to a single column
|
| 53 |
+
return (max_n_token - 2) // 2 * cell, cell
|
| 54 |
+
if max_h_float < 1.0: # very wide: collapse to a single row
|
| 55 |
+
return cell, (max_n_token - 3) * cell
|
| 56 |
+
beta = min(math.floor(max_w_float) * cell / width, math.floor(max_h_float) * cell / height)
|
| 57 |
+
return math.floor(height * beta / patch_size) * patch_size, math.floor(width * beta / patch_size) * patch_size
|
| 58 |
+
|
| 59 |
+
|
| 60 |
+
def safe_resize(height, width, best_height, best_width, patch_size, downsample_ratio, max_n_token):
|
| 61 |
+
"""Shrink the pixel size until the image costs at most max_n_token LLM tokens."""
|
| 62 |
+
n_llm_h, n_llm_w = llm_grid(best_height, best_width, patch_size, downsample_ratio)
|
| 63 |
+
if num_image_tokens(n_llm_h, n_llm_w) > max_n_token:
|
| 64 |
+
best_height, best_width = solve_resize_ratio(height, width, patch_size, downsample_ratio, max_n_token)
|
| 65 |
+
n_llm_h, n_llm_w = llm_grid(best_height, best_width, patch_size, downsample_ratio)
|
| 66 |
+
assert num_image_tokens(n_llm_h, n_llm_w) <= max_n_token
|
| 67 |
+
return n_llm_h, n_llm_w, best_height, best_width
|
| 68 |
+
|
| 69 |
+
|
| 70 |
+
def load_image_bytes(record) -> bytes:
|
| 71 |
+
"""Load image bytes from raw/base64 data, an Anthropic source, URL, or path."""
|
| 72 |
+
data = record.get("data")
|
| 73 |
+
if isinstance(data, bytes):
|
| 74 |
+
return data
|
| 75 |
+
if isinstance(data, str):
|
| 76 |
+
return base64.b64decode(data)
|
| 77 |
+
|
| 78 |
+
source = record.get("source")
|
| 79 |
+
if isinstance(source, dict):
|
| 80 |
+
if source.get("data") is not None:
|
| 81 |
+
return base64.b64decode(source["data"])
|
| 82 |
+
if source.get("url"):
|
| 83 |
+
return load_image_bytes({"url": source["url"]})
|
| 84 |
+
|
| 85 |
+
url = record.get("url")
|
| 86 |
+
if isinstance(url, str) and url:
|
| 87 |
+
if url.startswith("data:"):
|
| 88 |
+
header, _, payload = url.partition(",")
|
| 89 |
+
if ";base64" not in header:
|
| 90 |
+
raise ValueError(f"Unsupported data URL encoding: {header}")
|
| 91 |
+
return base64.b64decode(payload)
|
| 92 |
+
if url.startswith(("http://", "https://")):
|
| 93 |
+
with urlopen(url, timeout=30) as response:
|
| 94 |
+
return response.read()
|
| 95 |
+
with open(url, "rb") as file:
|
| 96 |
+
return file.read()
|
| 97 |
+
|
| 98 |
+
raise ValueError(f"Cannot load image from record: {list(record.keys())}")
|
| 99 |
+
|
| 100 |
+
|
| 101 |
+
def plan_image_grid(width: int, height: int, args):
|
| 102 |
+
"""Resize plan for an image of the given original size; a pure function of its arguments."""
|
| 103 |
+
p = args.vision_patch_size
|
| 104 |
+
if args.vision_max_wh_ratio is not None and width > height * args.vision_max_wh_ratio:
|
| 105 |
+
width = height * args.vision_max_wh_ratio
|
| 106 |
+
if 0 < width * height < args.vision_min_pixels:
|
| 107 |
+
ratio = (args.vision_min_pixels / (width * height)) ** 0.5
|
| 108 |
+
width = int(width * ratio)
|
| 109 |
+
height = int(height * ratio)
|
| 110 |
+
best_width = math.ceil(width / p) * p
|
| 111 |
+
best_height = math.ceil(height / p) * p
|
| 112 |
+
return safe_resize(height, width, best_height, best_width, p, args.vision_downsample_ratio, args.vision_max_n_token)
|
| 113 |
+
|
| 114 |
+
|
| 115 |
+
def load_image(record, args):
|
| 116 |
+
"""Load and transform one image record into ViT patches."""
|
| 117 |
+
p = args.vision_patch_size
|
| 118 |
+
with Image.open(io.BytesIO(load_image_bytes(record))) as source:
|
| 119 |
+
image = source.convert("RGB")
|
| 120 |
+
n_llm_h, n_llm_w, best_height, best_width = plan_image_grid(image.width, image.height, args)
|
| 121 |
+
n_vit_h, n_vit_w = best_height // p, best_width // p
|
| 122 |
+
if args.vision_max_wh_ratio is not None and image.width >= args.vision_max_wh_ratio * image.height:
|
| 123 |
+
image = image.resize((best_width, best_height))
|
| 124 |
+
else:
|
| 125 |
+
image = ImageOps.pad(image, (best_width, best_height), color=(127, 127, 127))
|
| 126 |
+
x = torch.from_numpy(np.asarray(image, dtype=np.float32)).permute(2, 0, 1) / 255
|
| 127 |
+
x = ((x - 0.5) / 0.5).to(torch.bfloat16)
|
| 128 |
+
patches = x.reshape(3, n_vit_h, p, n_vit_w, p).permute(1, 3, 0, 2, 4).reshape(n_vit_h * n_vit_w, 3, p, p)
|
| 129 |
+
return patches, n_vit_h, n_vit_w, n_llm_h, n_llm_w
|
| 130 |
+
|
| 131 |
+
|
| 132 |
+
def image_token_types(n_llm_h: int, n_llm_w: int) -> torch.Tensor:
|
| 133 |
+
"""Default layout: the aligner grid in reading order, one IMAGE_NEW_LINE per row."""
|
| 134 |
+
types = [IMAGE_START]
|
| 135 |
+
types += ([IMAGE] * n_llm_w + [IMAGE_NEW_LINE]) * n_llm_h
|
| 136 |
+
types.append(IMAGE_END)
|
| 137 |
+
return torch.tensor(types, dtype=torch.int64)
|
| 138 |
+
|
| 139 |
+
|
| 140 |
+
def prepare_vl_inputs(prompt, images, tokenizer, args):
|
| 141 |
+
"""Tokenize `prompt`, expanding each image placeholder token into its image span.
|
| 142 |
+
|
| 143 |
+
Returns (tokens, token_types, image_inputs). Image-span positions carry `args.image_token_id` in
|
| 144 |
+
`tokens` and are distinguished only by `token_types` (TEXT elsewhere). `image_inputs` is None when
|
| 145 |
+
the prompt has no images."""
|
| 146 |
+
from encoding import IMAGE_PLACEHOLDER
|
| 147 |
+
|
| 148 |
+
# The placeholder is spelled differently across tokenizer revisions, so the id comes from the
|
| 149 |
+
# config; only cross-check it when this tokenizer does know the training-time spelling.
|
| 150 |
+
image_token_id = args.image_token_id
|
| 151 |
+
placeholder_id = tokenizer.convert_tokens_to_ids(IMAGE_PLACEHOLDER)
|
| 152 |
+
if placeholder_id is not None and placeholder_id != tokenizer.unk_token_id:
|
| 153 |
+
assert placeholder_id == image_token_id, (placeholder_id, image_token_id)
|
| 154 |
+
prompt_tokens = tokenizer.encode(prompt)
|
| 155 |
+
num_placeholders = sum(token == image_token_id for token in prompt_tokens)
|
| 156 |
+
if num_placeholders != len(images):
|
| 157 |
+
raise ValueError(f"Found {num_placeholders} image tokens but got {len(images)} images")
|
| 158 |
+
if num_placeholders and not args.vision_enabled:
|
| 159 |
+
raise ValueError("The model config has no vision tower (vision_n_layers == 0) but the prompt contains images")
|
| 160 |
+
|
| 161 |
+
tokens, token_types, image_inputs = [], [], []
|
| 162 |
+
image_iter = iter(images)
|
| 163 |
+
for tok in prompt_tokens:
|
| 164 |
+
if tok != image_token_id:
|
| 165 |
+
tokens.append(tok)
|
| 166 |
+
token_types.append(TEXT)
|
| 167 |
+
continue
|
| 168 |
+
patches, n_vit_h, n_vit_w, n_llm_h, n_llm_w = load_image(next(image_iter), args)
|
| 169 |
+
types = image_token_types(n_llm_h, n_llm_w)
|
| 170 |
+
image_inputs.append(ImageInput(len(tokens), patches, n_vit_h, n_vit_w, types))
|
| 171 |
+
tokens += [image_token_id] * types.numel()
|
| 172 |
+
token_types += types.tolist()
|
| 173 |
+
return tokens, token_types, image_inputs or None
|
inference/kernel.py
ADDED
|
@@ -0,0 +1,591 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
import torch
|
| 2 |
+
import tilelang
|
| 3 |
+
import tilelang.language as T
|
| 4 |
+
from typing import Tuple, Optional
|
| 5 |
+
|
| 6 |
+
|
| 7 |
+
tilelang.set_log_level("WARNING")
|
| 8 |
+
|
| 9 |
+
pass_configs = {
|
| 10 |
+
tilelang.PassConfigKey.TL_DISABLE_WARP_SPECIALIZED: True,
|
| 11 |
+
tilelang.PassConfigKey.TL_DISABLE_TMA_LOWER: True,
|
| 12 |
+
}
|
| 13 |
+
|
| 14 |
+
FP8 = "float8_e4m3"
|
| 15 |
+
FP4 = "float4_e2m1fn"
|
| 16 |
+
FE8M0 = "float8_e8m0fnu"
|
| 17 |
+
BF16 = "bfloat16"
|
| 18 |
+
FP32 = "float32"
|
| 19 |
+
INT32 = "int32"
|
| 20 |
+
|
| 21 |
+
|
| 22 |
+
def fast_log2_ceil(x):
|
| 23 |
+
"""Compute ceil(log2(x)) via IEEE 754 bit manipulation. Avoids slow log/ceil intrinsics."""
|
| 24 |
+
bits_x = T.reinterpret("uint32", x)
|
| 25 |
+
exp_x = (bits_x >> 23) & 0xFF
|
| 26 |
+
man_bits = bits_x & ((1 << 23) - 1)
|
| 27 |
+
return T.Cast("int32", exp_x - 127 + T.if_then_else(man_bits != 0, 1, 0))
|
| 28 |
+
|
| 29 |
+
|
| 30 |
+
def fast_pow2(x):
|
| 31 |
+
"""Compute 2^x for integer x via IEEE 754 bit manipulation."""
|
| 32 |
+
bits_x = (x + 127) << 23
|
| 33 |
+
return T.reinterpret("float32", bits_x)
|
| 34 |
+
|
| 35 |
+
|
| 36 |
+
def fast_round_scale(amax, fp8_max_inv):
|
| 37 |
+
return fast_pow2(fast_log2_ceil(amax * fp8_max_inv))
|
| 38 |
+
|
| 39 |
+
|
| 40 |
+
@tilelang.jit(pass_configs=pass_configs)
|
| 41 |
+
def act_quant_kernel(N, block_size=128, in_dtype=BF16, out_dtype=FP8, scale_dtype=FP32, round_scale=False, inplace=False):
|
| 42 |
+
"""Block-wise FP8 quantization. inplace=True does fused quant+dequant back to BF16."""
|
| 43 |
+
M = T.symbolic("M")
|
| 44 |
+
fp8_min = -448.0
|
| 45 |
+
fp8_max = 448.0
|
| 46 |
+
fp8_max_inv = 1 / fp8_max
|
| 47 |
+
num_stages = 0 if round_scale or inplace else 2
|
| 48 |
+
blk_m = 32
|
| 49 |
+
group_size = block_size
|
| 50 |
+
# Internal computation in FP32; scale_dtype controls output storage format.
|
| 51 |
+
compute_dtype = FP32
|
| 52 |
+
out_dtype = in_dtype if inplace else out_dtype
|
| 53 |
+
|
| 54 |
+
@T.prim_func
|
| 55 |
+
def act_quant_kernel_(
|
| 56 |
+
X: T.Tensor[(M, N), in_dtype],
|
| 57 |
+
Y: T.Tensor[(M, N), out_dtype],
|
| 58 |
+
S: T.Tensor[(M, T.ceildiv(N, group_size)), scale_dtype],
|
| 59 |
+
):
|
| 60 |
+
with T.Kernel(T.ceildiv(M, blk_m), T.ceildiv(N, group_size), threads=128) as (
|
| 61 |
+
pid_m,
|
| 62 |
+
pid_n,
|
| 63 |
+
):
|
| 64 |
+
x_shared = T.alloc_shared((blk_m, group_size), in_dtype)
|
| 65 |
+
x_local = T.alloc_fragment((blk_m, group_size), in_dtype)
|
| 66 |
+
amax_local = T.alloc_fragment((blk_m,), compute_dtype)
|
| 67 |
+
s_local = T.alloc_fragment((blk_m,), compute_dtype)
|
| 68 |
+
y_local = T.alloc_fragment((blk_m, group_size), out_dtype)
|
| 69 |
+
y_shared = T.alloc_shared((blk_m, group_size), out_dtype)
|
| 70 |
+
|
| 71 |
+
for _ in T.Pipelined(1, num_stages=num_stages):
|
| 72 |
+
T.copy(X[pid_m * blk_m, pid_n * group_size], x_shared)
|
| 73 |
+
T.copy(x_shared, x_local)
|
| 74 |
+
T.reduce_absmax(x_local, amax_local, dim=1)
|
| 75 |
+
for i in T.Parallel(blk_m):
|
| 76 |
+
amax_local[i] = T.max(amax_local[i], 1e-4)
|
| 77 |
+
if round_scale:
|
| 78 |
+
s_local[i] = fast_round_scale(amax_local[i], fp8_max_inv)
|
| 79 |
+
else:
|
| 80 |
+
s_local[i] = amax_local[i] * fp8_max_inv
|
| 81 |
+
if inplace:
|
| 82 |
+
for i, j in T.Parallel(blk_m, group_size):
|
| 83 |
+
y_local[i, j] = T.Cast(
|
| 84 |
+
out_dtype,
|
| 85 |
+
T.Cast(compute_dtype, T.Cast(FP8, T.clamp(x_local[i, j] / s_local[i], fp8_min, fp8_max))) * s_local[i],
|
| 86 |
+
)
|
| 87 |
+
else:
|
| 88 |
+
for i, j in T.Parallel(blk_m, group_size):
|
| 89 |
+
y_local[i, j] = T.clamp(x_local[i, j] / s_local[i], fp8_min, fp8_max)
|
| 90 |
+
for i in T.Parallel(blk_m):
|
| 91 |
+
S[pid_m * blk_m + i, pid_n] = T.Cast(scale_dtype, s_local[i])
|
| 92 |
+
T.copy(y_local, y_shared)
|
| 93 |
+
T.copy(y_shared, Y[pid_m * blk_m, pid_n * group_size])
|
| 94 |
+
|
| 95 |
+
return act_quant_kernel_
|
| 96 |
+
|
| 97 |
+
|
| 98 |
+
def act_quant(
|
| 99 |
+
x: torch.Tensor,
|
| 100 |
+
block_size: int = 128,
|
| 101 |
+
scale_fmt: Optional[str] = None,
|
| 102 |
+
scale_dtype: torch.dtype = torch.float32,
|
| 103 |
+
inplace: bool = False,
|
| 104 |
+
) -> torch.Tensor:
|
| 105 |
+
"""Block-wise FP8 quantization. inplace=True does fused quant+dequant back to BF16.
|
| 106 |
+
When scale_fmt is set, scales are rounded to power-of-2 (MXFP)."""
|
| 107 |
+
N = x.size(-1)
|
| 108 |
+
assert N % block_size == 0
|
| 109 |
+
tl_dtype = FE8M0 if scale_dtype == torch.float8_e8m0fnu else FP32
|
| 110 |
+
z = x.contiguous()
|
| 111 |
+
y = torch.empty_like(z) if inplace else torch.empty_like(z, dtype=torch.float8_e4m3fn)
|
| 112 |
+
s = z.new_empty(*z.size()[:-1], N // block_size, dtype=scale_dtype)
|
| 113 |
+
kernel = act_quant_kernel(
|
| 114 |
+
N,
|
| 115 |
+
block_size,
|
| 116 |
+
scale_dtype=tl_dtype,
|
| 117 |
+
round_scale=scale_fmt is not None,
|
| 118 |
+
inplace=inplace,
|
| 119 |
+
)
|
| 120 |
+
kernel(z.view(-1, N), y.view(-1, N), s.view(-1, N // block_size))
|
| 121 |
+
if inplace:
|
| 122 |
+
x.copy_(y)
|
| 123 |
+
return x
|
| 124 |
+
return y, s
|
| 125 |
+
|
| 126 |
+
|
| 127 |
+
@tilelang.jit(pass_configs=pass_configs)
|
| 128 |
+
def fp4_quant_kernel(N, block_size=32, in_dtype=BF16, scale_dtype=FE8M0, inplace=False):
|
| 129 |
+
"""Block-wise FP4 with power-of-2 or E4M3 scales; optionally dequantize in place."""
|
| 130 |
+
M = T.symbolic("M")
|
| 131 |
+
fp4_max = 6.0
|
| 132 |
+
fp4_max_inv = 1.0 / fp4_max
|
| 133 |
+
blk_m = 32
|
| 134 |
+
group_size = block_size
|
| 135 |
+
compute_dtype = FP32
|
| 136 |
+
out_dtype = in_dtype if inplace else FP4
|
| 137 |
+
|
| 138 |
+
@T.prim_func
|
| 139 |
+
def fp4_quant_kernel_(
|
| 140 |
+
X: T.Tensor[(M, N), in_dtype],
|
| 141 |
+
Y: T.Tensor[(M, N), out_dtype],
|
| 142 |
+
S: T.Tensor[(M, T.ceildiv(N, group_size)), scale_dtype],
|
| 143 |
+
):
|
| 144 |
+
with T.Kernel(T.ceildiv(M, blk_m), T.ceildiv(N, group_size), threads=128) as (
|
| 145 |
+
pid_m,
|
| 146 |
+
pid_n,
|
| 147 |
+
):
|
| 148 |
+
x_shared = T.alloc_shared((blk_m, group_size), in_dtype)
|
| 149 |
+
x_local = T.alloc_fragment((blk_m, group_size), in_dtype)
|
| 150 |
+
amax_local = T.alloc_fragment((blk_m,), compute_dtype)
|
| 151 |
+
s_local = T.alloc_fragment((blk_m,), compute_dtype)
|
| 152 |
+
y_local = T.alloc_fragment((blk_m, group_size), out_dtype)
|
| 153 |
+
y_shared = T.alloc_shared((blk_m, group_size), out_dtype)
|
| 154 |
+
|
| 155 |
+
for _ in T.Pipelined(1, num_stages=2):
|
| 156 |
+
T.copy(X[pid_m * blk_m, pid_n * group_size], x_shared)
|
| 157 |
+
T.copy(x_shared, x_local)
|
| 158 |
+
T.reduce_absmax(x_local, amax_local, dim=1)
|
| 159 |
+
for i in T.Parallel(blk_m):
|
| 160 |
+
if scale_dtype == FP8:
|
| 161 |
+
# Training's compressed KV: keep even an all-zero group's scale nonzero.
|
| 162 |
+
amax_local[i] = T.max(amax_local[i], 6 * (2**-9))
|
| 163 |
+
s_local[i] = T.Cast(compute_dtype, T.Cast(FP8, amax_local[i] / fp4_max))
|
| 164 |
+
else:
|
| 165 |
+
amax_local[i] = T.max(amax_local[i], 6 * (2**-126))
|
| 166 |
+
s_local[i] = fast_round_scale(amax_local[i], fp4_max_inv)
|
| 167 |
+
if inplace:
|
| 168 |
+
for i, j in T.Parallel(blk_m, group_size):
|
| 169 |
+
y_local[i, j] = T.Cast(
|
| 170 |
+
out_dtype,
|
| 171 |
+
T.Cast(compute_dtype, T.Cast(FP4, T.clamp(x_local[i, j] / s_local[i], -fp4_max, fp4_max))) * s_local[i],
|
| 172 |
+
)
|
| 173 |
+
else:
|
| 174 |
+
for i, j in T.Parallel(blk_m, group_size):
|
| 175 |
+
y_local[i, j] = T.clamp(x_local[i, j] / s_local[i], -fp4_max, fp4_max)
|
| 176 |
+
for i in T.Parallel(blk_m):
|
| 177 |
+
S[pid_m * blk_m + i, pid_n] = T.Cast(scale_dtype, s_local[i])
|
| 178 |
+
T.copy(y_local, y_shared)
|
| 179 |
+
T.copy(y_shared, Y[pid_m * blk_m, pid_n * group_size])
|
| 180 |
+
|
| 181 |
+
return fp4_quant_kernel_
|
| 182 |
+
|
| 183 |
+
|
| 184 |
+
def fp4_act_quant(
|
| 185 |
+
x: torch.Tensor,
|
| 186 |
+
block_size: int = 32,
|
| 187 |
+
inplace: bool = False,
|
| 188 |
+
scale_dtype: torch.dtype = torch.float8_e8m0fnu,
|
| 189 |
+
) -> torch.Tensor:
|
| 190 |
+
"""FP4 with E8M0 scales for the indexer or E4M3 scales for compressed KV.
|
| 191 |
+
inplace=True writes the dequantized values back to x."""
|
| 192 |
+
assert scale_dtype in (torch.float8_e8m0fnu, torch.float8_e4m3fn)
|
| 193 |
+
N = x.size(-1)
|
| 194 |
+
assert N % block_size == 0
|
| 195 |
+
z = x.contiguous()
|
| 196 |
+
y = torch.empty_like(z) if inplace else z.new_empty(*z.shape[:-1], N // 2, dtype=torch.float4_e2m1fn_x2)
|
| 197 |
+
s = z.new_empty(*z.size()[:-1], N // block_size, dtype=scale_dtype)
|
| 198 |
+
tl_dtype = FP8 if scale_dtype == torch.float8_e4m3fn else FE8M0
|
| 199 |
+
kernel = fp4_quant_kernel(N, block_size, scale_dtype=tl_dtype, inplace=inplace)
|
| 200 |
+
kernel(z.view(-1, N), y.view(-1, y.size(-1)), s.view(-1, N // block_size))
|
| 201 |
+
if inplace:
|
| 202 |
+
x.copy_(y)
|
| 203 |
+
return x
|
| 204 |
+
return y, s
|
| 205 |
+
|
| 206 |
+
|
| 207 |
+
@tilelang.jit(pass_configs=pass_configs)
|
| 208 |
+
def fp8_gemm_kernel(
|
| 209 |
+
N,
|
| 210 |
+
K,
|
| 211 |
+
block_size=128,
|
| 212 |
+
out_dtype=BF16,
|
| 213 |
+
accum_dtype=FP32,
|
| 214 |
+
scale_dtype=FP32,
|
| 215 |
+
):
|
| 216 |
+
assert out_dtype in [BF16, FP32]
|
| 217 |
+
assert block_size in [32, 128]
|
| 218 |
+
|
| 219 |
+
M = T.symbolic("M")
|
| 220 |
+
group_size = block_size
|
| 221 |
+
block_M = 32
|
| 222 |
+
block_N = 128
|
| 223 |
+
block_K = group_size
|
| 224 |
+
num_stages = 4 if block_K == 128 else 2
|
| 225 |
+
|
| 226 |
+
@T.prim_func
|
| 227 |
+
def fp8_gemm_kernel_(
|
| 228 |
+
A: T.Tensor[(M, K), FP8],
|
| 229 |
+
B: T.Tensor[(N, K), FP8],
|
| 230 |
+
C: T.Tensor[(M, N), out_dtype],
|
| 231 |
+
scales_a: T.Tensor[(M, T.ceildiv(K, group_size)), scale_dtype],
|
| 232 |
+
scales_b: T.Tensor[(T.ceildiv(N, group_size), T.ceildiv(K, group_size)), scale_dtype],
|
| 233 |
+
):
|
| 234 |
+
with T.Kernel(T.ceildiv(N, block_N), T.ceildiv(M, block_M), threads=128) as (
|
| 235 |
+
bx,
|
| 236 |
+
by,
|
| 237 |
+
):
|
| 238 |
+
A_shared = T.alloc_shared((block_M, block_K), FP8)
|
| 239 |
+
B_shared = T.alloc_shared((block_N, block_K), FP8)
|
| 240 |
+
C_shared = T.alloc_shared((block_M, block_N), out_dtype)
|
| 241 |
+
C_local = T.alloc_fragment((block_M, block_N), accum_dtype)
|
| 242 |
+
C_local_accum = T.alloc_fragment((block_M, block_N), accum_dtype)
|
| 243 |
+
scale_a_frag = T.alloc_fragment((block_M,), FP32)
|
| 244 |
+
scale_b_frag = T.alloc_fragment((block_N,), FP32)
|
| 245 |
+
|
| 246 |
+
# Improve L2 Cache
|
| 247 |
+
T.use_swizzle(panel_size=10)
|
| 248 |
+
T.clear(C_local)
|
| 249 |
+
T.clear(C_local_accum)
|
| 250 |
+
|
| 251 |
+
K_iters = T.ceildiv(K, block_K)
|
| 252 |
+
for k in T.Pipelined(K_iters, num_stages=num_stages):
|
| 253 |
+
T.copy(A[by * block_M, k * block_K], A_shared)
|
| 254 |
+
T.copy(B[bx * block_N, k * block_K], B_shared)
|
| 255 |
+
|
| 256 |
+
# Activation scales are per row and K block. Weight scales are
|
| 257 |
+
# per (N block, K block), where the block can be 32 or 128.
|
| 258 |
+
for i in T.Parallel(block_M):
|
| 259 |
+
scale_a_frag[i] = T.Cast(FP32, scales_a[by * block_M + i, k])
|
| 260 |
+
for j in T.Parallel(block_N):
|
| 261 |
+
scale_b_frag[j] = T.Cast(
|
| 262 |
+
FP32,
|
| 263 |
+
scales_b[(bx * block_N + j) // group_size, k],
|
| 264 |
+
)
|
| 265 |
+
|
| 266 |
+
T.gemm(A_shared, B_shared, C_local, transpose_B=True)
|
| 267 |
+
# Separate accumulator for scale-corrected results.
|
| 268 |
+
for i, j in T.Parallel(block_M, block_N):
|
| 269 |
+
C_local_accum[i, j] += C_local[i, j] * scale_a_frag[i] * scale_b_frag[j]
|
| 270 |
+
T.clear(C_local)
|
| 271 |
+
T.copy(C_local_accum, C_shared)
|
| 272 |
+
T.copy(C_shared, C[by * block_M, bx * block_N])
|
| 273 |
+
|
| 274 |
+
return fp8_gemm_kernel_
|
| 275 |
+
|
| 276 |
+
|
| 277 |
+
def fp8_gemm(
|
| 278 |
+
a: torch.Tensor,
|
| 279 |
+
a_s: torch.Tensor,
|
| 280 |
+
b: torch.Tensor,
|
| 281 |
+
b_s: torch.Tensor,
|
| 282 |
+
scale_dtype: torch.dtype = torch.float32,
|
| 283 |
+
block_size: int = 128,
|
| 284 |
+
) -> torch.Tensor:
|
| 285 |
+
"""C[M,N] = A[M,K] @ B[N,K]^T with per-block FP8 scaling."""
|
| 286 |
+
assert a.is_contiguous() and b.is_contiguous(), "Input tensors must be contiguous"
|
| 287 |
+
assert a_s.is_contiguous() and b_s.is_contiguous(), "Scaling factor tensors must be contiguous"
|
| 288 |
+
assert block_size in (32, 128)
|
| 289 |
+
tl_dtype = FE8M0 if scale_dtype == torch.float8_e8m0fnu else FP32
|
| 290 |
+
K = a.size(-1)
|
| 291 |
+
M = a.numel() // K
|
| 292 |
+
N = b.size(0)
|
| 293 |
+
assert K % block_size == 0
|
| 294 |
+
assert a_s.numel() == M * (K // block_size)
|
| 295 |
+
assert b_s.shape == (
|
| 296 |
+
(N + block_size - 1) // block_size,
|
| 297 |
+
K // block_size,
|
| 298 |
+
)
|
| 299 |
+
c = a.new_empty(*a.size()[:-1], N, dtype=torch.get_default_dtype())
|
| 300 |
+
kernel = fp8_gemm_kernel(
|
| 301 |
+
N,
|
| 302 |
+
K,
|
| 303 |
+
block_size=block_size,
|
| 304 |
+
scale_dtype=tl_dtype,
|
| 305 |
+
)
|
| 306 |
+
kernel(a.view(M, K), b, c.view(M, N), a_s.view(M, -1), b_s)
|
| 307 |
+
return c
|
| 308 |
+
|
| 309 |
+
|
| 310 |
+
@tilelang.jit(pass_configs=pass_configs)
|
| 311 |
+
def sparse_attn_kernel(h: int, d: int, scale=None):
|
| 312 |
+
"""Sparse multi-head attention via index gathering + online softmax (FlashAttention-style).
|
| 313 |
+
For each (batch, seq_pos), gathers top-k KV positions by index, computes attention
|
| 314 |
+
with numerically stable running max/sum, and includes a learnable attn_sink bias."""
|
| 315 |
+
b = T.symbolic("b")
|
| 316 |
+
m = T.symbolic("m")
|
| 317 |
+
n = T.symbolic("n")
|
| 318 |
+
topk = T.symbolic("topk")
|
| 319 |
+
if scale is None:
|
| 320 |
+
scale = (1.0 / d) ** 0.5
|
| 321 |
+
|
| 322 |
+
num_stages = 2
|
| 323 |
+
threads = 256
|
| 324 |
+
block = 64
|
| 325 |
+
num_blocks = tilelang.cdiv(topk, block)
|
| 326 |
+
|
| 327 |
+
@T.prim_func
|
| 328 |
+
def sparse_attn_kernel_(
|
| 329 |
+
q: T.Tensor[(b, m, h, d), BF16],
|
| 330 |
+
kv: T.Tensor[(b, n, d), BF16],
|
| 331 |
+
o: T.Tensor[(b, m, h, d), BF16],
|
| 332 |
+
attn_sink: T.Tensor[(h,), FP32],
|
| 333 |
+
topk_idxs: T.Tensor[(b, m, topk), INT32],
|
| 334 |
+
):
|
| 335 |
+
with T.Kernel(m, b, threads=threads) as (bx, by):
|
| 336 |
+
q_shared = T.alloc_shared((h, d), BF16)
|
| 337 |
+
kv_shared = T.alloc_shared((block, d), BF16)
|
| 338 |
+
o_shared = T.alloc_shared((h, d), BF16)
|
| 339 |
+
acc_s_cast = T.alloc_shared((h, block), BF16)
|
| 340 |
+
|
| 341 |
+
idxs = T.alloc_fragment(block, INT32)
|
| 342 |
+
acc_s = T.alloc_fragment((h, block), FP32)
|
| 343 |
+
acc_o = T.alloc_fragment((h, d), FP32)
|
| 344 |
+
scores_max = T.alloc_fragment(h, FP32)
|
| 345 |
+
scores_max_prev = T.alloc_fragment(h, FP32)
|
| 346 |
+
scores_scale = T.alloc_fragment(h, FP32)
|
| 347 |
+
scores_sum = T.alloc_fragment(h, FP32)
|
| 348 |
+
sum_exp = T.alloc_fragment(h, FP32)
|
| 349 |
+
|
| 350 |
+
T.clear(acc_o)
|
| 351 |
+
T.clear(sum_exp)
|
| 352 |
+
# Finite lower bound instead of -inf: a row with no valid index (all -1) would otherwise
|
| 353 |
+
# produce exp(-inf - (-inf)) = NaN. With a finite bound such rows yield an all-zero output,
|
| 354 |
+
# matching the training kernel's convention.
|
| 355 |
+
T.fill(scores_max, -1e30)
|
| 356 |
+
T.copy(q[by, bx, :, :], q_shared)
|
| 357 |
+
|
| 358 |
+
for t in T.Pipelined(num_blocks, num_stages=num_stages):
|
| 359 |
+
for i in T.Parallel(block):
|
| 360 |
+
idxs[i] = T.if_then_else(t * block + i < topk, topk_idxs[by, bx, t * block + i], -1)
|
| 361 |
+
for i, j in T.Parallel(block, d):
|
| 362 |
+
kv_shared[i, j] = T.if_then_else(idxs[i] != -1, kv[by, idxs[i], j], 0)
|
| 363 |
+
for i, j in T.Parallel(h, block):
|
| 364 |
+
acc_s[i, j] = T.if_then_else(idxs[j] != -1, 0, -T.infinity(FP32))
|
| 365 |
+
T.gemm(q_shared, kv_shared, acc_s, transpose_B=True, policy=T.GemmWarpPolicy.FullRow)
|
| 366 |
+
for i, j in T.Parallel(h, block):
|
| 367 |
+
acc_s[i, j] *= scale
|
| 368 |
+
T.copy(scores_max, scores_max_prev)
|
| 369 |
+
T.reduce_max(acc_s, scores_max, dim=1, clear=False)
|
| 370 |
+
for i in T.Parallel(h):
|
| 371 |
+
scores_scale[i] = T.exp(scores_max_prev[i] - scores_max[i])
|
| 372 |
+
for i, j in T.Parallel(h, block):
|
| 373 |
+
acc_s[i, j] = T.exp(acc_s[i, j] - scores_max[i])
|
| 374 |
+
T.reduce_sum(acc_s, scores_sum, dim=1)
|
| 375 |
+
for i in T.Parallel(h):
|
| 376 |
+
sum_exp[i] = sum_exp[i] * scores_scale[i] + scores_sum[i]
|
| 377 |
+
T.copy(acc_s, acc_s_cast)
|
| 378 |
+
for i, j in T.Parallel(h, d):
|
| 379 |
+
acc_o[i, j] *= scores_scale[i]
|
| 380 |
+
T.gemm(acc_s_cast, kv_shared, acc_o, policy=T.GemmWarpPolicy.FullRow)
|
| 381 |
+
|
| 382 |
+
for i in T.Parallel(h):
|
| 383 |
+
sum_exp[i] += T.exp(attn_sink[i] - scores_max[i])
|
| 384 |
+
for i, j in T.Parallel(h, d):
|
| 385 |
+
acc_o[i, j] /= sum_exp[i]
|
| 386 |
+
T.copy(acc_o, o_shared)
|
| 387 |
+
T.copy(o_shared, o[by, bx, :, :])
|
| 388 |
+
|
| 389 |
+
return sparse_attn_kernel_
|
| 390 |
+
|
| 391 |
+
|
| 392 |
+
def sparse_attn(q: torch.Tensor, kv: torch.Tensor, attn_sink: torch.Tensor, topk_idxs: torch.Tensor, softmax_scale: float) -> torch.Tensor:
|
| 393 |
+
b, s, h, d = q.size()
|
| 394 |
+
# Pad heads to 16 for kernel efficiency (stripped after)
|
| 395 |
+
if h < 16:
|
| 396 |
+
q = torch.cat([q, q.new_zeros(b, s, 16 - h, d)], dim=2)
|
| 397 |
+
attn_sink = torch.cat([attn_sink, attn_sink.new_zeros(16 - h)])
|
| 398 |
+
o = torch.empty_like(q)
|
| 399 |
+
kernel = sparse_attn_kernel(q.size(2), d, softmax_scale)
|
| 400 |
+
kernel(q, kv, o, attn_sink, topk_idxs)
|
| 401 |
+
if h < 16:
|
| 402 |
+
o = o.narrow(2, 0, h).contiguous()
|
| 403 |
+
return o
|
| 404 |
+
|
| 405 |
+
|
| 406 |
+
@tilelang.jit(pass_configs=pass_configs)
|
| 407 |
+
def hc_split_sinkhorn_kernel(hc: int, sinkhorn_iters: int, eps: float):
|
| 408 |
+
n = T.symbolic("n")
|
| 409 |
+
mix_hc = (2 + hc) * hc
|
| 410 |
+
threads = 64
|
| 411 |
+
|
| 412 |
+
@T.prim_func
|
| 413 |
+
def hc_split_sinkhorn_kernel_(
|
| 414 |
+
mixes: T.Tensor[(n, mix_hc), FP32],
|
| 415 |
+
hc_scale: T.Tensor[(3,), FP32],
|
| 416 |
+
hc_base: T.Tensor[(mix_hc,), FP32],
|
| 417 |
+
pre: T.Tensor[(n, hc), FP32],
|
| 418 |
+
post: T.Tensor[(n, hc), FP32],
|
| 419 |
+
comb: T.Tensor[(n, hc, hc), FP32],
|
| 420 |
+
):
|
| 421 |
+
with T.Kernel(n, threads=threads) as i:
|
| 422 |
+
mixes_shared = T.alloc_shared(mix_hc, FP32)
|
| 423 |
+
comb_frag = T.alloc_fragment((hc, hc), FP32)
|
| 424 |
+
T.copy(mixes[i, :], mixes_shared)
|
| 425 |
+
|
| 426 |
+
for j in T.Parallel(hc):
|
| 427 |
+
pre[i, j] = T.sigmoid(mixes_shared[j] * hc_scale[0] + hc_base[j]) + eps
|
| 428 |
+
for j in T.Parallel(hc):
|
| 429 |
+
post[i, j] = 2 * T.sigmoid(mixes_shared[j + hc] * hc_scale[1] + hc_base[j + hc])
|
| 430 |
+
for j, k in T.Parallel(hc, hc):
|
| 431 |
+
comb_frag[j, k] = mixes_shared[j * hc + k + hc * 2] * hc_scale[2] + hc_base[j * hc + k + hc * 2]
|
| 432 |
+
|
| 433 |
+
row_sum = T.alloc_fragment(hc, FP32)
|
| 434 |
+
col_sum = T.alloc_fragment(hc, FP32)
|
| 435 |
+
|
| 436 |
+
# comb = comb.softmax(-1) + eps
|
| 437 |
+
row_max = T.alloc_fragment(hc, FP32)
|
| 438 |
+
T.reduce_max(comb_frag, row_max, dim=1)
|
| 439 |
+
for j, k in T.Parallel(hc, hc):
|
| 440 |
+
comb_frag[j, k] = T.exp(comb_frag[j, k] - row_max[j])
|
| 441 |
+
T.reduce_sum(comb_frag, row_sum, dim=1)
|
| 442 |
+
for j, k in T.Parallel(hc, hc):
|
| 443 |
+
comb_frag[j, k] = comb_frag[j, k] / row_sum[j] + eps
|
| 444 |
+
|
| 445 |
+
# comb = comb / (comb.sum(-2) + eps)
|
| 446 |
+
T.reduce_sum(comb_frag, col_sum, dim=0)
|
| 447 |
+
for j, k in T.Parallel(hc, hc):
|
| 448 |
+
comb_frag[j, k] = comb_frag[j, k] / (col_sum[k] + eps)
|
| 449 |
+
|
| 450 |
+
for _ in T.serial(sinkhorn_iters - 1):
|
| 451 |
+
# comb = comb / (comb.sum(-1) + eps)
|
| 452 |
+
T.reduce_sum(comb_frag, row_sum, dim=1)
|
| 453 |
+
for j, k in T.Parallel(hc, hc):
|
| 454 |
+
comb_frag[j, k] = comb_frag[j, k] / (row_sum[j] + eps)
|
| 455 |
+
# comb = comb / (comb.sum(-2) + eps)
|
| 456 |
+
T.reduce_sum(comb_frag, col_sum, dim=0)
|
| 457 |
+
for j, k in T.Parallel(hc, hc):
|
| 458 |
+
comb_frag[j, k] = comb_frag[j, k] / (col_sum[k] + eps)
|
| 459 |
+
|
| 460 |
+
T.copy(comb_frag, comb[i, :, :])
|
| 461 |
+
|
| 462 |
+
return hc_split_sinkhorn_kernel_
|
| 463 |
+
|
| 464 |
+
|
| 465 |
+
def hc_split_sinkhorn(
|
| 466 |
+
mixes: torch.Tensor, hc_scale: torch.Tensor, hc_base: torch.Tensor, hc_mult: int = 4, sinkhorn_iters: int = 20, eps: float = 1e-6
|
| 467 |
+
):
|
| 468 |
+
b, s, _ = mixes.size()
|
| 469 |
+
pre = mixes.new_empty(b, s, hc_mult)
|
| 470 |
+
post = mixes.new_empty(b, s, hc_mult)
|
| 471 |
+
comb = mixes.new_empty(b, s, hc_mult, hc_mult)
|
| 472 |
+
kernel = hc_split_sinkhorn_kernel(hc_mult, sinkhorn_iters, eps)
|
| 473 |
+
kernel(mixes.view(-1, (2 + hc_mult) * hc_mult), hc_scale, hc_base, pre.view(-1, hc_mult), post.view(-1, hc_mult), comb.view(-1, hc_mult, hc_mult))
|
| 474 |
+
return pre, post, comb
|
| 475 |
+
|
| 476 |
+
|
| 477 |
+
@tilelang.jit(pass_configs=pass_configs)
|
| 478 |
+
def fp4_gemm_kernel(
|
| 479 |
+
N,
|
| 480 |
+
K,
|
| 481 |
+
act_block_size=128,
|
| 482 |
+
out_dtype=BF16,
|
| 483 |
+
accum_dtype=FP32,
|
| 484 |
+
scale_dtype=FP32,
|
| 485 |
+
):
|
| 486 |
+
"""FP8 act x FP4 weight GEMM kernel.
|
| 487 |
+
|
| 488 |
+
C[M, N] = A_fp8[M, K] @ B_fp4[N, K]^T
|
| 489 |
+
|
| 490 |
+
Act: 1x32 or 1x128 quant on K, FP8 with configurable scale dtype
|
| 491 |
+
Weight: 1x32 quant on K (reduce dim), FP4 with E8M0 scale
|
| 492 |
+
|
| 493 |
+
B is stored as [N, K//2] in float4_e2m1fn_x2, logical [N, K] in fp4.
|
| 494 |
+
The FP4 values are packed along the K (last) dimension.
|
| 495 |
+
|
| 496 |
+
Strategy: load FP4 sub-blocks of size [block_N, sub_K] (sub_K=32),
|
| 497 |
+
cast FP4 to FP8 via float, then do FP8xFP8 GEMM.
|
| 498 |
+
Apply activation and weight scales to the accumulator.
|
| 499 |
+
"""
|
| 500 |
+
M = T.symbolic("M")
|
| 501 |
+
assert act_block_size in [32, 128]
|
| 502 |
+
act_group_size = act_block_size
|
| 503 |
+
weight_group_size = 32
|
| 504 |
+
block_M = 32
|
| 505 |
+
block_N = 128
|
| 506 |
+
block_K = 32 # matches weight_group_size for simple scale handling
|
| 507 |
+
n_sub = act_group_size // block_K
|
| 508 |
+
|
| 509 |
+
@T.prim_func
|
| 510 |
+
def fp4_gemm_kernel_(
|
| 511 |
+
A: T.Tensor[(M, K), FP8],
|
| 512 |
+
B: T.Tensor[(N, K), FP4],
|
| 513 |
+
C: T.Tensor[(M, N), out_dtype],
|
| 514 |
+
scales_a: T.Tensor[(M, T.ceildiv(K, act_group_size)), scale_dtype],
|
| 515 |
+
scales_b: T.Tensor[(N, T.ceildiv(K, weight_group_size)), scale_dtype],
|
| 516 |
+
):
|
| 517 |
+
with T.Kernel(T.ceildiv(N, block_N), T.ceildiv(M, block_M), threads=128) as (
|
| 518 |
+
bx,
|
| 519 |
+
by,
|
| 520 |
+
):
|
| 521 |
+
A_shared = T.alloc_shared((block_M, block_K), FP8)
|
| 522 |
+
B_fp4_shared = T.alloc_shared((block_N, block_K), FP4)
|
| 523 |
+
B_shared = T.alloc_shared((block_N, block_K), FP8)
|
| 524 |
+
C_shared = T.alloc_shared((block_M, block_N), out_dtype)
|
| 525 |
+
C_local = T.alloc_fragment((block_M, block_N), accum_dtype)
|
| 526 |
+
C_local_accum = T.alloc_fragment((block_M, block_N), accum_dtype)
|
| 527 |
+
scale_a_frag = T.alloc_fragment((block_M,), FP32)
|
| 528 |
+
scale_b_frag = T.alloc_fragment((block_N,), FP32)
|
| 529 |
+
|
| 530 |
+
T.use_swizzle(panel_size=10)
|
| 531 |
+
T.clear(C_local)
|
| 532 |
+
T.clear(C_local_accum)
|
| 533 |
+
|
| 534 |
+
K_iters = T.ceildiv(K, block_K)
|
| 535 |
+
for k in T.Pipelined(K_iters, num_stages=2):
|
| 536 |
+
T.copy(A[by * block_M, k * block_K], A_shared)
|
| 537 |
+
T.copy(B[bx * block_N, k * block_K], B_fp4_shared)
|
| 538 |
+
# FP4->FP8 cast must go through FP32 to avoid ambiguous C++ overload
|
| 539 |
+
for i, j in T.Parallel(block_N, block_K):
|
| 540 |
+
B_shared[i, j] = T.Cast(FP8, T.Cast(FP32, B_fp4_shared[i, j]))
|
| 541 |
+
|
| 542 |
+
# Weight scale: per 32 on K, indexed by k (each k is one block_K=32)
|
| 543 |
+
for i in T.Parallel(block_N):
|
| 544 |
+
scale_b_frag[i] = T.Cast(FP32, scales_b[bx * block_N + i, k])
|
| 545 |
+
|
| 546 |
+
# Activation scale: one value per act_group_size elements.
|
| 547 |
+
for i in T.Parallel(block_M):
|
| 548 |
+
scale_a_frag[i] = T.Cast(FP32, scales_a[by * block_M + i, k // n_sub])
|
| 549 |
+
|
| 550 |
+
T.gemm(A_shared, B_shared, C_local, transpose_B=True)
|
| 551 |
+
|
| 552 |
+
for i, j in T.Parallel(block_M, block_N):
|
| 553 |
+
C_local_accum[i, j] += C_local[i, j] * scale_a_frag[i] * scale_b_frag[j]
|
| 554 |
+
T.clear(C_local)
|
| 555 |
+
|
| 556 |
+
T.copy(C_local_accum, C_shared)
|
| 557 |
+
T.copy(C_shared, C[by * block_M, bx * block_N])
|
| 558 |
+
|
| 559 |
+
return fp4_gemm_kernel_
|
| 560 |
+
|
| 561 |
+
|
| 562 |
+
def fp4_gemm(
|
| 563 |
+
a: torch.Tensor,
|
| 564 |
+
a_s: torch.Tensor,
|
| 565 |
+
b: torch.Tensor,
|
| 566 |
+
b_s: torch.Tensor,
|
| 567 |
+
scale_dtype: torch.dtype = torch.float32,
|
| 568 |
+
act_block_size: int = 128,
|
| 569 |
+
) -> torch.Tensor:
|
| 570 |
+
"""C[M,N] = A_fp8[M,K] @ B_fp4[N,K]^T.
|
| 571 |
+
A has per-32 or per-128 activation scale; B has per-32 E8M0 weight scale.
|
| 572 |
+
B is stored as [N, K//2] in float4_e2m1fn_x2 (2 FP4 values per byte, packed along K)."""
|
| 573 |
+
assert a.is_contiguous() and b.is_contiguous(), "Input tensors must be contiguous"
|
| 574 |
+
assert a_s.is_contiguous() and b_s.is_contiguous(), "Scaling factor tensors must be contiguous"
|
| 575 |
+
tl_dtype = FE8M0 if scale_dtype == torch.float8_e8m0fnu else FP32
|
| 576 |
+
K = a.size(-1)
|
| 577 |
+
M = a.numel() // K
|
| 578 |
+
N = b.size(0)
|
| 579 |
+
assert act_block_size in (32, 128)
|
| 580 |
+
assert K % act_block_size == 0
|
| 581 |
+
assert a_s.numel() == M * (K // act_block_size)
|
| 582 |
+
assert b_s.shape == (N, K // 32)
|
| 583 |
+
c = a.new_empty(*a.size()[:-1], N, dtype=torch.get_default_dtype())
|
| 584 |
+
kernel = fp4_gemm_kernel(
|
| 585 |
+
N,
|
| 586 |
+
K,
|
| 587 |
+
act_block_size=act_block_size,
|
| 588 |
+
scale_dtype=tl_dtype,
|
| 589 |
+
)
|
| 590 |
+
kernel(a.view(M, K), b, c.view(M, N), a_s.view(M, -1), b_s)
|
| 591 |
+
return c
|
inference/model.py
ADDED
|
@@ -0,0 +1,1309 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
import math
|
| 2 |
+
from contextlib import contextmanager
|
| 3 |
+
from dataclasses import dataclass
|
| 4 |
+
from functools import lru_cache
|
| 5 |
+
from typing import Literal
|
| 6 |
+
|
| 7 |
+
import torch
|
| 8 |
+
import torch.distributed as dist
|
| 9 |
+
import torch.nn.functional as F
|
| 10 |
+
from engram import EngramLayout, NgramHashState
|
| 11 |
+
from image_processor import IMAGE, IMAGE_END, IMAGE_NEW_LINE, IMAGE_START
|
| 12 |
+
from kernel import (
|
| 13 |
+
act_quant,
|
| 14 |
+
fp4_act_quant,
|
| 15 |
+
fp4_gemm,
|
| 16 |
+
fp8_gemm,
|
| 17 |
+
hc_split_sinkhorn,
|
| 18 |
+
sparse_attn,
|
| 19 |
+
)
|
| 20 |
+
from torch import nn
|
| 21 |
+
from vision import Aligner, ViT
|
| 22 |
+
|
| 23 |
+
# Set once by Transformer.__init__; one model per process, so layers just read them.
|
| 24 |
+
world_size = 1
|
| 25 |
+
rank = 0
|
| 26 |
+
default_dtype = torch.float8_e4m3fn # storage dtype for Linear weights, from ModelArgs.dtype
|
| 27 |
+
fp8_block_size = 32 # one fp8 scale per 32x32 weight block / 32 activations
|
| 28 |
+
fp4_block_size = 32 # one fp4 scale per 32 elements along K
|
| 29 |
+
scale_fmt = "ue8m0"
|
| 30 |
+
scale_dtype = torch.float8_e8m0fnu
|
| 31 |
+
|
| 32 |
+
|
| 33 |
+
@contextmanager
|
| 34 |
+
def set_dtype(dtype):
|
| 35 |
+
"""Temporarily override torch's default dtype, restoring it even if the body raises."""
|
| 36 |
+
prev = torch.get_default_dtype()
|
| 37 |
+
torch.set_default_dtype(dtype)
|
| 38 |
+
try:
|
| 39 |
+
yield
|
| 40 |
+
finally:
|
| 41 |
+
torch.set_default_dtype(prev)
|
| 42 |
+
|
| 43 |
+
|
| 44 |
+
@dataclass
|
| 45 |
+
class ModelArgs:
|
| 46 |
+
"""Field names are exactly the config JSON keys. The defaults are a small model that
|
| 47 |
+
`python model.py` can run, not the released shapes -- though the scale-independent
|
| 48 |
+
values (norm_eps, score_func, hc_*, engram_*) do match it."""
|
| 49 |
+
|
| 50 |
+
# runtime limits rather than model shape: they size the KV caches
|
| 51 |
+
max_batch_size: int = 4
|
| 52 |
+
max_seq_len: int = 4096
|
| 53 |
+
temperature: float = 1
|
| 54 |
+
dtype: Literal["bf16", "fp8"] = "fp8"
|
| 55 |
+
expert_dtype: Literal["fp4"] | None = "fp4"
|
| 56 |
+
vocab_size: int = 129280
|
| 57 |
+
dim: int = 1024
|
| 58 |
+
moe_inter_dim: int = 1024
|
| 59 |
+
n_layers: int = 5
|
| 60 |
+
n_mtp_layers: int = 1 # extra draft layers appended after the backbone, indices n_layers..
|
| 61 |
+
n_heads: int = 16
|
| 62 |
+
# moe
|
| 63 |
+
n_routed_experts: int = 8
|
| 64 |
+
n_shared_experts: int = 1
|
| 65 |
+
n_activated_experts: int = 2
|
| 66 |
+
score_func: Literal["softmax", "sigmoid", "sqrtsoftplus"] = "sqrtsoftplus"
|
| 67 |
+
gate_temp: float = 1.0
|
| 68 |
+
norm_topk_prob: bool = True
|
| 69 |
+
route_scale: float = 1.0
|
| 70 |
+
swiglu_limit: float = 0.0
|
| 71 |
+
# attention: latent q/kv projections, plus a LoRA-factorised output projection over o_groups
|
| 72 |
+
q_lora_rank: int = 256
|
| 73 |
+
head_dim: int = 128
|
| 74 |
+
rope_head_dim: int = 32
|
| 75 |
+
norm_eps: float = 1e-20
|
| 76 |
+
o_groups: int = 8
|
| 77 |
+
o_lora_rank: int = 256
|
| 78 |
+
# sparse attention: every layer attends over a sliding window, and may add compressed KV on top
|
| 79 |
+
window_size: int = 128
|
| 80 |
+
# one entry per layer, MTP layers included: 0 = sliding window only, r = KV compressed r-to-1
|
| 81 |
+
compress_ratios: tuple[int, ...] = (0, 2, 2, 1, 1, 0)
|
| 82 |
+
# layers sharing a ratio also share one compressed KV and one indexer, produced by the first
|
| 83 |
+
kv_source_layers: tuple[int, ...] = (1, 3)
|
| 84 |
+
index_source_layers: tuple[int, ...] = (1, 3)
|
| 85 |
+
# rope, with YaRN extrapolation when original_seq_len > 0. Compressed KV rotates at its own
|
| 86 |
+
# theta because one latent stands for compress_ratio tokens, so its positions are further apart.
|
| 87 |
+
compress_rope_theta: float = 40000.0
|
| 88 |
+
original_seq_len: int = 0
|
| 89 |
+
rope_theta: float = 10000.0
|
| 90 |
+
rope_factor: float = 40
|
| 91 |
+
beta_fast: int = 32
|
| 92 |
+
beta_slow: int = 1
|
| 93 |
+
# the indexer: a small extra attention that scores compressed positions, so each query can keep
|
| 94 |
+
# just `index_topk` of them. Names match DeepSeek-V3.2-Exp, where this mechanism first appeared.
|
| 95 |
+
index_n_heads: int = 16
|
| 96 |
+
index_head_dim: int = 64
|
| 97 |
+
index_topk: int = 64
|
| 98 |
+
# candidate pre-filtering: candidate_source_layer < 0 turns it off and the other two are unused
|
| 99 |
+
candidate_source_layer: int = -1
|
| 100 |
+
candidate_topk_blocks: int = 0
|
| 101 |
+
candidate_block_size: int = 0
|
| 102 |
+
# hyper-connections: the residual stream is carried as hc_mult parallel copies
|
| 103 |
+
hc_mult: int = 4
|
| 104 |
+
hc_sinkhorn_iters: int = 20
|
| 105 |
+
hc_eps: float = 1e-6
|
| 106 |
+
# engram: n-gram hash lookups added into the residual stream at a few layers
|
| 107 |
+
engram_layer_ids: tuple[int, ...] = ()
|
| 108 |
+
engram_num_embeddings: tuple[int, ...] = () # unpadded table rows; each rank allocates ceil(rows / world_size)
|
| 109 |
+
engram_max_ngram_size: int = 1
|
| 110 |
+
engram_vocab_size: int = 0 # bucket size each (n-gram size, head) starts searching primes from
|
| 111 |
+
engram_n_heads: int = 0
|
| 112 |
+
engram_head_dim: int = 0
|
| 113 |
+
engram_pad_id: int = 2 # token that fills n-gram slots with no history; matches training
|
| 114 |
+
# size of the compressed tokenizer vocab; every hash multiplier is derived from it
|
| 115 |
+
engram_compressed_vocab_size: int = 0
|
| 116 |
+
# vision (VL); vision_n_layers == 0 disables the vision path
|
| 117 |
+
vision_n_layers: int = 0
|
| 118 |
+
vision_dim: int = 1024
|
| 119 |
+
vision_n_heads: int = 16
|
| 120 |
+
vision_inter_dim: int = 2816
|
| 121 |
+
vision_patch_size: int = 14
|
| 122 |
+
vision_rope_theta: float = 10000.0
|
| 123 |
+
vision_downsample_ratio: int = 3
|
| 124 |
+
vision_max_n_token: int = 1024
|
| 125 |
+
vision_min_pixels: int = 544 * 544
|
| 126 |
+
vision_max_wh_ratio: int | None = None
|
| 127 |
+
# raw id of <|deepseek_image|>; every position of an image span carries this id in input_ids
|
| 128 |
+
image_token_id: int = 129264
|
| 129 |
+
# dspark draft head. Only the forward pass is implemented here -- nothing calls forward_spec,
|
| 130 |
+
# so these are read but the speculative-decoding loop itself is out of scope for this repo.
|
| 131 |
+
dspark_block_size: int = 0
|
| 132 |
+
dspark_noise_token_id: int = 0
|
| 133 |
+
dspark_target_layer_ids: tuple[int, ...] = ()
|
| 134 |
+
dspark_markov_rank: int = 256
|
| 135 |
+
dspark_n_routed_experts: int = 0
|
| 136 |
+
dspark_n_activated_experts: int = 0
|
| 137 |
+
|
| 138 |
+
@property
|
| 139 |
+
def vision_enabled(self) -> bool:
|
| 140 |
+
return self.vision_n_layers > 0
|
| 141 |
+
|
| 142 |
+
def get_moe_config(self, layer_id: int) -> tuple[int, int]:
|
| 143 |
+
"""Return the routed/activated expert counts for a given layer."""
|
| 144 |
+
if layer_id < self.n_layers:
|
| 145 |
+
return self.n_routed_experts, self.n_activated_experts
|
| 146 |
+
return (
|
| 147 |
+
self.dspark_n_routed_experts or self.n_routed_experts,
|
| 148 |
+
self.dspark_n_activated_experts or self.n_activated_experts,
|
| 149 |
+
)
|
| 150 |
+
|
| 151 |
+
|
| 152 |
+
class ParallelEmbedding(nn.Module):
|
| 153 |
+
"""Embedding sharded along the vocab dimension. Each rank holds vocab_size // world_size rows.
|
| 154 |
+
Out-of-range indices are zero-masked before all_reduce to combine partial embeddings."""
|
| 155 |
+
|
| 156 |
+
def __init__(self, vocab_size: int, dim: int):
|
| 157 |
+
super().__init__()
|
| 158 |
+
self.vocab_size = vocab_size
|
| 159 |
+
self.dim = dim
|
| 160 |
+
assert vocab_size % world_size == 0, (
|
| 161 |
+
f"Vocabulary size must be divisible by world size (world_size={world_size})"
|
| 162 |
+
)
|
| 163 |
+
self.part_vocab_size = vocab_size // world_size
|
| 164 |
+
self.vocab_start_idx = rank * self.part_vocab_size
|
| 165 |
+
self.vocab_end_idx = self.vocab_start_idx + self.part_vocab_size
|
| 166 |
+
self.weight = nn.Parameter(torch.empty(self.part_vocab_size, self.dim))
|
| 167 |
+
|
| 168 |
+
def forward(self, x: torch.Tensor) -> torch.Tensor:
|
| 169 |
+
if world_size > 1:
|
| 170 |
+
# ids off this rank read row 0 then get zeroed, so the all_reduce sums one real row
|
| 171 |
+
mask = (x < self.vocab_start_idx) | (x >= self.vocab_end_idx)
|
| 172 |
+
x = x - self.vocab_start_idx
|
| 173 |
+
x[mask] = 0
|
| 174 |
+
y = F.embedding(x, self.weight)
|
| 175 |
+
if world_size > 1:
|
| 176 |
+
y[mask] = 0
|
| 177 |
+
dist.all_reduce(y)
|
| 178 |
+
return y
|
| 179 |
+
|
| 180 |
+
|
| 181 |
+
def linear(x: torch.Tensor, weight: torch.Tensor, bias: torch.Tensor | None = None) -> torch.Tensor:
|
| 182 |
+
"""Pick a GEMM from the weight dtype. Quantized weights need a quantized activation, and both
|
| 183 |
+
fp4 and fp8 weights take an fp8 one -- for fp4 the kernel handles the mixed precision."""
|
| 184 |
+
assert bias is None
|
| 185 |
+
|
| 186 |
+
if weight.dtype == torch.float4_e2m1fn_x2:
|
| 187 |
+
x, s = act_quant(x, fp8_block_size, scale_fmt, scale_dtype)
|
| 188 |
+
return fp4_gemm(
|
| 189 |
+
x,
|
| 190 |
+
s,
|
| 191 |
+
weight,
|
| 192 |
+
weight.scale,
|
| 193 |
+
scale_dtype,
|
| 194 |
+
act_block_size=fp8_block_size,
|
| 195 |
+
)
|
| 196 |
+
elif weight.dtype == torch.float8_e4m3fn:
|
| 197 |
+
x, s = act_quant(x, fp8_block_size, scale_fmt, scale_dtype)
|
| 198 |
+
return fp8_gemm(
|
| 199 |
+
x,
|
| 200 |
+
s,
|
| 201 |
+
weight,
|
| 202 |
+
weight.scale,
|
| 203 |
+
scale_dtype,
|
| 204 |
+
block_size=fp8_block_size,
|
| 205 |
+
)
|
| 206 |
+
else:
|
| 207 |
+
return F.linear(x, weight)
|
| 208 |
+
|
| 209 |
+
|
| 210 |
+
class Linear(nn.Module):
|
| 211 |
+
"""bf16, fp8 or fp4 weights. Quantized ones get a `scale`, also attached to `.weight` so that
|
| 212 |
+
`linear()` can reach it."""
|
| 213 |
+
|
| 214 |
+
def __init__(self, in_features: int, out_features: int, bias: bool = False, dtype=None):
|
| 215 |
+
super().__init__()
|
| 216 |
+
self.in_features = in_features
|
| 217 |
+
self.out_features = out_features
|
| 218 |
+
dtype = dtype or default_dtype
|
| 219 |
+
if dtype == torch.float4_e2m1fn_x2:
|
| 220 |
+
# two values per byte: [out, in] logically, [out, in//2] stored
|
| 221 |
+
self.weight = nn.Parameter(torch.empty(out_features, in_features // 2, dtype=torch.float4_e2m1fn_x2))
|
| 222 |
+
self.weight.scale = self.scale = nn.Parameter(
|
| 223 |
+
torch.empty(out_features, in_features // fp4_block_size, dtype=torch.float8_e8m0fnu)
|
| 224 |
+
)
|
| 225 |
+
elif dtype == torch.float8_e4m3fn:
|
| 226 |
+
self.weight = nn.Parameter(torch.empty(out_features, in_features, dtype=dtype))
|
| 227 |
+
self.weight.scale = self.scale = nn.Parameter(
|
| 228 |
+
torch.empty(
|
| 229 |
+
(out_features + fp8_block_size - 1) // fp8_block_size,
|
| 230 |
+
(in_features + fp8_block_size - 1) // fp8_block_size,
|
| 231 |
+
dtype=torch.float8_e8m0fnu,
|
| 232 |
+
)
|
| 233 |
+
)
|
| 234 |
+
else:
|
| 235 |
+
self.weight = nn.Parameter(torch.empty(out_features, in_features, dtype=dtype))
|
| 236 |
+
self.register_parameter("scale", None)
|
| 237 |
+
if bias:
|
| 238 |
+
self.bias = nn.Parameter(torch.empty(out_features))
|
| 239 |
+
else:
|
| 240 |
+
self.register_parameter("bias", None)
|
| 241 |
+
|
| 242 |
+
def forward(self, x: torch.Tensor) -> torch.Tensor:
|
| 243 |
+
return linear(x, self.weight, self.bias)
|
| 244 |
+
|
| 245 |
+
|
| 246 |
+
class ColumnParallelLinear(Linear):
|
| 247 |
+
"""Splits the output dim across ranks; each rank's slice of the output is already complete."""
|
| 248 |
+
|
| 249 |
+
def __init__(self, in_features: int, out_features: int, bias: bool = False, dtype=None):
|
| 250 |
+
assert out_features % world_size == 0, (
|
| 251 |
+
f"Output features must be divisible by world size (world_size={world_size})"
|
| 252 |
+
)
|
| 253 |
+
self.part_out_features = out_features // world_size
|
| 254 |
+
super().__init__(in_features, self.part_out_features, bias, dtype)
|
| 255 |
+
|
| 256 |
+
def forward(self, x: torch.Tensor) -> torch.Tensor:
|
| 257 |
+
return linear(x, self.weight, self.bias)
|
| 258 |
+
|
| 259 |
+
|
| 260 |
+
class RowParallelLinear(Linear):
|
| 261 |
+
"""Splits the reduction dim, so each rank holds a partial sum: hence the fp32 all_reduce, with
|
| 262 |
+
the bias added only after it."""
|
| 263 |
+
|
| 264 |
+
def __init__(self, in_features: int, out_features: int, bias: bool = False, dtype=None):
|
| 265 |
+
assert in_features % world_size == 0, (
|
| 266 |
+
f"Input features must be divisible by world size (world_size={world_size})"
|
| 267 |
+
)
|
| 268 |
+
self.part_in_features = in_features // world_size
|
| 269 |
+
super().__init__(self.part_in_features, out_features, bias, dtype)
|
| 270 |
+
|
| 271 |
+
def forward(self, x: torch.Tensor) -> torch.Tensor:
|
| 272 |
+
y = linear(x, self.weight, None)
|
| 273 |
+
if world_size > 1:
|
| 274 |
+
y = y.float()
|
| 275 |
+
dist.all_reduce(y)
|
| 276 |
+
if self.bias is not None:
|
| 277 |
+
y += self.bias
|
| 278 |
+
return y.type_as(x)
|
| 279 |
+
|
| 280 |
+
|
| 281 |
+
class RMSNorm(nn.Module):
|
| 282 |
+
def __init__(self, dim: int, eps: float = 1e-6):
|
| 283 |
+
super().__init__()
|
| 284 |
+
self.dim = dim
|
| 285 |
+
self.eps = eps
|
| 286 |
+
self.weight = nn.Parameter(torch.ones(dim))
|
| 287 |
+
|
| 288 |
+
def forward(self, x: torch.Tensor):
|
| 289 |
+
dtype = x.dtype
|
| 290 |
+
x = x.float()
|
| 291 |
+
var = x.square().mean(-1, keepdim=True)
|
| 292 |
+
x = x * torch.rsqrt(var + self.eps)
|
| 293 |
+
return (self.weight * x).to(dtype)
|
| 294 |
+
|
| 295 |
+
|
| 296 |
+
class ParallelEngramEmbedding(nn.Module):
|
| 297 |
+
"""The n-gram hash table, sharded over its rows. Stays fp8: rows are dequantized on lookup."""
|
| 298 |
+
|
| 299 |
+
def __init__(self, num_embeddings: int, dim: int):
|
| 300 |
+
super().__init__()
|
| 301 |
+
self.num_embeddings = num_embeddings
|
| 302 |
+
self.dim = dim
|
| 303 |
+
self.part_num_embeddings = (num_embeddings + world_size - 1) // world_size
|
| 304 |
+
self.vocab_start_idx = rank * self.part_num_embeddings
|
| 305 |
+
self.vocab_end_idx = self.vocab_start_idx + self.part_num_embeddings
|
| 306 |
+
|
| 307 |
+
self.block_size = fp8_block_size
|
| 308 |
+
# the table stays fp8 as stored: rows are dequantized with `scale` on lookup
|
| 309 |
+
self.weight = nn.Parameter(torch.empty(self.part_num_embeddings, dim, dtype=torch.float8_e4m3fn))
|
| 310 |
+
self.scale = nn.Parameter(torch.empty(self.part_num_embeddings, dim // self.block_size, dtype=scale_dtype))
|
| 311 |
+
|
| 312 |
+
def forward(self, indices: torch.Tensor) -> torch.Tensor:
|
| 313 |
+
mask = (indices < self.vocab_start_idx) | (indices >= self.vocab_end_idx)
|
| 314 |
+
local_indices = indices - self.vocab_start_idx
|
| 315 |
+
local_indices = local_indices.masked_fill(mask, 0)
|
| 316 |
+
|
| 317 |
+
values = F.embedding(local_indices, self.weight)
|
| 318 |
+
scales = F.embedding(local_indices, self.scale)
|
| 319 |
+
values = values.float().unflatten(-1, (-1, self.block_size)) * scales.float().unsqueeze(-1)
|
| 320 |
+
values = values.flatten(-2).to(torch.bfloat16)
|
| 321 |
+
values = values.masked_fill(mask.unsqueeze(-1), 0)
|
| 322 |
+
|
| 323 |
+
if world_size > 1:
|
| 324 |
+
dist.all_reduce(values)
|
| 325 |
+
return values
|
| 326 |
+
|
| 327 |
+
|
| 328 |
+
class Engram(nn.Module):
|
| 329 |
+
"""Writes an n-gram lookup into the residual stream, gated by how well it matches that stream.
|
| 330 |
+
|
| 331 |
+
The hash ids fetch `n_hash_cols` rows; `wkv` turns them into one key per hc copy plus a shared
|
| 332 |
+
value. The gate is a normalized dot product of stream against key.
|
| 333 |
+
"""
|
| 334 |
+
|
| 335 |
+
def __init__(self, args: ModelArgs, layer_id: int, layout: EngramLayout):
|
| 336 |
+
super().__init__()
|
| 337 |
+
self.layer_id = layer_id
|
| 338 |
+
self.layer_hash_index = layout.layer_ids.index(layer_id)
|
| 339 |
+
self.dim = args.dim
|
| 340 |
+
self.hc_mult = args.hc_mult
|
| 341 |
+
self.clamp_value = 1e-6
|
| 342 |
+
|
| 343 |
+
self.embed = ParallelEngramEmbedding(layout.num_embeddings[self.layer_hash_index], layout.head_dim)
|
| 344 |
+
n_hash_cols = (layout.max_ngram_size - 1) * layout.n_heads
|
| 345 |
+
self.wkv = Linear(n_hash_cols * layout.head_dim, args.dim * (args.hc_mult + 1))
|
| 346 |
+
self.eps = args.norm_eps
|
| 347 |
+
self.q_weight = nn.Parameter(torch.ones(args.hc_mult, args.dim))
|
| 348 |
+
self.k_weight = nn.Parameter(torch.ones(args.hc_mult, args.dim))
|
| 349 |
+
|
| 350 |
+
def forward(self, x: torch.Tensor, hash_ids: torch.Tensor, token_mask: torch.Tensor | None = None) -> torch.Tensor:
|
| 351 |
+
"""x: [B, L, hc_mult, dim]; hash_ids: [B, L, n_hash_cols]; token_mask: [B, L], False shuts
|
| 352 |
+
the gate so those positions pass through untouched."""
|
| 353 |
+
kv = self.wkv(self.embed(hash_ids).flatten(-2))
|
| 354 |
+
key, value = kv.split([self.hc_mult * self.dim, self.dim], dim=-1)
|
| 355 |
+
key = key.float().unflatten(-1, (self.hc_mult, self.dim))
|
| 356 |
+
weight = self.q_weight.float() * self.k_weight.float() # only ever used as a product
|
| 357 |
+
h, eps = x.float(), self.eps
|
| 358 |
+
# normalized per (token, hc copy) over `dim`, NOT jointly over the copies
|
| 359 |
+
rstd = torch.rsqrt(h.square().mean(-1) + eps) * torch.rsqrt(key.square().mean(-1) + eps)
|
| 360 |
+
dot = (h * weight * key).sum(-1) * rstd * self.dim**-0.5
|
| 361 |
+
# signed sqrt before the sigmoid, matching the training kernel
|
| 362 |
+
gate = torch.sigmoid(torch.copysign(dot.abs().clamp_min(self.clamp_value).sqrt(), dot))
|
| 363 |
+
if token_mask is not None:
|
| 364 |
+
gate = gate.masked_fill(~token_mask.unsqueeze(-1), 0)
|
| 365 |
+
return (h + gate.unsqueeze(-1) * value.float().unsqueeze(-2)).to(x.dtype)
|
| 366 |
+
|
| 367 |
+
|
| 368 |
+
@lru_cache(2)
|
| 369 |
+
def precompute_freqs_cis(dim, seqlen, original_seq_len, base, factor, beta_fast, beta_slow) -> torch.Tensor:
|
| 370 |
+
"""Rotary frequencies as complex exponentials, one row per position.
|
| 371 |
+
|
| 372 |
+
With original_seq_len > 0 this applies YaRN: dimensions whose wavelength already fits inside the
|
| 373 |
+
training context keep their frequency, those far beyond it are divided by `factor`, and the
|
| 374 |
+
`beta_fast`..`beta_slow` band in between is faded across with a linear ramp.
|
| 375 |
+
"""
|
| 376 |
+
freqs = 1.0 / (base ** (torch.arange(0, dim, 2, dtype=torch.float32) / dim))
|
| 377 |
+
if original_seq_len > 0:
|
| 378 |
+
# the dim whose wavelength completes `rotations` turns over the training context
|
| 379 |
+
def corrected_dim(rotations):
|
| 380 |
+
return dim * math.log(original_seq_len / (rotations * 2 * math.pi)) / (2 * math.log(base))
|
| 381 |
+
|
| 382 |
+
low = max(math.floor(corrected_dim(beta_fast)), 0)
|
| 383 |
+
high = min(math.ceil(corrected_dim(beta_slow)), dim - 1)
|
| 384 |
+
ramp = ((torch.arange(dim // 2, dtype=torch.float32) - low) / max(high - low, 1e-3)).clamp(0, 1)
|
| 385 |
+
smooth = 1 - ramp
|
| 386 |
+
freqs = freqs / factor * (1 - smooth) + freqs * smooth
|
| 387 |
+
|
| 388 |
+
freqs = torch.outer(torch.arange(seqlen), freqs)
|
| 389 |
+
return torch.polar(torch.ones_like(freqs), freqs)
|
| 390 |
+
|
| 391 |
+
|
| 392 |
+
def apply_rotary_emb(x: torch.Tensor, freqs_cis: torch.Tensor, inverse: bool = False) -> torch.Tensor:
|
| 393 |
+
"""Rotate `x` in place, taking adjacent element pairs as complex numbers. Accepts [b, s, d] and
|
| 394 |
+
[b, s, h, d]; `inverse` conjugates the rotation, which is how the attention output gets the
|
| 395 |
+
query's rotation removed again so the cache can stay in one shared rotated form."""
|
| 396 |
+
y = x
|
| 397 |
+
x = torch.view_as_complex(x.float().unflatten(-1, (-1, 2)))
|
| 398 |
+
if inverse:
|
| 399 |
+
freqs_cis = freqs_cis.conj()
|
| 400 |
+
if x.ndim == 3:
|
| 401 |
+
freqs_cis = freqs_cis.view(1, x.size(1), x.size(-1))
|
| 402 |
+
else:
|
| 403 |
+
freqs_cis = freqs_cis.view(1, x.size(1), 1, x.size(-1))
|
| 404 |
+
x = torch.view_as_real(x * freqs_cis).flatten(-2)
|
| 405 |
+
y.copy_(x)
|
| 406 |
+
return y
|
| 407 |
+
|
| 408 |
+
|
| 409 |
+
@lru_cache(1)
|
| 410 |
+
def get_window_topk_idxs(window_size: int, bsz: int, seqlen: int, start_pos: int):
|
| 411 |
+
"""Which sliding-window cache slots each query attends to; -1 marks a slot holding nothing.
|
| 412 |
+
|
| 413 |
+
The cache is a ring of `window_size` slots. Prefill needs one row per query, each seeing its own
|
| 414 |
+
causal window. A decode step has a single query that sees the whole ring, listed oldest first.
|
| 415 |
+
Order within a row does not matter to `sparse_attn`, which handles every slot independently.
|
| 416 |
+
"""
|
| 417 |
+
if start_pos == 0:
|
| 418 |
+
end = torch.arange(seqlen).unsqueeze(1)
|
| 419 |
+
idxs = (end - window_size + 1).clamp(0) + torch.arange(min(seqlen, window_size))
|
| 420 |
+
idxs = torch.where(idxs > end, -1, idxs) # before the sequence started
|
| 421 |
+
else:
|
| 422 |
+
oldest = start_pos % window_size + 1
|
| 423 |
+
idxs = torch.cat([torch.arange(oldest, window_size), torch.arange(oldest)])
|
| 424 |
+
idxs = torch.where(idxs > start_pos, -1, idxs) # ring still filling
|
| 425 |
+
# sparse_attn needs real [b, m, topk] int32 memory, hence the materializing expand
|
| 426 |
+
return idxs.int().unsqueeze(0).expand(bsz, -1, -1).contiguous()
|
| 427 |
+
|
| 428 |
+
|
| 429 |
+
class Compressor(nn.Module):
|
| 430 |
+
"""Pools `compress_ratio` consecutive tokens into one KV latent with a learned softmax gate.
|
| 431 |
+
|
| 432 |
+
Returns the latent before RoPE, or None while a group is still filling up -- so during decode it
|
| 433 |
+
only yields every `compress_ratio` steps, holding the partial group in `kv_state`/`score_state`.
|
| 434 |
+
Pre-RoPE is deliberate: the indexer needs the unrotated form, so Attention rotates afterwards.
|
| 435 |
+
"""
|
| 436 |
+
|
| 437 |
+
def __init__(self, args: ModelArgs, layer_id: int):
|
| 438 |
+
super().__init__()
|
| 439 |
+
compress_ratio = args.compress_ratios[layer_id]
|
| 440 |
+
head_dim = args.head_dim
|
| 441 |
+
self.compress_ratio = compress_ratio
|
| 442 |
+
self.head_dim = head_dim
|
| 443 |
+
self.norm = RMSNorm(head_dim, args.norm_eps)
|
| 444 |
+
# ratio 1 is a plain projection, so it stays in the checkpoint's bf16; the softmax pooling
|
| 445 |
+
# above ratio 1 runs in fp32, so those weights are promoted to fp32 to match
|
| 446 |
+
self.wkv = Linear(args.dim, head_dim, dtype=torch.float32 if compress_ratio > 1 else torch.bfloat16)
|
| 447 |
+
if compress_ratio > 1:
|
| 448 |
+
self.wgate = Linear(args.dim, head_dim, dtype=torch.float32)
|
| 449 |
+
# tail of an incomplete group, carried across decode steps
|
| 450 |
+
self.kv_state: torch.Tensor
|
| 451 |
+
self.score_state: torch.Tensor
|
| 452 |
+
state_shape = (args.max_batch_size, compress_ratio, head_dim)
|
| 453 |
+
self.register_buffer("kv_state", torch.zeros(state_shape, dtype=torch.float32), persistent=False)
|
| 454 |
+
self.register_buffer(
|
| 455 |
+
"score_state", torch.full(state_shape, -torch.inf, dtype=torch.float32), persistent=False
|
| 456 |
+
)
|
| 457 |
+
|
| 458 |
+
def forward(self, x: torch.Tensor, start_pos: int) -> torch.Tensor | None:
|
| 459 |
+
bsz, seqlen, _ = x.size()
|
| 460 |
+
ratio, dtype = self.compress_ratio, x.dtype
|
| 461 |
+
if ratio == 1: # one token per group: nothing to pool, so no gate and no fp32
|
| 462 |
+
return self.norm(self.wkv(x))
|
| 463 |
+
|
| 464 |
+
x = x.float()
|
| 465 |
+
kv, score = self.wkv(x), self.wgate(x)
|
| 466 |
+
if start_pos == 0:
|
| 467 |
+
should_compress = seqlen >= ratio
|
| 468 |
+
remainder = seqlen % ratio
|
| 469 |
+
cutoff = seqlen - remainder
|
| 470 |
+
if remainder: # trailing partial group waits in the state
|
| 471 |
+
kv, self.kv_state[:bsz, :remainder] = kv.split([cutoff, remainder], dim=1)
|
| 472 |
+
score, self.score_state[:bsz, :remainder] = score.split([cutoff, remainder], dim=1)
|
| 473 |
+
kv = kv.unflatten(1, (-1, ratio))
|
| 474 |
+
score = score.unflatten(1, (-1, ratio))
|
| 475 |
+
kv = (kv * score.softmax(dim=2)).sum(dim=2)
|
| 476 |
+
else: # one token per step: fill a slot, and pool only when the group just completed
|
| 477 |
+
should_compress = (start_pos + 1) % ratio == 0
|
| 478 |
+
slot = start_pos % ratio
|
| 479 |
+
self.kv_state[:bsz, slot] = kv.squeeze(1)
|
| 480 |
+
self.score_state[:bsz, slot] = score.squeeze(1)
|
| 481 |
+
if should_compress:
|
| 482 |
+
kv = (self.kv_state[:bsz] * self.score_state[:bsz].softmax(dim=1)).sum(dim=1, keepdim=True)
|
| 483 |
+
if not should_compress:
|
| 484 |
+
return None
|
| 485 |
+
return self.norm(kv.to(dtype))
|
| 486 |
+
|
| 487 |
+
|
| 488 |
+
class Indexer(torch.nn.Module):
|
| 489 |
+
"""Keeps the `index_topk` best compressed positions per query.
|
| 490 |
+
|
| 491 |
+
A small side attention: fp4 query heads against one shared key per compressed position, scores
|
| 492 |
+
rectified then combined by `weights_proj`. With a candidate source this is the second of two
|
| 493 |
+
levels; `select_candidate_blocks` is the first.
|
| 494 |
+
"""
|
| 495 |
+
|
| 496 |
+
def __init__(self, args: ModelArgs, layer_id: int):
|
| 497 |
+
super().__init__()
|
| 498 |
+
# the index keys are derived from the compressor's latent, so only a layer that compresses
|
| 499 |
+
# its own KV can produce them; every other indexer reads them from that layer's cache
|
| 500 |
+
self.owns_k = layer_id in args.kv_source_layers
|
| 501 |
+
self.compress_ratio = args.compress_ratios[layer_id]
|
| 502 |
+
self.is_candidate_source = layer_id == args.candidate_source_layer
|
| 503 |
+
self.uses_candidates = 0 <= args.candidate_source_layer < layer_id
|
| 504 |
+
self.candidate_topk_blocks = args.candidate_topk_blocks
|
| 505 |
+
self.candidate_block_size = args.candidate_block_size
|
| 506 |
+
self.dim = args.dim
|
| 507 |
+
self.n_heads = args.index_n_heads
|
| 508 |
+
self.n_local_heads = args.index_n_heads // world_size
|
| 509 |
+
self.index_head_dim = args.index_head_dim
|
| 510 |
+
self.rope_head_dim = args.rope_head_dim
|
| 511 |
+
self.index_topk = args.index_topk
|
| 512 |
+
self.q_lora_rank = args.q_lora_rank
|
| 513 |
+
self.softmax_scale = self.index_head_dim**-0.5
|
| 514 |
+
self.wq_b = ColumnParallelLinear(self.q_lora_rank, self.n_heads * self.index_head_dim)
|
| 515 |
+
self.weights_proj = ColumnParallelLinear(self.dim, self.n_heads, dtype=torch.bfloat16)
|
| 516 |
+
self.freqs_cis: torch.Tensor | None = None
|
| 517 |
+
if self.owns_k:
|
| 518 |
+
self.wk = Linear(args.head_dim, self.index_head_dim, dtype=torch.bfloat16)
|
| 519 |
+
self.k_norm = RMSNorm(self.index_head_dim, args.norm_eps)
|
| 520 |
+
self.k_cache: torch.Tensor
|
| 521 |
+
self.register_buffer(
|
| 522 |
+
"k_cache",
|
| 523 |
+
torch.zeros(args.max_batch_size, args.max_seq_len // self.compress_ratio, args.index_head_dim),
|
| 524 |
+
persistent=False,
|
| 525 |
+
)
|
| 526 |
+
|
| 527 |
+
def forward(self, x: torch.Tensor, qr: torch.Tensor, latent: torch.Tensor, start_pos: int, offset: int):
|
| 528 |
+
"""`latent` is this layer's RoPE-free compressed latent, None when this layer does not
|
| 529 |
+
compress or when its current group is still incomplete. An index-key owner turns it into
|
| 530 |
+
index keys here, which has to happen before Attention overwrites that same storage with
|
| 531 |
+
the RoPE'd, quantized values."""
|
| 532 |
+
assert self.freqs_cis is not None
|
| 533 |
+
bsz, seqlen, _ = x.size()
|
| 534 |
+
ratio, rd, end_pos = self.compress_ratio, self.rope_head_dim, start_pos + seqlen
|
| 535 |
+
|
| 536 |
+
# latent is None while a group is still filling up, so there is nothing to publish yet
|
| 537 |
+
if self.owns_k and latent is not None:
|
| 538 |
+
# a latent stands for the first token of its group, so group j takes position j * ratio
|
| 539 |
+
freqs = (
|
| 540 |
+
self.freqs_cis[: seqlen - seqlen % ratio : ratio]
|
| 541 |
+
if start_pos == 0
|
| 542 |
+
else self.freqs_cis[start_pos + 1 - ratio].unsqueeze(0)
|
| 543 |
+
)
|
| 544 |
+
k = self.k_norm(self.wk(latent))
|
| 545 |
+
apply_rotary_emb(k[..., -rd:], freqs)
|
| 546 |
+
fp4_act_quant(k, fp4_block_size, True)
|
| 547 |
+
self.k_cache[:bsz, start_pos // ratio : start_pos // ratio + k.size(1)] = k
|
| 548 |
+
shared_attn.index_k = self.k_cache
|
| 549 |
+
|
| 550 |
+
q = self.wq_b(qr).unflatten(-1, (self.n_local_heads, self.index_head_dim))
|
| 551 |
+
apply_rotary_emb(q[..., -rd:], self.freqs_cis[start_pos:end_pos])
|
| 552 |
+
fp4_act_quant(q, fp4_block_size, True)
|
| 553 |
+
|
| 554 |
+
index_k = shared_attn.index_k[:bsz, : end_pos // ratio]
|
| 555 |
+
weights = self.weights_proj(x) * (self.softmax_scale * self.n_heads**-0.5)
|
| 556 |
+
index_score = torch.einsum("bshd,btd->bsht", q, index_k)
|
| 557 |
+
index_score = (index_score.relu_() * weights.unsqueeze(-1)).sum(dim=2)
|
| 558 |
+
if world_size > 1:
|
| 559 |
+
dist.all_reduce(index_score)
|
| 560 |
+
|
| 561 |
+
# how many compressed positions each query can see: a block becomes visible once the query
|
| 562 |
+
# has passed its last token. One query per decode step, so there it is just a number.
|
| 563 |
+
if start_pos == 0:
|
| 564 |
+
compress_lens = (torch.arange(1, seqlen + 1, device=x.device) // ratio).unsqueeze(-1)
|
| 565 |
+
index_score.masked_fill_(torch.arange(seqlen // ratio, device=x.device) >= compress_lens, -torch.inf)
|
| 566 |
+
else:
|
| 567 |
+
compress_lens = end_pos // ratio
|
| 568 |
+
|
| 569 |
+
if self.is_candidate_source:
|
| 570 |
+
shared_attn.candidates = select_candidate_blocks(
|
| 571 |
+
index_score, compress_lens, self.candidate_topk_blocks, self.candidate_block_size
|
| 572 |
+
)
|
| 573 |
+
elif self.uses_candidates:
|
| 574 |
+
# level two: score with our own weights, but only inside the source's candidate blocks
|
| 575 |
+
index_score = index_score.masked_fill(~shared_attn.candidates, -torch.inf)
|
| 576 |
+
|
| 577 |
+
# top-k by score, re-sorted into position order; unreachable -> -1, rest shifted by offset
|
| 578 |
+
topk = min(self.index_topk, end_pos // ratio)
|
| 579 |
+
idxs = index_score.topk(topk, dim=-1, sorted=False).indices.sort(dim=-1).values
|
| 580 |
+
return torch.where(idxs < compress_lens, idxs + offset, -1).int()
|
| 581 |
+
|
| 582 |
+
|
| 583 |
+
def select_candidate_blocks(
|
| 584 |
+
logits: torch.Tensor,
|
| 585 |
+
compress_lens: torch.Tensor | int,
|
| 586 |
+
topk_blocks: int,
|
| 587 |
+
block_size: int,
|
| 588 |
+
) -> torch.Tensor:
|
| 589 |
+
"""Level one of the two-level top-k: keep the `topk_blocks` highest-scoring blocks per query.
|
| 590 |
+
|
| 591 |
+
`logits` is [..., n_positions] with positions the query cannot reach already at -inf, which is
|
| 592 |
+
what makes a block score of -inf mean "not reachable yet". `compress_lens` is a plain int during
|
| 593 |
+
decode, or broadcasts against logits' leading dims during prefill. Returns a bool mask shaped
|
| 594 |
+
like `logits`, so the layers consuming it just mask and never think about blocks again.
|
| 595 |
+
"""
|
| 596 |
+
width = logits.size(-1)
|
| 597 |
+
# score each block by its best position; -inf pads the last one out to block_size
|
| 598 |
+
scores = F.pad(logits, (0, -width % block_size), value=-torch.inf)
|
| 599 |
+
scores = scores.unflatten(-1, (-1, block_size)).amax(dim=-1)
|
| 600 |
+
num_blocks = scores.size(-1)
|
| 601 |
+
|
| 602 |
+
# the block with this query's newest position is only partly filled, so pin it in: it holds the
|
| 603 |
+
# most recent tokens but could otherwise be outscored by an older, full block
|
| 604 |
+
last = (compress_lens - 1) // block_size
|
| 605 |
+
scores = scores.masked_fill(torch.arange(num_blocks, device=logits.device) == last, torch.inf)
|
| 606 |
+
|
| 607 |
+
top = scores.topk(min(topk_blocks, num_blocks), dim=-1)
|
| 608 |
+
# fewer reachable blocks than topk_blocks means leftover picks came back -inf: drop them
|
| 609 |
+
keep = torch.zeros_like(scores, dtype=torch.bool).scatter_(-1, top.indices, top.values > -torch.inf)
|
| 610 |
+
return keep.repeat_interleave(block_size, dim=-1)[..., :width]
|
| 611 |
+
|
| 612 |
+
|
| 613 |
+
class Attention(nn.Module):
|
| 614 |
+
"""Latent attention over two KV sources at once, concatenated into one `sparse_attn` call: a
|
| 615 |
+
sliding window of raw KV, plus -- when compress_ratio > 0 -- `index_topk` compressed positions
|
| 616 |
+
reaching further back. Q and the output projection are both low-rank, the latter grouped.
|
| 617 |
+
|
| 618 |
+
compress_ratio > 0 does not mean the layer compresses its own KV: only kv_source_layers do,
|
| 619 |
+
the rest read that same cache.
|
| 620 |
+
"""
|
| 621 |
+
|
| 622 |
+
def __init__(self, layer_id: int, args: ModelArgs):
|
| 623 |
+
super().__init__()
|
| 624 |
+
self.layer_id = layer_id
|
| 625 |
+
self.dim = args.dim
|
| 626 |
+
self.n_heads = args.n_heads
|
| 627 |
+
self.n_local_heads = args.n_heads // world_size
|
| 628 |
+
self.q_lora_rank = args.q_lora_rank
|
| 629 |
+
self.o_lora_rank = args.o_lora_rank
|
| 630 |
+
self.head_dim = args.head_dim
|
| 631 |
+
self.rope_head_dim = args.rope_head_dim
|
| 632 |
+
self.nope_head_dim = args.head_dim - args.rope_head_dim
|
| 633 |
+
self.n_groups = args.o_groups
|
| 634 |
+
self.n_local_groups = self.n_groups // world_size
|
| 635 |
+
self.window_size = args.window_size
|
| 636 |
+
self.compress_ratio = args.compress_ratios[layer_id]
|
| 637 |
+
self.eps = args.norm_eps
|
| 638 |
+
|
| 639 |
+
self.attn_sink = nn.Parameter(torch.empty(self.n_local_heads, dtype=torch.float32))
|
| 640 |
+
self.wq_a = Linear(self.dim, self.q_lora_rank)
|
| 641 |
+
self.q_norm = RMSNorm(self.q_lora_rank, self.eps)
|
| 642 |
+
self.wq_b = ColumnParallelLinear(self.q_lora_rank, self.n_heads * self.head_dim)
|
| 643 |
+
self.wkv = Linear(self.dim, self.head_dim)
|
| 644 |
+
self.kv_norm = RMSNorm(self.head_dim, self.eps)
|
| 645 |
+
self.wo_a = ColumnParallelLinear(
|
| 646 |
+
self.n_heads * self.head_dim // self.n_groups,
|
| 647 |
+
self.n_groups * args.o_lora_rank,
|
| 648 |
+
dtype=torch.bfloat16,
|
| 649 |
+
)
|
| 650 |
+
self.wo_b = RowParallelLinear(self.n_groups * args.o_lora_rank, self.dim)
|
| 651 |
+
self.softmax_scale = self.head_dim**-0.5
|
| 652 |
+
|
| 653 |
+
is_backbone = layer_id < args.n_layers
|
| 654 |
+
self.is_kv_source = is_backbone and layer_id in args.kv_source_layers
|
| 655 |
+
self.is_index_source = is_backbone and layer_id in args.index_source_layers
|
| 656 |
+
self.compressor: Compressor | None = None
|
| 657 |
+
self.indexer: Indexer | None = None
|
| 658 |
+
if self.is_kv_source:
|
| 659 |
+
self.compressor = Compressor(args, layer_id)
|
| 660 |
+
if self.is_index_source:
|
| 661 |
+
self.indexer = Indexer(args, layer_id)
|
| 662 |
+
|
| 663 |
+
self.window_kv_cache: torch.Tensor
|
| 664 |
+
self.register_buffer(
|
| 665 |
+
"window_kv_cache",
|
| 666 |
+
torch.zeros(args.max_batch_size, args.window_size, self.head_dim),
|
| 667 |
+
persistent=False,
|
| 668 |
+
)
|
| 669 |
+
if self.is_kv_source:
|
| 670 |
+
self.compress_kv_cache: torch.Tensor
|
| 671 |
+
self.register_buffer(
|
| 672 |
+
"compress_kv_cache",
|
| 673 |
+
torch.zeros(
|
| 674 |
+
args.max_batch_size,
|
| 675 |
+
args.max_seq_len // self.compress_ratio,
|
| 676 |
+
self.head_dim,
|
| 677 |
+
),
|
| 678 |
+
persistent=False,
|
| 679 |
+
)
|
| 680 |
+
if self.compress_ratio:
|
| 681 |
+
original_seq_len, rope_theta = (
|
| 682 |
+
args.original_seq_len,
|
| 683 |
+
args.compress_rope_theta,
|
| 684 |
+
)
|
| 685 |
+
else:
|
| 686 |
+
# disable YaRN and use base rope_theta in pure sliding-window attention
|
| 687 |
+
original_seq_len, rope_theta = 0, args.rope_theta
|
| 688 |
+
freqs_cis = precompute_freqs_cis(
|
| 689 |
+
self.rope_head_dim,
|
| 690 |
+
args.max_seq_len,
|
| 691 |
+
original_seq_len,
|
| 692 |
+
rope_theta,
|
| 693 |
+
args.rope_factor,
|
| 694 |
+
args.beta_fast,
|
| 695 |
+
args.beta_slow,
|
| 696 |
+
)
|
| 697 |
+
self.freqs_cis: torch.Tensor
|
| 698 |
+
self.register_buffer("freqs_cis", freqs_cis, persistent=False)
|
| 699 |
+
|
| 700 |
+
def _window_kv(self, x, freqs_cis, start_pos):
|
| 701 |
+
"""This layer's sliding-window K and the window positions every query may attend to. The K
|
| 702 |
+
stays fp8, quantized over the whole post-RoPE vector, RoPE tail included."""
|
| 703 |
+
bsz, seqlen, _ = x.size()
|
| 704 |
+
win = self.window_size
|
| 705 |
+
kv = self.kv_norm(self.wkv(x))
|
| 706 |
+
apply_rotary_emb(kv[..., -self.rope_head_dim :], freqs_cis)
|
| 707 |
+
act_quant(kv, fp8_block_size, scale_fmt, scale_dtype, True)
|
| 708 |
+
if start_pos == 0: # prefill: attend over this chunk, seeding the ring buffer for decode
|
| 709 |
+
if seqlen <= win:
|
| 710 |
+
self.window_kv_cache[:bsz, :seqlen] = kv
|
| 711 |
+
else:
|
| 712 |
+
cutoff = seqlen % win
|
| 713 |
+
self.window_kv_cache[:bsz, cutoff:win], self.window_kv_cache[:bsz, :cutoff] = kv[:, -win:].split(
|
| 714 |
+
[win - cutoff, cutoff], dim=1
|
| 715 |
+
)
|
| 716 |
+
window_kv = kv
|
| 717 |
+
else: # decode: one token into the ring buffer, attend over the whole window
|
| 718 |
+
self.window_kv_cache[:bsz, start_pos % win] = kv.squeeze(1)
|
| 719 |
+
window_kv = self.window_kv_cache[:bsz]
|
| 720 |
+
return window_kv, get_window_topk_idxs(win, bsz, seqlen, start_pos)
|
| 721 |
+
|
| 722 |
+
def _compress_topk_idxs(self, x, qr, latent, start_pos, offset, compress_len):
|
| 723 |
+
"""Which compressed positions each query attends to. Index sources run their own indexer;
|
| 724 |
+
the layers in between reuse the result their source published."""
|
| 725 |
+
if not self.is_index_source:
|
| 726 |
+
return shared_attn.topk_idxs
|
| 727 |
+
|
| 728 |
+
bsz, seqlen, _ = x.size()
|
| 729 |
+
if compress_len == 0:
|
| 730 |
+
idxs = torch.empty(bsz, seqlen, 0, dtype=torch.int32, device=x.device)
|
| 731 |
+
else:
|
| 732 |
+
assert self.indexer is not None
|
| 733 |
+
if self.indexer.freqs_cis is None:
|
| 734 |
+
self.indexer.freqs_cis = self.freqs_cis
|
| 735 |
+
idxs = self.indexer(x, qr, latent, start_pos, offset)
|
| 736 |
+
shared_attn.topk_idxs = idxs
|
| 737 |
+
return idxs
|
| 738 |
+
|
| 739 |
+
def _compress_kv(self, x, qr, start_pos, offset):
|
| 740 |
+
"""The shared compressed KV and the compressed positions every query may attend to. This
|
| 741 |
+
layer compresses its own KV only when it is a source; otherwise it just reads the cache."""
|
| 742 |
+
bsz, seqlen, _ = x.size()
|
| 743 |
+
ratio = self.compress_ratio
|
| 744 |
+
compress_len = (start_pos + seqlen) // ratio
|
| 745 |
+
latent = None
|
| 746 |
+
if self.is_kv_source:
|
| 747 |
+
latent = self.compressor(x, start_pos)
|
| 748 |
+
shared_attn.compress_kv = self.compress_kv_cache
|
| 749 |
+
# the indexer needs the latent before RoPE, so it runs before the cache is written
|
| 750 |
+
idxs = self._compress_topk_idxs(x, qr, latent, start_pos, offset, compress_len)
|
| 751 |
+
if latent is not None:
|
| 752 |
+
# a latent stands for the first token of its group, so group j takes position j * ratio
|
| 753 |
+
freqs = (
|
| 754 |
+
self.freqs_cis[: seqlen - seqlen % ratio : ratio]
|
| 755 |
+
if start_pos == 0
|
| 756 |
+
else self.freqs_cis[start_pos + 1 - ratio].unsqueeze(0)
|
| 757 |
+
)
|
| 758 |
+
apply_rotary_emb(latent[..., -self.rope_head_dim :], freqs)
|
| 759 |
+
# Compressed KV uses groups of 16 with E4M3 scales; the indexer uses 32 with E8M0.
|
| 760 |
+
fp4_act_quant(latent, 16, True, scale_dtype=torch.float8_e4m3fn)
|
| 761 |
+
self.compress_kv_cache[:bsz, start_pos // ratio : start_pos // ratio + latent.size(1)] = latent
|
| 762 |
+
# read after the write, so this does not depend on the slice aliasing the cache
|
| 763 |
+
return shared_attn.compress_kv[:bsz, :compress_len], idxs
|
| 764 |
+
|
| 765 |
+
def forward(self, x: torch.Tensor, start_pos: int):
|
| 766 |
+
bsz, seqlen, _ = x.size()
|
| 767 |
+
freqs_cis = self.freqs_cis[start_pos : start_pos + seqlen]
|
| 768 |
+
rd = self.rope_head_dim
|
| 769 |
+
|
| 770 |
+
qr = self.q_norm(self.wq_a(x))
|
| 771 |
+
q = self.wq_b(qr).unflatten(-1, (self.n_local_heads, self.head_dim))
|
| 772 |
+
apply_rotary_emb(q[..., -rd:], freqs_cis)
|
| 773 |
+
|
| 774 |
+
kv, topk_idxs = self._window_kv(x, freqs_cis, start_pos)
|
| 775 |
+
if self.compress_ratio:
|
| 776 |
+
compress_kv, compress_idxs = self._compress_kv(x, qr, start_pos, kv.size(1))
|
| 777 |
+
kv = torch.cat([kv, compress_kv], dim=1)
|
| 778 |
+
topk_idxs = torch.cat([topk_idxs, compress_idxs], dim=-1)
|
| 779 |
+
|
| 780 |
+
o = sparse_attn(q, kv, self.attn_sink, topk_idxs, self.softmax_scale)
|
| 781 |
+
apply_rotary_emb(o[..., -rd:], freqs_cis, True)
|
| 782 |
+
|
| 783 |
+
# wo_a is block-diagonal over groups (each projects only its own heads), hence einsum not
|
| 784 |
+
# Linear. convert.py dequantizes it to bf16; an fp8 grouped GEMM would halve the memory.
|
| 785 |
+
o = o.view(bsz, seqlen, self.n_local_groups, -1)
|
| 786 |
+
wo_a = self.wo_a.weight.view(self.n_local_groups, self.o_lora_rank, -1)
|
| 787 |
+
o = torch.einsum("bsgd,grd->bsgr", o, wo_a)
|
| 788 |
+
x = self.wo_b(o.flatten(2))
|
| 789 |
+
return x
|
| 790 |
+
|
| 791 |
+
|
| 792 |
+
class Gate(nn.Module):
|
| 793 |
+
"""MoE gating. The correction bias steers expert selection only; the routing weights come from the
|
| 794 |
+
unbiased scores. Image-span tokens use a separate bias (training `noaux_tc_for_vl`)."""
|
| 795 |
+
|
| 796 |
+
def __init__(self, layer_id: int, args: ModelArgs):
|
| 797 |
+
super().__init__()
|
| 798 |
+
n_routed_experts, n_activated_experts = args.get_moe_config(layer_id)
|
| 799 |
+
self.dim = args.dim
|
| 800 |
+
self.topk = n_activated_experts
|
| 801 |
+
self.score_func = args.score_func
|
| 802 |
+
self.gate_temp = args.gate_temp
|
| 803 |
+
self.norm_topk_prob = args.norm_topk_prob
|
| 804 |
+
self.route_scale = args.route_scale
|
| 805 |
+
self.weight = nn.Parameter(torch.empty(n_routed_experts, args.dim))
|
| 806 |
+
self.bias = nn.Parameter(torch.empty(n_routed_experts, dtype=torch.float32))
|
| 807 |
+
self.bias_vl = nn.Parameter(torch.empty(n_routed_experts, dtype=torch.float32)) if args.vision_enabled else None
|
| 808 |
+
|
| 809 |
+
def forward(self, x: torch.Tensor, image_mask: torch.Tensor | None = None) -> tuple[torch.Tensor, torch.Tensor]:
|
| 810 |
+
"""x: [n, dim]; image_mask: [n] bool, True for tokens inside an image span."""
|
| 811 |
+
scores = linear(x.float(), self.weight.float()) / self.gate_temp
|
| 812 |
+
if self.score_func == "softmax":
|
| 813 |
+
scores = scores.softmax(dim=-1)
|
| 814 |
+
elif self.score_func == "sigmoid":
|
| 815 |
+
scores = scores.sigmoid()
|
| 816 |
+
else:
|
| 817 |
+
scores = F.softplus(scores).sqrt()
|
| 818 |
+
bias = self.bias
|
| 819 |
+
if image_mask is not None and self.bias_vl is not None:
|
| 820 |
+
bias = torch.where(image_mask.unsqueeze(-1), self.bias_vl, bias)
|
| 821 |
+
# the bias picks experts but does not scale them: weights come from the raw scores
|
| 822 |
+
indices = (scores + bias).topk(self.topk, dim=-1)[1]
|
| 823 |
+
weights = scores.gather(1, indices)
|
| 824 |
+
if self.norm_topk_prob and self.topk > 1:
|
| 825 |
+
weights /= weights.sum(dim=-1, keepdim=True) + 1e-20 # not norm_eps, matches training
|
| 826 |
+
weights *= self.route_scale
|
| 827 |
+
return weights, indices
|
| 828 |
+
|
| 829 |
+
|
| 830 |
+
class Expert(nn.Module):
|
| 831 |
+
"""One SwiGLU FFN. The clamps come straight from training, where they keep fp8/fp4 activations in
|
| 832 |
+
range: the up branch is clamped on both sides, the gate branch only from above."""
|
| 833 |
+
|
| 834 |
+
def __init__(self, dim: int, inter_dim: int, dtype=None, swiglu_limit=0.0):
|
| 835 |
+
super().__init__()
|
| 836 |
+
self.w1 = Linear(dim, inter_dim, dtype=dtype)
|
| 837 |
+
self.w2 = Linear(inter_dim, dim, dtype=dtype)
|
| 838 |
+
self.w3 = Linear(dim, inter_dim, dtype=dtype)
|
| 839 |
+
self.swiglu_limit = swiglu_limit
|
| 840 |
+
|
| 841 |
+
def forward(self, x: torch.Tensor, weights: torch.Tensor | None = None) -> torch.Tensor:
|
| 842 |
+
dtype = x.dtype
|
| 843 |
+
gate = self.w1(x).float()
|
| 844 |
+
up = self.w3(x).float()
|
| 845 |
+
if self.swiglu_limit > 0:
|
| 846 |
+
up = torch.clamp(up, min=-self.swiglu_limit, max=self.swiglu_limit)
|
| 847 |
+
gate = torch.clamp(gate, max=self.swiglu_limit)
|
| 848 |
+
x = F.silu(gate) * up
|
| 849 |
+
if weights is not None:
|
| 850 |
+
x = weights * x
|
| 851 |
+
return self.w2(x.to(dtype))
|
| 852 |
+
|
| 853 |
+
|
| 854 |
+
class MoE(nn.Module):
|
| 855 |
+
"""Top-k routed experts plus one shared expert every token goes through. Experts are split
|
| 856 |
+
across ranks, so `self.experts` is None for those another rank owns."""
|
| 857 |
+
|
| 858 |
+
def __init__(self, layer_id: int, args: ModelArgs):
|
| 859 |
+
super().__init__()
|
| 860 |
+
n_routed_experts, n_activated_experts = args.get_moe_config(layer_id)
|
| 861 |
+
self.layer_id = layer_id
|
| 862 |
+
self.dim = args.dim
|
| 863 |
+
assert n_routed_experts % world_size == 0, (
|
| 864 |
+
f"Number of experts must be divisible by world size (world_size={world_size})"
|
| 865 |
+
)
|
| 866 |
+
self.n_routed_experts = n_routed_experts
|
| 867 |
+
self.n_local_experts = n_routed_experts // world_size
|
| 868 |
+
self.n_activated_experts = n_activated_experts
|
| 869 |
+
self.experts_start_idx = rank * self.n_local_experts
|
| 870 |
+
self.experts_end_idx = self.experts_start_idx + self.n_local_experts
|
| 871 |
+
self.gate = Gate(layer_id, args)
|
| 872 |
+
expert_dtype = torch.float4_e2m1fn_x2 if args.expert_dtype == "fp4" else None
|
| 873 |
+
self.experts = nn.ModuleList(
|
| 874 |
+
[
|
| 875 |
+
Expert(
|
| 876 |
+
args.dim,
|
| 877 |
+
args.moe_inter_dim,
|
| 878 |
+
dtype=expert_dtype,
|
| 879 |
+
swiglu_limit=args.swiglu_limit,
|
| 880 |
+
)
|
| 881 |
+
if self.experts_start_idx <= i < self.experts_end_idx
|
| 882 |
+
else None
|
| 883 |
+
for i in range(self.n_routed_experts)
|
| 884 |
+
]
|
| 885 |
+
)
|
| 886 |
+
assert args.n_shared_experts == 1
|
| 887 |
+
self.shared_experts = Expert(args.dim, args.moe_inter_dim, swiglu_limit=args.swiglu_limit)
|
| 888 |
+
|
| 889 |
+
def forward(self, x: torch.Tensor, image_mask: torch.Tensor | None = None) -> torch.Tensor:
|
| 890 |
+
shape = x.size()
|
| 891 |
+
x = x.view(-1, self.dim)
|
| 892 |
+
weights, indices = self.gate(x, None if image_mask is None else image_mask.flatten())
|
| 893 |
+
y = torch.zeros_like(x, dtype=torch.float32)
|
| 894 |
+
counts = torch.bincount(indices.flatten(), minlength=self.n_routed_experts).tolist()
|
| 895 |
+
for i in range(self.experts_start_idx, self.experts_end_idx):
|
| 896 |
+
if counts[i] == 0:
|
| 897 |
+
continue
|
| 898 |
+
expert = self.experts[i]
|
| 899 |
+
idx, top = torch.where(indices == i)
|
| 900 |
+
y[idx] += expert(x[idx], weights[idx, top, None])
|
| 901 |
+
if world_size > 1:
|
| 902 |
+
dist.all_reduce(y)
|
| 903 |
+
y += self.shared_experts(x)
|
| 904 |
+
return y.type_as(x).view(shape)
|
| 905 |
+
|
| 906 |
+
|
| 907 |
+
class Block(nn.Module):
|
| 908 |
+
"""A block whose residual stream is `hc_mult` parallel copies (Hyper-Connections).
|
| 909 |
+
|
| 910 |
+
Attention and FFN each sit between `hc_pre` (collapse the copies into one sublayer input) and
|
| 911 |
+
`hc_post` (expand back out, mixing the residual in through `comb`). `hc_mixes` derives all three
|
| 912 |
+
coefficient sets from the stream itself, `comb` made doubly stochastic by Sinkhorn.
|
| 913 |
+
|
| 914 |
+
The coefficients a sublayer computes are used by the *next* one -- see `forward`.
|
| 915 |
+
"""
|
| 916 |
+
|
| 917 |
+
attention_cls = Attention
|
| 918 |
+
|
| 919 |
+
def __init__(
|
| 920 |
+
self,
|
| 921 |
+
layer_id: int,
|
| 922 |
+
args: ModelArgs,
|
| 923 |
+
engram_layout: EngramLayout | None = None,
|
| 924 |
+
):
|
| 925 |
+
super().__init__()
|
| 926 |
+
self.layer_id = layer_id
|
| 927 |
+
self.norm_eps = args.norm_eps
|
| 928 |
+
self.attn = self.attention_cls(layer_id, args)
|
| 929 |
+
self.ffn = MoE(layer_id, args)
|
| 930 |
+
self.engram = None
|
| 931 |
+
if engram_layout is not None and layer_id in engram_layout.layer_ids:
|
| 932 |
+
self.engram = Engram(args, layer_id, engram_layout)
|
| 933 |
+
self.attn_norm = RMSNorm(args.dim, self.norm_eps)
|
| 934 |
+
self.ffn_norm = RMSNorm(args.dim, self.norm_eps)
|
| 935 |
+
self.hc_mult = hc_mult = args.hc_mult
|
| 936 |
+
self.hc_sinkhorn_iters = args.hc_sinkhorn_iters
|
| 937 |
+
self.hc_eps = args.hc_eps
|
| 938 |
+
mix_hc = (2 + hc_mult) * hc_mult
|
| 939 |
+
hc_dim = hc_mult * args.dim
|
| 940 |
+
with set_dtype(torch.float32):
|
| 941 |
+
self.hc_attn_fn = nn.Parameter(torch.empty(mix_hc, hc_dim))
|
| 942 |
+
self.hc_ffn_fn = nn.Parameter(torch.empty(mix_hc, hc_dim))
|
| 943 |
+
self.hc_attn_base = nn.Parameter(torch.empty(mix_hc))
|
| 944 |
+
self.hc_ffn_base = nn.Parameter(torch.empty(mix_hc))
|
| 945 |
+
self.hc_attn_scale = nn.Parameter(torch.empty(3))
|
| 946 |
+
self.hc_ffn_scale = nn.Parameter(torch.empty(3))
|
| 947 |
+
|
| 948 |
+
def hc_mixes(self, x: torch.Tensor, hc_fn: torch.Tensor, hc_scale: torch.Tensor, hc_base: torch.Tensor):
|
| 949 |
+
"""x: [b,s,hc,d], hc_fn: [mix_hc, hc*d], hc_scale: [3], hc_base: [mix_hc]. Returns the
|
| 950 |
+
pre / post / comb coefficients, split out of one projection of the flattened stream."""
|
| 951 |
+
# normalized over the whole flattened hc*d stream, one statistic per token
|
| 952 |
+
x = x.flatten(2).float()
|
| 953 |
+
rsqrt = torch.rsqrt(x.square().mean(-1, keepdim=True) + self.norm_eps)
|
| 954 |
+
mixes = F.linear(x, hc_fn) * rsqrt
|
| 955 |
+
return hc_split_sinkhorn(mixes, hc_scale, hc_base, self.hc_mult, self.hc_sinkhorn_iters, self.hc_eps)
|
| 956 |
+
|
| 957 |
+
def hc_pre(self, x: torch.Tensor, pre_mix: torch.Tensor):
|
| 958 |
+
"""Collapse the hc copies into one, weighted by pre_mix. [b,s,hc,d] x [b,s,hc] -> [b,s,d]"""
|
| 959 |
+
y = torch.sum(pre_mix.unsqueeze(-1) * x.float(), dim=2)
|
| 960 |
+
return y.to(x.dtype)
|
| 961 |
+
|
| 962 |
+
def hc_post(self, x: torch.Tensor, residual: torch.Tensor, post: torch.Tensor, comb: torch.Tensor):
|
| 963 |
+
"""Expand the sublayer output back to hc copies and mix the residual in through `comb`.
|
| 964 |
+
x: [b,s,d], residual: [b,s,hc,d], post: [b,s,hc], comb: [b,s,hc,hc] -> [b,s,hc,d]"""
|
| 965 |
+
y = post.unsqueeze(-1) * x.unsqueeze(-2) + torch.sum(comb.unsqueeze(-1) * residual.unsqueeze(-2), dim=2)
|
| 966 |
+
return y.type_as(x)
|
| 967 |
+
|
| 968 |
+
def forward(
|
| 969 |
+
self,
|
| 970 |
+
x: torch.Tensor,
|
| 971 |
+
start_pos: int,
|
| 972 |
+
pre_mix: torch.Tensor,
|
| 973 |
+
image_mask: torch.Tensor | None,
|
| 974 |
+
*attn_args,
|
| 975 |
+
) -> tuple[torch.Tensor, torch.Tensor]:
|
| 976 |
+
"""`pre_mix` collapses the hc_mult copies down to one input for this block's attention. Each
|
| 977 |
+
sub-block's own `hc_mixes` produces the mix for the *next* one, so attention uses what the
|
| 978 |
+
previous layer's FFN produced and the FFN uses what this attention produced.
|
| 979 |
+
|
| 980 |
+
image_mask: [b, s] bool, True inside image spans (selects the VL routing bias)."""
|
| 981 |
+
residual = x
|
| 982 |
+
attn_pre, attn_post, attn_comb = self.hc_mixes(x, self.hc_attn_fn, self.hc_attn_scale, self.hc_attn_base)
|
| 983 |
+
x = self.hc_pre(x, pre_mix)
|
| 984 |
+
x = self.attn_norm(x)
|
| 985 |
+
x = self.attn(x, start_pos, *attn_args)
|
| 986 |
+
x = self.hc_post(x, residual, attn_post, attn_comb)
|
| 987 |
+
|
| 988 |
+
residual = x
|
| 989 |
+
ffn_pre, ffn_post, ffn_comb = self.hc_mixes(x, self.hc_ffn_fn, self.hc_ffn_scale, self.hc_ffn_base)
|
| 990 |
+
x = self.hc_pre(x, attn_pre)
|
| 991 |
+
x = self.ffn_norm(x)
|
| 992 |
+
x = self.ffn(x, image_mask)
|
| 993 |
+
x = self.hc_post(x, residual, ffn_post, ffn_comb)
|
| 994 |
+
return x, ffn_pre
|
| 995 |
+
|
| 996 |
+
|
| 997 |
+
class ParallelHead(nn.Module):
|
| 998 |
+
def __init__(self, vocab_size: int, dim: int, norm_eps: float = 1e-6, hc_eps: float = 1e-6):
|
| 999 |
+
super().__init__()
|
| 1000 |
+
self.vocab_size = vocab_size
|
| 1001 |
+
self.dim = dim
|
| 1002 |
+
self.norm_eps = norm_eps
|
| 1003 |
+
self.hc_eps = hc_eps
|
| 1004 |
+
self.part_vocab_size = vocab_size // world_size
|
| 1005 |
+
# bf16 in the checkpoint, kept as fp32 here so the logits come out in fp32 directly
|
| 1006 |
+
self.weight = nn.Parameter(torch.empty(self.part_vocab_size, self.dim, dtype=torch.float32))
|
| 1007 |
+
|
| 1008 |
+
def forward(self, x: torch.Tensor, full_logits=False):
|
| 1009 |
+
"""x: [b, s, d]. Generation only needs the last position, so that is the default."""
|
| 1010 |
+
if not full_logits:
|
| 1011 |
+
x = x[:, -1]
|
| 1012 |
+
logits = F.linear(x.float(), self.weight)
|
| 1013 |
+
if world_size > 1:
|
| 1014 |
+
all_logits = [torch.empty_like(logits) for _ in range(world_size)]
|
| 1015 |
+
dist.all_gather(all_logits, logits)
|
| 1016 |
+
logits = torch.cat(all_logits, dim=-1)
|
| 1017 |
+
return logits
|
| 1018 |
+
|
| 1019 |
+
|
| 1020 |
+
@lru_cache(1)
|
| 1021 |
+
def get_dspark_topk_idxs(window_size: int, bsz: int, block_size: int, start_pos: int):
|
| 1022 |
+
assert start_pos > 0
|
| 1023 |
+
matrix = torch.cat(
|
| 1024 |
+
[
|
| 1025 |
+
torch.arange(min(window_size, start_pos + 1)),
|
| 1026 |
+
window_size + torch.arange(block_size),
|
| 1027 |
+
]
|
| 1028 |
+
)
|
| 1029 |
+
return matrix.int().view(1, 1, -1).expand(bsz, block_size, -1).contiguous()
|
| 1030 |
+
|
| 1031 |
+
|
| 1032 |
+
class DSparkAttention(Attention):
|
| 1033 |
+
def forward(self, x: torch.Tensor, start_pos: int, main_x: torch.Tensor):
|
| 1034 |
+
assert self.compress_ratio == 0
|
| 1035 |
+
bsz, seqlen, _ = main_x.size()
|
| 1036 |
+
win = self.window_size
|
| 1037 |
+
rd = self.rope_head_dim
|
| 1038 |
+
|
| 1039 |
+
main_freqs_cis = self.freqs_cis[start_pos : start_pos + seqlen]
|
| 1040 |
+
main_kv = self.kv_norm(self.wkv(main_x))
|
| 1041 |
+
apply_rotary_emb(main_kv[..., -rd:], main_freqs_cis)
|
| 1042 |
+
act_quant(main_kv, fp8_block_size, scale_fmt, scale_dtype, True)
|
| 1043 |
+
|
| 1044 |
+
if start_pos == 0:
|
| 1045 |
+
if seqlen <= win:
|
| 1046 |
+
self.window_kv_cache[:bsz, :seqlen] = main_kv
|
| 1047 |
+
else:
|
| 1048 |
+
cutoff = seqlen % win
|
| 1049 |
+
self.window_kv_cache[:bsz, cutoff:win], self.window_kv_cache[:bsz, :cutoff] = main_kv[:, -win:].split(
|
| 1050 |
+
[win - cutoff, cutoff], dim=1
|
| 1051 |
+
)
|
| 1052 |
+
return x
|
| 1053 |
+
|
| 1054 |
+
bsz, block_size, _ = x.size()
|
| 1055 |
+
freqs_cis = self.freqs_cis[start_pos + seqlen : start_pos + seqlen + block_size]
|
| 1056 |
+
|
| 1057 |
+
qr = self.q_norm(self.wq_a(x))
|
| 1058 |
+
q = self.wq_b(qr).unflatten(-1, (self.n_local_heads, self.head_dim))
|
| 1059 |
+
apply_rotary_emb(q[..., -rd:], freqs_cis)
|
| 1060 |
+
kv = self.kv_norm(self.wkv(x))
|
| 1061 |
+
apply_rotary_emb(kv[..., -rd:], freqs_cis)
|
| 1062 |
+
act_quant(kv, fp8_block_size, scale_fmt, scale_dtype, True)
|
| 1063 |
+
|
| 1064 |
+
topk_idxs = get_dspark_topk_idxs(win, bsz, block_size, start_pos)
|
| 1065 |
+
self.window_kv_cache[:bsz, start_pos % win] = main_kv.squeeze(1)
|
| 1066 |
+
kv = torch.cat([self.window_kv_cache[:bsz], kv], dim=1)
|
| 1067 |
+
o = sparse_attn(q, kv, self.attn_sink, topk_idxs, self.softmax_scale)
|
| 1068 |
+
apply_rotary_emb(o[..., -rd:], freqs_cis, True)
|
| 1069 |
+
|
| 1070 |
+
o = o.view(bsz, block_size, self.n_local_groups, -1)
|
| 1071 |
+
wo_a = self.wo_a.weight.view(self.n_local_groups, self.o_lora_rank, -1)
|
| 1072 |
+
o = torch.einsum("bsgd,grd->bsgr", o, wo_a)
|
| 1073 |
+
x = self.wo_b(o.flatten(2))
|
| 1074 |
+
return x
|
| 1075 |
+
|
| 1076 |
+
|
| 1077 |
+
class DSparkMarkovHead(nn.Module):
|
| 1078 |
+
def __init__(self, vocab_size: int, dspark_markov_rank: int):
|
| 1079 |
+
super().__init__()
|
| 1080 |
+
self.embed = ParallelEmbedding(vocab_size, dspark_markov_rank)
|
| 1081 |
+
self.head = ParallelHead(vocab_size, dspark_markov_rank)
|
| 1082 |
+
|
| 1083 |
+
def forward(self, token_ids: torch.Tensor) -> tuple[torch.Tensor, torch.Tensor]:
|
| 1084 |
+
embed = self.embed(token_ids)
|
| 1085 |
+
logits = self.head(embed, full_logits=True)
|
| 1086 |
+
return logits, embed
|
| 1087 |
+
|
| 1088 |
+
|
| 1089 |
+
class DSparkConfidenceHead(nn.Module):
|
| 1090 |
+
def __init__(self, input_dim: int):
|
| 1091 |
+
super().__init__()
|
| 1092 |
+
# proj in the checkpoint is stored in bf16, while the parameter here is stored in fp32 for fp32 confidence score.
|
| 1093 |
+
self.proj = Linear(input_dim, 1, dtype=torch.float32)
|
| 1094 |
+
|
| 1095 |
+
def forward(self, hidden: torch.Tensor, markov_embed: torch.Tensor):
|
| 1096 |
+
hidden = torch.cat([hidden, markov_embed], dim=-1)
|
| 1097 |
+
return self.proj(hidden.float()).squeeze(-1)
|
| 1098 |
+
|
| 1099 |
+
|
| 1100 |
+
class DSparkBlock(Block):
|
| 1101 |
+
"""DSpark stage stored under the mtp.* checkpoint namespace."""
|
| 1102 |
+
|
| 1103 |
+
attention_cls = DSparkAttention
|
| 1104 |
+
|
| 1105 |
+
def __init__(self, layer_id: int, args: ModelArgs):
|
| 1106 |
+
super().__init__(layer_id, args)
|
| 1107 |
+
stage_id = layer_id - args.n_layers
|
| 1108 |
+
self.block_size = args.dspark_block_size
|
| 1109 |
+
self.noise_token_id = args.dspark_noise_token_id
|
| 1110 |
+
self.temperature = args.temperature
|
| 1111 |
+
if stage_id == 0:
|
| 1112 |
+
assert len(args.dspark_target_layer_ids) > 0, "DSpark needs target layers"
|
| 1113 |
+
self.main_proj = Linear(args.dim * len(args.dspark_target_layer_ids), args.dim)
|
| 1114 |
+
self.main_norm = RMSNorm(args.dim, args.norm_eps)
|
| 1115 |
+
if stage_id == args.n_mtp_layers - 1:
|
| 1116 |
+
self.norm = RMSNorm(args.dim, args.norm_eps)
|
| 1117 |
+
self.markov_head = DSparkMarkovHead(args.vocab_size, args.dspark_markov_rank)
|
| 1118 |
+
self.confidence_head = DSparkConfidenceHead(args.dim + args.dspark_markov_rank)
|
| 1119 |
+
self.embed: ParallelEmbedding | None = None
|
| 1120 |
+
self.head: ParallelHead | None = None
|
| 1121 |
+
|
| 1122 |
+
def forward(self, x: torch.Tensor, start_pos: int, pre_mix: torch.Tensor, main_x: torch.Tensor):
|
| 1123 |
+
if start_pos == 0:
|
| 1124 |
+
self.attn(x, start_pos, main_x) # prefill only seeds the window KV cache
|
| 1125 |
+
return x, pre_mix
|
| 1126 |
+
return super().forward(x, start_pos, pre_mix, None, main_x) # drafts are text: no VL bias
|
| 1127 |
+
|
| 1128 |
+
def forward_embed(self, main_hidden: torch.Tensor, input_ids: torch.Tensor):
|
| 1129 |
+
assert self.embed is not None
|
| 1130 |
+
main_x = self.main_norm(self.main_proj(main_hidden))
|
| 1131 |
+
draft_input_ids = input_ids.new_full([input_ids.size(0), self.block_size], self.noise_token_id)
|
| 1132 |
+
draft_input_ids[:, 0] = input_ids
|
| 1133 |
+
x = self.embed(draft_input_ids)
|
| 1134 |
+
x = x.unsqueeze(2).repeat(1, 1, self.hc_mult, 1)
|
| 1135 |
+
return x, main_x
|
| 1136 |
+
|
| 1137 |
+
def forward_head(
|
| 1138 |
+
self,
|
| 1139 |
+
x: torch.Tensor,
|
| 1140 |
+
pre_mix: torch.Tensor,
|
| 1141 |
+
input_ids: torch.Tensor,
|
| 1142 |
+
) -> tuple[torch.Tensor, torch.Tensor, torch.Tensor]:
|
| 1143 |
+
assert self.head is not None
|
| 1144 |
+
x = self.hc_pre(x, pre_mix)
|
| 1145 |
+
logits = self.head(self.norm(x), full_logits=True)
|
| 1146 |
+
output_ids = input_ids.new_empty(input_ids.size(0), self.block_size + 1)
|
| 1147 |
+
output_ids[:, 0] = input_ids
|
| 1148 |
+
markov_embeds = []
|
| 1149 |
+
for i in range(self.block_size):
|
| 1150 |
+
logits_bias, markov_embed = self.markov_head(output_ids[:, i])
|
| 1151 |
+
logits[:, i].add_(logits_bias)
|
| 1152 |
+
markov_embeds.append(markov_embed)
|
| 1153 |
+
output_ids[:, i + 1] = sample(logits[:, i], self.temperature)
|
| 1154 |
+
markov_embed = torch.stack(markov_embeds, dim=1)
|
| 1155 |
+
confidence = self.confidence_head(x, markov_embed)
|
| 1156 |
+
return output_ids, logits, confidence
|
| 1157 |
+
|
| 1158 |
+
|
| 1159 |
+
def make_identity_pre_mix(x: torch.Tensor, hc_mult: int) -> torch.Tensor:
|
| 1160 |
+
"""initial one-hot mix"""
|
| 1161 |
+
pre_mix = x.new_zeros(x.size(0), x.size(1), hc_mult, dtype=torch.float32)
|
| 1162 |
+
pre_mix[:, :, 0] = 1.0
|
| 1163 |
+
return pre_mix
|
| 1164 |
+
|
| 1165 |
+
|
| 1166 |
+
class SharedAttentionRuntime:
|
| 1167 |
+
"""What attention layers hand down the stack instead of recomputing. Layers run in order and
|
| 1168 |
+
every source writes before its consumers read, so one slot each is enough and nothing needs
|
| 1169 |
+
resetting between forwards. Sources: compress_kv and index_k from kv_source_layers, topk_idxs
|
| 1170 |
+
from index_source_layers, candidates from candidate_source_layer."""
|
| 1171 |
+
|
| 1172 |
+
def __init__(self):
|
| 1173 |
+
self.compress_kv: torch.Tensor | None = None
|
| 1174 |
+
self.index_k: torch.Tensor | None = None
|
| 1175 |
+
self.topk_idxs: torch.Tensor | None = None
|
| 1176 |
+
self.candidates: torch.Tensor | None = None
|
| 1177 |
+
|
| 1178 |
+
|
| 1179 |
+
# Only ever one model per process, same as world_size / rank / default_dtype above.
|
| 1180 |
+
shared_attn = SharedAttentionRuntime()
|
| 1181 |
+
|
| 1182 |
+
|
| 1183 |
+
class Transformer(nn.Module):
|
| 1184 |
+
"""DeepSeek-V4.1: embed -> expand to hc_mult copies -> blocks -> collapse -> logits. Building
|
| 1185 |
+
this sets the globals at the top of the file. The tokenizer only feeds the engram token map."""
|
| 1186 |
+
|
| 1187 |
+
def __init__(self, args: ModelArgs, tokenizer=None):
|
| 1188 |
+
global world_size, rank, default_dtype
|
| 1189 |
+
world_size = dist.get_world_size() if dist.is_initialized() else 1
|
| 1190 |
+
rank = dist.get_rank() if dist.is_initialized() else 0
|
| 1191 |
+
default_dtype = torch.float8_e4m3fn if args.dtype == "fp8" else torch.bfloat16
|
| 1192 |
+
super().__init__()
|
| 1193 |
+
self.max_seq_len = args.max_seq_len
|
| 1194 |
+
self.temperature = args.temperature
|
| 1195 |
+
self.norm_eps = args.norm_eps
|
| 1196 |
+
self.hc_eps = args.hc_eps
|
| 1197 |
+
self.engram_layout = EngramLayout.from_args(args)
|
| 1198 |
+
self.engram_hash = (
|
| 1199 |
+
NgramHashState(args, self.engram_layout, tokenizer) if self.engram_layout is not None else None
|
| 1200 |
+
)
|
| 1201 |
+
self.embed = ParallelEmbedding(args.vocab_size, args.dim)
|
| 1202 |
+
self.layers = torch.nn.ModuleList()
|
| 1203 |
+
for layer_id in range(args.n_layers):
|
| 1204 |
+
self.layers.append(Block(layer_id, args, self.engram_layout))
|
| 1205 |
+
self.norm = RMSNorm(args.dim, self.norm_eps)
|
| 1206 |
+
self.head = ParallelHead(args.vocab_size, args.dim, self.norm_eps, self.hc_eps)
|
| 1207 |
+
self.mtp = torch.nn.ModuleList()
|
| 1208 |
+
self.target_layer_ids = args.dspark_target_layer_ids
|
| 1209 |
+
if args.dspark_block_size:
|
| 1210 |
+
for layer_id in range(args.n_mtp_layers):
|
| 1211 |
+
self.mtp.append(DSparkBlock(args.n_layers + layer_id, args))
|
| 1212 |
+
self.mtp[-1].embed = self.embed
|
| 1213 |
+
self.mtp[-1].head = self.head
|
| 1214 |
+
self.hc_mult = args.hc_mult
|
| 1215 |
+
self.vision = None
|
| 1216 |
+
if args.vision_enabled:
|
| 1217 |
+
self.vision = ViT(args)
|
| 1218 |
+
self.aligner = Aligner(args)
|
| 1219 |
+
# learned embeddings for the image span delimiters
|
| 1220 |
+
self.image_start = nn.Parameter(torch.empty(args.dim))
|
| 1221 |
+
self.image_end = nn.Parameter(torch.empty(args.dim))
|
| 1222 |
+
self.image_newline = nn.Parameter(torch.empty(args.dim))
|
| 1223 |
+
|
| 1224 |
+
@torch.inference_mode()
|
| 1225 |
+
def encode_image(self, patches: torch.Tensor, n_vit_h: int, n_vit_w: int) -> torch.Tensor:
|
| 1226 |
+
return self.aligner(self.vision(patches, n_vit_h, n_vit_w), n_vit_h, n_vit_w)
|
| 1227 |
+
|
| 1228 |
+
def merge_image_embeddings(self, images, h: torch.Tensor):
|
| 1229 |
+
"""Overwrite each image's token span in h with its ViT/aligner features. The IMAGE slots take
|
| 1230 |
+
the aligner rows in row-major order; the span delimiters take learned embeddings."""
|
| 1231 |
+
for i, sample in enumerate(images):
|
| 1232 |
+
for img in sample or ():
|
| 1233 |
+
types = img.types.to(h.device)
|
| 1234 |
+
span = h[i, img.start : img.start + types.numel()]
|
| 1235 |
+
span[types == IMAGE_START] = self.image_start.to(h.dtype)
|
| 1236 |
+
span[types == IMAGE_END] = self.image_end.to(h.dtype)
|
| 1237 |
+
span[types == IMAGE_NEW_LINE] = self.image_newline.to(h.dtype)
|
| 1238 |
+
embeds = self.encode_image(img.patches.to(h.device), img.n_vit_h, img.n_vit_w)
|
| 1239 |
+
span[types == IMAGE] = embeds.to(h.dtype)
|
| 1240 |
+
|
| 1241 |
+
@torch.inference_mode()
|
| 1242 |
+
def forward(
|
| 1243 |
+
self, input_ids: torch.Tensor, start_pos: int = 0, images=None, token_types: torch.Tensor | None = None
|
| 1244 |
+
):
|
| 1245 |
+
"""input_ids: [b, s], every entry a real token id -- generate.py only ever passes positions it
|
| 1246 |
+
has already filled, so the padding it uses internally never reaches here. token_types /
|
| 1247 |
+
images carry the VL inputs built by image_processor.prepare_vl_inputs; image spans must lie
|
| 1248 |
+
inside the first (start_pos 0) chunk."""
|
| 1249 |
+
image_mask = None if token_types is None else token_types >= 0 # TEXT is -1
|
| 1250 |
+
# image tokens take no part in an n-gram and get no engram contribution; text-only needs no mask
|
| 1251 |
+
engram_mask = None if image_mask is None else ~image_mask
|
| 1252 |
+
engram_hashes = self.engram_hash(input_ids, start_pos, engram_mask) if self.engram_hash is not None else None
|
| 1253 |
+
h = self.embed(input_ids)
|
| 1254 |
+
if images is not None:
|
| 1255 |
+
assert start_pos == 0, "image spans must be prefilled in a single chunk"
|
| 1256 |
+
self.merge_image_embeddings(images, h)
|
| 1257 |
+
# Expand to hc_mult copies for Hyper-Connections
|
| 1258 |
+
h = h.unsqueeze(2).repeat(1, 1, self.hc_mult, 1)
|
| 1259 |
+
main_hiddens = []
|
| 1260 |
+
pre_mix = make_identity_pre_mix(h, self.hc_mult)
|
| 1261 |
+
for i, layer in enumerate(self.layers):
|
| 1262 |
+
if layer.engram is not None:
|
| 1263 |
+
h = layer.engram(h, engram_hashes[:, :, layer.engram.layer_hash_index, :], engram_mask)
|
| 1264 |
+
# the MTP head reads the attention input of its target layers, not their output
|
| 1265 |
+
if i in self.target_layer_ids:
|
| 1266 |
+
main_hiddens.append(h.mean(dim=2))
|
| 1267 |
+
h, pre_mix = layer(h, start_pos, pre_mix, image_mask)
|
| 1268 |
+
h = layer.hc_pre(h, pre_mix)
|
| 1269 |
+
logits = self.head(self.norm(h))
|
| 1270 |
+
output_ids = sample(logits, self.temperature)
|
| 1271 |
+
main_hidden = torch.cat(main_hiddens, dim=-1) if main_hiddens else None
|
| 1272 |
+
return output_ids, logits, main_hidden
|
| 1273 |
+
|
| 1274 |
+
@torch.inference_mode()
|
| 1275 |
+
def forward_spec(self, input_ids: torch.Tensor, main_hidden: torch.Tensor, start_pos: int = 0):
|
| 1276 |
+
h, main_x = self.mtp[0].forward_embed(main_hidden, input_ids)
|
| 1277 |
+
pre_mix = make_identity_pre_mix(h, self.hc_mult)
|
| 1278 |
+
for layer in self.mtp:
|
| 1279 |
+
h, pre_mix = layer(h, start_pos, pre_mix, main_x)
|
| 1280 |
+
if start_pos == 0:
|
| 1281 |
+
return None
|
| 1282 |
+
return self.mtp[-1].forward_head(h, pre_mix, input_ids)
|
| 1283 |
+
|
| 1284 |
+
|
| 1285 |
+
def sample(logits, temperature: float = 1.0):
|
| 1286 |
+
"""Gumbel-max trick: equivalent to multinomial sampling but faster on GPU,
|
| 1287 |
+
since it avoids the GPU-to-CPU sync in torch.multinomial."""
|
| 1288 |
+
if temperature == 0:
|
| 1289 |
+
return logits.argmax(dim=-1)
|
| 1290 |
+
logits = logits / max(temperature, 1e-5)
|
| 1291 |
+
probs = torch.softmax(logits, dim=-1, dtype=torch.float32)
|
| 1292 |
+
return probs.div_(torch.empty_like(probs).exponential_(1)).argmax(dim=-1)
|
| 1293 |
+
|
| 1294 |
+
|
| 1295 |
+
if __name__ == "__main__":
|
| 1296 |
+
torch.set_default_dtype(torch.bfloat16)
|
| 1297 |
+
torch.set_default_device("cuda")
|
| 1298 |
+
torch.manual_seed(0)
|
| 1299 |
+
args = ModelArgs(dspark_block_size=6, dspark_target_layer_ids=(3, 4))
|
| 1300 |
+
x = torch.randint(0, args.vocab_size, (2, 150))
|
| 1301 |
+
model = Transformer(args)
|
| 1302 |
+
|
| 1303 |
+
output_ids, logits, main_hidden = model(x[:, :128])
|
| 1304 |
+
model.forward_spec(output_ids, main_hidden)
|
| 1305 |
+
for i in range(128, 150):
|
| 1306 |
+
output_ids, logits, main_hidden = model(x[:, i : i + 1], i)
|
| 1307 |
+
result = model.forward_spec(output_ids, main_hidden, i)
|
| 1308 |
+
assert result is not None
|
| 1309 |
+
output_ids, logits, confidence = result
|
inference/requirements.txt
ADDED
|
@@ -0,0 +1,9 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
torch>=2.10.0
|
| 2 |
+
transformers
|
| 3 |
+
tokenizers
|
| 4 |
+
safetensors>=0.7.0
|
| 5 |
+
numpy
|
| 6 |
+
sympy
|
| 7 |
+
Pillow
|
| 8 |
+
tilelang==0.1.8
|
| 9 |
+
tqdm
|
inference/run.sh
ADDED
|
@@ -0,0 +1,54 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
#!/usr/bin/env bash
|
| 2 |
+
#
|
| 3 |
+
# Run the reference inference on a converted checkpoint.
|
| 4 |
+
#
|
| 5 |
+
# ./run.sh /path/to/DeepSeek-V4.1-Exp-TP8
|
| 6 |
+
# ./run.sh /path/to/DeepSeek-V4.1-Exp-TP8 examples/example_harmony.json
|
| 7 |
+
# MP=4 ./run.sh /path/to/DeepSeek-V4.1-Exp-TP4
|
| 8 |
+
#
|
| 9 |
+
# Paths inside an example are resolved from this directory, so run it from anywhere.
|
| 10 |
+
|
| 11 |
+
set -euo pipefail
|
| 12 |
+
cd "$(dirname "$0")"
|
| 13 |
+
|
| 14 |
+
CKPT_PATH="${1:-${CKPT_PATH:-}}"
|
| 15 |
+
INPUT_FILE="${2:-${INPUT_FILE:-examples/example_harmony.json}}"
|
| 16 |
+
MP="${MP:-8}"
|
| 17 |
+
CONFIG="${CONFIG:-config.json}"
|
| 18 |
+
|
| 19 |
+
usage() {
|
| 20 |
+
echo "usage: $0 <checkpoint-dir> [input-file]" >&2
|
| 21 |
+
echo >&2
|
| 22 |
+
echo " checkpoint-dir holds model0-mp${MP}.safetensors .. model$((MP - 1))-mp${MP}.safetensors," >&2
|
| 23 |
+
echo " as produced by convert.py --model-parallel ${MP}" >&2
|
| 24 |
+
echo " input-file TXT or JSON prompts (default: examples/example.txt)" >&2
|
| 25 |
+
echo >&2
|
| 26 |
+
echo " MP=${MP} CONFIG=${CONFIG} override with environment variables" >&2
|
| 27 |
+
exit 1
|
| 28 |
+
}
|
| 29 |
+
|
| 30 |
+
[ -n "${CKPT_PATH}" ] || usage
|
| 31 |
+
|
| 32 |
+
if [ ! -d "${CKPT_PATH}" ]; then
|
| 33 |
+
echo "error: checkpoint directory not found: ${CKPT_PATH}" >&2
|
| 34 |
+
usage
|
| 35 |
+
fi
|
| 36 |
+
|
| 37 |
+
missing=0
|
| 38 |
+
for rank in $(seq 0 $((MP - 1))); do
|
| 39 |
+
if [ ! -f "${CKPT_PATH}/model${rank}-mp${MP}.safetensors" ]; then
|
| 40 |
+
missing=$((missing + 1))
|
| 41 |
+
fi
|
| 42 |
+
done
|
| 43 |
+
if [ "${missing}" -ne 0 ]; then
|
| 44 |
+
echo "error: ${CKPT_PATH} is missing ${missing} of the ${MP} shards MP=${MP} needs" >&2
|
| 45 |
+
echo " expected model0-mp${MP}.safetensors .. model$((MP - 1))-mp${MP}.safetensors" >&2
|
| 46 |
+
usage
|
| 47 |
+
fi
|
| 48 |
+
|
| 49 |
+
[ -f "${INPUT_FILE}" ] || { echo "error: input file not found: ${INPUT_FILE}" >&2; usage; }
|
| 50 |
+
|
| 51 |
+
torchrun --nproc-per-node "${MP}" generate.py \
|
| 52 |
+
--ckpt-path "${CKPT_PATH}" \
|
| 53 |
+
--config "${CONFIG}" \
|
| 54 |
+
--input-file "${INPUT_FILE}"
|
inference/vision.py
ADDED
|
@@ -0,0 +1,119 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
from functools import lru_cache
|
| 2 |
+
|
| 3 |
+
import torch
|
| 4 |
+
import torch.nn.functional as F
|
| 5 |
+
from torch import nn
|
| 6 |
+
|
| 7 |
+
|
| 8 |
+
@lru_cache(8)
|
| 9 |
+
def get_vision_cos_sin(n_h: int, n_w: int, dim: int, theta: float):
|
| 10 |
+
inv_freq = 1.0 / (theta ** (torch.arange(0, dim, 2, dtype=torch.float32) / dim))
|
| 11 |
+
hpos = torch.arange(n_h).unsqueeze(1).expand(n_h, n_w)
|
| 12 |
+
wpos = torch.arange(n_w).unsqueeze(0).expand(n_h, n_w)
|
| 13 |
+
freqs = torch.stack([hpos, wpos], dim=-1).reshape(-1, 2, 1).float() * inv_freq
|
| 14 |
+
freqs = freqs.flatten(1)
|
| 15 |
+
return freqs.cos().unsqueeze(1), freqs.sin().unsqueeze(1)
|
| 16 |
+
|
| 17 |
+
|
| 18 |
+
def apply_rotary(x: torch.Tensor, cos: torch.Tensor, sin: torch.Tensor) -> torch.Tensor:
|
| 19 |
+
dtype = x.dtype
|
| 20 |
+
x1, x2 = x.float().chunk(2, dim=-1)
|
| 21 |
+
return torch.cat([x1 * cos - x2 * sin, x2 * cos + x1 * sin], dim=-1).to(dtype)
|
| 22 |
+
|
| 23 |
+
|
| 24 |
+
class RMSNorm(nn.Module):
|
| 25 |
+
def __init__(self, dim: int, eps: float = 1e-6):
|
| 26 |
+
super().__init__()
|
| 27 |
+
self.eps = eps
|
| 28 |
+
self.weight = nn.Parameter(torch.ones(dim, dtype=torch.float32))
|
| 29 |
+
|
| 30 |
+
def forward(self, x: torch.Tensor) -> torch.Tensor:
|
| 31 |
+
dtype = x.dtype
|
| 32 |
+
x = x.float()
|
| 33 |
+
x = x * torch.rsqrt(x.square().mean(-1, keepdim=True) + self.eps)
|
| 34 |
+
return (self.weight * x).to(dtype)
|
| 35 |
+
|
| 36 |
+
|
| 37 |
+
class PatchEmbed(nn.Module):
|
| 38 |
+
def __init__(self, args):
|
| 39 |
+
super().__init__()
|
| 40 |
+
self.proj = nn.Linear(3 * args.vision_patch_size**2, args.vision_dim)
|
| 41 |
+
|
| 42 |
+
def forward(self, x: torch.Tensor) -> torch.Tensor:
|
| 43 |
+
return self.proj(x.flatten(1))
|
| 44 |
+
|
| 45 |
+
|
| 46 |
+
class Attention(nn.Module):
|
| 47 |
+
def __init__(self, args):
|
| 48 |
+
super().__init__()
|
| 49 |
+
self.n_heads = args.vision_n_heads
|
| 50 |
+
self.head_dim = args.vision_dim // args.vision_n_heads
|
| 51 |
+
self.wqkv = nn.Linear(args.vision_dim, 3 * args.vision_dim)
|
| 52 |
+
self.wo = nn.Linear(args.vision_dim, args.vision_dim)
|
| 53 |
+
|
| 54 |
+
def forward(self, x: torch.Tensor, cos: torch.Tensor, sin: torch.Tensor) -> torch.Tensor:
|
| 55 |
+
n = x.size(0)
|
| 56 |
+
q, k, v = (t.view(n, self.n_heads, self.head_dim) for t in self.wqkv(x).chunk(3, dim=-1))
|
| 57 |
+
q = apply_rotary(q, cos, sin)
|
| 58 |
+
k = apply_rotary(k, cos, sin)
|
| 59 |
+
o = F.scaled_dot_product_attention(q.transpose(0, 1), k.transpose(0, 1), v.transpose(0, 1))
|
| 60 |
+
return self.wo(o.transpose(0, 1).reshape(n, -1))
|
| 61 |
+
|
| 62 |
+
|
| 63 |
+
class MLP(nn.Module):
|
| 64 |
+
def __init__(self, args):
|
| 65 |
+
super().__init__()
|
| 66 |
+
self.w1 = nn.Linear(args.vision_dim, 2 * args.vision_inter_dim, bias=False)
|
| 67 |
+
self.w2 = nn.Linear(args.vision_inter_dim, args.vision_dim, bias=False)
|
| 68 |
+
|
| 69 |
+
def forward(self, x: torch.Tensor) -> torch.Tensor:
|
| 70 |
+
gate, up = self.w1(x).chunk(2, dim=-1)
|
| 71 |
+
return self.w2(F.silu(gate) * up)
|
| 72 |
+
|
| 73 |
+
|
| 74 |
+
class Block(nn.Module):
|
| 75 |
+
def __init__(self, args):
|
| 76 |
+
super().__init__()
|
| 77 |
+
self.norm1 = RMSNorm(args.vision_dim)
|
| 78 |
+
self.attn = Attention(args)
|
| 79 |
+
self.norm2 = RMSNorm(args.vision_dim)
|
| 80 |
+
self.mlp = MLP(args)
|
| 81 |
+
|
| 82 |
+
def forward(self, x: torch.Tensor, cos: torch.Tensor, sin: torch.Tensor) -> torch.Tensor:
|
| 83 |
+
x = x + self.attn(self.norm1(x), cos, sin)
|
| 84 |
+
return x + self.mlp(self.norm2(x))
|
| 85 |
+
|
| 86 |
+
|
| 87 |
+
class ViT(nn.Module):
|
| 88 |
+
"""DeepSeek ViT: full bidirectional attention over one image with 2D RoPE."""
|
| 89 |
+
|
| 90 |
+
def __init__(self, args):
|
| 91 |
+
super().__init__()
|
| 92 |
+
self.rope_dim = args.vision_dim // args.vision_n_heads // 2
|
| 93 |
+
self.rope_theta = args.vision_rope_theta
|
| 94 |
+
self.patch_embed = PatchEmbed(args)
|
| 95 |
+
self.blocks = nn.ModuleList([Block(args) for _ in range(args.vision_n_layers)])
|
| 96 |
+
self.norm = RMSNorm(args.vision_dim)
|
| 97 |
+
|
| 98 |
+
def forward(self, patches: torch.Tensor, n_h: int, n_w: int) -> torch.Tensor:
|
| 99 |
+
x = self.patch_embed(patches)
|
| 100 |
+
cos, sin = get_vision_cos_sin(n_h, n_w, self.rope_dim, self.rope_theta)
|
| 101 |
+
for block in self.blocks:
|
| 102 |
+
x = block(x, cos, sin)
|
| 103 |
+
return self.norm(x)
|
| 104 |
+
|
| 105 |
+
|
| 106 |
+
class Aligner(nn.Module):
|
| 107 |
+
def __init__(self, args):
|
| 108 |
+
super().__init__()
|
| 109 |
+
self.downsample_ratio = args.vision_downsample_ratio
|
| 110 |
+
in_dim = args.vision_dim * self.downsample_ratio**2
|
| 111 |
+
self.w1 = nn.Linear(in_dim, args.dim)
|
| 112 |
+
self.w2 = nn.Linear(args.dim, args.dim)
|
| 113 |
+
|
| 114 |
+
def forward(self, x: torch.Tensor, n_h: int, n_w: int) -> torch.Tensor:
|
| 115 |
+
r = self.downsample_ratio
|
| 116 |
+
x = x.view(n_h, n_w, -1).permute(2, 0, 1)
|
| 117 |
+
x = F.pad(x, (0, -n_w % r, 0, -n_h % r))
|
| 118 |
+
x = F.unfold(x.unsqueeze(0), r, stride=r).squeeze(0).transpose(0, 1)
|
| 119 |
+
return self.w2(F.gelu(self.w1(x)))
|
model-00001-of-00048.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:886aebdafa08cc27bbae2165ed35bdfe0de9370bf88c1411283c155c6ae4ff89
|
| 3 |
+
size 970533624
|
model-00002-of-00048.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:4320066fc6958e5bc01d8c3feba79b7454b59f0f4b7299ab7145ed44bbf4ecec
|
| 3 |
+
size 1323858272
|
model-00003-of-00048.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:e1281f85d0ce4a3dfb63d41926fc4a47fa71f36ba20992e3597e702ead49d4c9
|
| 3 |
+
size 7389759032
|
model-00004-of-00048.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:79456c9db0cda3b8115fe1c726fe3db1a34b434584a3991917088a0ab56a39de
|
| 3 |
+
size 7389759032
|
model-00005-of-00048.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:4a42dc78698bee6b1a821aa01c9650749ef1f716143751f1cdb815c6400280a9
|
| 3 |
+
size 7405953784
|
model-00006-of-00048.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:020a6df51a2853452561d91268a65481f7a7d7954ed47f8e6c9ce69a4a134f77
|
| 3 |
+
size 7389759032
|
model-00007-of-00048.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:40f8b52f763f6380d41257e1af04eee3aad300af6a418c38e49ff99e3604163a
|
| 3 |
+
size 7389759032
|
model-00008-of-00048.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:d62cca4e698f030d4b96ec624c08bed7ad604cec13077da6d6b06669281c4650
|
| 3 |
+
size 7389759032
|
model-00009-of-00048.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:1ca62e4c294df31aee69a782974cb14269264fdc08465ab4835760258f05d6ef
|
| 3 |
+
size 7389759032
|
model-00010-of-00048.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:dd33c9750a40cbfcdfb19cd8335d955f533e3a18b790c0ee43d1e5d77911595c
|
| 3 |
+
size 7389759032
|
model-00011-of-00048.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:a9b309f90e0d1e2252a224ed6b057b9c82c27d3a49cff64bfbfef12efd067f7c
|
| 3 |
+
size 7405953784
|
model-00012-of-00048.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:b359227eceb3f839c80de19dddf946648ca89425d9b719ff44702cf5e8cfbe0e
|
| 3 |
+
size 7389759032
|
model-00013-of-00048.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:41d87a4c81fec1550f9cb975db05598a18ee0161c2664e8e1a0c7b60742755a6
|
| 3 |
+
size 7389761368
|