


Upload 6 files
Browse files- .gitattributes +5 -0
- ovis_blog_table2.pdf +3 -0
- ovis_blog_table2.png +3 -0
- ovis_embedding_data_centric.png +3 -0
- ovis_embedding_model_architecture.png +3 -0
- ovis_embedding_train_inference.png +3 -0
- vl-9b.md +123 -0
.gitattributes
CHANGED
|
@@ -33,3 +33,8 @@ saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
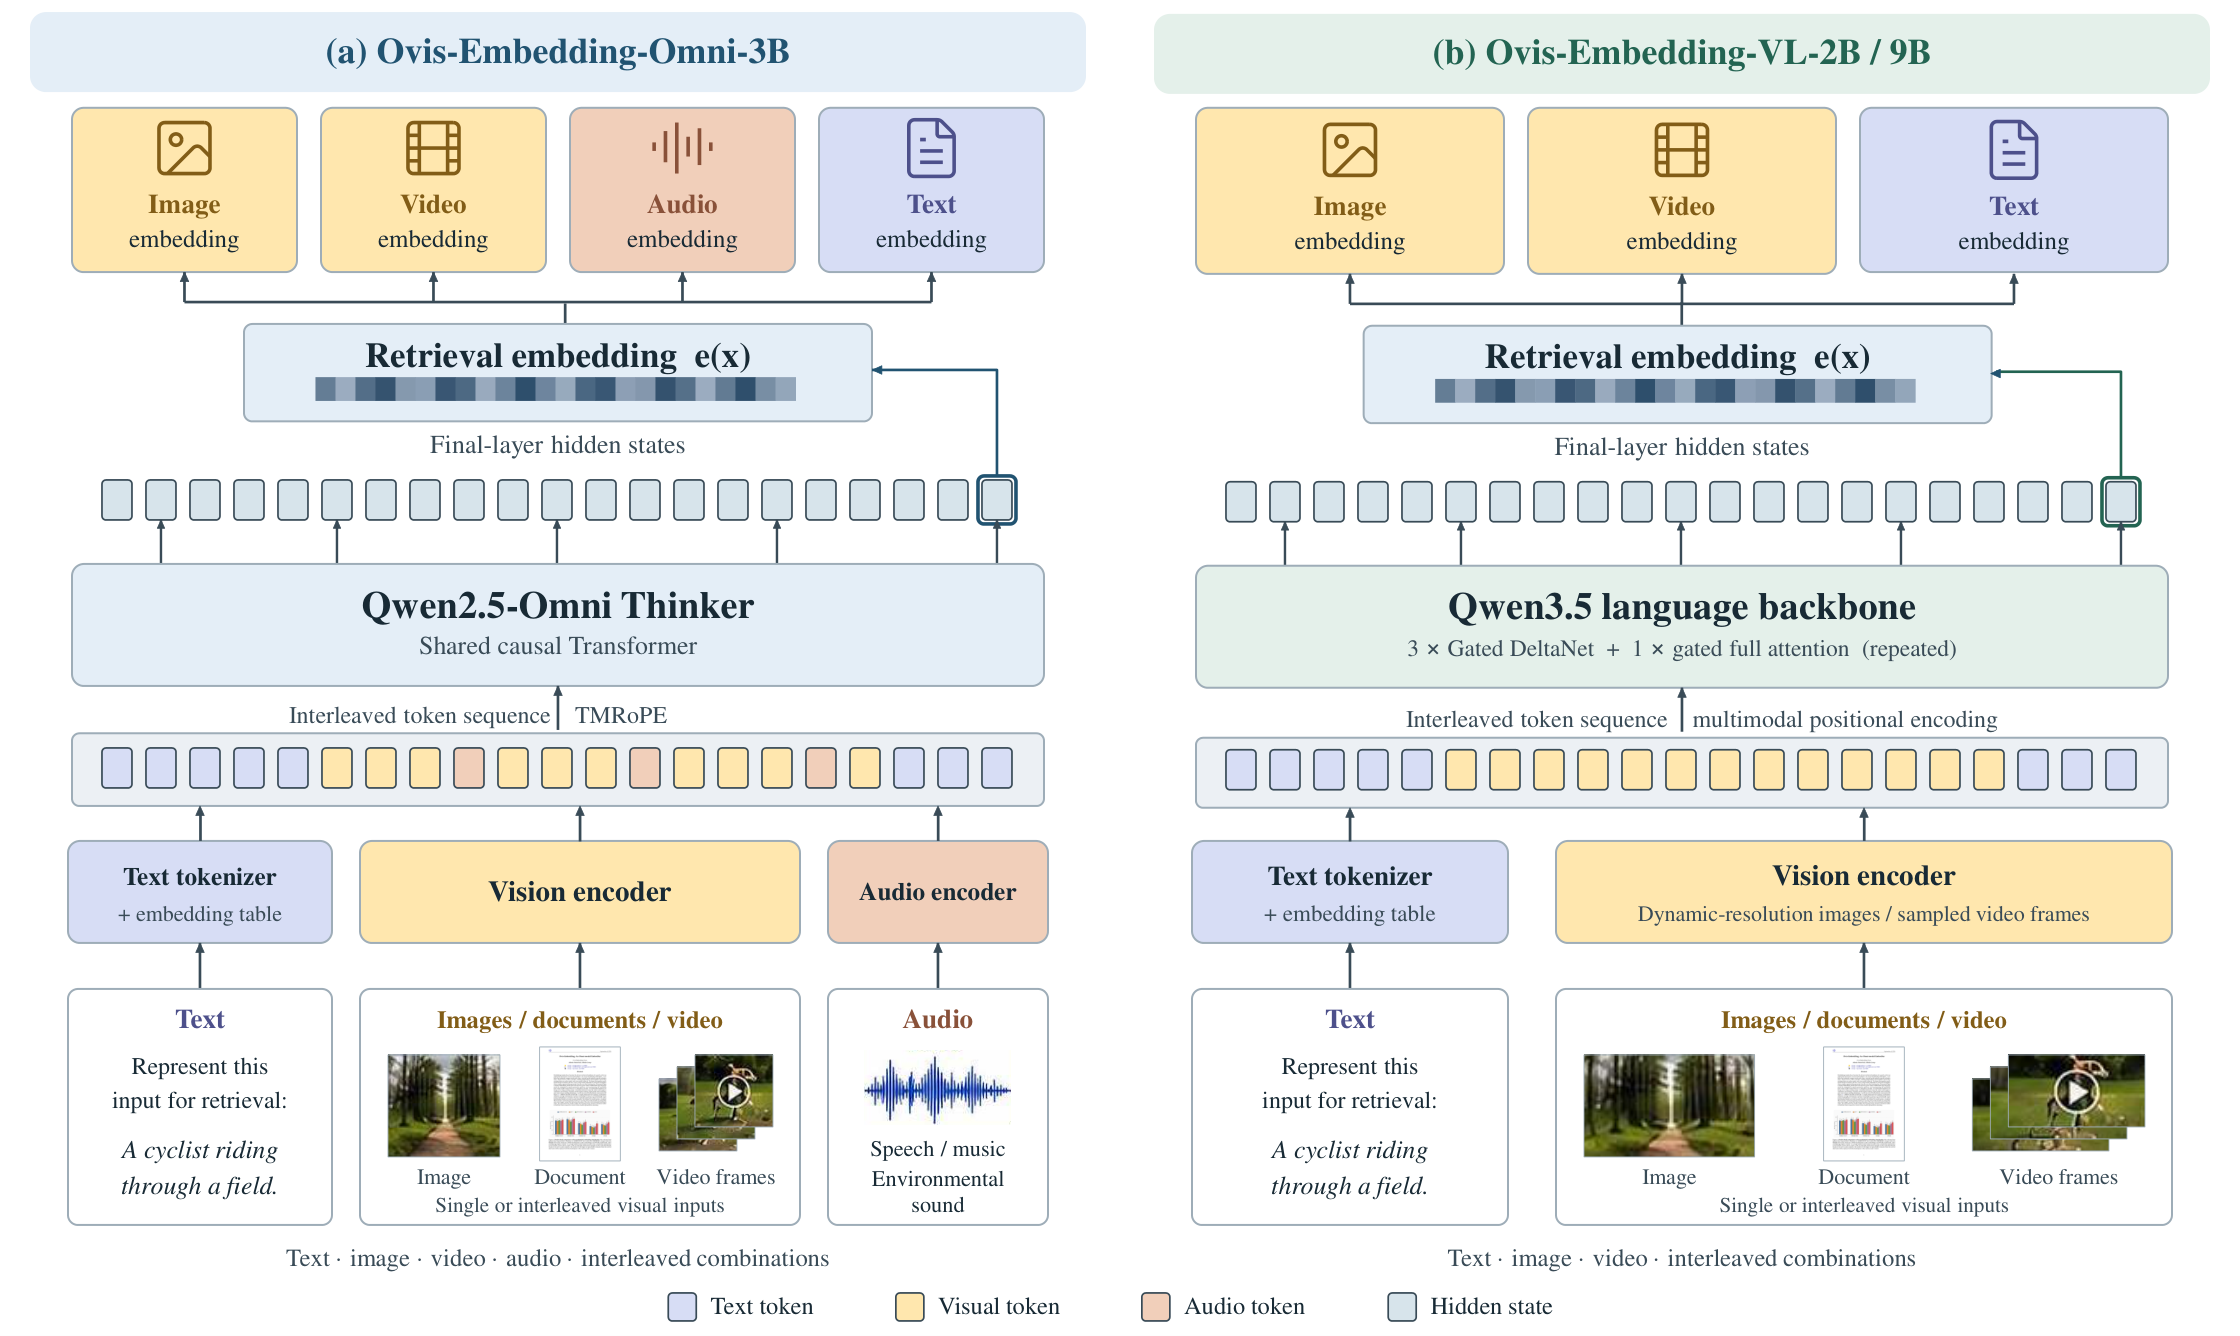
|
|
|
|
|
|
|
|
|
|
|
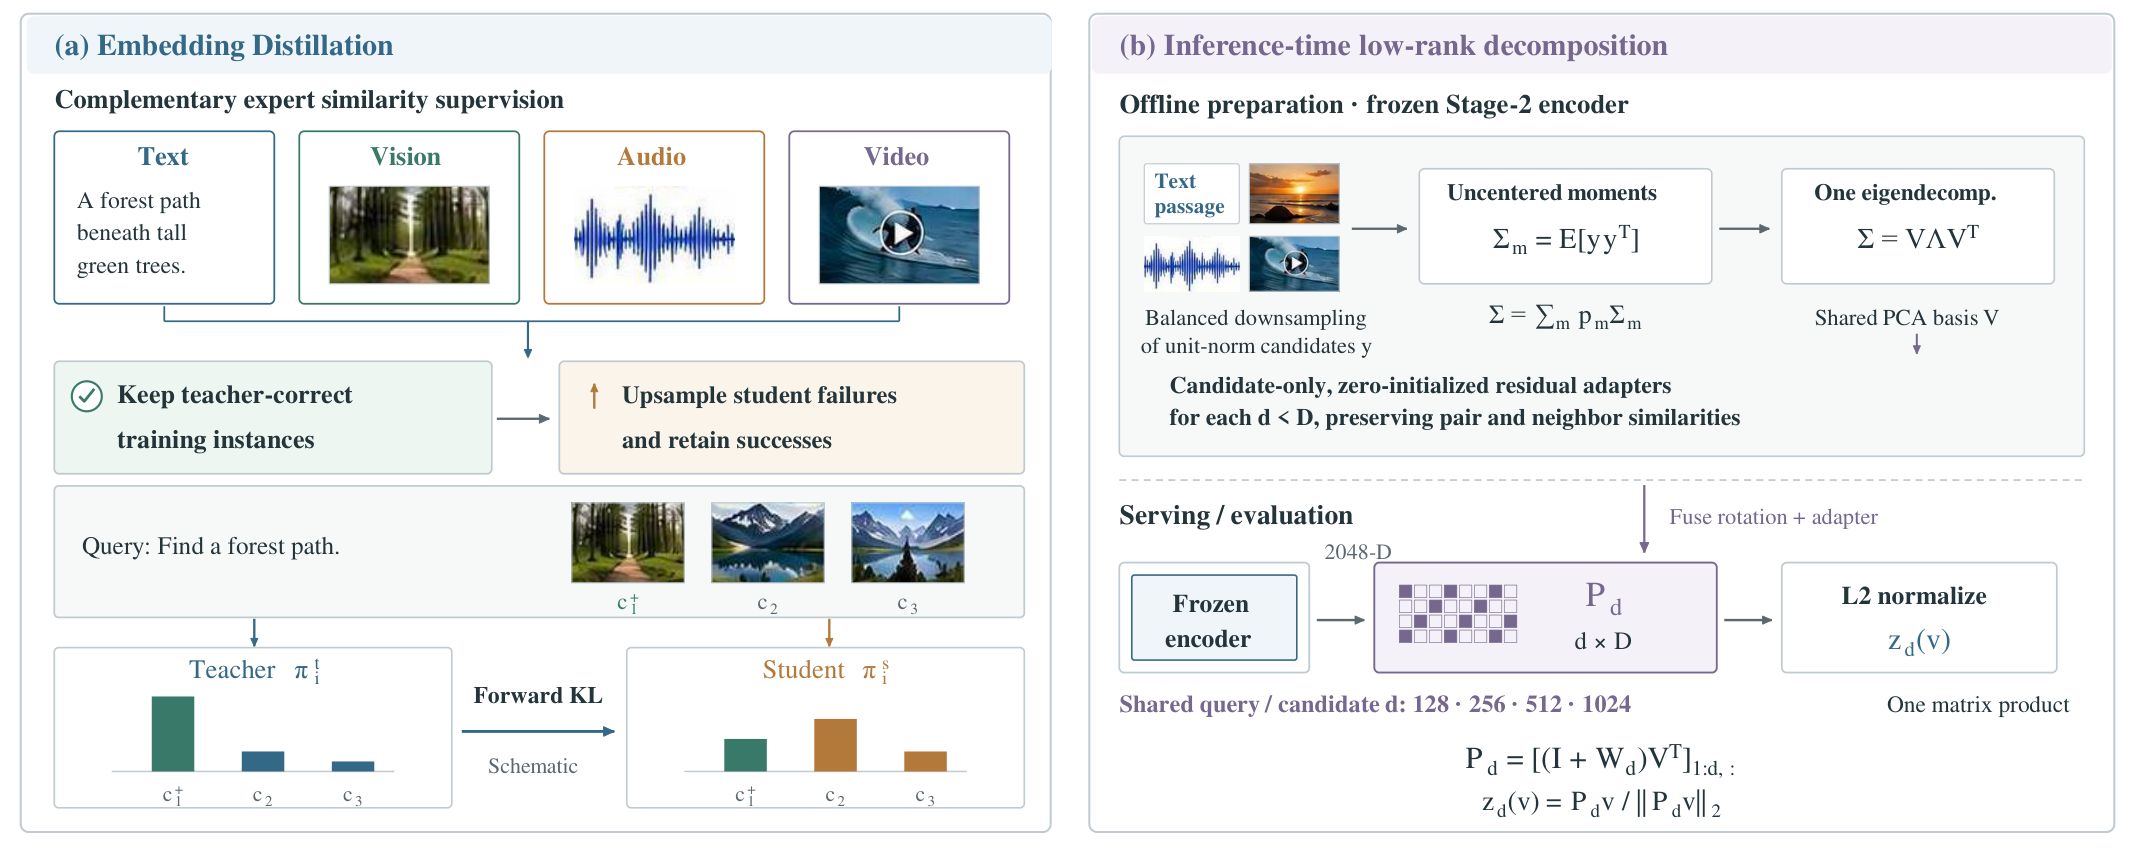
|
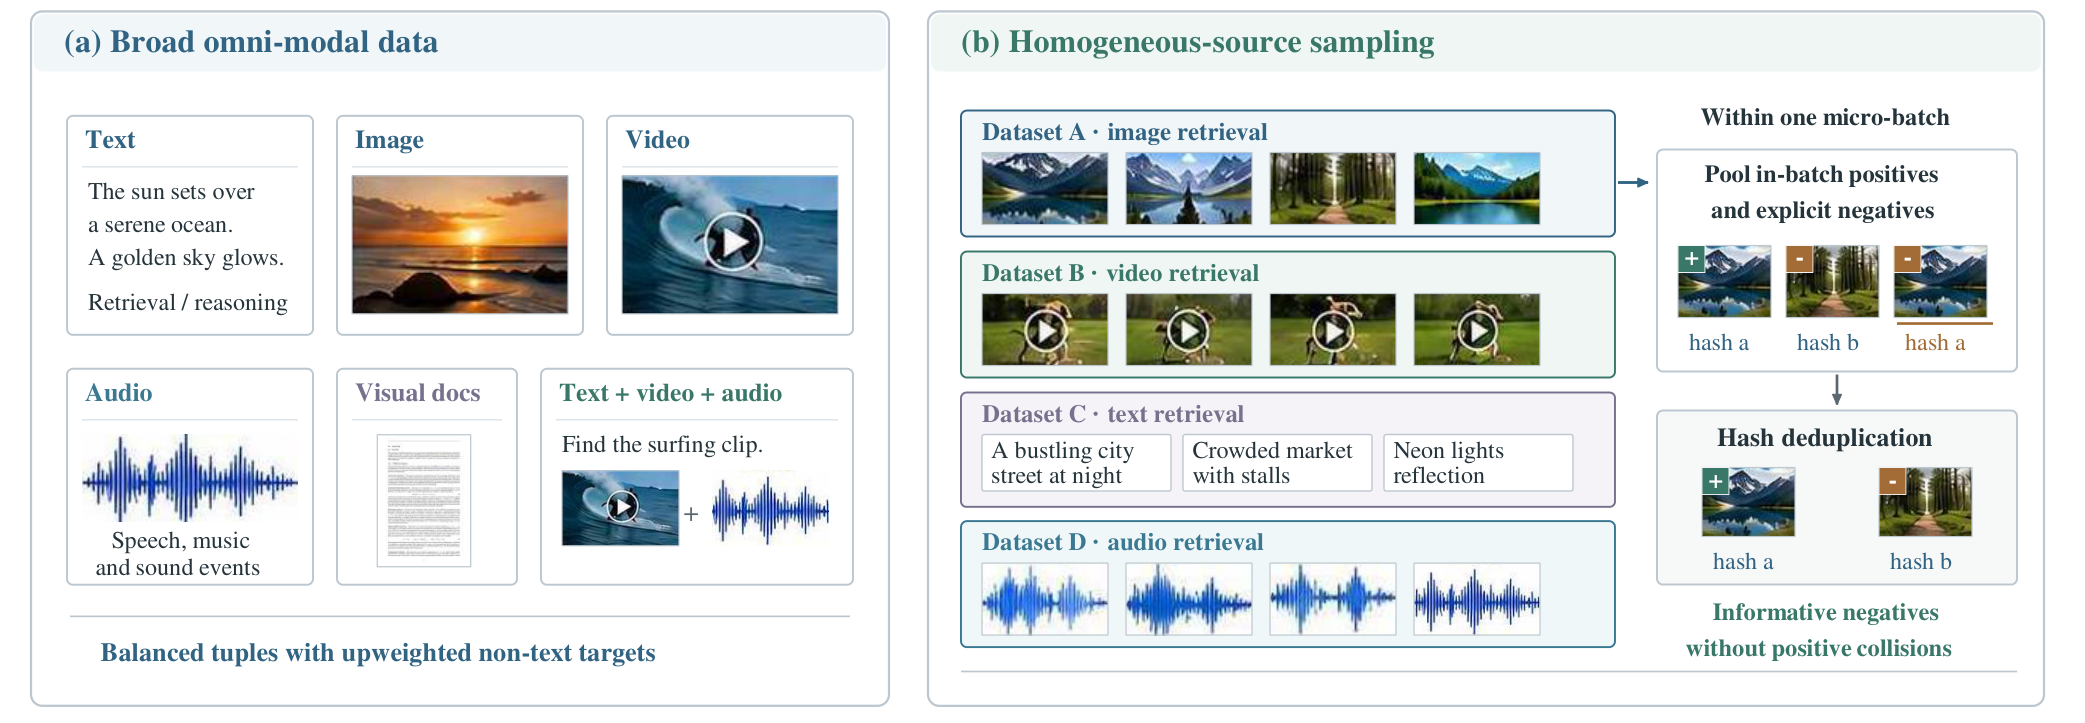
|
|
|
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
ovis_blog_table2.pdf filter=lfs diff=lfs merge=lfs -text
|
| 37 |
+
ovis_blog_table2.png filter=lfs diff=lfs merge=lfs -text
|
| 38 |
+
ovis_embedding_data_centric.png filter=lfs diff=lfs merge=lfs -text
|
| 39 |
+
ovis_embedding_model_architecture.png filter=lfs diff=lfs merge=lfs -text
|
| 40 |
+
ovis_embedding_train_inference.png filter=lfs diff=lfs merge=lfs -text
|
ovis_blog_table2.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:1cb316f64ae7b08db5b8c95e4f5ce5ab0b196d6fb3684df2629216d4b4f52aef
|
| 3 |
+
size 482110
|
ovis_blog_table2.png
ADDED

|
Git LFS Details
|
ovis_embedding_data_centric.png
ADDED
|
Git LFS Details
|
ovis_embedding_model_architecture.png
ADDED
|
Git LFS Details
|
ovis_embedding_train_inference.png
ADDED
|
Git LFS Details
|
vl-9b.md
ADDED
|
@@ -0,0 +1,123 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: apache-2.0
|
| 3 |
+
pipeline_tag: feature-extraction
|
| 4 |
+
library_name: transformers
|
| 5 |
+
tags:
|
| 6 |
+
- multimodal
|
| 7 |
+
- text
|
| 8 |
+
- image
|
| 9 |
+
- video
|
| 10 |
+
- visual-document
|
| 11 |
+
- embedding
|
| 12 |
+
- retrieval
|
| 13 |
+
---
|
| 14 |
+
|
| 15 |
+
<a href="https://github.com/ATH-MaaS/Ovis-VL-Embedding" target="_blank" style="margin: 2px;">
|
| 16 |
+
<img alt="GitHub" src="https://img.shields.io/badge/GitHub-Ovis--VL--Embedding-3157C8?logo=github" style="display: inline-block; vertical-align: middle;"/>
|
| 17 |
+
</a>
|
| 18 |
+
|
| 19 |
+
# Ovis-Embedding-VL-9B
|
| 20 |
+
|
| 21 |
+
**Ovis-Embedding-VL-9B** is a high-capacity vision-language embedding model for text, images, visual documents, video, and interleaved multimodal inputs. It maps every supported input type into one coherent representation space, enabling high-accuracy cross-modal retrieval with a single encoder.
|
| 22 |
+
|
| 23 |
+
The model is initialized from **Qwen3.5-9B**. It retains the native text and vision encoders together with the shared multimodal language backbone, removes the language-modeling head, and directly uses the final-layer hidden state at the last non-padding token as the retrieval embedding. No modality-specific projection head is added.
|
| 24 |
+
|
| 25 |
+
Ovis-Embedding-VL-9B is designed for high-quality multimodal search, multimodal RAG, image and visual-document retrieval, video search and temporal localization, recommendation, and nearest-neighbor matching.
|
| 26 |
+
|
| 27 |
+
## Model highlights
|
| 28 |
+
|
| 29 |
+
- **High-capacity vision-language encoder:** Provides strong text, image, document, and video representations with a 9B-scale native multimodal backbone.
|
| 30 |
+
- **Unified multimodal retrieval:** Queries and candidates may contain text, visual inputs, or interleaved text-image and text-video combinations.
|
| 31 |
+
- **One shared embedding interface:** All supported inputs are represented through last-token pooling and compared in the same cosine-similarity space.
|
| 32 |
+
- **Dynamic-resolution visual processing:** The native vision encoder handles images and sampled video frames at flexible resolutions while preserving spatial and temporal positions.
|
| 33 |
+
- **Difficulty-aware contrastive learning:** Focal embedding loss emphasizes unresolved queries with competitive negatives.
|
| 34 |
+
- **Fine-grained embedding distillation:** Teacher similarity distributions preserve relative relevance across both positive and negative candidates.
|
| 35 |
+
- **Homogeneous-source finetuning:** Task-consistent micro-batches provide informative in-batch negatives and reduce shortcuts based on modality or data format.
|
| 36 |
+
- **Strong temporal scaling:** Compared with the 2B variant, the 9B model gains most strongly on video question answering, video retrieval, and video moment retrieval.
|
| 37 |
+
|
| 38 |
+
## Architecture
|
| 39 |
+
|
| 40 |
+
<p align="center">
|
| 41 |
+
<img src="./ovis_embedding_model_architecture.png" alt="Architecture of Ovis-Embedding-Omni-3B and Ovis-Embedding-VL-2B/9B" width="100%"/>
|
| 42 |
+
</p>
|
| 43 |
+
|
| 44 |
+
*Figure 2 from the technical report. Ovis-Embedding-VL-9B encodes text, images, visual documents, and sampled video frames as one interleaved sequence. The final-layer hidden state at the last non-padding token becomes the retrieval embedding, with no modality-specific projection heads.*
|
| 45 |
+
|
| 46 |
+
The Qwen3.5-9B backbone contains 32 language layers with hidden size 4096. Its hybrid stack repeats three Gated DeltaNet layers followed by one gated full-attention layer, combining efficient long-context processing with periodic global token interaction. Multimodal positional encoding preserves temporal and two-dimensional spatial coordinates for visual tokens.
|
| 47 |
+
|
| 48 |
+
## Training
|
| 49 |
+
|
| 50 |
+
Training follows three stages:
|
| 51 |
+
|
| 52 |
+
1. **Multimodal contrastive pretraining.** Large-scale, multi-task data establish broad alignment across text, image, document, and video inputs. The objective combines difficulty-aware focal contrastive learning with similarity-distribution distillation.
|
| 53 |
+
2. **Full-parameter homogeneous finetuning.** High-quality downstream data refine fine-grained discrimination. Each micro-batch is drawn from one dataset so that gathered candidates form task-consistent negatives.
|
| 54 |
+
3. **Annealing Embedding Distillation.** Teacher-correct examples are retained, unresolved student examples are emphasized, and confidence-adaptive forward-KL supervision transfers complementary expert capabilities.
|
| 55 |
+
|
| 56 |
+
## Retrieval interface
|
| 57 |
+
|
| 58 |
+
Ovis-Embedding-VL-9B is a bi-encoder, not a cross-encoder:
|
| 59 |
+
|
| 60 |
+
1. Pair the query with the task instruction and format it with the native processor and chat template.
|
| 61 |
+
2. Encode queries and candidates independently.
|
| 62 |
+
3. Extract the final-layer hidden state at the last non-padding token.
|
| 63 |
+
4. L2-normalize the 4096-dimensional query and candidate embeddings.
|
| 64 |
+
5. Rank candidates by cosine similarity, equivalently the dot product of the normalized vectors.
|
| 65 |
+
|
| 66 |
+
No answer generation or query-candidate cross-attention is used during retrieval. Classification labels, passages, images, documents, videos, and interleaved multimodal items are all treated as candidates in the same embedding space.
|
| 67 |
+
|
| 68 |
+
## Performance
|
| 69 |
+
|
| 70 |
+
### MMEB-v2
|
| 71 |
+
|
| 72 |
+
MMEB-v2 evaluates vision-language embeddings over **78 datasets** spanning image, video, and visual-document tasks. Ovis-Embedding-VL-9B achieves **81.13 overall**, outperforming the strongest compared baseline by **1.04 points**.
|
| 73 |
+
|
| 74 |
+
| Group | Ovis-Embedding-VL-9B | Best compared baseline | Result |
|
| 75 |
+
|---|---:|---:|---:|
|
| 76 |
+
| Image | **83.96** | 81.86 | **+2.10** |
|
| 77 |
+
| Video | **72.90** | 75.95 | -3.05 |
|
| 78 |
+
| Visual document | **83.06** | 82.38 | **+0.68** |
|
| 79 |
+
| **All 78 datasets** | **81.13** | 80.09 | **+1.04** |
|
| 80 |
+
|
| 81 |
+
The model ranks first on all four image sub-tasks, video classification, video moment retrieval, the visual-document aggregate, and ViDoRe-V1. Scaling from 2B to 9B improves the overall score by 3.67 points, with the largest gains on video question answering (+7.64), video moment retrieval (+7.23), and video retrieval (+5.74).
|
| 82 |
+
|
| 83 |
+
<p align="center">
|
| 84 |
+
<img src="./ovis_blog_table2.png" alt="Complete MMEB-v2 comparison for Ovis-Embedding-VL-9B and four vision-language embedding baselines" width="100%"/>
|
| 85 |
+
</p>
|
| 86 |
+
|
| 87 |
+
*Scores are percentages and higher is better. Red marks the best result in each row, underlining marks the second best, and Ovis scores are bold. The overall score is the unweighted average over all 78 MMEB-v2 datasets.*
|
| 88 |
+
|
| 89 |
+
## Embedding dimensions
|
| 90 |
+
|
| 91 |
+
The native output width is **4096**, inherited directly from the Qwen3.5-9B backbone because no embedding projection head is added. Queries and candidates must use the same preprocessing, pooling rule, dimensionality, and L2 normalization.
|
| 92 |
+
|
| 93 |
+
## Intended use
|
| 94 |
+
|
| 95 |
+
The model is intended for embedding extraction and retrieval over supported unimodal or interleaved multimodal content, including:
|
| 96 |
+
|
| 97 |
+
- high-accuracy semantic and cross-modal search;
|
| 98 |
+
- text-to-image, image-to-text, and image-to-image retrieval;
|
| 99 |
+
- multimodal RAG indexing and retrieval;
|
| 100 |
+
- visual-document and page retrieval;
|
| 101 |
+
- text-to-video, video retrieval, and temporal localization;
|
| 102 |
+
- recommendation and nearest-neighbor matching.
|
| 103 |
+
|
| 104 |
+
## Limitations
|
| 105 |
+
|
| 106 |
+
- This checkpoint does not natively support audio input. Use Ovis-Embedding-Omni-3B for audio and general omni-modal retrieval.
|
| 107 |
+
- This checkpoint produces retrieval embeddings; it is not intended as a text or image generation model.
|
| 108 |
+
- Retrieval quality depends on task-appropriate query instructions and the native preprocessing and chat template.
|
| 109 |
+
- Performance varies by task. The reported model trails the strongest specialist baseline on the aggregate video score, video question answering, general video retrieval, ViDoRe-V2, VisRAG, and VisDoc-OOD.
|
| 110 |
+
- The 4096-dimensional output and 9B-scale backbone require more memory, storage, and inference compute than the 2B variant.
|
| 111 |
+
- Benchmark scores may not directly predict performance on a new domain. Evaluate with representative queries, candidates, and retrieval metrics before deployment.
|
| 112 |
+
|
| 113 |
+
## License
|
| 114 |
+
|
| 115 |
+
This model is released under the Apache 2.0 license.
|
| 116 |
+
|
| 117 |
+
## Resources
|
| 118 |
+
|
| 119 |
+
- [Ovis-VL-Embedding GitHub repository](https://github.com/ATH-MaaS/Ovis-VL-Embedding)
|
| 120 |
+
- [Ovis-Omni-Embedding GitHub repository](https://github.com/ATH-MaaS/Ovis-Omni-Embedding)
|
| 121 |
+
|
| 122 |
+
This repository contains the weights for **Ovis-Embedding-VL-9B**.
|
| 123 |
+
|