

2603
Browse files- dataset-Copy1.py +372 -0
- dataset.py +161 -229
- girl.jpg +2 -2
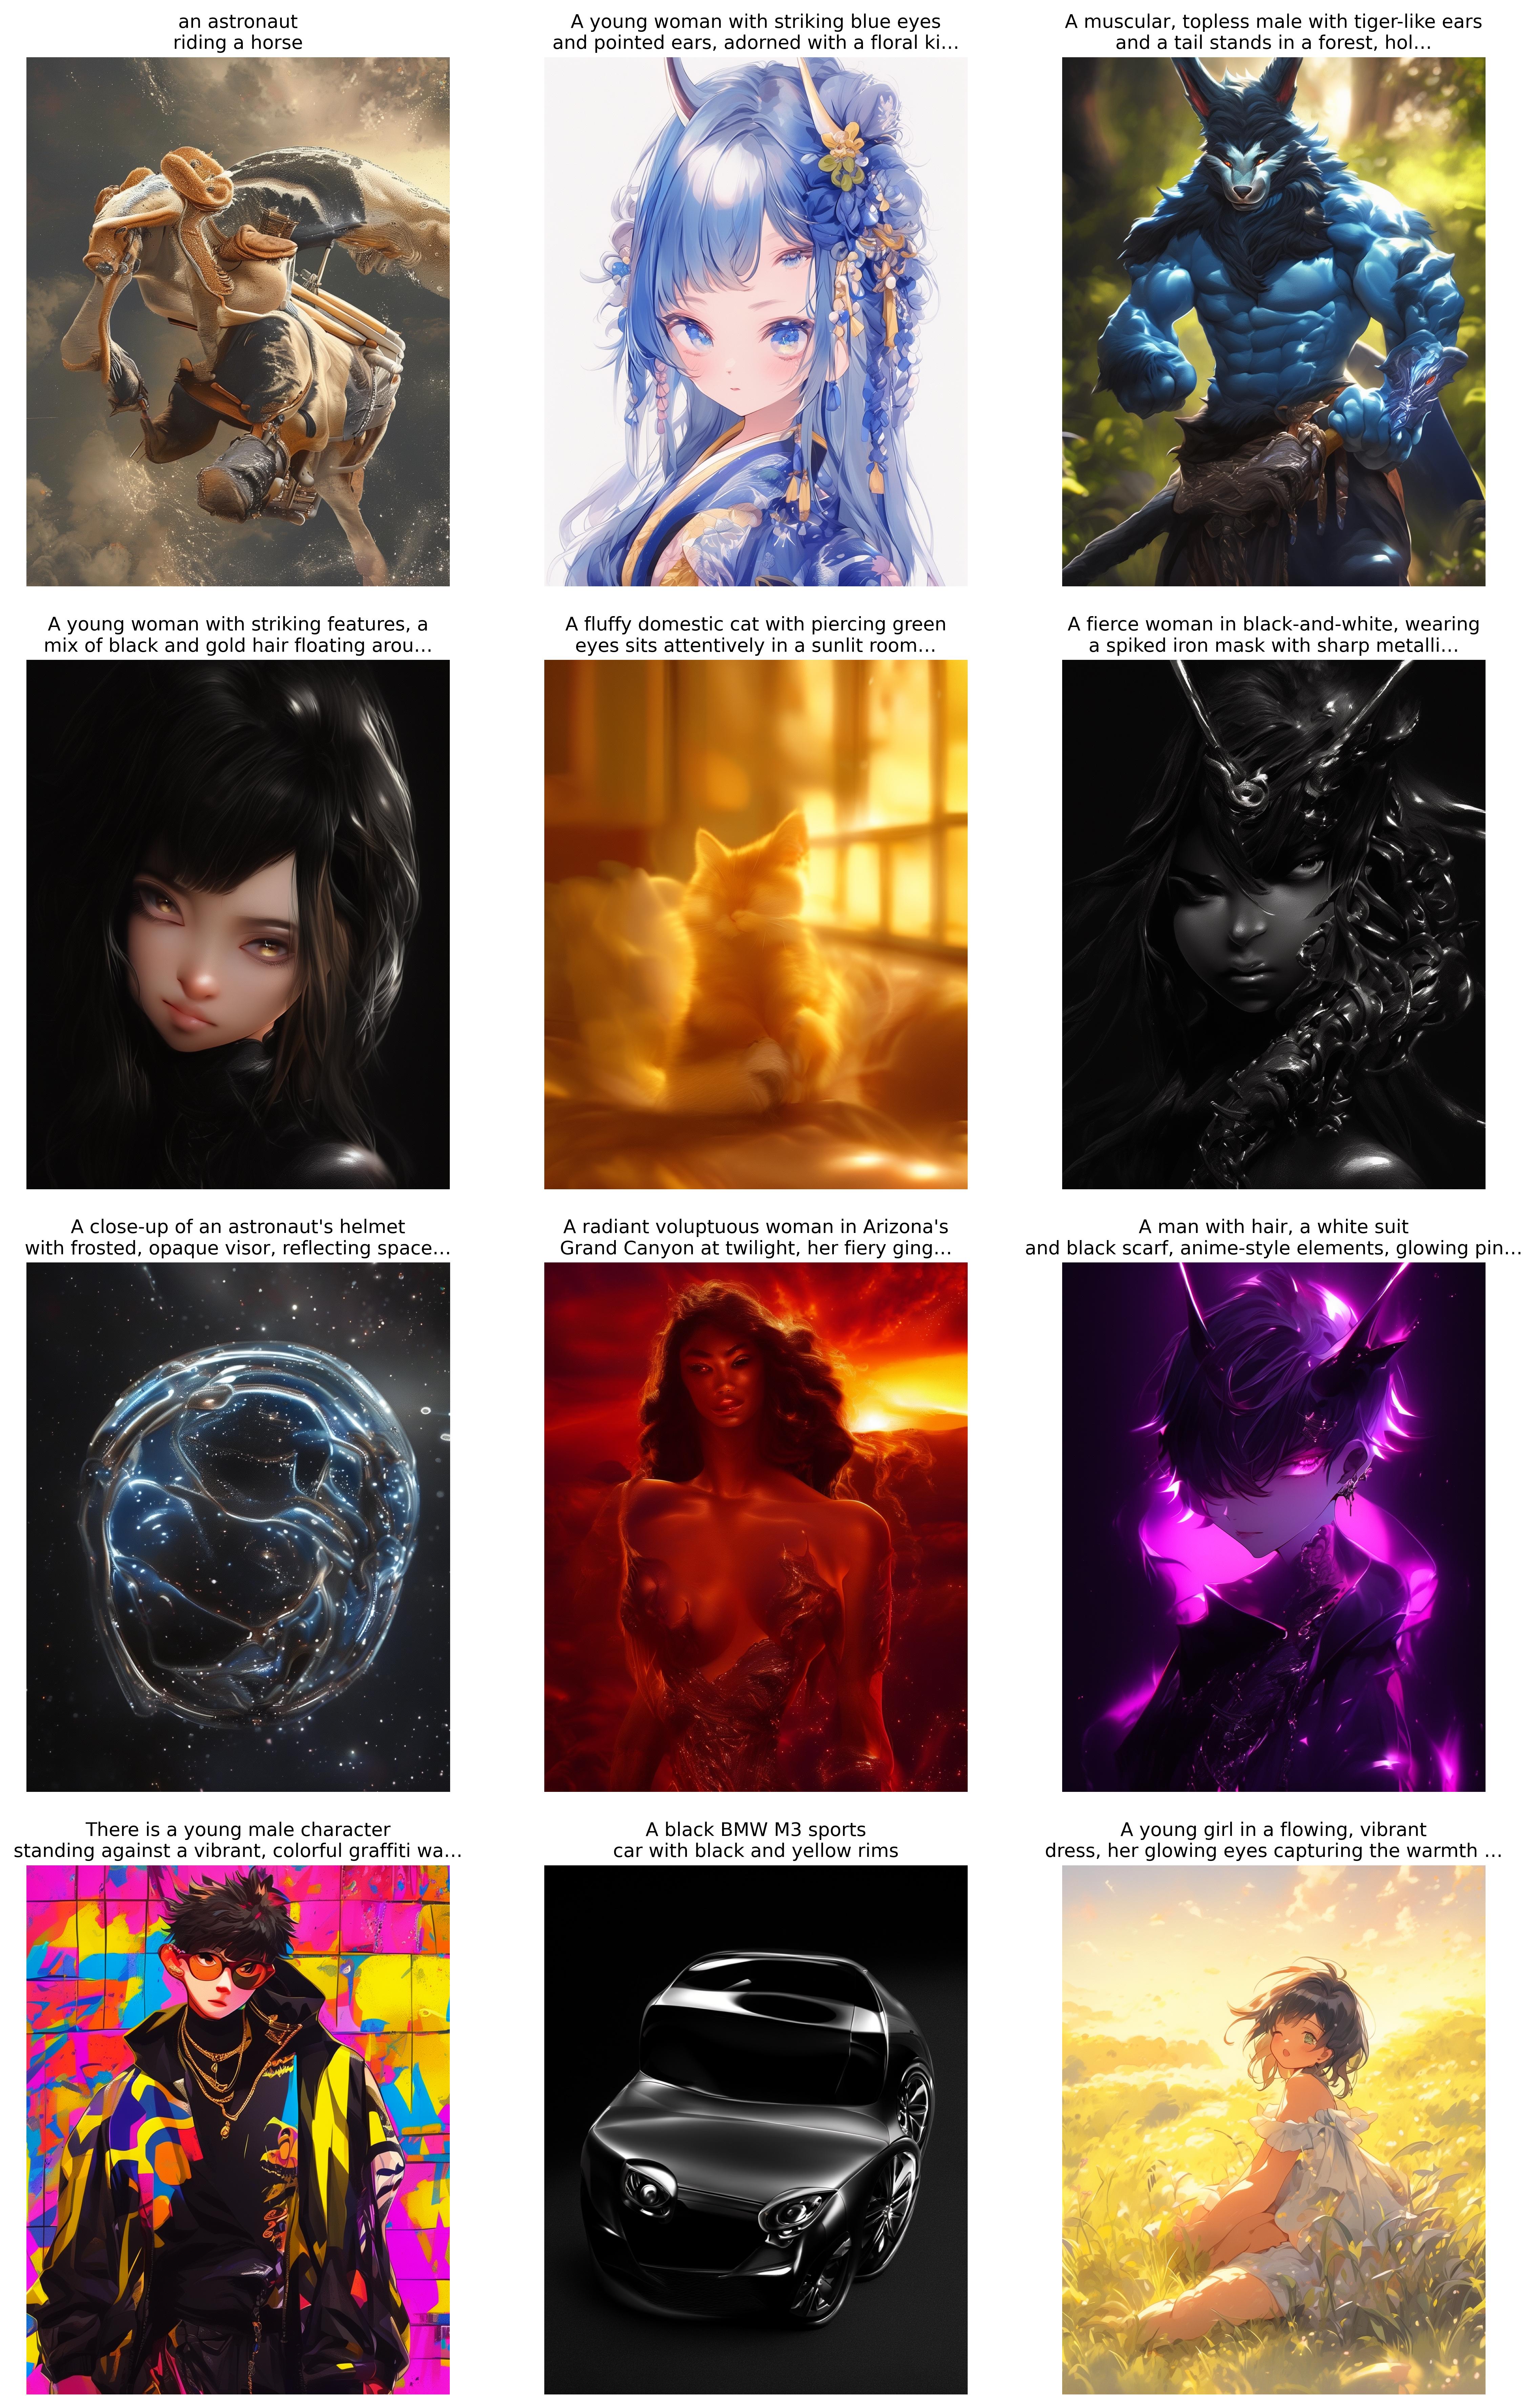
- media/result_grid.jpg +2 -2
- samples/unet_1024x1280_0.jpg +2 -2
- samples/unet_1088x1280_0.jpg +2 -2
- samples/unet_1152x1280_0.jpg +2 -2
- samples/unet_1216x1280_0.jpg +2 -2
- samples/unet_1280x1024_0.jpg +2 -2
- samples/unet_1280x1088_0.jpg +2 -2
- samples/unet_1280x1152_0.jpg +2 -2
- samples/unet_1280x1216_0.jpg +2 -2
- samples/unet_1280x1280_0.jpg +2 -2
- samples/unet_1280x640_0.jpg +2 -2
- samples/unet_1280x704_0.jpg +2 -2
- samples/unet_1280x768_0.jpg +2 -2
- samples/unet_1280x832_0.jpg +2 -2
- samples/unet_1280x896_0.jpg +2 -2
- samples/unet_1280x960_0.jpg +2 -2
- samples/unet_640x1280_0.jpg +2 -2
- samples/unet_704x1280_0.jpg +2 -2
- samples/unet_768x1280_0.jpg +2 -2
- samples/unet_832x1280_0.jpg +2 -2
- samples/unet_896x1280_0.jpg +2 -2
- samples/unet_960x1280_0.jpg +2 -2
- test.ipynb +2 -2
- unet/diffusion_pytorch_model.safetensors +1 -1
dataset-Copy1.py
ADDED
|
@@ -0,0 +1,372 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# pip install flash-attn --no-build-isolation
|
| 2 |
+
import torch
|
| 3 |
+
import os
|
| 4 |
+
import gc
|
| 5 |
+
import numpy as np
|
| 6 |
+
import random
|
| 7 |
+
import json
|
| 8 |
+
import shutil
|
| 9 |
+
import time
|
| 10 |
+
|
| 11 |
+
from datasets import Dataset, load_from_disk, concatenate_datasets
|
| 12 |
+
from diffusers import AutoencoderKL,AutoencoderKLWan,AsymmetricAutoencoderKL,AutoencoderKLFlux2
|
| 13 |
+
from torchvision.transforms import Resize, ToTensor, Normalize, Compose, InterpolationMode, Lambda
|
| 14 |
+
from transformers import AutoModel, AutoImageProcessor, AutoTokenizer, AutoModelForCausalLM
|
| 15 |
+
from typing import Dict, List, Tuple, Optional, Any
|
| 16 |
+
from PIL import Image
|
| 17 |
+
from tqdm import tqdm
|
| 18 |
+
from datetime import timedelta
|
| 19 |
+
|
| 20 |
+
# ---------------- 1️⃣ Настройки ----------------
|
| 21 |
+
dtype = torch.float16
|
| 22 |
+
device = torch.device("cuda" if torch.cuda.is_available() else "cpu")
|
| 23 |
+
batch_size = 5
|
| 24 |
+
min_size = 640 #320 #384 #320 #192 #256 #192
|
| 25 |
+
max_size = 1280 #640 #768 #640 #384 #256 #384
|
| 26 |
+
step = 64
|
| 27 |
+
empty_share = 0.0
|
| 28 |
+
limit = 0
|
| 29 |
+
# Основная процедура обработки
|
| 30 |
+
folder_path = "/workspace/ds" #alchemist"
|
| 31 |
+
save_path = "/workspace/ds1234_flux32" #"alchemist"
|
| 32 |
+
os.makedirs(save_path, exist_ok=True)
|
| 33 |
+
|
| 34 |
+
# Функция для очистки CUDA памяти
|
| 35 |
+
def clear_cuda_memory():
|
| 36 |
+
if torch.cuda.is_available():
|
| 37 |
+
used_gb = torch.cuda.max_memory_allocated() / 1024**3
|
| 38 |
+
print(f"used_gb: {used_gb:.2f} GB")
|
| 39 |
+
torch.cuda.empty_cache()
|
| 40 |
+
gc.collect()
|
| 41 |
+
|
| 42 |
+
# ---------------- 2️⃣ Загрузка моделей ----------------
|
| 43 |
+
def load_models():
|
| 44 |
+
print("Загрузка моделей...")
|
| 45 |
+
#vae = AsymmetricAutoencoderKL.from_pretrained("AiArtLab/sdxs-1b",subfolder="vae",torch_dtype=dtype).to(device).eval()
|
| 46 |
+
vae = AutoencoderKL.from_pretrained("vae", torch_dtype=dtype).to(device).eval()
|
| 47 |
+
return vae
|
| 48 |
+
|
| 49 |
+
vae = load_models()
|
| 50 |
+
|
| 51 |
+
shift_factor = getattr(vae.config, "shift_factor", 0.0)
|
| 52 |
+
if shift_factor is None:
|
| 53 |
+
shift_factor = 0.0
|
| 54 |
+
|
| 55 |
+
scaling_factor = getattr(vae.config, "scaling_factor", 1.0)
|
| 56 |
+
if scaling_factor is None:
|
| 57 |
+
scaling_factor = 1.0
|
| 58 |
+
|
| 59 |
+
mean = getattr(vae.config, "latents_mean", None)
|
| 60 |
+
std = getattr(vae.config, "latents_std", None)
|
| 61 |
+
if mean is not None and std is not None:
|
| 62 |
+
latents_std = torch.tensor(std, device=device, dtype=dtype).view(1, len(std), 1, 1)
|
| 63 |
+
latents_mean = torch.tensor(mean, device=device, dtype=dtype).view(1, len(mean), 1, 1)
|
| 64 |
+
|
| 65 |
+
# ---------------- 3️⃣ Трансформации ----------------
|
| 66 |
+
def get_image_transform(min_size=256, max_size=512, step=64):
|
| 67 |
+
def transform(img, dry_run=False):
|
| 68 |
+
# Сохраняем исходные размеры изображения
|
| 69 |
+
original_width, original_height = img.size
|
| 70 |
+
|
| 71 |
+
# 0. Ресайз: масштабируем изображение, чтобы максимальная сторона была равна max_size
|
| 72 |
+
if original_width >= original_height:
|
| 73 |
+
new_width = max_size
|
| 74 |
+
new_height = int(max_size * original_height / original_width)
|
| 75 |
+
else:
|
| 76 |
+
new_height = max_size
|
| 77 |
+
new_width = int(max_size * original_width / original_height)
|
| 78 |
+
|
| 79 |
+
if new_height < min_size or new_width < min_size:
|
| 80 |
+
# 1. Ресайз: масштабируем изображение, чтобы минимальная сторона была равна min_size
|
| 81 |
+
if original_width <= original_height:
|
| 82 |
+
new_width = min_size
|
| 83 |
+
new_height = int(min_size * original_height / original_width)
|
| 84 |
+
else:
|
| 85 |
+
new_height = min_size
|
| 86 |
+
new_width = int(min_size * original_width / original_height)
|
| 87 |
+
|
| 88 |
+
# 2. Проверка: если одна из сторон превышает max_size, готовимся к обрезке
|
| 89 |
+
crop_width = min(max_size, (new_width // step) * step)
|
| 90 |
+
crop_height = min(max_size, (new_height // step) * step)
|
| 91 |
+
|
| 92 |
+
# Убеждаемся, что размеры обрезки не меньше min_size
|
| 93 |
+
crop_width = max(min_size, crop_width)
|
| 94 |
+
crop_height = max(min_size, crop_height)
|
| 95 |
+
|
| 96 |
+
# Если запрошен только предварительный расчёт размеров
|
| 97 |
+
if dry_run:
|
| 98 |
+
return crop_width, crop_height
|
| 99 |
+
|
| 100 |
+
# Конвертация в RGB и ресайз
|
| 101 |
+
img_resized = img.convert("RGB").resize((new_width, new_height), Image.LANCZOS)
|
| 102 |
+
|
| 103 |
+
# Определение координат обрезки (обрезаем с учетом вотермарок - треть сверху)
|
| 104 |
+
top = (new_height - crop_height) // 3
|
| 105 |
+
left = 0
|
| 106 |
+
|
| 107 |
+
# Обрезка изображения
|
| 108 |
+
img_cropped = img_resized.crop((left, top, left + crop_width, top + crop_height))
|
| 109 |
+
|
| 110 |
+
# Сохраняем итоговые размеры после всех преобразований
|
| 111 |
+
final_width, final_height = img_cropped.size
|
| 112 |
+
|
| 113 |
+
# тензор
|
| 114 |
+
img_tensor = ToTensor()(img_cropped)
|
| 115 |
+
img_tensor = Normalize(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5])(img_tensor)
|
| 116 |
+
return img_tensor, img_cropped, final_width, final_height
|
| 117 |
+
|
| 118 |
+
return transform
|
| 119 |
+
|
| 120 |
+
# ---------------- 4️⃣ Функции обработки ----------------
|
| 121 |
+
def clean_label(label):
|
| 122 |
+
label = label.replace("Image 1", "").replace("Image 2", "").replace("Image 3", "").replace("Image 4", "").replace("The image depicts ","").replace("The image presents ","").replace("The image features ","").replace("The image portrays ","").replace("The image is ","").strip()
|
| 123 |
+
if label.startswith("."):
|
| 124 |
+
label = label[1:].lstrip()
|
| 125 |
+
return label
|
| 126 |
+
|
| 127 |
+
def process_labels_for_guidance(original_labels, prob_to_make_empty=0.01):
|
| 128 |
+
"""
|
| 129 |
+
Обрабатывает список меток для classifier-free guidance.
|
| 130 |
+
|
| 131 |
+
С вероятностью prob_to_make_empty:
|
| 132 |
+
- Метка в первом списке заменяется на пустую строку.
|
| 133 |
+
- К метке во втором списке добавляется префикс "zero:".
|
| 134 |
+
|
| 135 |
+
В противном случае метки в обоих списках остаются оригинальными.
|
| 136 |
+
|
| 137 |
+
"""
|
| 138 |
+
labels_for_model = []
|
| 139 |
+
labels_for_logging = []
|
| 140 |
+
|
| 141 |
+
for label in original_labels:
|
| 142 |
+
if random.random() < prob_to_make_empty:
|
| 143 |
+
labels_for_model.append("") # Заменяем на пустую строку для модели
|
| 144 |
+
labels_for_logging.append(f"zero: {label}") # Добавляем префикс для логгирования
|
| 145 |
+
else:
|
| 146 |
+
labels_for_model.append(label) # Оставляем оригинальную метку для модели
|
| 147 |
+
labels_for_logging.append(label) # Оставляем оригинальную метку для логгирования
|
| 148 |
+
|
| 149 |
+
return labels_for_model, labels_for_logging
|
| 150 |
+
|
| 151 |
+
|
| 152 |
+
def encode_to_latents(images, texts):
|
| 153 |
+
transform = get_image_transform(min_size, max_size, step)
|
| 154 |
+
|
| 155 |
+
try:
|
| 156 |
+
# Обработка изображений (все одинакового размера)
|
| 157 |
+
transformed_tensors = []
|
| 158 |
+
pil_images = []
|
| 159 |
+
widths, heights = [], []
|
| 160 |
+
|
| 161 |
+
# Применяем трансформацию ко всем изображениям
|
| 162 |
+
for img in images:
|
| 163 |
+
try:
|
| 164 |
+
t_img, pil_img, w, h = transform(img)
|
| 165 |
+
transformed_tensors.append(t_img)
|
| 166 |
+
pil_images.append(pil_img)
|
| 167 |
+
widths.append(w)
|
| 168 |
+
heights.append(h)
|
| 169 |
+
except Exception as e:
|
| 170 |
+
print(f"Ошибка трансформации: {e}")
|
| 171 |
+
continue
|
| 172 |
+
|
| 173 |
+
if not transformed_tensors:
|
| 174 |
+
return None
|
| 175 |
+
|
| 176 |
+
# Создаём батч
|
| 177 |
+
batch_tensor = torch.stack(transformed_tensors).to(device, dtype)
|
| 178 |
+
if batch_tensor.ndim==5:
|
| 179 |
+
batch_tensor = batch_tensor.unsqueeze(2) # [B, C, 1, H, W]
|
| 180 |
+
|
| 181 |
+
# Кодируем батч
|
| 182 |
+
with torch.no_grad():
|
| 183 |
+
posteriors = vae.encode(batch_tensor).latent_dist.mode()
|
| 184 |
+
if latents_mean is not None and latents_std is not None:
|
| 185 |
+
posteriors = (posteriors - latents_mean) / latents_std
|
| 186 |
+
posteriors = (posteriors - shift_factor) / scaling_factor
|
| 187 |
+
|
| 188 |
+
latents_np = posteriors.to(dtype).cpu().numpy()
|
| 189 |
+
|
| 190 |
+
# Обрабатываем тексты
|
| 191 |
+
text_labels = [clean_label(text) for text in texts]
|
| 192 |
+
|
| 193 |
+
model_prompts, text_labels = process_labels_for_guidance(text_labels, empty_share)
|
| 194 |
+
|
| 195 |
+
return {
|
| 196 |
+
"vae": latents_np,
|
| 197 |
+
"text": text_labels,
|
| 198 |
+
"width": widths,
|
| 199 |
+
"height": heights
|
| 200 |
+
}
|
| 201 |
+
|
| 202 |
+
except Exception as e:
|
| 203 |
+
print(f"Критическая ошибка в encode_to_latents: {e}")
|
| 204 |
+
raise
|
| 205 |
+
|
| 206 |
+
|
| 207 |
+
# ---------------- 5️⃣ Обработка папки с изображениями и текстами ----------------
|
| 208 |
+
def process_folder(folder_path, limit=None):
|
| 209 |
+
"""
|
| 210 |
+
Рекурсивно обходит указанную директорию и все вложенные директории,
|
| 211 |
+
собирая пути к изображениям и соответствующим текстовым файлам.
|
| 212 |
+
"""
|
| 213 |
+
image_paths = []
|
| 214 |
+
text_paths = []
|
| 215 |
+
width = []
|
| 216 |
+
height = []
|
| 217 |
+
transform = get_image_transform(min_size, max_size, step)
|
| 218 |
+
|
| 219 |
+
# Используем os.walk для рекурсивного обхода директорий
|
| 220 |
+
for root, dirs, files in os.walk(folder_path):
|
| 221 |
+
for filename in files:
|
| 222 |
+
# Проверяем, является ли файл изображением
|
| 223 |
+
if filename.lower().endswith((".jpg", ".jpeg", ".png")):
|
| 224 |
+
image_path = os.path.join(root, filename)
|
| 225 |
+
try:
|
| 226 |
+
img = Image.open(image_path)
|
| 227 |
+
except Exception as e:
|
| 228 |
+
print(f"Ошибка при открытии {image_path}: {e}")
|
| 229 |
+
os.remove(image_path)
|
| 230 |
+
text_path = os.path.splitext(image_path)[0] + ".txt"
|
| 231 |
+
if os.path.exists(text_path):
|
| 232 |
+
os.remove(text_path)
|
| 233 |
+
continue
|
| 234 |
+
# Применяем трансформацию только для получения размеров
|
| 235 |
+
w, h = transform(img, dry_run=True)
|
| 236 |
+
# Формируем путь к текстовому файлу
|
| 237 |
+
text_path = os.path.splitext(image_path)[0] + ".txt"
|
| 238 |
+
|
| 239 |
+
# Добавляем пути, если текстовый файл существует
|
| 240 |
+
if os.path.exists(text_path) and min(w, h)>0:
|
| 241 |
+
image_paths.append(image_path)
|
| 242 |
+
text_paths.append(text_path)
|
| 243 |
+
width.append(w) # Добавляем в список
|
| 244 |
+
height.append(h) # Добавляем в список
|
| 245 |
+
|
| 246 |
+
# Проверяем ограничение на количество
|
| 247 |
+
if limit and limit>0 and len(image_paths) >= limit:
|
| 248 |
+
print(f"Достигнут лимит в {limit} изображений")
|
| 249 |
+
return image_paths, text_paths, width, height
|
| 250 |
+
|
| 251 |
+
print(f"Найдено {len(image_paths)} изображений с текстовыми описаниями")
|
| 252 |
+
return image_paths, text_paths, width, height
|
| 253 |
+
|
| 254 |
+
def process_in_chunks(image_paths, text_paths, width, height, chunk_size=10000, batch_size=1):
|
| 255 |
+
total_files = len(image_paths)
|
| 256 |
+
start_time = time.time()
|
| 257 |
+
chunks = range(0, total_files, chunk_size)
|
| 258 |
+
|
| 259 |
+
for chunk_idx, start in enumerate(chunks, 1):
|
| 260 |
+
end = min(start + chunk_size, total_files)
|
| 261 |
+
chunk_image_paths = image_paths[start:end]
|
| 262 |
+
chunk_text_paths = text_paths[start:end]
|
| 263 |
+
chunk_widths = width[start:end] if isinstance(width, list) else [width] * len(chunk_image_paths)
|
| 264 |
+
chunk_heights = height[start:end] if isinstance(height, list) else [height] * len(chunk_image_paths)
|
| 265 |
+
|
| 266 |
+
# Чтение текстов
|
| 267 |
+
chunk_texts = []
|
| 268 |
+
for text_path in chunk_text_paths:
|
| 269 |
+
try:
|
| 270 |
+
with open(text_path, 'r', encoding='utf-8') as f:
|
| 271 |
+
text = f.read().strip()
|
| 272 |
+
chunk_texts.append(text)
|
| 273 |
+
except Exception as e:
|
| 274 |
+
print(f"Ошибка чтения {text_path}: {e}")
|
| 275 |
+
chunk_texts.append("")
|
| 276 |
+
|
| 277 |
+
# Группируем изображения по размерам
|
| 278 |
+
size_groups = {}
|
| 279 |
+
for i in range(len(chunk_image_paths)):
|
| 280 |
+
size_key = (chunk_widths[i], chunk_heights[i])
|
| 281 |
+
if size_key not in size_groups:
|
| 282 |
+
size_groups[size_key] = {"image_paths": [], "texts": []}
|
| 283 |
+
size_groups[size_key]["image_paths"].append(chunk_image_paths[i])
|
| 284 |
+
size_groups[size_key]["texts"].append(chunk_texts[i])
|
| 285 |
+
|
| 286 |
+
# Обрабатываем каждую группу размеров отдельно
|
| 287 |
+
for size_key, group_data in size_groups.items():
|
| 288 |
+
print(f"Обработка группы с размером {size_key[0]}x{size_key[1]} - {len(group_data['image_paths'])} изображений")
|
| 289 |
+
|
| 290 |
+
group_dataset = Dataset.from_dict({
|
| 291 |
+
"image_path": group_data["image_paths"],
|
| 292 |
+
"text": group_data["texts"]
|
| 293 |
+
})
|
| 294 |
+
|
| 295 |
+
# Теперь можно использовать указанный batch_size, т.к. все изображения одного размера
|
| 296 |
+
processed_group = group_dataset.map(
|
| 297 |
+
lambda examples: encode_to_latents(
|
| 298 |
+
[Image.open(path) for path in examples["image_path"]],
|
| 299 |
+
examples["text"]
|
| 300 |
+
),
|
| 301 |
+
batched=True,
|
| 302 |
+
batch_size=batch_size,
|
| 303 |
+
#remove_columns=["image_path"],
|
| 304 |
+
desc=f"Обработка группы размера {size_key[0]}x{size_key[1]}"
|
| 305 |
+
)
|
| 306 |
+
|
| 307 |
+
# Сохраняем результаты группы
|
| 308 |
+
group_save_path = f"{save_path}_temp/chunk_{chunk_idx}_size_{size_key[0]}x{size_key[1]}"
|
| 309 |
+
processed_group.save_to_disk(group_save_path)
|
| 310 |
+
clear_cuda_memory()
|
| 311 |
+
elapsed = time.time() - start_time
|
| 312 |
+
processed = (chunk_idx - 1) * chunk_size + sum([len(sg["image_paths"]) for sg in list(size_groups.values())[:list(size_groups.values()).index(group_data) + 1]])
|
| 313 |
+
if processed > 0:
|
| 314 |
+
remaining = (elapsed / processed) * (total_files - processed)
|
| 315 |
+
elapsed_str = str(timedelta(seconds=int(elapsed)))
|
| 316 |
+
remaining_str = str(timedelta(seconds=int(remaining)))
|
| 317 |
+
print(f"ETA: Прошло {elapsed_str}, О��талось {remaining_str}, Прогресс {processed}/{total_files} ({processed/total_files:.1%})")
|
| 318 |
+
|
| 319 |
+
# ---------------- 7️⃣ Объединение чанков ----------------
|
| 320 |
+
def combine_chunks(temp_path, final_path):
|
| 321 |
+
"""Объединение обработанных чанков в финальный датасет"""
|
| 322 |
+
chunks = sorted([
|
| 323 |
+
os.path.join(temp_path, d)
|
| 324 |
+
for d in os.listdir(temp_path)
|
| 325 |
+
if d.startswith("chunk_")
|
| 326 |
+
])
|
| 327 |
+
|
| 328 |
+
datasets = [load_from_disk(chunk) for chunk in chunks]
|
| 329 |
+
combined = concatenate_datasets(datasets)
|
| 330 |
+
combined.save_to_disk(final_path)
|
| 331 |
+
|
| 332 |
+
print(f"✅ Датасет успешно сохранен в: {final_path}")
|
| 333 |
+
|
| 334 |
+
|
| 335 |
+
|
| 336 |
+
# Создаем временную папку для чанков
|
| 337 |
+
temp_path = f"{save_path}_temp"
|
| 338 |
+
os.makedirs(temp_path, exist_ok=True)
|
| 339 |
+
|
| 340 |
+
# Получаем список файлов
|
| 341 |
+
image_paths, text_paths, width, height = process_folder(folder_path,limit)
|
| 342 |
+
print(f"Всего найдено {len(image_paths)} изображений")
|
| 343 |
+
|
| 344 |
+
# --- ВСТАВЛЯЕМ ЗДЕСЬ: Сортируем пути и размеры по ширине и высоте ---
|
| 345 |
+
# Создаем список индексов, отсортированных по (width, height)
|
| 346 |
+
#sorted_indices = sorted(range(len(width)), key=lambda i: (width[i], height[i]))
|
| 347 |
+
# Применяем сортировку ко всем спискам
|
| 348 |
+
#image_paths = [image_paths[i] for i in sorted_indices]
|
| 349 |
+
#text_paths = [text_paths[i] for i in sorted_indices]
|
| 350 |
+
#width = [width[i] for i in sorted_indices]
|
| 351 |
+
#height = [height[i] for i in sorted_indices]
|
| 352 |
+
# --- КОНЕЦ ВСТАВКИ ---
|
| 353 |
+
|
| 354 |
+
# Обработка с чанкованием
|
| 355 |
+
process_in_chunks(image_paths, text_paths, width, height, chunk_size=20000, batch_size=batch_size)
|
| 356 |
+
|
| 357 |
+
# Удаление папки
|
| 358 |
+
try:
|
| 359 |
+
shutil.rmtree(folder_path)
|
| 360 |
+
print(f"✅ Папка {folder_path} успешно удалена")
|
| 361 |
+
except Exception as e:
|
| 362 |
+
print(f"⚠️ Ошибка при удалении папки: {e}")
|
| 363 |
+
|
| 364 |
+
# Объединение чанков в финальный датасет
|
| 365 |
+
combine_chunks(temp_path, save_path)
|
| 366 |
+
|
| 367 |
+
# Удаление временной папки
|
| 368 |
+
try:
|
| 369 |
+
shutil.rmtree(temp_path)
|
| 370 |
+
print(f"✅ Временная папка {temp_path} успешно удалена")
|
| 371 |
+
except Exception as e:
|
| 372 |
+
print(f"⚠️ Ошибка при удалении временной папки: {e}")
|
dataset.py
CHANGED
|
@@ -17,58 +17,57 @@ from PIL import Image
|
|
| 17 |
from tqdm import tqdm
|
| 18 |
from datetime import timedelta
|
| 19 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 20 |
# ---------------- 1️⃣ Настройки ----------------
|
| 21 |
dtype = torch.float16
|
| 22 |
-
device = torch.device("cuda" if torch.cuda.is_available() else "cpu")
|
| 23 |
batch_size = 5
|
| 24 |
-
min_size = 640
|
| 25 |
-
max_size = 1280
|
| 26 |
step = 64
|
| 27 |
empty_share = 0.0
|
| 28 |
limit = 0
|
| 29 |
-
|
| 30 |
-
folder_path = "/workspace/ds"
|
| 31 |
-
save_path = "/workspace/ds1234_flux32"
|
| 32 |
os.makedirs(save_path, exist_ok=True)
|
| 33 |
|
| 34 |
-
# Функция для очистки CUDA памяти
|
| 35 |
def clear_cuda_memory():
|
| 36 |
if torch.cuda.is_available():
|
| 37 |
used_gb = torch.cuda.max_memory_allocated() / 1024**3
|
| 38 |
-
print(f"used_gb: {used_gb:.2f} GB")
|
| 39 |
torch.cuda.empty_cache()
|
| 40 |
gc.collect()
|
| 41 |
|
| 42 |
# ---------------- 2️⃣ Загрузка моделей ----------------
|
| 43 |
def load_models():
|
| 44 |
-
print("Загрузка моделей...")
|
| 45 |
-
#vae = AsymmetricAutoencoderKL.from_pretrained("AiArtLab/sdxs-1b",subfolder="vae",torch_dtype=dtype).to(device).eval()
|
| 46 |
vae = AutoencoderKL.from_pretrained("vae", torch_dtype=dtype).to(device).eval()
|
| 47 |
return vae
|
| 48 |
|
| 49 |
vae = load_models()
|
| 50 |
|
| 51 |
-
shift_factor = getattr(vae.config, "shift_factor", 0.0)
|
| 52 |
-
|
| 53 |
-
shift_factor = 0.0
|
| 54 |
|
| 55 |
-
scaling_factor = getattr(vae.config, "scaling_factor", 1.0)
|
| 56 |
-
if scaling_factor is None:
|
| 57 |
-
scaling_factor = 1.0
|
| 58 |
-
|
| 59 |
mean = getattr(vae.config, "latents_mean", None)
|
| 60 |
std = getattr(vae.config, "latents_std", None)
|
| 61 |
if mean is not None and std is not None:
|
| 62 |
latents_std = torch.tensor(std, device=device, dtype=dtype).view(1, len(std), 1, 1)
|
| 63 |
latents_mean = torch.tensor(mean, device=device, dtype=dtype).view(1, len(mean), 1, 1)
|
| 64 |
-
|
| 65 |
# ---------------- 3️⃣ Трансформации ----------------
|
| 66 |
def get_image_transform(min_size=256, max_size=512, step=64):
|
| 67 |
def transform(img, dry_run=False):
|
| 68 |
-
# Сохраняем исходные размеры изображения
|
| 69 |
original_width, original_height = img.size
|
| 70 |
|
| 71 |
-
# 0. Ресайз: масштабируем изображение, чтобы максимальная сторона была равна max_size
|
| 72 |
if original_width >= original_height:
|
| 73 |
new_width = max_size
|
| 74 |
new_height = int(max_size * original_height / original_width)
|
|
@@ -77,7 +76,6 @@ def get_image_transform(min_size=256, max_size=512, step=64):
|
|
| 77 |
new_width = int(max_size * original_width / original_height)
|
| 78 |
|
| 79 |
if new_height < min_size or new_width < min_size:
|
| 80 |
-
# 1. Ресайз: масштабируем изображение, чтобы минимальная сторона была равна min_size
|
| 81 |
if original_width <= original_height:
|
| 82 |
new_width = min_size
|
| 83 |
new_height = int(min_size * original_height / original_width)
|
|
@@ -85,288 +83,222 @@ def get_image_transform(min_size=256, max_size=512, step=64):
|
|
| 85 |
new_height = min_size
|
| 86 |
new_width = int(min_size * original_width / original_height)
|
| 87 |
|
| 88 |
-
# 2. Проверка: если одна из сторон превышает max_size, готовимся к обрезке
|
| 89 |
crop_width = min(max_size, (new_width // step) * step)
|
| 90 |
crop_height = min(max_size, (new_height // step) * step)
|
| 91 |
|
| 92 |
-
# Убеждаемся, что размеры обрезки не меньше min_size
|
| 93 |
crop_width = max(min_size, crop_width)
|
| 94 |
crop_height = max(min_size, crop_height)
|
| 95 |
-
|
| 96 |
-
# Если запрошен только предварительный расчёт размеров
|
| 97 |
if dry_run:
|
| 98 |
return crop_width, crop_height
|
| 99 |
-
|
| 100 |
-
# Конвертация в RGB и ресайз
|
| 101 |
img_resized = img.convert("RGB").resize((new_width, new_height), Image.LANCZOS)
|
| 102 |
-
|
| 103 |
-
# Определение координат обрезки (обрезаем с учетом вотермарок - треть сверху)
|
| 104 |
top = (new_height - crop_height) // 3
|
| 105 |
left = 0
|
| 106 |
-
|
| 107 |
-
# Обрезка изображения
|
| 108 |
img_cropped = img_resized.crop((left, top, left + crop_width, top + crop_height))
|
| 109 |
-
|
| 110 |
-
# Сохраняем итоговые разме��ы после всех преобразований
|
| 111 |
final_width, final_height = img_cropped.size
|
| 112 |
-
|
| 113 |
-
# тензор
|
| 114 |
img_tensor = ToTensor()(img_cropped)
|
| 115 |
-
img_tensor = Normalize(mean=[0.5
|
| 116 |
return img_tensor, img_cropped, final_width, final_height
|
| 117 |
|
| 118 |
return transform
|
| 119 |
|
| 120 |
# ---------------- 4️⃣ Функции обработки ----------------
|
| 121 |
def clean_label(label):
|
| 122 |
-
label = label.replace("Image 1",
|
|
|
|
|
|
|
| 123 |
if label.startswith("."):
|
| 124 |
label = label[1:].lstrip()
|
| 125 |
return label
|
| 126 |
|
| 127 |
def process_labels_for_guidance(original_labels, prob_to_make_empty=0.01):
|
| 128 |
-
"""
|
| 129 |
-
Обрабатывает список меток для classifier-free guidance.
|
| 130 |
-
|
| 131 |
-
С вероятностью prob_to_make_empty:
|
| 132 |
-
- Метка в первом списке заменяется на пустую строку.
|
| 133 |
-
- К метке во втором списке добавляется префикс "zero:".
|
| 134 |
-
|
| 135 |
-
В противном случае метки в обоих списках остаются оригинальными.
|
| 136 |
-
|
| 137 |
-
"""
|
| 138 |
labels_for_model = []
|
| 139 |
labels_for_logging = []
|
| 140 |
|
| 141 |
for label in original_labels:
|
| 142 |
if random.random() < prob_to_make_empty:
|
| 143 |
-
labels_for_model.append("")
|
| 144 |
-
labels_for_logging.append(f"zero: {label}")
|
| 145 |
else:
|
| 146 |
-
labels_for_model.append(label)
|
| 147 |
-
labels_for_logging.append(label)
|
| 148 |
|
| 149 |
return labels_for_model, labels_for_logging
|
| 150 |
|
| 151 |
-
|
| 152 |
def encode_to_latents(images, texts):
|
| 153 |
transform = get_image_transform(min_size, max_size, step)
|
| 154 |
|
| 155 |
-
|
| 156 |
-
|
| 157 |
-
|
| 158 |
-
|
| 159 |
-
|
| 160 |
-
|
| 161 |
-
|
| 162 |
-
|
| 163 |
-
|
| 164 |
-
|
| 165 |
-
|
| 166 |
-
|
| 167 |
-
|
| 168 |
-
|
| 169 |
-
|
| 170 |
-
|
| 171 |
-
|
| 172 |
-
|
| 173 |
-
|
| 174 |
-
|
| 175 |
-
|
| 176 |
-
|
| 177 |
-
|
| 178 |
-
|
| 179 |
-
|
| 180 |
-
|
| 181 |
-
|
| 182 |
-
|
| 183 |
-
|
| 184 |
-
|
| 185 |
-
|
| 186 |
-
|
| 187 |
-
|
| 188 |
-
|
| 189 |
-
|
| 190 |
-
|
| 191 |
-
|
| 192 |
-
|
| 193 |
-
|
| 194 |
-
|
| 195 |
-
return {
|
| 196 |
-
"vae": latents_np,
|
| 197 |
-
"text": text_labels,
|
| 198 |
-
"width": widths,
|
| 199 |
-
"height": heights
|
| 200 |
-
}
|
| 201 |
-
|
| 202 |
-
except Exception as e:
|
| 203 |
-
print(f"Критическая ошибка в encode_to_latents: {e}")
|
| 204 |
-
raise
|
| 205 |
-
|
| 206 |
-
|
| 207 |
-
# ---------------- 5️⃣ Обработка папки с изображениями и текстами ----------------
|
| 208 |
def process_folder(folder_path, limit=None):
|
| 209 |
-
|
| 210 |
-
Рекурсивно обходит указанную директорию и все вложенные директории,
|
| 211 |
-
собирая пути к изображениям и соответствующим текстовым файлам.
|
| 212 |
-
"""
|
| 213 |
-
image_paths = []
|
| 214 |
-
text_paths = []
|
| 215 |
-
width = []
|
| 216 |
-
height = []
|
| 217 |
transform = get_image_transform(min_size, max_size, step)
|
| 218 |
-
|
| 219 |
-
|
| 220 |
-
for root, dirs, files in os.walk(folder_path):
|
| 221 |
for filename in files:
|
| 222 |
-
|
| 223 |
-
if filename.lower().endswith((".jpg", ".jpeg", ".png")):
|
| 224 |
image_path = os.path.join(root, filename)
|
| 225 |
try:
|
| 226 |
img = Image.open(image_path)
|
| 227 |
-
except
|
| 228 |
-
print(f"Ошибка при открытии {image_path}: {e}")
|
| 229 |
-
os.remove(image_path)
|
| 230 |
-
text_path = os.path.splitext(image_path)[0] + ".txt"
|
| 231 |
-
if os.path.exists(text_path):
|
| 232 |
-
os.remove(text_path)
|
| 233 |
continue
|
| 234 |
-
|
| 235 |
-
w,
|
| 236 |
-
|
| 237 |
-
|
| 238 |
-
|
| 239 |
-
# Добавляем пути, если текстовый файл существует
|
| 240 |
-
if os.path.exists(text_path) and min(w, h)>0:
|
| 241 |
image_paths.append(image_path)
|
| 242 |
text_paths.append(text_path)
|
| 243 |
-
width.append(w)
|
| 244 |
-
height.append(h)
|
| 245 |
-
|
| 246 |
-
|
| 247 |
-
if limit and limit>0 and len(image_paths) >= limit:
|
| 248 |
-
print(f"Достигнут лимит в {limit} изображений")
|
| 249 |
-
return image_paths, text_paths, width, height
|
| 250 |
-
|
| 251 |
-
print(f"Найдено {len(image_paths)} изображений с текстовыми описаниями")
|
| 252 |
return image_paths, text_paths, width, height
|
| 253 |
-
|
| 254 |
def process_in_chunks(image_paths, text_paths, width, height, chunk_size=10000, batch_size=1):
|
| 255 |
total_files = len(image_paths)
|
| 256 |
start_time = time.time()
|
| 257 |
-
|
| 258 |
-
|
| 259 |
-
|
| 260 |
-
|
| 261 |
chunk_image_paths = image_paths[start:end]
|
| 262 |
chunk_text_paths = text_paths[start:end]
|
| 263 |
-
chunk_widths = width[start:end]
|
| 264 |
-
chunk_heights = height[start:end]
|
| 265 |
-
|
| 266 |
-
# Чтение текстов
|
| 267 |
chunk_texts = []
|
| 268 |
for text_path in chunk_text_paths:
|
| 269 |
try:
|
| 270 |
-
with open(text_path,
|
| 271 |
-
|
| 272 |
-
|
| 273 |
-
except Exception as e:
|
| 274 |
-
print(f"Ошибка чтения {text_path}: {e}")
|
| 275 |
chunk_texts.append("")
|
| 276 |
-
|
| 277 |
-
# Группируем изображения по размерам
|
| 278 |
size_groups = {}
|
| 279 |
for i in range(len(chunk_image_paths)):
|
| 280 |
-
|
| 281 |
-
|
| 282 |
-
|
| 283 |
-
size_groups[
|
| 284 |
-
|
| 285 |
-
|
| 286 |
-
|
| 287 |
-
|
| 288 |
-
print(f"Обработка группы с размером {size_key[0]}x{size_key[1]} - {len(group_data['image_paths'])} изображений")
|
| 289 |
-
|
| 290 |
-
group_dataset = Dataset.from_dict({
|
| 291 |
-
"image_path": group_data["image_paths"],
|
| 292 |
-
"text": group_data["texts"]
|
| 293 |
-
})
|
| 294 |
-
|
| 295 |
-
# Теперь можно использовать указанный batch_size, т.к. все изображения одного размера
|
| 296 |
processed_group = group_dataset.map(
|
| 297 |
-
lambda
|
| 298 |
-
[Image.open(
|
| 299 |
-
|
| 300 |
),
|
| 301 |
batched=True,
|
| 302 |
batch_size=batch_size,
|
| 303 |
-
#remove_columns=["image_path"],
|
| 304 |
-
desc=f"Обработка группы размера {size_key[0]}x{size_key[1]}"
|
| 305 |
)
|
| 306 |
-
|
| 307 |
-
#
|
| 308 |
-
group_save_path = f"{save_path}_temp/
|
|
|
|
|
|
|
| 309 |
processed_group.save_to_disk(group_save_path)
|
| 310 |
clear_cuda_memory()
|
| 311 |
-
|
| 312 |
-
|
| 313 |
-
if processed > 0:
|
| 314 |
-
remaining = (elapsed / processed) * (total_files - processed)
|
| 315 |
-
elapsed_str = str(timedelta(seconds=int(elapsed)))
|
| 316 |
-
remaining_str = str(timedelta(seconds=int(remaining)))
|
| 317 |
-
print(f"ETA: Прошло {elapsed_str}, Осталось {remaining_str}, Прогресс {processed}/{total_files} ({processed/total_files:.1%})")
|
| 318 |
-
|
| 319 |
-
# ---------------- 7️⃣ Объединение чанков ----------------
|
| 320 |
def combine_chunks(temp_path, final_path):
|
| 321 |
-
"""Объединение обработанных чанков в финальный датасет"""
|
| 322 |
chunks = sorted([
|
| 323 |
-
os.path.join(temp_path,
|
| 324 |
-
for d in os.listdir(temp_path)
|
| 325 |
-
if
|
| 326 |
])
|
| 327 |
-
|
| 328 |
-
datasets = [load_from_disk(
|
| 329 |
combined = concatenate_datasets(datasets)
|
| 330 |
combined.save_to_disk(final_path)
|
| 331 |
-
|
| 332 |
-
print(f"✅ Датасет успешно сохранен в: {final_path}")
|
| 333 |
|
| 334 |
-
|
| 335 |
|
| 336 |
-
#
|
| 337 |
temp_path = f"{save_path}_temp"
|
| 338 |
os.makedirs(temp_path, exist_ok=True)
|
| 339 |
|
| 340 |
-
# Получаем список файлов
|
| 341 |
image_paths, text_paths, width, height = process_folder(folder_path,limit)
|
| 342 |
-
|
| 343 |
-
|
| 344 |
-
|
| 345 |
-
|
| 346 |
-
|
| 347 |
-
|
| 348 |
-
|
| 349 |
-
|
| 350 |
-
#
|
| 351 |
-
|
| 352 |
-
|
| 353 |
-
|
| 354 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 355 |
process_in_chunks(image_paths, text_paths, width, height, chunk_size=20000, batch_size=batch_size)
|
| 356 |
|
| 357 |
-
#
|
| 358 |
-
|
| 359 |
-
|
| 360 |
-
|
| 361 |
-
|
| 362 |
-
|
| 363 |
-
|
| 364 |
-
|
| 365 |
-
|
| 366 |
-
|
| 367 |
-
|
| 368 |
-
|
| 369 |
-
|
| 370 |
-
|
| 371 |
-
|
| 372 |
-
|
|
|
|
|
|
|
|
|
| 17 |
from tqdm import tqdm
|
| 18 |
from datetime import timedelta
|
| 19 |
|
| 20 |
+
# --- NEW: accelerate ---
|
| 21 |
+
from accelerate import Accelerator
|
| 22 |
+
accelerator = Accelerator()
|
| 23 |
+
device = accelerator.device
|
| 24 |
+
is_main_process = accelerator.is_main_process
|
| 25 |
+
process_index = accelerator.process_index
|
| 26 |
+
num_processes = accelerator.num_processes
|
| 27 |
+
# --- END NEW ---
|
| 28 |
+
|
| 29 |
# ---------------- 1️⃣ Настройки ----------------
|
| 30 |
dtype = torch.float16
|
|
|
|
| 31 |
batch_size = 5
|
| 32 |
+
min_size = 640
|
| 33 |
+
max_size = 1280
|
| 34 |
step = 64
|
| 35 |
empty_share = 0.0
|
| 36 |
limit = 0
|
| 37 |
+
|
| 38 |
+
folder_path = "/workspace/ds"
|
| 39 |
+
save_path = "/workspace/ds1234_flux32"
|
| 40 |
os.makedirs(save_path, exist_ok=True)
|
| 41 |
|
|
|
|
| 42 |
def clear_cuda_memory():
|
| 43 |
if torch.cuda.is_available():
|
| 44 |
used_gb = torch.cuda.max_memory_allocated() / 1024**3
|
| 45 |
+
print(f"[GPU {process_index}] used_gb: {used_gb:.2f} GB")
|
| 46 |
torch.cuda.empty_cache()
|
| 47 |
gc.collect()
|
| 48 |
|
| 49 |
# ---------------- 2️⃣ Загрузка моделей ----------------
|
| 50 |
def load_models():
|
| 51 |
+
print(f"[GPU {process_index}] Загрузка моделей...")
|
|
|
|
| 52 |
vae = AutoencoderKL.from_pretrained("vae", torch_dtype=dtype).to(device).eval()
|
| 53 |
return vae
|
| 54 |
|
| 55 |
vae = load_models()
|
| 56 |
|
| 57 |
+
shift_factor = getattr(vae.config, "shift_factor", 0.0) or 0.0
|
| 58 |
+
scaling_factor = getattr(vae.config, "scaling_factor", 1.0) or 1.0
|
|
|
|
| 59 |
|
|
|
|
|
|
|
|
|
|
|
|
|
| 60 |
mean = getattr(vae.config, "latents_mean", None)
|
| 61 |
std = getattr(vae.config, "latents_std", None)
|
| 62 |
if mean is not None and std is not None:
|
| 63 |
latents_std = torch.tensor(std, device=device, dtype=dtype).view(1, len(std), 1, 1)
|
| 64 |
latents_mean = torch.tensor(mean, device=device, dtype=dtype).view(1, len(mean), 1, 1)
|
| 65 |
+
|
| 66 |
# ---------------- 3️⃣ Трансформации ----------------
|
| 67 |
def get_image_transform(min_size=256, max_size=512, step=64):
|
| 68 |
def transform(img, dry_run=False):
|
|
|
|
| 69 |
original_width, original_height = img.size
|
| 70 |
|
|
|
|
| 71 |
if original_width >= original_height:
|
| 72 |
new_width = max_size
|
| 73 |
new_height = int(max_size * original_height / original_width)
|
|
|
|
| 76 |
new_width = int(max_size * original_width / original_height)
|
| 77 |
|
| 78 |
if new_height < min_size or new_width < min_size:
|
|
|
|
| 79 |
if original_width <= original_height:
|
| 80 |
new_width = min_size
|
| 81 |
new_height = int(min_size * original_height / original_width)
|
|
|
|
| 83 |
new_height = min_size
|
| 84 |
new_width = int(min_size * original_width / original_height)
|
| 85 |
|
|
|
|
| 86 |
crop_width = min(max_size, (new_width // step) * step)
|
| 87 |
crop_height = min(max_size, (new_height // step) * step)
|
| 88 |
|
|
|
|
| 89 |
crop_width = max(min_size, crop_width)
|
| 90 |
crop_height = max(min_size, crop_height)
|
| 91 |
+
|
|
|
|
| 92 |
if dry_run:
|
| 93 |
return crop_width, crop_height
|
| 94 |
+
|
|
|
|
| 95 |
img_resized = img.convert("RGB").resize((new_width, new_height), Image.LANCZOS)
|
| 96 |
+
|
|
|
|
| 97 |
top = (new_height - crop_height) // 3
|
| 98 |
left = 0
|
| 99 |
+
|
|
|
|
| 100 |
img_cropped = img_resized.crop((left, top, left + crop_width, top + crop_height))
|
| 101 |
+
|
|
|
|
| 102 |
final_width, final_height = img_cropped.size
|
| 103 |
+
|
|
|
|
| 104 |
img_tensor = ToTensor()(img_cropped)
|
| 105 |
+
img_tensor = Normalize(mean=[0.5]*3, std=[0.5]*3)(img_tensor)
|
| 106 |
return img_tensor, img_cropped, final_width, final_height
|
| 107 |
|
| 108 |
return transform
|
| 109 |
|
| 110 |
# ---------------- 4️⃣ Функции обработки ----------------
|
| 111 |
def clean_label(label):
|
| 112 |
+
label = label.replace("Image 1","").replace("Image 2","").replace("Image 3","").replace("Image 4","")
|
| 113 |
+
label = label.replace("The image depicts ","").replace("The image presents ","")
|
| 114 |
+
label = label.replace("The image features ","").replace("The image portrays ","").replace("The image is ","").strip()
|
| 115 |
if label.startswith("."):
|
| 116 |
label = label[1:].lstrip()
|
| 117 |
return label
|
| 118 |
|
| 119 |
def process_labels_for_guidance(original_labels, prob_to_make_empty=0.01):
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 120 |
labels_for_model = []
|
| 121 |
labels_for_logging = []
|
| 122 |
|
| 123 |
for label in original_labels:
|
| 124 |
if random.random() < prob_to_make_empty:
|
| 125 |
+
labels_for_model.append("")
|
| 126 |
+
labels_for_logging.append(f"zero: {label}")
|
| 127 |
else:
|
| 128 |
+
labels_for_model.append(label)
|
| 129 |
+
labels_for_logging.append(label)
|
| 130 |
|
| 131 |
return labels_for_model, labels_for_logging
|
| 132 |
|
|
|
|
| 133 |
def encode_to_latents(images, texts):
|
| 134 |
transform = get_image_transform(min_size, max_size, step)
|
| 135 |
|
| 136 |
+
transformed_tensors = []
|
| 137 |
+
widths, heights = [], []
|
| 138 |
+
|
| 139 |
+
for img in images:
|
| 140 |
+
try:
|
| 141 |
+
t_img, _, w, h = transform(img)
|
| 142 |
+
transformed_tensors.append(t_img)
|
| 143 |
+
widths.append(w)
|
| 144 |
+
heights.append(h)
|
| 145 |
+
except Exception as e:
|
| 146 |
+
print(f"Ошибка трансформации: {e}")
|
| 147 |
+
|
| 148 |
+
if not transformed_tensors:
|
| 149 |
+
return None
|
| 150 |
+
|
| 151 |
+
batch_tensor = torch.stack(transformed_tensors).to(device, dtype)
|
| 152 |
+
|
| 153 |
+
if batch_tensor.ndim==5:
|
| 154 |
+
batch_tensor = batch_tensor.unsqueeze(2)
|
| 155 |
+
|
| 156 |
+
with torch.no_grad():
|
| 157 |
+
posteriors = vae.encode(batch_tensor).latent_dist.mode()
|
| 158 |
+
if mean is not None and std is not None:
|
| 159 |
+
posteriors = (posteriors - latents_mean) / latents_std
|
| 160 |
+
posteriors = (posteriors - shift_factor) / scaling_factor
|
| 161 |
+
|
| 162 |
+
latents_np = posteriors.cpu().numpy()
|
| 163 |
+
|
| 164 |
+
text_labels = [clean_label(text) for text in texts]
|
| 165 |
+
_, text_labels = process_labels_for_guidance(text_labels, empty_share)
|
| 166 |
+
|
| 167 |
+
return {
|
| 168 |
+
"vae": latents_np,
|
| 169 |
+
"text": text_labels,
|
| 170 |
+
"width": widths,
|
| 171 |
+
"height": heights
|
| 172 |
+
}
|
| 173 |
+
|
| 174 |
+
# ---------------- 5️⃣ Обработка папки ----------------
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 175 |
def process_folder(folder_path, limit=None):
|
| 176 |
+
image_paths, text_paths, width, height = [], [], [], []
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 177 |
transform = get_image_transform(min_size, max_size, step)
|
| 178 |
+
|
| 179 |
+
for root, _, files in os.walk(folder_path):
|
|
|
|
| 180 |
for filename in files:
|
| 181 |
+
if filename.lower().endswith((".jpg",".jpeg",".png")):
|
|
|
|
| 182 |
image_path = os.path.join(root, filename)
|
| 183 |
try:
|
| 184 |
img = Image.open(image_path)
|
| 185 |
+
except:
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 186 |
continue
|
| 187 |
+
|
| 188 |
+
w,h = transform(img, dry_run=True)
|
| 189 |
+
text_path = os.path.splitext(image_path)[0]+".txt"
|
| 190 |
+
|
| 191 |
+
if os.path.exists(text_path):
|
|
|
|
|
|
|
| 192 |
image_paths.append(image_path)
|
| 193 |
text_paths.append(text_path)
|
| 194 |
+
width.append(w)
|
| 195 |
+
height.append(h)
|
| 196 |
+
|
| 197 |
+
print(f"Найдено {len(image_paths)} изображений")
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 198 |
return image_paths, text_paths, width, height
|
| 199 |
+
|
| 200 |
def process_in_chunks(image_paths, text_paths, width, height, chunk_size=10000, batch_size=1):
|
| 201 |
total_files = len(image_paths)
|
| 202 |
start_time = time.time()
|
| 203 |
+
|
| 204 |
+
for chunk_idx, start in enumerate(range(0,total_files,chunk_size),1):
|
| 205 |
+
end = min(start+chunk_size,total_files)
|
| 206 |
+
|
| 207 |
chunk_image_paths = image_paths[start:end]
|
| 208 |
chunk_text_paths = text_paths[start:end]
|
| 209 |
+
chunk_widths = width[start:end]
|
| 210 |
+
chunk_heights = height[start:end]
|
| 211 |
+
|
|
|
|
| 212 |
chunk_texts = []
|
| 213 |
for text_path in chunk_text_paths:
|
| 214 |
try:
|
| 215 |
+
with open(text_path,'r',encoding='utf-8') as f:
|
| 216 |
+
chunk_texts.append(f.read().strip())
|
| 217 |
+
except:
|
|
|
|
|
|
|
| 218 |
chunk_texts.append("")
|
| 219 |
+
|
|
|
|
| 220 |
size_groups = {}
|
| 221 |
for i in range(len(chunk_image_paths)):
|
| 222 |
+
key=(chunk_widths[i],chunk_heights[i])
|
| 223 |
+
size_groups.setdefault(key,{"image_paths":[],"texts":[]})
|
| 224 |
+
size_groups[key]["image_paths"].append(chunk_image_paths[i])
|
| 225 |
+
size_groups[key]["texts"].append(chunk_texts[i])
|
| 226 |
+
|
| 227 |
+
for size_key,group_data in size_groups.items():
|
| 228 |
+
group_dataset = Dataset.from_dict(group_data)
|
| 229 |
+
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 230 |
processed_group = group_dataset.map(
|
| 231 |
+
lambda ex: encode_to_latents(
|
| 232 |
+
[Image.open(p) for p in ex["image_paths"]],
|
| 233 |
+
ex["texts"]
|
| 234 |
),
|
| 235 |
batched=True,
|
| 236 |
batch_size=batch_size,
|
|
|
|
|
|
|
| 237 |
)
|
| 238 |
+
|
| 239 |
+
# --- NEW: уникальный путь ---
|
| 240 |
+
group_save_path = f"{save_path}_temp/proc_{process_index}_chunk_{chunk_idx}_{size_key[0]}x{size_key[1]}"
|
| 241 |
+
# --- END NEW ---
|
| 242 |
+
|
| 243 |
processed_group.save_to_disk(group_save_path)
|
| 244 |
clear_cuda_memory()
|
| 245 |
+
|
| 246 |
+
# ---------------- 7️⃣ Объединение ----------------
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 247 |
def combine_chunks(temp_path, final_path):
|
|
|
|
| 248 |
chunks = sorted([
|
| 249 |
+
os.path.join(temp_path,d)
|
| 250 |
+
for d in os.listdir(temp_path)
|
| 251 |
+
if "chunk_" in d
|
| 252 |
])
|
| 253 |
+
|
| 254 |
+
datasets = [load_from_disk(c) for c in chunks]
|
| 255 |
combined = concatenate_datasets(datasets)
|
| 256 |
combined.save_to_disk(final_path)
|
|
|
|
|
|
|
| 257 |
|
| 258 |
+
print("✅ Сохранено")
|
| 259 |
|
| 260 |
+
# ---------------- MAIN ----------------
|
| 261 |
temp_path = f"{save_path}_temp"
|
| 262 |
os.makedirs(temp_path, exist_ok=True)
|
| 263 |
|
|
|
|
| 264 |
image_paths, text_paths, width, height = process_folder(folder_path,limit)
|
| 265 |
+
|
| 266 |
+
# сортировка
|
| 267 |
+
sorted_indices = sorted(range(len(width)), key=lambda i:(width[i],height[i]))
|
| 268 |
+
image_paths = [image_paths[i] for i in sorted_indices]
|
| 269 |
+
text_paths = [text_paths[i] for i in sorted_indices]
|
| 270 |
+
width = [width[i] for i in sorted_indices]
|
| 271 |
+
height = [height[i] for i in sorted_indices]
|
| 272 |
+
|
| 273 |
+
# --- NEW: shard по GPU ---
|
| 274 |
+
indices = list(range(len(image_paths)))
|
| 275 |
+
indices = indices[process_index::num_processes]
|
| 276 |
+
|
| 277 |
+
image_paths = [image_paths[i] for i in indices]
|
| 278 |
+
text_paths = [text_paths[i] for i in indices]
|
| 279 |
+
width = [width[i] for i in indices]
|
| 280 |
+
height = [height[i] for i in indices]
|
| 281 |
+
|
| 282 |
+
print(f"[GPU {process_index}] обрабатывает {len(image_paths)} файлов")
|
| 283 |
+
# --- END NEW ---
|
| 284 |
+
|
| 285 |
process_in_chunks(image_paths, text_paths, width, height, chunk_size=20000, batch_size=batch_size)
|
| 286 |
|
| 287 |
+
# --- NEW: sync ---
|
| 288 |
+
accelerator.wait_for_everyone()
|
| 289 |
+
# --- END NEW ---
|
| 290 |
+
|
| 291 |
+
# --- NEW: только главный процесс ---
|
| 292 |
+
if is_main_process:
|
| 293 |
+
try:
|
| 294 |
+
shutil.rmtree(folder_path)
|
| 295 |
+
except:
|
| 296 |
+
pass
|
| 297 |
+
|
| 298 |
+
combine_chunks(temp_path, save_path)
|
| 299 |
+
|
| 300 |
+
try:
|
| 301 |
+
shutil.rmtree(temp_path)
|
| 302 |
+
except:
|
| 303 |
+
pass
|
| 304 |
+
# --- END NEW ---
|
girl.jpg
CHANGED

|
Git LFS Details
|

|
Git LFS Details
|
media/result_grid.jpg
CHANGED
|
Git LFS Details
|

|
Git LFS Details
|
samples/unet_1024x1280_0.jpg
CHANGED
|
Git LFS Details
|

|
Git LFS Details
|
samples/unet_1088x1280_0.jpg
CHANGED

|
Git LFS Details
|

|
Git LFS Details
|
samples/unet_1152x1280_0.jpg
CHANGED
|
Git LFS Details
|

|
Git LFS Details
|
samples/unet_1216x1280_0.jpg
CHANGED

|
Git LFS Details
|

|
Git LFS Details
|
samples/unet_1280x1024_0.jpg
CHANGED
|
Git LFS Details
|

|
Git LFS Details
|
samples/unet_1280x1088_0.jpg
CHANGED

|
Git LFS Details
|

|
Git LFS Details
|
samples/unet_1280x1152_0.jpg
CHANGED
|
Git LFS Details
|

|
Git LFS Details
|
samples/unet_1280x1216_0.jpg
CHANGED
|
Git LFS Details
|

|
Git LFS Details
|
samples/unet_1280x1280_0.jpg
CHANGED
|
Git LFS Details
|

|
Git LFS Details
|
samples/unet_1280x640_0.jpg
CHANGED

|
Git LFS Details
|

|
Git LFS Details
|
samples/unet_1280x704_0.jpg
CHANGED
|
Git LFS Details
|

|
Git LFS Details
|
samples/unet_1280x768_0.jpg
CHANGED
|
Git LFS Details
|

|
Git LFS Details
|
samples/unet_1280x832_0.jpg
CHANGED
|
Git LFS Details
|

|
Git LFS Details
|
samples/unet_1280x896_0.jpg
CHANGED

|
Git LFS Details
|

|
Git LFS Details
|
samples/unet_1280x960_0.jpg
CHANGED
|
Git LFS Details
|

|
Git LFS Details
|
samples/unet_640x1280_0.jpg
CHANGED

|
Git LFS Details
|

|
Git LFS Details
|
samples/unet_704x1280_0.jpg
CHANGED
|
Git LFS Details
|

|
Git LFS Details
|
samples/unet_768x1280_0.jpg
CHANGED
|
Git LFS Details
|

|
Git LFS Details
|
samples/unet_832x1280_0.jpg
CHANGED
|
Git LFS Details
|

|
Git LFS Details
|
samples/unet_896x1280_0.jpg
CHANGED
|
Git LFS Details
|

|
Git LFS Details
|
samples/unet_960x1280_0.jpg
CHANGED
|
Git LFS Details
|

|
Git LFS Details
|
test.ipynb
CHANGED
|
@@ -1,3 +1,3 @@
|
|
| 1 |
version https://git-lfs.github.com/spec/v1
|
| 2 |
-
oid sha256:
|
| 3 |
-
size
|
|
|
|
| 1 |
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:faf7be1e5cdebb1b6183b35157a275dff605c4a03ade67a19da702b683b658c7
|
| 3 |
+
size 5815496
|
unet/diffusion_pytorch_model.safetensors
CHANGED
|
@@ -1,3 +1,3 @@
|
|
| 1 |
version https://git-lfs.github.com/spec/v1
|
| 2 |
-
oid sha256:
|
| 3 |
size 6318956752
|
|
|
|
| 1 |
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:de4e90a0bfd3a0448c78356a6e727f406e56f8517dbd2dc2d448a69b139fb9b3
|
| 3 |
size 6318956752
|