

Adapter v12 in the DiT: 2304-slot position table, trained at the real edit geometry
Browse filesThe bundled text_fusion is now revision v12 (vision cosine against the native Qwen3-VL-8B encoder
0.930 -> 0.971, text unchanged at 0.951/24.2%). Two things moved: the attention-branch position table
covers 2304 slots, and the fine-tune ran at the real inference geometry (--geom 1024), so the ~2000
token condition of a two-image edit no longer falls into a zero-padded tail.
transformer/config.json text_fusion_config.max_len goes 512 -> 2304 to match the table; the model card,
the conditioning row and the card media are re-rendered with the shipped weights.
- README.md +10 -2
- media/edit_char.jpg +2 -2
- media/edit_single.jpg +2 -2
- media/edit_swap.jpg +2 -2
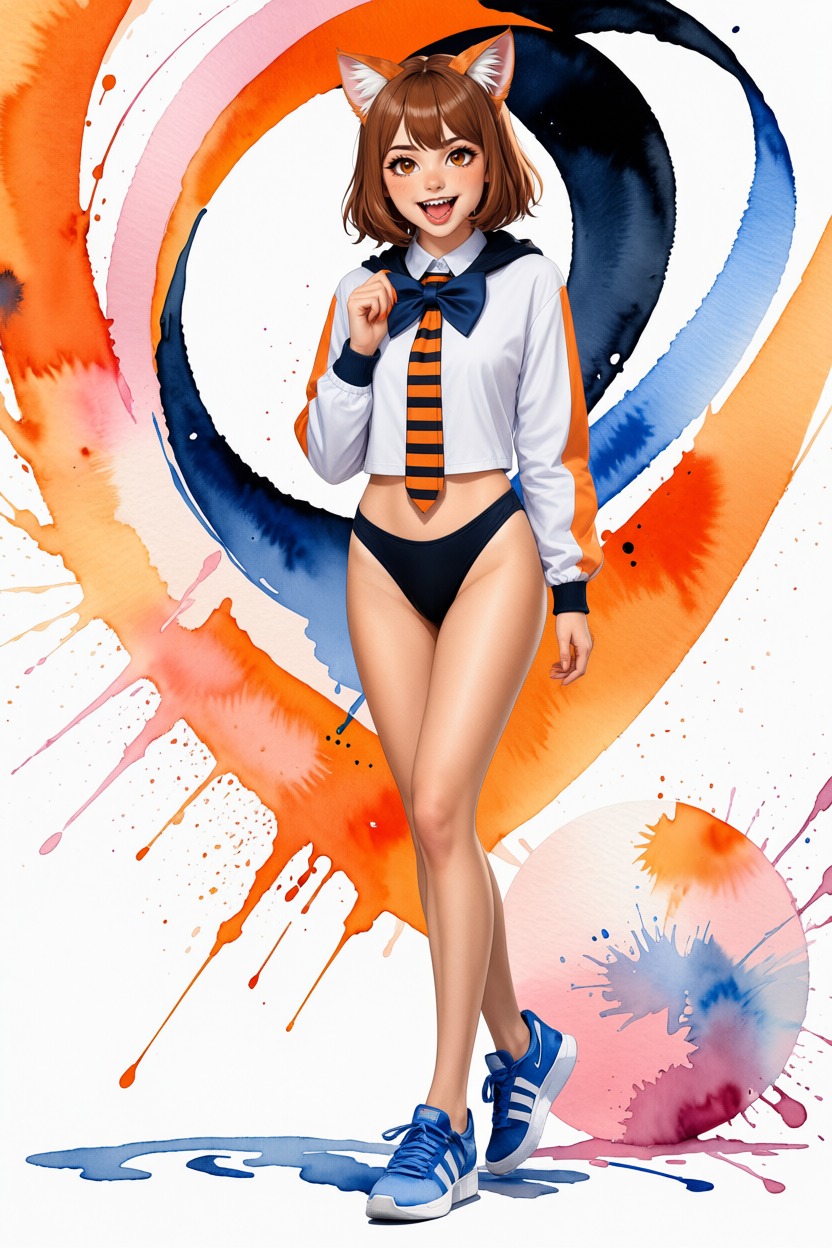
- media/edit_three.jpg +2 -2
- media/limit_numbers.jpg +2 -2
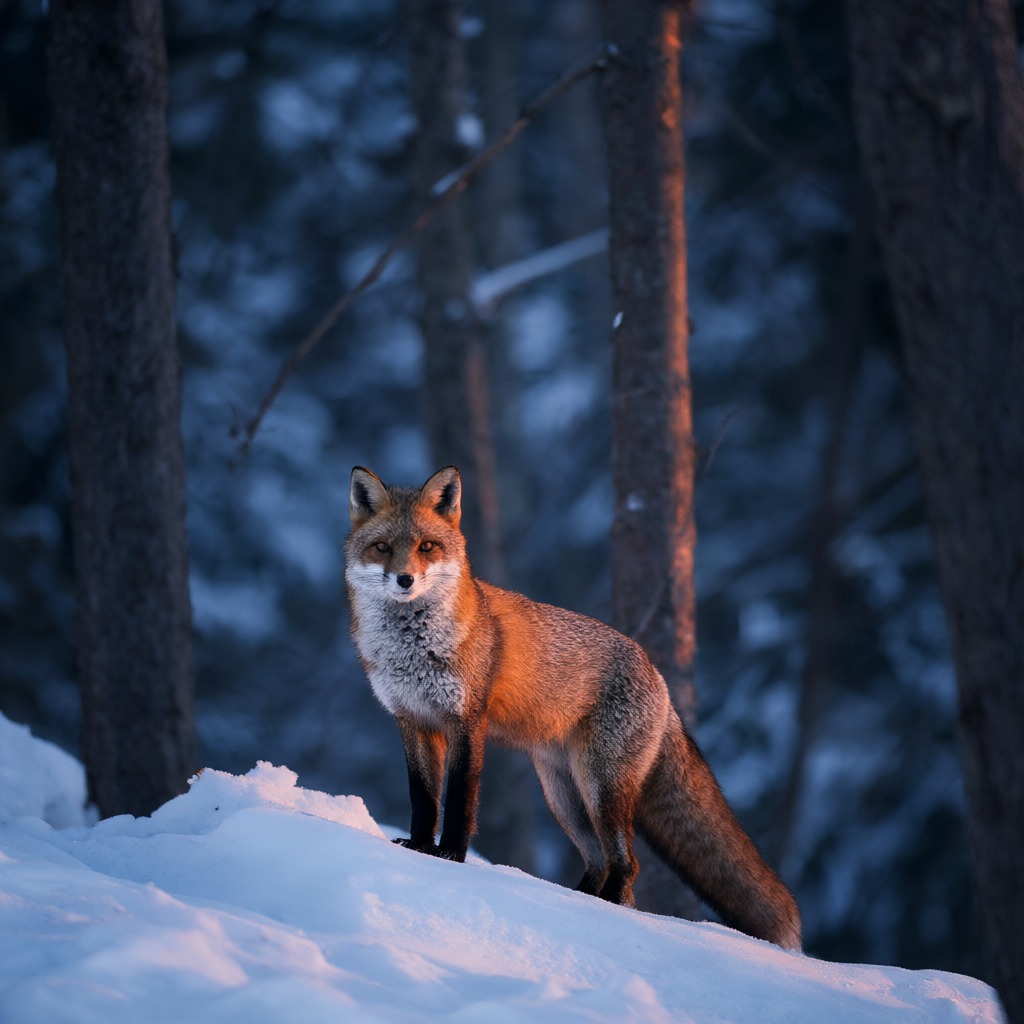
- media/t2i.jpg +2 -2
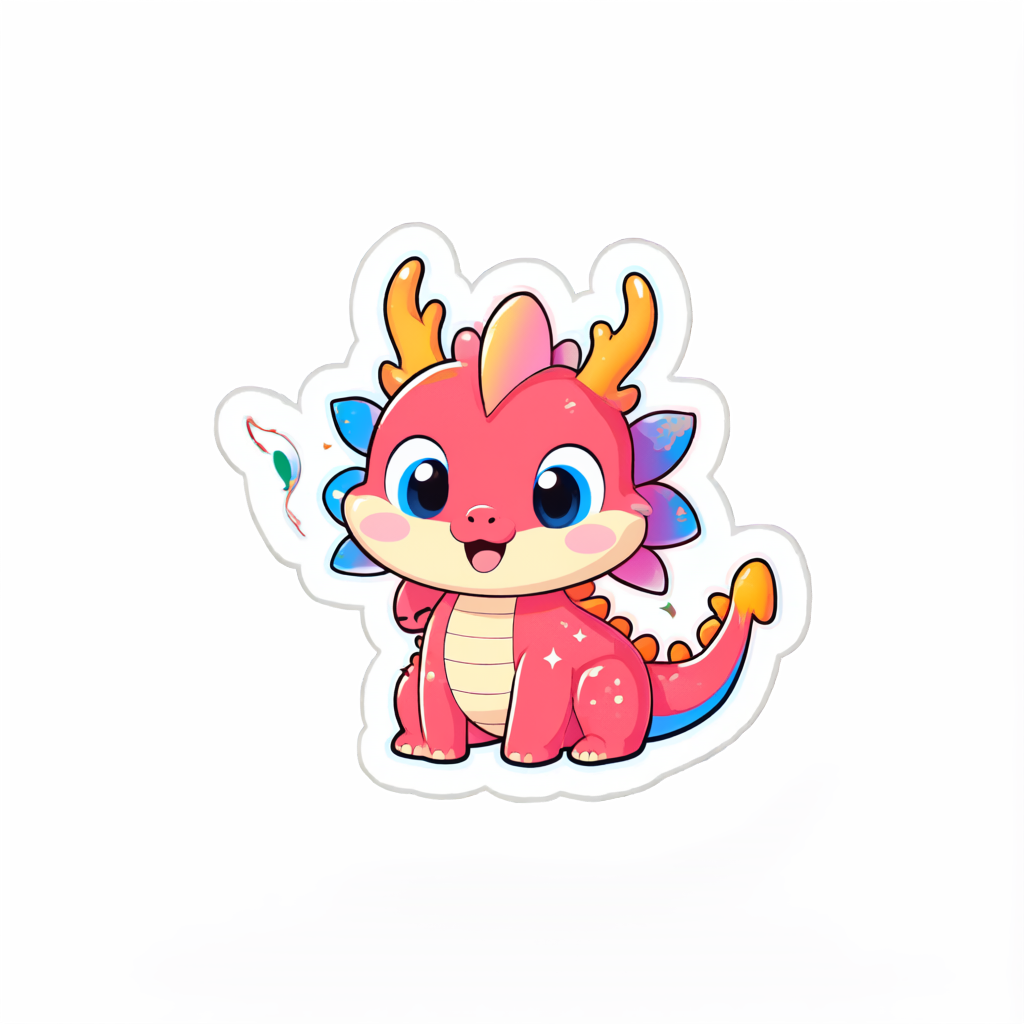
- media/transparent.png +2 -2
- transformer/config.json +1 -1
- transformer/diffusion_pytorch_model-00001-of-00002.safetensors +2 -2
README.md
CHANGED
|
@@ -28,7 +28,7 @@ Text-to-image, character and scene editing, and transparent (RGBA) generation in
|
|
| 28 |
|---|---|
|
| 29 |
| transformer | Qwen-Image-2.1 DiT — 32 layers, 14.5 GB fp16, plus a **158M text-fusion adapter** inside |
|
| 30 |
| text encoder | **Qwen3.5-0.8B**, 1.7 GB fp16 — upstream checkpoint re-saved to fp16, tokenizer/processor files unchanged (native: Qwen3-VL-8B, 17.5 GB) |
|
| 31 |
-
| conditioning | cosine **0.
|
| 32 |
| VAE | Qwen-Image-2.1, 16× spatial, fp32 |
|
| 33 |
| scheduler | `FlowMatchEulerDiscreteScheduler`, plain static shift 5.0 (dynamic shifting off) |
|
| 34 |
| resolution | `output_resolution`, 1024 by default; follows the condition image aspect ratio |
|
|
@@ -43,6 +43,11 @@ images (**Improved using Qwen**). The adapter lives *inside* the DiT as its text
|
|
| 43 |
whole model is one self-contained diffusers folder and no 17.5 GB encoder is needed anywhere. The
|
| 44 |
sampler runs a plain static shift of 5.0 instead of the original dynamic shifting.
|
| 45 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 46 |
### Examples
|
| 47 |
|
| 48 |
Every image below is generated by this pipeline with 30 steps at 1024 px.
|
|
@@ -64,7 +69,8 @@ pose, clothing and scene; the identity is copied from `<image2>`)
|
|
| 64 |
|---|---|
|
| 65 |
|  |  |
|
| 66 |
|
| 67 |
-
**Edit — three condition images** (
|
|
|
|
| 68 |
|
| 69 |

|
| 70 |
|
|
@@ -170,6 +176,8 @@ would not find the DiT class.
|
|
| 170 |
* **English only** — that is all the adapter was trained and tested on; other languages drift.
|
| 171 |
* **Numerals on signage** come out wrong: "OPEN 24 HOURS" renders as "OPEN **26** HOURS" on every
|
| 172 |
seed tried. Words are fine. 
|
|
|
|
|
|
|
| 173 |
* Batch size >1 at 1024 px peaks near 28 GB; one prompt per call is the safe mode.
|
| 174 |
|
| 175 |
### NOTICE
|
|
|
|
| 28 |
|---|---|
|
| 29 |
| transformer | Qwen-Image-2.1 DiT — 32 layers, 14.5 GB fp16, plus a **158M text-fusion adapter** inside |
|
| 30 |
| text encoder | **Qwen3.5-0.8B**, 1.7 GB fp16 — upstream checkpoint re-saved to fp16, tokenizer/processor files unchanged (native: Qwen3-VL-8B, 17.5 GB) |
|
| 31 |
+
| conditioning | cosine **0.95** on text, **0.97** on the vision positions of edit prompts, against the native Qwen3-VL-8B encoder |
|
| 32 |
| VAE | Qwen-Image-2.1, 16× spatial, fp32 |
|
| 33 |
| scheduler | `FlowMatchEulerDiscreteScheduler`, plain static shift 5.0 (dynamic shifting off) |
|
| 34 |
| resolution | `output_resolution`, 1024 by default; follows the condition image aspect ratio |
|
|
|
|
| 43 |
whole model is one self-contained diffusers folder and no 17.5 GB encoder is needed anywhere. The
|
| 44 |
sampler runs a plain static shift of 5.0 instead of the original dynamic shifting.
|
| 45 |
|
| 46 |
+
The bundled adapter is revision **v12**: its attention-branch position table covers 2304 slots and it
|
| 47 |
+
was fine-tuned at the real inference geometry (~2000-token conditions at 1024 px), so reference images
|
| 48 |
+
keep their positions instead of falling into a zero-padded tail — the vision cosine against the native
|
| 49 |
+
encoder moved 0.93 → 0.97, text stayed at 0.95.
|
| 50 |
+
|
| 51 |
### Examples
|
| 52 |
|
| 53 |
Every image below is generated by this pipeline with 30 steps at 1024 px.
|
|
|
|
| 69 |
|---|---|
|
| 70 |
|  |  |
|
| 71 |
|
| 72 |
+
**Edit — three condition images** (target and composition from `<image1>`, the person from `<image2>`,
|
| 73 |
+
colour and lighting from `<image3>`)
|
| 74 |
|
| 75 |

|
| 76 |
|
|
|
|
| 176 |
* **English only** — that is all the adapter was trained and tested on; other languages drift.
|
| 177 |
* **Numerals on signage** come out wrong: "OPEN 24 HOURS" renders as "OPEN **26** HOURS" on every
|
| 178 |
seed tried. Words are fine. 
|
| 179 |
+
* **Non-photo references transfer less faithfully** than photographic ones: the adapter imitates the
|
| 180 |
+
native encoder, so its ceiling is the native encoder's ceiling.
|
| 181 |
* Batch size >1 at 1024 px peaks near 28 GB; one prompt per call is the safe mode.
|
| 182 |
|
| 183 |
### NOTICE
|
media/edit_char.jpg
CHANGED
|
Git LFS Details
|

|
Git LFS Details
|
media/edit_single.jpg
CHANGED
|
Git LFS Details
|

|
Git LFS Details
|
media/edit_swap.jpg
CHANGED
|
Git LFS Details
|

|
Git LFS Details
|
media/edit_three.jpg
CHANGED

|
Git LFS Details
|
|
Git LFS Details
|
media/limit_numbers.jpg
CHANGED

|
Git LFS Details
|

|
Git LFS Details
|
media/t2i.jpg
CHANGED
|
Git LFS Details
|

|
Git LFS Details
|
media/transparent.png
CHANGED
|
Git LFS Details
|

|
Git LFS Details
|
transformer/config.json
CHANGED
|
@@ -26,7 +26,7 @@
|
|
| 26 |
"attention": 2,
|
| 27 |
"attn_dim": 1024,
|
| 28 |
"attn_heads": 8,
|
| 29 |
-
"max_len":
|
| 30 |
"mixer": 2,
|
| 31 |
"mixer_heads": 8,
|
| 32 |
"mixer_ffn": 2,
|
|
|
|
| 26 |
"attention": 2,
|
| 27 |
"attn_dim": 1024,
|
| 28 |
"attn_heads": 8,
|
| 29 |
+
"max_len": 2304,
|
| 30 |
"mixer": 2,
|
| 31 |
"mixer_heads": 8,
|
| 32 |
"mixer_ffn": 2,
|
transformer/diffusion_pytorch_model-00001-of-00002.safetensors
CHANGED
|
@@ -1,3 +1,3 @@
|
|
| 1 |
version https://git-lfs.github.com/spec/v1
|
| 2 |
-
oid sha256:
|
| 3 |
-
size
|
|
|
|
| 1 |
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:3e706b011865bbcf5e36c9a62e189549179de9fcbf8c886afc110ce2b30992bc
|
| 3 |
+
size 10287829484
|