

Fix the editing convention: the FIRST image is the target, not the last
Browse filesThe tag/build order in the usage example was inverted, which made swaps silently fail: the model
edits <image1>, so passing the reference first asks it to edit the reference. Verified on one pair
both ways (identity transfers only with the target first); the two edit examples in media/ are
regenerated with the correct order.
- README.md +12 -4
- example.py +4 -3
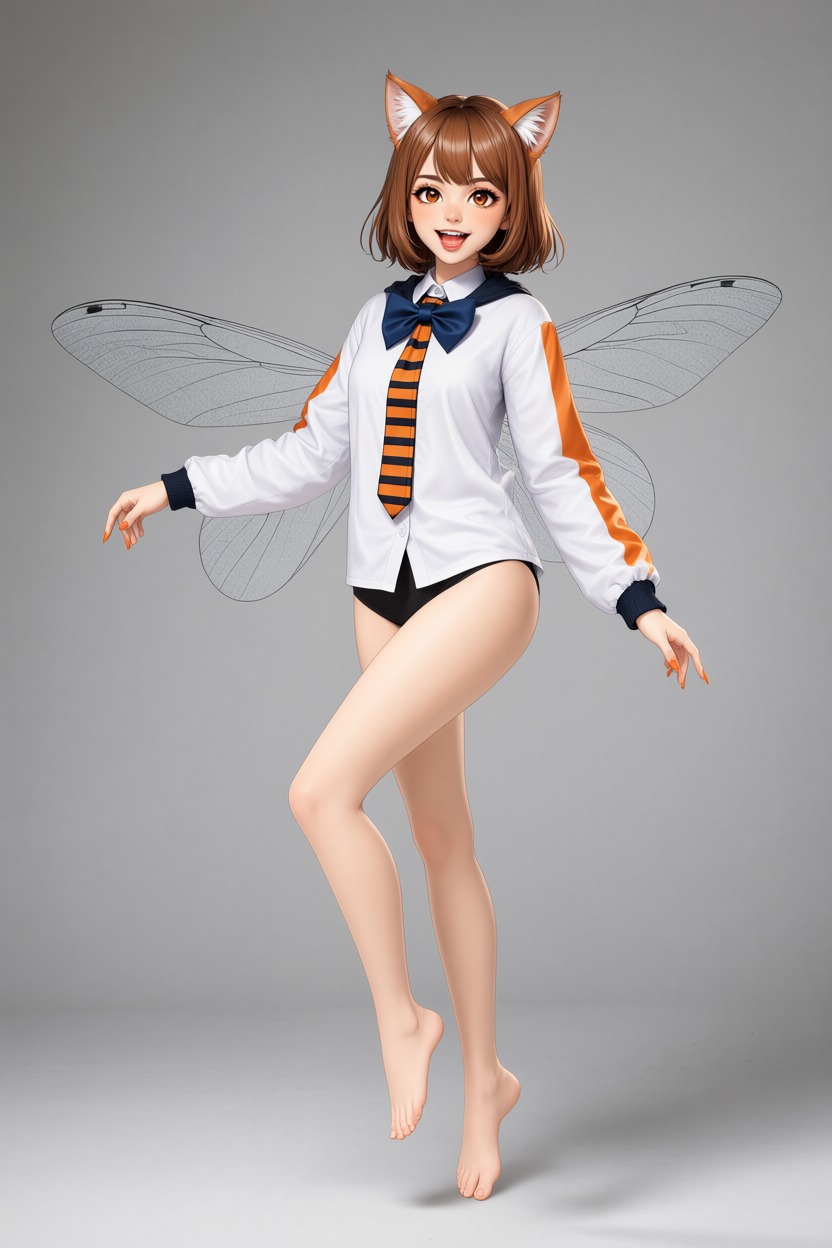
- media/edit_char.jpg +2 -2
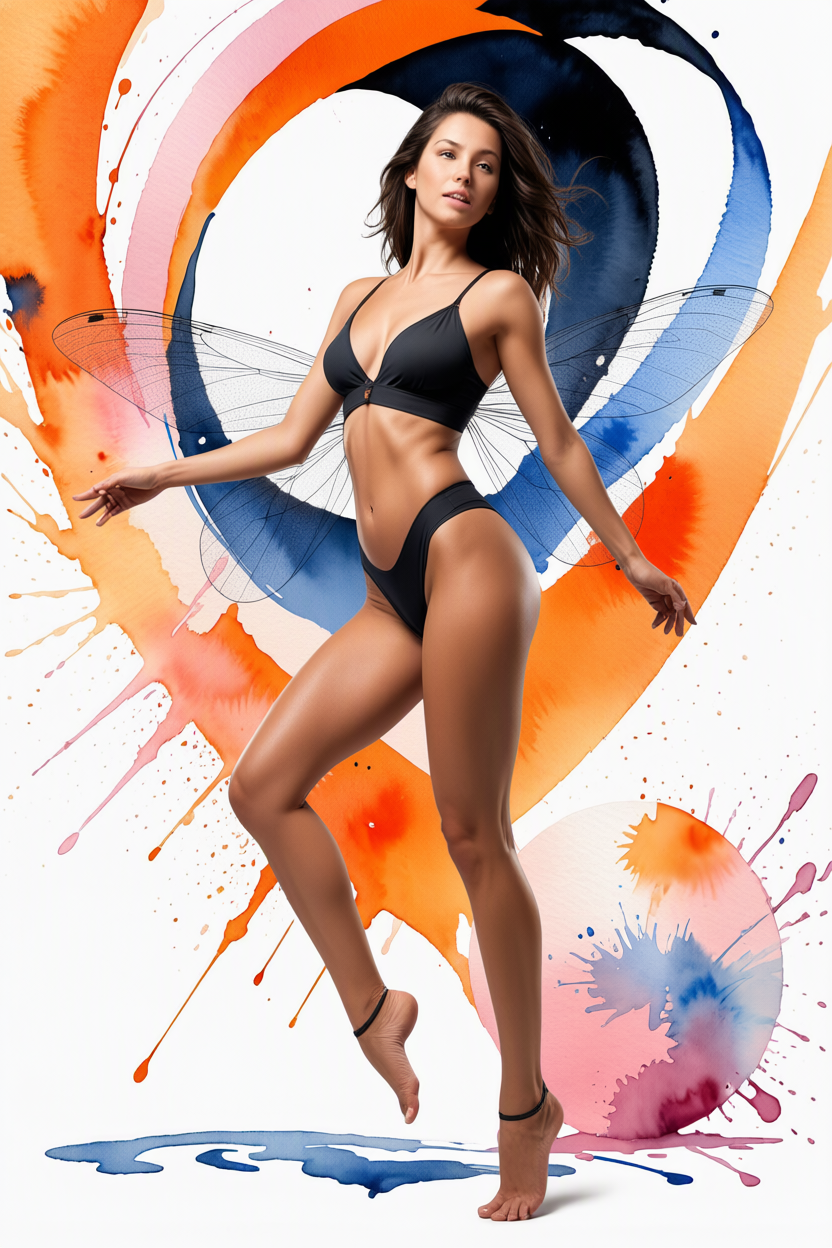
- media/edit_swap.jpg +2 -2
README.md
CHANGED
|
@@ -57,7 +57,8 @@ Every image below is generated by this pipeline with 30 steps at 1024 px.
|
|
| 57 |
|
| 58 |

|
| 59 |
|
| 60 |
-
**Edit — two condition images** (character replacement:
|
|
|
|
| 61 |
|
| 62 |
| | |
|
| 63 |
|---|---|
|
|
@@ -86,14 +87,21 @@ image = pipe(prompt="a red fox in a snowy forest at dusk, cinematic, 85mm",
|
|
| 86 |
output_resolution=1024, num_inference_steps=30,
|
| 87 |
generator=torch.Generator("cuda").manual_seed(1234)).images[0]
|
| 88 |
|
| 89 |
-
# editing: 1..N condition images
|
| 90 |
-
|
|
|
|
| 91 |
"clothing and background unchanged.",
|
| 92 |
-
image=[
|
| 93 |
output_resolution=1024, num_inference_steps=30,
|
| 94 |
generator=torch.Generator("cuda").manual_seed(1234)).images[0]
|
| 95 |
```
|
| 96 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 97 |
`custom_pipeline="pipeline"` builds the shipped `pipeline.py` and `trust_remote_code=True` lets it run,
|
| 98 |
so no clone is needed. (`_class_name` is kept a plain string in `model_index.json` because that is what
|
| 99 |
Hub tooling expects; the `[file, class]` form diffusers also accepts makes the Hub print a
|
|
|
|
| 57 |
|
| 58 |

|
| 59 |
|
| 60 |
+
**Edit — two condition images** (character replacement: `<image1>` is the edit target and keeps its
|
| 61 |
+
pose, clothing and scene; the identity is copied from `<image2>`)
|
| 62 |
|
| 63 |
| | |
|
| 64 |
|---|---|
|
|
|
|
| 87 |
output_resolution=1024, num_inference_steps=30,
|
| 88 |
generator=torch.Generator("cuda").manual_seed(1234)).images[0]
|
| 89 |
|
| 90 |
+
# editing: 1..N condition images. The FIRST one is the edit target, the rest are references;
|
| 91 |
+
# reference them in the prompt by TAG <image1>, <image2>, ...
|
| 92 |
+
image = pipe(prompt="Replace the woman in <image1> with the woman from <image2>; keep <image1> pose, "
|
| 93 |
"clothing and background unchanged.",
|
| 94 |
+
image=[scene_image, ref_image],
|
| 95 |
output_resolution=1024, num_inference_steps=30,
|
| 96 |
generator=torch.Generator("cuda").manual_seed(1234)).images[0]
|
| 97 |
```
|
| 98 |
|
| 99 |
+
Editing convention: the **first** image is the one being edited (`<image1>`), everything after it is a
|
| 100 |
+
reference. That is the model's own convention and what the stock ComfyUI node documents; feeding the
|
| 101 |
+
reference first is the usual reason a swap "does not happen" (the model then edits the reference).
|
| 102 |
+
Note that the *canvas size* still comes from the last image's aspect ratio — pass `height`/`width`
|
| 103 |
+
explicitly to pin it.
|
| 104 |
+
|
| 105 |
`custom_pipeline="pipeline"` builds the shipped `pipeline.py` and `trust_remote_code=True` lets it run,
|
| 106 |
so no clone is needed. (`_class_name` is kept a plain string in `model_index.json` because that is what
|
| 107 |
Hub tooling expects; the `[file, class]` form diffusers also accepts makes the Hub print a
|
example.py
CHANGED
|
@@ -7,9 +7,10 @@ On the GPU: Qwen3.5-0.8B (~1.7 GB), the DiT with the adapter inside (~14.5 GB) a
|
|
| 7 |
# text-to-image
|
| 8 |
python example.py --prompt "a red fox in a snowy forest at dusk, cinematic, 85mm" --out fox.png
|
| 9 |
|
| 10 |
-
# editing: 1..N condition images
|
| 11 |
-
|
| 12 |
-
|
|
|
|
| 13 |
clothing and background unchanged." --out swap.png
|
| 14 |
|
| 15 |
# a batch from a text file: one prompt per line, '#' starts a comment, blank lines are skipped
|
|
|
|
| 7 |
# text-to-image
|
| 8 |
python example.py --prompt "a red fox in a snowy forest at dusk, cinematic, 85mm" --out fox.png
|
| 9 |
|
| 10 |
+
# editing: 1..N condition images. The FIRST one is the edit target, the rest are references;
|
| 11 |
+
# the prompt refers to them as <image1>, <image2>, ...
|
| 12 |
+
python example.py --image scene.png ref.png \
|
| 13 |
+
--prompt "Replace the woman in <image1> with the woman from <image2>; keep <image1> pose, \\
|
| 14 |
clothing and background unchanged." --out swap.png
|
| 15 |
|
| 16 |
# a batch from a text file: one prompt per line, '#' starts a comment, blank lines are skipped
|
media/edit_char.jpg
CHANGED

|
Git LFS Details
|
|
Git LFS Details
|
media/edit_swap.jpg
CHANGED

|
Git LFS Details
|
|
Git LFS Details
|