

Add 25 LoRA(s): thigh-gap-slider-krea2, 70s-giallo-thriller, schoolgirl-outfit, hair-volume-slider-krea2-zit…
Browse filesThis view is limited to 50 files because it contains too many changes. See raw diff
- .gitattributes +146 -0
- 70s-giallo-thriller/70sGialloThrillerKrea2Raw.safetensors +3 -0
- 70s-giallo-thriller/example_images/01_image.jpeg +3 -0
- 70s-giallo-thriller/example_images/02_image.jpeg +3 -0
- 70s-giallo-thriller/example_images/03_image.jpeg +3 -0
- 70s-giallo-thriller/example_images/04_image.jpeg +3 -0
- 70s-giallo-thriller/example_images/05_image.jpeg +3 -0
- 70s-giallo-thriller/example_images/06_image.jpeg +3 -0
- 70s-giallo-thriller/info.txt +278 -0
- 70s-giallo-thriller/metadata.json +134 -0
- 90s-gothic-boudoir/90sVampBoudoirKrea2Raw.safetensors +3 -0
- 90s-gothic-boudoir/example_images/01_image.jpeg +3 -0
- 90s-gothic-boudoir/example_images/02_image.jpeg +3 -0
- 90s-gothic-boudoir/example_images/03_image.jpeg +3 -0
- 90s-gothic-boudoir/example_images/04_image.jpeg +3 -0
- 90s-gothic-boudoir/example_images/05_image.jpeg +3 -0
- 90s-gothic-boudoir/example_images/06_image.jpeg +3 -0
- 90s-gothic-boudoir/info.txt +278 -0
- 90s-gothic-boudoir/metadata.json +137 -0
- between-pages/Between Pages - Krea2_000002750.safetensors +3 -0
- between-pages/example_images/01_image.jpeg +3 -0
- between-pages/example_images/02_image.jpeg +3 -0
- between-pages/example_images/03_image.jpeg +3 -0
- between-pages/example_images/04_image.jpeg +3 -0
- between-pages/example_images/05_image.jpeg +3 -0
- between-pages/example_images/06_image.jpeg +3 -0
- between-pages/info.txt +363 -0
- between-pages/metadata.json +141 -0
- cutecaption-ultrainsta-the-ultimate-influencer-character/example_images/01_image.jpeg +3 -0
- cutecaption-ultrainsta-the-ultimate-influencer-character/example_images/02_image.jpeg +0 -0
- cutecaption-ultrainsta-the-ultimate-influencer-character/example_images/03_image.jpeg +3 -0
- cutecaption-ultrainsta-the-ultimate-influencer-character/example_images/04_image.jpeg +3 -0
- cutecaption-ultrainsta-the-ultimate-influencer-character/example_images/05_image.jpeg +3 -0
- cutecaption-ultrainsta-the-ultimate-influencer-character/example_images/06_image.jpeg +3 -0
- cutecaption-ultrainsta-the-ultimate-influencer-character/info.txt +400 -0
- cutecaption-ultrainsta-the-ultimate-influencer-character/metadata.json +150 -0
- cutecaption-ultrainsta-the-ultimate-influencer-character/ultrainsta_krea2_V3_000004995.safetensors +3 -0
- desi-dark-lora-for-indian-south-asian-faces-and-darker/D351_D4rk_Krea2_Turbo_v1.safetensors +3 -0
- desi-dark-lora-for-indian-south-asian-faces-and-darker/example_images/01_image.jpeg +3 -0
- desi-dark-lora-for-indian-south-asian-faces-and-darker/example_images/02_poster.jpg +0 -0
- desi-dark-lora-for-indian-south-asian-faces-and-darker/example_images/02_video.mp4 +3 -0
- desi-dark-lora-for-indian-south-asian-faces-and-darker/example_images/03_image.jpeg +3 -0
- desi-dark-lora-for-indian-south-asian-faces-and-darker/example_images/04_image.jpeg +3 -0
- desi-dark-lora-for-indian-south-asian-faces-and-darker/example_images/05_image.jpeg +3 -0
- desi-dark-lora-for-indian-south-asian-faces-and-darker/example_images/06_image.jpeg +3 -0
- desi-dark-lora-for-indian-south-asian-faces-and-darker/info.txt +267 -0
- desi-dark-lora-for-indian-south-asian-faces-and-darker/metadata.json +142 -0
- feet/example_images/01_image.jpeg +3 -0
- feet/example_images/02_image.jpeg +3 -0
- feet/example_images/03_image.jpeg +3 -0
.gitattributes
CHANGED
|
@@ -1316,3 +1316,149 @@ elusarca-s-krea-2-smartphone-photography-slider-lora/example_images/03_image.jpe
|
|
| 1316 |
elusarca-s-krea-2-smartphone-photography-slider-lora/example_images/04_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1317 |
elusarca-s-krea-2-smartphone-photography-slider-lora/example_images/05_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1318 |
elusarca-s-krea-2-smartphone-photography-slider-lora/example_images/06_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1316 |
elusarca-s-krea-2-smartphone-photography-slider-lora/example_images/04_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1317 |
elusarca-s-krea-2-smartphone-photography-slider-lora/example_images/05_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1318 |
elusarca-s-krea-2-smartphone-photography-slider-lora/example_images/06_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1319 |
+
thigh-gap-slider-krea2/example_images/01_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1320 |
+
thigh-gap-slider-krea2/example_images/02_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1321 |
+
thigh-gap-slider-krea2/example_images/03_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1322 |
+
thigh-gap-slider-krea2/example_images/04_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1323 |
+
thigh-gap-slider-krea2/example_images/05_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1324 |
+
thigh-gap-slider-krea2/example_images/06_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1325 |
+
70s-giallo-thriller/example_images/01_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1326 |
+
70s-giallo-thriller/example_images/02_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1327 |
+
70s-giallo-thriller/example_images/03_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1328 |
+
70s-giallo-thriller/example_images/04_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1329 |
+
70s-giallo-thriller/example_images/05_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1330 |
+
70s-giallo-thriller/example_images/06_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1331 |
+
schoolgirl-outfit/example_images/01_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1332 |
+
schoolgirl-outfit/example_images/02_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1333 |
+
schoolgirl-outfit/example_images/03_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1334 |
+
hair-volume-slider-krea2-zit/example_images/01_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1335 |
+
hair-volume-slider-krea2-zit/example_images/02_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1336 |
+
hair-volume-slider-krea2-zit/example_images/03_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1337 |
+
hair-volume-slider-krea2-zit/example_images/04_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1338 |
+
hair-volume-slider-krea2-zit/example_images/05_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1339 |
+
hair-volume-slider-krea2-zit/example_images/06_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1340 |
+
players-handbook-style-don-t-split-the-party-anima-3p-krea2/example_images/01_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1341 |
+
players-handbook-style-don-t-split-the-party-anima-3p-krea2/example_images/02_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1342 |
+
players-handbook-style-don-t-split-the-party-anima-3p-krea2/example_images/03_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1343 |
+
players-handbook-style-don-t-split-the-party-anima-3p-krea2/example_images/04_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1344 |
+
players-handbook-style-don-t-split-the-party-anima-3p-krea2/example_images/05_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1345 |
+
players-handbook-style-don-t-split-the-party-anima-3p-krea2/example_images/06_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1346 |
+
krea-2-realistic-skin-texture/example_images/01_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1347 |
+
krea-2-realistic-skin-texture/example_images/02_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1348 |
+
krea-2-realistic-skin-texture/example_images/03_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1349 |
+
krea-2-realistic-skin-texture/example_images/04_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1350 |
+
krea-2-realistic-skin-texture/example_images/05_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1351 |
+
krea-2-realistic-skin-texture/example_images/06_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1352 |
+
z3zz4-krea-2/example_images/01_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1353 |
+
z3zz4-krea-2/example_images/02_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1354 |
+
z3zz4-krea-2/example_images/03_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1355 |
+
z3zz4-krea-2/example_images/04_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1356 |
+
z3zz4-krea-2/example_images/05_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1357 |
+
z3zz4-krea-2/example_images/06_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1358 |
+
cutecaption-ultrainsta-the-ultimate-influencer-character/example_images/01_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1359 |
+
cutecaption-ultrainsta-the-ultimate-influencer-character/example_images/03_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1360 |
+
cutecaption-ultrainsta-the-ultimate-influencer-character/example_images/04_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1361 |
+
cutecaption-ultrainsta-the-ultimate-influencer-character/example_images/05_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1362 |
+
cutecaption-ultrainsta-the-ultimate-influencer-character/example_images/06_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1363 |
+
between-pages/example_images/01_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1364 |
+
between-pages/example_images/02_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1365 |
+
between-pages/example_images/03_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1366 |
+
between-pages/example_images/04_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1367 |
+
between-pages/example_images/05_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1368 |
+
between-pages/example_images/06_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1369 |
+
quasarcake-style-anima-krea-2/example_images/01_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1370 |
+
quasarcake-style-anima-krea-2/example_images/02_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1371 |
+
quasarcake-style-anima-krea-2/example_images/03_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1372 |
+
quasarcake-style-anima-krea-2/example_images/04_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1373 |
+
quasarcake-style-anima-krea-2/example_images/05_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1374 |
+
quasarcake-style-anima-krea-2/example_images/06_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1375 |
+
desi-dark-lora-for-indian-south-asian-faces-and-darker/example_images/01_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1376 |
+
desi-dark-lora-for-indian-south-asian-faces-and-darker/example_images/02_video.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 1377 |
+
desi-dark-lora-for-indian-south-asian-faces-and-darker/example_images/03_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1378 |
+
desi-dark-lora-for-indian-south-asian-faces-and-darker/example_images/04_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1379 |
+
desi-dark-lora-for-indian-south-asian-faces-and-darker/example_images/05_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1380 |
+
desi-dark-lora-for-indian-south-asian-faces-and-darker/example_images/06_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1381 |
+
rly-thot-shot-jessi-krea-2-zib-zit/example_images/01_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1382 |
+
rly-thot-shot-jessi-krea-2-zib-zit/example_images/02_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1383 |
+
rly-thot-shot-jessi-krea-2-zib-zit/example_images/03_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1384 |
+
rly-thot-shot-jessi-krea-2-zib-zit/example_images/04_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1385 |
+
rly-thot-shot-jessi-krea-2-zib-zit/example_images/05_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1386 |
+
rly-thot-shot-jessi-krea-2-zib-zit/example_images/06_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1387 |
+
krea2-beautiful-lora/example_images/01_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1388 |
+
krea2-beautiful-lora/example_images/02_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1389 |
+
krea2-beautiful-lora/example_images/03_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1390 |
+
krea2-beautiful-lora/example_images/04_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1391 |
+
krea2-beautiful-lora/example_images/05_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1392 |
+
krea2-beautiful-lora/example_images/06_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1393 |
+
90s-gothic-boudoir/example_images/01_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1394 |
+
90s-gothic-boudoir/example_images/02_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1395 |
+
90s-gothic-boudoir/example_images/03_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1396 |
+
90s-gothic-boudoir/example_images/04_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1397 |
+
90s-gothic-boudoir/example_images/05_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1398 |
+
90s-gothic-boudoir/example_images/06_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1399 |
+
shoes-cleavage-krea-2-zit/example_images/01_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1400 |
+
shoes-cleavage-krea-2-zit/example_images/02_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1401 |
+
shoes-cleavage-krea-2-zit/example_images/03_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1402 |
+
shoes-cleavage-krea-2-zit/example_images/04_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1403 |
+
shoes-cleavage-krea-2-zit/example_images/05_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1404 |
+
shoes-cleavage-krea-2-zit/example_images/06_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1405 |
+
sick-dolls-mercy-overwatch/example_images/01_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1406 |
+
sick-dolls-mercy-overwatch/example_images/02_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1407 |
+
sick-dolls-mercy-overwatch/example_images/03_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1408 |
+
sick-dolls-mercy-overwatch/example_images/04_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1409 |
+
sick-dolls-mercy-overwatch/example_images/05_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1410 |
+
sick-dolls-mercy-overwatch/example_images/06_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1411 |
+
moody-gal-weiwei-krea2-zimage/example_images/01_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1412 |
+
moody-gal-weiwei-krea2-zimage/example_images/02_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1413 |
+
moody-gal-weiwei-krea2-zimage/example_images/03_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1414 |
+
moody-gal-weiwei-krea2-zimage/example_images/04_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1415 |
+
moody-gal-weiwei-krea2-zimage/example_images/05_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1416 |
+
moody-gal-weiwei-krea2-zimage/example_images/06_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1417 |
+
finger-drawing-on-a-fogged-glass/example_images/01_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1418 |
+
finger-drawing-on-a-fogged-glass/example_images/02_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1419 |
+
finger-drawing-on-a-fogged-glass/example_images/03_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1420 |
+
finger-drawing-on-a-fogged-glass/example_images/04_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1421 |
+
finger-drawing-on-a-fogged-glass/example_images/05_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1422 |
+
finger-drawing-on-a-fogged-glass/example_images/06_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1423 |
+
sci-fi-mood-krea-2/example_images/01_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1424 |
+
sci-fi-mood-krea-2/example_images/02_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1425 |
+
sci-fi-mood-krea-2/example_images/03_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1426 |
+
sci-fi-mood-krea-2/example_images/04_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1427 |
+
sci-fi-mood-krea-2/example_images/05_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1428 |
+
sci-fi-mood-krea-2/example_images/06_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1429 |
+
krea-2-afterlight/example_images/01_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1430 |
+
krea-2-afterlight/example_images/02_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1431 |
+
krea-2-afterlight/example_images/03_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1432 |
+
krea-2-afterlight/example_images/04_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1433 |
+
krea-2-afterlight/example_images/05_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1434 |
+
krea-2-afterlight/example_images/06_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1435 |
+
herraw/example_images/01_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1436 |
+
herraw/example_images/02_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1437 |
+
herraw/example_images/03_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1438 |
+
herraw/example_images/04_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1439 |
+
herraw/example_images/05_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1440 |
+
herraw/example_images/06_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1441 |
+
feet/example_images/01_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1442 |
+
feet/example_images/02_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1443 |
+
feet/example_images/03_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1444 |
+
feet/example_images/04_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1445 |
+
feet/example_images/05_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1446 |
+
feet/example_images/06_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1447 |
+
krea2-semi-real-illustration-lora-harustyle/example_images/01_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1448 |
+
krea2-semi-real-illustration-lora-harustyle/example_images/02_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1449 |
+
krea2-semi-real-illustration-lora-harustyle/example_images/03_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1450 |
+
krea2-semi-real-illustration-lora-harustyle/example_images/04_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1451 |
+
krea2-semi-real-illustration-lora-harustyle/example_images/05_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1452 |
+
krea2-semi-real-illustration-lora-harustyle/example_images/06_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1453 |
+
krea2-furry/example_images/01_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1454 |
+
krea2-furry/example_images/02_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1455 |
+
krea2-furry/example_images/03_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1456 |
+
krea2-furry/example_images/04_video.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 1457 |
+
krea2-furry/example_images/05_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1458 |
+
krea2-furry/example_images/06_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1459 |
+
sick-dolls-brigette-overwatch/example_images/01_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1460 |
+
sick-dolls-brigette-overwatch/example_images/02_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1461 |
+
sick-dolls-brigette-overwatch/example_images/03_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1462 |
+
sick-dolls-brigette-overwatch/example_images/04_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1463 |
+
sick-dolls-brigette-overwatch/example_images/05_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 1464 |
+
sick-dolls-brigette-overwatch/example_images/06_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
70s-giallo-thriller/70sGialloThrillerKrea2Raw.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:f933bf14f7b49fdb73ce6c2cbd33511751c9e67e722088c1ddbaedd642eb6b47
|
| 3 |
+
size 228587744
|
70s-giallo-thriller/example_images/01_image.jpeg
ADDED
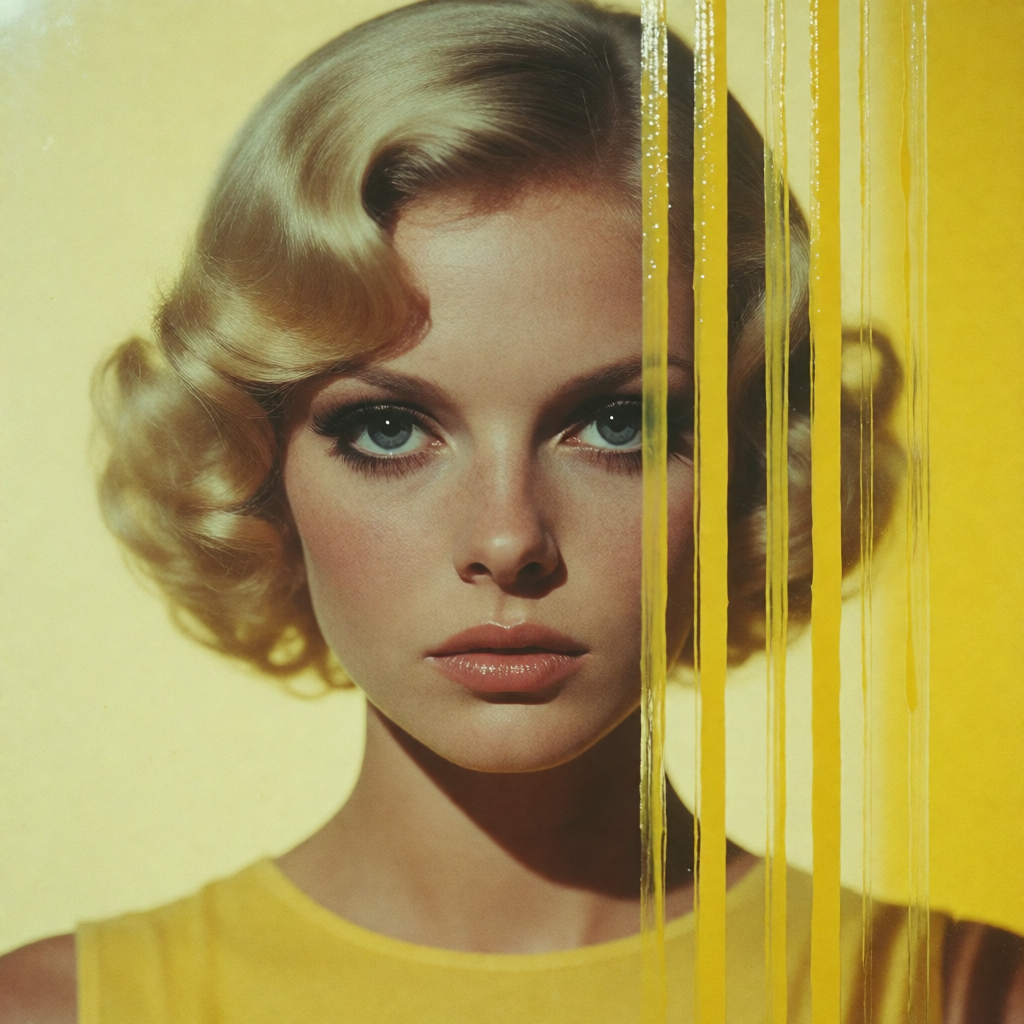
|
Git LFS Details
|
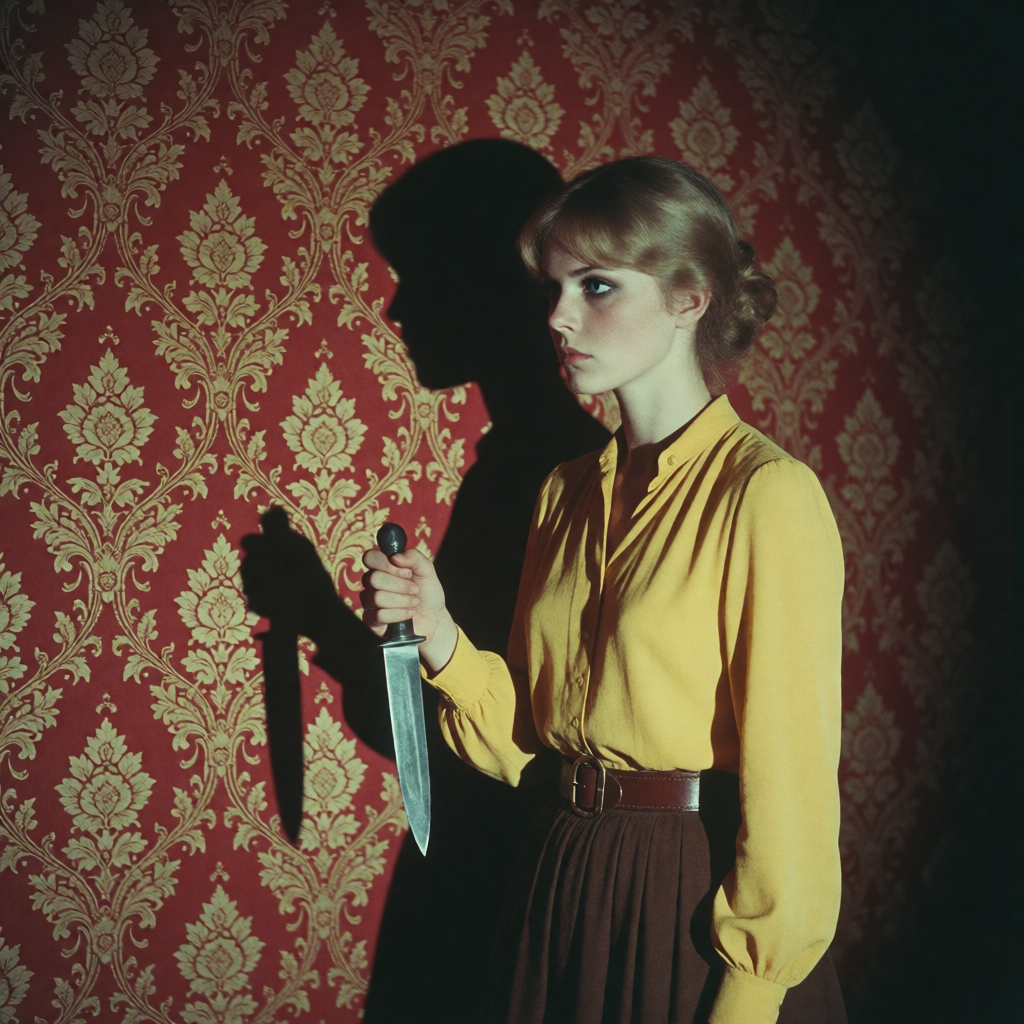
70s-giallo-thriller/example_images/02_image.jpeg
ADDED
|
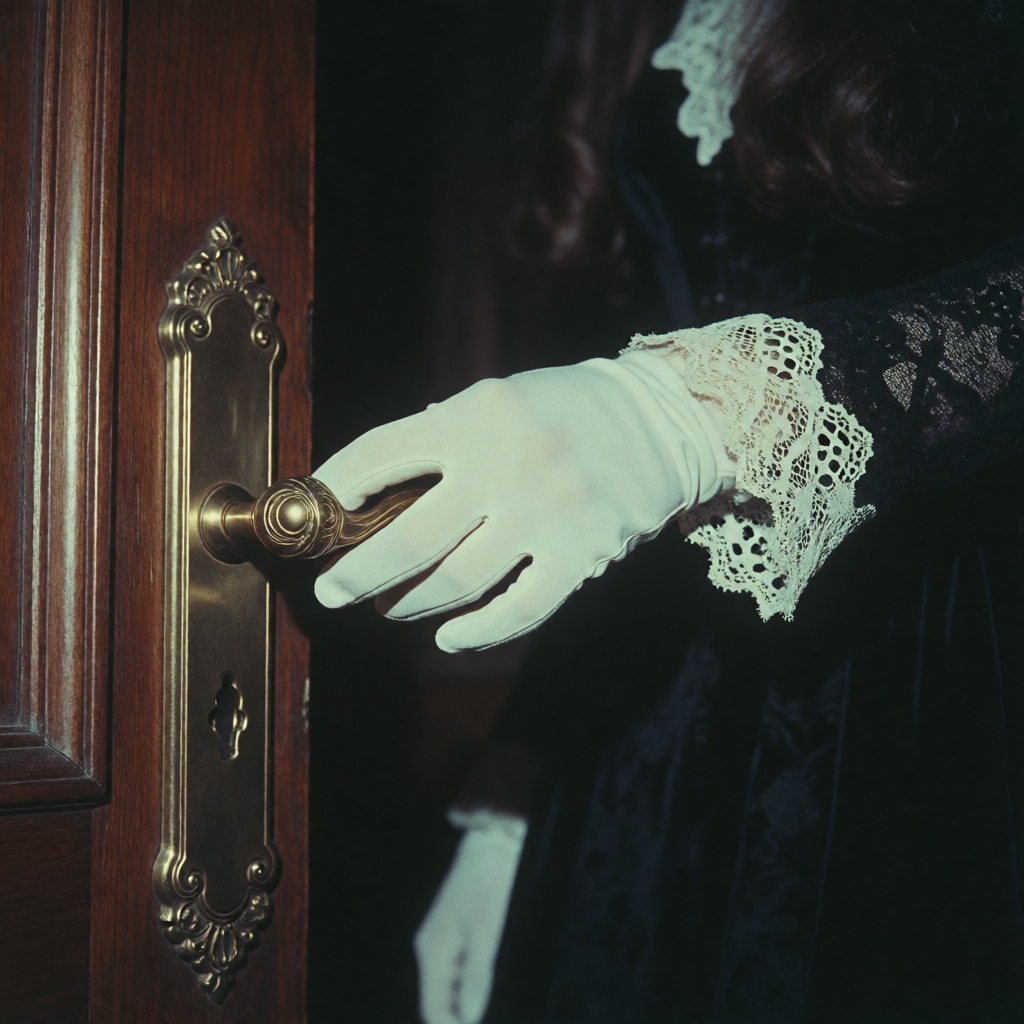
Git LFS Details
|
70s-giallo-thriller/example_images/03_image.jpeg
ADDED
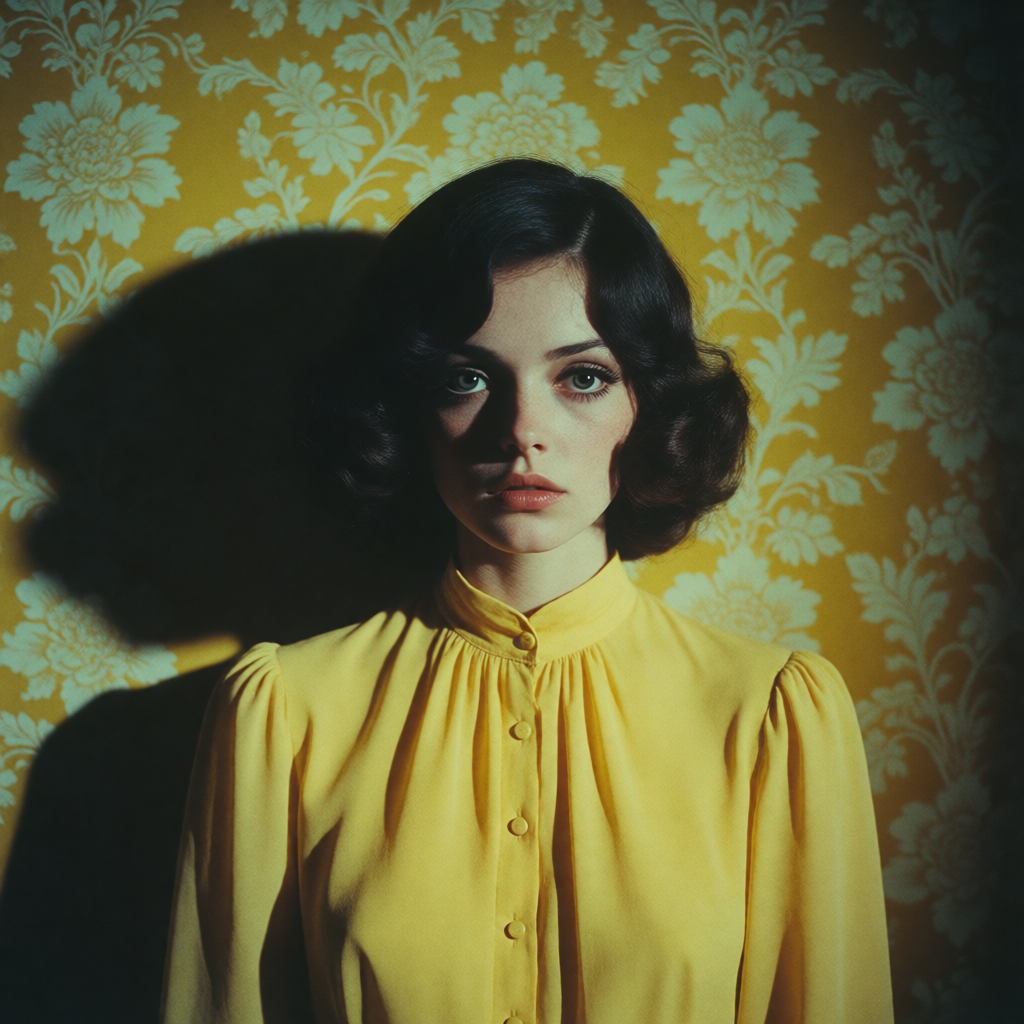
|
Git LFS Details
|
70s-giallo-thriller/example_images/04_image.jpeg
ADDED
|
Git LFS Details
|
70s-giallo-thriller/example_images/05_image.jpeg
ADDED
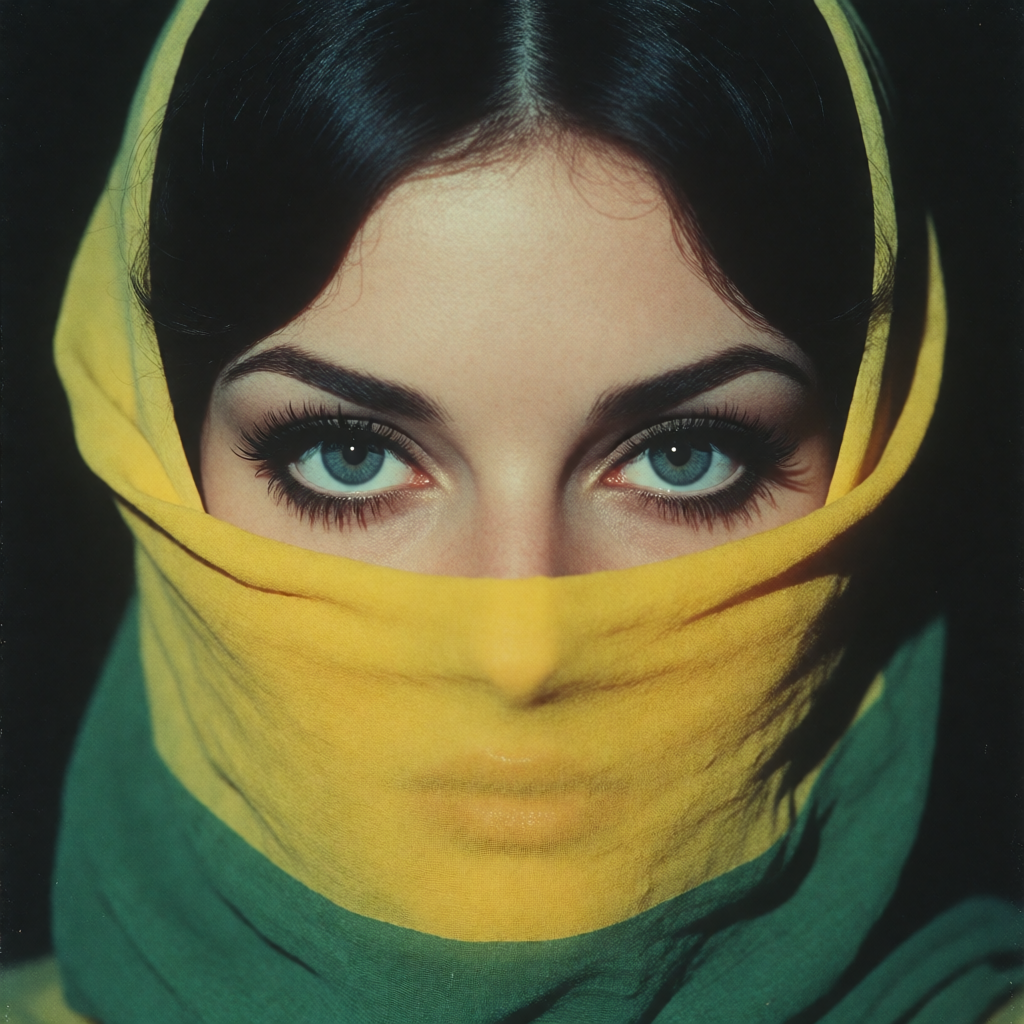
|
Git LFS Details
|
70s-giallo-thriller/example_images/06_image.jpeg
ADDED
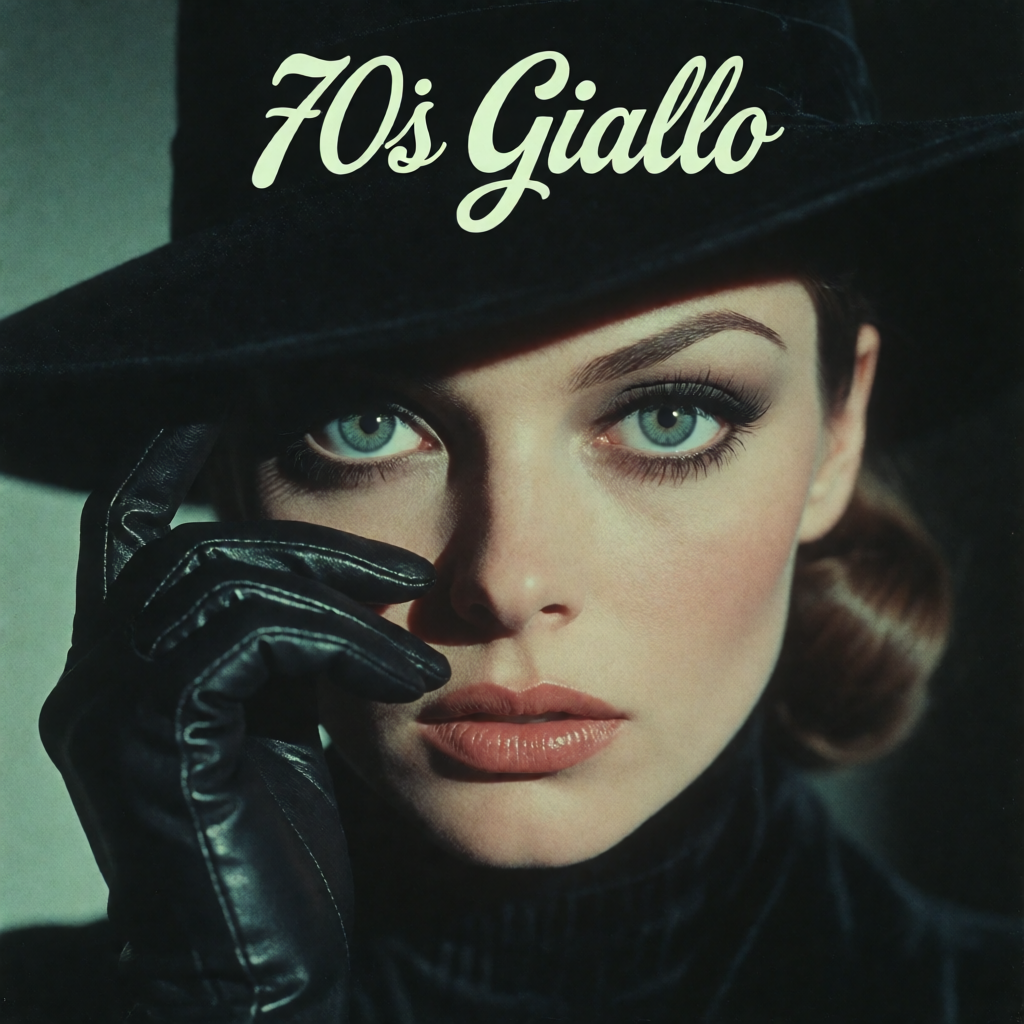
|
Git LFS Details
|
70s-giallo-thriller/info.txt
ADDED
|
@@ -0,0 +1,278 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
═══════════════════════════════════════════════════════════════════════════════
|
| 2 |
+
70S GIALLO THRILLER
|
| 3 |
+
═══════════════════════════════════════════════════════════════════════════════
|
| 4 |
+
|
| 5 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 6 |
+
IDENTITY
|
| 7 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 8 |
+
Base model Krea 2
|
| 9 |
+
Generation mode not declared by the author
|
| 10 |
+
Checkpoint not determined — verify before use
|
| 11 |
+
Category Visual style
|
| 12 |
+
Author ArsMachina
|
| 13 |
+
Source https://civitai.com/models/1743845
|
| 14 |
+
Provenance CivitAI · model 1743845 · version 3183842
|
| 15 |
+
|
| 16 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 17 |
+
WEIGHTS
|
| 18 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 19 |
+
File 70sGialloThrillerKrea2Raw.safetensors
|
| 20 |
+
Version Krea2
|
| 21 |
+
Size 218.0 MB
|
| 22 |
+
Format SafeTensor / unknown precision
|
| 23 |
+
SHA256 f933bf14f7b49fdb73ce6c2cbd33511751c9e67e722088c1ddbaedd642eb6b47
|
| 24 |
+
Published 2026-08-15
|
| 25 |
+
|
| 26 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 27 |
+
TRIGGER WORDS
|
| 28 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 29 |
+
› "Movie still from a 70s Giallo thriller"
|
| 30 |
+
|
| 31 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 32 |
+
RECOMMENDED SETTINGS
|
| 33 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 34 |
+
The author did not publish specific settings.
|
| 35 |
+
No author settings were published. Community baseline: steps Turbo: 8
|
| 36 |
+
(official README and HF card CLI example; the ComfyUI template ships 8).
|
| 37 |
+
Raw: 52 (official README). The krea-2 CLI's generic default is 28.
|
| 38 |
+
Community Turbo LoRAs commonly suggest 8-12 (e.g. the Identity Edit card
|
| 39 |
+
recommends Turbo at 8-12, or Raw at 20 for removals). A community 4-step
|
| 40 |
+
LoRA on Turbo makes 4 valid; its author calls 2 steps an out-of-spec
|
| 41 |
+
preview mode., cfg Turbo: CFG disabled - guidance_scale 0.0 in diffusers
|
| 42 |
+
and --cfg 0.0 in the krea-2 CLI, which is cfg 1.0 in ComfyUI's KSampler
|
| 43 |
+
(the official template ships cfg 1). These are the same thing; do not set
|
| 44 |
+
ComfyUI cfg to 0. Raw: CFG 3.5 (official README; CLI generic default 4.5).
|
| 45 |
+
Negative prompting on Turbo is effectively unused - the official templates
|
| 46 |
+
route ConditioningZeroOut into the negative slot., sampler ComfyUI:
|
| 47 |
+
KSampler with sampler euler, scheduler simple, denoise 1.0 (verified in
|
| 48 |
+
image_krea2_turbo_t2i.json: [seed, 'randomize', 8, 1, 'euler', 'simple',
|
| 49 |
+
1]). Timestep shift mu = 1.15 for Turbo; ComfyUI bakes this in via
|
| 50 |
+
Krea2.sampling_settings = {"multiplier": 1.0, "shift": 1.15}, so the plain
|
| 51 |
+
t2i template needs no ModelSampling node, while the style-reference
|
| 52 |
+
template adds ModelSamplingFlux at max_shift 1.15 / base_shift 0.5. The CLI
|
| 53 |
+
exposes --mu 1.15 for Turbo; Raw uses a resolution-derived mu interpolated
|
| 54 |
+
between --y1 0.5 and --y2 1.15 (ai-toolkit mirrors this as base_shift 0.5 /
|
| 55 |
+
max_shift 1.15 over image_seq_len 256-6400, exponential time shift).,
|
| 56 |
+
resolution 1024x1024 default. Turbo: 1K-2K (the official CLI example
|
| 57 |
+
generates 2048x2048; ComfyUI's ResolutionSelector defaults to 1 megapixel,
|
| 58 |
+
set 2.0 for 2K). Raw: "trained to generate upto 1k resolution".
|
| 59 |
+
Width/height are padded up to a multiple of 16., lora_strength 1.0 for
|
| 60 |
+
Krea's nine official style LoRAs (docs.comfy.org lists Recommended Strength
|
| 61 |
+
1.0 for every one), though the shipped t2i template's LoraLoaderModelOnly
|
| 62 |
+
is set to 0.8. The style-reference LoRA is used at 1.0 in its template. The
|
| 63 |
+
4-step distill LoRA documents 1.0 as its trained point, 1.0-1.5 as coherent
|
| 64 |
+
extrapolation and above ~1.5 as speckle artefacting. Community subject
|
| 65 |
+
LoRAs are typically recommended around 0.8-1.2 and dropped toward 0.6-0.9
|
| 66 |
+
when several are stacked..
|
| 67 |
+
|
| 68 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 69 |
+
ADOPTION & POPULARITY
|
| 70 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 71 |
+
Downloads 3,035
|
| 72 |
+
Rating 100% positive (234/234)
|
| 73 |
+
Comments 0
|
| 74 |
+
Published 21 days ago
|
| 75 |
+
Download rate 27.9/day since release
|
| 76 |
+
|
| 77 |
+
Adoption rank #87 of 200 in this collection (Moderate)
|
| 78 |
+
Momentum rank #152 of 200 by download rate (Long tail · fresh release)
|
| 79 |
+
|
| 80 |
+
Adoption tier is the percentile of total downloads within this collection;
|
| 81 |
+
momentum is the percentile of downloads-per-day since release. Momentum is
|
| 82 |
+
ranked rather than measured against a fixed rate, because this base model
|
| 83 |
+
is itself new and every LoRA looks fast on an absolute scale. Both numbers
|
| 84 |
+
are CivitAI's, read on the scrape date at the foot of this file.
|
| 85 |
+
|
| 86 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 87 |
+
CHAINING / STACKING
|
| 88 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 89 |
+
Stacks with others not stated
|
| 90 |
+
|
| 91 |
+
The author gave no chaining guidance. The rules below are the
|
| 92 |
+
general Krea 2 ones, not anything specific to this LoRA.
|
| 93 |
+
|
| 94 |
+
General Krea 2 rules that apply here (see REFERENCE.txt):
|
| 95 |
+
|
| 96 |
+
• The most important rule is not about chaining but about which
|
| 97 |
+
checkpoint you chain onto: the official README says in bold "TRAIN on
|
| 98 |
+
Raw and RUN on Turbo", and "We highly recommend using RAW for training
|
| 99 |
+
LoRAs and applying them on Turbo for inference." LoRAs trained on Raw
|
| 100 |
+
are stated to work well on Turbo.
|
| 101 |
+
• Chain with LoraLoaderModelOnly nodes in series (model -> model). Krea 2
|
| 102 |
+
LoRAs are DiT-only, so there is no CLIP side to chain and the text-
|
| 103 |
+
encoder branch stays untouched however many LoRAs you add.
|
| 104 |
+
• Krea 2 LoRAs stack in practice and the community treats multi-LoRA as
|
| 105 |
+
routine - style + character, style + slider, realism + character.
|
| 106 |
+
Several CivitAI Krea 2 authors state their LoRAs stack cleanly; one
|
| 107 |
+
writes "I recently stacked over 20 of my own LoRAs on a single
|
| 108 |
+
generation and the output still came out great."
|
| 109 |
+
• Reduce per-LoRA strength when stacking. CivitAI Krea 2 authors converge
|
| 110 |
+
on dropping from ~1.0 to roughly 0.6-0.9 once more than one adapter is
|
| 111 |
+
loaded. The CivitAI 12GB training guide also notes rank affects
|
| 112 |
+
composability: "rank 8 produced a lighter style influence that was
|
| 113 |
+
easier to stack with other LoRAs, rank 16 provided a useful balance
|
| 114 |
+
between concept strength and composability, and rank 32 was better
|
| 115 |
+
suited to a precise object or concept intended to take priority over
|
| 116 |
+
other stacked LoRAs."
|
| 117 |
+
• Accelerator LoRAs are position-sensitive in intent, not in node order:
|
| 118 |
+
a Raw-to-Turbo delta adapter belongs on the Raw checkpoint, a
|
| 119 |
+
sub-8-step LoRA belongs on Turbo (or on Raw already carrying a Raw-to-
|
| 120 |
+
Turbo adapter). Chaining Raw -> Raw-to-Turbo adapter -> 4-step LoRA is
|
| 121 |
+
explicitly recommended by the 4-step LoRA's author.
|
| 122 |
+
• Whatever you stack, the schedule must stay Turbo's: cfg 1.0 in ComfyUI
|
| 123 |
+
(guidance 0.0 in diffusers) and mu/shift 1.15. The 4-step LoRA's card
|
| 124 |
+
says "Keep mu = 1.15. The training targets are anchored to that grid; a
|
| 125 |
+
different shift moves the [sampler off them]"; the same reasoning
|
| 126 |
+
applies to any Turbo-trained adapter in the chain.
|
| 127 |
+
• Reference/edit LoRAs are designed to be stacked under ordinary subject
|
| 128 |
+
and style LoRAs - the Identity Edit card states "Composes with your
|
| 129 |
+
LoRAs: character/body/style LoRAs stack on top and steer the prior" and
|
| 130 |
+
recommends a stacked subject LoRA when unusual subjects drift toward
|
| 131 |
+
the base prior.
|
| 132 |
+
• Krea 2 LoRAs cannot be chained with LoRAs for any other base model.
|
| 133 |
+
Many CivitAI pages carry multi-model titles like "(Krea-2 + ZIT)" or
|
| 134 |
+
"[Flux | ZIB | Krea2]" - those are separate files for separate
|
| 135 |
+
architectures shipped under one model page, not a combined adapter.
|
| 136 |
+
• To combine two full Krea 2 checkpoints rather than adapters, ComfyUI
|
| 137 |
+
ships a dedicated ModelMergeKrea2 node (added in v0.27.0) with per-
|
| 138 |
+
section weights for first., tmlp., txtmlp., tproj.,
|
| 139 |
+
txtfusion.projector, txtfusion.layerwise_blocks.0-1,
|
| 140 |
+
txtfusion.refiner_blocks.0-1, blocks.0-27 and last.
|
| 141 |
+
• The author never states which weight family this targets. Silent
|
| 142 |
+
degradation, never a hard error, between Raw and Turbo. The two share
|
| 143 |
+
one architecture - ai-toolkit's config is commented "The reference
|
| 144 |
+
'single_mmdit_large_wide' architecture (oss_raw / oss_turbo share it)"
|
| 145 |
+
- so every LoRA tensor shape matches on both and ComfyUI/diffuser
|
| 146 |
+
|
| 147 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 148 |
+
PROS
|
| 149 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 150 |
+
+ Well established — 3,035 downloads. [source: CivitAI stats]
|
| 151 |
+
+ Positively received — 234 thumbs-up with no down-votes. [source:
|
| 152 |
+
CivitAI stats]
|
| 153 |
+
+ Explicit trigger word(s) — Movie still from a 70s Giallo thriller — so
|
| 154 |
+
the effect can be turned on and off from the prompt. [source: model
|
| 155 |
+
metadata]
|
| 156 |
+
+ Compact at 218 MB — cheap to stack with other LoRAs. [source: file
|
| 157 |
+
size]
|
| 158 |
+
|
| 159 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 160 |
+
CONS & CAVEATS
|
| 161 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 162 |
+
- Author never states which generation mode it was trained for; test
|
| 163 |
+
against your own workflow before relying on it. [source: description]
|
| 164 |
+
|
| 165 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 166 |
+
COMPATIBILITY WARNING
|
| 167 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 168 |
+
Silent degradation, never a hard error, between Raw and Turbo. The two
|
| 169 |
+
share one architecture - ai-toolkit's config is commented "The reference
|
| 170 |
+
'single_mmdit_large_wide' architecture (oss_raw / oss_turbo share it)" - so
|
| 171 |
+
every LoRA tensor shape matches on both and ComfyUI/diffusers will load an
|
| 172 |
+
adapter against either without complaint. The lvladikov 4-step LoRA card
|
| 173 |
+
states this for the reverse direction: "Every layer it targets also exists
|
| 174 |
+
in Krea 2 Raw, so it will load there without complaint - but that is a side
|
| 175 |
+
effect of the shared architecture, not a supported mode", and reports
|
| 176 |
+
mixed, subject-dependent results with malformed subjects (duplicated heads,
|
| 177 |
+
fused limbs) at low step counts, needing 14+ steps with Raw's CFG on before
|
| 178 |
+
output is coherent. The intended direction (train on Raw, run on Turbo) is
|
| 179 |
+
officially blessed. The more common practical failure is a settings
|
| 180 |
+
mismatch rather than a weight mismatch: running a Turbo-targeted LoRA at
|
| 181 |
+
Raw's 52 steps + CFG 3.5, or leaving CFG enabled on Turbo, degrades output
|
| 182 |
+
with no warning. Loading a Krea 2 LoRA against a different model family
|
| 183 |
+
entirely (Flux, Qwen-Image, Z-Image) is also not an error - ComfyUI logs
|
| 184 |
+
"lora key not loaded: {key}" per key and generates as if no LoRA were
|
| 185 |
+
applied.
|
| 186 |
+
|
| 187 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 188 |
+
AUTHOR'S DESCRIPTION
|
| 189 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 190 |
+
70s Giallo Movie Still In this LoRA I tried to recreate the vivid, stylized
|
| 191 |
+
look of 1970s Italian Giallo movies.
|
| 192 |
+
The main features are bold colored lighting , dramatic shadows , and
|
| 193 |
+
voyeuristic camera angles . Perfect for tense, atmospheric scenes dripping
|
| 194 |
+
with mystery, glamour, and dread.
|
| 195 |
+
|
| 196 |
+
────────────────────────────────────────────────────────────────���──────────────
|
| 197 |
+
EXAMPLE MEDIA
|
| 198 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 199 |
+
6 preview(s) in ./example_images/ — community results for
|
| 200 |
+
this LoRA. Videos keep a matching _poster.jpg still frame.
|
| 201 |
+
|
| 202 |
+
No prompts are recorded below: CivitAI's public API flags these posts as
|
| 203 |
+
having generation metadata but does not return it, so the prompts cannot be
|
| 204 |
+
scraped. Open the model page to read them.
|
| 205 |
+
|
| 206 |
+
01_image.jpeg (image, 1024x1024)
|
| 207 |
+
02_image.jpeg (image, 1024x1024)
|
| 208 |
+
03_image.jpeg (image, 1024x1024)
|
| 209 |
+
04_image.jpeg (image, 1024x1024)
|
| 210 |
+
05_image.jpeg (image, 1024x1024)
|
| 211 |
+
06_image.jpeg (image, 1024x1024)
|
| 212 |
+
|
| 213 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 214 |
+
HOW TO USE (COMFYUI)
|
| 215 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 216 |
+
1. Update ComfyUI to at least v0.26.0 (released 2026-06-23), which added
|
| 217 |
+
local Krea2 support. For reference-image / style-reference / edit LoRAs you
|
| 218 |
+
need at least v0.29.0 (2026-07-29), which added regular and timestep-zero
|
| 219 |
+
reference images for Krea 2. ModelMergeKrea2 arrived in v0.27.0
|
| 220 |
+
(2026-06-30).
|
| 221 |
+
|
| 222 |
+
2. Put the base stack in place (files from huggingface.co/Comfy-Org/Krea-2,
|
| 223 |
+
which is not gated):
|
| 224 |
+
- ComfyUI/models/diffusion_models/krea2_turbo_fp8_scaled.safetensors
|
| 225 |
+
(documented recommended default; the repo also holds krea2_turbo_bf16,
|
| 226 |
+
_int8_convrot, _mxfp8, _nvfp4 and krea2_raw_bf16 / _fp8_scaled /
|
| 227 |
+
_int8_convrot)
|
| 228 |
+
- ComfyUI/models/text_encoders/qwen3vl_4b_fp8_scaled.safetensors (bf16
|
| 229 |
+
also available)
|
| 230 |
+
- ComfyUI/models/vae/qwen_image_vae.safetensors
|
| 231 |
+
|
| 232 |
+
3. Put the LoRA .safetensors in ComfyUI/models/loras/ - flat, no per-model
|
| 233 |
+
subfolder required.
|
| 234 |
+
|
| 235 |
+
4. Build or load the graph. The official image_krea2_turbo_t2i.json
|
| 236 |
+
template is: UNETLoader (krea2_turbo_fp8_scaled.safetensors) ->
|
| 237 |
+
LoraLoaderModelOnly -> KSampler; CLIPLoader
|
| 238 |
+
(qwen3vl_4b_fp8_scaled.safetensors, type "krea2") -> text encode ->
|
| 239 |
+
KSampler positive, with ConditioningZeroOut into negative; VAELoader
|
| 240 |
+
(qwen_image_vae.safetensors) -> VAEDecode -> SaveImage; EmptyLatentImage
|
| 241 |
+
1024x1024 driven by ResolutionSelector. An int8 sibling template
|
| 242 |
+
(image_krea2_turbo_t2i_int8.json) also ships.
|
| 243 |
+
|
| 244 |
+
5. Load the LoRA with LoraLoaderModelOnly, not LoraLoader - both official
|
| 245 |
+
templates do. Krea 2 LoRAs patch the DiT only; note that the DiT's own
|
| 246 |
+
text_fusion / txtfusion blocks are a normal LoRA target (the official style
|
| 247 |
+
LoRAs patch them), but the Qwen3-VL text encoder itself is not. Set
|
| 248 |
+
strength 1.0 for Krea's official style LoRAs (the shipped template uses
|
| 249 |
+
0.8) and add the LoRA's trigger word to the prompt.
|
| 250 |
+
|
| 251 |
+
6. Sampler settings: steps 8, cfg 1, sampler euler, scheduler simple,
|
| 252 |
+
denoise 1.0. Do not add a ModelSampling node for plain t2i - ComfyUI
|
| 253 |
+
already applies shift 1.15 from Krea2.sampling_settings.
|
| 254 |
+
|
| 255 |
+
7. For style reference, use the dedicated template: UNETLoader
|
| 256 |
+
krea2_turbo_int8_convrot.safetensors, LoraLoaderModelOnly
|
| 257 |
+
krea2_style_reference.safetensors at 1.0, ModelSamplingFlux (1.15, 0.5),
|
| 258 |
+
TextEncodeQwenImageEditPlus fed by LoadImage,
|
| 259 |
+
FluxKontextMultiReferenceLatentMethod set to index_timestep_zero, and
|
| 260 |
+
SamplerCustomAdvanced with KSamplerSelect euler + BasicScheduler simple/8 +
|
| 261 |
+
CFGGuider cfg 1.
|
| 262 |
+
|
| 263 |
+
8. For instruction editing (Krea 2 Identity Edit), stock nodes are not
|
| 264 |
+
enough: install the ComfyUI-Krea2Edit node pack, which ships its own
|
| 265 |
+
workflows, and run Turbo at 8-12 steps / cfg 1 (or Raw at 20 steps / cfg 3
|
| 266 |
+
for removals) with LoRA strength 1.0.
|
| 267 |
+
|
| 268 |
+
9. Low-VRAM alternative: install city96's ComfyUI-GGUF and use a community
|
| 269 |
+
GGUF build (realrebelai/KREA-2_GGUFs, quantized from Turbo;
|
| 270 |
+
molbal/krea2-gguf, quantized from Raw) with the Unet Loader (GGUF) node in
|
| 271 |
+
place of UNETLoader. There is no official GGUF release. LoRA loading is
|
| 272 |
+
unchanged.
|
| 273 |
+
|
| 274 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 275 |
+
Scraped by lorakit on 2026-09-05 03:58 UTC.
|
| 276 |
+
Stats and description are the author's; pros/cons are derived from the
|
| 277 |
+
evidence tagged beside each line.
|
| 278 |
+
───────────────────────────────────────────────────────────────────────────────
|
70s-giallo-thriller/metadata.json
ADDED
|
@@ -0,0 +1,134 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"name": "70s Giallo thriller",
|
| 3 |
+
"slug": "70s-giallo-thriller",
|
| 4 |
+
"base_model": "Krea 2",
|
| 5 |
+
"media_type": "image",
|
| 6 |
+
"model_id": 1743845,
|
| 7 |
+
"version_id": 3183842,
|
| 8 |
+
"version_name": "Krea2",
|
| 9 |
+
"source": "civitai",
|
| 10 |
+
"url": "https://civitai.com/models/1743845",
|
| 11 |
+
"repo_id": null,
|
| 12 |
+
"file_path": null,
|
| 13 |
+
"author": "ArsMachina",
|
| 14 |
+
"category": {
|
| 15 |
+
"key": "style",
|
| 16 |
+
"label": "Visual style"
|
| 17 |
+
},
|
| 18 |
+
"modalities": [],
|
| 19 |
+
"primary_modality": "unspecified",
|
| 20 |
+
"checkpoint_family": "unknown",
|
| 21 |
+
"trigger_words": [
|
| 22 |
+
"Movie still from a 70s Giallo thriller"
|
| 23 |
+
],
|
| 24 |
+
"recommended_settings": {},
|
| 25 |
+
"chaining": {
|
| 26 |
+
"author": {
|
| 27 |
+
"stacks": "not stated",
|
| 28 |
+
"notes": "",
|
| 29 |
+
"avoid": [],
|
| 30 |
+
"requires": [],
|
| 31 |
+
"order": "",
|
| 32 |
+
"strength": "",
|
| 33 |
+
"stated": false
|
| 34 |
+
},
|
| 35 |
+
"general_rules": [
|
| 36 |
+
"The most important rule is not about chaining but about which checkpoint you chain onto: the official README says in bold \"TRAIN on Raw and RUN on Turbo\", and \"We highly recommend using RAW for training LoRAs and applying them on Turbo for inference.\" LoRAs trained on Raw are stated to work well on Turbo.",
|
| 37 |
+
"Chain with LoraLoaderModelOnly nodes in series (model -> model). Krea 2 LoRAs are DiT-only, so there is no CLIP side to chain and the text-encoder branch stays untouched however many LoRAs you add.",
|
| 38 |
+
"Krea 2 LoRAs stack in practice and the community treats multi-LoRA as routine - style + character, style + slider, realism + character. Several CivitAI Krea 2 authors state their LoRAs stack cleanly; one writes \"I recently stacked over 20 of my own LoRAs on a single generation and the output still came out great.\"",
|
| 39 |
+
"Reduce per-LoRA strength when stacking. CivitAI Krea 2 authors converge on dropping from ~1.0 to roughly 0.6-0.9 once more than one adapter is loaded. The CivitAI 12GB training guide also notes rank affects composability: \"rank 8 produced a lighter style influence that was easier to stack with other LoRAs, rank 16 provided a useful balance between concept strength and composability, and rank 32 was better suited to a precise object or concept intended to take priority over other stacked LoRAs.\"",
|
| 40 |
+
"Accelerator LoRAs are position-sensitive in intent, not in node order: a Raw-to-Turbo delta adapter belongs on the Raw checkpoint, a sub-8-step LoRA belongs on Turbo (or on Raw already carrying a Raw-to-Turbo adapter). Chaining Raw -> Raw-to-Turbo adapter -> 4-step LoRA is explicitly recommended by the 4-step LoRA's author.",
|
| 41 |
+
"Whatever you stack, the schedule must stay Turbo's: cfg 1.0 in ComfyUI (guidance 0.0 in diffusers) and mu/shift 1.15. The 4-step LoRA's card says \"Keep mu = 1.15. The training targets are anchored to that grid; a different shift moves the [sampler off them]\"; the same reasoning applies to any Turbo-trained adapter in the chain.",
|
| 42 |
+
"Reference/edit LoRAs are designed to be stacked under ordinary subject and style LoRAs - the Identity Edit card states \"Composes with your LoRAs: character/body/style LoRAs stack on top and steer the prior\" and recommends a stacked subject LoRA when unusual subjects drift toward the base prior.",
|
| 43 |
+
"Krea 2 LoRAs cannot be chained with LoRAs for any other base model. Many CivitAI pages carry multi-model titles like \"(Krea-2 + ZIT)\" or \"[Flux | ZIB | Krea2]\" - those are separate files for separate architectures shipped under one model page, not a combined adapter.",
|
| 44 |
+
"To combine two full Krea 2 checkpoints rather than adapters, ComfyUI ships a dedicated ModelMergeKrea2 node (added in v0.27.0) with per-section weights for first., tmlp., txtmlp., tproj., txtfusion.projector, txtfusion.layerwise_blocks.0-1, txtfusion.refiner_blocks.0-1, blocks.0-27 and last.",
|
| 45 |
+
"The author never states which weight family this targets. Silent degradation, never a hard error, between Raw and Turbo. The two share one architecture - ai-toolkit's config is commented \"The reference 'single_mmdit_large_wide' architecture (oss_raw / oss_turbo share it)\" - so every LoRA tensor shape matches on both and ComfyUI/diffuser"
|
| 46 |
+
]
|
| 47 |
+
},
|
| 48 |
+
"pros": [
|
| 49 |
+
"Well established — 3,035 downloads. [source: CivitAI stats]",
|
| 50 |
+
"Positively received — 234 thumbs-up with no down-votes. [source: CivitAI stats]",
|
| 51 |
+
"Explicit trigger word(s) — Movie still from a 70s Giallo thriller — so the effect can be turned on and off from the prompt. [source: model metadata]",
|
| 52 |
+
"Compact at 218 MB — cheap to stack with other LoRAs. [source: file size]"
|
| 53 |
+
],
|
| 54 |
+
"cons": [
|
| 55 |
+
"Author never states which generation mode it was trained for; test against your own workflow before relying on it. [source: description]"
|
| 56 |
+
],
|
| 57 |
+
"file": {
|
| 58 |
+
"name": "70sGialloThrillerKrea2Raw.safetensors",
|
| 59 |
+
"size_bytes": 228587744,
|
| 60 |
+
"size_mb": 218.0,
|
| 61 |
+
"sha256": "f933bf14f7b49fdb73ce6c2cbd33511751c9e67e722088c1ddbaedd642eb6b47"
|
| 62 |
+
},
|
| 63 |
+
"stats": {
|
| 64 |
+
"downloads": 3035,
|
| 65 |
+
"thumbs_up": 234,
|
| 66 |
+
"thumbs_down": 0
|
| 67 |
+
},
|
| 68 |
+
"popularity": {
|
| 69 |
+
"downloads": 3035,
|
| 70 |
+
"thumbs_up": 234,
|
| 71 |
+
"thumbs_down": 0,
|
| 72 |
+
"comments": 0,
|
| 73 |
+
"approval": "100% positive (234/234)",
|
| 74 |
+
"age_days": 20.6,
|
| 75 |
+
"downloads_per_day": 27.88,
|
| 76 |
+
"rank_by_downloads": 87,
|
| 77 |
+
"rank_by_momentum": 152,
|
| 78 |
+
"of_total": 200,
|
| 79 |
+
"adoption_tier": "Moderate",
|
| 80 |
+
"momentum": "Long tail · fresh release"
|
| 81 |
+
},
|
| 82 |
+
"selection_score": 85.9,
|
| 83 |
+
"selection_reasons": [
|
| 84 |
+
"3,035 downloads",
|
| 85 |
+
"234 thumbs-up",
|
| 86 |
+
"top-ranked for its category"
|
| 87 |
+
],
|
| 88 |
+
"example_media": [
|
| 89 |
+
{
|
| 90 |
+
"file": "01_image.jpeg",
|
| 91 |
+
"type": "image",
|
| 92 |
+
"resolution": "1024x1024",
|
| 93 |
+
"prompt": ""
|
| 94 |
+
},
|
| 95 |
+
{
|
| 96 |
+
"file": "02_image.jpeg",
|
| 97 |
+
"type": "image",
|
| 98 |
+
"resolution": "1024x1024",
|
| 99 |
+
"prompt": ""
|
| 100 |
+
},
|
| 101 |
+
{
|
| 102 |
+
"file": "03_image.jpeg",
|
| 103 |
+
"type": "image",
|
| 104 |
+
"resolution": "1024x1024",
|
| 105 |
+
"prompt": ""
|
| 106 |
+
},
|
| 107 |
+
{
|
| 108 |
+
"file": "04_image.jpeg",
|
| 109 |
+
"type": "image",
|
| 110 |
+
"resolution": "1024x1024",
|
| 111 |
+
"prompt": ""
|
| 112 |
+
},
|
| 113 |
+
{
|
| 114 |
+
"file": "05_image.jpeg",
|
| 115 |
+
"type": "image",
|
| 116 |
+
"resolution": "1024x1024",
|
| 117 |
+
"prompt": ""
|
| 118 |
+
},
|
| 119 |
+
{
|
| 120 |
+
"file": "06_image.jpeg",
|
| 121 |
+
"type": "image",
|
| 122 |
+
"resolution": "1024x1024",
|
| 123 |
+
"prompt": ""
|
| 124 |
+
}
|
| 125 |
+
],
|
| 126 |
+
"tags": [
|
| 127 |
+
"giallo",
|
| 128 |
+
"70s",
|
| 129 |
+
"style",
|
| 130 |
+
"thriller"
|
| 131 |
+
],
|
| 132 |
+
"scraped_at": "2026-09-05T03:58:51+00:00",
|
| 133 |
+
"path": "krea-2/70s-giallo-thriller"
|
| 134 |
+
}
|
90s-gothic-boudoir/90sVampBoudoirKrea2Raw.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:ed2867e6f455689695850078c4046fea1a46ed9c490fa04626a2c68c28fa347f
|
| 3 |
+
size 228587736
|
90s-gothic-boudoir/example_images/01_image.jpeg
ADDED
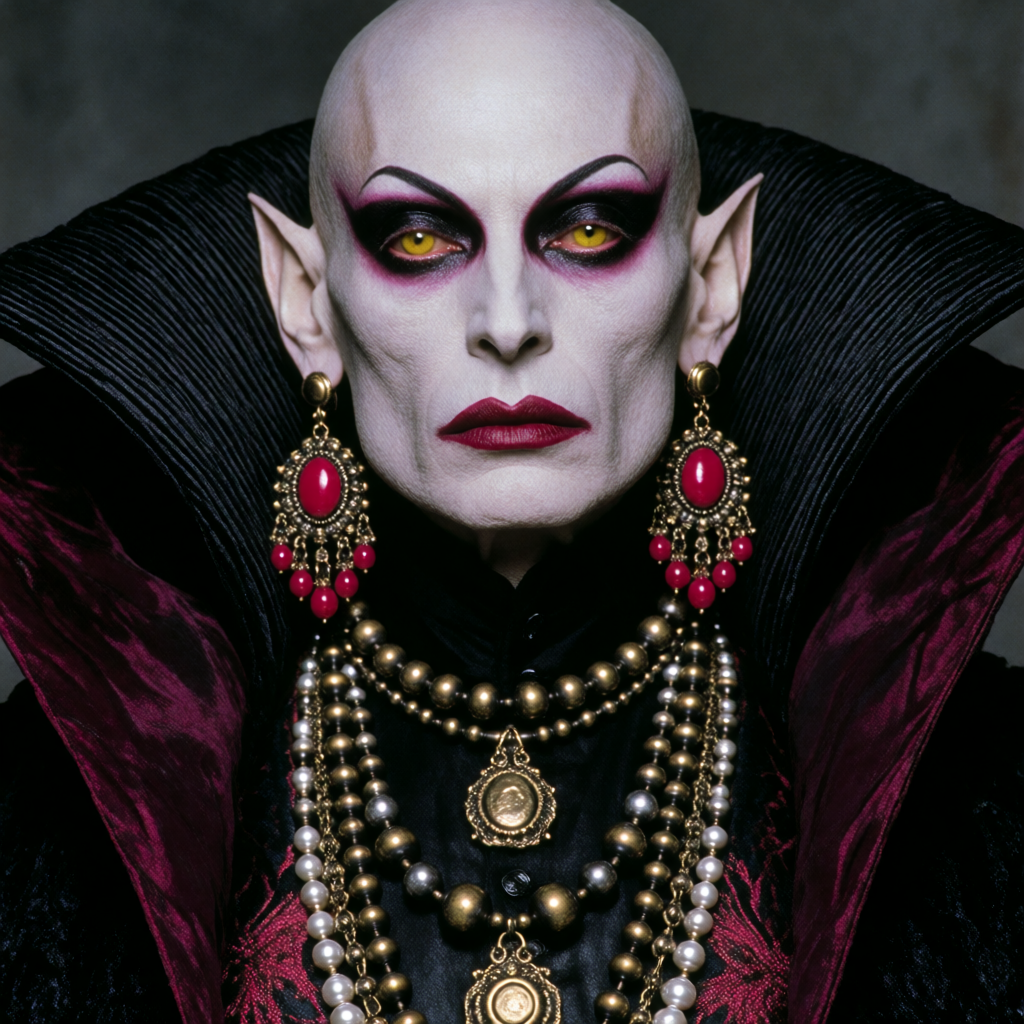
|
Git LFS Details
|
90s-gothic-boudoir/example_images/02_image.jpeg
ADDED

|
Git LFS Details
|
90s-gothic-boudoir/example_images/03_image.jpeg
ADDED
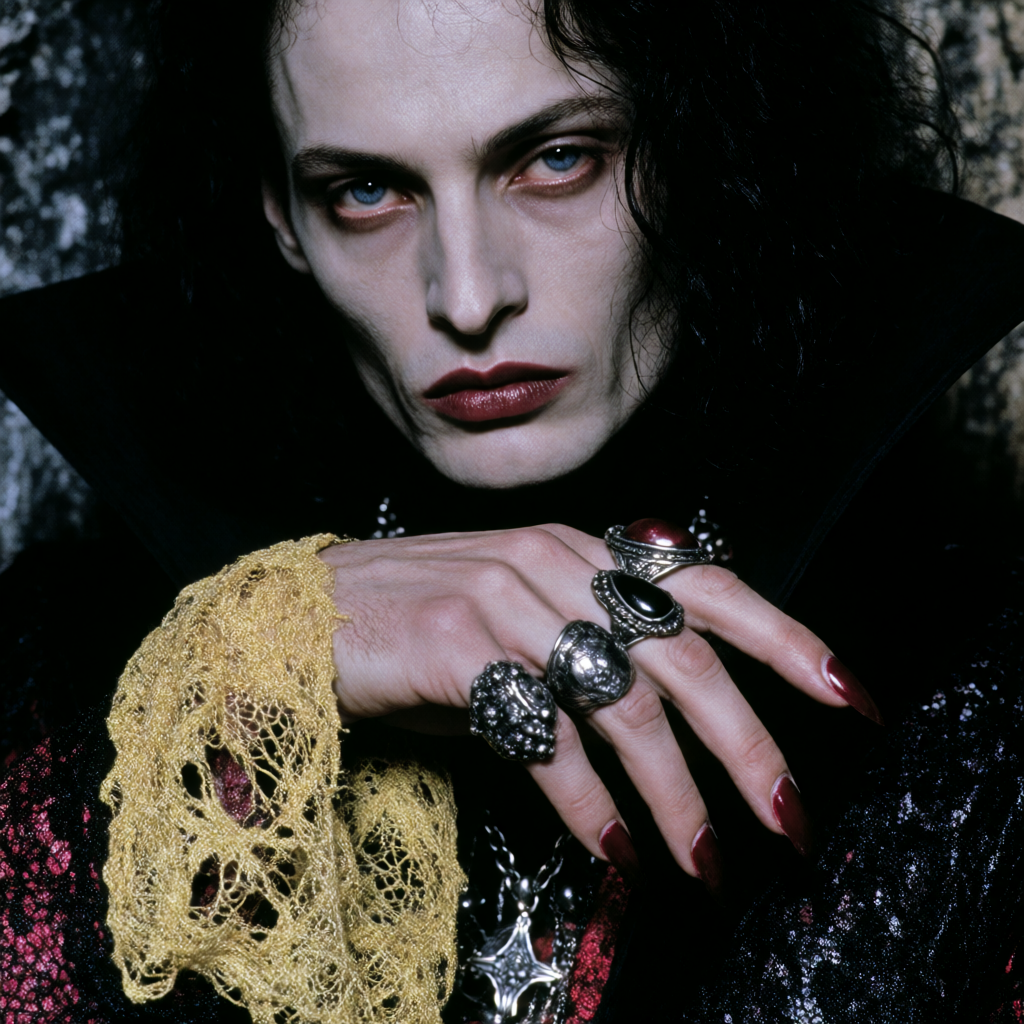
|
Git LFS Details
|
90s-gothic-boudoir/example_images/04_image.jpeg
ADDED
|
Git LFS Details
|
90s-gothic-boudoir/example_images/05_image.jpeg
ADDED
|
Git LFS Details
|
90s-gothic-boudoir/example_images/06_image.jpeg
ADDED
|
Git LFS Details
|
90s-gothic-boudoir/info.txt
ADDED
|
@@ -0,0 +1,278 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
═══════════════════════════════════════════════════════════════════════════════
|
| 2 |
+
90S GOTHIC BOUDOIR
|
| 3 |
+
═══════════════════════════════════════════════════════════════════════════════
|
| 4 |
+
|
| 5 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 6 |
+
IDENTITY
|
| 7 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 8 |
+
Base model Krea 2
|
| 9 |
+
Generation mode not declared by the author
|
| 10 |
+
Checkpoint not determined — verify before use
|
| 11 |
+
Category Visual style
|
| 12 |
+
Author ArsMachina
|
| 13 |
+
Source https://civitai.com/models/2617913
|
| 14 |
+
Provenance CivitAI · model 2617913 · version 3181601
|
| 15 |
+
|
| 16 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 17 |
+
WEIGHTS
|
| 18 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 19 |
+
File 90sVampBoudoirKrea2Raw.safetensors
|
| 20 |
+
Version Krea2
|
| 21 |
+
Size 218.0 MB
|
| 22 |
+
Format SafeTensor / unknown precision
|
| 23 |
+
SHA256 ed2867e6f455689695850078c4046fea1a46ed9c490fa04626a2c68c28fa347f
|
| 24 |
+
Published 2026-08-25
|
| 25 |
+
|
| 26 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 27 |
+
TRIGGER WORDS
|
| 28 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 29 |
+
› "90s Gothic Boudoir,"
|
| 30 |
+
|
| 31 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 32 |
+
RECOMMENDED SETTINGS
|
| 33 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 34 |
+
The author did not publish specific settings.
|
| 35 |
+
No author settings were published. Community baseline: steps Turbo: 8
|
| 36 |
+
(official README and HF card CLI example; the ComfyUI template ships 8).
|
| 37 |
+
Raw: 52 (official README). The krea-2 CLI's generic default is 28.
|
| 38 |
+
Community Turbo LoRAs commonly suggest 8-12 (e.g. the Identity Edit card
|
| 39 |
+
recommends Turbo at 8-12, or Raw at 20 for removals). A community 4-step
|
| 40 |
+
LoRA on Turbo makes 4 valid; its author calls 2 steps an out-of-spec
|
| 41 |
+
preview mode., cfg Turbo: CFG disabled - guidance_scale 0.0 in diffusers
|
| 42 |
+
and --cfg 0.0 in the krea-2 CLI, which is cfg 1.0 in ComfyUI's KSampler
|
| 43 |
+
(the official template ships cfg 1). These are the same thing; do not set
|
| 44 |
+
ComfyUI cfg to 0. Raw: CFG 3.5 (official README; CLI generic default 4.5).
|
| 45 |
+
Negative prompting on Turbo is effectively unused - the official templates
|
| 46 |
+
route ConditioningZeroOut into the negative slot., sampler ComfyUI:
|
| 47 |
+
KSampler with sampler euler, scheduler simple, denoise 1.0 (verified in
|
| 48 |
+
image_krea2_turbo_t2i.json: [seed, 'randomize', 8, 1, 'euler', 'simple',
|
| 49 |
+
1]). Timestep shift mu = 1.15 for Turbo; ComfyUI bakes this in via
|
| 50 |
+
Krea2.sampling_settings = {"multiplier": 1.0, "shift": 1.15}, so the plain
|
| 51 |
+
t2i template needs no ModelSampling node, while the style-reference
|
| 52 |
+
template adds ModelSamplingFlux at max_shift 1.15 / base_shift 0.5. The CLI
|
| 53 |
+
exposes --mu 1.15 for Turbo; Raw uses a resolution-derived mu interpolated
|
| 54 |
+
between --y1 0.5 and --y2 1.15 (ai-toolkit mirrors this as base_shift 0.5 /
|
| 55 |
+
max_shift 1.15 over image_seq_len 256-6400, exponential time shift).,
|
| 56 |
+
resolution 1024x1024 default. Turbo: 1K-2K (the official CLI example
|
| 57 |
+
generates 2048x2048; ComfyUI's ResolutionSelector defaults to 1 megapixel,
|
| 58 |
+
set 2.0 for 2K). Raw: "trained to generate upto 1k resolution".
|
| 59 |
+
Width/height are padded up to a multiple of 16., lora_strength 1.0 for
|
| 60 |
+
Krea's nine official style LoRAs (docs.comfy.org lists Recommended Strength
|
| 61 |
+
1.0 for every one), though the shipped t2i template's LoraLoaderModelOnly
|
| 62 |
+
is set to 0.8. The style-reference LoRA is used at 1.0 in its template. The
|
| 63 |
+
4-step distill LoRA documents 1.0 as its trained point, 1.0-1.5 as coherent
|
| 64 |
+
extrapolation and above ~1.5 as speckle artefacting. Community subject
|
| 65 |
+
LoRAs are typically recommended around 0.8-1.2 and dropped toward 0.6-0.9
|
| 66 |
+
when several are stacked..
|
| 67 |
+
|
| 68 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 69 |
+
ADOPTION & POPULARITY
|
| 70 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 71 |
+
Downloads 1,234
|
| 72 |
+
Rating 100% positive (84/84)
|
| 73 |
+
Comments 0
|
| 74 |
+
Published 10 days ago
|
| 75 |
+
Download rate 29.7/day since release
|
| 76 |
+
|
| 77 |
+
Adoption rank #142 of 200 in this collection (Modest)
|
| 78 |
+
Momentum rank #137 of 200 by download rate (Long tail · fresh release)
|
| 79 |
+
|
| 80 |
+
Adoption tier is the percentile of total downloads within this collection;
|
| 81 |
+
momentum is the percentile of downloads-per-day since release. Momentum is
|
| 82 |
+
ranked rather than measured against a fixed rate, because this base model
|
| 83 |
+
is itself new and every LoRA looks fast on an absolute scale. Both numbers
|
| 84 |
+
are CivitAI's, read on the scrape date at the foot of this file.
|
| 85 |
+
|
| 86 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 87 |
+
CHAINING / STACKING
|
| 88 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 89 |
+
Stacks with others not stated
|
| 90 |
+
|
| 91 |
+
The author gave no chaining guidance. The rules below are the
|
| 92 |
+
general Krea 2 ones, not anything specific to this LoRA.
|
| 93 |
+
|
| 94 |
+
General Krea 2 rules that apply here (see REFERENCE.txt):
|
| 95 |
+
|
| 96 |
+
• The most important rule is not about chaining but about which
|
| 97 |
+
checkpoint you chain onto: the official README says in bold "TRAIN on
|
| 98 |
+
Raw and RUN on Turbo", and "We highly recommend using RAW for training
|
| 99 |
+
LoRAs and applying them on Turbo for inference." LoRAs trained on Raw
|
| 100 |
+
are stated to work well on Turbo.
|
| 101 |
+
• Chain with LoraLoaderModelOnly nodes in series (model -> model). Krea 2
|
| 102 |
+
LoRAs are DiT-only, so there is no CLIP side to chain and the text-
|
| 103 |
+
encoder branch stays untouched however many LoRAs you add.
|
| 104 |
+
• Krea 2 LoRAs stack in practice and the community treats multi-LoRA as
|
| 105 |
+
routine - style + character, style + slider, realism + character.
|
| 106 |
+
Several CivitAI Krea 2 authors state their LoRAs stack cleanly; one
|
| 107 |
+
writes "I recently stacked over 20 of my own LoRAs on a single
|
| 108 |
+
generation and the output still came out great."
|
| 109 |
+
• Reduce per-LoRA strength when stacking. CivitAI Krea 2 authors converge
|
| 110 |
+
on dropping from ~1.0 to roughly 0.6-0.9 once more than one adapter is
|
| 111 |
+
loaded. The CivitAI 12GB training guide also notes rank affects
|
| 112 |
+
composability: "rank 8 produced a lighter style influence that was
|
| 113 |
+
easier to stack with other LoRAs, rank 16 provided a useful balance
|
| 114 |
+
between concept strength and composability, and rank 32 was better
|
| 115 |
+
suited to a precise object or concept intended to take priority over
|
| 116 |
+
other stacked LoRAs."
|
| 117 |
+
• Accelerator LoRAs are position-sensitive in intent, not in node order:
|
| 118 |
+
a Raw-to-Turbo delta adapter belongs on the Raw checkpoint, a
|
| 119 |
+
sub-8-step LoRA belongs on Turbo (or on Raw already carrying a Raw-to-
|
| 120 |
+
Turbo adapter). Chaining Raw -> Raw-to-Turbo adapter -> 4-step LoRA is
|
| 121 |
+
explicitly recommended by the 4-step LoRA's author.
|
| 122 |
+
• Whatever you stack, the schedule must stay Turbo's: cfg 1.0 in ComfyUI
|
| 123 |
+
(guidance 0.0 in diffusers) and mu/shift 1.15. The 4-step LoRA's card
|
| 124 |
+
says "Keep mu = 1.15. The training targets are anchored to that grid; a
|
| 125 |
+
different shift moves the [sampler off them]"; the same reasoning
|
| 126 |
+
applies to any Turbo-trained adapter in the chain.
|
| 127 |
+
• Reference/edit LoRAs are designed to be stacked under ordinary subject
|
| 128 |
+
and style LoRAs - the Identity Edit card states "Composes with your
|
| 129 |
+
LoRAs: character/body/style LoRAs stack on top and steer the prior" and
|
| 130 |
+
recommends a stacked subject LoRA when unusual subjects drift toward
|
| 131 |
+
the base prior.
|
| 132 |
+
• Krea 2 LoRAs cannot be chained with LoRAs for any other base model.
|
| 133 |
+
Many CivitAI pages carry multi-model titles like "(Krea-2 + ZIT)" or
|
| 134 |
+
"[Flux | ZIB | Krea2]" - those are separate files for separate
|
| 135 |
+
architectures shipped under one model page, not a combined adapter.
|
| 136 |
+
• To combine two full Krea 2 checkpoints rather than adapters, ComfyUI
|
| 137 |
+
ships a dedicated ModelMergeKrea2 node (added in v0.27.0) with per-
|
| 138 |
+
section weights for first., tmlp., txtmlp., tproj.,
|
| 139 |
+
txtfusion.projector, txtfusion.layerwise_blocks.0-1,
|
| 140 |
+
txtfusion.refiner_blocks.0-1, blocks.0-27 and last.
|
| 141 |
+
• The author never states which weight family this targets. Silent
|
| 142 |
+
degradation, never a hard error, between Raw and Turbo. The two share
|
| 143 |
+
one architecture - ai-toolkit's config is commented "The reference
|
| 144 |
+
'single_mmdit_large_wide' architecture (oss_raw / oss_turbo share it)"
|
| 145 |
+
- so every LoRA tensor shape matches on both and ComfyUI/diffuser
|
| 146 |
+
|
| 147 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 148 |
+
PROS
|
| 149 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 150 |
+
+ Well established — 1,234 downloads. [source: CivitAI stats]
|
| 151 |
+
+ Positively received — 84 thumbs-up with no down-votes. [source: CivitAI
|
| 152 |
+
stats]
|
| 153 |
+
+ Explicit trigger word(s) — 90s Gothic Boudoir, — so the effect can be
|
| 154 |
+
turned on and off from the prompt. [source: model metadata]
|
| 155 |
+
+ Compact at 218 MB — cheap to stack with other LoRAs. [source: file
|
| 156 |
+
size]
|
| 157 |
+
|
| 158 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 159 |
+
CONS & CAVEATS
|
| 160 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 161 |
+
- Author never states which generation mode it was trained for; test
|
| 162 |
+
against your own workflow before relying on it. [source: description]
|
| 163 |
+
|
| 164 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 165 |
+
COMPATIBILITY WARNING
|
| 166 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 167 |
+
Silent degradation, never a hard error, between Raw and Turbo. The two
|
| 168 |
+
share one architecture - ai-toolkit's config is commented "The reference
|
| 169 |
+
'single_mmdit_large_wide' architecture (oss_raw / oss_turbo share it)" - so
|
| 170 |
+
every LoRA tensor shape matches on both and ComfyUI/diffusers will load an
|
| 171 |
+
adapter against either without complaint. The lvladikov 4-step LoRA card
|
| 172 |
+
states this for the reverse direction: "Every layer it targets also exists
|
| 173 |
+
in Krea 2 Raw, so it will load there without complaint - but that is a side
|
| 174 |
+
effect of the shared architecture, not a supported mode", and reports
|
| 175 |
+
mixed, subject-dependent results with malformed subjects (duplicated heads,
|
| 176 |
+
fused limbs) at low step counts, needing 14+ steps with Raw's CFG on before
|
| 177 |
+
output is coherent. The intended direction (train on Raw, run on Turbo) is
|
| 178 |
+
officially blessed. The more common practical failure is a settings
|
| 179 |
+
mismatch rather than a weight mismatch: running a Turbo-targeted LoRA at
|
| 180 |
+
Raw's 52 steps + CFG 3.5, or leaving CFG enabled on Turbo, degrades output
|
| 181 |
+
with no warning. Loading a Krea 2 LoRA against a different model family
|
| 182 |
+
entirely (Flux, Qwen-Image, Z-Image) is also not an error - ComfyUI logs
|
| 183 |
+
"lora key not loaded: {key}" per key and generates as if no LoRA were
|
| 184 |
+
applied.
|
| 185 |
+
|
| 186 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 187 |
+
AUTHOR'S DESCRIPTION
|
| 188 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 189 |
+
Late 80s/Early 90s New Orleans grit meets decadent vampire ruin. This LoRA
|
| 190 |
+
is inspired by the Ricean gothic movies and a cluttered aesthetic that can
|
| 191 |
+
be described as "Haunted Whorehouse".
|
| 192 |
+
Expect leopard print, smudged eyeliner, and tattered Victorian opulence.
|
| 193 |
+
Mainly focused on portraits.
|
| 194 |
+
Keyword - 90s Gothic Boudoir
|
| 195 |
+
|
| 196 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 197 |
+
EXAMPLE MEDIA
|
| 198 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 199 |
+
6 preview(s) in ./example_images/ — community results for
|
| 200 |
+
this LoRA. Videos keep a matching _poster.jpg still frame.
|
| 201 |
+
|
| 202 |
+
No prompts are recorded below: CivitAI's public API flags these posts as
|
| 203 |
+
having generation metadata but does not return it, so the prompts cannot be
|
| 204 |
+
scraped. Open the model page to read them.
|
| 205 |
+
|
| 206 |
+
01_image.jpeg (image, 1024x1024)
|
| 207 |
+
02_image.jpeg (image, 1024x1024)
|
| 208 |
+
03_image.jpeg (image, 1024x1024)
|
| 209 |
+
04_image.jpeg (image, 1024x1024)
|
| 210 |
+
05_image.jpeg (image, 1024x1024)
|
| 211 |
+
06_image.jpeg (image, 832x1248)
|
| 212 |
+
|
| 213 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 214 |
+
HOW TO USE (COMFYUI)
|
| 215 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 216 |
+
1. Update ComfyUI to at least v0.26.0 (released 2026-06-23), which added
|
| 217 |
+
local Krea2 support. For reference-image / style-reference / edit LoRAs you
|
| 218 |
+
need at least v0.29.0 (2026-07-29), which added regular and timestep-zero
|
| 219 |
+
reference images for Krea 2. ModelMergeKrea2 arrived in v0.27.0
|
| 220 |
+
(2026-06-30).
|
| 221 |
+
|
| 222 |
+
2. Put the base stack in place (files from huggingface.co/Comfy-Org/Krea-2,
|
| 223 |
+
which is not gated):
|
| 224 |
+
- ComfyUI/models/diffusion_models/krea2_turbo_fp8_scaled.safetensors
|
| 225 |
+
(documented recommended default; the repo also holds krea2_turbo_bf16,
|
| 226 |
+
_int8_convrot, _mxfp8, _nvfp4 and krea2_raw_bf16 / _fp8_scaled /
|
| 227 |
+
_int8_convrot)
|
| 228 |
+
- ComfyUI/models/text_encoders/qwen3vl_4b_fp8_scaled.safetensors (bf16
|
| 229 |
+
also available)
|
| 230 |
+
- ComfyUI/models/vae/qwen_image_vae.safetensors
|
| 231 |
+
|
| 232 |
+
3. Put the LoRA .safetensors in ComfyUI/models/loras/ - flat, no per-model
|
| 233 |
+
subfolder required.
|
| 234 |
+
|
| 235 |
+
4. Build or load the graph. The official image_krea2_turbo_t2i.json
|
| 236 |
+
template is: UNETLoader (krea2_turbo_fp8_scaled.safetensors) ->
|
| 237 |
+
LoraLoaderModelOnly -> KSampler; CLIPLoader
|
| 238 |
+
(qwen3vl_4b_fp8_scaled.safetensors, type "krea2") -> text encode ->
|
| 239 |
+
KSampler positive, with ConditioningZeroOut into negative; VAELoader
|
| 240 |
+
(qwen_image_vae.safetensors) -> VAEDecode -> SaveImage; EmptyLatentImage
|
| 241 |
+
1024x1024 driven by ResolutionSelector. An int8 sibling template
|
| 242 |
+
(image_krea2_turbo_t2i_int8.json) also ships.
|
| 243 |
+
|
| 244 |
+
5. Load the LoRA with LoraLoaderModelOnly, not LoraLoader - both official
|
| 245 |
+
templates do. Krea 2 LoRAs patch the DiT only; note that the DiT's own
|
| 246 |
+
text_fusion / txtfusion blocks are a normal LoRA target (the official style
|
| 247 |
+
LoRAs patch them), but the Qwen3-VL text encoder itself is not. Set
|
| 248 |
+
strength 1.0 for Krea's official style LoRAs (the shipped template uses
|
| 249 |
+
0.8) and add the LoRA's trigger word to the prompt.
|
| 250 |
+
|
| 251 |
+
6. Sampler settings: steps 8, cfg 1, sampler euler, scheduler simple,
|
| 252 |
+
denoise 1.0. Do not add a ModelSampling node for plain t2i - ComfyUI
|
| 253 |
+
already applies shift 1.15 from Krea2.sampling_settings.
|
| 254 |
+
|
| 255 |
+
7. For style reference, use the dedicated template: UNETLoader
|
| 256 |
+
krea2_turbo_int8_convrot.safetensors, LoraLoaderModelOnly
|
| 257 |
+
krea2_style_reference.safetensors at 1.0, ModelSamplingFlux (1.15, 0.5),
|
| 258 |
+
TextEncodeQwenImageEditPlus fed by LoadImage,
|
| 259 |
+
FluxKontextMultiReferenceLatentMethod set to index_timestep_zero, and
|
| 260 |
+
SamplerCustomAdvanced with KSamplerSelect euler + BasicScheduler simple/8 +
|
| 261 |
+
CFGGuider cfg 1.
|
| 262 |
+
|
| 263 |
+
8. For instruction editing (Krea 2 Identity Edit), stock nodes are not
|
| 264 |
+
enough: install the ComfyUI-Krea2Edit node pack, which ships its own
|
| 265 |
+
workflows, and run Turbo at 8-12 steps / cfg 1 (or Raw at 20 steps / cfg 3
|
| 266 |
+
for removals) with LoRA strength 1.0.
|
| 267 |
+
|
| 268 |
+
9. Low-VRAM alternative: install city96's ComfyUI-GGUF and use a community
|
| 269 |
+
GGUF build (realrebelai/KREA-2_GGUFs, quantized from Turbo;
|
| 270 |
+
molbal/krea2-gguf, quantized from Raw) with the Unet Loader (GGUF) node in
|
| 271 |
+
place of UNETLoader. There is no official GGUF release. LoRA loading is
|
| 272 |
+
unchanged.
|
| 273 |
+
|
| 274 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 275 |
+
Scraped by lorakit on 2026-09-05 03:59 UTC.
|
| 276 |
+
Stats and description are the author's; pros/cons are derived from the
|
| 277 |
+
evidence tagged beside each line.
|
| 278 |
+
───────────────────────────────────────────────────────────────────────────────
|
90s-gothic-boudoir/metadata.json
ADDED
|
@@ -0,0 +1,137 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"name": "90s Gothic Boudoir",
|
| 3 |
+
"slug": "90s-gothic-boudoir",
|
| 4 |
+
"base_model": "Krea 2",
|
| 5 |
+
"media_type": "image",
|
| 6 |
+
"model_id": 2617913,
|
| 7 |
+
"version_id": 3181601,
|
| 8 |
+
"version_name": "Krea2",
|
| 9 |
+
"source": "civitai",
|
| 10 |
+
"url": "https://civitai.com/models/2617913",
|
| 11 |
+
"repo_id": null,
|
| 12 |
+
"file_path": null,
|
| 13 |
+
"author": "ArsMachina",
|
| 14 |
+
"category": {
|
| 15 |
+
"key": "style",
|
| 16 |
+
"label": "Visual style"
|
| 17 |
+
},
|
| 18 |
+
"modalities": [],
|
| 19 |
+
"primary_modality": "unspecified",
|
| 20 |
+
"checkpoint_family": "unknown",
|
| 21 |
+
"trigger_words": [
|
| 22 |
+
"90s Gothic Boudoir,"
|
| 23 |
+
],
|
| 24 |
+
"recommended_settings": {},
|
| 25 |
+
"chaining": {
|
| 26 |
+
"author": {
|
| 27 |
+
"stacks": "not stated",
|
| 28 |
+
"notes": "",
|
| 29 |
+
"avoid": [],
|
| 30 |
+
"requires": [],
|
| 31 |
+
"order": "",
|
| 32 |
+
"strength": "",
|
| 33 |
+
"stated": false
|
| 34 |
+
},
|
| 35 |
+
"general_rules": [
|
| 36 |
+
"The most important rule is not about chaining but about which checkpoint you chain onto: the official README says in bold \"TRAIN on Raw and RUN on Turbo\", and \"We highly recommend using RAW for training LoRAs and applying them on Turbo for inference.\" LoRAs trained on Raw are stated to work well on Turbo.",
|
| 37 |
+
"Chain with LoraLoaderModelOnly nodes in series (model -> model). Krea 2 LoRAs are DiT-only, so there is no CLIP side to chain and the text-encoder branch stays untouched however many LoRAs you add.",
|
| 38 |
+
"Krea 2 LoRAs stack in practice and the community treats multi-LoRA as routine - style + character, style + slider, realism + character. Several CivitAI Krea 2 authors state their LoRAs stack cleanly; one writes \"I recently stacked over 20 of my own LoRAs on a single generation and the output still came out great.\"",
|
| 39 |
+
"Reduce per-LoRA strength when stacking. CivitAI Krea 2 authors converge on dropping from ~1.0 to roughly 0.6-0.9 once more than one adapter is loaded. The CivitAI 12GB training guide also notes rank affects composability: \"rank 8 produced a lighter style influence that was easier to stack with other LoRAs, rank 16 provided a useful balance between concept strength and composability, and rank 32 was better suited to a precise object or concept intended to take priority over other stacked LoRAs.\"",
|
| 40 |
+
"Accelerator LoRAs are position-sensitive in intent, not in node order: a Raw-to-Turbo delta adapter belongs on the Raw checkpoint, a sub-8-step LoRA belongs on Turbo (or on Raw already carrying a Raw-to-Turbo adapter). Chaining Raw -> Raw-to-Turbo adapter -> 4-step LoRA is explicitly recommended by the 4-step LoRA's author.",
|
| 41 |
+
"Whatever you stack, the schedule must stay Turbo's: cfg 1.0 in ComfyUI (guidance 0.0 in diffusers) and mu/shift 1.15. The 4-step LoRA's card says \"Keep mu = 1.15. The training targets are anchored to that grid; a different shift moves the [sampler off them]\"; the same reasoning applies to any Turbo-trained adapter in the chain.",
|
| 42 |
+
"Reference/edit LoRAs are designed to be stacked under ordinary subject and style LoRAs - the Identity Edit card states \"Composes with your LoRAs: character/body/style LoRAs stack on top and steer the prior\" and recommends a stacked subject LoRA when unusual subjects drift toward the base prior.",
|
| 43 |
+
"Krea 2 LoRAs cannot be chained with LoRAs for any other base model. Many CivitAI pages carry multi-model titles like \"(Krea-2 + ZIT)\" or \"[Flux | ZIB | Krea2]\" - those are separate files for separate architectures shipped under one model page, not a combined adapter.",
|
| 44 |
+
"To combine two full Krea 2 checkpoints rather than adapters, ComfyUI ships a dedicated ModelMergeKrea2 node (added in v0.27.0) with per-section weights for first., tmlp., txtmlp., tproj., txtfusion.projector, txtfusion.layerwise_blocks.0-1, txtfusion.refiner_blocks.0-1, blocks.0-27 and last.",
|
| 45 |
+
"The author never states which weight family this targets. Silent degradation, never a hard error, between Raw and Turbo. The two share one architecture - ai-toolkit's config is commented \"The reference 'single_mmdit_large_wide' architecture (oss_raw / oss_turbo share it)\" - so every LoRA tensor shape matches on both and ComfyUI/diffuser"
|
| 46 |
+
]
|
| 47 |
+
},
|
| 48 |
+
"pros": [
|
| 49 |
+
"Well established — 1,234 downloads. [source: CivitAI stats]",
|
| 50 |
+
"Positively received — 84 thumbs-up with no down-votes. [source: CivitAI stats]",
|
| 51 |
+
"Explicit trigger word(s) — 90s Gothic Boudoir, — so the effect can be turned on and off from the prompt. [source: model metadata]",
|
| 52 |
+
"Compact at 218 MB — cheap to stack with other LoRAs. [source: file size]"
|
| 53 |
+
],
|
| 54 |
+
"cons": [
|
| 55 |
+
"Author never states which generation mode it was trained for; test against your own workflow before relying on it. [source: description]"
|
| 56 |
+
],
|
| 57 |
+
"file": {
|
| 58 |
+
"name": "90sVampBoudoirKrea2Raw.safetensors",
|
| 59 |
+
"size_bytes": 228587736,
|
| 60 |
+
"size_mb": 218.0,
|
| 61 |
+
"sha256": "ed2867e6f455689695850078c4046fea1a46ed9c490fa04626a2c68c28fa347f"
|
| 62 |
+
},
|
| 63 |
+
"stats": {
|
| 64 |
+
"downloads": 1234,
|
| 65 |
+
"thumbs_up": 84,
|
| 66 |
+
"thumbs_down": 0
|
| 67 |
+
},
|
| 68 |
+
"popularity": {
|
| 69 |
+
"downloads": 1234,
|
| 70 |
+
"thumbs_up": 84,
|
| 71 |
+
"thumbs_down": 0,
|
| 72 |
+
"comments": 0,
|
| 73 |
+
"approval": "100% positive (84/84)",
|
| 74 |
+
"age_days": 10.4,
|
| 75 |
+
"downloads_per_day": 29.7,
|
| 76 |
+
"rank_by_downloads": 142,
|
| 77 |
+
"rank_by_momentum": 137,
|
| 78 |
+
"of_total": 200,
|
| 79 |
+
"adoption_tier": "Modest",
|
| 80 |
+
"momentum": "Long tail · fresh release"
|
| 81 |
+
},
|
| 82 |
+
"selection_score": 85.4,
|
| 83 |
+
"selection_reasons": [
|
| 84 |
+
"1,234 downloads",
|
| 85 |
+
"84 thumbs-up",
|
| 86 |
+
"documented triggers + usage notes",
|
| 87 |
+
"top-ranked for its category"
|
| 88 |
+
],
|
| 89 |
+
"example_media": [
|
| 90 |
+
{
|
| 91 |
+
"file": "01_image.jpeg",
|
| 92 |
+
"type": "image",
|
| 93 |
+
"resolution": "1024x1024",
|
| 94 |
+
"prompt": ""
|
| 95 |
+
},
|
| 96 |
+
{
|
| 97 |
+
"file": "02_image.jpeg",
|
| 98 |
+
"type": "image",
|
| 99 |
+
"resolution": "1024x1024",
|
| 100 |
+
"prompt": ""
|
| 101 |
+
},
|
| 102 |
+
{
|
| 103 |
+
"file": "03_image.jpeg",
|
| 104 |
+
"type": "image",
|
| 105 |
+
"resolution": "1024x1024",
|
| 106 |
+
"prompt": ""
|
| 107 |
+
},
|
| 108 |
+
{
|
| 109 |
+
"file": "04_image.jpeg",
|
| 110 |
+
"type": "image",
|
| 111 |
+
"resolution": "1024x1024",
|
| 112 |
+
"prompt": ""
|
| 113 |
+
},
|
| 114 |
+
{
|
| 115 |
+
"file": "05_image.jpeg",
|
| 116 |
+
"type": "image",
|
| 117 |
+
"resolution": "1024x1024",
|
| 118 |
+
"prompt": ""
|
| 119 |
+
},
|
| 120 |
+
{
|
| 121 |
+
"file": "06_image.jpeg",
|
| 122 |
+
"type": "image",
|
| 123 |
+
"resolution": "832x1248",
|
| 124 |
+
"prompt": ""
|
| 125 |
+
}
|
| 126 |
+
],
|
| 127 |
+
"tags": [
|
| 128 |
+
"movie",
|
| 129 |
+
"80s",
|
| 130 |
+
"vampire",
|
| 131 |
+
"90s",
|
| 132 |
+
"boudoir",
|
| 133 |
+
"style"
|
| 134 |
+
],
|
| 135 |
+
"scraped_at": "2026-09-05T03:59:31+00:00",
|
| 136 |
+
"path": "krea-2/90s-gothic-boudoir"
|
| 137 |
+
}
|
between-pages/Between Pages - Krea2_000002750.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:68261c1ef5b78804f301a6f9c24d469e86934b47f5fbcc1e1d19e2bd79435117
|
| 3 |
+
size 228587800
|
between-pages/example_images/01_image.jpeg
ADDED

|
Git LFS Details
|
between-pages/example_images/02_image.jpeg
ADDED
|
Git LFS Details
|
between-pages/example_images/03_image.jpeg
ADDED
|
Git LFS Details
|
between-pages/example_images/04_image.jpeg
ADDED
|
Git LFS Details
|
between-pages/example_images/05_image.jpeg
ADDED
|
Git LFS Details
|
between-pages/example_images/06_image.jpeg
ADDED
|
Git LFS Details
|
between-pages/info.txt
ADDED
|
@@ -0,0 +1,363 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
═══════════════════════════════════════════════════════════════════════════════
|
| 2 |
+
BETWEEN PAGES
|
| 3 |
+
═══════════════════════════════════════════════════════════════════════════════
|
| 4 |
+
|
| 5 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 6 |
+
IDENTITY
|
| 7 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 8 |
+
Base model Krea 2
|
| 9 |
+
Generation mode not declared by the author
|
| 10 |
+
Checkpoint not determined — verify before use
|
| 11 |
+
Category Photorealism
|
| 12 |
+
Author Daalis
|
| 13 |
+
Source https://civitai.com/models/2375795
|
| 14 |
+
Provenance CivitAI · model 2375795 · version 3272240
|
| 15 |
+
|
| 16 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 17 |
+
WEIGHTS
|
| 18 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 19 |
+
File Between Pages - Krea2_000002750.safetensors
|
| 20 |
+
Version v1.0 Krea 2
|
| 21 |
+
Size 218.0 MB
|
| 22 |
+
Format SafeTensor / unknown precision
|
| 23 |
+
SHA256 68261c1ef5b78804f301a6f9c24d469e86934b47f5fbcc1e1d19e2bd79435117
|
| 24 |
+
Published 2026-08-27
|
| 25 |
+
|
| 26 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 27 |
+
TRIGGER WORDS
|
| 28 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 29 |
+
› "PagesDaal"
|
| 30 |
+
|
| 31 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 32 |
+
RECOMMENDED SETTINGS
|
| 33 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 34 |
+
The author did not publish specific settings.
|
| 35 |
+
No author settings were published. Community baseline: steps Turbo: 8
|
| 36 |
+
(official README and HF card CLI example; the ComfyUI template ships 8).
|
| 37 |
+
Raw: 52 (official README). The krea-2 CLI's generic default is 28.
|
| 38 |
+
Community Turbo LoRAs commonly suggest 8-12 (e.g. the Identity Edit card
|
| 39 |
+
recommends Turbo at 8-12, or Raw at 20 for removals). A community 4-step
|
| 40 |
+
LoRA on Turbo makes 4 valid; its author calls 2 steps an out-of-spec
|
| 41 |
+
preview mode., cfg Turbo: CFG disabled - guidance_scale 0.0 in diffusers
|
| 42 |
+
and --cfg 0.0 in the krea-2 CLI, which is cfg 1.0 in ComfyUI's KSampler
|
| 43 |
+
(the official template ships cfg 1). These are the same thing; do not set
|
| 44 |
+
ComfyUI cfg to 0. Raw: CFG 3.5 (official README; CLI generic default 4.5).
|
| 45 |
+
Negative prompting on Turbo is effectively unused - the official templates
|
| 46 |
+
route ConditioningZeroOut into the negative slot., sampler ComfyUI:
|
| 47 |
+
KSampler with sampler euler, scheduler simple, denoise 1.0 (verified in
|
| 48 |
+
image_krea2_turbo_t2i.json: [seed, 'randomize', 8, 1, 'euler', 'simple',
|
| 49 |
+
1]). Timestep shift mu = 1.15 for Turbo; ComfyUI bakes this in via
|
| 50 |
+
Krea2.sampling_settings = {"multiplier": 1.0, "shift": 1.15}, so the plain
|
| 51 |
+
t2i template needs no ModelSampling node, while the style-reference
|
| 52 |
+
template adds ModelSamplingFlux at max_shift 1.15 / base_shift 0.5. The CLI
|
| 53 |
+
exposes --mu 1.15 for Turbo; Raw uses a resolution-derived mu interpolated
|
| 54 |
+
between --y1 0.5 and --y2 1.15 (ai-toolkit mirrors this as base_shift 0.5 /
|
| 55 |
+
max_shift 1.15 over image_seq_len 256-6400, exponential time shift).,
|
| 56 |
+
resolution 1024x1024 default. Turbo: 1K-2K (the official CLI example
|
| 57 |
+
generates 2048x2048; ComfyUI's ResolutionSelector defaults to 1 megapixel,
|
| 58 |
+
set 2.0 for 2K). Raw: "trained to generate upto 1k resolution".
|
| 59 |
+
Width/height are padded up to a multiple of 16., lora_strength 1.0 for
|
| 60 |
+
Krea's nine official style LoRAs (docs.comfy.org lists Recommended Strength
|
| 61 |
+
1.0 for every one), though the shipped t2i template's LoraLoaderModelOnly
|
| 62 |
+
is set to 0.8. The style-reference LoRA is used at 1.0 in its template. The
|
| 63 |
+
4-step distill LoRA documents 1.0 as its trained point, 1.0-1.5 as coherent
|
| 64 |
+
extrapolation and above ~1.5 as speckle artefacting. Community subject
|
| 65 |
+
LoRAs are typically recommended around 0.8-1.2 and dropped toward 0.6-0.9
|
| 66 |
+
when several are stacked..
|
| 67 |
+
|
| 68 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 69 |
+
ADOPTION & POPULARITY
|
| 70 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 71 |
+
Downloads 1,687
|
| 72 |
+
Rating 100% positive (173/173)
|
| 73 |
+
Comments 4
|
| 74 |
+
Published 8 days ago
|
| 75 |
+
Download rate 24.0/day since release
|
| 76 |
+
|
| 77 |
+
Adoption rank #128 of 200 in this collection (Modest)
|
| 78 |
+
Momentum rank #166 of 200 by download rate (Long tail · fresh release)
|
| 79 |
+
|
| 80 |
+
Adoption tier is the percentile of total downloads within this collection;
|
| 81 |
+
momentum is the percentile of downloads-per-day since release. Momentum is
|
| 82 |
+
ranked rather than measured against a fixed rate, because this base model
|
| 83 |
+
is itself new and every LoRA looks fast on an absolute scale. Both numbers
|
| 84 |
+
are CivitAI's, read on the scrape date at the foot of this file.
|
| 85 |
+
|
| 86 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 87 |
+
CHAINING / STACKING
|
| 88 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 89 |
+
Stacks with others not stated
|
| 90 |
+
|
| 91 |
+
The author gave no chaining guidance. The rules below are the
|
| 92 |
+
general Krea 2 ones, not anything specific to this LoRA.
|
| 93 |
+
|
| 94 |
+
General Krea 2 rules that apply here (see REFERENCE.txt):
|
| 95 |
+
|
| 96 |
+
• The most important rule is not about chaining but about which
|
| 97 |
+
checkpoint you chain onto: the official README says in bold "TRAIN on
|
| 98 |
+
Raw and RUN on Turbo", and "We highly recommend using RAW for training
|
| 99 |
+
LoRAs and applying them on Turbo for inference." LoRAs trained on Raw
|
| 100 |
+
are stated to work well on Turbo.
|
| 101 |
+
• Chain with LoraLoaderModelOnly nodes in series (model -> model). Krea 2
|
| 102 |
+
LoRAs are DiT-only, so there is no CLIP side to chain and the text-
|
| 103 |
+
encoder branch stays untouched however many LoRAs you add.
|
| 104 |
+
• Krea 2 LoRAs stack in practice and the community treats multi-LoRA as
|
| 105 |
+
routine - style + character, style + slider, realism + character.
|
| 106 |
+
Several CivitAI Krea 2 authors state their LoRAs stack cleanly; one
|
| 107 |
+
writes "I recently stacked over 20 of my own LoRAs on a single
|
| 108 |
+
generation and the output still came out great."
|
| 109 |
+
• Reduce per-LoRA strength when stacking. CivitAI Krea 2 authors converge
|
| 110 |
+
on dropping from ~1.0 to roughly 0.6-0.9 once more than one adapter is
|
| 111 |
+
loaded. The CivitAI 12GB training guide also notes rank affects
|
| 112 |
+
composability: "rank 8 produced a lighter style influence that was
|
| 113 |
+
easier to stack with other LoRAs, rank 16 provided a useful balance
|
| 114 |
+
between concept strength and composability, and rank 32 was better
|
| 115 |
+
suited to a precise object or concept intended to take priority over
|
| 116 |
+
other stacked LoRAs."
|
| 117 |
+
• Accelerator LoRAs are position-sensitive in intent, not in node order:
|
| 118 |
+
a Raw-to-Turbo delta adapter belongs on the Raw checkpoint, a
|
| 119 |
+
sub-8-step LoRA belongs on Turbo (or on Raw already carrying a Raw-to-
|
| 120 |
+
Turbo adapter). Chaining Raw -> Raw-to-Turbo adapter -> 4-step LoRA is
|
| 121 |
+
explicitly recommended by the 4-step LoRA's author.
|
| 122 |
+
• Whatever you stack, the schedule must stay Turbo's: cfg 1.0 in ComfyUI
|
| 123 |
+
(guidance 0.0 in diffusers) and mu/shift 1.15. The 4-step LoRA's card
|
| 124 |
+
says "Keep mu = 1.15. The training targets are anchored to that grid; a
|
| 125 |
+
different shift moves the [sampler off them]"; the same reasoning
|
| 126 |
+
applies to any Turbo-trained adapter in the chain.
|
| 127 |
+
• Reference/edit LoRAs are designed to be stacked under ordinary subject
|
| 128 |
+
and style LoRAs - the Identity Edit card states "Composes with your
|
| 129 |
+
LoRAs: character/body/style LoRAs stack on top and steer the prior" and
|
| 130 |
+
recommends a stacked subject LoRA when unusual subjects drift toward
|
| 131 |
+
the base prior.
|
| 132 |
+
• Krea 2 LoRAs cannot be chained with LoRAs for any other base model.
|
| 133 |
+
Many CivitAI pages carry multi-model titles like "(Krea-2 + ZIT)" or
|
| 134 |
+
"[Flux | ZIB | Krea2]" - those are separate files for separate
|
| 135 |
+
architectures shipped under one model page, not a combined adapter.
|
| 136 |
+
• To combine two full Krea 2 checkpoints rather than adapters, ComfyUI
|
| 137 |
+
ships a dedicated ModelMergeKrea2 node (added in v0.27.0) with per-
|
| 138 |
+
section weights for first., tmlp., txtmlp., tproj.,
|
| 139 |
+
txtfusion.projector, txtfusion.layerwise_blocks.0-1,
|
| 140 |
+
txtfusion.refiner_blocks.0-1, blocks.0-27 and last.
|
| 141 |
+
• The author never states which weight family this targets. Silent
|
| 142 |
+
degradation, never a hard error, between Raw and Turbo. The two share
|
| 143 |
+
one architecture - ai-toolkit's config is commented "The reference
|
| 144 |
+
'single_mmdit_large_wide' architecture (oss_raw / oss_turbo share it)"
|
| 145 |
+
- so every LoRA tensor shape matches on both and ComfyUI/diffuser
|
| 146 |
+
|
| 147 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 148 |
+
PROS
|
| 149 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 150 |
+
+ Well established — 1,687 downloads. [source: CivitAI stats]
|
| 151 |
+
+ Positively received — 173 thumbs-up with no down-votes. [source:
|
| 152 |
+
CivitAI stats]
|
| 153 |
+
+ Explicit trigger word(s) — PagesDaal — so the effect can be turned on
|
| 154 |
+
and off from the prompt. [source: model metadata]
|
| 155 |
+
+ Compact at 218 MB — cheap to stack with other LoRAs. [source: file
|
| 156 |
+
size]
|
| 157 |
+
|
| 158 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 159 |
+
CONS & CAVEATS
|
| 160 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 161 |
+
- Needs a reduced strength; the default 1.0 is likely too strong.
|
| 162 |
+
[source: description]
|
| 163 |
+
- Author never states which generation mode it was trained for; test
|
| 164 |
+
against your own workflow before relying on it. [source: description]
|
| 165 |
+
|
| 166 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 167 |
+
COMPATIBILITY WARNING
|
| 168 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 169 |
+
Silent degradation, never a hard error, between Raw and Turbo. The two
|
| 170 |
+
share one architecture - ai-toolkit's config is commented "The reference
|
| 171 |
+
'single_mmdit_large_wide' architecture (oss_raw / oss_turbo share it)" - so
|
| 172 |
+
every LoRA tensor shape matches on both and ComfyUI/diffusers will load an
|
| 173 |
+
adapter against either without complaint. The lvladikov 4-step LoRA card
|
| 174 |
+
states this for the reverse direction: "Every layer it targets also exists
|
| 175 |
+
in Krea 2 Raw, so it will load there without complaint - but that is a side
|
| 176 |
+
effect of the shared architecture, not a supported mode", and reports
|
| 177 |
+
mixed, subject-dependent results with malformed subjects (duplicated heads,
|
| 178 |
+
fused limbs) at low step counts, needing 14+ steps with Raw's CFG on before
|
| 179 |
+
output is coherent. The intended direction (train on Raw, run on Turbo) is
|
| 180 |
+
officially blessed. The more common practical failure is a settings
|
| 181 |
+
mismatch rather than a weight mismatch: running a Turbo-targeted LoRA at
|
| 182 |
+
Raw's 52 steps + CFG 3.5, or leaving CFG enabled on Turbo, degrades output
|
| 183 |
+
with no warning. Loading a Krea 2 LoRA against a different model family
|
| 184 |
+
entirely (Flux, Qwen-Image, Z-Image) is also not an error - ComfyUI logs
|
| 185 |
+
"lora key not loaded: {key}" per key and generates as if no LoRA were
|
| 186 |
+
applied.
|
| 187 |
+
|
| 188 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 189 |
+
AUTHOR'S DESCRIPTION
|
| 190 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 191 |
+
Between Pages is a style LoRA built for that delicious in-between moment:
|
| 192 |
+
the start of a chapter, the end of a scene, the pause where something
|
| 193 |
+
meaningful is about to happen. It wraps subjects in painterly storybook
|
| 194 |
+
realism , soft cinematic lighting, and a gentle emotional gravity that
|
| 195 |
+
feels cozy, wistful, and quietly magical. Expect big expressive eyes, soft
|
| 196 |
+
textures, muted color palettes with warm accents, and compositions that
|
| 197 |
+
leave space for the viewer’s imagination to finish the sentence.
|
| 198 |
+
This LoRA is especially stellar for valentine-y feels : tender glances,
|
| 199 |
+
small acts of care, shy affection, warm interiors, gentle whimsy, and that
|
| 200 |
+
soft ache of almost-connection.
|
| 201 |
+
How to use Trigger keyword: PagesDaal
|
| 202 |
+
Recommended strength:
|
| 203 |
+
- 0.5 to 1.5 overall working range
|
| 204 |
+
|
| 205 |
+
- 1.0 is the sweet spot for strong adherence
|
| 206 |
+
|
| 207 |
+
- Lower strengths (0.5 to 0.8): more of your base model shows through,
|
| 208 |
+
subtler storybook treatment
|
| 209 |
+
|
| 210 |
+
- Higher strengths (1.2 to 1.5): more stylized, more cartoony, sometimes
|
| 211 |
+
more abstract and illustrative
|
| 212 |
+
|
| 213 |
+
What it does to your images - Storybook mood and pacing : scenes feel like
|
| 214 |
+
a page illustration from a larger tale
|
| 215 |
+
|
| 216 |
+
- Soft wonder, gentle melancholy : emotionally present, never loud or
|
| 217 |
+
chaotic
|
| 218 |
+
|
| 219 |
+
- Painterly texture : brushed edges, subtle grain, warm highlights against
|
| 220 |
+
cool atmospheres
|
| 221 |
+
|
| 222 |
+
- Scale and stillness : characters often feel small in a larger world, with
|
| 223 |
+
generous negative space
|
| 224 |
+
|
| 225 |
+
- Cute, not cloying : whimsical without going full sugar blast
|
| 226 |
+
|
| 227 |
+
Prompting tips This style loves moments , not mayhem.
|
| 228 |
+
Use phrases like:
|
| 229 |
+
- “quiet chapter break”
|
| 230 |
+
|
| 231 |
+
- “a pause before leaving”
|
| 232 |
+
|
| 233 |
+
- “soft window light”
|
| 234 |
+
|
| 235 |
+
- “lantern glow”
|
| 236 |
+
|
| 237 |
+
- “muted palette, warm accents”
|
| 238 |
+
|
| 239 |
+
- “painterly storybook illustration”
|
| 240 |
+
|
| 241 |
+
- “gentle surrealism”
|
| 242 |
+
|
| 243 |
+
- “tender, wistful mood”
|
| 244 |
+
|
| 245 |
+
- “soft cinematic lighting”
|
| 246 |
+
|
| 247 |
+
- “subtle brush texture, illustrated realism”
|
| 248 |
+
|
| 249 |
+
It also responds really well to:
|
| 250 |
+
- small props with emotional meaning (letters, lanterns, jars, scarves,
|
| 251 |
+
tiny gifts)
|
| 252 |
+
|
| 253 |
+
- rainy streets, warm rooms, twilight forests
|
| 254 |
+
|
| 255 |
+
- shy affection and “almost” moments
|
| 256 |
+
|
| 257 |
+
Quick starter prompts Use these as simple templates and swap subjects.
|
| 258 |
+
1) Cozy Valentine Moment PagesDaal, a small creature holding an envelope
|
| 259 |
+
with a wax seal, warm lamplight, quiet cozy room, soft painterly storybook
|
| 260 |
+
realism, tender valentine mood, muted colors with warm accents, gentle
|
| 261 |
+
stillness
|
| 262 |
+
2) Train Platform Chapter Ending PagesDaal, two people sitting close on a
|
| 263 |
+
quiet train, dusk light through windows, intimate silence, soft cinematic
|
| 264 |
+
lighting, painterly illustration, wistful romantic atmosphere, negative
|
| 265 |
+
space, calm and reflective
|
| 266 |
+
3) Magical Little Gift PagesDaal, a tiny fox-like being offering a heart-
|
| 267 |
+
shaped charm, lantern glow, soft brush texture, muted palette, warm
|
| 268 |
+
highlights, gentle wonder, like a page from a storybook
|
| 269 |
+
Please share the buzz If this LoRA makes you smile, give it a thumbs up and
|
| 270 |
+
post your first image to the LoRA page. Seeing what you create keeps me
|
| 271 |
+
inspired, and it helps the algorithmic gremlins notice that something
|
| 272 |
+
charming is happening here.
|
| 273 |
+
|
| 274 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 275 |
+
VERSION NOTES
|
| 276 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 277 |
+
Another in the update series. I found this to work very well. Interestingly
|
| 278 |
+
I found when I gave it very long prompts it tended to shade bluer. It
|
| 279 |
+
strongly resonates with emotions and storytelling in my testing.
|
| 280 |
+
|
| 281 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 282 |
+
EXAMPLE MEDIA
|
| 283 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 284 |
+
6 preview(s) in ./example_images/ — community results for
|
| 285 |
+
this LoRA. Videos keep a matching _poster.jpg still frame.
|
| 286 |
+
|
| 287 |
+
No prompts are recorded below: CivitAI's public API flags these posts as
|
| 288 |
+
having generation metadata but does not return it, so the prompts cannot be
|
| 289 |
+
scraped. Open the model page to read them.
|
| 290 |
+
|
| 291 |
+
01_image.jpeg (image, 1408x2048)
|
| 292 |
+
02_image.jpeg (image, 840x1256)
|
| 293 |
+
03_image.jpeg (image, 840x1256)
|
| 294 |
+
04_image.jpeg (image, 832x1248)
|
| 295 |
+
05_image.jpeg (image, 832x1248)
|
| 296 |
+
06_image.jpeg (image, 832x1248)
|
| 297 |
+
|
| 298 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 299 |
+
HOW TO USE (COMFYUI)
|
| 300 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 301 |
+
1. Update ComfyUI to at least v0.26.0 (released 2026-06-23), which added
|
| 302 |
+
local Krea2 support. For reference-image / style-reference / edit LoRAs you
|
| 303 |
+
need at least v0.29.0 (2026-07-29), which added regular and timestep-zero
|
| 304 |
+
reference images for Krea 2. ModelMergeKrea2 arrived in v0.27.0
|
| 305 |
+
(2026-06-30).
|
| 306 |
+
|
| 307 |
+
2. Put the base stack in place (files from huggingface.co/Comfy-Org/Krea-2,
|
| 308 |
+
which is not gated):
|
| 309 |
+
- ComfyUI/models/diffusion_models/krea2_turbo_fp8_scaled.safetensors
|
| 310 |
+
(documented recommended default; the repo also holds krea2_turbo_bf16,
|
| 311 |
+
_int8_convrot, _mxfp8, _nvfp4 and krea2_raw_bf16 / _fp8_scaled /
|
| 312 |
+
_int8_convrot)
|
| 313 |
+
- ComfyUI/models/text_encoders/qwen3vl_4b_fp8_scaled.safetensors (bf16
|
| 314 |
+
also available)
|
| 315 |
+
- ComfyUI/models/vae/qwen_image_vae.safetensors
|
| 316 |
+
|
| 317 |
+
3. Put the LoRA .safetensors in ComfyUI/models/loras/ - flat, no per-model
|
| 318 |
+
subfolder required.
|
| 319 |
+
|
| 320 |
+
4. Build or load the graph. The official image_krea2_turbo_t2i.json
|
| 321 |
+
template is: UNETLoader (krea2_turbo_fp8_scaled.safetensors) ->
|
| 322 |
+
LoraLoaderModelOnly -> KSampler; CLIPLoader
|
| 323 |
+
(qwen3vl_4b_fp8_scaled.safetensors, type "krea2") -> text encode ->
|
| 324 |
+
KSampler positive, with ConditioningZeroOut into negative; VAELoader
|
| 325 |
+
(qwen_image_vae.safetensors) -> VAEDecode -> SaveImage; EmptyLatentImage
|
| 326 |
+
1024x1024 driven by ResolutionSelector. An int8 sibling template
|
| 327 |
+
(image_krea2_turbo_t2i_int8.json) also ships.
|
| 328 |
+
|
| 329 |
+
5. Load the LoRA with LoraLoaderModelOnly, not LoraLoader - both official
|
| 330 |
+
templates do. Krea 2 LoRAs patch the DiT only; note that the DiT's own
|
| 331 |
+
text_fusion / txtfusion blocks are a normal LoRA target (the official style
|
| 332 |
+
LoRAs patch them), but the Qwen3-VL text encoder itself is not. Set
|
| 333 |
+
strength 1.0 for Krea's official style LoRAs (the shipped template uses
|
| 334 |
+
0.8) and add the LoRA's trigger word to the prompt.
|
| 335 |
+
|
| 336 |
+
6. Sampler settings: steps 8, cfg 1, sampler euler, scheduler simple,
|
| 337 |
+
denoise 1.0. Do not add a ModelSampling node for plain t2i - ComfyUI
|
| 338 |
+
already applies shift 1.15 from Krea2.sampling_settings.
|
| 339 |
+
|
| 340 |
+
7. For style reference, use the dedicated template: UNETLoader
|
| 341 |
+
krea2_turbo_int8_convrot.safetensors, LoraLoaderModelOnly
|
| 342 |
+
krea2_style_reference.safetensors at 1.0, ModelSamplingFlux (1.15, 0.5),
|
| 343 |
+
TextEncodeQwenImageEditPlus fed by LoadImage,
|
| 344 |
+
FluxKontextMultiReferenceLatentMethod set to index_timestep_zero, and
|
| 345 |
+
SamplerCustomAdvanced with KSamplerSelect euler + BasicScheduler simple/8 +
|
| 346 |
+
CFGGuider cfg 1.
|
| 347 |
+
|
| 348 |
+
8. For instruction editing (Krea 2 Identity Edit), stock nodes are not
|
| 349 |
+
enough: install the ComfyUI-Krea2Edit node pack, which ships its own
|
| 350 |
+
workflows, and run Turbo at 8-12 steps / cfg 1 (or Raw at 20 steps / cfg 3
|
| 351 |
+
for removals) with LoRA strength 1.0.
|
| 352 |
+
|
| 353 |
+
9. Low-VRAM alternative: install city96's ComfyUI-GGUF and use a community
|
| 354 |
+
GGUF build (realrebelai/KREA-2_GGUFs, quantized from Turbo;
|
| 355 |
+
molbal/krea2-gguf, quantized from Raw) with the Unet Loader (GGUF) node in
|
| 356 |
+
place of UNETLoader. There is no official GGUF release. LoRA loading is
|
| 357 |
+
unchanged.
|
| 358 |
+
|
| 359 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 360 |
+
Scraped by lorakit on 2026-09-05 03:59 UTC.
|
| 361 |
+
Stats and description are the author's; pros/cons are derived from the
|
| 362 |
+
evidence tagged beside each line.
|
| 363 |
+
───────────────────────────────────────────────────────────────────────────────
|
between-pages/metadata.json
ADDED
|
@@ -0,0 +1,141 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"name": "Between Pages",
|
| 3 |
+
"slug": "between-pages",
|
| 4 |
+
"base_model": "Krea 2",
|
| 5 |
+
"media_type": "image",
|
| 6 |
+
"model_id": 2375795,
|
| 7 |
+
"version_id": 3272240,
|
| 8 |
+
"version_name": "v1.0 Krea 2",
|
| 9 |
+
"source": "civitai",
|
| 10 |
+
"url": "https://civitai.com/models/2375795",
|
| 11 |
+
"repo_id": null,
|
| 12 |
+
"file_path": null,
|
| 13 |
+
"author": "Daalis",
|
| 14 |
+
"category": {
|
| 15 |
+
"key": "photoreal",
|
| 16 |
+
"label": "Photorealism"
|
| 17 |
+
},
|
| 18 |
+
"modalities": [],
|
| 19 |
+
"primary_modality": "unspecified",
|
| 20 |
+
"checkpoint_family": "unknown",
|
| 21 |
+
"trigger_words": [
|
| 22 |
+
"PagesDaal"
|
| 23 |
+
],
|
| 24 |
+
"recommended_settings": {},
|
| 25 |
+
"chaining": {
|
| 26 |
+
"author": {
|
| 27 |
+
"stacks": "not stated",
|
| 28 |
+
"notes": "",
|
| 29 |
+
"avoid": [],
|
| 30 |
+
"requires": [],
|
| 31 |
+
"order": "",
|
| 32 |
+
"strength": "",
|
| 33 |
+
"stated": false
|
| 34 |
+
},
|
| 35 |
+
"general_rules": [
|
| 36 |
+
"The most important rule is not about chaining but about which checkpoint you chain onto: the official README says in bold \"TRAIN on Raw and RUN on Turbo\", and \"We highly recommend using RAW for training LoRAs and applying them on Turbo for inference.\" LoRAs trained on Raw are stated to work well on Turbo.",
|
| 37 |
+
"Chain with LoraLoaderModelOnly nodes in series (model -> model). Krea 2 LoRAs are DiT-only, so there is no CLIP side to chain and the text-encoder branch stays untouched however many LoRAs you add.",
|
| 38 |
+
"Krea 2 LoRAs stack in practice and the community treats multi-LoRA as routine - style + character, style + slider, realism + character. Several CivitAI Krea 2 authors state their LoRAs stack cleanly; one writes \"I recently stacked over 20 of my own LoRAs on a single generation and the output still came out great.\"",
|
| 39 |
+
"Reduce per-LoRA strength when stacking. CivitAI Krea 2 authors converge on dropping from ~1.0 to roughly 0.6-0.9 once more than one adapter is loaded. The CivitAI 12GB training guide also notes rank affects composability: \"rank 8 produced a lighter style influence that was easier to stack with other LoRAs, rank 16 provided a useful balance between concept strength and composability, and rank 32 was better suited to a precise object or concept intended to take priority over other stacked LoRAs.\"",
|
| 40 |
+
"Accelerator LoRAs are position-sensitive in intent, not in node order: a Raw-to-Turbo delta adapter belongs on the Raw checkpoint, a sub-8-step LoRA belongs on Turbo (or on Raw already carrying a Raw-to-Turbo adapter). Chaining Raw -> Raw-to-Turbo adapter -> 4-step LoRA is explicitly recommended by the 4-step LoRA's author.",
|
| 41 |
+
"Whatever you stack, the schedule must stay Turbo's: cfg 1.0 in ComfyUI (guidance 0.0 in diffusers) and mu/shift 1.15. The 4-step LoRA's card says \"Keep mu = 1.15. The training targets are anchored to that grid; a different shift moves the [sampler off them]\"; the same reasoning applies to any Turbo-trained adapter in the chain.",
|
| 42 |
+
"Reference/edit LoRAs are designed to be stacked under ordinary subject and style LoRAs - the Identity Edit card states \"Composes with your LoRAs: character/body/style LoRAs stack on top and steer the prior\" and recommends a stacked subject LoRA when unusual subjects drift toward the base prior.",
|
| 43 |
+
"Krea 2 LoRAs cannot be chained with LoRAs for any other base model. Many CivitAI pages carry multi-model titles like \"(Krea-2 + ZIT)\" or \"[Flux | ZIB | Krea2]\" - those are separate files for separate architectures shipped under one model page, not a combined adapter.",
|
| 44 |
+
"To combine two full Krea 2 checkpoints rather than adapters, ComfyUI ships a dedicated ModelMergeKrea2 node (added in v0.27.0) with per-section weights for first., tmlp., txtmlp., tproj., txtfusion.projector, txtfusion.layerwise_blocks.0-1, txtfusion.refiner_blocks.0-1, blocks.0-27 and last.",
|
| 45 |
+
"The author never states which weight family this targets. Silent degradation, never a hard error, between Raw and Turbo. The two share one architecture - ai-toolkit's config is commented \"The reference 'single_mmdit_large_wide' architecture (oss_raw / oss_turbo share it)\" - so every LoRA tensor shape matches on both and ComfyUI/diffuser"
|
| 46 |
+
]
|
| 47 |
+
},
|
| 48 |
+
"pros": [
|
| 49 |
+
"Well established — 1,687 downloads. [source: CivitAI stats]",
|
| 50 |
+
"Positively received — 173 thumbs-up with no down-votes. [source: CivitAI stats]",
|
| 51 |
+
"Explicit trigger word(s) — PagesDaal — so the effect can be turned on and off from the prompt. [source: model metadata]",
|
| 52 |
+
"Compact at 218 MB — cheap to stack with other LoRAs. [source: file size]"
|
| 53 |
+
],
|
| 54 |
+
"cons": [
|
| 55 |
+
"Needs a reduced strength; the default 1.0 is likely too strong. [source: description]",
|
| 56 |
+
"Author never states which generation mode it was trained for; test against your own workflow before relying on it. [source: description]"
|
| 57 |
+
],
|
| 58 |
+
"file": {
|
| 59 |
+
"name": "Between Pages - Krea2_000002750.safetensors",
|
| 60 |
+
"size_bytes": 228587800,
|
| 61 |
+
"size_mb": 218.0,
|
| 62 |
+
"sha256": "68261c1ef5b78804f301a6f9c24d469e86934b47f5fbcc1e1d19e2bd79435117"
|
| 63 |
+
},
|
| 64 |
+
"stats": {
|
| 65 |
+
"downloads": 1687,
|
| 66 |
+
"thumbs_up": 173,
|
| 67 |
+
"thumbs_down": 0
|
| 68 |
+
},
|
| 69 |
+
"popularity": {
|
| 70 |
+
"downloads": 1687,
|
| 71 |
+
"thumbs_up": 173,
|
| 72 |
+
"thumbs_down": 0,
|
| 73 |
+
"comments": 4,
|
| 74 |
+
"approval": "100% positive (173/173)",
|
| 75 |
+
"age_days": 8.5,
|
| 76 |
+
"downloads_per_day": 23.96,
|
| 77 |
+
"rank_by_downloads": 128,
|
| 78 |
+
"rank_by_momentum": 166,
|
| 79 |
+
"of_total": 200,
|
| 80 |
+
"adoption_tier": "Modest",
|
| 81 |
+
"momentum": "Long tail · fresh release"
|
| 82 |
+
},
|
| 83 |
+
"selection_score": 85.6,
|
| 84 |
+
"selection_reasons": [
|
| 85 |
+
"1,687 downloads",
|
| 86 |
+
"173 thumbs-up",
|
| 87 |
+
"documented triggers + usage notes",
|
| 88 |
+
"top-ranked for its category"
|
| 89 |
+
],
|
| 90 |
+
"example_media": [
|
| 91 |
+
{
|
| 92 |
+
"file": "01_image.jpeg",
|
| 93 |
+
"type": "image",
|
| 94 |
+
"resolution": "1408x2048",
|
| 95 |
+
"prompt": ""
|
| 96 |
+
},
|
| 97 |
+
{
|
| 98 |
+
"file": "02_image.jpeg",
|
| 99 |
+
"type": "image",
|
| 100 |
+
"resolution": "840x1256",
|
| 101 |
+
"prompt": ""
|
| 102 |
+
},
|
| 103 |
+
{
|
| 104 |
+
"file": "03_image.jpeg",
|
| 105 |
+
"type": "image",
|
| 106 |
+
"resolution": "840x1256",
|
| 107 |
+
"prompt": ""
|
| 108 |
+
},
|
| 109 |
+
{
|
| 110 |
+
"file": "04_image.jpeg",
|
| 111 |
+
"type": "image",
|
| 112 |
+
"resolution": "832x1248",
|
| 113 |
+
"prompt": ""
|
| 114 |
+
},
|
| 115 |
+
{
|
| 116 |
+
"file": "05_image.jpeg",
|
| 117 |
+
"type": "image",
|
| 118 |
+
"resolution": "832x1248",
|
| 119 |
+
"prompt": ""
|
| 120 |
+
},
|
| 121 |
+
{
|
| 122 |
+
"file": "06_image.jpeg",
|
| 123 |
+
"type": "image",
|
| 124 |
+
"resolution": "832x1248",
|
| 125 |
+
"prompt": ""
|
| 126 |
+
}
|
| 127 |
+
],
|
| 128 |
+
"tags": [
|
| 129 |
+
"cute",
|
| 130 |
+
"girls",
|
| 131 |
+
"book",
|
| 132 |
+
"big eyes",
|
| 133 |
+
"animals",
|
| 134 |
+
"concept",
|
| 135 |
+
"warm",
|
| 136 |
+
"love",
|
| 137 |
+
"emotion"
|
| 138 |
+
],
|
| 139 |
+
"scraped_at": "2026-09-05T03:59:13+00:00",
|
| 140 |
+
"path": "krea-2/between-pages"
|
| 141 |
+
}
|
cutecaption-ultrainsta-the-ultimate-influencer-character/example_images/01_image.jpeg
ADDED

|
Git LFS Details
|
cutecaption-ultrainsta-the-ultimate-influencer-character/example_images/02_image.jpeg
ADDED

|
cutecaption-ultrainsta-the-ultimate-influencer-character/example_images/03_image.jpeg
ADDED

|
Git LFS Details
|
cutecaption-ultrainsta-the-ultimate-influencer-character/example_images/04_image.jpeg
ADDED

|
Git LFS Details
|
cutecaption-ultrainsta-the-ultimate-influencer-character/example_images/05_image.jpeg
ADDED

|
Git LFS Details
|
cutecaption-ultrainsta-the-ultimate-influencer-character/example_images/06_image.jpeg
ADDED

|
Git LFS Details
|
cutecaption-ultrainsta-the-ultimate-influencer-character/info.txt
ADDED
|
@@ -0,0 +1,400 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
═══════════════════════════════════════════════════════════════════════════════
|
| 2 |
+
CUTECAPTION | ULTRAINSTA - THE ULTIMATE INFLUENCER CHARACTER CREATION
|
| 3 |
+
SOLUTION
|
| 4 |
+
═══════════════════════════════════════════════════════════════════════════════
|
| 5 |
+
|
| 6 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 7 |
+
IDENTITY
|
| 8 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 9 |
+
Base model Krea 2
|
| 10 |
+
Generation mode not declared by the author
|
| 11 |
+
Checkpoint not determined — verify before use
|
| 12 |
+
Category Speed / step-reduction
|
| 13 |
+
Author CuteCaption
|
| 14 |
+
Source https://civitai.com/models/2410789
|
| 15 |
+
Provenance CivitAI · model 2410789 · version 3155234
|
| 16 |
+
|
| 17 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 18 |
+
WEIGHTS
|
| 19 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 20 |
+
File ultrainsta_krea2_V3_000004995.safetensors
|
| 21 |
+
Version V1.1 Krea2
|
| 22 |
+
Size 531.3 MB
|
| 23 |
+
Format SafeTensor / unknown precision
|
| 24 |
+
SHA256 9068d03e5d3938a718f79d6dfe247997bec9053879aa1871d82554cb48bbbeae
|
| 25 |
+
Published 2026-07-23
|
| 26 |
+
|
| 27 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 28 |
+
TRIGGER WORDS
|
| 29 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 30 |
+
› "1NST4GR4M"
|
| 31 |
+
› "OnlyFans Style"
|
| 32 |
+
› "Instagram Style Selfie"
|
| 33 |
+
|
| 34 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 35 |
+
RECOMMENDED SETTINGS
|
| 36 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 37 |
+
Taken verbatim from the author's description:
|
| 38 |
+
|
| 39 |
+
LoRA strength 0.10
|
| 40 |
+
|
| 41 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 42 |
+
ADOPTION & POPULARITY
|
| 43 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 44 |
+
Downloads 2,220
|
| 45 |
+
Rating 100% positive (112/112)
|
| 46 |
+
Comments 7
|
| 47 |
+
Published 44 days ago
|
| 48 |
+
Download rate 20.4/day since release
|
| 49 |
+
|
| 50 |
+
Adoption rank #108 of 200 in this collection (Modest)
|
| 51 |
+
Momentum rank #183 of 200 by download rate (Long tail · fresh release)
|
| 52 |
+
|
| 53 |
+
Adoption tier is the percentile of total downloads within this collection;
|
| 54 |
+
momentum is the percentile of downloads-per-day since release. Momentum is
|
| 55 |
+
ranked rather than measured against a fixed rate, because this base model
|
| 56 |
+
is itself new and every LoRA looks fast on an absolute scale. Both numbers
|
| 57 |
+
are CivitAI's, read on the scrape date at the foot of this file.
|
| 58 |
+
|
| 59 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 60 |
+
CHAINING / STACKING
|
| 61 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 62 |
+
Stacks with others not stated
|
| 63 |
+
|
| 64 |
+
The author gave no chaining guidance. The rules below are the
|
| 65 |
+
general Krea 2 ones, not anything specific to this LoRA.
|
| 66 |
+
|
| 67 |
+
General Krea 2 rules that apply here (see REFERENCE.txt):
|
| 68 |
+
|
| 69 |
+
• The most important rule is not about chaining but about which
|
| 70 |
+
checkpoint you chain onto: the official README says in bold "TRAIN on
|
| 71 |
+
Raw and RUN on Turbo", and "We highly recommend using RAW for training
|
| 72 |
+
LoRAs and applying them on Turbo for inference." LoRAs trained on Raw
|
| 73 |
+
are stated to work well on Turbo.
|
| 74 |
+
• Chain with LoraLoaderModelOnly nodes in series (model -> model). Krea 2
|
| 75 |
+
LoRAs are DiT-only, so there is no CLIP side to chain and the text-
|
| 76 |
+
encoder branch stays untouched however many LoRAs you add.
|
| 77 |
+
• Krea 2 LoRAs stack in practice and the community treats multi-LoRA as
|
| 78 |
+
routine - style + character, style + slider, realism + character.
|
| 79 |
+
Several CivitAI Krea 2 authors state their LoRAs stack cleanly; one
|
| 80 |
+
writes "I recently stacked over 20 of my own LoRAs on a single
|
| 81 |
+
generation and the output still came out great."
|
| 82 |
+
• Reduce per-LoRA strength when stacking. CivitAI Krea 2 authors converge
|
| 83 |
+
on dropping from ~1.0 to roughly 0.6-0.9 once more than one adapter is
|
| 84 |
+
loaded. The CivitAI 12GB training guide also notes rank affects
|
| 85 |
+
composability: "rank 8 produced a lighter style influence that was
|
| 86 |
+
easier to stack with other LoRAs, rank 16 provided a useful balance
|
| 87 |
+
between concept strength and composability, and rank 32 was better
|
| 88 |
+
suited to a precise object or concept intended to take priority over
|
| 89 |
+
other stacked LoRAs."
|
| 90 |
+
• Accelerator LoRAs are position-sensitive in intent, not in node order:
|
| 91 |
+
a Raw-to-Turbo delta adapter belongs on the Raw checkpoint, a
|
| 92 |
+
sub-8-step LoRA belongs on Turbo (or on Raw already carrying a Raw-to-
|
| 93 |
+
Turbo adapter). Chaining Raw -> Raw-to-Turbo adapter -> 4-step LoRA is
|
| 94 |
+
explicitly recommended by the 4-step LoRA's author.
|
| 95 |
+
• Whatever you stack, the schedule must stay Turbo's: cfg 1.0 in ComfyUI
|
| 96 |
+
(guidance 0.0 in diffusers) and mu/shift 1.15. The 4-step LoRA's card
|
| 97 |
+
says "Keep mu = 1.15. The training targets are anchored to that grid; a
|
| 98 |
+
different shift moves the [sampler off them]"; the same reasoning
|
| 99 |
+
applies to any Turbo-trained adapter in the chain.
|
| 100 |
+
• Reference/edit LoRAs are designed to be stacked under ordinary subject
|
| 101 |
+
and style LoRAs - the Identity Edit card states "Composes with your
|
| 102 |
+
LoRAs: character/body/style LoRAs stack on top and steer the prior" and
|
| 103 |
+
recommends a stacked subject LoRA when unusual subjects drift toward
|
| 104 |
+
the base prior.
|
| 105 |
+
• Krea 2 LoRAs cannot be chained with LoRAs for any other base model.
|
| 106 |
+
Many CivitAI pages carry multi-model titles like "(Krea-2 + ZIT)" or
|
| 107 |
+
"[Flux | ZIB | Krea2]" - those are separate files for separate
|
| 108 |
+
architectures shipped under one model page, not a combined adapter.
|
| 109 |
+
• To combine two full Krea 2 checkpoints rather than adapters, ComfyUI
|
| 110 |
+
ships a dedicated ModelMergeKrea2 node (added in v0.27.0) with per-
|
| 111 |
+
section weights for first., tmlp., txtmlp., tproj.,
|
| 112 |
+
txtfusion.projector, txtfusion.layerwise_blocks.0-1,
|
| 113 |
+
txtfusion.refiner_blocks.0-1, blocks.0-27 and last.
|
| 114 |
+
• Krea 2 Turbo is itself the official step-reduction artefact - the
|
| 115 |
+
technical report describes a final timestep-distillation stage using
|
| 116 |
+
TDM (Trajectory Distribution Matching), chosen for being "simple to
|
| 117 |
+
tune, with minimal hyperparameters", producing an 8-step CFG-free
|
| 118 |
+
checkpoint from Raw. It is a full checkpoint, not a LoRA. Three LoRA-
|
| 119 |
+
shaped accelerators exist around it: 1. Raw-to-Turbo delta adapters.
|
| 120 |
+
Comfy-Org/Krea-2 ships loras/krea2_turbo_lora_rank_64_bf16.safetensors
|
| 121 |
+
- I read its header directly: 535 tensors, rank 64, ComfyUI-native
|
| 122 |
+
diffusion_model.*.lora_down/lora_up keys, no __metadata
|
| 123 |
+
• The author never states which weight family this targets. Silent
|
| 124 |
+
degradation, never a hard error, between Raw and Turbo. The two share
|
| 125 |
+
one architecture - ai-toolkit's config is commented "The reference
|
| 126 |
+
'single_mmdit_large_wide' architecture (oss_raw / oss_turbo share it)"
|
| 127 |
+
- so every LoRA tensor shape matches on both and ComfyUI/diffuser
|
| 128 |
+
|
| 129 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 130 |
+
PROS
|
| 131 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 132 |
+
+ Well established — 2,220 downloads. [source: CivitAI stats]
|
| 133 |
+
+ Positively received — 112 thumbs-up with no down-votes. [source:
|
| 134 |
+
CivitAI stats]
|
| 135 |
+
+ Explicit trigger word(s) — 1NST4GR4M, OnlyFans Style, Instagram Style
|
| 136 |
+
Selfie — so the effect can be turned on and off from the prompt.
|
| 137 |
+
[source: model metadata]
|
| 138 |
+
+ Author published concrete recommended settings. [source: description]
|
| 139 |
+
|
| 140 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 141 |
+
CONS & CAVEATS
|
| 142 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 143 |
+
- Author labels this experimental — results vary shot to shot. [source:
|
| 144 |
+
description]
|
| 145 |
+
- Author references NSFW output — review before using in shared work.
|
| 146 |
+
[source: description]
|
| 147 |
+
- Author never states which generation mode it was trained for; test
|
| 148 |
+
against your own workflow before relying on it. [source: description]
|
| 149 |
+
|
| 150 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 151 |
+
COMPATIBILITY WARNING
|
| 152 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 153 |
+
Silent degradation, never a hard error, between Raw and Turbo. The two
|
| 154 |
+
share one architecture - ai-toolkit's config is commented "The reference
|
| 155 |
+
'single_mmdit_large_wide' architecture (oss_raw / oss_turbo share it)" - so
|
| 156 |
+
every LoRA tensor shape matches on both and ComfyUI/diffusers will load an
|
| 157 |
+
adapter against either without complaint. The lvladikov 4-step LoRA card
|
| 158 |
+
states this for the reverse direction: "Every layer it targets also exists
|
| 159 |
+
in Krea 2 Raw, so it will load there without complaint - but that is a side
|
| 160 |
+
effect of the shared architecture, not a supported mode", and reports
|
| 161 |
+
mixed, subject-dependent results with malformed subjects (duplicated heads,
|
| 162 |
+
fused limbs) at low step counts, needing 14+ steps with Raw's CFG on before
|
| 163 |
+
output is coherent. The intended direction (train on Raw, run on Turbo) is
|
| 164 |
+
officially blessed. The more common practical failure is a settings
|
| 165 |
+
mismatch rather than a weight mismatch: running a Turbo-targeted LoRA at
|
| 166 |
+
Raw's 52 steps + CFG 3.5, or leaving CFG enabled on Turbo, degrades output
|
| 167 |
+
with no warning. Loading a Krea 2 LoRA against a different model family
|
| 168 |
+
entirely (Flux, Qwen-Image, Z-Image) is also not an error - ComfyUI logs
|
| 169 |
+
"lora key not loaded: {key}" per key and generates as if no LoRA were
|
| 170 |
+
applied.
|
| 171 |
+
|
| 172 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 173 |
+
AUTHOR'S DESCRIPTION
|
| 174 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 175 |
+
For Krea2 no noising strategies used... Sigmoid, ProdigyPlus, Rank 78,
|
| 176 |
+
trained on pixel areas: - 512 - 768 - 1024 - 1280 - 1328
|
| 177 |
+
weight_decay: 0.01 d_coef: 1.5 ~2,000 images curated curated and pruned
|
| 178 |
+
over span of 3 years -- only about 500 of the original dataset images
|
| 179 |
+
remain, as images have been added and removed over training iterations and
|
| 180 |
+
model architectures, slowly refining the vibe. We are so happy with Krea2
|
| 181 |
+
and the training results. For the actual training, this was written for
|
| 182 |
+
Z-Image, the UltraInsta story stays the same! This LoRA is the full weights
|
| 183 |
+
of a 5k step high noising > balanced noising strategy, that is meant to be
|
| 184 |
+
block-balanced, and then combined with a balanced noising > high noising
|
| 185 |
+
for a merge. I'm pre-releasing it while the final versions of the resulting
|
| 186 |
+
merges are being created and close to being finished. *Please note, this
|
| 187 |
+
LoRA does perform well and creates very beautiful shots, but my plan
|
| 188 |
+
initially was to fine-tune the blocks and release a more finely tuned
|
| 189 |
+
version, but since this process has wound up taking over a month, I've
|
| 190 |
+
decided to release the full weights for the 5k-highnoise>balanced version -
|
| 191 |
+
we are training at Rank 200, FP32 and a slow learning rate. *This LoRA was
|
| 192 |
+
trained before the Stochastic-rounding issues with AdamW8bit were fully
|
| 193 |
+
understood -- for the sake of testing, we will train this LoRA with
|
| 194 |
+
ProdigyPlus for the next versions, but it's possible that training such a
|
| 195 |
+
large dataset on AdamW8bit resulted in minor issues with anatomy under
|
| 196 |
+
certain conditions [training with different noising emphasizes different
|
| 197 |
+
body and face types in my testing, and so by training 2 LoRAs of the same
|
| 198 |
+
dataset with separate strategies, I can block-inject 4-8 blocks from the
|
| 199 |
+
balanced strategy into the high noising strategy, to get the best of both
|
| 200 |
+
worlds (body+face), but the testing has taken a considerable amount of time
|
| 201 |
+
and I want to put out something that the community can use while I continue
|
| 202 |
+
fine-tuning]
|
| 203 |
+
|
| 204 |
+
This LoRA is designed to allow the user to create high quality, unique, and
|
| 205 |
+
extremely beautiful faces and bodies. It is not perfect 100% of the time,
|
| 206 |
+
but when it does work it excels. If you do not get the face you want right
|
| 207 |
+
away, do a batch of 10-20.
|
| 208 |
+
https://comfy.icu/extension/RamonGuthrie__ComfyUI-RBG-SmartSeedVariance You
|
| 209 |
+
can get great results without this, but you should be able to use this node
|
| 210 |
+
with great success if your hope is to engineer a unique, original and
|
| 211 |
+
stunning face that has never existed before, without having to adjust the
|
| 212 |
+
prompt as much. This model will never output 1:1 of any of the subjects in
|
| 213 |
+
the datasets, but has achieve a convergence on a natural, aesthetic balance
|
| 214 |
+
of the dataset contents resulting this vibe being locked into the LoRA. It
|
| 215 |
+
also works great with this: https://github.com/shootthesound/comfyUI-
|
| 216 |
+
Realtime-Lora
|
| 217 |
+
|
| 218 |
+
*If you have a result that you like in another workflow or vanilla ZiT, or
|
| 219 |
+
want to give some aesthetic flavor to an existing photo, try turning on the
|
| 220 |
+
LoRA at a very low weight, and inputting INST4GR4M somewhere in the prompt
|
| 221 |
+
near the area of the prompt you are describing the subject or the subject's
|
| 222 |
+
face, to modulate your existing face.
|
| 223 |
+
|
| 224 |
+
For full generations, you will more than likely need to reduce the weight
|
| 225 |
+
to at least .70, but it will also work as a style and body/face slider.
|
| 226 |
+
Most of the anatomy issues I've encountered are a result of tweaking or
|
| 227 |
+
modifying the block weights using the Realtime LoRA node, or having the
|
| 228 |
+
weight too high. You should be able to achieve great results with the
|
| 229 |
+
typical number of steps for ZiT (8-12)
|
| 230 |
+
**Nude shots: This LoRA had an extremely limited number of nude shots, and
|
| 231 |
+
so it is most likely not going to be a true NSFW solution -- having said
|
| 232 |
+
that though, there is a dedicated portion of images that are strictly from
|
| 233 |
+
OnlyFans, and so it does have some NSFW capability, but I have not tested
|
| 234 |
+
it sufficiently to be able to promise that it will perform well for nude
|
| 235 |
+
shots or things like nipples.
|
| 236 |
+
You may start by creating a base image, that is somewhat close to what you
|
| 237 |
+
want, and then add the LoRA starting at very small weights to introduce
|
| 238 |
+
some aesthetic and style. The closer you get to around .50, the more it
|
| 239 |
+
will change the image. Finally, weights closer to .70 + will result in the
|
| 240 |
+
entire image coming straight from the LoRA, and it acts more like a style
|
| 241 |
+
LoRA than a slider at that point.
|
| 242 |
+
The dataset for this model has been hyper curated for well over a year. It
|
| 243 |
+
has experienced many iterations, prunes and trainings.
|
| 244 |
+
**There will be an updated version of this released soon which is actually
|
| 245 |
+
a block-balanced approach. These are the full weights, which I was not
|
| 246 |
+
planning on releasing. After having been tweaking the blocks for some time,
|
| 247 |
+
and being unable to decide on the best version, I have decided to just
|
| 248 |
+
release the full weights.
|
| 249 |
+
This version is something I am releasing to give the community something
|
| 250 |
+
they can use, while I work to balance the blocks of the main LoRA.
|
| 251 |
+
*I am also going to release the 7k step version, which seems to give a
|
| 252 |
+
slightly different body aesthetic.
|
| 253 |
+
|
| 254 |
+
This is a strategy that started with High-Noising for 1 epoch, so it saw
|
| 255 |
+
every image once with this approach. After the first epoch, I have changed
|
| 256 |
+
the training back to balanced, and allowed it to run for another several
|
| 257 |
+
thousand steps.
|
| 258 |
+
This is 5000k steps, so 2000k steps with high noise, and then the remaining
|
| 259 |
+
was balanced.
|
| 260 |
+
|
| 261 |
+
This LoRA serves to help create new characters, faces and bodies.
|
| 262 |
+
|
| 263 |
+
You can use the trigger INST4GR4M as an activator, or as a modulator. It
|
| 264 |
+
does not need to be put at the beginning of every prompt exclusively; while
|
| 265 |
+
this does work, you can use it anywhere in the prompt to conjure the style
|
| 266 |
+
(or by placing it strategically next to your descriptions of bodies or
|
| 267 |
+
poses).
|
| 268 |
+
In addition to this trigger word, you also have access to "OnlyFans Style",
|
| 269 |
+
which you can use as a trigger or modulator.
|
| 270 |
+
Finally, you also have the option of using "Instagram Style Selfie" -- the
|
| 271 |
+
LoRA was trained on mostly Instagram images,and the most timeless, classic
|
| 272 |
+
selfies were tagged with Instagram Style Selfie.
|
| 273 |
+
You can experiment with using very, very short prompts, with just the
|
| 274 |
+
triggers and modulators.
|
| 275 |
+
You can also utilize very long, extensive prompts.
|
| 276 |
+
The dataset itself was captioned with a diverse captioning strategy. About
|
| 277 |
+
15-20% of the captions are very long and highly descriptive. About 50% of
|
| 278 |
+
the captions have a moderate caption length, with the remaining 10-25% have
|
| 279 |
+
very, very short captions. In my experience, this allows the model to
|
| 280 |
+
become more robust, and allows the user to choose the amount of detail they
|
| 281 |
+
want to provide in their prompt.
|
| 282 |
+
Notes: With higher weights, or manipulating the blocks, we do start to see
|
| 283 |
+
some anatomy issues.
|
| 284 |
+
*Usage Note: If you merge this LoRA with something else, please provide
|
| 285 |
+
credits on the model release page. We have spent hundreds of dollars on
|
| 286 |
+
training and countless thousands of hours refining the dataset and
|
| 287 |
+
improving our training strategy, and the model is completely free.
|
| 288 |
+
https://discord.gg/2gQ5eBtRCj - CuteCaption Discord -- post your results,
|
| 289 |
+
ask questions, tips, etc -- this is also our small community for
|
| 290 |
+
CuteCaption, which is gearing up for a Summer release: a state-of-the-art
|
| 291 |
+
captioning and dataset tooling solution for LoRA engineers.
|
| 292 |
+
|
| 293 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 294 |
+
VERSION NOTES
|
| 295 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 296 |
+
The LoRA can be used for existing generations as a slider to introduce some
|
| 297 |
+
flavor or vibe into the shot, without changing too much so you can start
|
| 298 |
+
with as low as 0.10 strength -- community reports are that it is stable up
|
| 299 |
+
to almost 2.00 strength! So feel free to experiment. If the strength is
|
| 300 |
+
this high, it may have some overbaked feeling, but the compositions remain
|
| 301 |
+
really good so you can easily take them to ChatGPT Images 2.0 and have them
|
| 302 |
+
remastered. For strengths lower than 1.6 or so, the overbaked isn't as bad,
|
| 303 |
+
and actually pushing the LoRA strength seems to really help with the
|
| 304 |
+
amateur vibe For the last 2 years, I have continued to improve, prune and
|
| 305 |
+
refine the Ultra Insta dataset. The timing for Krea2 could not be better.
|
| 306 |
+
Full transparency: During a previous phase of editing the dataset, there
|
| 307 |
+
were around 30-50 images that wound up sneaking in with an artifact of a
|
| 308 |
+
white border on the left and sometimes the left and top. I targeted
|
| 309 |
+
hundreds of images to remove jewelry and simplify some of the scenes, and
|
| 310 |
+
the export process unfortunately has a byproduct of this artifact which I
|
| 311 |
+
did not realize white away. We will eventually re-train this, but it would
|
| 312 |
+
be a waste of a perfectly good model to not upload it due to this. We find
|
| 313 |
+
that it happens with much higher strength, but sometimes it just doesn't
|
| 314 |
+
happen it all. When it does, it's very limited, around 1px. If you are
|
| 315 |
+
using very high strength will want to inspect your images for any white or
|
| 316 |
+
artificial borders just in case.
|
| 317 |
+
|
| 318 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 319 |
+
EXAMPLE MEDIA
|
| 320 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 321 |
+
6 preview(s) in ./example_images/ — community results for
|
| 322 |
+
this LoRA. Videos keep a matching _poster.jpg still frame.
|
| 323 |
+
|
| 324 |
+
No prompts are recorded below: CivitAI's public API flags these posts as
|
| 325 |
+
having generation metadata but does not return it, so the prompts cannot be
|
| 326 |
+
scraped. Open the model page to read them.
|
| 327 |
+
|
| 328 |
+
01_image.jpeg (image, 1776x2368)
|
| 329 |
+
02_image.jpeg (image, 1024x1024)
|
| 330 |
+
03_image.jpeg (image, 1024x1024)
|
| 331 |
+
04_image.jpeg (image, 1536x2304)
|
| 332 |
+
05_image.jpeg (image, 3584x4608)
|
| 333 |
+
06_image.jpeg (image, 3584x4608)
|
| 334 |
+
|
| 335 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 336 |
+
HOW TO USE (COMFYUI)
|
| 337 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 338 |
+
1. Update ComfyUI to at least v0.26.0 (released 2026-06-23), which added
|
| 339 |
+
local Krea2 support. For reference-image / style-reference / edit LoRAs you
|
| 340 |
+
need at least v0.29.0 (2026-07-29), which added regular and timestep-zero
|
| 341 |
+
reference images for Krea 2. ModelMergeKrea2 arrived in v0.27.0
|
| 342 |
+
(2026-06-30).
|
| 343 |
+
|
| 344 |
+
2. Put the base stack in place (files from huggingface.co/Comfy-Org/Krea-2,
|
| 345 |
+
which is not gated):
|
| 346 |
+
- ComfyUI/models/diffusion_models/krea2_turbo_fp8_scaled.safetensors
|
| 347 |
+
(documented recommended default; the repo also holds krea2_turbo_bf16,
|
| 348 |
+
_int8_convrot, _mxfp8, _nvfp4 and krea2_raw_bf16 / _fp8_scaled /
|
| 349 |
+
_int8_convrot)
|
| 350 |
+
- ComfyUI/models/text_encoders/qwen3vl_4b_fp8_scaled.safetensors (bf16
|
| 351 |
+
also available)
|
| 352 |
+
- ComfyUI/models/vae/qwen_image_vae.safetensors
|
| 353 |
+
|
| 354 |
+
3. Put the LoRA .safetensors in ComfyUI/models/loras/ - flat, no per-model
|
| 355 |
+
subfolder required.
|
| 356 |
+
|
| 357 |
+
4. Build or load the graph. The official image_krea2_turbo_t2i.json
|
| 358 |
+
template is: UNETLoader (krea2_turbo_fp8_scaled.safetensors) ->
|
| 359 |
+
LoraLoaderModelOnly -> KSampler; CLIPLoader
|
| 360 |
+
(qwen3vl_4b_fp8_scaled.safetensors, type "krea2") -> text encode ->
|
| 361 |
+
KSampler positive, with ConditioningZeroOut into negative; VAELoader
|
| 362 |
+
(qwen_image_vae.safetensors) -> VAEDecode -> SaveImage; EmptyLatentImage
|
| 363 |
+
1024x1024 driven by ResolutionSelector. An int8 sibling template
|
| 364 |
+
(image_krea2_turbo_t2i_int8.json) also ships.
|
| 365 |
+
|
| 366 |
+
5. Load the LoRA with LoraLoaderModelOnly, not LoraLoader - both official
|
| 367 |
+
templates do. Krea 2 LoRAs patch the DiT only; note that the DiT's own
|
| 368 |
+
text_fusion / txtfusion blocks are a normal LoRA target (the official style
|
| 369 |
+
LoRAs patch them), but the Qwen3-VL text encoder itself is not. Set
|
| 370 |
+
strength 1.0 for Krea's official style LoRAs (the shipped template uses
|
| 371 |
+
0.8) and add the LoRA's trigger word to the prompt.
|
| 372 |
+
|
| 373 |
+
6. Sampler settings: steps 8, cfg 1, sampler euler, scheduler simple,
|
| 374 |
+
denoise 1.0. Do not add a ModelSampling node for plain t2i - ComfyUI
|
| 375 |
+
already applies shift 1.15 from Krea2.sampling_settings.
|
| 376 |
+
|
| 377 |
+
7. For style reference, use the dedicated template: UNETLoader
|
| 378 |
+
krea2_turbo_int8_convrot.safetensors, LoraLoaderModelOnly
|
| 379 |
+
krea2_style_reference.safetensors at 1.0, ModelSamplingFlux (1.15, 0.5),
|
| 380 |
+
TextEncodeQwenImageEditPlus fed by LoadImage,
|
| 381 |
+
FluxKontextMultiReferenceLatentMethod set to index_timestep_zero, and
|
| 382 |
+
SamplerCustomAdvanced with KSamplerSelect euler + BasicScheduler simple/8 +
|
| 383 |
+
CFGGuider cfg 1.
|
| 384 |
+
|
| 385 |
+
8. For instruction editing (Krea 2 Identity Edit), stock nodes are not
|
| 386 |
+
enough: install the ComfyUI-Krea2Edit node pack, which ships its own
|
| 387 |
+
workflows, and run Turbo at 8-12 steps / cfg 1 (or Raw at 20 steps / cfg 3
|
| 388 |
+
for removals) with LoRA strength 1.0.
|
| 389 |
+
|
| 390 |
+
9. Low-VRAM alternative: install city96's ComfyUI-GGUF and use a community
|
| 391 |
+
GGUF build (realrebelai/KREA-2_GGUFs, quantized from Turbo;
|
| 392 |
+
molbal/krea2-gguf, quantized from Raw) with the Unet Loader (GGUF) node in
|
| 393 |
+
place of UNETLoader. There is no official GGUF release. LoRA loading is
|
| 394 |
+
unchanged.
|
| 395 |
+
|
| 396 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 397 |
+
Scraped by lorakit on 2026-09-05 03:59 UTC.
|
| 398 |
+
Stats and description are the author's; pros/cons are derived from the
|
| 399 |
+
evidence tagged beside each line.
|
| 400 |
+
───────────────────────────────────────────────────────────────────────────────
|
cutecaption-ultrainsta-the-ultimate-influencer-character/metadata.json
ADDED
|
@@ -0,0 +1,150 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"name": "CuteCaption | UltraInsta - The Ultimate Influencer Character Creation Solution",
|
| 3 |
+
"slug": "cutecaption-ultrainsta-the-ultimate-influencer-character",
|
| 4 |
+
"base_model": "Krea 2",
|
| 5 |
+
"media_type": "image",
|
| 6 |
+
"model_id": 2410789,
|
| 7 |
+
"version_id": 3155234,
|
| 8 |
+
"version_name": "V1.1 Krea2",
|
| 9 |
+
"source": "civitai",
|
| 10 |
+
"url": "https://civitai.com/models/2410789",
|
| 11 |
+
"repo_id": null,
|
| 12 |
+
"file_path": null,
|
| 13 |
+
"author": "CuteCaption",
|
| 14 |
+
"category": {
|
| 15 |
+
"key": "accelerator",
|
| 16 |
+
"label": "Speed / step-reduction"
|
| 17 |
+
},
|
| 18 |
+
"modalities": [],
|
| 19 |
+
"primary_modality": "unspecified",
|
| 20 |
+
"checkpoint_family": "unknown",
|
| 21 |
+
"trigger_words": [
|
| 22 |
+
"1NST4GR4M",
|
| 23 |
+
"OnlyFans Style",
|
| 24 |
+
"Instagram Style Selfie"
|
| 25 |
+
],
|
| 26 |
+
"recommended_settings": {
|
| 27 |
+
"LoRA strength": "0.10"
|
| 28 |
+
},
|
| 29 |
+
"chaining": {
|
| 30 |
+
"author": {
|
| 31 |
+
"stacks": "not stated",
|
| 32 |
+
"notes": "",
|
| 33 |
+
"avoid": [],
|
| 34 |
+
"requires": [],
|
| 35 |
+
"order": "",
|
| 36 |
+
"strength": "",
|
| 37 |
+
"stated": false
|
| 38 |
+
},
|
| 39 |
+
"general_rules": [
|
| 40 |
+
"The most important rule is not about chaining but about which checkpoint you chain onto: the official README says in bold \"TRAIN on Raw and RUN on Turbo\", and \"We highly recommend using RAW for training LoRAs and applying them on Turbo for inference.\" LoRAs trained on Raw are stated to work well on Turbo.",
|
| 41 |
+
"Chain with LoraLoaderModelOnly nodes in series (model -> model). Krea 2 LoRAs are DiT-only, so there is no CLIP side to chain and the text-encoder branch stays untouched however many LoRAs you add.",
|
| 42 |
+
"Krea 2 LoRAs stack in practice and the community treats multi-LoRA as routine - style + character, style + slider, realism + character. Several CivitAI Krea 2 authors state their LoRAs stack cleanly; one writes \"I recently stacked over 20 of my own LoRAs on a single generation and the output still came out great.\"",
|
| 43 |
+
"Reduce per-LoRA strength when stacking. CivitAI Krea 2 authors converge on dropping from ~1.0 to roughly 0.6-0.9 once more than one adapter is loaded. The CivitAI 12GB training guide also notes rank affects composability: \"rank 8 produced a lighter style influence that was easier to stack with other LoRAs, rank 16 provided a useful balance between concept strength and composability, and rank 32 was better suited to a precise object or concept intended to take priority over other stacked LoRAs.\"",
|
| 44 |
+
"Accelerator LoRAs are position-sensitive in intent, not in node order: a Raw-to-Turbo delta adapter belongs on the Raw checkpoint, a sub-8-step LoRA belongs on Turbo (or on Raw already carrying a Raw-to-Turbo adapter). Chaining Raw -> Raw-to-Turbo adapter -> 4-step LoRA is explicitly recommended by the 4-step LoRA's author.",
|
| 45 |
+
"Whatever you stack, the schedule must stay Turbo's: cfg 1.0 in ComfyUI (guidance 0.0 in diffusers) and mu/shift 1.15. The 4-step LoRA's card says \"Keep mu = 1.15. The training targets are anchored to that grid; a different shift moves the [sampler off them]\"; the same reasoning applies to any Turbo-trained adapter in the chain.",
|
| 46 |
+
"Reference/edit LoRAs are designed to be stacked under ordinary subject and style LoRAs - the Identity Edit card states \"Composes with your LoRAs: character/body/style LoRAs stack on top and steer the prior\" and recommends a stacked subject LoRA when unusual subjects drift toward the base prior.",
|
| 47 |
+
"Krea 2 LoRAs cannot be chained with LoRAs for any other base model. Many CivitAI pages carry multi-model titles like \"(Krea-2 + ZIT)\" or \"[Flux | ZIB | Krea2]\" - those are separate files for separate architectures shipped under one model page, not a combined adapter.",
|
| 48 |
+
"To combine two full Krea 2 checkpoints rather than adapters, ComfyUI ships a dedicated ModelMergeKrea2 node (added in v0.27.0) with per-section weights for first., tmlp., txtmlp., tproj., txtfusion.projector, txtfusion.layerwise_blocks.0-1, txtfusion.refiner_blocks.0-1, blocks.0-27 and last.",
|
| 49 |
+
"Krea 2 Turbo is itself the official step-reduction artefact - the technical report describes a final timestep-distillation stage using TDM (Trajectory Distribution Matching), chosen for being \"simple to tune, with minimal hyperparameters\", producing an 8-step CFG-free checkpoint from Raw. It is a full checkpoint, not a LoRA. Three LoRA-shaped accelerators exist around it: 1. Raw-to-Turbo delta adapters. Comfy-Org/Krea-2 ships loras/krea2_turbo_lora_rank_64_bf16.safetensors - I read its header directly: 535 tensors, rank 64, ComfyUI-native diffusion_model.*.lora_down/lora_up keys, no __metadata",
|
| 50 |
+
"The author never states which weight family this targets. Silent degradation, never a hard error, between Raw and Turbo. The two share one architecture - ai-toolkit's config is commented \"The reference 'single_mmdit_large_wide' architecture (oss_raw / oss_turbo share it)\" - so every LoRA tensor shape matches on both and ComfyUI/diffuser"
|
| 51 |
+
]
|
| 52 |
+
},
|
| 53 |
+
"pros": [
|
| 54 |
+
"Well established — 2,220 downloads. [source: CivitAI stats]",
|
| 55 |
+
"Positively received — 112 thumbs-up with no down-votes. [source: CivitAI stats]",
|
| 56 |
+
"Explicit trigger word(s) — 1NST4GR4M, OnlyFans Style, Instagram Style Selfie — so the effect can be turned on and off from the prompt. [source: model metadata]",
|
| 57 |
+
"Author published concrete recommended settings. [source: description]"
|
| 58 |
+
],
|
| 59 |
+
"cons": [
|
| 60 |
+
"Author labels this experimental — results vary shot to shot. [source: description]",
|
| 61 |
+
"Author references NSFW output — review before using in shared work. [source: description]",
|
| 62 |
+
"Author never states which generation mode it was trained for; test against your own workflow before relying on it. [source: description]"
|
| 63 |
+
],
|
| 64 |
+
"file": {
|
| 65 |
+
"name": "ultrainsta_krea2_V3_000004995.safetensors",
|
| 66 |
+
"size_bytes": 557091360,
|
| 67 |
+
"size_mb": 531.28,
|
| 68 |
+
"sha256": "9068d03e5d3938a718f79d6dfe247997bec9053879aa1871d82554cb48bbbeae"
|
| 69 |
+
},
|
| 70 |
+
"stats": {
|
| 71 |
+
"downloads": 2220,
|
| 72 |
+
"thumbs_up": 112,
|
| 73 |
+
"thumbs_down": 0
|
| 74 |
+
},
|
| 75 |
+
"popularity": {
|
| 76 |
+
"downloads": 2220,
|
| 77 |
+
"thumbs_up": 112,
|
| 78 |
+
"thumbs_down": 0,
|
| 79 |
+
"comments": 7,
|
| 80 |
+
"approval": "100% positive (112/112)",
|
| 81 |
+
"age_days": 44.1,
|
| 82 |
+
"downloads_per_day": 20.4,
|
| 83 |
+
"rank_by_downloads": 108,
|
| 84 |
+
"rank_by_momentum": 183,
|
| 85 |
+
"of_total": 200,
|
| 86 |
+
"adoption_tier": "Modest",
|
| 87 |
+
"momentum": "Long tail · fresh release"
|
| 88 |
+
},
|
| 89 |
+
"selection_score": 85.7,
|
| 90 |
+
"selection_reasons": [
|
| 91 |
+
"2,220 downloads",
|
| 92 |
+
"112 thumbs-up",
|
| 93 |
+
"documented triggers + usage notes",
|
| 94 |
+
"top-ranked for its category"
|
| 95 |
+
],
|
| 96 |
+
"example_media": [
|
| 97 |
+
{
|
| 98 |
+
"file": "01_image.jpeg",
|
| 99 |
+
"type": "image",
|
| 100 |
+
"resolution": "1776x2368",
|
| 101 |
+
"prompt": ""
|
| 102 |
+
},
|
| 103 |
+
{
|
| 104 |
+
"file": "02_image.jpeg",
|
| 105 |
+
"type": "image",
|
| 106 |
+
"resolution": "1024x1024",
|
| 107 |
+
"prompt": ""
|
| 108 |
+
},
|
| 109 |
+
{
|
| 110 |
+
"file": "03_image.jpeg",
|
| 111 |
+
"type": "image",
|
| 112 |
+
"resolution": "1024x1024",
|
| 113 |
+
"prompt": ""
|
| 114 |
+
},
|
| 115 |
+
{
|
| 116 |
+
"file": "04_image.jpeg",
|
| 117 |
+
"type": "image",
|
| 118 |
+
"resolution": "1536x2304",
|
| 119 |
+
"prompt": ""
|
| 120 |
+
},
|
| 121 |
+
{
|
| 122 |
+
"file": "05_image.jpeg",
|
| 123 |
+
"type": "image",
|
| 124 |
+
"resolution": "3584x4608",
|
| 125 |
+
"prompt": ""
|
| 126 |
+
},
|
| 127 |
+
{
|
| 128 |
+
"file": "06_image.jpeg",
|
| 129 |
+
"type": "image",
|
| 130 |
+
"resolution": "3584x4608",
|
| 131 |
+
"prompt": ""
|
| 132 |
+
}
|
| 133 |
+
],
|
| 134 |
+
"tags": [
|
| 135 |
+
"style",
|
| 136 |
+
"instagram",
|
| 137 |
+
"vibe slider",
|
| 138 |
+
"style slider",
|
| 139 |
+
"vibe enhancer",
|
| 140 |
+
"body enhancer",
|
| 141 |
+
"face enhancer",
|
| 142 |
+
"body shape",
|
| 143 |
+
"curvy",
|
| 144 |
+
"character creator",
|
| 145 |
+
"portrait",
|
| 146 |
+
"influencer"
|
| 147 |
+
],
|
| 148 |
+
"scraped_at": "2026-09-05T03:59:08+00:00",
|
| 149 |
+
"path": "krea-2/cutecaption-ultrainsta-the-ultimate-influencer-character"
|
| 150 |
+
}
|
cutecaption-ultrainsta-the-ultimate-influencer-character/ultrainsta_krea2_V3_000004995.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:9068d03e5d3938a718f79d6dfe247997bec9053879aa1871d82554cb48bbbeae
|
| 3 |
+
size 557091360
|
desi-dark-lora-for-indian-south-asian-faces-and-darker/D351_D4rk_Krea2_Turbo_v1.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:92a80c711f5d133b0e88b8127d173d35f45f9834b82a2a878bfe0e20ea1aa8f7
|
| 3 |
+
size 228587800
|
desi-dark-lora-for-indian-south-asian-faces-and-darker/example_images/01_image.jpeg
ADDED

|
Git LFS Details
|
desi-dark-lora-for-indian-south-asian-faces-and-darker/example_images/02_poster.jpg
ADDED

|
desi-dark-lora-for-indian-south-asian-faces-and-darker/example_images/02_video.mp4
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:fe5e2eb1d0656f3b326aaf8583809de907367557938f35e45ea5c0f8b2dd0b28
|
| 3 |
+
size 2557823
|
desi-dark-lora-for-indian-south-asian-faces-and-darker/example_images/03_image.jpeg
ADDED

|
Git LFS Details
|
desi-dark-lora-for-indian-south-asian-faces-and-darker/example_images/04_image.jpeg
ADDED

|
Git LFS Details
|
desi-dark-lora-for-indian-south-asian-faces-and-darker/example_images/05_image.jpeg
ADDED

|
Git LFS Details
|
desi-dark-lora-for-indian-south-asian-faces-and-darker/example_images/06_image.jpeg
ADDED

|
Git LFS Details
|
desi-dark-lora-for-indian-south-asian-faces-and-darker/info.txt
ADDED
|
@@ -0,0 +1,267 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
═══════════════════════════════════════════════════════════════════════════════
|
| 2 |
+
DESI DARK - LORA FOR INDIAN/ SOUTH ASIAN FACES AND DARKER SKINTONE - KREA 2
|
| 3 |
+
═══════════════════════════════════════════════════════════════════════════════
|
| 4 |
+
|
| 5 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 6 |
+
IDENTITY
|
| 7 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 8 |
+
Base model Krea 2
|
| 9 |
+
Generation mode not declared by the author
|
| 10 |
+
Checkpoint not determined — verify before use
|
| 11 |
+
Category Speed / step-reduction
|
| 12 |
+
Author Desi_Cafe
|
| 13 |
+
Source https://civitai.com/models/2882959
|
| 14 |
+
Provenance CivitAI · model 2882959 · version 3258632
|
| 15 |
+
|
| 16 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 17 |
+
WEIGHTS
|
| 18 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 19 |
+
File D351_D4rk_Krea2_Turbo_v1.safetensors
|
| 20 |
+
Version v1.0
|
| 21 |
+
Size 218.0 MB
|
| 22 |
+
Format SafeTensor / unknown precision
|
| 23 |
+
SHA256 92a80c711f5d133b0e88b8127d173d35f45f9834b82a2a878bfe0e20ea1aa8f7
|
| 24 |
+
Published 2026-08-23
|
| 25 |
+
|
| 26 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 27 |
+
TRIGGER WORDS
|
| 28 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 29 |
+
› "d351 d4rk"
|
| 30 |
+
|
| 31 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 32 |
+
RECOMMENDED SETTINGS
|
| 33 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 34 |
+
Taken verbatim from the author's description:
|
| 35 |
+
|
| 36 |
+
LoRA strength 0.6
|
| 37 |
+
Sampler steps 4–8
|
| 38 |
+
CFG / guidance 1
|
| 39 |
+
Sampler Euler
|
| 40 |
+
|
| 41 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 42 |
+
ADOPTION & POPULARITY
|
| 43 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 44 |
+
Downloads 477
|
| 45 |
+
Rating 100% positive (35/35)
|
| 46 |
+
Comments 0
|
| 47 |
+
Published 13 days ago
|
| 48 |
+
Download rate 37.7/day since release
|
| 49 |
+
|
| 50 |
+
Adoption rank #197 of 200 in this collection (Niche)
|
| 51 |
+
Momentum rank #101 of 200 by download rate (Long tail · fresh release)
|
| 52 |
+
|
| 53 |
+
Adoption tier is the percentile of total downloads within this collection;
|
| 54 |
+
momentum is the percentile of downloads-per-day since release. Momentum is
|
| 55 |
+
ranked rather than measured against a fixed rate, because this base model
|
| 56 |
+
is itself new and every LoRA looks fast on an absolute scale. Both numbers
|
| 57 |
+
are CivitAI's, read on the scrape date at the foot of this file.
|
| 58 |
+
|
| 59 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 60 |
+
CHAINING / STACKING
|
| 61 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 62 |
+
Stacks with others not stated
|
| 63 |
+
|
| 64 |
+
The author gave no chaining guidance. The rules below are the
|
| 65 |
+
general Krea 2 ones, not anything specific to this LoRA.
|
| 66 |
+
|
| 67 |
+
General Krea 2 rules that apply here (see REFERENCE.txt):
|
| 68 |
+
|
| 69 |
+
• The most important rule is not about chaining but about which
|
| 70 |
+
checkpoint you chain onto: the official README says in bold "TRAIN on
|
| 71 |
+
Raw and RUN on Turbo", and "We highly recommend using RAW for training
|
| 72 |
+
LoRAs and applying them on Turbo for inference." LoRAs trained on Raw
|
| 73 |
+
are stated to work well on Turbo.
|
| 74 |
+
• Chain with LoraLoaderModelOnly nodes in series (model -> model). Krea 2
|
| 75 |
+
LoRAs are DiT-only, so there is no CLIP side to chain and the text-
|
| 76 |
+
encoder branch stays untouched however many LoRAs you add.
|
| 77 |
+
• Krea 2 LoRAs stack in practice and the community treats multi-LoRA as
|
| 78 |
+
routine - style + character, style + slider, realism + character.
|
| 79 |
+
Several CivitAI Krea 2 authors state their LoRAs stack cleanly; one
|
| 80 |
+
writes "I recently stacked over 20 of my own LoRAs on a single
|
| 81 |
+
generation and the output still came out great."
|
| 82 |
+
• Reduce per-LoRA strength when stacking. CivitAI Krea 2 authors converge
|
| 83 |
+
on dropping from ~1.0 to roughly 0.6-0.9 once more than one adapter is
|
| 84 |
+
loaded. The CivitAI 12GB training guide also notes rank affects
|
| 85 |
+
composability: "rank 8 produced a lighter style influence that was
|
| 86 |
+
easier to stack with other LoRAs, rank 16 provided a useful balance
|
| 87 |
+
between concept strength and composability, and rank 32 was better
|
| 88 |
+
suited to a precise object or concept intended to take priority over
|
| 89 |
+
other stacked LoRAs."
|
| 90 |
+
• Accelerator LoRAs are position-sensitive in intent, not in node order:
|
| 91 |
+
a Raw-to-Turbo delta adapter belongs on the Raw checkpoint, a
|
| 92 |
+
sub-8-step LoRA belongs on Turbo (or on Raw already carrying a Raw-to-
|
| 93 |
+
Turbo adapter). Chaining Raw -> Raw-to-Turbo adapter -> 4-step LoRA is
|
| 94 |
+
explicitly recommended by the 4-step LoRA's author.
|
| 95 |
+
• Whatever you stack, the schedule must stay Turbo's: cfg 1.0 in ComfyUI
|
| 96 |
+
(guidance 0.0 in diffusers) and mu/shift 1.15. The 4-step LoRA's card
|
| 97 |
+
says "Keep mu = 1.15. The training targets are anchored to that grid; a
|
| 98 |
+
different shift moves the [sampler off them]"; the same reasoning
|
| 99 |
+
applies to any Turbo-trained adapter in the chain.
|
| 100 |
+
• Reference/edit LoRAs are designed to be stacked under ordinary subject
|
| 101 |
+
and style LoRAs - the Identity Edit card states "Composes with your
|
| 102 |
+
LoRAs: character/body/style LoRAs stack on top and steer the prior" and
|
| 103 |
+
recommends a stacked subject LoRA when unusual subjects drift toward
|
| 104 |
+
the base prior.
|
| 105 |
+
• Krea 2 LoRAs cannot be chained with LoRAs for any other base model.
|
| 106 |
+
Many CivitAI pages carry multi-model titles like "(Krea-2 + ZIT)" or
|
| 107 |
+
"[Flux | ZIB | Krea2]" - those are separate files for separate
|
| 108 |
+
architectures shipped under one model page, not a combined adapter.
|
| 109 |
+
• To combine two full Krea 2 checkpoints rather than adapters, ComfyUI
|
| 110 |
+
ships a dedicated ModelMergeKrea2 node (added in v0.27.0) with per-
|
| 111 |
+
section weights for first., tmlp., txtmlp., tproj.,
|
| 112 |
+
txtfusion.projector, txtfusion.layerwise_blocks.0-1,
|
| 113 |
+
txtfusion.refiner_blocks.0-1, blocks.0-27 and last.
|
| 114 |
+
• Krea 2 Turbo is itself the official step-reduction artefact - the
|
| 115 |
+
technical report describes a final timestep-distillation stage using
|
| 116 |
+
TDM (Trajectory Distribution Matching), chosen for being "simple to
|
| 117 |
+
tune, with minimal hyperparameters", producing an 8-step CFG-free
|
| 118 |
+
checkpoint from Raw. It is a full checkpoint, not a LoRA. Three LoRA-
|
| 119 |
+
shaped accelerators exist around it: 1. Raw-to-Turbo delta adapters.
|
| 120 |
+
Comfy-Org/Krea-2 ships loras/krea2_turbo_lora_rank_64_bf16.safetensors
|
| 121 |
+
- I read its header directly: 535 tensors, rank 64, ComfyUI-native
|
| 122 |
+
diffusion_model.*.lora_down/lora_up keys, no __metadata
|
| 123 |
+
• The author never states which weight family this targets. Silent
|
| 124 |
+
degradation, never a hard error, between Raw and Turbo. The two share
|
| 125 |
+
one architecture - ai-toolkit's config is commented "The reference
|
| 126 |
+
'single_mmdit_large_wide' architecture (oss_raw / oss_turbo share it)"
|
| 127 |
+
- so every LoRA tensor shape matches on both and ComfyUI/diffuser
|
| 128 |
+
|
| 129 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 130 |
+
PROS
|
| 131 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 132 |
+
+ Explicit trigger word(s) — d351 d4rk — so the effect can be turned on
|
| 133 |
+
and off from the prompt. [source: model metadata]
|
| 134 |
+
+ Compact at 218 MB — cheap to stack with other LoRAs. [source: file
|
| 135 |
+
size]
|
| 136 |
+
+ Author published concrete recommended settings. [source: description]
|
| 137 |
+
|
| 138 |
+
───────────��───────────────────────────────────────────────────────────────────
|
| 139 |
+
CONS & CAVEATS
|
| 140 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 141 |
+
- Author never states which generation mode it was trained for; test
|
| 142 |
+
against your own workflow before relying on it. [source: description]
|
| 143 |
+
- Modest adoption (477 downloads) — less community feedback to rely on.
|
| 144 |
+
[source: source stats]
|
| 145 |
+
|
| 146 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 147 |
+
COMPATIBILITY WARNING
|
| 148 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 149 |
+
Silent degradation, never a hard error, between Raw and Turbo. The two
|
| 150 |
+
share one architecture - ai-toolkit's config is commented "The reference
|
| 151 |
+
'single_mmdit_large_wide' architecture (oss_raw / oss_turbo share it)" - so
|
| 152 |
+
every LoRA tensor shape matches on both and ComfyUI/diffusers will load an
|
| 153 |
+
adapter against either without complaint. The lvladikov 4-step LoRA card
|
| 154 |
+
states this for the reverse direction: "Every layer it targets also exists
|
| 155 |
+
in Krea 2 Raw, so it will load there without complaint - but that is a side
|
| 156 |
+
effect of the shared architecture, not a supported mode", and reports
|
| 157 |
+
mixed, subject-dependent results with malformed subjects (duplicated heads,
|
| 158 |
+
fused limbs) at low step counts, needing 14+ steps with Raw's CFG on before
|
| 159 |
+
output is coherent. The intended direction (train on Raw, run on Turbo) is
|
| 160 |
+
officially blessed. The more common practical failure is a settings
|
| 161 |
+
mismatch rather than a weight mismatch: running a Turbo-targeted LoRA at
|
| 162 |
+
Raw's 52 steps + CFG 3.5, or leaving CFG enabled on Turbo, degrades output
|
| 163 |
+
with no warning. Loading a Krea 2 LoRA against a different model family
|
| 164 |
+
entirely (Flux, Qwen-Image, Z-Image) is also not an error - ComfyUI logs
|
| 165 |
+
"lora key not loaded: {key}" per key and generates as if no LoRA were
|
| 166 |
+
applied.
|
| 167 |
+
|
| 168 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 169 |
+
AUTHOR'S DESCRIPTION
|
| 170 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 171 |
+
A LoRA that draws on the same data set as other Desi Coffee models produce
|
| 172 |
+
women with Indian features and dark skin tones.
|
| 173 |
+
Recommended settings:
|
| 174 |
+
- CFG: 1-1.5
|
| 175 |
+
|
| 176 |
+
- Steps: 4-8
|
| 177 |
+
|
| 178 |
+
- Weight: 0.6-1
|
| 179 |
+
|
| 180 |
+
- Sampler: Euler/ ER SDE
|
| 181 |
+
|
| 182 |
+
- Scheduler: Beta
|
| 183 |
+
|
| 184 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 185 |
+
EXAMPLE MEDIA
|
| 186 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 187 |
+
6 preview(s) in ./example_images/ — community results for
|
| 188 |
+
this LoRA. Videos keep a matching _poster.jpg still frame.
|
| 189 |
+
|
| 190 |
+
No prompts are recorded below: CivitAI's public API flags these posts as
|
| 191 |
+
having generation metadata but does not return it, so the prompts cannot be
|
| 192 |
+
scraped. Open the model page to read them.
|
| 193 |
+
|
| 194 |
+
01_image.jpeg (image, 944x1280)
|
| 195 |
+
02_video.mp4 (video, 752x1024)
|
| 196 |
+
still: 02_poster.jpg
|
| 197 |
+
03_image.jpeg (image, 856x1280)
|
| 198 |
+
04_image.jpeg (image, 944x1280)
|
| 199 |
+
05_image.jpeg (image, 856x1280)
|
| 200 |
+
06_image.jpeg (image, 1280x1280)
|
| 201 |
+
|
| 202 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 203 |
+
HOW TO USE (COMFYUI)
|
| 204 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 205 |
+
1. Update ComfyUI to at least v0.26.0 (released 2026-06-23), which added
|
| 206 |
+
local Krea2 support. For reference-image / style-reference / edit LoRAs you
|
| 207 |
+
need at least v0.29.0 (2026-07-29), which added regular and timestep-zero
|
| 208 |
+
reference images for Krea 2. ModelMergeKrea2 arrived in v0.27.0
|
| 209 |
+
(2026-06-30).
|
| 210 |
+
|
| 211 |
+
2. Put the base stack in place (files from huggingface.co/Comfy-Org/Krea-2,
|
| 212 |
+
which is not gated):
|
| 213 |
+
- ComfyUI/models/diffusion_models/krea2_turbo_fp8_scaled.safetensors
|
| 214 |
+
(documented recommended default; the repo also holds krea2_turbo_bf16,
|
| 215 |
+
_int8_convrot, _mxfp8, _nvfp4 and krea2_raw_bf16 / _fp8_scaled /
|
| 216 |
+
_int8_convrot)
|
| 217 |
+
- ComfyUI/models/text_encoders/qwen3vl_4b_fp8_scaled.safetensors (bf16
|
| 218 |
+
also available)
|
| 219 |
+
- ComfyUI/models/vae/qwen_image_vae.safetensors
|
| 220 |
+
|
| 221 |
+
3. Put the LoRA .safetensors in ComfyUI/models/loras/ - flat, no per-model
|
| 222 |
+
subfolder required.
|
| 223 |
+
|
| 224 |
+
4. Build or load the graph. The official image_krea2_turbo_t2i.json
|
| 225 |
+
template is: UNETLoader (krea2_turbo_fp8_scaled.safetensors) ->
|
| 226 |
+
LoraLoaderModelOnly -> KSampler; CLIPLoader
|
| 227 |
+
(qwen3vl_4b_fp8_scaled.safetensors, type "krea2") -> text encode ->
|
| 228 |
+
KSampler positive, with ConditioningZeroOut into negative; VAELoader
|
| 229 |
+
(qwen_image_vae.safetensors) -> VAEDecode -> SaveImage; EmptyLatentImage
|
| 230 |
+
1024x1024 driven by ResolutionSelector. An int8 sibling template
|
| 231 |
+
(image_krea2_turbo_t2i_int8.json) also ships.
|
| 232 |
+
|
| 233 |
+
5. Load the LoRA with LoraLoaderModelOnly, not LoraLoader - both official
|
| 234 |
+
templates do. Krea 2 LoRAs patch the DiT only; note that the DiT's own
|
| 235 |
+
text_fusion / txtfusion blocks are a normal LoRA target (the official style
|
| 236 |
+
LoRAs patch them), but the Qwen3-VL text encoder itself is not. Set
|
| 237 |
+
strength 1.0 for Krea's official style LoRAs (the shipped template uses
|
| 238 |
+
0.8) and add the LoRA's trigger word to the prompt.
|
| 239 |
+
|
| 240 |
+
6. Sampler settings: steps 8, cfg 1, sampler euler, scheduler simple,
|
| 241 |
+
denoise 1.0. Do not add a ModelSampling node for plain t2i - ComfyUI
|
| 242 |
+
already applies shift 1.15 from Krea2.sampling_settings.
|
| 243 |
+
|
| 244 |
+
7. For style reference, use the dedicated template: UNETLoader
|
| 245 |
+
krea2_turbo_int8_convrot.safetensors, LoraLoaderModelOnly
|
| 246 |
+
krea2_style_reference.safetensors at 1.0, ModelSamplingFlux (1.15, 0.5),
|
| 247 |
+
TextEncodeQwenImageEditPlus fed by LoadImage,
|
| 248 |
+
FluxKontextMultiReferenceLatentMethod set to index_timestep_zero, and
|
| 249 |
+
SamplerCustomAdvanced with KSamplerSelect euler + BasicScheduler simple/8 +
|
| 250 |
+
CFGGuider cfg 1.
|
| 251 |
+
|
| 252 |
+
8. For instruction editing (Krea 2 Identity Edit), stock nodes are not
|
| 253 |
+
enough: install the ComfyUI-Krea2Edit node pack, which ships its own
|
| 254 |
+
workflows, and run Turbo at 8-12 steps / cfg 1 (or Raw at 20 steps / cfg 3
|
| 255 |
+
for removals) with LoRA strength 1.0.
|
| 256 |
+
|
| 257 |
+
9. Low-VRAM alternative: install city96's ComfyUI-GGUF and use a community
|
| 258 |
+
GGUF build (realrebelai/KREA-2_GGUFs, quantized from Turbo;
|
| 259 |
+
molbal/krea2-gguf, quantized from Raw) with the Unet Loader (GGUF) node in
|
| 260 |
+
place of UNETLoader. There is no official GGUF release. LoRA loading is
|
| 261 |
+
unchanged.
|
| 262 |
+
|
| 263 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 264 |
+
Scraped by lorakit on 2026-09-05 03:59 UTC.
|
| 265 |
+
Stats and description are the author's; pros/cons are derived from the
|
| 266 |
+
evidence tagged beside each line.
|
| 267 |
+
───────────────────────────────────────────────────────────────────────────────
|
desi-dark-lora-for-indian-south-asian-faces-and-darker/metadata.json
ADDED
|
@@ -0,0 +1,142 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"name": "Desi Dark - LoRA for Indian/ South Asian Faces and Darker Skintone - Krea 2",
|
| 3 |
+
"slug": "desi-dark-lora-for-indian-south-asian-faces-and-darker",
|
| 4 |
+
"base_model": "Krea 2",
|
| 5 |
+
"media_type": "image",
|
| 6 |
+
"model_id": 2882959,
|
| 7 |
+
"version_id": 3258632,
|
| 8 |
+
"version_name": "v1.0",
|
| 9 |
+
"source": "civitai",
|
| 10 |
+
"url": "https://civitai.com/models/2882959",
|
| 11 |
+
"repo_id": null,
|
| 12 |
+
"file_path": null,
|
| 13 |
+
"author": "Desi_Cafe",
|
| 14 |
+
"category": {
|
| 15 |
+
"key": "accelerator",
|
| 16 |
+
"label": "Speed / step-reduction"
|
| 17 |
+
},
|
| 18 |
+
"modalities": [],
|
| 19 |
+
"primary_modality": "unspecified",
|
| 20 |
+
"checkpoint_family": "unknown",
|
| 21 |
+
"trigger_words": [
|
| 22 |
+
"d351 d4rk"
|
| 23 |
+
],
|
| 24 |
+
"recommended_settings": {
|
| 25 |
+
"LoRA strength": "0.6",
|
| 26 |
+
"Sampler steps": "4–8",
|
| 27 |
+
"CFG / guidance": "1",
|
| 28 |
+
"Sampler": "Euler"
|
| 29 |
+
},
|
| 30 |
+
"chaining": {
|
| 31 |
+
"author": {
|
| 32 |
+
"stacks": "not stated",
|
| 33 |
+
"notes": "",
|
| 34 |
+
"avoid": [],
|
| 35 |
+
"requires": [],
|
| 36 |
+
"order": "",
|
| 37 |
+
"strength": "",
|
| 38 |
+
"stated": false
|
| 39 |
+
},
|
| 40 |
+
"general_rules": [
|
| 41 |
+
"The most important rule is not about chaining but about which checkpoint you chain onto: the official README says in bold \"TRAIN on Raw and RUN on Turbo\", and \"We highly recommend using RAW for training LoRAs and applying them on Turbo for inference.\" LoRAs trained on Raw are stated to work well on Turbo.",
|
| 42 |
+
"Chain with LoraLoaderModelOnly nodes in series (model -> model). Krea 2 LoRAs are DiT-only, so there is no CLIP side to chain and the text-encoder branch stays untouched however many LoRAs you add.",
|
| 43 |
+
"Krea 2 LoRAs stack in practice and the community treats multi-LoRA as routine - style + character, style + slider, realism + character. Several CivitAI Krea 2 authors state their LoRAs stack cleanly; one writes \"I recently stacked over 20 of my own LoRAs on a single generation and the output still came out great.\"",
|
| 44 |
+
"Reduce per-LoRA strength when stacking. CivitAI Krea 2 authors converge on dropping from ~1.0 to roughly 0.6-0.9 once more than one adapter is loaded. The CivitAI 12GB training guide also notes rank affects composability: \"rank 8 produced a lighter style influence that was easier to stack with other LoRAs, rank 16 provided a useful balance between concept strength and composability, and rank 32 was better suited to a precise object or concept intended to take priority over other stacked LoRAs.\"",
|
| 45 |
+
"Accelerator LoRAs are position-sensitive in intent, not in node order: a Raw-to-Turbo delta adapter belongs on the Raw checkpoint, a sub-8-step LoRA belongs on Turbo (or on Raw already carrying a Raw-to-Turbo adapter). Chaining Raw -> Raw-to-Turbo adapter -> 4-step LoRA is explicitly recommended by the 4-step LoRA's author.",
|
| 46 |
+
"Whatever you stack, the schedule must stay Turbo's: cfg 1.0 in ComfyUI (guidance 0.0 in diffusers) and mu/shift 1.15. The 4-step LoRA's card says \"Keep mu = 1.15. The training targets are anchored to that grid; a different shift moves the [sampler off them]\"; the same reasoning applies to any Turbo-trained adapter in the chain.",
|
| 47 |
+
"Reference/edit LoRAs are designed to be stacked under ordinary subject and style LoRAs - the Identity Edit card states \"Composes with your LoRAs: character/body/style LoRAs stack on top and steer the prior\" and recommends a stacked subject LoRA when unusual subjects drift toward the base prior.",
|
| 48 |
+
"Krea 2 LoRAs cannot be chained with LoRAs for any other base model. Many CivitAI pages carry multi-model titles like \"(Krea-2 + ZIT)\" or \"[Flux | ZIB | Krea2]\" - those are separate files for separate architectures shipped under one model page, not a combined adapter.",
|
| 49 |
+
"To combine two full Krea 2 checkpoints rather than adapters, ComfyUI ships a dedicated ModelMergeKrea2 node (added in v0.27.0) with per-section weights for first., tmlp., txtmlp., tproj., txtfusion.projector, txtfusion.layerwise_blocks.0-1, txtfusion.refiner_blocks.0-1, blocks.0-27 and last.",
|
| 50 |
+
"Krea 2 Turbo is itself the official step-reduction artefact - the technical report describes a final timestep-distillation stage using TDM (Trajectory Distribution Matching), chosen for being \"simple to tune, with minimal hyperparameters\", producing an 8-step CFG-free checkpoint from Raw. It is a full checkpoint, not a LoRA. Three LoRA-shaped accelerators exist around it: 1. Raw-to-Turbo delta adapters. Comfy-Org/Krea-2 ships loras/krea2_turbo_lora_rank_64_bf16.safetensors - I read its header directly: 535 tensors, rank 64, ComfyUI-native diffusion_model.*.lora_down/lora_up keys, no __metadata",
|
| 51 |
+
"The author never states which weight family this targets. Silent degradation, never a hard error, between Raw and Turbo. The two share one architecture - ai-toolkit's config is commented \"The reference 'single_mmdit_large_wide' architecture (oss_raw / oss_turbo share it)\" - so every LoRA tensor shape matches on both and ComfyUI/diffuser"
|
| 52 |
+
]
|
| 53 |
+
},
|
| 54 |
+
"pros": [
|
| 55 |
+
"Explicit trigger word(s) — d351 d4rk — so the effect can be turned on and off from the prompt. [source: model metadata]",
|
| 56 |
+
"Compact at 218 MB — cheap to stack with other LoRAs. [source: file size]",
|
| 57 |
+
"Author published concrete recommended settings. [source: description]"
|
| 58 |
+
],
|
| 59 |
+
"cons": [
|
| 60 |
+
"Author never states which generation mode it was trained for; test against your own workflow before relying on it. [source: description]",
|
| 61 |
+
"Modest adoption (477 downloads) — less community feedback to rely on. [source: source stats]"
|
| 62 |
+
],
|
| 63 |
+
"file": {
|
| 64 |
+
"name": "D351_D4rk_Krea2_Turbo_v1.safetensors",
|
| 65 |
+
"size_bytes": 228587800,
|
| 66 |
+
"size_mb": 218.0,
|
| 67 |
+
"sha256": "92a80c711f5d133b0e88b8127d173d35f45f9834b82a2a878bfe0e20ea1aa8f7"
|
| 68 |
+
},
|
| 69 |
+
"stats": {
|
| 70 |
+
"downloads": 477,
|
| 71 |
+
"thumbs_up": 35,
|
| 72 |
+
"thumbs_down": 0
|
| 73 |
+
},
|
| 74 |
+
"popularity": {
|
| 75 |
+
"downloads": 477,
|
| 76 |
+
"thumbs_up": 35,
|
| 77 |
+
"thumbs_down": 0,
|
| 78 |
+
"comments": 0,
|
| 79 |
+
"approval": "100% positive (35/35)",
|
| 80 |
+
"age_days": 12.6,
|
| 81 |
+
"downloads_per_day": 37.72,
|
| 82 |
+
"rank_by_downloads": 197,
|
| 83 |
+
"rank_by_momentum": 101,
|
| 84 |
+
"of_total": 200,
|
| 85 |
+
"adoption_tier": "Niche",
|
| 86 |
+
"momentum": "Long tail · fresh release"
|
| 87 |
+
},
|
| 88 |
+
"selection_score": 85.5,
|
| 89 |
+
"selection_reasons": [
|
| 90 |
+
"477 downloads",
|
| 91 |
+
"35 thumbs-up",
|
| 92 |
+
"top-ranked for its category"
|
| 93 |
+
],
|
| 94 |
+
"example_media": [
|
| 95 |
+
{
|
| 96 |
+
"file": "01_image.jpeg",
|
| 97 |
+
"type": "image",
|
| 98 |
+
"resolution": "944x1280",
|
| 99 |
+
"prompt": ""
|
| 100 |
+
},
|
| 101 |
+
{
|
| 102 |
+
"file": "02_video.mp4",
|
| 103 |
+
"type": "video",
|
| 104 |
+
"resolution": "752x1024",
|
| 105 |
+
"prompt": "",
|
| 106 |
+
"poster": "02_poster.jpg"
|
| 107 |
+
},
|
| 108 |
+
{
|
| 109 |
+
"file": "03_image.jpeg",
|
| 110 |
+
"type": "image",
|
| 111 |
+
"resolution": "856x1280",
|
| 112 |
+
"prompt": ""
|
| 113 |
+
},
|
| 114 |
+
{
|
| 115 |
+
"file": "04_image.jpeg",
|
| 116 |
+
"type": "image",
|
| 117 |
+
"resolution": "944x1280",
|
| 118 |
+
"prompt": ""
|
| 119 |
+
},
|
| 120 |
+
{
|
| 121 |
+
"file": "05_image.jpeg",
|
| 122 |
+
"type": "image",
|
| 123 |
+
"resolution": "856x1280",
|
| 124 |
+
"prompt": ""
|
| 125 |
+
},
|
| 126 |
+
{
|
| 127 |
+
"file": "06_image.jpeg",
|
| 128 |
+
"type": "image",
|
| 129 |
+
"resolution": "1280x1280",
|
| 130 |
+
"prompt": ""
|
| 131 |
+
}
|
| 132 |
+
],
|
| 133 |
+
"tags": [
|
| 134 |
+
"indian",
|
| 135 |
+
"concept",
|
| 136 |
+
"ethnicity",
|
| 137 |
+
"skin tone",
|
| 138 |
+
"desi"
|
| 139 |
+
],
|
| 140 |
+
"scraped_at": "2026-09-05T03:59:17+00:00",
|
| 141 |
+
"path": "krea-2/desi-dark-lora-for-indian-south-asian-faces-and-darker"
|
| 142 |
+
}
|
feet/example_images/01_image.jpeg
ADDED

|
Git LFS Details
|
feet/example_images/02_image.jpeg
ADDED
|
Git LFS Details
|
feet/example_images/03_image.jpeg
ADDED
|
Git LFS Details
|