

Add LTX 2.3 - LTX Image Generator (LORA + Workflow)
Browse files- .gitattributes +6 -0
- ltx-2-3-ltx-image-generator-lora-workflow/example_images/01_image.jpeg +3 -0
- ltx-2-3-ltx-image-generator-lora-workflow/example_images/02_image.jpeg +3 -0
- ltx-2-3-ltx-image-generator-lora-workflow/example_images/03_image.jpeg +3 -0
- ltx-2-3-ltx-image-generator-lora-workflow/example_images/04_image.jpeg +3 -0
- ltx-2-3-ltx-image-generator-lora-workflow/example_images/05_image.jpeg +3 -0
- ltx-2-3-ltx-image-generator-lora-workflow/example_images/06_image.jpeg +3 -0
- ltx-2-3-ltx-image-generator-lora-workflow/info.txt +290 -0
- ltx-2-3-ltx-image-generator-lora-workflow/ltx23_jxlstyle_jxlstyl3.safetensors +3 -0
- ltx-2-3-ltx-image-generator-lora-workflow/metadata.json +135 -0
.gitattributes
CHANGED
|
@@ -727,3 +727,9 @@ yrsa-fjellheim/example_images/02_video.mp4 filter=lfs diff=lfs merge=lfs -text
|
|
| 727 |
formula-1-cockpit-cam-t-cam/example_images/01_video.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 728 |
formula-1-cockpit-cam-t-cam/example_images/02_poster.jpg filter=lfs diff=lfs merge=lfs -text
|
| 729 |
formula-1-cockpit-cam-t-cam/example_images/02_video.mp4 filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 727 |
formula-1-cockpit-cam-t-cam/example_images/01_video.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 728 |
formula-1-cockpit-cam-t-cam/example_images/02_poster.jpg filter=lfs diff=lfs merge=lfs -text
|
| 729 |
formula-1-cockpit-cam-t-cam/example_images/02_video.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 730 |
+
ltx-2-3-ltx-image-generator-lora-workflow/example_images/01_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 731 |
+
ltx-2-3-ltx-image-generator-lora-workflow/example_images/02_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 732 |
+
ltx-2-3-ltx-image-generator-lora-workflow/example_images/03_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 733 |
+
ltx-2-3-ltx-image-generator-lora-workflow/example_images/04_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 734 |
+
ltx-2-3-ltx-image-generator-lora-workflow/example_images/05_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 735 |
+
ltx-2-3-ltx-image-generator-lora-workflow/example_images/06_image.jpeg filter=lfs diff=lfs merge=lfs -text
|
ltx-2-3-ltx-image-generator-lora-workflow/example_images/01_image.jpeg
ADDED
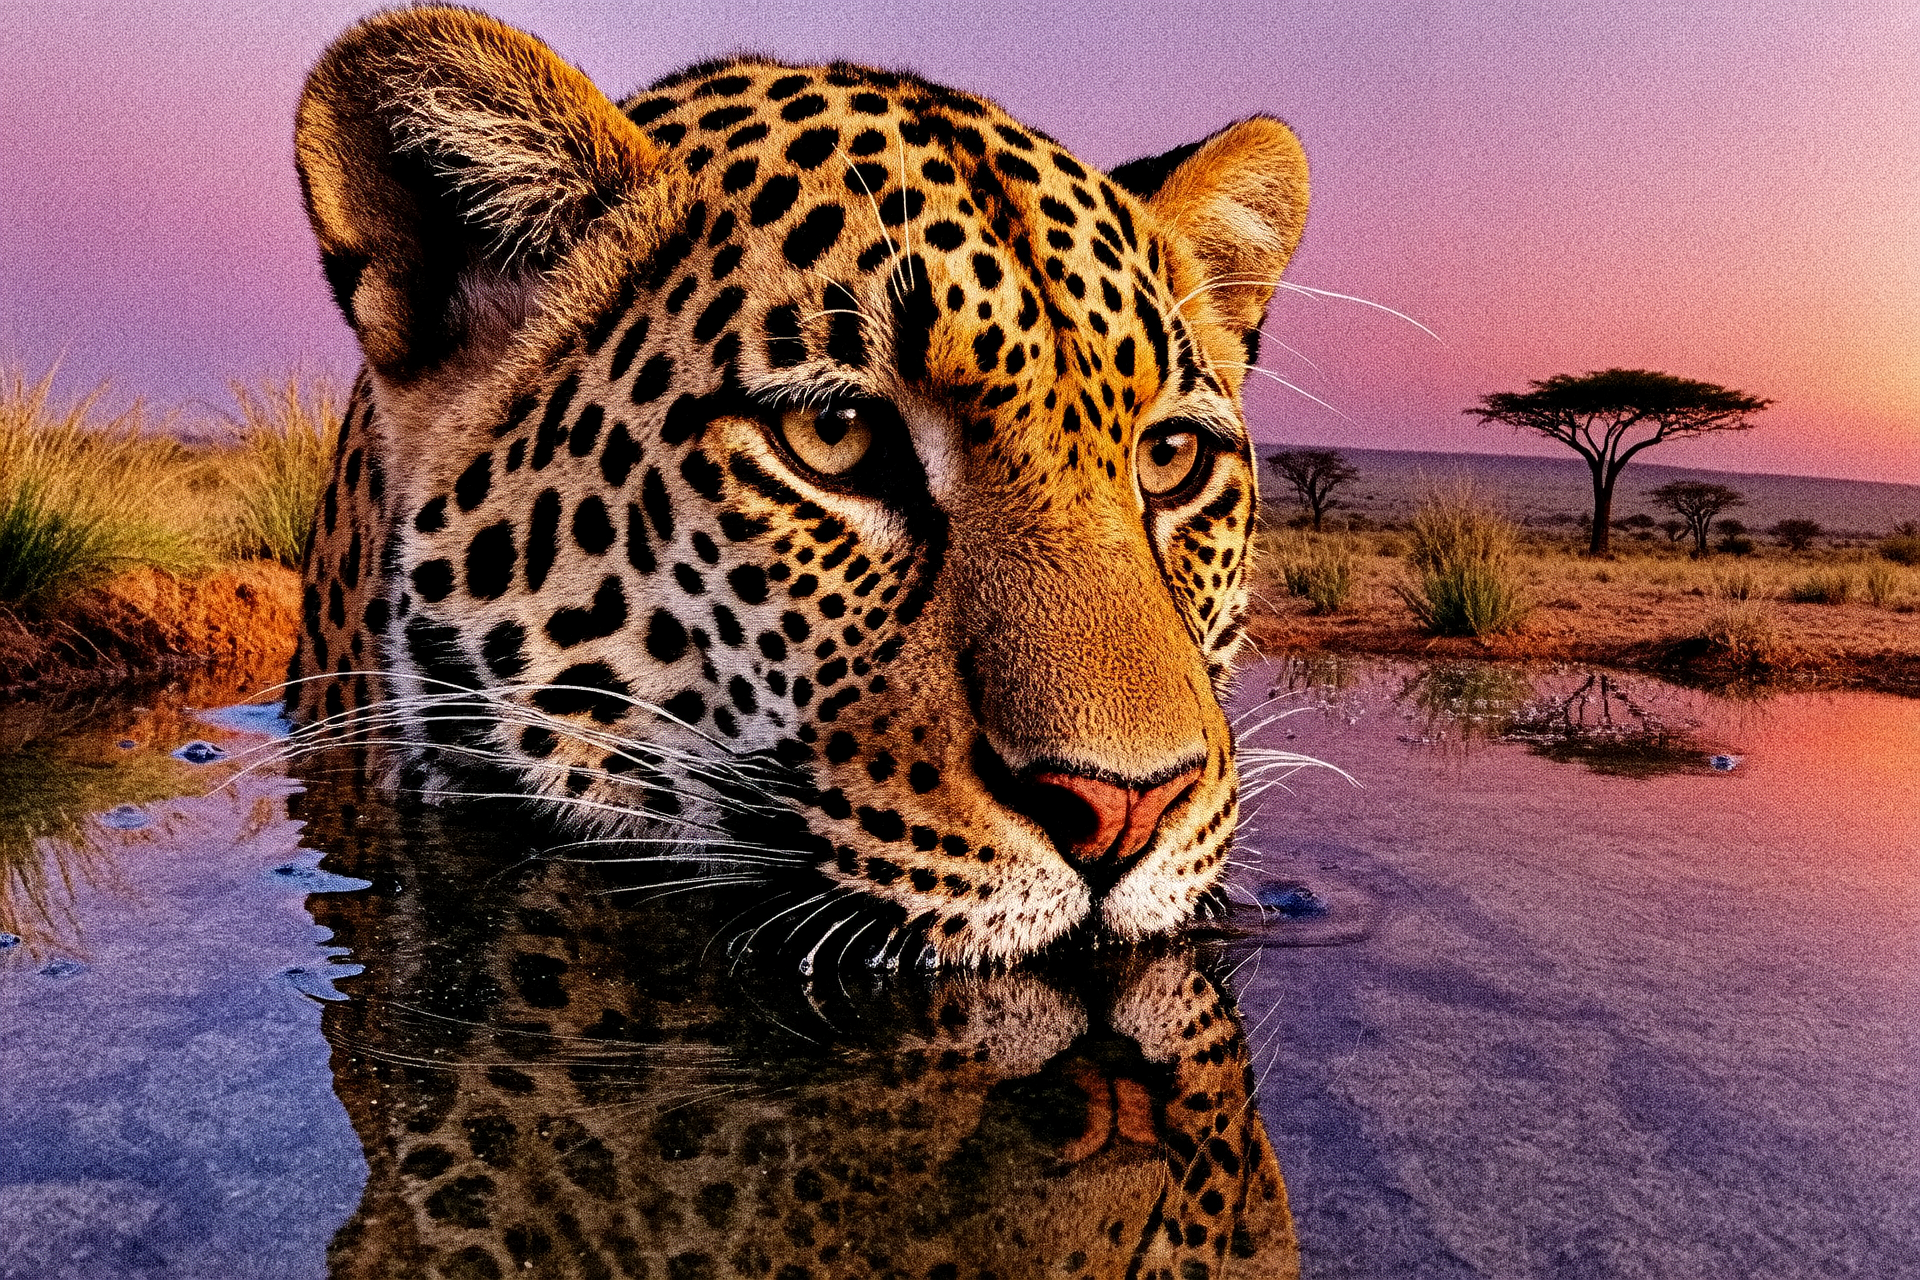
|
Git LFS Details
|
ltx-2-3-ltx-image-generator-lora-workflow/example_images/02_image.jpeg
ADDED
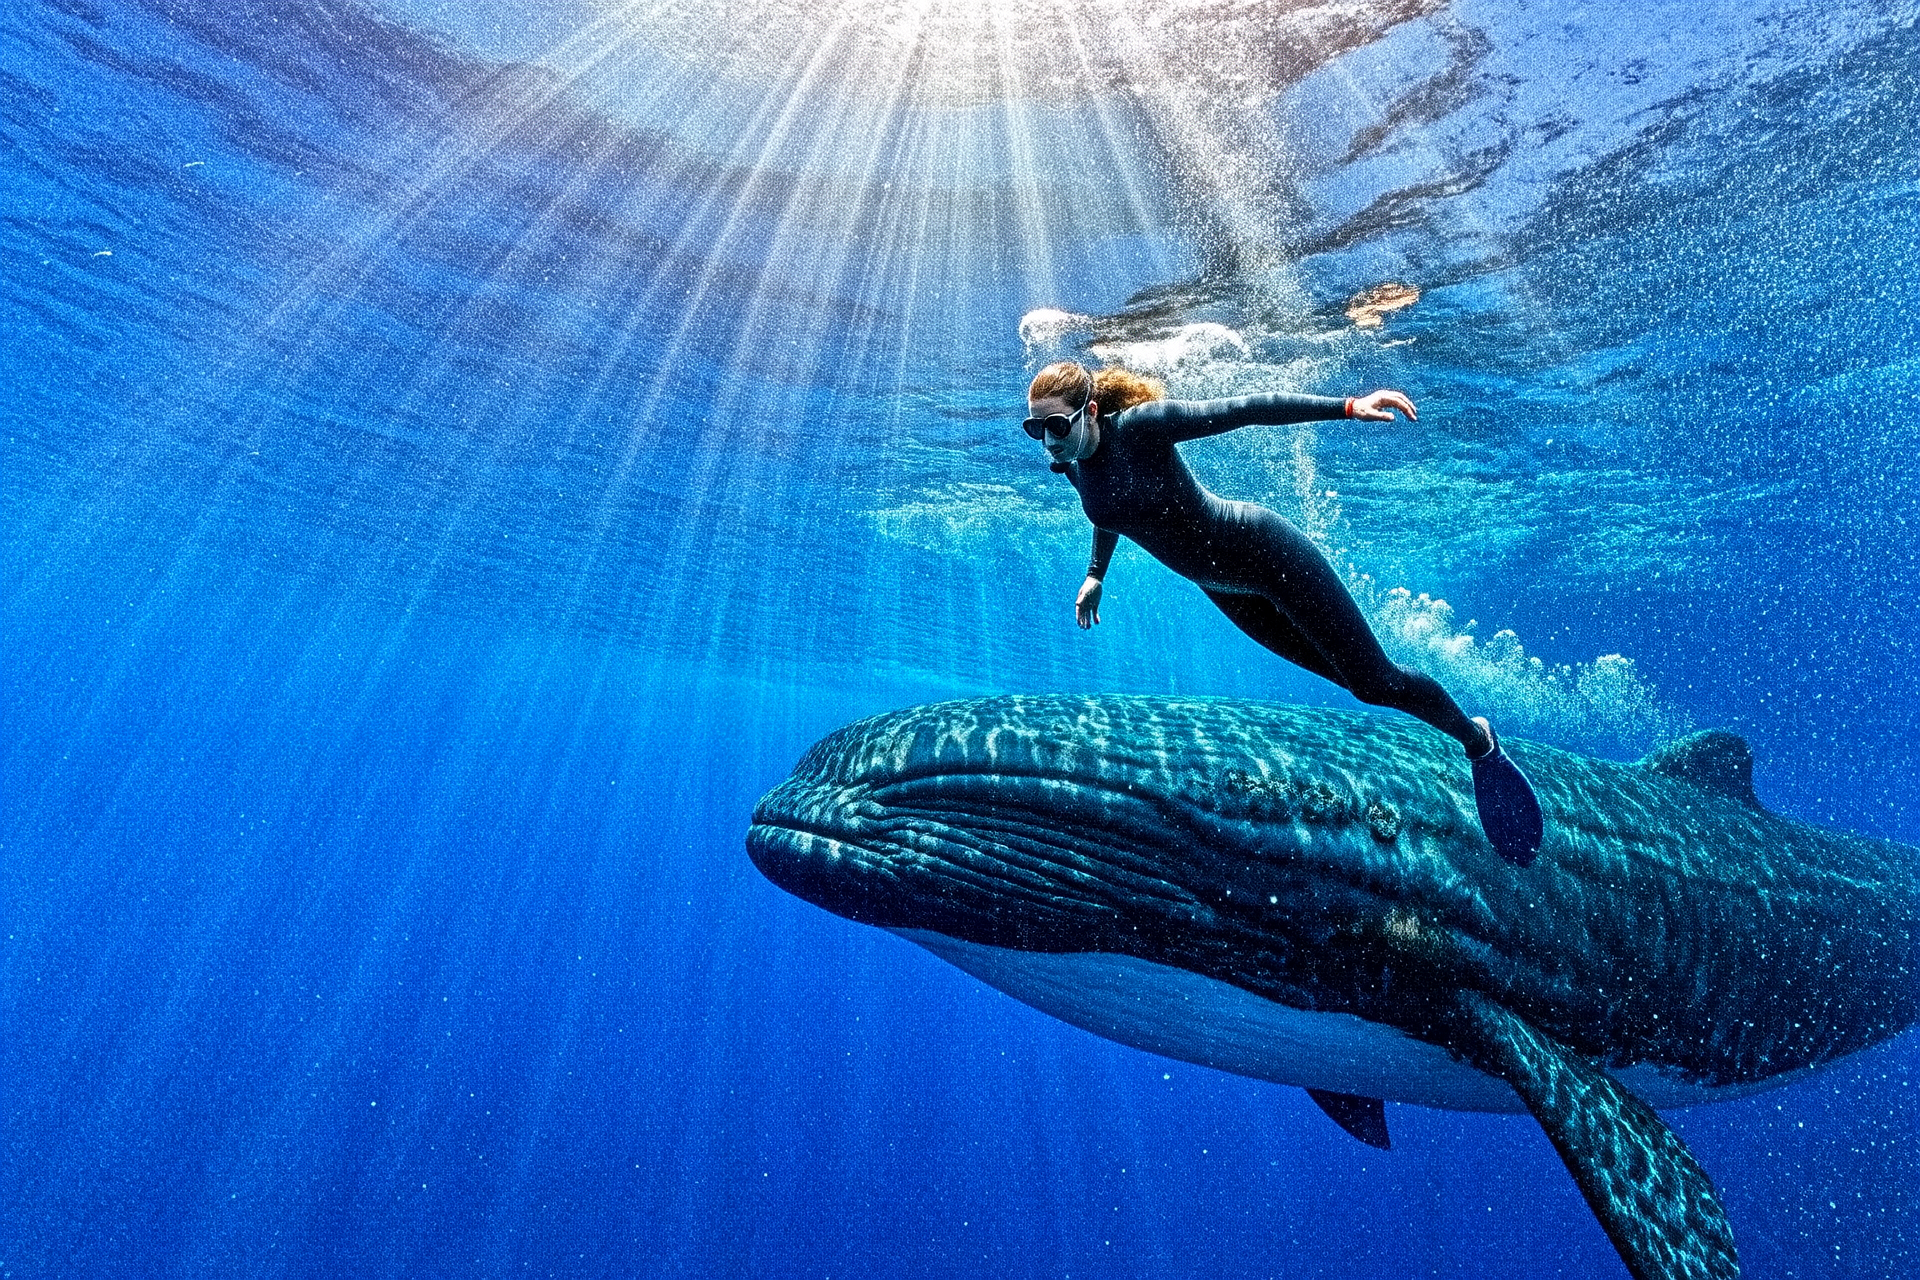
|
Git LFS Details
|
ltx-2-3-ltx-image-generator-lora-workflow/example_images/03_image.jpeg
ADDED
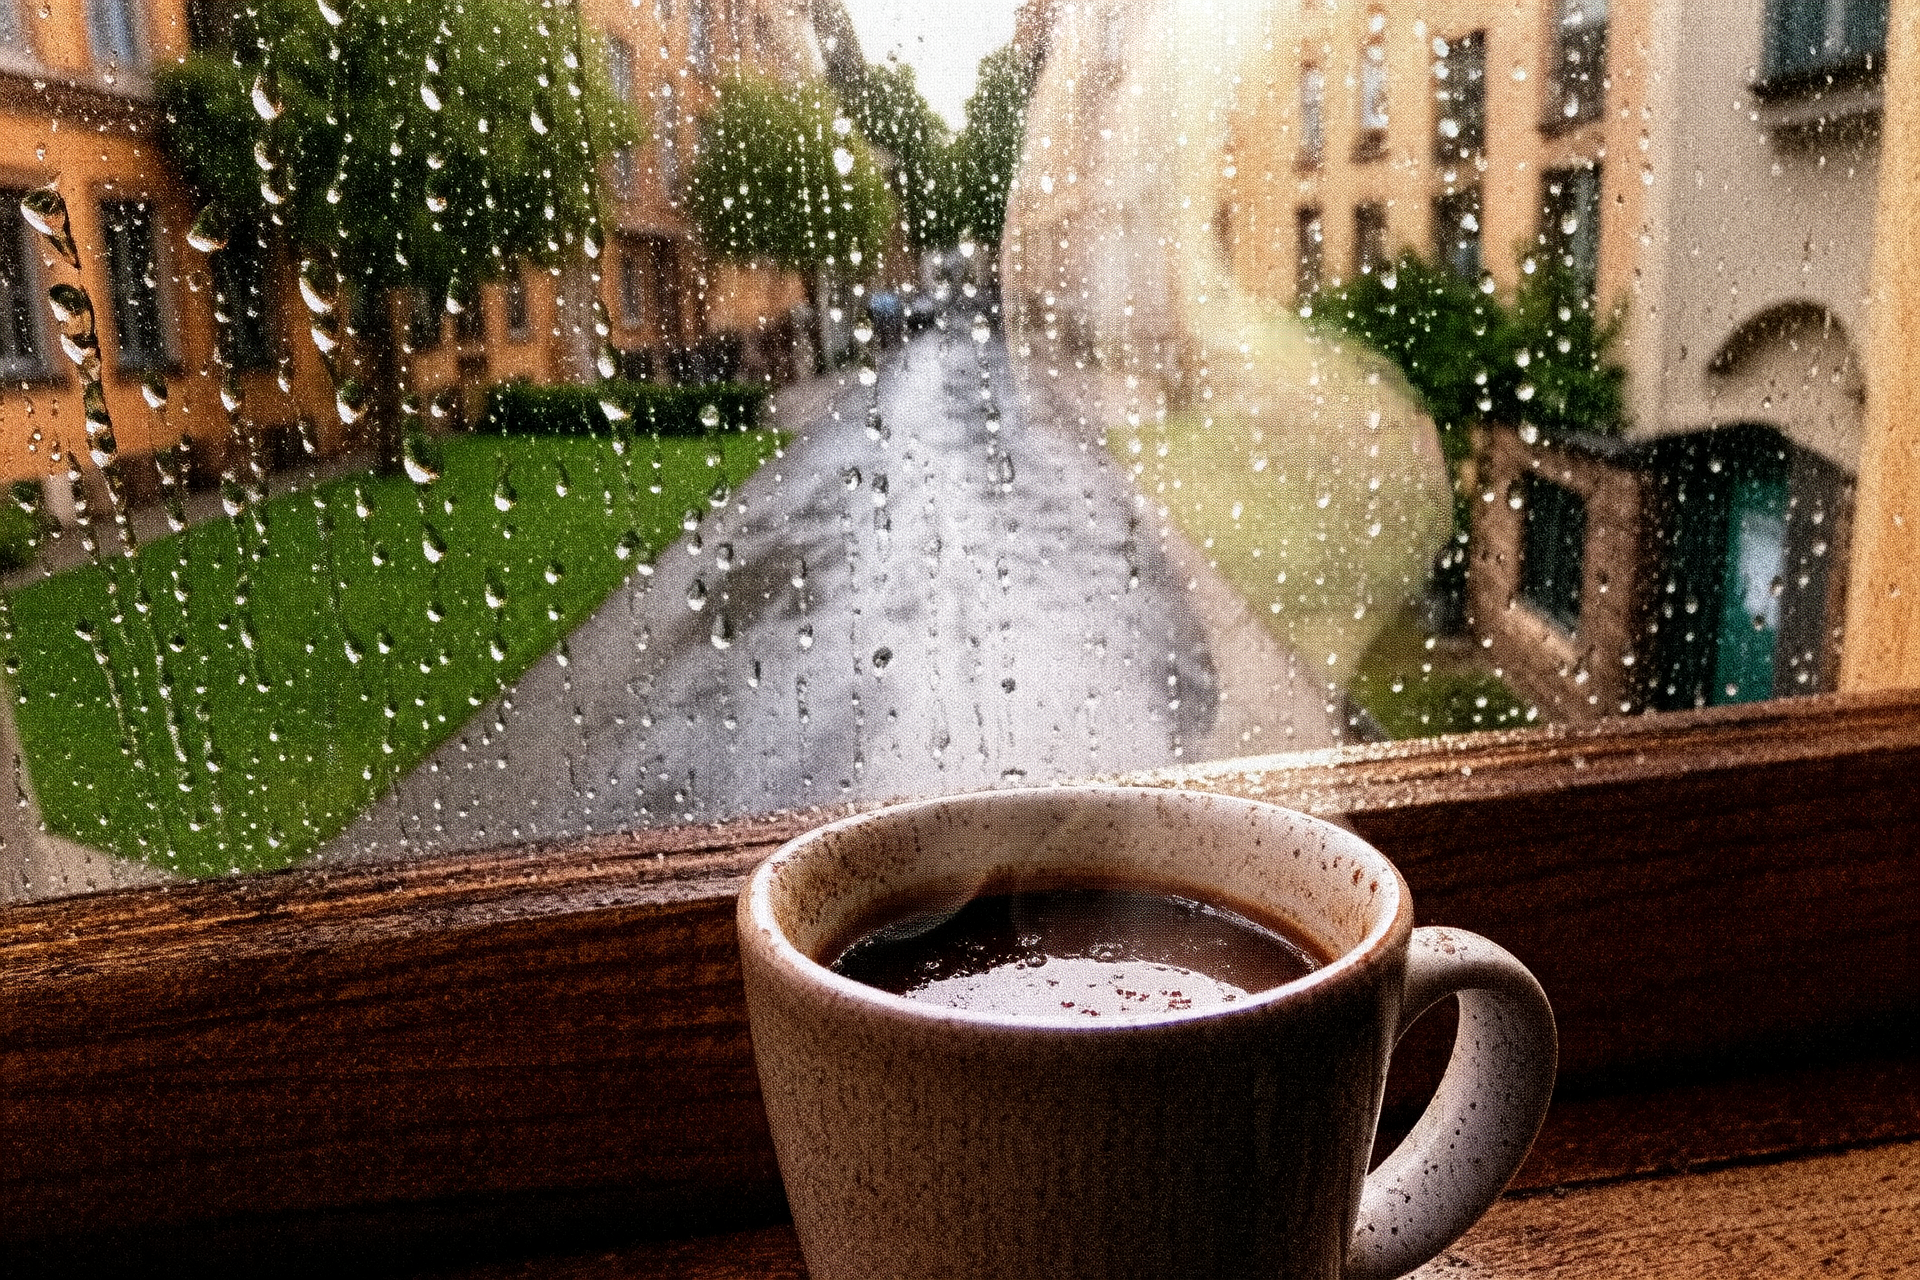
|
Git LFS Details
|
ltx-2-3-ltx-image-generator-lora-workflow/example_images/04_image.jpeg
ADDED
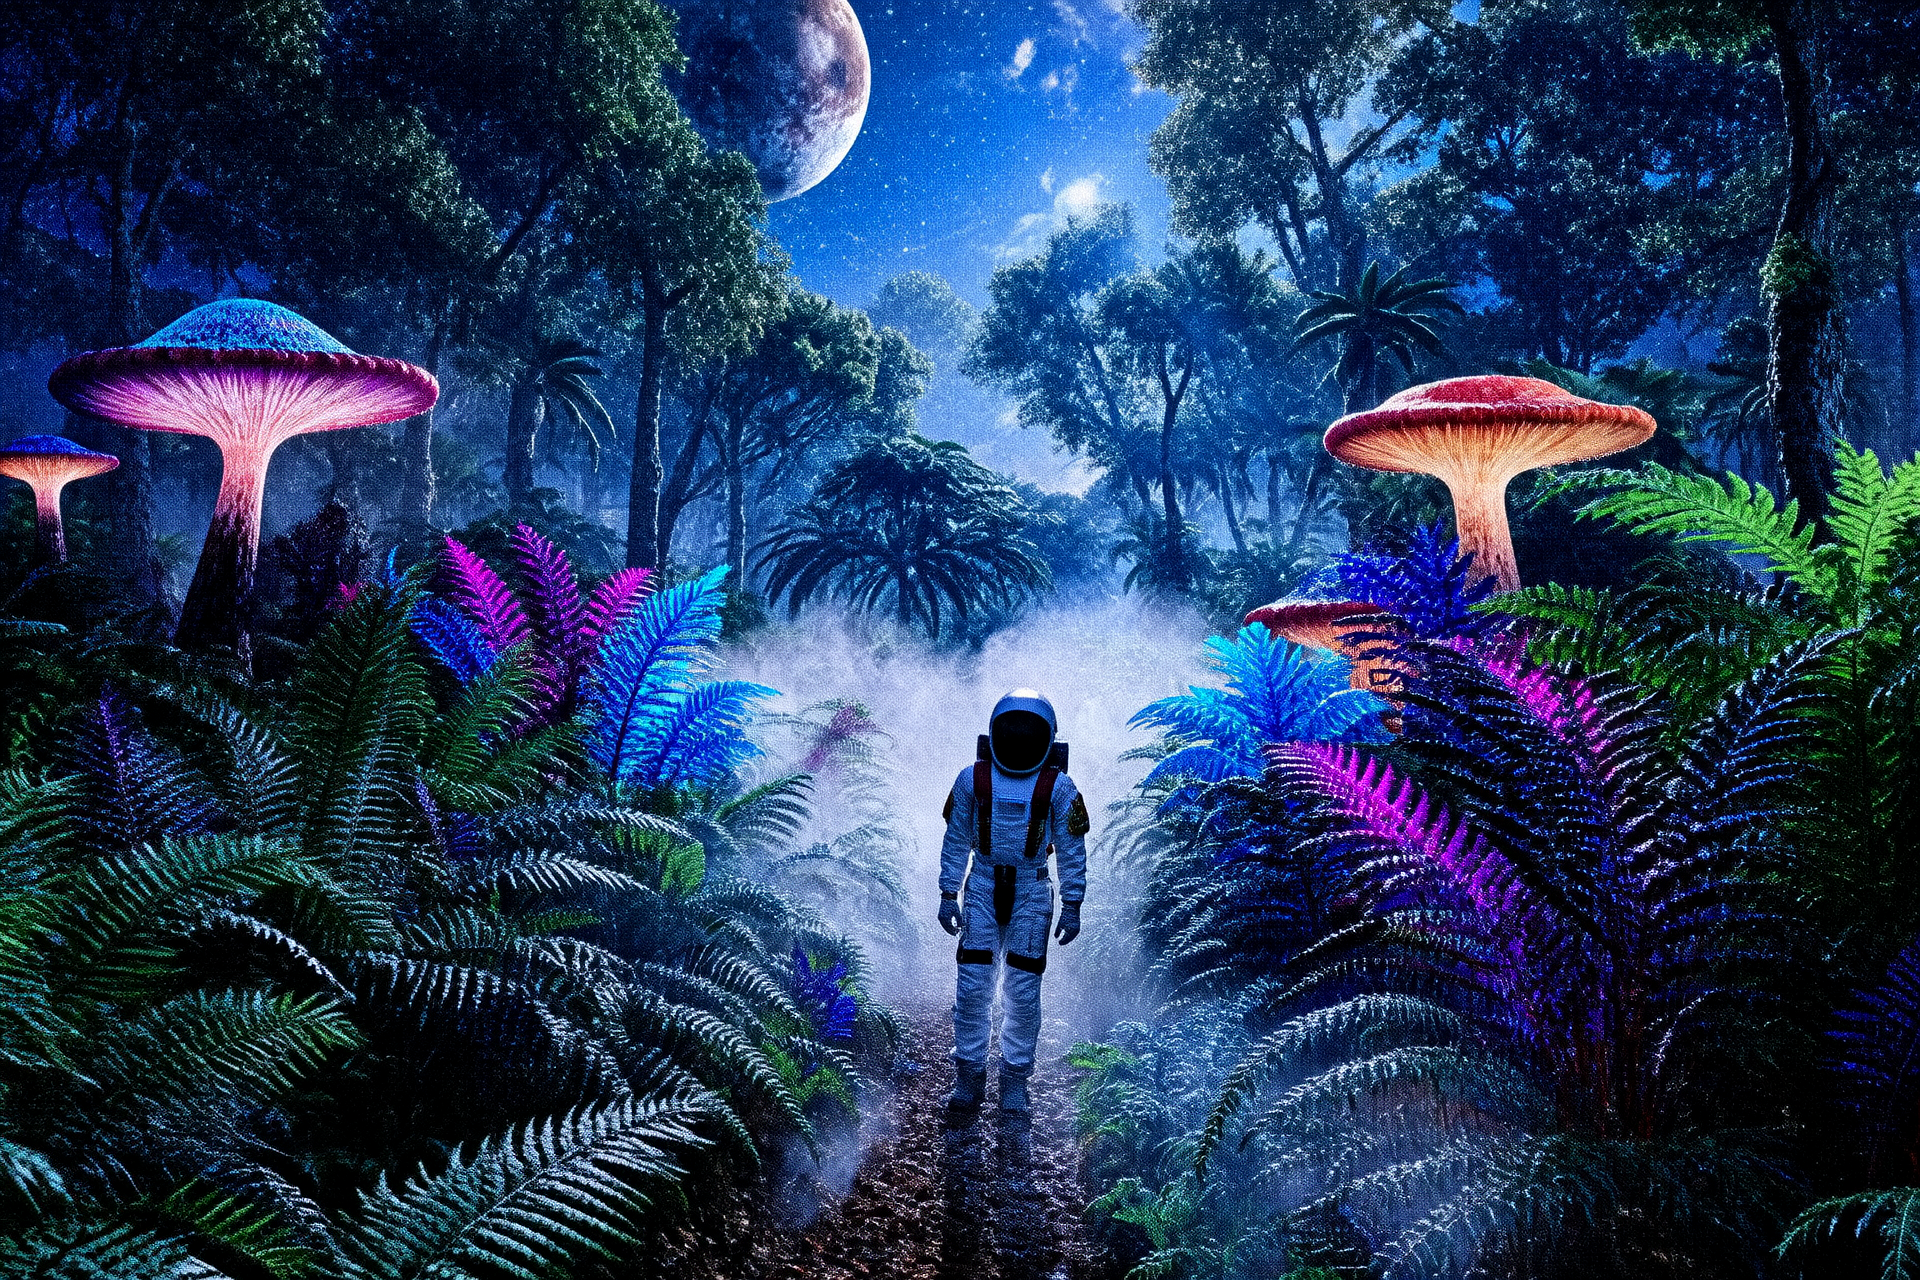
|
Git LFS Details
|
ltx-2-3-ltx-image-generator-lora-workflow/example_images/05_image.jpeg
ADDED
|
Git LFS Details
|
ltx-2-3-ltx-image-generator-lora-workflow/example_images/06_image.jpeg
ADDED
|
Git LFS Details
|
ltx-2-3-ltx-image-generator-lora-workflow/info.txt
ADDED
|
@@ -0,0 +1,290 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
═══════════════════════════════════════════════════════════════════════════════
|
| 2 |
+
LTX 2.3 - LTX IMAGE GENERATOR (LORA + WORKFLOW)
|
| 3 |
+
═══════════════════════════════════════════════════════════════════════════════
|
| 4 |
+
|
| 5 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 6 |
+
IDENTITY
|
| 7 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 8 |
+
Base model LTX-2.3
|
| 9 |
+
Generation mode not declared by the author
|
| 10 |
+
Checkpoint not determined — verify before use
|
| 11 |
+
Category Visual style
|
| 12 |
+
Author JonXL
|
| 13 |
+
Source https://civitai.com/models/2717880
|
| 14 |
+
Provenance CivitAI · model 2717880 · version 3054035
|
| 15 |
+
|
| 16 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 17 |
+
WEIGHTS
|
| 18 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 19 |
+
File ltx23_jxlstyle_jxlstyl3.safetensors
|
| 20 |
+
Version v1.0
|
| 21 |
+
Size 768.1 MB
|
| 22 |
+
Format SafeTensor / unknown precision
|
| 23 |
+
SHA256 4a8862d19cfce611d602fece3bf507f0b4ccf3e5e294fcb99c4a8ff730af7b3c
|
| 24 |
+
Published 2026-06-20
|
| 25 |
+
|
| 26 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 27 |
+
TRIGGER WORDS
|
| 28 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 29 |
+
No trigger word. The LoRA applies as soon as it is loaded —
|
| 30 |
+
strength is the only way to dial the effect up or down.
|
| 31 |
+
|
| 32 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 33 |
+
RECOMMENDED SETTINGS
|
| 34 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 35 |
+
Taken verbatim from the author's description:
|
| 36 |
+
|
| 37 |
+
Resolution 1920x1280
|
| 38 |
+
CFG / guidance 2
|
| 39 |
+
|
| 40 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 41 |
+
ADOPTION & POPULARITY
|
| 42 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 43 |
+
Downloads 338
|
| 44 |
+
Rating 100% positive (28/28)
|
| 45 |
+
Comments 0
|
| 46 |
+
Published 76 days ago
|
| 47 |
+
Download rate 4.4/day since release
|
| 48 |
+
|
| 49 |
+
Adoption rank #88 of 150 in this collection (Modest)
|
| 50 |
+
Momentum rank #65 of 150 by download rate (Steady)
|
| 51 |
+
|
| 52 |
+
Adoption tier is the percentile of total downloads within this collection;
|
| 53 |
+
momentum is the percentile of downloads-per-day since release. Momentum is
|
| 54 |
+
ranked rather than measured against a fixed rate, because this base model
|
| 55 |
+
is itself new and every LoRA looks fast on an absolute scale. Both numbers
|
| 56 |
+
are CivitAI's, read on the scrape date at the foot of this file.
|
| 57 |
+
|
| 58 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 59 |
+
CHAINING / STACKING
|
| 60 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 61 |
+
Stacks with others not stated
|
| 62 |
+
|
| 63 |
+
The author gave no chaining guidance. The rules below are the
|
| 64 |
+
general LTX-2.3 ones, not anything specific to this LoRA.
|
| 65 |
+
|
| 66 |
+
General LTX-2.3 rules that apply here (see REFERENCE.txt):
|
| 67 |
+
|
| 68 |
+
• Stacking an acceleration LoRA with a task LoRA is officially
|
| 69 |
+
sanctioned: the ID-LoRA template chains LoraLoaderModelOnly(ltx_2.3_22b
|
| 70 |
+
_distilled_1.1_lora_dynamic_fro09_avg_rank_111_bf16, 0.5) into
|
| 71 |
+
LoraLoaderModelOnly(ltx-2.3-id-lora-talkvid-3k, 1.0) on the dev
|
| 72 |
+
checkpoint.
|
| 73 |
+
• The Python CLI exposes `--lora <path> [strength]` as a repeatable flag
|
| 74 |
+
with default strength 1.0, so multiple adapters at once is a supported
|
| 75 |
+
configuration, not a hack.
|
| 76 |
+
• Load the acceleration/distilled LoRA on the dev checkpoint only. The
|
| 77 |
+
two-stage pipelines require it for the full model but explicitly do not
|
| 78 |
+
use it for DistilledPipeline, ICLoraPipeline or DubItPipeline, which
|
| 79 |
+
already run distilled weights.
|
| 80 |
+
• Do not stack two distillation LoRAs (e.g. the official rank-384 /
|
| 81 |
+
rank-111 one plus a community DMD LoRA). The DaSiWa DMD LoRA already
|
| 82 |
+
blends 75-80% of the official distilled delta into its audio-output
|
| 83 |
+
route and is described by its author as recreating the distilled model
|
| 84 |
+
on top of stock dev, i.e. a replacement.
|
| 85 |
+
• IC-LoRAs are not chained like ordinary LoRAs: each carries a
|
| 86 |
+
reference_downscale_factor in its safetensors metadata and needs a node
|
| 87 |
+
that reads it (GetICLoRAParameters -> LTXVAddGuide in core, or
|
| 88 |
+
LTXICLoRALoaderModelOnly + LTXAddVideoICLoRAGuide in ComfyUI-LTXVideo).
|
| 89 |
+
Without one the factor silently defaults to 1.
|
| 90 |
+
• Two IC-LoRA reference guides can be driven from a single IC-LoRA: the
|
| 91 |
+
CrossView Warp author wires both a depth-warp video and the original
|
| 92 |
+
video into separate reference guides and sets latent_downscale_factor =
|
| 93 |
+
1 on both.
|
| 94 |
+
• DubItPipeline accepts exactly one Dub-It IC-LoRA (`--lora` exactly
|
| 95 |
+
once) and applies it in both stages — that path is single-adapter by
|
| 96 |
+
design.
|
| 97 |
+
• Community convention on strengths when stacking: the IC-LoRA Dual-
|
| 98 |
+
Character author recommends 0.6-1.0 for a content LoRA used alone,
|
| 99 |
+
dropped to 0.3-0.5 when combined with others.
|
| 100 |
+
• Some LoRA pairs are designed to be blended against each other — the LTX
|
| 101 |
+
2.3 Crisp Enhance / Soft Enhance pair is described by its author as
|
| 102 |
+
"can be used together and balanced at different strengths".
|
| 103 |
+
• The gemma-3-12b-it-abliterated LoRA is not a video LoRA and does not
|
| 104 |
+
belong in the DiT chain — it patches the Gemma text encoder through a
|
| 105 |
+
model+clip LoraLoader, as the official templates wire it.
|
| 106 |
+
• The author never states which weight family this targets. Within
|
| 107 |
+
LTX-2.3, dev vs distilled is low risk: they are the same architecture
|
| 108 |
+
and the distillation itself is published as a LoRA that the model card
|
| 109 |
+
calls "applicable to the full model", so ordinary content LoRAs load on
|
| 110 |
+
both. Expect style/strength drift rather than breakage; the
|
| 111 |
+
|
| 112 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 113 |
+
PROS
|
| 114 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 115 |
+
+ Author published concrete recommended settings. [source: description]
|
| 116 |
+
|
| 117 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 118 |
+
CONS & CAVEATS
|
| 119 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 120 |
+
- No trigger word — the LoRA is always on once loaded, so strength is the
|
| 121 |
+
only control. [source: model metadata]
|
| 122 |
+
- Author never states which generation mode it was trained for; test
|
| 123 |
+
against your own workflow before relying on it. [source: description]
|
| 124 |
+
- Large at 768 MB — slower to load and heavier to stack. [source: file
|
| 125 |
+
size]
|
| 126 |
+
- Modest adoption (338 downloads) — less community feedback to rely on.
|
| 127 |
+
[source: CivitAI stats]
|
| 128 |
+
|
| 129 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 130 |
+
COMPATIBILITY WARNING
|
| 131 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 132 |
+
Within LTX-2.3, dev vs distilled is low risk: they are the same
|
| 133 |
+
architecture and the distillation itself is published as a LoRA that the
|
| 134 |
+
model card calls "applicable to the full model", so ordinary content LoRAs
|
| 135 |
+
load on both. Expect style/strength drift rather than breakage; the
|
| 136 |
+
distilled LoRA is meant to be applied to a dev checkpoint, not stacked on
|
| 137 |
+
an already-distilled one (the Python pipelines that start from a distilled
|
| 138 |
+
checkpoint — DistilledPipeline, ICLoraPipeline, DubItPipeline — explicitly
|
| 139 |
+
do not take --distilled-lora). The genuine risk is cross-version and cross-
|
| 140 |
+
format, and it is silent rather than a hard error: the LTX-2 repo README
|
| 141 |
+
states flatly that files "are not interchangeable between the two models,
|
| 142 |
+
and a LoRA only works with the model it was trained on", and a wrong-
|
| 143 |
+
version LoRA surfaces only as a stream of "lora key not loaded:
|
| 144 |
+
diffusion_model...." console warnings while generation proceeds as if no
|
| 145 |
+
LoRA were attached. The same silent no-op hits correctly-versioned LoRAs
|
| 146 |
+
saved in a non-ComfyUI key layout: SimpleTuner issue #2349 shows keys like
|
| 147 |
+
diffusion_model.connectors.audio_connector.transformer_blocks.N.attn1.to_q
|
| 148 |
+
going unloaded, where the LTX-2 trainer's own layout is attn1/attn2 for
|
| 149 |
+
video, audio_attn1/audio_attn2 for audio and audio_to_video_attn /
|
| 150 |
+
video_to_audio_attn for cross-modal. Community finetunes (Sulphur 2, JoyAI-
|
| 151 |
+
Echo merges) load stock LTX-2.3 LoRAs but shift the result. And an IC-LoRA
|
| 152 |
+
loaded without a metadata-reading node loses its reference scale: ComfyUI's
|
| 153 |
+
GetICLoRAParameters reads reference_downscale_factor out of the LoRA's
|
| 154 |
+
safetensors metadata and silently falls back to 1 when it is absent, so a
|
| 155 |
+
ref0.5 IC-LoRA wired straight into LTXVAddGuide without it feeds the
|
| 156 |
+
reference at the wrong latent scale.
|
| 157 |
+
|
| 158 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 159 |
+
AUTHOR'S DESCRIPTION
|
| 160 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 161 |
+
LTX 2.3 - LTX Image Generator (LORA + Workflow)
|
| 162 |
+
Make sure to download the workflow from the 'optional downloads' as well!
|
| 163 |
+
A conceptual lora and workflow to create 1920x1280 images with LTX 2.3.
|
| 164 |
+
Remember image generation on WAN? Now you can generate images with LTX too.
|
| 165 |
+
The workflow captures the last frame out of a fade-in video (lora trained)
|
| 166 |
+
where the resulting image appears.
|
| 167 |
+
Usage:
|
| 168 |
+
- The workflow is absolutely necessary
|
| 169 |
+
- (As it has extremely specific parameters)
|
| 170 |
+
|
| 171 |
+
- Preferably, use the following sentence to activate the image generation
|
| 172 |
+
- jxlstyl3, A fade in from black to a static image
|
| 173 |
+
|
| 174 |
+
- Keep the initial parameters, although you can experiment with
|
| 175 |
+
- ' cfg' , 'custom lora strength' and 'distill lora strength'
|
| 176 |
+
|
| 177 |
+
- Please generate on 1920x1280 resolution
|
| 178 |
+
- Although other resolution may work, it was mainly trained for 3:2 at
|
| 179 |
+
1920x1280
|
| 180 |
+
|
| 181 |
+
- Feel free to post your results, though keep it decent
|
| 182 |
+
|
| 183 |
+
- Let me know your feedback, as this is the only image generator workflow
|
| 184 |
+
that I know exists for LTX so far :)
|
| 185 |
+
|
| 186 |
+
Known issues:
|
| 187 |
+
- This is a concept for generating high res images, and I think it works
|
| 188 |
+
pretty well
|
| 189 |
+
- However, LTX 2.3 is a video model, not an image model. Realise that the
|
| 190 |
+
model is being tricked and mis-used into behaving like an image model.
|
| 191 |
+
|
| 192 |
+
- A limitation of LTX is that reflection and text do not work really well,
|
| 193 |
+
which this lora did not resolve
|
| 194 |
+
|
| 195 |
+
- The workflow may complain about an image needed to be loaded, just feed
|
| 196 |
+
it an image (ignore that it will have any effect though)
|
| 197 |
+
|
| 198 |
+
- You may need to either install Kijai's nodes, or bypass the
|
| 199 |
+
ChunkFeedForward node inside the subgraph, follow the install instructions
|
| 200 |
+
here:
|
| 201 |
+
- https://github.com/kijai/ComfyUI-KJNodes
|
| 202 |
+
|
| 203 |
+
- If you really need to use your own workflow or use the on site generator
|
| 204 |
+
(I haven't tried), then these are the required parameters
|
| 205 |
+
- Pass 1 - 30 sigma steps @ CFG 2, Lora strength 2, Lora distill strength 0
|
| 206 |
+
|
| 207 |
+
- Pass 2- 4 sigma steps @ CFG 1, Lora strength 2, Lora distill strength ~
|
| 208 |
+
0.19
|
| 209 |
+
|
| 210 |
+
- And somehow take the last frame from the video
|
| 211 |
+
|
| 212 |
+
- But just use the supplied workflow if you can
|
| 213 |
+
|
| 214 |
+
Why make this?
|
| 215 |
+
I was curious to see what LTX 2.3 could do when tricked into creating
|
| 216 |
+
static images. By using a fade-in transition on a high-res image dataset
|
| 217 |
+
that has been pre-processed (added film grain and some bleach bypass) it
|
| 218 |
+
became possible to let LTX 2.3 generate a static transition video of which
|
| 219 |
+
an output frame can be extracted as an image.
|
| 220 |
+
While it took a few working days and many hours (40?) of lora training
|
| 221 |
+
experimentation, to get to a working state, I am now content with the
|
| 222 |
+
result. There is some room in the adjustement of parameters though, so if
|
| 223 |
+
you happen to have better results, let me know!
|
| 224 |
+
|
| 225 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 226 |
+
EXAMPLE MEDIA
|
| 227 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 228 |
+
6 preview(s) in ./example_images/ — community results for
|
| 229 |
+
this LoRA. Videos keep a matching _poster.jpg still frame.
|
| 230 |
+
|
| 231 |
+
No prompts are recorded below: CivitAI's public API flags these posts as
|
| 232 |
+
having generation metadata but does not return it, so the prompts cannot be
|
| 233 |
+
scraped. Open the model page to read them.
|
| 234 |
+
|
| 235 |
+
01_image.jpeg (image, 1920x1280)
|
| 236 |
+
02_image.jpeg (image, 1920x1280)
|
| 237 |
+
03_image.jpeg (image, 1920x1280)
|
| 238 |
+
04_image.jpeg (image, 1920x1280)
|
| 239 |
+
05_image.jpeg (image, 1920x1280)
|
| 240 |
+
06_image.jpeg (image, 1920x1280)
|
| 241 |
+
|
| 242 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 243 |
+
HOW TO USE (COMFYUI)
|
| 244 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 245 |
+
1. Update ComfyUI. LTX-2.3 is supported in ComfyUI core
|
| 246 |
+
(comfy_extras/nodes_lt.py provides EmptyLTXVLatentVideo, LTXVAddGuide,
|
| 247 |
+
GetICLoRAParameters, LTXVConditioning, LTXVScheduler,
|
| 248 |
+
LTXVConcatAVLatent/LTXVSeparateAVLatent, LTXVReferenceAudio and more) and
|
| 249 |
+
the six official templates need no custom nodes; install the Lightricks
|
| 250 |
+
"ComfyUI-LTXVideo" custom node pack only if you want IC-LoRA loaders, low-
|
| 251 |
+
VRAM loaders, HDR decode, audio-only nodes or Q8 nodes.
|
| 252 |
+
2. Put the base checkpoint in ComfyUI/models/checkpoints/ —
|
| 253 |
+
ltx-2.3-22b-dev-fp8.safetensors (29.15 GB) or ltx-2.3-22b-distilled-
|
| 254 |
+
fp8.safetensors (29.53 GB) from Lightricks/LTX-2.3-fp8, or the bf16
|
| 255 |
+
originals (46.15 GB) from Lightricks/LTX-2.3. It is a single file that also
|
| 256 |
+
carries the video VAE, the audio VAE and the text projection.
|
| 257 |
+
3. Put gemma_3_12B_it_fp4_mixed.safetensors in
|
| 258 |
+
ComfyUI/models/text_encoders/ (from Comfy-Org/ltx-2). The Python package
|
| 259 |
+
instead wants the full google/gemma-3-12b-it-qat-q4_0-unquantized folder.
|
| 260 |
+
4. Put ltx-2.3-spatial-upscaler-x2-1.1.safetensors in
|
| 261 |
+
ComfyUI/models/latent_upscale_models/ (needed by every two-stage template),
|
| 262 |
+
and moge_2_vitl_normal_fp16.safetensors (Comfy-Org/MoGe) in
|
| 263 |
+
ComfyUI/models/geometry_estimation/ if you use the IC-LoRA depth path.
|
| 264 |
+
5. Put every LoRA .safetensors in ComfyUI/models/loras/. Subfolders are
|
| 265 |
+
fine — Lightricks' own workflows reference
|
| 266 |
+
"ltxv/ltx2/ltx-2.3-22b-distilled-lora-384-1.1.safetensors".
|
| 267 |
+
6. Load a normal content/style LoRA with LoraLoaderModelOnly, wired between
|
| 268 |
+
CheckpointLoaderSimple's MODEL output and the guider/sampler. In the stock
|
| 269 |
+
templates you chain it after the distilled-LoRA loader. Use the full
|
| 270 |
+
LoraLoader (model + clip) only for the gemma-3-12b-it-abliterated LoRA,
|
| 271 |
+
which patches the Gemma text encoder rather than the video model.
|
| 272 |
+
7. On a dev checkpoint, also load the acceleration LoRA
|
| 273 |
+
(ltx_2.3_22b_distilled_1.1_lora_dynamic_fro09_avg_rank_111_bf16.safetensors
|
| 274 |
+
at 0.5) unless you intend to run the slow guided path.
|
| 275 |
+
8. For an IC-LoRA, the LoRA loader alone is not enough: either use
|
| 276 |
+
LTXICLoRALoaderModelOnly + LTXAddVideoICLoRAGuide (ComfyUI-LTXVideo), or —
|
| 277 |
+
as the official ic_lora template does — feed the LoRA-loaded model through
|
| 278 |
+
core's GetICLoRAParameters into LTXVAddGuide, so the
|
| 279 |
+
reference_downscale_factor stored in the file's safetensors metadata is
|
| 280 |
+
read instead of defaulting to 1.
|
| 281 |
+
9. Template Library > Video > any LTX-2.3 workflow gives you correct wiring
|
| 282 |
+
to start from; workflow JSONs are at Comfy-Org/workflow_templates/templates
|
| 283 |
+
/video_ltx2_3_{t2v,i2v,ia2v,flf2v,ic_lora,id_lora}.json and
|
| 284 |
+
Lightricks/ComfyUI-LTXVideo/example_workflows/2.3/.
|
| 285 |
+
|
| 286 |
+
───────────────────────────────────────────────────────────────────────────────
|
| 287 |
+
Scraped by lorakit on 2026-09-04 23:21 UTC.
|
| 288 |
+
Stats and description are the author's; pros/cons are derived from the
|
| 289 |
+
evidence tagged beside each line.
|
| 290 |
+
───────────────────────────────────────────────────────────────────────────────
|
ltx-2-3-ltx-image-generator-lora-workflow/ltx23_jxlstyle_jxlstyl3.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:4a8862d19cfce611d602fece3bf507f0b4ccf3e5e294fcb99c4a8ff730af7b3c
|
| 3 |
+
size 805415368
|
ltx-2-3-ltx-image-generator-lora-workflow/metadata.json
ADDED
|
@@ -0,0 +1,135 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"name": "LTX 2.3 - LTX Image Generator (LORA + Workflow)",
|
| 3 |
+
"slug": "ltx-2-3-ltx-image-generator-lora-workflow",
|
| 4 |
+
"base_model": "LTX-2.3",
|
| 5 |
+
"media_type": "video",
|
| 6 |
+
"model_id": 2717880,
|
| 7 |
+
"version_id": 3054035,
|
| 8 |
+
"version_name": "v1.0",
|
| 9 |
+
"source": "civitai",
|
| 10 |
+
"url": "https://civitai.com/models/2717880",
|
| 11 |
+
"repo_id": null,
|
| 12 |
+
"file_path": null,
|
| 13 |
+
"author": "JonXL",
|
| 14 |
+
"category": {
|
| 15 |
+
"key": "style",
|
| 16 |
+
"label": "Visual style"
|
| 17 |
+
},
|
| 18 |
+
"modalities": [],
|
| 19 |
+
"primary_modality": "unspecified",
|
| 20 |
+
"checkpoint_family": "unknown",
|
| 21 |
+
"trigger_words": [],
|
| 22 |
+
"recommended_settings": {
|
| 23 |
+
"Resolution": "1920x1280",
|
| 24 |
+
"CFG / guidance": "2"
|
| 25 |
+
},
|
| 26 |
+
"chaining": {
|
| 27 |
+
"author": {
|
| 28 |
+
"stacks": "not stated",
|
| 29 |
+
"notes": "",
|
| 30 |
+
"avoid": [],
|
| 31 |
+
"requires": [],
|
| 32 |
+
"order": "",
|
| 33 |
+
"strength": "",
|
| 34 |
+
"stated": false
|
| 35 |
+
},
|
| 36 |
+
"general_rules": [
|
| 37 |
+
"Stacking an acceleration LoRA with a task LoRA is officially sanctioned: the ID-LoRA template chains LoraLoaderModelOnly(ltx_2.3_22b_distilled_1.1_lora_dynamic_fro09_avg_rank_111_bf16, 0.5) into LoraLoaderModelOnly(ltx-2.3-id-lora-talkvid-3k, 1.0) on the dev checkpoint.",
|
| 38 |
+
"The Python CLI exposes `--lora <path> [strength]` as a repeatable flag with default strength 1.0, so multiple adapters at once is a supported configuration, not a hack.",
|
| 39 |
+
"Load the acceleration/distilled LoRA on the dev checkpoint only. The two-stage pipelines require it for the full model but explicitly do not use it for DistilledPipeline, ICLoraPipeline or DubItPipeline, which already run distilled weights.",
|
| 40 |
+
"Do not stack two distillation LoRAs (e.g. the official rank-384 / rank-111 one plus a community DMD LoRA). The DaSiWa DMD LoRA already blends 75-80% of the official distilled delta into its audio-output route and is described by its author as recreating the distilled model on top of stock dev, i.e. a replacement.",
|
| 41 |
+
"IC-LoRAs are not chained like ordinary LoRAs: each carries a reference_downscale_factor in its safetensors metadata and needs a node that reads it (GetICLoRAParameters -> LTXVAddGuide in core, or LTXICLoRALoaderModelOnly + LTXAddVideoICLoRAGuide in ComfyUI-LTXVideo). Without one the factor silently defaults to 1.",
|
| 42 |
+
"Two IC-LoRA reference guides can be driven from a single IC-LoRA: the CrossView Warp author wires both a depth-warp video and the original video into separate reference guides and sets latent_downscale_factor = 1 on both.",
|
| 43 |
+
"DubItPipeline accepts exactly one Dub-It IC-LoRA (`--lora` exactly once) and applies it in both stages — that path is single-adapter by design.",
|
| 44 |
+
"Community convention on strengths when stacking: the IC-LoRA Dual-Character author recommends 0.6-1.0 for a content LoRA used alone, dropped to 0.3-0.5 when combined with others.",
|
| 45 |
+
"Some LoRA pairs are designed to be blended against each other — the LTX 2.3 Crisp Enhance / Soft Enhance pair is described by its author as \"can be used together and balanced at different strengths\".",
|
| 46 |
+
"The gemma-3-12b-it-abliterated LoRA is not a video LoRA and does not belong in the DiT chain — it patches the Gemma text encoder through a model+clip LoraLoader, as the official templates wire it.",
|
| 47 |
+
"The author never states which weight family this targets. Within LTX-2.3, dev vs distilled is low risk: they are the same architecture and the distillation itself is published as a LoRA that the model card calls \"applicable to the full model\", so ordinary content LoRAs load on both. Expect style/strength drift rather than breakage; the"
|
| 48 |
+
]
|
| 49 |
+
},
|
| 50 |
+
"pros": [
|
| 51 |
+
"Author published concrete recommended settings. [source: description]"
|
| 52 |
+
],
|
| 53 |
+
"cons": [
|
| 54 |
+
"No trigger word — the LoRA is always on once loaded, so strength is the only control. [source: model metadata]",
|
| 55 |
+
"Author never states which generation mode it was trained for; test against your own workflow before relying on it. [source: description]",
|
| 56 |
+
"Large at 768 MB — slower to load and heavier to stack. [source: file size]",
|
| 57 |
+
"Modest adoption (338 downloads) — less community feedback to rely on. [source: CivitAI stats]"
|
| 58 |
+
],
|
| 59 |
+
"file": {
|
| 60 |
+
"name": "ltx23_jxlstyle_jxlstyl3.safetensors",
|
| 61 |
+
"size_bytes": 805415368,
|
| 62 |
+
"size_mb": 768.1,
|
| 63 |
+
"sha256": "4a8862d19cfce611d602fece3bf507f0b4ccf3e5e294fcb99c4a8ff730af7b3c"
|
| 64 |
+
},
|
| 65 |
+
"stats": {
|
| 66 |
+
"downloads": 338,
|
| 67 |
+
"thumbs_up": 28,
|
| 68 |
+
"thumbs_down": 0
|
| 69 |
+
},
|
| 70 |
+
"popularity": {
|
| 71 |
+
"downloads": 338,
|
| 72 |
+
"thumbs_up": 28,
|
| 73 |
+
"thumbs_down": 0,
|
| 74 |
+
"comments": 0,
|
| 75 |
+
"approval": "100% positive (28/28)",
|
| 76 |
+
"age_days": 76.0,
|
| 77 |
+
"downloads_per_day": 4.45,
|
| 78 |
+
"rank_by_downloads": 88,
|
| 79 |
+
"rank_by_momentum": 65,
|
| 80 |
+
"of_total": 150,
|
| 81 |
+
"adoption_tier": "Modest",
|
| 82 |
+
"momentum": "Steady"
|
| 83 |
+
},
|
| 84 |
+
"selection_score": 674.0,
|
| 85 |
+
"selection_reasons": [
|
| 86 |
+
"338 downloads",
|
| 87 |
+
"28 thumbs-up",
|
| 88 |
+
"top-ranked for its category"
|
| 89 |
+
],
|
| 90 |
+
"example_media": [
|
| 91 |
+
{
|
| 92 |
+
"file": "01_image.jpeg",
|
| 93 |
+
"type": "image",
|
| 94 |
+
"resolution": "1920x1280",
|
| 95 |
+
"prompt": ""
|
| 96 |
+
},
|
| 97 |
+
{
|
| 98 |
+
"file": "02_image.jpeg",
|
| 99 |
+
"type": "image",
|
| 100 |
+
"resolution": "1920x1280",
|
| 101 |
+
"prompt": ""
|
| 102 |
+
},
|
| 103 |
+
{
|
| 104 |
+
"file": "03_image.jpeg",
|
| 105 |
+
"type": "image",
|
| 106 |
+
"resolution": "1920x1280",
|
| 107 |
+
"prompt": ""
|
| 108 |
+
},
|
| 109 |
+
{
|
| 110 |
+
"file": "04_image.jpeg",
|
| 111 |
+
"type": "image",
|
| 112 |
+
"resolution": "1920x1280",
|
| 113 |
+
"prompt": ""
|
| 114 |
+
},
|
| 115 |
+
{
|
| 116 |
+
"file": "05_image.jpeg",
|
| 117 |
+
"type": "image",
|
| 118 |
+
"resolution": "1920x1280",
|
| 119 |
+
"prompt": ""
|
| 120 |
+
},
|
| 121 |
+
{
|
| 122 |
+
"file": "06_image.jpeg",
|
| 123 |
+
"type": "image",
|
| 124 |
+
"resolution": "1920x1280",
|
| 125 |
+
"prompt": ""
|
| 126 |
+
}
|
| 127 |
+
],
|
| 128 |
+
"tags": [
|
| 129 |
+
"image generation",
|
| 130 |
+
"style",
|
| 131 |
+
"ltx 2.3 image generator"
|
| 132 |
+
],
|
| 133 |
+
"scraped_at": "2026-09-04T23:21:44+00:00",
|
| 134 |
+
"path": "ltxv-2.3/ltx-2-3-ltx-image-generator-lora-workflow"
|
| 135 |
+
}
|