---
base_model: incoai/Qwen3.8-27B-DFlash2
tags:
- transformers
- safetensors
- qwen3
- dflash2
- speculative-decoding
- block-diffusion
- draft-model
- sglang
- vllm
- text-generation
- base_model:Qwen/Qwen3.8-27B
- base_model:finetune:Qwen/Qwen3.8-27B
- license:apache-2.0
- text-generation-inference
- region:us
---
# Qwen 3.8 27B DFlash2 GGUF
GGUF quantizations of [**Inco AI DFlash2 draft model**](https://huggingface.co/incoai/Qwen3.8-27B-DFlash2) for [**Qwen 3.8 27B**](https://huggingface.co/Qwen/Qwen3.8-27B).
Use with [BeeLlama.cpp](https://github.com/Anbeeld/beellama.cpp), a llama.cpp fork with advanced quantization features.
## Benchmark results
### Machine configuration
- OS: Windows 11 Pro
- CPU: AMD Ryzen 9 9950X 16-Core Processor
- GPU: NVIDIA GeForce RTX 3090
- Server CPU thread pool: 16 threads
### Test setup
- Runtime: [BeeLlama.cpp v0.4.4](https://github.com/Anbeeld/beellama.cpp), CUDA 13.1
- Target model: [Qwen3.8-27B-UD-Q4_K_M](https://huggingface.co/unsloth/Qwen3.8-27B-GGUF)
- 15 generations per each prompt + quant pair
- DFlash2 setup: 7 draft tokens per block
- Context: 8192 tokens
- Batch size 4096, micro-batch size 1024
- Temperature 1.0, top-p 0.95, top-k 20
- Reasoning disabled
### Task store module
Show prompt
```text
Write one complete Python 3 file using only the standard library.
Return only Python code. Do not use markdown, comments, tests, examples, or explanatory text.
Implement a deterministic Task store module with a compact, repetitive structure that is easy to predict.
Required shape:
- imports: dataclasses, datetime, typing
- dataclass Task with fields id: int, title: str, status: str, created_at: str
- class TaskStore with an internal dict[int, Task]
- methods: add, get, rename, mark_done, reopen, delete, clear, list_all, list_open, list_done, count_open, count_done, titles, to_dicts, __len__, __contains__
- add assigns increasing integer ids starting at 1
- valid statuses are "open" and "done"
- all list methods return tasks sorted by id
- count_open and count_done use explicit loops
- titles returns task titles sorted by task id
- to_dicts returns deterministic dictionaries sorted by id
- to_dicts includes id, title, status, and created_at keys for every task
- raise ValueError for empty title or missing task id
- use straightforward if statements and explicit loops
- keep method bodies short and similar in style
- no argparse, no JSON, no file IO, no unittest, no pytest
- target about 110 to 132 lines of code
- define __all__ = ["Task", "TaskStore"]
- stop immediately after defining __all__
```
| Quant type | Size (MB) | Mean length | Median tok/s | Mean tok/s | Median AR | Mean AR |
|---|---:|---:|---:|---:|---:|---:|
| Baseline | n/a | 897.93 | 42.222 | 42.237 | n/a | n/a |
| Q2_K | 705.43 | 891.20 | 109.128 | 109.079 | 0.912 | 0.913 |
| Q3_K_M | 916.70 | 891.20 | 108.330 | 108.747 | 0.916 | 0.915 |
| Q4_K_M | 1,143.01 | 893.00 | 108.123 | 107.906 | 0.910 | 0.908 |
| Q5_K_M | 1,359.93 | 899.87 | 107.408 | 107.332 | 0.906 | 0.907 |
| Q6_K | 1,590.41 | 906.80 | 106.738 | 107.123 | 0.895 | 0.900 |
| Q8_0 | 2,056.41 | 890.93 | 109.767 | 109.067 | 0.916 | 0.911 |
| bf16 | 3,860.29 | 899.47 | 108.508 | 108.468 | 0.915 | 0.914 |
### Key-value report module
Show prompt
```text
Write one complete Python 3 file using only the standard library.
Return only Python code. Do not use markdown, comments, tests, examples, or explanatory text.
Implement a deterministic KV report module with a compact, repetitive structure that is easy to predict.
Required shape:
- imports: dataclasses, typing
- dataclass Row with fields key: str, value: str
- class Report with an internal list[Row]
- methods: add, set, get, delete, clear, keys, values, items, sorted_rows, render_lines, render_text, render_csv, filter_prefix, update_many, to_dict, copy, count_prefix, first_key, __len__, __contains__
- add appends a new row and rejects duplicate keys
- set updates an existing row or appends a new row
- get returns the value for a key
- delete removes a row by key
- keys, values, and items preserve insertion order
- sorted_rows returns rows sorted by key
- render_lines returns strings formatted as "key: value"
- render_text joins render_lines with newline characters
- render_csv returns deterministic "key,value" lines with a header
- filter_prefix returns a new Report containing keys that start with the prefix
- update_many applies set for each key and value in a dictionary sorted by key
- to_dict returns a deterministic dictionary sorted by key
- copy returns a new Report with the same rows in the same order
- count_prefix returns the number of keys that start with the prefix using an explicit loop
- first_key returns the first key and raises ValueError when there are no rows
- raise ValueError for empty keys, duplicate keys, or missing keys
- use straightforward if statements and explicit loops
- keep method bodies short and similar in style
- no enum, no alignment modes, no markdown table, no textwrap, no itertools, no unittest, no pytest
- target about 130 to 155 lines of code
- define __all__ = ["Row", "Report"]
- stop immediately after defining __all__
```
| Quant type | Size (MB) | Mean length | Median tok/s | Mean tok/s | Median AR | Mean AR |
|---|---:|---:|---:|---:|---:|---:|
| Baseline | n/a | 1,026.60 | 41.865 | 41.829 | n/a | n/a |
| Q2_K | 705.43 | 980.80 | 105.876 | 105.453 | 0.888 | 0.886 |
| Q3_K_M | 916.70 | 1,007.53 | 105.543 | 105.158 | 0.885 | 0.883 |
| Q4_K_M | 1,143.01 | 1,002.20 | 106.475 | 105.659 | 0.895 | 0.890 |
| Q5_K_M | 1,359.93 | 1,003.00 | 104.483 | 104.082 | 0.886 | 0.883 |
| Q6_K | 1,590.41 | 1,022.80 | 107.050 | 106.483 | 0.900 | 0.894 |
| Q8_0 | 2,056.41 | 992.40 | 108.184 | 108.047 | 0.893 | 0.895 |
| bf16 | 3,860.29 | 1,001.47 | 103.355 | 103.295 | 0.874 | 0.878 |
---
# Qwen3.8-27B-DFlash2
[Blog](https://inco.ai/blog/dflash2/) | [GitHub](https://github.com/z-lab/dflash)
This repository contains the DFlash 2 draft model for
[`Qwen/Qwen3.8-27B`](https://huggingface.co/Qwen/Qwen3.8-27B).
It is not a standalone language model: it runs inside a speculative
decoding server and drafts tokens for the target model to verify. The checkpoint is also
mirrored at [`z-lab/Qwen3.8-27B-DFlash2`](https://huggingface.co/z-lab/Qwen3.8-27B-DFlash2).
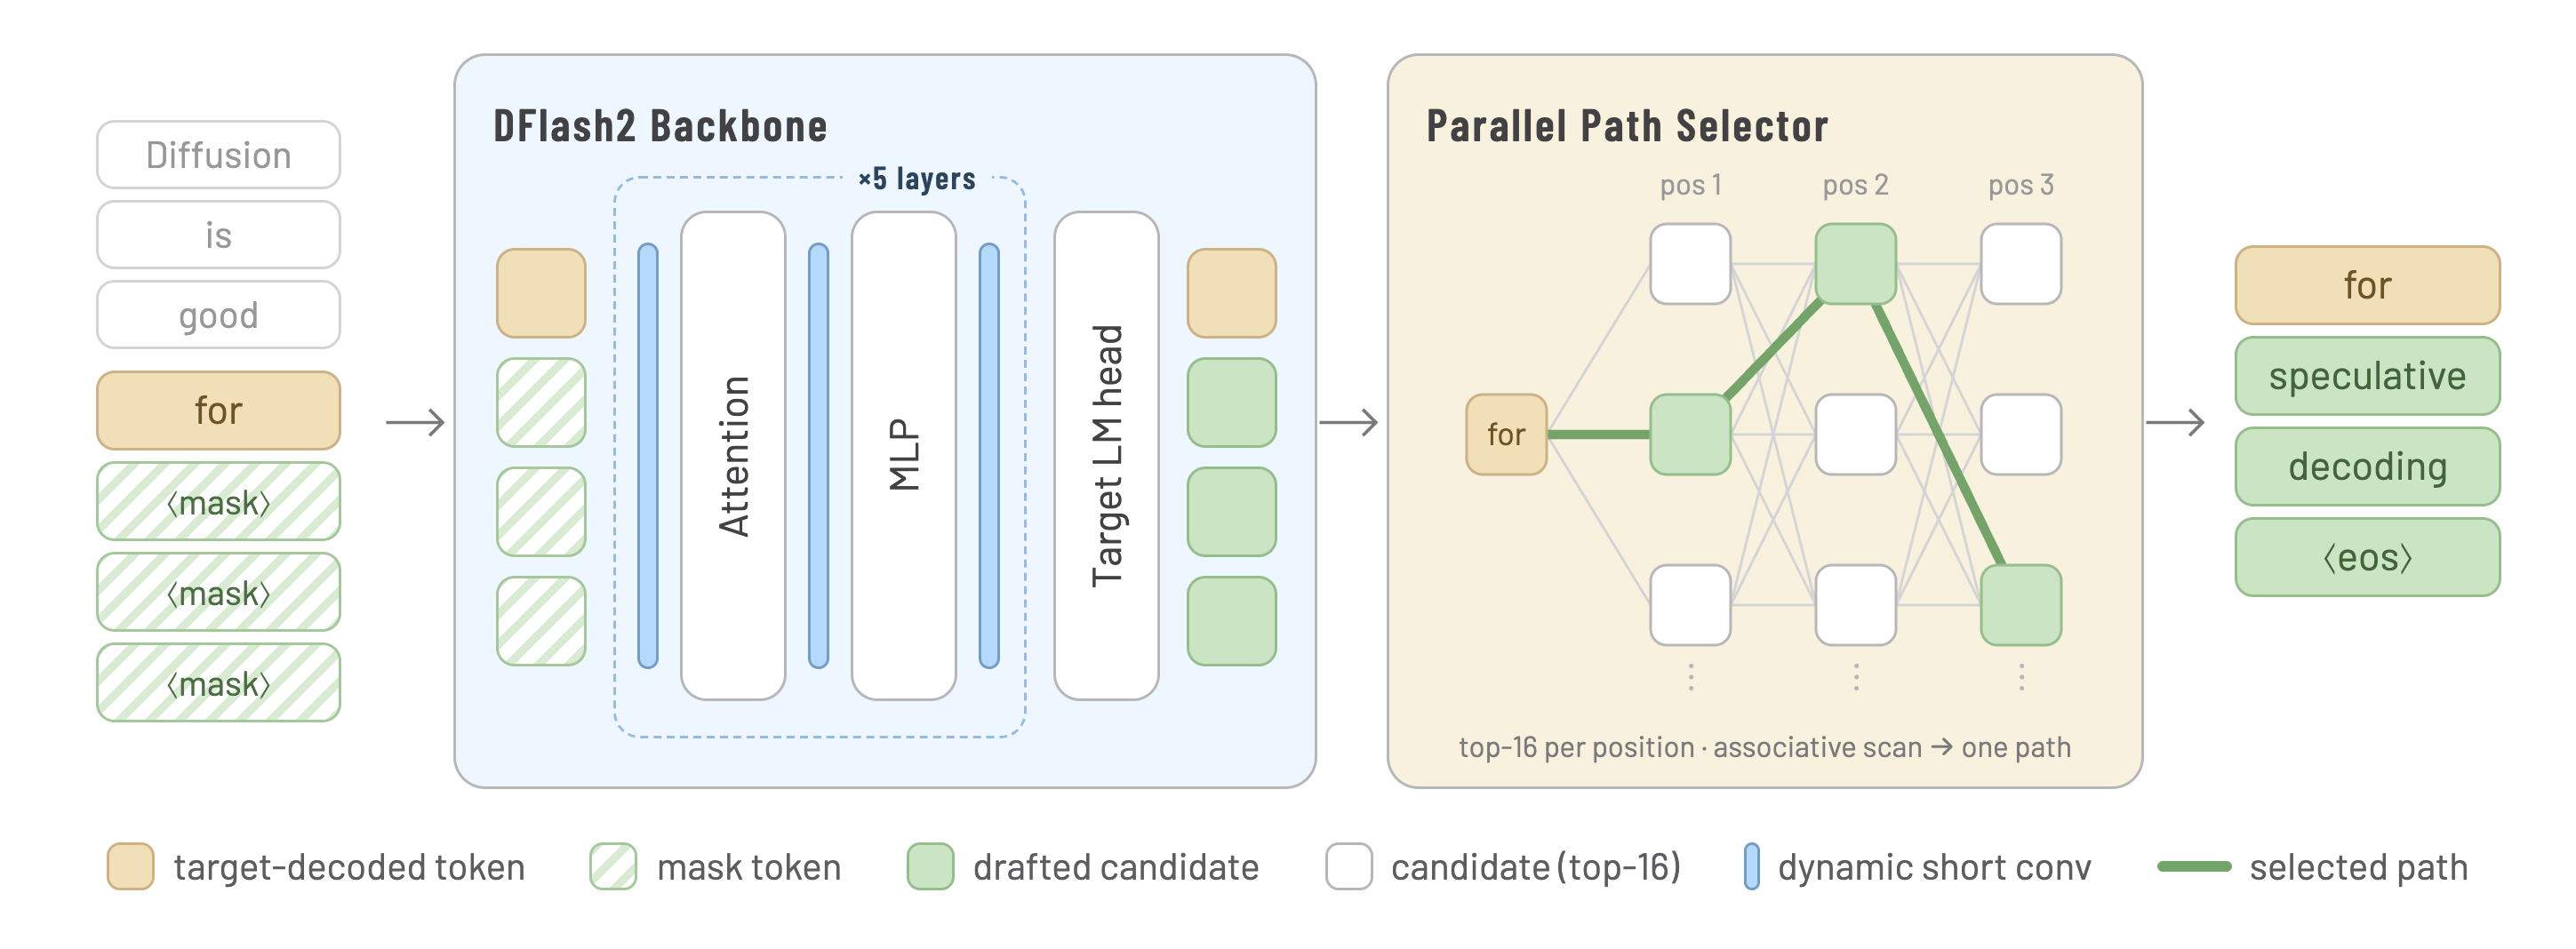
DFlash 2 is a block-diffusion drafter for speculative decoding. It predicts
a whole block of tokens in a single pass and keeps the top candidates at
every position. A lightweight selector then traces one coherent path through them.
Two-tap dynamic convolutions in the backbone keep the draft from decaying
toward the end of the block. Decoding is lossless: greedy output
matches the target model exactly, and sampling preserves its distribution.
## Quick Start
Serve with [SGLang](https://github.com/sgl-project/sglang):
```bash
pip install "sglang[all] @ git+https://github.com/sgl-project/sglang.git#subdirectory=python"
python -m sglang.launch_server \
--model-path Qwen/Qwen3.8-27B \
--speculative-algorithm DFLASH \
--speculative-draft-model-path incoai/Qwen3.8-27B-DFlash2 \
--speculative-num-draft-tokens 8
```
Or with [vLLM](https://github.com/vllm-project/vllm):
```bash
pip install -U "vllm @ git+https://github.com/vllm-project/vllm.git@refs/pull/52816/head"
vllm serve Qwen/Qwen3.8-27B \
--speculative-config '{
"method": "dflash",
"model": "incoai/Qwen3.8-27B-DFlash2",
"num_speculative_tokens": 7
}'
```
See the [blog post](https://inco.ai/blog/dflash2/) for other engines and more details.
## Evaluation
- Runtime: SGLang on one NVIDIA H200, with FlashAttention 3 for target and draft attention
- Speculation block size: 8 (7 draft tokens per verification step)
- Sampling: Qwen3.8's officially recommended parameters (temperature 1.0, top-p 0.95, top-k 20), with `xhigh` reasoning effort
- Maximum new tokens: 4096
- Prompts: benchmark formatting from [`z-lab/dflash`](https://github.com/z-lab/dflash)
We compare autoregressive decoding, Qwen3.8's built-in seven-token MTP,
a community DSpark drafter
([`RadixArk/Qwen3.8-27B-DSpark`](https://huggingface.co/RadixArk/Qwen3.8-27B-DSpark)),
and DFlash 2. All speculative methods propose seven draft tokens per
verification step.
### Acceptance Length
Acceptance length is the per-request mean of completion tokens divided by verification steps.
Higher is better.
| Task | MTP | DSpark | DFlash 2 |
| :--- | ---: | ---: | ---: |
| GSM8K | 5.02 | 4.36 | **5.46** |
| MATH-500 | 4.72 | 3.92 | **5.28** |
| HumanEval | 3.91 | 3.30 | **4.39** |
| MBPP | 3.99 | 3.51 | **4.79** |
| MT-Bench | 3.74 | 3.01 | **4.10** |
### Throughput
Throughput is total output tokens divided by end-to-end wall time.
Each cell shows `output tok/s (speedup vs. autoregressive)`.
#### Concurrency 1
| Task | Autoregressive | MTP | DSpark | DFlash 2 |
| :--- | ---: | ---: | ---: | ---: |
| GSM8K | 68.9 | 178.5 (2.59×) | 185.3 (2.69×) | **236.1 (3.43×)** |
| MATH-500 | 69.0 | 172.8 (2.51×) | 174.5 (2.53×) | **230.7 (3.34×)** |
| HumanEval | 69.0 | 151.9 (2.20×) | 159.9 (2.32×) | **214.6 (3.11×)** |
| MBPP | 69.0 | 153.1 (2.22×) | 163.3 (2.37×) | **226.9 (3.29×)** |
| MT-Bench | 68.9 | 134.9 (1.96×) | 137.6 (2.00×) | **184.0 (2.67×)** |
#### Concurrency 8
| Task | Autoregressive | MTP | DSpark | DFlash 2 |
| :--- | ---: | ---: | ---: | ---: |
| GSM8K | 467.2 | 1,022.1 (2.19×) | 1,040.8 (2.23×) | **1,328.7 (2.84×)** |
| MATH-500 | 480.0 | 1,023.5 (2.13×) | 1,025.8 (2.14×) | **1,368.3 (2.85×)** |
| HumanEval | 483.4 | 934.2 (1.93×) | 956.5 (1.98×) | **1,291.5 (2.67×)** |
| MBPP | 478.0 | 938.1 (1.96×) | 974.1 (2.04×) | **1,328.0 (2.78×)** |
| MT-Bench | 480.5 | 835.2 (1.74×) | 802.3 (1.67×) | **1,090.2 (2.27×)** |
#### Concurrency 32
| Task | Autoregressive | MTP | DSpark | DFlash 2 |
| :--- | ---: | ---: | ---: | ---: |
| GSM8K | 1,329.8 | 1,381.1 (1.04×) | 1,506.5 (1.13×) | **1,922.5 (1.45×)** |
| MATH-500 | 1,505.8 | 1,415.6 (0.94×) | 1,429.0 (0.95×) | **1,951.8 (1.30×)** |
| HumanEval | 1,546.5 | 1,296.8 (0.84×) | 1,330.1 (0.86×) | **1,799.0 (1.16×)** |
| MBPP | 1,507.7 | 1,314.9 (0.87×) | 1,361.3 (0.90×) | **1,886.8 (1.25×)** |
| MT-Bench | 1,507.4 | 1,159.7 (0.77×) | 1,115.5 (0.74×) | **1,525.3 (1.01×)** |
## Citation
If you find DFlash 2 useful, please cite:
```bibtex
@misc{inco2026dflash2,
title = {{DFlash 2: Keep Drafting Parallel}},
author = {{Inco AI}},
year = {2026},
month = {August},
url = {https://inco.ai/blog/dflash2/}
}
```
Please also cite the original DFlash paper:
```bibtex
@inproceedings{chen2026dflash,
title = {{DFlash: Block Diffusion for Flash Speculative Decoding}},
author = {Chen, Jian and Liang, Yesheng and Liu, Zhijian},
booktitle = {International Conference on Machine Learning (ICML)},
year = {2026}
}
```