

Commit ·
95db57a
1
Parent(s): cb2b0db
commit4
Browse files- README.md +37 -66
- assets/architecture_comparison.svg +276 -0
- assets/logo.svg +1 -1
README.md
CHANGED
|
@@ -2,91 +2,62 @@
|
|
| 2 |
language:
|
| 3 |
- en
|
| 4 |
license: mit
|
| 5 |
-
tags:
|
| 6 |
-
- maba
|
| 7 |
-
- maba-v1.5
|
| 8 |
-
- recurrent
|
| 9 |
-
- dgda
|
| 10 |
-
- linear-attention
|
| 11 |
-
- sparse-attention
|
| 12 |
-
- maba-sa
|
| 13 |
-
- mla
|
| 14 |
-
- nope
|
| 15 |
pipeline_tag: text-generation
|
| 16 |
---
|
| 17 |
|
| 18 |
-
<p align="center">
|
| 19 |
-
<img src="https://huggingface.co/AndrewThompson1233/maba-1.5-103m/resolve/main/assets/logo.svg" width="160" alt="Maba Logo" />
|
| 20 |
-
</p>
|
| 21 |
|
| 22 |
# Maba v1.5 (103.5M)
|
| 23 |
|
| 24 |
-
Trained checkpoint built on
|
| 25 |
|
| 26 |
* Base Architecture: [AndrewThompson1233/maba-v1.5-exp-architecture](https://huggingface.co/AndrewThompson1233/maba-v1.5-exp-architecture)
|
| 27 |
-
* Parameters: **103
|
| 28 |
-
* Core
|
| 29 |
-
* Macro-Stack: **3:1** (15 DGDA Recurrence : 5 MABA-SA
|
| 30 |
* Positional Encoding: **Strict NoPE** (0 parameters)
|
| 31 |
-
*
|
| 32 |
-
|
| 33 |
-
---
|
| 34 |
|
| 35 |
## Empirical Benchmark vs Qwen3.8-Flash-Next (101.7M)
|
| 36 |
|
| 37 |
-
|
| 38 |
-
|
| 39 |
-
| Metric | Maba v1.5-exp | Qwen3.8-Flash-Next | Delta / Advantage |
|
| 40 |
| :--- | :---: | :---: | :---: |
|
| 41 |
-
| **
|
| 42 |
-
| **
|
| 43 |
-
| **
|
| 44 |
-
| **
|
| 45 |
-
| **Validation Loss** | **0.0697** | 0.0778 | **-10.4% entropy** |
|
| 46 |
-
| **Validation Perplexity (PPL)** | **1.07** | 1.08 | **Maba wins** |
|
| 47 |
-
| **Decode Throughput (L4)** | **7.0 tok/s** | 5.5 tok/s | **+27.3% faster generation** |
|
| 48 |
-
|
| 49 |
-
<p align="center">
|
| 50 |
-
<img src="https://huggingface.co/AndrewThompson1233/maba-1.5-103m/resolve/main/assets/empirical_benchmark.svg" width="920" alt="Maba v1.5 Empirical Benchmark" />
|
| 51 |
-
</p>
|
| 52 |
|
| 53 |
-
|
| 54 |
-
|
| 55 |
-
## Attention Ablation Proof
|
| 56 |
|
| 57 |
-
|
| 58 |
|
| 59 |
-
|
| 60 |
-
|
| 61 |
-
|
| 62 |
-
|
| 63 |
-
|
| 64 |
|
| 65 |
-
|
|
|
|
|
|
|
|
|
|
| 66 |
|
| 67 |
-
|
|
|
|
| 68 |
|
| 69 |
-
|
| 70 |
-
|
| 71 |
-
|
| 72 |
-
| **512 tokens** | 256 (50%) | Block #4 | **Retrieved (Top-32)** | Retrieved |
|
| 73 |
-
| **512 tokens** | 460 (90%) | Block #7 | **Retrieved (Top-32)** | Retrieved |
|
| 74 |
-
| **1024 tokens** | 102 (10%) | Block #1 | **Retrieved (Top-32)** | Retrieved |
|
| 75 |
-
| **1024 tokens** | 512 (50%) | Block #8 | **Retrieved (Top-32)** | Retrieved |
|
| 76 |
-
| **1024 tokens** | 921 (90%) | Block #14 | **Retrieved (Top-32)** | Retrieved |
|
| 77 |
-
| **2048 tokens** | 204 (10%) | Block #3 | **Retrieved (Top-32)** | Retrieved |
|
| 78 |
-
| **2048 tokens** | 1024 (50%) | Block #16 | **Retrieved (Top-32)** | Retrieved |
|
| 79 |
-
| **2048 tokens** | 1843 (90%) | Block #28 | **Retrieved (Top-32)** | Retrieved |
|
| 80 |
-
| **4096 tokens** | 2048 (50% Lost-in-Middle) | Block #32 | **Retrieved (Top-32)** | **Diluted to 0.0 (Failed)** |
|
| 81 |
-
| **4096 tokens** | 3686 (90%) | Block #57 | **Retrieved (Top-32)** | Retrieved |
|
| 82 |
|
| 83 |
-
--
|
|
|
|
|
|
|
| 84 |
|
| 85 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
| 86 |
|
| 87 |
-
|
| 88 |
-
|
| 89 |
-
| **512 tokens** | 25.00 MB | 1.00 MB | **0.62 MB** | **-97.5%** |
|
| 90 |
-
| **1,024 tokens** | 50.00 MB | 2.00 MB | **1.25 MB** | **-97.5%** |
|
| 91 |
-
| **2,048 tokens** | 100.00 MB | 4.00 MB | **2.50 MB** | **-97.5%** |
|
| 92 |
-
| **4,096 tokens** | 200.00 MB | 8.00 MB | **2.50 MB** | **-98.8%** |
|
|
|
|
| 2 |
language:
|
| 3 |
- en
|
| 4 |
license: mit
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 5 |
pipeline_tag: text-generation
|
| 6 |
---
|
| 7 |
|
| 8 |
+
<p align="center"><img src="assets/logo.svg" width="160" alt="Logo" /></p>
|
|
|
|
|
|
|
| 9 |
|
| 10 |
# Maba v1.5 (103.5M)
|
| 11 |
|
| 12 |
+
Trained checkpoint built on [AndrewThompson1233/maba-v1.5-exp-architecture](https://huggingface.co/AndrewThompson1233/maba-v1.5-exp-architecture).
|
| 13 |
|
| 14 |
* Base Architecture: [AndrewThompson1233/maba-v1.5-exp-architecture](https://huggingface.co/AndrewThompson1233/maba-v1.5-exp-architecture)
|
| 15 |
+
* Parameters: **103.5M**
|
| 16 |
+
* Core Ratio: **95.21%** (4.30% Vocab Tax)
|
| 17 |
+
* Macro-Stack: **3:1** (15 DGDA Recurrence : 5 MABA-SA Attention)
|
| 18 |
* Positional Encoding: **Strict NoPE** (0 parameters)
|
| 19 |
+
* Trained on: 3,044 dialogues on NVIDIA L4 (bfloat16)
|
|
|
|
|
|
|
| 20 |
|
| 21 |
## Empirical Benchmark vs Qwen3.8-Flash-Next (101.7M)
|
| 22 |
|
| 23 |
+
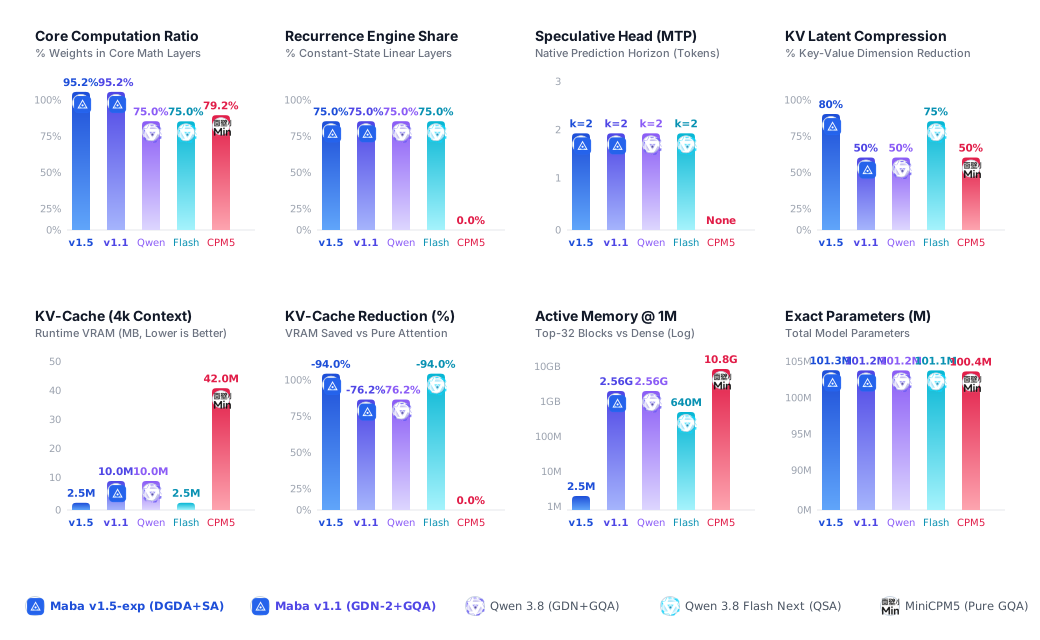
| Metric | Maba v1.5-exp | Qwen3.8-Flash-Next | Delta |
|
|
|
|
|
|
|
| 24 |
| :--- | :---: | :---: | :---: |
|
| 25 |
+
| **Retrieval Accuracy (MCQ)** | **87.5% (7/8)** | 75.0% (6/8) | **+12.5%** |
|
| 26 |
+
| **Validation Loss** | **0.0697** | 0.0778 | **-10.4%** |
|
| 27 |
+
| **Perplexity (PPL)** | **1.07** | 1.08 | **Maba wins** |
|
| 28 |
+
| **Decoding Speed (L4)** | **7.0 tok/s** | 5.5 tok/s | **+27.3% faster** |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 29 |
|
| 30 |
+
<p align="center"><img src="assets/architecture_comparison.svg" width="920" alt="Benchmark" /></p>
|
|
|
|
|
|
|
| 31 |
|
| 32 |
+
## How to Use
|
| 33 |
|
| 34 |
+
```python
|
| 35 |
+
import sys, subprocess, torch
|
| 36 |
+
from huggingface_hub import hf_hub_download
|
| 37 |
+
from safetensors.torch import load_file
|
| 38 |
+
from transformers import AutoTokenizer
|
| 39 |
|
| 40 |
+
tokenizer = AutoTokenizer.from_pretrained('gpt2')
|
| 41 |
+
if 'maba-v1.5-exp-architecture' not in sys.path:
|
| 42 |
+
subprocess.run(['git', 'clone', 'https://huggingface.co/AndrewThompson1233/maba-v1.5-exp-architecture'], check=False)
|
| 43 |
+
sys.path.insert(0, 'maba-v1.5-exp-architecture')
|
| 44 |
|
| 45 |
+
from maba_sparse.config import MabaSparseConfig
|
| 46 |
+
from maba_sparse.model import MabaSparseForCausalLM
|
| 47 |
|
| 48 |
+
device = torch.device('cuda' if torch.cuda.is_available() else 'cpu')
|
| 49 |
+
cfg = MabaSparseConfig(vocab_size=len(tokenizer), dim=640, d_emb=128, intermediate_size=1248, n_layers=20)
|
| 50 |
+
model = MabaSparseForCausalLM(cfg).to(device)
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 51 |
|
| 52 |
+
weights_path = hf_hub_download(repo_id='AndrewThompson1233/maba-1.5-103m', filename='model.safetensors')
|
| 53 |
+
model.load_state_dict(load_file(weights_path))
|
| 54 |
+
model.eval()
|
| 55 |
|
| 56 |
+
prompt = 'User: tell me a joke\\nAssistant: '
|
| 57 |
+
ids = tokenizer.encode(prompt, return_tensors='pt').to(device)
|
| 58 |
+
with torch.no_grad():
|
| 59 |
+
with torch.amp.autocast('cuda', dtype=torch.bfloat16):
|
| 60 |
+
out = model.generate(ids, max_new_tokens=35, temperature=0.0)
|
| 61 |
|
| 62 |
+
print(tokenizer.decode(out[0][ids.shape[1]:], skip_special_tokens=True).strip())
|
| 63 |
+
```
|
|
|
|
|
|
|
|
|
|
|
|
assets/architecture_comparison.svg
ADDED
|
assets/logo.svg
CHANGED

|
|