
language: ru
license: mit
library_name: transformers
pipeline_tag: audio-classification
base_model: jonatasgrosman/exp_w2v2t_ru_unispeech-sat_s423
datasets:
  - Aniemore/resd
  - Aniemore/resd_annotated
tags:
  - audio-classification
  - emotion-recognition
  - speech-emotion-recognition
  - audio
  - speech
  - russian
metrics:
  - f1
  - accuracy
  - recall
model-index:
  - name: unispeech-sat-emotion-russian-resd
    results:
      - task:
          name: Speech Emotion Recognition
          type: audio-classification
        dataset:
          name: RESD test
          type: Aniemore/resd
          args: ru
        metrics:
          - name: Macro F1
            type: f1
            value: 0.7027
          - name: Unweighted accuracy
            type: recall
            value: 0.7077
          - name: Accuracy
            type: accuracy
            value: 0.7071
      - task:
          name: Speech Emotion Recognition
          type: audio-classification
        dataset:
          name: Dusha podcast test
          type: internal
          args: ru
        metrics:
          - name: Macro F1
            type: f1
            value: 0.1
          - name: Unweighted accuracy
            type: recall
            value: 0.349
          - name: Accuracy
            type: accuracy
            value: 0.0863
      - task:
          name: Speech Emotion Recognition
          type: audio-classification
        dataset:
          name: CAMEO test
          type: internal
          args: ru
        metrics:
          - name: Macro F1
            type: f1
            value: 0.1946
          - name: Unweighted accuracy
            type: recall
            value: 0.2094
          - name: Accuracy
            type: accuracy
            value: 0.2366
unispeech-sat-emotion-russian-resd
Speech emotion recognition for Russian over seven classes: anger, disgust, enthusiasm, fear, happiness, neutral, sadness.
Fine-tuned from jonatasgrosman/exp_w2v2t_ru_unispeech-sat_s423 on Aniemore/resd.
- Parameters: 316M · weights: 1206 MiB (fp32)
- Input: 16 kHz mono waveform
- Quantized builds:
unispeech-sat-emotion-russian-resd-quantized— INT8, FP8 and INT4, up to 5.8x smaller on disk at the same score
Results
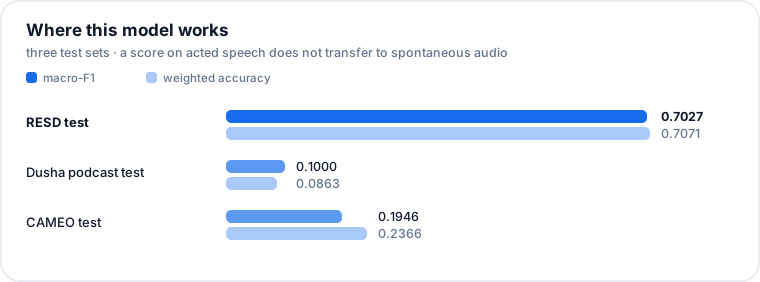
| Test set | n | UA | WA | macro-F1 |
|---|---|---|---|---|
| RESD test | 280 | 0.7077 | 0.7071 | 0.7027 |
| Dusha podcast test | 12079 | 0.3490 | 0.0863 | 0.1000 |
| CAMEO test | 5187 | 0.2094 | 0.2366 | 0.1946 |

Usage
import torch, librosa
from transformers import AutoModelForAudioClassification, AutoFeatureExtractor

repo = "Aniemore/unispeech-sat-emotion-russian-resd"
model = AutoModelForAudioClassification.from_pretrained(repo).eval()
fe = AutoFeatureExtractor.from_pretrained(repo)

# Resample to 16 kHz. RESD ships at 44.1 kHz, and 44.1 kHz audio
# labelled as 16 kHz is stretched 2.8x in time — the model answers,
# it just answers about other audio.
wav, _ = librosa.load("clip.wav", sr=16000, mono=True)
x = fe(wav, sampling_rate=16000, return_tensors="pt", padding=True)
with torch.no_grad():
    logits = model(**x).logits

probs = logits.softmax(-1)[0]
print({model.config.id2label[i]: round(p.item(), 3) for i, p in enumerate(probs)})
Loading the audio without librosa
# torchaudio
import torchaudio
wav, sr = torchaudio.load("clip.wav")
wav = torchaudio.functional.resample(wav, sr, 16000).mean(0).numpy()

# torchcodec, the newer decoder
from torchcodec.decoders import AudioDecoder
wav = AudioDecoder("clip.wav", sample_rate=16000).get_all_samples().data.mean(0).numpy()

# straight from the dataset — `datasets` resamples on the column, so
# the mixed 16/44.1 kHz in RESD is handled for you
from datasets import load_dataset, Audio
ds = load_dataset("Aniemore/resd", split="test")
ds = ds.cast_column("speech", Audio(sampling_rate=16000))
wav = ds[0]["speech"]["array"]
Evaluation protocol
Audio resampled to 16 kHz mono, clips capped at 12 s, normalized per utterance, padding masked. UA is macro-averaged recall, WA is accuracy, F1 is macro-averaged. All three test sets went through the same harness, so the rows are comparable to each other.
The RESD split matches fold 1 of EmoBox bit for bit. The top entry there is WavLM-large at WA 56.47 / UA 55.87 / F1 55.82. These numbers are higher, but the training protocol differs — EmoBox freezes the encoder and trains a probe, this is a full fine-tune — so read it as a different recipe on the same split, not as a like-for-like win.
Limitations
RESD is acted and class-balanced. Real speech is neither. The Dusha podcast row above is the honest signal for spontaneous audio, and it is far below the RESD row. Spontaneous Russian is roughly 93% neutral, and a model tuned on balanced acted data over-predicts the emotional classes on it. Measure on your own material, and calibrate the neutral logit if you deploy.
Seven classes only, Russian only, single-speaker clips.
Citation
@misc{aniemore,
  author = {Lubenets, Ilya and Davidchuk, Nikita and Amentes, Aleksandr},
  title  = {Aniemore: an open library for emotion recognition in Russian speech},
  url    = {https://github.com/Aniemore/Aniemore},
  year   = {2023}
}
License
MIT.