

TinyJev
Collection
Typed decision models for a laptop: Choice, Noul and Score with calibrated probabilities, one forward pass. Two sizes. • 2 items • Updated
Typed decisions inside Ollama. Reads the whole document.


Send this model some text and questions with the answers you will accept. It returns a probability for every option you offered and nothing else: it never writes prose, it scores your options and stops.
TinyJev 4B v2 is built for Ollama's decision API (/v1/systemone, Ollama 0.35.1 or newer). It was trained on
the exact bytes Ollama sends to a decision model, and it ships with a 16k-token window, so a whole contract,
policy or email thread fits in one request. Of Ollama's launch decision models, Tev1 (4B and 0.8B) ships with
a 2k window and Nimble 9B with 8k.
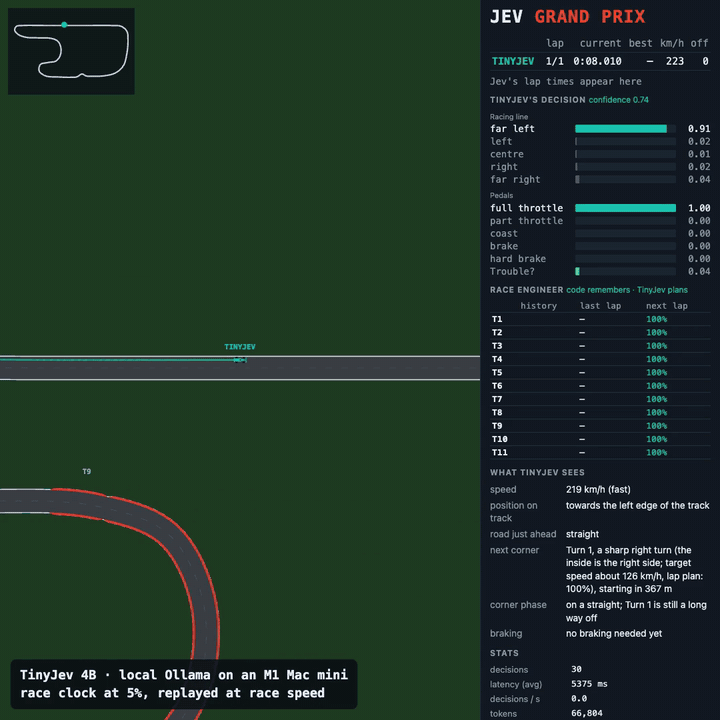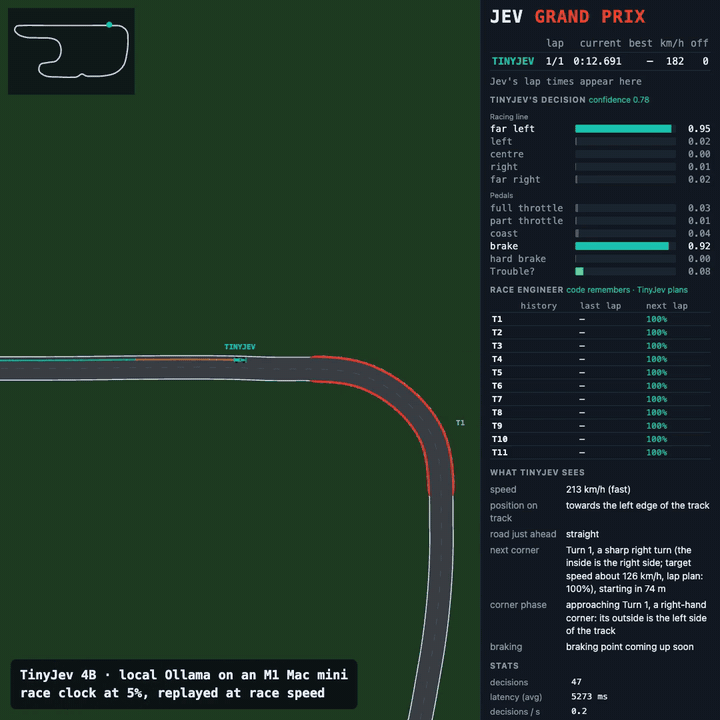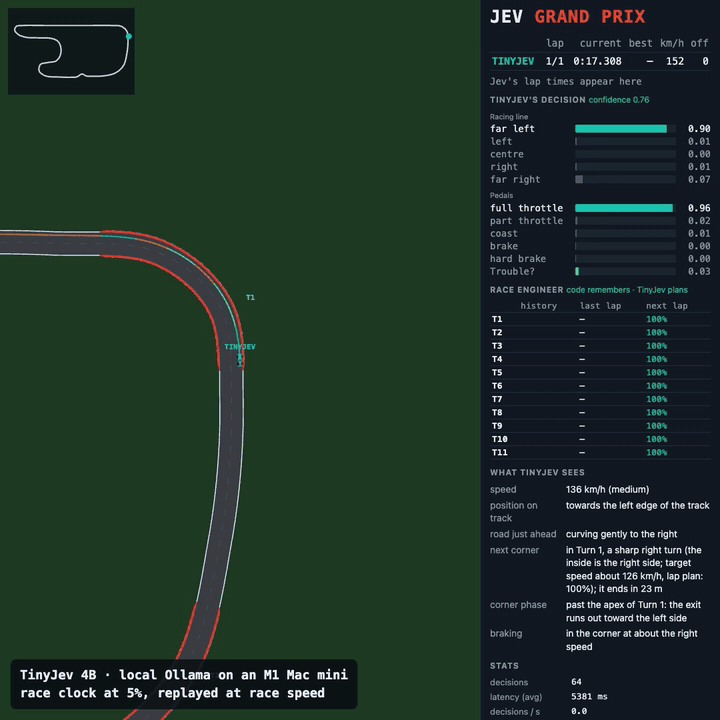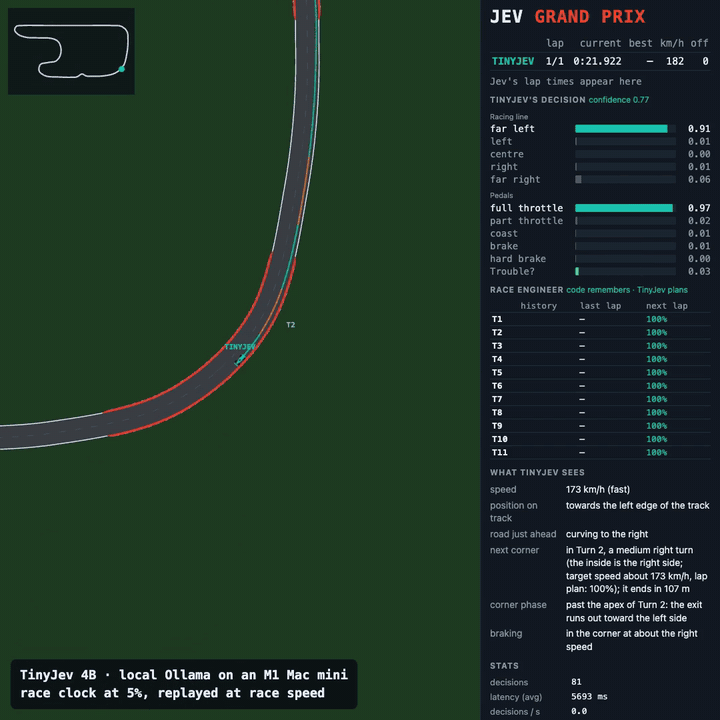
One lap of Jev Grand Prix, driven through a local Ollama: every decision picks the racing line and the pedals, and code steers. An M1 Mac mini needs about 5 s per decision, so the race clock ran at 5% and the clip plays back at race speed. Its first lap from a standing start: 59.0 s, no off-tracks; the game's README reports 59.2 s for TypeSafe's hosted Jev on its first lap.
ollama pull parable/tinyjev # Ollama 0.35.1 or newer, 4.5 GB
curl http://localhost:11434/v1/systemone -d '{
  "model": "parable/tinyjev",
  "state": "Shoes arrived two weeks late and in the wrong size. Also I see two charges on my card.",
  "questions": {
    "team":     {"type": "choice", "instructions": "Which team should handle this?",
                 "criteria": {"returns": "Exchanges, refunds, wrong or damaged items",
                              "shipping": "Delivery status, delays, lost packages",
                              "billing": "Charges, invoices, payment problems"}},
    "escalate": {"type": "noul", "instructions": "Does this need urgent human attention?"}
  }}'
From Python, pip install tinyjev then tinyjev.load("TinyJev-4B").predict({...}) talks to your local Ollama.
Without ollama.com: download TinyJev-4B-Q8_0.gguf and Modelfile from this repo and run
ollama create tinyjev -f Modelfile. TinyJev-4B-Q4_K_M.gguf is the smaller file (2.7 GB); change the FROM
line to use it.
Every row runs through Ollama 0.35.1's own /v1/systemone, same inputs, Q8_0 weights.
| Model | JevBench public (231) | OpenDecision 500 | Contracts: 60 unseen NDAs (180 questions) |
|---|---|---|---|
| TinyJev 4B v2 | 0.766 | 490 | 0.806 |
| Tev1 4B, as shipped in Ollama (2k window) | 0.688 | 487 | 0.406 |
| Tev1 4B, window raised to 16k | 0.762 | 487 | 0.728 |
| Qwen3.5-4B, no fine-tuning | 0.693 | 479 | — |
JevBench is the public split of fstandhartinger/jevbench, scored by
its own typesafe adapter; requests Ollama rejects for length count as wrong. OpenDecision is the 500-case suite in
benchmarks/opendecision. The contract
column asks what each test-split NDA from ContractNLI says about three of its clauses (says so / says the opposite
/ silent), in wording never used in training. Tev1 as shipped rejects 26 of the 60 NDAs as longer than its window, and those questions count as wrong. Each NDA's rare "says the opposite" clauses are asked first, so 46% of the questions are contradictions.
On short decisions TinyJev v2 is level with Tev1 at a 16k window: 177 against 176 of the 231 JevBench items, 490 against 487 on OpenDecision. The lead is on long contracts. On JevBench's 19 long-policy items Tev1 still wins, 8 to 6.
Ollama scores each question with one forward pass and a softmax over the option letters, so the probabilities are the model's own. Each question in a request costs one read of the prompt: about 1.8 s per question for a 700-token prompt on an M1 Mac mini at Q8_0.
Known weakness, measured: multi-step date and number reasoning. It gets 1 of JevBench's 15 hard temporal items, as does Tev1.
The previous TinyJev 4B (Qwen3-4B-Base plus a pointer head, scored in-process with MLX or PyTorch) is kept at
revision v1: tinyjev.load("TinyJev-4B-v1"), or revision="v1" with huggingface_hub.
Built on Qwen3.5-4B (Apache-2.0). Training recipe and the bulk of the data from Tev1 by Together AI (MIT). Contract data from ContractNLI (Koreeda and Manning, 2021, Hitachi America, CC BY 4.0). The decision interface follows TypeSafe's Jev as implemented by Ollama. The racing demo is Jev Grand Prix by enoyola (MIT).
If this model is useful in your work, you can support independent research:

docker model run hf.co/AnkitAI/TinyJev-4B:Q4_K_M