

Sync model repo (text/metadata)
Browse files- .gitattributes +1 -0
- README.md +210 -0
- benchmarks/esrgan-graviton-g4-fp32.yaml +35 -0
- benchmarks/esrgan-graviton-g4-int8.yaml +36 -0
- config.yaml +17 -0
- example.py +139 -0
- metadata.yaml +23 -0
- sample_input.jpg +0 -0
- sample_output.png +3 -0
- super_resolution.json +11 -0
.gitattributes
CHANGED
|
@@ -33,3 +33,4 @@ saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
sample_output.png filter=lfs diff=lfs merge=lfs -text
|
README.md
ADDED
|
@@ -0,0 +1,210 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
library_name: executorch
|
| 3 |
+
display_name: ESRGAN x4 INT8 — ExecuTorch + XNNPACK
|
| 4 |
+
license: apache-2.0
|
| 5 |
+
base_model: kadirnar/RRDB_PSNR_x4
|
| 6 |
+
base_model_relation: quantized
|
| 7 |
+
tags:
|
| 8 |
+
- image-to-image
|
| 9 |
+
- esrgan
|
| 10 |
+
- int8
|
| 11 |
+
- quantized
|
| 12 |
+
- xnnpack
|
| 13 |
+
- arm
|
| 14 |
+
- executorch
|
| 15 |
+
- edge-ai
|
| 16 |
+
- urban100
|
| 17 |
+
- super-resolution
|
| 18 |
+
pipeline_tag: image-to-image
|
| 19 |
+
datasets:
|
| 20 |
+
- urban100
|
| 21 |
+
metrics:
|
| 22 |
+
- psnr
|
| 23 |
+
model-index:
|
| 24 |
+
- name: esrgan-int8-xnnpack-executorch-graviton-g4
|
| 25 |
+
results:
|
| 26 |
+
- task:
|
| 27 |
+
type: image-to-image
|
| 28 |
+
name: Super Resolution
|
| 29 |
+
dataset:
|
| 30 |
+
type: urban100
|
| 31 |
+
name: Urban100
|
| 32 |
+
split: validation
|
| 33 |
+
args:
|
| 34 |
+
evaluation_samples: 100
|
| 35 |
+
metrics:
|
| 36 |
+
- type: psnr
|
| 37 |
+
value: 26.81
|
| 38 |
+
name: PSNR (dB)
|
| 39 |
+
---
|
| 40 |
+
|
| 41 |
+
# ESRGAN x4 INT8 (ExecuTorch + XNNPACK)
|
| 42 |
+
|
| 43 |
+
This is an INT8-quantized version of [ESRGAN RRDBNet](https://github.com/xinntao/ESRGAN) optimized for edge deployment on ARM devices using [ExecuTorch](https://github.com/pytorch/executorch) with the XNNPACK backend. The model was quantized using PT2E static symmetric per-channel quantization and exported to the `.pte` format for efficient inference on ARM Cortex-A processors (AWS Graviton, mobile ARM, embedded).
|
| 44 |
+
|
| 45 |
+
The PSNR-oriented weights (`RRDB_PSNR_x4.pth`) from [kadirnar/RRDB_PSNR_x4](https://huggingface.co/kadirnar/RRDB_PSNR_x4) are used — the L1-trained high-PSNR variant whose metrics are directly comparable to standard SR benchmark figures.
|
| 46 |
+
|
| 47 |
+
## Key Highlights
|
| 48 |
+
|
| 49 |
+
Compared to the FP32 baseline:
|
| 50 |
+
|
| 51 |
+
- **2.76x smaller** — 64.07 MB to 23.18 MB
|
| 52 |
+
- **2.44x faster** — 1763 ms to 724 ms on AWS Graviton (Neoverse-V2)
|
| 53 |
+
- **Minimal quality loss** — −0.22 dB PSNR on Urban100
|
| 54 |
+
|
| 55 |
+
## Model Details
|
| 56 |
+
|
| 57 |
+
### Model Description
|
| 58 |
+
|
| 59 |
+
Quantized version of ESRGAN (Enhanced Super-Resolution Generative Adversarial Network) with a 23-block RRDBNet backbone. The model performs 4x bicubic super-resolution on urban scene images, optimized for efficient edge inference via INT8 quantization and the ExecuTorch runtime.
|
| 60 |
+
|
| 61 |
+
- **Developed by:** Xintao Wang et al. (ESRGAN), Marvik AI (quantization & optimization)
|
| 62 |
+
- **Model type:** Super Resolution (4x upscaling)
|
| 63 |
+
- **License:** Apache-2.0
|
| 64 |
+
- **Base model:** [ESRGAN RRDBNet](https://github.com/xinntao/ESRGAN) — quantized, not finetuned
|
| 65 |
+
|
| 66 |
+
### Model Sources
|
| 67 |
+
|
| 68 |
+
- **Repository:** https://github.com/xinntao/ESRGAN
|
| 69 |
+
- **Pretrained weights:** https://huggingface.co/kadirnar/RRDB_PSNR_x4
|
| 70 |
+
|
| 71 |
+
## How to Get Started with the Model
|
| 72 |
+
|
| 73 |
+
### Install dependencies
|
| 74 |
+
|
| 75 |
+
```bash
|
| 76 |
+
pip install executorch torch torchvision pillow numpy
|
| 77 |
+
```
|
| 78 |
+
|
| 79 |
+
### Download the model
|
| 80 |
+
|
| 81 |
+
```python
|
| 82 |
+
from huggingface_hub import hf_hub_download
|
| 83 |
+
|
| 84 |
+
model_path = hf_hub_download(
|
| 85 |
+
repo_id="Arm/esrgan-int8-xnnpack-executorch-graviton-g4",
|
| 86 |
+
filename="esrgan-x4-int8-executorch.pte",
|
| 87 |
+
)
|
| 88 |
+
```
|
| 89 |
+
|
| 90 |
+
### Run inference
|
| 91 |
+
|
| 92 |
+
```bash
|
| 93 |
+
python example.py
|
| 94 |
+
```
|
| 95 |
+
|
| 96 |
+
Or use the core inference loop directly:
|
| 97 |
+
|
| 98 |
+
```python
|
| 99 |
+
from executorch.runtime import Runtime
|
| 100 |
+
from PIL import Image
|
| 101 |
+
from torchvision import transforms
|
| 102 |
+
|
| 103 |
+
# Load model
|
| 104 |
+
runtime = Runtime.get()
|
| 105 |
+
program = runtime.load_program("esrgan-x4-int8-executorch.pte")
|
| 106 |
+
method = program.load_method("forward")
|
| 107 |
+
|
| 108 |
+
# Preprocess (no normalization — model expects raw [0, 1] values)
|
| 109 |
+
image = Image.open("input.jpg").convert("RGB")
|
| 110 |
+
to_tensor = transforms.ToTensor()
|
| 111 |
+
input_tensor = to_tensor(image).unsqueeze(0) # [1, 3, H, W]
|
| 112 |
+
|
| 113 |
+
# Run a single 128x128 tile
|
| 114 |
+
tile = input_tensor[:, :, :128, :128]
|
| 115 |
+
outputs = method.execute([tile])
|
| 116 |
+
# outputs[0] shape: [1, 3, 512, 512] — the 4x super-resolved tile
|
| 117 |
+
# See example.py for full tiled inference on arbitrary-size images
|
| 118 |
+
```
|
| 119 |
+
|
| 120 |
+
## Evaluation
|
| 121 |
+
|
| 122 |
+
### Testing Data, Factors & Metrics
|
| 123 |
+
|
| 124 |
+
#### Testing Data
|
| 125 |
+
|
| 126 |
+
Evaluated on 100 images from Urban100 (validation split). Urban100 is a standard super-resolution benchmark consisting of urban scenes with repetitive structures, specifically chosen to challenge SR models on fine detail reconstruction.
|
| 127 |
+
|
| 128 |
+
#### Metrics
|
| 129 |
+
|
| 130 |
+
- **PSNR (Peak Signal-to-Noise Ratio, dB)** — measures pixel-level fidelity between the super-resolved output and the ground-truth high-resolution image; higher is better
|
| 131 |
+
- **SSIM (Structural Similarity Index)** — measures perceived structural similarity; higher is better
|
| 132 |
+
|
| 133 |
+
### Results
|
| 134 |
+
|
| 135 |
+
#### Quality
|
| 136 |
+
|
| 137 |
+
| Metric | FP32 (Original) | INT8 (Optimized) | Delta |
|
| 138 |
+
|:---|:---:|:---:|:---:|
|
| 139 |
+
| PSNR (dB) | 27.03 | 26.81 | −0.22 dB |
|
| 140 |
+
| SSIM | 0.8176 | 0.8109 | −0.007 |
|
| 141 |
+
|
| 142 |
+
#### Efficiency
|
| 143 |
+
|
| 144 |
+
| Metric | FP32 (Original) | INT8 (Optimized) | Improvement |
|
| 145 |
+
|:---|:---:|:---:|:---:|
|
| 146 |
+
| Model Size (.pte) | 64.07 MB | 23.18 MB | **2.76x smaller** |
|
| 147 |
+
| Graviton Latency (mean) | 1763 ms | 724 ms | **2.44x faster** |
|
| 148 |
+
| Graviton Latency (p50) | 1763 ms | 704 ms | **2.50x faster** |
|
| 149 |
+
| Graviton Latency (p90) | 1765 ms | 780 ms | **2.26x faster** |
|
| 150 |
+
| Graviton Cold Start | 66.3 ms | 36.7 ms | **1.81x faster** |
|
| 151 |
+
|
| 152 |
+
*Latency measured on AWS Graviton G4 (Neoverse-V2, 16 cores) with ExecuTorch 1.1.0, XNNPACK + KleidiAI backend, batch size 1, 10 warmup runs + 100 measurement runs.*
|
| 153 |
+
|
| 154 |
+
## Technical Specifications
|
| 155 |
+
|
| 156 |
+
### Objective
|
| 157 |
+
|
| 158 |
+
4x single-image super-resolution from bicubic-degraded low-resolution inputs, targeting urban scenes with repetitive structures.
|
| 159 |
+
|
| 160 |
+
### Quantization
|
| 161 |
+
|
| 162 |
+
- **Method**: PT2E Static Quantization via XNNPACKQuantizer
|
| 163 |
+
- **Precision**: INT8 symmetric, per-channel
|
| 164 |
+
- **Backend**: XNNPACK
|
| 165 |
+
- **Layers kept in FP32**: upsampling layers (`upconv1`, `upconv2`, `HRconv`, `conv_last`) and the first 3 RRDB body blocks (`body.0`–`body.2`) to preserve output fidelity
|
| 166 |
+
- **Calibration**: 100 images from Urban100 (random subset, patch mode)
|
| 167 |
+
|
| 168 |
+
### Export Pipeline
|
| 169 |
+
|
| 170 |
+
1. Load pretrained FP32 RRDBNet with PSNR-oriented weights from HuggingFace (`kadirnar/RRDB_PSNR_x4`)
|
| 171 |
+
2. Capture model graph via `torch.export` at fixed 128×128 tile size
|
| 172 |
+
3. Insert quantization observers (XNNPACKQuantizer, skipping upsampling + first 3 body blocks)
|
| 173 |
+
4. Calibrate with 100 Urban100 patches
|
| 174 |
+
5. Convert observers to Q/DQ pairs
|
| 175 |
+
6. Post-quantization graph surgery (remove spurious Q/DQ pairs from `cat` nodes in FP32 body blocks)
|
| 176 |
+
7. Export to ExecuTorch `.pte` with XNNPACK backend
|
| 177 |
+
|
| 178 |
+
### Preprocessing
|
| 179 |
+
|
| 180 |
+
| Property | Value |
|
| 181 |
+
|---|---|
|
| 182 |
+
| Input shape | `[1, 3, 128, 128]` (BCHW, single tile) |
|
| 183 |
+
| Data type | float32 |
|
| 184 |
+
| Value range | [0.0, 1.0] |
|
| 185 |
+
| Color space | RGB |
|
| 186 |
+
|
| 187 |
+
**Steps**:
|
| 188 |
+
1. Convert PIL image to float32 tensor via `ToTensor()` (maps [0, 255] → [0, 1])
|
| 189 |
+
2. For images larger than 128×128: split into overlapping 128×128 tiles with 8-pixel overlap; each tile is processed independently
|
| 190 |
+
|
| 191 |
+
**Normalization**: None required — the model expects raw [0, 1] pixel values.
|
| 192 |
+
|
| 193 |
+
### Postprocessing
|
| 194 |
+
|
| 195 |
+
| Property | Value |
|
| 196 |
+
|---|---|
|
| 197 |
+
| Output shape | `[1, 3, 512, 512]` per tile (4x upscaled) |
|
| 198 |
+
| Output format | Float32 RGB tensor, values may exceed [0, 1] before clamping |
|
| 199 |
+
|
| 200 |
+
**Steps**:
|
| 201 |
+
1. Clamp output tensor to [0, 1]
|
| 202 |
+
2. For tiled inputs: accumulate tile outputs into a full-resolution canvas, averaging overlapping regions
|
| 203 |
+
3. Convert to uint8 for saving (`* 255`, round, cast)
|
| 204 |
+
|
| 205 |
+
## Known Limitations
|
| 206 |
+
|
| 207 |
+
- Evaluated on 100 images from Urban100 — a benchmark focused on urban/architectural scenes; performance on natural landscapes or faces may differ
|
| 208 |
+
- Fixed tile size of 128×128: images must be at least 128×128; the tiling inference handles arbitrary sizes automatically
|
| 209 |
+
- Input images are not aspect-ratio padded — tiles are extracted at stride `tile_size - overlap` with edge tiles placed at the image boundary
|
| 210 |
+
- XNNPACK operator coverage is approximately 49%: upsampling, LeakyReLU, and some transpose operations fall back to non-XNNPACK kernels; latency figures reflect this mixed execution
|
benchmarks/esrgan-graviton-g4-fp32.yaml
ADDED
|
@@ -0,0 +1,35 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version: 1.0.0
|
| 2 |
+
report_type: image-to-image
|
| 3 |
+
profile: Baseline
|
| 4 |
+
created_at: '2026-07-09T19:02:52Z'
|
| 5 |
+
context:
|
| 6 |
+
target_ref: aws-graviton-g4-16-core
|
| 7 |
+
runtime:
|
| 8 |
+
name: executorch
|
| 9 |
+
execution_backend: cpu
|
| 10 |
+
config:
|
| 11 |
+
optimisations:
|
| 12 |
+
- XNNPACK
|
| 13 |
+
- KleidiAI
|
| 14 |
+
version: 1.1.0
|
| 15 |
+
dataset:
|
| 16 |
+
name: urban100
|
| 17 |
+
sample_count: 100
|
| 18 |
+
benchmark:
|
| 19 |
+
batch_size: 1
|
| 20 |
+
input_resolution: 128x128x3
|
| 21 |
+
num_runs: 100
|
| 22 |
+
warmup_runs: 10
|
| 23 |
+
performance:
|
| 24 |
+
end_to_end_latency_ms:
|
| 25 |
+
p50: 1762.73
|
| 26 |
+
p90: 1764.721
|
| 27 |
+
p99: 1771.111
|
| 28 |
+
model_load_time_ms: 66.291
|
| 29 |
+
time_to_first_inference_ms: 1968.651
|
| 30 |
+
peak_memory_mb: 799.74
|
| 31 |
+
average_memory_mb: 797.35
|
| 32 |
+
frames_per_second: 0.57
|
| 33 |
+
accuracy:
|
| 34 |
+
psnr_db: 27.03
|
| 35 |
+
ssim: 0.8176
|
benchmarks/esrgan-graviton-g4-int8.yaml
ADDED
|
@@ -0,0 +1,36 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version: 1.0.0
|
| 2 |
+
report_type: image-to-image
|
| 3 |
+
profile: Arm-Optimized
|
| 4 |
+
created_at: '2026-06-02T23:36:48Z'
|
| 5 |
+
context:
|
| 6 |
+
target_ref: aws-graviton-g4-16-core
|
| 7 |
+
runtime:
|
| 8 |
+
name: executorch
|
| 9 |
+
execution_backend: cpu
|
| 10 |
+
config:
|
| 11 |
+
optimisations:
|
| 12 |
+
- XNNPACK
|
| 13 |
+
- KleidiAI
|
| 14 |
+
version: 1.1.0
|
| 15 |
+
dataset:
|
| 16 |
+
name: urban100
|
| 17 |
+
sample_count: 100
|
| 18 |
+
benchmark:
|
| 19 |
+
batch_size: 1
|
| 20 |
+
input_resolution: 128x128x3
|
| 21 |
+
num_runs: 100
|
| 22 |
+
warmup_runs: 10
|
| 23 |
+
performance:
|
| 24 |
+
end_to_end_latency_ms:
|
| 25 |
+
p50: 704.416
|
| 26 |
+
p90: 779.704
|
| 27 |
+
p99: 819.723
|
| 28 |
+
model_load_time_ms: 36.666
|
| 29 |
+
time_to_first_inference_ms: 906.879
|
| 30 |
+
peak_memory_mb: 795.07
|
| 31 |
+
average_memory_mb: 754.93
|
| 32 |
+
frames_per_second: 1.42
|
| 33 |
+
delegation_pct: 97.62
|
| 34 |
+
accuracy:
|
| 35 |
+
psnr_db: 26.81
|
| 36 |
+
ssim: 0.8109
|
config.yaml
ADDED
|
@@ -0,0 +1,17 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
input:
|
| 2 |
+
shape: [1, 3, 128, 128]
|
| 3 |
+
dtype: float32
|
| 4 |
+
range: [0.0, 1.0]
|
| 5 |
+
color_space: RGB
|
| 6 |
+
preprocessing:
|
| 7 |
+
- to_tensor # PIL RGB -> [0, 1] float32 tensor
|
| 8 |
+
- tile_size: [128, 128] # model processes 128x128 tiles; larger images are tiled automatically
|
| 9 |
+
|
| 10 |
+
output:
|
| 11 |
+
shape: [1, 3, 512, 512] # 4x upscaled (128 * 4 = 512)
|
| 12 |
+
dtype: float32
|
| 13 |
+
range: [0.0, 1.0]
|
| 14 |
+
postprocessing:
|
| 15 |
+
- clamp: [0.0, 1.0] # raw output clamped to valid pixel range
|
| 16 |
+
- scale: 4 # spatial upscale factor
|
| 17 |
+
- tiling_overlap: 8 # pixel overlap between adjacent tiles (blended by averaging)
|
example.py
ADDED
|
@@ -0,0 +1,139 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Minimal inference example for ESRGAN 4x Super-Resolution using ExecuTorch.
|
| 2 |
+
|
| 3 |
+
Loads a quantized .pte model and runs super-resolution inference on a single image.
|
| 4 |
+
The model upscales the input image by 4x. For images larger than 128x128, the
|
| 5 |
+
input is automatically split into overlapping tiles, each tile is super-resolved,
|
| 6 |
+
and the results are blended and stitched into the final output.
|
| 7 |
+
"""
|
| 8 |
+
|
| 9 |
+
import json
|
| 10 |
+
from pathlib import Path
|
| 11 |
+
|
| 12 |
+
import numpy as np
|
| 13 |
+
import torch
|
| 14 |
+
from executorch.runtime import Runtime
|
| 15 |
+
from PIL import Image
|
| 16 |
+
from torchvision import transforms
|
| 17 |
+
|
| 18 |
+
# ── Configuration ──────────────────────────────────────────────────────────────
|
| 19 |
+
MODEL_PATH = "esrgan-x4-int8-executorch.pte"
|
| 20 |
+
IMAGE_PATH = "sample_input.jpg"
|
| 21 |
+
TILE_SIZE = 128 # model was exported with 128x128 input tiles
|
| 22 |
+
SCALE = 4 # 4x upscaling factor
|
| 23 |
+
TILE_OVERLAP = 8 # pixel overlap between tiles for seamless blending
|
| 24 |
+
|
| 25 |
+
|
| 26 |
+
# ── Model Loading ──────────────────────────────────────────────────────────────
|
| 27 |
+
def load_model(pte_path: str):
|
| 28 |
+
"""Load ExecuTorch .pte model and return the forward method."""
|
| 29 |
+
runtime = Runtime.get()
|
| 30 |
+
program = runtime.load_program(pte_path)
|
| 31 |
+
return program.load_method("forward")
|
| 32 |
+
|
| 33 |
+
|
| 34 |
+
# ── Preprocessing ──────────────────────────────────────────────────────────────
|
| 35 |
+
def preprocess(image_path: str) -> tuple[torch.Tensor, tuple[int, int]]:
|
| 36 |
+
"""Load and preprocess image for model input.
|
| 37 |
+
|
| 38 |
+
The model expects [0, 1] float32 RGB tensors — no normalization is applied.
|
| 39 |
+
Returns the input tensor and the original image size for reference.
|
| 40 |
+
"""
|
| 41 |
+
image = Image.open(image_path).convert("RGB")
|
| 42 |
+
original_size = (image.width, image.height)
|
| 43 |
+
to_tensor = transforms.ToTensor() # converts [0-255] uint8 -> [0, 1] float32
|
| 44 |
+
input_tensor = to_tensor(image).unsqueeze(0) # [1, 3, H, W]
|
| 45 |
+
return input_tensor, original_size
|
| 46 |
+
|
| 47 |
+
|
| 48 |
+
# ── Tiled Inference ────────────────────────────────────────────────────────────
|
| 49 |
+
def run_tiled_inference(method, input_tensor: torch.Tensor) -> torch.Tensor:
|
| 50 |
+
"""Run super-resolution inference with overlapping tile stitching.
|
| 51 |
+
|
| 52 |
+
Splits the input into overlapping 128x128 tiles, runs each through the
|
| 53 |
+
model, and blends overlapping regions using pixel-level averaging.
|
| 54 |
+
"""
|
| 55 |
+
_, _, h, w = input_tensor.shape
|
| 56 |
+
out_h, out_w = h * SCALE, w * SCALE
|
| 57 |
+
|
| 58 |
+
output = torch.zeros(1, 3, out_h, out_w)
|
| 59 |
+
weights = torch.zeros(1, 1, out_h, out_w)
|
| 60 |
+
|
| 61 |
+
stride = TILE_SIZE - TILE_OVERLAP
|
| 62 |
+
|
| 63 |
+
y_positions = list(range(0, max(1, h - TILE_SIZE + 1), stride))
|
| 64 |
+
if not y_positions or y_positions[-1] + TILE_SIZE < h:
|
| 65 |
+
y_positions.append(max(0, h - TILE_SIZE))
|
| 66 |
+
|
| 67 |
+
x_positions = list(range(0, max(1, w - TILE_SIZE + 1), stride))
|
| 68 |
+
if not x_positions or x_positions[-1] + TILE_SIZE < w:
|
| 69 |
+
x_positions.append(max(0, w - TILE_SIZE))
|
| 70 |
+
|
| 71 |
+
for y in y_positions:
|
| 72 |
+
for x in x_positions:
|
| 73 |
+
tile = input_tensor[:, :, y:y + TILE_SIZE, x:x + TILE_SIZE].contiguous()
|
| 74 |
+
sr_tile = method.execute([tile])[0]
|
| 75 |
+
|
| 76 |
+
oy, ox = y * SCALE, x * SCALE
|
| 77 |
+
oh, ow = TILE_SIZE * SCALE, TILE_SIZE * SCALE
|
| 78 |
+
output[:, :, oy:oy + oh, ox:ox + ow] += sr_tile
|
| 79 |
+
weights[:, :, oy:oy + oh, ox:ox + ow] += 1.0
|
| 80 |
+
|
| 81 |
+
return output / weights.clamp(min=1.0)
|
| 82 |
+
|
| 83 |
+
|
| 84 |
+
# ── Postprocessing ─────────────────────────────────────────────────────────────
|
| 85 |
+
def postprocess(raw_output: torch.Tensor) -> np.ndarray:
|
| 86 |
+
"""Clamp output to [0, 1] and convert to uint8 numpy array (H, W, 3)."""
|
| 87 |
+
sr_tensor = raw_output.clamp(0.0, 1.0).squeeze(0) # [3, H*4, W*4]
|
| 88 |
+
sr_array = (sr_tensor.permute(1, 2, 0).numpy() * 255.0).round().astype(np.uint8)
|
| 89 |
+
return sr_array
|
| 90 |
+
|
| 91 |
+
|
| 92 |
+
# ── Save Results ──────────────────────────────────────────────────────────────
|
| 93 |
+
def save_results(sr_array: np.ndarray, original_size: tuple[int, int]) -> None:
|
| 94 |
+
"""Save the super-resolved image and a JSON summary to the script directory."""
|
| 95 |
+
script_dir = Path(__file__).parent
|
| 96 |
+
|
| 97 |
+
# Save super-resolved image
|
| 98 |
+
output_image = Image.fromarray(sr_array)
|
| 99 |
+
output_path = script_dir / "sample_output.png"
|
| 100 |
+
output_image.save(output_path)
|
| 101 |
+
print(f"Super-resolved image saved to: {output_path}")
|
| 102 |
+
|
| 103 |
+
# Save JSON summary
|
| 104 |
+
summary = {
|
| 105 |
+
"input_size": {"width": original_size[0], "height": original_size[1]},
|
| 106 |
+
"output_size": {"width": sr_array.shape[1], "height": sr_array.shape[0]},
|
| 107 |
+
"scale_factor": SCALE,
|
| 108 |
+
}
|
| 109 |
+
json_path = script_dir / "super_resolution.json"
|
| 110 |
+
with open(json_path, "w") as f:
|
| 111 |
+
json.dump(summary, f, indent=2)
|
| 112 |
+
print(f"Summary saved to: {json_path}")
|
| 113 |
+
|
| 114 |
+
|
| 115 |
+
# ── Main ───────────────────────────────────────────────────────────────────────
|
| 116 |
+
def main():
|
| 117 |
+
script_dir = Path(__file__).parent
|
| 118 |
+
model_path = script_dir / MODEL_PATH
|
| 119 |
+
image_path = script_dir / IMAGE_PATH
|
| 120 |
+
|
| 121 |
+
print(f"Loading model from: {model_path}")
|
| 122 |
+
method = load_model(str(model_path))
|
| 123 |
+
|
| 124 |
+
print(f"Preprocessing image: {image_path}")
|
| 125 |
+
input_tensor, original_size = preprocess(str(image_path))
|
| 126 |
+
_, _, h, w = input_tensor.shape
|
| 127 |
+
print(f" Input size: {w}x{h} -> output will be {w * SCALE}x{h * SCALE}")
|
| 128 |
+
|
| 129 |
+
print("Running tiled super-resolution inference...")
|
| 130 |
+
raw_output = run_tiled_inference(method, input_tensor)
|
| 131 |
+
|
| 132 |
+
sr_array = postprocess(raw_output)
|
| 133 |
+
print(f" Output shape: {sr_array.shape[1]}x{sr_array.shape[0]} (WxH)")
|
| 134 |
+
|
| 135 |
+
save_results(sr_array, original_size)
|
| 136 |
+
|
| 137 |
+
|
| 138 |
+
if __name__ == "__main__":
|
| 139 |
+
main()
|
metadata.yaml
ADDED
|
@@ -0,0 +1,23 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
schema_version: 1.0.0
|
| 2 |
+
report_type: image-to-image
|
| 3 |
+
task_type: image-to-image
|
| 4 |
+
title: ESRGAN x4 INT8 — ExecuTorch + XNNPACK
|
| 5 |
+
id: Arm/esrgan-int8-xnnpack-executorch-graviton-g4
|
| 6 |
+
filename: esrgan-x4-int8-executorch.pte
|
| 7 |
+
base_model_id: kadirnar/RRDB_PSNR_x4
|
| 8 |
+
profile: Arm-Optimized
|
| 9 |
+
weight_dtype: int8
|
| 10 |
+
model_size_mb: 23.176
|
| 11 |
+
parameter_count: 16697987
|
| 12 |
+
format: pte
|
| 13 |
+
quantization:
|
| 14 |
+
method: PTQ-static
|
| 15 |
+
weight_bits: 8
|
| 16 |
+
activation_bits: 8
|
| 17 |
+
symmetric: true
|
| 18 |
+
mode: static
|
| 19 |
+
weight_granularity: per-channel
|
| 20 |
+
calibration:
|
| 21 |
+
dataset_name: urban100
|
| 22 |
+
sample_count: 100
|
| 23 |
+
selection: random
|
sample_input.jpg
ADDED
|
sample_output.png
ADDED
|
Git LFS Details
|
super_resolution.json
ADDED
|
@@ -0,0 +1,11 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"input_size": {
|
| 3 |
+
"width": 256,
|
| 4 |
+
"height": 161
|
| 5 |
+
},
|
| 6 |
+
"output_size": {
|
| 7 |
+
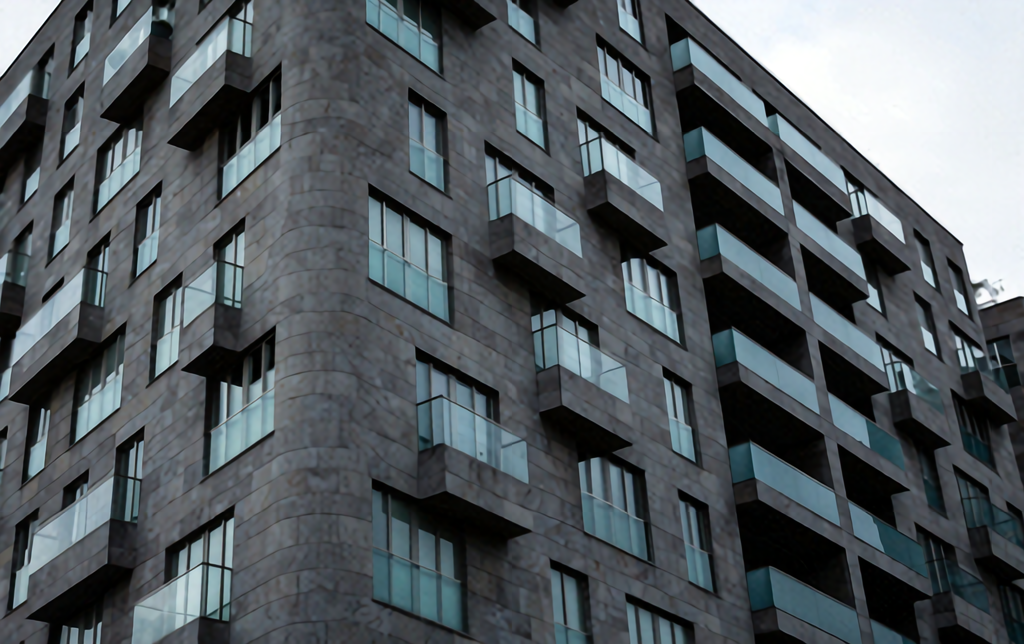
"width": 1024,
|
| 8 |
+
"height": 644
|
| 9 |
+
},
|
| 10 |
+
"scale_factor": 4
|
| 11 |
+
}
|