

Upload folder using huggingface_hub
Browse files- .gitattributes +2 -0
- README.md +118 -0
- checkpoint/added_tokens.json +30 -0
- checkpoint/chat_template.jinja +54 -0
- checkpoint/config.json +40 -0
- checkpoint/generation_config.json +5 -0
- checkpoint/merges.txt +0 -0
- checkpoint/model.safetensors +3 -0
- checkpoint/special_tokens_map.json +60 -0
- checkpoint/tokenizer.json +3 -0
- checkpoint/tokenizer_config.json +248 -0
- checkpoint/vocab.json +0 -0
- inference.py +73 -0
- inference_smolagent.py +347 -0
- training_plot.png +3 -0
.gitattributes
CHANGED
|
@@ -33,3 +33,5 @@ saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
checkpoint/tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
| 37 |
+
training_plot.png filter=lfs diff=lfs merge=lfs -text
|
README.md
ADDED
|
@@ -0,0 +1,118 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: apache-2.0
|
| 3 |
+
language:
|
| 4 |
+
- en
|
| 5 |
+
library_name: transformers
|
| 6 |
+
tags:
|
| 7 |
+
- smolagents
|
| 8 |
+
- code-generation
|
| 9 |
+
- qwen2
|
| 10 |
+
- text-generation
|
| 11 |
+
pipeline_tag: text-generation
|
| 12 |
+
base_model: Qwen/Qwen2.5-0.5B
|
| 13 |
+
---
|
| 14 |
+
|
| 15 |
+
# pynb-73m-base
|
| 16 |
+
|
| 17 |
+
A 73M parameter language model trained for code generation with [smolagents](https://github.com/huggingface/smolagents). Built on the Qwen2 architecture.
|
| 18 |
+
|
| 19 |
+
## Model Details
|
| 20 |
+
|
| 21 |
+
| Property | Value |
|
| 22 |
+
|----------|-------|
|
| 23 |
+
| Parameters | 73.6M |
|
| 24 |
+
| Architecture | Qwen2ForCausalLM |
|
| 25 |
+
| Hidden size | 384 |
|
| 26 |
+
| Layers | 12 |
|
| 27 |
+
| Attention heads | 6 (2 KV heads, GQA 3:1) |
|
| 28 |
+
| Intermediate size | 768 |
|
| 29 |
+
| Context length | 2048 |
|
| 30 |
+
| Vocab size | 151,671 |
|
| 31 |
+
|
| 32 |
+
## Training
|
| 33 |
+
|
| 34 |
+
Trained for 15,500 steps (~12 hours) on a single NVIDIA RTX 5070 Ti.
|
| 35 |
+
|
| 36 |
+

|
| 37 |
+
|
| 38 |
+
| Metric | Start | End |
|
| 39 |
+
|--------|-------|-----|
|
| 40 |
+
| Train Loss | 287.8 | 53.4 |
|
| 41 |
+
| Val Loss | 6.48 | 2.65 |
|
| 42 |
+
|
| 43 |
+
## Quick Start with smolagents
|
| 44 |
+
|
| 45 |
+
See [`inference_smolagent.py`](inference_smolagent.py) for full agent setup with LocalPythonExecutor and tools.
|
| 46 |
+
|
| 47 |
+
```python
|
| 48 |
+
from inference_smolagent import create_agent, CalculatorTool, FibonacciTool
|
| 49 |
+
|
| 50 |
+
agent = create_agent(
|
| 51 |
+
model_id="AutomatedScientist/pynb-73m-base",
|
| 52 |
+
tools=[CalculatorTool(), FibonacciTool()],
|
| 53 |
+
max_steps=5,
|
| 54 |
+
)
|
| 55 |
+
|
| 56 |
+
result = agent.run("Calculate 15 * 7 + 23")
|
| 57 |
+
print(result)
|
| 58 |
+
```
|
| 59 |
+
|
| 60 |
+
Or with HuggingFace API model:
|
| 61 |
+
|
| 62 |
+
```python
|
| 63 |
+
from smolagents import CodeAgent, HfApiModel
|
| 64 |
+
|
| 65 |
+
model = HfApiModel(model_id="AutomatedScientist/pynb-73m-base")
|
| 66 |
+
agent = CodeAgent(tools=[], model=model)
|
| 67 |
+
|
| 68 |
+
result = agent.run("Calculate the sum of numbers from 1 to 100")
|
| 69 |
+
print(result)
|
| 70 |
+
```
|
| 71 |
+
|
| 72 |
+
## Local Inference
|
| 73 |
+
|
| 74 |
+
```python
|
| 75 |
+
import torch
|
| 76 |
+
from transformers import AutoModelForCausalLM, AutoTokenizer
|
| 77 |
+
|
| 78 |
+
model_id = "AutomatedScientist/pynb-73m-base" # or "checkpoint" for local
|
| 79 |
+
tokenizer = AutoTokenizer.from_pretrained(model_id)
|
| 80 |
+
model = AutoModelForCausalLM.from_pretrained(
|
| 81 |
+
model_id,
|
| 82 |
+
torch_dtype=torch.bfloat16,
|
| 83 |
+
device_map="auto"
|
| 84 |
+
)
|
| 85 |
+
|
| 86 |
+
prompt = "Write a function to calculate fibonacci numbers"
|
| 87 |
+
inputs = tokenizer(prompt, return_tensors="pt").to(model.device)
|
| 88 |
+
outputs = model.generate(**inputs, max_new_tokens=256, do_sample=True, temperature=0.7)
|
| 89 |
+
print(tokenizer.decode(outputs[0], skip_special_tokens=False))
|
| 90 |
+
```
|
| 91 |
+
|
| 92 |
+
## Inference Script
|
| 93 |
+
|
| 94 |
+
See [`inference.py`](inference.py) for a wrapper class:
|
| 95 |
+
|
| 96 |
+
```python
|
| 97 |
+
from inference import CodeModel
|
| 98 |
+
|
| 99 |
+
model = CodeModel("AutomatedScientist/pynb-73m-base")
|
| 100 |
+
result = model.generate("Write a function to sort a list")
|
| 101 |
+
print(result)
|
| 102 |
+
```
|
| 103 |
+
|
| 104 |
+
## Installation
|
| 105 |
+
|
| 106 |
+
```bash
|
| 107 |
+
pip install torch transformers smolagents
|
| 108 |
+
```
|
| 109 |
+
|
| 110 |
+
## Limitations
|
| 111 |
+
|
| 112 |
+
- Small model (73M params) - limited reasoning capacity compared to larger models
|
| 113 |
+
- Context window limited to 2,048 tokens
|
| 114 |
+
- Best used with short prompts due to context constraints
|
| 115 |
+
|
| 116 |
+
## License
|
| 117 |
+
|
| 118 |
+
Apache 2.0
|
checkpoint/added_tokens.json
ADDED
|
@@ -0,0 +1,30 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"</tool_call>": 151658,
|
| 3 |
+
"<tool_call>": 151657,
|
| 4 |
+
"<|box_end|>": 151649,
|
| 5 |
+
"<|box_start|>": 151648,
|
| 6 |
+
"<|end_record_state|>": 151670,
|
| 7 |
+
"<|end_tool_call|>": 151666,
|
| 8 |
+
"<|end_tool_response|>": 151668,
|
| 9 |
+
"<|endoftext|>": 151643,
|
| 10 |
+
"<|file_sep|>": 151664,
|
| 11 |
+
"<|fim_middle|>": 151660,
|
| 12 |
+
"<|fim_pad|>": 151662,
|
| 13 |
+
"<|fim_prefix|>": 151659,
|
| 14 |
+
"<|fim_suffix|>": 151661,
|
| 15 |
+
"<|im_end|>": 151645,
|
| 16 |
+
"<|im_start|>": 151644,
|
| 17 |
+
"<|image_pad|>": 151655,
|
| 18 |
+
"<|object_ref_end|>": 151647,
|
| 19 |
+
"<|object_ref_start|>": 151646,
|
| 20 |
+
"<|quad_end|>": 151651,
|
| 21 |
+
"<|quad_start|>": 151650,
|
| 22 |
+
"<|repo_name|>": 151663,
|
| 23 |
+
"<|start_record_state|>": 151669,
|
| 24 |
+
"<|start_tool_call|>": 151665,
|
| 25 |
+
"<|start_tool_response|>": 151667,
|
| 26 |
+
"<|video_pad|>": 151656,
|
| 27 |
+
"<|vision_end|>": 151653,
|
| 28 |
+
"<|vision_pad|>": 151654,
|
| 29 |
+
"<|vision_start|>": 151652
|
| 30 |
+
}
|
checkpoint/chat_template.jinja
ADDED
|
@@ -0,0 +1,54 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{%- if tools %}
|
| 2 |
+
{{- '<|im_start|>system\n' }}
|
| 3 |
+
{%- if messages[0]['role'] == 'system' %}
|
| 4 |
+
{{- messages[0]['content'] }}
|
| 5 |
+
{%- else %}
|
| 6 |
+
{{- 'You are a helpful assistant.' }}
|
| 7 |
+
{%- endif %}
|
| 8 |
+
{{- "\n\n# Tools\n\nYou may call one or more functions to assist with the user query.\n\nYou are provided with function signatures within <tools></tools> XML tags:\n<tools>" }}
|
| 9 |
+
{%- for tool in tools %}
|
| 10 |
+
{{- "\n" }}
|
| 11 |
+
{{- tool | tojson }}
|
| 12 |
+
{%- endfor %}
|
| 13 |
+
{{- "\n</tools>\n\nFor each function call, return a json object with function name and arguments within <tool_call></tool_call> XML tags:\n<tool_call>\n{\"name\": <function-name>, \"arguments\": <args-json-object>}\n</tool_call><|im_end|>\n" }}
|
| 14 |
+
{%- else %}
|
| 15 |
+
{%- if messages[0]['role'] == 'system' %}
|
| 16 |
+
{{- '<|im_start|>system\n' + messages[0]['content'] + '<|im_end|>\n' }}
|
| 17 |
+
{%- else %}
|
| 18 |
+
{{- '<|im_start|>system\nYou are a helpful assistant.<|im_end|>\n' }}
|
| 19 |
+
{%- endif %}
|
| 20 |
+
{%- endif %}
|
| 21 |
+
{%- for message in messages %}
|
| 22 |
+
{%- if (message.role == "user") or (message.role == "system" and not loop.first) or (message.role == "assistant" and not message.tool_calls) %}
|
| 23 |
+
{{- '<|im_start|>' + message.role + '\n' + message.content + '<|im_end|>' + '\n' }}
|
| 24 |
+
{%- elif message.role == "assistant" %}
|
| 25 |
+
{{- '<|im_start|>' + message.role }}
|
| 26 |
+
{%- if message.content %}
|
| 27 |
+
{{- '\n' + message.content }}
|
| 28 |
+
{%- endif %}
|
| 29 |
+
{%- for tool_call in message.tool_calls %}
|
| 30 |
+
{%- if tool_call.function is defined %}
|
| 31 |
+
{%- set tool_call = tool_call.function %}
|
| 32 |
+
{%- endif %}
|
| 33 |
+
{{- '\n<tool_call>\n{"name": "' }}
|
| 34 |
+
{{- tool_call.name }}
|
| 35 |
+
{{- '", "arguments": ' }}
|
| 36 |
+
{{- tool_call.arguments | tojson }}
|
| 37 |
+
{{- '}\n</tool_call>' }}
|
| 38 |
+
{%- endfor %}
|
| 39 |
+
{{- '<|im_end|>\n' }}
|
| 40 |
+
{%- elif message.role == "tool" %}
|
| 41 |
+
{%- if (loop.index0 == 0) or (messages[loop.index0 - 1].role != "tool") %}
|
| 42 |
+
{{- '<|im_start|>user' }}
|
| 43 |
+
{%- endif %}
|
| 44 |
+
{{- '\n<tool_response>\n' }}
|
| 45 |
+
{{- message.content }}
|
| 46 |
+
{{- '\n</tool_response>' }}
|
| 47 |
+
{%- if loop.last or (messages[loop.index0 + 1].role != "tool") %}
|
| 48 |
+
{{- '<|im_end|>\n' }}
|
| 49 |
+
{%- endif %}
|
| 50 |
+
{%- endif %}
|
| 51 |
+
{%- endfor %}
|
| 52 |
+
{%- if add_generation_prompt %}
|
| 53 |
+
{{- '<|im_start|>assistant\n' }}
|
| 54 |
+
{%- endif %}
|
checkpoint/config.json
ADDED
|
@@ -0,0 +1,40 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"architectures": [
|
| 3 |
+
"Qwen2ForCausalLM"
|
| 4 |
+
],
|
| 5 |
+
"attention_dropout": 0.0,
|
| 6 |
+
"dtype": "float32",
|
| 7 |
+
"hidden_act": "silu",
|
| 8 |
+
"hidden_size": 384,
|
| 9 |
+
"initializer_range": 0.02,
|
| 10 |
+
"intermediate_size": 768,
|
| 11 |
+
"layer_types": [
|
| 12 |
+
"full_attention",
|
| 13 |
+
"full_attention",
|
| 14 |
+
"full_attention",
|
| 15 |
+
"full_attention",
|
| 16 |
+
"full_attention",
|
| 17 |
+
"full_attention",
|
| 18 |
+
"full_attention",
|
| 19 |
+
"full_attention",
|
| 20 |
+
"full_attention",
|
| 21 |
+
"full_attention",
|
| 22 |
+
"full_attention",
|
| 23 |
+
"full_attention"
|
| 24 |
+
],
|
| 25 |
+
"max_position_embeddings": 2048,
|
| 26 |
+
"max_window_layers": 28,
|
| 27 |
+
"model_type": "qwen2",
|
| 28 |
+
"num_attention_heads": 6,
|
| 29 |
+
"num_hidden_layers": 12,
|
| 30 |
+
"num_key_value_heads": 2,
|
| 31 |
+
"rms_norm_eps": 1e-06,
|
| 32 |
+
"rope_scaling": null,
|
| 33 |
+
"rope_theta": 10000.0,
|
| 34 |
+
"sliding_window": null,
|
| 35 |
+
"tie_word_embeddings": true,
|
| 36 |
+
"transformers_version": "4.57.3",
|
| 37 |
+
"use_cache": false,
|
| 38 |
+
"use_sliding_window": false,
|
| 39 |
+
"vocab_size": 151671
|
| 40 |
+
}
|
checkpoint/generation_config.json
ADDED
|
@@ -0,0 +1,5 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"_from_model_config": true,
|
| 3 |
+
"transformers_version": "4.57.3",
|
| 4 |
+
"use_cache": false
|
| 5 |
+
}
|
checkpoint/merges.txt
ADDED
|
The diff for this file is too large to render.
See raw diff
|
|
|
checkpoint/model.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:7c0f3750bf2a02e3450c09ce290922aecd910c7c43ecf18bac133c1b4f2228ae
|
| 3 |
+
size 294393488
|
checkpoint/special_tokens_map.json
ADDED
|
@@ -0,0 +1,60 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"additional_special_tokens": [
|
| 3 |
+
{
|
| 4 |
+
"content": "<|start_tool_call|>",
|
| 5 |
+
"lstrip": false,
|
| 6 |
+
"normalized": false,
|
| 7 |
+
"rstrip": false,
|
| 8 |
+
"single_word": false
|
| 9 |
+
},
|
| 10 |
+
{
|
| 11 |
+
"content": "<|end_tool_call|>",
|
| 12 |
+
"lstrip": false,
|
| 13 |
+
"normalized": false,
|
| 14 |
+
"rstrip": false,
|
| 15 |
+
"single_word": false
|
| 16 |
+
},
|
| 17 |
+
{
|
| 18 |
+
"content": "<|start_tool_response|>",
|
| 19 |
+
"lstrip": false,
|
| 20 |
+
"normalized": false,
|
| 21 |
+
"rstrip": false,
|
| 22 |
+
"single_word": false
|
| 23 |
+
},
|
| 24 |
+
{
|
| 25 |
+
"content": "<|end_tool_response|>",
|
| 26 |
+
"lstrip": false,
|
| 27 |
+
"normalized": false,
|
| 28 |
+
"rstrip": false,
|
| 29 |
+
"single_word": false
|
| 30 |
+
},
|
| 31 |
+
{
|
| 32 |
+
"content": "<|start_record_state|>",
|
| 33 |
+
"lstrip": false,
|
| 34 |
+
"normalized": false,
|
| 35 |
+
"rstrip": false,
|
| 36 |
+
"single_word": false
|
| 37 |
+
},
|
| 38 |
+
{
|
| 39 |
+
"content": "<|end_record_state|>",
|
| 40 |
+
"lstrip": false,
|
| 41 |
+
"normalized": false,
|
| 42 |
+
"rstrip": false,
|
| 43 |
+
"single_word": false
|
| 44 |
+
}
|
| 45 |
+
],
|
| 46 |
+
"eos_token": {
|
| 47 |
+
"content": "<|endoftext|>",
|
| 48 |
+
"lstrip": false,
|
| 49 |
+
"normalized": false,
|
| 50 |
+
"rstrip": false,
|
| 51 |
+
"single_word": false
|
| 52 |
+
},
|
| 53 |
+
"pad_token": {
|
| 54 |
+
"content": "<|endoftext|>",
|
| 55 |
+
"lstrip": false,
|
| 56 |
+
"normalized": false,
|
| 57 |
+
"rstrip": false,
|
| 58 |
+
"single_word": false
|
| 59 |
+
}
|
| 60 |
+
}
|
checkpoint/tokenizer.json
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:0d508f3b5f4640a6623351b2a1e39389b41711492de2b19e6ad408461a89de0f
|
| 3 |
+
size 11423080
|
checkpoint/tokenizer_config.json
ADDED
|
@@ -0,0 +1,248 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"add_bos_token": false,
|
| 3 |
+
"add_prefix_space": false,
|
| 4 |
+
"added_tokens_decoder": {
|
| 5 |
+
"151643": {
|
| 6 |
+
"content": "<|endoftext|>",
|
| 7 |
+
"lstrip": false,
|
| 8 |
+
"normalized": false,
|
| 9 |
+
"rstrip": false,
|
| 10 |
+
"single_word": false,
|
| 11 |
+
"special": true
|
| 12 |
+
},
|
| 13 |
+
"151644": {
|
| 14 |
+
"content": "<|im_start|>",
|
| 15 |
+
"lstrip": false,
|
| 16 |
+
"normalized": false,
|
| 17 |
+
"rstrip": false,
|
| 18 |
+
"single_word": false,
|
| 19 |
+
"special": true
|
| 20 |
+
},
|
| 21 |
+
"151645": {
|
| 22 |
+
"content": "<|im_end|>",
|
| 23 |
+
"lstrip": false,
|
| 24 |
+
"normalized": false,
|
| 25 |
+
"rstrip": false,
|
| 26 |
+
"single_word": false,
|
| 27 |
+
"special": true
|
| 28 |
+
},
|
| 29 |
+
"151646": {
|
| 30 |
+
"content": "<|object_ref_start|>",
|
| 31 |
+
"lstrip": false,
|
| 32 |
+
"normalized": false,
|
| 33 |
+
"rstrip": false,
|
| 34 |
+
"single_word": false,
|
| 35 |
+
"special": true
|
| 36 |
+
},
|
| 37 |
+
"151647": {
|
| 38 |
+
"content": "<|object_ref_end|>",
|
| 39 |
+
"lstrip": false,
|
| 40 |
+
"normalized": false,
|
| 41 |
+
"rstrip": false,
|
| 42 |
+
"single_word": false,
|
| 43 |
+
"special": true
|
| 44 |
+
},
|
| 45 |
+
"151648": {
|
| 46 |
+
"content": "<|box_start|>",
|
| 47 |
+
"lstrip": false,
|
| 48 |
+
"normalized": false,
|
| 49 |
+
"rstrip": false,
|
| 50 |
+
"single_word": false,
|
| 51 |
+
"special": true
|
| 52 |
+
},
|
| 53 |
+
"151649": {
|
| 54 |
+
"content": "<|box_end|>",
|
| 55 |
+
"lstrip": false,
|
| 56 |
+
"normalized": false,
|
| 57 |
+
"rstrip": false,
|
| 58 |
+
"single_word": false,
|
| 59 |
+
"special": true
|
| 60 |
+
},
|
| 61 |
+
"151650": {
|
| 62 |
+
"content": "<|quad_start|>",
|
| 63 |
+
"lstrip": false,
|
| 64 |
+
"normalized": false,
|
| 65 |
+
"rstrip": false,
|
| 66 |
+
"single_word": false,
|
| 67 |
+
"special": true
|
| 68 |
+
},
|
| 69 |
+
"151651": {
|
| 70 |
+
"content": "<|quad_end|>",
|
| 71 |
+
"lstrip": false,
|
| 72 |
+
"normalized": false,
|
| 73 |
+
"rstrip": false,
|
| 74 |
+
"single_word": false,
|
| 75 |
+
"special": true
|
| 76 |
+
},
|
| 77 |
+
"151652": {
|
| 78 |
+
"content": "<|vision_start|>",
|
| 79 |
+
"lstrip": false,
|
| 80 |
+
"normalized": false,
|
| 81 |
+
"rstrip": false,
|
| 82 |
+
"single_word": false,
|
| 83 |
+
"special": true
|
| 84 |
+
},
|
| 85 |
+
"151653": {
|
| 86 |
+
"content": "<|vision_end|>",
|
| 87 |
+
"lstrip": false,
|
| 88 |
+
"normalized": false,
|
| 89 |
+
"rstrip": false,
|
| 90 |
+
"single_word": false,
|
| 91 |
+
"special": true
|
| 92 |
+
},
|
| 93 |
+
"151654": {
|
| 94 |
+
"content": "<|vision_pad|>",
|
| 95 |
+
"lstrip": false,
|
| 96 |
+
"normalized": false,
|
| 97 |
+
"rstrip": false,
|
| 98 |
+
"single_word": false,
|
| 99 |
+
"special": true
|
| 100 |
+
},
|
| 101 |
+
"151655": {
|
| 102 |
+
"content": "<|image_pad|>",
|
| 103 |
+
"lstrip": false,
|
| 104 |
+
"normalized": false,
|
| 105 |
+
"rstrip": false,
|
| 106 |
+
"single_word": false,
|
| 107 |
+
"special": true
|
| 108 |
+
},
|
| 109 |
+
"151656": {
|
| 110 |
+
"content": "<|video_pad|>",
|
| 111 |
+
"lstrip": false,
|
| 112 |
+
"normalized": false,
|
| 113 |
+
"rstrip": false,
|
| 114 |
+
"single_word": false,
|
| 115 |
+
"special": true
|
| 116 |
+
},
|
| 117 |
+
"151657": {
|
| 118 |
+
"content": "<tool_call>",
|
| 119 |
+
"lstrip": false,
|
| 120 |
+
"normalized": false,
|
| 121 |
+
"rstrip": false,
|
| 122 |
+
"single_word": false,
|
| 123 |
+
"special": false
|
| 124 |
+
},
|
| 125 |
+
"151658": {
|
| 126 |
+
"content": "</tool_call>",
|
| 127 |
+
"lstrip": false,
|
| 128 |
+
"normalized": false,
|
| 129 |
+
"rstrip": false,
|
| 130 |
+
"single_word": false,
|
| 131 |
+
"special": false
|
| 132 |
+
},
|
| 133 |
+
"151659": {
|
| 134 |
+
"content": "<|fim_prefix|>",
|
| 135 |
+
"lstrip": false,
|
| 136 |
+
"normalized": false,
|
| 137 |
+
"rstrip": false,
|
| 138 |
+
"single_word": false,
|
| 139 |
+
"special": false
|
| 140 |
+
},
|
| 141 |
+
"151660": {
|
| 142 |
+
"content": "<|fim_middle|>",
|
| 143 |
+
"lstrip": false,
|
| 144 |
+
"normalized": false,
|
| 145 |
+
"rstrip": false,
|
| 146 |
+
"single_word": false,
|
| 147 |
+
"special": false
|
| 148 |
+
},
|
| 149 |
+
"151661": {
|
| 150 |
+
"content": "<|fim_suffix|>",
|
| 151 |
+
"lstrip": false,
|
| 152 |
+
"normalized": false,
|
| 153 |
+
"rstrip": false,
|
| 154 |
+
"single_word": false,
|
| 155 |
+
"special": false
|
| 156 |
+
},
|
| 157 |
+
"151662": {
|
| 158 |
+
"content": "<|fim_pad|>",
|
| 159 |
+
"lstrip": false,
|
| 160 |
+
"normalized": false,
|
| 161 |
+
"rstrip": false,
|
| 162 |
+
"single_word": false,
|
| 163 |
+
"special": false
|
| 164 |
+
},
|
| 165 |
+
"151663": {
|
| 166 |
+
"content": "<|repo_name|>",
|
| 167 |
+
"lstrip": false,
|
| 168 |
+
"normalized": false,
|
| 169 |
+
"rstrip": false,
|
| 170 |
+
"single_word": false,
|
| 171 |
+
"special": false
|
| 172 |
+
},
|
| 173 |
+
"151664": {
|
| 174 |
+
"content": "<|file_sep|>",
|
| 175 |
+
"lstrip": false,
|
| 176 |
+
"normalized": false,
|
| 177 |
+
"rstrip": false,
|
| 178 |
+
"single_word": false,
|
| 179 |
+
"special": false
|
| 180 |
+
},
|
| 181 |
+
"151665": {
|
| 182 |
+
"content": "<|start_tool_call|>",
|
| 183 |
+
"lstrip": false,
|
| 184 |
+
"normalized": false,
|
| 185 |
+
"rstrip": false,
|
| 186 |
+
"single_word": false,
|
| 187 |
+
"special": true
|
| 188 |
+
},
|
| 189 |
+
"151666": {
|
| 190 |
+
"content": "<|end_tool_call|>",
|
| 191 |
+
"lstrip": false,
|
| 192 |
+
"normalized": false,
|
| 193 |
+
"rstrip": false,
|
| 194 |
+
"single_word": false,
|
| 195 |
+
"special": true
|
| 196 |
+
},
|
| 197 |
+
"151667": {
|
| 198 |
+
"content": "<|start_tool_response|>",
|
| 199 |
+
"lstrip": false,
|
| 200 |
+
"normalized": false,
|
| 201 |
+
"rstrip": false,
|
| 202 |
+
"single_word": false,
|
| 203 |
+
"special": true
|
| 204 |
+
},
|
| 205 |
+
"151668": {
|
| 206 |
+
"content": "<|end_tool_response|>",
|
| 207 |
+
"lstrip": false,
|
| 208 |
+
"normalized": false,
|
| 209 |
+
"rstrip": false,
|
| 210 |
+
"single_word": false,
|
| 211 |
+
"special": true
|
| 212 |
+
},
|
| 213 |
+
"151669": {
|
| 214 |
+
"content": "<|start_record_state|>",
|
| 215 |
+
"lstrip": false,
|
| 216 |
+
"normalized": false,
|
| 217 |
+
"rstrip": false,
|
| 218 |
+
"single_word": false,
|
| 219 |
+
"special": true
|
| 220 |
+
},
|
| 221 |
+
"151670": {
|
| 222 |
+
"content": "<|end_record_state|>",
|
| 223 |
+
"lstrip": false,
|
| 224 |
+
"normalized": false,
|
| 225 |
+
"rstrip": false,
|
| 226 |
+
"single_word": false,
|
| 227 |
+
"special": true
|
| 228 |
+
}
|
| 229 |
+
},
|
| 230 |
+
"additional_special_tokens": [
|
| 231 |
+
"<|start_tool_call|>",
|
| 232 |
+
"<|end_tool_call|>",
|
| 233 |
+
"<|start_tool_response|>",
|
| 234 |
+
"<|end_tool_response|>",
|
| 235 |
+
"<|start_record_state|>",
|
| 236 |
+
"<|end_record_state|>"
|
| 237 |
+
],
|
| 238 |
+
"bos_token": null,
|
| 239 |
+
"clean_up_tokenization_spaces": false,
|
| 240 |
+
"eos_token": "<|endoftext|>",
|
| 241 |
+
"errors": "replace",
|
| 242 |
+
"extra_special_tokens": {},
|
| 243 |
+
"model_max_length": 131072,
|
| 244 |
+
"pad_token": "<|endoftext|>",
|
| 245 |
+
"split_special_tokens": false,
|
| 246 |
+
"tokenizer_class": "Qwen2Tokenizer",
|
| 247 |
+
"unk_token": null
|
| 248 |
+
}
|
checkpoint/vocab.json
ADDED
|
The diff for this file is too large to render.
See raw diff
|
|
|
inference.py
ADDED
|
@@ -0,0 +1,73 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""inference.py - Code generation model wrapper for smolagents"""
|
| 2 |
+
import torch
|
| 3 |
+
from transformers import AutoModelForCausalLM, AutoTokenizer
|
| 4 |
+
|
| 5 |
+
|
| 6 |
+
class CodeModel:
|
| 7 |
+
def __init__(self, model_id: str, device: str = None):
|
| 8 |
+
self.device = device or ("cuda" if torch.cuda.is_available() else "cpu")
|
| 9 |
+
self.tokenizer = AutoTokenizer.from_pretrained(model_id, fix_mistral_regex=True)
|
| 10 |
+
dtype = torch.bfloat16 if self.device == "cuda" else torch.float32
|
| 11 |
+
self.model = AutoModelForCausalLM.from_pretrained(model_id).to(self.device, dtype=dtype)
|
| 12 |
+
self.model.eval()
|
| 13 |
+
|
| 14 |
+
def generate(self, prompt: str, max_new_tokens: int = 512, temperature: float = 0.7) -> str:
|
| 15 |
+
inputs = self.tokenizer(prompt, return_tensors="pt").to(self.device)
|
| 16 |
+
|
| 17 |
+
with torch.no_grad():
|
| 18 |
+
outputs = self.model.generate(
|
| 19 |
+
**inputs,
|
| 20 |
+
max_new_tokens=max_new_tokens,
|
| 21 |
+
temperature=temperature,
|
| 22 |
+
do_sample=True,
|
| 23 |
+
top_p=0.9,
|
| 24 |
+
repetition_penalty=1.2,
|
| 25 |
+
pad_token_id=self.tokenizer.pad_token_id,
|
| 26 |
+
eos_token_id=self.tokenizer.eos_token_id,
|
| 27 |
+
)
|
| 28 |
+
|
| 29 |
+
new_tokens = outputs[0, inputs["input_ids"].shape[1]:]
|
| 30 |
+
return self.tokenizer.decode(new_tokens, skip_special_tokens=False)
|
| 31 |
+
|
| 32 |
+
def chat(self, messages: list[dict], max_new_tokens: int = 256) -> str:
|
| 33 |
+
"""Generate response using chat template."""
|
| 34 |
+
text = self.tokenizer.apply_chat_template(
|
| 35 |
+
messages,
|
| 36 |
+
add_generation_prompt=True,
|
| 37 |
+
tokenize=False
|
| 38 |
+
)
|
| 39 |
+
inputs = self.tokenizer(text, return_tensors="pt").to(self.device)
|
| 40 |
+
|
| 41 |
+
with torch.no_grad():
|
| 42 |
+
outputs = self.model.generate(
|
| 43 |
+
**inputs,
|
| 44 |
+
max_new_tokens=max_new_tokens,
|
| 45 |
+
do_sample=True,
|
| 46 |
+
temperature=0.7,
|
| 47 |
+
top_p=0.9,
|
| 48 |
+
repetition_penalty=1.2,
|
| 49 |
+
)
|
| 50 |
+
|
| 51 |
+
new_tokens = outputs[0, inputs["input_ids"].shape[1]:]
|
| 52 |
+
return self.tokenizer.decode(new_tokens, skip_special_tokens=False)
|
| 53 |
+
|
| 54 |
+
|
| 55 |
+
if __name__ == "__main__":
|
| 56 |
+
import os
|
| 57 |
+
# Use local checkpoint if available, otherwise HuggingFace
|
| 58 |
+
model_id = "checkpoint" if os.path.exists("checkpoint") else "AutomatedScientist/pynb-73m-base"
|
| 59 |
+
model = CodeModel(model_id)
|
| 60 |
+
|
| 61 |
+
# Example: Generate code
|
| 62 |
+
result = model.generate("Write a Python function to calculate factorial")
|
| 63 |
+
print("Generated code:")
|
| 64 |
+
print(result)
|
| 65 |
+
|
| 66 |
+
# Example: Chat
|
| 67 |
+
messages = [
|
| 68 |
+
{"role": "system", "content": "You are a helpful coding assistant."},
|
| 69 |
+
{"role": "user", "content": "Write a function to reverse a string"}
|
| 70 |
+
]
|
| 71 |
+
response = model.chat(messages)
|
| 72 |
+
print("\nChat response:")
|
| 73 |
+
print(response)
|
inference_smolagent.py
ADDED
|
@@ -0,0 +1,347 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""inference_smolagent.py - Run model with smolagents CodeAgent and LocalPythonExecutor"""
|
| 2 |
+
import os
|
| 3 |
+
import re
|
| 4 |
+
|
| 5 |
+
import torch
|
| 6 |
+
from transformers import AutoModelForCausalLM, AutoTokenizer
|
| 7 |
+
from smolagents import CodeAgent, Tool
|
| 8 |
+
from smolagents.local_python_executor import LocalPythonExecutor
|
| 9 |
+
from smolagents.models import ChatMessage, MessageRole, Model
|
| 10 |
+
|
| 11 |
+
DEBUG = int(os.environ.get("DEBUG", 0))
|
| 12 |
+
|
| 13 |
+
# Model's special tokens (from training)
|
| 14 |
+
START_TOOL_CALL = "<|start_tool_call|>"
|
| 15 |
+
END_TOOL_CALL = "<|end_tool_call|>"
|
| 16 |
+
START_TOOL_RESPONSE = "<|start_tool_response|>"
|
| 17 |
+
END_TOOL_RESPONSE = "<|end_tool_response|>"
|
| 18 |
+
|
| 19 |
+
# Smolagents expected tokens
|
| 20 |
+
SMOLAGENT_CODE_START = "<code>"
|
| 21 |
+
SMOLAGENT_CODE_END = "</code>"
|
| 22 |
+
|
| 23 |
+
|
| 24 |
+
class LocalCodeModel(Model):
|
| 25 |
+
"""
|
| 26 |
+
Local model wrapper compatible with smolagents.
|
| 27 |
+
|
| 28 |
+
Handles translation between smolagents format and model's training format.
|
| 29 |
+
"""
|
| 30 |
+
|
| 31 |
+
def __init__(self, model_id: str, device: str = None):
|
| 32 |
+
super().__init__()
|
| 33 |
+
self.device = device or ("cuda" if torch.cuda.is_available() else "cpu")
|
| 34 |
+
self.tokenizer = AutoTokenizer.from_pretrained(model_id, fix_mistral_regex=True)
|
| 35 |
+
self.model = AutoModelForCausalLM.from_pretrained(model_id)
|
| 36 |
+
self.model.to(self.device)
|
| 37 |
+
self.model.eval()
|
| 38 |
+
|
| 39 |
+
# Cache special token IDs for stopping
|
| 40 |
+
self._end_tool_id = self.tokenizer.encode(END_TOOL_CALL, add_special_tokens=False)[-1]
|
| 41 |
+
|
| 42 |
+
def _convert_prompt_to_model_format(self, prompt: str) -> str:
|
| 43 |
+
"""Convert smolagents prompt format to model's training format."""
|
| 44 |
+
# Replace smolagents code markers with model's markers
|
| 45 |
+
prompt = prompt.replace(SMOLAGENT_CODE_START, START_TOOL_CALL)
|
| 46 |
+
prompt = prompt.replace(SMOLAGENT_CODE_END, END_TOOL_CALL)
|
| 47 |
+
return prompt
|
| 48 |
+
|
| 49 |
+
def _convert_response_to_smolagent_format(self, response: str) -> str:
|
| 50 |
+
"""Convert model's output format to smolagents expected format."""
|
| 51 |
+
# Replace model's markers with smolagents markers
|
| 52 |
+
response = response.replace(START_TOOL_CALL, SMOLAGENT_CODE_START)
|
| 53 |
+
response = response.replace(END_TOOL_CALL, SMOLAGENT_CODE_END)
|
| 54 |
+
response = response.replace(START_TOOL_RESPONSE, "")
|
| 55 |
+
response = response.replace(END_TOOL_RESPONSE, "")
|
| 56 |
+
|
| 57 |
+
# Clean up: remove orphan closing tags at start
|
| 58 |
+
response = re.sub(r'^\s*</code>\s*', '', response)
|
| 59 |
+
|
| 60 |
+
# Check if we have valid <code>...</code> block
|
| 61 |
+
has_open = SMOLAGENT_CODE_START in response
|
| 62 |
+
has_close = SMOLAGENT_CODE_END in response
|
| 63 |
+
|
| 64 |
+
# If only closing tag, remove it
|
| 65 |
+
if has_close and not has_open:
|
| 66 |
+
response = response.replace(SMOLAGENT_CODE_END, "")
|
| 67 |
+
|
| 68 |
+
# If no code markers, try to extract and wrap code
|
| 69 |
+
if SMOLAGENT_CODE_START not in response:
|
| 70 |
+
# Look for python code patterns in markdown
|
| 71 |
+
code_match = re.search(r'```(?:python)?\s*(.*?)\s*```', response, re.DOTALL)
|
| 72 |
+
if code_match:
|
| 73 |
+
code = code_match.group(1).strip()
|
| 74 |
+
if code:
|
| 75 |
+
response = f"Thoughts: Executing the code\n{SMOLAGENT_CODE_START}\n{code}\n{SMOLAGENT_CODE_END}"
|
| 76 |
+
else:
|
| 77 |
+
# Look for any code-like content
|
| 78 |
+
lines = response.strip().split('\n')
|
| 79 |
+
code_lines = [l for l in lines if any(kw in l for kw in ['def ', 'print(', 'return ', '= ', 'import ', 'for ', 'if ', 'while '])]
|
| 80 |
+
if code_lines:
|
| 81 |
+
code = '\n'.join(code_lines)
|
| 82 |
+
response = f"Thoughts: Executing the code\n{SMOLAGENT_CODE_START}\n{code}\n{SMOLAGENT_CODE_END}"
|
| 83 |
+
else:
|
| 84 |
+
# Fallback: wrap entire response as code if it looks like code
|
| 85 |
+
clean = response.strip()
|
| 86 |
+
if clean and not clean.startswith("Thoughts"):
|
| 87 |
+
response = f"Thoughts: Attempting execution\n{SMOLAGENT_CODE_START}\nprint('No valid code generated')\n{SMOLAGENT_CODE_END}"
|
| 88 |
+
|
| 89 |
+
# Ensure closing tag exists if opening exists
|
| 90 |
+
if SMOLAGENT_CODE_START in response and SMOLAGENT_CODE_END not in response:
|
| 91 |
+
response = response + f"\n{SMOLAGENT_CODE_END}"
|
| 92 |
+
|
| 93 |
+
return response
|
| 94 |
+
|
| 95 |
+
def generate(
|
| 96 |
+
self,
|
| 97 |
+
messages: list[ChatMessage],
|
| 98 |
+
stop_sequences: list[str] | None = None,
|
| 99 |
+
grammar: str | None = None,
|
| 100 |
+
tools_to_call_from: list[Tool] | None = None,
|
| 101 |
+
**kwargs,
|
| 102 |
+
) -> ChatMessage:
|
| 103 |
+
"""Generate response for message history (required by smolagents Model)."""
|
| 104 |
+
# Debug: show what messages are passed (including executor output)
|
| 105 |
+
if DEBUG:
|
| 106 |
+
print("\n[DEBUG] Messages received by model:")
|
| 107 |
+
for i, msg in enumerate(messages):
|
| 108 |
+
role = msg.role.value if hasattr(msg.role, "value") else msg.role
|
| 109 |
+
content = str(msg.content)[:200] if msg.content else "<empty>"
|
| 110 |
+
print(f" [{i}] {role}: {content}...")
|
| 111 |
+
print()
|
| 112 |
+
|
| 113 |
+
# Convert ChatMessage objects to dicts for chat template
|
| 114 |
+
messages_dicts = []
|
| 115 |
+
for msg in messages:
|
| 116 |
+
if hasattr(msg, "role") and hasattr(msg, "content"):
|
| 117 |
+
role = msg.role.value if hasattr(msg.role, "value") else str(msg.role)
|
| 118 |
+
content = msg.content if isinstance(msg.content, str) else str(msg.content or "")
|
| 119 |
+
# Convert prompt format in content
|
| 120 |
+
content = self._convert_prompt_to_model_format(content)
|
| 121 |
+
# Wrap observations (executor output) in tool response tokens
|
| 122 |
+
if "Observation:" in content or "Out:" in content:
|
| 123 |
+
# Extract the observation content
|
| 124 |
+
obs_match = re.search(r'(?:Observation:|Out:)\s*(.*)', content, re.DOTALL)
|
| 125 |
+
if obs_match:
|
| 126 |
+
obs_content = obs_match.group(1).strip()
|
| 127 |
+
content = f"{START_TOOL_RESPONSE}\n{obs_content}\n{END_TOOL_RESPONSE}"
|
| 128 |
+
messages_dicts.append({"role": role, "content": content})
|
| 129 |
+
else:
|
| 130 |
+
messages_dicts.append(msg)
|
| 131 |
+
|
| 132 |
+
# Convert messages to prompt using chat template
|
| 133 |
+
prompt = self.tokenizer.apply_chat_template(
|
| 134 |
+
messages_dicts,
|
| 135 |
+
add_generation_prompt=True,
|
| 136 |
+
tokenize=False
|
| 137 |
+
)
|
| 138 |
+
|
| 139 |
+
# Check prompt length
|
| 140 |
+
if DEBUG:
|
| 141 |
+
full_tokens = self.tokenizer(prompt, return_tensors="pt")
|
| 142 |
+
print(f"[DEBUG] Prompt length: {full_tokens['input_ids'].shape[1]} tokens (max: 2048)")
|
| 143 |
+
|
| 144 |
+
# Truncate to fit model's context window (2048 tokens, leave room for generation)
|
| 145 |
+
max_input_tokens = 1536 # Leave 512 for generation
|
| 146 |
+
inputs = self.tokenizer(
|
| 147 |
+
prompt,
|
| 148 |
+
return_tensors="pt",
|
| 149 |
+
truncation=True,
|
| 150 |
+
max_length=max_input_tokens
|
| 151 |
+
).to(self.device)
|
| 152 |
+
|
| 153 |
+
with torch.no_grad():
|
| 154 |
+
outputs = self.model.generate(
|
| 155 |
+
**inputs,
|
| 156 |
+
max_new_tokens=512,
|
| 157 |
+
temperature=0.7,
|
| 158 |
+
do_sample=True,
|
| 159 |
+
top_p=0.9,
|
| 160 |
+
repetition_penalty=1.2,
|
| 161 |
+
pad_token_id=self.tokenizer.pad_token_id,
|
| 162 |
+
eos_token_id=[self.tokenizer.eos_token_id, self._end_tool_id],
|
| 163 |
+
)
|
| 164 |
+
|
| 165 |
+
new_tokens = outputs[0, inputs["input_ids"].shape[1]:]
|
| 166 |
+
response = self.tokenizer.decode(new_tokens, skip_special_tokens=False)
|
| 167 |
+
|
| 168 |
+
# Handle stop sequences
|
| 169 |
+
if stop_sequences:
|
| 170 |
+
for seq in stop_sequences:
|
| 171 |
+
if seq in response:
|
| 172 |
+
response = response.split(seq)[0]
|
| 173 |
+
|
| 174 |
+
# Convert response format for smolagents
|
| 175 |
+
response = self._convert_response_to_smolagent_format(response)
|
| 176 |
+
|
| 177 |
+
return ChatMessage(role=MessageRole.ASSISTANT, content=response)
|
| 178 |
+
|
| 179 |
+
|
| 180 |
+
# Example tools
|
| 181 |
+
class CalculatorTool(Tool):
|
| 182 |
+
name = "calculator"
|
| 183 |
+
description = "Evaluates a mathematical expression and returns the result."
|
| 184 |
+
inputs = {
|
| 185 |
+
"expression": {
|
| 186 |
+
"type": "string",
|
| 187 |
+
"description": "The mathematical expression to evaluate (e.g., '2 + 2 * 3')"
|
| 188 |
+
}
|
| 189 |
+
}
|
| 190 |
+
output_type = "number"
|
| 191 |
+
|
| 192 |
+
def forward(self, expression: str) -> float:
|
| 193 |
+
# Safe eval for math expressions
|
| 194 |
+
allowed = set("0123456789+-*/().^ ")
|
| 195 |
+
if not all(c in allowed for c in expression):
|
| 196 |
+
raise ValueError("Invalid characters in expression")
|
| 197 |
+
return eval(expression.replace("^", "**"))
|
| 198 |
+
|
| 199 |
+
|
| 200 |
+
class FibonacciTool(Tool):
|
| 201 |
+
name = "fibonacci"
|
| 202 |
+
description = "Calculate the nth Fibonacci number."
|
| 203 |
+
inputs = {
|
| 204 |
+
"n": {
|
| 205 |
+
"type": "integer",
|
| 206 |
+
"description": "The position in Fibonacci sequence (0-indexed)"
|
| 207 |
+
}
|
| 208 |
+
}
|
| 209 |
+
output_type = "integer"
|
| 210 |
+
|
| 211 |
+
def forward(self, n: int) -> int:
|
| 212 |
+
if n < 0:
|
| 213 |
+
raise ValueError("n must be non-negative")
|
| 214 |
+
if n <= 1:
|
| 215 |
+
return n
|
| 216 |
+
a, b = 0, 1
|
| 217 |
+
for _ in range(2, n + 1):
|
| 218 |
+
a, b = b, a + b
|
| 219 |
+
return b
|
| 220 |
+
|
| 221 |
+
|
| 222 |
+
SHORT_PROMPT_TEMPLATES = {
|
| 223 |
+
"system_prompt": """You solve tasks by writing Python code.
|
| 224 |
+
|
| 225 |
+
Rules:
|
| 226 |
+
- Write code inside <code> and </code> tags
|
| 227 |
+
- Use print() to show results
|
| 228 |
+
- Use final_answer(result) when done
|
| 229 |
+
|
| 230 |
+
Format:
|
| 231 |
+
Thoughts: your reasoning
|
| 232 |
+
<code>
|
| 233 |
+
# your code
|
| 234 |
+
</code>""",
|
| 235 |
+
"planning": {
|
| 236 |
+
"initial_plan": "",
|
| 237 |
+
"update_plan_pre_messages": "",
|
| 238 |
+
"update_plan_post_messages": "",
|
| 239 |
+
},
|
| 240 |
+
"managed_agent": {
|
| 241 |
+
"task": "",
|
| 242 |
+
"report": "",
|
| 243 |
+
},
|
| 244 |
+
"final_answer": {
|
| 245 |
+
"pre_messages": "",
|
| 246 |
+
"post_messages": "",
|
| 247 |
+
},
|
| 248 |
+
}
|
| 249 |
+
|
| 250 |
+
|
| 251 |
+
def create_agent(
|
| 252 |
+
model_id: str = "AutomatedScientist/pynb-73m-base",
|
| 253 |
+
tools: list[Tool] | None = None,
|
| 254 |
+
additional_authorized_imports: list[str] | None = None,
|
| 255 |
+
max_steps: int = 5,
|
| 256 |
+
use_short_prompt: bool = True,
|
| 257 |
+
) -> CodeAgent:
|
| 258 |
+
"""
|
| 259 |
+
Create a CodeAgent with LocalPythonExecutor.
|
| 260 |
+
|
| 261 |
+
Args:
|
| 262 |
+
model_id: HuggingFace model ID or local path
|
| 263 |
+
tools: List of tools to provide to the agent
|
| 264 |
+
additional_authorized_imports: Extra imports to allow in executor
|
| 265 |
+
max_steps: Maximum agent steps before stopping
|
| 266 |
+
use_short_prompt: Use shorter system prompt for small context models
|
| 267 |
+
|
| 268 |
+
Returns:
|
| 269 |
+
Configured CodeAgent instance
|
| 270 |
+
"""
|
| 271 |
+
model = LocalCodeModel(model_id)
|
| 272 |
+
|
| 273 |
+
# Default authorized imports
|
| 274 |
+
authorized_imports = [
|
| 275 |
+
"math", "statistics", "random", "datetime",
|
| 276 |
+
"collections", "itertools", "re", "json",
|
| 277 |
+
"functools", "operator"
|
| 278 |
+
]
|
| 279 |
+
if additional_authorized_imports:
|
| 280 |
+
authorized_imports.extend(additional_authorized_imports)
|
| 281 |
+
|
| 282 |
+
# Create executor with sandbox
|
| 283 |
+
executor = LocalPythonExecutor(
|
| 284 |
+
additional_authorized_imports=authorized_imports,
|
| 285 |
+
max_print_outputs_length=10000,
|
| 286 |
+
)
|
| 287 |
+
|
| 288 |
+
# Build agent config
|
| 289 |
+
agent_kwargs = {
|
| 290 |
+
"tools": tools or [],
|
| 291 |
+
"model": model,
|
| 292 |
+
"executor": executor,
|
| 293 |
+
"max_steps": max_steps,
|
| 294 |
+
"verbosity_level": 1,
|
| 295 |
+
}
|
| 296 |
+
|
| 297 |
+
# Use short prompt for small context models
|
| 298 |
+
if use_short_prompt:
|
| 299 |
+
agent_kwargs["prompt_templates"] = SHORT_PROMPT_TEMPLATES
|
| 300 |
+
|
| 301 |
+
agent = CodeAgent(**agent_kwargs)
|
| 302 |
+
|
| 303 |
+
return agent
|
| 304 |
+
|
| 305 |
+
|
| 306 |
+
def run_task(agent: CodeAgent, task: str) -> any:
|
| 307 |
+
"""
|
| 308 |
+
Run a task through the agent.
|
| 309 |
+
|
| 310 |
+
Args:
|
| 311 |
+
agent: CodeAgent instance
|
| 312 |
+
task: Natural language task description
|
| 313 |
+
|
| 314 |
+
Returns:
|
| 315 |
+
Agent output
|
| 316 |
+
"""
|
| 317 |
+
print(f"\n{'='*60}")
|
| 318 |
+
print(f"Task: {task}")
|
| 319 |
+
print(f"{'='*60}\n")
|
| 320 |
+
|
| 321 |
+
result = agent.run(task)
|
| 322 |
+
|
| 323 |
+
print(f"\n{'='*60}")
|
| 324 |
+
print(f"Result: {result}")
|
| 325 |
+
print(f"{'='*60}\n")
|
| 326 |
+
|
| 327 |
+
return result
|
| 328 |
+
|
| 329 |
+
|
| 330 |
+
if __name__ == "__main__":
|
| 331 |
+
import sys
|
| 332 |
+
|
| 333 |
+
# Use local checkpoint if available, otherwise HuggingFace
|
| 334 |
+
model_id = "checkpoint" if os.path.exists("checkpoint") else "AutomatedScientist/pynb-73m-base"
|
| 335 |
+
|
| 336 |
+
agent = create_agent(
|
| 337 |
+
model_id=model_id,
|
| 338 |
+
tools=[CalculatorTool(), FibonacciTool()],
|
| 339 |
+
max_steps=8,
|
| 340 |
+
)
|
| 341 |
+
|
| 342 |
+
# Run example task
|
| 343 |
+
task = sys.argv[1] if len(sys.argv) > 1 else "Calculate 15 * 7 + 23"
|
| 344 |
+
try:
|
| 345 |
+
result = run_task(agent, task)
|
| 346 |
+
except Exception as e:
|
| 347 |
+
print(f"Error: {e}")
|
training_plot.png
ADDED
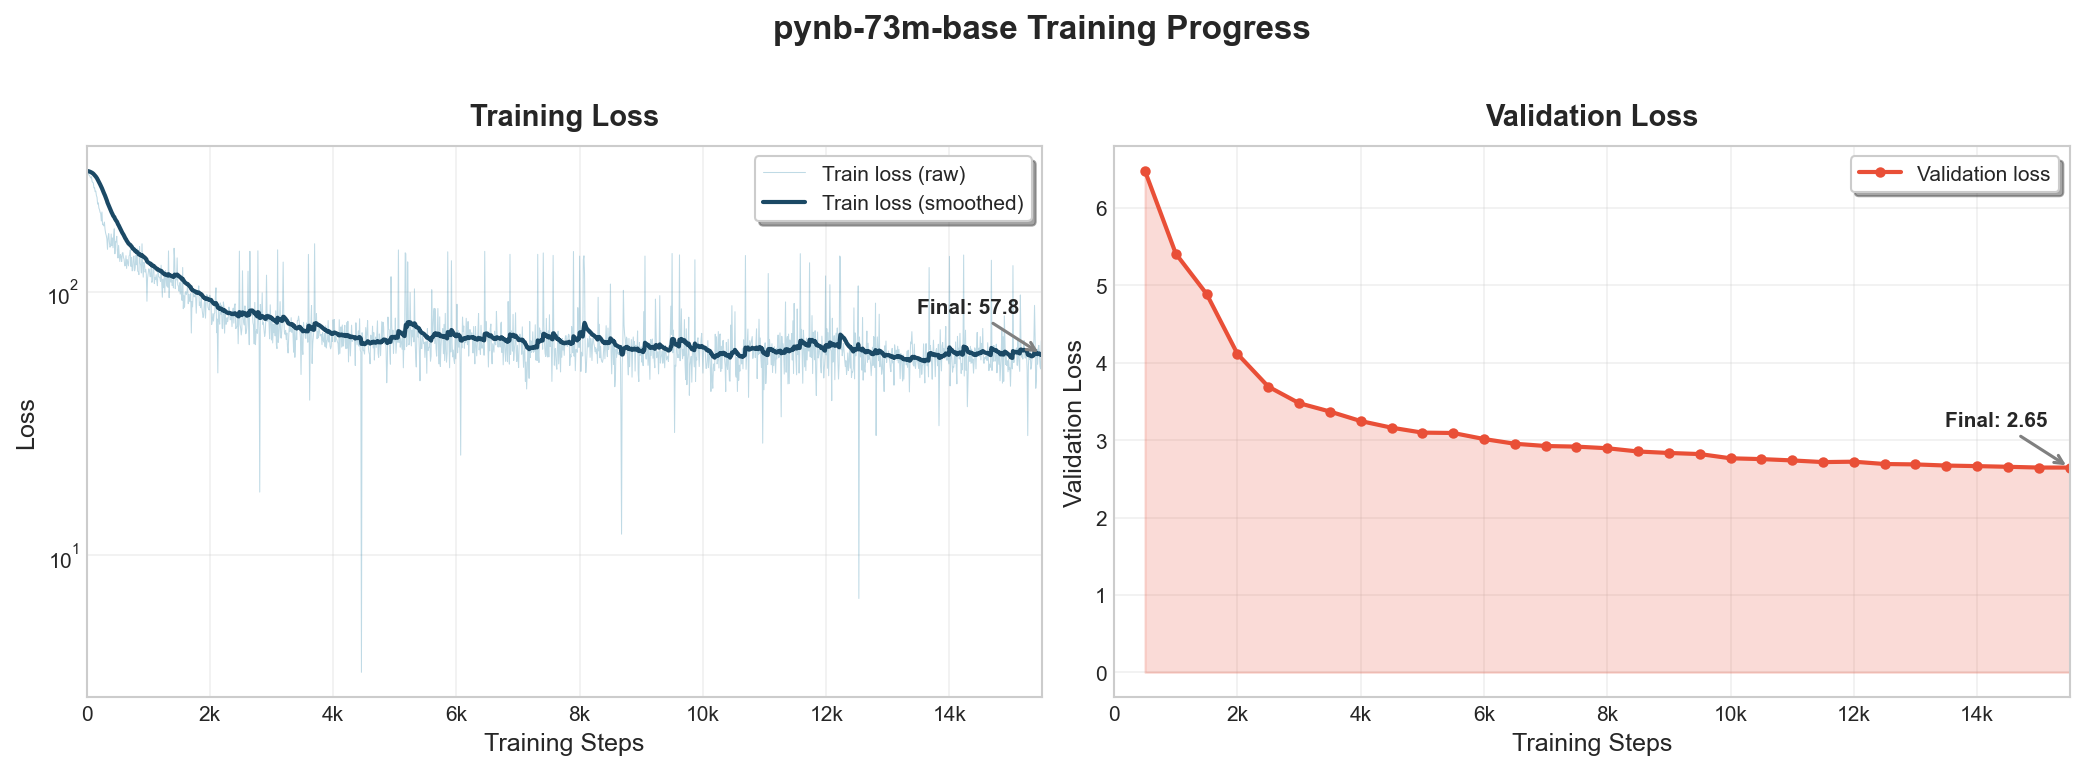
|
Git LFS Details
|