| --- |
| license: other |
| pipeline_tag: image-to-image |
| --- |
| |
|
|
| [English Documentation](./README.md) |
|
|
| <div align="center"> |
|
|
| <img src="./assets/logo.png" alt="HunyuanImage-3.0 Logo" width="600"> |
|
|
| # 🎨 HunyuanImage-3.0: 强大的原生多模态图像生成模型 |
|
|
| </div> |
|
|
|
|
| <div align="center"> |
| <img src="./assets/banner.png" alt="HunyuanImage-3.0 Banner" width="800"> |
|
|
| </div> |
|
|
| <div align="center"> |
| <a href=https://hunyuan.tencent.com/image target="_blank"><img src=https://img.shields.io/badge/Official%20Site-333399.svg?logo=homepage height=22px></a> |
| <a href=https://huggingface.co/tencent/HunyuanImage-3.0-Instruct target="_blank"><img src=https://img.shields.io/badge/%F0%9F%A4%97%20Models-d96902.svg height=22px></a> |
| <a href=https://github.com/Tencent-Hunyuan/HunyuanImage-3.0 target="_blank"><img src= https://img.shields.io/badge/Page-bb8a2e.svg?logo=github height=22px></a> |
| <a href=https://arxiv.org/pdf/2509.23951 target="_blank"><img src=https://img.shields.io/badge/Report-b5212f.svg?logo=arxiv height=22px></a> |
| <a href=https://x.com/TencentHunyuan target="_blank"><img src=https://img.shields.io/badge/Hunyuan-black.svg?logo=x height=22px></a> |
| <a href=https://docs.qq.com/doc/DUVVadmhCdG9qRXBU target="_blank"><img src=https://img.shields.io/badge/📚-提示词手册-blue.svg?logo=book height=22px></a> |
| </div> |
|
|
|
|
| <p align="center"> |
| 👏 加入我们的 <a href="./assets/WECHAT.md" target="_blank">微信</a> 和 <a href="https://discord.gg/ehjWMqF5wY">Discord</a> | |
| 💻 <a href="https://hunyuan.tencent.com/chat/HunyuanDefault?from=modelSquare&modelId=Hunyuan-Image-3.0-Instruct">官网试用我们的模型!</a>   |
| </p> |
| |
| ## 🔥🔥🔥 最新消息 |
|
|
| - **2026年1月26日**: 🚀 **[HunyuanImage-3.0-Instruct-Distil](https://huggingface.co/tencent/HunyuanImage-3.0-Instruct-Distil)** - 蒸馏版本用于高效部署(推荐8步采样)。 |
| - **2026年1月26日**: 🎉 **[HunyuanImage-3.0-Instruct](https://huggingface.co/tencent/HunyuanImage-3.0-Instruct)** - 发布了 **Instruct(带推理能力)**版本,支持智能提示词增强和**图像到图像**生成用于创意编辑。 |
| - **2025年10月30日**: 🚀 **[HunyuanImage-3.0 vLLM 加速](./vllm_infer/README.md)** - 通过 vLLM 支持实现显著更快的推理速度。 |
| - **2025年09月28日**: 📖 **[HunyuanImage-3.0 技术报告](https://arxiv.org/pdf/2509.23951)** - 全面的技术文档现已发布。 |
| - **2025年09月28日**: 🎉 **[HunyuanImage-3.0 开源](https://github.com/Tencent-Hunyuan/HunyuanImage-3.0)** - 推理代码和模型权重现已公开可用。 |
|
|
|
|
| ## 🧩 社区贡献 |
|
|
| 如果您在项目中使用或开发了 HunyuanImage-3.0,欢迎告知我们。 |
|
|
| ## 📑 开源计划 |
|
|
| - HunyuanImage-3.0 (图像生成模型) |
| - [x] 推理代码 |
| - [x] HunyuanImage-3.0 模型权重 |
| - [x] HunyuanImage-3.0-Instruct 模型权重(带推理能力) |
| - [x] vLLM 支持 |
| - [x] 蒸馏版本权重 |
| - [x] 图像到图像生成 |
| - [ ] 多轮交互能力 |
|
|
|
|
| ## 🗂️ 目录 |
| - [🔥🔥🔥 最新消息](#-最新消息) |
| - [🧩 社区贡献](#-社区贡献) |
| - [📑 开源计划](#-开源计划) |
| - [📖 概览](#-概览) |
| - [✨ 模型亮点](#-模型亮点) |
| - [🚀 使用方法](#-使用方法) |
| - [📦 环境配置](#-环境配置) |
| - [📥 安装依赖](#-安装依赖) |
| - [HunyuanImage-3.0-Instruct](#hunyuanimage-30-instruct-指令推理和图像到图像生成包括编辑和多图像融合) |
| - [🔥 使用 Transformers 快速开始](#-使用-transformers-快速开始) |
| - [1️⃣ 下载模型权重](#1-下载模型权重) |
| - [2️⃣ 使用 Transformers 运行](#2-使用-transformers-运行) |
| - [🏠 本地安装和使用](#-本地安装和使用) |
| - [1️⃣ 克隆仓库](#1-克隆仓库) |
| - [2️⃣ 下载模型权重](#2-下载模型权重) |
| - [3️⃣ 运行演示](#3-运行演示) |
| - [4️⃣ 命令行参数](#4-命令行参数) |
| - [5️⃣ 更少的采样步数](#5-更少的采样步数) |
| - [HunyuanImage-3.0 (文本生成图像)](#hunyuanimage-30-文本生成图像) |
| - [🔥 使用 Transformers 快速开始](#-使用-transformers-快速开始-1) |
| - [1️⃣ 下载模型权重](#1-下载模型权重-1) |
| - [2️⃣ 使用 Transformers 运行](#2-使用-transformers-运行-1) |
| - [🏠 本地安装和使用](#-本地安装和使用-1) |
| - [1️⃣ 克隆仓库](#1-克隆仓库-1) |
| - [2️⃣ 下载模型权重](#2-下载模型权重-1) |
| - [3️⃣ 运行演示](#3-运行演示-1) |
| - [4️⃣ 命令行参数](#4-命令行参数-1) |
| - [🎨 交互式 Gradio 演示](#-交互式-gradio-演示) |
| - [1️⃣ 安装 Gradio](#1-安装-gradio) |
| - [2️⃣ 配置环境](#2-配置环境) |
| - [3️⃣ 启动 Web 界面](#3-启动-web-界面) |
| - [4️⃣ 访问界面](#4-访问界面) |
| - [🧱 模型卡片](#-模型卡片) |
| - [📊 评估结果](#-评估结果) |
| - [HunyuanImage-3.0-Instruct 评估](#hunyuanimage-30-instruct-评估) |
| - [HunyuanImage-3.0 评估](#hunyuanimage-30-评估) |
| - [🖼️ 展示](#-展示) |
| - [HunyuanImage-3.0-Instruct 展示](#hunyuanimage-30-instruct-展示) |
| - [📚 引用](#-引用) |
| - [🙏 致谢](#-致谢) |
| - [🌟🚀 GitHub Star 历史](#-github-star-历史) |
|
|
| --- |
|
|
| ## 📖 概览 |
|
|
| **HunyuanImage-3.0** 是一个突破性的原生多模态模型,它在自回归框架内统一了多模态理解和生成任务。它的文生图和图生图能力实现了与领先的闭源模型**相当或更优**的性能。 |
|
|
|
|
| <div align="center"> |
| <img src="./assets/framework.png" alt="HunyuanImage-3.0 Framework" width="90%"> |
| </div> |
|
|
| ## ✨ 模型亮点 |
|
|
| * 🧠 **统一的多模态架构:** HunyuanImage-3.0 突破当前主流的 DiT 架构,采用统一的自回归框架。该设计能更直接、统一地对文本与图像模态进行建模,实现了语义理解与图像生成的高度融合,从而生成效果惊人、语境丰富的图像。 |
|
|
| * 🏆 **最大规模图像生成MoE模型:** 作为当前开源社区参数规模最大的图像生成 MoE 模型,其拥有64个专家、总参数量达 800 亿,单 token 激活 130 亿参数,显著提升了模型容量与性能表现。 |
|
|
| * 🎨 **卓越的图像生成质量:** 通过精细的数据集构建与强化学习后训练,我们在语义准确性与视觉表现力间取得最佳平衡。该模型不仅能精准遵循提示词要求,更可生成细节丰富、具有摄影级真实感与艺术美感的图像。 |
|
|
| * 💭 **智能图像理解与世界知识推理:** 得益于统一的多模态架构,HunyuanImage-3.0 拥有强大的推理能力。它不仅能深度理解用户输入的图像,还能利用其海量的世界知识精准解读用户意图。针对简略的提示词(prompts),它能够自动补全符合语境的细节,从而生成更出色、更完整的视觉作品。 |
|
|
|
|
| ## 🚀 使用方法 |
|
|
| ### 📦 环境配置 |
|
|
| * 🐍 **Python:** 3.12+ (推荐并已测试) |
| * ⚡ **CUDA:** 12.8 |
|
|
| #### 📥 安装依赖 |
|
|
| ```bash |
| # 1. 首先安装 PyTorch (CUDA 12.8 版本) |
| pip install torch==2.8.0 torchvision==0.23.0 torchaudio==2.8.0 --index-url https://download.pytorch.org/whl/cu128 |
| |
| # 2. 安装 tencentcloud-sdk(仅用于 HunyuanImage-3.0 的提示词增强(PE),不适用于 HunyuanImage-3.0-Instruct) |
| pip install -i https://mirrors.tencent.com/pypi/simple/ --upgrade tencentcloud-sdk-python |
| |
| # 3. 然后安装其他依赖 |
| pip install -r requirements.txt |
| ``` |
|
|
| 为了**获得多达3倍的推理加速**,请安装以下优化: |
|
|
| ```bash |
| # FlashInfer 用于优化的 moe 推理。v0.5.0 已测试。 |
| pip install flashinfer-python==0.5.0 |
| ``` |
| > 💡**安装提示:** PyTorch 使用的 CUDA 版本必须与系统的 CUDA 版本匹配,这一点至关重要。 |
| > FlashInfer 依赖此兼容性在运行时编译内核。 |
| > 推荐使用 GCC 版本 >=9 来编译 FlashAttention 和 FlashInfer。 |
|
|
| > ⚡ **性能提示:** 这些优化可以显著加快您的推理速度! |
|
|
| > 💡**注意:** 启用 FlashInfer 时,首次推理可能会较慢(约 10 分钟),因为需要编译内核。在同一台机器上的后续推理会快得多。 |
|
|
| ### HunyuanImage-3.0-Instruct (指令推理和图像到图像生成,包括编辑和多图像融合) |
|
|
| #### 🔥 使用 Transformers 快速开始 |
|
|
| ##### 1️⃣ 下载模型权重 |
|
|
| ```bash |
| # 从 HuggingFace 下载并重命名目录。 |
| # 注意目录名称不应包含点号,否则使用 Transformers 加载时可能出现问题。 |
| hf download tencent/HunyuanImage-3.0-Instruct --local-dir ./HunyuanImage-3-Instruct |
| ``` |
|
|
| ##### 2️⃣ 使用 Transformers 运行 |
|
|
| ```python |
| from transformers import AutoModelForCausalLM |
| |
| # 加载模型 |
| model_id = "./HunyuanImage-3-Instruct" |
| # 目前我们无法使用 HF 模型 ID `tencent/HunyuanImage-3.0-Instruct` 直接加载模型 |
| # 因为名称中包含点号。 |
| |
| kwargs = dict( |
| attn_implementation="sdpa", |
| trust_remote_code=True, |
| torch_dtype="auto", |
| device_map="auto", |
| moe_impl="eager", # 如果已安装 FlashInfer,可使用 "flashinfer" |
| moe_drop_tokens=True, |
| ) |
| |
| model = AutoModelForCausalLM.from_pretrained(model_id, **kwargs) |
| model.load_tokenizer(model_id) |
| |
| # 图像到图像生成 (TI2I) |
| prompt = "基于图一的logo,参考图二中冰箱贴的材质,制作一个新的冰箱贴" |
| |
| input_img1 = "./assets/demo_instruct_imgs/input_1_0.png" |
| input_img2 = "./assets/demo_instruct_imgs/input_1_1.png" |
| imgs_input = [input_img1, input_img2] |
| |
| cot_text, samples = model.generate_image( |
| prompt=prompt, |
| image=imgs_input, |
| seed=42, |
| image_size="auto", |
| use_system_prompt="en_unified", |
| bot_task="think_recaption", # 使用 "think_recaption" 进行推理和增强 |
| infer_align_image_size=True, # 将输出图像大小对齐到输入图像大小 |
| diff_infer_steps=50, |
| verbose=2 |
| ) |
| |
| # 保存生成的图像 |
| samples[0].save("image_edit.png") |
| ``` |
|
|
| #### 🏠 本地安装和使用 |
|
|
| ##### 1️⃣ 克隆仓库 |
|
|
| ```bash |
| git clone https://github.com/Tencent-Hunyuan/HunyuanImage-3.0.git |
| cd HunyuanImage-3.0/ |
| ``` |
|
|
| ##### 2️⃣ 下载模型权重 |
|
|
| ```bash |
| # 从 HuggingFace 下载 |
| hf download tencent/HunyuanImage-3.0-Instruct --local-dir ./HunyuanImage-3-Instruct |
| ``` |
|
|
| ##### 3️⃣ 运行演示 |
|
|
| 更多演示在 `run_demo_instruct.sh` 中。 |
|
|
| ```bash |
| export MODEL_PATH="./HunyuanImage-3-Instruct" |
| bash run_demo_instruct.sh |
| ``` |
|
|
| ##### 4️⃣ 命令行参数 |
|
|
| | 参数 | 说明 | 推荐值 | |
| |----------------------|------------------------------------------------|-------------| |
| | `--prompt` | 输入提示词 | (必填) | |
| | `--image` | 要处理的图像。多个图像使用逗号分隔的路径(例如 'img1.png,img2.png') | (必填) | |
| | `--model-id` | 模型路径 | (必填) | |
| | `--attn-impl` | Attention 实现方式。目前仅支持 'sdpa' | `sdpa` | |
| | `--moe-impl` | MoE 实现方式。可选 `eager` 或 `flashinfer` | `flashinfer` | |
| | `--seed` | 图像生成的随机种子。使用 None 表示随机种子 | `None` | |
| | `--diff-infer-steps` | 推理步数 | `50` | |
| | `--image-size` | 图像分辨率。可以是 `auto`、`1280x768` 或 `16:9` | `auto` | |
| | `--use-system-prompt` | 系统提示词类型。选项:`None`、`dynamic`、`en_vanilla`、`en_recaption`、`en_think_recaption`、`en_unified`、`custom` | `en_unified` | |
| | `--system-prompt` | 自定义系统提示词。当 `--use-system-prompt` 为 `custom` 时使用 | `None` | |
| | `--bot-task` | 任务类型。`image` 用于直接生成;`auto` 用于文本;`recaption` 用于重写->图像;`think_recaption` 用于思考->重写->图像 | `think_recaption` | |
| | `--save` | 图像保存路径 | `image.png` | |
| | `--verbose` | 详细程度 | `2` | |
| | `--reproduce` | 是否复现结果 | `True` | |
| | `--infer-align-image-size` | 是否将目标图像大小对齐到源图像大小 | `True` | |
| | `--max_new_tokens` | 生成的最大 token 数 | `2048` | |
| | `--use-taylor-cache` | 采样时使用 Taylor Cache | `False` | |
|
|
| ##### 5️⃣ 更少的采样步数 |
|
|
| 我们推荐使用模型 [HunyuanImage-3.0-Instruct-Distil](https://huggingface.co/tencent/HunyuanImage-3.0-Instruct-Distil),设置 `--diff-infer-steps 8`,同时保持所有其他推荐参数值**不变**。 |
|
|
| ```bash |
| # 从 HuggingFace 下载 HunyuanImage-3.0-Instruct-Distil |
| hf download tencent/HunyuanImage-3.0-Instruct-Distil --local-dir ./HunyuanImage-3-Instruct-Distil |
| |
| # 使用 8 步采样运行演示 |
| export MODEL_PATH="./HunyuanImage-3-Instruct-Distil" |
| bash run_demo_instruct_distil.sh |
| ``` |
|
|
| <details> |
| <summary> 先前版本(纯文本生成图像) </summary> |
|
|
| ### HunyuanImage-3.0 (文本生成图像) |
|
|
| #### 🔥 使用 Transformers 快速开始 |
|
|
| ##### 1️⃣ 下载模型权重 |
|
|
| ```bash |
| # 从 HuggingFace 下载并重命名目录。 |
| # 注意目录名称不应包含点号,否则使用 Transformers 加载时可能出现问题。 |
| hf download tencent/HunyuanImage-3.0 --local-dir ./HunyuanImage-3 |
| ``` |
|
|
| ##### 2️⃣ 使用 Transformers 运行 |
|
|
| ```python |
| from transformers import AutoModelForCausalLM |
| |
| # 加载模型 |
| model_id = "./HunyuanImage-3" |
| # 目前我们无法使用 HF 模型 ID `tencent/HunyuanImage-3.0` 直接加载模型 |
| # 因为名称中包含点号。 |
| |
| kwargs = dict( |
| attn_implementation="sdpa", # 如果已安装 FlashAttention,可使用 "flash_attention_2" |
| trust_remote_code=True, |
| torch_dtype="auto", |
| device_map="auto", |
| moe_impl="eager", # 如果已安装 FlashInfer,可使用 "flashinfer" |
| ) |
| |
| model = AutoModelForCausalLM.from_pretrained(model_id, **kwargs) |
| model.load_tokenizer(model_id) |
| |
| # 生成图像 |
| prompt = "一只棕色和白色相间的小狗奔跑在草地上" |
| image = model.generate_image(prompt=prompt, stream=True) |
| image.save("image.png") |
| ``` |
|
|
| #### 🏠 本地安装和使用 |
|
|
| ##### 1️⃣ 克隆仓库 |
|
|
| ```bash |
| git clone https://github.com/Tencent-Hunyuan/HunyuanImage-3.0.git |
| cd HunyuanImage-3.0/ |
| ``` |
|
|
| ##### 2️⃣ 下载模型权重 |
|
|
| ```bash |
| # 从 HuggingFace 下载 |
| hf download tencent/HunyuanImage-3.0 --local-dir ./HunyuanImage-3 |
| ``` |
|
|
| ##### 3️⃣ 运行演示 |
| 预训练检查点不会自动重写或增强输入提示词,为了获得最佳效果,我们目前建议社区伙伴使用 deepseek 来重写提示词。您可以前往[腾讯云](https://cloud.tencent.com/document/product/1772/115963#.E5.BF.AB.E9.80.9F.E6.8E.A5.E5.85.A5)申请 API Key。 |
|
|
| ```bash |
| # Without PE |
| export MODEL_PATH="./HunyuanImage-3" |
| python3 run_image_gen.py \ |
| --model-id $MODEL_PATH \ |
| --verbose 1 \ |
| --prompt "一只棕色和白色相间的小狗奔跑在草地上" \ |
| --bot-task image \ |
| --image-size "1024x1024" \ |
| --save ./image.png \ |
| --moe-impl flashinfer |
| |
| # With PE |
| export DEEPSEEK_KEY_ID="your_deepseek_key_id" |
| export DEEPSEEK_KEY_SECRET="your_deepseek_key_secret" |
| export MODEL_PATH="./HunyuanImage-3" |
| python3 run_image_gen.py \ |
| --model-id $MODEL_PATH \ |
| --verbose 1 \ |
| --prompt "一只棕色和白色相间的小狗奔跑在草地上" \ |
| --bot-task image \ |
| --image-size "1024x1024" \ |
| --save ./image.png \ |
| --moe-impl flashinfer \ |
| --rewrite 1 |
| |
| ``` |
|
|
| ##### 4️⃣ 命令行参数 |
|
|
| | 参数 | 说明 | 推荐值 | |
| |----------------------|------------------------------------------------|-------------| |
| | `--prompt` | 输入提示词 | (必填) | |
| | `--model-id` | 模型路径 | (必填) | |
| | `--attn-impl` | Attention 实现方式。可选 `sdpa` 或 `flash_attention_2` | `sdpa` | |
| | `--moe-impl` | MoE 实现方式。可选 `eager` 或 `flashinfer` | `flashinfer` | |
| | `--seed` | 图像生成的随机种子 | `None` | |
| | `--diff-infer-steps` | Diffusion 推理步数 | `50` | |
| | `--image-size` | 图像分辨率。可以是 `auto`、`1280x768` 或 `16:9` | `auto` | |
| | `--save` | 图像保存路径 | `image.png` | |
| | `--verbose` | 详细程度。0: 无日志;1: 记录推理信息。 | `0` | |
| | `--rewrite` | 是否启用重写 | `1` | |
|
|
| #### 🎨 交互式 Gradio 演示 |
|
|
| 启动交互式 Web 界面,方便进行文本到图像生成。 |
|
|
| ##### 1️⃣ 安装 Gradio |
|
|
| ```bash |
| pip install gradio>=4.21.0 |
| ``` |
|
|
| ##### 2️⃣ 配置环境 |
|
|
| ```bash |
| # 设置您的模型路径 |
| export MODEL_ID="path/to/your/model" |
| |
| # 可选:配置 GPU 使用(默认:0,1,2,3) |
| export GPUS="0,1,2,3" |
| |
| # 可选:配置主机和端口(默认:0.0.0.0:443) |
| export HOST="0.0.0.0" |
| export PORT="443" |
| ``` |
|
|
| ##### 3️⃣ 启动 Web 界面 |
|
|
| **基础启动:** |
| ```bash |
| sh run_app.sh |
| ``` |
|
|
| **使用性能优化:** |
| ```bash |
| # 同时使用两种优化以获得最佳性能 |
| sh run_app.sh --moe-impl flashinfer --attn-impl flash_attention_2 |
| ``` |
|
|
| ##### 4️⃣ 访问界面 |
|
|
| > 🌐 **Web 界面:** 打开浏览器并访问 `http://localhost:443`(或您配置的端口) |
|
|
| </details> |
|
|
| ## 🧱 模型卡片 |
|
|
| | 模型 | 参数量 | 下载地址 | 推荐显存 | 支持功能 | |
| |---------------------------| --- | --- | --- | --- | |
| | HunyuanImage-3.0 | 总计 80B (激活 13B) | [HuggingFace](https://huggingface.co/tencent/HunyuanImage-3.0) | ≥ 3 × 80 GB | ✅ 文本生成图像 |
| | HunyuanImage-3.0-Instruct | 总计 80B (激活 13B) | [HuggingFace](https://huggingface.co/tencent/HunyuanImage-3.0-Instruct) | ≥ 8 × 80 GB | ✅ 文本生成图像<br>✅ 文本图像到图像<br>✅ 提示词自动重写 <br>✅ CoT 思考 |
| | HunyuanImage-3.0-Instruct-Distil | 总计 80B (激活 13B) | [HuggingFace](https://huggingface.co/tencent/HunyuanImage-3.0-Instruct-Distil) | ≥ 8 × 80 GB |✅ 文本生成图像<br>✅ 文本图像到图像<br>✅ 提示词自动重写 <br>✅ CoT 思考 <br>✅ 更少的采样步数(推荐 8 步) |
|
|
| 注意事项: |
| - 安装性能优化工具(FlashAttention、FlashInfer)以获得更快的推理速度。 |
| - 基础模型推荐使用多 GPU 推理。 |
|
|
| ## 📊 评估结果 |
|
|
| ### HunyuanImage-3.0-Instruct 评估 |
| * 👥 **GSB (人工评估)** |
| 我们采用了 GSB(好/相同/差)评估方法,该方法通常用于从整体图像感知角度评估两个模型之间的相对性能。我们总共使用了 1000+ 个单图像和多图像编辑案例,在一次运行中为所有比较的模型生成相等数量的图像样本。为了公平比较,我们对每个提示词只进行一次推理,避免任何结果筛选。在与基线方法比较时,我们保持了所有选定模型的默认设置。评估由 100 多名专业评估员执行。 |
|
|
| <p align="center"> |
| <img src="./assets/gsb_instruct.png" width=60% alt="Human Evaluation with Other Models"> |
| </p> |
|
|
|
|
| ### HunyuanImage-3.0 评估 |
|
|
| * 🤖 **SSAE (机器评估)** |
| SSAE(结构化语义对齐评估)是一种基于先进多模态大语言模型(MLLMs)的图像-文本对齐智能评估指标。我们提取了 12 个类别的 3500 个关键点,然后使用多模态大语言模型通过将生成的图像与这些关键点进行比较,基于图像的视觉内容自动评估和打分。平均图像准确率表示所有关键点的图像级平均分数,而全局准确率直接计算所有关键点的平均分数。 |
|
|
| <p align="center"> |
| <img src="./assets/ssae_side_by_side_comparison.png" width=98% alt="Human Evaluation with Other Models"> |
| </p> |
|
|
| <p align="center"> |
| <img src="./assets/ssae_side_by_side_heatmap.png" width=98% alt="Human Evaluation with Other Models"> |
| </p> |
|
|
|
|
| * 👥 **GSB (人工评估)** |
|
|
| 我们采用了 GSB(好/相同/差)评估方法,该方法通常用于从整体图像感知角度评估两个模型之间的相对性能。我们总共使用了 1000 个文本提示词,在一次运行中为所有比较的模型生成相等数量的图像样本。为了公平比较,我们对每个提示词只进行一次推理,避免任何结果筛选。在与基线方法比较时,我们保持了所有选定模型的默认设置。评估由 100 多名专业评估员执行。 |
|
|
| <p align="center"> |
| <img src="./assets/gsb.png" width=98% alt="Human Evaluation with Other Models"> |
| </p> |
|
|
| ## 🖼️ 展示 |
|
|
| 我们的模型可以遵循复杂指令生成高质量、富有创意的图像。 |
|
|
| <div align="center"> |
| <img src="./assets/banner_all.jpg" width=100% alt="HunyuanImage 3.0 Demo"> |
| </div> |
|
|
| 文本生成图像的展示,请点击以下链接: |
|
|
| - [HunyuanImage-3.0](./Hunyuan-Image3.md) |
|
|
| ### HunyuanImage-3.0-Instruct 展示 |
|
|
| HunyuanImage-3.0-Instruct 展示了在智能图像生成和编辑方面的强大能力。以下展示突出了其核心功能: |
|
|
| * 🧠 **智能视觉理解与推理(CoT Think)**: 模型执行结构化思考,分析用户输入的图像和提示词,将用户的意图和编辑任务扩展为结构化、全面的指令,从而带来更好的图像生成和编辑表现。 |
|
|
| 将复杂的提示词和编辑任务分解为详细的视觉组件,包括主体、构图、光照、色彩搭配和风格。 |
|
|
| * ✏️ **提示词自动重写**: 自动将稀疏或模糊的提示词增强为专业级、细节丰富的描述,更准确地捕捉用户意图。 |
|
|
| * 🎨 **文本生成图像(T2I)**: 从文本提示词生成高质量图像,具有出色的提示词遵循度和照片级真实感。 |
|
|
| * 🖼️ **图像到图像(TI2I)**: 支持创意图像编辑,包括添加元素、移除对象、修改风格和无缝背景替换,同时保留关键视觉元素。 |
|
|
| * 🔀 **多图像融合**: 智能组合多个参考图像(最多3个参考图输入),创建融合来自不同来源的视觉元素的连贯合成图像。 |
|
|
|
|
| **展示 1: 详细的思考和推理过程** |
|
|
| <div align="center"> |
| <img src="./assets/pg_instruct_imgs/cot_ti2i.gif" alt="HunyuanImage-3.0-Instruct Showcase 1" width="90%"> |
| </div> |
|
|
| **展示 2: 具有复杂场景理解的创意 T2I 生成** |
|
|
| > Prompt: 3D 毛绒质感拟人化马,暖棕浅棕肌理,穿藏蓝西装、白衬衫,戴深棕手套;疲惫带期待,坐于电脑前,旁置印 "HAPPY AGAIN" 的马克杯。橙红渐变背景,配超大号藏蓝粗体 "马上下班",叠加米黄 "Happy New Year" 并标 "(2026)"。橙红为主,藏蓝米黄撞色,毛绒温暖柔和。 |
|
|
| <div align="center"> |
| <img src="./assets/pg_instruct_imgs/image0.png" alt="HunyuanImage-3.0-Instruct Showcase 2" width="75%"> |
| </div> |
|
|
| **展示 3: 精确图像编辑与元素保留** |
|
|
| <div align="center"> |
| <img src="./assets/pg_instruct_imgs/image1.png" alt="HunyuanImage-3.0-Instruct Showcase 3" width="85%"> |
| </div> |
|
|
| **展示 4: 风格转换与主题增强** |
|
|
| <div align="center"> |
| <img src="./assets/pg_instruct_imgs/image2.png" alt="HunyuanImage-3.0-Instruct Showcase 4" width="85%"> |
| </div> |
|
|
|
|
| **展示 5: 高级风格转换与产品效果图生成** |
|
|
| <div align="center"> |
| <img src="./assets/pg_instruct_imgs/image3.png" alt="HunyuanImage-3.0-Instruct Showcase 5" width="85%"> |
| </div> |
|
|
|
|
| **展示 6: 多图像融合与创意合成** |
|
|
| <div align="center"> |
| <img src="./assets/pg_instruct_imgs/image4.png" alt="HunyuanImage-3.0-Instruct Showcase 6" width="85%"> |
| </div> |
|
|
| ## 📚 引用 |
|
|
| 如果您在研究中发现 HunyuanImage-3.0 有用,请引用我们的工作: |
|
|
| ```bibtex |
| @article{cao2025hunyuanimage, |
| title={HunyuanImage 3.0 Technical Report}, |
| author={Cao, Siyu and Chen, Hangting and Chen, Peng and Cheng, Yiji and Cui, Yutao and Deng, Xinchi and Dong, Ying and Gong, Kipper and Gu, Tianpeng and Gu, Xiusen and others}, |
| journal={arXiv preprint arXiv:2509.23951}, |
| year={2025} |
| } |
| ``` |
|
|
| ## 🙏 致谢 |
|
|
| 我们衷心感谢以下开源项目和社区的宝贵贡献: |
|
|
| * 🤗 [Transformers](https://github.com/huggingface/transformers) - 最先进的 NLP 库 |
| * 🎨 [Diffusers](https://github.com/huggingface/diffusers) - 扩散模型库 |
| * 🌐 [HuggingFace](https://huggingface.co/) - AI 模型中心和社区 |
| * ⚡ [FlashAttention](https://github.com/Dao-AILab/flash-attention) - 内存高效的注意力机制 |
| * 🚀 [FlashInfer](https://github.com/flashinfer-ai/flashinfer) - 优化的推理引擎 |
|
|
| ## 🌟🚀 GitHub Star 历史 |
|
|
| [](https://github.com/Tencent-Hunyuan/HunyuanImage-3.0) |
| [](https://github.com/Tencent-Hunyuan/HunyuanImage-3.0) |
|
|
| [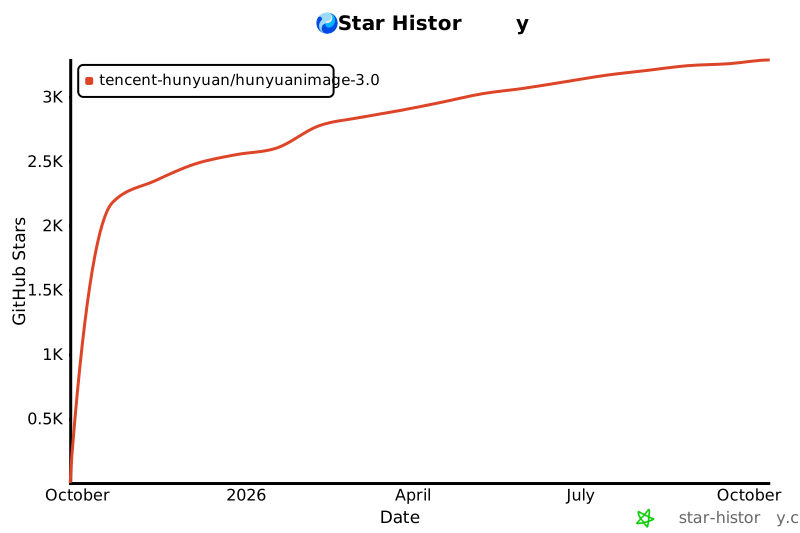](https://www.star-history.com/#Tencent-Hunyuan/HunyuanImage-3.0&Date) |
|
|