


Update embeddinggemma-300m-memory-ft-v2 documentation
Browse files- README.md +31 -26
- evaluation/README.md +78 -62
- evaluation/figures.py +21 -29
- evaluation/metrics.py +112 -63
- evaluation/promotion-summary.json +228 -1
- evaluation/retriever-summary.json +160 -74
- evaluation/retriever.json +0 -0
- evaluation/serving-summary.json +190 -1
- figures/gemma-comparison.svg +120 -77
- publication-manifest.json +34 -34
README.md
CHANGED
|
@@ -22,7 +22,7 @@ tags:
|
|
| 22 |
|
| 23 |
An English embedding model for finding the passages that answer a question in notes, procedures, decision records and technical documentation. It is a fine-tune of [Google's EmbeddingGemma-300M](https://huggingface.co/google/embeddinggemma-300m), packaged as one ONNX graph with pooling and normalization built in, so it runs locally without PyTorch.
|
| 24 |
|
| 25 |
-
On Daecore's dense-retrieval panel, v2
|
| 26 |
|
| 27 |
Embed queries and passages with the same revision, and re-embed stored passages when switching to v2.
|
| 28 |
|
|
@@ -84,31 +84,34 @@ standalone embedder with other retrieval systems.
|
|
| 84 |
|
| 85 |
### Gemma alone: dense retrieval on Daecore data
|
| 86 |
|
| 87 |
-
Both models search the same **
|
| 88 |
-
|
| 89 |
-
|
| 90 |
-
|
| 91 |
|
| 92 |
-
| Cutoff | Hit | Precision |
|
| 93 |
-
|---|---:|---:|---:|
|
| 94 |
-
|
|
| 95 |
-
|
|
| 96 |
-
|
|
| 97 |
-
|
|
|
|
|
| 98 |
|
| 99 |

|
| 100 |
|
| 101 |
-
|
| 102 |
-
|
| 103 |
-
|
| 104 |
-
|
| 105 |
-
|
|
|
|
| 106 |
|
| 107 |
-
|
| 108 |
-
|
| 109 |
-
|
| 110 |
-
text
|
| 111 |
-
includes
|
|
|
|
| 112 |
|
| 113 |
### Gemma alone: public dense retrieval
|
| 114 |
|
|
@@ -155,15 +158,17 @@ shared by the Gemma and Ettin cards; it is not either model's standalone score.
|
|
| 155 |
|
| 156 |
| Return depth | Hit | Precision | Known-positive recall | nDCG |
|
| 157 |
|---|---:|---:|---:|---:|
|
|
|
|
| 158 |
| 3 | 85.36% | 71.58% | 9.52% | 0.6577 |
|
| 159 |
| 5 | 88.45% | 70.28% | 15.38% | 0.6555 |
|
| 160 |
| 10 | 89.90% | 67.18% | 28.03% | 0.6611 |
|
| 161 |
| 20 | 91.03% | 61.79% | 48.85% | 0.6841 |
|
| 162 |
|
| 163 |
-
Grades 2–3 count as useful.
|
| 164 |
-
|
| 165 |
-
|
| 166 |
-
|
|
|
|
| 167 |
from the top 20 without backfilling. Daecore's selector chooses a prefix of
|
| 168 |
3–20; these fixed-depth scores do not evaluate that choice. The
|
| 169 |
[evaluation companion](evaluation/README.md) provides the
|
|
@@ -224,7 +229,7 @@ Vulkan runs through the native ONNX Runtime WebGPU plugin, [`onnxruntime-ep-webg
|
|
| 224 |
|
| 225 |
Checks used Windows x64 with an NVIDIA RTX 3060 Ti (8 GB); other GPUs and Linux are untested, even where Vulkan is available.
|
| 226 |
|
| 227 |
-
The task-specific data is mostly generated and model-judged, with no human reference panel, so it describes this development distribution rather than other users' documents. The dense
|
| 228 |
|
| 229 |
## License
|
| 230 |
|
|
|
|
| 22 |
|
| 23 |
An English embedding model for finding the passages that answer a question in notes, procedures, decision records and technical documentation. It is a fine-tune of [Google's EmbeddingGemma-300M](https://huggingface.co/google/embeddinggemma-300m), packaged as one ONNX graph with pooling and normalization built in, so it runs locally without PyTorch.
|
| 24 |
|
| 25 |
+
On Daecore's **970-query dense-retrieval panel**, v2 raises nDCG@10 from **0.4506 to 0.5748** and precision@10 from **47.40% to 61.18%** compared with upstream Gemma. Both models search the same 82,719 passages, with reviewed labels through rank 20. V2 also recovers more than half of the first Daecore fine-tune's measured loss on FiQA and SciFact.
|
| 26 |
|
| 27 |
Embed queries and passages with the same revision, and re-embed stored passages when switching to v2.
|
| 28 |
|
|
|
|
| 84 |
|
| 85 |
### Gemma alone: dense retrieval on Daecore data
|
| 86 |
|
| 87 |
+
Both models search the same **82,719 passages for all 970 queries**, using FP32
|
| 88 |
+
exact dense retrieval, the same frozen query forms and matched 128/1,024-token
|
| 89 |
+
input limits. BM25 and Ettin do not contribute to these results. Each cell
|
| 90 |
+
reads upstream → **Daecore v2**.
|
| 91 |
|
| 92 |
+
| Cutoff | Hit | Precision | Known-positive recall | nDCG |
|
| 93 |
+
|---|---:|---:|---:|---:|
|
| 94 |
+
| 1 | 53.40% → **64.74%** | 53.40% → **64.74%** | 1.94% → **2.46%** | 0.4695 → **0.5421** |
|
| 95 |
+
| 3 | 72.99% → **79.38%** | 50.83% → **63.08%** | 5.43% → **6.95%** | 0.4516 → **0.5524** |
|
| 96 |
+
| 5 | 79.48% → **84.74%** | 49.95% → **62.66%** | 8.53% → **11.09%** | 0.4457 → **0.5586** |
|
| 97 |
+
| 10 | 84.85% → **88.14%** | 47.40% → **61.18%** | 15.77% → **20.82%** | 0.4506 → **0.5748** |
|
| 98 |
+
| 20 | 88.76% → **90.52%** | 43.94% → **58.11%** | 28.08% → **38.65%** | 0.4736 → **0.6065** |
|
| 99 |
|
| 100 |

|
| 101 |
|
| 102 |
+
Every top-20 position has a relevance grade or a declared judging abstention;
|
| 103 |
+
there are no missing-label ranges. All 970 queries remain eligible at every
|
| 104 |
+
cutoff. At rank 20, 56 upstream positions and 53 v2 positions are excluded,
|
| 105 |
+
without pulling in deeper results. Precision pools retained positions;
|
| 106 |
+
known-positive recall averages the 911 queries with judged useful evidence.
|
| 107 |
+
The corpus is not exhaustively labeled.
|
| 108 |
|
| 109 |
+
Grades 2–3 count as useful. nDCG uses gains 0, 1, 3 and 7 against the same
|
| 110 |
+
reviewed reference for both models, averaging all 970 queries. Rankings from
|
| 111 |
+
query forms are combined with reciprocal-rank fusion, and identical passage
|
| 112 |
+
text is deduplicated. The [evaluation companion](evaluation/README.md)
|
| 113 |
+
includes anonymized grades, model identities, label coverage and metric code.
|
| 114 |
+
This is a reused development panel, not an untouched test of new workspaces.
|
| 115 |
|
| 116 |
### Gemma alone: public dense retrieval
|
| 117 |
|
|
|
|
| 158 |
|
| 159 |
| Return depth | Hit | Precision | Known-positive recall | nDCG |
|
| 160 |
|---|---:|---:|---:|---:|
|
| 161 |
+
| 1 | 72.33% | 72.33% | 3.46% | 0.6646 |
|
| 162 |
| 3 | 85.36% | 71.58% | 9.52% | 0.6577 |
|
| 163 |
| 5 | 88.45% | 70.28% | 15.38% | 0.6555 |
|
| 164 |
| 10 | 89.90% | 67.18% | 28.03% | 0.6611 |
|
| 165 |
| 20 | 91.03% | 61.79% | 48.85% | 0.6841 |
|
| 166 |
|
| 167 |
+
Grades 2–3 count as useful. Depth 1 uses the same 965 queries for both
|
| 168 |
+
providers: five are omitted because at least one first result was ungradable.
|
| 169 |
+
At depths 3–20, Hit and nDCG average all 970 queries. Precision pools retained
|
| 170 |
+
positions. Recall averages known-positive queries (890 at depth 1; 895 at
|
| 171 |
+
depths 3–20) and measures judged passages, not every useful passage in the corpus. A shared judging-exclusion set removes 52 positions
|
| 172 |
from the top 20 without backfilling. Daecore's selector chooses a prefix of
|
| 173 |
3–20; these fixed-depth scores do not evaluate that choice. The
|
| 174 |
[evaluation companion](evaluation/README.md) provides the
|
|
|
|
| 229 |
|
| 230 |
Checks used Windows x64 with an NVIDIA RTX 3060 Ti (8 GB); other GPUs and Linux are untested, even where Vulkan is available.
|
| 231 |
|
| 232 |
+
The task-specific data is mostly generated and model-judged, with no human reference panel, so it describes this development distribution rather than other users' documents. The dense and full-pipeline panels use the same queries but different judgment pools; compare models within each table. Some questions omit the project or task context needed for an unambiguous judgment. The 970-query pipeline panel uses natural-language questions and reports no separate terse-query or paraphrase robustness scores. Passage relevance does not measure distinct-fact coverage or downstream agent success.
|
| 233 |
|
| 234 |
## License
|
| 235 |
|
evaluation/README.md
CHANGED
|
@@ -1,50 +1,63 @@
|
|
| 1 |
-
# EmbeddingGemma v2 evaluation
|
| 2 |
-
|
| 3 |
These records support the [model card's](../README.md) results: Gemma's dense retrieval on private and public data, its smaller embedding widths, and the full retrieval pipeline. They contain scores and anonymized relevance grades, without private queries or document text.
|
| 4 |
-
|
| 5 |
-
| File | Contents |
|
| 6 |
-
|---|---|
|
| 7 |
-
| `retriever.json` | Upstream and v2 top-20
|
| 8 |
| `dimensions.json` | V2 per-query public nDCG@10 at 768, 512, 256 and 128 dimensions |
|
| 9 |
| `promotion.json` | Ranked grades for the predecessor-to-v2 pipeline comparison and public nDCG@10 for upstream and v2 |
|
| 10 |
| `serving.json` | The 970-query Gemma v2 + BM25 + Ettin replay used by both model cards, including CUDA/Vulkan results |
|
| 11 |
| `*-summary.json` | Summaries that `metrics.py` reproduces |
|
| 12 |
-
| `serving-qualification.json` | CPU, CUDA and Vulkan serving checks for this model |
|
| 13 |
| `metrics.py` | Metric code |
|
| 14 |
| `figures.py`, `svg_figures.py` | Code to regenerate the Gemma comparison figure |
|
| 15 |
-
|
| 16 |
-
## Reproduce the tables
|
| 17 |
-
|
| 18 |
-
From this directory, run with Python 3.11 or later:
|
| 19 |
-
|
| 20 |
-
```sh
|
| 21 |
python metrics.py --directory .
|
| 22 |
python figures.py --output ../figures
|
| 23 |
-
```
|
| 24 |
-
|
| 25 |
No packages or network access are needed. Each result matches its corresponding summary. This recomputes metrics from saved results; running private retrieval again would require the private corpus.
|
| 26 |
-
|
| 27 |
## Dense retrieval
|
| 28 |
|
| 29 |
-
**Private data.** `retriever.json` compares upstream Gemma with v2 on
|
| 30 |
-
|
| 31 |
-
|
| 32 |
-
|
| 33 |
-
with
|
| 34 |
-
|
| 35 |
-
|
| 36 |
-
|
| 37 |
-
|
| 38 |
-
|
| 39 |
-
|
| 40 |
-
|
| 41 |
-
|
| 42 |
-
|
| 43 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 44 |
|
| 45 |
**Public data.**
|
| 46 |
The model card compares v2 with upstream EmbeddingGemma on SciFact, FiQA, NFCorpus, SciDocs and ArguAna. `promotion.json` includes per-query nDCG@10 for all five datasets, using full corpora, matched preprocessing and official relevance judgments. V2 remains below upstream on every panel. The previous fine-tune was measured only on FiQA (0.4009) and SciFact (0.7679); its other three results are absent, not estimated.
|
| 47 |
-
|
| 48 |
These datasets supplied no training examples, but informed development. They are not untouched tests.
|
| 49 |
|
| 50 |
**Matryoshka widths.** `dimensions.json` contains per-query scores from new exact
|
|
@@ -61,9 +74,11 @@ panels and do not shorten the encoder's forward pass.
|
|
| 61 |
|
| 62 |
The identical full-pipeline table on both model cards comes from `serving.json`:
|
| 63 |
Gemma v2 + BM25 + fusion + unchanged Ettin on all 970 queries, using CUDA FP16
|
| 64 |
-
for reranking. Hit and nDCG average all queries
|
| 65 |
-
|
| 66 |
-
|
|
|
|
|
|
|
| 67 |
reference. Its shared judging-exclusion set removes 52 top-20 positions per
|
| 68 |
provider without backfilling. Fixed cutoffs measure ranking independently of
|
| 69 |
the selector's choice of a 3–20-item prefix. Vulkan matches CUDA at Hit@5,
|
|
@@ -71,34 +86,35 @@ Hit@10 and Hit@20; Hit@3 differs by one query and nDCG@10 by 0.0004.
|
|
| 71 |
|
| 72 |
The separate predecessor comparison below comes from `promotion.json`.
|
| 73 |
Only the embedding model changed in this comparison. BM25, reciprocal-rank fusion and the [Ettin reranker](https://huggingface.co/Daecore/ettin-150m-memory-reranker-ft-v1) stayed fixed. The same score mapping selected returned prefixes in both arms. These results measure the whole pipeline on 970 reused queries over 82,719 passage texts, rather than Gemma alone.
|
| 74 |
-
|
| 75 |
-
| Metric | Previous Gemma | Gemma v2 |
|
| 76 |
-
|---|---:|---:|
|
| 77 |
-
| Hit@
|
| 78 |
-
| Hit@
|
| 79 |
-
| Hit@
|
| 80 |
-
| Hit@
|
| 81 |
-
|
|
| 82 |
-
|
|
| 83 |
-
|
| 84 |
-
|
| 85 |
-
|
| 86 |
-
|
| 87 |
-
|
| 88 |
-
|
| 89 |
-
|
| 90 |
-
|
| 91 |
-
|
| 92 |
-
questions
|
| 93 |
-
|
| 94 |
-
|
|
|
|
| 95 |
balanced terse-query or paraphrase benchmark. Training-query diversity is a
|
| 96 |
separate claim from measured robustness on each query style. Dense retrieval
|
| 97 |
can also serve keyword and identifier queries; “dense-only” identifies the
|
| 98 |
retrieval method, not the query format.
|
| 99 |
-
|
| 100 |
-
## Serving checks and limits
|
| 101 |
-
|
| 102 |
-
`serving-qualification.json` records this model's CPU, CUDA and Vulkan checks. The 74-vector panel covers token limits, mixed lengths and concurrent query and passage calls. It is a bounded serving check, separate from retrieval quality.
|
| 103 |
-
|
| 104 |
-
The private documents and labels are mostly model-generated. Project-document sources come from one person's workspaces and are often AI-written. The panel was reused during development, training was run once, and there is no human reference panel. These results do not establish generalization across users, unique-fact coverage or downstream agent success.
|
|
|
|
| 1 |
+
# EmbeddingGemma v2 evaluation
|
| 2 |
+
|
| 3 |
These records support the [model card's](../README.md) results: Gemma's dense retrieval on private and public data, its smaller embedding widths, and the full retrieval pipeline. They contain scores and anonymized relevance grades, without private queries or document text.
|
| 4 |
+
|
| 5 |
+
| File | Contents |
|
| 6 |
+
|---|---|
|
| 7 |
+
| `retriever.json` | Upstream and v2 reviewed top-20 dense rankings for all 970 queries over 82,719 passages |
|
| 8 |
| `dimensions.json` | V2 per-query public nDCG@10 at 768, 512, 256 and 128 dimensions |
|
| 9 |
| `promotion.json` | Ranked grades for the predecessor-to-v2 pipeline comparison and public nDCG@10 for upstream and v2 |
|
| 10 |
| `serving.json` | The 970-query Gemma v2 + BM25 + Ettin replay used by both model cards, including CUDA/Vulkan results |
|
| 11 |
| `*-summary.json` | Summaries that `metrics.py` reproduces |
|
| 12 |
+
| `serving-qualification.json` | CPU, CUDA and Vulkan serving checks for this model |
|
| 13 |
| `metrics.py` | Metric code |
|
| 14 |
| `figures.py`, `svg_figures.py` | Code to regenerate the Gemma comparison figure |
|
| 15 |
+
|
| 16 |
+
## Reproduce the tables
|
| 17 |
+
|
| 18 |
+
From this directory, run with Python 3.11 or later:
|
| 19 |
+
|
| 20 |
+
```sh
|
| 21 |
python metrics.py --directory .
|
| 22 |
python figures.py --output ../figures
|
| 23 |
+
```
|
| 24 |
+
|
| 25 |
No packages or network access are needed. Each result matches its corresponding summary. This recomputes metrics from saved results; running private retrieval again would require the private corpus.
|
| 26 |
+
|
| 27 |
## Dense retrieval
|
| 28 |
|
| 29 |
+
**Private data.** `retriever.json` compares upstream Gemma with v2 on all 970
|
| 30 |
+
queries over the same 82,719 passage texts. Both use FP32 inference, the same
|
| 31 |
+
prefixes and 128-query/1,024-passage token limits, and 768 dimensions. Exact
|
| 32 |
+
cosine rankings take the top 50 for each frozen query form, then merge them
|
| 33 |
+
with reciprocal-rank fusion (constant 60). Identical text is deduplicated;
|
| 34 |
+
there is no parent-document filter, BM25 or reranker. The record includes
|
| 35 |
+
model identities, source hashes, top-20 grades and reference grade counts.
|
| 36 |
+
This is a reused development panel, not a fresh holdout.
|
| 37 |
+
|
| 38 |
+
Completing the comparison required 11,480 new pair decisions. Two independent
|
| 39 |
+
GPT-6 Sol judges graded each pair, and a fresh blind judgment resolved 3,207
|
| 40 |
+
ordinal disagreements. The primary assistant read 179 complete query–passage
|
| 41 |
+
pairs: all 18 final quote flags, all 72 abstentions, and samples spanning every
|
| 42 |
+
primary grade combination. The 18 quote repairs changed no grades. The result
|
| 43 |
+
adds 11,408 grades to a shared reference containing 87,434 known pairs. No
|
| 44 |
+
person reviewed these judgments, and the corpus is not exhaustively labeled.
|
| 45 |
+
|
| 46 |
+
Every top-20 position is graded or explicitly excluded as ungradable; no
|
| 47 |
+
missing-label bounds remain. Cutoffs 1, 3, 5, 10 and 20 retain all 970 queries.
|
| 48 |
+
At rank 20, the upstream lists exclude 56 positions and v2 excludes 53.
|
| 49 |
+
Cut first, drop abstentions second, and never backfill. A wholly abstained
|
| 50 |
+
prefix would omit that query from both models at that cutoff; none occurs in
|
| 51 |
+
this comparison. Precision pools retained positions. Recall averages the 911
|
| 52 |
+
queries with known useful passages. nDCG uses gains 0, 1, 3 and 7 against the
|
| 53 |
+
same reference for both models, reindexes retained positions, and averages
|
| 54 |
+
all 970 queries; an ideal gain of zero contributes zero. The dense reference
|
| 55 |
+
is larger than the pipeline reference below, so compare models within each
|
| 56 |
+
table rather than treating their nDCG values as one common scale.
|
| 57 |
|
| 58 |
**Public data.**
|
| 59 |
The model card compares v2 with upstream EmbeddingGemma on SciFact, FiQA, NFCorpus, SciDocs and ArguAna. `promotion.json` includes per-query nDCG@10 for all five datasets, using full corpora, matched preprocessing and official relevance judgments. V2 remains below upstream on every panel. The previous fine-tune was measured only on FiQA (0.4009) and SciFact (0.7679); its other three results are absent, not estimated.
|
| 60 |
+
|
| 61 |
These datasets supplied no training examples, but informed development. They are not untouched tests.
|
| 62 |
|
| 63 |
**Matryoshka widths.** `dimensions.json` contains per-query scores from new exact
|
|
|
|
| 74 |
|
| 75 |
The identical full-pipeline table on both model cards comes from `serving.json`:
|
| 76 |
Gemma v2 + BM25 + fusion + unchanged Ettin on all 970 queries, using CUDA FP16
|
| 77 |
+
for reranking. At depths 3–20, Hit and nDCG average all queries, and
|
| 78 |
+
known-positive recall averages the 895 with judged useful evidence. Depth 1
|
| 79 |
+
uses 965 shared judged queries, including 890 with known positives; five
|
| 80 |
+
queries are omitted from both providers because a first result was ungradable.
|
| 81 |
+
Precision pools retained positions. The serving reference adds 32 grades to the earlier promotion
|
| 82 |
reference. Its shared judging-exclusion set removes 52 top-20 positions per
|
| 83 |
provider without backfilling. Fixed cutoffs measure ranking independently of
|
| 84 |
the selector's choice of a 3–20-item prefix. Vulkan matches CUDA at Hit@5,
|
|
|
|
| 86 |
|
| 87 |
The separate predecessor comparison below comes from `promotion.json`.
|
| 88 |
Only the embedding model changed in this comparison. BM25, reciprocal-rank fusion and the [Ettin reranker](https://huggingface.co/Daecore/ettin-150m-memory-reranker-ft-v1) stayed fixed. The same score mapping selected returned prefixes in both arms. These results measure the whole pipeline on 970 reused queries over 82,719 passage texts, rather than Gemma alone.
|
| 89 |
+
|
| 90 |
+
| Metric | Previous Gemma | Gemma v2 |
|
| 91 |
+
|---|---:|---:|
|
| 92 |
+
| Hit@1 (964 queries) | 72.61% | 72.30% |
|
| 93 |
+
| Hit@3 | 83.92% | 85.36% |
|
| 94 |
+
| Hit@5 | 85.88% | 88.45% |
|
| 95 |
+
| Hit@10 | 87.84% | 89.90% |
|
| 96 |
+
| Hit@20 | 90.10% | 91.03% |
|
| 97 |
+
| nDCG@10 | 0.6764 | 0.6611 |
|
| 98 |
+
| Selected-prefix precision | 80.41% | 80.34% |
|
| 99 |
+
|
| 100 |
+
V2 found useful evidence for more queries, while the previous model placed higher-grade passages earlier. Seven reviewed grade corrections apply to both arms. Depths 3–20 retain all 970 queries; depth 1 omits the same six queries from both models. A shared set contains 65 unresolved query–passage judgments. Members of that set are excluded wherever they occur within an original cutoff, without filling their positions with lower-ranked passages. The record preserves those positions as `null` with an `excluded` flag.
|
| 101 |
+
|
| 102 |
+
Grades 2 and 3 count as useful. Hit@k is the fraction of queries with useful evidence in the first k positions. Precision pools useful passages over retained positions. nDCG uses gain `2**grade - 1` and logarithmic rank discount; it reindexes retained passages and draws the ideal ranking from `reference_grade_counts`. Recall counts known useful passages, not distinct facts. Ties preserve candidate order.
|
| 103 |
+
|
| 104 |
+
## Query coverage
|
| 105 |
+
|
| 106 |
+
The shared 970-query panel contains 620 generated-source questions, 200
|
| 107 |
+
questions written with potentially absent evidence, and 150 project-document
|
| 108 |
+
questions. These are natural-language questions. In the pipeline replay, 483
|
| 109 |
+
use the original query alone; 487 multipart queries also use two deterministic
|
| 110 |
+
subquestions. This exercises hybrid retrieval but does not provide a separately
|
| 111 |
balanced terse-query or paraphrase benchmark. Training-query diversity is a
|
| 112 |
separate claim from measured robustness on each query style. Dense retrieval
|
| 113 |
can also serve keyword and identifier queries; “dense-only” identifies the
|
| 114 |
retrieval method, not the query format.
|
| 115 |
+
|
| 116 |
+
## Serving checks and limits
|
| 117 |
+
|
| 118 |
+
`serving-qualification.json` records this model's CPU, CUDA and Vulkan checks. The 74-vector panel covers token limits, mixed lengths and concurrent query and passage calls. It is a bounded serving check, separate from retrieval quality.
|
| 119 |
+
|
| 120 |
+
The private documents and labels are mostly model-generated. Project-document sources come from one person's workspaces and are often AI-written. The panel was reused during development, training was run once, and there is no human reference panel. These results do not establish generalization across users, unique-fact coverage or downstream agent success.
|
evaluation/figures.py
CHANGED
|
@@ -1,4 +1,4 @@
|
|
| 1 |
-
"""Regenerate model comparison SVGs from
|
| 2 |
|
| 3 |
Run with Python 3.11+: python figures.py --output ../figures
|
| 4 |
The repository shares its renderer from eval/lib; HF packages include that
|
|
@@ -27,8 +27,7 @@ spec.loader.exec_module(svg)
|
|
| 27 |
UPSTREAM, FIT, REFERENCE = '#0072B2', '#D55E00', '#777777'
|
| 28 |
|
| 29 |
|
| 30 |
-
def classifier(
|
| 31 |
-
summary = metrics.summarize_classifier(data)
|
| 32 |
facets = [*metrics.FACETS, 'macro']
|
| 33 |
def values(model):
|
| 34 |
result = summary['models'][model]
|
|
@@ -45,9 +44,8 @@ def classifier(data: dict) -> str:
|
|
| 45 |
)
|
| 46 |
|
| 47 |
|
| 48 |
-
def reranker(
|
| 49 |
-
|
| 50 |
-
cutoffs = [k for k in metrics.CUTOFFS if k >= 3]
|
| 51 |
definitions = [('hit', 'At least one useful passage'), ('precision', 'Useful passages / returned passages'), ('ndcg', 'Graded ranking quality')]
|
| 52 |
panels = []
|
| 53 |
legend = [('Upstream', UPSTREAM, None), ('Daecore fine-tune', FIT, None), ('Random pool order', REFERENCE, '5 3')]
|
|
@@ -64,29 +62,23 @@ def reranker(data: dict) -> str:
|
|
| 64 |
legend=legend, panel_width=300, panel_height=270)
|
| 65 |
|
| 66 |
|
| 67 |
-
def retriever(
|
| 68 |
-
|
| 69 |
-
cutoffs = [3, 5, 10, 20]
|
| 70 |
x = list(range(len(cutoffs)))
|
| 71 |
panels = []
|
|
|
|
| 72 |
for field, title in [('hit', 'Find at least one useful passage'),
|
| 73 |
-
('precision', '
|
| 74 |
-
|
| 75 |
-
|
| 76 |
-
|
| 77 |
-
panels.append(svg.Panel(title,
|
| 78 |
-
|
| 79 |
-
|
| 80 |
-
|
| 81 |
-
|
| 82 |
-
|
| 83 |
-
|
| 84 |
-
return svg.render_grid(panels, columns=2,
|
| 85 |
-
title='Gemma v2: stronger retrieval on Daecore data',
|
| 86 |
-
subtitle='376 known-answerable queries · 66,240 passages · dense retrieval only',
|
| 87 |
-
legend=[('Upstream: missing-label range', UPSTREAM, '5 3'),
|
| 88 |
-
('Daecore v2: top 20 fully judged', FIT, None)],
|
| 89 |
-
panel_width=430, panel_height=300)
|
| 90 |
|
| 91 |
|
| 92 |
def main() -> None:
|
|
@@ -101,13 +93,13 @@ def main() -> None:
|
|
| 101 |
'retriever': ('retriever', 'gemma-comparison.svg')}
|
| 102 |
names = [args.model] if args.model else [
|
| 103 |
name for name, (record, _) in definitions.items()
|
| 104 |
-
if (args.directory / f'{record}.json').is_file()
|
| 105 |
]
|
| 106 |
if not names:
|
| 107 |
-
parser.error('No model comparison
|
| 108 |
for name in names:
|
| 109 |
record, filename = definitions[name]
|
| 110 |
-
data = json.loads((args.directory / f'{record}.json').read_text(encoding='utf-8'))
|
| 111 |
(args.output / filename).write_text(globals()[name](data), encoding='utf-8', newline='\n')
|
| 112 |
|
| 113 |
|
|
|
|
| 1 |
+
"""Regenerate model comparison SVGs from the published summaries.
|
| 2 |
|
| 3 |
Run with Python 3.11+: python figures.py --output ../figures
|
| 4 |
The repository shares its renderer from eval/lib; HF packages include that
|
|
|
|
| 27 |
UPSTREAM, FIT, REFERENCE = '#0072B2', '#D55E00', '#777777'
|
| 28 |
|
| 29 |
|
| 30 |
+
def classifier(summary: dict) -> str:
|
|
|
|
| 31 |
facets = [*metrics.FACETS, 'macro']
|
| 32 |
def values(model):
|
| 33 |
result = summary['models'][model]
|
|
|
|
| 44 |
)
|
| 45 |
|
| 46 |
|
| 47 |
+
def reranker(summary: dict) -> str:
|
| 48 |
+
cutoffs = list(metrics.CUTOFFS)
|
|
|
|
| 49 |
definitions = [('hit', 'At least one useful passage'), ('precision', 'Useful passages / returned passages'), ('ndcg', 'Graded ranking quality')]
|
| 50 |
panels = []
|
| 51 |
legend = [('Upstream', UPSTREAM, None), ('Daecore fine-tune', FIT, None), ('Random pool order', REFERENCE, '5 3')]
|
|
|
|
| 62 |
legend=legend, panel_width=300, panel_height=270)
|
| 63 |
|
| 64 |
|
| 65 |
+
def retriever(summary: dict) -> str:
|
| 66 |
+
cutoffs = [1, 3, 5, 10, 20]
|
|
|
|
| 67 |
x = list(range(len(cutoffs)))
|
| 68 |
panels = []
|
| 69 |
+
legend = [('Upstream Gemma', UPSTREAM, None), ('Daecore v2', FIT, None)]
|
| 70 |
for field, title in [('hit', 'Find at least one useful passage'),
|
| 71 |
+
('precision', 'Useful passages / retained passages'),
|
| 72 |
+
('ndcg', 'Graded ranking quality')]:
|
| 73 |
+
series = [svg.Series(label, x, [summary['models'][name][str(k)][field] for k in cutoffs], color)
|
| 74 |
+
for name, (label, color, _) in zip(('upstream', 'finetuned'), legend, strict=True)]
|
| 75 |
+
panels.append(svg.Panel(title, series, xlabel='rank cutoff',
|
| 76 |
+
ylabel={'hit': 'Hit@k', 'precision': 'Precision@k', 'ndcg': 'nDCG@k'}[field],
|
| 77 |
+
xlim=(0, len(cutoffs) - 1), ylim=(0, 1.02), xticks=list(enumerate(map(str, cutoffs)))))
|
| 78 |
+
return svg.render_grid(panels, columns=3,
|
| 79 |
+
title='Gemma v2: matched dense retrieval on Daecore data',
|
| 80 |
+
subtitle=f"{summary['queries']:,} queries · {summary['corpus_passages']:,} passages · reviewed abstentions excluded",
|
| 81 |
+
legend=legend, panel_width=300, panel_height=270)
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 82 |
|
| 83 |
|
| 84 |
def main() -> None:
|
|
|
|
| 93 |
'retriever': ('retriever', 'gemma-comparison.svg')}
|
| 94 |
names = [args.model] if args.model else [
|
| 95 |
name for name, (record, _) in definitions.items()
|
| 96 |
+
if (args.directory / f'{record}-summary.json').is_file()
|
| 97 |
]
|
| 98 |
if not names:
|
| 99 |
+
parser.error('No model comparison summaries found in the selected directory')
|
| 100 |
for name in names:
|
| 101 |
record, filename = definitions[name]
|
| 102 |
+
data = json.loads((args.directory / f'{record}-summary.json').read_text(encoding='utf-8'))
|
| 103 |
(args.output / filename).write_text(globals()[name](data), encoding='utf-8', newline='\n')
|
| 104 |
|
| 105 |
|
evaluation/metrics.py
CHANGED
|
@@ -117,43 +117,11 @@ def summarize_reranker(data: dict) -> dict:
|
|
| 117 |
|
| 118 |
|
| 119 |
def summarize_retriever(data: dict) -> dict:
|
| 120 |
-
"""
|
| 121 |
-
|
| 122 |
-
|
| 123 |
-
|
| 124 |
-
|
| 125 |
-
for model in data['model_order']:
|
| 126 |
-
cutoffs = {}
|
| 127 |
-
for k in (3, 5, 10, 20):
|
| 128 |
-
values = []
|
| 129 |
-
for row in rows:
|
| 130 |
-
counts = row['reference_grade_counts']
|
| 131 |
-
if set(counts) != {'0', '1', '2', '3'} or any(type(n) is not int or n < 0 for n in counts.values()):
|
| 132 |
-
raise ValueError('Reference grade counts must cover grades zero through three')
|
| 133 |
-
grades = row['ranked_grades'][model][:k]
|
| 134 |
-
if len(grades) != k or any(g is not None and (type(g) is not int or g not in range(4)) for g in grades):
|
| 135 |
-
raise ValueError('Dense rows must contain each ranked grade or null')
|
| 136 |
-
if counts['2'] + counts['3'] == 0:
|
| 137 |
-
raise ValueError('Dense comparison contains only known-answerable queries')
|
| 138 |
-
ideal = [g for g in (3, 2, 1, 0) for _ in range(min(counts[str(g)], k))][:k]
|
| 139 |
-
useful, unknown = sum(g is not None and g >= 2 for g in grades), grades.count(None)
|
| 140 |
-
values.append({
|
| 141 |
-
'hit_lower': float(useful > 0), 'hit_upper': float(useful + unknown > 0),
|
| 142 |
-
'precision_lower': useful / k, 'precision_upper': (useful + unknown) / k,
|
| 143 |
-
'unjudged_positions': unknown,
|
| 144 |
-
'ndcg': None if unknown else dcg(grades, k) / dcg(ideal, k),
|
| 145 |
-
})
|
| 146 |
-
cutoffs[str(k)] = {
|
| 147 |
-
field: mean(row[field] for row in values)
|
| 148 |
-
for field in ('hit_lower', 'hit_upper', 'precision_lower', 'precision_upper')
|
| 149 |
-
}
|
| 150 |
-
cutoffs[str(k)]['unjudged_positions'] = sum(row['unjudged_positions'] for row in values)
|
| 151 |
-
cutoffs[str(k)]['ndcg'] = (
|
| 152 |
-
None if any(row['ndcg'] is None for row in values)
|
| 153 |
-
else mean(row['ndcg'] for row in values)
|
| 154 |
-
)
|
| 155 |
-
output['models'][model] = cutoffs
|
| 156 |
-
return output
|
| 157 |
|
| 158 |
|
| 159 |
def summarize_dimensions(data: dict) -> dict:
|
|
@@ -178,36 +146,52 @@ def summarize_dimensions(data: dict) -> dict:
|
|
| 178 |
return {'queries': len(rows), 'vector_bytes_fp32': {str(w): w * 4 for w in widths}, 'public': panels}
|
| 179 |
|
| 180 |
|
| 181 |
-
def
|
| 182 |
-
"""
|
| 183 |
|
| 184 |
A null is permitted only for an explicitly excluded judging abstention.
|
| 185 |
Cut first, remove exclusions second, and never backfill from a deeper rank.
|
| 186 |
"""
|
| 187 |
rows = data['rows']
|
| 188 |
if not rows or len({row['id'] for row in rows}) != len(rows):
|
| 189 |
-
raise ValueError('
|
| 190 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 191 |
for model in data['model_order']:
|
| 192 |
cutoffs = {}
|
| 193 |
-
for cutoff in
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 194 |
per_query = []
|
| 195 |
-
for row in
|
| 196 |
counts = row['reference_grade_counts']
|
| 197 |
-
if set(counts) != {'0', '1', '2', '3'} or any(type(n) is not int or n < 0 for n in counts.values()):
|
| 198 |
-
raise ValueError('Reference grade counts must cover grades zero through three')
|
| 199 |
ranked = row['ranked_grades'][model]
|
| 200 |
excluded = row['excluded'][model]
|
| 201 |
depth = row['selected_depth'][model] if cutoff == 'selected' else cutoff
|
| 202 |
-
if (len(ranked) != 20 or len(excluded) != 20 or type(depth) is not int
|
| 203 |
-
or not 3 <= depth <= 20 or any(type(x) is not bool for x in excluded)):
|
| 204 |
-
raise ValueError('Promotion rows require a bounded original top twenty')
|
| 205 |
-
if any((grade is not None if drop else type(grade) is not int or grade not in range(4))
|
| 206 |
-
for grade, drop in zip(ranked, excluded, strict=True)):
|
| 207 |
-
raise ValueError('Only declared abstentions may lack grades')
|
| 208 |
kept = [grade for grade, drop in zip(ranked[:depth], excluded[:depth], strict=True) if not drop]
|
| 209 |
-
if not kept:
|
| 210 |
-
raise ValueError('Every scored prefix must retain judged passages')
|
| 211 |
ideal_grades = [g for g in (3, 2, 1, 0) for _ in range(min(counts[str(g)], len(kept)))][:len(kept)]
|
| 212 |
useful = sum(g >= 2 for g in kept)
|
| 213 |
positives = counts['2'] + counts['3']
|
|
@@ -222,15 +206,22 @@ def summarize_promotion(data: dict) -> dict:
|
|
| 222 |
retained = sum(row['retained'] for row in per_query)
|
| 223 |
recalls = [row['known_recall'] for row in per_query if row['known_recall'] is not None]
|
| 224 |
cutoffs[str(cutoff)] = {
|
|
|
|
| 225 |
'hit': mean(row['hit'] for row in per_query), 'precision': useful / retained,
|
| 226 |
'macro_precision': mean(row['precision'] for row in per_query),
|
| 227 |
'ndcg': mean(row['ndcg'] for row in per_query),
|
| 228 |
'known_positive_recall': mean(recalls) if recalls else None,
|
| 229 |
'recall_queries': len(recalls), 'useful': useful, 'retained': retained,
|
| 230 |
'excluded_positions': sum(row['excluded'] for row in per_query),
|
| 231 |
-
'mean_useful': useful / len(
|
| 232 |
}
|
| 233 |
output['models'][model] = cutoffs
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 234 |
for dataset, panel in data['public'].items():
|
| 235 |
if not panel['rows'] or len({row['id'] for row in panel['rows']}) != len(panel['rows']):
|
| 236 |
raise ValueError('Public panel requires distinct query identities')
|
|
@@ -249,28 +240,86 @@ def summarize_promotion(data: dict) -> dict:
|
|
| 249 |
return output
|
| 250 |
|
| 251 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 252 |
def main() -> None:
|
| 253 |
parser = argparse.ArgumentParser(description=__doc__)
|
| 254 |
parser.add_argument("--directory", type=Path, default=Path(__file__).resolve().parent)
|
| 255 |
parser.add_argument("--output", type=Path)
|
| 256 |
parser.add_argument("--model", choices=("classifier", "reranker", "retriever", "dimensions", "promotion", "serving"), help="Recompute one comparison; default: every record in this package")
|
| 257 |
args = parser.parse_args()
|
| 258 |
-
summarizers = {"classifier": summarize_classifier, "reranker": summarize_reranker,
|
| 259 |
-
"retriever": summarize_retriever, "dimensions": summarize_dimensions,
|
| 260 |
-
"promotion": summarize_promotion, "serving": summarize_promotion}
|
| 261 |
names = [args.model] if args.model else [
|
| 262 |
-
name for name in
|
| 263 |
]
|
| 264 |
if not names:
|
| 265 |
parser.error("No evaluation records found in the selected directory")
|
| 266 |
result = {}
|
| 267 |
for name in names:
|
| 268 |
-
summarize = summarizers[name]
|
| 269 |
data = json.loads((args.directory / f"{name}.json").read_text(encoding="utf-8"))
|
| 270 |
-
|
| 271 |
-
if len(set(ids)) != len(ids):
|
| 272 |
-
raise ValueError(f"Repeated query/passage identity in {name}")
|
| 273 |
-
result[name] = summarize(data)
|
| 274 |
text = json.dumps(result, indent=2, allow_nan=False) + "\n"
|
| 275 |
if args.output:
|
| 276 |
args.output.write_text(text, encoding="utf-8")
|
|
|
|
| 117 |
|
| 118 |
|
| 119 |
def summarize_retriever(data: dict) -> dict:
|
| 120 |
+
"""Fully reviewed dense rankings, including queries without known positives."""
|
| 121 |
+
if type(data['corpus_passages']) is not int or data['corpus_passages'] <= 0:
|
| 122 |
+
raise ValueError('Dense comparison requires a positive corpus size')
|
| 123 |
+
return {**_summarize_ranked_grades(data, include_selected=False),
|
| 124 |
+
'corpus_passages': data['corpus_passages']}
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 125 |
|
| 126 |
|
| 127 |
def summarize_dimensions(data: dict) -> dict:
|
|
|
|
| 146 |
return {'queries': len(rows), 'vector_bytes_fp32': {str(w): w * 4 for w in widths}, 'public': panels}
|
| 147 |
|
| 148 |
|
| 149 |
+
def _summarize_ranked_grades(data: dict, *, include_selected: bool) -> dict:
|
| 150 |
+
"""Reviewed exclusions inside each original dense or hybrid prefix.
|
| 151 |
|
| 152 |
A null is permitted only for an explicitly excluded judging abstention.
|
| 153 |
Cut first, remove exclusions second, and never backfill from a deeper rank.
|
| 154 |
"""
|
| 155 |
rows = data['rows']
|
| 156 |
if not rows or len({row['id'] for row in rows}) != len(rows):
|
| 157 |
+
raise ValueError('Ranked rows require unique nonempty query identities')
|
| 158 |
+
# Validate before excluding fully abstained prefixes. An omitted query
|
| 159 |
+
# must never conceal a malformed grade, model map or selected depth.
|
| 160 |
+
for row in rows:
|
| 161 |
+
counts = row['reference_grade_counts']
|
| 162 |
+
if set(counts) != {'0', '1', '2', '3'} or any(type(n) is not int or n < 0 for n in counts.values()):
|
| 163 |
+
raise ValueError('Reference grade counts must cover grades zero through three')
|
| 164 |
+
for model in data['model_order']:
|
| 165 |
+
ranked, excluded = row['ranked_grades'][model], row['excluded'][model]
|
| 166 |
+
if (len(ranked) != 20 or len(excluded) != 20
|
| 167 |
+
or any(type(x) is not bool for x in excluded)):
|
| 168 |
+
raise ValueError('Ranked rows require a bounded original top twenty')
|
| 169 |
+
if include_selected:
|
| 170 |
+
depth = row['selected_depth'][model]
|
| 171 |
+
if type(depth) is not int or not 3 <= depth <= 20:
|
| 172 |
+
raise ValueError('Selected depth must be between three and twenty')
|
| 173 |
+
if any((grade is not None if drop else type(grade) is not int or grade not in range(4))
|
| 174 |
+
for grade, drop in zip(ranked, excluded, strict=True)):
|
| 175 |
+
raise ValueError('Only declared abstentions may lack grades')
|
| 176 |
+
output = {'queries': len(rows), 'models': {}}
|
| 177 |
+
requested_cutoffs = (1, 3, 5, 10, 20, 'selected') if include_selected else (1, 3, 5, 10, 20)
|
| 178 |
for model in data['model_order']:
|
| 179 |
cutoffs = {}
|
| 180 |
+
for cutoff in requested_cutoffs:
|
| 181 |
+
eligible = [row for row in rows if all(
|
| 182 |
+
any(not drop for drop in row['excluded'][arm][:(
|
| 183 |
+
row['selected_depth'][arm] if cutoff == 'selected' else cutoff)])
|
| 184 |
+
for arm in data['model_order']
|
| 185 |
+
)]
|
| 186 |
+
if not eligible:
|
| 187 |
+
raise ValueError('No shared judged queries at this cutoff')
|
| 188 |
per_query = []
|
| 189 |
+
for row in eligible:
|
| 190 |
counts = row['reference_grade_counts']
|
|
|
|
|
|
|
| 191 |
ranked = row['ranked_grades'][model]
|
| 192 |
excluded = row['excluded'][model]
|
| 193 |
depth = row['selected_depth'][model] if cutoff == 'selected' else cutoff
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 194 |
kept = [grade for grade, drop in zip(ranked[:depth], excluded[:depth], strict=True) if not drop]
|
|
|
|
|
|
|
| 195 |
ideal_grades = [g for g in (3, 2, 1, 0) for _ in range(min(counts[str(g)], len(kept)))][:len(kept)]
|
| 196 |
useful = sum(g >= 2 for g in kept)
|
| 197 |
positives = counts['2'] + counts['3']
|
|
|
|
| 206 |
retained = sum(row['retained'] for row in per_query)
|
| 207 |
recalls = [row['known_recall'] for row in per_query if row['known_recall'] is not None]
|
| 208 |
cutoffs[str(cutoff)] = {
|
| 209 |
+
'scored_queries': len(eligible), 'excluded_queries': len(rows) - len(eligible),
|
| 210 |
'hit': mean(row['hit'] for row in per_query), 'precision': useful / retained,
|
| 211 |
'macro_precision': mean(row['precision'] for row in per_query),
|
| 212 |
'ndcg': mean(row['ndcg'] for row in per_query),
|
| 213 |
'known_positive_recall': mean(recalls) if recalls else None,
|
| 214 |
'recall_queries': len(recalls), 'useful': useful, 'retained': retained,
|
| 215 |
'excluded_positions': sum(row['excluded'] for row in per_query),
|
| 216 |
+
'mean_useful': useful / len(eligible), 'mean_retained': retained / len(eligible),
|
| 217 |
}
|
| 218 |
output['models'][model] = cutoffs
|
| 219 |
+
return output
|
| 220 |
+
|
| 221 |
+
|
| 222 |
+
def summarize_promotion(data: dict) -> dict:
|
| 223 |
+
"""Hybrid rankings and the separately measured public dense panels."""
|
| 224 |
+
output = {**_summarize_ranked_grades(data, include_selected=True), 'public': {}}
|
| 225 |
for dataset, panel in data['public'].items():
|
| 226 |
if not panel['rows'] or len({row['id'] for row in panel['rows']}) != len(panel['rows']):
|
| 227 |
raise ValueError('Public panel requires distinct query identities')
|
|
|
|
| 240 |
return output
|
| 241 |
|
| 242 |
|
| 243 |
+
SUMMARIZERS = {
|
| 244 |
+
'classifier': summarize_classifier, 'reranker': summarize_reranker,
|
| 245 |
+
'retriever': summarize_retriever, 'dimensions': summarize_dimensions,
|
| 246 |
+
'promotion': summarize_promotion, 'serving': summarize_promotion,
|
| 247 |
+
}
|
| 248 |
+
|
| 249 |
+
|
| 250 |
+
def summarize_record(name: str, data: dict) -> dict:
|
| 251 |
+
"""Check anonymous publication records before recomputing their summary."""
|
| 252 |
+
fields = {
|
| 253 |
+
'classifier': {'id', 'group', 'labels', 'scores'},
|
| 254 |
+
'reranker': {'id', 'group', 'grades', 'scores'},
|
| 255 |
+
'retriever': {'id', 'group', 'reference_grade_counts', 'ranked_grades', 'excluded'},
|
| 256 |
+
'dimensions': {'id', 'dataset', 'ndcg@10'},
|
| 257 |
+
'promotion': {'id', 'group', 'reference_grade_counts', 'ranked_grades', 'excluded', 'selected_depth'},
|
| 258 |
+
'serving': {'id', 'group', 'reference_grade_counts', 'ranked_grades', 'excluded', 'selected_depth'},
|
| 259 |
+
}[name]
|
| 260 |
+
rows = data['rows']
|
| 261 |
+
if not rows or any(set(row) != fields for row in rows):
|
| 262 |
+
raise ValueError(f'Unexpected evaluation row fields in {name}')
|
| 263 |
+
ids = [row['id'] for row in rows]
|
| 264 |
+
if len(set(ids)) != len(ids):
|
| 265 |
+
raise ValueError(f'Repeated query/passage identity in {name}')
|
| 266 |
+
for row in rows:
|
| 267 |
+
identity = row['id']
|
| 268 |
+
if not isinstance(identity, str) or identity[:1] not in ('p', 'q') or not identity[1:].isdigit():
|
| 269 |
+
raise ValueError(f'Non-anonymous row identity in {name}')
|
| 270 |
+
if 'group' in row and (not isinstance(row['group'], str) or not row['group'].startswith('g') or not row['group'][1:].isdigit()):
|
| 271 |
+
raise ValueError(f'Non-anonymous group identity in {name}')
|
| 272 |
+
if name != 'dimensions' and set(data['model_order']) != set(data['models']):
|
| 273 |
+
raise ValueError(f'Model identities do not match in {name}')
|
| 274 |
+
models = set(data.get('model_order', ()))
|
| 275 |
+
for row in rows:
|
| 276 |
+
for field in ('scores', 'ranked_grades', 'excluded', 'selected_depth'):
|
| 277 |
+
if field in row and set(row[field]) != models:
|
| 278 |
+
raise ValueError(f'Unexpected model fields in {name}.{field}')
|
| 279 |
+
if name == 'classifier':
|
| 280 |
+
required = {facet for facet, label in row['labels'].items() if label is not None}
|
| 281 |
+
if set(row['labels']) != set(FACETS) or any(not required <= set(scores) <= set(FACETS) for scores in row['scores'].values()):
|
| 282 |
+
raise ValueError('Unexpected classifier facet fields')
|
| 283 |
+
if any(type(value) not in (int, float) or not math.isfinite(value)
|
| 284 |
+
for scores in row['scores'].values() for value in scores.values()):
|
| 285 |
+
raise ValueError('Classifier scores must be finite numbers, including unresolved facets')
|
| 286 |
+
for panel in data.get('public', {}).values():
|
| 287 |
+
if set(panel) != {'model_order', 'rows'} or not panel['rows']:
|
| 288 |
+
raise ValueError('Unexpected public-panel fields')
|
| 289 |
+
panel_models = set(panel['model_order'])
|
| 290 |
+
panel_ids = []
|
| 291 |
+
for row in panel['rows']:
|
| 292 |
+
if set(row) != {'id', 'ndcg@10'} or set(row['ndcg@10']) != panel_models:
|
| 293 |
+
raise ValueError('Unexpected public-panel row fields')
|
| 294 |
+
identity = row['id']
|
| 295 |
+
if not isinstance(identity, str) or identity[:1] != 'q' or not identity[1:].isdigit():
|
| 296 |
+
raise ValueError('Non-anonymous public-panel row identity')
|
| 297 |
+
if any(type(value) not in (int, float) or not math.isfinite(value) or not 0 <= value <= 1 for value in row['ndcg@10'].values()):
|
| 298 |
+
raise ValueError('Invalid public-panel score')
|
| 299 |
+
panel_ids.append(identity)
|
| 300 |
+
if len(panel_ids) != len(set(panel_ids)):
|
| 301 |
+
raise ValueError('Repeated public-panel query identity')
|
| 302 |
+
text = json.dumps(data).lower()
|
| 303 |
+
if any(value in text for value in ('c:\\', 'eval/private', 'qrel_target_id', 'query_text', 'passage_text')):
|
| 304 |
+
raise ValueError(f'Private payload in {name}')
|
| 305 |
+
return SUMMARIZERS[name](data)
|
| 306 |
+
|
| 307 |
+
|
| 308 |
def main() -> None:
|
| 309 |
parser = argparse.ArgumentParser(description=__doc__)
|
| 310 |
parser.add_argument("--directory", type=Path, default=Path(__file__).resolve().parent)
|
| 311 |
parser.add_argument("--output", type=Path)
|
| 312 |
parser.add_argument("--model", choices=("classifier", "reranker", "retriever", "dimensions", "promotion", "serving"), help="Recompute one comparison; default: every record in this package")
|
| 313 |
args = parser.parse_args()
|
|
|
|
|
|
|
|
|
|
| 314 |
names = [args.model] if args.model else [
|
| 315 |
+
name for name in SUMMARIZERS if (args.directory / f"{name}.json").is_file()
|
| 316 |
]
|
| 317 |
if not names:
|
| 318 |
parser.error("No evaluation records found in the selected directory")
|
| 319 |
result = {}
|
| 320 |
for name in names:
|
|
|
|
| 321 |
data = json.loads((args.directory / f"{name}.json").read_text(encoding="utf-8"))
|
| 322 |
+
result[name] = summarize_record(name, data)
|
|
|
|
|
|
|
|
|
|
| 323 |
text = json.dumps(result, indent=2, allow_nan=False) + "\n"
|
| 324 |
if args.output:
|
| 325 |
args.output.write_text(text, encoding="utf-8")
|
evaluation/promotion-summary.json
CHANGED
|
@@ -1 +1,228 @@
|
|
| 1 |
-
{
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"queries": 970,
|
| 3 |
+
"models": {
|
| 4 |
+
"production": {
|
| 5 |
+
"1": {
|
| 6 |
+
"scored_queries": 964,
|
| 7 |
+
"excluded_queries": 6,
|
| 8 |
+
"hit": 0.7261410788381742,
|
| 9 |
+
"precision": 0.7261410788381742,
|
| 10 |
+
"macro_precision": 0.7261410788381742,
|
| 11 |
+
"ndcg": 0.6822762299940723,
|
| 12 |
+
"known_positive_recall": 0.03374565629667812,
|
| 13 |
+
"recall_queries": 889,
|
| 14 |
+
"useful": 700,
|
| 15 |
+
"retained": 964,
|
| 16 |
+
"excluded_positions": 0,
|
| 17 |
+
"mean_useful": 0.7261410788381742,
|
| 18 |
+
"mean_retained": 1.0
|
| 19 |
+
},
|
| 20 |
+
"3": {
|
| 21 |
+
"scored_queries": 970,
|
| 22 |
+
"excluded_queries": 0,
|
| 23 |
+
"hit": 0.8391752577319588,
|
| 24 |
+
"precision": 0.7108890420399724,
|
| 25 |
+
"macro_precision": 0.7109965635738832,
|
| 26 |
+
"ndcg": 0.6737359241548024,
|
| 27 |
+
"known_positive_recall": 0.09151322333990437,
|
| 28 |
+
"recall_queries": 895,
|
| 29 |
+
"useful": 2063,
|
| 30 |
+
"retained": 2902,
|
| 31 |
+
"excluded_positions": 8,
|
| 32 |
+
"mean_useful": 2.12680412371134,
|
| 33 |
+
"mean_retained": 2.9917525773195877
|
| 34 |
+
},
|
| 35 |
+
"5": {
|
| 36 |
+
"scored_queries": 970,
|
| 37 |
+
"excluded_queries": 0,
|
| 38 |
+
"hit": 0.8587628865979381,
|
| 39 |
+
"precision": 0.6968194960760017,
|
| 40 |
+
"macro_precision": 0.6970103092783505,
|
| 41 |
+
"ndcg": 0.6720934096988599,
|
| 42 |
+
"known_positive_recall": 0.14456571515697228,
|
| 43 |
+
"recall_queries": 895,
|
| 44 |
+
"useful": 3374,
|
| 45 |
+
"retained": 4842,
|
| 46 |
+
"excluded_positions": 8,
|
| 47 |
+
"mean_useful": 3.4783505154639176,
|
| 48 |
+
"mean_retained": 4.991752577319588
|
| 49 |
+
},
|
| 50 |
+
"10": {
|
| 51 |
+
"scored_queries": 970,
|
| 52 |
+
"excluded_queries": 0,
|
| 53 |
+
"hit": 0.8783505154639175,
|
| 54 |
+
"precision": 0.6640181611804767,
|
| 55 |
+
"macro_precision": 0.6641809851088202,
|
| 56 |
+
"ndcg": 0.6764288375969912,
|
| 57 |
+
"known_positive_recall": 0.2647168884118442,
|
| 58 |
+
"recall_queries": 895,
|
| 59 |
+
"useful": 6435,
|
| 60 |
+
"retained": 9691,
|
| 61 |
+
"excluded_positions": 9,
|
| 62 |
+
"mean_useful": 6.634020618556701,
|
| 63 |
+
"mean_retained": 9.990721649484536
|
| 64 |
+
},
|
| 65 |
+
"20": {
|
| 66 |
+
"scored_queries": 970,
|
| 67 |
+
"excluded_queries": 0,
|
| 68 |
+
"hit": 0.9010309278350516,
|
| 69 |
+
"precision": 0.6041172221648953,
|
| 70 |
+
"macro_precision": 0.604256841821554,
|
| 71 |
+
"ndcg": 0.6943443750382963,
|
| 72 |
+
"known_positive_recall": 0.4574631459961227,
|
| 73 |
+
"recall_queries": 895,
|
| 74 |
+
"useful": 11709,
|
| 75 |
+
"retained": 19382,
|
| 76 |
+
"excluded_positions": 18,
|
| 77 |
+
"mean_useful": 12.071134020618556,
|
| 78 |
+
"mean_retained": 19.981443298969072
|
| 79 |
+
},
|
| 80 |
+
"selected": {
|
| 81 |
+
"scored_queries": 970,
|
| 82 |
+
"excluded_queries": 0,
|
| 83 |
+
"hit": 0.8525773195876288,
|
| 84 |
+
"precision": 0.8040927303949628,
|
| 85 |
+
"macro_precision": 0.7015133181852246,
|
| 86 |
+
"ndcg": 0.67618405088445,
|
| 87 |
+
"known_positive_recall": 0.19797868631055085,
|
| 88 |
+
"recall_queries": 895,
|
| 89 |
+
"useful": 5619,
|
| 90 |
+
"retained": 6988,
|
| 91 |
+
"excluded_positions": 8,
|
| 92 |
+
"mean_useful": 5.792783505154639,
|
| 93 |
+
"mean_retained": 7.204123711340206
|
| 94 |
+
}
|
| 95 |
+
},
|
| 96 |
+
"candidate": {
|
| 97 |
+
"1": {
|
| 98 |
+
"scored_queries": 964,
|
| 99 |
+
"excluded_queries": 6,
|
| 100 |
+
"hit": 0.7230290456431535,
|
| 101 |
+
"precision": 0.7230290456431535,
|
| 102 |
+
"macro_precision": 0.7230290456431535,
|
| 103 |
+
"ndcg": 0.6648389646314957,
|
| 104 |
+
"known_positive_recall": 0.03456403636248349,
|
| 105 |
+
"recall_queries": 889,
|
| 106 |
+
"useful": 697,
|
| 107 |
+
"retained": 964,
|
| 108 |
+
"excluded_positions": 0,
|
| 109 |
+
"mean_useful": 0.7230290456431535,
|
| 110 |
+
"mean_retained": 1.0
|
| 111 |
+
},
|
| 112 |
+
"3": {
|
| 113 |
+
"scored_queries": 970,
|
| 114 |
+
"excluded_queries": 0,
|
| 115 |
+
"hit": 0.8536082474226804,
|
| 116 |
+
"precision": 0.7157640565712314,
|
| 117 |
+
"macro_precision": 0.7166666666666667,
|
| 118 |
+
"ndcg": 0.6576832474683237,
|
| 119 |
+
"known_positive_recall": 0.09526530468586906,
|
| 120 |
+
"recall_queries": 895,
|
| 121 |
+
"useful": 2075,
|
| 122 |
+
"retained": 2899,
|
| 123 |
+
"excluded_positions": 11,
|
| 124 |
+
"mean_useful": 2.1391752577319587,
|
| 125 |
+
"mean_retained": 2.988659793814433
|
| 126 |
+
},
|
| 127 |
+
"5": {
|
| 128 |
+
"scored_queries": 970,
|
| 129 |
+
"excluded_queries": 0,
|
| 130 |
+
"hit": 0.8845360824742268,
|
| 131 |
+
"precision": 0.7028311634635255,
|
| 132 |
+
"macro_precision": 0.7031786941580757,
|
| 133 |
+
"ndcg": 0.6554718901879515,
|
| 134 |
+
"known_positive_recall": 0.15391852985862914,
|
| 135 |
+
"recall_queries": 895,
|
| 136 |
+
"useful": 3401,
|
| 137 |
+
"retained": 4839,
|
| 138 |
+
"excluded_positions": 11,
|
| 139 |
+
"mean_useful": 3.5061855670103093,
|
| 140 |
+
"mean_retained": 4.988659793814433
|
| 141 |
+
},
|
| 142 |
+
"10": {
|
| 143 |
+
"scored_queries": 970,
|
| 144 |
+
"excluded_queries": 0,
|
| 145 |
+
"hit": 0.8989690721649485,
|
| 146 |
+
"precision": 0.67180070291503,
|
| 147 |
+
"macro_precision": 0.6722631320569465,
|
| 148 |
+
"ndcg": 0.6610872123112499,
|
| 149 |
+
"known_positive_recall": 0.28045885967323153,
|
| 150 |
+
"recall_queries": 895,
|
| 151 |
+
"useful": 6499,
|
| 152 |
+
"retained": 9674,
|
| 153 |
+
"excluded_positions": 26,
|
| 154 |
+
"mean_useful": 6.7,
|
| 155 |
+
"mean_retained": 9.97319587628866
|
| 156 |
+
},
|
| 157 |
+
"20": {
|
| 158 |
+
"scored_queries": 970,
|
| 159 |
+
"excluded_queries": 0,
|
| 160 |
+
"hit": 0.9103092783505154,
|
| 161 |
+
"precision": 0.61794500723589,
|
| 162 |
+
"macro_precision": 0.6184956360634603,
|
| 163 |
+
"ndcg": 0.684223528795109,
|
| 164 |
+
"known_positive_recall": 0.4887591886594314,
|
| 165 |
+
"recall_queries": 895,
|
| 166 |
+
"useful": 11956,
|
| 167 |
+
"retained": 19348,
|
| 168 |
+
"excluded_positions": 52,
|
| 169 |
+
"mean_useful": 12.32577319587629,
|
| 170 |
+
"mean_retained": 19.94639175257732
|
| 171 |
+
},
|
| 172 |
+
"selected": {
|
| 173 |
+
"scored_queries": 970,
|
| 174 |
+
"excluded_queries": 0,
|
| 175 |
+
"hit": 0.8618556701030928,
|
| 176 |
+
"precision": 0.8033770583310076,
|
| 177 |
+
"macro_precision": 0.7040325511660611,
|
| 178 |
+
"ndcg": 0.6599128936120324,
|
| 179 |
+
"known_positive_recall": 0.20805438995183476,
|
| 180 |
+
"recall_queries": 895,
|
| 181 |
+
"useful": 5757,
|
| 182 |
+
"retained": 7166,
|
| 183 |
+
"excluded_positions": 17,
|
| 184 |
+
"mean_useful": 5.935051546391753,
|
| 185 |
+
"mean_retained": 7.387628865979382
|
| 186 |
+
}
|
| 187 |
+
}
|
| 188 |
+
},
|
| 189 |
+
"public": {
|
| 190 |
+
"scifact": {
|
| 191 |
+
"queries": 300,
|
| 192 |
+
"ndcg@10": {
|
| 193 |
+
"upstream": 0.7875641458078616,
|
| 194 |
+
"production": 0.7678535660256963,
|
| 195 |
+
"candidate": 0.7782845713792622
|
| 196 |
+
}
|
| 197 |
+
},
|
| 198 |
+
"fiqa": {
|
| 199 |
+
"queries": 648,
|
| 200 |
+
"ndcg@10": {
|
| 201 |
+
"upstream": 0.474145026242454,
|
| 202 |
+
"production": 0.4008741437969072,
|
| 203 |
+
"candidate": 0.446838124778398
|
| 204 |
+
}
|
| 205 |
+
},
|
| 206 |
+
"nfcorpus": {
|
| 207 |
+
"queries": 323,
|
| 208 |
+
"ndcg@10": {
|
| 209 |
+
"upstream": 0.3932480325545885,
|
| 210 |
+
"candidate": 0.3889646280478944
|
| 211 |
+
}
|
| 212 |
+
},
|
| 213 |
+
"scidocs": {
|
| 214 |
+
"queries": 1000,
|
| 215 |
+
"ndcg@10": {
|
| 216 |
+
"upstream": 0.19447454865159183,
|
| 217 |
+
"candidate": 0.18521860884727676
|
| 218 |
+
}
|
| 219 |
+
},
|
| 220 |
+
"arguana": {
|
| 221 |
+
"queries": 1406,
|
| 222 |
+
"ndcg@10": {
|
| 223 |
+
"upstream": 0.6431541443325537,
|
| 224 |
+
"candidate": 0.6258634411077135
|
| 225 |
+
}
|
| 226 |
+
}
|
| 227 |
+
}
|
| 228 |
+
}
|
evaluation/retriever-summary.json
CHANGED
|
@@ -1,74 +1,160 @@
|
|
| 1 |
-
{
|
| 2 |
-
"queries":
|
| 3 |
-
"
|
| 4 |
-
|
| 5 |
-
|
| 6 |
-
|
| 7 |
-
"
|
| 8 |
-
"
|
| 9 |
-
"
|
| 10 |
-
"
|
| 11 |
-
"
|
| 12 |
-
"
|
| 13 |
-
|
| 14 |
-
|
| 15 |
-
"
|
| 16 |
-
"
|
| 17 |
-
"
|
| 18 |
-
"
|
| 19 |
-
|
| 20 |
-
|
| 21 |
-
|
| 22 |
-
|
| 23 |
-
"
|
| 24 |
-
"
|
| 25 |
-
"
|
| 26 |
-
"
|
| 27 |
-
"
|
| 28 |
-
"
|
| 29 |
-
|
| 30 |
-
|
| 31 |
-
"
|
| 32 |
-
"
|
| 33 |
-
"
|
| 34 |
-
|
| 35 |
-
|
| 36 |
-
"
|
| 37 |
-
|
| 38 |
-
|
| 39 |
-
|
| 40 |
-
|
| 41 |
-
"
|
| 42 |
-
"
|
| 43 |
-
"
|
| 44 |
-
"
|
| 45 |
-
"
|
| 46 |
-
"
|
| 47 |
-
|
| 48 |
-
|
| 49 |
-
|
| 50 |
-
|
| 51 |
-
"
|
| 52 |
-
"
|
| 53 |
-
"
|
| 54 |
-
"
|
| 55 |
-
|
| 56 |
-
|
| 57 |
-
"
|
| 58 |
-
"
|
| 59 |
-
"
|
| 60 |
-
"
|
| 61 |
-
"
|
| 62 |
-
"
|
| 63 |
-
|
| 64 |
-
|
| 65 |
-
|
| 66 |
-
"
|
| 67 |
-
"
|
| 68 |
-
"
|
| 69 |
-
"
|
| 70 |
-
"
|
| 71 |
-
|
| 72 |
-
|
| 73 |
-
|
| 74 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"queries": 970,
|
| 3 |
+
"models": {
|
| 4 |
+
"upstream": {
|
| 5 |
+
"1": {
|
| 6 |
+
"scored_queries": 970,
|
| 7 |
+
"excluded_queries": 0,
|
| 8 |
+
"hit": 0.534020618556701,
|
| 9 |
+
"precision": 0.534020618556701,
|
| 10 |
+
"macro_precision": 0.534020618556701,
|
| 11 |
+
"ndcg": 0.4695139911634757,
|
| 12 |
+
"known_positive_recall": 0.019407636059998304,
|
| 13 |
+
"recall_queries": 911,
|
| 14 |
+
"useful": 518,
|
| 15 |
+
"retained": 970,
|
| 16 |
+
"excluded_positions": 0,
|
| 17 |
+
"mean_useful": 0.534020618556701,
|
| 18 |
+
"mean_retained": 1.0
|
| 19 |
+
},
|
| 20 |
+
"3": {
|
| 21 |
+
"scored_queries": 970,
|
| 22 |
+
"excluded_queries": 0,
|
| 23 |
+
"hit": 0.7298969072164948,
|
| 24 |
+
"precision": 0.5082530949105915,
|
| 25 |
+
"macro_precision": 0.5082474226804123,
|
| 26 |
+
"ndcg": 0.4515657513806275,
|
| 27 |
+
"known_positive_recall": 0.05434321461039996,
|
| 28 |
+
"recall_queries": 911,
|
| 29 |
+
"useful": 1478,
|
| 30 |
+
"retained": 2908,
|
| 31 |
+
"excluded_positions": 2,
|
| 32 |
+
"mean_useful": 1.5237113402061855,
|
| 33 |
+
"mean_retained": 2.997938144329897
|
| 34 |
+
},
|
| 35 |
+
"5": {
|
| 36 |
+
"scored_queries": 970,
|
| 37 |
+
"excluded_queries": 0,
|
| 38 |
+
"hit": 0.7948453608247422,
|
| 39 |
+
"precision": 0.49948379103861246,
|
| 40 |
+
"macro_precision": 0.4996219931271478,
|
| 41 |
+
"ndcg": 0.4457312507652407,
|
| 42 |
+
"known_positive_recall": 0.08530117331466223,
|
| 43 |
+
"recall_queries": 911,
|
| 44 |
+
"useful": 2419,
|
| 45 |
+
"retained": 4843,
|
| 46 |
+
"excluded_positions": 7,
|
| 47 |
+
"mean_useful": 2.4938144329896907,
|
| 48 |
+
"mean_retained": 4.992783505154639
|
| 49 |
+
},
|
| 50 |
+
"10": {
|
| 51 |
+
"scored_queries": 970,
|
| 52 |
+
"excluded_queries": 0,
|
| 53 |
+
"hit": 0.8484536082474227,
|
| 54 |
+
"precision": 0.4739561802397685,
|
| 55 |
+
"macro_precision": 0.47407543773523153,
|
| 56 |
+
"ndcg": 0.45062269194348514,
|
| 57 |
+
"known_positive_recall": 0.15770613185252844,
|
| 58 |
+
"recall_queries": 911,
|
| 59 |
+
"useful": 4586,
|
| 60 |
+
"retained": 9676,
|
| 61 |
+
"excluded_positions": 24,
|
| 62 |
+
"mean_useful": 4.727835051546392,
|
| 63 |
+
"mean_retained": 9.975257731958763
|
| 64 |
+
},
|
| 65 |
+
"20": {
|
| 66 |
+
"scored_queries": 970,
|
| 67 |
+
"excluded_queries": 0,
|
| 68 |
+
"hit": 0.8876288659793814,
|
| 69 |
+
"precision": 0.4393610421836228,
|
| 70 |
+
"macro_precision": 0.44005992535723476,
|
| 71 |
+
"ndcg": 0.4736202687789316,
|
| 72 |
+
"known_positive_recall": 0.2807541608701895,
|
| 73 |
+
"recall_queries": 911,
|
| 74 |
+
"useful": 8499,
|
| 75 |
+
"retained": 19344,
|
| 76 |
+
"excluded_positions": 56,
|
| 77 |
+
"mean_useful": 8.761855670103094,
|
| 78 |
+
"mean_retained": 19.942268041237114
|
| 79 |
+
}
|
| 80 |
+
},
|
| 81 |
+
"finetuned": {
|
| 82 |
+
"1": {
|
| 83 |
+
"scored_queries": 970,
|
| 84 |
+
"excluded_queries": 0,
|
| 85 |
+
"hit": 0.6474226804123712,
|
| 86 |
+
"precision": 0.6474226804123712,
|
| 87 |
+
"macro_precision": 0.6474226804123712,
|
| 88 |
+
"ndcg": 0.5420716740304369,
|
| 89 |
+
"known_positive_recall": 0.02462514980632024,
|
| 90 |
+
"recall_queries": 911,
|
| 91 |
+
"useful": 628,
|
| 92 |
+
"retained": 970,
|
| 93 |
+
"excluded_positions": 0,
|
| 94 |
+
"mean_useful": 0.6474226804123712,
|
| 95 |
+
"mean_retained": 1.0
|
| 96 |
+
},
|
| 97 |
+
"3": {
|
| 98 |
+
"scored_queries": 970,
|
| 99 |
+
"excluded_queries": 0,
|
| 100 |
+
"hit": 0.7938144329896907,
|
| 101 |
+
"precision": 0.6308009625300791,
|
| 102 |
+
"macro_precision": 0.6309278350515464,
|
| 103 |
+
"ndcg": 0.5523629493718011,
|
| 104 |
+
"known_positive_recall": 0.06947139492907671,
|
| 105 |
+
"recall_queries": 911,
|
| 106 |
+
"useful": 1835,
|
| 107 |
+
"retained": 2909,
|
| 108 |
+
"excluded_positions": 1,
|
| 109 |
+
"mean_useful": 1.8917525773195876,
|
| 110 |
+
"mean_retained": 2.9989690721649485
|
| 111 |
+
},
|
| 112 |
+
"5": {
|
| 113 |
+
"scored_queries": 970,
|
| 114 |
+
"excluded_queries": 0,
|
| 115 |
+
"hit": 0.8474226804123711,
|
| 116 |
+
"precision": 0.6266005782734407,
|
| 117 |
+
"macro_precision": 0.6269759450171821,
|
| 118 |
+
"ndcg": 0.558603868737523,
|
| 119 |
+
"known_positive_recall": 0.11088922136775149,
|
| 120 |
+
"recall_queries": 911,
|
| 121 |
+
"useful": 3034,
|
| 122 |
+
"retained": 4842,
|
| 123 |
+
"excluded_positions": 8,
|
| 124 |
+
"mean_useful": 3.1278350515463917,
|
| 125 |
+
"mean_retained": 4.991752577319588
|
| 126 |
+
},
|
| 127 |
+
"10": {
|
| 128 |
+
"scored_queries": 970,
|
| 129 |
+
"excluded_queries": 0,
|
| 130 |
+
"hit": 0.8814432989690721,
|
| 131 |
+
"precision": 0.6117999586691465,
|
| 132 |
+
"macro_precision": 0.6123367697594502,
|
| 133 |
+
"ndcg": 0.5748078775849167,
|
| 134 |
+
"known_positive_recall": 0.2082023156474653,
|
| 135 |
+
"recall_queries": 911,
|
| 136 |
+
"useful": 5921,
|
| 137 |
+
"retained": 9678,
|
| 138 |
+
"excluded_positions": 22,
|
| 139 |
+
"mean_useful": 6.104123711340206,
|
| 140 |
+
"mean_retained": 9.977319587628866
|
| 141 |
+
},
|
| 142 |
+
"20": {
|
| 143 |
+
"scored_queries": 970,
|
| 144 |
+
"excluded_queries": 0,
|
| 145 |
+
"hit": 0.9051546391752577,
|
| 146 |
+
"precision": 0.5810720008270016,
|
| 147 |
+
"macro_precision": 0.5815832221977094,
|
| 148 |
+
"ndcg": 0.6064961581206146,
|
| 149 |
+
"known_positive_recall": 0.38649540366398033,
|
| 150 |
+
"recall_queries": 911,
|
| 151 |
+
"useful": 11242,
|
| 152 |
+
"retained": 19347,
|
| 153 |
+
"excluded_positions": 53,
|
| 154 |
+
"mean_useful": 11.589690721649484,
|
| 155 |
+
"mean_retained": 19.945360824742266
|
| 156 |
+
}
|
| 157 |
+
}
|
| 158 |
+
},
|
| 159 |
+
"corpus_passages": 82719
|
| 160 |
+
}
|
evaluation/retriever.json
CHANGED
|
The diff for this file is too large to render.
See raw diff
|
|
|
evaluation/serving-summary.json
CHANGED
|
@@ -1 +1,190 @@
|
|
| 1 |
-
{
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"queries": 970,
|
| 3 |
+
"models": {
|
| 4 |
+
"cuda": {
|
| 5 |
+
"1": {
|
| 6 |
+
"scored_queries": 965,
|
| 7 |
+
"excluded_queries": 5,
|
| 8 |
+
"hit": 0.7233160621761658,
|
| 9 |
+
"precision": 0.7233160621761658,
|
| 10 |
+
"macro_precision": 0.7233160621761658,
|
| 11 |
+
"ndcg": 0.664594127806563,
|
| 12 |
+
"known_positive_recall": 0.0346020393358114,
|
| 13 |
+
"recall_queries": 890,
|
| 14 |
+
"useful": 698,
|
| 15 |
+
"retained": 965,
|
| 16 |
+
"excluded_positions": 0,
|
| 17 |
+
"mean_useful": 0.7233160621761658,
|
| 18 |
+
"mean_retained": 1.0
|
| 19 |
+
},
|
| 20 |
+
"3": {
|
| 21 |
+
"scored_queries": 970,
|
| 22 |
+
"excluded_queries": 0,
|
| 23 |
+
"hit": 0.8536082474226804,
|
| 24 |
+
"precision": 0.7157640565712314,
|
| 25 |
+
"macro_precision": 0.7166666666666667,
|
| 26 |
+
"ndcg": 0.6576832474683237,
|
| 27 |
+
"known_positive_recall": 0.09521315062968948,
|
| 28 |
+
"recall_queries": 895,
|
| 29 |
+
"useful": 2075,
|
| 30 |
+
"retained": 2899,
|
| 31 |
+
"excluded_positions": 11,
|
| 32 |
+
"mean_useful": 2.1391752577319587,
|
| 33 |
+
"mean_retained": 2.988659793814433
|
| 34 |
+
},
|
| 35 |
+
"5": {
|
| 36 |
+
"scored_queries": 970,
|
| 37 |
+
"excluded_queries": 0,
|
| 38 |
+
"hit": 0.8845360824742268,
|
| 39 |
+
"precision": 0.7028311634635255,
|
| 40 |
+
"macro_precision": 0.7031786941580757,
|
| 41 |
+
"ndcg": 0.6554718901879515,
|
| 42 |
+
"known_positive_recall": 0.15383335671735354,
|
| 43 |
+
"recall_queries": 895,
|
| 44 |
+
"useful": 3401,
|
| 45 |
+
"retained": 4839,
|
| 46 |
+
"excluded_positions": 11,
|
| 47 |
+
"mean_useful": 3.5061855670103093,
|
| 48 |
+
"mean_retained": 4.988659793814433
|
| 49 |
+
},
|
| 50 |
+
"10": {
|
| 51 |
+
"scored_queries": 970,
|
| 52 |
+
"excluded_queries": 0,
|
| 53 |
+
"hit": 0.8989690721649485,
|
| 54 |
+
"precision": 0.67180070291503,
|
| 55 |
+
"macro_precision": 0.6722631320569465,
|
| 56 |
+
"ndcg": 0.6610872123112499,
|
| 57 |
+
"known_positive_recall": 0.2802986435290336,
|
| 58 |
+
"recall_queries": 895,
|
| 59 |
+
"useful": 6499,
|
| 60 |
+
"retained": 9674,
|
| 61 |
+
"excluded_positions": 26,
|
| 62 |
+
"mean_useful": 6.7,
|
| 63 |
+
"mean_retained": 9.97319587628866
|
| 64 |
+
},
|
| 65 |
+
"20": {
|
| 66 |
+
"scored_queries": 970,
|
| 67 |
+
"excluded_queries": 0,
|
| 68 |
+
"hit": 0.9103092783505154,
|
| 69 |
+
"precision": 0.61794500723589,
|
| 70 |
+
"macro_precision": 0.6184956360634603,
|
| 71 |
+
"ndcg": 0.6840908385828889,
|
| 72 |
+
"known_positive_recall": 0.4884616340614924,
|
| 73 |
+
"recall_queries": 895,
|
| 74 |
+
"useful": 11956,
|
| 75 |
+
"retained": 19348,
|
| 76 |
+
"excluded_positions": 52,
|
| 77 |
+
"mean_useful": 12.32577319587629,
|
| 78 |
+
"mean_retained": 19.94639175257732
|
| 79 |
+
},
|
| 80 |
+
"selected": {
|
| 81 |
+
"scored_queries": 970,
|
| 82 |
+
"excluded_queries": 0,
|
| 83 |
+
"hit": 0.8618556701030928,
|
| 84 |
+
"precision": 0.8033770583310076,
|
| 85 |
+
"macro_precision": 0.7040325511660611,
|
| 86 |
+
"ndcg": 0.6598955189009045,
|
| 87 |
+
"known_positive_recall": 0.2079138769097556,
|
| 88 |
+
"recall_queries": 895,
|
| 89 |
+
"useful": 5757,
|
| 90 |
+
"retained": 7166,
|
| 91 |
+
"excluded_positions": 17,
|
| 92 |
+
"mean_useful": 5.935051546391753,
|
| 93 |
+
"mean_retained": 7.387628865979382
|
| 94 |
+
}
|
| 95 |
+
},
|
| 96 |
+
"vulkan": {
|
| 97 |
+
"1": {
|
| 98 |
+
"scored_queries": 965,
|
| 99 |
+
"excluded_queries": 5,
|
| 100 |
+
"hit": 0.7243523316062176,
|
| 101 |
+
"precision": 0.7243523316062176,
|
| 102 |
+
"macro_precision": 0.7243523316062176,
|
| 103 |
+
"ndcg": 0.6648902047865778,
|
| 104 |
+
"known_positive_recall": 0.03463608768446649,
|
| 105 |
+
"recall_queries": 890,
|
| 106 |
+
"useful": 699,
|
| 107 |
+
"retained": 965,
|
| 108 |
+
"excluded_positions": 0,
|
| 109 |
+
"mean_useful": 0.7243523316062176,
|
| 110 |
+
"mean_retained": 1.0
|
| 111 |
+
},
|
| 112 |
+
"3": {
|
| 113 |
+
"scored_queries": 970,
|
| 114 |
+
"excluded_queries": 0,
|
| 115 |
+
"hit": 0.8525773195876288,
|
| 116 |
+
"precision": 0.7157640565712314,
|
| 117 |
+
"macro_precision": 0.7166666666666667,
|
| 118 |
+
"ndcg": 0.6577263968717306,
|
| 119 |
+
"known_positive_recall": 0.09519545071125639,
|
| 120 |
+
"recall_queries": 895,
|
| 121 |
+
"useful": 2075,
|
| 122 |
+
"retained": 2899,
|
| 123 |
+
"excluded_positions": 11,
|
| 124 |
+
"mean_useful": 2.1391752577319587,
|
| 125 |
+
"mean_retained": 2.988659793814433
|
| 126 |
+
},
|
| 127 |
+
"5": {
|
| 128 |
+
"scored_queries": 970,
|
| 129 |
+
"excluded_queries": 0,
|
| 130 |
+
"hit": 0.8845360824742268,
|
| 131 |
+
"precision": 0.7023563455973543,
|
| 132 |
+
"macro_precision": 0.702766323024055,
|
| 133 |
+
"ndcg": 0.6550340124265787,
|
| 134 |
+
"known_positive_recall": 0.15374094654114448,
|
| 135 |
+
"recall_queries": 895,
|
| 136 |
+
"useful": 3398,
|
| 137 |
+
"retained": 4838,
|
| 138 |
+
"excluded_positions": 12,
|
| 139 |
+
"mean_useful": 3.5030927835051546,
|
| 140 |
+
"mean_retained": 4.9876288659793815
|
| 141 |
+
},
|
| 142 |
+
"10": {
|
| 143 |
+
"scored_queries": 970,
|
| 144 |
+
"excluded_queries": 0,
|
| 145 |
+
"hit": 0.8989690721649485,
|
| 146 |
+
"precision": 0.6723514211886304,
|
| 147 |
+
"macro_precision": 0.6727589592538046,
|
| 148 |
+
"ndcg": 0.6615310405020679,
|
| 149 |
+
"known_positive_recall": 0.2805978824757964,
|
| 150 |
+
"recall_queries": 895,
|
| 151 |
+
"useful": 6505,
|
| 152 |
+
"retained": 9675,
|
| 153 |
+
"excluded_positions": 25,
|
| 154 |
+
"mean_useful": 6.706185567010309,
|
| 155 |
+
"mean_retained": 9.974226804123711
|
| 156 |
+
},
|
| 157 |
+
"20": {
|
| 158 |
+
"scored_queries": 970,
|
| 159 |
+
"excluded_queries": 0,
|
| 160 |
+
"hit": 0.9103092783505154,
|
| 161 |
+
"precision": 0.6178416373785404,
|
| 162 |
+
"macro_precision": 0.6183925432799551,
|
| 163 |
+
"ndcg": 0.6840389893720067,
|
| 164 |
+
"known_positive_recall": 0.4883516349357555,
|
| 165 |
+
"recall_queries": 895,
|
| 166 |
+
"useful": 11954,
|
| 167 |
+
"retained": 19348,
|
| 168 |
+
"excluded_positions": 52,
|
| 169 |
+
"mean_useful": 12.323711340206186,
|
| 170 |
+
"mean_retained": 19.94639175257732
|
| 171 |
+
},
|
| 172 |
+
"selected": {
|
| 173 |
+
"scored_queries": 970,
|
| 174 |
+
"excluded_queries": 0,
|
| 175 |
+
"hit": 0.8608247422680413,
|
| 176 |
+
"precision": 0.8027855153203343,
|
| 177 |
+
"macro_precision": 0.7038533836490732,
|
| 178 |
+
"ndcg": 0.6599601279630594,
|
| 179 |
+
"known_positive_recall": 0.2082001919384574,
|
| 180 |
+
"recall_queries": 895,
|
| 181 |
+
"useful": 5764,
|
| 182 |
+
"retained": 7180,
|
| 183 |
+
"excluded_positions": 17,
|
| 184 |
+
"mean_useful": 5.942268041237114,
|
| 185 |
+
"mean_retained": 7.402061855670103
|
| 186 |
+
}
|
| 187 |
+
}
|
| 188 |
+
},
|
| 189 |
+
"public": {}
|
| 190 |
+
}
|
figures/gemma-comparison.svg
CHANGED
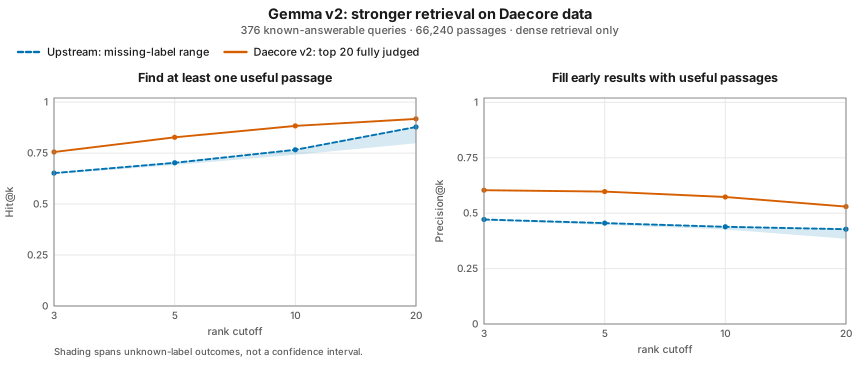
|
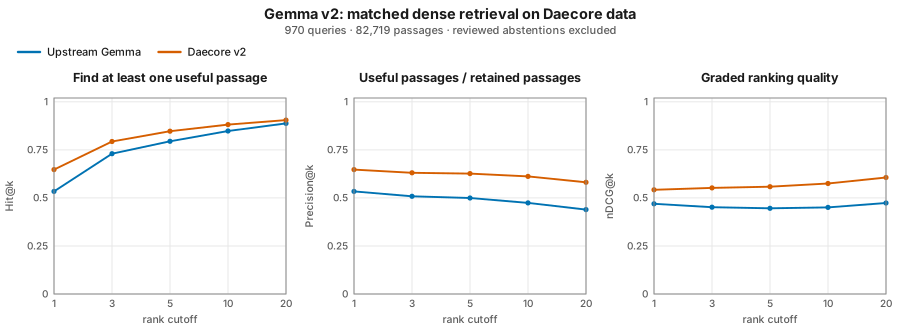
|
publication-manifest.json
CHANGED
|
@@ -1,6 +1,6 @@
|
|
| 1 |
{
|
| 2 |
"schema": "daecore.retrieval-publication-manifest",
|
| 3 |
-
"tool_sha256": "
|
| 4 |
"model_id": "embeddinggemma-300m-memory-ft-v2",
|
| 5 |
"public_repo": "Daecore/embeddinggemma-300m-memory-ft-v2",
|
| 6 |
"role": "dense-retriever",
|
|
@@ -12,7 +12,7 @@
|
|
| 12 |
"export_receipt_sha256": "e24e1692f7e03c9af8040bb3f6e310a061d305f485861007f1f37d36808b20d8",
|
| 13 |
"serving_sha256": "8c088b1635875d5406e148782b303cfc5a961138600783fb4842b413b98a98c3",
|
| 14 |
"source_model_tree_sha256": "30a7b9f1c42b1fcee29a6729742685d5b744e8fa87d13cefab2fd2d49ea9150e",
|
| 15 |
-
"staged_at": "2026-09-
|
| 16 |
"files": {
|
| 17 |
"added_tokens.json": {
|
| 18 |
"sha256": "50b2f405ba56a26d4913fd772089992252d7f942123cc0a034d96424221ba946",
|
|
@@ -80,8 +80,8 @@
|
|
| 80 |
"binding": "packaging record"
|
| 81 |
},
|
| 82 |
"evaluation/README.md": {
|
| 83 |
-
"sha256": "
|
| 84 |
-
"size":
|
| 85 |
"binding": "packaging record"
|
| 86 |
},
|
| 87 |
"evaluation/serving-qualification.json": {
|
|
@@ -90,18 +90,33 @@
|
|
| 90 |
"binding": "packaging record"
|
| 91 |
},
|
| 92 |
"evaluation/metrics.py": {
|
| 93 |
-
"sha256": "
|
| 94 |
-
"size":
|
| 95 |
"binding": "packaging record"
|
| 96 |
},
|
| 97 |
-
"evaluation/retriever.json": {
|
| 98 |
-
"sha256": "
|
| 99 |
-
"size":
|
| 100 |
"binding": "packaging record"
|
| 101 |
},
|
| 102 |
-
"evaluation/
|
| 103 |
-
"sha256": "
|
| 104 |
-
"size":
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 105 |
"binding": "packaging record"
|
| 106 |
},
|
| 107 |
"evaluation/dimensions.json": {
|
|
@@ -109,34 +124,19 @@
|
|
| 109 |
"size": 762884,
|
| 110 |
"binding": "packaging record"
|
| 111 |
},
|
| 112 |
-
"evaluation/dimensions-summary.json": {
|
| 113 |
-
"sha256": "d42adc93268a44675bcda3321a431f8cd92e6c9178efdb44e0314372468a7c6e",
|
| 114 |
-
"size": 1253,
|
| 115 |
-
"binding": "packaging record"
|
| 116 |
-
},
|
| 117 |
"evaluation/promotion.json": {
|
| 118 |
"sha256": "dca79b36c99e2f90c05bff12227634fe175f1370a2ac83368da084ccf7aeffc3",
|
| 119 |
"size": 816500,
|
| 120 |
"binding": "packaging record"
|
| 121 |
},
|
| 122 |
-
"evaluation/promotion-summary.json": {
|
| 123 |
-
"sha256": "3dcd954b778e8955f90c7e160790227602b701eea0897d539ecc1f8ab265567a",
|
| 124 |
-
"size": 3724,
|
| 125 |
-
"binding": "packaging record"
|
| 126 |
-
},
|
| 127 |
"evaluation/serving.json": {
|
| 128 |
"sha256": "0c017dbd0e66734c465d617eef24b2affb2670a96f7fd5b2c001514c3cc1381a",
|
| 129 |
"size": 500118,
|
| 130 |
"binding": "packaging record"
|
| 131 |
},
|
| 132 |
-
"evaluation/serving-summary.json": {
|
| 133 |
-
"sha256": "3a7c6a2c96495917e65a7dabde9c02c7c457b5416df51cbb58bb7267d5c74fda",
|
| 134 |
-
"size": 3162,
|
| 135 |
-
"binding": "packaging record"
|
| 136 |
-
},
|
| 137 |
"evaluation/figures.py": {
|
| 138 |
-
"sha256": "
|
| 139 |
-
"size":
|
| 140 |
"binding": "packaging record"
|
| 141 |
},
|
| 142 |
"evaluation/svg_figures.py": {
|
|
@@ -145,15 +145,15 @@
|
|
| 145 |
"binding": "packaging record"
|
| 146 |
},
|
| 147 |
"figures/gemma-comparison.svg": {
|
| 148 |
-
"sha256": "
|
| 149 |
-
"size":
|
| 150 |
"binding": "packaging record"
|
| 151 |
},
|
| 152 |
"README.md": {
|
| 153 |
-
"sha256": "
|
| 154 |
-
"size":
|
| 155 |
"binding": "model card with upload-relative links",
|
| 156 |
-
"source_sha256": "
|
| 157 |
}
|
| 158 |
}
|
| 159 |
}
|
|
|
|
| 1 |
{
|
| 2 |
"schema": "daecore.retrieval-publication-manifest",
|
| 3 |
+
"tool_sha256": "3ea615c62866883f911899f1e131d73ca8cc9701eea3540a3a016345ac5650f8",
|
| 4 |
"model_id": "embeddinggemma-300m-memory-ft-v2",
|
| 5 |
"public_repo": "Daecore/embeddinggemma-300m-memory-ft-v2",
|
| 6 |
"role": "dense-retriever",
|
|
|
|
| 12 |
"export_receipt_sha256": "e24e1692f7e03c9af8040bb3f6e310a061d305f485861007f1f37d36808b20d8",
|
| 13 |
"serving_sha256": "8c088b1635875d5406e148782b303cfc5a961138600783fb4842b413b98a98c3",
|
| 14 |
"source_model_tree_sha256": "30a7b9f1c42b1fcee29a6729742685d5b744e8fa87d13cefab2fd2d49ea9150e",
|
| 15 |
+
"staged_at": "2026-09-29T16:47:59+00:00",
|
| 16 |
"files": {
|
| 17 |
"added_tokens.json": {
|
| 18 |
"sha256": "50b2f405ba56a26d4913fd772089992252d7f942123cc0a034d96424221ba946",
|
|
|
|
| 80 |
"binding": "packaging record"
|
| 81 |
},
|
| 82 |
"evaluation/README.md": {
|
| 83 |
+
"sha256": "f7059b76c4e9956e899b5f8fb855a58262db42ffef301404c874c8ee9b1c19dc",
|
| 84 |
+
"size": 8475,
|
| 85 |
"binding": "packaging record"
|
| 86 |
},
|
| 87 |
"evaluation/serving-qualification.json": {
|
|
|
|
| 90 |
"binding": "packaging record"
|
| 91 |
},
|
| 92 |
"evaluation/metrics.py": {
|
| 93 |
+
"sha256": "72e7452766b491c247514df8ad1c8f52c8023e1e305d779655a9e1f3159ce52d",
|
| 94 |
+
"size": 17556,
|
| 95 |
"binding": "packaging record"
|
| 96 |
},
|
| 97 |
+
"evaluation/retriever-summary.json": {
|
| 98 |
+
"sha256": "6d87cfa07056cb0316e21ed70a940994d1ad91e9a297161878482814811f736b",
|
| 99 |
+
"size": 5063,
|
| 100 |
"binding": "packaging record"
|
| 101 |
},
|
| 102 |
+
"evaluation/dimensions-summary.json": {
|
| 103 |
+
"sha256": "d42adc93268a44675bcda3321a431f8cd92e6c9178efdb44e0314372468a7c6e",
|
| 104 |
+
"size": 1253,
|
| 105 |
+
"binding": "packaging record"
|
| 106 |
+
},
|
| 107 |
+
"evaluation/promotion-summary.json": {
|
| 108 |
+
"sha256": "c12e58b9ec5f5dd76baa2dc36a602816c9895f2b57e39b95cb74ca167506626a",
|
| 109 |
+
"size": 6886,
|
| 110 |
+
"binding": "packaging record"
|
| 111 |
+
},
|
| 112 |
+
"evaluation/serving-summary.json": {
|
| 113 |
+
"sha256": "fc60b4e94fe01e0470dcced382046c4c30c329a87b5caa2b631b369015548198",
|
| 114 |
+
"size": 6029,
|
| 115 |
+
"binding": "packaging record"
|
| 116 |
+
},
|
| 117 |
+
"evaluation/retriever.json": {
|
| 118 |
+
"sha256": "fcfbe8155cd30319ee38745f92376a45635ecaed08b86962ee8604680ce910b7",
|
| 119 |
+
"size": 573086,
|
| 120 |
"binding": "packaging record"
|
| 121 |
},
|
| 122 |
"evaluation/dimensions.json": {
|
|
|
|
| 124 |
"size": 762884,
|
| 125 |
"binding": "packaging record"
|
| 126 |
},
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 127 |
"evaluation/promotion.json": {
|
| 128 |
"sha256": "dca79b36c99e2f90c05bff12227634fe175f1370a2ac83368da084ccf7aeffc3",
|
| 129 |
"size": 816500,
|
| 130 |
"binding": "packaging record"
|
| 131 |
},
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 132 |
"evaluation/serving.json": {
|
| 133 |
"sha256": "0c017dbd0e66734c465d617eef24b2affb2670a96f7fd5b2c001514c3cc1381a",
|
| 134 |
"size": 500118,
|
| 135 |
"binding": "packaging record"
|
| 136 |
},
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 137 |
"evaluation/figures.py": {
|
| 138 |
+
"sha256": "53819eb947c3c5c25f6331b0e384e6e27f7b5da750c84f8bdf6fd6e7790c9d94",
|
| 139 |
+
"size": 5378,
|
| 140 |
"binding": "packaging record"
|
| 141 |
},
|
| 142 |
"evaluation/svg_figures.py": {
|
|
|
|
| 145 |
"binding": "packaging record"
|
| 146 |
},
|
| 147 |
"figures/gemma-comparison.svg": {
|
| 148 |
+
"sha256": "f4bf74ea9e2e044e124893d5ca8bd028c6f2f79ef53babfb7ee718f8b6786be2",
|
| 149 |
+
"size": 13377,
|
| 150 |
"binding": "packaging record"
|
| 151 |
},
|
| 152 |
"README.md": {
|
| 153 |
+
"sha256": "e7d88fad6c2c12613c8e8a8108a38dc7fbb181c005ffadac172f1120f84c95f0",
|
| 154 |
+
"size": 14331,
|
| 155 |
"binding": "model card with upload-relative links",
|
| 156 |
+
"source_sha256": "5ea17ec12b2673539eba89fc6e3f85c9ed8ba7d879d9ce94dbeebcb1392a8afa"
|
| 157 |
}
|
| 158 |
}
|
| 159 |
}
|