


Update embeddinggemma-300m-memory-ft-v2 documentation
Browse files- README.md +74 -71
- evaluation/README.md +55 -30
- evaluation/dimensions-summary.json +253 -0
- evaluation/figures.py +3 -1
- evaluation/metrics.py +16 -3
- evaluation/retriever-summary.json +189 -0
- evaluation/serving-summary.json +220 -1
- figures/gemma-comparison.svg +43 -43
- publication-manifest.json +18 -18
README.md
CHANGED
|
@@ -24,13 +24,13 @@ An English embedding model for finding the passages that answer a question in no
|
|
| 24 |
|
| 25 |
| Stronger private retrieval | Less forgetting | Local deployment |
|
| 26 |
|---|---|---|
|
| 27 |
-
| nDCG@10 **0.
|
| 28 |
|
| 29 |
-
The private comparison
|
| 30 |
-
|
| 31 |
-
|
| 32 |
-
|
| 33 |
-
|
| 34 |
|
| 35 |
Embed queries and passages with the same revision, and re-embed stored passages when switching to v2.
|
| 36 |
|
|
@@ -99,44 +99,46 @@ the 50 candidates admitted after Gemma and BM25 are fused and deduplicated.
|
|
| 99 |
|
| 100 |
### Gemma alone: dense retrieval on Daecore data
|
| 101 |
|
| 102 |
-
Both models search the same **82,719 passages
|
| 103 |
-
|
| 104 |
-
|
| 105 |
-
|
| 106 |
|
| 107 |
-
**Reference:**
|
| 108 |
-
|
| 109 |
-
|
|
|
|
| 110 |
|
| 111 |
| Cutoff | Hit | Precision | Known-positive recall | nDCG |
|
| 112 |
|---|---:|---:|---:|---:|
|
| 113 |
-
| 1 |
|
| 114 |
-
| 3 |
|
| 115 |
-
| 5 |
|
| 116 |
-
| 10 |
|
| 117 |
-
| 20 |
|
| 118 |
-
| 50 |
|
| 119 |
|
| 120 |

|
| 121 |
|
| 122 |
-
Every top-50 position is graded or explicitly excluded as ungradable,
|
| 123 |
-
missing-label ranges. All
|
| 124 |
-
50, 164 upstream positions and 167 v2 positions are excluded
|
| 125 |
-
Precision pools retained positions
|
| 126 |
-
|
|
|
|
| 127 |
|
| 128 |
-
At 50, v2 finds useful evidence for **
|
| 129 |
-
of known useful passages, versus
|
| 130 |
-
pool below has lower coverage on
|
| 131 |
-
after reranking. Adding BM25 and capping the fused list at 50
|
| 132 |
-
|
| 133 |
|
| 134 |
Grades 2–3 count as useful. nDCG uses gains 0, 1, 3 and 7 against the same
|
| 135 |
-
reviewed reference for both models
|
| 136 |
-
|
| 137 |
-
|
| 138 |
-
|
| 139 |
-
|
| 140 |
|
| 141 |
### Gemma alone: public dense retrieval
|
| 142 |
|
|
@@ -158,16 +160,16 @@ The model was trained at 768, 512, 256 and 128 dimensions. To use a smaller
|
|
| 158 |
width, keep the first dimensions and normalize the shortened vector again.
|
| 159 |
Use the same width for queries and passages. Each quality column below is
|
| 160 |
**v2 nDCG@10**, computed from exact rankings of cached FP32 vectors. The Daecore
|
| 161 |
-
column covers the same
|
| 162 |
-
each width, against the same **
|
| 163 |
reproduce the corresponding full-width scores.
|
| 164 |
|
| 165 |
| Dimensions | Bytes per FP32 vector | Daecore | SciFact | FiQA | NFCorpus | SciDocs | ArguAna |
|
| 166 |
|---|---:|---:|---:|---:|---:|---:|---:|
|
| 167 |
-
| 768 (default) | 3,072 | 0.
|
| 168 |
-
| 512 | 2,048 | 0.
|
| 169 |
-
| 256 | 1,024 | 0.
|
| 170 |
-
| 128 | 512 | 0.
|
| 171 |
|
| 172 |
At 512 dimensions, each raw FP32 vector uses one-third less storage, with
|
| 173 |
slightly higher Daecore nDCG@10 in this measurement and lower scores on four
|
|
@@ -179,40 +181,41 @@ smaller widths have not been qualified through the full hybrid pipeline.
|
|
| 179 |
### Full pipeline: Gemma v2 + BM25 + Ettin
|
| 180 |
|
| 181 |
This replay measures semantic and lexical search, reciprocal-rank fusion, then
|
| 182 |
-
Ettin reranking over **
|
| 183 |
-
|
| 184 |
-
|
|
|
|
|
|
|
| 185 |
|
| 186 |
-
**Reference:**
|
| 187 |
-
|
| 188 |
|
| 189 |
| Return depth | Hit | Precision | Known-positive recall | nDCG |
|
| 190 |
|---|---:|---:|---:|---:|
|
| 191 |
-
| 1 |
|
| 192 |
-
| 3 |
|
| 193 |
-
| 5 |
|
| 194 |
-
| 10 |
|
| 195 |
-
| 20 |
|
| 196 |
-
| 50 |
|
| 197 |
-
|
| 198 |
-
**The hybrid candidate ceiling is
|
| 199 |
-
recall@50
|
| 200 |
-
reranking cannot change them.
|
| 201 |
-
|
| 202 |
-
|
| 203 |
-
|
| 204 |
-
Grades 2–3 count as useful. At depth 1, both providers use the same
|
| 205 |
-
five are omitted because a first result was ungradable. Depths
|
| 206 |
-
|
| 207 |
-
|
| 208 |
-
|
| 209 |
-
|
| 210 |
-
|
| 211 |
-
|
| 212 |
-
|
| 213 |
-
|
| 214 |
-
|
| 215 |
-
[pipeline overview](https://huggingface.co/Daecore) explains retrieval and selection.
|
| 216 |
|
| 217 |
## Training data and objective
|
| 218 |
|
|
@@ -273,7 +276,7 @@ Vulkan runs through the native ONNX Runtime WebGPU plugin, [`onnxruntime-ep-webg
|
|
| 273 |
|
| 274 |
Checks used Windows x64 with an NVIDIA RTX 3060 Ti (8 GB); other GPUs and Linux are untested, even where Vulkan is available.
|
| 275 |
|
| 276 |
-
The task-specific data is mostly generated and model-judged, with no human reference panel, so it describes this development distribution rather than other users' documents. The dense and full-pipeline panels share queries and a pooled relevance reference, but evaluate different retrieval paths. Some questions omit the project or task context needed for an unambiguous judgment. The 970-query
|
| 277 |
|
| 278 |
## License
|
| 279 |
|
|
|
|
| 24 |
|
| 25 |
| Stronger private retrieval | Less forgetting | Local deployment |
|
| 26 |
|---|---|---|
|
| 27 |
+
| nDCG@10 **0.4418 → 0.5621**; precision@10 **49.71% → 64.16%** | Recovers **more than half** of the first fine-tune's loss on FiQA and SciFact | **300M parameters**, ONNX, CPU / CUDA / Vulkan |
|
| 28 |
|
| 29 |
+
The private comparison uses **925 queries with known useful evidence**, drawn
|
| 30 |
+
from 970 queries over **82,719 passages**, with reviewed results through rank
|
| 31 |
+
50. Daecore accepted some general-retrieval loss for stronger evidence retrieval
|
| 32 |
+
on its document workflow. The tables show both the gains and remaining
|
| 33 |
+
public-benchmark gaps.
|
| 34 |
|
| 35 |
Embed queries and passages with the same revision, and re-embed stored passages when switching to v2.
|
| 36 |
|
|
|
|
| 99 |
|
| 100 |
### Gemma alone: dense retrieval on Daecore data
|
| 101 |
|
| 102 |
+
Both models search the same **82,719 passages**, using FP32 exact dense
|
| 103 |
+
retrieval, the same frozen query forms and matched 128/1,024-token input
|
| 104 |
+
limits. BM25 and Ettin do not contribute. Each cell reads upstream →
|
| 105 |
+
**Daecore v2**.
|
| 106 |
|
| 107 |
+
**Reference:** 925 queries with known grade-2/3 evidence · **122,231 graded
|
| 108 |
+
query–passage pairs** for those queries, within the shared 127,665-pair top-50
|
| 109 |
+
reference (September 2026). The same subset applies to both models, including
|
| 110 |
+
queries where either model misses all useful passages.
|
| 111 |
|
| 112 |
| Cutoff | Hit | Precision | Known-positive recall | nDCG |
|
| 113 |
|---|---:|---:|---:|---:|
|
| 114 |
+
| 1 | 56.00% → **67.89%** | 56.00% → **67.89%** | 1.44% → **1.79%** | 0.4621 → **0.5366** |
|
| 115 |
+
| 3 | 76.54% → **83.24%** | 53.30% → **66.15%** | 3.94% → **5.03%** | 0.4466 → **0.5440** |
|
| 116 |
+
| 5 | 83.35% → **88.86%** | 52.38% → **65.71%** | 6.17% → **8.06%** | 0.4398 → **0.5486** |
|
| 117 |
+
| 10 | 88.97% → **92.43%** | 49.71% → **64.16%** | 11.18% → **15.07%** | 0.4418 → **0.5621** |
|
| 118 |
+
| 20 | 93.08% → **94.92%** | 46.08% → **60.94%** | 19.61% → **27.56%** | 0.4580 → **0.5888** |
|
| 119 |
+
| 50 | 97.73% → **99.03%** | 40.48% → **52.92%** | 41.12% → **57.92%** | 0.5145 → **0.6525** |
|
| 120 |
|
| 121 |

|
| 122 |
|
| 123 |
+
Every measured top-50 position is graded or explicitly excluded as ungradable,
|
| 124 |
+
with no missing-label ranges. All 925 queries remain eligible at every dense
|
| 125 |
+
cutoff. At rank 50, 164 upstream positions and 167 v2 positions are excluded
|
| 126 |
+
without backfill. Precision pools retained positions. The corpus is not
|
| 127 |
+
exhaustively labeled; the other 45 source queries have no *known* useful
|
| 128 |
+
passage, which does not prove none exists.
|
| 129 |
|
| 130 |
+
At 50, v2 finds useful evidence for **99.03%** of these queries and retrieves
|
| 131 |
+
**57.92%** of their known useful passages, versus 97.73% and 41.12% upstream.
|
| 132 |
+
The hybrid pool below has lower coverage on the same subset, despite stronger
|
| 133 |
+
early precision after reranking. Adding BM25 and capping the fused list at 50
|
| 134 |
+
can displace dense candidates.
|
| 135 |
|
| 136 |
Grades 2–3 count as useful. nDCG uses gains 0, 1, 3 and 7 against the same
|
| 137 |
+
reviewed reference for both models. Rankings from query forms are combined
|
| 138 |
+
with reciprocal-rank fusion, and identical passage text is deduplicated. The
|
| 139 |
+
[evaluation companion](evaluation/README.md) includes all-query
|
| 140 |
+
coverage, anonymized grades, identities and metric code. This is a reused
|
| 141 |
+
development panel, not an untouched test of new workspaces.
|
| 142 |
|
| 143 |
### Gemma alone: public dense retrieval
|
| 144 |
|
|
|
|
| 160 |
width, keep the first dimensions and normalize the shortened vector again.
|
| 161 |
Use the same width for queries and passages. Each quality column below is
|
| 162 |
**v2 nDCG@10**, computed from exact rankings of cached FP32 vectors. The Daecore
|
| 163 |
+
column covers the same 925-query dense panel with reviewed top-10 labels at
|
| 164 |
+
each width, against the same **122,231 graded pairs** for these queries. The 768-wide results
|
| 165 |
reproduce the corresponding full-width scores.
|
| 166 |
|
| 167 |
| Dimensions | Bytes per FP32 vector | Daecore | SciFact | FiQA | NFCorpus | SciDocs | ArguAna |
|
| 168 |
|---|---:|---:|---:|---:|---:|---:|---:|
|
| 169 |
+
| 768 (default) | 3,072 | 0.5621 | 0.7783 | 0.4468 | 0.3890 | 0.1852 | 0.6259 |
|
| 170 |
+
| 512 | 2,048 | 0.5648 | 0.7841 | 0.4374 | 0.3876 | 0.1793 | 0.6137 |
|
| 171 |
+
| 256 | 1,024 | 0.5323 | 0.7757 | 0.4091 | 0.3660 | 0.1708 | 0.5987 |
|
| 172 |
+
| 128 | 512 | 0.5069 | 0.7488 | 0.3668 | 0.3311 | 0.1484 | 0.5533 |
|
| 173 |
|
| 174 |
At 512 dimensions, each raw FP32 vector uses one-third less storage, with
|
| 175 |
slightly higher Daecore nDCG@10 in this measurement and lower scores on four
|
|
|
|
| 181 |
### Full pipeline: Gemma v2 + BM25 + Ettin
|
| 182 |
|
| 183 |
This replay measures semantic and lexical search, reciprocal-rank fusion, then
|
| 184 |
+
Ettin reranking over **82,719 passages**. The table uses the same **925 queries
|
| 185 |
+
with known useful evidence** as Gemma's dense comparison, selected from the
|
| 186 |
+
970-query source panel. A query remains included when this pipeline misses its
|
| 187 |
+
answer. Both cards share this CUDA FP16 table; it is not either model's
|
| 188 |
+
standalone score.
|
| 189 |
|
| 190 |
+
**Reference:** 122,231 graded query–passage pairs for these 925 queries, within
|
| 191 |
+
the shared 127,665-pair top-50 reference (September 2026). Abstentions are excluded.
|
| 192 |
|
| 193 |
| Return depth | Hit | Precision | Known-positive recall | nDCG |
|
| 194 |
|---|---:|---:|---:|---:|
|
| 195 |
+
| 1 | 75.87% | 75.87% | 2.12% | 0.6513 |
|
| 196 |
+
| 3 | 89.51% | 75.07% | 5.89% | 0.6423 |
|
| 197 |
+
| 5 | 92.76% | 73.71% | 9.35% | 0.6376 |
|
| 198 |
+
| 10 | 94.27% | 70.46% | 17.04% | 0.6378 |
|
| 199 |
+
| 20 | 95.46% | 64.81% | 29.72% | 0.6491 |
|
| 200 |
+
| 50 | 97.62% | 42.40% | 45.98% | 0.6130 |
|
| 201 |
+
|
| 202 |
+
**The hybrid candidate ceiling is 97.62% Hit@50 and 45.98% known-positive
|
| 203 |
+
recall@50** on this shared answerable subset. These coverage measures describe
|
| 204 |
+
the actual 50-candidate pool; reranking cannot change them. Daecore returns a
|
| 205 |
+
selected prefix of 3–20, so fixed-depth scores do not evaluate the selector's
|
| 206 |
+
choice.
|
| 207 |
+
|
| 208 |
+
Grades 2–3 count as useful. At depth 1, both providers use the same **920
|
| 209 |
+
queries**; five are omitted because a first result was ungradable. Depths
|
| 210 |
+
3–50 use all 925. Precision pools judged positions. Abstentions remove 52
|
| 211 |
+
positions at rank 20 and 93 at rank 50 per provider, without drawing in deeper
|
| 212 |
+
passages. Known-positive recall counts judged passages, not every useful
|
| 213 |
+
passage in the corpus.
|
| 214 |
+
|
| 215 |
+
The [evaluation companion](evaluation/README.md) retains
|
| 216 |
+
coverage across all 970 source queries and explains the shared reference,
|
| 217 |
+
exclusions and CUDA/Vulkan comparison. The [pipeline overview](https://huggingface.co/Daecore)
|
| 218 |
+
explains retrieval and selection.
|
|
|
|
| 219 |
|
| 220 |
## Training data and objective
|
| 221 |
|
|
|
|
| 276 |
|
| 277 |
Checks used Windows x64 with an NVIDIA RTX 3060 Ti (8 GB); other GPUs and Linux are untested, even where Vulkan is available.
|
| 278 |
|
| 279 |
+
The task-specific data is mostly generated and model-judged, with no human reference panel, so it describes this development distribution rather than other users' documents. The dense and full-pipeline panels share queries and a pooled relevance reference, but evaluate different retrieval paths. Some questions omit the project or task context needed for an unambiguous judgment. The 970-query source panel uses natural-language questions and reports no separate terse-query or paraphrase robustness scores. Passage relevance does not measure distinct-fact coverage or downstream agent success.
|
| 280 |
|
| 281 |
## License
|
| 282 |
|
evaluation/README.md
CHANGED
|
@@ -26,7 +26,7 @@ python metrics.py --directory .
|
|
| 26 |
python figures.py --output ../figures
|
| 27 |
```
|
| 28 |
|
| 29 |
-
No packages or network access are needed. Each result matches its corresponding summary. This recomputes metrics from saved results; running private retrieval again would require the private corpus.
|
| 30 |
|
| 31 |
## Dense retrieval
|
| 32 |
|
|
@@ -37,6 +37,11 @@ cosine rankings take the top 50 for each frozen query form, then merge them
|
|
| 37 |
with reciprocal-rank fusion (constant 60). Identical text is deduplicated;
|
| 38 |
there is no parent-document filter, BM25 or reranker. The record includes
|
| 39 |
model identities, source hashes, top-50 grades and reference grade counts.
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 40 |
This is a reused development panel, not a fresh holdout.
|
| 41 |
|
| 42 |
The shared reference contains **127,665 graded query–passage pairs**. The top-50
|
|
@@ -49,22 +54,25 @@ from either primary judge remained excluded. The primary assistant read all
|
|
| 49 |
stratified sample. Sixteen quotation repairs changed no grades. No person
|
| 50 |
reviewed the labels.
|
| 51 |
|
| 52 |
-
Every top-50 position is graded or explicitly excluded. All
|
| 53 |
-
eligible at 1, 3, 5, 10, 20 and 50. Upstream excludes 164
|
| 54 |
-
v2 excludes 167. Cut the original prefix first, drop
|
| 55 |
-
never backfill. A wholly abstained prefix would omit
|
| 56 |
-
at that depth. Precision pools retained positions.
|
| 57 |
-
|
| 58 |
-
|
| 59 |
-
|
| 60 |
-
|
| 61 |
-
|
| 62 |
-
|
| 63 |
-
|
| 64 |
-
|
| 65 |
-
|
| 66 |
-
|
| 67 |
-
the
|
|
|
|
|
|
|
|
|
|
| 68 |
|
| 69 |
**Public data.**
|
| 70 |
The model card compares v2 with upstream EmbeddingGemma on SciFact, FiQA, NFCorpus, SciDocs and ArguAna. `promotion.json` includes per-query nDCG@10 for all five datasets, using full corpora, matched preprocessing and official relevance judgments. V2 remains below upstream on every panel. The previous fine-tune was measured only on FiQA (0.4009) and SciFact (0.7679); its other three results are absent, not estimated.
|
|
@@ -81,7 +89,7 @@ order for ties and official linear-gain nDCG. All 1,406 ArguAna queries remain,
|
|
| 81 |
including five whose positives are absent from the corpus. These public
|
| 82 |
scores are unchanged. Private scoring uses the same frozen query forms,
|
| 83 |
dense-only fusion and expanded relevance reference as the 768-wide comparison.
|
| 84 |
-
|
| 85 |
and 37 respectively. The 768-wide results reproduce both references exactly.
|
| 86 |
Smaller widths have not been qualified through the full pipeline and do not
|
| 87 |
shorten the encoder's forward pass.
|
|
@@ -89,21 +97,38 @@ shorten the encoder's forward pass.
|
|
| 89 |
## Effect in the retrieval pipeline
|
| 90 |
|
| 91 |
The identical table on both cards comes from `serving.json`: Gemma v2 +
|
| 92 |
-
BM25 + fusion + unchanged Ettin
|
| 93 |
-
|
| 94 |
-
|
| 95 |
-
|
| 96 |
-
|
| 97 |
-
|
| 98 |
-
|
| 99 |
-
|
| 100 |
-
|
| 101 |
-
|
| 102 |
-
ungradable. Precision pools retained positions. Each provider excludes 52
|
| 103 |
positions at rank 20 and 93 at rank 50 without backfill. Fixed cutoffs are
|
| 104 |
separate from the selector's choice of a 3–20-item prefix. Vulkan matches
|
| 105 |
CUDA at Hit@5, Hit@10, Hit@20 and Hit@50; Hit@3 differs by one query and
|
| 106 |
-
nDCG@10 by 0.
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 107 |
|
| 108 |
### Historical predecessor comparison
|
| 109 |
|
|
|
|
| 26 |
python figures.py --output ../figures
|
| 27 |
```
|
| 28 |
|
| 29 |
+
No packages or network access are needed. Each result matches its corresponding summary. The `answerable` section of the dense and serving summaries supplies the card tables; `private.answerable` supplies the private width column. The outer `models` sections retain all-query results. This recomputes metrics from saved results; running private retrieval again would require the private corpus.
|
| 30 |
|
| 31 |
## Dense retrieval
|
| 32 |
|
|
|
|
| 37 |
with reciprocal-rank fusion (constant 60). Identical text is deduplicated;
|
| 38 |
there is no parent-document filter, BM25 or reranker. The record includes
|
| 39 |
model identities, source hashes, top-50 grades and reference grade counts.
|
| 40 |
+
The card reports the **925 queries with at least one known grade-2/3 passage**
|
| 41 |
+
in the shared reference. This same subset is used for both models, including
|
| 42 |
+
queries where a model retrieves no useful evidence. It contains **122,231
|
| 43 |
+
graded pairs** within the full 127,665-pair reference. The other 45 have no
|
| 44 |
+
known useful passage; their true corpus-wide answerability is unresolved.
|
| 45 |
This is a reused development panel, not a fresh holdout.
|
| 46 |
|
| 47 |
The shared reference contains **127,665 graded query–passage pairs**. The top-50
|
|
|
|
| 54 |
stratified sample. Sixteen quotation repairs changed no grades. No person
|
| 55 |
reviewed the labels.
|
| 56 |
|
| 57 |
+
Every top-50 position is graded or explicitly excluded. All 925 answerable
|
| 58 |
+
queries remain eligible at 1, 3, 5, 10, 20 and 50. Upstream excludes 164
|
| 59 |
+
positions at rank 50; v2 excludes 167. Cut the original prefix first, drop
|
| 60 |
+
abstentions second, and never backfill. A wholly abstained prefix would omit
|
| 61 |
+
the query from both arms at that depth. Precision pools retained positions.
|
| 62 |
+
Recall counts known useful passages, not exhaustive corpus labels. nDCG uses
|
| 63 |
+
gains 0, 1, 3 and 7 and reindexes retained positions.
|
| 64 |
+
|
| 65 |
+
**Reference and population changes.** Expanding the reference preserved the
|
| 66 |
+
old top-20 grades, rankings, Hit and precision. Across all 970 queries, dense
|
| 67 |
+
nDCG@10 changed from 0.4506 to 0.4363 upstream and from 0.5748 to 0.5574 for
|
| 68 |
+
v2 because newly judged relevant passages can raise ideal DCG. The earlier
|
| 69 |
+
reference contained 87,434 graded pairs.
|
| 70 |
+
|
| 71 |
+
The subsequent decision to headline the same 925 known-answerable queries
|
| 72 |
+
changes the averaging population, not the labels or rankings. On that subset,
|
| 73 |
+
nDCG@10 is **0.4418 upstream and 0.5621 for v2**. The shared reference supports
|
| 74 |
+
dense, smaller-width and current pipeline results. The historical predecessor
|
| 75 |
+
comparison below keeps its original reference and population.
|
| 76 |
|
| 77 |
**Public data.**
|
| 78 |
The model card compares v2 with upstream EmbeddingGemma on SciFact, FiQA, NFCorpus, SciDocs and ArguAna. `promotion.json` includes per-query nDCG@10 for all five datasets, using full corpora, matched preprocessing and official relevance judgments. V2 remains below upstream on every panel. The previous fine-tune was measured only on FiQA (0.4009) and SciFact (0.7679); its other three results are absent, not estimated.
|
|
|
|
| 89 |
including five whose positives are absent from the corpus. These public
|
| 90 |
scores are unchanged. Private scoring uses the same frozen query forms,
|
| 91 |
dense-only fusion and expanded relevance reference as the 768-wide comparison.
|
| 92 |
+
The same 925 answerable queries remain eligible at top 10; excluded positions are 22, 26, 16
|
| 93 |
and 37 respectively. The 768-wide results reproduce both references exactly.
|
| 94 |
Smaller widths have not been qualified through the full pipeline and do not
|
| 95 |
shorten the encoder's forward pass.
|
|
|
|
| 97 |
## Effect in the retrieval pipeline
|
| 98 |
|
| 99 |
The identical table on both cards comes from `serving.json`: Gemma v2 +
|
| 100 |
+
BM25 + fusion + unchanged Ettin. It uses the **same 925 known-answerable
|
| 101 |
+
queries and 122,231 graded pairs** as the dense table. CUDA FP16 and Vulkan
|
| 102 |
+
FP32 use the same 50 candidates for each query. At 50, Hit is **97.62%** and
|
| 103 |
+
known-positive recall is **45.98%**; reranking cannot change candidate
|
| 104 |
+
coverage. Dense v2 reaches 99.03% and 57.92% on this subset. Fusion with a
|
| 105 |
+
fixed 50-slot budget can displace dense candidates even while reranking
|
| 106 |
+
improves early precision.
|
| 107 |
+
|
| 108 |
+
Depths 3–50 use all 925 queries. Depth 1 uses 920 shared judged queries; five
|
| 109 |
+
are omitted because a first result was ungradable. Each provider excludes 52
|
|
|
|
| 110 |
positions at rank 20 and 93 at rank 50 without backfill. Fixed cutoffs are
|
| 111 |
separate from the selector's choice of a 3–20-item prefix. Vulkan matches
|
| 112 |
CUDA at Hit@5, Hit@10, Hit@20 and Hit@50; Hit@3 differs by one query and
|
| 113 |
+
nDCG@10 by 0.0004.
|
| 114 |
+
|
| 115 |
+
### All-query coverage
|
| 116 |
+
|
| 117 |
+
The records preserve all 970 source queries. This audit view includes the 45
|
| 118 |
+
without known useful evidence and is separate from the card's answerable-only
|
| 119 |
+
quality table. Hybrid top 1 uses 965 queries after shared abstention
|
| 120 |
+
exclusions; dense top 1 retains all 970. The counts below use the full
|
| 121 |
+
127,665-pair reference.
|
| 122 |
+
|
| 123 |
+
| Retrieval path | Queries | Hit@3 | Hit@50 | nDCG@10 |
|
| 124 |
+
|---|---:|---:|---:|---:|
|
| 125 |
+
| Upstream Gemma, dense | 970 | 72.99% | 93.20% | 0.4363 |
|
| 126 |
+
| Gemma v2, dense | 970 | 79.38% | 94.43% | 0.5574 |
|
| 127 |
+
| Gemma v2 + BM25 + Ettin, CUDA | 970 | 85.36% | 93.09% | 0.6315 |
|
| 128 |
+
|
| 129 |
+
A query with no known positive contributes zero Hit; grade-1 passages can
|
| 130 |
+
still contribute to nDCG. These numbers should not be mixed with the card's
|
| 131 |
+
925-query results.
|
| 132 |
|
| 133 |
### Historical predecessor comparison
|
| 134 |
|
evaluation/dimensions-summary.json
CHANGED
|
@@ -305,6 +305,259 @@
|
|
| 305 |
}
|
| 306 |
}
|
| 307 |
},
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 308 |
"corpus_passages": 82719
|
| 309 |
}
|
| 310 |
}
|
|
|
|
| 305 |
}
|
| 306 |
}
|
| 307 |
},
|
| 308 |
+
"answerable": {
|
| 309 |
+
"queries": 925,
|
| 310 |
+
"models": {
|
| 311 |
+
"768": {
|
| 312 |
+
"1": {
|
| 313 |
+
"scored_queries": 919,
|
| 314 |
+
"excluded_queries": 6,
|
| 315 |
+
"hit": 0.676822633297062,
|
| 316 |
+
"precision": 0.676822633297062,
|
| 317 |
+
"macro_precision": 0.676822633297062,
|
| 318 |
+
"ndcg": 0.53541634281569,
|
| 319 |
+
"known_positive_recall": 0.01788016629109334,
|
| 320 |
+
"recall_queries": 919,
|
| 321 |
+
"useful": 622,
|
| 322 |
+
"retained": 919,
|
| 323 |
+
"excluded_positions": 0,
|
| 324 |
+
"mean_useful": 0.676822633297062,
|
| 325 |
+
"mean_retained": 1.0
|
| 326 |
+
},
|
| 327 |
+
"3": {
|
| 328 |
+
"scored_queries": 925,
|
| 329 |
+
"excluded_queries": 0,
|
| 330 |
+
"hit": 0.8324324324324325,
|
| 331 |
+
"precision": 0.6614996395097332,
|
| 332 |
+
"macro_precision": 0.6616216216216216,
|
| 333 |
+
"ndcg": 0.5439797460516042,
|
| 334 |
+
"known_positive_recall": 0.05034823759106709,
|
| 335 |
+
"recall_queries": 925,
|
| 336 |
+
"useful": 1835,
|
| 337 |
+
"retained": 2774,
|
| 338 |
+
"excluded_positions": 1,
|
| 339 |
+
"mean_useful": 1.9837837837837837,
|
| 340 |
+
"mean_retained": 2.998918918918919
|
| 341 |
+
},
|
| 342 |
+
"5": {
|
| 343 |
+
"scored_queries": 925,
|
| 344 |
+
"excluded_queries": 0,
|
| 345 |
+
"hit": 0.8886486486486487,
|
| 346 |
+
"precision": 0.6571366688325753,
|
| 347 |
+
"macro_precision": 0.6574774774774775,
|
| 348 |
+
"ndcg": 0.5486144310934794,
|
| 349 |
+
"known_positive_recall": 0.08055790386567772,
|
| 350 |
+
"recall_queries": 925,
|
| 351 |
+
"useful": 3034,
|
| 352 |
+
"retained": 4617,
|
| 353 |
+
"excluded_positions": 8,
|
| 354 |
+
"mean_useful": 3.28,
|
| 355 |
+
"mean_retained": 4.991351351351351
|
| 356 |
+
},
|
| 357 |
+
"10": {
|
| 358 |
+
"scored_queries": 925,
|
| 359 |
+
"excluded_queries": 0,
|
| 360 |
+
"hit": 0.9243243243243243,
|
| 361 |
+
"precision": 0.6416341569137408,
|
| 362 |
+
"macro_precision": 0.6421261261261262,
|
| 363 |
+
"ndcg": 0.5620625351358739,
|
| 364 |
+
"known_positive_recall": 0.15074270958466607,
|
| 365 |
+
"recall_queries": 925,
|
| 366 |
+
"useful": 5921,
|
| 367 |
+
"retained": 9228,
|
| 368 |
+
"excluded_positions": 22,
|
| 369 |
+
"mean_useful": 6.401081081081081,
|
| 370 |
+
"mean_retained": 9.976216216216216
|
| 371 |
+
}
|
| 372 |
+
},
|
| 373 |
+
"512": {
|
| 374 |
+
"1": {
|
| 375 |
+
"scored_queries": 919,
|
| 376 |
+
"excluded_queries": 6,
|
| 377 |
+
"hit": 0.6779107725788901,
|
| 378 |
+
"precision": 0.6779107725788901,
|
| 379 |
+
"macro_precision": 0.6779107725788901,
|
| 380 |
+
"ndcg": 0.5517902481993886,
|
| 381 |
+
"known_positive_recall": 0.01775688496570127,
|
| 382 |
+
"recall_queries": 919,
|
| 383 |
+
"useful": 623,
|
| 384 |
+
"retained": 919,
|
| 385 |
+
"excluded_positions": 0,
|
| 386 |
+
"mean_useful": 0.6779107725788901,
|
| 387 |
+
"mean_retained": 1.0
|
| 388 |
+
},
|
| 389 |
+
"3": {
|
| 390 |
+
"scored_queries": 925,
|
| 391 |
+
"excluded_queries": 0,
|
| 392 |
+
"hit": 0.8356756756756757,
|
| 393 |
+
"precision": 0.6661854926019487,
|
| 394 |
+
"macro_precision": 0.6664864864864865,
|
| 395 |
+
"ndcg": 0.5454577108638902,
|
| 396 |
+
"known_positive_recall": 0.05057307077004017,
|
| 397 |
+
"recall_queries": 925,
|
| 398 |
+
"useful": 1846,
|
| 399 |
+
"retained": 2771,
|
| 400 |
+
"excluded_positions": 4,
|
| 401 |
+
"mean_useful": 1.9956756756756757,
|
| 402 |
+
"mean_retained": 2.9956756756756757
|
| 403 |
+
},
|
| 404 |
+
"5": {
|
| 405 |
+
"scored_queries": 925,
|
| 406 |
+
"excluded_queries": 0,
|
| 407 |
+
"hit": 0.8832432432432432,
|
| 408 |
+
"precision": 0.6616117850953206,
|
| 409 |
+
"macro_precision": 0.6617657657657657,
|
| 410 |
+
"ndcg": 0.5530614761090054,
|
| 411 |
+
"known_positive_recall": 0.08121602068063129,
|
| 412 |
+
"recall_queries": 925,
|
| 413 |
+
"useful": 3054,
|
| 414 |
+
"retained": 4616,
|
| 415 |
+
"excluded_positions": 9,
|
| 416 |
+
"mean_useful": 3.3016216216216216,
|
| 417 |
+
"mean_retained": 4.99027027027027
|
| 418 |
+
},
|
| 419 |
+
"10": {
|
| 420 |
+
"scored_queries": 925,
|
| 421 |
+
"excluded_queries": 0,
|
| 422 |
+
"hit": 0.9254054054054054,
|
| 423 |
+
"precision": 0.643213356461405,
|
| 424 |
+
"macro_precision": 0.6438635778635778,
|
| 425 |
+
"ndcg": 0.5647836166130059,
|
| 426 |
+
"known_positive_recall": 0.15004173661513098,
|
| 427 |
+
"recall_queries": 925,
|
| 428 |
+
"useful": 5933,
|
| 429 |
+
"retained": 9224,
|
| 430 |
+
"excluded_positions": 26,
|
| 431 |
+
"mean_useful": 6.414054054054054,
|
| 432 |
+
"mean_retained": 9.971891891891891
|
| 433 |
+
}
|
| 434 |
+
},
|
| 435 |
+
"256": {
|
| 436 |
+
"1": {
|
| 437 |
+
"scored_queries": 919,
|
| 438 |
+
"excluded_queries": 6,
|
| 439 |
+
"hit": 0.6332970620239391,
|
| 440 |
+
"precision": 0.6332970620239391,
|
| 441 |
+
"macro_precision": 0.6332970620239391,
|
| 442 |
+
"ndcg": 0.5139126379605161,
|
| 443 |
+
"known_positive_recall": 0.015976956236435802,
|
| 444 |
+
"recall_queries": 919,
|
| 445 |
+
"useful": 582,
|
| 446 |
+
"retained": 919,
|
| 447 |
+
"excluded_positions": 0,
|
| 448 |
+
"mean_useful": 0.6332970620239391,
|
| 449 |
+
"mean_retained": 1.0
|
| 450 |
+
},
|
| 451 |
+
"3": {
|
| 452 |
+
"scored_queries": 925,
|
| 453 |
+
"excluded_queries": 0,
|
| 454 |
+
"hit": 0.7978378378378378,
|
| 455 |
+
"precision": 0.6245487364620939,
|
| 456 |
+
"macro_precision": 0.6252252252252252,
|
| 457 |
+
"ndcg": 0.5122675608706706,
|
| 458 |
+
"known_positive_recall": 0.046233615834183193,
|
| 459 |
+
"recall_queries": 925,
|
| 460 |
+
"useful": 1730,
|
| 461 |
+
"retained": 2770,
|
| 462 |
+
"excluded_positions": 5,
|
| 463 |
+
"mean_useful": 1.8702702702702703,
|
| 464 |
+
"mean_retained": 2.9945945945945946
|
| 465 |
+
},
|
| 466 |
+
"5": {
|
| 467 |
+
"scored_queries": 925,
|
| 468 |
+
"excluded_queries": 0,
|
| 469 |
+
"hit": 0.8616216216216216,
|
| 470 |
+
"precision": 0.6214285714285714,
|
| 471 |
+
"macro_precision": 0.6217837837837837,
|
| 472 |
+
"ndcg": 0.519156867098927,
|
| 473 |
+
"known_positive_recall": 0.0744111972114428,
|
| 474 |
+
"recall_queries": 925,
|
| 475 |
+
"useful": 2871,
|
| 476 |
+
"retained": 4620,
|
| 477 |
+
"excluded_positions": 5,
|
| 478 |
+
"mean_useful": 3.1037837837837836,
|
| 479 |
+
"mean_retained": 4.994594594594594
|
| 480 |
+
},
|
| 481 |
+
"10": {
|
| 482 |
+
"scored_queries": 925,
|
| 483 |
+
"excluded_queries": 0,
|
| 484 |
+
"hit": 0.9156756756756756,
|
| 485 |
+
"precision": 0.6102447476716483,
|
| 486 |
+
"macro_precision": 0.6107237237237237,
|
| 487 |
+
"ndcg": 0.5322729475032464,
|
| 488 |
+
"known_positive_recall": 0.1419199356602385,
|
| 489 |
+
"recall_queries": 925,
|
| 490 |
+
"useful": 5635,
|
| 491 |
+
"retained": 9234,
|
| 492 |
+
"excluded_positions": 16,
|
| 493 |
+
"mean_useful": 6.091891891891892,
|
| 494 |
+
"mean_retained": 9.982702702702703
|
| 495 |
+
}
|
| 496 |
+
},
|
| 497 |
+
"128": {
|
| 498 |
+
"1": {
|
| 499 |
+
"scored_queries": 919,
|
| 500 |
+
"excluded_queries": 6,
|
| 501 |
+
"hit": 0.6006528835690969,
|
| 502 |
+
"precision": 0.6006528835690969,
|
| 503 |
+
"macro_precision": 0.6006528835690969,
|
| 504 |
+
"ndcg": 0.4720969998445515,
|
| 505 |
+
"known_positive_recall": 0.015019269226427342,
|
| 506 |
+
"recall_queries": 919,
|
| 507 |
+
"useful": 552,
|
| 508 |
+
"retained": 919,
|
| 509 |
+
"excluded_positions": 0,
|
| 510 |
+
"mean_useful": 0.6006528835690969,
|
| 511 |
+
"mean_retained": 1.0
|
| 512 |
+
},
|
| 513 |
+
"3": {
|
| 514 |
+
"scored_queries": 925,
|
| 515 |
+
"excluded_queries": 0,
|
| 516 |
+
"hit": 0.7762162162162162,
|
| 517 |
+
"precision": 0.6061482820976491,
|
| 518 |
+
"macro_precision": 0.6061261261261262,
|
| 519 |
+
"ndcg": 0.48302039261543295,
|
| 520 |
+
"known_positive_recall": 0.044531751738185646,
|
| 521 |
+
"recall_queries": 925,
|
| 522 |
+
"useful": 1676,
|
| 523 |
+
"retained": 2765,
|
| 524 |
+
"excluded_positions": 10,
|
| 525 |
+
"mean_useful": 1.8118918918918918,
|
| 526 |
+
"mean_retained": 2.9891891891891893
|
| 527 |
+
},
|
| 528 |
+
"5": {
|
| 529 |
+
"scored_queries": 925,
|
| 530 |
+
"excluded_queries": 0,
|
| 531 |
+
"hit": 0.8432432432432433,
|
| 532 |
+
"precision": 0.6026475694444444,
|
| 533 |
+
"macro_precision": 0.6025585585585586,
|
| 534 |
+
"ndcg": 0.4894363954353818,
|
| 535 |
+
"known_positive_recall": 0.07159737689223461,
|
| 536 |
+
"recall_queries": 925,
|
| 537 |
+
"useful": 2777,
|
| 538 |
+
"retained": 4608,
|
| 539 |
+
"excluded_positions": 17,
|
| 540 |
+
"mean_useful": 3.002162162162162,
|
| 541 |
+
"mean_retained": 4.981621621621621
|
| 542 |
+
},
|
| 543 |
+
"10": {
|
| 544 |
+
"scored_queries": 925,
|
| 545 |
+
"excluded_queries": 0,
|
| 546 |
+
"hit": 0.907027027027027,
|
| 547 |
+
"precision": 0.5936177140996418,
|
| 548 |
+
"macro_precision": 0.5940930930930931,
|
| 549 |
+
"ndcg": 0.506862270631805,
|
| 550 |
+
"known_positive_recall": 0.13623796718702827,
|
| 551 |
+
"recall_queries": 925,
|
| 552 |
+
"useful": 5469,
|
| 553 |
+
"retained": 9213,
|
| 554 |
+
"excluded_positions": 37,
|
| 555 |
+
"mean_useful": 5.912432432432432,
|
| 556 |
+
"mean_retained": 9.96
|
| 557 |
+
}
|
| 558 |
+
}
|
| 559 |
+
}
|
| 560 |
+
},
|
| 561 |
"corpus_passages": 82719
|
| 562 |
}
|
| 563 |
}
|
evaluation/figures.py
CHANGED
|
@@ -63,6 +63,8 @@ def reranker(summary: dict) -> str:
|
|
| 63 |
|
| 64 |
|
| 65 |
def retriever(summary: dict) -> str:
|
|
|
|
|
|
|
| 66 |
cutoffs = sorted(map(int, summary['models']['upstream']))
|
| 67 |
x = list(range(len(cutoffs)))
|
| 68 |
panels = []
|
|
@@ -77,7 +79,7 @@ def retriever(summary: dict) -> str:
|
|
| 77 |
xlim=(0, len(cutoffs) - 1), ylim=(0, 1.02), xticks=list(enumerate(map(str, cutoffs)))))
|
| 78 |
return svg.render_grid(panels, columns=3,
|
| 79 |
title='Gemma v2: matched dense retrieval on Daecore data',
|
| 80 |
-
subtitle=f"{summary['queries']:,} queries · {
|
| 81 |
legend=legend, panel_width=300, panel_height=270)
|
| 82 |
|
| 83 |
|
|
|
|
| 63 |
|
| 64 |
|
| 65 |
def retriever(summary: dict) -> str:
|
| 66 |
+
corpus_passages = summary['corpus_passages']
|
| 67 |
+
summary = summary['answerable']
|
| 68 |
cutoffs = sorted(map(int, summary['models']['upstream']))
|
| 69 |
x = list(range(len(cutoffs)))
|
| 70 |
panels = []
|
|
|
|
| 79 |
xlim=(0, len(cutoffs) - 1), ylim=(0, 1.02), xticks=list(enumerate(map(str, cutoffs)))))
|
| 80 |
return svg.render_grid(panels, columns=3,
|
| 81 |
title='Gemma v2: matched dense retrieval on Daecore data',
|
| 82 |
+
subtitle=f"{summary['queries']:,} known-answerable queries · {corpus_passages:,} passages · abstentions excluded",
|
| 83 |
legend=legend, panel_width=300, panel_height=270)
|
| 84 |
|
| 85 |
|
evaluation/metrics.py
CHANGED
|
@@ -117,10 +117,11 @@ def summarize_reranker(data: dict) -> dict:
|
|
| 117 |
|
| 118 |
|
| 119 |
def summarize_retriever(data: dict) -> dict:
|
| 120 |
-
"""
|
| 121 |
if type(data['corpus_passages']) is not int or data['corpus_passages'] <= 0:
|
| 122 |
raise ValueError('Dense comparison requires a positive corpus size')
|
| 123 |
return {**_summarize_ranked_grades(data, include_selected=False),
|
|
|
|
| 124 |
'corpus_passages': data['corpus_passages']}
|
| 125 |
|
| 126 |
|
|
@@ -152,7 +153,7 @@ def summarize_dimensions(data: dict) -> dict:
|
|
| 152 |
return result
|
| 153 |
|
| 154 |
|
| 155 |
-
def _summarize_ranked_grades(data: dict, *, include_selected: bool) -> dict:
|
| 156 |
"""Reviewed exclusions inside each original dense or hybrid prefix.
|
| 157 |
|
| 158 |
A null is permitted only for an explicitly excluded judging abstention.
|
|
@@ -185,7 +186,13 @@ def _summarize_ranked_grades(data: dict, *, include_selected: bool) -> dict:
|
|
| 185 |
if any((grade is not None if drop else type(grade) is not int or grade not in range(4))
|
| 186 |
for grade, drop in zip(ranked, excluded, strict=True)):
|
| 187 |
raise ValueError('Only declared abstentions may lack grades')
|
|
|
|
|
|
|
|
|
|
|
|
|
| 188 |
output = {'queries': len(rows), 'models': {}}
|
|
|
|
|
|
|
| 189 |
requested_cutoffs = tuple(k for k in CUTOFFS if k <= depth_limit)
|
| 190 |
if include_selected:
|
| 191 |
requested_cutoffs += ('selected',)
|
|
@@ -254,10 +261,16 @@ def summarize_promotion(data: dict) -> dict:
|
|
| 254 |
return output
|
| 255 |
|
| 256 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 257 |
SUMMARIZERS = {
|
| 258 |
'classifier': summarize_classifier, 'reranker': summarize_reranker,
|
| 259 |
'retriever': summarize_retriever, 'dimensions': summarize_dimensions,
|
| 260 |
-
'promotion': summarize_promotion, 'serving':
|
| 261 |
}
|
| 262 |
|
| 263 |
|
|
|
|
| 117 |
|
| 118 |
|
| 119 |
def summarize_retriever(data: dict) -> dict:
|
| 120 |
+
"""Dense rankings, with both full-panel and known-answerable summaries."""
|
| 121 |
if type(data['corpus_passages']) is not int or data['corpus_passages'] <= 0:
|
| 122 |
raise ValueError('Dense comparison requires a positive corpus size')
|
| 123 |
return {**_summarize_ranked_grades(data, include_selected=False),
|
| 124 |
+
'answerable': _summarize_ranked_grades(data, include_selected=False, answerable_only=True),
|
| 125 |
'corpus_passages': data['corpus_passages']}
|
| 126 |
|
| 127 |
|
|
|
|
| 153 |
return result
|
| 154 |
|
| 155 |
|
| 156 |
+
def _summarize_ranked_grades(data: dict, *, include_selected: bool, answerable_only: bool = False) -> dict:
|
| 157 |
"""Reviewed exclusions inside each original dense or hybrid prefix.
|
| 158 |
|
| 159 |
A null is permitted only for an explicitly excluded judging abstention.
|
|
|
|
| 186 |
if any((grade is not None if drop else type(grade) is not int or grade not in range(4))
|
| 187 |
for grade, drop in zip(ranked, excluded, strict=True)):
|
| 188 |
raise ValueError('Only declared abstentions may lack grades')
|
| 189 |
+
# The shared relevance reference defines answerability, never one arm's
|
| 190 |
+
# retrieved prefix. Validate every source row before applying this filter.
|
| 191 |
+
if answerable_only:
|
| 192 |
+
rows = [row for row in rows if row['reference_grade_counts']['2'] + row['reference_grade_counts']['3'] > 0]
|
| 193 |
output = {'queries': len(rows), 'models': {}}
|
| 194 |
+
if not rows:
|
| 195 |
+
return output # No conditional score exists; do not substitute zeros.
|
| 196 |
requested_cutoffs = tuple(k for k in CUTOFFS if k <= depth_limit)
|
| 197 |
if include_selected:
|
| 198 |
requested_cutoffs += ('selected',)
|
|
|
|
| 261 |
return output
|
| 262 |
|
| 263 |
|
| 264 |
+
def summarize_serving(data: dict) -> dict:
|
| 265 |
+
"""Current hybrid quality uses the same reference-defined eligible queries."""
|
| 266 |
+
return {**summarize_promotion(data),
|
| 267 |
+
'answerable': _summarize_ranked_grades(data, include_selected=True, answerable_only=True)}
|
| 268 |
+
|
| 269 |
+
|
| 270 |
SUMMARIZERS = {
|
| 271 |
'classifier': summarize_classifier, 'reranker': summarize_reranker,
|
| 272 |
'retriever': summarize_retriever, 'dimensions': summarize_dimensions,
|
| 273 |
+
'promotion': summarize_promotion, 'serving': summarize_serving,
|
| 274 |
}
|
| 275 |
|
| 276 |
|
evaluation/retriever-summary.json
CHANGED
|
@@ -186,5 +186,194 @@
|
|
| 186 |
}
|
| 187 |
}
|
| 188 |
},
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 189 |
"corpus_passages": 82719
|
| 190 |
}
|
|
|
|
| 186 |
}
|
| 187 |
}
|
| 188 |
},
|
| 189 |
+
"answerable": {
|
| 190 |
+
"queries": 925,
|
| 191 |
+
"models": {
|
| 192 |
+
"upstream": {
|
| 193 |
+
"1": {
|
| 194 |
+
"scored_queries": 925,
|
| 195 |
+
"excluded_queries": 0,
|
| 196 |
+
"hit": 0.56,
|
| 197 |
+
"precision": 0.56,
|
| 198 |
+
"macro_precision": 0.56,
|
| 199 |
+
"ndcg": 0.46208494208494205,
|
| 200 |
+
"known_positive_recall": 0.014444554022554491,
|
| 201 |
+
"recall_queries": 925,
|
| 202 |
+
"useful": 518,
|
| 203 |
+
"retained": 925,
|
| 204 |
+
"excluded_positions": 0,
|
| 205 |
+
"mean_useful": 0.56,
|
| 206 |
+
"mean_retained": 1.0
|
| 207 |
+
},
|
| 208 |
+
"3": {
|
| 209 |
+
"scored_queries": 925,
|
| 210 |
+
"excluded_queries": 0,
|
| 211 |
+
"hit": 0.7654054054054054,
|
| 212 |
+
"precision": 0.5329967544175983,
|
| 213 |
+
"macro_precision": 0.532972972972973,
|
| 214 |
+
"ndcg": 0.44657619780045693,
|
| 215 |
+
"known_positive_recall": 0.03938697535513605,
|
| 216 |
+
"recall_queries": 925,
|
| 217 |
+
"useful": 1478,
|
| 218 |
+
"retained": 2773,
|
| 219 |
+
"excluded_positions": 2,
|
| 220 |
+
"mean_useful": 1.597837837837838,
|
| 221 |
+
"mean_retained": 2.997837837837838
|
| 222 |
+
},
|
| 223 |
+
"5": {
|
| 224 |
+
"scored_queries": 925,
|
| 225 |
+
"excluded_queries": 0,
|
| 226 |
+
"hit": 0.8335135135135135,
|
| 227 |
+
"precision": 0.5238198354265916,
|
| 228 |
+
"macro_precision": 0.523927927927928,
|
| 229 |
+
"ndcg": 0.4398171919899157,
|
| 230 |
+
"known_positive_recall": 0.06172226483192968,
|
| 231 |
+
"recall_queries": 925,
|
| 232 |
+
"useful": 2419,
|
| 233 |
+
"retained": 4618,
|
| 234 |
+
"excluded_positions": 7,
|
| 235 |
+
"mean_useful": 2.615135135135135,
|
| 236 |
+
"mean_retained": 4.992432432432432
|
| 237 |
+
},
|
| 238 |
+
"10": {
|
| 239 |
+
"scored_queries": 925,
|
| 240 |
+
"excluded_queries": 0,
|
| 241 |
+
"hit": 0.8897297297297297,
|
| 242 |
+
"precision": 0.49707348796878387,
|
| 243 |
+
"macro_precision": 0.49713856713856713,
|
| 244 |
+
"ndcg": 0.4417676357044915,
|
| 245 |
+
"known_positive_recall": 0.11180689389376004,
|
| 246 |
+
"recall_queries": 925,
|
| 247 |
+
"useful": 4586,
|
| 248 |
+
"retained": 9226,
|
| 249 |
+
"excluded_positions": 24,
|
| 250 |
+
"mean_useful": 4.957837837837838,
|
| 251 |
+
"mean_retained": 9.974054054054054
|
| 252 |
+
},
|
| 253 |
+
"20": {
|
| 254 |
+
"scored_queries": 925,
|
| 255 |
+
"excluded_queries": 0,
|
| 256 |
+
"hit": 0.9308108108108109,
|
| 257 |
+
"precision": 0.46080026024723486,
|
| 258 |
+
"macro_precision": 0.4614682460502894,
|
| 259 |
+
"ndcg": 0.4579770106113412,
|
| 260 |
+
"known_positive_recall": 0.19611550928151497,
|
| 261 |
+
"recall_queries": 925,
|
| 262 |
+
"useful": 8499,
|
| 263 |
+
"retained": 18444,
|
| 264 |
+
"excluded_positions": 56,
|
| 265 |
+
"mean_useful": 9.188108108108109,
|
| 266 |
+
"mean_retained": 19.93945945945946
|
| 267 |
+
},
|
| 268 |
+
"50": {
|
| 269 |
+
"scored_queries": 925,
|
| 270 |
+
"excluded_queries": 0,
|
| 271 |
+
"hit": 0.9772972972972973,
|
| 272 |
+
"precision": 0.4048301002473636,
|
| 273 |
+
"macro_precision": 0.4055311496261139,
|
| 274 |
+
"ndcg": 0.5145143143872781,
|
| 275 |
+
"known_positive_recall": 0.41118693689165037,
|
| 276 |
+
"recall_queries": 925,
|
| 277 |
+
"useful": 18657,
|
| 278 |
+
"retained": 46086,
|
| 279 |
+
"excluded_positions": 164,
|
| 280 |
+
"mean_useful": 20.16972972972973,
|
| 281 |
+
"mean_retained": 49.8227027027027
|
| 282 |
+
}
|
| 283 |
+
},
|
| 284 |
+
"finetuned": {
|
| 285 |
+
"1": {
|
| 286 |
+
"scored_queries": 925,
|
| 287 |
+
"excluded_queries": 0,
|
| 288 |
+
"hit": 0.6789189189189189,
|
| 289 |
+
"precision": 0.6789189189189189,
|
| 290 |
+
"macro_precision": 0.6789189189189189,
|
| 291 |
+
"ndcg": 0.5365765765765765,
|
| 292 |
+
"known_positive_recall": 0.017869431761799028,
|
| 293 |
+
"recall_queries": 925,
|
| 294 |
+
"useful": 628,
|
| 295 |
+
"retained": 925,
|
| 296 |
+
"excluded_positions": 0,
|
| 297 |
+
"mean_useful": 0.6789189189189189,
|
| 298 |
+
"mean_retained": 1.0
|
| 299 |
+
},
|
| 300 |
+
"3": {
|
| 301 |
+
"scored_queries": 925,
|
| 302 |
+
"excluded_queries": 0,
|
| 303 |
+
"hit": 0.8324324324324325,
|
| 304 |
+
"precision": 0.6614996395097332,
|
| 305 |
+
"macro_precision": 0.6616216216216216,
|
| 306 |
+
"ndcg": 0.5439797460516042,
|
| 307 |
+
"known_positive_recall": 0.05034823759106709,
|
| 308 |
+
"recall_queries": 925,
|
| 309 |
+
"useful": 1835,
|
| 310 |
+
"retained": 2774,
|
| 311 |
+
"excluded_positions": 1,
|
| 312 |
+
"mean_useful": 1.9837837837837837,
|
| 313 |
+
"mean_retained": 2.998918918918919
|
| 314 |
+
},
|
| 315 |
+
"5": {
|
| 316 |
+
"scored_queries": 925,
|
| 317 |
+
"excluded_queries": 0,
|
| 318 |
+
"hit": 0.8886486486486487,
|
| 319 |
+
"precision": 0.6571366688325753,
|
| 320 |
+
"macro_precision": 0.6574774774774775,
|
| 321 |
+
"ndcg": 0.5486144310934794,
|
| 322 |
+
"known_positive_recall": 0.08055790386567772,
|
| 323 |
+
"recall_queries": 925,
|
| 324 |
+
"useful": 3034,
|
| 325 |
+
"retained": 4617,
|
| 326 |
+
"excluded_positions": 8,
|
| 327 |
+
"mean_useful": 3.28,
|
| 328 |
+
"mean_retained": 4.991351351351351
|
| 329 |
+
},
|
| 330 |
+
"10": {
|
| 331 |
+
"scored_queries": 925,
|
| 332 |
+
"excluded_queries": 0,
|
| 333 |
+
"hit": 0.9243243243243243,
|
| 334 |
+
"precision": 0.6416341569137408,
|
| 335 |
+
"macro_precision": 0.6421261261261262,
|
| 336 |
+
"ndcg": 0.5620625351358739,
|
| 337 |
+
"known_positive_recall": 0.15074270958466607,
|
| 338 |
+
"recall_queries": 925,
|
| 339 |
+
"useful": 5921,
|
| 340 |
+
"retained": 9228,
|
| 341 |
+
"excluded_positions": 22,
|
| 342 |
+
"mean_useful": 6.401081081081081,
|
| 343 |
+
"mean_retained": 9.976216216216216
|
| 344 |
+
},
|
| 345 |
+
"20": {
|
| 346 |
+
"scored_queries": 925,
|
| 347 |
+
"excluded_queries": 0,
|
| 348 |
+
"hit": 0.9491891891891892,
|
| 349 |
+
"precision": 0.6094215861657722,
|
| 350 |
+
"macro_precision": 0.6098764600343548,
|
| 351 |
+
"ndcg": 0.5888460119487677,
|
| 352 |
+
"known_positive_recall": 0.27556154002694083,
|
| 353 |
+
"recall_queries": 925,
|
| 354 |
+
"useful": 11242,
|
| 355 |
+
"retained": 18447,
|
| 356 |
+
"excluded_positions": 53,
|
| 357 |
+
"mean_useful": 12.153513513513513,
|
| 358 |
+
"mean_retained": 19.942702702702704
|
| 359 |
+
},
|
| 360 |
+
"50": {
|
| 361 |
+
"scored_queries": 925,
|
| 362 |
+
"excluded_queries": 0,
|
| 363 |
+
"hit": 0.9902702702702703,
|
| 364 |
+
"precision": 0.5291539179306902,
|
| 365 |
+
"macro_precision": 0.5297403182882328,
|
| 366 |
+
"ndcg": 0.6524763537042031,
|
| 367 |
+
"known_positive_recall": 0.5791516627126307,
|
| 368 |
+
"recall_queries": 925,
|
| 369 |
+
"useful": 24385,
|
| 370 |
+
"retained": 46083,
|
| 371 |
+
"excluded_positions": 167,
|
| 372 |
+
"mean_useful": 26.36216216216216,
|
| 373 |
+
"mean_retained": 49.81945945945946
|
| 374 |
+
}
|
| 375 |
+
}
|
| 376 |
+
}
|
| 377 |
+
},
|
| 378 |
"corpus_passages": 82719
|
| 379 |
}
|
evaluation/serving-summary.json
CHANGED
|
@@ -216,5 +216,224 @@
|
|
| 216 |
}
|
| 217 |
}
|
| 218 |
},
|
| 219 |
-
"public": {}
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 220 |
}
|
|
|
|
| 216 |
}
|
| 217 |
}
|
| 218 |
},
|
| 219 |
+
"public": {},
|
| 220 |
+
"answerable": {
|
| 221 |
+
"queries": 925,
|
| 222 |
+
"models": {
|
| 223 |
+
"cuda": {
|
| 224 |
+
"1": {
|
| 225 |
+
"scored_queries": 920,
|
| 226 |
+
"excluded_queries": 5,
|
| 227 |
+
"hit": 0.758695652173913,
|
| 228 |
+
"precision": 0.758695652173913,
|
| 229 |
+
"macro_precision": 0.758695652173913,
|
| 230 |
+
"ndcg": 0.6513457556935818,
|
| 231 |
+
"known_positive_recall": 0.021209009540392988,
|
| 232 |
+
"recall_queries": 920,
|
| 233 |
+
"useful": 698,
|
| 234 |
+
"retained": 920,
|
| 235 |
+
"excluded_positions": 0,
|
| 236 |
+
"mean_useful": 0.758695652173913,
|
| 237 |
+
"mean_retained": 1.0
|
| 238 |
+
},
|
| 239 |
+
"3": {
|
| 240 |
+
"scored_queries": 925,
|
| 241 |
+
"excluded_queries": 0,
|
| 242 |
+
"hit": 0.8951351351351351,
|
| 243 |
+
"precision": 0.7507235890014472,
|
| 244 |
+
"macro_precision": 0.7515315315315315,
|
| 245 |
+
"ndcg": 0.6422807686434969,
|
| 246 |
+
"known_positive_recall": 0.0589083117861917,
|
| 247 |
+
"recall_queries": 925,
|
| 248 |
+
"useful": 2075,
|
| 249 |
+
"retained": 2764,
|
| 250 |
+
"excluded_positions": 11,
|
| 251 |
+
"mean_useful": 2.2432432432432434,
|
| 252 |
+
"mean_retained": 2.9881081081081082
|
| 253 |
+
},
|
| 254 |
+
"5": {
|
| 255 |
+
"scored_queries": 925,
|
| 256 |
+
"excluded_queries": 0,
|
| 257 |
+
"hit": 0.9275675675675675,
|
| 258 |
+
"precision": 0.7371044646727352,
|
| 259 |
+
"macro_precision": 0.7373873873873874,
|
| 260 |
+
"ndcg": 0.6375956845322198,
|
| 261 |
+
"known_positive_recall": 0.09351524011264825,
|
| 262 |
+
"recall_queries": 925,
|
| 263 |
+
"useful": 3401,
|
| 264 |
+
"retained": 4614,
|
| 265 |
+
"excluded_positions": 11,
|
| 266 |
+
"mean_useful": 3.676756756756757,
|
| 267 |
+
"mean_retained": 4.988108108108108
|
| 268 |
+
},
|
| 269 |
+
"10": {
|
| 270 |
+
"scored_queries": 925,
|
| 271 |
+
"excluded_queries": 0,
|
| 272 |
+
"hit": 0.9427027027027027,
|
| 273 |
+
"precision": 0.7045750216825672,
|
| 274 |
+
"macro_precision": 0.704967824967825,
|
| 275 |
+
"ndcg": 0.6377512015628823,
|
| 276 |
+
"known_positive_recall": 0.17039667688880922,
|
| 277 |
+
"recall_queries": 925,
|
| 278 |
+
"useful": 6499,
|
| 279 |
+
"retained": 9224,
|
| 280 |
+
"excluded_positions": 26,
|
| 281 |
+
"mean_useful": 7.025945945945946,
|
| 282 |
+
"mean_retained": 9.971891891891891
|
| 283 |
+
},
|
| 284 |
+
"20": {
|
| 285 |
+
"scored_queries": 925,
|
| 286 |
+
"excluded_queries": 0,
|
| 287 |
+
"hit": 0.9545945945945946,
|
| 288 |
+
"precision": 0.6480919340849957,
|
| 289 |
+
"macro_precision": 0.648584612953034,
|
| 290 |
+
"ndcg": 0.6491335337062211,
|
| 291 |
+
"known_positive_recall": 0.29717756138114526,
|
| 292 |
+
"recall_queries": 925,
|
| 293 |
+
"useful": 11956,
|
| 294 |
+
"retained": 18448,
|
| 295 |
+
"excluded_positions": 52,
|
| 296 |
+
"mean_useful": 12.925405405405405,
|
| 297 |
+
"mean_retained": 19.943783783783783
|
| 298 |
+
},
|
| 299 |
+
"50": {
|
| 300 |
+
"scored_queries": 925,
|
| 301 |
+
"excluded_queries": 0,
|
| 302 |
+
"hit": 0.9762162162162162,
|
| 303 |
+
"precision": 0.424031024546656,
|
| 304 |
+
"macro_precision": 0.42417201849319736,
|
| 305 |
+
"ndcg": 0.6129768665312807,
|
| 306 |
+
"known_positive_recall": 0.4598077844640693,
|
| 307 |
+
"recall_queries": 925,
|
| 308 |
+
"useful": 19572,
|
| 309 |
+
"retained": 46157,
|
| 310 |
+
"excluded_positions": 93,
|
| 311 |
+
"mean_useful": 21.158918918918918,
|
| 312 |
+
"mean_retained": 49.89945945945946
|
| 313 |
+
},
|
| 314 |
+
"selected": {
|
| 315 |
+
"scored_queries": 925,
|
| 316 |
+
"excluded_queries": 0,
|
| 317 |
+
"hit": 0.9037837837837838,
|
| 318 |
+
"precision": 0.8188024463092021,
|
| 319 |
+
"macro_precision": 0.7382827833849506,
|
| 320 |
+
"ndcg": 0.6407625959742856,
|
| 321 |
+
"known_positive_recall": 0.128026594631235,
|
| 322 |
+
"recall_queries": 925,
|
| 323 |
+
"useful": 5757,
|
| 324 |
+
"retained": 7031,
|
| 325 |
+
"excluded_positions": 17,
|
| 326 |
+
"mean_useful": 6.223783783783784,
|
| 327 |
+
"mean_retained": 7.601081081081081
|
| 328 |
+
}
|
| 329 |
+
},
|
| 330 |
+
"vulkan": {
|
| 331 |
+
"1": {
|
| 332 |
+
"scored_queries": 920,
|
| 333 |
+
"excluded_queries": 5,
|
| 334 |
+
"hit": 0.7597826086956522,
|
| 335 |
+
"precision": 0.7597826086956522,
|
| 336 |
+
"macro_precision": 0.7597826086956522,
|
| 337 |
+
"ndcg": 0.6516563146997929,
|
| 338 |
+
"known_positive_recall": 0.021228078953055077,
|
| 339 |
+
"recall_queries": 920,
|
| 340 |
+
"useful": 699,
|
| 341 |
+
"retained": 920,
|
| 342 |
+
"excluded_positions": 0,
|
| 343 |
+
"mean_useful": 0.7597826086956522,
|
| 344 |
+
"mean_retained": 1.0
|
| 345 |
+
},
|
| 346 |
+
"3": {
|
| 347 |
+
"scored_queries": 925,
|
| 348 |
+
"excluded_queries": 0,
|
| 349 |
+
"hit": 0.894054054054054,
|
| 350 |
+
"precision": 0.7507235890014472,
|
| 351 |
+
"macro_precision": 0.7515315315315315,
|
| 352 |
+
"ndcg": 0.6421528020036147,
|
| 353 |
+
"known_positive_recall": 0.05893952330659241,
|
| 354 |
+
"recall_queries": 925,
|
| 355 |
+
"useful": 2075,
|
| 356 |
+
"retained": 2764,
|
| 357 |
+
"excluded_positions": 11,
|
| 358 |
+
"mean_useful": 2.2432432432432434,
|
| 359 |
+
"mean_retained": 2.9881081081081082
|
| 360 |
+
},
|
| 361 |
+
"5": {
|
| 362 |
+
"scored_queries": 925,
|
| 363 |
+
"excluded_queries": 0,
|
| 364 |
+
"hit": 0.9275675675675675,
|
| 365 |
+
"precision": 0.7366139171905485,
|
| 366 |
+
"macro_precision": 0.736954954954955,
|
| 367 |
+
"ndcg": 0.6371821653908674,
|
| 368 |
+
"known_positive_recall": 0.09344587015679974,
|
| 369 |
+
"recall_queries": 925,
|
| 370 |
+
"useful": 3398,
|
| 371 |
+
"retained": 4613,
|
| 372 |
+
"excluded_positions": 12,
|
| 373 |
+
"mean_useful": 3.6735135135135133,
|
| 374 |
+
"mean_retained": 4.987027027027027
|
| 375 |
+
},
|
| 376 |
+
"10": {
|
| 377 |
+
"scored_queries": 925,
|
| 378 |
+
"excluded_queries": 0,
|
| 379 |
+
"hit": 0.9427027027027027,
|
| 380 |
+
"precision": 0.7051490514905149,
|
| 381 |
+
"macro_precision": 0.7054877734877735,
|
| 382 |
+
"ndcg": 0.6381124055299272,
|
| 383 |
+
"known_positive_recall": 0.17053838380216288,
|
| 384 |
+
"recall_queries": 925,
|
| 385 |
+
"useful": 6505,
|
| 386 |
+
"retained": 9225,
|
| 387 |
+
"excluded_positions": 25,
|
| 388 |
+
"mean_useful": 7.032432432432432,
|
| 389 |
+
"mean_retained": 9.972972972972974
|
| 390 |
+
},
|
| 391 |
+
"20": {
|
| 392 |
+
"scored_queries": 925,
|
| 393 |
+
"excluded_queries": 0,
|
| 394 |
+
"hit": 0.9545945945945946,
|
| 395 |
+
"precision": 0.6479835212489159,
|
| 396 |
+
"macro_precision": 0.6484765048449259,
|
| 397 |
+
"ndcg": 0.6490652861835569,
|
| 398 |
+
"known_positive_recall": 0.2971249330393808,
|
| 399 |
+
"recall_queries": 925,
|
| 400 |
+
"useful": 11954,
|
| 401 |
+
"retained": 18448,
|
| 402 |
+
"excluded_positions": 52,
|
| 403 |
+
"mean_useful": 12.923243243243244,
|
| 404 |
+
"mean_retained": 19.943783783783783
|
| 405 |
+
},
|
| 406 |
+
"50": {
|
| 407 |
+
"scored_queries": 925,
|
| 408 |
+
"excluded_queries": 0,
|
| 409 |
+
"hit": 0.9762162162162162,
|
| 410 |
+
"precision": 0.424031024546656,
|
| 411 |
+
"macro_precision": 0.42417201849319736,
|
| 412 |
+
"ndcg": 0.6129402668287812,
|
| 413 |
+
"known_positive_recall": 0.4598077844640693,
|
| 414 |
+
"recall_queries": 925,
|
| 415 |
+
"useful": 19572,
|
| 416 |
+
"retained": 46157,
|
| 417 |
+
"excluded_positions": 93,
|
| 418 |
+
"mean_useful": 21.158918918918918,
|
| 419 |
+
"mean_retained": 49.89945945945946
|
| 420 |
+
},
|
| 421 |
+
"selected": {
|
| 422 |
+
"scored_queries": 925,
|
| 423 |
+
"excluded_queries": 0,
|
| 424 |
+
"hit": 0.9027027027027027,
|
| 425 |
+
"precision": 0.8181689141234918,
|
| 426 |
+
"macro_precision": 0.7380948996103794,
|
| 427 |
+
"ndcg": 0.640658479488419,
|
| 428 |
+
"known_positive_recall": 0.12825382711378852,
|
| 429 |
+
"recall_queries": 925,
|
| 430 |
+
"useful": 5764,
|
| 431 |
+
"retained": 7045,
|
| 432 |
+
"excluded_positions": 17,
|
| 433 |
+
"mean_useful": 6.231351351351352,
|
| 434 |
+
"mean_retained": 7.616216216216216
|
| 435 |
+
}
|
| 436 |
+
}
|
| 437 |
+
}
|
| 438 |
+
}
|
| 439 |
}
|
figures/gemma-comparison.svg
CHANGED
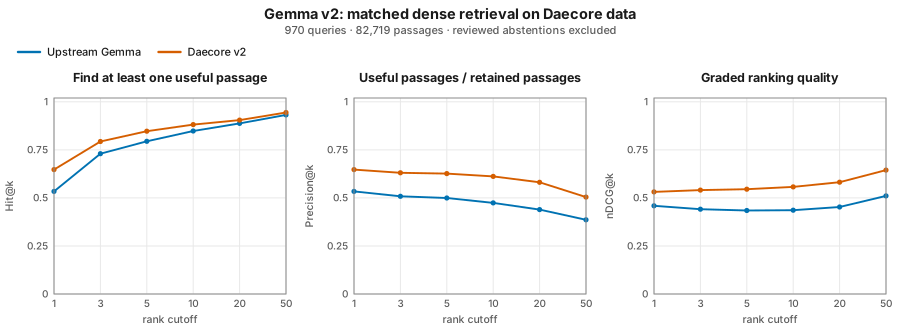
|
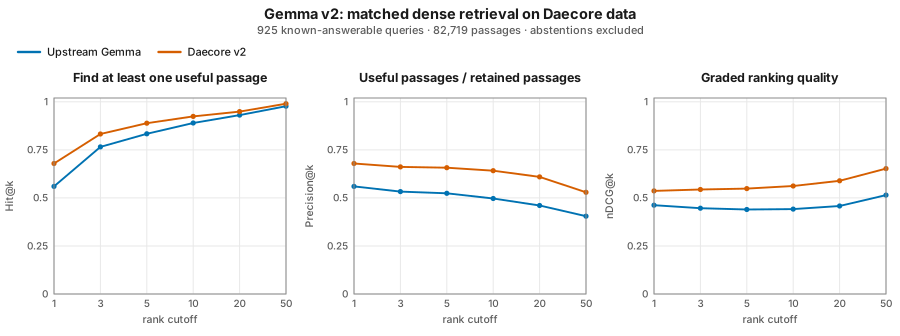
|
publication-manifest.json
CHANGED
|
@@ -12,7 +12,7 @@
|
|
| 12 |
"export_receipt_sha256": "e24e1692f7e03c9af8040bb3f6e310a061d305f485861007f1f37d36808b20d8",
|
| 13 |
"serving_sha256": "8c088b1635875d5406e148782b303cfc5a961138600783fb4842b413b98a98c3",
|
| 14 |
"source_model_tree_sha256": "30a7b9f1c42b1fcee29a6729742685d5b744e8fa87d13cefab2fd2d49ea9150e",
|
| 15 |
-
"staged_at": "2026-09-
|
| 16 |
"files": {
|
| 17 |
"added_tokens.json": {
|
| 18 |
"sha256": "50b2f405ba56a26d4913fd772089992252d7f942123cc0a034d96424221ba946",
|
|
@@ -80,8 +80,8 @@
|
|
| 80 |
"binding": "packaging record"
|
| 81 |
},
|
| 82 |
"evaluation/README.md": {
|
| 83 |
-
"sha256": "
|
| 84 |
-
"size":
|
| 85 |
"binding": "packaging record"
|
| 86 |
},
|
| 87 |
"evaluation/serving-qualification.json": {
|
|
@@ -90,8 +90,8 @@
|
|
| 90 |
"binding": "packaging record"
|
| 91 |
},
|
| 92 |
"evaluation/metrics.py": {
|
| 93 |
-
"sha256": "
|
| 94 |
-
"size":
|
| 95 |
"binding": "packaging record"
|
| 96 |
},
|
| 97 |
"evaluation/chunking.md": {
|
|
@@ -100,13 +100,13 @@
|
|
| 100 |
"binding": "packaging record"
|
| 101 |
},
|
| 102 |
"evaluation/retriever-summary.json": {
|
| 103 |
-
"sha256": "
|
| 104 |
-
"size":
|
| 105 |
"binding": "packaging record"
|
| 106 |
},
|
| 107 |
"evaluation/dimensions-summary.json": {
|
| 108 |
-
"sha256": "
|
| 109 |
-
"size":
|
| 110 |
"binding": "packaging record"
|
| 111 |
},
|
| 112 |
"evaluation/promotion-summary.json": {
|
|
@@ -115,8 +115,8 @@
|
|
| 115 |
"binding": "packaging record"
|
| 116 |
},
|
| 117 |
"evaluation/serving-summary.json": {
|
| 118 |
-
"sha256": "
|
| 119 |
-
"size":
|
| 120 |
"binding": "packaging record"
|
| 121 |
},
|
| 122 |
"evaluation/retriever.json": {
|
|
@@ -140,8 +140,8 @@
|
|
| 140 |
"binding": "packaging record"
|
| 141 |
},
|
| 142 |
"evaluation/figures.py": {
|
| 143 |
-
"sha256": "
|
| 144 |
-
"size":
|
| 145 |
"binding": "packaging record"
|
| 146 |
},
|
| 147 |
"evaluation/svg_figures.py": {
|
|
@@ -150,15 +150,15 @@
|
|
| 150 |
"binding": "packaging record"
|
| 151 |
},
|
| 152 |
"figures/gemma-comparison.svg": {
|
| 153 |
-
"sha256": "
|
| 154 |
-
"size":
|
| 155 |
"binding": "packaging record"
|
| 156 |
},
|
| 157 |
"README.md": {
|
| 158 |
-
"sha256": "
|
| 159 |
-
"size":
|
| 160 |
"binding": "model card with upload-relative links",
|
| 161 |
-
"source_sha256": "
|
| 162 |
}
|
| 163 |
}
|
| 164 |
}
|
|
|
|
| 12 |
"export_receipt_sha256": "e24e1692f7e03c9af8040bb3f6e310a061d305f485861007f1f37d36808b20d8",
|
| 13 |
"serving_sha256": "8c088b1635875d5406e148782b303cfc5a961138600783fb4842b413b98a98c3",
|
| 14 |
"source_model_tree_sha256": "30a7b9f1c42b1fcee29a6729742685d5b744e8fa87d13cefab2fd2d49ea9150e",
|
| 15 |
+
"staged_at": "2026-09-30T02:12:24+00:00",
|
| 16 |
"files": {
|
| 17 |
"added_tokens.json": {
|
| 18 |
"sha256": "50b2f405ba56a26d4913fd772089992252d7f942123cc0a034d96424221ba946",
|
|
|
|
| 80 |
"binding": "packaging record"
|
| 81 |
},
|
| 82 |
"evaluation/README.md": {
|
| 83 |
+
"sha256": "bf96501863235b426b679d84e0bba96bc5b5d7fdba76571966af92993ce4150e",
|
| 84 |
+
"size": 11100,
|
| 85 |
"binding": "packaging record"
|
| 86 |
},
|
| 87 |
"evaluation/serving-qualification.json": {
|
|
|
|
| 90 |
"binding": "packaging record"
|
| 91 |
},
|
| 92 |
"evaluation/metrics.py": {
|
| 93 |
+
"sha256": "22536c4437be0b8c678df0dee4c45e31c5413e91f1fecf104750486f3e372d46",
|
| 94 |
+
"size": 19120,
|
| 95 |
"binding": "packaging record"
|
| 96 |
},
|
| 97 |
"evaluation/chunking.md": {
|
|
|
|
| 100 |
"binding": "packaging record"
|
| 101 |
},
|
| 102 |
"evaluation/retriever-summary.json": {
|
| 103 |
+
"sha256": "1cf1586a83ee90246588cd31b93b7aec0115c620c39ed646d4b3936fed1f7b4f",
|
| 104 |
+
"size": 12432,
|
| 105 |
"binding": "packaging record"
|
| 106 |
},
|
| 107 |
"evaluation/dimensions-summary.json": {
|
| 108 |
+
"sha256": "4fd5d6bd5659612618e9b4ca3c5245e9b497dfcb0a8d0f3b3b70d65e55b358b1",
|
| 109 |
+
"size": 18756,
|
| 110 |
"binding": "packaging record"
|
| 111 |
},
|
| 112 |
"evaluation/promotion-summary.json": {
|
|
|
|
| 115 |
"binding": "packaging record"
|
| 116 |
},
|
| 117 |
"evaluation/serving-summary.json": {
|
| 118 |
+
"sha256": "029b323fee810cae91c0a37c4d234e560a727b8219d582f1e7bd5fcb74b317de",
|
| 119 |
+
"size": 14521,
|
| 120 |
"binding": "packaging record"
|
| 121 |
},
|
| 122 |
"evaluation/retriever.json": {
|
|
|
|
| 140 |
"binding": "packaging record"
|
| 141 |
},
|
| 142 |
"evaluation/figures.py": {
|
| 143 |
+
"sha256": "f13945b350e007deb18a2eafbe1c5708a71b9df62ee12b6833d07f3e2a06094e",
|
| 144 |
+
"size": 5490,
|
| 145 |
"binding": "packaging record"
|
| 146 |
},
|
| 147 |
"evaluation/svg_figures.py": {
|
|
|
|
| 150 |
"binding": "packaging record"
|
| 151 |
},
|
| 152 |
"figures/gemma-comparison.svg": {
|
| 153 |
+
"sha256": "700dd8262d27ce78ba7433efb054da3d5ea950c5bfaf4ae83f909eae283d4022",
|
| 154 |
+
"size": 14511,
|
| 155 |
"binding": "packaging record"
|
| 156 |
},
|
| 157 |
"README.md": {
|
| 158 |
+
"sha256": "7c9add0392d4d28e8e048a2308ac4cf88b5ac0d9ee2e5e49160625d3731975cb",
|
| 159 |
+
"size": 16352,
|
| 160 |
"binding": "model card with upload-relative links",
|
| 161 |
+
"source_sha256": "38f074c37bde704f74971f782fa291850fdd325a4030671a344ef0ba4152a93d"
|
| 162 |
}
|
| 163 |
}
|
| 164 |
}
|