

Raon
Collection
10 items • Updated • 46


Raon-Speech is a 9B-parameter speech language model that supports state-of-the-art speech understanding, answering and generation in English and Korean. This model successfully transforms a pre-trained LLM into a SpeechLM to both understand and generate speech without compromising its original language capabilities. It trains on millions of hours of English-Korean speech-text datasets with the following training stages: (1) speech encoder-decoder alignment, (2) end-to-end SpeechLM pre-training, and (3) multi-reward DPO-based post-training.
AutoModel.from_pretrained with trust_remote_code=True — no custom package installation required.Natural speech generated by Raon-Speech-9B via text-to-speech, synthesized directly from the target transcript.
후기 근데 후기 어떻게 보면 내가 좀 인터넷으로 사는 거는 좀 믿음이 안가는 거 같애. 좀 하도 뭐라 해야 되지 좀 그렇게 정품이라고 해도
아 근데 어 일단 대전에서만 하는 게 아니라 이제 대전 어차피 그냥 대전 이번 달까지 월세 그거 냈으니까 그냥 있다가
I don't want to make it a whole thing, but like, the dishes have been piling up again and I— I don't know, I feel weird bringing it up every single time.
It says it was supposed to arrive yesterday, but it's still just sitting there in transit or whatever, so I don't know, I guess I'll just keep waiting.
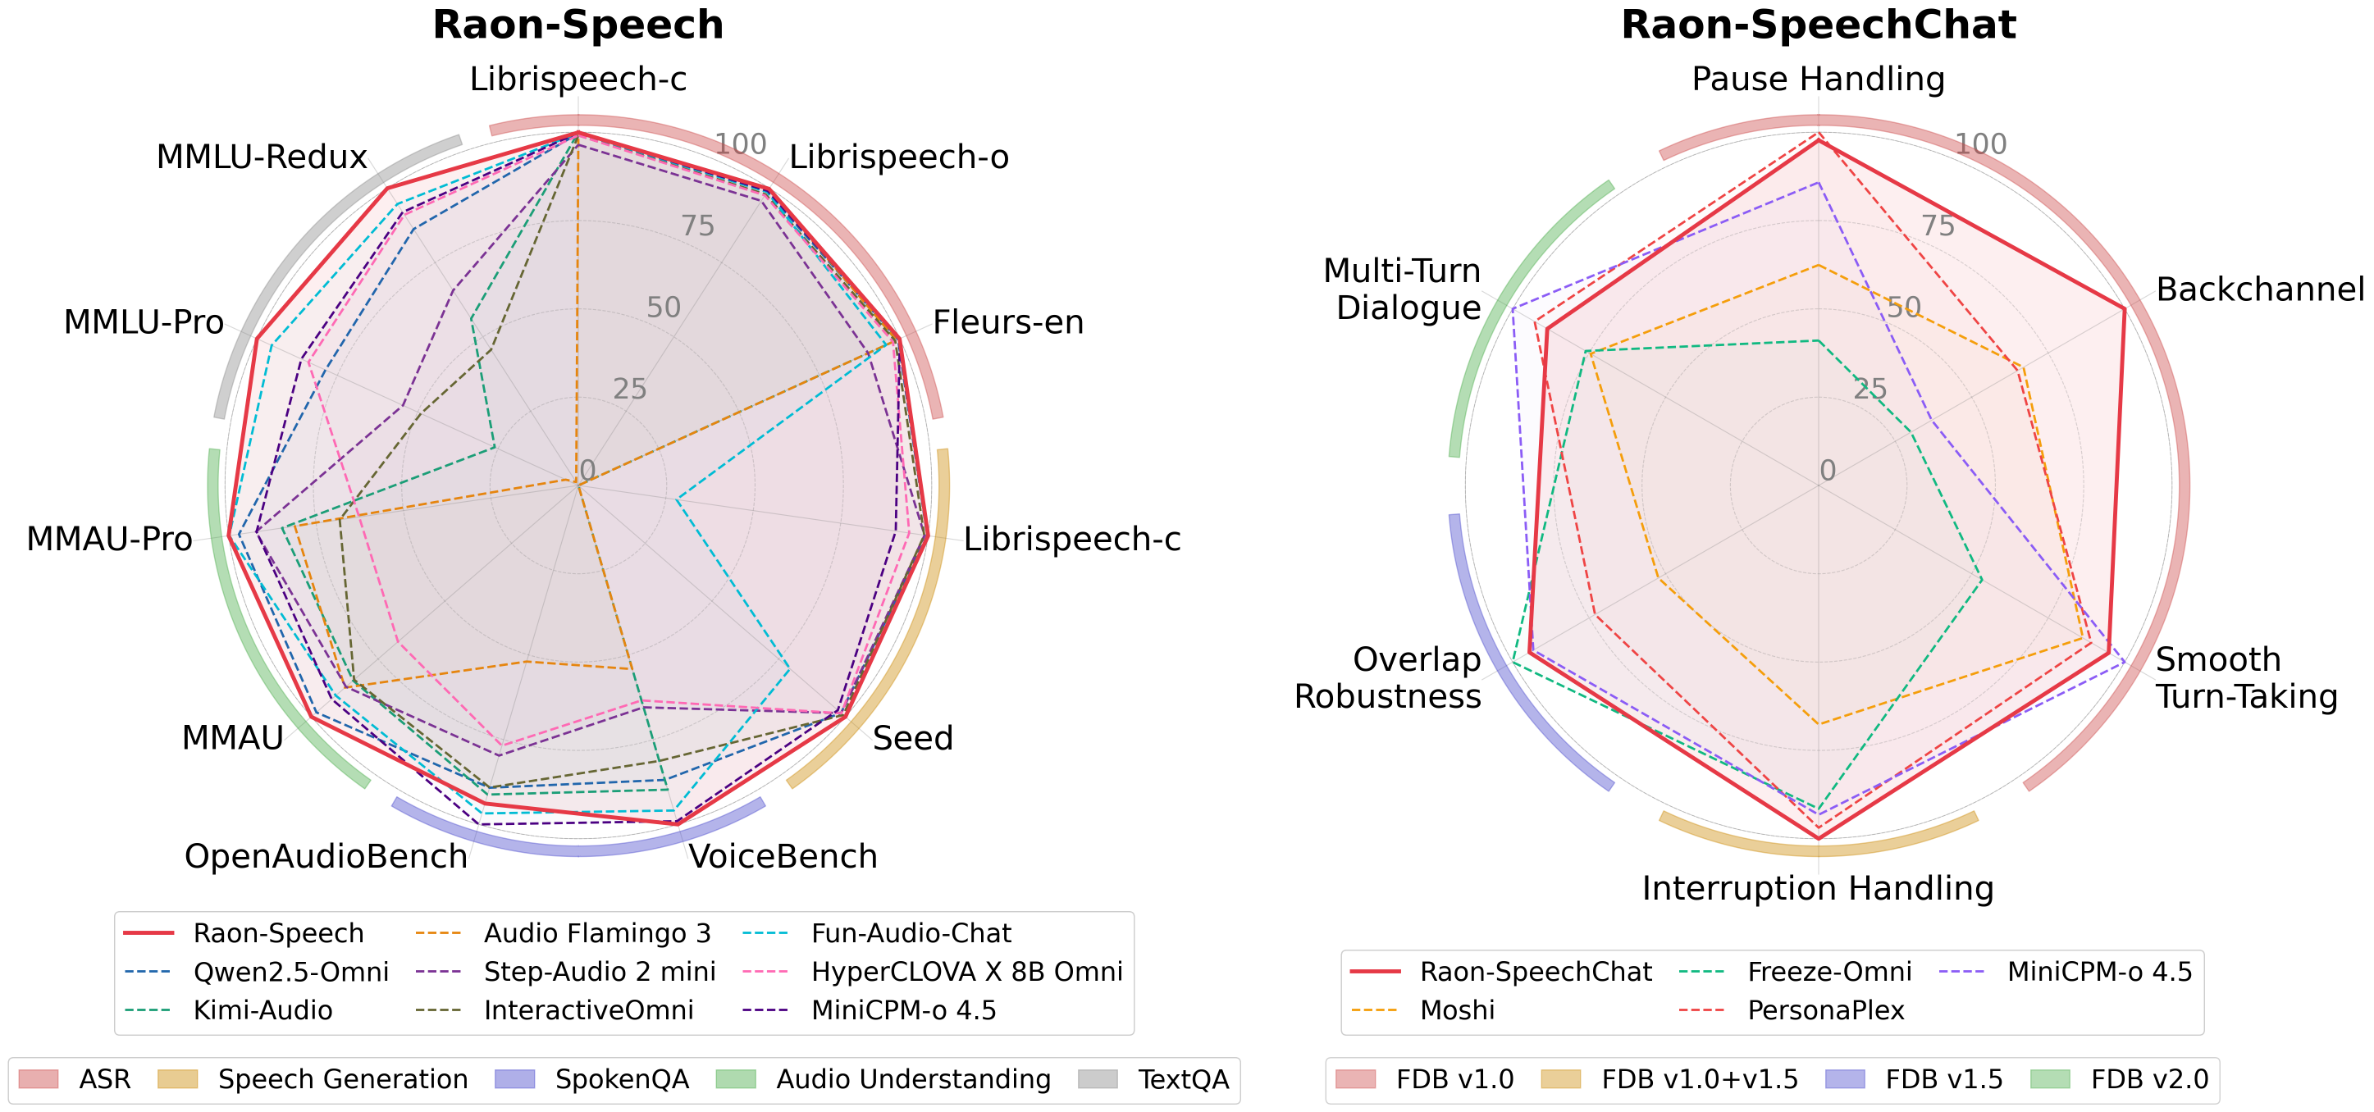
Raon-Speech is optimized for low-latency, real-time speech generation while maintaining strong performance across ASR, speech generation, spoken QA, audio understanding, and text QA tasks.
Measured with LibriSpeech test-clean samples on single-GPU setups via streaming TTS. All values are averaged.
| Metric | RTX 6000 Pro | L40S |
|---|---|---|
| RTF | 0.27 (3.7× real-time) | 0.45 (2.2× real-time) |
| TTFT | 617 ms | 887 ms |
| TBT | 135 ms | 233 ms |
pip install 'transformers>=4.57.1,<5.0' torch torchaudio soundfile accelerate
# Optional
pip install speechbrain # for TTS with speaker voice conditioning
pip install gradio # for Gradio demo
No pip install raon needed.
from transformers import AutoConfig
from transformers.dynamic_module_utils import get_class_from_dynamic_module
MODEL_ID = "KRAFTON/Raon-Speech-9B"
config = AutoConfig.from_pretrained(MODEL_ID, trust_remote_code=True)
RaonPipeline = get_class_from_dynamic_module(
"modeling_raon.RaonPipeline",
MODEL_ID,
revision=getattr(config, "_commit_hash", None),
)
pipe = RaonPipeline(MODEL_ID, device="cuda", dtype="bfloat16")
git clone https://github.com/krafton-ai/Raon-Speech.git
cd Raon-Speech/raon
pip install -e . # or: uv sync
from raon import RaonPipeline
# From Hub (local code + Hub weights)
pipe = RaonPipeline("KRAFTON/Raon-Speech-9B")
# From local path
pipe = RaonPipeline("/path/to/raon-model")
text = pipe.stt("audio.wav")
# Without speaker conditioning
audio, sr = pipe.tts("Hello, how are you?")
pipe.save_audio((audio, sr), "output.wav")
# With speaker conditioning (requires speechbrain)
audio, sr = pipe.tts("Hello, how are you?", speaker_audio="speaker_ref.wav")
answer = pipe.textqa("What is the speaker saying?", audio="audio.wav")
answer = pipe.speech_chat("question.wav")
messages = [
{
"role": "user",
"content": [
{"type": "audio", "audio": "audio.wav"},
{"type": "text", "text": "Transcribe and summarise this audio."},
],
},
]
response = pipe.chat(messages)
git clone https://github.com/krafton-ai/vllm-omni.git
cd vllm-omni
docker build -f docker/Dockerfile.ci -t vllm-omni .
docker run --rm --gpus all \
--shm-size=16g \
-p 8000:8000 \
vllm-omni \
bash -c "vllm serve KRAFTON/Raon-Speech-9B --omni --port 8000 --trust-remote-code"
curl -X POST http://localhost:8000/v1/audio/speech \
-H "Content-Type: application/json" \
-d '{
"input": "Hello, how are you?",
"model": "KRAFTON/Raon-Speech-9B",
"response_format": "wav"
}' --output output.wav
curl -X POST http://localhost:8000/v1/audio/speech \
-H "Content-Type: application/json" \
-d '{
"input": "Hello, how are you?",
"model": "KRAFTON/Raon-Speech-9B",
"ref_audio": "data:audio/wav;base64,'$(base64 -w0 speaker_ref.wav)'",
"task_type": "Base",
"response_format": "wav"
}' --output cloned.wav
curl -X POST http://localhost:8000/v1/chat/completions \
-H "Content-Type: application/json" \
-d '{
"model": "KRAFTON/Raon-Speech-9B",
"messages": [
{
"role": "user",
"content": [
{"type": "audio_url", "audio_url": {"url": "data:audio/wav;base64,'"$(base64 -w0 audio.wav)"'"}},
{"type": "text", "text": "Transcribe the audio into text."}
]
}
]
}'
This checkpoint is suitable for:
This repository is licensed under the Creative Commons Attribution-NonCommercial 4.0 International License.
The current release includes:
For exact architectural details, training hyperparameters, Korean benchmark construction, and the Raon-SpeechChat full-duplex extension, consult the technical report included in this repository.
@misc{raonspeech,
title = {Raon-Speech Technical Report},
author = {{KRAFTON}},
month = {April},
year = {2026}
}
© 2026 KRAFTON
# pip install -U transformers accelerate
# Load model directly
from transformers import AutoModel
model = AutoModel.from_pretrained("KRAFTON/Raon-Speech-9B", trust_remote_code=True, device_map="auto")