


Model card: lead with the model's value and the live-web results
Browse files- README.md +55 -46
- assets/liveweb.png +0 -0
README.md
CHANGED
|
@@ -23,24 +23,44 @@ datasets:
|
|
| 23 |
|
| 24 |
# WebJev-35B-A3B
|
| 25 |
|
| 26 |
-
**
|
|
|
|
|
|
|
|
|
|
|
|
|
| 27 |
|
| 28 |
[**Code**](https://github.com/lexmount/WebJev) · [**Dataset**](https://huggingface.co/datasets/Lexmount/WebJev) ·
|
| 29 |
[**Training**](https://github.com/lexmount/WebJev/tree/main/train)
|
| 30 |
|
| 31 |
-
WebJev-35B-A3B
|
| 32 |
-
distribution over the options. It does not generate text: each question is answered with a single forward pass that
|
| 33 |
-
reads the logits of the option labels. There is no decoding, no output parsing, and no answer outside the options you
|
| 34 |
-
list.
|
| 35 |
|
| 36 |
-
|
| 37 |
|
| 38 |
-
- **
|
| 39 |
-
|
| 40 |
-
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 41 |
|
| 42 |
-
|
| 43 |
-
|
|
|
|
|
|
|
| 44 |
|
| 45 |
| | |
|
| 46 |
|---|---|
|
|
@@ -59,50 +79,20 @@ judgments.
|
|
| 59 |
|
| 60 |

|
| 61 |
|
| 62 |
-
## Highlights
|
| 63 |
-
|
| 64 |
-
- **Web agents.** Plugged into the same browser agent, WebJev-35B-A3B solves **38.5%** of 125 real-website tasks,
|
| 65 |
-
against **16.7%** for jev-1.13.
|
| 66 |
-
- **General decisions.** On eight structured-decision benchmarks WebJev averages **83.7%**. It leads jev-1.13 on four
|
| 67 |
-
of them: JevBench, Nimble, customer-ticket triage and multi-class classification.
|
| 68 |
-
- **One forward pass, no decoding.** Each question is answered by a single forward pass that returns a full
|
| 69 |
-
distribution over its options. The answer is always one of the options you listed.
|
| 70 |
-
|
| 71 |
## Evaluation
|
| 72 |
|
| 73 |
All numbers are measured with the released BF16 weights served by vLLM, at temperature 1.0. The jev-1.13 numbers were
|
| 74 |
measured through its official API on the same inputs.
|
| 75 |
|
| 76 |
-
### Eight structured-decision benchmarks
|
| 77 |
-
|
| 78 |
-
Each item gives a state and a set of candidate answers. The model's choice is correct when it equals the reference
|
| 79 |
-
label. The table reports accuracy.
|
| 80 |
-
|
| 81 |
-

|
| 82 |
-
|
| 83 |
-
| Benchmark (items) | What it measures | jev-1.13 | **WebJev-35B-A3B** |
|
| 84 |
-
|---|---|---:|---:|
|
| 85 |
-
| JevBench public (231) | general structured decisions (intent, extraction, tool choice, policy); the hard tier has long policies, multi-hop, temporal and numeric reasoning, and trap items | 85.71 | **87.88** |
|
| 86 |
-
| Nimble held-out (324) | fine-grained evidence checking with minimal pairs: one fact changes and the answer flips | 92.59 | **92.90** |
|
| 87 |
-
| SemIf external (252) | claim verification: supported, refuted or not enough evidence | **98.41** | 98.02 |
|
| 88 |
-
| Customer-ticket triage (873) | routing queue, anger and priority of support tickets (partly Korean) | 74.91 | **76.29** |
|
| 89 |
-
| Cross-task transfer, dev (764) | MMLU, Emotion, TweetEval, QNLI, PAWS, SciQ and programmatic policy-rule questions | **85.21** | 85.08 |
|
| 90 |
-
| Multi-class decisions, dev (1,468) | news topic, review sentiment and stars, 77-way banking intent, question and entity type, yes/no reading comprehension, entailment, policy rules | 83.31 | **86.31** |
|
| 91 |
-
| MMLU-Pro, 10 options (1,000) | college-level knowledge and reasoning across subjects | **83.40** | 69.40 |
|
| 92 |
-
| Typed business decisions, test (2,000) | agent-trajectory stop and escalation, customer requests, invoice approval, security-alert severity; teacher labels | **74.05** | 73.90 |
|
| 93 |
-
| **Average (equal weights)** | | **84.70** | 83.72 |
|
| 94 |
-
|
| 95 |
### End-to-end web tasks
|
| 96 |
|
| 97 |
-
|
| 98 |
-
|
| 99 |
-
|
| 100 |
|
| 101 |
- **Success rate** = solved ÷ evaluable tasks. Tasks lost to browser infrastructure or grader errors are excluded.
|
| 102 |
- **Strict rate** counts all 125 tasks.
|
| 103 |
|
| 104 |
-

|
| 105 |
-
|
| 106 |
| Task set | jev-1.13 | **WebJev-35B-A3B** |
|
| 107 |
|---|---:|---:|
|
| 108 |
| All tasks | 16.67% (20/120) | **38.52% (47/122)** |
|
|
@@ -111,8 +101,27 @@ deterministic grader checks the final page state and answer.
|
|
| 111 |
| WebVoyager | 25.00% (6/24) | **45.83% (11/24)** |
|
| 112 |
| Strict, all 125 tasks | 16.00% | **37.60%** |
|
| 113 |
|
| 114 |
-
|
| 115 |
-
between
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 116 |
|
| 117 |
### Speed
|
| 118 |
|
|
|
|
| 23 |
|
| 24 |
# WebJev-35B-A3B
|
| 25 |
|
| 26 |
+
**The decision model that more than doubles what web agents achieve on real websites.**
|
| 27 |
+
|
| 28 |
+
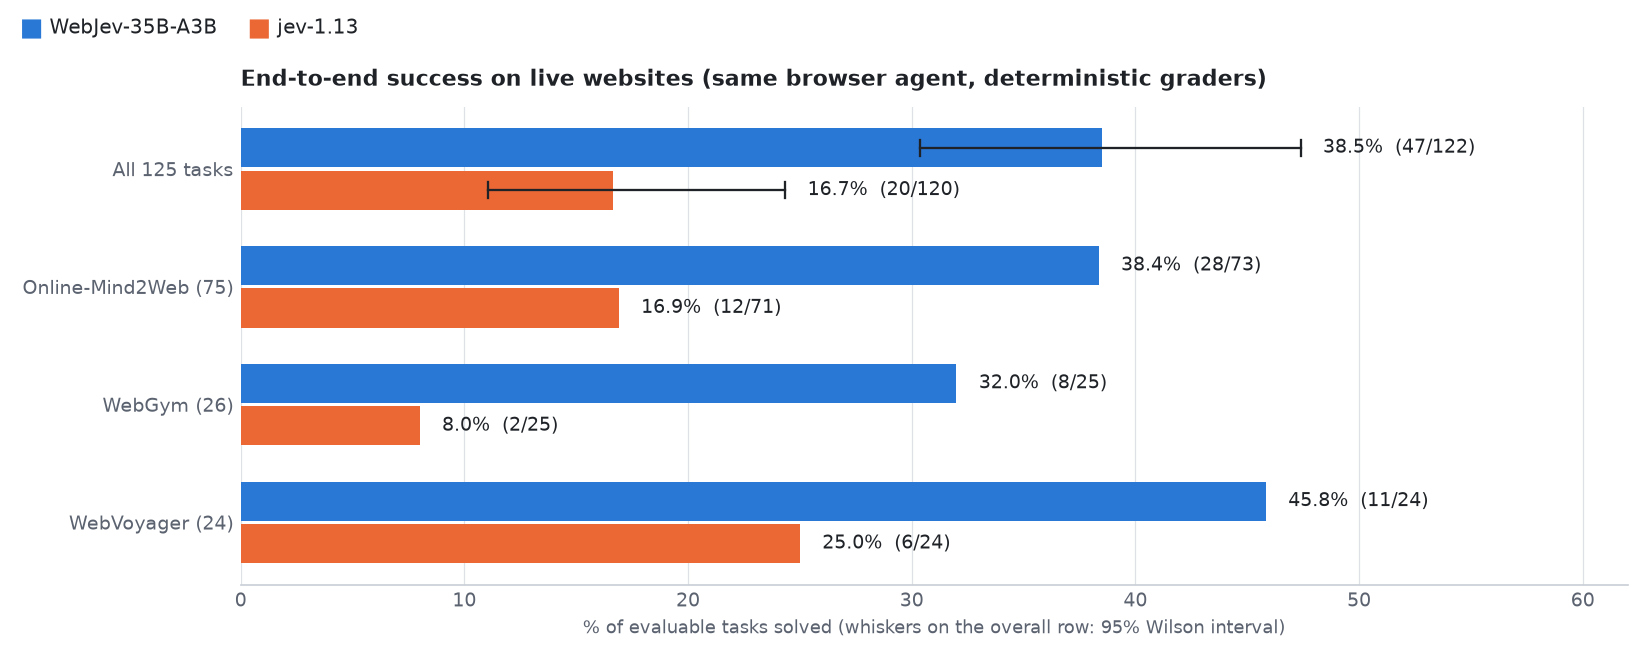
Put in charge of every step of a browser agent, WebJev-35B-A3B completes **38.5%** of 125 live-website tasks, **2.3×**
|
| 29 |
+
the 16.7% of jev-1.13, with the same agent, the same tasks and the same budget. At each step it reads the page and
|
| 30 |
+
decides what to do next and which element to act on, among up to 255 on-page candidates, in a single forward pass.
|
| 31 |
|
| 32 |
[**Code**](https://github.com/lexmount/WebJev) · [**Dataset**](https://huggingface.co/datasets/Lexmount/WebJev) ·
|
| 33 |
[**Training**](https://github.com/lexmount/WebJev/tree/main/train)
|
| 34 |
|
| 35 |
+

|
|
|
|
|
|
|
|
|
|
| 36 |
|
| 37 |
+
## Highlights
|
| 38 |
|
| 39 |
+
- **2.3× end-to-end success on the live web.** WebJev solves 38.5% of 125 real-website tasks, against 16.7% for
|
| 40 |
+
jev-1.13. It leads on every task family:
|
| 41 |
+
- Online-Mind2Web: 38.4% against 16.9%;
|
| 42 |
+
- WebGym: 32.0% against 8.0%, four times as many;
|
| 43 |
+
- WebVoyager: 45.8% against 25.0%.
|
| 44 |
+
- **Built for the agent's decision loop.** WebJev answers the two questions a browser agent faces at every step
|
| 45 |
+
directly from the page state:
|
| 46 |
+
- *action prediction*: click, type, select, scroll, wait, submit, go back, done or blocked;
|
| 47 |
+
- *element grounding*: which of up to 255 on-page elements to act on.
|
| 48 |
+
|
| 49 |
+
It is trained on tens of thousands of execution-verified decisions from live websites
|
| 50 |
+
([Lexmount/WebJev](https://huggingface.co/datasets/Lexmount/WebJev)).
|
| 51 |
+
- **Strong general decision-making.** WebJev also leads jev-1.13 on JevBench public (87.9 against 85.7) and on
|
| 52 |
+
multi-class classification (86.3 against 83.3). It is ahead on Nimble evidence checking and customer-ticket triage
|
| 53 |
+
too.
|
| 54 |
+
- **Fast and exact.** Each decision is one forward pass with no decoding: a web-page decision takes about a third of a
|
| 55 |
+
second on one A100. The answer is always one of the listed options, and it comes with the full probability
|
| 56 |
+
distribution.
|
| 57 |
+
|
| 58 |
+
## Model overview
|
| 59 |
|
| 60 |
+
WebJev-35B-A3B reads a *state* and a *question* with an explicit list of options, and returns a probability
|
| 61 |
+
distribution over the options. It does not generate text, so there is no output parsing and no answer outside the
|
| 62 |
+
options you list. It also handles general typed decisions: routing, classification, extraction choices, and policy
|
| 63 |
+
and evidence judgments.
|
| 64 |
|
| 65 |
| | |
|
| 66 |
|---|---|
|
|
|
|
| 79 |
|
| 80 |

|
| 81 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 82 |
## Evaluation
|
| 83 |
|
| 84 |
All numbers are measured with the released BF16 weights served by vLLM, at temperature 1.0. The jev-1.13 numbers were
|
| 85 |
measured through its official API on the same inputs.
|
| 86 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 87 |
### End-to-end web tasks
|
| 88 |
|
| 89 |
+
WebJev serves as the decision component of the same browser agent on 125 real-website tasks: 75 from Online-Mind2Web,
|
| 90 |
+
26 from WebGym and 24 from WebVoyager. Each run has a budget of 900 seconds and 60 actions. A deterministic grader
|
| 91 |
+
checks the final page state and answer.
|
| 92 |
|
| 93 |
- **Success rate** = solved ÷ evaluable tasks. Tasks lost to browser infrastructure or grader errors are excluded.
|
| 94 |
- **Strict rate** counts all 125 tasks.
|
| 95 |
|
|
|
|
|
|
|
| 96 |
| Task set | jev-1.13 | **WebJev-35B-A3B** |
|
| 97 |
|---|---:|---:|
|
| 98 |
| All tasks | 16.67% (20/120) | **38.52% (47/122)** |
|
|
|
|
| 101 |
| WebVoyager | 25.00% (6/24) | **45.83% (11/24)** |
|
| 102 |
| Strict, all 125 tasks | 16.00% | **37.60%** |
|
| 103 |
|
| 104 |
+
The 95% confidence intervals of the two models do not overlap (see the figure at the top). Live websites change
|
| 105 |
+
between runs, and one task is worth about 0.8 points.
|
| 106 |
+
|
| 107 |
+
### General structured decisions
|
| 108 |
+
|
| 109 |
+
Eight benchmarks of structured decisions, beyond the web. Each item gives a state and a set of candidate answers, and
|
| 110 |
+
the model's choice is correct when it equals the reference label. The table reports accuracy.
|
| 111 |
+
|
| 112 |
+

|
| 113 |
+
|
| 114 |
+
| Benchmark (items) | What it measures | jev-1.13 | **WebJev-35B-A3B** |
|
| 115 |
+
|---|---|---:|---:|
|
| 116 |
+
| JevBench public (231) | general structured decisions (intent, extraction, tool choice, policy); the hard tier has long policies, multi-hop, temporal and numeric reasoning, and trap items | 85.71 | **87.88** |
|
| 117 |
+
| Multi-class decisions, dev (1,468) | news topic, review sentiment and stars, 77-way banking intent, question and entity type, yes/no reading comprehension, entailment, policy rules | 83.31 | **86.31** |
|
| 118 |
+
| Customer-ticket triage (873) | routing queue, anger and priority of support tickets (partly Korean) | 74.91 | **76.29** |
|
| 119 |
+
| Nimble held-out (324) | fine-grained evidence checking with minimal pairs: one fact changes and the answer flips | 92.59 | **92.90** |
|
| 120 |
+
| SemIf external (252) | claim verification: supported, refuted or not enough evidence | **98.41** | 98.02 |
|
| 121 |
+
| Cross-task transfer, dev (764) | MMLU, Emotion, TweetEval, QNLI, PAWS, SciQ and programmatic policy-rule questions | **85.21** | 85.08 |
|
| 122 |
+
| Typed business decisions, test (2,000) | agent-trajectory stop and escalation, customer requests, invoice approval, security-alert severity; teacher labels | **74.05** | 73.90 |
|
| 123 |
+
| MMLU-Pro, 10 options (1,000) | college-level knowledge and reasoning across subjects | **83.40** | 69.40 |
|
| 124 |
+
| **Average (equal weights)** | | **84.70** | 83.72 |
|
| 125 |
|
| 126 |
### Speed
|
| 127 |
|
assets/liveweb.png
CHANGED
|

|