


Model card: evaluation link, simplified live-web figure and table
Browse files- README.md +2 -7
- assets/liveweb.png +2 -2
README.md
CHANGED
|
@@ -86,7 +86,7 @@ parsing and no answer outside the options you list.
|
|
| 86 |
|
| 87 |

|
| 88 |
|
| 89 |
-
## Evaluation
|
| 90 |
|
| 91 |
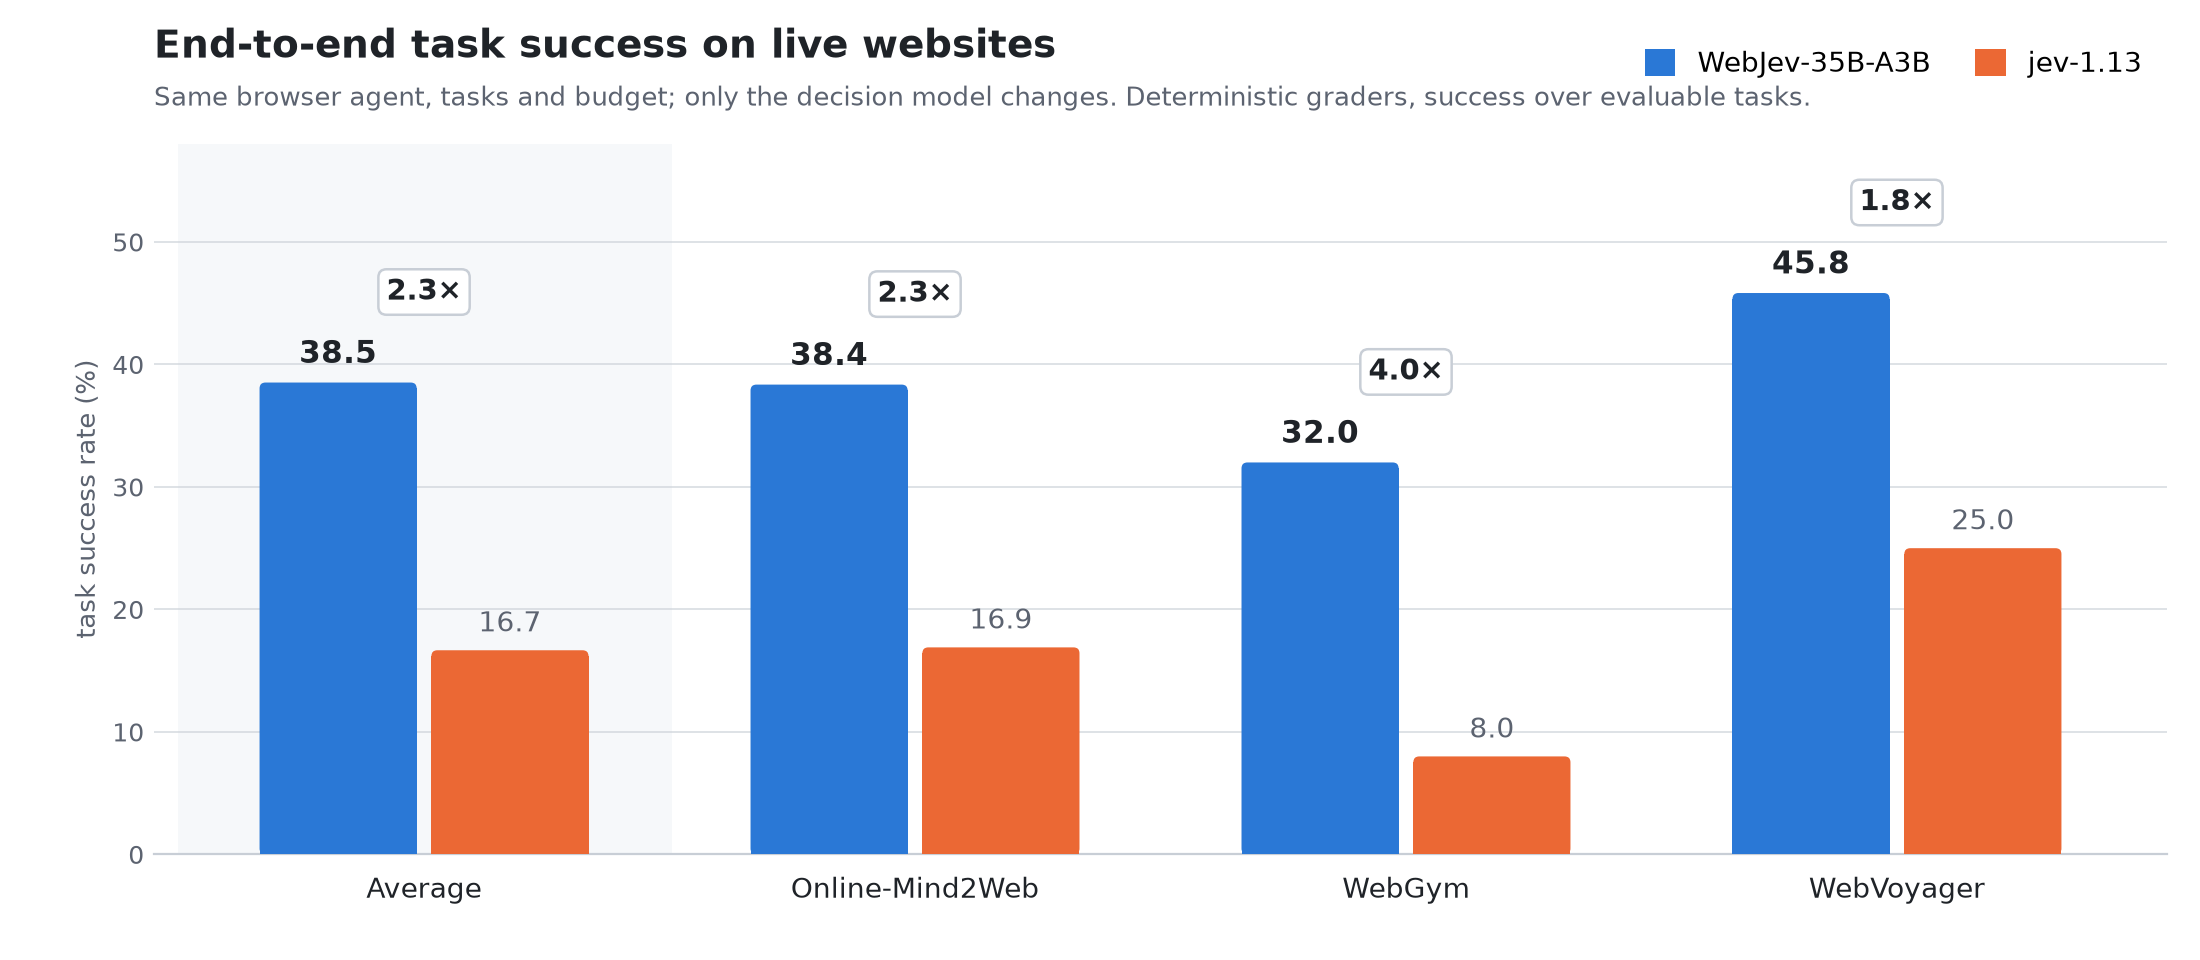
All numbers are measured with the released BF16 weights served by vLLM, at temperature 1.0. The jev-1.13 numbers were
|
| 92 |
measured through its official API on the same inputs.
|
|
@@ -97,8 +97,7 @@ WebJev serves as the decision component of the same browser agent on 125 real-we
|
|
| 97 |
26 from WebGym and 24 from WebVoyager. Each run has a budget of 900 seconds and 60 actions. A deterministic grader
|
| 98 |
checks the final page state and answer.
|
| 99 |
|
| 100 |
-
|
| 101 |
-
- **Strict rate** counts all 125 tasks.
|
| 102 |
|
| 103 |
| Task set | jev-1.13 | **WebJev-35B-A3B** |
|
| 104 |
|---|---:|---:|
|
|
@@ -106,10 +105,6 @@ checks the final page state and answer.
|
|
| 106 |
| Online-Mind2Web | 16.90% (12/71) | **38.36% (28/73)** |
|
| 107 |
| WebGym | 8.00% (2/25) | **32.00% (8/25)** |
|
| 108 |
| WebVoyager | 25.00% (6/24) | **45.83% (11/24)** |
|
| 109 |
-
| Strict, all 125 tasks | 16.00% | **37.60%** |
|
| 110 |
-
|
| 111 |
-
The 95% Wilson intervals of the overall rates do not overlap: 30–47% for WebJev against 11–24% for
|
| 112 |
-
jev-1.13. Live websites change between runs, and one task is worth about 0.8 points.
|
| 113 |
|
| 114 |
### General structured decisions
|
| 115 |
|
|
|
|
| 86 |
|
| 87 |

|
| 88 |
|
| 89 |
+
## [Evaluation](https://github.com/lexmount/WebJev/tree/main/evaluation)
|
| 90 |
|
| 91 |
All numbers are measured with the released BF16 weights served by vLLM, at temperature 1.0. The jev-1.13 numbers were
|
| 92 |
measured through its official API on the same inputs.
|
|
|
|
| 97 |
26 from WebGym and 24 from WebVoyager. Each run has a budget of 900 seconds and 60 actions. A deterministic grader
|
| 98 |
checks the final page state and answer.
|
| 99 |
|
| 100 |
+
Success rate = solved ÷ evaluable tasks; tasks lost to browser infrastructure or grader errors are excluded.
|
|
|
|
| 101 |
|
| 102 |
| Task set | jev-1.13 | **WebJev-35B-A3B** |
|
| 103 |
|---|---:|---:|
|
|
|
|
| 105 |
| Online-Mind2Web | 16.90% (12/71) | **38.36% (28/73)** |
|
| 106 |
| WebGym | 8.00% (2/25) | **32.00% (8/25)** |
|
| 107 |
| WebVoyager | 25.00% (6/24) | **45.83% (11/24)** |
|
|
|
|
|
|
|
|
|
|
|
|
|
| 108 |
|
| 109 |
### General structured decisions
|
| 110 |
|
assets/liveweb.png
CHANGED

|
Git LFS Details
|
|
Git LFS Details
|