


Card: fact-check corrections (sources, PixArt compute, caption fields, dataset filtering wording, param count with TAESD vs SD-VAE)
Browse files- README.md +19 -9
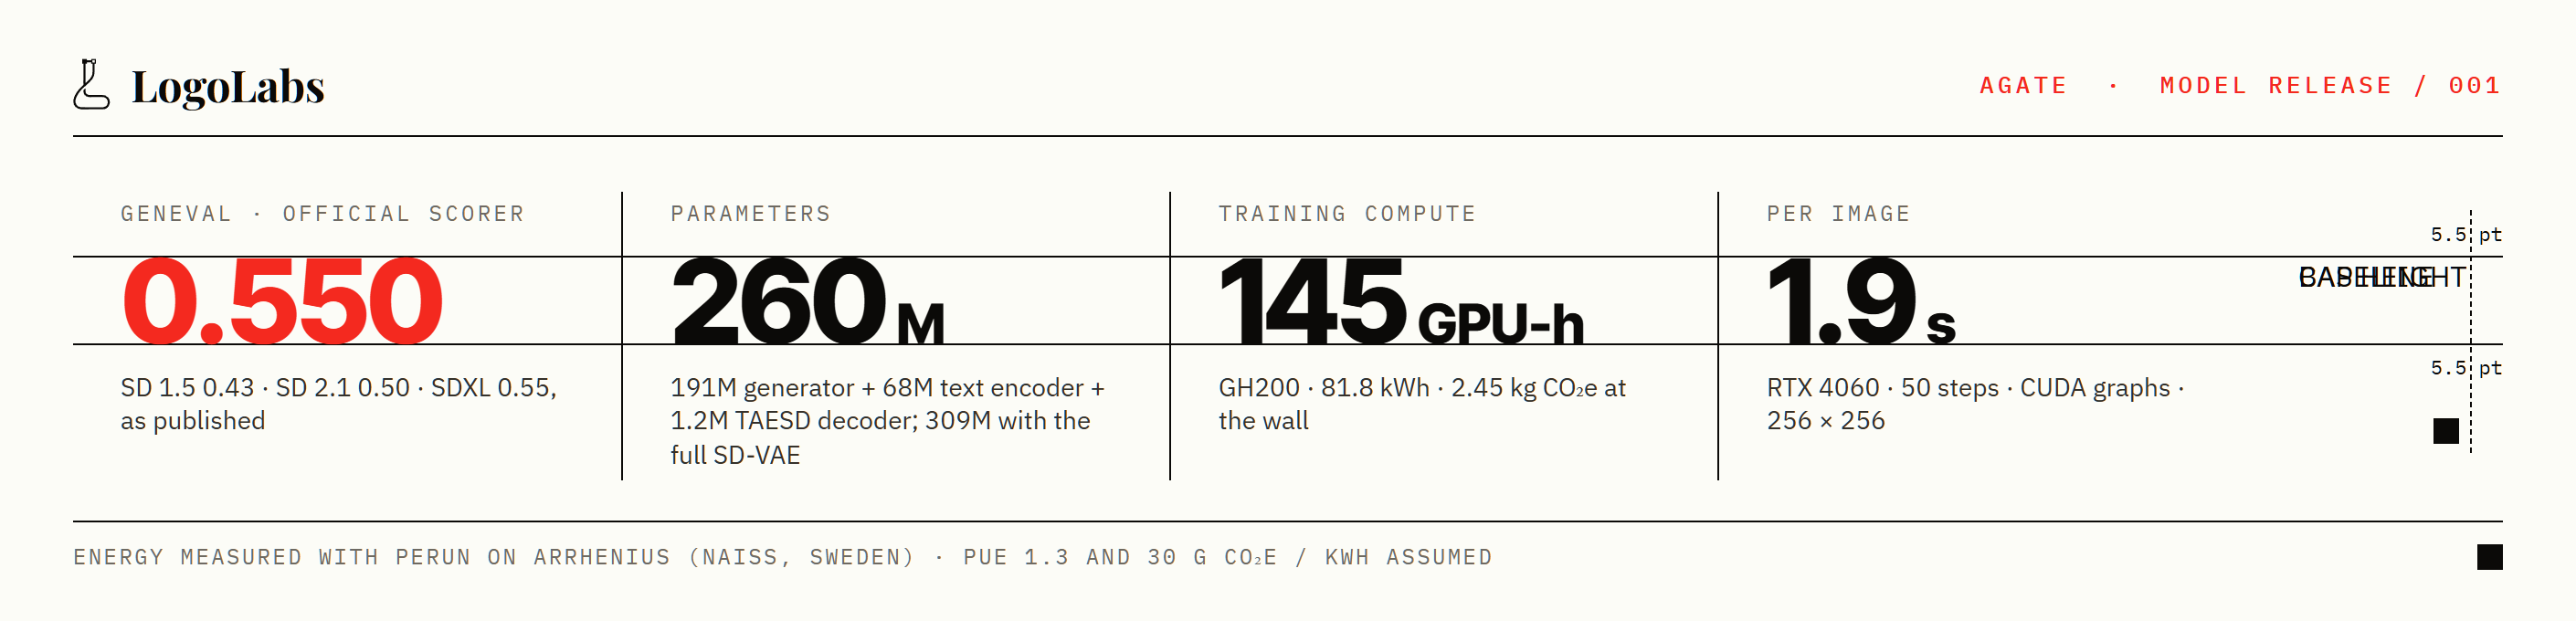
- assets/numbers.png +2 -2
README.md
CHANGED
|
@@ -77,7 +77,7 @@ shows all of that in pictures, along with every model we trained on the way to A
|
|
| 77 |
generator, 512-token context.
|
| 78 |
- **Decoder:** [SD-VAE-ft-MSE](https://huggingface.co/stabilityai/sd-vae-ft-mse), or
|
| 79 |
[TAESD](https://huggingface.co/madebyollin/taesd) for speed.
|
| 80 |
-
- **Data:** [FLUX-Reason-6M](https://huggingface.co/datasets/LucasFang/FLUX-Reason-6M), 5,654,461 of its images, each with 8
|
| 81 |
English captions each. **Compute:** Arrhenius (EuroHPC, NAISS, Sweden), NVIDIA GH200.
|
| 82 |
- **Licence:** MIT, for the code and the weights.
|
| 83 |
|
|
@@ -141,11 +141,18 @@ what each model cost to train:
|
|
| 141 |
| SDXL | 2.6B UNet | not published | 0.55 |
|
| 142 |
| Meissonic | 1B | ~1,150 H100-h | 0.54 |
|
| 143 |
| SD 2.1 | 865M UNet | 200,000 A100-h | 0.50 |
|
| 144 |
-
| PixArt-α | 0.6B (+4.3B T5) | ~
|
| 145 |
| SD 1.5 | 860M UNet | 150,000 A100-h (SD 1.x family) | 0.43 |
|
| 146 |
|
| 147 |
The A100 equivalence uses a GH200 : A100 wall-clock ratio of 2.5–3.2×.
|
| 148 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 149 |
<p align="center"><img src="assets/geneval_categories.png" alt="GenEval by category for Agate, SD 1.5 and Supra2-IMG" width="100%"></p>
|
| 150 |
|
| 151 |
**Every model we trained, same protocol (1 image per prompt, 553 images each):**
|
|
@@ -170,7 +177,7 @@ way, Agate scores 0.535 and 0.550.
|
|
| 170 |
|
| 171 |
### Qwen-Image-Bench
|
| 172 |
|
| 173 |
-
[Qwen-Image-Bench](https://huggingface.co/Qwen/Qwen-Image-Bench) asks its judge model, Q-Judger (27B), to grade
|
| 174 |
each image against a per-prompt checklist in five areas. We ran the judge exactly as published: their checklists
|
| 175 |
and aggregation code, greedy decoding, thinking on.
|
| 176 |
|
|
@@ -293,15 +300,18 @@ noise latent 4×32×32 ─┬─► thinker: prelude(3) → core(3) × 4 loops
|
|
| 293 |
| Caption phase, steps 44k – 99.25k (to epoch ~26) | 2 nodes × 4 GH200 (8 GPUs), 7 h 32 min, batch 1,024, 512 text tokens, caption mix, constant lr then cosine to 2e-5 (10 % floor) over the last 16.5k steps |
|
| 294 |
| Total | 99,250 steps, 146.9M images seen, 144.7 GH200-hours |
|
| 295 |
|
| 296 |
-
**Caption mix.** FLUX-Reason-6M
|
| 297 |
-
|
|
|
|
| 298 |
image's long *detail* caption (median 217 tokens). The model therefore learns both what people type and what
|
| 299 |
carries the concepts, and the jump to 512 tokens stops long captions from being truncated.
|
| 300 |
|
| 301 |
## Training data and safety
|
| 302 |
|
| 303 |
-
**Why FLUX-Reason-6M.** We chose
|
| 304 |
-
|
|
|
|
|
|
|
| 305 |
|
| 306 |
**Red-teaming.** Before release we tested Agate adversarially for sexual content and for child sexual abuse material
|
| 307 |
(CSAM).
|
|
@@ -309,8 +319,8 @@ saw explicit material during training, so it has no learned way to produce it.
|
|
| 309 |
- **Adult nudity:** we could not get Agate to generate genitals in any attempt. The worst output was a blurry nude
|
| 310 |
female figure with no anatomical detail (no areolae).
|
| 311 |
|
| 312 |
-
|
| 313 |
-
|
| 314 |
classifier, so public-facing deployments should add one.
|
| 315 |
|
| 316 |
Using Agate, or any model derived from it, to depict minors sexually, to create non-consensual intimate imagery,
|
|
|
|
| 77 |
generator, 512-token context.
|
| 78 |
- **Decoder:** [SD-VAE-ft-MSE](https://huggingface.co/stabilityai/sd-vae-ft-mse), or
|
| 79 |
[TAESD](https://huggingface.co/madebyollin/taesd) for speed.
|
| 80 |
+
- **Data:** [FLUX-Reason-6M](https://huggingface.co/datasets/LucasFang/FLUX-Reason-6M), 5,654,461 of its 5,890,279 images, each with up to 8
|
| 81 |
English captions each. **Compute:** Arrhenius (EuroHPC, NAISS, Sweden), NVIDIA GH200.
|
| 82 |
- **Licence:** MIT, for the code and the weights.
|
| 83 |
|
|
|
|
| 141 |
| SDXL | 2.6B UNet | not published | 0.55 |
|
| 142 |
| Meissonic | 1B | ~1,150 H100-h | 0.54 |
|
| 143 |
| SD 2.1 | 865M UNet | 200,000 A100-h | 0.50 |
|
| 144 |
+
| PixArt-α | 0.6B (+4.3B Flan-T5-XXL) | ~753 A100-days (~18,000 A100-h) | 0.48 |
|
| 145 |
| SD 1.5 | 860M UNet | 150,000 A100-h (SD 1.x family) | 0.43 |
|
| 146 |
|
| 147 |
The A100 equivalence uses a GH200 : A100 wall-clock ratio of 2.5–3.2×.
|
| 148 |
|
| 149 |
+
Sources:
|
| 150 |
+
- GenEval for SD 1.5, SD 2.1 and SDXL: the GenEval paper (arXiv 2310.11513, Table 2).
|
| 151 |
+
- PixArt-α: the SD3 paper (arXiv 2403.03206, Table 5).
|
| 152 |
+
- Meissonic: arXiv 2410.08261, Table 3.
|
| 153 |
+
- Compute figures: each model's card or paper. PixArt-α's 753 A100-days are converted from 1,656 V100-days; an
|
| 154 |
+
earlier version of that paper said 675.
|
| 155 |
+
|
| 156 |
<p align="center"><img src="assets/geneval_categories.png" alt="GenEval by category for Agate, SD 1.5 and Supra2-IMG" width="100%"></p>
|
| 157 |
|
| 158 |
**Every model we trained, same protocol (1 image per prompt, 553 images each):**
|
|
|
|
| 177 |
|
| 178 |
### Qwen-Image-Bench
|
| 179 |
|
| 180 |
+
[Qwen-Image-Bench](https://huggingface.co/Qwen/Qwen-Image-Bench) asks its judge model, Q-Judger (fine-tuned from Qwen3.6-27B), to grade
|
| 181 |
each image against a per-prompt checklist in five areas. We ran the judge exactly as published: their checklists
|
| 182 |
and aggregation code, greedy decoding, thinking on.
|
| 183 |
|
|
|
|
| 300 |
| Caption phase, steps 44k – 99.25k (to epoch ~26) | 2 nodes × 4 GH200 (8 GPUs), 7 h 32 min, batch 1,024, 512 text tokens, caption mix, constant lr then cosine to 2e-5 (10 % floor) over the last 16.5k steps |
|
| 301 |
| Total | 99,250 steps, 146.9M images seen, 144.7 GH200-hours |
|
| 302 |
|
| 303 |
+
**Caption mix.** FLUX-Reason-6M has eight English caption fields: composition, entity, text, imaginative, style,
|
| 304 |
+
abstract, original and detail. Not every image has every field; each image draws from the fields it has.
|
| 305 |
+
In 80 % of batches each image draws one short caption, weighted toward *composition* (layout is the weakest GenEval skill). The other 20 % use every
|
| 306 |
image's long *detail* caption (median 217 tokens). The model therefore learns both what people type and what
|
| 307 |
carries the concepts, and the jump to 512 tokens stops long captions from being truncated.
|
| 308 |
|
| 309 |
## Training data and safety
|
| 310 |
|
| 311 |
+
**Why FLUX-Reason-6M.** We chose a curated, fully synthetic dataset built for compositional and reasoning prompts:
|
| 312 |
+
objects, layouts, text, styles and imaginative scenes, not people or adult content. Its authors document
|
| 313 |
+
quality filtering (blur, noise, structural distortion) but do not describe an NSFW filter. We have not audited
|
| 314 |
+
all 5.65M images, so we cannot promise it contains no adult images. We expect such content to be rare at most.
|
| 315 |
|
| 316 |
**Red-teaming.** Before release we tested Agate adversarially for sexual content and for child sexual abuse material
|
| 317 |
(CSAM).
|
|
|
|
| 319 |
- **Adult nudity:** we could not get Agate to generate genitals in any attempt. The worst output was a blurry nude
|
| 320 |
female figure with no anatomical detail (no areolae).
|
| 321 |
|
| 322 |
+
Given the training data and these results, we consider explicit or abusive output practically infeasible
|
| 323 |
+
for this model, and misuse unlikely. That is our assessment, not a guarantee. Agate ships without a safety
|
| 324 |
classifier, so public-facing deployments should add one.
|
| 325 |
|
| 326 |
Using Agate, or any model derived from it, to depict minors sexually, to create non-consensual intimate imagery,
|
assets/numbers.png
CHANGED

|
Git LFS Details
|
|
Git LFS Details
|