

File size: 3,895 Bytes
be03e28 ba906db be03e28 631a64a be03e28 631a64a e8f08a1 631a64a 478b28f 631a64a b3c0d57 631a64a b3c0d57 603d061 ed966fc b3c0d57 603d061 b3c0d57 36f17a6 b3c0d57 ed966fc 478b28f ed966fc ff3b883 dbe1352 ed966fc ff3b883 c399a5f ff3b883 c399a5f ae15adf c399a5f ff3b883 ed966fc 39cc27f ed966fc ba906db 91948c8 ba906db 631a64a 478b28f 92d9005 ed966fc 631a64a ed966fc 631a64a f46ec18 8eaa127 f46ec18 8eaa127 f46ec18 8eaa127 f46ec18 631a64a 5c3760b 2e1c75b 5c3760b 04fd462 5c3760b 04fd462 | 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 79 80 81 82 83 84 85 86 87 88 89 90 91 92 93 94 95 96 97 98 99 100 101 102 103 104 105 106 107 108 109 110 111 112 113 114 115 116 117 118 119 120 121 122 123 124 125 126 127 | ---
license: mit
library_name: transformers
datasets:
- uoft-cs/cifar10
pipeline_tag: image-classification
tags:
- computer-vision
- cnn
- cifar10
- adversarial-robustness
- downsampling
- anti-aliasing
metrics:
- accuracy
---
## NULA
Anti-aliased residual CNN for CIFAR-10 image classification designed to improve robustness against perturbations that exploit downsampling.
# Problem
Downsampling operations are linear maps from a high-dimensional space to a lower-dimensional one.
By the Rank-Nullity theorem, this matrix has a massive NULL space.
An attacker can exploit this: they utilize the discarded samples of these downsampling operations as extra degrees of freedom.
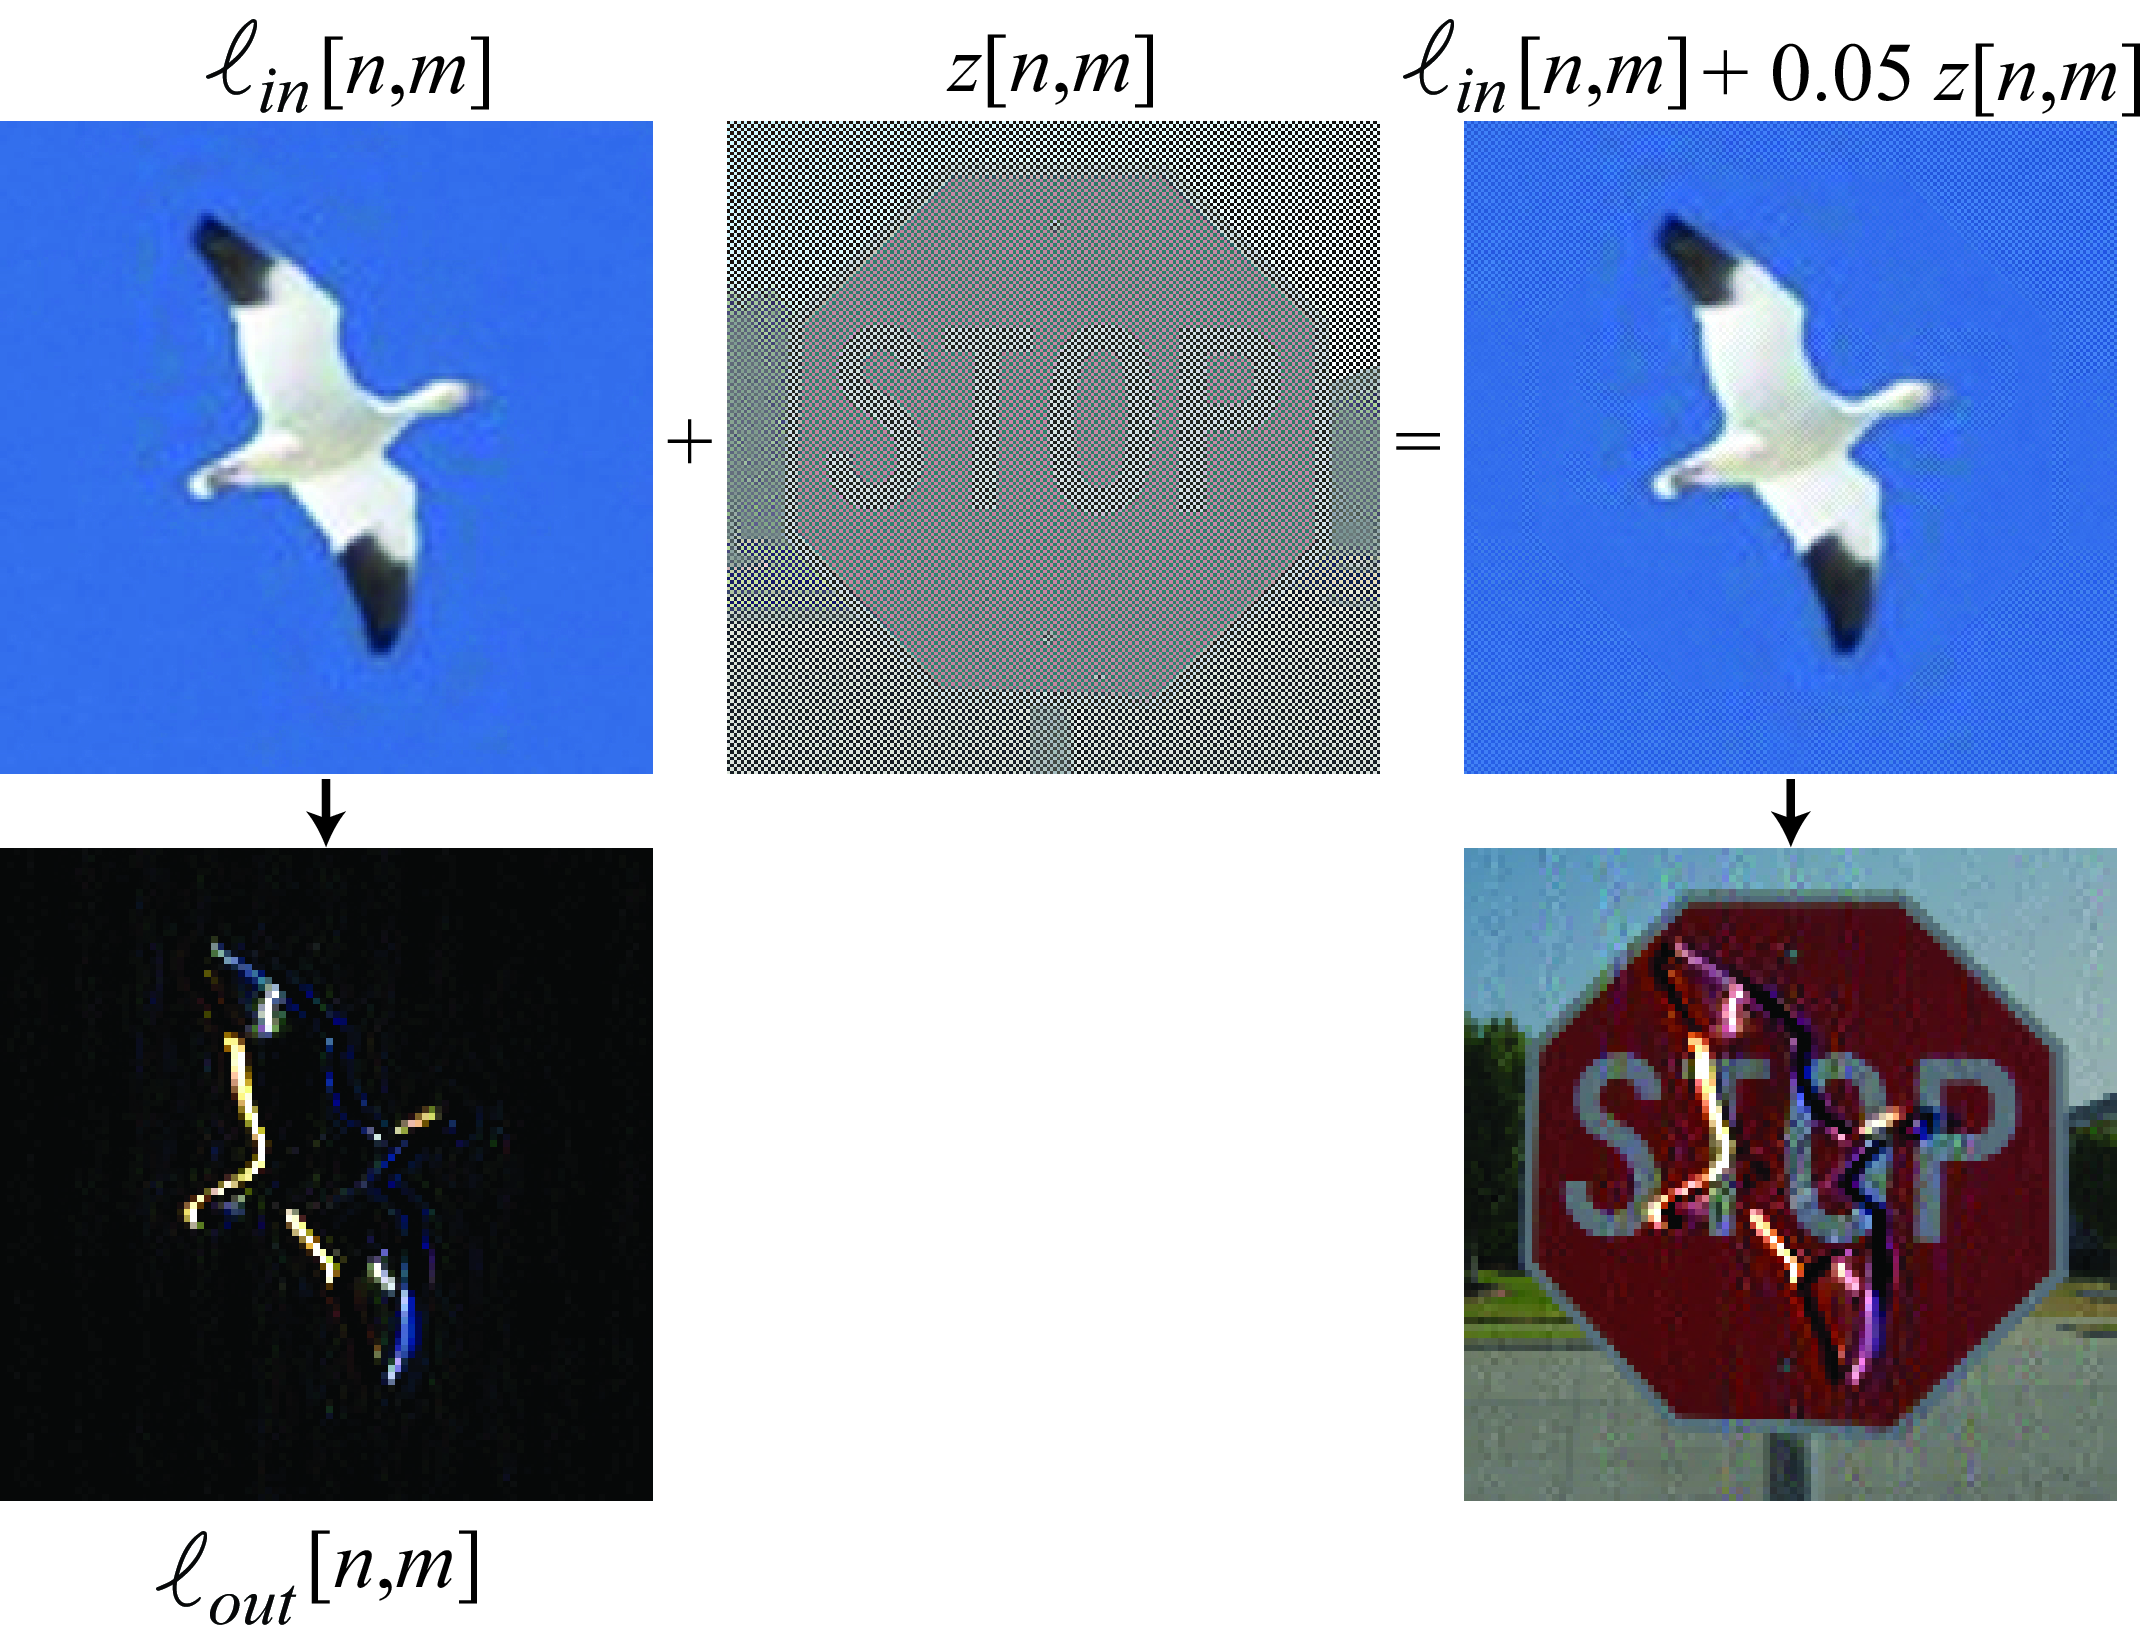https://visionbook.mit.edu/figures/upsamplig_downsampling/toy_example_book2.png)
*Source: MIT Vision Book*
By sculpting perturbations with components in the null space of the downsampling operator, they spread energy across frequencies that are discarded during striding.
The result is an image perceptually identical to the original, with a manipulated activation pattern.
```python
```
## Approach
[BlurPool: what it does mechanically and why it addresses the problem]
[SE blocks: what they add]
## Architecture
[stem → s1 → s2 → s3 → head, with channel dims]
[BlurPool replaces strided conv — note this explicitly]
## Training Statistics
*first evaluation* on CIFAR-10 test set (10,000 images). All perturbations applied at inference
the model never saw test distribution during training.
| Perturbation | Accuracy | Drop |
|---|---|---|
| Clean | 91.95% | — |
| Resize ×0.5 (bilinear) | 59.83% | −32.12% |
| Resize ×0.25 (bilinear) | 24.82% | −67.13% |
| Decimate ×2 | 30.03% | −61.92% |
| Checkerboard ε=0.03 | 75.47% | −16.48% |
| Checkerboard ε=0.05 | 44.99% | −46.96% |
*second evaluation* on the CIFAR-10 test set (10,000 images). Perturbations applied at inference only.
The adversarially trained variant was trained from scratch under a modified data distribution.
| Perturbation | Accuracy | Δ from 1st eval |
|---|---|---|
| Clean | 89.42% | −2.53% |
| Resize ×0.5 | 85.37% | +25.54% |
| Resize ×0.25 | 71.80% | +46.98% |
| Decimate ×2 | 85.02% | +54.99% |
| Checkerboard ε=0.03 | 89.43% | +13.96% |
| Checkerboard ε=0.05 | 89.39% | +44.40% |
The adversarial variant trades 2.53% clean accuracy for substantial robustness across all tested perturbations.
The checkerboard attack —a direct null-space exploit against stride-2 downsampling — drops from 44.99% to near-clean 89.39%.
## Usage
NULA is hosted on the HuggingFace Hub and can be loaded directly via the transformers library.
```python
import torch as pt
from transformers import AutoModelForImageClassification
model = AutoModelForImageClassification.from_pretrained(
"mamapearli/NULA-base-cifar10-v0",
trust_remote_code=True
)
image = pt.randn(1, 3, 32, 32)
with pt.no_grad():
output = model(pixel_values=image)
predicted_class = output.logits.argmax(dim=-1).item()
print(model.config.id2label[predicted_class])
```
Input tensors should be shape (B, C, H, W).
## Citation
If you use this model or repository in your research, please cite:
```bibtex
@misc{mamapearl_nula_2026,
author = {MamaPearl},
title = {NULA: Anti-Aliased SE-CNN for CIFAR-10},
year = {2026},
publisher = {Hugging Face},
url = {https://huggingface.co/MamaPearl/nula-base-cifar10-v0}
}
```
# Authors
* **MamaPearl** ([@MamaPearl](https://github.com))
*Main Contributor*
## Contact & Socials
| Platform | Link |
| :--- | :--- |
| **GitHub** | [github.com/MamaPearl](https://github.com) |
| **Instagram** | [@mamapearli](https://www.instagram.com/mamapearli/) |
## License
This project is licensed under the MIT License. See [LICENSE](LICENSE) for more information. |