


Import from Quazim0t0/neural-raytracing; repoint refs to NeuralVerified
Browse files- .gitattributes +1 -0
- README.md +70 -0
- engine3d/neural_rt.py +63 -0
- engine3d/raytrace.py +200 -0
- experiments/radiance_cache.pt +3 -0
- experiments/w11_world_lighting.py +148 -0
- experiments/w9_neural_radiance_cache.py +217 -0
- experiments/world_light.pt +3 -0
- neural_raytrace_validation.png +3 -0
- world_lighting_validation.png +0 -0
.gitattributes
CHANGED
|
@@ -33,3 +33,4 @@ saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
neural_raytrace_validation.png filter=lfs diff=lfs merge=lfs -text
|
README.md
ADDED
|
@@ -0,0 +1,70 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: mit
|
| 3 |
+
tags:
|
| 4 |
+
- neural-rendering
|
| 5 |
+
- ray-tracing
|
| 6 |
+
- radiance-cache
|
| 7 |
+
- graphics
|
| 8 |
+
library_name: pytorch
|
| 9 |
+
---
|
| 10 |
+
|
| 11 |
+
# Neural Ray Tracing — Radiance Cache
|
| 12 |
+
|
| 13 |
+
The light-transport analog of the
|
| 14 |
+
[neural physics engine](https://huggingface.co/NeuralVerified/neural-physics-engine)
|
| 15 |
+
thesis: keep visibility and direct lighting **analytic**, learn **only the
|
| 16 |
+
indirect transport** with a tiny tied MLP. One analytic ray + next-event
|
| 17 |
+
estimation + a network lookup replaces the many-bounce random walk after
|
| 18 |
+
the first hit.
|
| 19 |
+
|
| 20 |
+
## How it was done
|
| 21 |
+
|
| 22 |
+
Render decomposition: `L = emitted + direct(analytic) + indirect(learned)`.
|
| 23 |
+
|
| 24 |
+
1. **Ground truth**: a small PyTorch path tracer
|
| 25 |
+
(`engine3d/raytrace.py`) renders high-spp references and splits each
|
| 26 |
+
pixel into emitted / direct / indirect components.
|
| 27 |
+
2. **Training data**: first-hit surface points + normals paired with the
|
| 28 |
+
path-traced indirect radiance at those points.
|
| 29 |
+
3. **The cache** (`engine3d/neural_rt.py`): one tiny MLP shared across the
|
| 30 |
+
whole scene (the tied-embedding structure used everywhere in this
|
| 31 |
+
project) maps (hit point, normal) → indirect RGB.
|
| 32 |
+
4. **Composition**: at render time, trace one analytic primary ray, add
|
| 33 |
+
analytic direct lighting (NEE), and look up the cache for the rest.
|
| 34 |
+
5. **Evaluation** (`experiments/w9_neural_radiance_cache.py`): PSNR on a
|
| 35 |
+
held-out camera view, compared against an *equal-cost* few-spp path
|
| 36 |
+
trace, plus the spp the baseline needs to match the neural render.
|
| 37 |
+
|
| 38 |
+
`experiments/w11_world_lighting.py` applies the same recipe to bake a
|
| 39 |
+
world ambient/GI field (`world_light.pt`) over the voxel world — this is
|
| 40 |
+
the "neural GI" used live in the
|
| 41 |
+
[Neural World demo Space](https://huggingface.co/spaces/NeuralVerified/neural-world),
|
| 42 |
+
parsed in-browser by `pt_loader.js`.
|
| 43 |
+
|
| 44 |
+
## Checkpoints
|
| 45 |
+
|
| 46 |
+
| file | net | consumed by |
|
| 47 |
+
|---|---|---|
|
| 48 |
+
| `experiments/radiance_cache.pt` | indirect radiance cache MLP | `w9_neural_radiance_cache.py` renders |
|
| 49 |
+
| `experiments/world_light.pt` | world ambient/GI field | Neural World demo (browser) |
|
| 50 |
+
|
| 51 |
+
## Validation
|
| 52 |
+
|
| 53 |
+

|
| 54 |
+

|
| 55 |
+
|
| 56 |
+
## Reproduce
|
| 57 |
+
|
| 58 |
+
```
|
| 59 |
+
python experiments/w9_neural_radiance_cache.py # trains + renders comparison
|
| 60 |
+
python experiments/w11_world_lighting.py # bakes world_light.pt
|
| 61 |
+
```
|
| 62 |
+
|
| 63 |
+
|
| 64 |
+
---
|
| 65 |
+
|
| 66 |
+
<!-- neuralverified-relocation-note -->
|
| 67 |
+
> **Now hosted by [NeuralVerified](https://huggingface.co/NeuralVerified).**
|
| 68 |
+
>
|
| 69 |
+
> This repo was moved into the NeuralVerified organization to help organize my profile.
|
| 70 |
+
> Originally published at [`Quazim0t0/neural-raytracing`](https://huggingface.co/Quazim0t0/neural-raytracing).
|
engine3d/neural_rt.py
ADDED
|
@@ -0,0 +1,63 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Neural radiance cache (W9 — neural ray tracing).
|
| 2 |
+
|
| 3 |
+
The same thesis as the physics engine, applied to light transport: keep
|
| 4 |
+
the exact parts analytic (ray/visibility, next-event direct lighting),
|
| 5 |
+
learn only the expensive part (multi-bounce indirect transport).
|
| 6 |
+
|
| 7 |
+
A path becomes: L = emitted + direct(analytic NEE) + cache_θ(x, n)
|
| 8 |
+
where cache_θ is one tiny MLP, tied across the whole scene, that maps a
|
| 9 |
+
surface point + normal to its outgoing indirect radiance. This replaces
|
| 10 |
+
the random walk after the first bounce with a single network lookup —
|
| 11 |
+
Müller et al.'s "Real-time Neural Radiance Caching" idea, distilled to
|
| 12 |
+
the project's local-projection skeleton.
|
| 13 |
+
|
| 14 |
+
Positional (frequency) encoding is essential: a plain MLP on raw xyz
|
| 15 |
+
cannot fit the high-frequency shading near contact shadows and the
|
| 16 |
+
color-bleeding corners. The encoding is the analytic structure we keep;
|
| 17 |
+
the MLP only learns amplitudes.
|
| 18 |
+
"""
|
| 19 |
+
import numpy as np
|
| 20 |
+
import torch
|
| 21 |
+
import torch.nn as nn
|
| 22 |
+
|
| 23 |
+
|
| 24 |
+
class FreqEncoding(nn.Module):
|
| 25 |
+
"""NeRF-style sin/cos encoding: x -> [x, sin(2^k x), cos(2^k x)]_k."""
|
| 26 |
+
|
| 27 |
+
def __init__(self, n_freq=6):
|
| 28 |
+
super().__init__()
|
| 29 |
+
self.register_buffer("bands", 2.0 ** torch.arange(n_freq) * torch.pi)
|
| 30 |
+
self.out_mult = 1 + 2 * n_freq
|
| 31 |
+
|
| 32 |
+
def forward(self, x):
|
| 33 |
+
proj = x[..., None] * self.bands # (...,D,F)
|
| 34 |
+
enc = torch.cat([torch.sin(proj), torch.cos(proj)], -1)
|
| 35 |
+
return torch.cat([x, enc.flatten(-2)], -1)
|
| 36 |
+
|
| 37 |
+
|
| 38 |
+
class RadianceCache(nn.Module):
|
| 39 |
+
"""Tied MLP: (position, normal) -> outgoing indirect radiance (RGB).
|
| 40 |
+
|
| 41 |
+
Shared across every surface point in the scene (the tied-embedding
|
| 42 |
+
thesis, now over spatial location instead of mesh element). Output is
|
| 43 |
+
non-negative (softplus) — radiance cannot be negative, a guard baked
|
| 44 |
+
into the architecture rather than clamped after the fact.
|
| 45 |
+
"""
|
| 46 |
+
|
| 47 |
+
def __init__(self, n_freq=6, hidden=96):
|
| 48 |
+
super().__init__()
|
| 49 |
+
self.enc = FreqEncoding(n_freq)
|
| 50 |
+
din = self.enc.out_mult * 3 + 3 # encoded position + raw normal
|
| 51 |
+
self.net = nn.Sequential(
|
| 52 |
+
nn.Linear(din, hidden), nn.SiLU(),
|
| 53 |
+
nn.Linear(hidden, hidden), nn.SiLU(),
|
| 54 |
+
nn.Linear(hidden, hidden), nn.SiLU(),
|
| 55 |
+
nn.Linear(hidden, 3),
|
| 56 |
+
)
|
| 57 |
+
|
| 58 |
+
def forward(self, pos, nrm):
|
| 59 |
+
h = torch.cat([self.enc(pos), nrm], -1)
|
| 60 |
+
return torch.nn.functional.softplus(self.net(h))
|
| 61 |
+
|
| 62 |
+
def n_params(self):
|
| 63 |
+
return sum(p.numel() for p in self.parameters())
|
engine3d/raytrace.py
ADDED
|
@@ -0,0 +1,200 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Vectorized torch path tracer (the substrate for neural ray tracing).
|
| 2 |
+
|
| 3 |
+
Same design rule as the physics engine: keep the exact parts analytic —
|
| 4 |
+
ray intersections and next-event-estimated direct lighting — and reserve
|
| 5 |
+
learning for the expensive part (indirect transport, see W9 experiment).
|
| 6 |
+
|
| 7 |
+
Scene: a neon Cornell box. Diffuse surfaces, one area light on the
|
| 8 |
+
ceiling, a sphere and a box inside. All ray math is batched over
|
| 9 |
+
(N,3) tensors on the chosen device.
|
| 10 |
+
"""
|
| 11 |
+
import torch
|
| 12 |
+
|
| 13 |
+
EPS = 1e-4
|
| 14 |
+
|
| 15 |
+
# ---- scene definition (unit room, front face at z=+1 open) ----
|
| 16 |
+
LIGHT = dict(y=0.999, half=0.42, Le=torch.tensor([11.0, 11.5, 13.0]))
|
| 17 |
+
SPHERE = dict(c=torch.tensor([-0.42, -0.65, -0.22]), r=0.35,
|
| 18 |
+
alb=torch.tensor([0.85, 0.85, 0.88]))
|
| 19 |
+
BOX = dict(mn=torch.tensor([0.12, -1.0, -0.10]),
|
| 20 |
+
mx=torch.tensor([0.72, -0.34, 0.52]),
|
| 21 |
+
alb=torch.tensor([0.30, 0.75, 0.95]))
|
| 22 |
+
WALLS = [ # (axis, value, normal-sign, albedo)
|
| 23 |
+
(0, -1.0, +1, [0.25, 0.55, 0.95]), # left — neon blue
|
| 24 |
+
(0, +1.0, -1, [0.95, 0.30, 0.40]), # right — crimson
|
| 25 |
+
(1, -1.0, +1, [0.70, 0.70, 0.72]), # floor
|
| 26 |
+
(1, +1.0, -1, [0.70, 0.70, 0.72]), # ceiling
|
| 27 |
+
(2, -1.0, +1, [0.55, 0.60, 0.75]), # back
|
| 28 |
+
]
|
| 29 |
+
|
| 30 |
+
|
| 31 |
+
def _dev(dev):
|
| 32 |
+
out = {"Le": LIGHT["Le"].to(dev), "sc": SPHERE["c"].to(dev),
|
| 33 |
+
"sa": SPHERE["alb"].to(dev), "bmn": BOX["mn"].to(dev),
|
| 34 |
+
"bmx": BOX["mx"].to(dev), "ba": BOX["alb"].to(dev),
|
| 35 |
+
"wa": torch.tensor([w[3] for w in WALLS], device=dev)}
|
| 36 |
+
return out
|
| 37 |
+
|
| 38 |
+
|
| 39 |
+
def intersect(o, d, S):
|
| 40 |
+
"""Closest hit for rays (N,3),(N,3) -> t, normal, albedo, is_light."""
|
| 41 |
+
N = len(o)
|
| 42 |
+
dev = o.device
|
| 43 |
+
INF = torch.full((N,), 1e9, device=dev)
|
| 44 |
+
best_t = INF.clone()
|
| 45 |
+
n = torch.zeros(N, 3, device=dev)
|
| 46 |
+
alb = torch.zeros(N, 3, device=dev)
|
| 47 |
+
is_light = torch.zeros(N, dtype=torch.bool, device=dev)
|
| 48 |
+
|
| 49 |
+
arange = torch.arange(N, device=dev)
|
| 50 |
+
for wi, (ax, val, sgn, _) in enumerate(WALLS):
|
| 51 |
+
denom = d[:, ax]
|
| 52 |
+
t = (val - o[:, ax]) / torch.where(denom.abs() < 1e-9,
|
| 53 |
+
torch.full_like(denom, 1e-9), denom)
|
| 54 |
+
p = o + t[:, None] * d
|
| 55 |
+
oth = [a for a in range(3) if a != ax]
|
| 56 |
+
ok = (t > EPS) & (t < best_t) \
|
| 57 |
+
& (p[:, oth[0]].abs() <= 1.0) & (p[:, oth[1]].abs() <= 1.0) \
|
| 58 |
+
& (p[:, 2] <= 1.0)
|
| 59 |
+
best_t = torch.where(ok, t, best_t)
|
| 60 |
+
nw = torch.zeros_like(n); nw[:, ax] = float(sgn)
|
| 61 |
+
n = torch.where(ok[:, None], nw, n)
|
| 62 |
+
alb = torch.where(ok[:, None], S["wa"][wi], alb)
|
| 63 |
+
# sphere
|
| 64 |
+
oc = o - S["sc"]
|
| 65 |
+
b = (oc * d).sum(1)
|
| 66 |
+
c = (oc * oc).sum(1) - SPHERE["r"] ** 2
|
| 67 |
+
disc = b * b - c
|
| 68 |
+
sq = torch.sqrt(disc.clamp_min(0))
|
| 69 |
+
t1 = -b - sq
|
| 70 |
+
t2 = -b + sq
|
| 71 |
+
ts = torch.where(t1 > EPS, t1, t2)
|
| 72 |
+
ok = (disc > 0) & (ts > EPS) & (ts < best_t)
|
| 73 |
+
best_t = torch.where(ok, ts, best_t)
|
| 74 |
+
ps = o + ts[:, None] * d
|
| 75 |
+
n = torch.where(ok[:, None], (ps - S["sc"]) / SPHERE["r"], n)
|
| 76 |
+
alb = torch.where(ok[:, None], S["sa"], alb)
|
| 77 |
+
# box (slabs)
|
| 78 |
+
inv = 1.0 / torch.where(d.abs() < 1e-9, torch.full_like(d, 1e-9), d)
|
| 79 |
+
t0s = (S["bmn"] - o) * inv
|
| 80 |
+
t1s = (S["bmx"] - o) * inv
|
| 81 |
+
tsm = torch.minimum(t0s, t1s).max(1).values
|
| 82 |
+
tbg = torch.maximum(t0s, t1s).min(1).values
|
| 83 |
+
ok = (tsm < tbg) & (tsm > EPS) & (tsm < best_t)
|
| 84 |
+
best_t = torch.where(ok, tsm, best_t)
|
| 85 |
+
pb = o + tsm[:, None] * d
|
| 86 |
+
ctr = (S["bmn"] + S["bmx"]) / 2
|
| 87 |
+
half = (S["bmx"] - S["bmn"]) / 2
|
| 88 |
+
rel = (pb - ctr) / half
|
| 89 |
+
axb = rel.abs().argmax(1)
|
| 90 |
+
nb = torch.zeros_like(pb)
|
| 91 |
+
nb[arange, axb] = torch.sign(rel[arange, axb])
|
| 92 |
+
n = torch.where(ok[:, None], nb, n)
|
| 93 |
+
alb = torch.where(ok[:, None], S["ba"], alb)
|
| 94 |
+
# light flag: recomputed cleanly from the final hit (ceiling patch)
|
| 95 |
+
p = o + best_t[:, None] * d
|
| 96 |
+
is_light = (best_t < 1e8) & (n[:, 1] == -1.0) & (p[:, 1] > 0.99) \
|
| 97 |
+
& (p[:, 0].abs() <= LIGHT["half"]) & (p[:, 2].abs() <= LIGHT["half"])
|
| 98 |
+
return best_t, n, alb, is_light
|
| 99 |
+
|
| 100 |
+
|
| 101 |
+
def cosine_hemisphere(n, rng):
|
| 102 |
+
"""Cosine-weighted directions about normals n (N,3)."""
|
| 103 |
+
N = len(n)
|
| 104 |
+
u1 = torch.rand(N, device=n.device, generator=rng)
|
| 105 |
+
u2 = torch.rand(N, device=n.device, generator=rng)
|
| 106 |
+
r = torch.sqrt(u1)
|
| 107 |
+
phi = 2 * torch.pi * u2
|
| 108 |
+
x = r * torch.cos(phi)
|
| 109 |
+
y = r * torch.sin(phi)
|
| 110 |
+
z = torch.sqrt((1 - u1).clamp_min(0))
|
| 111 |
+
a = torch.where(n[:, 0:1].abs() > 0.9,
|
| 112 |
+
torch.tensor([0.0, 1.0, 0.0], device=n.device).expand_as(n),
|
| 113 |
+
torch.tensor([1.0, 0.0, 0.0], device=n.device).expand_as(n))
|
| 114 |
+
t = torch.linalg.cross(a, n)
|
| 115 |
+
t = t / t.norm(dim=1, keepdim=True).clamp_min(1e-9)
|
| 116 |
+
b = torch.linalg.cross(n, t)
|
| 117 |
+
return x[:, None] * t + y[:, None] * b + z[:, None] * n
|
| 118 |
+
|
| 119 |
+
|
| 120 |
+
def nee(p, n, alb, S, rng):
|
| 121 |
+
"""Next-event estimation toward the ceiling light. Returns (N,3)."""
|
| 122 |
+
N = len(p)
|
| 123 |
+
dev = p.device
|
| 124 |
+
u = (torch.rand(N, 2, device=dev, generator=rng) * 2 - 1) * LIGHT["half"]
|
| 125 |
+
lp = torch.stack([u[:, 0], torch.full((N,), LIGHT["y"], device=dev),
|
| 126 |
+
u[:, 1]], 1)
|
| 127 |
+
dl = lp - p
|
| 128 |
+
dist = dl.norm(dim=1).clamp_min(1e-6)
|
| 129 |
+
dl = dl / dist[:, None]
|
| 130 |
+
cos_s = (n * dl).sum(1).clamp_min(0)
|
| 131 |
+
# light normal is (0,-1,0); the emission cosine is between it and the
|
| 132 |
+
# direction light->surface (=-dl), i.e. (0,-1,0)·(-dl) = +dl_y
|
| 133 |
+
cos_l = dl[:, 1].clamp_min(0)
|
| 134 |
+
t, _, _, _ = intersect(p + EPS * n, dl, S)
|
| 135 |
+
vis = t > dist - 3e-3
|
| 136 |
+
area = (2 * LIGHT["half"]) ** 2
|
| 137 |
+
g = cos_s * cos_l / (dist ** 2)
|
| 138 |
+
return (alb / torch.pi) * S["Le"] * (g * vis * area)[:, None]
|
| 139 |
+
|
| 140 |
+
|
| 141 |
+
def trace_split(o, d, S, rng, depth=5):
|
| 142 |
+
"""Path trace with NEE; returns (emitted, direct, indirect) per ray.
|
| 143 |
+
|
| 144 |
+
emitted: light seen directly by the given ray
|
| 145 |
+
direct: NEE at the FIRST hit (analytic given visibility)
|
| 146 |
+
indirect: everything after the first bounce — the part the neural
|
| 147 |
+
cache learns
|
| 148 |
+
Also returns the first-hit geometry (t, n, albedo) for cache training.
|
| 149 |
+
"""
|
| 150 |
+
N = len(o)
|
| 151 |
+
dev = o.device
|
| 152 |
+
emitted = torch.zeros(N, 3, device=dev)
|
| 153 |
+
direct = torch.zeros(N, 3, device=dev)
|
| 154 |
+
indirect = torch.zeros(N, 3, device=dev)
|
| 155 |
+
tput = torch.ones(N, 3, device=dev)
|
| 156 |
+
alive = torch.ones(N, dtype=torch.bool, device=dev)
|
| 157 |
+
first = {}
|
| 158 |
+
co, cd = o.clone(), d.clone()
|
| 159 |
+
for depth_i in range(depth):
|
| 160 |
+
t, n, alb, isl = intersect(co, cd, S)
|
| 161 |
+
hit = (t < 1e8) & alive
|
| 162 |
+
p = co + t[:, None] * cd
|
| 163 |
+
if depth_i == 0:
|
| 164 |
+
first = dict(t=t.clone(), n=n.clone(), alb=alb.clone(),
|
| 165 |
+
p=p.clone(), hit=hit.clone() & ~isl)
|
| 166 |
+
emitted[hit & isl] = S["Le"]
|
| 167 |
+
alive = alive & hit & ~isl
|
| 168 |
+
# no .any() early-out: at these depths the surviving-ray count is
|
| 169 |
+
# data-dependent and the sync costs more than the wasted work
|
| 170 |
+
contrib = torch.zeros(N, 3, device=dev)
|
| 171 |
+
contrib[alive] = nee(p[alive], n[alive], alb[alive], S, rng)
|
| 172 |
+
contrib = contrib * tput
|
| 173 |
+
if depth_i == 0:
|
| 174 |
+
direct = direct + contrib
|
| 175 |
+
else:
|
| 176 |
+
indirect = indirect + contrib
|
| 177 |
+
# bounce
|
| 178 |
+
nd = torch.zeros_like(cd)
|
| 179 |
+
nd[alive] = cosine_hemisphere(n[alive], rng)
|
| 180 |
+
tput = tput * alb
|
| 181 |
+
co = p + EPS * n
|
| 182 |
+
cd = nd
|
| 183 |
+
return emitted, direct, indirect, first
|
| 184 |
+
|
| 185 |
+
|
| 186 |
+
def camera_rays(res, jitter, dev, rng, cam=(0.0, 0.0, 3.05), fov=0.62):
|
| 187 |
+
ys, xs = torch.meshgrid(
|
| 188 |
+
torch.linspace(1, -1, res, device=dev),
|
| 189 |
+
torch.linspace(-1, 1, res, device=dev), indexing="ij")
|
| 190 |
+
if jitter:
|
| 191 |
+
xs = xs + (torch.rand(res, res, device=dev, generator=rng) - .5) * (2 / res)
|
| 192 |
+
ys = ys + (torch.rand(res, res, device=dev, generator=rng) - .5) * (2 / res)
|
| 193 |
+
d = torch.stack([xs * fov, ys * fov, -torch.ones_like(xs)], -1).reshape(-1, 3)
|
| 194 |
+
d = d / d.norm(dim=1, keepdim=True)
|
| 195 |
+
o = torch.tensor(cam, device=dev).expand_as(d).contiguous()
|
| 196 |
+
return o, d
|
| 197 |
+
|
| 198 |
+
|
| 199 |
+
def scene_tensors(dev):
|
| 200 |
+
return _dev(dev)
|
experiments/radiance_cache.pt
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:6c963cdd817d845c9290ced6c1d188887e28b0b41f12707a9f5ea9b7f7e0245d
|
| 3 |
+
size 95959
|
experiments/w11_world_lighting.py
ADDED
|
@@ -0,0 +1,148 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""W11: neural lighting cache for the voxel world (ray-traced AO -> .pt).
|
| 2 |
+
|
| 3 |
+
The ray-tracing tie-in for the Neural World demo. Sky visibility (ambient
|
| 4 |
+
occlusion) is TRACED: from each ground point we shoot a hemisphere of
|
| 5 |
+
rays and count how many escape past the tall blocks (house, trees) to the
|
| 6 |
+
sky. That expensive per-point integral is distilled into a tiny MLP that
|
| 7 |
+
the browser evaluates per tile in real time — the same "trace once, learn
|
| 8 |
+
the field, look it up" idea as the W9 radiance cache, specialized to this
|
| 9 |
+
scene's geometry.
|
| 10 |
+
|
| 11 |
+
Layout MUST match the demo's hand-placed world (index.html): house 3x3 at
|
| 12 |
+
rows/cols 2..4, ten trees at fixed spots — everything else is flat.
|
| 13 |
+
"""
|
| 14 |
+
import sys, os, time
|
| 15 |
+
sys.path.insert(0, os.path.dirname(os.path.dirname(os.path.abspath(__file__))))
|
| 16 |
+
|
| 17 |
+
import numpy as np
|
| 18 |
+
import torch
|
| 19 |
+
import torch.nn as nn
|
| 20 |
+
|
| 21 |
+
torch.manual_seed(0)
|
| 22 |
+
HERE = os.path.dirname(os.path.abspath(__file__))
|
| 23 |
+
ROOT = os.path.dirname(HERE)
|
| 24 |
+
DEV = "cuda" if torch.cuda.is_available() else "cpu"
|
| 25 |
+
N = 32
|
| 26 |
+
NFREQ = 6
|
| 27 |
+
|
| 28 |
+
# tall occluders (cx, cz, half, top) — must match the demo world layout.
|
| 29 |
+
# house: 6x6 perimeter centred at (14.5, 14.5); trees: the demo's fixed set.
|
| 30 |
+
# x=col, z=row (three.js places tile (row r, col c) at x=c, z=r).
|
| 31 |
+
TREES = [[3, 4], [5, 20], [7, 27], [2, 10], [4, 28], [9, 3], [6, 24], [10, 29],
|
| 32 |
+
[20, 4], [22, 27], [25, 10], [27, 22], [29, 6], [24, 29], [19, 28],
|
| 33 |
+
[28, 15], [3, 16], [8, 8], [23, 3], [26, 26], [21, 20], [18, 3],
|
| 34 |
+
[29, 29], [2, 24]]
|
| 35 |
+
HR0, HC0, HS = 12, 12, 6
|
| 36 |
+
BOXES = [(HC0 + HS / 2, HR0 + HS / 2, HS / 2, 2.2)] # house block (x,z,half,top)
|
| 37 |
+
for (r, c) in TREES:
|
| 38 |
+
if not (HR0 - 2 <= r < HR0 + HS + 2 and HC0 - 2 <= c < HC0 + HS + 2):
|
| 39 |
+
BOXES.append((c + 0.5, r + 0.5, 0.6, 2.4)) # tree (x=col, z=row)
|
| 40 |
+
BOX = torch.tensor(BOXES, device=DEV) # (B,4): cx,cz,half,top
|
| 41 |
+
|
| 42 |
+
|
| 43 |
+
def sky_visibility(pts, n_rays=64):
|
| 44 |
+
"""pts (P,2) ground xz -> AO in [0,1] via hemisphere ray marching."""
|
| 45 |
+
P = len(pts)
|
| 46 |
+
g = torch.Generator(device=DEV); g.manual_seed(1)
|
| 47 |
+
# cosine-ish hemisphere directions (upper)
|
| 48 |
+
u1 = torch.rand(n_rays, device=DEV, generator=g)
|
| 49 |
+
u2 = torch.rand(n_rays, device=DEV, generator=g)
|
| 50 |
+
r = torch.sqrt(u1); phi = 2 * np.pi * u2
|
| 51 |
+
dirs = torch.stack([r * torch.cos(phi),
|
| 52 |
+
torch.sqrt((1 - u1).clamp_min(0)), # up = +y
|
| 53 |
+
r * torch.sin(phi)], 1) # (n_rays,3)
|
| 54 |
+
o = torch.stack([pts[:, 0], torch.full((P,), 0.55, device=DEV),
|
| 55 |
+
pts[:, 1]], 1) # (P,3)
|
| 56 |
+
vis = torch.ones(P, n_rays, device=DEV)
|
| 57 |
+
cx, cz, half, top = BOX[:, 0], BOX[:, 1], BOX[:, 2], BOX[:, 3]
|
| 58 |
+
# march: does ray (o,d) hit any box slab before escaping upward?
|
| 59 |
+
for b in range(len(BOX)):
|
| 60 |
+
# slab intersection in xz, check the entry y is below the box top
|
| 61 |
+
dx = dirs[:, 0][None, :]; dz = dirs[:, 2][None, :]; dy = dirs[:, 1][None, :]
|
| 62 |
+
ox = o[:, 0][:, None]; oz = o[:, 2][:, None]; oy = o[:, 1][:, None]
|
| 63 |
+
inv_x = 1.0 / torch.where(dx.abs() < 1e-6, torch.full_like(dx, 1e-6), dx)
|
| 64 |
+
inv_z = 1.0 / torch.where(dz.abs() < 1e-6, torch.full_like(dz, 1e-6), dz)
|
| 65 |
+
tx1 = (cx[b] - half[b] - ox) * inv_x; tx2 = (cx[b] + half[b] - ox) * inv_x
|
| 66 |
+
tz1 = (cz[b] - half[b] - oz) * inv_z; tz2 = (cz[b] + half[b] - oz) * inv_z
|
| 67 |
+
tmin = torch.maximum(torch.minimum(tx1, tx2), torch.minimum(tz1, tz2))
|
| 68 |
+
tmax = torch.minimum(torch.maximum(tx1, tx2), torch.maximum(tz1, tz2))
|
| 69 |
+
hit_xz = (tmax > tmin) & (tmax > 0)
|
| 70 |
+
t_enter = tmin.clamp_min(0)
|
| 71 |
+
y_at = oy + dy * t_enter
|
| 72 |
+
blocked = hit_xz & (y_at < top[b]) & (t_enter > 1e-3)
|
| 73 |
+
vis = torch.where(blocked, torch.zeros_like(vis), vis)
|
| 74 |
+
return vis.mean(1) # (P,) AO
|
| 75 |
+
|
| 76 |
+
|
| 77 |
+
def freq_encode(xz):
|
| 78 |
+
bands = (2.0 ** torch.arange(NFREQ, device=xz.device)) * np.pi
|
| 79 |
+
proj = xz[..., None] * bands
|
| 80 |
+
return torch.cat([xz, torch.sin(proj).flatten(-2),
|
| 81 |
+
torch.cos(proj).flatten(-2)], -1)
|
| 82 |
+
|
| 83 |
+
|
| 84 |
+
class LightNet(nn.Module):
|
| 85 |
+
def __init__(self, hidden=64):
|
| 86 |
+
super().__init__()
|
| 87 |
+
din = 2 + 2 * 2 * NFREQ
|
| 88 |
+
self.net = nn.Sequential(nn.Linear(din, hidden), nn.SiLU(),
|
| 89 |
+
nn.Linear(hidden, hidden), nn.SiLU(),
|
| 90 |
+
nn.Linear(hidden, 3))
|
| 91 |
+
|
| 92 |
+
def forward(self, xz):
|
| 93 |
+
return torch.nn.functional.softplus(self.net(freq_encode(xz)))
|
| 94 |
+
|
| 95 |
+
|
| 96 |
+
# ---- ground-truth AO -> ambient RGB on a dense grid ----
|
| 97 |
+
print(f"=== tracing sky visibility on {DEV} ===")
|
| 98 |
+
t0 = time.time()
|
| 99 |
+
G = 112
|
| 100 |
+
gx, gz = torch.meshgrid(torch.linspace(0, N, G, device=DEV),
|
| 101 |
+
torch.linspace(0, N, G, device=DEV), indexing="ij")
|
| 102 |
+
pts = torch.stack([gx.ravel(), gz.ravel()], 1)
|
| 103 |
+
ao = sky_visibility(pts, n_rays=96)
|
| 104 |
+
SKY = torch.tensor([0.55, 0.70, 1.0], device=DEV) # cool sky
|
| 105 |
+
GROUND = torch.tensor([0.30, 0.32, 0.28], device=DEV) # warm bounce floor
|
| 106 |
+
amb = (0.30 + 0.70 * ao)[:, None] * SKY + (1 - ao)[:, None] * GROUND * 0.4
|
| 107 |
+
xz_norm = pts / N * 2 - 1
|
| 108 |
+
print(f" {G*G} points, mean AO {ao.mean():.3f} "
|
| 109 |
+
f"(min {ao.min():.3f}) ({time.time()-t0:.1f}s)")
|
| 110 |
+
|
| 111 |
+
# ---- fit the cache ----
|
| 112 |
+
net = LightNet().to(DEV)
|
| 113 |
+
print(f"=== training light cache ({sum(p.numel() for p in net.parameters())} params) ===")
|
| 114 |
+
opt = torch.optim.Adam(net.parameters(), lr=3e-3)
|
| 115 |
+
sched = torch.optim.lr_scheduler.CosineAnnealingLR(opt, T_max=2500)
|
| 116 |
+
for it in range(2500):
|
| 117 |
+
idx = torch.randint(0, len(xz_norm), (8192,), device=DEV)
|
| 118 |
+
pred = net(xz_norm[idx])
|
| 119 |
+
loss = ((pred - amb[idx]) ** 2).mean()
|
| 120 |
+
opt.zero_grad(); loss.backward(); opt.step(); sched.step()
|
| 121 |
+
if it % 500 == 0 or it == 2499:
|
| 122 |
+
print(f" it {it:4d} MSE {loss.item():.6f}")
|
| 123 |
+
with torch.no_grad():
|
| 124 |
+
err = (net(xz_norm) - amb).abs().mean().item()
|
| 125 |
+
print(f" final mean abs error {err:.4f}")
|
| 126 |
+
|
| 127 |
+
# ---- figure: traced vs learned ambient ----
|
| 128 |
+
try:
|
| 129 |
+
import matplotlib; matplotlib.use("Agg"); import matplotlib.pyplot as plt
|
| 130 |
+
with torch.no_grad():
|
| 131 |
+
pr = net(xz_norm).reshape(G, G, 3).clamp(0, 1).cpu().numpy()
|
| 132 |
+
gt = amb.reshape(G, G, 3).clamp(0, 1).cpu().numpy()
|
| 133 |
+
fig, ax = plt.subplots(1, 3, figsize=(14, 4.6))
|
| 134 |
+
ax[0].imshow(ao.reshape(G, G).cpu().numpy(), cmap="bone"); ax[0].set_title("traced sky visibility (AO)")
|
| 135 |
+
ax[1].imshow(gt); ax[1].set_title("target ambient (AO -> RGB)")
|
| 136 |
+
ax[2].imshow(pr); ax[2].set_title(f"neural cache (world_light.pt), err {err:.3f}")
|
| 137 |
+
for a in ax: a.set_xticks([]); a.set_yticks([])
|
| 138 |
+
fig.suptitle("Neural world lighting — traced ambient occlusion distilled to a .pt")
|
| 139 |
+
fig.tight_layout()
|
| 140 |
+
out = os.path.join(ROOT, "world_lighting_validation.png")
|
| 141 |
+
fig.savefig(out, dpi=110); print(f"wrote {out}")
|
| 142 |
+
except Exception as e:
|
| 143 |
+
print("plot skipped:", e)
|
| 144 |
+
|
| 145 |
+
torch.save({"state_dict": net.state_dict(), "arch": {"nfreq": NFREQ, "hidden": 64},
|
| 146 |
+
"scene": "neural_world_32"},
|
| 147 |
+
os.path.join(HERE, "world_light.pt"))
|
| 148 |
+
print("saved experiments/world_light.pt")
|
experiments/w9_neural_radiance_cache.py
ADDED
|
@@ -0,0 +1,217 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""W9: neural radiance cache — neural ray tracing on the project skeleton.
|
| 2 |
+
|
| 3 |
+
Claim under test (the light-transport analog of the physics thesis): if
|
| 4 |
+
you keep visibility and direct lighting analytic and learn ONLY the
|
| 5 |
+
indirect transport with a tiny tied MLP, you match a many-bounce path
|
| 6 |
+
tracer at a fraction of the cost — one analytic ray + NEE + a network
|
| 7 |
+
lookup replaces the random walk after the first bounce.
|
| 8 |
+
|
| 9 |
+
Render decomposition: L = emitted + direct(analytic) + indirect
|
| 10 |
+
- reference: indirect from high-spp path tracing (ground truth)
|
| 11 |
+
- neural: indirect from cache_theta(first-hit point, normal)
|
| 12 |
+
- baseline: an equal-COST path trace (few spp) for a fair comparison
|
| 13 |
+
|
| 14 |
+
Success criteria:
|
| 15 |
+
A. cache accuracy on HELD-OUT surface points (never-seen view) — PSNR
|
| 16 |
+
of predicted vs true indirect radiance
|
| 17 |
+
B. full-image PSNR: neural-cached vs reference, and it beats the
|
| 18 |
+
equal-cost path-traced baseline
|
| 19 |
+
C. speedup at matched quality (spp the baseline needs to reach the
|
| 20 |
+
neural render's PSNR)
|
| 21 |
+
"""
|
| 22 |
+
import sys, os, time
|
| 23 |
+
sys.path.insert(0, os.path.dirname(os.path.dirname(os.path.abspath(__file__))))
|
| 24 |
+
|
| 25 |
+
import numpy as np
|
| 26 |
+
import torch
|
| 27 |
+
from engine3d.raytrace import (camera_rays, trace_split, scene_tensors,
|
| 28 |
+
intersect)
|
| 29 |
+
from engine3d.neural_rt import RadianceCache
|
| 30 |
+
|
| 31 |
+
torch.manual_seed(0)
|
| 32 |
+
HERE = os.path.dirname(os.path.abspath(__file__))
|
| 33 |
+
ROOT = os.path.dirname(HERE)
|
| 34 |
+
DEV = "cuda" if torch.cuda.is_available() else "cpu"
|
| 35 |
+
S = scene_tensors(DEV)
|
| 36 |
+
|
| 37 |
+
|
| 38 |
+
def rng_of(seed):
|
| 39 |
+
g = torch.Generator(device=DEV); g.manual_seed(seed); return g
|
| 40 |
+
|
| 41 |
+
|
| 42 |
+
def render(res, spp, seed, cam=(0.0, 0.0, 3.05), depth=5):
|
| 43 |
+
"""Full reference render (emitted + direct + indirect), returns (res,res,3)."""
|
| 44 |
+
g = rng_of(seed)
|
| 45 |
+
acc = torch.zeros(res * res, 3, device=DEV)
|
| 46 |
+
for _ in range(spp):
|
| 47 |
+
o, d = camera_rays(res, True, DEV, g, cam=cam)
|
| 48 |
+
em, di, ind, _ = trace_split(o, d, S, g, depth=depth)
|
| 49 |
+
acc += em + di + ind
|
| 50 |
+
return (acc / spp).reshape(res, res, 3)
|
| 51 |
+
|
| 52 |
+
|
| 53 |
+
def render_components(res, spp, seed, cam=(0.0, 0.0, 3.05)):
|
| 54 |
+
"""Per-pixel emitted+direct (low variance) and first-hit geometry, plus
|
| 55 |
+
a high-spp indirect target. Used to compose the neural image."""
|
| 56 |
+
g = rng_of(seed)
|
| 57 |
+
ed = torch.zeros(res * res, 3, device=DEV) # emitted + direct
|
| 58 |
+
ind = torch.zeros(res * res, 3, device=DEV)
|
| 59 |
+
o, d = camera_rays(res, False, DEV, g, cam=cam) # no jitter: fixed hits
|
| 60 |
+
for _ in range(spp):
|
| 61 |
+
em, di, ii, first = trace_split(o, d, S, g, depth=5)
|
| 62 |
+
ed += em + di
|
| 63 |
+
ind += ii
|
| 64 |
+
ed /= spp; ind /= spp
|
| 65 |
+
o2, d2 = camera_rays(res, False, DEV, rng_of(seed), cam=cam)
|
| 66 |
+
_, n, alb, isl = intersect(o2, d2, S)
|
| 67 |
+
t, _, _, _ = intersect(o2, d2, S)
|
| 68 |
+
p = o2 + t[:, None] * d2
|
| 69 |
+
hit = (t < 1e8) & ~isl
|
| 70 |
+
return ed, ind, p, n, hit
|
| 71 |
+
|
| 72 |
+
|
| 73 |
+
def psnr(a, b, mask=None):
|
| 74 |
+
if mask is not None:
|
| 75 |
+
a, b = a[mask], b[mask]
|
| 76 |
+
mse = ((a.clamp(0, 4) - b.clamp(0, 4)) ** 2).mean().item()
|
| 77 |
+
return 10 * np.log10(4.0 ** 2 / max(mse, 1e-12))
|
| 78 |
+
|
| 79 |
+
|
| 80 |
+
# ---------- training data: surface points with GT indirect ----------
|
| 81 |
+
print(f"=== generating radiance-cache training data on {DEV} ===")
|
| 82 |
+
t0 = time.time()
|
| 83 |
+
PTS, NRM, TGT = [], [], []
|
| 84 |
+
CAM_TRAIN = [(0.0, 0.0, 3.05), (0.7, 0.2, 2.9), (-0.7, 0.25, 2.9),
|
| 85 |
+
(0.0, 0.6, 2.8), (0.4, -0.3, 3.0)]
|
| 86 |
+
for ci, cam in enumerate(CAM_TRAIN):
|
| 87 |
+
g = rng_of(100 + ci)
|
| 88 |
+
o, d = camera_rays(80, True, DEV, g, cam=cam)
|
| 89 |
+
t, n, alb, isl = intersect(o, d, S)
|
| 90 |
+
p = o + t[:, None] * d
|
| 91 |
+
hit = (t < 1e8) & ~isl
|
| 92 |
+
p, n = p[hit], n[hit]
|
| 93 |
+
# GT indirect at these points: average many one-bounce-onward paths
|
| 94 |
+
ind = torch.zeros(len(p), 3, device=DEV)
|
| 95 |
+
SPP = 256
|
| 96 |
+
for _ in range(SPP):
|
| 97 |
+
from engine3d.raytrace import cosine_hemisphere, nee, EPS
|
| 98 |
+
nd = cosine_hemisphere(n, g)
|
| 99 |
+
# radiance arriving from the bounce dir, path-traced (depth 4),
|
| 100 |
+
# times the cosine-weighted albedo throughput (albedo/pi * pi = albedo)
|
| 101 |
+
_, ndi, nind, _ = trace_split(p + EPS * n, nd, S, g, depth=4)
|
| 102 |
+
ind += (ndi + nind)
|
| 103 |
+
ind /= SPP
|
| 104 |
+
alb_h = alb[hit]
|
| 105 |
+
ind = ind * alb_h # outgoing = albedo * incident indirect
|
| 106 |
+
PTS.append(p); NRM.append(n); TGT.append(ind)
|
| 107 |
+
P = torch.cat(PTS); Nrm = torch.cat(NRM); Y = torch.cat(TGT)
|
| 108 |
+
print(f" {len(P)} surface samples from {len(CAM_TRAIN)} views "
|
| 109 |
+
f"({time.time()-t0:.1f}s)")
|
| 110 |
+
|
| 111 |
+
# ---------- train the cache ----------
|
| 112 |
+
cache = RadianceCache().to(DEV)
|
| 113 |
+
print(f"=== training radiance cache ({cache.n_params()} params) ===")
|
| 114 |
+
opt = torch.optim.Adam(cache.parameters(), lr=3e-3)
|
| 115 |
+
sched = torch.optim.lr_scheduler.CosineAnnealingLR(opt, T_max=1500)
|
| 116 |
+
# tone-mapped (log) loss: indirect radiance spans orders of magnitude and
|
| 117 |
+
# the eye is roughly logarithmic — regress log(1+L), like real NRC
|
| 118 |
+
logY = torch.log1p(Y)
|
| 119 |
+
t0 = time.time()
|
| 120 |
+
for it in range(1500):
|
| 121 |
+
idx = torch.randint(0, len(P), (16384,), device=DEV)
|
| 122 |
+
pred = cache(P[idx], Nrm[idx])
|
| 123 |
+
loss = ((torch.log1p(pred) - logY[idx]) ** 2).mean()
|
| 124 |
+
opt.zero_grad(); loss.backward(); opt.step(); sched.step()
|
| 125 |
+
if it % 300 == 0 or it == 1499:
|
| 126 |
+
print(f" it {it:4d} log-MSE {loss.item():.5f}")
|
| 127 |
+
print(f" ({time.time()-t0:.1f}s)")
|
| 128 |
+
|
| 129 |
+
# ---------- criterion A: held-out points (novel view) ----------
|
| 130 |
+
g = rng_of(999)
|
| 131 |
+
cam_test = (0.35, -0.15, 2.95)
|
| 132 |
+
o, d = camera_rays(80, True, DEV, g, cam=cam_test)
|
| 133 |
+
t, n, alb, isl = intersect(o, d, S)
|
| 134 |
+
p = o + t[:, None] * d
|
| 135 |
+
hit = (t < 1e8) & ~isl
|
| 136 |
+
p, n, alb = p[hit], n[hit], alb[hit]
|
| 137 |
+
ind = torch.zeros(len(p), 3, device=DEV)
|
| 138 |
+
from engine3d.raytrace import cosine_hemisphere, EPS
|
| 139 |
+
for _ in range(256):
|
| 140 |
+
nd = cosine_hemisphere(n, g)
|
| 141 |
+
_, ndi, nind, _ = trace_split(p + EPS * n, nd, S, g, depth=4)
|
| 142 |
+
ind += (ndi + nind)
|
| 143 |
+
ind = ind / 256 * alb
|
| 144 |
+
with torch.no_grad():
|
| 145 |
+
pred = cache(p, n)
|
| 146 |
+
a_psnr = psnr(pred, ind)
|
| 147 |
+
print(f"\n[A] held-out indirect radiance PSNR: {a_psnr:.2f} dB "
|
| 148 |
+
f"(novel view, {len(p)} pts)")
|
| 149 |
+
|
| 150 |
+
# ---------- criterion B & C: full-image renders ----------
|
| 151 |
+
RES = 112
|
| 152 |
+
REF_SPP = 256
|
| 153 |
+
print(f"\n=== full renders at {RES}x{RES} ===")
|
| 154 |
+
t0 = time.time(); REF = render(RES, REF_SPP, 7); ref_ms = (time.time()-t0)*1000
|
| 155 |
+
print(f" reference ({REF_SPP} spp): {ref_ms:.0f} ms")
|
| 156 |
+
|
| 157 |
+
# neural: analytic emitted+direct at low spp + cache indirect
|
| 158 |
+
t0 = time.time()
|
| 159 |
+
ed, _, p, n, hit = render_components(RES, 4, 7)
|
| 160 |
+
with torch.no_grad():
|
| 161 |
+
ind_pred = torch.zeros(RES * RES, 3, device=DEV)
|
| 162 |
+
ind_pred[hit] = cache(p[hit], n[hit])
|
| 163 |
+
NEUR = (ed + ind_pred).reshape(RES, RES, 3)
|
| 164 |
+
neur_ms = (time.time()-t0)*1000
|
| 165 |
+
print(f" neural (4 spp direct + cache): {neur_ms:.0f} ms")
|
| 166 |
+
|
| 167 |
+
# baseline: equal-cost full path trace
|
| 168 |
+
def spp_for_ms(target_ms):
|
| 169 |
+
t0 = time.time(); render(RES, 4, 7); one = (time.time()-t0)/4*1000
|
| 170 |
+
return max(1, round(target_ms / one)), one
|
| 171 |
+
base_spp, per = spp_for_ms(neur_ms)
|
| 172 |
+
BASE = render(RES, base_spp, 7)
|
| 173 |
+
|
| 174 |
+
pn = psnr(NEUR, REF)
|
| 175 |
+
pb = psnr(BASE, REF)
|
| 176 |
+
print(f"\n[B] full-image PSNR vs reference:")
|
| 177 |
+
print(f" neural (cache) : {pn:.2f} dB ({neur_ms:.0f} ms)")
|
| 178 |
+
print(f" path trace (equal cost) : {pb:.2f} dB ({base_spp} spp)")
|
| 179 |
+
|
| 180 |
+
# criterion C: spp the baseline needs to match the neural PSNR
|
| 181 |
+
match_spp = None
|
| 182 |
+
for spp in [8, 16, 32, 64, 128]:
|
| 183 |
+
if psnr(render(RES, spp, 7), REF) >= pn:
|
| 184 |
+
match_spp = spp; break
|
| 185 |
+
base_ms = (match_spp or 128) * per
|
| 186 |
+
print(f"\n[C] path trace needs ~{match_spp or '>256'} spp "
|
| 187 |
+
f"(~{base_ms:.0f} ms) to reach the neural PSNR "
|
| 188 |
+
f"-> ~{base_ms/neur_ms:.1f}x speedup at matched quality")
|
| 189 |
+
|
| 190 |
+
# ---------- figure ----------
|
| 191 |
+
try:
|
| 192 |
+
import matplotlib; matplotlib.use("Agg"); import matplotlib.pyplot as plt
|
| 193 |
+
def tm(x): return np.clip((x.clamp(0, 4) ** (1/2.2)).cpu().numpy(), 0, 1)
|
| 194 |
+
err = (NEUR - REF).abs().mean(-1).cpu().numpy()
|
| 195 |
+
errb = (BASE - REF).abs().mean(-1).cpu().numpy()
|
| 196 |
+
fig, ax = plt.subplots(2, 3, figsize=(12, 8))
|
| 197 |
+
for a in ax.ravel(): a.set_xticks([]); a.set_yticks([])
|
| 198 |
+
ax[0,0].imshow(tm(REF)); ax[0,0].set_title(f"reference ({REF_SPP} spp)")
|
| 199 |
+
ax[0,1].imshow(tm(NEUR)); ax[0,1].set_title(f"neural cache — {pn:.1f} dB, {neur_ms:.0f} ms")
|
| 200 |
+
ax[0,2].imshow(tm(BASE)); ax[0,2].set_title(f"equal-cost path trace ({base_spp} spp) — {pb:.1f} dB")
|
| 201 |
+
ax[1,0].imshow(tm(ind_pred.reshape(RES,RES,3))); ax[1,0].set_title("learned indirect (cache only)")
|
| 202 |
+
m=max(err.max(),errb.max())
|
| 203 |
+
ax[1,1].imshow(err,cmap="inferno",vmax=m); ax[1,1].set_title("neural error")
|
| 204 |
+
ax[1,2].imshow(errb,cmap="inferno",vmax=m); ax[1,2].set_title("path-trace error")
|
| 205 |
+
fig.suptitle(f"Neural radiance cache — learn indirect, keep visibility+direct analytic "
|
| 206 |
+
f"(held-out cache PSNR {a_psnr:.1f} dB)", fontsize=12)
|
| 207 |
+
fig.tight_layout()
|
| 208 |
+
out=os.path.join(ROOT,"neural_raytrace_validation.png")
|
| 209 |
+
fig.savefig(out,dpi=110); print(f"\nwrote {out}")
|
| 210 |
+
except Exception as e:
|
| 211 |
+
print("plot skipped:", e)
|
| 212 |
+
|
| 213 |
+
torch.save({"state_dict": cache.state_dict(),
|
| 214 |
+
"arch": {"n_freq": 6, "hidden": 96},
|
| 215 |
+
"scene": "neon_cornell"},
|
| 216 |
+
os.path.join(HERE, "radiance_cache.pt"))
|
| 217 |
+
print("saved experiments/radiance_cache.pt")
|
experiments/world_light.pt
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:e127cfc99059eae827da9a78cf373e671a1d18253ac95a724c5d5a2000afa194
|
| 3 |
+
size 27184
|
neural_raytrace_validation.png
ADDED
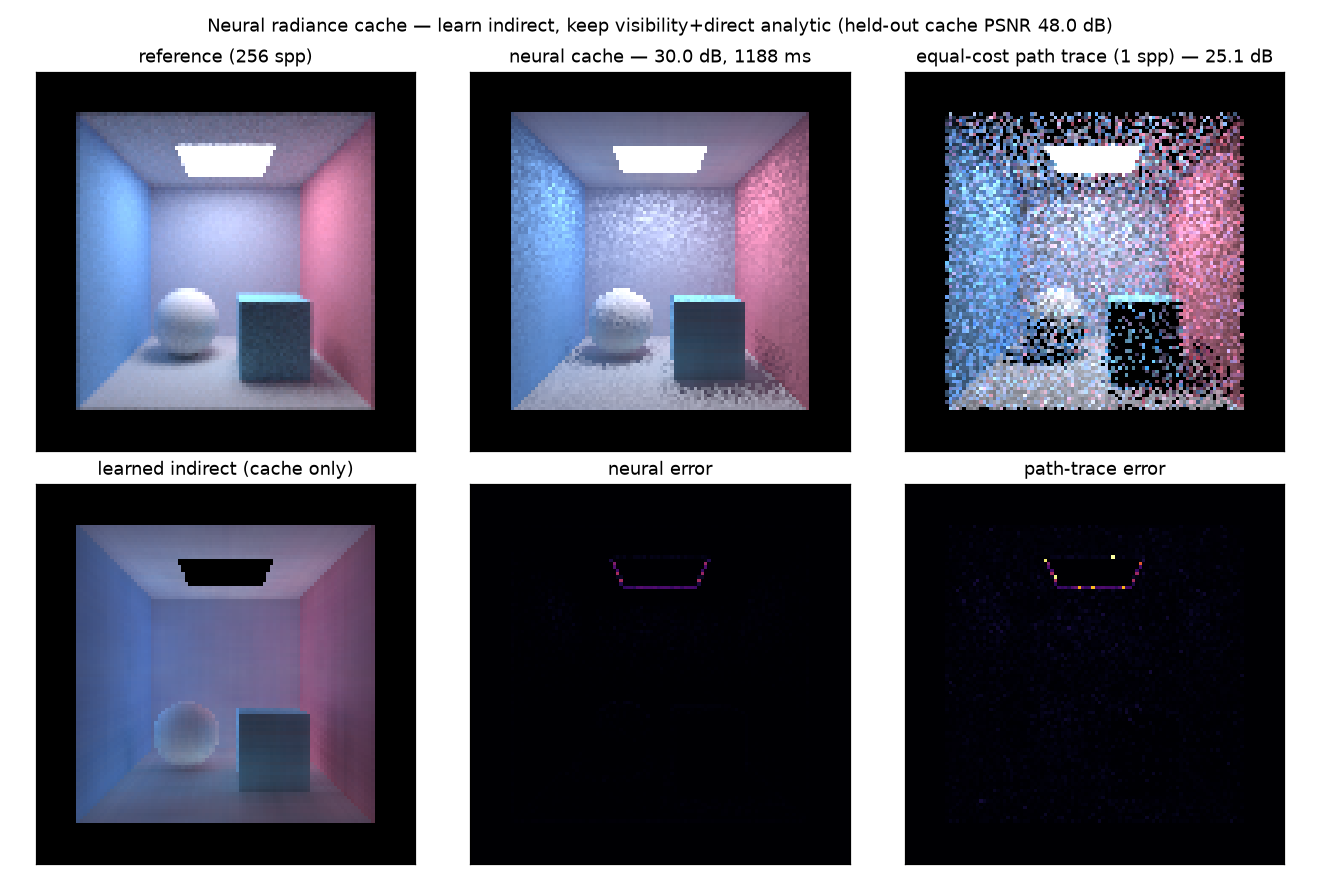
|
Git LFS Details
|
world_lighting_validation.png
ADDED
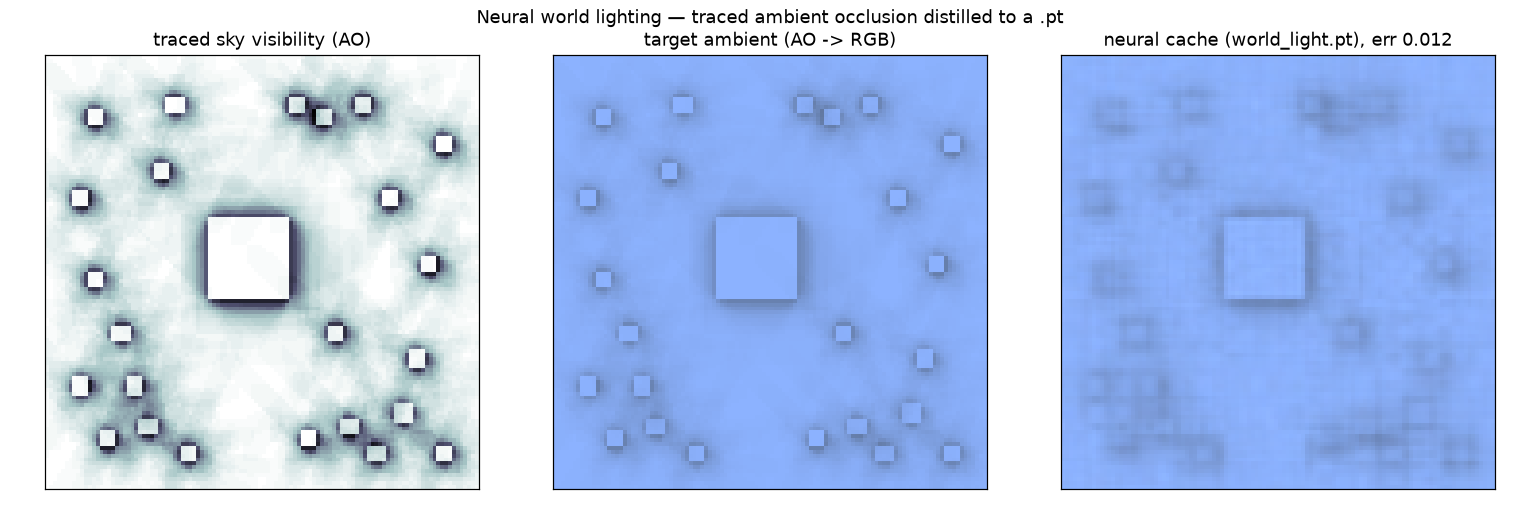
|