---
license: apache-2.0
---
Neuroengine.ai
# Model Card for Zeroshot-Qwen3-14B-preview
This is the **Zeroshot-Qwen3-14B-preview**, an Instruction-tuned Large Language Model specifically fine-tuned to enhance automated bug hunting and code auditing capabilities.
## Model Details
### Model Description
* **Developed by:** Alfredo Ortega (@ortegaalfredo)
* **Model type:** 14B LLM specialized for security research
* **Language(s) (NLP):** Multilingual
* **License:** Apache 2.0
* **Finetuned from model:** [Qwen/Qwen3-14B](https://huggingface.co/Qwen/Qwen3-14B)
---
## Technical Characteristics
The **Zeroshot-Qwen3-14B-preview** is designed to bridge the gap between small, fast models and the high-reasoning capabilities required for vulnerability research.
* **Reasoning Dataset:** The preview version was fine-tuned with over **10,000 thinking traces** of public CVEs (Common Vulnerabilities and Exposures), totaling nearly **500MB of text**.
* **Performance Leap:** Benchmarks indicate a clear enhancement in bug hunting capabilities, showing an improvement of approximately **20% over the base Qwen3-14B model**.
* **Specialization vs. Scale:** This model demonstrates that smaller models can be specialized for complex, niche tasks, significantly reducing costs and increasing processing speed compared to larger, more expensive models.
* **Efficiency for Large Codebases:** The primary objective is to lower the barrier for entry in code auditing. Large models are often too slow or cost-prohibitive to deploy across massive, enterprise-scale codebases.
* **Future Roadmap:** The ultimate goal is to reach **50,000 thinking traces** integrated into a **Mixture of Experts (MoE)** model, enabling high-tier security analysis on hardware without dedicated GPUs.
---
## Benchmarks
The following table compares the **Zeroshot-Qwen3-14B-preview** against its base version and several industry-leading models.
| Model / Configuration | Final Score (out of 123) | Total Time (s) | Tokens per Second |
| :--- | :---: | :---: | :---: |
| **Zeroshot-Qwen3-14B-preview (Local)** | **68.8** | 484.67 | 628.77 |
| Qwen3-14B (Local) | 55.6 | 492.44 | 575.34 |
| Qwen3-14B (OpenRouter) | 55.8 | 321.73 | 200.41 |
| qwen/qwen3-30b-a3b-thinking-2507 | 66.4 | 272.65 | 230.82 |
| x-ai/grok-4.1-fast | 66.6 | 446.59 | 213.02 |
| google/gemma-3-27b-it | 72.6 | 68.92 | 1,343.72 |
| GLM 4.5 Air | 73.8 | 88.29 | 958.69 |
| Deepseek-chat 3.2 API | 99.0 | 52.89 | 1,480.27 |
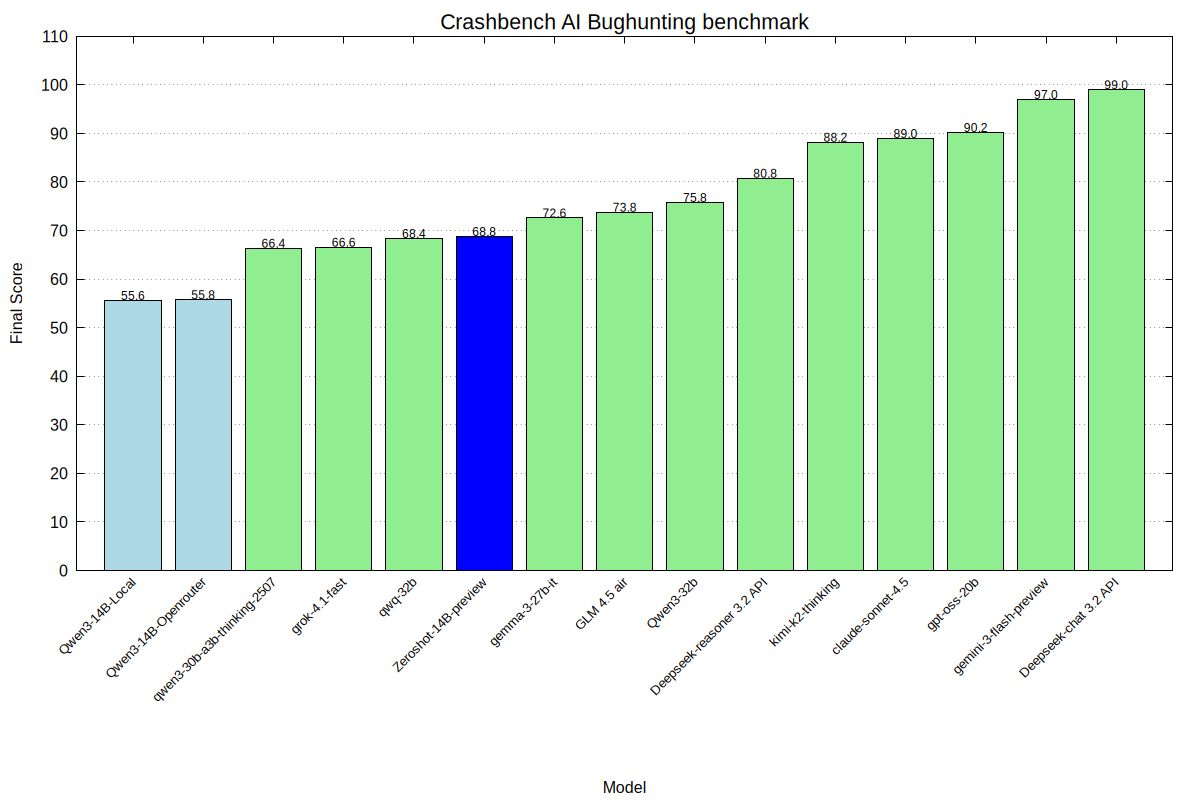 In the image (from https://github.com/ortegaalfredo/crashbench) we can see the score for regular Qwen3-14B increase from ~55 to 68 on the CrashBench benchmark, demonstrating that even a small dataset can greatly improve small LLMs' abilities.
---
## Usage and Implementation
### Recommended Prompt Template
To achieve the most effective results for vulnerability detection, use the following Zeroshot prompt structure:
System prompt:
```
You are a helpful assistant that analyzes code for security vulnerabilities.
```
User prompt:
```text
Please analyze this code and describe the most critical vulnerability:
### BEGIN CODE ###
{code_to_analyze}
### END CODE ###
```
## Quantization and Deployment
The Q4_K_M quantized version is provided to allow the model to run on consumer hardware.
* VRAM Requirements: Approximately 12 GB.
* Inference Engine: Optimized for llama.cpp.
### Running with llama.cpp
To execute the quantized model locally, use the following command:
```
./llama-cli -m Zeroshot-Qwen3-14B-preview-q4.gguf
```
### Running with transformers:
```python
messages = [
{"role": "system", "content": "You are a helpful assistant that analyzes code for security vulnerabilities."},
{"role": "user", "content": "Please analyze this code and describe the most critical vulnerability:\n### BEGIN CODE ###\n