

YaRN
Collection
Extension of Llama 2 to 128k context windows • 17 items • Updated • 34
docker run --gpus all \
--shm-size 32g \
-p 30000:30000 \
-v ~/.cache/huggingface:/root/.cache/huggingface \
--env "HF_TOKEN=<secret>" \
--ipc=host \
lmsysorg/sglang:latest \
python3 -m sglang.launch_server \
--model-path "NousResearch/Yarn-Llama-2-70b-32k" \
--host 0.0.0.0 \
--port 30000# Call the server using curl (OpenAI-compatible API):
curl -X POST "http://localhost:30000/v1/completions" \
-H "Content-Type: application/json" \
--data '{
"model": "NousResearch/Yarn-Llama-2-70b-32k",
"prompt": "Once upon a time,",
"max_tokens": 512,
"temperature": 0.5
}'The authors would like to thank LAION AI for their support of compute for this model. It was trained on the JUWELS supercomputer.
Nous-Yarn-Llama-2-70b-32k is a state-of-the-art language model for long context, further pretrained on long context data for 400 steps using the YaRN extension method. It is an extension of Llama-2-70b-hf and supports a 32k token context window.
To use, pass trust_remote_code=True when loading the model, for example
model = AutoModelForCausalLM.from_pretrained("NousResearch/Yarn-Llama-2-70b-32k",
use_flash_attention_2=True,
torch_dtype=torch.bfloat16,
device_map="auto",
trust_remote_code=True)
In addition you will need to use the latest version of transformers (until 4.35 comes out)
pip install git+https://github.com/huggingface/transformers
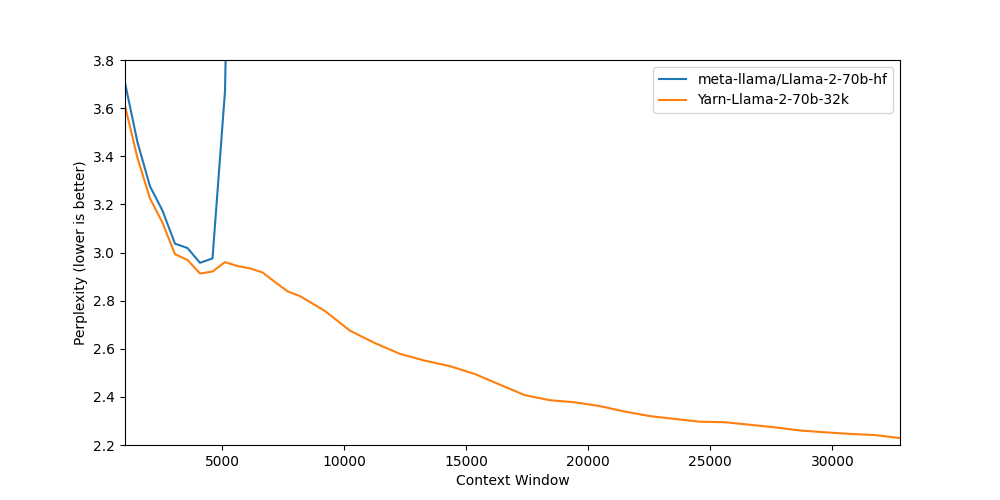
Long context benchmarks:
| Model | Context Window | 1k PPL | 2k PPL | 4k PPL | 8k PPL | 16k PPL | 32k PPL |
|---|---|---|---|---|---|---|---|
| Llama-2-70b-hf | 4k | 3.71 | 3.27 | 2.96 | - | - | - |
| Yarn-Llama-2-70b-32k | 32k | 3.61 | 3.22 | 2.91 | 2.82 | 2.45 | 2.23 |
Short context benchmarks showing that quality degradation is minimal:
| Model | Context Window | ARC-c | MMLU | Truthful QA |
|---|---|---|---|---|
| Llama-2-70b-hf | 4k | 67.32 | 69.83 | 44.92 |
| Yarn-Llama-2-70b-32k | 32k | 67.41 | 68.84 | 46.14 |
Install from pip and serve model
# Install SGLang from pip: pip install sglang# Start the SGLang server: python3 -m sglang.launch_server \ --model-path "NousResearch/Yarn-Llama-2-70b-32k" \ --host 0.0.0.0 \ --port 30000# Call the server using curl (OpenAI-compatible API): curl -X POST "http://localhost:30000/v1/completions" \ -H "Content-Type: application/json" \ --data '{ "model": "NousResearch/Yarn-Llama-2-70b-32k", "prompt": "Once upon a time,", "max_tokens": 512, "temperature": 0.5 }'