Instructions to use Scicom-intl/gpt-oss-20b-Malaysian-Reasoning-SFT-v0.1 with libraries, inference providers, notebooks, and local apps. Follow these links to get started.
- Libraries
- Transformers
How to use Scicom-intl/gpt-oss-20b-Malaysian-Reasoning-SFT-v0.1 with Transformers:
# Use a pipeline as a high-level helper from transformers import pipeline pipe = pipeline("text-generation", model="Scicom-intl/gpt-oss-20b-Malaysian-Reasoning-SFT-v0.1") messages = [ {"role": "user", "content": "Who are you?"}, ] pipe(messages)# Load model directly from transformers import AutoTokenizer, AutoModelForCausalLM tokenizer = AutoTokenizer.from_pretrained("Scicom-intl/gpt-oss-20b-Malaysian-Reasoning-SFT-v0.1") model = AutoModelForCausalLM.from_pretrained("Scicom-intl/gpt-oss-20b-Malaysian-Reasoning-SFT-v0.1", device_map="auto") messages = [ {"role": "user", "content": "Who are you?"}, ] inputs = tokenizer.apply_chat_template( messages, add_generation_prompt=True, tokenize=True, return_dict=True, return_tensors="pt", ).to(model.device) outputs = model.generate(**inputs, max_new_tokens=40) print(tokenizer.decode(outputs[0][inputs["input_ids"].shape[-1]:])) - Notebooks
- Google Colab
- Kaggle
- Local Apps Settings
- vLLM
How to use Scicom-intl/gpt-oss-20b-Malaysian-Reasoning-SFT-v0.1 with vLLM:
Install from pip and serve model
# Install vLLM from pip: pip install vllm # Start the vLLM server: vllm serve "Scicom-intl/gpt-oss-20b-Malaysian-Reasoning-SFT-v0.1" # Call the server using curl (OpenAI-compatible API): curl -X POST "http://localhost:8000/v1/chat/completions" \ -H "Content-Type: application/json" \ --data '{ "model": "Scicom-intl/gpt-oss-20b-Malaysian-Reasoning-SFT-v0.1", "messages": [ { "role": "user", "content": "What is the capital of France?" } ] }'Use Docker
docker model run hf.co/Scicom-intl/gpt-oss-20b-Malaysian-Reasoning-SFT-v0.1
- SGLang
How to use Scicom-intl/gpt-oss-20b-Malaysian-Reasoning-SFT-v0.1 with SGLang:
Install from pip and serve model
# Install SGLang from pip: pip install sglang # Start the SGLang server: python3 -m sglang.launch_server \ --model-path "Scicom-intl/gpt-oss-20b-Malaysian-Reasoning-SFT-v0.1" \ --host 0.0.0.0 \ --port 30000 # Call the server using curl (OpenAI-compatible API): curl -X POST "http://localhost:30000/v1/chat/completions" \ -H "Content-Type: application/json" \ --data '{ "model": "Scicom-intl/gpt-oss-20b-Malaysian-Reasoning-SFT-v0.1", "messages": [ { "role": "user", "content": "What is the capital of France?" } ] }'Use Docker images
docker run --gpus all \ --shm-size 32g \ -p 30000:30000 \ -v ~/.cache/huggingface:/root/.cache/huggingface \ --env "HF_TOKEN=<secret>" \ --ipc=host \ lmsysorg/sglang:latest \ python3 -m sglang.launch_server \ --model-path "Scicom-intl/gpt-oss-20b-Malaysian-Reasoning-SFT-v0.1" \ --host 0.0.0.0 \ --port 30000 # Call the server using curl (OpenAI-compatible API): curl -X POST "http://localhost:30000/v1/chat/completions" \ -H "Content-Type: application/json" \ --data '{ "model": "Scicom-intl/gpt-oss-20b-Malaysian-Reasoning-SFT-v0.1", "messages": [ { "role": "user", "content": "What is the capital of France?" } ] }' - Docker Model Runner
How to use Scicom-intl/gpt-oss-20b-Malaysian-Reasoning-SFT-v0.1 with Docker Model Runner:
docker model run hf.co/Scicom-intl/gpt-oss-20b-Malaysian-Reasoning-SFT-v0.1
# Load model directly
from transformers import AutoTokenizer, AutoModelForCausalLM
tokenizer = AutoTokenizer.from_pretrained("Scicom-intl/gpt-oss-20b-Malaysian-Reasoning-SFT-v0.1")
model = AutoModelForCausalLM.from_pretrained("Scicom-intl/gpt-oss-20b-Malaysian-Reasoning-SFT-v0.1", device_map="auto")
messages = [
{"role": "user", "content": "Who are you?"},
]
inputs = tokenizer.apply_chat_template(
messages,
add_generation_prompt=True,
tokenize=True,
return_dict=True,
return_tensors="pt",
).to(model.device)
outputs = model.generate(**inputs, max_new_tokens=40)
print(tokenizer.decode(outputs[0][inputs["input_ids"].shape[-1]:]))gpt-oss-20b-Malaysian-Reasoning-SFT-v0.1
LoRA SFT openai/gpt-oss-20b on initial mesolitica/Malaysian-Reasoning
Ablation on GPT OSS 20B
- Use
kernels-community/vllm-flash-attn3for Flash Attention 3 with Sink. - Multipacking variable length 16384 context length, with global batch size of 8, so global total tokens is 65536.
- All self attention linear layers with rank 16, 32, 64, 128, 256, 512 with alpha multiply by 2.0
- All expert gate up projection and down projection with rank 16, 32, 64, 128, 256, 512 with alpha multiply by 2.0 +
- Selected expert gate up projection and down projection based on square root mean
exp_avg_sq, top 4 selected layers are 3, 2, 18, and 1. + - Liger fused cross entropy.
- 2e-4 learning rate, 50 warmup, 2 epoch only.
+ with the rank of each equal to the total rank divided by the number of active experts, https://thinkingmachines.ai/blog/lora/
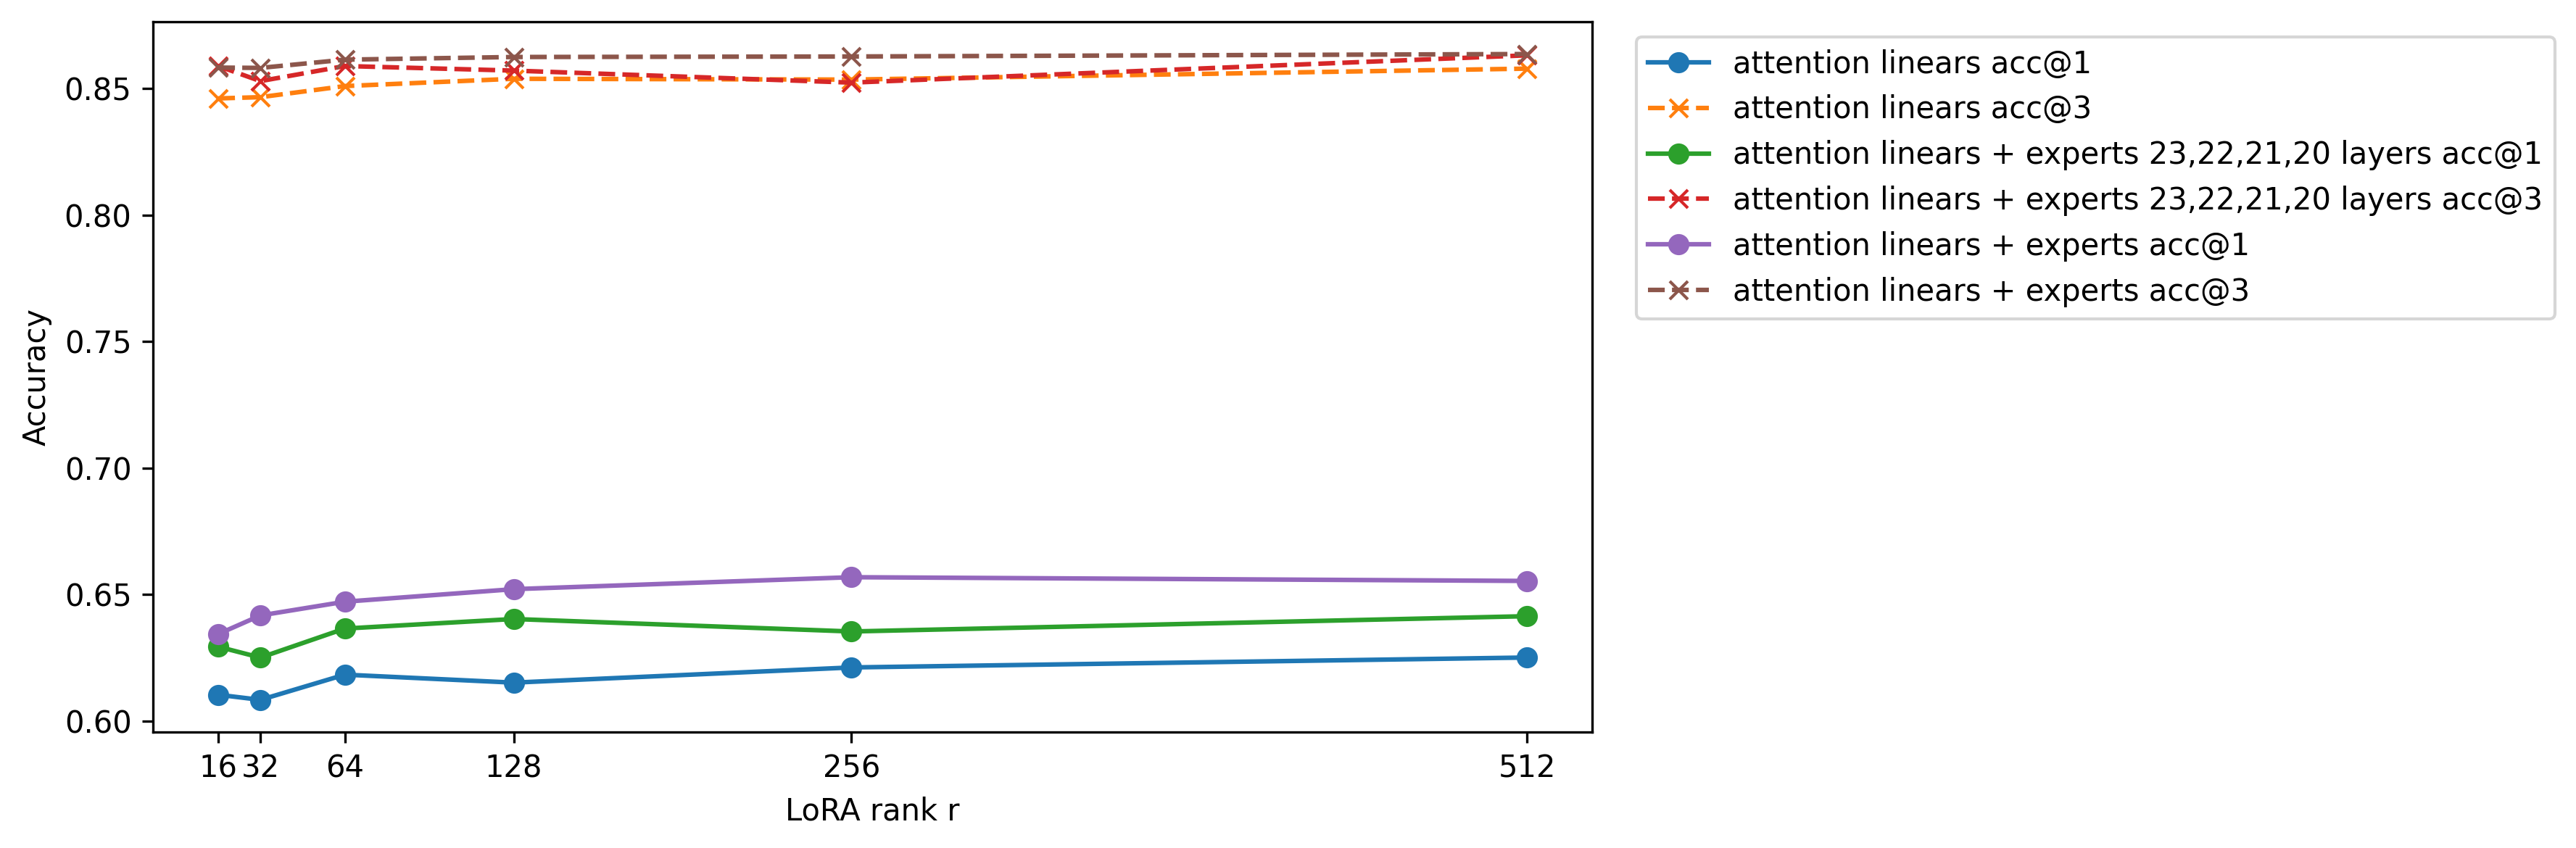
We only upload the best model
This model repository we only upload the best, only attention linear layers with rank 256 alpha 512.
Source code
Source code at https://github.com/Scicom-AI-Enterprise-Organization/small-ablation/blob/main/malaysian-reasoning
Acknowledgement
Special thanks to https://www.scitix.ai/ for H100 Node!
- Downloads last month
- 78
# Use a pipeline as a high-level helper from transformers import pipeline pipe = pipeline("text-generation", model="Scicom-intl/gpt-oss-20b-Malaysian-Reasoning-SFT-v0.1") messages = [ {"role": "user", "content": "Who are you?"}, ] pipe(messages)