


Model card: comparison with other open detectors under eot-bench + charts
Browse files- .gitattributes +4 -0
- README.md +28 -17
- assets/auc.png +0 -0
- assets/cutoff_at_budget.png +3 -0
- assets/heatmap.png +3 -0
- assets/latency_at_budget.png +3 -0
- assets/pareto.png +3 -0
.gitattributes
CHANGED
|
@@ -33,3 +33,7 @@ saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
assets/cutoff_at_budget.png filter=lfs diff=lfs merge=lfs -text
|
| 37 |
+
assets/heatmap.png filter=lfs diff=lfs merge=lfs -text
|
| 38 |
+
assets/latency_at_budget.png filter=lfs diff=lfs merge=lfs -text
|
| 39 |
+
assets/pareto.png filter=lfs diff=lfs merge=lfs -text
|
README.md
CHANGED
|
@@ -92,6 +92,34 @@ silence evidence; the extra encoder capacity buys the most exactly there (AUC 0.
|
|
| 92 |
start). In the LiveKit pipeline, which asks after the VAD's 0.4–0.55 s of silence, the two are one cut-off
|
| 93 |
turn apart.
|
| 94 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 95 |
## Files
|
| 96 |
|
| 97 |
| file | what |
|
|
@@ -141,23 +169,6 @@ Use `p ≥ 0.3` as "the turn is over" for the operating point in the table above
|
|
| 141 |
snippet (a `WhisperEncoder` subclass that accepts the 8 s window + the 3-layer head) is on the tiny model's
|
| 142 |
card and works unchanged with this repo id (`d_model` 512).
|
| 143 |
|
| 144 |
-
## Training
|
| 145 |
-
|
| 146 |
-
Same as the tiny model: `Scicom-intl/semantic-vad-eot-emgs` (private call-centre telephony, Malay/English,
|
| 147 |
-
customer + agent channels), all train + validation files, early stopping (patience 3) on a fixed 4 000-cut
|
| 148 |
-
sample of the test split — the pipeline benchmark's 300 turns come from that split too, so the numbers are
|
| 149 |
-
in-distribution. Six cut offsets per pause drawn uniformly in [−0.4, +1.2] s (never a fixed grid — it gets
|
| 150 |
-
memorised), 8 s left-padded window, mean of the last 5 encoder frames → `EoTHead`. `openai/whisper-base`
|
| 151 |
-
encoder (6 layers, d 512) fully fine-tuned in bf16, batch 128, AdamW lr 5e-5 constant after warm-up.
|
| 152 |
-
Early-stopped at step 32 000 (validation AUC 0.877 on uniform cuts; tiny: 0.859 at step 8 000). ONNX via
|
| 153 |
-
`torch.onnx.export` at the fixed 800-frame input, MatMul-only dynamic int8.
|
| 154 |
-
|
| 155 |
-
## Limitations
|
| 156 |
-
|
| 157 |
-
As for the tiny model: telephony Malay/English only (matches, does not beat, the VAD baseline on Malay read
|
| 158 |
-
speech); expects the raw phone channel (noise cancellation in front of it hurt); feed unit-scale float audio;
|
| 159 |
-
query it after a short VAD silence, not on every frame; a 300-turn sample stands behind the pipeline numbers.
|
| 160 |
-
|
| 161 |
## License
|
| 162 |
|
| 163 |
Apache-2.0 (the Whisper encoder it fine-tunes is Apache-2.0). The training data is not released.
|
|
|
|
| 92 |
start). In the LiveKit pipeline, which asks after the VAD's 0.4–0.55 s of silence, the two are one cut-off
|
| 93 |
turn apart.
|
| 94 |
|
| 95 |
+
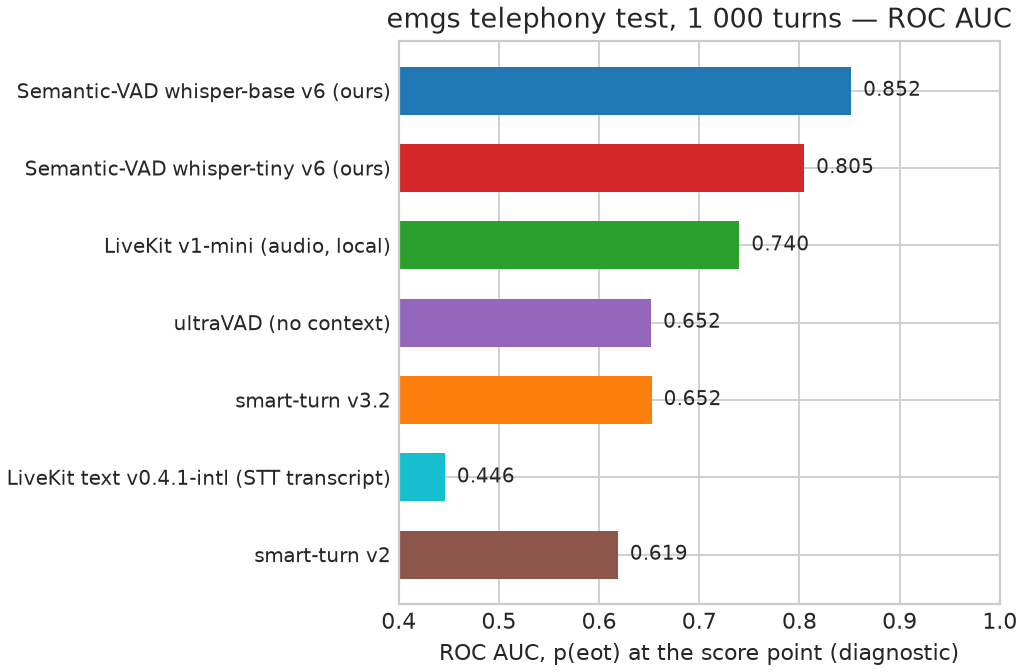
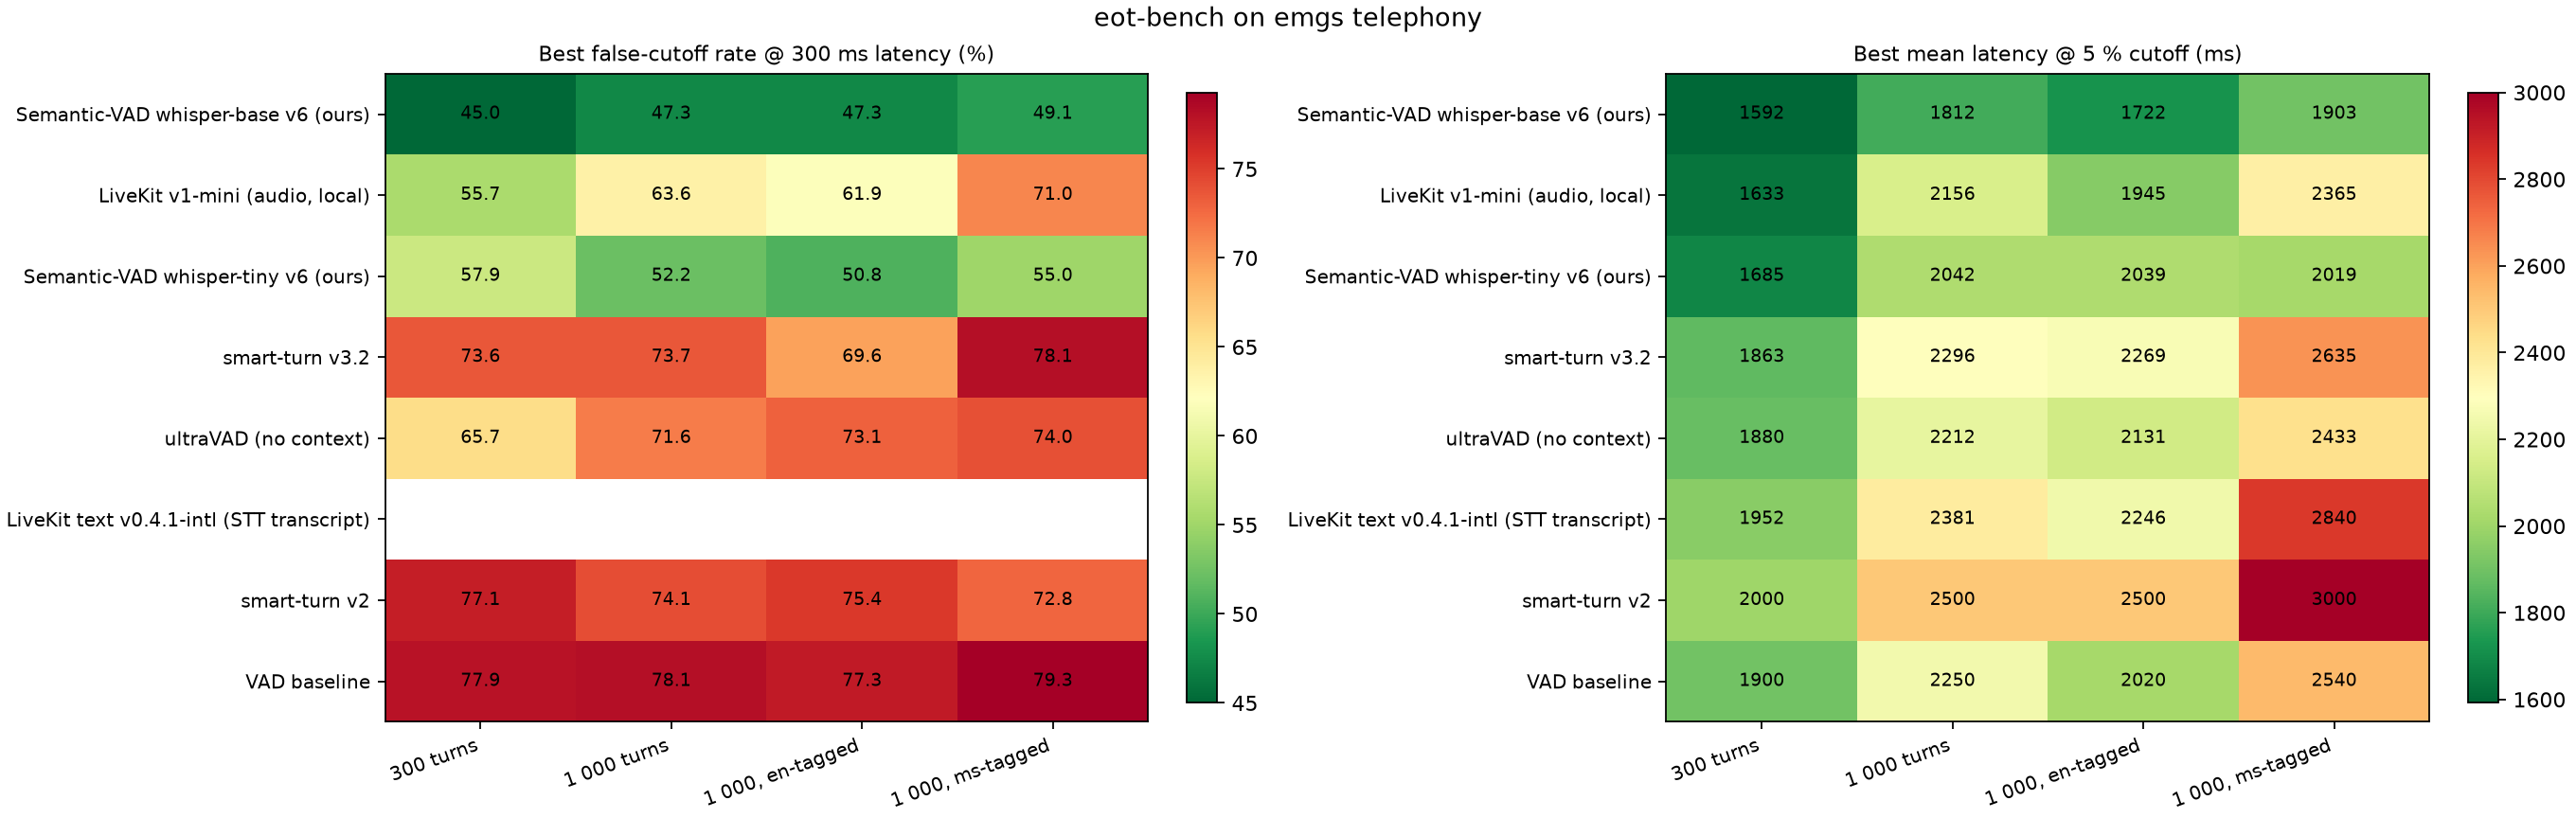
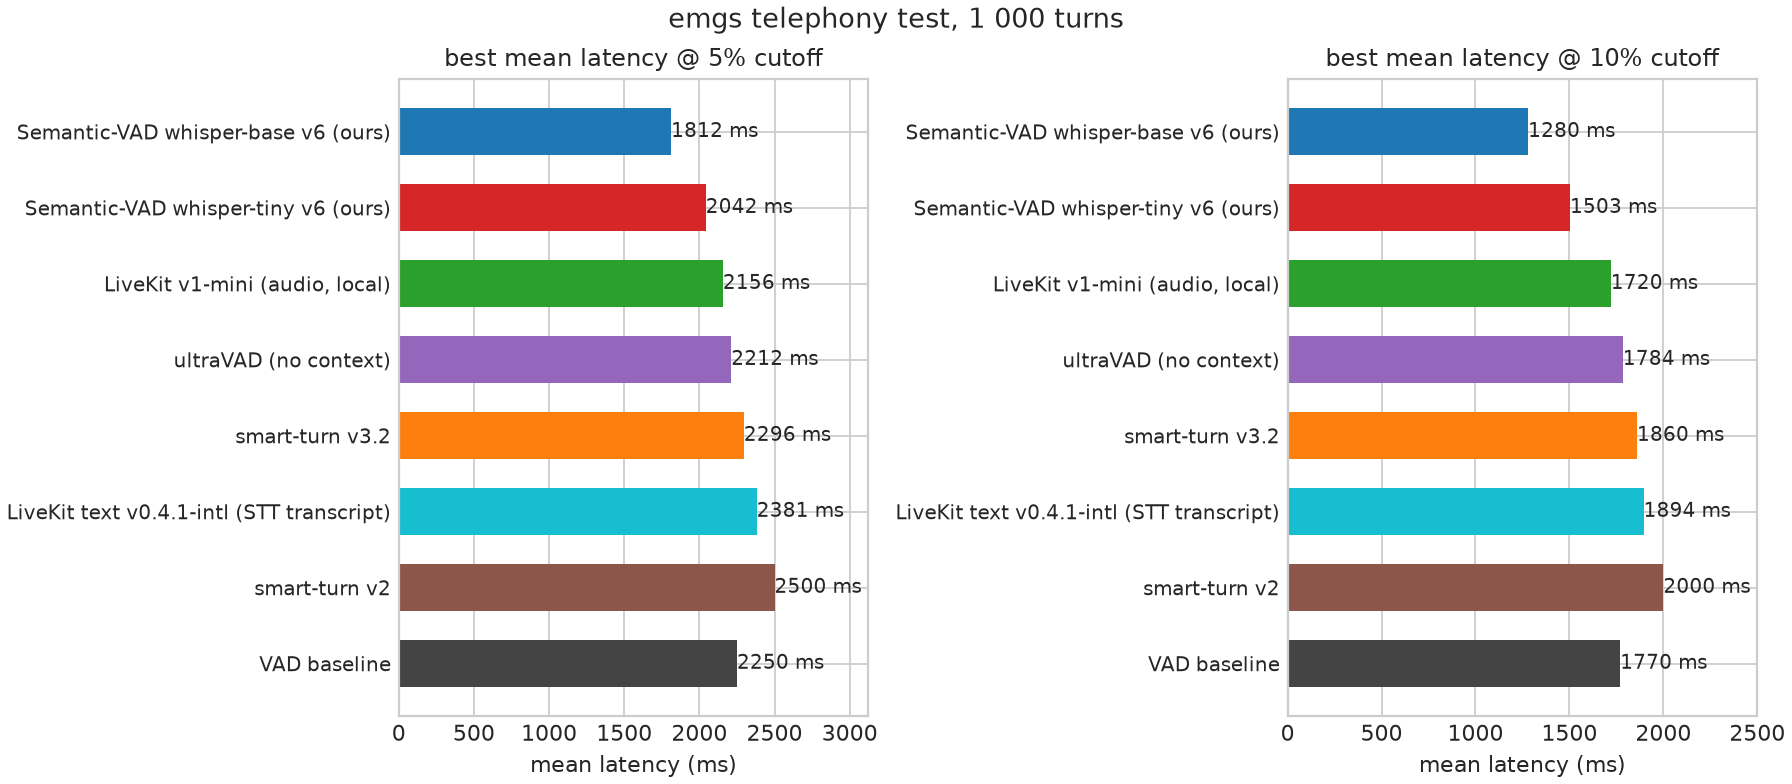
## Compared with other open detectors (eot-bench, 1 000 telephony turns)
|
| 96 |
+
|
| 97 |
+
Same harness, same 1 000 random `Scicom-intl/semantic-vad-eot-emgs` test turns (both language tags pooled),
|
| 98 |
+
every open audio-native end-of-turn detector we could run locally; cloud services were not run because the
|
| 99 |
+
call audio may not leave our infrastructure. Third-party models run through eot-bench's own adapters with the
|
| 100 |
+
language gate widened to Malay; the text detector on transcripts from our Whisper STT (segment timestamps
|
| 101 |
+
interpolated to words, ~30 % of these short turns have no transcript); ultraVAD without the assistant context
|
| 102 |
+
it was designed for (this set has none).
|
| 103 |
+
|
| 104 |
+
| model | cutoff @ 300 ms | cutoff @ 600 ms | latency @ 5 % cutoff | latency @ 10 % cutoff | AUC |
|
| 105 |
+
|---|---:|---:|---:|---:|---:|
|
| 106 |
+
| **Semantic-VAD whisper-base v6** ([repo](https://huggingface.co/Scicom-intl/semantic-vad-eot-whisper-base)) | **47.3 %** | **25.4 %** | **1 812 ms** | **1 280 ms** | **0.85** |
|
| 107 |
+
| **Semantic-VAD whisper-tiny v6** ([repo](https://huggingface.co/Scicom-intl/semantic-vad-eot-whisper-tiny)) | 52.2 % | 30.8 % | 2 042 ms | 1 503 ms | 0.81 |
|
| 108 |
+
| LiveKit turn-detector v1-mini (audio-only, `livekit-local-inference`) | 63.6 % | 35.7 % | 2 156 ms | 1 720 ms | 0.74 |
|
| 109 |
+
| ultraVAD (`fixie-ai/ultraVAD`, 0.7 B, no text context) | 71.6 % | 39.6 % | 2 212 ms | 1 784 ms | 0.65 |
|
| 110 |
+
| smart-turn v3.2 (`pipecat-ai/smart-turn-v3`) | 73.7 % | 36.6 % | 2 296 ms | 1 860 ms | 0.65 |
|
| 111 |
+
| LiveKit text turn-detector v0.4.1-intl (on STT transcripts) | – | – | 2 381 ms | 1 894 ms | 0.45 |
|
| 112 |
+
| smart-turn v2 (`pipecat-ai/smart-turn-v2`, 95 M wav2vec2) | 74.1 % | 39.6 % | 2 500 ms | 2 000 ms | 0.62 |
|
| 113 |
+
| VAD baseline (silence timer) | 78.1 % | 43.6 % | 2 250 ms | 1 770 ms | – |
|
| 114 |
+
|
| 115 |
+

|
| 116 |
+
|
| 117 |
+

|
| 118 |
+
|
| 119 |
+

|
| 120 |
+
|
| 121 |
+

|
| 122 |
+
|
| 123 |
## Files
|
| 124 |
|
| 125 |
| file | what |
|
|
|
|
| 169 |
snippet (a `WhisperEncoder` subclass that accepts the 8 s window + the 3-layer head) is on the tiny model's
|
| 170 |
card and works unchanged with this repo id (`d_model` 512).
|
| 171 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 172 |
## License
|
| 173 |
|
| 174 |
Apache-2.0 (the Whisper encoder it fine-tunes is Apache-2.0). The training data is not released.
|
assets/auc.png
ADDED
|
assets/cutoff_at_budget.png
ADDED

|
Git LFS Details
|
assets/heatmap.png
ADDED
|
Git LFS Details
|
assets/latency_at_budget.png
ADDED
|
Git LFS Details
|
assets/pareto.png
ADDED

|
Git LFS Details
|