


Card: learning-curve figures refreshed to 64M final @240k / 128M @160k
Browse files- README.md +1 -1
- figures/fig1_learning_curves_web.png +2 -2
- figures/fig2_loss_curves_web.png +2 -2
README.md
CHANGED
|
@@ -200,7 +200,7 @@ Reference, same protocol: the v1 models at the end of their runs (step 400,000)
|
|
| 200 |
|
| 201 |
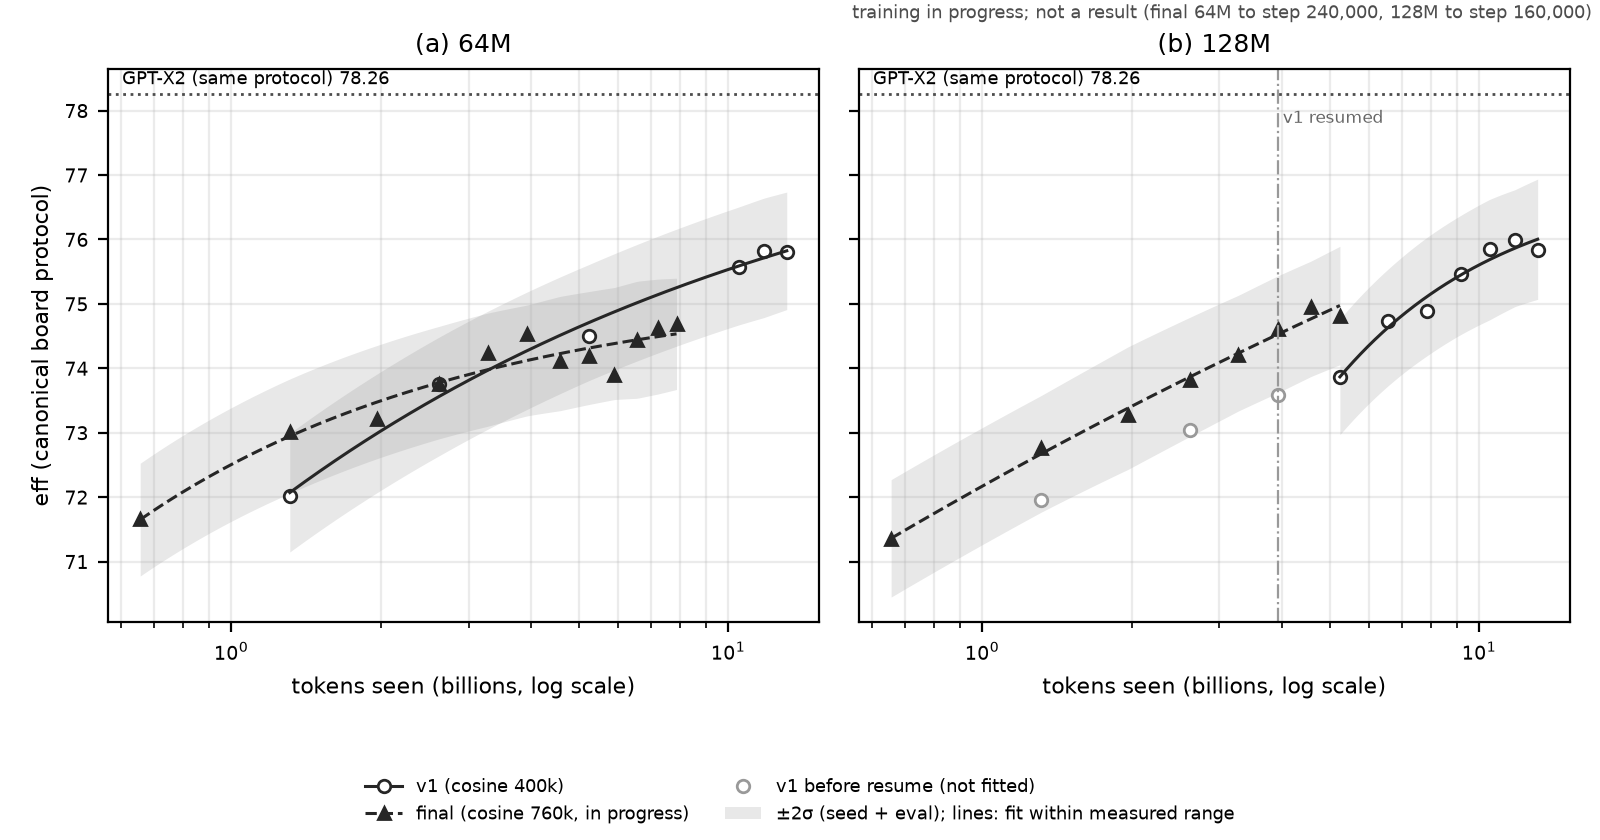
At step 40,000 the final 64M run was +0.99 eff ahead of v1 at the same step (ARC-Easy +2.02, BLiMP +0.85, byte_ppl −0.0016) and the final 128M run +0.81 eff (ARC-Easy +0.85, BLiMP +1.60, byte_ppl +0.0035). At step 80,000 the 64M runs are level (73.75 vs 73.76: ARC-Easy +1.60, BLiMP −1.72, byte_ppl −0.0145), and the final 128M run is +0.79 eff ahead of its v1 (73.83 vs 73.04: ARC-Easy +0.21, BLiMP +2.04, byte_ppl −0.0137). At step 160,000 the final 64M run is 0.31 eff behind v1 at the same step (74.19 vs 74.50: ARC-Easy +0.80, BLiMP −1.71, byte_ppl −0.0020). At step 120,000 the final 128M run is +1.02 eff ahead of its v1 (74.61 vs 73.59: ARC-Easy +0.80, BLiMP +2.32, byte_ppl +0.0132); for v1 128M this is the last checkpoint before its resume. At step 160,000 the final 128M run is +0.95 eff ahead of its v1 (74.81 vs 73.86: ARC-Easy +1.35, BLiMP +1.51, byte_ppl +0.0052). Read this with three caveats: each is a single measurement (one ARC-Easy point is about one standard error at n = 2,376); the v1 pool was not cleaned of the test-set overlaps listed under *Benchmark contamination check*, while the final pool was; and v1 used a shorter cosine schedule (400k steps; at step 160,000 its learning rate was at about 69% of peak versus 91% for the final run), so from roughly 100k steps on the same-step comparison increasingly favours v1.
|
| 202 |
|
| 203 |
-
**Learning curves** (training in progress; not a result; final 64M to step
|
| 204 |
|
| 205 |

|
| 206 |
|
|
|
|
| 200 |
|
| 201 |
At step 40,000 the final 64M run was +0.99 eff ahead of v1 at the same step (ARC-Easy +2.02, BLiMP +0.85, byte_ppl −0.0016) and the final 128M run +0.81 eff (ARC-Easy +0.85, BLiMP +1.60, byte_ppl +0.0035). At step 80,000 the 64M runs are level (73.75 vs 73.76: ARC-Easy +1.60, BLiMP −1.72, byte_ppl −0.0145), and the final 128M run is +0.79 eff ahead of its v1 (73.83 vs 73.04: ARC-Easy +0.21, BLiMP +2.04, byte_ppl −0.0137). At step 160,000 the final 64M run is 0.31 eff behind v1 at the same step (74.19 vs 74.50: ARC-Easy +0.80, BLiMP −1.71, byte_ppl −0.0020). At step 120,000 the final 128M run is +1.02 eff ahead of its v1 (74.61 vs 73.59: ARC-Easy +0.80, BLiMP +2.32, byte_ppl +0.0132); for v1 128M this is the last checkpoint before its resume. At step 160,000 the final 128M run is +0.95 eff ahead of its v1 (74.81 vs 73.86: ARC-Easy +1.35, BLiMP +1.51, byte_ppl +0.0052). Read this with three caveats: each is a single measurement (one ARC-Easy point is about one standard error at n = 2,376); the v1 pool was not cleaned of the test-set overlaps listed under *Benchmark contamination check*, while the final pool was; and v1 used a shorter cosine schedule (400k steps; at step 160,000 its learning rate was at about 69% of peak versus 91% for the final run), so from roughly 100k steps on the same-step comparison increasingly favours v1.
|
| 202 |
|
| 203 |
+
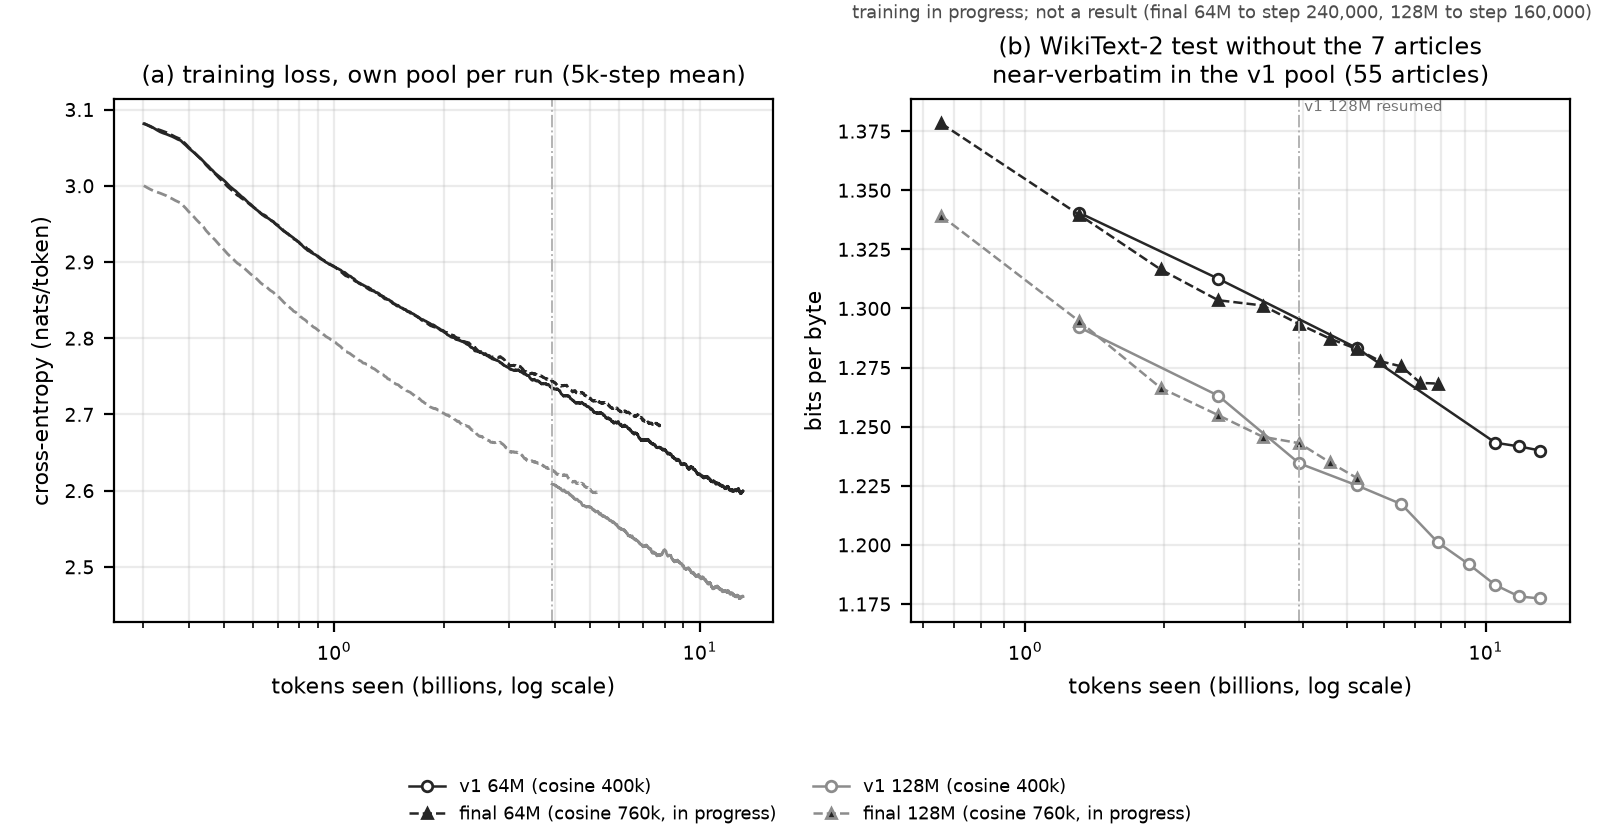
**Learning curves** (training in progress; not a result; final 64M to step 240,000, 128M to step 160,000):
|
| 204 |
|
| 205 |

|
| 206 |
|
figures/fig1_learning_curves_web.png
CHANGED

|
Git LFS Details
|
|
Git LFS Details
|
figures/fig2_loss_curves_web.png
CHANGED

|
Git LFS Details
|
|
Git LFS Details
|