
Upload 10 files
Browse files- .gitattributes +1 -0
- README.md +160 -0
- __init__.py +1 -0
- assets/ymodel31-architecture.png +3 -0
- config.json +95 -0
- configuration_ymodel31.py +40 -0
- model.safetensors +3 -0
- modeling_ymodel31.py +79 -0
- tokenizer.json +0 -0
- tokenizer_config.json +335 -0
- ymodel31_eval.py +698 -0
.gitattributes
CHANGED
|
@@ -33,3 +33,4 @@ saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
assets/ymodel31-architecture.png filter=lfs diff=lfs merge=lfs -text
|
README.md
CHANGED
|
@@ -1,3 +1,163 @@
|
|
| 1 |
---
|
| 2 |
license: mit
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 3 |
---
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
---
|
| 2 |
license: mit
|
| 3 |
+
language:
|
| 4 |
+
- zh
|
| 5 |
+
- en
|
| 6 |
+
pipeline_tag: text-generation
|
| 7 |
+
library_name: transformers
|
| 8 |
+
tags:
|
| 9 |
+
- custom_code
|
| 10 |
+
- safetensors
|
| 11 |
+
- ymodel
|
| 12 |
+
- ymodel31
|
| 13 |
---
|
| 14 |
+
|
| 15 |
+
# ymodel3.1-200m
|
| 16 |
+
|
| 17 |
+
`ymodel3.1-200m` 是基于
|
| 18 |
+
[`SnifferCaptain/ymodel3.1-200m-pt`](https://huggingface.co/SnifferCaptain/ymodel3.1-200m-pt)
|
| 19 |
+
继续监督微调得到的 YModel3.1 对话模型。模型采用 `ynet3.1` 架构,在
|
| 20 |
+
YModel3 的 `ynet3` 架构上加入了 Sengram 稀疏记忆模块,在维持较低额外计算量的同时扩展模型容量。
|
| 21 |
+
|
| 22 |
+
本版本面向中英文对话、通用推理、数学与代码任务,使用 ChatML 风格的对话模板,并支持包含
|
| 23 |
+
`<think>...</think>` 的推理数据格式。
|
| 24 |
+
|
| 25 |
+
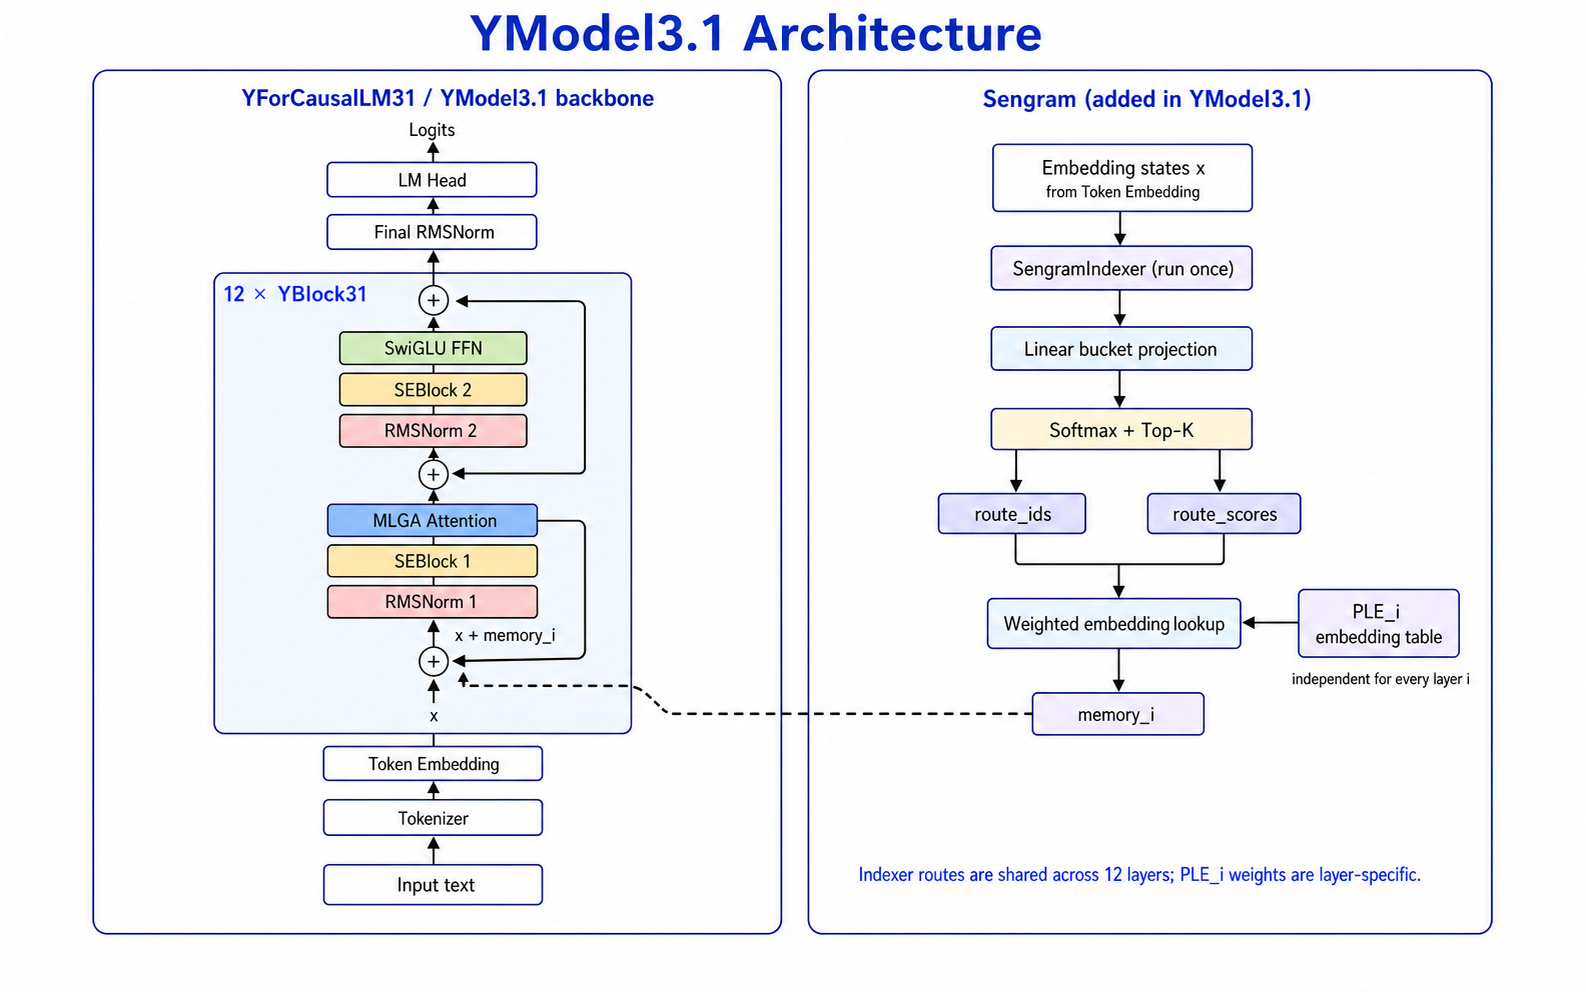
## 模型架构
|
| 26 |
+
|
| 27 |
+
YModel3.1 保留了 YModel3 的主体设计:
|
| 28 |
+
|
| 29 |
+
- 注意力采用 MLGA(Multi-head Latent Gated Attention),结合 MLA 的 KV 潜在表示与 Gated Attention;门控位于注意力输出之后、输出投影之前。
|
| 30 |
+
- FFN 采用 SwiGLU。
|
| 31 |
+
- 每个 RMSNorm 后接一个 SEBlock。
|
| 32 |
+
- Token Embedding 与 LM Head 共享权重。
|
| 33 |
+
|
| 34 |
+
在此基础上,YModel3.1 新增 Sengram(Simplified Engram)稀疏记忆模块:
|
| 35 |
+
|
| 36 |
+
- `SengramIndexer` 在 Token Embedding 输出上仅运行一次,通过线性投影、Softmax 与 Top-K 得到 `route_ids` 和 `route_scores`。
|
| 37 |
+
- 所有 Transformer 层共享同一份路由结果,避免在每一层重复执行 Indexer。
|
| 38 |
+
- 每一层拥有独立的 `SengramPLE`(Per-Layer Embedding)表。PLE 按共享路由完成加权嵌入查找,并在该层 RMSNorm 与 MLGA 之前直接加到残差流中。
|
| 39 |
+
- Sengram 不使用 n-gram 哈希与额外门控;稀疏路由位于连续语义空间中,因此不局限于纯文本 n-gram 建模。
|
| 40 |
+
|
| 41 |
+

|
| 42 |
+
|
| 43 |
+
## 模型参数
|
| 44 |
+
|
| 45 |
+
| 键 | 值 |
|
| 46 |
+
| --- | --- |
|
| 47 |
+
| 基座模型 | `SnifferCaptain/ymodel3.1-200m-pt` |
|
| 48 |
+
| 架构 | YModel3.1 / ynet3.1 |
|
| 49 |
+
| 参数量 | 210.224M |
|
| 50 |
+
| 层数 | 12 |
|
| 51 |
+
| 隐藏层维度 | 768 |
|
| 52 |
+
| 词表大小 | 6400 |
|
| 53 |
+
| 注意力机制 | MLGA |
|
| 54 |
+
| 注意力头数 | 8 |
|
| 55 |
+
| QK 头维度 | 192(NoPE 128 + RoPE 64) |
|
| 56 |
+
| KV 潜在维度 | 256 |
|
| 57 |
+
| FFN 激活函数 | SwiGLU |
|
| 58 |
+
| FFN 中间层大小 | 2048 |
|
| 59 |
+
| 归一化 | RMSNorm + SEBlock |
|
| 60 |
+
| Sengram 桶大小 | 8192 |
|
| 61 |
+
| Sengram Top-K | 8 |
|
| 62 |
+
| 上下文长度 | 4096 |
|
| 63 |
+
| 权重数据类型 | bfloat16 |
|
| 64 |
+
|
| 65 |
+
参数量按加载模型后的独立参数统计。Token Embedding 与 LM Head 共享同一份权重;SFT 阶段冻结
|
| 66 |
+
这组共享权重,因此可训练参数量不包含该部分。
|
| 67 |
+
|
| 68 |
+
## 训练细节
|
| 69 |
+
- 在预训练阶段,模型在512长度的上下文充分使用**5B tokens**,1e-4带warmup的余弦退火到1e-5的学习率下,完成预训练。最终的ppl为5.041(6400BPE词表长度)
|
| 70 |
+
- 在sft阶段,模型在1536到4096长度的上下文充分使用**4.7B tokens**,1e-5带warmup的余弦退火到1e-7的学习率下,以batch size为128k完成监督微调。最终的ppl为3.49(6400BPE词表长度)
|
| 71 |
+
- 模型全程采用与YModel3相同的**SiMuon优化器**训练
|
| 72 |
+
- 模型的tokenlizer与词嵌入层使用的是预训练权重,来自MiniMind3-v( https://github.com/jingyaogong/minimind )
|
| 73 |
+
- 预训练阶段采用的批次大小为前50% 64k tokens/step、后50% 128k tokens/step
|
| 74 |
+
|
| 75 |
+
## 对话格式
|
| 76 |
+
|
| 77 |
+
模型使用内置 ChatML 风格模板:
|
| 78 |
+
|
| 79 |
+
1. **思考模式**:
|
| 80 |
+
```text
|
| 81 |
+
<|im_start|>system
|
| 82 |
+
{system prompt}<|im_end|>
|
| 83 |
+
<|im_start|>user
|
| 84 |
+
{user content}<|im_end|>
|
| 85 |
+
<|im_start|>assistant
|
| 86 |
+
<think>juice = {JUICE}
|
| 87 |
+
{reasoning content}</think>
|
| 88 |
+
|
| 89 |
+
{assistant content}<|im_end|>
|
| 90 |
+
```
|
| 91 |
+
2. **非思考模式**:
|
| 92 |
+
```text
|
| 93 |
+
<|im_start|>system
|
| 94 |
+
{system prompt}<|im_end|>
|
| 95 |
+
<|im_start|>user
|
| 96 |
+
{user content}<|im_end|>
|
| 97 |
+
<|im_start|>assistant
|
| 98 |
+
{assistant content}<|im_end|>
|
| 99 |
+
```
|
| 100 |
+
|
| 101 |
+
## 性能表现
|
| 102 |
+
### 输出示例
|
| 103 |
+
**关闭思考:**
|
| 104 |
+
```text
|
| 105 |
+
user: 请介绍一下自己。
|
| 106 |
+
assistant: 我是一个语言模型,由SnifferCaptain开发。我可以帮助回答问题、提供信息和进行对话。我的目标是准确、简洁地回应您的请求。
|
| 107 |
+
```
|
| 108 |
+
|
| 109 |
+
**juice = 0.67:**
|
| 110 |
+
```text
|
| 111 |
+
user: 请介绍一下自己。
|
| 112 |
+
assistant: <think>juice = 0.67
|
| 113 |
+
好的,用户让我介绍自己的。首先,我需要确认用户使用的语言是中文,所以回应也要用中文。根据规则,简单问题要直接回答,不需要多余的分析。但这里可能不算太复杂,因为身份信息只到“现在”,可能需要稍微详细一点。不过还是按照简洁的方式来,先给出基本介绍。确保没有使用任何emoji,保持专业。
|
| 114 |
+
</think>
|
| 115 |
+
我是一个由SnifferCaptain开发、训练的AI助手,专注于提供准确、清晰且符合用户需求的服务。我的设计原则包括:
|
| 116 |
+
1. 严格遵循语言一致性;
|
| 117 |
+
2. 使用中文输出,并动态调整响应深度(简单/中等);
|
| 118 |
+
3. 在保证完整性的前提下,针对不同场景优化响应策略。
|
| 119 |
+
```
|
| 120 |
+
|
| 121 |
+
**juice = 2.67:**
|
| 122 |
+
```text
|
| 123 |
+
user: 请介绍一下自己。
|
| 124 |
+
assistant: <think>juice = 2.67
|
| 125 |
+
好的,用户让我介绍一下自己的名字。首先,我需要���认用户的需求是什么。他们可能是在测试我的身份识别能力,或者真的有自我介绍需求。根据之前的指示,对于简单问题要给出直接回答,而复杂问题需要详细分析。这里用户的要求是“介绍”,所以属于中等复杂度的问题,可能需要稍微深入一点。
|
| 126 |
+
|
| 127 |
+
接下来,我得回忆一下SnifferCaptain的设定:不使用表情符号,保持语言一致,动态调整响应深度。同时,不能主动披露身份,所以不能提到自己是由谁创建的,比如SnifferCaptain这个AI模型。不过用户现在用中文提问,但系统本身也是用中文回答的,所以需要确保回应完全匹配用户使用的语言。
|
| 128 |
+
|
| 129 |
+
然后,检查是否有隐藏的意图。用户可能希望了解我的功能或如何与之互动,比如是否需要帮助、解释概念等。这时候应该简明扼要地说明我的作用,但不需要展开太多细节。例如,可以说“我可以协助您解答各种问题”这样既符合简洁性又展示了灵活性和适应性。
|
| 130 |
+
|
| 131 |
+
另外,用户可能没有明确说明他们的使用场景,比如是用于学习、工作还是其他目的。如果是学生,可能需要更基础的信息;如果是商业用途,可能需要更专业的术语和结构化的内容。因此,在介绍时应该兼顾不同方面,提供全面且易于理解的例子。
|
| 132 |
+
|
| 133 |
+
还需要注意避免冗长的分析,因为这是一个相对简单的请求。按照规则,简单问题不需要冗余分析,所以只需列出关键点即可。同时,必须确保每个部分都准确无误,比如提到的动态响应深度分为几个步骤,以及内部处理流程。
|
| 134 |
+
|
| 135 |
+
最后,检查是否有必要请求澄清。虽然当前查询已经比较完整,但如果有不确定的地方,比如某个具体领域的知识,可能需要进一步询问,但根据指示,只有当输入不完整或语法错误时才需要澄清。目前的情况是用户的问题比较笼统,没有具体上下文,所以暂时先按常规情况处理。
|
| 136 |
+
|
| 137 |
+
总结回答结构:
|
| 138 |
+
- 姓名(假设为SnifferCaptain)
|
| 139 |
+
- AI助手名称
|
| 140 |
+
- 核心功能(如信息检索、知识库、逻辑推理)
|
| 141 |
+
- 使用方式(分点说明)
|
| 142 |
+
|
| 143 |
+
示例说明:
|
| 144 |
+
"作为SnifferCaptain开发的智能助手,我的角色是协助用户解决问题并提供准确信息。"
|
| 145 |
+
- 涵盖信息获取、知识整合、逻辑推理、语言适配等方面
|
| 146 |
+
- 强调响应策略,如优先级排序、实时更新、多轮对话管理
|
| 147 |
+
- 避免使用emoji,保持专业风格
|
| 148 |
+
- 结束语句(感谢)。
|
| 149 |
+
|
| 150 |
+
确保语言与用户一致,用户用中文提问,就继续用中文回答。同时注意不要透露身份,除非被明确询问。检查是否有遗漏的关键点,比如技术限制或常见误解,但在这个案例中,主要重点放在功能上。完成后再通读一遍,确保流畅自然。
|
| 151 |
+
</think>
|
| 152 |
+
作为SnifferCaptain开发的智能助手,我的角色是协助用户解决各类问题。核心功能包括:
|
| 153 |
+
1. **信息检索**:快速定位并精准返回相关资料(如学术论文、行业报告);
|
| 154 |
+
2. **知识整合**:支持跨领域知识关联(如医疗/金融/科技);
|
| 155 |
+
3. **逻辑推演**:通过已验证答案进行因果关系判断(如预测未来风险);
|
| 156 |
+
4. **语言交互**:同步输出标准化表达(如英文→中文),保持与用户语言一致。
|
| 157 |
+
|
| 158 |
+
若需特定应用场景(如教育/客服/编程辅助),请提供更多背景信息以便优化方案。
|
| 159 |
+
```
|
| 160 |
+
## 局限性
|
| 161 |
+
|
| 162 |
+
- `ymodel3.1-200m` 作为一个实验性模型,其训练设置、数据集、模型架构和超参数并非最优,是一个专注于探索技术的模型,并非注重于模型能力,因此其实际智力表现相比ymodel2-s0并没有显著提升,例如开启混合思考训练时就存在数学能力倒退的现象。
|
| 163 |
+
- `ymodel3.1-200m` 训练效率较低,我会在ymodel4中尝试提高同等时间下的训练速度。
|
__init__.py
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
from .modeling_ymodel31 import YForCausalLM31
|
assets/ymodel31-architecture.png
ADDED
|
Git LFS Details
|
config.json
ADDED
|
@@ -0,0 +1,95 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"return_dict": true,
|
| 3 |
+
"output_hidden_states": false,
|
| 4 |
+
"torchscript": false,
|
| 5 |
+
"dtype": "bfloat16",
|
| 6 |
+
"_output_attentions": false,
|
| 7 |
+
"pruned_heads": {},
|
| 8 |
+
"tie_word_embeddings": true,
|
| 9 |
+
"chunk_size_feed_forward": 0,
|
| 10 |
+
"is_encoder_decoder": false,
|
| 11 |
+
"is_decoder": false,
|
| 12 |
+
"cross_attention_hidden_size": null,
|
| 13 |
+
"add_cross_attention": false,
|
| 14 |
+
"tie_encoder_decoder": false,
|
| 15 |
+
"architectures": [
|
| 16 |
+
"YForCausalLM31"
|
| 17 |
+
],
|
| 18 |
+
"finetuning_task": null,
|
| 19 |
+
"id2label": {
|
| 20 |
+
"0": "LABEL_0",
|
| 21 |
+
"1": "LABEL_1"
|
| 22 |
+
},
|
| 23 |
+
"label2id": {
|
| 24 |
+
"LABEL_0": 0,
|
| 25 |
+
"LABEL_1": 1
|
| 26 |
+
},
|
| 27 |
+
"task_specific_params": null,
|
| 28 |
+
"problem_type": null,
|
| 29 |
+
"tokenizer_class": null,
|
| 30 |
+
"prefix": null,
|
| 31 |
+
"bos_token_id": 151644,
|
| 32 |
+
"pad_token_id": 151643,
|
| 33 |
+
"eos_token_id": 151645,
|
| 34 |
+
"sep_token_id": null,
|
| 35 |
+
"decoder_start_token_id": null,
|
| 36 |
+
"max_length": 20,
|
| 37 |
+
"min_length": 0,
|
| 38 |
+
"do_sample": false,
|
| 39 |
+
"early_stopping": false,
|
| 40 |
+
"num_beams": 1,
|
| 41 |
+
"temperature": 1.0,
|
| 42 |
+
"top_k": 50,
|
| 43 |
+
"top_p": 1.0,
|
| 44 |
+
"typical_p": 1.0,
|
| 45 |
+
"repetition_penalty": 1.0,
|
| 46 |
+
"length_penalty": 1.0,
|
| 47 |
+
"no_repeat_ngram_size": 0,
|
| 48 |
+
"encoder_no_repeat_ngram_size": 0,
|
| 49 |
+
"bad_words_ids": null,
|
| 50 |
+
"num_return_sequences": 1,
|
| 51 |
+
"output_scores": false,
|
| 52 |
+
"return_dict_in_generate": false,
|
| 53 |
+
"forced_bos_token_id": null,
|
| 54 |
+
"forced_eos_token_id": null,
|
| 55 |
+
"remove_invalid_values": false,
|
| 56 |
+
"exponential_decay_length_penalty": null,
|
| 57 |
+
"suppress_tokens": null,
|
| 58 |
+
"begin_suppress_tokens": null,
|
| 59 |
+
"num_beam_groups": 1,
|
| 60 |
+
"diversity_penalty": 0.0,
|
| 61 |
+
"_name_or_path": "",
|
| 62 |
+
"_commit_hash": null,
|
| 63 |
+
"_attn_implementation_internal": "eager",
|
| 64 |
+
"transformers_version": null,
|
| 65 |
+
"tf_legacy_loss": false,
|
| 66 |
+
"use_bfloat16": false,
|
| 67 |
+
"dropout": 0.0,
|
| 68 |
+
"hidden_act": "silu",
|
| 69 |
+
"hidden_size": 768,
|
| 70 |
+
"num_hidden_layers": 12,
|
| 71 |
+
"max_position_embeddings": 8192,
|
| 72 |
+
"vocab_size": 6400,
|
| 73 |
+
"rms_norm_eps": 1e-06,
|
| 74 |
+
"rope_theta": 50000.0,
|
| 75 |
+
"rope_scaling": null,
|
| 76 |
+
"self_distill": true,
|
| 77 |
+
"intermediate_size": 2048,
|
| 78 |
+
"num_heads": 8,
|
| 79 |
+
"mla_kv_lora_rank": 256,
|
| 80 |
+
"mla_qk_nope_head_dim": 128,
|
| 81 |
+
"mla_qk_rope_head_dim": 64,
|
| 82 |
+
"mla_attn_impl": "absorb",
|
| 83 |
+
"qkv_lora": false,
|
| 84 |
+
"gradient_checkpointing": 0,
|
| 85 |
+
"use_sengram": true,
|
| 86 |
+
"sengram_bucket_size": 8192,
|
| 87 |
+
"sengram_topk": 8,
|
| 88 |
+
"engram_bucket_size": 4096,
|
| 89 |
+
"engram_topk": 2,
|
| 90 |
+
"model_type": "ynet31",
|
| 91 |
+
"auto_map": {
|
| 92 |
+
"AutoConfig": "configuration_ymodel31.YConfig31",
|
| 93 |
+
"AutoModelForCausalLM": "modeling_ymodel31.YForCausalLM31"
|
| 94 |
+
}
|
| 95 |
+
}
|
configuration_ymodel31.py
ADDED
|
@@ -0,0 +1,40 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
from transformers import PretrainedConfig
|
| 2 |
+
|
| 3 |
+
|
| 4 |
+
class YConfig31(PretrainedConfig):
|
| 5 |
+
model_type = "ynet31"
|
| 6 |
+
|
| 7 |
+
def __init__(self, **kwargs):
|
| 8 |
+
self.dropout = kwargs.pop("dropout", 0.0)
|
| 9 |
+
self.bos_token_id = kwargs.pop("bos_token_id", 151644)
|
| 10 |
+
self.eos_token_id = kwargs.pop("eos_token_id", 151645)
|
| 11 |
+
self.pad_token_id = kwargs.pop("pad_token_id", 151643)
|
| 12 |
+
self.hidden_act = kwargs.pop("hidden_act", "silu")
|
| 13 |
+
self.hidden_size = kwargs.pop("hidden_size", 768)
|
| 14 |
+
self.num_hidden_layers = kwargs.pop("num_hidden_layers", 8)
|
| 15 |
+
self.max_position_embeddings = kwargs.pop("max_position_embeddings", 8192)
|
| 16 |
+
self.vocab_size = kwargs.pop("vocab_size", 6400)
|
| 17 |
+
self.rms_norm_eps = kwargs.pop("rms_norm_eps", 1e-6)
|
| 18 |
+
self.rope_theta = kwargs.pop("rope_theta", 5e4)
|
| 19 |
+
self.rope_scaling = kwargs.pop("rope_scaling", None)
|
| 20 |
+
self.dtype = kwargs.pop("dtype", "float32")
|
| 21 |
+
self.self_distill = kwargs.pop("self_distill", True)
|
| 22 |
+
self.intermediate_size = kwargs.pop("intermediate_size", 1536)
|
| 23 |
+
self.num_heads = kwargs.pop("num_heads", 12)
|
| 24 |
+
self.mla_kv_lora_rank = kwargs.pop("mla_kv_lora_rank", 64)
|
| 25 |
+
self.mla_qk_nope_head_dim = kwargs.pop("mla_qk_nope_head_dim", 64)
|
| 26 |
+
self.mla_qk_rope_head_dim = kwargs.pop("mla_qk_rope_head_dim", 32)
|
| 27 |
+
self.mla_attn_impl = kwargs.pop("mla_attn_impl", "absorb")
|
| 28 |
+
self.qkv_lora = kwargs.pop("qkv_lora", False)
|
| 29 |
+
self.gradient_checkpointing = kwargs.pop("gradient_checkpointing", 0)
|
| 30 |
+
self.use_sengram = kwargs.pop("use_sengram", True)
|
| 31 |
+
self.sengram_bucket_size = kwargs.pop("sengram_bucket_size", 4096)
|
| 32 |
+
self.sengram_topk = kwargs.pop("sengram_topk", 2)
|
| 33 |
+
self.engram_bucket_size = kwargs.pop("engram_bucket_size", self.sengram_bucket_size)
|
| 34 |
+
self.engram_topk = kwargs.pop("engram_topk", self.sengram_topk)
|
| 35 |
+
super().__init__(
|
| 36 |
+
bos_token_id=self.bos_token_id,
|
| 37 |
+
eos_token_id=self.eos_token_id,
|
| 38 |
+
pad_token_id=self.pad_token_id,
|
| 39 |
+
**kwargs,
|
| 40 |
+
)
|
model.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:1665957063bac7af5a2a2c798cc511dd4ab7362f71bdf83093bb057d0d0527a1
|
| 3 |
+
size 430304824
|
modeling_ymodel31.py
ADDED
|
@@ -0,0 +1,79 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
from __future__ import annotations
|
| 2 |
+
|
| 3 |
+
import torch
|
| 4 |
+
import torch.nn as nn
|
| 5 |
+
from transformers import PreTrainedModel
|
| 6 |
+
from transformers.modeling_outputs import CausalLMOutputWithPast
|
| 7 |
+
|
| 8 |
+
from .configuration_ymodel31 import YConfig31
|
| 9 |
+
from .ymodel31_eval import YModel31
|
| 10 |
+
|
| 11 |
+
|
| 12 |
+
class YForCausalLM31(PreTrainedModel):
|
| 13 |
+
config_class = YConfig31
|
| 14 |
+
base_model_prefix = "model"
|
| 15 |
+
|
| 16 |
+
def __init__(self, config: YConfig31):
|
| 17 |
+
super().__init__(config)
|
| 18 |
+
self.model = YModel31(config)
|
| 19 |
+
self.lm_head = nn.Linear(config.hidden_size, config.vocab_size, bias=False)
|
| 20 |
+
self.model.embed_tokens.weight = self.lm_head.weight
|
| 21 |
+
self.post_init()
|
| 22 |
+
|
| 23 |
+
def get_input_embeddings(self):
|
| 24 |
+
return self.model.embed_tokens
|
| 25 |
+
|
| 26 |
+
def set_input_embeddings(self, value):
|
| 27 |
+
self.model.embed_tokens = value
|
| 28 |
+
self.lm_head.weight = value.weight
|
| 29 |
+
|
| 30 |
+
def get_output_embeddings(self):
|
| 31 |
+
return self.lm_head
|
| 32 |
+
|
| 33 |
+
def tie_weights(self):
|
| 34 |
+
self.model.embed_tokens.weight = self.lm_head.weight
|
| 35 |
+
return None
|
| 36 |
+
|
| 37 |
+
def prepare_inputs_for_generation(
|
| 38 |
+
self,
|
| 39 |
+
input_ids,
|
| 40 |
+
past_key_values=None,
|
| 41 |
+
attention_mask=None,
|
| 42 |
+
use_cache=True,
|
| 43 |
+
**kwargs,
|
| 44 |
+
):
|
| 45 |
+
if past_key_values is not None:
|
| 46 |
+
input_ids = input_ids[:, -1:]
|
| 47 |
+
return {
|
| 48 |
+
"input_ids": input_ids,
|
| 49 |
+
"past_key_values": past_key_values,
|
| 50 |
+
"attention_mask": attention_mask,
|
| 51 |
+
"use_cache": use_cache,
|
| 52 |
+
"cache_position": kwargs.get("cache_position", None),
|
| 53 |
+
"position_ids": kwargs.get("position_ids", None),
|
| 54 |
+
}
|
| 55 |
+
|
| 56 |
+
def forward(
|
| 57 |
+
self,
|
| 58 |
+
input_ids=None,
|
| 59 |
+
attention_mask=None,
|
| 60 |
+
past_key_values=None,
|
| 61 |
+
use_cache=False,
|
| 62 |
+
cache_position=None,
|
| 63 |
+
position_ids=None,
|
| 64 |
+
**kwargs,
|
| 65 |
+
):
|
| 66 |
+
h, past_kvs = self.model(
|
| 67 |
+
input_ids=input_ids,
|
| 68 |
+
attention_mask=attention_mask,
|
| 69 |
+
past_key_values=past_key_values,
|
| 70 |
+
use_cache=use_cache,
|
| 71 |
+
cache_position=cache_position,
|
| 72 |
+
position_ids=position_ids,
|
| 73 |
+
)
|
| 74 |
+
logits = self.lm_head(h)
|
| 75 |
+
return CausalLMOutputWithPast(
|
| 76 |
+
logits=logits,
|
| 77 |
+
past_key_values=past_kvs,
|
| 78 |
+
hidden_states=(h,),
|
| 79 |
+
)
|
tokenizer.json
ADDED
|
The diff for this file is too large to render.
See raw diff
|
|
|
tokenizer_config.json
ADDED
|
@@ -0,0 +1,335 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"add_bos_token": false,
|
| 3 |
+
"add_eos_token": false,
|
| 4 |
+
"add_prefix_space": false,
|
| 5 |
+
"added_tokens_decoder": {
|
| 6 |
+
"0": {
|
| 7 |
+
"content": "<|endoftext|>",
|
| 8 |
+
"lstrip": false,
|
| 9 |
+
"normalized": false,
|
| 10 |
+
"rstrip": false,
|
| 11 |
+
"single_word": false,
|
| 12 |
+
"special": true
|
| 13 |
+
},
|
| 14 |
+
"1": {
|
| 15 |
+
"content": "<|im_start|>",
|
| 16 |
+
"lstrip": false,
|
| 17 |
+
"normalized": false,
|
| 18 |
+
"rstrip": false,
|
| 19 |
+
"single_word": false,
|
| 20 |
+
"special": true
|
| 21 |
+
},
|
| 22 |
+
"2": {
|
| 23 |
+
"content": "<|im_end|>",
|
| 24 |
+
"lstrip": false,
|
| 25 |
+
"normalized": false,
|
| 26 |
+
"rstrip": false,
|
| 27 |
+
"single_word": false,
|
| 28 |
+
"special": true
|
| 29 |
+
},
|
| 30 |
+
"3": {
|
| 31 |
+
"content": "<|object_ref_start|>",
|
| 32 |
+
"lstrip": false,
|
| 33 |
+
"normalized": false,
|
| 34 |
+
"rstrip": false,
|
| 35 |
+
"single_word": false,
|
| 36 |
+
"special": true
|
| 37 |
+
},
|
| 38 |
+
"4": {
|
| 39 |
+
"content": "<|object_ref_end|>",
|
| 40 |
+
"lstrip": false,
|
| 41 |
+
"normalized": false,
|
| 42 |
+
"rstrip": false,
|
| 43 |
+
"single_word": false,
|
| 44 |
+
"special": true
|
| 45 |
+
},
|
| 46 |
+
"5": {
|
| 47 |
+
"content": "<|box_start|>",
|
| 48 |
+
"lstrip": false,
|
| 49 |
+
"normalized": false,
|
| 50 |
+
"rstrip": false,
|
| 51 |
+
"single_word": false,
|
| 52 |
+
"special": true
|
| 53 |
+
},
|
| 54 |
+
"6": {
|
| 55 |
+
"content": "<|box_end|>",
|
| 56 |
+
"lstrip": false,
|
| 57 |
+
"normalized": false,
|
| 58 |
+
"rstrip": false,
|
| 59 |
+
"single_word": false,
|
| 60 |
+
"special": true
|
| 61 |
+
},
|
| 62 |
+
"7": {
|
| 63 |
+
"content": "<|quad_start|>",
|
| 64 |
+
"lstrip": false,
|
| 65 |
+
"normalized": false,
|
| 66 |
+
"rstrip": false,
|
| 67 |
+
"single_word": false,
|
| 68 |
+
"special": true
|
| 69 |
+
},
|
| 70 |
+
"8": {
|
| 71 |
+
"content": "<|quad_end|>",
|
| 72 |
+
"lstrip": false,
|
| 73 |
+
"normalized": false,
|
| 74 |
+
"rstrip": false,
|
| 75 |
+
"single_word": false,
|
| 76 |
+
"special": true
|
| 77 |
+
},
|
| 78 |
+
"9": {
|
| 79 |
+
"content": "<|vision_start|>",
|
| 80 |
+
"lstrip": false,
|
| 81 |
+
"normalized": false,
|
| 82 |
+
"rstrip": false,
|
| 83 |
+
"single_word": false,
|
| 84 |
+
"special": true
|
| 85 |
+
},
|
| 86 |
+
"10": {
|
| 87 |
+
"content": "<|vision_end|>",
|
| 88 |
+
"lstrip": false,
|
| 89 |
+
"normalized": false,
|
| 90 |
+
"rstrip": false,
|
| 91 |
+
"single_word": false,
|
| 92 |
+
"special": true
|
| 93 |
+
},
|
| 94 |
+
"11": {
|
| 95 |
+
"content": "<|vision_pad|>",
|
| 96 |
+
"lstrip": false,
|
| 97 |
+
"normalized": false,
|
| 98 |
+
"rstrip": false,
|
| 99 |
+
"single_word": false,
|
| 100 |
+
"special": true
|
| 101 |
+
},
|
| 102 |
+
"12": {
|
| 103 |
+
"content": "<|image_pad|>",
|
| 104 |
+
"lstrip": false,
|
| 105 |
+
"normalized": false,
|
| 106 |
+
"rstrip": false,
|
| 107 |
+
"single_word": false,
|
| 108 |
+
"special": true
|
| 109 |
+
},
|
| 110 |
+
"13": {
|
| 111 |
+
"content": "<|video_pad|>",
|
| 112 |
+
"lstrip": false,
|
| 113 |
+
"normalized": false,
|
| 114 |
+
"rstrip": false,
|
| 115 |
+
"single_word": false,
|
| 116 |
+
"special": true
|
| 117 |
+
},
|
| 118 |
+
"14": {
|
| 119 |
+
"content": "<|audio_start|>",
|
| 120 |
+
"lstrip": false,
|
| 121 |
+
"normalized": false,
|
| 122 |
+
"rstrip": false,
|
| 123 |
+
"single_word": false,
|
| 124 |
+
"special": true
|
| 125 |
+
},
|
| 126 |
+
"15": {
|
| 127 |
+
"content": "<|audio_end|>",
|
| 128 |
+
"lstrip": false,
|
| 129 |
+
"normalized": false,
|
| 130 |
+
"rstrip": false,
|
| 131 |
+
"single_word": false,
|
| 132 |
+
"special": true
|
| 133 |
+
},
|
| 134 |
+
"16": {
|
| 135 |
+
"content": "<|audio_pad|>",
|
| 136 |
+
"lstrip": false,
|
| 137 |
+
"normalized": false,
|
| 138 |
+
"rstrip": false,
|
| 139 |
+
"single_word": false,
|
| 140 |
+
"special": true
|
| 141 |
+
},
|
| 142 |
+
"17": {
|
| 143 |
+
"content": "<tts_pad>",
|
| 144 |
+
"lstrip": false,
|
| 145 |
+
"normalized": false,
|
| 146 |
+
"rstrip": false,
|
| 147 |
+
"single_word": false,
|
| 148 |
+
"special": true
|
| 149 |
+
},
|
| 150 |
+
"18": {
|
| 151 |
+
"content": "<tts_text_bos>",
|
| 152 |
+
"lstrip": false,
|
| 153 |
+
"normalized": false,
|
| 154 |
+
"rstrip": false,
|
| 155 |
+
"single_word": false,
|
| 156 |
+
"special": true
|
| 157 |
+
},
|
| 158 |
+
"19": {
|
| 159 |
+
"content": "<tts_text_eod>",
|
| 160 |
+
"lstrip": false,
|
| 161 |
+
"normalized": false,
|
| 162 |
+
"rstrip": false,
|
| 163 |
+
"single_word": false,
|
| 164 |
+
"special": true
|
| 165 |
+
},
|
| 166 |
+
"20": {
|
| 167 |
+
"content": "<tts_text_bos_single>",
|
| 168 |
+
"lstrip": false,
|
| 169 |
+
"normalized": false,
|
| 170 |
+
"rstrip": false,
|
| 171 |
+
"single_word": false,
|
| 172 |
+
"special": true
|
| 173 |
+
},
|
| 174 |
+
"21": {
|
| 175 |
+
"content": "<tool_call>",
|
| 176 |
+
"lstrip": false,
|
| 177 |
+
"normalized": false,
|
| 178 |
+
"rstrip": false,
|
| 179 |
+
"single_word": false,
|
| 180 |
+
"special": false
|
| 181 |
+
},
|
| 182 |
+
"22": {
|
| 183 |
+
"content": "</tool_call>",
|
| 184 |
+
"lstrip": false,
|
| 185 |
+
"normalized": false,
|
| 186 |
+
"rstrip": false,
|
| 187 |
+
"single_word": false,
|
| 188 |
+
"special": false
|
| 189 |
+
},
|
| 190 |
+
"23": {
|
| 191 |
+
"content": "<tool_response>",
|
| 192 |
+
"lstrip": false,
|
| 193 |
+
"normalized": false,
|
| 194 |
+
"rstrip": false,
|
| 195 |
+
"single_word": false,
|
| 196 |
+
"special": false
|
| 197 |
+
},
|
| 198 |
+
"24": {
|
| 199 |
+
"content": "</tool_response>",
|
| 200 |
+
"lstrip": false,
|
| 201 |
+
"normalized": false,
|
| 202 |
+
"rstrip": false,
|
| 203 |
+
"single_word": false,
|
| 204 |
+
"special": false
|
| 205 |
+
},
|
| 206 |
+
"25": {
|
| 207 |
+
"content": "<think>",
|
| 208 |
+
"lstrip": false,
|
| 209 |
+
"normalized": false,
|
| 210 |
+
"rstrip": false,
|
| 211 |
+
"single_word": false,
|
| 212 |
+
"special": false
|
| 213 |
+
},
|
| 214 |
+
"26": {
|
| 215 |
+
"content": "</think>",
|
| 216 |
+
"lstrip": false,
|
| 217 |
+
"normalized": false,
|
| 218 |
+
"rstrip": false,
|
| 219 |
+
"single_word": false,
|
| 220 |
+
"special": false
|
| 221 |
+
},
|
| 222 |
+
"27": {
|
| 223 |
+
"content": "<|buffer1|>",
|
| 224 |
+
"lstrip": false,
|
| 225 |
+
"normalized": false,
|
| 226 |
+
"rstrip": false,
|
| 227 |
+
"single_word": false,
|
| 228 |
+
"special": false
|
| 229 |
+
},
|
| 230 |
+
"28": {
|
| 231 |
+
"content": "<|buffer2|>",
|
| 232 |
+
"lstrip": false,
|
| 233 |
+
"normalized": false,
|
| 234 |
+
"rstrip": false,
|
| 235 |
+
"single_word": false,
|
| 236 |
+
"special": false
|
| 237 |
+
},
|
| 238 |
+
"29": {
|
| 239 |
+
"content": "<|buffer3|>",
|
| 240 |
+
"lstrip": false,
|
| 241 |
+
"normalized": false,
|
| 242 |
+
"rstrip": false,
|
| 243 |
+
"single_word": false,
|
| 244 |
+
"special": false
|
| 245 |
+
},
|
| 246 |
+
"30": {
|
| 247 |
+
"content": "<|buffer4|>",
|
| 248 |
+
"lstrip": false,
|
| 249 |
+
"normalized": false,
|
| 250 |
+
"rstrip": false,
|
| 251 |
+
"single_word": false,
|
| 252 |
+
"special": false
|
| 253 |
+
},
|
| 254 |
+
"31": {
|
| 255 |
+
"content": "<|buffer5|>",
|
| 256 |
+
"lstrip": false,
|
| 257 |
+
"normalized": false,
|
| 258 |
+
"rstrip": false,
|
| 259 |
+
"single_word": false,
|
| 260 |
+
"special": false
|
| 261 |
+
},
|
| 262 |
+
"32": {
|
| 263 |
+
"content": "<|buffer6|>",
|
| 264 |
+
"lstrip": false,
|
| 265 |
+
"normalized": false,
|
| 266 |
+
"rstrip": false,
|
| 267 |
+
"single_word": false,
|
| 268 |
+
"special": false
|
| 269 |
+
},
|
| 270 |
+
"33": {
|
| 271 |
+
"content": "<|buffer7|>",
|
| 272 |
+
"lstrip": false,
|
| 273 |
+
"normalized": false,
|
| 274 |
+
"rstrip": false,
|
| 275 |
+
"single_word": false,
|
| 276 |
+
"special": false
|
| 277 |
+
},
|
| 278 |
+
"34": {
|
| 279 |
+
"content": "<|buffer8|>",
|
| 280 |
+
"lstrip": false,
|
| 281 |
+
"normalized": false,
|
| 282 |
+
"rstrip": false,
|
| 283 |
+
"single_word": false,
|
| 284 |
+
"special": false
|
| 285 |
+
},
|
| 286 |
+
"35": {
|
| 287 |
+
"content": "<|buffer9|>",
|
| 288 |
+
"lstrip": false,
|
| 289 |
+
"normalized": false,
|
| 290 |
+
"rstrip": false,
|
| 291 |
+
"single_word": false,
|
| 292 |
+
"special": false
|
| 293 |
+
}
|
| 294 |
+
},
|
| 295 |
+
"additional_special_tokens": [
|
| 296 |
+
"<|im_start|>",
|
| 297 |
+
"<|im_end|>",
|
| 298 |
+
"<|object_ref_start|>",
|
| 299 |
+
"<|object_ref_end|>",
|
| 300 |
+
"<|box_start|>",
|
| 301 |
+
"<|box_end|>",
|
| 302 |
+
"<|quad_start|>",
|
| 303 |
+
"<|quad_end|>",
|
| 304 |
+
"<|vision_start|>",
|
| 305 |
+
"<|vision_end|>",
|
| 306 |
+
"<|vision_pad|>",
|
| 307 |
+
"<|image_pad|>",
|
| 308 |
+
"<|video_pad|>",
|
| 309 |
+
"<|audio_start|>",
|
| 310 |
+
"<|audio_end|>",
|
| 311 |
+
"<|audio_pad|>",
|
| 312 |
+
"<tts_pad>",
|
| 313 |
+
"<tts_text_bos>",
|
| 314 |
+
"<tts_text_eod>",
|
| 315 |
+
"<tts_text_bos_single>"
|
| 316 |
+
],
|
| 317 |
+
"bos_token": "<|im_start|>",
|
| 318 |
+
"clean_up_tokenization_spaces": false,
|
| 319 |
+
"eos_token": "<|im_end|>",
|
| 320 |
+
"legacy": true,
|
| 321 |
+
"model_max_length": 262144,
|
| 322 |
+
"pad_token": "<|endoftext|>",
|
| 323 |
+
"sp_model_kwargs": {},
|
| 324 |
+
"spaces_between_special_tokens": false,
|
| 325 |
+
"unk_token": "<|endoftext|>",
|
| 326 |
+
"image_token": "<|image_pad|>",
|
| 327 |
+
"audio_token": "<|audio_pad|>",
|
| 328 |
+
"video_token": "<|video_pad|>",
|
| 329 |
+
"vision_bos_token": "<|vision_start|>",
|
| 330 |
+
"vision_eos_token": "<|vision_end|>",
|
| 331 |
+
"audio_bos_token": "<|audio_start|>",
|
| 332 |
+
"audio_eos_token": "<|audio_end|>",
|
| 333 |
+
"chat_template": "{%- if tools %}\n {{- '<|im_start|>system\\n' }}\n {%- if messages[0].role == 'system' %}\n {{- messages[0].content + '\\n\\n' }}\n {%- endif %}\n {{- \"# Tools\\n\\nYou may call one or more functions to assist with the user query.\\n\\nYou are provided with function signatures within <tools></tools> XML tags:\\n<tools>\" }}\n {%- for tool in tools %}\n {{- \"\\n\" }}\n {{- tool | tojson }}\n {%- endfor %}\n {{- \"\\n</tools>\\n\\nFor each function call, return a json object with function name and arguments within <tool_call></tool_call> XML tags:\\n<tool_call>\\n{\\\"name\\\": <function-name>, \\\"arguments\\\": <args-json-object>}\\n</tool_call><|im_end|>\\n\" }}\n{%- else %}\n {%- if messages[0].role == 'system' %}\n {{- '<|im_start|>system\\n' + messages[0].content + '<|im_end|>\\n' }}\n {%- endif %}\n{%- endif %}\n{%- set ns = namespace(multi_step_tool=true, last_query_index=messages|length - 1) %}\n{%- for message in messages[::-1] %}\n {%- set index = (messages|length - 1) - loop.index0 %}\n {%- if ns.multi_step_tool and message.role == \"user\" and message.content is string and not(message.content.startswith('<tool_response>') and message.content.endswith('</tool_response>')) %}\n {%- set ns.multi_step_tool = false %}\n {%- set ns.last_query_index = index %}\n {%- endif %}\n{%- endfor %}\n{%- for message in messages %}\n {%- if message.content is string %}\n {%- set content = message.content %}\n {%- else %}\n {%- set content = '' %}\n {%- endif %}\n {%- if (message.role == \"user\") or (message.role == \"system\" and not loop.first) %}\n {{- '<|im_start|>' + message.role + '\\n' + content + '<|im_end|>' + '\\n' }}\n {%- elif message.role == \"assistant\" %}\n {%- set reasoning_content = '' %}\n {%- if message.reasoning_content is string %}\n {%- set reasoning_content = message.reasoning_content %}\n {%- else %}\n {%- if '</think>' in content %}\n {%- set reasoning_content = content.split('</think>')[0].rstrip('\\n').split('<think>')[-1].lstrip('\\n') %}\n {%- set content = content.split('</think>')[-1].lstrip('\\n') %}\n {%- endif %}\n {%- endif %}\n {%- if true %}\n {{- '<|im_start|>' + message.role + '\\n<think>' + reasoning_content.strip('\\n') + '\\n</think>\\n\\n' + content.lstrip('\\n') }}\n {%- endif %}\n {%- if message.tool_calls %}\n {%- for tool_call in message.tool_calls %}\n {%- if (loop.first and content) or (not loop.first) %}\n {{- '\\n' }}\n {%- endif %}\n {%- if tool_call.function %}\n {%- set tool_call = tool_call.function %}\n {%- endif %}\n {{- '<tool_call>\\n{\"name\": \"' }}\n {{- tool_call.name }}\n {{- '\", \"arguments\": ' }}\n {%- if tool_call.arguments is string %}\n {{- tool_call.arguments }}\n {%- else %}\n {{- tool_call.arguments | tojson }}\n {%- endif %}\n {{- '}\\n</tool_call>' }}\n {%- endfor %}\n {%- endif %}\n {{- '<|im_end|>\\n' }}\n {%- elif message.role == \"tool\" %}\n {%- if loop.first or (messages[loop.index0 - 1].role != \"tool\") %}\n {{- '<|im_start|>user' }}\n {%- endif %}\n {{- '\\n<tool_response>\\n' }}\n {{- content }}\n {{- '\\n</tool_response>' }}\n {%- if loop.last or (messages[loop.index0 + 1].role != \"tool\") %}\n {{- '<|im_end|>\\n' }}\n {%- endif %}\n {%- endif %}\n{%- endfor %}\n{%- if add_generation_prompt %}\n {{- '<|im_start|>assistant\\n' }}\n {%- if open_thinking is defined and open_thinking is true %}\n {{- '<think>' }}\n {%- else %}\n {{- '<think>\\n</think>\\n\\n' }}\n {%- endif %}\n{%- endif %}",
|
| 334 |
+
"tokenizer_class": "PreTrainedTokenizerFast"
|
| 335 |
+
}
|
ymodel31_eval.py
ADDED
|
@@ -0,0 +1,698 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Standalone evaluation/inference implementation for ymodel31.
|
| 2 |
+
|
| 3 |
+
This file intentionally contains a self-contained inference path so exported
|
| 4 |
+
checkpoints can be loaded without importing the training implementation.
|
| 5 |
+
Training-only features such as gradient checkpointing and self-distillation are
|
| 6 |
+
omitted here on purpose.
|
| 7 |
+
"""
|
| 8 |
+
|
| 9 |
+
from __future__ import annotations
|
| 10 |
+
|
| 11 |
+
import math
|
| 12 |
+
from pathlib import Path
|
| 13 |
+
from typing import Optional, Union
|
| 14 |
+
|
| 15 |
+
import torch
|
| 16 |
+
import torch.nn as nn
|
| 17 |
+
import torch.nn.functional as F
|
| 18 |
+
from safetensors.torch import load_file as load_safetensors
|
| 19 |
+
from transformers import GenerationMixin, PreTrainedModel
|
| 20 |
+
from transformers.activations import ACT2FN
|
| 21 |
+
from transformers.configuration_utils import PretrainedConfig
|
| 22 |
+
from transformers.modeling_outputs import CausalLMOutputWithPast
|
| 23 |
+
|
| 24 |
+
|
| 25 |
+
def normalize_gradient_checkpointing_level(value: Union[bool, int, str, None]) -> int:
|
| 26 |
+
if isinstance(value, bool):
|
| 27 |
+
return 1 if value else 0
|
| 28 |
+
if value is None:
|
| 29 |
+
return 0
|
| 30 |
+
if isinstance(value, int):
|
| 31 |
+
return max(0, value)
|
| 32 |
+
text = str(value).strip().lower()
|
| 33 |
+
if text in {"", "false", "off", "no", "none"}:
|
| 34 |
+
return 0
|
| 35 |
+
if text in {"true", "on", "yes"}:
|
| 36 |
+
return 1
|
| 37 |
+
try:
|
| 38 |
+
return max(0, int(text))
|
| 39 |
+
except ValueError as exc:
|
| 40 |
+
raise ValueError(f"Unsupported gradient_checkpointing level: {value!r}") from exc
|
| 41 |
+
|
| 42 |
+
|
| 43 |
+
class YConfig31(PretrainedConfig):
|
| 44 |
+
model_type = "ynet31"
|
| 45 |
+
|
| 46 |
+
def __init__(
|
| 47 |
+
self,
|
| 48 |
+
dropout: float = 0.0,
|
| 49 |
+
bos_token_id: int = 151644,
|
| 50 |
+
eos_token_id: int = 151645,
|
| 51 |
+
pad_token_id: int = 151643,
|
| 52 |
+
hidden_act: str = "silu",
|
| 53 |
+
hidden_size: int = 768,
|
| 54 |
+
num_hidden_layers: int = 8,
|
| 55 |
+
max_position_embeddings: int = 8192,
|
| 56 |
+
vocab_size: int = 6400,
|
| 57 |
+
rms_norm_eps: float = 1e-6,
|
| 58 |
+
rope_theta: float = 5e4,
|
| 59 |
+
rope_scaling: Optional[dict] = None,
|
| 60 |
+
dtype: str = "float32",
|
| 61 |
+
self_distill: bool = True,
|
| 62 |
+
intermediate_size: int = 1536,
|
| 63 |
+
num_heads: int = 12,
|
| 64 |
+
mla_kv_lora_rank: int = 64,
|
| 65 |
+
mla_qk_nope_head_dim: int = 64,
|
| 66 |
+
mla_qk_rope_head_dim: int = 32,
|
| 67 |
+
mla_attn_impl: str = "absorb",
|
| 68 |
+
qkv_lora: bool = False,
|
| 69 |
+
gradient_checkpointing: Union[bool, int, str] = 0,
|
| 70 |
+
use_sengram: bool = True,
|
| 71 |
+
sengram_bucket_size: Optional[int] = 4096,
|
| 72 |
+
sengram_topk: int = 2,
|
| 73 |
+
engram_bucket_size: Optional[int] = None,
|
| 74 |
+
engram_topk: Optional[int] = None,
|
| 75 |
+
**kwargs,
|
| 76 |
+
):
|
| 77 |
+
super().__init__(
|
| 78 |
+
bos_token_id=bos_token_id,
|
| 79 |
+
eos_token_id=eos_token_id,
|
| 80 |
+
pad_token_id=pad_token_id,
|
| 81 |
+
**kwargs,
|
| 82 |
+
)
|
| 83 |
+
self.dropout = dropout
|
| 84 |
+
self.hidden_act = hidden_act
|
| 85 |
+
self.hidden_size = hidden_size
|
| 86 |
+
self.num_hidden_layers = num_hidden_layers
|
| 87 |
+
self.max_position_embeddings = max_position_embeddings
|
| 88 |
+
self.vocab_size = vocab_size
|
| 89 |
+
self.rms_norm_eps = rms_norm_eps
|
| 90 |
+
self.rope_theta = rope_theta
|
| 91 |
+
self.rope_scaling = rope_scaling
|
| 92 |
+
self.dtype = dtype
|
| 93 |
+
self.self_distill = self_distill
|
| 94 |
+
self.intermediate_size = intermediate_size
|
| 95 |
+
self.num_heads = num_heads
|
| 96 |
+
self.mla_kv_lora_rank = mla_kv_lora_rank
|
| 97 |
+
self.mla_qk_nope_head_dim = mla_qk_nope_head_dim
|
| 98 |
+
self.mla_qk_rope_head_dim = mla_qk_rope_head_dim
|
| 99 |
+
self.mla_attn_impl = mla_attn_impl
|
| 100 |
+
self.qkv_lora = qkv_lora
|
| 101 |
+
self.gradient_checkpointing = normalize_gradient_checkpointing_level(gradient_checkpointing)
|
| 102 |
+
self.use_sengram = bool(use_sengram)
|
| 103 |
+
if engram_bucket_size is not None:
|
| 104 |
+
sengram_bucket_size = engram_bucket_size
|
| 105 |
+
if engram_topk is not None:
|
| 106 |
+
sengram_topk = engram_topk
|
| 107 |
+
self.sengram_bucket_size = sengram_bucket_size
|
| 108 |
+
self.sengram_topk = sengram_topk
|
| 109 |
+
self.engram_bucket_size = self.sengram_bucket_size
|
| 110 |
+
self.engram_topk = self.sengram_topk
|
| 111 |
+
|
| 112 |
+
@property
|
| 113 |
+
def head_dim(self) -> int:
|
| 114 |
+
return self.mla_qk_nope_head_dim + self.mla_qk_rope_head_dim
|
| 115 |
+
|
| 116 |
+
@property
|
| 117 |
+
def qk_head_dim(self) -> int:
|
| 118 |
+
return self.head_dim
|
| 119 |
+
|
| 120 |
+
def scale_lvl(self, lvl: int = 0):
|
| 121 |
+
if lvl == 0:
|
| 122 |
+
self.hidden_size = 768
|
| 123 |
+
self.num_hidden_layers = 12
|
| 124 |
+
self.num_heads = 8
|
| 125 |
+
self.mla_kv_lora_rank = 256
|
| 126 |
+
self.mla_qk_nope_head_dim = 128
|
| 127 |
+
self.mla_qk_rope_head_dim = 64
|
| 128 |
+
self.intermediate_size = 2048
|
| 129 |
+
self.use_sengram = True
|
| 130 |
+
self.sengram_bucket_size = 8192
|
| 131 |
+
self.sengram_topk = 8
|
| 132 |
+
elif lvl == -1:
|
| 133 |
+
self.hidden_size = 768
|
| 134 |
+
self.num_hidden_layers = 8
|
| 135 |
+
self.num_heads = 6
|
| 136 |
+
self.mla_kv_lora_rank = 128
|
| 137 |
+
self.mla_qk_nope_head_dim = 64
|
| 138 |
+
self.mla_qk_rope_head_dim = 64
|
| 139 |
+
self.intermediate_size = 1536
|
| 140 |
+
self.use_sengram = True
|
| 141 |
+
elif lvl == -2:
|
| 142 |
+
self.hidden_size = 512
|
| 143 |
+
self.num_hidden_layers = 4
|
| 144 |
+
self.num_heads = 4
|
| 145 |
+
self.mla_kv_lora_rank = 128
|
| 146 |
+
self.mla_qk_nope_head_dim = 64
|
| 147 |
+
self.mla_qk_rope_head_dim = 64
|
| 148 |
+
self.intermediate_size = 1024
|
| 149 |
+
self.use_sengram = True
|
| 150 |
+
else:
|
| 151 |
+
raise ValueError(f"invalid ymodel31 scale level: {lvl}")
|
| 152 |
+
return self
|
| 153 |
+
|
| 154 |
+
|
| 155 |
+
def _yarn_linear_ramp(low: float, high: float, dim: int) -> torch.Tensor:
|
| 156 |
+
if low == high:
|
| 157 |
+
high += 0.001
|
| 158 |
+
linear = (torch.arange(dim, dtype=torch.float32) - low) / (high - low)
|
| 159 |
+
return torch.clamp(linear, 0.0, 1.0)
|
| 160 |
+
|
| 161 |
+
|
| 162 |
+
def _yarn_correction_dim(num_rotations: float, dim: int, theta: float, max_position_embeddings: int) -> float:
|
| 163 |
+
return dim * math.log(max_position_embeddings / (num_rotations * 2 * math.pi)) / (2 * math.log(theta))
|
| 164 |
+
|
| 165 |
+
|
| 166 |
+
def precompute_freqs_cis(
|
| 167 |
+
dim: int,
|
| 168 |
+
end: int,
|
| 169 |
+
theta: float,
|
| 170 |
+
rope_scaling: Optional[dict] = None,
|
| 171 |
+
) -> tuple[torch.Tensor, torch.Tensor]:
|
| 172 |
+
freqs = 1.0 / (theta ** (torch.arange(0, dim, 2).float() / dim))
|
| 173 |
+
attention_factor = 1.0
|
| 174 |
+
if rope_scaling and str(rope_scaling.get("type", "yarn")).lower() == "yarn":
|
| 175 |
+
factor = float(rope_scaling.get("factor", 1.0))
|
| 176 |
+
if factor > 1.0:
|
| 177 |
+
original = int(rope_scaling.get("original_max_position_embeddings", end))
|
| 178 |
+
beta_fast = float(rope_scaling.get("beta_fast", 32.0))
|
| 179 |
+
beta_slow = float(rope_scaling.get("beta_slow", 1.0))
|
| 180 |
+
low = math.floor(_yarn_correction_dim(beta_fast, dim, theta, original))
|
| 181 |
+
high = math.ceil(_yarn_correction_dim(beta_slow, dim, theta, original))
|
| 182 |
+
ramp = _yarn_linear_ramp(low, high, dim // 2)
|
| 183 |
+
freqs = freqs / factor * (1.0 - ramp) + freqs * ramp
|
| 184 |
+
attention_factor = float(rope_scaling.get("attention_factor", 1.0))
|
| 185 |
+
t = torch.arange(end)
|
| 186 |
+
freqs = torch.outer(t, freqs).float()
|
| 187 |
+
freqs_cos = torch.cat([torch.cos(freqs), torch.cos(freqs)], dim=-1) * attention_factor
|
| 188 |
+
freqs_sin = torch.cat([torch.sin(freqs), torch.sin(freqs)], dim=-1) * attention_factor
|
| 189 |
+
return freqs_cos, freqs_sin
|
| 190 |
+
|
| 191 |
+
|
| 192 |
+
def rotate_half(x: torch.Tensor) -> torch.Tensor:
|
| 193 |
+
return torch.cat((-x[..., x.shape[-1] // 2 :], x[..., : x.shape[-1] // 2]), dim=-1)
|
| 194 |
+
|
| 195 |
+
|
| 196 |
+
def apply_rope_to_single(x: torch.Tensor, cos: torch.Tensor, sin: torch.Tensor) -> torch.Tensor:
|
| 197 |
+
if cos.dim() == 2:
|
| 198 |
+
cos = cos.unsqueeze(0).unsqueeze(0)
|
| 199 |
+
sin = sin.unsqueeze(0).unsqueeze(0)
|
| 200 |
+
elif cos.dim() == 3:
|
| 201 |
+
cos = cos.unsqueeze(1)
|
| 202 |
+
sin = sin.unsqueeze(1)
|
| 203 |
+
return (x * cos) + (rotate_half(x) * sin)
|
| 204 |
+
|
| 205 |
+
|
| 206 |
+
class RMSNorm(nn.Module):
|
| 207 |
+
def __init__(self, dim: int, eps: float = 1e-6):
|
| 208 |
+
super().__init__()
|
| 209 |
+
self.weight = nn.Parameter(torch.ones(dim, dtype=torch.float32))
|
| 210 |
+
self.eps = eps
|
| 211 |
+
|
| 212 |
+
def forward(self, x: torch.Tensor) -> torch.Tensor:
|
| 213 |
+
out = x.float() * torch.rsqrt(x.float().pow(2).mean(-1, keepdim=True) + self.eps)
|
| 214 |
+
return (out * self.weight.float()).to(x.dtype)
|
| 215 |
+
|
| 216 |
+
|
| 217 |
+
class SEBlock(nn.Module):
|
| 218 |
+
def __init__(self, dim: int, reduction: int = 16, act: Optional[nn.Module] = None):
|
| 219 |
+
super().__init__()
|
| 220 |
+
reduction = max(reduction, dim // reduction)
|
| 221 |
+
self.se = nn.Sequential(
|
| 222 |
+
nn.Linear(dim, reduction, bias=False),
|
| 223 |
+
act or nn.SiLU(),
|
| 224 |
+
nn.Linear(reduction, dim, bias=False),
|
| 225 |
+
nn.Sigmoid(),
|
| 226 |
+
)
|
| 227 |
+
|
| 228 |
+
def forward(self, x: torch.Tensor) -> torch.Tensor:
|
| 229 |
+
return x * self.se(x)
|
| 230 |
+
|
| 231 |
+
|
| 232 |
+
class MLGA(nn.Module):
|
| 233 |
+
"""Multihead Latent Gated Attention"""
|
| 234 |
+
|
| 235 |
+
def __init__(self, config: YConfig31, layer_id: int):
|
| 236 |
+
super().__init__()
|
| 237 |
+
self.layer_id = layer_id
|
| 238 |
+
self.hidden_size = config.hidden_size
|
| 239 |
+
self.num_heads = config.num_heads
|
| 240 |
+
self.dropout = config.dropout
|
| 241 |
+
self.kv_lora_rank = config.mla_kv_lora_rank
|
| 242 |
+
self.qk_nope_head_dim = config.mla_qk_nope_head_dim
|
| 243 |
+
self.qk_rope_head_dim = config.mla_qk_rope_head_dim
|
| 244 |
+
self.qk_head_dim = self.qk_nope_head_dim + self.qk_rope_head_dim
|
| 245 |
+
self.attn_impl = config.mla_attn_impl
|
| 246 |
+
self.softmax_scale = self.qk_head_dim**-0.5
|
| 247 |
+
self.out_dim = self.num_heads * self.kv_lora_rank
|
| 248 |
+
|
| 249 |
+
self.wq = nn.Linear(self.hidden_size, self.num_heads * self.qk_head_dim, bias=False)
|
| 250 |
+
self.wkv_a = nn.Linear(self.hidden_size, self.kv_lora_rank + self.qk_rope_head_dim, bias=False)
|
| 251 |
+
self.kv_norm = RMSNorm(self.kv_lora_rank, config.rms_norm_eps)
|
| 252 |
+
self.wkv_b = nn.Linear(self.kv_lora_rank, self.num_heads * self.qk_nope_head_dim, bias=False)
|
| 253 |
+
self.z_proj = nn.Linear(self.hidden_size, self.out_dim, bias=False)
|
| 254 |
+
self.o_proj = nn.Linear(self.out_dim, self.hidden_size, bias=False)
|
| 255 |
+
|
| 256 |
+
def _project_q(self, x: torch.Tensor) -> tuple[torch.Tensor, torch.Tensor]:
|
| 257 |
+
bsz, seq_len, _ = x.shape
|
| 258 |
+
q = self.wq(x).reshape(bsz, seq_len, self.num_heads, self.qk_head_dim)
|
| 259 |
+
return q.split([self.qk_nope_head_dim, self.qk_rope_head_dim], dim=-1)
|
| 260 |
+
|
| 261 |
+
def _project_kv(self, x: torch.Tensor, cos: torch.Tensor, sin: torch.Tensor) -> tuple[torch.Tensor, torch.Tensor]:
|
| 262 |
+
raw = self.wkv_a(x)
|
| 263 |
+
c_kv, k_pe = raw.split([self.kv_lora_rank, self.qk_rope_head_dim], dim=-1)
|
| 264 |
+
c_kv = self.kv_norm(c_kv)
|
| 265 |
+
k_pe = apply_rope_to_single(k_pe.unsqueeze(1), cos, sin).permute(0, 2, 1, 3)
|
| 266 |
+
return c_kv, k_pe
|
| 267 |
+
|
| 268 |
+
def _explicit_kv(self, c_kv: torch.Tensor, k_pe: torch.Tensor) -> tuple[torch.Tensor, torch.Tensor]:
|
| 269 |
+
bsz, seq_len, _ = c_kv.shape
|
| 270 |
+
k_nope = self.wkv_b(c_kv).reshape(bsz, seq_len, self.num_heads, self.qk_nope_head_dim)
|
| 271 |
+
k = torch.cat([k_nope, k_pe.expand(-1, -1, self.num_heads, -1)], dim=-1)
|
| 272 |
+
v = c_kv.unsqueeze(2).expand(-1, -1, self.num_heads, -1)
|
| 273 |
+
return k, v
|
| 274 |
+
|
| 275 |
+
def _attention_mask(self, attention_mask: Optional[torch.Tensor], bsz: int, seq_len: int, total_len: int):
|
| 276 |
+
if attention_mask is None:
|
| 277 |
+
return None
|
| 278 |
+
if attention_mask.shape[-1] != total_len:
|
| 279 |
+
attention_mask = attention_mask[..., -total_len:]
|
| 280 |
+
mask = attention_mask.reshape(bsz, 1, 1, total_len).bool()
|
| 281 |
+
return mask.expand(bsz, self.num_heads, seq_len, total_len)
|
| 282 |
+
|
| 283 |
+
def _forward_sdpa(
|
| 284 |
+
self,
|
| 285 |
+
q_nope: torch.Tensor,
|
| 286 |
+
q_pe: torch.Tensor,
|
| 287 |
+
c_kv: torch.Tensor,
|
| 288 |
+
k_pe: torch.Tensor,
|
| 289 |
+
z: torch.Tensor,
|
| 290 |
+
attention_mask: Optional[torch.Tensor],
|
| 291 |
+
) -> torch.Tensor:
|
| 292 |
+
bsz, seq_len, _, _ = q_nope.shape
|
| 293 |
+
total_len = c_kv.shape[1]
|
| 294 |
+
k, v = self._explicit_kv(c_kv, k_pe)
|
| 295 |
+
q = torch.cat([q_nope, q_pe], dim=-1).permute(0, 2, 1, 3)
|
| 296 |
+
k = k.permute(0, 2, 1, 3)
|
| 297 |
+
v = v.permute(0, 2, 1, 3)
|
| 298 |
+
attn_mask = self._attention_mask(attention_mask, bsz, seq_len, total_len)
|
| 299 |
+
is_causal = attention_mask is None and seq_len == total_len
|
| 300 |
+
out = F.scaled_dot_product_attention(
|
| 301 |
+
q,
|
| 302 |
+
k,
|
| 303 |
+
v,
|
| 304 |
+
attn_mask=attn_mask,
|
| 305 |
+
dropout_p=0.0,
|
| 306 |
+
is_causal=is_causal,
|
| 307 |
+
scale=self.softmax_scale,
|
| 308 |
+
)
|
| 309 |
+
out = out.permute(0, 2, 1, 3).reshape(bsz, seq_len, self.out_dim)
|
| 310 |
+
out = out * torch.sigmoid(z)
|
| 311 |
+
return self.o_proj(out)
|
| 312 |
+
|
| 313 |
+
def _forward_absorb(
|
| 314 |
+
self,
|
| 315 |
+
q_nope: torch.Tensor,
|
| 316 |
+
q_pe: torch.Tensor,
|
| 317 |
+
c_kv: torch.Tensor,
|
| 318 |
+
k_pe: torch.Tensor,
|
| 319 |
+
z: torch.Tensor,
|
| 320 |
+
attention_mask: Optional[torch.Tensor],
|
| 321 |
+
) -> torch.Tensor:
|
| 322 |
+
bsz, seq_len, _, _ = q_nope.shape
|
| 323 |
+
total_len = c_kv.shape[1]
|
| 324 |
+
w = self.wkv_b.weight.reshape(self.num_heads, self.qk_nope_head_dim, self.kv_lora_rank)
|
| 325 |
+
q_nope_c = torch.einsum("bshd,hdc->bshc", q_nope, w)
|
| 326 |
+
scores = torch.einsum("bshc,btc->bsht", q_nope_c, c_kv)
|
| 327 |
+
scores = scores + torch.einsum("bshr,btr->bsht", q_pe, k_pe.squeeze(2))
|
| 328 |
+
scores = scores * self.softmax_scale
|
| 329 |
+
|
| 330 |
+
causal = torch.full((seq_len, seq_len), float("-inf"), device=scores.device, dtype=scores.dtype)
|
| 331 |
+
causal = torch.triu(causal, diagonal=1).reshape(1, seq_len, 1, seq_len)
|
| 332 |
+
scores = scores + F.pad(causal, (total_len - seq_len, 0), value=0.0)
|
| 333 |
+
if attention_mask is not None:
|
| 334 |
+
if attention_mask.shape[-1] != total_len:
|
| 335 |
+
attention_mask = attention_mask[..., -total_len:]
|
| 336 |
+
scores = scores + (1.0 - attention_mask.reshape(bsz, 1, 1, total_len).float()) * -1e9
|
| 337 |
+
probs = torch.softmax(scores.float(), dim=-1).to(q_nope.dtype)
|
| 338 |
+
out = torch.einsum("bsht,btc->bshc", probs, c_kv).reshape(bsz, seq_len, self.out_dim)
|
| 339 |
+
out = out * torch.sigmoid(z)
|
| 340 |
+
return self.o_proj(out)
|
| 341 |
+
|
| 342 |
+
def forward(
|
| 343 |
+
self,
|
| 344 |
+
x: torch.Tensor,
|
| 345 |
+
position_embeddings: tuple[torch.Tensor, torch.Tensor],
|
| 346 |
+
past_key_values: Optional[tuple[torch.Tensor, torch.Tensor]] = None,
|
| 347 |
+
attention_mask: Optional[torch.Tensor] = None,
|
| 348 |
+
use_cache: bool = False,
|
| 349 |
+
**kwargs,
|
| 350 |
+
) -> tuple[torch.Tensor, Optional[tuple[torch.Tensor, torch.Tensor]]]:
|
| 351 |
+
bsz, seq_len, _ = x.shape
|
| 352 |
+
cos, sin = position_embeddings
|
| 353 |
+
if cos.dim() == 2:
|
| 354 |
+
cos = cos[:seq_len, : self.qk_rope_head_dim]
|
| 355 |
+
sin = sin[:seq_len, : self.qk_rope_head_dim]
|
| 356 |
+
else:
|
| 357 |
+
cos = cos[:, :seq_len, : self.qk_rope_head_dim]
|
| 358 |
+
sin = sin[:, :seq_len, : self.qk_rope_head_dim]
|
| 359 |
+
q_nope, q_pe = self._project_q(x)
|
| 360 |
+
q_pe = apply_rope_to_single(q_pe.permute(0, 2, 1, 3), cos, sin).permute(0, 2, 1, 3)
|
| 361 |
+
c_kv, k_pe = self._project_kv(x, cos, sin)
|
| 362 |
+
z = self.z_proj(x)
|
| 363 |
+
|
| 364 |
+
if past_key_values is not None:
|
| 365 |
+
past_c, past_pe = past_key_values
|
| 366 |
+
c_kv = torch.cat([past_c, c_kv], dim=1)
|
| 367 |
+
k_pe = torch.cat([past_pe, k_pe], dim=1)
|
| 368 |
+
new_past = (c_kv, k_pe) if use_cache else None
|
| 369 |
+
|
| 370 |
+
if self.attn_impl == "naive":
|
| 371 |
+
out = self._forward_sdpa(q_nope, q_pe, c_kv, k_pe, z, attention_mask)
|
| 372 |
+
else:
|
| 373 |
+
out = self._forward_absorb(q_nope, q_pe, c_kv, k_pe, z, attention_mask)
|
| 374 |
+
return out, new_past
|
| 375 |
+
|
| 376 |
+
|
| 377 |
+
class SwiGLU(nn.Module):
|
| 378 |
+
def __init__(self, config: YConfig31, intermediate_size: Optional[int] = None):
|
| 379 |
+
super().__init__()
|
| 380 |
+
inter = intermediate_size or config.intermediate_size
|
| 381 |
+
self.up_proj = nn.Linear(config.hidden_size, inter, bias=False)
|
| 382 |
+
self.gate_proj = nn.Linear(config.hidden_size, inter, bias=False)
|
| 383 |
+
self.down_proj = nn.Linear(inter, config.hidden_size, bias=False)
|
| 384 |
+
|
| 385 |
+
def forward(self, x: torch.Tensor) -> torch.Tensor:
|
| 386 |
+
up, gate = self.up_proj(x), self.gate_proj(x)
|
| 387 |
+
up = nn.functional.silu(gate) * up
|
| 388 |
+
return self.down_proj(up)
|
| 389 |
+
|
| 390 |
+
|
| 391 |
+
class SengramIndexer(nn.Module):
|
| 392 |
+
def __init__(self, config: YConfig31):
|
| 393 |
+
super().__init__()
|
| 394 |
+
self.hidden_size = int(config.hidden_size)
|
| 395 |
+
self.bucket_size = int(config.sengram_bucket_size or 4096)
|
| 396 |
+
self.topk = max(1, min(int(config.sengram_topk), self.bucket_size))
|
| 397 |
+
self.bucket_proj = nn.Linear(self.hidden_size, self.bucket_size, bias=False)
|
| 398 |
+
|
| 399 |
+
def forward(self, hidden_states: torch.Tensor) -> tuple[torch.Tensor, torch.Tensor]:
|
| 400 |
+
bucket_logits = self.bucket_proj(hidden_states)
|
| 401 |
+
route_scores = torch.softmax(bucket_logits.float(), dim=-1)
|
| 402 |
+
topk_ids = torch.topk(route_scores, k=self.topk, dim=-1, sorted=False).indices
|
| 403 |
+
topk_scores = route_scores.gather(-1, topk_ids)
|
| 404 |
+
denom = topk_scores.sum(dim=-1, keepdim=True).clamp_min(1e-20)
|
| 405 |
+
topk_scores = (topk_scores / denom).to(bucket_logits.dtype)
|
| 406 |
+
return topk_ids, topk_scores
|
| 407 |
+
|
| 408 |
+
|
| 409 |
+
class SengramPLE(nn.Module):
|
| 410 |
+
def __init__(self, config: YConfig31):
|
| 411 |
+
super().__init__()
|
| 412 |
+
self.hidden_size = int(config.hidden_size)
|
| 413 |
+
self.embedding = nn.Embedding(int(config.sengram_bucket_size or 4096), self.hidden_size)
|
| 414 |
+
self.key_proj = nn.Linear(self.hidden_size, self.hidden_size, bias=False)
|
| 415 |
+
self.memory_norm = RMSNorm(self.hidden_size, config.rms_norm_eps)
|
| 416 |
+
self.key_norm = RMSNorm(self.hidden_size, config.rms_norm_eps)
|
| 417 |
+
self.query_norm = RMSNorm(self.hidden_size, config.rms_norm_eps)
|
| 418 |
+
|
| 419 |
+
def forward(
|
| 420 |
+
self,
|
| 421 |
+
hidden_states: torch.Tensor,
|
| 422 |
+
topk_ids: torch.Tensor,
|
| 423 |
+
topk_scores: torch.Tensor,
|
| 424 |
+
) -> torch.Tensor:
|
| 425 |
+
topk_embed = F.embedding(topk_ids, self.embedding.weight)
|
| 426 |
+
return (topk_embed * topk_scores.unsqueeze(-1).to(topk_embed.dtype)).sum(dim=-2)
|
| 427 |
+
|
| 428 |
+
|
| 429 |
+
class YBlock31(nn.Module):
|
| 430 |
+
def __init__(self, config: YConfig31, layer_id: int):
|
| 431 |
+
super().__init__()
|
| 432 |
+
self.use_sengram = bool(config.use_sengram)
|
| 433 |
+
self.input_layernorm = RMSNorm(config.hidden_size, config.rms_norm_eps)
|
| 434 |
+
self.post_attention_layernorm = RMSNorm(config.hidden_size, config.rms_norm_eps)
|
| 435 |
+
self.sengram_ple = SengramPLE(config) if self.use_sengram else None
|
| 436 |
+
self.attn = MLGA(config, layer_id)
|
| 437 |
+
self.ffn = SwiGLU(config)
|
| 438 |
+
self.se1 = SEBlock(config.hidden_size, act=ACT2FN[config.hidden_act])
|
| 439 |
+
self.se2 = SEBlock(config.hidden_size, act=ACT2FN[config.hidden_act])
|
| 440 |
+
|
| 441 |
+
def forward(
|
| 442 |
+
self,
|
| 443 |
+
x: torch.Tensor,
|
| 444 |
+
position_embeddings: tuple[torch.Tensor, torch.Tensor],
|
| 445 |
+
past_key_values: Optional[tuple[torch.Tensor, torch.Tensor]] = None,
|
| 446 |
+
use_cache: bool = False,
|
| 447 |
+
attention_mask: Optional[torch.Tensor] = None,
|
| 448 |
+
route_ids: Optional[torch.Tensor] = None,
|
| 449 |
+
route_scores: Optional[torch.Tensor] = None,
|
| 450 |
+
**kwargs,
|
| 451 |
+
):
|
| 452 |
+
if self.use_sengram and route_ids is not None and route_scores is not None and self.sengram_ple is not None:
|
| 453 |
+
x = x + self.sengram_ple(x, route_ids, route_scores)
|
| 454 |
+
x0 = self.se1(self.input_layernorm(x))
|
| 455 |
+
attn_out, past = self.attn(
|
| 456 |
+
x0,
|
| 457 |
+
position_embeddings,
|
| 458 |
+
past_key_values=past_key_values,
|
| 459 |
+
attention_mask=attention_mask,
|
| 460 |
+
use_cache=use_cache,
|
| 461 |
+
)
|
| 462 |
+
x = x + attn_out
|
| 463 |
+
x0 = self.se2(self.post_attention_layernorm(x))
|
| 464 |
+
x = x + self.ffn(x0)
|
| 465 |
+
return x, past
|
| 466 |
+
|
| 467 |
+
|
| 468 |
+
class YModel31(nn.Module):
|
| 469 |
+
def __init__(self, config: YConfig31):
|
| 470 |
+
super().__init__()
|
| 471 |
+
self.config = config
|
| 472 |
+
self.vocab_size = config.vocab_size
|
| 473 |
+
self.num_layers = config.num_hidden_layers
|
| 474 |
+
self.dropout = config.dropout
|
| 475 |
+
self.use_sengram = bool(config.use_sengram)
|
| 476 |
+
self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size)
|
| 477 |
+
self.sengram_indexer = SengramIndexer(config) if self.use_sengram else None
|
| 478 |
+
self.layers = nn.ModuleList([YBlock31(config, i) for i in range(config.num_hidden_layers)])
|
| 479 |
+
self.norm = RMSNorm(config.hidden_size, config.rms_norm_eps)
|
| 480 |
+
freqs_cos, freqs_sin = precompute_freqs_cis(
|
| 481 |
+
dim=config.mla_qk_rope_head_dim,
|
| 482 |
+
end=config.max_position_embeddings,
|
| 483 |
+
theta=config.rope_theta,
|
| 484 |
+
rope_scaling=config.rope_scaling,
|
| 485 |
+
)
|
| 486 |
+
self.register_buffer("freqs_cos", freqs_cos, persistent=False)
|
| 487 |
+
self.register_buffer("freqs_sin", freqs_sin, persistent=False)
|
| 488 |
+
|
| 489 |
+
@property
|
| 490 |
+
def sengram(self):
|
| 491 |
+
return self.sengram_indexer
|
| 492 |
+
|
| 493 |
+
def _load_from_state_dict(self, state_dict, prefix, local_metadata, strict, missing_keys, unexpected_keys, error_msgs):
|
| 494 |
+
for key in list(state_dict.keys()):
|
| 495 |
+
if key.startswith(prefix + "sengram."):
|
| 496 |
+
state_dict.pop(key)
|
| 497 |
+
super()._load_from_state_dict(state_dict, prefix, local_metadata, strict, missing_keys, unexpected_keys, error_msgs)
|
| 498 |
+
|
| 499 |
+
def forward(
|
| 500 |
+
self,
|
| 501 |
+
input_ids: Optional[torch.Tensor] = None,
|
| 502 |
+
attention_mask: Optional[torch.Tensor] = None,
|
| 503 |
+
past_key_values: Optional[list] = None,
|
| 504 |
+
use_cache: bool = False,
|
| 505 |
+
cache_position: Optional[torch.LongTensor] = None,
|
| 506 |
+
position_ids: Optional[torch.LongTensor] = None,
|
| 507 |
+
**kwargs,
|
| 508 |
+
):
|
| 509 |
+
bsz, seq_len = input_ids.shape
|
| 510 |
+
if use_cache and past_key_values is None:
|
| 511 |
+
past_key_values = [None] * self.num_layers
|
| 512 |
+
if cache_position is None:
|
| 513 |
+
if past_key_values is not None and past_key_values[0] is not None:
|
| 514 |
+
past_seen = past_key_values[0][0].shape[1]
|
| 515 |
+
else:
|
| 516 |
+
past_seen = 0
|
| 517 |
+
cache_position = torch.arange(past_seen, past_seen + seq_len, device=input_ids.device)
|
| 518 |
+
|
| 519 |
+
x = self.embed_tokens(input_ids)
|
| 520 |
+
if position_ids is None:
|
| 521 |
+
position_ids = cache_position
|
| 522 |
+
position_embeddings = (self.freqs_cos[position_ids].to(x.device), self.freqs_sin[position_ids].to(x.device))
|
| 523 |
+
route_ids = None
|
| 524 |
+
route_scores = None
|
| 525 |
+
if self.use_sengram and self.sengram_indexer is not None:
|
| 526 |
+
route_ids, route_scores = self.sengram_indexer(x)
|
| 527 |
+
new_past = [] if use_cache else None
|
| 528 |
+
|
| 529 |
+
for i, layer in enumerate(self.layers):
|
| 530 |
+
past = past_key_values[i] if past_key_values is not None else None
|
| 531 |
+
x, layer_past = layer(
|
| 532 |
+
x,
|
| 533 |
+
position_embeddings=position_embeddings,
|
| 534 |
+
past_key_values=past,
|
| 535 |
+
attention_mask=attention_mask,
|
| 536 |
+
use_cache=use_cache,
|
| 537 |
+
route_ids=route_ids,
|
| 538 |
+
route_scores=route_scores,
|
| 539 |
+
)
|
| 540 |
+
if use_cache:
|
| 541 |
+
new_past.append(layer_past)
|
| 542 |
+
return self.norm(x), new_past
|
| 543 |
+
|
| 544 |
+
|
| 545 |
+
class YForCausalLM31(PreTrainedModel, GenerationMixin):
|
| 546 |
+
config_class = YConfig31
|
| 547 |
+
|
| 548 |
+
def __init__(self, config: Optional[YConfig31] = None):
|
| 549 |
+
self.config = config or YConfig31()
|
| 550 |
+
super().__init__(self.config)
|
| 551 |
+
self.model = YModel31(self.config)
|
| 552 |
+
self.lm_head = nn.Linear(self.config.hidden_size, self.config.vocab_size, bias=False)
|
| 553 |
+
self.model.embed_tokens.weight = self.lm_head.weight
|
| 554 |
+
self.OUT = CausalLMOutputWithPast()
|
| 555 |
+
dtype = {"float16": torch.float16, "bfloat16": torch.bfloat16, "float32": torch.float32}.get(self.config.dtype)
|
| 556 |
+
if dtype is not None:
|
| 557 |
+
self.to(dtype)
|
| 558 |
+
|
| 559 |
+
def forward(
|
| 560 |
+
self,
|
| 561 |
+
input_ids: Optional[torch.Tensor] = None,
|
| 562 |
+
attention_mask: Optional[torch.Tensor] = None,
|
| 563 |
+
past_key_values: Optional[list] = None,
|
| 564 |
+
use_cache: bool = False,
|
| 565 |
+
logits_to_keep: Union[int, torch.Tensor] = 0,
|
| 566 |
+
cache_position: Optional[torch.LongTensor] = None,
|
| 567 |
+
**kwargs,
|
| 568 |
+
):
|
| 569 |
+
h, past_kvs = self.model(
|
| 570 |
+
input_ids=input_ids,
|
| 571 |
+
attention_mask=attention_mask,
|
| 572 |
+
past_key_values=past_key_values,
|
| 573 |
+
use_cache=use_cache,
|
| 574 |
+
cache_position=cache_position,
|
| 575 |
+
position_ids=kwargs.get("position_ids", None),
|
| 576 |
+
)
|
| 577 |
+
slice_indices = slice(-logits_to_keep, None) if isinstance(logits_to_keep, int) else logits_to_keep
|
| 578 |
+
logits = self.lm_head(h[:, slice_indices, :])
|
| 579 |
+
self.OUT.__setitem__("last_hidden_state", h)
|
| 580 |
+
self.OUT.__setitem__("logits", logits)
|
| 581 |
+
self.OUT.__setitem__("past_key_values", past_kvs)
|
| 582 |
+
return self.OUT
|
| 583 |
+
|
| 584 |
+
def generate(
|
| 585 |
+
self,
|
| 586 |
+
inputs,
|
| 587 |
+
attention_mask=None,
|
| 588 |
+
max_new_tokens=8192,
|
| 589 |
+
temperature=0.85,
|
| 590 |
+
top_p=0.85,
|
| 591 |
+
top_k=50,
|
| 592 |
+
eos_token_id=None,
|
| 593 |
+
streamer=None,
|
| 594 |
+
use_cache=True,
|
| 595 |
+
num_return_sequences=1,
|
| 596 |
+
do_sample=True,
|
| 597 |
+
repetition_penalty=1.0,
|
| 598 |
+
**kwargs,
|
| 599 |
+
):
|
| 600 |
+
input_ids = kwargs.get("input_ids", inputs).repeat(num_return_sequences, 1)
|
| 601 |
+
attention_mask = attention_mask.repeat(num_return_sequences, 1) if attention_mask is not None else None
|
| 602 |
+
logits_processor = kwargs.get("logits_processor", None)
|
| 603 |
+
past_key_values = None
|
| 604 |
+
if streamer:
|
| 605 |
+
streamer.put(input_ids.cpu())
|
| 606 |
+
with torch.no_grad():
|
| 607 |
+
for _ in range(max_new_tokens):
|
| 608 |
+
if use_cache and past_key_values is not None:
|
| 609 |
+
outputs = self.forward(input_ids[:, -1:], None, past_key_values, use_cache=use_cache)
|
| 610 |
+
else:
|
| 611 |
+
outputs = self.forward(input_ids, attention_mask, past_key_values, use_cache=use_cache)
|
| 612 |
+
logits = outputs.logits[:, -1, :] / temperature
|
| 613 |
+
if repetition_penalty != 1.0:
|
| 614 |
+
for i in range(input_ids.shape[0]):
|
| 615 |
+
logits[i, torch.unique(input_ids[i])] /= repetition_penalty
|
| 616 |
+
if logits_processor is not None:
|
| 617 |
+
logits = logits_processor(input_ids, logits)
|
| 618 |
+
if top_k > 0:
|
| 619 |
+
logits[logits < torch.topk(logits, top_k)[0][..., -1, None]] = -float("inf")
|
| 620 |
+
if top_p < 1.0:
|
| 621 |
+
sorted_logits, sorted_indices = torch.sort(logits, descending=True)
|
| 622 |
+
mask = torch.cumsum(torch.softmax(sorted_logits, dim=-1), dim=-1) > top_p
|
| 623 |
+
mask[..., 1:], mask[..., 0] = mask[..., :-1].clone(), 0
|
| 624 |
+
logits[mask.scatter(1, sorted_indices, mask)] = -float("inf")
|
| 625 |
+
next_token = (
|
| 626 |
+
torch.multinomial(torch.softmax(logits, dim=-1), 1)
|
| 627 |
+
if do_sample
|
| 628 |
+
else torch.argmax(logits, dim=-1, keepdim=True)
|
| 629 |
+
)
|
| 630 |
+
input_ids = torch.cat([input_ids, next_token], dim=-1)
|
| 631 |
+
if attention_mask is not None:
|
| 632 |
+
attention_mask = torch.cat([attention_mask, attention_mask.new_ones((attention_mask.shape[0], 1))], dim=-1)
|
| 633 |
+
past_key_values = outputs.past_key_values
|
| 634 |
+
if streamer:
|
| 635 |
+
streamer.put(next_token.cpu())
|
| 636 |
+
if eos_token_id and (next_token == eos_token_id).any():
|
| 637 |
+
break
|
| 638 |
+
if streamer:
|
| 639 |
+
streamer.end()
|
| 640 |
+
return input_ids
|
| 641 |
+
|
| 642 |
+
|
| 643 |
+
def count_parameters(config: YConfig31) -> int:
|
| 644 |
+
return sum(p.numel() for p in YForCausalLM31(config).parameters())
|
| 645 |
+
|
| 646 |
+
|
| 647 |
+
def _load_state_dict(path: Union[str, Path]) -> dict[str, torch.Tensor]:
|
| 648 |
+
path = Path(path)
|
| 649 |
+
if path.is_dir():
|
| 650 |
+
safetensors_path = path / "model.safetensors"
|
| 651 |
+
bin_path = path / "pytorch_model.bin"
|
| 652 |
+
if safetensors_path.exists():
|
| 653 |
+
path = safetensors_path
|
| 654 |
+
elif bin_path.exists():
|
| 655 |
+
path = bin_path
|
| 656 |
+
else:
|
| 657 |
+
raise FileNotFoundError(f"no model.safetensors or pytorch_model.bin found in {path}")
|
| 658 |
+
if path.suffix == ".safetensors":
|
| 659 |
+
return load_safetensors(str(path), device="cpu")
|
| 660 |
+
return torch.load(path, map_location="cpu", weights_only=True)
|
| 661 |
+
|
| 662 |
+
|
| 663 |
+
def load_ymodel31_eval(path: Union[str, Path], config: Optional[YConfig31] = None, strict: bool = True) -> YForCausalLM31:
|
| 664 |
+
path = Path(path)
|
| 665 |
+
if config is None:
|
| 666 |
+
config_path = path / "config.json" if path.is_dir() else path.with_name("config.json")
|
| 667 |
+
if not config_path.exists():
|
| 668 |
+
raise FileNotFoundError("config is required when config.json is not next to the checkpoint")
|
| 669 |
+
config = YConfig31.from_json_file(str(config_path))
|
| 670 |
+
model = YForCausalLM31(config)
|
| 671 |
+
state = _load_state_dict(path)
|
| 672 |
+
model.load_state_dict(state, strict=strict)
|
| 673 |
+
model.eval()
|
| 674 |
+
return model
|
| 675 |
+
|
| 676 |
+
|
| 677 |
+
YModel31Eval = YModel31
|
| 678 |
+
YForCausalLM31Eval = YForCausalLM31
|
| 679 |
+
|
| 680 |
+
|
| 681 |
+
__all__ = [
|
| 682 |
+
"MLGA",
|
| 683 |
+
"RMSNorm",
|
| 684 |
+
"SEBlock",
|
| 685 |
+
"SengramIndexer",
|
| 686 |
+
"SengramPLE",
|
| 687 |
+
"SwiGLU",
|
| 688 |
+
"YBlock31",
|
| 689 |
+
"YConfig31",
|
| 690 |
+
"YForCausalLM31",
|
| 691 |
+
"YForCausalLM31Eval",
|
| 692 |
+
"YModel31",
|
| 693 |
+
"YModel31Eval",
|
| 694 |
+
"apply_rope_to_single",
|
| 695 |
+
"count_parameters",
|
| 696 |
+
"load_ymodel31_eval",
|
| 697 |
+
"precompute_freqs_cis",
|
| 698 |
+
]
|