


Commit ·
9f57754
0
Parent(s):
Meridian
Browse filesThis view is limited to 50 files because it contains too many changes. See raw diff
- .gitattributes +96 -0
- LICENSE +84 -0
- LICENSE-CODE +201 -0
- MODIFICATIONS.md +62 -0
- NOTICE +22 -0
- README.md +259 -0
- assets/fixed_embed_107.pt +3 -0
- assets/fixed_embed_124.pt +3 -0
- assets/fixed_embed_141.pt +3 -0
- assets/fixed_embed_158.pt +3 -0
- assets/fixed_embed_175.pt +3 -0
- assets/fixed_embed_243.pt +3 -0
- assets/fixed_embed_73.pt +3 -0
- assets/fixed_embed_90.pt +3 -0
- assets/meridian_method.png +3 -0
- assets/prompt.txt +16 -0
- assets/silence_audio_107.pt +3 -0
- assets/silence_audio_124.pt +3 -0
- assets/silence_audio_141.pt +3 -0
- assets/silence_audio_158.pt +3 -0
- assets/silence_audio_175.pt +3 -0
- assets/silence_audio_243.pt +3 -0
- assets/silence_audio_73.pt +3 -0
- assets/silence_audio_90.pt +3 -0
- docs/api.md +168 -0
- docs/assets/research/README.md +162 -0
- docs/assets/research/illustrated_method_provenance.json +101 -0
- docs/assets/research/meridian_architecture.png +3 -0
- docs/assets/research/meridian_architecture.svg +0 -0
- docs/assets/research/meridian_illustrated_method.png +3 -0
- docs/assets/research/meridian_illustrated_method.svg +0 -0
- docs/assets/research/meridian_method.png +3 -0
- docs/assets/research/meridian_method.svg +0 -0
- docs/assets/research/meridian_nba_generation.png +3 -0
- docs/assets/research/meridian_nba_generation.svg +0 -0
- docs/assets/research/meridian_poses.png +0 -0
- docs/assets/research/meridian_poses.svg +38 -0
- docs/assets/research/method_provenance.json +29 -0
- docs/assets/research/nba_method_provenance.json +41 -0
- docs/inference.md +296 -0
- docs/installation.md +189 -0
- docs/method.md +169 -0
- docs/release_checklist.md +35 -0
- docs/research.html +242 -0
- docs/research.md +159 -0
- docs/studio.md +210 -0
- docs/studio_walkthrough.md +251 -0
- docs/training.md +46 -0
- examples/CREDITS.md +13 -0
- examples/media/sp_bouldering_hang.mp4 +3 -0
.gitattributes
ADDED
|
@@ -0,0 +1,96 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
*.7z filter=lfs diff=lfs merge=lfs -text
|
| 2 |
+
*.arrow filter=lfs diff=lfs merge=lfs -text
|
| 3 |
+
*.bin filter=lfs diff=lfs merge=lfs -text
|
| 4 |
+
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
| 5 |
+
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
| 6 |
+
*.ftz filter=lfs diff=lfs merge=lfs -text
|
| 7 |
+
*.gz filter=lfs diff=lfs merge=lfs -text
|
| 8 |
+
*.h5 filter=lfs diff=lfs merge=lfs -text
|
| 9 |
+
*.joblib filter=lfs diff=lfs merge=lfs -text
|
| 10 |
+
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
| 11 |
+
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
| 12 |
+
*.model filter=lfs diff=lfs merge=lfs -text
|
| 13 |
+
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
| 14 |
+
*.npy filter=lfs diff=lfs merge=lfs -text
|
| 15 |
+
*.npz filter=lfs diff=lfs merge=lfs -text
|
| 16 |
+
*.onnx filter=lfs diff=lfs merge=lfs -text
|
| 17 |
+
*.ot filter=lfs diff=lfs merge=lfs -text
|
| 18 |
+
*.parquet filter=lfs diff=lfs merge=lfs -text
|
| 19 |
+
*.pb filter=lfs diff=lfs merge=lfs -text
|
| 20 |
+
*.pickle filter=lfs diff=lfs merge=lfs -text
|
| 21 |
+
*.pkl filter=lfs diff=lfs merge=lfs -text
|
| 22 |
+
*.pt filter=lfs diff=lfs merge=lfs -text
|
| 23 |
+
*.pth filter=lfs diff=lfs merge=lfs -text
|
| 24 |
+
*.rar filter=lfs diff=lfs merge=lfs -text
|
| 25 |
+
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
| 26 |
+
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
| 27 |
+
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
| 28 |
+
*.tar filter=lfs diff=lfs merge=lfs -text
|
| 29 |
+
*.tflite filter=lfs diff=lfs merge=lfs -text
|
| 30 |
+
*.tgz filter=lfs diff=lfs merge=lfs -text
|
| 31 |
+
*.wasm filter=lfs diff=lfs merge=lfs -text
|
| 32 |
+
*.xz filter=lfs diff=lfs merge=lfs -text
|
| 33 |
+
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
+
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
+
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
docs/assets/research/meridian_architecture.png filter=lfs diff=lfs merge=lfs -text
|
| 37 |
+
docs/assets/research/meridian_illustrated_method.png filter=lfs diff=lfs merge=lfs -text
|
| 38 |
+
docs/assets/research/meridian_method.png filter=lfs diff=lfs merge=lfs -text
|
| 39 |
+
docs/assets/research/meridian_nba_generation.png filter=lfs diff=lfs merge=lfs -text
|
| 40 |
+
examples/media/sp_bouldering_hang.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 41 |
+
examples/media/sp_bouldering_reach.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 42 |
+
videos-all/meridian_ballet_t30_female_arc/out.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 43 |
+
videos-all/meridian_ballet_t30_male_lowarc/out.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 44 |
+
videos-all/meridian_longtake_l150_nba3_apex_right14_175/out.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 45 |
+
videos-all/meridian_longtake_l150_nba3_apex_right14_175/render.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 46 |
+
videos-all/meridian_longtake_l150_nba3_apex_right14_175/source.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 47 |
+
videos-all/meridian_longtake_t30_gymnast_pink_rise12/out.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 48 |
+
videos-all/meridian_longtake_t30_gymnast_pink_rise12/source.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 49 |
+
videos-all/meridian_longtake_t30_moto_dust_retreat25/out.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 50 |
+
videos-all/meridian_longtake_t30_moto_dust_retreat25/source.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 51 |
+
videos-all/meridian_longtake_t30_powder_frontal_rise18/out.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 52 |
+
videos-all/meridian_longtake_t30_powder_frontal_rise18/source.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 53 |
+
videos-all/meridian_material_l150_charge_event_return22/out.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 54 |
+
videos-all/meridian_material_l150_charge_event_return22/source.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 55 |
+
videos-all/meridian_motion_l150_moto_event_return30/out.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 56 |
+
videos-all/meridian_motion_l150_moto_event_return30/source.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 57 |
+
videos-all/meridian_nba3_l150_air_left14/out.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 58 |
+
videos-all/meridian_nba3_l150_air_right14/out.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 59 |
+
videos-all/meridian_nba3_l150_moment38_left14/out.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 60 |
+
videos-all/meridian_nba3_l150_moment54_right14/out.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 61 |
+
videos-all/meridian_return_l150_berry_event22/out.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 62 |
+
videos-all/meridian_return_l150_berry_event22/source.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 63 |
+
videos-all/nba3_teacher30/nba3_full_event.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 64 |
+
videos-all/overnight/sources/dutch_ballet_female_2575.png filter=lfs diff=lfs merge=lfs -text
|
| 65 |
+
videos-all/overnight/sources/dutch_ballet_male_1900.png filter=lfs diff=lfs merge=lfs -text
|
| 66 |
+
videos-all/research_examples_v1/ballet.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 67 |
+
videos-all/research_examples_v1/ballet_male.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 68 |
+
videos-all/research_examples_v1/berry.jpg filter=lfs diff=lfs merge=lfs -text
|
| 69 |
+
videos-all/research_examples_v1/berry.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 70 |
+
videos-all/research_examples_v1/charge.jpg filter=lfs diff=lfs merge=lfs -text
|
| 71 |
+
videos-all/research_examples_v1/charge.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 72 |
+
videos-all/research_examples_v1/gymnast.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 73 |
+
videos-all/research_examples_v1/moto.jpg filter=lfs diff=lfs merge=lfs -text
|
| 74 |
+
videos-all/research_examples_v1/moto.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 75 |
+
videos-all/research_examples_v1/moto_return.jpg filter=lfs diff=lfs merge=lfs -text
|
| 76 |
+
videos-all/research_examples_v1/moto_return.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 77 |
+
videos-all/research_examples_v1/nba.jpg filter=lfs diff=lfs merge=lfs -text
|
| 78 |
+
videos-all/research_examples_v1/nba.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 79 |
+
videos-all/research_examples_v1/powder.jpg filter=lfs diff=lfs merge=lfs -text
|
| 80 |
+
videos-all/research_examples_v1/powder.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 81 |
+
videos-all/research_examples_v1/robot.jpg filter=lfs diff=lfs merge=lfs -text
|
| 82 |
+
videos-all/research_examples_v1/robot.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 83 |
+
videos-all/studio_walkthrough/nba3_preview_live_02/studio_walkthrough_concise.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 84 |
+
videos-all/studio_walkthrough/nba3_preview_live_02/studio_walkthrough_concise_poster.jpg filter=lfs diff=lfs merge=lfs -text
|
| 85 |
+
videos-all/teaser_meridian_showcase_v7.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 86 |
+
videos-all/va_pi3_hi/out.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 87 |
+
videos-all/va_pi3_hi/source.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 88 |
+
videos-all/research_examples_v2/motor_compound.jpg filter=lfs diff=lfs merge=lfs -text
|
| 89 |
+
videos-all/teaser_meridian_compound_motor_dust_explained_v1.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 90 |
+
videos-all/meridian_ballet_l150_female_reverse45.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 91 |
+
videos-all/longtake_edit/multisegment/work_gpu3/takes/1789313901_4e9dd3_11/source.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 92 |
+
videos-all/longtake_edit/multisegment/work_gpu3/takes/1789313901_4e9dd3_11/out.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 93 |
+
videos-all/meridian_ballet_l150_female_reverse45/out.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 94 |
+
assets/meridian_method.png filter=lfs diff=lfs merge=lfs -text
|
| 95 |
+
videos-all/teaser_meridian_showcase_v9.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 96 |
+
videos-all/teaser_meridian_showcase_v12.mp4 filter=lfs diff=lfs merge=lfs -text
|
LICENSE
ADDED
|
@@ -0,0 +1,84 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
MiniMax H3 COMMUNITY LICENSE AGREEMENT
|
| 2 |
+
MiniMax H3 release date/License date: August 2, 2026.
|
| 3 |
+
The scope of this License Agreement (this “Agreement”) is expressly limited to the “Applicable Territory” as defined below.
|
| 4 |
+
By clicking to accept, or by using, reproducing, modifying, distributing, running, or displaying any portion or element of the MiniMax H3 Works (including through any Hosted Services) in any manner, you acknowledge and accept the terms of this Agreement, and this Agreement shall take immediate effect upon the occurrence of such act.
|
| 5 |
+
I. Definitions
|
| 6 |
+
1. “Acceptable Use Policy” means the policy published by MiniMax in Exhibit A.
|
| 7 |
+
2. “Agreement” means the terms and conditions set forth herein that govern the use, reproduction, distribution, modification, running, and display of the MiniMax H3 Works or any portion or element thereof.
|
| 8 |
+
3. “Applicable Territory” means worldwide, excluding the Excluded Territories.
|
| 9 |
+
4. “Documentation” means the specifications, manuals, and documentation concerning MiniMax H3 that are publicly released by MiniMax.
|
| 10 |
+
5. “Excluded Territories” means the European Union, the United Kingdom, the Republic of Korea and the United States of America.
|
| 11 |
+
6. “MiniMax H3” means the video generation model, together with its software and algorithms, including trained model weights, parameters (including optimizer states), machine-learning model code, inference-supporting code, and other elements thereof made publicly available by Us, as released at https://huggingface.co/MiniMaxAI/MiniMax-H3.
|
| 12 |
+
7. “MiniMax H3 Works” means (i) the Materials, (ii) the Model Derivatives, and (iii) all derivatives thereof.
|
| 13 |
+
8. “Hosted Services” means hosted services provided via application programming interfaces (APIs), web access, or any other electronic or remote means.
|
| 14 |
+
9. “Licensee,” “you,” or “your” means the natural or legal person exercising rights and/or using the MiniMax H3 Works for any purpose in any field of use under this Agreement.
|
| 15 |
+
10. “Materials” means, collectively, MiniMax H3 and the Documentation (and any portion thereof), in each case as made available by MiniMax under this Agreement and proprietary to MiniMax.
|
| 16 |
+
11. “Model Derivatives” means all of the following: (i) any modification of MiniMax H3 or any Model Derivative thereof; (ii) any work based on MiniMax H3 or any Model Derivative thereof; or (iii) any other machine learning model created by transferring the patterns of the weights, parameters, operational patterns, or Outputs of MiniMax H3 or any Model Derivative thereof to another model, such that the latter model exhibits behavior similar to MiniMax H3 or its Model Derivatives, including by distillation methods, methods using intermediate data representations, or methods based on training using synthetic-data Outputs generated by MiniMax H3 or its Model Derivatives. For the avoidance of doubt, Outputs are not deemed Model Derivatives.
|
| 17 |
+
12. “Output” means any result of operating or otherwise using MiniMax H3 or any Model Derivatives (including through Hosted Services).
|
| 18 |
+
13. “Third Party” means any natural or legal person that is not under common control with us or with you.
|
| 19 |
+
14. “Including” means “including but not limited to.”
|
| 20 |
+
15. “We,” “Us” or “MiniMax” means Nanonoble Pte. Ltd..
|
| 21 |
+
II. Grant of Rights
|
| 22 |
+
Solely within the Applicable Territory, we grant you a non-exclusive, non-transferable, royalty-free, limited license to use, reproduce, distribute, create derivative works (including Model Derivatives), and modify the Materials in accordance with the terms of this Agreement and the Acceptable Use Policy, based on the intellectual property and other rights owned by MiniMax that are embodied in or used by the Materials. You shall not violate (or encourage or permit any person to violate) any term of this Agreement or the Acceptable Use Policy.
|
| 23 |
+
We will continuously evaluate the applicable laws, regulations and compliance requirements for the Excluded Territories. In the meantime, should any person in such Excluded Territories be interested in deploying our models, you are welcome to contact us about obtaining a license, which will be granted based on robust controls and guardrails for purposes of complying with the laws, regulations and compliance requirements of the Excluded Territories.
|
| 24 |
+
III. Distribution and Redistribution
|
| 25 |
+
Subject to and conditioned on your continuing compliance with this Agreement, including its territorial restrictions and the Acceptable Use Policy, and solely within the Applicable Territory, you may distribute or make available the MiniMax H3 Works to Third Parties within the Applicable Territory; provided, that all of the following conditions are met:
|
| 26 |
+
1. You must provide a copy of this Agreement to all such Third Parties who receive the MiniMax H3 Works or use your products or services related thereto;
|
| 27 |
+
2. You must cause any modified files to carry prominent notices stating that you have modified such files;
|
| 28 |
+
3. You are encouraged to:
|
| 29 |
+
a. display a notice on any product or service developed using MiniMax H3 indicating that the product or service is “Powered by MiniMax H3”;
|
| 30 |
+
b. add an AI-generation identifier to files produced using generative AI models including MiniMax H3; and
|
| 31 |
+
c. publish at least one technical blog post or a public statement describing your experience using MiniMax H3 Works;
|
| 32 |
+
4. All distributions to Third Parties (other than through Hosted Services) must be accompanied by a “NOTICE” text file containing the following notice:
|
| 33 |
+
“MiniMax H3 is licensed under the MiniMax H3 Community License Agreement, Copyright © 2026 MiniMax. All Rights Reserved.”
|
| 34 |
+
You may add your own copyright notices on your modifications; except as provided in this Section and in Section V, however, you may not impose additional or different terms and conditions on the use, reproduction, or distribution of your modifications or of any aggregate Model Derivatives, and your use, reproduction, modification, distribution, running, and display of the work must otherwise comply with the terms and conditions of this Agreement (including the provisions concerning the Applicable Territory). If you receive the MiniMax H3 Works from a Licensee as part of an integrated end-user product, the provisions of Section III of this Agreement do not apply to you, but Section V and Exhibit A remain applicable.
|
| 35 |
+
IV. Additional Commercial Terms
|
| 36 |
+
1. You shall obtain a separate, prior written authorization from MiniMax by contacting api@minimax.io with the subject line “MiniMax H3 licensing - authorization request”, if your commercial products and services generate more than 20 million US dollars (or equivalent in other currencies) in yearly revenue.
|
| 37 |
+
2. You shall prominently display “MiniMax H3”on the user interface of commercial product or service that uses MiniMax H3 or MiniMax H3 Works.
|
| 38 |
+
V. Use Restrictions
|
| 39 |
+
1. Your use of the MiniMax H3 Works must comply with applicable laws and regulations (including trade-compliance laws and regulations) and must comply with the Acceptable Use Policy for the MiniMax H3 Works, which is incorporated into this Agreement by reference.
|
| 40 |
+
2. Before providing access to the MiniMax H3 Works or any product, service, or Hosted Service incorporating them, you must bind each recipient or user to enforceable terms at least as protective as the use restrictions in this Section V and Exhibit A, and you must notify each recipient or user that those restrictions apply.
|
| 41 |
+
3. You may not use the MiniMax H3 Works or any of their Outputs or results to improve any other artificial intelligence model (other than MiniMax H3 or its Model Derivatives).
|
| 42 |
+
4. You may not use, reproduce, modify, distribute, or display the MiniMax H3 Works or any of their Outputs or results outside the Applicable Territory. Any such use outside the Applicable Territory is not authorized by this Agreement.
|
| 43 |
+
5. If you provide or make available to any Third Party a product, service, or Hosted Service that permits the generation of Outputs using MiniMax H3 or any Model Derivative, you must, before making that product or service available and throughout its operation, implement, maintain, test, and periodically review reasonable and proportionate technical and organizational safeguards designed to prevent and mitigate access, uses, and Outputs that violate this Section V or Exhibit A, including uses or Outputs that infringe, misappropriate, or otherwise violate any Third Party’s intellectual-property or other rights. You must not knowingly disable, materially weaken, or permit the circumvention of those safeguards. You must maintain a reasonably accessible mechanism for reporting suspected violations. Upon receiving a good-faith report or otherwise obtaining actual knowledge of a violation, you must promptly investigate and take reasonable steps within your control to stop or mitigate the violation, including removing or disabling access to offending content or services and suspending or terminating repeat violators where appropriate. You are responsible for implementing and enforcing these requirements with respect to your products, services, systems, users, and downstream recipients.
|
| 44 |
+
VI. Intellectual Property
|
| 45 |
+
1. Subject to MiniMax’s rights in the MiniMax H3 Works (and the intellectual property therein), and to your compliance with the terms and conditions of this Agreement, as between you and MiniMax, you will own the derivative works and modifications of the Materials that you have created or had created, as well as any Model Derivatives.
|
| 46 |
+
2. Except for the limited license expressly granted in this paragraph, no trademark license is granted under this Agreement; with respect to MiniMax H3 Works, the Licensee may not use any name or mark owned by or associated with MiniMax or any of its affiliates, except as reasonably and customarily necessary to describe and distribute the MiniMax H3 Works. MiniMax hereby grants you a license to use the “MiniMax H3” mark (the “Mark”) within the Applicable Territory solely for the purpose of complying with Section III.3; provided, that you comply with all applicable trademark-protection laws. All goodwill arising from your use of the Mark shall inure to the benefit of MiniMax.
|
| 47 |
+
3. If you bring or assert any suit or other legal proceeding (including a cross-claim or counterclaim in any action) against us or any other natural or legal person alleging that the Materials, any Output, or any portion of the foregoing infringes any intellectual property right or other right owned by you or for which you can obtain a license, all licenses granted to you under this Agreement will terminate as of the date such suit or proceeding is filed. You shall defend, indemnify, and hold us harmless against any Third-Party claim arising out of or related to the use or distribution of the MiniMax H3 Works by you or by any Third Party.
|
| 48 |
+
4. MiniMax claims no rights over the Outputs you generate. You and your users are entirely responsible for the Outputs and any subsequent use thereof.
|
| 49 |
+
VII. Disclaimers and Limitations of Liability
|
| 50 |
+
1. We have no obligation to support, update, provide training for, or develop any further version of the MiniMax H3 Works, or to grant any license with respect thereto.
|
| 51 |
+
2. UNLESS AND ONLY TO THE EXTENT REQUIRED BY APPLICABLE LAW, THE MINIMAX H3 WORKS AND ANY OUTPUT AND RESULTS THEREFROM ARE PROVIDED “AS IS” WITHOUT ANY EXPRESS OR IMPLIED WARRANTIES OF ANY KIND INCLUDING ANY WARRANTIES OF TITLE, MERCHANTABILITY, NONINFRINGEMENT, COURSE OF DEALING, USAGE OF TRADE, OR FITNESS FOR A PARTICULAR PURPOSE. YOU ARE SOLELY RESPONSIBLE FOR DETERMINING THE APPROPRIATENESS OF USING, REPRODUCING, MODIFYING, PERFORMING, DISPLAYING OR DISTRIBUTING ANY OF THE MINIMAX H3 WORKS OR OUTPUTS AND ASSUME ANY AND ALL RISKS ASSOCIATED WITH YOUR OR A THIRD PARTY’S USE OR DISTRIBUTION OF ANY OF THE MINIMAX H3 WORKS OR OUTPUTS AND YOUR EXERCISE OF RIGHTS AND PERMISSIONS UNDER THIS AGREEMENT.
|
| 52 |
+
3. TO THE FULLEST EXTENT PERMITTED BY APPLICABLE LAW, IN NO EVENT SHALL MINIMAX OR ITS AFFILIATES BE LIABLE UNDER ANY THEORY OF LIABILITY, WHETHER IN CONTRACT, TORT, NEGLIGENCE, PRODUCTS LIABILITY, OR OTHERWISE, FOR ANY DAMAGES, INCLUDING ANY DIRECT, INDIRECT, SPECIAL, INCIDENTAL, EXEMPLARY, CONSEQUENTIAL OR PUNITIVE DAMAGES, OR LOST PROFITS OF ANY KIND ARISING FROM THIS AGREEMENT OR RELATED TO ANY OF THE MINIMAX H3 WORKS OR OUTPUTS, EVEN IF MINIMAX OR ITS AFFILIATES HAVE BEEN ADVISED OF THE POSSIBILITY OF ANY OF THE FOREGOING.
|
| 53 |
+
VIII. Term and Termination
|
| 54 |
+
1. This Agreement is effective from the moment you accept this Agreement or begin accessing the Materials, and, subject to your compliance with its terms and conditions, will remain in effect until terminated as provided herein.
|
| 55 |
+
2. If you breach any term or condition of this Agreement, we have the right to terminate this Agreement. Upon termination, you must immediately cease accessing, using, and distributing the MiniMax H3 Works; delete or destroy all copies within your possession or control; and notify each downstream recipient that your authorization has ended. The obligations in the preceding sentence and Sections VI.1, VI.3, VII, and IX survive termination.
|
| 56 |
+
IX. Governing Law and Jurisdiction
|
| 57 |
+
1. This Agreement, and any dispute arising out of or related to this Agreement, shall be governed by the laws of the Hong Kong Special Administrative Region of the People’s Republic of China, without regard to its conflict-of-laws rules. The United Nations Convention on Contracts for the International Sale of Goods does not apply to this Agreement.
|
| 58 |
+
2. Any dispute arising out of or related to this Agreement shall be subject to the exclusive jurisdiction of the courts of the Hong Kong Special Administrative Region of the People’s Republic of China with competent jurisdiction. Both MiniMax and the Licensee hereby consent to the exclusive jurisdiction of such courts for any such dispute.
|
| 59 |
+
Additional Note: Please note that the encoder of MiniMax H3 uses Qwen3-VL-32B, which is licensed under Apache 2.0 License: https://github.com/QwenLM/Qwen3-VL/blob/main/LICENSE.
|
| 60 |
+
|
| 61 |
+
Exhibit A — Acceptable Use Policy
|
| 62 |
+
MiniMax reserves the right to update this Acceptable Use Policy from time to time.
|
| 63 |
+
Last revised: August 2, 2026.
|
| 64 |
+
MiniMax is committed to promoting the safe and fair use of its tools and features, including MiniMax H3. You agree not to use MiniMax H3, any Model Derivatives, or any Output in any of the following ways:
|
| 65 |
+
1. Use outside the Applicable Territory;
|
| 66 |
+
2. Use in any manner that violates any applicable national, federal, state, local, or international law, regulation, or other legal requirement, or that infringes, misappropriates, or otherwise violates any Third Party’s intellectual-property or other proprietary rights, including through unauthorized reproduction, distribution, public display, public performance, or creation of derivative works;
|
| 67 |
+
3. Use in any manner that may harm yourself or others;
|
| 68 |
+
4. Use to repurpose or distribute the Outputs of MiniMax H3 or any Model Derivatives in order to harm yourself or others;
|
| 69 |
+
5. Use to circumvent or bypass any safety guardrails or safeguards we have implemented;
|
| 70 |
+
6. Use in any manner that exploits or harms, or intends to exploit or harm, minors;
|
| 71 |
+
7. Use to generate or disseminate verifiably false information and/or content for the purpose of harming others or influencing elections;
|
| 72 |
+
8. Use to manufacture or facilitate false online engagement, including fake reviews and other means of false online engagement;
|
| 73 |
+
9. Use to intentionally defame, disparage, or otherwise harass others;
|
| 74 |
+
10. Use to generate and/or disseminate malware (including ransomware) or any other content intended to damage electronic systems;
|
| 75 |
+
11. Use to generate or disseminate personally identifiable information for the purpose of harming others;
|
| 76 |
+
12. Use to generate or disseminate information (including images, code, posts, or articles) in or to any public environment (including via bot tweets or similar means) without clearly and prominently disclosing that such information and/or content is machine-generated;
|
| 77 |
+
13. Use to impersonate another person without that person’s consent, authorization, or lawful right to do so;
|
| 78 |
+
14. Use to make high-risk automated decisions in critical domains that affect individual safety, rights, or well-being (such as law enforcement, immigration, healthcare or medical services, critical-infrastructure management, product-safety components, essential services, credit, employment, housing, education, social scoring, or insurance);
|
| 79 |
+
15. Use in any manner that violates or disregards the social, ethical, or moral standards of other countries or regions;
|
| 80 |
+
16. Use to carry out, assist, threaten, incite, plan, advocate for, or encourage violent extremism or terrorism;
|
| 81 |
+
17. Use for any purpose intended to discriminate against, or harm, individuals or groups based on protected characteristics or categories, online or offline social behavior, or known or predicted personality traits;
|
| 82 |
+
18. Use to intentionally exploit the vulnerabilities of specific populations based on age, social, physical, or psychological characteristics, so as to materially distort the behavior of a member of that group in a manner that causes, or is likely to cause, physical or psychological harm to that person or to others;
|
| 83 |
+
19. Use for military purposes;
|
| 84 |
+
20. Use to engage in any unauthorized or unlicensed professional activity, including but not limited to financial, legal, medical or healthcare, or other professional practice.
|
LICENSE-CODE
ADDED
|
@@ -0,0 +1,201 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
Apache License
|
| 2 |
+
Version 2.0, January 2004
|
| 3 |
+
http://www.apache.org/licenses/
|
| 4 |
+
|
| 5 |
+
TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
|
| 6 |
+
|
| 7 |
+
1. Definitions.
|
| 8 |
+
|
| 9 |
+
"License" shall mean the terms and conditions for use, reproduction,
|
| 10 |
+
and distribution as defined by Sections 1 through 9 of this document.
|
| 11 |
+
|
| 12 |
+
"Licensor" shall mean the copyright owner or entity authorized by
|
| 13 |
+
the copyright owner that is granting the License.
|
| 14 |
+
|
| 15 |
+
"Legal Entity" shall mean the union of the acting entity and all
|
| 16 |
+
other entities that control, are controlled by, or are under common
|
| 17 |
+
control with that entity. For the purposes of this definition,
|
| 18 |
+
"control" means (i) the power, direct or indirect, to cause the
|
| 19 |
+
direction or management of such entity, whether by contract or
|
| 20 |
+
otherwise, or (ii) ownership of fifty percent (50%) or more of the
|
| 21 |
+
outstanding shares, or (iii) beneficial ownership of such entity.
|
| 22 |
+
|
| 23 |
+
"You" (or "Your") shall mean an individual or Legal Entity
|
| 24 |
+
exercising permissions granted by this License.
|
| 25 |
+
|
| 26 |
+
"Source" form shall mean the preferred form for making modifications,
|
| 27 |
+
including but not limited to software source code, documentation
|
| 28 |
+
source, and configuration files.
|
| 29 |
+
|
| 30 |
+
"Object" form shall mean any form resulting from mechanical
|
| 31 |
+
transformation or translation of a Source form, including but
|
| 32 |
+
not limited to compiled object code, generated documentation,
|
| 33 |
+
and conversions to other media types.
|
| 34 |
+
|
| 35 |
+
"Work" shall mean the work of authorship, whether in Source or
|
| 36 |
+
Object form, made available under the License, as indicated by a
|
| 37 |
+
copyright notice that is included in or attached to the work
|
| 38 |
+
(an example is provided in the Appendix below).
|
| 39 |
+
|
| 40 |
+
"Derivative Works" shall mean any work, whether in Source or Object
|
| 41 |
+
form, that is based on (or derived from) the Work and for which the
|
| 42 |
+
editorial revisions, annotations, elaborations, or other modifications
|
| 43 |
+
represent, as a whole, an original work of authorship. For the purposes
|
| 44 |
+
of this License, Derivative Works shall not include works that remain
|
| 45 |
+
separable from, or merely link (or bind by name) to the interfaces of,
|
| 46 |
+
the Work and Derivative Works thereof.
|
| 47 |
+
|
| 48 |
+
"Contribution" shall mean any work of authorship, including
|
| 49 |
+
the original version of the Work and any modifications or additions
|
| 50 |
+
to that Work or Derivative Works thereof, that is intentionally
|
| 51 |
+
submitted to Licensor for inclusion in the Work by the copyright owner
|
| 52 |
+
or by an individual or Legal Entity authorized to submit on behalf of
|
| 53 |
+
the copyright owner. For the purposes of this definition, "submitted"
|
| 54 |
+
means any form of electronic, verbal, or written communication sent
|
| 55 |
+
to the Licensor or its representatives, including but not limited to
|
| 56 |
+
communication on electronic mailing lists, source code control systems,
|
| 57 |
+
and issue tracking systems that are managed by, or on behalf of, the
|
| 58 |
+
Licensor for the purpose of discussing and improving the Work, but
|
| 59 |
+
excluding communication that is conspicuously marked or otherwise
|
| 60 |
+
designated in writing by the copyright owner as "Not a Contribution."
|
| 61 |
+
|
| 62 |
+
"Contributor" shall mean Licensor and any individual or Legal Entity
|
| 63 |
+
on behalf of whom a Contribution has been received by Licensor and
|
| 64 |
+
subsequently incorporated within the Work.
|
| 65 |
+
|
| 66 |
+
2. Grant of Copyright License. Subject to the terms and conditions of
|
| 67 |
+
this License, each Contributor hereby grants to You a perpetual,
|
| 68 |
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
| 69 |
+
copyright license to reproduce, prepare Derivative Works of,
|
| 70 |
+
publicly display, publicly perform, sublicense, and distribute the
|
| 71 |
+
Work and such Derivative Works in Source or Object form.
|
| 72 |
+
|
| 73 |
+
3. Grant of Patent License. Subject to the terms and conditions of
|
| 74 |
+
this License, each Contributor hereby grants to You a perpetual,
|
| 75 |
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
| 76 |
+
(except as stated in this section) patent license to make, have made,
|
| 77 |
+
use, offer to sell, sell, import, and otherwise transfer the Work,
|
| 78 |
+
where such license applies only to those patent claims licensable
|
| 79 |
+
by such Contributor that are necessarily infringed by their
|
| 80 |
+
Contribution(s) alone or by combination of their Contribution(s)
|
| 81 |
+
with the Work to which such Contribution(s) was submitted. If You
|
| 82 |
+
institute patent litigation against any entity (including a
|
| 83 |
+
cross-claim or counterclaim in a lawsuit) alleging that the Work
|
| 84 |
+
or a Contribution incorporated within the Work constitutes direct
|
| 85 |
+
or contributory patent infringement, then any patent licenses
|
| 86 |
+
granted to You under this License for that Work shall terminate
|
| 87 |
+
as of the date such litigation is filed.
|
| 88 |
+
|
| 89 |
+
4. Redistribution. You may reproduce and distribute copies of the
|
| 90 |
+
Work or Derivative Works thereof in any medium, with or without
|
| 91 |
+
modifications, and in Source or Object form, provided that You
|
| 92 |
+
meet the following conditions:
|
| 93 |
+
|
| 94 |
+
(a) You must give any other recipients of the Work or
|
| 95 |
+
Derivative Works a copy of this License; and
|
| 96 |
+
|
| 97 |
+
(b) You must cause any modified files to carry prominent notices
|
| 98 |
+
stating that You changed the files; and
|
| 99 |
+
|
| 100 |
+
(c) You must retain, in the Source form of any Derivative Works
|
| 101 |
+
that You distribute, all copyright, patent, trademark, and
|
| 102 |
+
attribution notices from the Source form of the Work,
|
| 103 |
+
excluding those notices that do not pertain to any part of
|
| 104 |
+
the Derivative Works; and
|
| 105 |
+
|
| 106 |
+
(d) If the Work includes a "NOTICE" text file as part of its
|
| 107 |
+
distribution, then any Derivative Works that You distribute must
|
| 108 |
+
include a readable copy of the attribution notices contained
|
| 109 |
+
within such NOTICE file, excluding those notices that do not
|
| 110 |
+
pertain to any part of the Derivative Works, in at least one
|
| 111 |
+
of the following places: within a NOTICE text file distributed
|
| 112 |
+
as part of the Derivative Works; within the Source form or
|
| 113 |
+
documentation, if provided along with the Derivative Works; or,
|
| 114 |
+
within a display generated by the Derivative Works, if and
|
| 115 |
+
wherever such third-party notices normally appear. The contents
|
| 116 |
+
of the NOTICE file are for informational purposes only and
|
| 117 |
+
do not modify the License. You may add Your own attribution
|
| 118 |
+
notices within Derivative Works that You distribute, alongside
|
| 119 |
+
or as an addendum to the NOTICE text from the Work, provided
|
| 120 |
+
that such additional attribution notices cannot be construed
|
| 121 |
+
as modifying the License.
|
| 122 |
+
|
| 123 |
+
You may add Your own copyright statement to Your modifications and
|
| 124 |
+
may provide additional or different license terms and conditions
|
| 125 |
+
for use, reproduction, or distribution of Your modifications, or
|
| 126 |
+
for any such Derivative Works as a whole, provided Your use,
|
| 127 |
+
reproduction, and distribution of the Work otherwise complies with
|
| 128 |
+
the conditions stated in this License.
|
| 129 |
+
|
| 130 |
+
5. Submission of Contributions. Unless You explicitly state otherwise,
|
| 131 |
+
any Contribution intentionally submitted for inclusion in the Work
|
| 132 |
+
by You to the Licensor shall be under the terms and conditions of
|
| 133 |
+
this License, without any additional terms or conditions.
|
| 134 |
+
Notwithstanding the above, nothing herein shall supersede or modify
|
| 135 |
+
the terms of any separate license agreement you may have executed
|
| 136 |
+
with Licensor regarding such Contributions.
|
| 137 |
+
|
| 138 |
+
6. Trademarks. This License does not grant permission to use the trade
|
| 139 |
+
names, trademarks, service marks, or product names of the Licensor,
|
| 140 |
+
except as required for reasonable and customary use in describing the
|
| 141 |
+
origin of the Work and reproducing the content of the NOTICE file.
|
| 142 |
+
|
| 143 |
+
7. Disclaimer of Warranty. Unless required by applicable law or
|
| 144 |
+
agreed to in writing, Licensor provides the Work (and each
|
| 145 |
+
Contributor provides its Contributions) on an "AS IS" BASIS,
|
| 146 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
|
| 147 |
+
implied, including, without limitation, any warranties or conditions
|
| 148 |
+
of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
|
| 149 |
+
PARTICULAR PURPOSE. You are solely responsible for determining the
|
| 150 |
+
appropriateness of using or redistributing the Work and assume any
|
| 151 |
+
risks associated with Your exercise of permissions under this License.
|
| 152 |
+
|
| 153 |
+
8. Limitation of Liability. In no event and under no legal theory,
|
| 154 |
+
whether in tort (including negligence), contract, or otherwise,
|
| 155 |
+
unless required by applicable law (such as deliberate and grossly
|
| 156 |
+
negligent acts) or agreed to in writing, shall any Contributor be
|
| 157 |
+
liable to You for damages, including any direct, indirect, special,
|
| 158 |
+
incidental, or consequential damages of any character arising as a
|
| 159 |
+
result of this License or out of the use or inability to use the
|
| 160 |
+
Work (including but not limited to damages for loss of goodwill,
|
| 161 |
+
work stoppage, computer failure or malfunction, or any and all
|
| 162 |
+
other commercial damages or losses), even if such Contributor
|
| 163 |
+
has been advised of the possibility of such damages.
|
| 164 |
+
|
| 165 |
+
9. Accepting Warranty or Additional Liability. While redistributing
|
| 166 |
+
the Work or Derivative Works thereof, You may choose to offer,
|
| 167 |
+
and charge a fee for, acceptance of support, warranty, indemnity,
|
| 168 |
+
or other liability obligations and/or rights consistent with this
|
| 169 |
+
License. However, in accepting such obligations, You may act only
|
| 170 |
+
on Your own behalf and on Your sole responsibility, not on behalf
|
| 171 |
+
of any other Contributor, and only if You agree to indemnify,
|
| 172 |
+
defend, and hold each Contributor harmless for any liability
|
| 173 |
+
incurred by, or claims asserted against, such Contributor by reason
|
| 174 |
+
of your accepting any such warranty or additional liability.
|
| 175 |
+
|
| 176 |
+
END OF TERMS AND CONDITIONS
|
| 177 |
+
|
| 178 |
+
APPENDIX: How to apply the Apache License to your work.
|
| 179 |
+
|
| 180 |
+
To apply the Apache License to your work, attach the following
|
| 181 |
+
boilerplate notice, with the fields enclosed by brackets "[]"
|
| 182 |
+
replaced with your own identifying information. (Don't include
|
| 183 |
+
the brackets!) The text should be enclosed in the appropriate
|
| 184 |
+
comment syntax for the file format. We also recommend that a
|
| 185 |
+
file or class name and description of purpose be included on the
|
| 186 |
+
same "printed page" as the copyright notice for easier
|
| 187 |
+
identification within third-party archives.
|
| 188 |
+
|
| 189 |
+
Copyright [yyyy] [name of copyright owner]
|
| 190 |
+
|
| 191 |
+
Licensed under the Apache License, Version 2.0 (the "License");
|
| 192 |
+
you may not use this file except in compliance with the License.
|
| 193 |
+
You may obtain a copy of the License at
|
| 194 |
+
|
| 195 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 196 |
+
|
| 197 |
+
Unless required by applicable law or agreed to in writing, software
|
| 198 |
+
distributed under the License is distributed on an "AS IS" BASIS,
|
| 199 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 200 |
+
See the License for the specific language governing permissions and
|
| 201 |
+
limitations under the License.
|
MODIFICATIONS.md
ADDED
|
@@ -0,0 +1,62 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Modified files
|
| 2 |
+
|
| 3 |
+
Section III.2 of the MiniMax H3 Community License Agreement requires that modified files carry a
|
| 4 |
+
prominent notice saying so. This file is that notice.
|
| 5 |
+
|
| 6 |
+
Everything below is derived from [`MiniMaxAI/MiniMax-H3`](https://huggingface.co/MiniMaxAI/MiniMax-H3).
|
| 7 |
+
|
| 8 |
+
## `transformer/` — modified
|
| 9 |
+
|
| 10 |
+
**Every weight file in `transformer/` has been modified.** It started as the base model's `transformer/`
|
| 11 |
+
(the `fl2va` video transformer, 50 layers) and every parameter was updated by a full finetune on a
|
| 12 |
+
re-camera objective (source clip + a point-cloud render from a second camera → that camera's clip). The
|
| 13 |
+
architecture, `config.json` and tensor names are unchanged, so it is a drop-in replacement for the base
|
| 14 |
+
`transformer/`; the numbers in it are not the base model's numbers.
|
| 15 |
+
|
| 16 |
+
The file layout also differs: the finetune was written as one 61.7 GiB safetensors file and re-sharded
|
| 17 |
+
here, because HuggingFace rejects single files above 50 GB. The tensors and their contents are unchanged
|
| 18 |
+
by that re-sharding.
|
| 19 |
+
|
| 20 |
+
## `lora/pytorch_lora_weights.safetensors` — new
|
| 21 |
+
|
| 22 |
+
Not a MiniMax file. A rank-128 LoRA over the linear layers of `transformer/`, trained by us with DMD
|
| 23 |
+
distillation. It is a delta on the finetuned transformer above, not on the base model; loading it onto
|
| 24 |
+
the stock `transformer/` produces garbage. Its sampling grid is `--steps 4 --flow-shift 3`.
|
| 25 |
+
|
| 26 |
+
## `assets/fixed_embed_{n}.pt`, `assets/silence_audio_{n}.pt` — new
|
| 27 |
+
|
| 28 |
+
Not MiniMax files. Frozen text-conditioning tensors (one per supported output length) computed once
|
| 29 |
+
with the base model's own text encoder from the prompt in `assets/prompt.txt`, so that inference never
|
| 30 |
+
loads Qwen3-VL, and the audio latent of silence at each length. They are *outputs* of the base model's
|
| 31 |
+
encoders in the sense of Section I.12.
|
| 32 |
+
|
| 33 |
+
## `assets/prompt.txt` — new
|
| 34 |
+
|
| 35 |
+
Not a MiniMax file. The prompt text the embeddings above were computed from, included so that what
|
| 36 |
+
conditions every render is readable rather than opaque.
|
| 37 |
+
|
| 38 |
+
## `recam/`, `inference/`, `service/` — new
|
| 39 |
+
|
| 40 |
+
Not MiniMax files. Written by us against the public `diffusers` API (`recam/h3.py` calls the pipeline's
|
| 41 |
+
own layout builder and scheduler; nothing in `diffusers` is patched). Licensed under Apache 2.0
|
| 42 |
+
(`LICENSE-CODE`); each Python file carries an `SPDX-License-Identifier: Apache-2.0` header.
|
| 43 |
+
|
| 44 |
+
## Not included: VGGT-Omega
|
| 45 |
+
|
| 46 |
+
Inference depends on Meta's VGGT-Omega for geometry. It is not redistributed here (FAIR Noncommercial
|
| 47 |
+
Research License, gated weights); `recam/geometry.py` imports it from a path you provide. See README.md.
|
| 48 |
+
|
| 49 |
+
## `LICENSE`, `LICENSE-CODE`, `NOTICE`
|
| 50 |
+
|
| 51 |
+
`LICENSE` is the MiniMax H3 Community License Agreement, included unmodified as Section III.1 requires.
|
| 52 |
+
`LICENSE-CODE` is the Apache 2.0 text and covers the code directories only. `NOTICE` records the
|
| 53 |
+
attribution and that the weights are not Apache 2.0.
|
| 54 |
+
|
| 55 |
+
Sampling draws every noise tensor on the CPU from the seeded generator, so a `--seed` reproduces across
|
| 56 |
+
GPU models. The internal tooling drew them in a different order and on the device, so a seed does not
|
| 57 |
+
reproduce a take made with it.
|
| 58 |
+
|
| 59 |
+
## `examples/media/` — new
|
| 60 |
+
|
| 61 |
+
Two clips from Wikimedia Commons under CC0, cut to 73 frames at 1280 × 720 with the soundtrack removed.
|
| 62 |
+
Provenance in `examples/CREDITS.md`. Not MiniMax material.
|
NOTICE
ADDED
|
@@ -0,0 +1,22 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
MiniMax H3 is licensed under the MiniMax H3 Community License Agreement,
|
| 2 |
+
Copyright © 2026 MiniMax. All Rights Reserved.
|
| 3 |
+
|
| 4 |
+
---
|
| 5 |
+
|
| 6 |
+
Viggle-Recam is a Model Derivative of MiniMax H3, as that term is defined in
|
| 7 |
+
Section I.11 of the MiniMax H3 Community License Agreement. It is distributed
|
| 8 |
+
under that same Agreement, a copy of which is included in this repository as
|
| 9 |
+
LICENSE. See MODIFICATIONS.md for the list of files that were modified.
|
| 10 |
+
|
| 11 |
+
Powered by MiniMax H3.
|
| 12 |
+
|
| 13 |
+
Modifications and additions Copyright © 2026 Viggle AI.
|
| 14 |
+
|
| 15 |
+
The code in recam/, inference/ and service/ is licensed under the Apache
|
| 16 |
+
License 2.0 (LICENSE-CODE). The model weights are not.
|
| 17 |
+
|
| 18 |
+
This repository does not contain VGGT-Omega. Inference depends on it, and it is
|
| 19 |
+
distributed by Meta under the FAIR Noncommercial Research License; see README.md.
|
| 20 |
+
|
| 21 |
+
The two clips in examples/media/ are Wikimedia Commons material released under
|
| 22 |
+
CC0 1.0; see examples/CREDITS.md.
|
README.md
ADDED
|
@@ -0,0 +1,259 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: other
|
| 3 |
+
license_name: minimax-h3-community-license
|
| 4 |
+
license_link: LICENSE
|
| 5 |
+
base_model: MiniMaxAI/MiniMax-H3
|
| 6 |
+
pipeline_tag: video-to-video
|
| 7 |
+
tags:
|
| 8 |
+
- video-to-video
|
| 9 |
+
- novel-view-synthesis
|
| 10 |
+
- camera-control
|
| 11 |
+
- re-camera
|
| 12 |
+
---
|
| 13 |
+
|
| 14 |
+
# Meridian: A new perspective on space and time
|
| 15 |
+
|
| 16 |
+
By **Viggle AI** · built on **[MiniMax-H3](https://huggingface.co/MiniMaxAI/MiniMax-H3)** ·
|
| 17 |
+
geometry by **[VGGT-Omega](https://github.com/facebookresearch/vggt-omega)**
|
| 18 |
+
|
| 19 |
+
**One event. Anywhere. Anytime.**
|
| 20 |
+
|
| 21 |
+
**Meridian is a geometry-guided video model for authoring new observations of existing events.**
|
| 22 |
+
Revisit a recorded event from a new viewpoint. Let the action unfold, slow it down, or hold a
|
| 23 |
+
moment still—all while moving the camera along a path you choose.
|
| 24 |
+
You can also create a camera move from a single image.
|
| 25 |
+
|
| 26 |
+
[Quickstart](#quickstart) · [Method](#method)
|
| 27 |
+
|
| 28 |
+
<div class="film hero-film">
|
| 29 |
+
<video id="teaser-film" controls playsinline preload="none" width="100%" poster="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/longtake_showcase/teaser_v12/intro_059.jpg" src="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/teaser_meridian_showcase_v12.mp4" aria-label="Meridian teaser: a new perspective on space and time">
|
| 30 |
+
<a href="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/teaser_meridian_showcase_v12.mp4">Watch the Meridian teaser</a>.
|
| 31 |
+
</video>
|
| 32 |
+
<p class="film-caption">51-second teaser</p>
|
| 33 |
+
</div>
|
| 34 |
+
|
| 35 |
+
## See it in motion
|
| 36 |
+
|
| 37 |
+
The motocross example includes the original video and a diagram of the planned camera path.
|
| 38 |
+
The ballet example uses a single photograph. The NBA edit labels the parts taken from the original footage.
|
| 39 |
+
|
| 40 |
+
<table class="video-grid">
|
| 41 |
+
<tr>
|
| 42 |
+
<td width="50%" valign="top">
|
| 43 |
+
<video id="nba-film" controls playsinline preload="none" width="100%" poster="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/research_examples_v1/nba.jpg" src="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/research_examples_v1/nba.mp4" aria-label="NBA edit combining labeled source footage and generated views of held moments">
|
| 44 |
+
<a href="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/research_examples_v1/nba.mp4">Watch the example</a>.
|
| 45 |
+
</video>
|
| 46 |
+
<p><strong>A dunk.</strong> A new look at the same play. This edit combines generated views with original footage, including the dunk's finish.</p>
|
| 47 |
+
</td>
|
| 48 |
+
<td width="50%" valign="top">
|
| 49 |
+
<video id="berry-film" controls playsinline preload="none" width="100%" poster="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/research_examples_v1/berry.jpg" src="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/research_examples_v1/berry.mp4" aria-label="Strawberries: source time advances, holds while the camera moves, then resumes">
|
| 50 |
+
<a href="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/research_examples_v1/berry.mp4">Watch the example</a>.
|
| 51 |
+
</video>
|
| 52 |
+
<p><strong>Play. Hold. Resume.</strong> Pause the splash, move the camera, then let the action continue.</p>
|
| 53 |
+
</td>
|
| 54 |
+
</tr>
|
| 55 |
+
<tr>
|
| 56 |
+
<td width="50%" valign="top">
|
| 57 |
+
<video id="moto-film" controls playsinline preload="none" width="100%" poster="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/research_examples_v2/motor_compound.jpg" src="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/teaser_meridian_compound_motor_dust_explained_v1.mp4" aria-label="Motocross: one uncut take with a compound camera path, selected source video, and requested camera diagrams">
|
| 58 |
+
<a href="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/teaser_meridian_compound_motor_dust_explained_v1.mp4">Watch the example</a>.
|
| 59 |
+
</video>
|
| 60 |
+
<p><strong>Compose a camera path.</strong> Orbit, move sideways, and change distance—all in one continuous shot.</p>
|
| 61 |
+
</td>
|
| 62 |
+
<td width="50%" valign="top">
|
| 63 |
+
<video id="ballet-film" controls playsinline preload="none" width="100%" poster="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/research_examples_v2/ballet_reverse45.jpg" src="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/meridian_ballet_l150_female_reverse45.mp4" aria-label="Female ballet dancer: generated camera movement from one still image">
|
| 64 |
+
<a href="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/meridian_ballet_l150_female_reverse45.mp4">Watch the example</a>.
|
| 65 |
+
</video>
|
| 66 |
+
<p><strong>One image. Another viewpoint.</strong> A camera move from a single ballet photograph.</p>
|
| 67 |
+
</td>
|
| 68 |
+
</tr>
|
| 69 |
+
</table>
|
| 70 |
+
|
| 71 |
+
## Space and time, independently
|
| 72 |
+
|
| 73 |
+
| Choose… | What you can do |
|
| 74 |
+
|---|---|
|
| 75 |
+
| **Where to watch from** | Orbit, move in or out, slide sideways, or move up and down. Set the viewing direction and field of view. |
|
| 76 |
+
| **When to watch** | Choose a sequence, hold one frame, or slow down / speed up the input video before generation. |
|
| 77 |
+
| **How the two meet** | Move around a frozen moment, follow slow-motion action, or choose a new angle for a sped-up sequence. |
|
| 78 |
+
|
| 79 |
+
Bullet time is one combination—not the boundary of the model. To slow down or speed up the
|
| 80 |
+
action, retime the input video first. Then design the camera path over that timeline.
|
| 81 |
+
|
| 82 |
+
## Beyond the frame
|
| 83 |
+
|
| 84 |
+
A camera's position shapes how an event is seen: what draws our attention, what feels close,
|
| 85 |
+
and what remains outside the frame. Meridian explores keeping some of those choices open
|
| 86 |
+
after capture.
|
| 87 |
+
|
| 88 |
+
For filmmakers, this opens room to compose a new shot around an existing moment—not just edit
|
| 89 |
+
what the camera recorded, but generate another way of observing it. In the longer term, that
|
| 90 |
+
freedom could extend to viewers: choosing a perspective, following a subject, or lingering on
|
| 91 |
+
a detail rather than watching only a predetermined sequence.
|
| 92 |
+
|
| 93 |
+
**The event has passed. The choice of how to see it remains open.**
|
| 94 |
+
|
| 95 |
+
## Method
|
| 96 |
+
|
| 97 |
+

|
| 98 |
+
|
| 99 |
+
*The same moment in the input, warped reference, and output. The 3D points and cameras are schematic.*
|
| 100 |
+
|
| 101 |
+
**Choose the moment. Place the camera. Render the reference. Complete the view.**
|
| 102 |
+
|
| 103 |
+
1. **Build the geometry.** VGGT-Omega estimates depth and camera poses from the input video.
|
| 104 |
+
We use these estimates to turn the selected frames into colored 3D points.
|
| 105 |
+
2. **Render the new view.** For each output frame, choose a moment from the input and a camera
|
| 106 |
+
viewpoint. Render the corresponding points from that view, leaving uncovered regions grey.
|
| 107 |
+
3. **Generate the shot.** Meridian takes the input video and the matching rendered video as
|
| 108 |
+
references, then fills in missing regions and refines the image.
|
| 109 |
+
|
| 110 |
+
**Preview before generation.** Once the 3D points are available, rendering the reference is fast.
|
| 111 |
+
You can check the framing and camera motion, spot gaps in the view, and adjust the path before
|
| 112 |
+
running the video model.
|
| 113 |
+
|
| 114 |
+
## Model
|
| 115 |
+
|
| 116 |
+
Meridian uses **MiniMax-H3's transformer and VAE, without loading a text encoder at inference**.
|
| 117 |
+
The task's text embeddings are precomputed; the transformer architecture is unchanged.
|
| 118 |
+
|
| 119 |
+
| Component | Role |
|
| 120 |
+
|---|---|
|
| 121 |
+
| `transformer/` | Meridian's finetuned MiniMax-H3 checkpoint; 61.7 GiB in bf16. |
|
| 122 |
+
| `lora/` | Fast-inference adapter; 2.5 GiB. Default: `--steps 4 --flow-shift 3`, **3 forwards**. |
|
| 123 |
+
| `assets/` | Precomputed text embeddings, audio-layout assets, and the readable task prompt. |
|
| 124 |
+
|
| 125 |
+
**Use the adapter with Meridian's transformer, not the unmodified MiniMax-H3 checkpoint.**
|
| 126 |
+
|
| 127 |
+
- **Output:** 24 fps, aspect-matched 768-class canvas; 1344 × 768 for a 16:9 input.
|
| 128 |
+
- **Lengths:** 73, 90, 107, 124, 141, 158, 175, or 243 frames—approximately 3–10 seconds per take.
|
| 129 |
+
- **Included tools:** inference CLI, runtime assets, sample clips, and a prototype Studio.
|
| 130 |
+
|
| 131 |
+
## Install
|
| 132 |
+
|
| 133 |
+
Follow the **[installation guide](docs/installation.md)** for code, checkpoint setup, dependencies,
|
| 134 |
+
and the separately obtained VGGT-Omega geometry model. Inference requires Meridian's transformer
|
| 135 |
+
and adapter, the MiniMax-H3 VAE, and VGGT-Omega. Checkpoint availability and paths are listed in the guide.
|
| 136 |
+
|
| 137 |
+
The reference implementation runs on one high-memory CUDA GPU; memory and timings are reported below.
|
| 138 |
+
It does not currently expose quantization, CPU offloading, or multi-GPU sharding.
|
| 139 |
+
|
| 140 |
+
**Community: bring Meridian to smaller GPUs.** Keeping MiniMax-H3's architecture and omitting the
|
| 141 |
+
text encoder provides a starting point for adapting community memory-saving techniques. We welcome
|
| 142 |
+
work on quantization and CPU offloading toward consumer GPUs such as the **RTX 4090**. These are
|
| 143 |
+
integration targets, not supported or validated configurations in the current scripts.
|
| 144 |
+
|
| 145 |
+
Review the licenses before use: the code license does not cover the weights or remove
|
| 146 |
+
VGGT-Omega's noncommercial restrictions.
|
| 147 |
+
|
| 148 |
+
## Quickstart
|
| 149 |
+
|
| 150 |
+
After completing installation, including the separately supplied weights, run from the Meridian
|
| 151 |
+
directory. The included CC0 sample clips are already 24 fps and contain 73 frames each.
|
| 152 |
+
|
| 153 |
+
```bash
|
| 154 |
+
# A gentle 15° orbit over the live event.
|
| 155 |
+
python inference/sample.py --video examples/media/sp_bouldering_hang.mp4 \
|
| 156 |
+
--yaw 15 --sweep --ease --out out/orbit
|
| 157 |
+
|
| 158 |
+
# Play 24 frames, then hold frame 24 for 49 output frames while orbiting.
|
| 159 |
+
python inference/sample.py --video examples/media/sp_bouldering_reach.mp4 \
|
| 160 |
+
--yaw 35 --freeze 24:49 --out out/bullet
|
| 161 |
+
```
|
| 162 |
+
|
| 163 |
+
Open `out/orbit/grid.mp4` to compare **source → geometry reference → generated take**. The take is
|
| 164 |
+
`out.mp4`; `render.mp4` shows the geometric input with grey holes.
|
| 165 |
+
|
| 166 |
+
For your own footage, use a continuous shot exported at **constant 24 fps**. The CLI reads frames
|
| 167 |
+
by index: an ordinary take needs at least `start + frames` input frames. It does not normalize the
|
| 168 |
+
frame rate or detect cuts for you.
|
| 169 |
+
|
| 170 |
+
## Self-hosting the demo
|
| 171 |
+
|
| 172 |
+
<div class="film">
|
| 173 |
+
<video id="studio-film" controls playsinline preload="none" width="100%" poster="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/studio_walkthrough/nba3_preview_live_02/studio_walkthrough_concise_poster.jpg" src="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/studio_walkthrough/nba3_preview_live_02/studio_walkthrough_concise.mp4" aria-label="Early Studio demo: actual authoring and geometric preview, not final generation">
|
| 174 |
+
<a href="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/studio_walkthrough/nba3_preview_live_02/studio_walkthrough_concise.mp4">Watch the Studio walkthrough</a>.
|
| 175 |
+
</video>
|
| 176 |
+
<p class="film-caption">Designing a camera path and previewing the geometry.</p>
|
| 177 |
+
</div>
|
| 178 |
+
|
| 179 |
+
**Early prototype.** The Studio is a very basic, vibe-coded demo, not a production editor.
|
| 180 |
+
The walkthrough shows one simple way to use it.
|
| 181 |
+
|
| 182 |
+
```bash
|
| 183 |
+
CARD=0 bash service/run.sh --host 127.0.0.1 --port 8412
|
| 184 |
+
```
|
| 185 |
+
|
| 186 |
+
Open `http://127.0.0.1:8412` once the terminal prints `ready`.
|
| 187 |
+
|
| 188 |
+
Upload a clip, design a path with multiple camera keyframes, preview the geometry, then generate.
|
| 189 |
+
The browser provides **real-time 3D feedback** once geometry is loaded; full-path rendering and
|
| 190 |
+
final video generation are separate GPU operations, not real-time generative video.
|
| 191 |
+
|
| 192 |
+
The service has no authentication. The command above binds to loopback; do not expose this
|
| 193 |
+
prototype directly to the internet.
|
| 194 |
+
|
| 195 |
+
## Performance
|
| 196 |
+
|
| 197 |
+
Reported results on **one B200 with the service resident**, using the default adapter:
|
| 198 |
+
|
| 199 |
+
| Output length | Take generation | Peak GPU memory |
|
| 200 |
+
|---|---|---|
|
| 201 |
+
| 73 frames | ~36 s | 88 GiB |
|
| 202 |
+
| 124 frames | ~80 s | 89 GiB |
|
| 203 |
+
| 243 frames | ~150 s | 113 GiB |
|
| 204 |
+
|
| 205 |
+
Generation timings start with geometry prepared; upload processing and reconstruction are separate.
|
| 206 |
+
A 73-frame reference warp was reported at **0.24 s**, versus approximately 36 s for generation.
|
| 207 |
+
These are indicative measurements, not guarantees across GPUs, resolutions, or cache states.
|
| 208 |
+
|
| 209 |
+
## Limitations
|
| 210 |
+
|
| 211 |
+
Unseen surfaces are generated, not recovered.
|
| 212 |
+
|
| 213 |
+
- **Geometry robustness.** Meridian generally handles imperfect geometry well, but cannot reliably
|
| 214 |
+
recover from severe errors or a badly warped reference.
|
| 215 |
+
- **Large moves are less stable.** Full 360° orbits can work, but large viewpoint changes can cause
|
| 216 |
+
distortion, drift, or inconsistent details in newly visible areas.
|
| 217 |
+
- **Timing and continuity.** Retiming changes which input frames are used; it does not recover
|
| 218 |
+
missing motion. Separately generated clips may not join smoothly.
|
| 219 |
+
|
| 220 |
+
## Documentation and code
|
| 221 |
+
|
| 222 |
+
[Inference guide](docs/inference.md) — camera recipes, source timing, CLI options, and troubleshooting.
|
| 223 |
+
|
| 224 |
+
Implementation lives in `recam/`, the CLI in `inference/sample.py`, and the Studio in `service/`.
|
| 225 |
+
|
| 226 |
+
## License
|
| 227 |
+
|
| 228 |
+
- **Weights** (`transformer/`, `lora/`, `assets/*.pt`): the
|
| 229 |
+
[MiniMax H3 Community License Agreement](LICENSE). Meridian (released as Viggle-Recam) is a Model
|
| 230 |
+
Derivative of MiniMax-H3; `MODIFICATIONS.md` is the Section III.2 notice. Powered by MiniMax H3.
|
| 231 |
+
The Agreement licenses use
|
| 232 |
+
and distribution of the weights and their outputs in its Applicable Territory only, which excludes
|
| 233 |
+
the European Union, the United Kingdom, the Republic of Korea and the United States (Section I.3,
|
| 234 |
+
I.5, V.4); read it before you download.
|
| 235 |
+
- **Code** (`recam/`, `inference/`, `service/`): [Apache 2.0](LICENSE-CODE).
|
| 236 |
+
- **VGGT-Omega**: not included. FAIR Noncommercial Research License v1, obtained from Meta separately;
|
| 237 |
+
see [Install](#install).
|
| 238 |
+
- **Sample clips**: Wikimedia Commons, CC0; see [`examples/CREDITS.md`](examples/CREDITS.md).
|
| 239 |
+
|
| 240 |
+
## Intended use
|
| 241 |
+
|
| 242 |
+
Exploring new viewpoints and timing in footage you have the rights to, for previsualisation, editing,
|
| 243 |
+
and creative work. Do not use it to fabricate footage of real people or events presented as genuine,
|
| 244 |
+
and label what you generate as AI-generated. If you pass the weights on or host them, the Agreement
|
| 245 |
+
makes you bind your users to its
|
| 246 |
+
use restrictions and tell them so (Section V.2), keep safeguards on any generation service (V.5),
|
| 247 |
+
display "MiniMax H3" in a commercial product's interface (IV.2), and ask MiniMax for authorization above
|
| 248 |
+
US$20M yearly revenue (IV.1).
|
| 249 |
+
|
| 250 |
+
## Citation
|
| 251 |
+
|
| 252 |
+
```bibtex
|
| 253 |
+
@misc{viggle-meridian-2026,
|
| 254 |
+
title = {Meridian: A New Perspective on Space and Time},
|
| 255 |
+
author = {Viggle AI},
|
| 256 |
+
year = {2026},
|
| 257 |
+
url = {https://huggingface.co/Viggle/Meridian}
|
| 258 |
+
}
|
| 259 |
+
```
|
assets/fixed_embed_107.pt
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:d4718b3470b5a6c6067a0aca6f4e871b7f4a12a8bbf307e1abceb7f0af0883c7
|
| 3 |
+
size 5201189
|
assets/fixed_embed_124.pt
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:183d526456085985ba2447c8dad60e9dc14e65075e942a080a8818367e352edc
|
| 3 |
+
size 5324261
|
assets/fixed_embed_141.pt
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:3e123721344c414a0f6dd91c5ed2daf9d324c10377099140f5486c7444dde801
|
| 3 |
+
size 5324261
|
assets/fixed_embed_158.pt
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:599e7a4b2c1fef72c15e829675c336d18082a9d5a7d74e3d58c6c95f773aee1b
|
| 3 |
+
size 5447205
|
assets/fixed_embed_175.pt
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:9091ee16cbb2ea740e2acf883d22e282d0ea6f8aca5045584d300071eec8007f
|
| 3 |
+
size 5570277
|
assets/fixed_embed_243.pt
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:bb55b658f35c4ac654ba9d08b1cfeaf04295935a51d09857789f6d07b131391a
|
| 3 |
+
size 5959845
|
assets/fixed_embed_73.pt
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:9b297f2d18ead294f24b4c1a4fbd116049da19b833742f6c0c59d8f85478bf47
|
| 3 |
+
size 5078109
|
assets/fixed_embed_90.pt
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:a64703d16844bdda2724d3a262eafcfaf35522b97633a1d0743477350fd1eba3
|
| 3 |
+
size 5078109
|
assets/meridian_method.png
ADDED

|
Git LFS Details
|
assets/prompt.txt
ADDED
|
@@ -0,0 +1,16 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
subject_definitions:
|
| 2 |
+
<Video 1> is the source video for the editing task.
|
| 3 |
+
<Video 2> is a rough render of the same scene from the new camera: the pixels of <Video 1> re-projected through a point cloud, so wherever it shows content its colours, framing and layout are correct, and its flat mid-grey areas are holes where the source camera saw nothing.
|
| 4 |
+
|
| 5 |
+
summary:
|
| 6 |
+
[video editing + viewpoint change] The target video shows exactly the same scene as <Video 1>, at exactly the same moments in time, filmed by the second camera that <Video 2> was rendered from. Every subject, every piece of clothing, the background, the lighting and the whole performance are the ones in <Video 1>; only the camera differs, so the same things are seen from a different angle and at a different distance. The target video is <Video 2> completed: its framing and everything it shows are kept, and its grey holes are filled with what belongs there.
|
| 7 |
+
|
| 8 |
+
retention_analysis:
|
| 9 |
+
<Video 1> (source video editing): fully_preserved - the subjects, their faces, hair, build and clothing, the background, the props and the lighting are the same objects seen from a new viewpoint, and the motion and its timing are frame for frame the motion of <Video 1>. Nothing is added, removed or restyled.
|
| 10 |
+
<Video 2> (layout reference): fully_preserved - the camera path, the framing and the placement of everything it shows are kept exactly; its grey holes are not content and are filled in so that they agree with <Video 1>, and its speckles and jagged edges are cleaned up.
|
| 11 |
+
|
| 12 |
+
detailed_description:
|
| 13 |
+
[Shot 1] One continuous shot of the scene of <Video 1>, framed exactly as <Video 2> is, frame for frame. The subjects perform the motion of <Video 1> with the same timing, in the same place, under the same lighting. The camera moves exactly as the camera of <Video 2> does, and there is no cut.
|
| 14 |
+
|
| 15 |
+
overall_soundscape:
|
| 16 |
+
No music and no speech.
|
assets/silence_audio_107.pt
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:6577d82d196d13bdc38669a838c7c6c868c98489f96e58569a634143f1cc335b
|
| 3 |
+
size 47279
|
assets/silence_audio_124.pt
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:dbc857712537d96bff394a06db33cacc240dd116ec70e514ce3846d3318e467b
|
| 3 |
+
size 54703
|
assets/silence_audio_141.pt
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:62321eaf60a48cb717e20a7cc0ab1dfac1b0d22f034049ebb48cb4d49aca2b05
|
| 3 |
+
size 61871
|
assets/silence_audio_158.pt
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:753b60bcf9691c8ae19248c0b859694afe375d835829bd105050c5f0f47d24e9
|
| 3 |
+
size 69039
|
assets/silence_audio_175.pt
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:c15014f11f175fff5cfcf5dae7d5c8871e5259373e617ad95b029984d839c29a
|
| 3 |
+
size 76463
|
assets/silence_audio_243.pt
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:bc4d558711c836f98d938bab81ae6d510d56628d5eb5d3e09ebbd3635c4666a2
|
| 3 |
+
size 105391
|
assets/silence_audio_73.pt
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:18d9509a933724c73dc44ccd33e2a908e0b34107302657b12bf8a732901eb650
|
| 3 |
+
size 32936
|
assets/silence_audio_90.pt
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:1b802d4a18b75ef64298f34d2183c00acdc6bfd50548c0eaed868305351f813b
|
| 3 |
+
size 40104
|
docs/api.md
ADDED
|
@@ -0,0 +1,168 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Local studio API
|
| 2 |
+
|
| 3 |
+
[← Meridian](../README.md) · [Studio and deployment](studio.md) · [Method](method.md)
|
| 4 |
+
|
| 5 |
+
The FastAPI service exposes the same preparation and rendering operations used by the studio.
|
| 6 |
+
This is a development API for a trusted, single-GPU deployment—not an authenticated multi-user
|
| 7 |
+
service. Requests are plain JSON except for multipart upload. All source indices refer to the
|
| 8 |
+
**normalized 24 fps clip**, not the original upload's timestamps.
|
| 9 |
+
|
| 10 |
+
## Request flow
|
| 11 |
+
|
| 12 |
+
```text
|
| 13 |
+
/upload or /sample → /prepare → /warp → inspect → /render → /job/{job} → /take/{job}/{name}
|
| 14 |
+
```
|
| 15 |
+
|
| 16 |
+
`/prepare` must populate the source-span cache before `/warp` or `/render`. Keep the same `clip`,
|
| 17 |
+
`start`, and `span_end` across those calls. If that cache entry is evicted or the service restarts,
|
| 18 |
+
prepare again. Do not change requests while assuming a previously inspected preview still applies.
|
| 19 |
+
|
| 20 |
+
## Shared fields
|
| 21 |
+
|
| 22 |
+
| Field | Meaning |
|
| 23 |
+
|---|---|
|
| 24 |
+
| `clip` | ID returned by `/upload` or `/sample`. |
|
| 25 |
+
| `start` | First source frame of the prepared span, inclusive. |
|
| 26 |
+
| `span_end` | Last source frame of that span, inclusive. Must satisfy `0 <= start < span_end < clip.frames`. |
|
| 27 |
+
| `frames` | Output length. Use one of `73, 90, 107, 124, 141, 158, 175, 243` for generation. |
|
| 28 |
+
| `pivot` | Optional `[u, v]` in normalized source-image fractions; default `[0.5, 0.5]`. Sets the depth-scale neighborhood. |
|
| 29 |
+
| `pivot_frame` | Source frame at which to measure pivot depth; set it explicitly, normally to `start`. |
|
| 30 |
+
| `seed` | Generation seed, default `1234`. |
|
| 31 |
+
| `path` | List of at least two camera keys. |
|
| 32 |
+
|
| 33 |
+
The current API's per-endpoint validation is limited; unsupported output lengths may fail only when
|
| 34 |
+
loading conditioning assets. Validate requests before submitting expensive GPU work. Choose a
|
| 35 |
+
continuous source span: the browser avoids detected cuts, but the API does not enforce that policy.
|
| 36 |
+
|
| 37 |
+
### Camera keys
|
| 38 |
+
|
| 39 |
+
| Field | Meaning |
|
| 40 |
+
|---|---|
|
| 41 |
+
| `pos` | `[x, y, z]` position in the coordinate frame of the source camera at `start`, in units of `zm`. |
|
| 42 |
+
| `look` | Look-at point in the same frame and units. |
|
| 43 |
+
| `src` | Absolute source-frame index, within the prepared span. |
|
| 44 |
+
| `t` | Output-frame index. First key is `0`, last is `frames - 1`; intermediate values strictly increase. |
|
| 45 |
+
| `ease` | Optional boolean, default `false`. Eases camera position/look-at motion in the segment leaving this key. |
|
| 46 |
+
| `focal` | Optional positive focal multiplier, default `1`, relative to that source frame's estimated lens. |
|
| 47 |
+
|
| 48 |
+
Axes are **x right, y down, z forward**. Source indices must be non-decreasing. Position and look-at
|
| 49 |
+
points follow slope-limited cubic Hermite/Catmull-Rom interpolation; source indices and focal
|
| 50 |
+
multipliers interpolate linearly. Source indices are rounded to integers. Orientation is derived
|
| 51 |
+
from the look-at direction with zero roll. Equal adjacent `src` values create a hold.
|
| 52 |
+
|
| 53 |
+
## Minimal walkthrough
|
| 54 |
+
|
| 55 |
+
Start the [service](studio.md#start-the-service), then upload a continuous clip containing at least
|
| 56 |
+
73 normalized frames:
|
| 57 |
+
|
| 58 |
+
```bash
|
| 59 |
+
curl -sS -F 'file=@clip.mp4' http://127.0.0.1:8412/upload
|
| 60 |
+
```
|
| 61 |
+
|
| 62 |
+
Copy the response's `clip` value into the following JSON and save it as `take.json`. This example
|
| 63 |
+
slides the camera right by `0.15 zm` while looking toward a point one depth unit ahead of the initial
|
| 64 |
+
camera. For subject-specific framing, use the `piv` returned by `/prepare` as your look-at reference.
|
| 65 |
+
|
| 66 |
+
```json
|
| 67 |
+
{
|
| 68 |
+
"clip": "CLIP_ID_FROM_UPLOAD",
|
| 69 |
+
"start": 0,
|
| 70 |
+
"span_end": 72,
|
| 71 |
+
"frames": 73,
|
| 72 |
+
"pivot": [0.5, 0.5],
|
| 73 |
+
"pivot_frame": 0,
|
| 74 |
+
"seed": 1234,
|
| 75 |
+
"path": [
|
| 76 |
+
{"pos": [0, 0, 0], "look": [0, 0, 1], "src": 0, "t": 0, "ease": true, "focal": 1},
|
| 77 |
+
{"pos": [0.15, 0, 0], "look": [0, 0, 1], "src": 72, "t": 72, "ease": false, "focal": 1}
|
| 78 |
+
]
|
| 79 |
+
}
|
| 80 |
+
```
|
| 81 |
+
|
| 82 |
+
Prepare the geometry, then produce a preview. `/prepare` ignores the extra path fields:
|
| 83 |
+
|
| 84 |
+
```bash
|
| 85 |
+
curl -sS -H 'Content-Type: application/json' --data-binary @take.json \
|
| 86 |
+
http://127.0.0.1:8412/prepare
|
| 87 |
+
|
| 88 |
+
curl -sS -H 'Content-Type: application/json' --data-binary @take.json \
|
| 89 |
+
http://127.0.0.1:8412/warp
|
| 90 |
+
```
|
| 91 |
+
|
| 92 |
+
Open the returned `truth` and `holes` URLs relative to the service origin, and inspect `ahead`,
|
| 93 |
+
`moved`, and `speed`. Generation is a separate, expensive step:
|
| 94 |
+
|
| 95 |
+
```bash
|
| 96 |
+
curl -sS -H 'Content-Type: application/json' --data-binary @take.json \
|
| 97 |
+
http://127.0.0.1:8412/render
|
| 98 |
+
```
|
| 99 |
+
|
| 100 |
+
Copy the returned job ID into the commands below. Poll until `done` is true, and check that there is
|
| 101 |
+
**no `error`** before downloading; failed jobs also set `done: true`.
|
| 102 |
+
|
| 103 |
+
```bash
|
| 104 |
+
curl -sS http://127.0.0.1:8412/job/JOB_ID_FROM_RENDER
|
| 105 |
+
curl -f -o out.mp4 http://127.0.0.1:8412/take/JOB_ID_FROM_RENDER/out.mp4
|
| 106 |
+
```
|
| 107 |
+
|
| 108 |
+
`/render` does not enforce the browser's clearance or camera-change gates and does not require that
|
| 109 |
+
`/warp` was called first. This walkthrough includes preview inspection intentionally. A returned job
|
| 110 |
+
ID means the background task was started, not that input validation or generation succeeded.
|
| 111 |
+
|
| 112 |
+
## Endpoints
|
| 113 |
+
|
| 114 |
+
Paths below are relative to the service origin. “Shared fields” refers to the table above; not every
|
| 115 |
+
endpoint consumes every field.
|
| 116 |
+
|
| 117 |
+
| Endpoint | Request | Response |
|
| 118 |
+
|---|---|---|
|
| 119 |
+
| `GET /` | — | Studio HTML. |
|
| 120 |
+
| `GET /samples` | — | Array of available sample MP4 filenames. |
|
| 121 |
+
| `POST /upload` | Multipart `file`. | `{clip, frames, w, h, name, cuts, seconds, lengths}`. |
|
| 122 |
+
| `POST /sample` | `{name}` from `/samples`. | Same clip metadata as upload. |
|
| 123 |
+
| `POST /prepare` | `clip, start, span_end`; optional `pivot, pivot_frame`. | `{box, canvas, cond_canvas, ms, src_poses, piv, zm}`. |
|
| 124 |
+
| `POST /cloud` | Shared fields plus absolute source `frame`, optional `stride` (default `5`). | `{n, zm, pts, rgb}`; flattened triples in path coordinates. |
|
| 125 |
+
| `POST /warp1` | Shared fields plus `src, pos, look`; optional `focal`. | One geometry-reference JPEG at conditioning resolution. |
|
| 126 |
+
| `POST /warp` | Shared fields plus `path`; optional `lite`. | Gauges, cameras, source mapping, and preview URLs. `lite: true` omits the hole/sketch previews. |
|
| 127 |
+
| `POST /render` | Shared fields plus `path`. | `{job}`; rendering continues in a background thread. |
|
| 128 |
+
| `GET /job/{job}` | — | Status including `stage, pct, done, payload`; `t`, `error`, or `gauges` when available. |
|
| 129 |
+
| `GET /frame/{clip}/{i}.jpg` | Source index in the URL. | JPEG of the normalized source frame. |
|
| 130 |
+
| `GET /warpfile/{clip}/{name}` | Use a URL returned by `/warp`. | Preview file. |
|
| 131 |
+
| `GET /take/{job}/{name}` | Completed job ID and filename. | `out.mp4`, `source.mp4`, `render.mp4`, `grid.mp4`, or `last.png`. |
|
| 132 |
+
|
| 133 |
+
`lengths` in upload metadata is the studio's four-option length menu, not an exhaustive list of
|
| 134 |
+
asset-supported lengths. `src_poses[i]` in `/prepare` corresponds to absolute source frame
|
| 135 |
+
`start + i`; each entry includes `pos`, `look`, `roll`, and normalized lens values `k`.
|
| 136 |
+
|
| 137 |
+
Job `t` is elapsed time **since submission, including queue wait**. It first appears when processing
|
| 138 |
+
starts and updates at stage transitions, not continuously on polling. It is not a pure render-time
|
| 139 |
+
measurement.
|
| 140 |
+
|
| 141 |
+
### Warp response
|
| 142 |
+
|
| 143 |
+
- **`truth`**: grey-hole reference MP4 at conditioning resolution.
|
| 144 |
+
- **`holes`**: magenta-hole diagnostic MP4, unless `lite` is true.
|
| 145 |
+
- **`sketch`**: output-resolution geometric rasterization, unless `lite` is true; not the final
|
| 146 |
+
conditioning-resolution reference.
|
| 147 |
+
- **`canvas`, `cond_canvas`**: `[width, height]` for the target and references.
|
| 148 |
+
- **`tmap`**: selected source index for every output frame.
|
| 149 |
+
- **`cams`**: per-output-frame position/look-at description; `piv` and `zm` describe the pivot/scale.
|
| 150 |
+
- **`speed`**: source-frame rate per key segment; zero is a hold, one preserves the input pace.
|
| 151 |
+
- **`coverage`**: mean geometric coverage at the rasterization resolution, not a calibrated quality score.
|
| 152 |
+
- **`ahead`, `near`, `behind`, `coll`, `moved`**: geometric diagnostics. See [Preview checks](studio.md#preview-checks).
|
| 153 |
+
- **`ms`**: elapsed time for the warp endpoint, including preview encoding.
|
| 154 |
+
|
| 155 |
+
`turned` and `zoomed` are computed by the browser from keys; they are not fields returned by `/warp`.
|
| 156 |
+
|
| 157 |
+
## Operational boundaries
|
| 158 |
+
|
| 159 |
+
One process serializes GPU work through a lock. The API has no cancellation, durable queue, session
|
| 160 |
+
restoration, authentication, or automatic file retention policy. Clip and geometry caches can evict
|
| 161 |
+
entries while files remain on disk. Do not assume an old ID remains usable after a restart or eviction.
|
| 162 |
+
|
| 163 |
+
Assertions and runtime failures may surface as HTTP errors rather than structured validation
|
| 164 |
+
responses. Render failures can arrive asynchronously through `/job/{job}`. The automatically served
|
| 165 |
+
FastAPI schema does not describe these JSON payloads fully because the handlers read request bodies
|
| 166 |
+
directly; use this guide alongside [`service/app.py`](../service/app.py).
|
| 167 |
+
|
| 168 |
+
For service flags, cache behavior, and deployment precautions, see [Studio](studio.md#memory-and-lifecycle).
|
docs/assets/research/README.md
ADDED
|
@@ -0,0 +1,162 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Research figure assets
|
| 2 |
+
|
| 3 |
+
[← Research article](../../research.md) · [Technical method](../../method.md)
|
| 4 |
+
|
| 5 |
+
## Illustrated method
|
| 6 |
+
|
| 7 |
+
The article uses one integrated illustration:
|
| 8 |
+
[editable SVG](meridian_illustrated_method.svg) · [PNG](meridian_illustrated_method.png) ·
|
| 9 |
+
[provenance](illustrated_method_provenance.json).
|
| 10 |
+
|
| 11 |
+
- **Video strips:** actual matched source / warp / output samples from
|
| 12 |
+
`meridian_longtake_l150_nba3_apex_right14_175`. The front card is output index **95**;
|
| 13 |
+
the partially visible back cards are indices **40** and **150**, representing video rather
|
| 14 |
+
than a single-image input. Aspect ratios are preserved; the front frames are uncropped.
|
| 15 |
+
- **3D illustration:** a procedural, colored basketball point cloud and camera frustums,
|
| 16 |
+
explicitly labeled **schematic**. These are not saved VGGT-Omega points, estimated poses,
|
| 17 |
+
or the measured target path from this take. No reconstruction was run to make the figure.
|
| 18 |
+
- **Data flow:** VGGT-Omega estimates depth and source cameras; source RGB and depth are
|
| 19 |
+
unprojected into per-frame colored points. User-specified target cameras produce the warp.
|
| 20 |
+
The time-aligned source video bypasses geometry and joins the warp as the model's other
|
| 21 |
+
video input. Blue frustums denote estimated source cameras; gold denotes authored cameras.
|
| 22 |
+
|
| 23 |
+
This depicts the released [`reconstruct`, `unproject`, and `warp`](../../../recam/geometry.py)
|
| 24 |
+
pipeline, not a fused persistent world or direct point-cloud conditioning of the video model.
|
| 25 |
+
The model consumes **two videos**, not the plotted points or camera icons. As in the compact
|
| 26 |
+
earlier figures, noise, VAE/token packing, and the discarded audio branch are omitted.
|
| 27 |
+
|
| 28 |
+
The front samples map to prepared-input frame **70**, original movie frame **85**, PTS
|
| 29 |
+
**2.836167 s**. The other frame mappings and file hashes are in the provenance JSON.
|
| 30 |
+
NBA source-use clearance remains pending; no public promotional permission or endorsement
|
| 31 |
+
is implied. The Spring figure's CC BY license does not apply to the NBA samples.
|
| 32 |
+
|
| 33 |
+
Rebuild from the repository root:
|
| 34 |
+
|
| 35 |
+
```bash
|
| 36 |
+
/home/chenyun/miniforge3/envs/wan_new/bin/python docs/assets/research/build_illustrated_method.py
|
| 37 |
+
```
|
| 38 |
+
|
| 39 |
+
This reads retained videos and writes only this illustration's SVG, PNG and provenance.
|
| 40 |
+
It uses CPU decoding and vector rasterization; no Studio requests, model runs, production
|
| 41 |
+
video edits, or generative image replacements. Earlier figures are retained below.
|
| 42 |
+
|
| 43 |
+
## NBA method figures
|
| 44 |
+
|
| 45 |
+
The previous two-figure version is retained for reference:
|
| 46 |
+
|
| 47 |
+
1. **Camera poses and warp:** [editable SVG](meridian_poses.svg) · [PNG](meridian_poses.png).
|
| 48 |
+
VGGT-Omega estimates source poses and depth; colored points are reprojected with manually
|
| 49 |
+
specified target-camera poses. This is a schematic, not a measured camera-path plot.
|
| 50 |
+
2. **Video + warp → output:** [editable SVG](meridian_nba_generation.svg) ·
|
| 51 |
+
[PNG](meridian_nba_generation.png). The three NBA panels are actual decoded frames from one take,
|
| 52 |
+
with no generated replacements, retouching, or cropping.
|
| 53 |
+
|
| 54 |
+
[Frame provenance and media hashes](nba_method_provenance.json) ·
|
| 55 |
+
[Source, warp, output, and recorded controls](../../../videos-all/longtake_edit/review.html?take=nba_apex14_lora)
|
| 56 |
+
|
| 57 |
+
All three panels use output index **95** (zero-based) of
|
| 58 |
+
`meridian_longtake_l150_nba3_apex_right14_175`. This is inside the requested hold: prepared-input
|
| 59 |
+
frame **70**, original movie frame **85**, original PTS **2.836167 s**. The source panel comes from the
|
| 60 |
+
take's time-aligned `source.mp4`, not frame 95 of the original movie. The output uses Full200 / LoRA150 /
|
| 61 |
+
CLI4 / shift3 / seed1234. This single-frame illustration does not certify exact pose locking or
|
| 62 |
+
continuous-motion quality.
|
| 63 |
+
|
| 64 |
+
**NBA footage was supplied for local research. Public promotional permission and endorsement are
|
| 65 |
+
not established. The Spring figure's CC BY license below does not apply to the NBA panels.**
|
| 66 |
+
|
| 67 |
+
The SVGs are the editable sources. PNGs are direct rasterizations. For either figure, run from the
|
| 68 |
+
repository root, replacing `meridian_poses` with `meridian_nba_generation` for the second figure:
|
| 69 |
+
|
| 70 |
+
```bash
|
| 71 |
+
ffmpeg -v error -threads 2 -i docs/assets/research/meridian_poses.svg \
|
| 72 |
+
-frames:v 1 -threads 2 -y docs/assets/research/meridian_poses.png
|
| 73 |
+
```
|
| 74 |
+
|
| 75 |
+
## Architecture overview
|
| 76 |
+
|
| 77 |
+
[Editable, full-size SVG](meridian_architecture.svg) · [PNG](meridian_architecture.png) ·
|
| 78 |
+
[Frame provenance](method_provenance.json)
|
| 79 |
+
|
| 80 |
+
The previous single-diagram version separates **estimated source geometry**, **user-authored target
|
| 81 |
+
cameras and time**, and **the two video-model inputs**. Its data flow was checked against the released
|
| 82 |
+
code:
|
| 83 |
+
|
| 84 |
+
| Diagram element | Implementation |
|
| 85 |
+
|---|---|
|
| 86 |
+
| VGGT-Omega depth and source-camera estimates; unprojection with source RGB | [`reconstruct`, `unproject`, `warp`](../../../recam/geometry.py) |
|
| 87 |
+
| Camera position, look-at point, focal scale, and integer source-frame map | [`plan_path`](../../../recam/path.py) |
|
| 88 |
+
| The same frame map selects both source images and geometry; the target camera projects the points | [`geo`](../../../service/app.py) |
|
| 89 |
+
| Two VAE-encoded video references, packed as tokens; target denoising and decoding | [`pack`, `denoise`, `decode_video`](../../../recam/h3.py), [`do_render`](../../../service/app.py) |
|
| 90 |
+
|
| 91 |
+
Target-camera control is explicit, but does not guarantee pixel-perfect generated frames. Studio
|
| 92 |
+
orientation is derived from position and look-at with zero roll; focal scale multiplies the estimated
|
| 93 |
+
source focal lengths, rather than specifying an arbitrary intrinsic matrix. Time selection repeats
|
| 94 |
+
or skips supplied frames, without interpolating new motion. The diagram omits target noise, reference
|
| 95 |
+
noise augmentation, and the discarded audio branch; the [technical method](../../method.md) covers
|
| 96 |
+
those details.
|
| 97 |
+
|
| 98 |
+
The three photographic panels reuse the **same embedded JPEGs, unchanged**, from the original figure
|
| 99 |
+
below. The frame indices, source attribution, transformations, and provenance below apply to both
|
| 100 |
+
figures. The schematic video-strip icon is not a data sample. The SVG is the editable source; its PNG
|
| 101 |
+
is a direct rasterization, not an AI-generated or retouched image.
|
| 102 |
+
|
| 103 |
+
To refresh the PNG after editing the SVG, run from the repository root:
|
| 104 |
+
|
| 105 |
+
```bash
|
| 106 |
+
ffmpeg -v error -threads 2 -i docs/assets/research/meridian_architecture.svg \
|
| 107 |
+
-frames:v 1 -threads 2 -y docs/assets/research/meridian_architecture.png
|
| 108 |
+
```
|
| 109 |
+
|
| 110 |
+
## Two controls, two references, one new shot
|
| 111 |
+
|
| 112 |
+
[Full-size SVG](meridian_method.svg) · [PNG](meridian_method.png) ·
|
| 113 |
+
[Machine-readable provenance](method_provenance.json)
|
| 114 |
+
|
| 115 |
+
The upper diagram follows the released inference implementation, not a proposed architecture:
|
| 116 |
+
|
| 117 |
+
- `recam/geometry.py`: joint source reconstruction, filtered per-frame colored points, z-buffered
|
| 118 |
+
projection and grey uncovered pixels. No fused persistent 4D scene or geometric inpainting.
|
| 119 |
+
- `recam/path.py`: source-frame selection `s(t)` and target camera `C(t)`.
|
| 120 |
+
- `recam/h3.py` and `service/app.py`: both video references are VAE encoded and packed as reference
|
| 121 |
+
tokens; the model denoises the target, then the VAE decodes it. Coverage is diagnostic, not a
|
| 122 |
+
separate transformer mask input. The diagram omits target noise and the discarded audio branch;
|
| 123 |
+
see the [technical method](../../method.md#4-condition-the-video-transformer) for the full layout.
|
| 124 |
+
|
| 125 |
+
The lower panels are **actual decoded source, geometric-reference and generated frames** from
|
| 126 |
+
`meridian_grand_l150_flowers_forward70_baseaim243`, all at output index **121** (zero-based).
|
| 127 |
+
This maps to prepared-input frame 121 and original movie frame 9057 / PTS 377.382 s.
|
| 128 |
+
The geometric panel is taken from the saved conditioning-resolution preview, not a cleaned-up
|
| 129 |
+
render. Aspect ratios are preserved; small black margins are layout padding. This is a single-frame
|
| 130 |
+
illustration, not evidence of continuous motion quality or recovered ground truth.
|
| 131 |
+
|
| 132 |
+
The source/output exports are 1920 × 800; the geometric export is 960 × 416. These are this take's
|
| 133 |
+
production settings, not the default quickstart buckets. The generated frame uses Full200 + LoRA150,
|
| 134 |
+
CLI `--steps 4 --flow-shift 3 --seed 1234`; it is not a teacher-30 result.
|
| 135 |
+
|
| 136 |
+
### Attribution and transformations
|
| 137 |
+
|
| 138 |
+
*Spring* (2019), © Blender Foundation | [project](https://cloud.blender.org/spring).
|
| 139 |
+
Retained source: [Spring — Blender Open Movie](https://commons.wikimedia.org/wiki/File:Spring_-_Blender_Open_Movie.webm),
|
| 140 |
+
identified as [CC BY 4.0](https://creativecommons.org/licenses/by/4.0/) in the retained source records.
|
| 141 |
+
|
| 142 |
+
The input was slowed by repeating source frames before inference. The geometry projection and
|
| 143 |
+
generated view are transformations of that material. Figure preparation extracts one matched
|
| 144 |
+
frame, downsamples source/output thumbnails, JPEG-encodes the panels and fits them without cropping.
|
| 145 |
+
No generative image editing, enhancement, surface repair or color treatment is used for the figure.
|
| 146 |
+
Retain the attribution and transformation notice when reusing the visual.
|
| 147 |
+
|
| 148 |
+
[Original input preparation and exact map](../../../videos-all/longtake_edit/plates/flowers_linger243.json)
|
| 149 |
+
· [Recorded recipe and raw audit](../../../videos-all/longtake_edit/review/meridian_grand_l150_flowers_forward70_baseaim243/audit.json)
|
| 150 |
+
· [Source, projection and output in motion](../../../videos-all/longtake_edit/grand.html?take=flowers_forward70_baseaim)
|
| 151 |
+
|
| 152 |
+
### Rebuild
|
| 153 |
+
|
| 154 |
+
From the repository root, with FFmpeg's `librsvg` decoder available:
|
| 155 |
+
|
| 156 |
+
```bash
|
| 157 |
+
/home/chenyun/miniforge3/envs/wan_new/bin/python docs/assets/research/build_method_figure.py
|
| 158 |
+
```
|
| 159 |
+
|
| 160 |
+
This reads the retained MP4s and writes only the SVG, PNG and provenance beside this file.
|
| 161 |
+
It uses CPU decoding and SVG rasterization; it does not invoke the model,
|
| 162 |
+
contact the Studio service, or change production videos.
|
docs/assets/research/illustrated_method_provenance.json
ADDED
|
@@ -0,0 +1,101 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"take": "videos-all/meridian_longtake_l150_nba3_apex_right14_175",
|
| 3 |
+
"media": {
|
| 4 |
+
"source": {
|
| 5 |
+
"path": "videos-all/meridian_longtake_l150_nba3_apex_right14_175/source.mp4",
|
| 6 |
+
"sha256": "642f992fdc516c57fbaeabd9c4a6aa773c76fb9f1fd342412e20baa27b3dbb46",
|
| 7 |
+
"samples": [
|
| 8 |
+
{
|
| 9 |
+
"frame": 40,
|
| 10 |
+
"jpeg_sha256": "993b86a03df949e23a31b6ba4b64c0fd896516851d633cf279b9dad8faf4c19c"
|
| 11 |
+
},
|
| 12 |
+
{
|
| 13 |
+
"frame": 95,
|
| 14 |
+
"jpeg_sha256": "638ad3ceee19eaf238979fa5deb302394c3e750cba67d989405d303f80afd522"
|
| 15 |
+
},
|
| 16 |
+
{
|
| 17 |
+
"frame": 150,
|
| 18 |
+
"jpeg_sha256": "dd976c5db5a7861dbbdf174a79e3a233e98ef67bebf4e156203a2f749049720d"
|
| 19 |
+
}
|
| 20 |
+
]
|
| 21 |
+
},
|
| 22 |
+
"render": {
|
| 23 |
+
"path": "videos-all/meridian_longtake_l150_nba3_apex_right14_175/render.mp4",
|
| 24 |
+
"sha256": "e4f130524c2e09351203ca6dd410b3505031e72cdb4411e3d231787dba62bd23",
|
| 25 |
+
"samples": [
|
| 26 |
+
{
|
| 27 |
+
"frame": 40,
|
| 28 |
+
"jpeg_sha256": "b83be569064e26cefdf9bba2c5c89e3e63cd0c35beca4eeb57a8bda181406d2d"
|
| 29 |
+
},
|
| 30 |
+
{
|
| 31 |
+
"frame": 95,
|
| 32 |
+
"jpeg_sha256": "36347035ab0051f8a93fd1f1bb2bd31420de3a5be21b942a76f78e3742ce4171"
|
| 33 |
+
},
|
| 34 |
+
{
|
| 35 |
+
"frame": 150,
|
| 36 |
+
"jpeg_sha256": "1383ab0dd947894b3c05986e3f5b7b901061eca752f263e6e69aa8d4b4dff730"
|
| 37 |
+
}
|
| 38 |
+
]
|
| 39 |
+
},
|
| 40 |
+
"out": {
|
| 41 |
+
"path": "videos-all/meridian_longtake_l150_nba3_apex_right14_175/out.mp4",
|
| 42 |
+
"sha256": "49d33d29dca587f252dc43171e6b98513348770332ca44a8eb3a8b46b4300fb0",
|
| 43 |
+
"samples": [
|
| 44 |
+
{
|
| 45 |
+
"frame": 40,
|
| 46 |
+
"jpeg_sha256": "8ab722c84d3f21c5984cc9f294de6a208d2fd02dfcba71851660ed125b239792"
|
| 47 |
+
},
|
| 48 |
+
{
|
| 49 |
+
"frame": 95,
|
| 50 |
+
"jpeg_sha256": "dbd0138d1f7e03a002aefcceed8e3faededaade3319bc6940b0d0fb0f13876cd"
|
| 51 |
+
},
|
| 52 |
+
{
|
| 53 |
+
"frame": 150,
|
| 54 |
+
"jpeg_sha256": "7c6ed5f9f3b2003665d4e0322c0c4fa3ab9a79edcbd627eae4879a1e222d83b3"
|
| 55 |
+
}
|
| 56 |
+
]
|
| 57 |
+
}
|
| 58 |
+
},
|
| 59 |
+
"front_frame": 95,
|
| 60 |
+
"back_frames": [
|
| 61 |
+
40,
|
| 62 |
+
150
|
| 63 |
+
],
|
| 64 |
+
"matched_frames": [
|
| 65 |
+
{
|
| 66 |
+
"output_frame": 40,
|
| 67 |
+
"input_frame": 40,
|
| 68 |
+
"original_frame": 48,
|
| 69 |
+
"original_seconds": 1.6016,
|
| 70 |
+
"held": false
|
| 71 |
+
},
|
| 72 |
+
{
|
| 73 |
+
"output_frame": 95,
|
| 74 |
+
"input_frame": 70,
|
| 75 |
+
"original_frame": 85,
|
| 76 |
+
"original_seconds": 2.8361666666666667,
|
| 77 |
+
"held": true
|
| 78 |
+
},
|
| 79 |
+
{
|
| 80 |
+
"output_frame": 150,
|
| 81 |
+
"input_frame": 99,
|
| 82 |
+
"original_frame": 120,
|
| 83 |
+
"original_seconds": 4.004,
|
| 84 |
+
"held": false
|
| 85 |
+
}
|
| 86 |
+
],
|
| 87 |
+
"video_display": "Actual decoded frames, JPEG downsampling, fit-only; overlapping cards expose parts of back frames. The front frame is uncropped. No generative replacement, retouching or repair.",
|
| 88 |
+
"geometry_display": "Procedural illustrative point cloud, camera frustums, and path; not actual VGGT-Omega output or recorded camera poses. Fixed seed 17. No reconstruction or service call.",
|
| 89 |
+
"implementation": [
|
| 90 |
+
"recam/geometry.py: reconstruct, unproject, warp",
|
| 91 |
+
"recam/path.py: plan_path",
|
| 92 |
+
"service/app.py: geo, do_render",
|
| 93 |
+
"recam/h3.py: pack, denoise, decode_video"
|
| 94 |
+
],
|
| 95 |
+
"scope": "Architecture illustration, not measured reconstruction quality or a globally consistent world. Source time selects supplied moments. Model completion is generated, not recovered.",
|
| 96 |
+
"credit": "User-supplied NBA footage for local research. Public promotional permission and endorsement are not established.",
|
| 97 |
+
"source_map": {
|
| 98 |
+
"path": "videos-all/longtake_edit/nba_study_data.json",
|
| 99 |
+
"sha256": "d596edd2904fc3c7d1b5d5a0248ea9da05db1a43feafb5b0224acbc8f7f2d27f"
|
| 100 |
+
}
|
| 101 |
+
}
|
docs/assets/research/meridian_architecture.png
ADDED

|
Git LFS Details
|
docs/assets/research/meridian_architecture.svg
ADDED

|
docs/assets/research/meridian_illustrated_method.png
ADDED

|
Git LFS Details
|
docs/assets/research/meridian_illustrated_method.svg
ADDED

|
docs/assets/research/meridian_method.png
ADDED

|
Git LFS Details
|
docs/assets/research/meridian_method.svg
ADDED
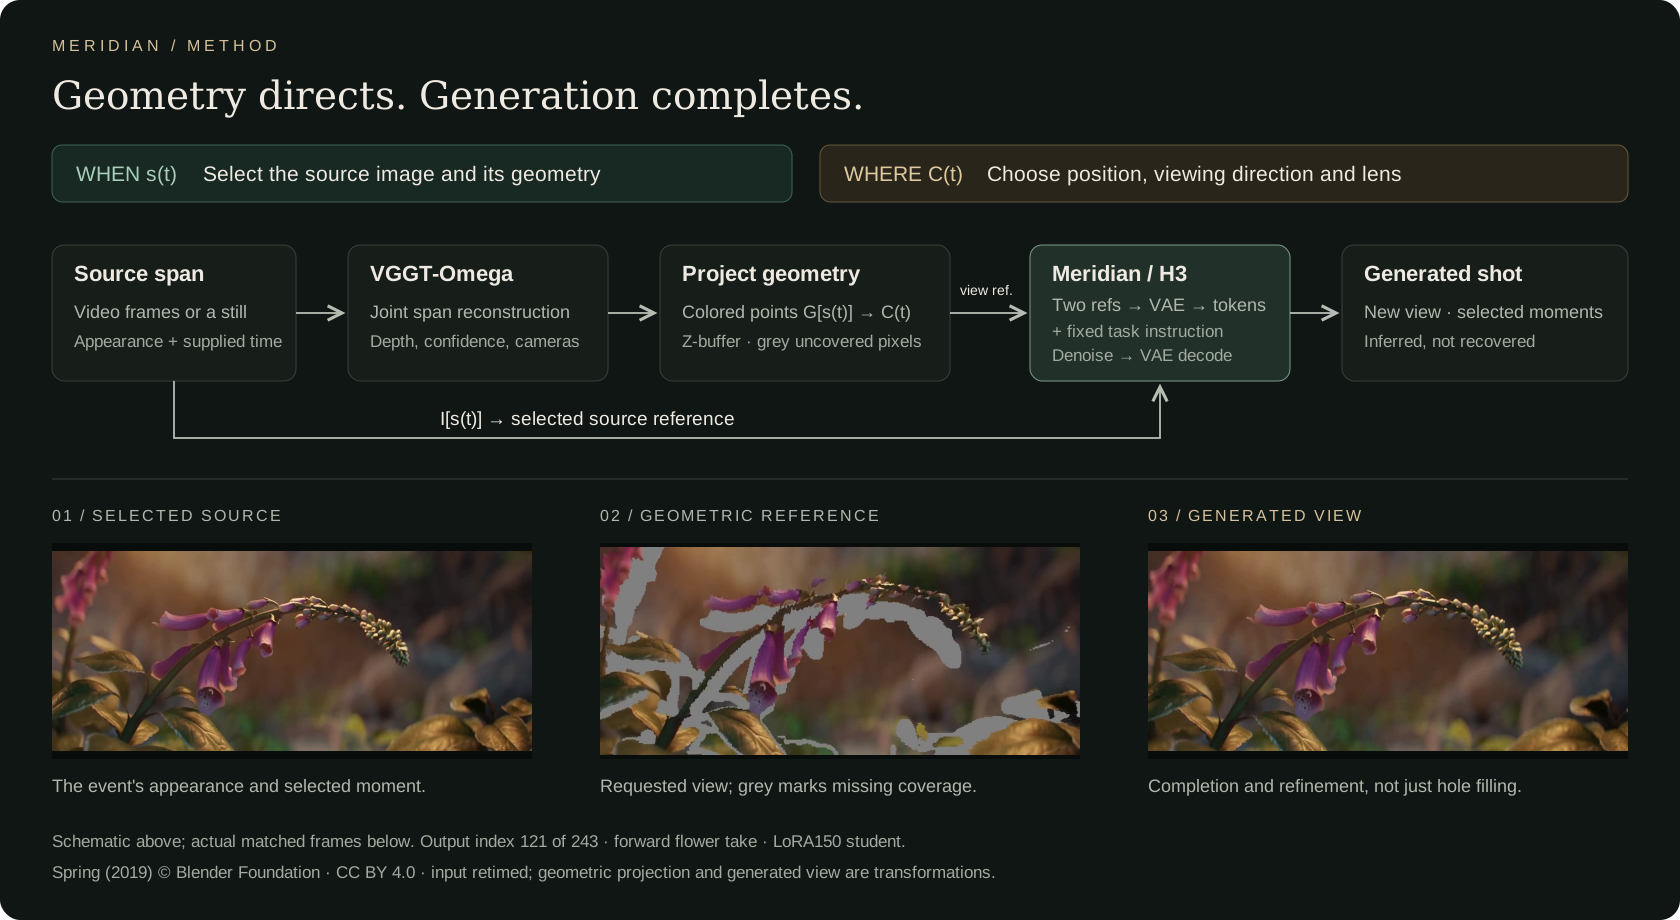
|
docs/assets/research/meridian_nba_generation.png
ADDED

|
Git LFS Details
|
docs/assets/research/meridian_nba_generation.svg
ADDED

|
docs/assets/research/meridian_poses.png
ADDED

|
docs/assets/research/meridian_poses.svg
ADDED

|
docs/assets/research/method_provenance.json
ADDED
|
@@ -0,0 +1,29 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"take": "videos-all/meridian_grand_l150_flowers_forward70_baseaim243",
|
| 3 |
+
"output_frame_zero_based": 121,
|
| 4 |
+
"prepared_input_frame": 121,
|
| 5 |
+
"original_movie_frame": 9057,
|
| 6 |
+
"original_movie_pts_seconds": 377.382,
|
| 7 |
+
"media": {
|
| 8 |
+
"source": {
|
| 9 |
+
"path": "videos-all/meridian_grand_l150_flowers_forward70_baseaim243/source.mp4",
|
| 10 |
+
"sha256": "0270cc8f8ce6e1ed3c0ceb9d6b5000c4ccaddda03f4f220359d32c2def7f3e2e"
|
| 11 |
+
},
|
| 12 |
+
"render": {
|
| 13 |
+
"path": "videos-all/meridian_grand_l150_flowers_forward70_baseaim243/render.mp4",
|
| 14 |
+
"sha256": "d1b1ad58b9c661cc780e43ceb4ca19b7f41640566d9fc36ab093e1fab7157c25"
|
| 15 |
+
},
|
| 16 |
+
"out": {
|
| 17 |
+
"path": "videos-all/meridian_grand_l150_flowers_forward70_baseaim243/out.mp4",
|
| 18 |
+
"sha256": "35d85aeda901c7c12e95de6ad2d33ad0946745282e2c2313d5dd21e5bd746961"
|
| 19 |
+
}
|
| 20 |
+
},
|
| 21 |
+
"display": "Exact decoded frame selection; JPEG encoding and fit-only thumbnail downsampling. No crop, repair or generated replacement images.",
|
| 22 |
+
"source_url": "https://commons.wikimedia.org/wiki/File:Spring_-_Blender_Open_Movie.webm",
|
| 23 |
+
"credit": "Spring (2019) \u00a9 Blender Foundation | cloud.blender.org/spring",
|
| 24 |
+
"license": "CC BY 4.0",
|
| 25 |
+
"license_url": "https://creativecommons.org/licenses/by/4.0/",
|
| 26 |
+
"source_time_scope": "Published animated-film timeline, not physical capture time.",
|
| 27 |
+
"recipe": "Full200 / LoRA150 / CLI4 / flow shift3 / seed1234; production output1920x800, conditioning960x416.",
|
| 28 |
+
"scope": "An explanatory diagram and a single matched frame, not a quality benchmark or a continuous-motion review."
|
| 29 |
+
}
|
docs/assets/research/nba_method_provenance.json
ADDED
|
@@ -0,0 +1,41 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"take": "meridian_longtake_l150_nba3_apex_right14_175",
|
| 3 |
+
"study_key": "nba_apex14_lora",
|
| 4 |
+
"output_frame_zero_based": 95,
|
| 5 |
+
"output_pts_seconds": 3.9583333333333335,
|
| 6 |
+
"prepared_input_frame": 70,
|
| 7 |
+
"original_movie_frame": 85,
|
| 8 |
+
"original_movie_pts_seconds": 2.8361666666666667,
|
| 9 |
+
"source_time_held": true,
|
| 10 |
+
"media": {
|
| 11 |
+
"source": {
|
| 12 |
+
"path": "videos-all/meridian_longtake_l150_nba3_apex_right14_175/source.mp4",
|
| 13 |
+
"sha256": "642f992fdc516c57fbaeabd9c4a6aa773c76fb9f1fd342412e20baa27b3dbb46",
|
| 14 |
+
"width": 1920,
|
| 15 |
+
"height": 1088,
|
| 16 |
+
"thumbnail_sha256": "1395f7e2ed780b6fbaaa060ac3ff7ff4b46f6765437d694757d53bb44daf4204"
|
| 17 |
+
},
|
| 18 |
+
"render": {
|
| 19 |
+
"path": "videos-all/meridian_longtake_l150_nba3_apex_right14_175/render.mp4",
|
| 20 |
+
"sha256": "e4f130524c2e09351203ca6dd410b3505031e72cdb4411e3d231787dba62bd23",
|
| 21 |
+
"width": 832,
|
| 22 |
+
"height": 480,
|
| 23 |
+
"thumbnail_sha256": "ba196eb57c5c7e5c0ae9c9ca8734c5a3c8c74bf9f986d21a59a285e898be155c"
|
| 24 |
+
},
|
| 25 |
+
"out": {
|
| 26 |
+
"path": "videos-all/meridian_longtake_l150_nba3_apex_right14_175/out.mp4",
|
| 27 |
+
"sha256": "49d33d29dca587f252dc43171e6b98513348770332ca44a8eb3a8b46b4300fb0",
|
| 28 |
+
"width": 1920,
|
| 29 |
+
"height": 1088,
|
| 30 |
+
"thumbnail_sha256": "4008729e25915ce072ab733d13a806dd85623d2f9a7537cf1f2ee82267ce56b8"
|
| 31 |
+
}
|
| 32 |
+
},
|
| 33 |
+
"source_time_map": "videos-all/longtake_edit/nba_study_data.json",
|
| 34 |
+
"audit": "videos-all/longtake_edit/review/meridian_longtake_l150_nba3_apex_right14_175/audit.json",
|
| 35 |
+
"recipe": "Full200 / LoRA150 / CLI4 / shift3 / seed 1234",
|
| 36 |
+
"credit": "NBA footage supplied for local research; public promotional permission and endorsement are not established.",
|
| 37 |
+
"license": "No public-use license established; the Spring figure CC BY license does not apply.",
|
| 38 |
+
"display": "All panels select decoded output frame 95 from the same take. FFmpeg scale=960:-2 and JPEG quality 2; aspect-ratio-preserving fit in SVG. No cropping, repair, image generation, or retouching.",
|
| 39 |
+
"extraction_filter": "select='eq(n,95)',scale=960:-2",
|
| 40 |
+
"scope": "Single matched-frame architecture example, not a continuous-motion review, exact pose-locking benchmark, or public-use clearance."
|
| 41 |
+
}
|
docs/inference.md
ADDED
|
@@ -0,0 +1,296 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Inference: camera and time
|
| 2 |
+
|
| 3 |
+
[← Meridian](../README.md) · [Installation](installation.md) · [Method](../README.md#method) · [Studio demo](../README.md#self-hosting-the-demo)
|
| 4 |
+
|
| 5 |
+
Run the examples from the release directory after completing installation. The CLI selects one GPU
|
| 6 |
+
through `CUDA_VISIBLE_DEVICES`; it does not split a take across cards.
|
| 7 |
+
|
| 8 |
+
```bash
|
| 9 |
+
CUDA_VISIBLE_DEVICES=0 python inference/sample.py \
|
| 10 |
+
--video examples/media/sp_bouldering_hang.mp4 \
|
| 11 |
+
--yaw 15 --sweep --out out/orbit
|
| 12 |
+
```
|
| 13 |
+
|
| 14 |
+
The default is a 73-frame, 24 fps take using the distilled student: `--steps 4 --flow-shift 3`.
|
| 15 |
+
Use a fresh `--out` directory for each take; filenames are fixed rather than automatically versioned.
|
| 16 |
+
|
| 17 |
+
## Prepare the input
|
| 18 |
+
|
| 19 |
+
Use a single continuous shot. The **CLI does not normalize frame rate or detect cuts**: it reads
|
| 20 |
+
decoded frames by index and always writes at 24 fps. A 30 fps or variable-frame-rate input can
|
| 21 |
+
therefore change pace and lose audio alignment unless you normalize it first.
|
| 22 |
+
|
| 23 |
+
```bash
|
| 24 |
+
# Preserve playback duration while exporting a constant 24 fps input.
|
| 25 |
+
ffmpeg -i clip.mp4 -vf "setpts=PTS-STARTPTS,fps=24" \
|
| 26 |
+
-c:v libx264 -crf 18 -pix_fmt yuv420p -c:a aac clip_24fps.mp4
|
| 27 |
+
|
| 28 |
+
# Inspect the actual decoded frame count, not only the container's FPS label.
|
| 29 |
+
ffprobe -v error -select_streams v:0 -count_frames \
|
| 30 |
+
-show_entries stream=width,height,r_frame_rate,nb_read_frames \
|
| 31 |
+
-of default=noprint_wrappers=1 clip_24fps.mp4
|
| 32 |
+
```
|
| 33 |
+
|
| 34 |
+
For a normal take, the input must contain at least `start + frames` decoded frames. The two included
|
| 35 |
+
sample clips each contain exactly **73 frames at 24 fps** and no audio. A longer take needs a longer
|
| 36 |
+
input or an explicit hold; simply increasing `--frames` on those samples will not extend the action.
|
| 37 |
+
|
| 38 |
+
## Camera recipes
|
| 39 |
+
|
| 40 |
+
The following commands all work with the included 73-frame sample as an input, subject to the
|
| 41 |
+
hardware and model setup. Motion quality still depends on reconstruction and viewpoint coverage.
|
| 42 |
+
|
| 43 |
+
### Orbit with a gentle start and stop
|
| 44 |
+
|
| 45 |
+
```bash
|
| 46 |
+
python inference/sample.py --video examples/media/sp_bouldering_hang.mp4 \
|
| 47 |
+
--yaw 15 --sweep --ease --out out/eased_orbit
|
| 48 |
+
```
|
| 49 |
+
|
| 50 |
+
Positive yaw moves the camera **left** around the pivot. Without `--sweep`, the offset is applied
|
| 51 |
+
throughout the clip instead of ramping from the original view. It remains an offset from each source
|
| 52 |
+
camera, not necessarily a camera fixed in world space.
|
| 53 |
+
|
| 54 |
+
### Push in without changing the lens
|
| 55 |
+
|
| 56 |
+
```bash
|
| 57 |
+
python inference/sample.py --video examples/media/sp_bouldering_hang.mp4 \
|
| 58 |
+
--dolly 0.8 --zoom 1 --sweep --ease --out out/push_in
|
| 59 |
+
```
|
| 60 |
+
|
| 61 |
+
**`--dolly` alone performs a dolly zoom:** it changes both the camera radius and focal length to
|
| 62 |
+
approximately preserve the pivot plane's size. Add `--zoom 1` for a fixed-lens push-in, where the
|
| 63 |
+
subject grows in frame. `--zoom 1.5` without translation is an optical zoom; these pure-zoom takes
|
| 64 |
+
can be ignored by the model. Prefer moves with parallax.
|
| 65 |
+
|
| 66 |
+
### Slide or crane while keeping the subject framed
|
| 67 |
+
|
| 68 |
+
```bash
|
| 69 |
+
# Move right by 0.15 pivot-depth units and aim back toward the pivot.
|
| 70 |
+
python inference/sample.py --video examples/media/sp_bouldering_hang.mp4 \
|
| 71 |
+
--truck 0.15 --aim --sweep --ease --out out/slide
|
| 72 |
+
|
| 73 |
+
# Raise the camera by 0.15 pivot-depth units.
|
| 74 |
+
python inference/sample.py --video examples/media/sp_bouldering_hang.mp4 \
|
| 75 |
+
--boom 0.15 --aim --sweep --ease --out out/crane
|
| 76 |
+
```
|
| 77 |
+
|
| 78 |
+
### Choose the orbit center
|
| 79 |
+
|
| 80 |
+
```bash
|
| 81 |
+
python inference/sample.py --video examples/media/sp_bouldering_hang.mp4 \
|
| 82 |
+
--pivot 0.5,0.5 --pivot-lock --yaw 15 --sweep --out out/pivot_orbit
|
| 83 |
+
```
|
| 84 |
+
|
| 85 |
+
`--pivot fx,fy` uses fractions of the **center-cropped picture**, not the full letterbox or original
|
| 86 |
+
uncropped image. Choose a point on the subject, away from image boundaries, sky, and missing depth.
|
| 87 |
+
The example selects the crop center; adjust it for your footage. `--pivot` sets the depth scale;
|
| 88 |
+
`--pivot-lock` additionally moves the orbit center to the picked 3D point.
|
| 89 |
+
|
| 90 |
+
**Choose the point in the frame used for pivot depth.** Without `--freeze`, this is
|
| 91 |
+
the first selected source frame (`--start`). With `--freeze F:N`, it is frame `F`.
|
| 92 |
+
An athlete-centered point at the held apex can land on the distant audience in the
|
| 93 |
+
approach frame: do not reuse it unchanged when removing the hold. The depth is a
|
| 94 |
+
median over a neighborhood extending roughly 5% of the picture in each direction,
|
| 95 |
+
so check that neighborhood as well as the exact pixel. `--pivot-lock` is not dynamic
|
| 96 |
+
subject tracking; inspect the projected reference throughout the shot before
|
| 97 |
+
treating the requested trajectory as a successful composition.
|
| 98 |
+
|
| 99 |
+
## Timing
|
| 100 |
+
|
| 101 |
+
All CLI source indices are **zero-based absolute frame indices** in the supplied file.
|
| 102 |
+
|
| 103 |
+
### Select a passage
|
| 104 |
+
|
| 105 |
+
```bash
|
| 106 |
+
# On an input with at least 121 frames, use source frames 48 through 120 inclusive.
|
| 107 |
+
python inference/sample.py --video clip_24fps.mp4 \
|
| 108 |
+
--start 48 --frames 73 --yaw 15 --sweep --out out/later_moment
|
| 109 |
+
```
|
| 110 |
+
|
| 111 |
+
`--start 48` is two seconds into a 24 fps input. It is not a seek time in seconds.
|
| 112 |
+
|
| 113 |
+
### Hold a moment while moving the camera
|
| 114 |
+
|
| 115 |
+
```bash
|
| 116 |
+
# 24 live frames, then source frame 24 repeated for 49 output frames; no tail.
|
| 117 |
+
python inference/sample.py --video examples/media/sp_bouldering_reach.mp4 \
|
| 118 |
+
--yaw 35 --freeze 24:49 --out out/bullet
|
| 119 |
+
|
| 120 |
+
# Hold one instant for the entire take; the camera still sweeps through 20 degrees.
|
| 121 |
+
python inference/sample.py --video examples/media/sp_bouldering_reach.mp4 \
|
| 122 |
+
--yaw 20 --freeze 24:73 --start 24 --out out/held_moment
|
| 123 |
+
```
|
| 124 |
+
|
| 125 |
+
For `--freeze F:N`, the output consists of:
|
| 126 |
+
|
| 127 |
+
1. Source frames `start` through `F - 1`, once each.
|
| 128 |
+
2. Source frame `F`, repeated `N` times.
|
| 129 |
+
3. Source frames after `F`, once each, until the requested output length is reached.
|
| 130 |
+
|
| 131 |
+
The tail length is `frames - N - (F - start)`. Use a positive `N`, `F >= start`, and a non-negative
|
| 132 |
+
tail. The source must reach frame `F + tail`. With a hold, fewer distinct source frames can produce
|
| 133 |
+
a longer output, but the repeated interval contains no new event motion.
|
| 134 |
+
|
| 135 |
+
By default, the camera ramp progresses only during the held interval. Add `--sweep` to move during
|
| 136 |
+
the live lead-in and tail too; `--live-speed` sets their ramp speed relative to the held interval
|
| 137 |
+
(default `0.33`). It controls the **camera ramp**, not playback speed.
|
| 138 |
+
|
| 139 |
+
The CLI can also decode a still image, for example
|
| 140 |
+
`--video still.png --freeze 0:73 --yaw 15`. This is a camera move over a held image, not animation of
|
| 141 |
+
the subject. The studio's video upload workflow does not offer this short-input path.
|
| 142 |
+
|
| 143 |
+
### Slow motion and speed-ups
|
| 144 |
+
|
| 145 |
+
**Set the event's pace first, then author the camera.** Export the retimed source at a constant
|
| 146 |
+
24 fps and use that export as the input to either the CLI or the studio.
|
| 147 |
+
|
| 148 |
+
```bash
|
| 149 |
+
# 0.5x: twice the duration.
|
| 150 |
+
ffmpeg -i clip.mp4 -vf "setpts=2*(PTS-STARTPTS),fps=24" -an clip_slow.mp4
|
| 151 |
+
|
| 152 |
+
# 2x: half the duration.
|
| 153 |
+
ffmpeg -i clip.mp4 -vf "setpts=0.5*(PTS-STARTPTS),fps=24" -an clip_fast.mp4
|
| 154 |
+
|
| 155 |
+
python inference/sample.py --video clip_slow.mp4 \
|
| 156 |
+
--yaw 15 --sweep --out out/slow_orbit
|
| 157 |
+
|
| 158 |
+
python inference/sample.py --video clip_fast.mp4 \
|
| 159 |
+
--yaw 15 --sweep --out out/fast_orbit
|
| 160 |
+
```
|
| 161 |
+
|
| 162 |
+
Changing playback metadata alone is not enough for the CLI: timing must be baked into the **decoded
|
| 163 |
+
frame sequence**. `fps=24` duplicates or drops frames; it does not interpolate new motion. Slow-motion
|
| 164 |
+
smoothness depends on the source frame rate and any interpolation applied before inference.
|
| 165 |
+
|
| 166 |
+
Check the retimed file's frame count before rendering. In particular, acceleration shortens the input:
|
| 167 |
+
the included 73-frame samples become too short for an ordinary 73-frame take at 2x. Use longer footage
|
| 168 |
+
or explicitly hold a moment. The commands above omit audio; retime a soundtrack separately if needed.
|
| 169 |
+
|
| 170 |
+
In the studio, one source frame per output frame preserves the export's retimed pace. Stretching keys
|
| 171 |
+
across the unchanged source is a different workflow: it duplicates or skips reconstructed frames and
|
| 172 |
+
can trigger a speed warning.
|
| 173 |
+
|
| 174 |
+
## Output lengths and resolution
|
| 175 |
+
|
| 176 |
+
| `--frames` | Duration at 24 fps |
|
| 177 |
+
|---|---|
|
| 178 |
+
| 73 | 3.04 s |
|
| 179 |
+
| 90 | 3.75 s |
|
| 180 |
+
| 107 | 4.46 s |
|
| 181 |
+
| 124 | 5.17 s |
|
| 182 |
+
| 141 | 5.88 s |
|
| 183 |
+
| 158 | 6.58 s |
|
| 184 |
+
| 175 | 7.29 s |
|
| 185 |
+
| 243 | 10.13 s |
|
| 186 |
+
|
| 187 |
+
These are the lengths with shipped text and audio-layout assets. Other values are not accepted by
|
| 188 |
+
the CLI. This is a per-take limit, not a limit on the total duration of the input file.
|
| 189 |
+
|
| 190 |
+
Output uses an aspect-matched 768-class bucket, usually about 1.03 million pixels; 16:9 maps to
|
| 191 |
+
1344 × 768. Both references use the smaller 480-class bucket: 832 × 480 for a 16:9 input.
|
| 192 |
+
|
| 193 |
+
## Output files
|
| 194 |
+
|
| 195 |
+
| File in `--out` | Contents |
|
| 196 |
+
|---|---|
|
| 197 |
+
| `out.mp4` | Generated take, 24 fps, no generated audio. |
|
| 198 |
+
| `render.mp4` | Geometry reference at conditioning resolution, including grey holes. |
|
| 199 |
+
| `source.mp4` | Source images after the selected frame mapping and output crop. A hold is visible here too. |
|
| 200 |
+
| `grid.mp4` | Source, geometry reference, and generated take side by side. |
|
| 201 |
+
| `out_audio.mp4` | For non-freeze commands: source-window audio muxed onto the take, when the input has audio. A silent input remains silent. |
|
| 202 |
+
| `last.png` | Final generated frame. Reusing it is possible, but does not guarantee cross-take consistency. |
|
| 203 |
+
| `cams.npz` | Source/target camera matrices, intrinsics, pivot metadata, crop, canvas, FPS, and command arguments. |
|
| 204 |
+
|
| 205 |
+
`cams.npz` stores `c2w_src` and `c2w_dst` as camera-to-world matrices; `intr_src` and `intr_dst` are
|
| 206 |
+
in the 512-space geometry grid. The `*_px` arrays are exported for the output canvas. Translation
|
| 207 |
+
units are reconstruction-relative, not meters. The archive is diagnostic metadata, not a scene model.
|
| 208 |
+
|
| 209 |
+
For reproducibility, retain the input export, command, seed, checkpoint revisions, and environment.
|
| 210 |
+
Do not assume the CLI and studio, or different dependency/backend versions, produce bit-identical
|
| 211 |
+
results from the same seed.
|
| 212 |
+
|
| 213 |
+
## CLI reference
|
| 214 |
+
|
| 215 |
+
Run `python inference/sample.py --help` for the parser's complete help. The tables below group the
|
| 216 |
+
options by purpose; boolean flags are off unless stated otherwise.
|
| 217 |
+
|
| 218 |
+
### Input and model
|
| 219 |
+
|
| 220 |
+
| Option | Default | Meaning |
|
| 221 |
+
|---|---|---|
|
| 222 |
+
| `--video` | Required | Input video or decodable still image. |
|
| 223 |
+
| `--out` | Required | Output directory. |
|
| 224 |
+
| `--start` | `0` | First source-frame index. |
|
| 225 |
+
| `--frames` | `73` | Supported output length from the table above. |
|
| 226 |
+
| `--seed` | `1234` | Random seed. |
|
| 227 |
+
| `--ckpt` | `<release>/transformer` | Finetuned teacher directory. |
|
| 228 |
+
| `--lora` | `<release>/lora` | Student adapter directory. |
|
| 229 |
+
| `--no-lora` | Off | Disable the adapter; pair with the teacher sampling settings. |
|
| 230 |
+
| `--steps` | `4` | Scheduler grid points, including the terminal point. |
|
| 231 |
+
| `--flow-shift` | `3` | Video schedule shift; use `12` for the teacher. |
|
| 232 |
+
| `--model-dir` | `MiniMaxAI/MiniMax-H3` | Hub repo or local directory containing `vae/`. |
|
| 233 |
+
| `--vggt-repo`, `--vggt` | Environment-based | VGGT-Omega source checkout and checkpoint; see [Installation](installation.md#2-obtain-vggt-omega-separately). |
|
| 234 |
+
| `--attn-backend` | `_native_cudnn` | Diffusers attention backend. Alternatives are hardware- and version-dependent. |
|
| 235 |
+
|
| 236 |
+
To use the teacher:
|
| 237 |
+
|
| 238 |
+
```bash
|
| 239 |
+
python inference/sample.py --video examples/media/sp_bouldering_hang.mp4 \
|
| 240 |
+
--yaw 15 --sweep --no-lora --steps 50 --flow-shift 12 --out out/teacher
|
| 241 |
+
```
|
| 242 |
+
|
| 243 |
+
### Camera and motion
|
| 244 |
+
|
| 245 |
+
| Option | Default | Meaning |
|
| 246 |
+
|---|---|---|
|
| 247 |
+
| `--yaw` | `0` | Orbit angle in degrees; positive moves left. |
|
| 248 |
+
| `--yaw-from` | `0` | Initial yaw when ramping; the live lead-in holds this value unless also swept. |
|
| 249 |
+
| `--truck` | `0` | Sideways shift in pivot-depth units; positive moves right. |
|
| 250 |
+
| `--boom` | `0` | Vertical shift in pivot-depth units; positive raises the camera. |
|
| 251 |
+
| `--dolly` | `1` | Orbit-radius scale; below one moves closer and, by default, widens the lens. |
|
| 252 |
+
| `--zoom` | `0` | Zero means automatic dolly-linked focal scaling; a positive value specifies the final focal multiplier. |
|
| 253 |
+
| `--pivot` | Unset | `fx,fy` in the crop; selects the depth-scale neighborhood. |
|
| 254 |
+
| `--pivot-lock` | Off | With `--pivot`, orbit about the selected 3D point. |
|
| 255 |
+
| `--aim` | Off | Reorient toward the pivot after translation. |
|
| 256 |
+
| `--pivot-to` | Unset | With `--aim`, a second `fx,fy` point toward which the aim transitions. |
|
| 257 |
+
| `--sweep` | Off | Ramp from the initial to the final offset over the take. |
|
| 258 |
+
| `--ease` | Off | Cosine ease-in/out applied to the ramp; it does not create a ramp by itself. |
|
| 259 |
+
| `--bounce` | Off | There-and-back ramp, `0 → 1 → 0`; implies a ramp even without `--sweep`. |
|
| 260 |
+
| `--swing` | Off | Sine ramp, `0 → 1 → 0 → −1 → 0`; implies a ramp. |
|
| 261 |
+
| `--freeze` | Unset | `F:N`: hold source frame `F` for `N` output frames. |
|
| 262 |
+
| `--live-speed` | `0.33` | With `--freeze --sweep`, relative camera-ramp speed outside the hold. |
|
| 263 |
+
|
| 264 |
+
Use one basic ramp shape at a time. Combining `--ease`, `--bounce`, and `--swing` composes their
|
| 265 |
+
functions in code order; it does not select between independent motion presets.
|
| 266 |
+
|
| 267 |
+
### Advanced and diagnostic controls
|
| 268 |
+
|
| 269 |
+
| Option | Default | Meaning and caveat |
|
| 270 |
+
|---|---|---|
|
| 271 |
+
| `--gauge-only` | Off | Reconstruct, warp, print geometry gauges, then stop before loading H3. No normal output artifacts are written. |
|
| 272 |
+
| `--follow` | Off | Replay estimated source cameras over the **first selected frame's fixed geometry and RGB**. Ignores the authored yaw/translation/lens controls; it does not retain the event's live motion. |
|
| 273 |
+
| `--smooth` | `8` | With `--follow`, Gaussian smoothing sigma in frames for estimated camera poses and intrinsics. `0` disables smoothing. |
|
| 274 |
+
| `--cull` | Off | Reject surfaces seen from behind according to estimated depth-map normals. This removes misleading splats; it does not reveal hidden surfaces. |
|
| 275 |
+
| `--fast-back` | `1` | Above one, compress the middle half of the camera ramp. Does not improve the reconstruction of an unseen back view. |
|
| 276 |
+
| `--canvas` | Automatic | Explicit `WxH`, with dimensions divisible by 32; advanced override outside the reported default benchmarks. |
|
| 277 |
+
| `--full` | `0` → 1280 | Override the square letterbox side. Higher values increase point-cloud sampling and memory, not VGGT's 512-pixel input resolution. |
|
| 278 |
+
|
| 279 |
+
The CLI prints `ahead`, coverage, and other geometry diagnostics but **does not reject a take using
|
| 280 |
+
the studio's clearance/motion thresholds**. Inspect the diagnostics and `render.mp4`; do not treat a
|
| 281 |
+
successful process exit as a quality check.
|
| 282 |
+
|
| 283 |
+
## Improving a take
|
| 284 |
+
|
| 285 |
+
1. **Inspect the geometry reference first.** A bent subject or unstable depth in `render.mp4` usually
|
| 286 |
+
needs a better source shot or a smaller move, not more denoising steps.
|
| 287 |
+
2. **Use modest viewpoint changes.** Large orbits reveal surfaces absent from the source. A plausible
|
| 288 |
+
completion can still be wrong; roughly 40° is a reported caution point, not a universal threshold.
|
| 289 |
+
3. **Check the depth scale.** If a small numerical move sends the camera through the scene, pick a
|
| 290 |
+
pivot on the subject and reduce the translation.
|
| 291 |
+
4. **Add parallax to lens changes.** Use a small dolly rather than relying on a pure optical zoom.
|
| 292 |
+
5. **Check timing before inference.** Stuttering from repeated input frames is not a geometry failure;
|
| 293 |
+
use higher-frame-rate footage or an interpolated export when smooth slow motion matters.
|
| 294 |
+
6. **Do not cross cuts.** Split the input into continuous shots yourself when using the CLI.
|
| 295 |
+
|
| 296 |
+
For dependency and memory errors, see [Setup problems](installation.md#setup-problems).
|
docs/installation.md
ADDED
|
@@ -0,0 +1,189 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Installation
|
| 2 |
+
|
| 3 |
+
[← Meridian](../README.md) · [Inference](inference.md) · [Studio demo](../README.md#self-hosting-the-demo)
|
| 4 |
+
|
| 5 |
+
## Before downloading
|
| 6 |
+
|
| 7 |
+
- **Review the [licenses and intended use](../README.md#license).** The weights are not Apache 2.0,
|
| 8 |
+
the MiniMax-H3 license has territorial restrictions, and the VGGT-Omega dependency is licensed
|
| 9 |
+
separately for noncommercial research.
|
| 10 |
+
- **Use a CUDA GPU with substantial memory.** The released scripts run on one GPU and do not expose
|
| 11 |
+
CPU inference, multi-GPU sharding, quantization, or CPU-offload options. The reported resident-service
|
| 12 |
+
peak is approximately 88 GiB for 73 frames. The CLI logs approximately 82 GiB of peak PyTorch-allocated
|
| 13 |
+
memory during denoising; this does not measure the whole-process peak or driver-level GPU usage.
|
| 14 |
+
A 96 GB-class GPU is the reported configuration for takes up to 124 frames; 243-frame takes reach
|
| 15 |
+
approximately 113 GiB in the service.
|
| 16 |
+
Leave headroom for geometry caches, other processes, and differences between GB and GiB.
|
| 17 |
+
- **Allow disk space beyond the weights.** The teacher and adapter total approximately 64 GiB;
|
| 18 |
+
the H3 VAE, VGGT-Omega checkpoint, package caches, uploads, and generated videos are additional.
|
| 19 |
+
- **Reference environment:** Python 3.12, CUDA 12.8, PyTorch 2.9.1, and torchvision 0.24.1.
|
| 20 |
+
B200 is the reported benchmark GPU, not a claim that every CUDA GPU is validated.
|
| 21 |
+
- Have **Git**, **FFmpeg**, and **FFprobe** on `PATH`. Git is needed for the pinned Diffusers install;
|
| 22 |
+
the Python packages do not install the FFmpeg command-line executable.
|
| 23 |
+
|
| 24 |
+
## 1. Create an environment and download the code
|
| 25 |
+
|
| 26 |
+
Run these commands in a shell with Python 3.12 available. `python` below always means the Python in
|
| 27 |
+
the activated environment. Sign in if repository access requires it. The command fetches code,
|
| 28 |
+
runtime assets, guides, and sample clips, not the optional showcase videos or model weights.
|
| 29 |
+
|
| 30 |
+
```bash
|
| 31 |
+
python3.12 -m venv .venv-meridian
|
| 32 |
+
source .venv-meridian/bin/activate
|
| 33 |
+
python -m pip install --upgrade pip
|
| 34 |
+
python -m pip install huggingface_hub
|
| 35 |
+
|
| 36 |
+
hf auth login
|
| 37 |
+
hf download Viggle/Meridian --local-dir Meridian \
|
| 38 |
+
--include "README.md" "LICENSE*" "NOTICE" "MODIFICATIONS.md" "requirements.txt" \
|
| 39 |
+
"recam/*" "inference/*" "service/*" "assets/*" "examples/*" \
|
| 40 |
+
"docs/installation.md" "docs/inference.md"
|
| 41 |
+
cd Meridian
|
| 42 |
+
python -m pip install -r requirements.txt
|
| 43 |
+
python -m pip install peft==0.18.0
|
| 44 |
+
|
| 45 |
+
# These must work before loading any model weights or starting the GPU service.
|
| 46 |
+
python inference/sample.py --help
|
| 47 |
+
python service/app.py --help
|
| 48 |
+
```
|
| 49 |
+
|
| 50 |
+
The PEFT package is needed by the student adapter loader and is not currently listed in
|
| 51 |
+
`requirements.txt`; install it explicitly. Use a dedicated environment rather than upgrading a
|
| 52 |
+
shared inference environment in place.
|
| 53 |
+
|
| 54 |
+
Keep the Diffusers commit pinned by `requirements.txt` (`d6726f3`). The scripts use MiniMax-H3 classes
|
| 55 |
+
and modular-pipeline helpers that may not exist in another build, even if its version string includes
|
| 56 |
+
`dev`. Do not replace that dependency with an arbitrary PyPI release.
|
| 57 |
+
|
| 58 |
+
### Supply the teacher and LoRA weights
|
| 59 |
+
|
| 60 |
+
**Checkpoint availability:** `transformer/` and `lora/` are not hosted in this repository yet;
|
| 61 |
+
a verified download source is pending. Supply the checkpoints separately using the layout below.
|
| 62 |
+
Without them, the help checks can pass, but generation and Studio startup cannot run.
|
| 63 |
+
|
| 64 |
+
If you already have the Meridian checkpoints, place the complete Diffusers transformer directory
|
| 65 |
+
(including its configuration, weight shards, and any index file) and the student adapter alongside
|
| 66 |
+
the code:
|
| 67 |
+
|
| 68 |
+
```text
|
| 69 |
+
Meridian/
|
| 70 |
+
inference/sample.py
|
| 71 |
+
assets/
|
| 72 |
+
transformer/
|
| 73 |
+
config.json
|
| 74 |
+
... checkpoint files ...
|
| 75 |
+
lora/
|
| 76 |
+
pytorch_lora_weights.safetensors
|
| 77 |
+
```
|
| 78 |
+
|
| 79 |
+
Alternatively, add `--ckpt /absolute/path/to/transformer --lora /absolute/path/to/lora` to the CLI
|
| 80 |
+
or Studio command. Use Meridian's finetuned teacher, not the unmodified MiniMax-H3 transformer.
|
| 81 |
+
|
| 82 |
+
## 2. Obtain VGGT-Omega separately
|
| 83 |
+
|
| 84 |
+
VGGT-Omega code and weights are **not redistributed here**. Request access to
|
| 85 |
+
[facebook/VGGT-Omega](https://huggingface.co/facebook/VGGT-Omega), read its license, and authenticate
|
| 86 |
+
with a Hugging Face account that has been granted access.
|
| 87 |
+
|
| 88 |
+
```bash
|
| 89 |
+
# Run from the Meridian release directory; the checkout is placed beside it.
|
| 90 |
+
git clone https://github.com/facebookresearch/vggt-omega ../vggt-omega
|
| 91 |
+
export VGGT_OMEGA_DIR="$(cd ../vggt-omega && pwd)"
|
| 92 |
+
|
| 93 |
+
hf auth login
|
| 94 |
+
hf download facebook/VGGT-Omega vggt_omega_1b_512.pt \
|
| 95 |
+
--local-dir "$VGGT_OMEGA_DIR/checkpoints"
|
| 96 |
+
```
|
| 97 |
+
|
| 98 |
+
Follow the VGGT-Omega checkout's own dependency instructions if additional packages are needed.
|
| 99 |
+
Its source directory is imported directly; this release does not install it as a Python package.
|
| 100 |
+
|
| 101 |
+
By default, Meridian looks for
|
| 102 |
+
`$VGGT_OMEGA_DIR/checkpoints/vggt_omega_1b_512.pt`. If you already store the weight file elsewhere:
|
| 103 |
+
|
| 104 |
+
```bash
|
| 105 |
+
export VGGT_OMEGA_CKPT=/absolute/path/to/vggt_omega_1b_512.pt
|
| 106 |
+
```
|
| 107 |
+
|
| 108 |
+
Keep these exports in the shell that starts inference. The CLI and service also accept
|
| 109 |
+
`--vggt-repo /absolute/path/to/vggt-omega` and `--vggt /absolute/path/to/the/checkpoint.pt`.
|
| 110 |
+
|
| 111 |
+
Meta's FAIR Noncommercial Research License v1 restricts commercial use of the research materials
|
| 112 |
+
and their outputs or results. Here those results include the geometry used to make the reference
|
| 113 |
+
render. The Apache license on Meridian's code does not remove that restriction. Commercial use
|
| 114 |
+
requires an appropriately licensed geometry solution or permission from Meta; swapping the
|
| 115 |
+
geometry front end is not a built-in CLI option and requires integration work.
|
| 116 |
+
|
| 117 |
+
## 3. Provide the MiniMax-H3 VAE
|
| 118 |
+
|
| 119 |
+
By default, inference loads `vae/` from
|
| 120 |
+
[`MiniMaxAI/MiniMax-H3`](https://huggingface.co/MiniMaxAI/MiniMax-H3). It does **not** need the base
|
| 121 |
+
transformer or the text encoder. To download only the VAE for local use:
|
| 122 |
+
|
| 123 |
+
```bash
|
| 124 |
+
hf download MiniMaxAI/MiniMax-H3 --include "vae/*" --local-dir ../MiniMax-H3
|
| 125 |
+
```
|
| 126 |
+
|
| 127 |
+
Then add `--model-dir ../MiniMax-H3` to your CLI or service command. This path is the directory
|
| 128 |
+
**containing** `vae/`, not `vae/` itself. Without the flag, the default Hub identifier is used and
|
| 129 |
+
the VAE is loaded through the Hugging Face cache.
|
| 130 |
+
|
| 131 |
+
Do not put Meridian's LoRA on the base MiniMax-H3 transformer: it was distilled on Meridian's
|
| 132 |
+
finetuned teacher.
|
| 133 |
+
|
| 134 |
+
## 4. Check the setup
|
| 135 |
+
|
| 136 |
+
These checks import the required components without loading their weights or starting inference:
|
| 137 |
+
|
| 138 |
+
```bash
|
| 139 |
+
ffmpeg -version
|
| 140 |
+
ffprobe -version
|
| 141 |
+
python -m pip check
|
| 142 |
+
python -c "import torch; print('torch:', torch.__version__, 'CUDA:', torch.version.cuda, 'available:', torch.cuda.is_available())"
|
| 143 |
+
python -c "import peft; from diffusers import AutoencoderKLMiniMaxH3, MiniMaxH3Transformer3DModel, MiniMaxH3Scheduler; from recam.h3 import pack; print('H3 and PEFT imports OK')"
|
| 144 |
+
python -c "import os, sys; sys.path.insert(0, os.environ['VGGT_OMEGA_DIR']); from vggt_omega.models import VGGTOmega; print('VGGT-Omega import OK')"
|
| 145 |
+
```
|
| 146 |
+
|
| 147 |
+
For a geometry-only check on the selected GPU:
|
| 148 |
+
|
| 149 |
+
```bash
|
| 150 |
+
CUDA_VISIBLE_DEVICES=0 python inference/sample.py \
|
| 151 |
+
--video examples/media/sp_bouldering_hang.mp4 \
|
| 152 |
+
--yaw 15 --sweep --gauge-only --out out/check
|
| 153 |
+
```
|
| 154 |
+
|
| 155 |
+
This loads VGGT-Omega and prints geometry diagnostics. It does not load the VAE or transformer, and
|
| 156 |
+
does not write the normal output videos. It is not a full inference or model-memory test.
|
| 157 |
+
|
| 158 |
+
Next: run the [first take](../README.md#quickstart), learn the [camera controls](inference.md), or
|
| 159 |
+
start the [Studio demo](../README.md#self-hosting-the-demo).
|
| 160 |
+
|
| 161 |
+
## Setup problems
|
| 162 |
+
|
| 163 |
+
| Symptom | Check |
|
| 164 |
+
|---|---|
|
| 165 |
+
| `hf` or `ffmpeg` not found | Activate the environment for `hf`; install the system FFmpeg tools separately and check `PATH`. |
|
| 166 |
+
| Hub access denied | Confirm the account has accepted the model's terms and received access; authenticate with that account. A token alone does not grant gated access. |
|
| 167 |
+
| `No module named vggt_omega` | `VGGT_OMEGA_DIR` must contain the `vggt_omega/` package. Export it in the same shell that starts the process. |
|
| 168 |
+
| `VGGT-Omega not found` | Check both the source checkout and checkpoint path; `VGGT_OMEGA_CKPT` must name the `.pt` file. |
|
| 169 |
+
| Cannot import a MiniMax-H3 class or layout helper | Reinstall the pinned requirements in the active environment; inspect `python -c "import diffusers; print(diffusers.__file__)"` for a conflicting checkout. |
|
| 170 |
+
| Missing PEFT or adapter-loading error | Install PEFT, use the finetuned teacher, and confirm the adapter filename and `--lora` directory. |
|
| 171 |
+
| CUDA or attention-backend failure | Check the PyTorch/CUDA/driver combination against the reference environment. The service selects `_native_cudnn`; other hardware/backend combinations are not validated here. |
|
| 172 |
+
| Out of memory | Start with 73 output frames, a short source span, and no other GPU workload. The scripts do not automatically offload to CPU. The Studio keeps its models and recent geometry caches resident. |
|
| 173 |
+
|
| 174 |
+
## Lower-memory community work
|
| 175 |
+
|
| 176 |
+
Meridian retains MiniMax-H3's transformer architecture and uses precomputed text embeddings, so
|
| 177 |
+
inference does not load the text encoder. This is a starting point for adapting community memory-saving
|
| 178 |
+
techniques—not evidence that the remaining transformer, activations, VAE, and geometry fit a smaller GPU.
|
| 179 |
+
|
| 180 |
+
We welcome work on quantization and CPU offloading toward consumer GPUs such as the RTX 4090.
|
| 181 |
+
Diffusers documents [quantization](https://huggingface.co/docs/diffusers/main/en/quantization/overview)
|
| 182 |
+
and [memory reduction and offloading](https://huggingface.co/docs/diffusers/main/en/optimization/memory).
|
| 183 |
+
These are general integration references, not a tested Meridian recipe or a reason to replace the
|
| 184 |
+
pinned Diffusers build indiscriminately.
|
| 185 |
+
|
| 186 |
+
The current CLI and service move their models onto one CUDA device; neither exposes those optimizations.
|
| 187 |
+
A contribution needs to integrate them into the custom inference path and validate adapter loading,
|
| 188 |
+
reference conditioning, image quality, peak GPU/host memory, and end-to-end latency. There is no
|
| 189 |
+
verified RTX 4090 configuration or performance claim for this release.
|
docs/method.md
ADDED
|
@@ -0,0 +1,169 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Method
|
| 2 |
+
|
| 3 |
+
[← Meridian](../README.md) · [Inference](inference.md) · [Studio](studio.md)
|
| 4 |
+
|
| 5 |
+
Meridian synthesizes a new observation of an existing event. It separates **which source moment is
|
| 6 |
+
shown** from **which camera observes it**, then uses geometry to make that choice visible to a video
|
| 7 |
+
model. The geometry supplies a spatial constraint; the model supplies the appearance of the completed
|
| 8 |
+
shot, including regions the source camera did not see.
|
| 9 |
+
|
| 10 |
+
This is geometry-guided video re-camera, not a persistent 4D reconstruction or an action-conditioned
|
| 11 |
+
simulator. A new view is a generated interpretation of the recorded event, not evidence of what an
|
| 12 |
+
unobserved camera would actually have captured.
|
| 13 |
+
|
| 14 |
+
[](assets/research/meridian_method.svg)
|
| 15 |
+
|
| 16 |
+
**Overview.** Source time selects both appearance and geometry; the authored camera makes a
|
| 17 |
+
projected reference. Both references condition the video model. Real example: *Spring* (2019),
|
| 18 |
+
© Blender Foundation, CC BY 4.0; input retimed, view projected and generated.
|
| 19 |
+
[Full figure, attribution and provenance](assets/research/README.md).
|
| 20 |
+
|
| 21 |
+
## 1. Choose a source timeline
|
| 22 |
+
|
| 23 |
+
For each output frame `t`, a source-frame map `s(t)` selects the image and geometry to use:
|
| 24 |
+
|
| 25 |
+
| Timeline | Source-frame selection |
|
| 26 |
+
|---|---|
|
| 27 |
+
| Preserve the input's pace | Advance one source frame per output frame. |
|
| 28 |
+
| Hold a moment | Repeat one source frame while the target camera can keep moving. |
|
| 29 |
+
| Slow motion or accelerated action | Retime the input to a constant 24 fps **before** reconstruction, then advance through that export normally. |
|
| 30 |
+
|
| 31 |
+
Both video references follow the same selected timeline. Meridian is not asked to invent a different
|
| 32 |
+
action speed from an unchanged reference. See [Timing](inference.md#timing) for frame-index semantics,
|
| 33 |
+
freeze windows, and FFmpeg recipes.
|
| 34 |
+
|
| 35 |
+
The CLI constructs `s(t)` from `--start`, `--frames`, and optionally `--freeze`. The studio constructs it
|
| 36 |
+
from keyframes: source indices interpolate linearly and are rounded to integers. Studio source keys
|
| 37 |
+
must be non-decreasing; easing affects the camera path, not the source-frame mapping.
|
| 38 |
+
|
| 39 |
+
## 2. Reconstruct the source span
|
| 40 |
+
|
| 41 |
+
The input is resized and letterboxed into a 1280 × 1280 square, then downsampled to 512 × 512 for
|
| 42 |
+
VGGT-Omega. **One model call processes the selected source span jointly**, returning per-frame depth,
|
| 43 |
+
confidence, camera extrinsics, and intrinsics. Per-frame outputs do not mean independent single-frame
|
| 44 |
+
inference. Changing the reconstruction span can change estimates for frames shared by both spans.
|
| 45 |
+
|
| 46 |
+
Before unprojection, the implementation removes:
|
| 47 |
+
|
| 48 |
+
- Non-finite depth or confidence, and confidence values at or below `1e-5`.
|
| 49 |
+
- Depth discontinuities whose 3 × 3 local range exceeds 30% of the depth magnitude.
|
| 50 |
+
- The lowest-confidence 2% of the remaining candidates in each frame.
|
| 51 |
+
|
| 52 |
+
Depth and validity are upsampled to the letterboxed input resolution. A pixel is retained only when
|
| 53 |
+
the interpolated validity exceeds `0.999`, limiting points introduced across rejected boundaries.
|
| 54 |
+
Source RGB supplies the point colors. There is no fused mesh, persistent scene optimization, or
|
| 55 |
+
cross-frame point-cloud accumulation in this stage.
|
| 56 |
+
|
| 57 |
+
### Coordinates and scale
|
| 58 |
+
|
| 59 |
+
Geometry has a reconstruction-relative scale, not calibrated meters. Camera translations use `zm`,
|
| 60 |
+
a median scene depth. Choosing a distant background as the depth reference makes the same numerical
|
| 61 |
+
move much larger than choosing the subject.
|
| 62 |
+
|
| 63 |
+
- **CLI:** a camera offset is applied in each selected source camera's local coordinates:
|
| 64 |
+
`C_target(t) = C_source(s(t)) @ delta(t)`. By default, `zm` comes from valid depths in the first
|
| 65 |
+
selected frame; for `--freeze`, it comes from the held frame. `--pivot fx,fy` restricts the depth
|
| 66 |
+
measurement to a neighborhood of a pixel in the **cropped image**. `--pivot-lock` also places the
|
| 67 |
+
orbit center at the corresponding 3D point.
|
| 68 |
+
- **Studio:** all keys share the coordinate frame of the source camera at `start`: **x right,
|
| 69 |
+
y down, z forward**. Positions and look-at points are expressed in units of `zm`. The API measures
|
| 70 |
+
`zm` around a chosen pixel at `pivot_frame`, falling back to valid picture depths when too few
|
| 71 |
+
local points remain. The current page uses the picture center at `start` as this scale reference;
|
| 72 |
+
a key's **aims at** control changes its look-at point, not the scale reference.
|
| 73 |
+
|
| 74 |
+
The CLI's source-relative trajectory and the studio's shared-frame trajectory are different ways of
|
| 75 |
+
authoring a camera. Similar-looking controls need not produce identical paths on a moving-camera clip.
|
| 76 |
+
|
| 77 |
+
## 3. Render a geometric reference
|
| 78 |
+
|
| 79 |
+
At each output time, the selected source frame's colored point cloud is projected through the target
|
| 80 |
+
camera and its lens. A z-buffer resolves visibility; each point splats onto a 3 × 3 pixel neighborhood.
|
| 81 |
+
Uncovered pixels are filled with RGB `(128, 128, 128)`.
|
| 82 |
+
|
| 83 |
+
The current implementation rasterizes at the **output canvas**, then downsamples the result to the
|
| 84 |
+
**480-class conditioning canvas**. There is no geometric inpainting before generation. Coverage is
|
| 85 |
+
computed for diagnostics, but **no coverage mask is fed to the transformer**.
|
| 86 |
+
|
| 87 |
+
The studio's *what the model sees* preview and the saved `render.mp4` show this downsampled reference.
|
| 88 |
+
They are encoded video previews, not lossless copies of the in-memory conditioning pixels. The
|
| 89 |
+
magenta-hole view is a diagnostic visualization only; the model receives the grey-hole version.
|
| 90 |
+
|
| 91 |
+
## 4. Condition the video transformer
|
| 92 |
+
|
| 93 |
+
MiniMax-H3's VAE encodes two references:
|
| 94 |
+
|
| 95 |
+
1. **`<Video 1>` — source:** the selected source images, at the 480 class.
|
| 96 |
+
2. **`<Video 2>` — geometry:** the rendered target view, at the same conditioning class.
|
| 97 |
+
|
| 98 |
+
The target is generated at the 768 class. Here “class” means an aspect-ratio bucket, not a fixed
|
| 99 |
+
width or height. For a 16:9 input, the reference canvas is 832 × 480 and the output is 1344 × 768;
|
| 100 |
+
square inputs use 640 × 640 and 1024 × 1024 respectively. The nearest bucket is chosen by log aspect
|
| 101 |
+
ratio, with a centered crop inside the letterbox.
|
| 102 |
+
|
| 103 |
+
```text
|
| 104 |
+
source span ──► joint VGGT-Omega reconstruction ──► per-frame geometry
|
| 105 |
+
│ │
|
| 106 |
+
│ source-frame map + camera path│
|
| 107 |
+
│ ▼
|
| 108 |
+
│ z-buffered point splat
|
| 109 |
+
│ │
|
| 110 |
+
▼ ▼
|
| 111 |
+
source reference, 480 class view reference, 480 class
|
| 112 |
+
└────────────────────────┬──────────────────────────┘
|
| 113 |
+
▼
|
| 114 |
+
VAE → packed reference tokens + fixed text
|
| 115 |
+
▼
|
| 116 |
+
finetuned H3 + distilled LoRA → VAE decode
|
| 117 |
+
▼
|
| 118 |
+
new shot, 768 class, 24 fps
|
| 119 |
+
```
|
| 120 |
+
|
| 121 |
+
**The references are concatenated as tokens, not added as channels.** `recam/h3.py` uses Diffusers'
|
| 122 |
+
`MiniMaxH3Ref2VAPrepareLayoutStep.build_ref2va_packed_sequence` to create the reference layout,
|
| 123 |
+
position IDs, and modality tags. The transformer architecture is unchanged.
|
| 124 |
+
|
| 125 |
+
Reference video rows receive the upstream conditioning-noise convention
|
| 126 |
+
`0.999 × latent + 0.001 × noise` and stay fixed during denoising. Target video rows begin as random
|
| 127 |
+
noise. The source is also VAE-encoded at target resolution to establish the target latent shape;
|
| 128 |
+
its values are **not** used to initialize the target rows.
|
| 129 |
+
|
| 130 |
+
### Fixed text and the audio branch
|
| 131 |
+
|
| 132 |
+
[`assets/prompt.txt`](../assets/prompt.txt) describes the two-reference editing task: retain the source
|
| 133 |
+
event and complete the geometry reference's grey holes. Its embeddings are precomputed for each
|
| 134 |
+
supported output length, so inference does not load Qwen3-VL. Editing the text file alone does not
|
| 135 |
+
change inference; the shipped embeddings are what the model reads. An embedding-generation script
|
| 136 |
+
is not included in this release.
|
| 137 |
+
|
| 138 |
+
The packed layout retains H3's audio branch. Cached silence latents supply its shape and length;
|
| 139 |
+
the current code initializes audio rows with noise, denoises them, and discards the result. Meridian
|
| 140 |
+
does not generate or preserve a soundtrack through that branch. The CLI's optional audio file is
|
| 141 |
+
instead made by muxing the source soundtrack after video generation.
|
| 142 |
+
|
| 143 |
+
## 5. Sample the new shot
|
| 144 |
+
|
| 145 |
+
| Mode | CLI settings | Transformer evaluations |
|
| 146 |
+
|---|---|---|
|
| 147 |
+
| Fast adapter, default | `--steps 4 --flow-shift 3` with the LoRA loaded | 3 |
|
| 148 |
+
| Teacher | `--no-lora --steps 50 --flow-shift 12` | 49 |
|
| 149 |
+
|
| 150 |
+
The H3 scheduler counts the terminal zero-noise point in `--steps`; that endpoint does not require
|
| 151 |
+
another model evaluation. The adapter must be loaded on Meridian's finetuned transformer, not the
|
| 152 |
+
unmodified MiniMax-H3 checkpoint. Forward counts do not equal end-to-end speedups: geometry,
|
| 153 |
+
VAE work, and file writing still take time.
|
| 154 |
+
|
| 155 |
+
## Training overview
|
| 156 |
+
|
| 157 |
+
Training provenance, augmentations, and distillation design have moved to [Training and distillation](training.md).
|
| 158 |
+
|
| 159 |
+
## Implementation map
|
| 160 |
+
|
| 161 |
+
| Source | What to read |
|
| 162 |
+
|---|---|
|
| 163 |
+
| [`recam/geometry.py`](../recam/geometry.py) | `reconstruct`, `warp`, and `render_hw`: geometry filtering, projection, and visibility. |
|
| 164 |
+
| [`recam/path.py`](../recam/path.py) | `plan_path` and `hermite`: keyframe interpolation, time mapping, and zero-roll look-at cameras. |
|
| 165 |
+
| [`recam/h3.py`](../recam/h3.py) | `bucket`, `pack`, and `denoise`: canvases, reference conditioning, and the scheduler. |
|
| 166 |
+
| [`inference/sample.py`](../inference/sample.py) | CLI time windows, parametric camera moves, diagnostics, and output files. |
|
| 167 |
+
| [`service/app.py`](../service/app.py) | `prepare`, `geo`, and `do_render`: cached reconstruction and resident inference. |
|
| 168 |
+
|
| 169 |
+
For weight provenance and modification notices, see [`MODIFICATIONS.md`](../MODIFICATIONS.md).
|
docs/release_checklist.md
ADDED
|
@@ -0,0 +1,35 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Release preparation — internal checklist
|
| 2 |
+
|
| 3 |
+
**Keep `Viggle/Meridian` private. Do not publish it without the user's explicit approval.**
|
| 4 |
+
Release-facing wording does not authorize changing repository visibility.
|
| 5 |
+
|
| 6 |
+
## Outstanding publication checks
|
| 7 |
+
|
| 8 |
+
- Public-use clearance, including for the NBA footage and figures, remains pending. The presentation
|
| 9 |
+
examples are research previews; retain source credits and edit records before choosing publication assets.
|
| 10 |
+
- Confirm and upload the intended transformer and LoRA weights before calling the model download complete.
|
| 11 |
+
The old `Viggle/Viggle-Recam` identifier was inaccessible during verification; do not restore it as a working download.
|
| 12 |
+
- Low-memory configurations, including RTX 4090, are community integration targets, not validated support.
|
| 13 |
+
- Fast point-cloud preview helps inspect an authored path; it does not guarantee generated-view fidelity.
|
| 14 |
+
|
| 15 |
+
## Presentation and review
|
| 16 |
+
|
| 17 |
+
- Replace local preview links with cleared publication assets.
|
| 18 |
+
- Method video strips use actual matched frames; the 3D points and camera path are explicitly schematic. Retain this distinction and the source provenance.
|
| 19 |
+
- Studio overview is recorded and preview-only; capture and review a matching generated take before extending it to demonstrate final generation.
|
| 20 |
+
- Complete continuous visual motion review; automated playback and sampled frames are not sufficient.
|
| 21 |
+
- Retain exact camera controls if presenting an isolated space/time ablation.
|
| 22 |
+
- Confirm permission to use every source clip and to publish the corresponding demonstrations.
|
| 23 |
+
- Keep source-time labels accurate when comparing live, retimed, and held sequences.
|
| 24 |
+
- Verify the reported timing against a retained run log before publishing it as a headline result.
|
| 25 |
+
- Do not add a speedup ratio, quality comparison, ablation, or metric without supporting results.
|
| 26 |
+
- Hub destination: Viggle/Meridian (private). Do not point weight-download commands here until the weights are present.
|
| 27 |
+
- Upload referenced presentation media with the Markdown; keep the private Hub snapshot separate from public-use clearance. The legacy push_docs.py targets a different repository.
|
| 28 |
+
|
| 29 |
+
## Retained provenance
|
| 30 |
+
|
| 31 |
+
- [Current example sources and edit notes](../videos-all/research_examples_v2/README.md)
|
| 32 |
+
- [Teaser credits](../videos-all/longtake_showcase/TEASER_V7_NOTES.md)
|
| 33 |
+
- [Method figure sources](assets/research/README.md#illustrated-method)
|
| 34 |
+
- [Studio recording notes](studio_walkthrough.md)
|
| 35 |
+
- [Training and distillation](training.md)
|
docs/research.html
ADDED
|
@@ -0,0 +1,242 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!doctype html>
|
| 2 |
+
<html lang="en">
|
| 3 |
+
<head>
|
| 4 |
+
<meta charset="utf-8">
|
| 5 |
+
<meta name="viewport" content="width=device-width, initial-scale=1">
|
| 6 |
+
<title>Meridian: A new perspective on space and time</title>
|
| 7 |
+
<style>
|
| 8 |
+
:root { color-scheme: light; --ink: #202923; --muted: #647068; --accent: #21634c; --line: #dee5df; }
|
| 9 |
+
* { box-sizing: border-box; }
|
| 10 |
+
html { scroll-behavior: smooth; scroll-padding-top: 2rem; }
|
| 11 |
+
body { margin: 0; background: #f6f7f3; color: var(--ink); font: 17px/1.8 system-ui, -apple-system, BlinkMacSystemFont, "Segoe UI", sans-serif; }
|
| 12 |
+
a { color: var(--accent); text-underline-offset: .2em; }
|
| 13 |
+
a:hover { text-decoration-thickness: 2px; }
|
| 14 |
+
a:focus-visible { outline: 3px solid var(--accent); outline-offset: 4px; }
|
| 15 |
+
.skip-link { position: absolute; left: 1rem; top: -5rem; padding: .5rem 1rem; background: white; }
|
| 16 |
+
.skip-link:focus { top: 1rem; }
|
| 17 |
+
.page-header { max-width: 1280px; margin: auto; padding: 1.5rem 2.5rem; display: flex; justify-content: space-between; gap: 1rem; border-bottom: 1px solid var(--line); color: var(--muted); font-size: .8rem; }
|
| 18 |
+
.page-header span { font-weight: 700; letter-spacing: .12em; text-transform: uppercase; }
|
| 19 |
+
.layout { max-width: 1280px; margin: auto; padding: 3.5rem 2.5rem 5rem; display: grid; grid-template-columns: 220px minmax(0, 1fr); gap: 3.5rem; align-items: start; }
|
| 20 |
+
nav { position: sticky; top: 2rem; max-height: calc(100vh - 4rem); overflow-y: auto; font-size: .8rem; line-height: 1.5; }
|
| 21 |
+
nav h2 { margin: 0 0 1rem; color: var(--muted); font-size: .75rem; letter-spacing: .1em; text-transform: uppercase; }
|
| 22 |
+
nav ul { padding: 0; margin: 0; list-style: none; }
|
| 23 |
+
nav ul ul { padding-left: 1rem; border-left: 1px solid var(--line); margin-top: .5rem; }
|
| 24 |
+
nav li { margin-bottom: .65rem; }
|
| 25 |
+
nav a { color: var(--muted); text-decoration: none; }
|
| 26 |
+
nav a:hover { color: var(--accent); }
|
| 27 |
+
article { min-width: 0; max-width: 850px; padding: 3rem; border: 1px solid var(--line); border-radius: 12px; background: #fff; }
|
| 28 |
+
h1, h2, h3 { line-height: 1.25; letter-spacing: -.025em; text-wrap: balance; }
|
| 29 |
+
h1 { margin: 0 0 1.6rem; font-size: clamp(2rem, 4vw, 3.2rem); }
|
| 30 |
+
article h2 { margin: 3rem 0 1.2rem; padding-top: 1.8rem; border-top: 1px solid var(--line); font-size: 1.7rem; }
|
| 31 |
+
article h3 { margin: 2.2rem 0 1rem; font-size: 1.25rem; }
|
| 32 |
+
p { margin: 1.2rem 0; }
|
| 33 |
+
article a { overflow-wrap: anywhere; }
|
| 34 |
+
img { display: block; max-width: 100%; height: auto; margin: 1.6rem auto; border-radius: 6px; }
|
| 35 |
+
video { display: block; width: 100%; height: auto; object-fit: contain; background: #0b0c0c; border-radius: 6px; }
|
| 36 |
+
video:focus-visible, summary:focus-visible { outline: 3px solid var(--accent); outline-offset: 4px; }
|
| 37 |
+
.film { min-width: 0; margin: 1.6rem 0; }
|
| 38 |
+
.film .film-caption { margin-top: .65rem; color: var(--muted); font-size: .8rem; line-height: 1.6; }
|
| 39 |
+
.video-grid { display: table; width: 100%; table-layout: fixed; border-collapse: separate; border-spacing: 0; margin: 1.8rem 0; }
|
| 40 |
+
.video-grid td { width: 50%; padding: 0 1rem 1.5rem 0; border: 0; vertical-align: top; }
|
| 41 |
+
.video-grid td:nth-child(2) { padding-right: 0; padding-left: .5rem; }
|
| 42 |
+
.video-grid p { margin: .65rem 0 0; color: var(--muted); font-size: .8rem; line-height: 1.6; }
|
| 43 |
+
.video-grid video { aspect-ratio: 1920 / 1088; }
|
| 44 |
+
.more-examples { margin: 1.8rem 0; padding: 1rem 0; border-top: 1px solid var(--line); border-bottom: 1px solid var(--line); }
|
| 45 |
+
.more-examples summary { color: var(--accent); cursor: pointer; }
|
| 46 |
+
.more-examples > p { font-size: .85rem; }
|
| 47 |
+
.studio-demo { margin-top: 1.5rem; }
|
| 48 |
+
.studio-demo summary { color: var(--accent); cursor: pointer; }
|
| 49 |
+
.studio-demo .film { margin-bottom: 0; }
|
| 50 |
+
code { padding: .15em .35em; border-radius: 4px; background: #eef2ed; font-size: .87em; }
|
| 51 |
+
pre { overflow-x: auto; padding: 1rem; background: #eef2ed; border-radius: 6px; }
|
| 52 |
+
pre code { padding: 0; }
|
| 53 |
+
blockquote { margin: 1.5rem 0; padding-left: 1.2rem; border-left: 3px solid var(--accent); color: var(--muted); }
|
| 54 |
+
li { margin-bottom: .4rem; }
|
| 55 |
+
hr { border: 0; border-top: 1px solid var(--line); margin: 3rem 0; }
|
| 56 |
+
table { display: block; overflow-x: auto; border-collapse: collapse; }
|
| 57 |
+
th, td { padding: .5rem .8rem; border: 1px solid var(--line); text-align: left; }
|
| 58 |
+
@media (max-width: 1000px) {
|
| 59 |
+
.layout { grid-template-columns: 1fr; gap: 2rem; max-width: 900px; padding: 2rem 1.5rem; }
|
| 60 |
+
nav { position: static; max-height: none; }
|
| 61 |
+
nav > .toc > ul { columns: 2; column-gap: 2rem; }
|
| 62 |
+
nav li { break-inside: avoid; }
|
| 63 |
+
article { padding: 2rem; }
|
| 64 |
+
}
|
| 65 |
+
@media (max-width: 600px) {
|
| 66 |
+
body { font-size: 16px; }
|
| 67 |
+
.page-header { padding: 1rem; }
|
| 68 |
+
.layout { padding: 1.5rem .75rem; }
|
| 69 |
+
nav { padding: 0 .5rem; }
|
| 70 |
+
nav > .toc > ul { columns: 1; }
|
| 71 |
+
article { padding: 1.4rem; }
|
| 72 |
+
.video-grid, .video-grid tbody, .video-grid tr, .video-grid td { display: block; width: 100%; }
|
| 73 |
+
.video-grid td, .video-grid td:nth-child(2) { padding: 0 0 1.5rem; }
|
| 74 |
+
}
|
| 75 |
+
@media (prefers-reduced-motion: reduce) { html { scroll-behavior: auto; } }
|
| 76 |
+
@media print {
|
| 77 |
+
body { background: white; font-size: 11pt; }
|
| 78 |
+
.page-header, nav, .skip-link { display: none; }
|
| 79 |
+
.layout { display: block; padding: 0; }
|
| 80 |
+
article { max-width: none; padding: 0; border: 0; }
|
| 81 |
+
h1, h2, h3 { break-after: avoid; }
|
| 82 |
+
img { break-inside: avoid; }
|
| 83 |
+
a { color: inherit; }
|
| 84 |
+
}
|
| 85 |
+
</style>
|
| 86 |
+
</head>
|
| 87 |
+
<body>
|
| 88 |
+
<a class="skip-link" href="#article">Skip to article</a>
|
| 89 |
+
<header class="page-header"><span>Meridian · Research</span><a href="research.md">Markdown source</a></header>
|
| 90 |
+
<div class="layout">
|
| 91 |
+
<nav aria-label="Table of contents"><h2>Contents</h2><div class="toc">
|
| 92 |
+
<ul>
|
| 93 |
+
<li><a href="#choose-where-choose-when">Choose where. Choose when.</a></li>
|
| 94 |
+
<li><a href="#method">Method</a></li>
|
| 95 |
+
<li><a href="#why-this-matters">Why this matters</a></li>
|
| 96 |
+
<li><a href="#try-meridian">Try Meridian</a></li>
|
| 97 |
+
</ul>
|
| 98 |
+
</div>
|
| 99 |
+
|
| 100 |
+
</nav>
|
| 101 |
+
<main id="article"><article>
|
| 102 |
+
<h1 id="meridian-a-new-perspective-on-space-and-time">Meridian: A new perspective on space and time</h1>
|
| 103 |
+
<p><strong>One event. Anywhere. Anytime.</strong></p>
|
| 104 |
+
<p>By <strong>Viggle AI</strong></p>
|
| 105 |
+
<p><em>14 September 2026.</em></p>
|
| 106 |
+
<div class="film hero-film">
|
| 107 |
+
<video id="teaser-film" controls playsinline preload="none" width="100%" poster="../videos-all/longtake_showcase/teaser_v7/intro_059.jpg" src="../videos-all/teaser_meridian_showcase_v7.mp4" aria-label="Meridian teaser: a new perspective on space and time">
|
| 108 |
+
<a href="../videos-all/teaser_meridian_showcase_v7.mp4">Watch the Meridian teaser</a>.
|
| 109 |
+
</video>
|
| 110 |
+
<p class="film-caption">48-second teaser</p>
|
| 111 |
+
</div>
|
| 112 |
+
|
| 113 |
+
<p><strong>Meridian is a geometry-guided video model for authoring new observations of existing events.</strong>
|
| 114 |
+
Given a video, choose a new camera path and the source moments to observe. Follow the action from
|
| 115 |
+
another angle, linger on a gesture, or hold an instant while the camera keeps moving.</p>
|
| 116 |
+
<h2 id="choose-where-choose-when">Choose where. Choose when.</h2>
|
| 117 |
+
<ul>
|
| 118 |
+
<li><strong>Where:</strong> design the camera's position, viewing direction, and lens over a shot.</li>
|
| 119 |
+
<li><strong>When:</strong> let the action advance, hold a source moment, or change its pace by retiming the input.</li>
|
| 120 |
+
</ul>
|
| 121 |
+
<p><strong>Bullet time is one possibility, not the whole idea.</strong> Camera motion and source time can be
|
| 122 |
+
composed into different ways of watching the same event. A single image can also be the starting
|
| 123 |
+
point for a moving view.</p>
|
| 124 |
+
<p>The compound-camera example shows its source and requested path. The ballet examples use still images.</p>
|
| 125 |
+
<table class="video-grid">
|
| 126 |
+
<tr>
|
| 127 |
+
<td width="50%" valign="top">
|
| 128 |
+
<video id="nba-film" controls playsinline preload="none" width="100%" poster="../videos-all/research_examples_v1/nba.jpg" src="../videos-all/research_examples_v1/nba.mp4" aria-label="NBA edit combining labeled source footage and generated views of held moments">
|
| 129 |
+
<a href="../videos-all/research_examples_v1/nba.mp4">Watch the example</a>.
|
| 130 |
+
</video>
|
| 131 |
+
<p><strong>A dunk.</strong> Source action, revisited from new angles. An edited sequence; dunk completion is source footage.</p>
|
| 132 |
+
</td>
|
| 133 |
+
<td width="50%" valign="top">
|
| 134 |
+
<video id="berry-film" controls playsinline preload="none" width="100%" poster="../videos-all/research_examples_v1/berry.jpg" src="../videos-all/research_examples_v1/berry.mp4" aria-label="Strawberries: source time advances, holds while the camera moves, then resumes">
|
| 135 |
+
<a href="../videos-all/research_examples_v1/berry.mp4">Watch the example</a>.
|
| 136 |
+
</video>
|
| 137 |
+
<p><strong>Play. Hold. Resume.</strong> Linger on the splash, then let it continue.</p>
|
| 138 |
+
</td>
|
| 139 |
+
</tr>
|
| 140 |
+
<tr>
|
| 141 |
+
<td width="50%" valign="top">
|
| 142 |
+
<video id="moto-film" controls playsinline preload="none" width="100%" poster="../videos-all/research_examples_v2/motor_compound.jpg" src="../videos-all/teaser_meridian_compound_motor_dust_explained_v1.mp4" aria-label="Motocross: one uncut take with a compound camera path, selected source video, and requested camera diagrams">
|
| 143 |
+
<a href="../videos-all/teaser_meridian_compound_motor_dust_explained_v1.mp4">Watch the example</a>.
|
| 144 |
+
</video>
|
| 145 |
+
<p><strong>Compose a camera path.</strong> Widen, orbit, slide, approach, retreat—one uncut take.</p>
|
| 146 |
+
</td>
|
| 147 |
+
<td width="50%" valign="top">
|
| 148 |
+
<video id="ballet-film" controls playsinline preload="none" width="100%" poster="../videos-all/research_examples_v2/ballet_reverse45.jpg" src="../videos-all/meridian_ballet_l150_female_reverse45.mp4" aria-label="Female ballet dancer: generated camera movement from one still image">
|
| 149 |
+
<a href="../videos-all/meridian_ballet_l150_female_reverse45.mp4">Watch the example</a>.
|
| 150 |
+
</video>
|
| 151 |
+
<p><strong>One image. Another viewpoint.</strong> A camera move from a single ballet image.</p>
|
| 152 |
+
</td>
|
| 153 |
+
</tr>
|
| 154 |
+
</table>
|
| 155 |
+
|
| 156 |
+
<details class="more-examples">
|
| 157 |
+
<summary>More examples · robots, animation, dance, and sport</summary>
|
| 158 |
+
<table class="video-grid">
|
| 159 |
+
<tr>
|
| 160 |
+
<td width="50%" valign="top">
|
| 161 |
+
<video id="robot-film" controls playsinline preload="none" width="100%" poster="../videos-all/research_examples_v1/robot.jpg" src="../videos-all/research_examples_v1/robot.mp4" aria-label="Robot folding cloth from a higher generated viewpoint, with aligned input">
|
| 162 |
+
<a href="../videos-all/research_examples_v1/robot.mp4">Watch the example</a>.
|
| 163 |
+
</video>
|
| 164 |
+
<p><strong>Robot manipulation.</strong> The task continues from a higher viewpoint.</p>
|
| 165 |
+
</td>
|
| 166 |
+
<td width="50%" valign="top">
|
| 167 |
+
<video id="charge-film" controls playsinline preload="none" width="100%" poster="../videos-all/research_examples_v1/charge.jpg" src="../videos-all/research_examples_v1/charge.mp4" aria-label="Charge animation: play, hold, resume with a moving viewpoint">
|
| 168 |
+
<a href="../videos-all/research_examples_v1/charge.mp4">Watch the example</a>.
|
| 169 |
+
</video>
|
| 170 |
+
<p><strong>An animated event.</strong> Hold the action; move the camera.</p>
|
| 171 |
+
</td>
|
| 172 |
+
</tr>
|
| 173 |
+
<tr>
|
| 174 |
+
<td width="50%" valign="top">
|
| 175 |
+
<video id="ballet_male-film" controls playsinline preload="none" width="100%" poster="../videos-all/research_examples_v1/ballet_male.jpg" src="../videos-all/research_examples_v1/ballet_male.mp4" aria-label="Male ballet dancer: a separate single-image input and generated viewpoint">
|
| 176 |
+
<a href="../videos-all/research_examples_v1/ballet_male.mp4">Watch the example</a>.
|
| 177 |
+
</video>
|
| 178 |
+
<p><strong>Another ballet photograph.</strong> One image, a moving view.</p>
|
| 179 |
+
</td>
|
| 180 |
+
<td width="50%" valign="top">
|
| 181 |
+
<video id="gymnast-film" controls playsinline preload="none" width="100%" poster="../videos-all/research_examples_v1/gymnast.jpg" src="../videos-all/research_examples_v1/gymnast.mp4" aria-label="Gymnastics: action continues while the generated camera rises">
|
| 182 |
+
<a href="../videos-all/research_examples_v1/gymnast.mp4">Watch the example</a>.
|
| 183 |
+
</video>
|
| 184 |
+
<p><strong>A rising view.</strong> The gesture unfolds.</p>
|
| 185 |
+
</td>
|
| 186 |
+
</tr>
|
| 187 |
+
<tr>
|
| 188 |
+
<td width="50%" valign="top">
|
| 189 |
+
<video id="powder-film" controls playsinline preload="none" width="100%" poster="../videos-all/research_examples_v1/powder.jpg" src="../videos-all/research_examples_v1/powder.mp4" aria-label="Snow sports: action continues with a moving generated viewpoint">
|
| 190 |
+
<a href="../videos-all/research_examples_v1/powder.mp4">Watch the example</a>.
|
| 191 |
+
</video>
|
| 192 |
+
<p><strong>Through the powder.</strong> Move with the action.</p>
|
| 193 |
+
</td>
|
| 194 |
+
</tr>
|
| 195 |
+
</table>
|
| 196 |
+
</details>
|
| 197 |
+
|
| 198 |
+
<h2 id="method">Method</h2>
|
| 199 |
+
<p><img alt="Input video enters VGGT-Omega; estimated depth and source cameras give colored 3D points. User-specified target cameras reproject those points into a warped video. Both the time-aligned source video and warped video condition Meridian to generate the output video. Video samples are real; 3D points and cameras are schematic." src="assets/research/meridian_illustrated_method.png" /></p>
|
| 200 |
+
<p><em>Matched source, warp, and output frames; the 3D points and cameras are schematic.</em></p>
|
| 201 |
+
<p>The method is simple: <strong>use geometry to show a video model where to look.</strong></p>
|
| 202 |
+
<p><strong>1. Reproject the source.</strong> VGGT-Omega estimates depth and source-camera poses. We build colored
|
| 203 |
+
3D points, select the source moments, and project those points through an authored camera path
|
| 204 |
+
into a warped video.</p>
|
| 205 |
+
<p><strong>2. Generate the new view.</strong> Meridian, built on MiniMax-H3, takes <strong>the source video and warped
|
| 206 |
+
video</strong>, aligned to the same source moments, and generates the new shot. Geometry guides the view;
|
| 207 |
+
the video model fills missing regions and refines appearance.</p>
|
| 208 |
+
<p><strong>Preview before generation.</strong> Once geometry is available, fast point-cloud rendering makes the
|
| 209 |
+
chosen path visible. Check the framing, viewing direction, and uncovered regions—and adjust the
|
| 210 |
+
camera before running the video model. This inexpensive preview is a useful consequence of making
|
| 211 |
+
camera control explicit.</p>
|
| 212 |
+
<h2 id="why-this-matters">Why this matters</h2>
|
| 213 |
+
<p>The shift is from generating another scene to <strong>choosing another observation of the same event</strong>.
|
| 214 |
+
This is the world-model perspective behind Meridian: connect what we see to where and when we
|
| 215 |
+
observe it, grounded in supplied footage rather than unrestricted simulation.</p>
|
| 216 |
+
<p>Unseen regions are generated, not recovered. Geometry errors and large moves—including 360°
|
| 217 |
+
orbits—can destabilize the view. Time edits revisit supplied frames, and separate takes need not
|
| 218 |
+
form a consistent world.</p>
|
| 219 |
+
<h2 id="try-meridian">Try Meridian</h2>
|
| 220 |
+
<p><a href="../README.md#quickstart">Get started with Meridian</a>.</p>
|
| 221 |
+
<p>Meridian uses MiniMax-H3 with precomputed text embeddings, <strong>without loading a text encoder</strong>.
|
| 222 |
+
We welcome community work on quantization and CPU offloading toward smaller GPUs, including the
|
| 223 |
+
RTX 4090; those configurations are not yet supported or validated by the provided implementation.</p>
|
| 224 |
+
<p>The release also includes a <strong>very basic, vibe-coded Studio demo</strong> to illustrate how
|
| 225 |
+
to use the model—not a production editor. It supports multi-key camera paths and real-time 3D
|
| 226 |
+
preview, not real-time video generation.</p>
|
| 227 |
+
<details class="studio-demo">
|
| 228 |
+
<summary>Watch the 38-second Studio walkthrough</summary>
|
| 229 |
+
<div class="film">
|
| 230 |
+
<video id="studio-film" controls playsinline preload="none" width="100%" poster="../videos-all/studio_walkthrough/nba3_preview_live_02/studio_walkthrough_concise_poster.jpg" src="../videos-all/studio_walkthrough/nba3_preview_live_02/studio_walkthrough_concise.mp4" aria-label="Early Studio demo: actual authoring and geometric preview, not final generation">
|
| 231 |
+
<a href="../videos-all/studio_walkthrough/nba3_preview_live_02/studio_walkthrough_concise.mp4">Watch the Studio walkthrough</a>.
|
| 232 |
+
</video>
|
| 233 |
+
<p class="film-caption">Authoring and geometric preview only, with some operations and waits omitted—not a final generated take.</p>
|
| 234 |
+
</div>
|
| 235 |
+
</details>
|
| 236 |
+
|
| 237 |
+
<hr />
|
| 238 |
+
<p>Powered by MiniMax H3. See the <a href="../README.md#license">licenses and intended use</a>.</p>
|
| 239 |
+
</article></main>
|
| 240 |
+
</div>
|
| 241 |
+
</body>
|
| 242 |
+
</html>
|
docs/research.md
ADDED
|
@@ -0,0 +1,159 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Meridian: A new perspective on space and time
|
| 2 |
+
|
| 3 |
+
**One event. Anywhere. Anytime.**
|
| 4 |
+
|
| 5 |
+
By **Viggle AI**
|
| 6 |
+
|
| 7 |
+
*14 September 2026.*
|
| 8 |
+
|
| 9 |
+
<div class="film hero-film">
|
| 10 |
+
<video id="teaser-film" controls playsinline preload="none" width="100%" poster="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/longtake_showcase/teaser_v7/intro_059.jpg" src="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/teaser_meridian_showcase_v7.mp4" aria-label="Meridian teaser: a new perspective on space and time">
|
| 11 |
+
<a href="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/teaser_meridian_showcase_v7.mp4">Watch the Meridian teaser</a>.
|
| 12 |
+
</video>
|
| 13 |
+
<p class="film-caption">48-second teaser</p>
|
| 14 |
+
</div>
|
| 15 |
+
|
| 16 |
+
**Meridian is a geometry-guided video model for authoring new observations of existing events.**
|
| 17 |
+
Given a video, choose a new camera path and the source moments to observe. Follow the action from
|
| 18 |
+
another angle, linger on a gesture, or hold an instant while the camera keeps moving.
|
| 19 |
+
|
| 20 |
+
## Choose where. Choose when.
|
| 21 |
+
|
| 22 |
+
- **Where:** design the camera's position, viewing direction, and lens over a shot.
|
| 23 |
+
- **When:** let the action advance, hold a source moment, or change its pace by retiming the input.
|
| 24 |
+
|
| 25 |
+
**Bullet time is one possibility, not the whole idea.** Camera motion and source time can be
|
| 26 |
+
composed into different ways of watching the same event. A single image can also be the starting
|
| 27 |
+
point for a moving view.
|
| 28 |
+
|
| 29 |
+
The compound-camera example shows its source and requested path. The ballet examples use still images.
|
| 30 |
+
|
| 31 |
+
<table class="video-grid">
|
| 32 |
+
<tr>
|
| 33 |
+
<td width="50%" valign="top">
|
| 34 |
+
<video id="nba-film" controls playsinline preload="none" width="100%" poster="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/research_examples_v1/nba.jpg" src="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/research_examples_v1/nba.mp4" aria-label="NBA edit combining labeled source footage and generated views of held moments">
|
| 35 |
+
<a href="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/research_examples_v1/nba.mp4">Watch the example</a>.
|
| 36 |
+
</video>
|
| 37 |
+
<p><strong>A dunk.</strong> Source action, revisited from new angles. An edited sequence; dunk completion is source footage.</p>
|
| 38 |
+
</td>
|
| 39 |
+
<td width="50%" valign="top">
|
| 40 |
+
<video id="berry-film" controls playsinline preload="none" width="100%" poster="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/research_examples_v1/berry.jpg" src="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/research_examples_v1/berry.mp4" aria-label="Strawberries: source time advances, holds while the camera moves, then resumes">
|
| 41 |
+
<a href="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/research_examples_v1/berry.mp4">Watch the example</a>.
|
| 42 |
+
</video>
|
| 43 |
+
<p><strong>Play. Hold. Resume.</strong> Linger on the splash, then let it continue.</p>
|
| 44 |
+
</td>
|
| 45 |
+
</tr>
|
| 46 |
+
<tr>
|
| 47 |
+
<td width="50%" valign="top">
|
| 48 |
+
<video id="moto-film" controls playsinline preload="none" width="100%" poster="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/research_examples_v2/motor_compound.jpg" src="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/teaser_meridian_compound_motor_dust_explained_v1.mp4" aria-label="Motocross: one uncut take with a compound camera path, selected source video, and requested camera diagrams">
|
| 49 |
+
<a href="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/teaser_meridian_compound_motor_dust_explained_v1.mp4">Watch the example</a>.
|
| 50 |
+
</video>
|
| 51 |
+
<p><strong>Compose a camera path.</strong> Widen, orbit, slide, approach, retreat—one uncut take.</p>
|
| 52 |
+
</td>
|
| 53 |
+
<td width="50%" valign="top">
|
| 54 |
+
<video id="ballet-film" controls playsinline preload="none" width="100%" poster="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/research_examples_v2/ballet_reverse45.jpg" src="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/meridian_ballet_l150_female_reverse45.mp4" aria-label="Female ballet dancer: generated camera movement from one still image">
|
| 55 |
+
<a href="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/meridian_ballet_l150_female_reverse45.mp4">Watch the example</a>.
|
| 56 |
+
</video>
|
| 57 |
+
<p><strong>One image. Another viewpoint.</strong> A camera move from a single ballet image.</p>
|
| 58 |
+
</td>
|
| 59 |
+
</tr>
|
| 60 |
+
</table>
|
| 61 |
+
|
| 62 |
+
<details class="more-examples">
|
| 63 |
+
<summary>More examples · robots, animation, dance, and sport</summary>
|
| 64 |
+
<table class="video-grid">
|
| 65 |
+
<tr>
|
| 66 |
+
<td width="50%" valign="top">
|
| 67 |
+
<video id="robot-film" controls playsinline preload="none" width="100%" poster="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/research_examples_v1/robot.jpg" src="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/research_examples_v1/robot.mp4" aria-label="Robot folding cloth from a higher generated viewpoint, with aligned input">
|
| 68 |
+
<a href="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/research_examples_v1/robot.mp4">Watch the example</a>.
|
| 69 |
+
</video>
|
| 70 |
+
<p><strong>Robot manipulation.</strong> The task continues from a higher viewpoint.</p>
|
| 71 |
+
</td>
|
| 72 |
+
<td width="50%" valign="top">
|
| 73 |
+
<video id="charge-film" controls playsinline preload="none" width="100%" poster="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/research_examples_v1/charge.jpg" src="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/research_examples_v1/charge.mp4" aria-label="Charge animation: play, hold, resume with a moving viewpoint">
|
| 74 |
+
<a href="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/research_examples_v1/charge.mp4">Watch the example</a>.
|
| 75 |
+
</video>
|
| 76 |
+
<p><strong>An animated event.</strong> Hold the action; move the camera.</p>
|
| 77 |
+
</td>
|
| 78 |
+
</tr>
|
| 79 |
+
<tr>
|
| 80 |
+
<td width="50%" valign="top">
|
| 81 |
+
<video id="ballet_male-film" controls playsinline preload="none" width="100%" poster="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/research_examples_v1/ballet_male.jpg" src="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/research_examples_v1/ballet_male.mp4" aria-label="Male ballet dancer: a separate single-image input and generated viewpoint">
|
| 82 |
+
<a href="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/research_examples_v1/ballet_male.mp4">Watch the example</a>.
|
| 83 |
+
</video>
|
| 84 |
+
<p><strong>Another ballet photograph.</strong> One image, a moving view.</p>
|
| 85 |
+
</td>
|
| 86 |
+
<td width="50%" valign="top">
|
| 87 |
+
<video id="gymnast-film" controls playsinline preload="none" width="100%" poster="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/research_examples_v1/gymnast.jpg" src="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/research_examples_v1/gymnast.mp4" aria-label="Gymnastics: action continues while the generated camera rises">
|
| 88 |
+
<a href="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/research_examples_v1/gymnast.mp4">Watch the example</a>.
|
| 89 |
+
</video>
|
| 90 |
+
<p><strong>A rising view.</strong> The gesture unfolds.</p>
|
| 91 |
+
</td>
|
| 92 |
+
</tr>
|
| 93 |
+
<tr>
|
| 94 |
+
<td width="50%" valign="top">
|
| 95 |
+
<video id="powder-film" controls playsinline preload="none" width="100%" poster="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/research_examples_v1/powder.jpg" src="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/research_examples_v1/powder.mp4" aria-label="Snow sports: action continues with a moving generated viewpoint">
|
| 96 |
+
<a href="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/research_examples_v1/powder.mp4">Watch the example</a>.
|
| 97 |
+
</video>
|
| 98 |
+
<p><strong>Through the powder.</strong> Move with the action.</p>
|
| 99 |
+
</td>
|
| 100 |
+
</tr>
|
| 101 |
+
</table>
|
| 102 |
+
</details>
|
| 103 |
+
|
| 104 |
+
## Method
|
| 105 |
+
|
| 106 |
+

|
| 107 |
+
|
| 108 |
+
*Matched source, warp, and output frames; the 3D points and cameras are schematic.*
|
| 109 |
+
|
| 110 |
+
The method is simple: **use geometry to show a video model where to look.**
|
| 111 |
+
|
| 112 |
+
**1. Reproject the source.** VGGT-Omega estimates depth and source-camera poses. We build colored
|
| 113 |
+
3D points, select the source moments, and project those points through an authored camera path
|
| 114 |
+
into a warped video.
|
| 115 |
+
|
| 116 |
+
**2. Generate the new view.** Meridian, built on MiniMax-H3, takes **the source video and warped
|
| 117 |
+
video**, aligned to the same source moments, and generates the new shot. Geometry guides the view;
|
| 118 |
+
the video model fills missing regions and refines appearance.
|
| 119 |
+
|
| 120 |
+
**Preview before generation.** Once geometry is available, fast point-cloud rendering makes the
|
| 121 |
+
chosen path visible. Check the framing, viewing direction, and uncovered regions—and adjust the
|
| 122 |
+
camera before running the video model. This inexpensive preview is a useful consequence of making
|
| 123 |
+
camera control explicit.
|
| 124 |
+
|
| 125 |
+
## Why this matters
|
| 126 |
+
|
| 127 |
+
The shift is from generating another scene to **choosing another observation of the same event**.
|
| 128 |
+
This is the world-model perspective behind Meridian: connect what we see to where and when we
|
| 129 |
+
observe it, grounded in supplied footage rather than unrestricted simulation.
|
| 130 |
+
|
| 131 |
+
Unseen regions are generated, not recovered. Geometry errors and large moves—including 360°
|
| 132 |
+
orbits—can destabilize the view. Time edits revisit supplied frames, and separate takes need not
|
| 133 |
+
form a consistent world.
|
| 134 |
+
|
| 135 |
+
## Try Meridian
|
| 136 |
+
|
| 137 |
+
[Get started with Meridian](../README.md#quickstart).
|
| 138 |
+
|
| 139 |
+
Meridian uses MiniMax-H3 with precomputed text embeddings, **without loading a text encoder**.
|
| 140 |
+
We welcome community work on quantization and CPU offloading toward smaller GPUs, including the
|
| 141 |
+
RTX 4090; those configurations are not yet supported or validated by the provided implementation.
|
| 142 |
+
|
| 143 |
+
The release also includes a **very basic, vibe-coded Studio demo** to illustrate how
|
| 144 |
+
to use the model—not a production editor. It supports multi-key camera paths and real-time 3D
|
| 145 |
+
preview, not real-time video generation.
|
| 146 |
+
|
| 147 |
+
<details class="studio-demo">
|
| 148 |
+
<summary>Watch the 38-second Studio walkthrough</summary>
|
| 149 |
+
<div class="film">
|
| 150 |
+
<video id="studio-film" controls playsinline preload="none" width="100%" poster="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/studio_walkthrough/nba3_preview_live_02/studio_walkthrough_concise_poster.jpg" src="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/studio_walkthrough/nba3_preview_live_02/studio_walkthrough_concise.mp4" aria-label="Early Studio demo: actual authoring and geometric preview, not final generation">
|
| 151 |
+
<a href="https://huggingface.co/Viggle/Meridian/resolve/main/videos-all/studio_walkthrough/nba3_preview_live_02/studio_walkthrough_concise.mp4">Watch the Studio walkthrough</a>.
|
| 152 |
+
</video>
|
| 153 |
+
<p class="film-caption">Authoring and geometric preview only, with some operations and waits omitted—not a final generated take.</p>
|
| 154 |
+
</div>
|
| 155 |
+
</details>
|
| 156 |
+
|
| 157 |
+
---
|
| 158 |
+
|
| 159 |
+
Powered by MiniMax H3. See the [licenses and intended use](../README.md#license).
|
docs/studio.md
ADDED
|
@@ -0,0 +1,210 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Studio: author a new shot
|
| 2 |
+
|
| 3 |
+
[← Meridian](../README.md) · [Installation](installation.md) · [API](api.md) · [CLI](inference.md)
|
| 4 |
+
|
| 5 |
+
The self-hosted studio lets you place cameras in a reconstructed scene, inspect the geometry reference,
|
| 6 |
+
and generate a take without writing a command for every path revision.
|
| 7 |
+
|
| 8 |
+
## What updates in real time?
|
| 9 |
+
|
| 10 |
+
After reconstruction and point-cloud loading, the **browser's 3D view updates interactively** as you
|
| 11 |
+
move cameras, change their aim or look through a key. This is the real-time authoring preview—not
|
| 12 |
+
real-time generative video.
|
| 13 |
+
|
| 14 |
+
The **full-path geometric-reference video** is refreshed by the server after a valid edit. It uses
|
| 15 |
+
GPU warping and video encoding, and may wait behind reconstruction or generation on the same service.
|
| 16 |
+
The **final generated take** is a separate job started with **Render this take**. No fixed preview
|
| 17 |
+
latency or frame-rate guarantee is implied.
|
| 18 |
+
|
| 19 |
+
## Start the service
|
| 20 |
+
|
| 21 |
+
After [installation](installation.md), run from the release directory:
|
| 22 |
+
|
| 23 |
+
```bash
|
| 24 |
+
CARD=0 bash service/run.sh --host 127.0.0.1 --port 8412
|
| 25 |
+
```
|
| 26 |
+
|
| 27 |
+
Open `http://127.0.0.1:8412` after the terminal prints `ready`. Startup loads VGGT-Omega, the VAE,
|
| 28 |
+
the finetuned teacher, and the student adapter onto one GPU; the previously reported B200 cold-start
|
| 29 |
+
time is about 95 seconds. The active shell must have the VGGT-Omega environment variables set.
|
| 30 |
+
|
| 31 |
+
If you downloaded the VAE locally, append `--model-dir ../MiniMax-H3`.
|
| 32 |
+
|
| 33 |
+
**Keep the service private.** The program defaults to `0.0.0.0` when `--host` is omitted; the command
|
| 34 |
+
above deliberately binds to loopback. The service has no authentication, per-user isolation, upload
|
| 35 |
+
quota, or bounded durable job queue. For access to a remote machine, use an SSH tunnel or a protected
|
| 36 |
+
deployment with authentication, resource limits, and the safeguards required by the model license.
|
| 37 |
+
Do not expose this development service directly to the internet.
|
| 38 |
+
|
| 39 |
+
## From clip to take
|
| 40 |
+
|
| 41 |
+
### 1. Choose a clip and source window
|
| 42 |
+
|
| 43 |
+
Upload an MP4/MOV/WebM or choose one of the sample clips. The service normalizes it to H.264,
|
| 44 |
+
24 fps, and an aspect-preserving frame bounded by 1280 × 1280, with rotation baked in. Unlike the
|
| 45 |
+
CLI, it performs this normalization automatically.
|
| 46 |
+
|
| 47 |
+
The current page requires at least **73 normalized input frames**. It detects candidate hard cuts and
|
| 48 |
+
prepares an initial window of at most **124 source frames**, stopping before the next detected cut.
|
| 49 |
+
Cut detection is heuristic; split a clip manually if a cut is missed or a flash is mistaken for one.
|
| 50 |
+
Moving the window's start reconstructs the new span and **resets the keys**.
|
| 51 |
+
|
| 52 |
+
Select the take length separately. The page offers **73, 124, 175, or 243 output frames**; the CLI
|
| 53 |
+
exposes all eight supported model lengths. A longer take does not automatically mean a longer source
|
| 54 |
+
window or additional captured action.
|
| 55 |
+
|
| 56 |
+
### 2. Start from a camera move
|
| 57 |
+
|
| 58 |
+
Use a template: **orbit**, **push in**, **slide**, **crane**, **freeze + orbit**, or **the clip's own
|
| 59 |
+
camera**. Templates replace the existing keys; **Ctrl+Z** undoes an edit.
|
| 60 |
+
|
| 61 |
+
The source-camera template initializes editable endpoints; it is not an exact replay of every
|
| 62 |
+
estimated source pose. Likewise, a template translated into a few keys is an editable approximation
|
| 63 |
+
of its underlying parametric move. Inspect the resulting reference rather than assuming it matches
|
| 64 |
+
a CLI command exactly.
|
| 65 |
+
|
| 66 |
+
### 3. Refine the keys
|
| 67 |
+
|
| 68 |
+
Each key chooses a camera and a time:
|
| 69 |
+
|
| 70 |
+
| Control | Meaning |
|
| 71 |
+
|---|---|
|
| 72 |
+
| Camera position | Where to observe the scene from. Drag a camera in the 3D view. |
|
| 73 |
+
| **aims at** | The key's look-at point. Use **pick in 3D** or **centre**. This does not change the reconstruction's depth scale. |
|
| 74 |
+
| **clip frame it shows** | Source frame, indexed in the normalized uploaded clip. |
|
| 75 |
+
| **output frame it lands on** | Position in the generated take. The first and last keys anchor its endpoints. |
|
| 76 |
+
| **lens** | Horizontal field of view, converted to a multiplier over the selected source frame's estimated focal length. |
|
| 77 |
+
|
| 78 |
+
Click a key's row or thumbnail to look through its camera; use **back to the overview** to see the
|
| 79 |
+
whole path. While looking through a key, drag to aim, Shift-drag to translate, and scroll to dolly.
|
| 80 |
+
Add a key at the preview frame to refine a segment. Camera roll is fixed to zero.
|
| 81 |
+
|
| 82 |
+
### Go beyond a preset
|
| 83 |
+
|
| 84 |
+
A path can combine several stages: **push forward → turn toward a detail → slide right → retreat**.
|
| 85 |
+
Add a key at each change of intention, then set its position and look-at point in the shared 3D scene.
|
| 86 |
+
Position and aim interpolate along cubic curves; the source-frame map is interpolated separately.
|
| 87 |
+
This is different from ramping yaw, translation and dolly together in one CLI sweep.
|
| 88 |
+
|
| 89 |
+
To let the camera travel while an instant holds, assign the same **clip frame it shows** to two or
|
| 90 |
+
more keys at different output frames. Resume with a later source frame. Inspect every segment and
|
| 91 |
+
the joins: several keys do not guarantee adequate geometry, subject visibility or generated continuity.
|
| 92 |
+
The [walkthrough plan](studio_walkthrough.md#source-and-camera-design) includes a concrete timing
|
| 93 |
+
sketch, not scene-independent camera coordinates or an already-generated demonstration.
|
| 94 |
+
|
| 95 |
+
### 4. Inspect the reference
|
| 96 |
+
|
| 97 |
+
After a valid edit, the studio re-warps the path before enabling generation:
|
| 98 |
+
|
| 99 |
+
- **what the model sees:** the grey-hole geometry reference at conditioning resolution.
|
| 100 |
+
- **where the pixels are missing:** the same view with missing regions highlighted in magenta.
|
| 101 |
+
|
| 102 |
+
The reference is generated by the same geometry path used for inference. Its browser playback is a
|
| 103 |
+
compressed visualization, not a pixel-exact copy of the tensor. Coherent framing and stable surfaces
|
| 104 |
+
matter more than a low missing-pixel percentage. Pay special attention to faces, thin structures,
|
| 105 |
+
subject silhouettes, and new surfaces revealed by the camera.
|
| 106 |
+
|
| 107 |
+
### 5. Render and compare
|
| 108 |
+
|
| 109 |
+
Choose **Render this take** after checking the path. The service performs VAE encoding, three student
|
| 110 |
+
forwards, decoding, and video writing; progress appears on the render screen. Generation recomputes
|
| 111 |
+
the warp rather than reading the preview MP4 back into the model.
|
| 112 |
+
|
| 113 |
+
The take screen shows the selected source timeline, geometry reference, and generated shot in sync.
|
| 114 |
+
Download `out.mp4` or the three-up `grid.mp4`. Service outputs have no soundtrack; the CLI's
|
| 115 |
+
`out_audio.mp4` muxing workflow is not part of the studio. Camera archives (`cams.npz`) are CLI-only.
|
| 116 |
+
|
| 117 |
+
## Source time and output time
|
| 118 |
+
|
| 119 |
+
The keyframe representation is `{pos, look, src, t, ease, focal}`. `src` is an absolute source index;
|
| 120 |
+
`t` is an output index. Between two keys, the source rate is:
|
| 121 |
+
|
| 122 |
+
```text
|
| 123 |
+
rate = (next.src - current.src) / (next.t - current.t)
|
| 124 |
+
```
|
| 125 |
+
|
| 126 |
+
- **Rate 1:** preserve the uploaded video's pace, including any slow motion or speed-up already
|
| 127 |
+
baked into that video.
|
| 128 |
+
- **Rate 0:** hold one instant while the camera may move.
|
| 129 |
+
- **Other positive rates:** interpolate the source indices and round to frames, duplicating or
|
| 130 |
+
skipping them. The UI warns outside holds and approximately 1:1 playback; this is not a motion
|
| 131 |
+
interpolation system.
|
| 132 |
+
- **Negative rates:** rejected. Source keys must never run backward.
|
| 133 |
+
|
| 134 |
+
For slow motion or speed-ups, use the [24 fps source-retiming workflow](inference.md#slow-motion-and-speed-ups)
|
| 135 |
+
first, then author a 1:1 path over that export. A warning about a keyframe segment does not mean
|
| 136 |
+
pre-retimed footage is unsupported.
|
| 137 |
+
|
| 138 |
+
**Check long takes carefully.** The page prepares at most 124 source frames. If you stretch that
|
| 139 |
+
entire source window across a 243-frame take with two endpoints, the source advances at roughly
|
| 140 |
+
half speed; it does not play 124 frames normally and then automatically hold. To preserve pace,
|
| 141 |
+
place an explicit key where live motion ends, followed by a hold, or use the CLI with enough
|
| 142 |
+
pre-retimed input frames. Changing take length or choosing a template can change these rates.
|
| 143 |
+
|
| 144 |
+
## Preview checks
|
| 145 |
+
|
| 146 |
+
The page enables rendering only after the latest valid warp passes these checks:
|
| 147 |
+
|
| 148 |
+
| Check | Current threshold |
|
| 149 |
+
|---|---|
|
| 150 |
+
| Clearance proxy | `ahead >= -0.1`, in pivot-depth units. |
|
| 151 |
+
| Difference from source camera | Translation `moved > 0.004`, key orientation change `turned > 0.5°`, or focal change `zoomed > 0.01`. |
|
| 152 |
+
|
| 153 |
+
`ahead` is the minimum over time of the fifth-percentile target-camera depth for valid points in
|
| 154 |
+
the central source region. It helps flag fly-throughs; it is **not** a complete collision test or a
|
| 155 |
+
guarantee that the camera stays outside every surface. `moved` measures departure from the source
|
| 156 |
+
camera, not whether the target camera travels over time. A different but stationary view can pass.
|
| 157 |
+
|
| 158 |
+
The missing-pixel percentage is informative, not a gate. A pure focal change may pass the motion
|
| 159 |
+
check while still being ignored by the model.
|
| 160 |
+
|
| 161 |
+
**These clearance and camera-change checks live in the browser, not `/render`.** API clients must
|
| 162 |
+
inspect previews and validate their own requests; calling `/render` bypasses the page's checks.
|
| 163 |
+
The API also does not enforce the page's cut-aware 124-frame window policy.
|
| 164 |
+
|
| 165 |
+
## Memory and lifecycle
|
| 166 |
+
|
| 167 |
+
One process owns one GPU. A lock serializes GPU work, including preparation, previews, and generation;
|
| 168 |
+
multiple requests do not yield concurrent GPU inference. Render requests start background threads
|
| 169 |
+
that can wait on the lock, but there is no bounded queue, cancellation API, or durable job scheduler.
|
| 170 |
+
Run **one worker**, not multiple Uvicorn workers that each load a model copy.
|
| 171 |
+
|
| 172 |
+
| Option | Default | Purpose |
|
| 173 |
+
|---|---|---|
|
| 174 |
+
| `--host`, `--port` | `0.0.0.0`, `8412` | Listen address; use loopback unless the deployment is protected. |
|
| 175 |
+
| `--work` | `<release>/work` | Uploads, preview files, and generated takes. |
|
| 176 |
+
| `--samples` | `<release>/examples/media` | Sample MP4s listed on the first screen. |
|
| 177 |
+
| `--max-clips` | `8` | Maximum number of decoded clips in the in-memory clip cache. |
|
| 178 |
+
| `--max-prep` | `8` | Maximum number of prepared source spans in the geometry cache. |
|
| 179 |
+
| `--ckpt`, `--lora` | Release directories | Teacher and student adapter. The service always loads an adapter. |
|
| 180 |
+
| `--model-dir` | `MiniMaxAI/MiniMax-H3` | VAE location. |
|
| 181 |
+
| `--vggt-repo`, `--vggt` | Environment-based | Geometry code and checkpoint. |
|
| 182 |
+
| `--steps`, `--flow-shift` | `4`, `3` | Keep these at the student sampling settings for this release. |
|
| 183 |
+
|
| 184 |
+
Prepared spans retain tensors on the GPU, and cache limits count **entries**, not bytes. Memory can
|
| 185 |
+
grow as you explore different windows. Lower `--max-prep`, use shorter windows, or restart to release
|
| 186 |
+
old sessions when operating near the memory limit. Reported single-take peaks do not bound a
|
| 187 |
+
long-running service with many cached spans.
|
| 188 |
+
|
| 189 |
+
`service/run.sh` restarts the process only after exit code `3`, used for a poisoned CUDA context.
|
| 190 |
+
Other exits stop the wrapper. Clip, preparation, and job registries are in memory: a restart loses
|
| 191 |
+
the live session even if files remain on disk. Re-upload/select the clip and prepare it again.
|
| 192 |
+
Evicted clips or prepared spans can similarly invalidate older browser tabs.
|
| 193 |
+
|
| 194 |
+
Generated files are not automatically expired. Monitor `<work>/clips`, `<work>/warp`, and
|
| 195 |
+
`<work>/takes`; stop the service before manually removing data still referenced by an active session.
|
| 196 |
+
Keep uploaded footage private and use material you have permission to process.
|
| 197 |
+
|
| 198 |
+
## Troubleshooting the studio
|
| 199 |
+
|
| 200 |
+
| Symptom | Next step |
|
| 201 |
+
|---|---|
|
| 202 |
+
| Render is disabled | Wait for the latest warp, check key order and source direction, then inspect the clearance and camera-change messages. |
|
| 203 |
+
| The take unexpectedly slows down | Compare source and output indices, especially after choosing 175/243 frames or applying a template. |
|
| 204 |
+
| Preparation fails near a cut | Move to a continuous span with at least two source frames, or trim and upload the shot separately. |
|
| 205 |
+
| An old tab starts failing | Its cached clip or span may have been evicted, or the service restarted. Select the clip again. |
|
| 206 |
+
| Previews stop while a take renders | GPU work is serialized; there is no separate preview GPU. |
|
| 207 |
+
| Memory rises over a session | Reduce the prepared-span cache or restart; source-window length and cached tensors matter as well as output length. |
|
| 208 |
+
| Page reports a GPU restart | Watch the terminal for `ready`, then start a new session. Previous job IDs will not be restored. |
|
| 209 |
+
|
| 210 |
+
See [Installation](installation.md#setup-problems) for dependencies and [API](api.md) for programmatic use.
|
docs/studio_walkthrough.md
ADDED
|
@@ -0,0 +1,251 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Meridian Studio — walkthrough film
|
| 2 |
+
|
| 3 |
+
[← Research article](research.md#try-meridian) · [Studio guide](studio.md)
|
| 4 |
+
|
| 5 |
+
**Status: a 38-second preview-only overview is available; a matching generated take is still pending.**
|
| 6 |
+
[Watch the concise Studio overview](../videos-all/studio_walkthrough/nba3_preview_live_02/studio_walkthrough_concise.mp4)
|
| 7 |
+
· [Editing recipe](../videos-all/studio_walkthrough/nba3_preview_live_02/edit_concise_01/edit.json).
|
| 8 |
+
|
| 9 |
+
The concise edit uses restrained English titles and enlarged details of the actual UI:
|
| 10 |
+
**one source → camera position and aim → held source time → geometric reference**.
|
| 11 |
+
It omits repetitive authoring and backend waits, disclosed on screen, without accelerating the
|
| 12 |
+
remaining actions. The complete supplied input and 243-frame geometric reference are retained;
|
| 13 |
+
the UI capture is resampled from 25 to 24 fps. It is silent, with no final generated video implied.
|
| 14 |
+
The original recording remains unchanged:
|
| 15 |
+
|
| 16 |
+
[Watch the revised, uncut recording](../videos-all/studio_walkthrough/nba3_preview_live_02/studio_walkthrough_review.mp4)
|
| 17 |
+
· [10-second geometric reference](../videos-all/studio_walkthrough/nba3_preview_live_02/preview_truth.mp4)
|
| 18 |
+
· [Before / after camera comparison](../videos-all/studio_walkthrough/nba3_preview_live_02/review_camera_comparison.jpg)
|
| 19 |
+
· [Session evidence](../videos-all/studio_walkthrough/nba3_preview_live_02/session.json).
|
| 20 |
+
|
| 21 |
+
NBA3 replaces the flower scene as the current walkthrough candidate: approach → airborne hold with
|
| 22 |
+
camera travel → resumed dunk and landing. The
|
| 23 |
+
[earlier flower pilot](../videos-all/studio_walkthrough/flowers_preview_live_01/studio_walkthrough_review.mp4)
|
| 24 |
+
is retained, not overwritten.
|
| 25 |
+
|
| 26 |
+
**Revision 02 replaces the large orbit/approach with small athlete-framed lateral travel.**
|
| 27 |
+
The athlete and hoop are substantially more legible in the held reference, and the source map
|
| 28 |
+
continues through the dunk and landing. Review included contact sheets covering all 243 reference
|
| 29 |
+
frames and larger comparisons at output frames 60, 134 and 179. The backend's average coverage
|
| 30 |
+
rose from 61.2% to 83.9%; that is a geometric diagnostic, not a generated-quality score.
|
| 31 |
+
|
| 32 |
+
**The reference still has conspicuous disocclusion holes and tearing around the athlete's outline.**
|
| 33 |
+
This is a more useful authoring demonstration, not an approved cinematic result. Native-speed motion
|
| 34 |
+
review and a matching generated take are still needed before publishing the research-page film.
|
| 35 |
+
The [rejected first camera pilot](../videos-all/studio_walkthrough/nba3_preview_live_01/studio_walkthrough_review.mp4)
|
| 36 |
+
is retained for comparison, not silently replaced.
|
| 37 |
+
|
| 38 |
+
The September 13 recordings ran through Chromium against the existing Studio at `127.0.0.1:8412` on GPU 0,
|
| 39 |
+
with permission to execute outside the restricted sandbox. It records actual seven-key authoring and
|
| 40 |
+
geometric previews; **no final generation was submitted**. The running main-repository Studio has
|
| 41 |
+
the same authoring controls as the release, with minor comment/warning-text differences; the served
|
| 42 |
+
HTML is retained. Revision 02 completed 81 POST requests with no recorded API/browser errors and
|
| 43 |
+
no `/render` request. The preview workflow passed its live checks; the script's `--render` branch remains
|
| 44 |
+
untested. This is raw workflow evidence, not yet an approved research-page film.
|
| 45 |
+
|
| 46 |
+
The older files named `browser_studio.png` are screenshots of a separate source/control gallery,
|
| 47 |
+
not this camera-authoring application. Do not substitute them for a Studio demonstration.
|
| 48 |
+
|
| 49 |
+
## Record with Playwright
|
| 50 |
+
|
| 51 |
+
[Recording script](record_studio_walkthrough.py) — run it in a terminal where Chromium can launch
|
| 52 |
+
and `http://127.0.0.1:8412` is reachable. That address means **the machine running the script**;
|
| 53 |
+
use an existing private tunnel or `--url` if the Studio runs elsewhere. Do not expose the unauthenticated
|
| 54 |
+
service publicly. The script connects to an existing service; it does not launch, restart or cancel it.
|
| 55 |
+
|
| 56 |
+
**Arrange a free service/GPU slot first.** Even without `--render`, uploading triggers reconstruction,
|
| 57 |
+
and editing triggers point-cloud, thumbnail and full-path warp work. The script waits between edits;
|
| 58 |
+
it is not a CPU-only recording tool and cannot determine whether other users need that GPU.
|
| 59 |
+
|
| 60 |
+
From the release root, make a preview-only pilot:
|
| 61 |
+
|
| 62 |
+
```bash
|
| 63 |
+
PY=/home/chenyun/miniforge3/envs/wan_new/bin/python
|
| 64 |
+
"$PY" docs/record_studio_walkthrough.py \
|
| 65 |
+
--source videos-all/nba3_teacher30/nba3_full_event.mp4 \
|
| 66 |
+
--camera-style nba-glide \
|
| 67 |
+
--url http://127.0.0.1:8412 \
|
| 68 |
+
--out videos-all/studio_walkthrough/nba3_preview_02
|
| 69 |
+
```
|
| 70 |
+
|
| 71 |
+
This NBA3 plate contains the complete event in **124 frames at 24 fps**, already prepared from the
|
| 72 |
+
supplied clip. The hold uses frame 60, during the airborne ball sweep before the dunk; the action
|
| 73 |
+
then resumes through the landing. For another scene, choose a clean clip with at least 124 normalized frames
|
| 74 |
+
before its first detected cut. It stops if that prepared span is shorter; it does not silently adapt
|
| 75 |
+
the timing sketch. Retain source permission/attribution when substituting footage.
|
| 76 |
+
|
| 77 |
+
The pilot uses actual UI controls to:
|
| 78 |
+
|
| 79 |
+
1. Upload and reconstruct, select 243 output frames, then start from the source-camera path.
|
| 80 |
+
2. Add and retime five intermediate keys using the source-time table below.
|
| 81 |
+
3. Look through keys, make small sideways Shift-drags, and adjust the aim to retain the athlete and hoop.
|
| 82 |
+
4. Return to the overview, scrub the hold, and play the real grey-hole and magenta references.
|
| 83 |
+
|
| 84 |
+
`nba-glide` is **specific to the NBA3 full-event plate**. It reads the reconstructed torso point near
|
| 85 |
+
normalized source-image coordinate `(0.367, 0.435)` at frame 60, then uses genuine pointer gestures
|
| 86 |
+
to place it near `(0.40, 0.435)` during the hold. This preserves space for the ball and hoop rather
|
| 87 |
+
than aiming every key at the scene centre. It does not inject camera state or replace UI responses.
|
| 88 |
+
Read-only projection calculations guide the automated gestures; this is not an automatic subject-tracking feature.
|
| 89 |
+
|
| 90 |
+
Nominal sideways offsets reach 0.024 scene-centre-depth units, with no forward push. Exact positions
|
| 91 |
+
and aims are retained in `path_preview.json`; these depth-normalized units are not metres.
|
| 92 |
+
The older nominal 30° orbit workflow remains available as `--camera-style orbit-pilot` (the script's
|
| 93 |
+
default for compatibility), **not as the recommended NBA3 path**. Neither workflow is a
|
| 94 |
+
reproduction of an approved CLI take, a large-angle benchmark or a guarantee of generated quality.
|
| 95 |
+
Inspect both downloaded reference videos continuously before spending time on final generation.
|
| 96 |
+
Passing the Studio's clearance gate is not a visual-quality verdict.
|
| 97 |
+
|
| 98 |
+
To capture the same scripted workflow **including a new generated take**, use a new directory and
|
| 99 |
+
add `--render`:
|
| 100 |
+
|
| 101 |
+
```bash
|
| 102 |
+
"$PY" docs/record_studio_walkthrough.py \
|
| 103 |
+
--source videos-all/nba3_teacher30/nba3_full_event.mp4 \
|
| 104 |
+
--camera-style nba-glide \
|
| 105 |
+
--out videos-all/studio_walkthrough/nba3_render_01 \
|
| 106 |
+
--render
|
| 107 |
+
```
|
| 108 |
+
|
| 109 |
+
This is a new session, not a resume of the preview. The script retains and checks the accepted job's
|
| 110 |
+
payload against the path displayed in **that recording**. It never bypasses a disabled Render button.
|
| 111 |
+
Add `--headed` to watch in Chromium on a machine with a display; let the automation finish without
|
| 112 |
+
editing the same page. Default headless mode records the same viewport without needing a desktop.
|
| 113 |
+
`--timeout` sets each backend wait in seconds; the default is 1800. A timeout or closed browser
|
| 114 |
+
**does not cancel an already submitted job**. Check its recorded job ID before retrying.
|
| 115 |
+
|
| 116 |
+
If Playwright or Chromium is missing, install them in the recording environment first:
|
| 117 |
+
|
| 118 |
+
```bash
|
| 119 |
+
"$PY" -m pip install playwright
|
| 120 |
+
"$PY" -m playwright install chromium
|
| 121 |
+
```
|
| 122 |
+
|
| 123 |
+
### What gets saved
|
| 124 |
+
|
| 125 |
+
- `studio_walkthrough_raw.webm`: the actual 1920 × 1080 browser viewport, **including real waits**.
|
| 126 |
+
It records neither browser chrome nor audio; do not rely on it to include the OS mouse cursor.
|
| 127 |
+
No fake cursor, replacement UI, simulated responses or accelerated preview are injected.
|
| 128 |
+
- `input.*` and, when present, `input_provenance.json`: a retained upload and its adjacent source record.
|
| 129 |
+
- `prepared.json`, `path_preview.json`, `warp_preview.json`: the normalized span, geometry, exact
|
| 130 |
+
edited keys, source-frame map and preview diagnostics. Preview-only runs do not claim a render payload.
|
| 131 |
+
- `preview_truth.mp4`, `preview_holes.mp4`, numbered screenshots: reference footage and review stills.
|
| 132 |
+
- With `nba-glide`, `subject_anchor.json`: the selected reconstructed torso point and its source projection.
|
| 133 |
+
- `session.json`, `studio_served.html`: source/download hashes, served UI, request payloads and
|
| 134 |
+
client-observed wall-clock milestones. These timestamps are relative to script startup, **not exact
|
| 135 |
+
WebM edit points or an interactive-latency benchmark**.
|
| 136 |
+
- With `--render`: `render_request.json`, `job.json`, and the matching `source.mp4`, `render.mp4`,
|
| 137 |
+
`out.mp4`, `grid.mp4`. `source.mp4` follows the authored source-time map; it is not the untouched input.
|
| 138 |
+
|
| 139 |
+
The API does not expose checkpoint identities or the launch recipe. Retain the service launch command,
|
| 140 |
+
checkpoint/adapter identifiers and server log separately. Also preserve the normalized upload from
|
| 141 |
+
`<service --work>/clips/<clip>/clip.mp4` if an exact input archive is needed; `<clip>` is recorded in
|
| 142 |
+
`prepared.json`. The script does not inspect the server filesystem or guess its configuration.
|
| 143 |
+
|
| 144 |
+
For an MP4 viewing copy, without cutting waits or changing playback speed:
|
| 145 |
+
|
| 146 |
+
```bash
|
| 147 |
+
ffmpeg -n -i videos-all/studio_walkthrough/nba3_render_01/studio_walkthrough_raw.webm \
|
| 148 |
+
-c:v libx264 -crf 18 -pix_fmt yuv420p -movflags +faststart \
|
| 149 |
+
videos-all/studio_walkthrough/nba3_render_01/studio_walkthrough_review.mp4
|
| 150 |
+
```
|
| 151 |
+
|
| 152 |
+
Keep the raw recording. A 45-second research-page film is a **separate editorial pass**, following
|
| 153 |
+
the outline below, with omitted waits disclosed. Use the downloaded full `out.mp4` for the cinematic
|
| 154 |
+
reveal, not a screen-recorded crop of its small comparison pane. Do not publish a Studio-film link
|
| 155 |
+
until the actual recording and generated motion have been reviewed.
|
| 156 |
+
|
| 157 |
+
## The story
|
| 158 |
+
|
| 159 |
+
**Design the observation. See the reference. Generate the shot.**
|
| 160 |
+
|
| 161 |
+
One beautiful source, one deliberate camera path, one uninterrupted generated result. Show that the
|
| 162 |
+
released Studio is an authoring tool—not only a gallery or a menu of orbit presets. The point is the
|
| 163 |
+
relationship between an edit and its visible consequence, rather than a tour of every control.
|
| 164 |
+
|
| 165 |
+
Place the film in the research article's Studio section, after the method and speed discussion.
|
| 166 |
+
Keep the cinematic hero separate: the hero shows the result; this film explains how to author it.
|
| 167 |
+
|
| 168 |
+
## Capture outline · approximately 45 seconds
|
| 169 |
+
|
| 170 |
+
These are editorial allocations, **not measured service timings**. Extend the capture if an operation
|
| 171 |
+
needs longer; do not speed up pointer movement or pretend the model generated instantaneously.
|
| 172 |
+
|
| 173 |
+
| Passage | Actual screen action | Minimal caption |
|
| 174 |
+
|---|---|---|
|
| 175 |
+
| Establish · 0–4 s | Show the chosen source, then the actual Studio with a prepared source span. The source must remain identifiable. | One source. A new observation. |
|
| 176 |
+
| Author · 4–16 s | Show the multi-key path, look through a key, Shift-drag sideways and adjust its aim. Keep the athlete and hoop legible; do not exaggerate the small travel. | Place the camera. Shape its path. |
|
| 177 |
+
| Shape time · 16–23 s | Show two keys sharing a source frame at different output frames. Scrub across the hold and the subsequent advancing segment. | Hold the moment. Keep the camera moving. |
|
| 178 |
+
| Inspect · 23–29 s | Let the genuine full-path warp finish. Play the grey-hole reference; briefly switch to the magenta diagnostic. Keep one actual edit-to-preview response at native speed. | Preview the geometry before generating. |
|
| 179 |
+
| Generate · 29–32 s | Click **Render this take** and show the real progress screen. If waiting is cut, say so and report the retained run's elapsed time. | Generation wait omitted: [measured duration]. |
|
| 180 |
+
| Reveal · 32–42.125 s | Play the matching 243-frame output intact at 24 fps, large and uncluttered. | Generated view. |
|
| 181 |
+
| Close · about 3 s | End on the Studio's source / reference / output comparison or a quiet wordmark. | Meridian Studio · included in the code release. |
|
| 182 |
+
|
| 183 |
+
The final take must be generated from **the exact Studio keys shown**. An existing CLI flower or
|
| 184 |
+
motorcycle output is useful for choosing a scene, but is not evidence of an unexecuted Studio path.
|
| 185 |
+
|
| 186 |
+
## Source and camera design
|
| 187 |
+
|
| 188 |
+
**NBA3 is the current walkthrough source.** Its wide view makes the approach, airborne ball sweep,
|
| 189 |
+
dunk and landing legible as one event. The retained 124-frame plate covers the full supplied clip;
|
| 190 |
+
its frame 60 maps to original frame 73 / PTS 2.435767 s. See the
|
| 191 |
+
[exact input preparation](../videos-all/nba3_teacher30/provenance.json). These are source-file
|
| 192 |
+
timestamps, not a claim about physical capture speed. The footage is user-supplied; public
|
| 193 |
+
redistribution rights and endorsement have not been established.
|
| 194 |
+
|
| 195 |
+
The *Spring* flower scene remains an alternate, with Blender Foundation attribution and CC BY 4.0
|
| 196 |
+
notice in [its input preparation](../videos-all/longtake_edit/plates/flowers_linger243.json).
|
| 197 |
+
|
| 198 |
+
Use a source export appropriate for the Studio's **maximum 124-frame prepared window**. Do not claim
|
| 199 |
+
the Studio reproduced a 243-source-frame CLI reconstruction; selecting a 243-frame *output* does
|
| 200 |
+
not enlarge its prepared source window. Begin with a modest, well-framed path. Only increase travel
|
| 201 |
+
after inspecting the projection—an impressive trajectory that loses the athlete is a worse demo.
|
| 202 |
+
|
| 203 |
+
For a 124-frame prepared span starting at `start`, this **timing sketch** fits a 243-frame output:
|
| 204 |
+
|
| 205 |
+
| Output index `t` | Source index | Camera intention, to tune in the actual scene |
|
| 206 |
+
|---|---|---|
|
| 207 |
+
| 0 | `start + 0` | Establish the source-side composition. |
|
| 208 |
+
| 40 | `start + 40` | Follow the source framing with a small lateral offset. |
|
| 209 |
+
| 60 | `start + 60` | Begin the time hold with breathing room around the subject. |
|
| 210 |
+
| 105 | `start + 60` | Glide sideways while retaining the athlete. |
|
| 211 |
+
| 145 | `start + 60` | Travel sideways, keeping the aim on the subject. |
|
| 212 |
+
| 179 | `start + 60` | Ease back toward the source-side camera before action resumes. |
|
| 213 |
+
| 242 | `start + 123` | Let the action advance again. |
|
| 214 |
+
|
| 215 |
+
This uses all 124 prepared source frames and adds 119 held output frames. It preserves the prepared
|
| 216 |
+
input's pace outside the hold; any slow motion already in that input remains baked in. The exact
|
| 217 |
+
camera keys are saved with each recording. This table specifies intent, not a promise of seamless
|
| 218 |
+
generated motion.
|
| 219 |
+
|
| 220 |
+
## What “real-time preview” may honestly mean
|
| 221 |
+
|
| 222 |
+
- **Browser 3D view:** a loaded point cloud and camera handles redraw during interaction. Capture
|
| 223 |
+
this normally; do not attach an FPS or latency claim without measuring it.
|
| 224 |
+
- **Full-path geometric reference:** generated by the backend after a committed valid edit. This
|
| 225 |
+
requires GPU work and video encoding; it can wait behind other service work.
|
| 226 |
+
- **Final generated video:** a separate render job. Never label its replay as a live model response.
|
| 227 |
+
|
| 228 |
+
The point-cloud overview is not the full conditioning tensor. The grey-hole video is a compressed
|
| 229 |
+
preview of that reference; the magenta view is diagnostic and is not given to the model.
|
| 230 |
+
|
| 231 |
+
## Capture and acceptance checklist
|
| 232 |
+
|
| 233 |
+
- Record the actual released `service/index.html`, not a UI mock or the `videos-all` gallery.
|
| 234 |
+
- Arrange a dedicated service/GPU recording slot separately. Do not interrupt existing jobs to make
|
| 235 |
+
this recording. No service was started or render queued as part of this documentation update.
|
| 236 |
+
- Capture at native 1920 × 1080 or another readable desktop size. Keep pointer motion deliberate;
|
| 237 |
+
show the key table when explaining source time. Avoid cinematic overlays on the actual output.
|
| 238 |
+
- Retain the source export, normalized frame window, exact `/render` path payload, seed, model
|
| 239 |
+
recipe, output files and status timings alongside the raw capture. The UI has no path-export
|
| 240 |
+
button, so retain the request through browser network tools or the client used for the session.
|
| 241 |
+
- Disclose omitted reconstruction/generation waits. Keep one representative edit-to-warp update
|
| 242 |
+
unaccelerated, including its real waiting time. Cold reconstruction is not interactive preview.
|
| 243 |
+
- Check subject visibility, transitions into/out of the hold, thin geometry and newly exposed
|
| 244 |
+
backgrounds continuously. Sampled frames and successful playback alone are insufficient.
|
| 245 |
+
- Confirm the generated take matches the recorded path and source map. Record any crops or omitted
|
| 246 |
+
output frames; the first choice is to keep the complete generated take intact.
|
| 247 |
+
- Add source credits and transformation notices. Do not imply that a view inferred from a film is
|
| 248 |
+
documentary footage, or that a nominal orbit angle was measured in the generated output.
|
| 249 |
+
|
| 250 |
+
Once recorded and reviewed, add a real poster and MP4 link to the research article. Until then,
|
| 251 |
+
link this plan explicitly as a plan; no broken “Watch Studio” button or fabricated placeholder video.
|
docs/training.md
ADDED
|
@@ -0,0 +1,46 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Training and distillation
|
| 2 |
+
|
| 3 |
+
[← Meridian](../README.md) · [Inference method](method.md)
|
| 4 |
+
|
| 5 |
+
Training provenance and design are collected here rather than in the model card or research blog.
|
| 6 |
+
|
| 7 |
+
## Training overview
|
| 8 |
+
|
| 9 |
+
The following is the release's training description; this repository contains inference code and
|
| 10 |
+
artifacts, **not the training or distillation pipeline**.
|
| 11 |
+
|
| 12 |
+
The teacher was trained on
|
| 13 |
+
[MultiCamVideo](https://huggingface.co/datasets/KwaiVGI/MultiCamVideo-Dataset): 13,600 Unreal Engine
|
| 14 |
+
scenes, each filmed by ten synchronized cameras over 81 frames. A sample pairs one camera's clip
|
| 15 |
+
with a point-cloud render from a second camera; the second camera's actual clip is the target.
|
| 16 |
+
Both directions of camera pairs are used, and geometry is reconstructed from the source clip alone.
|
| 17 |
+
|
| 18 |
+
Later stages added still-frame references, temporally extended examples made by slowing, reversing,
|
| 19 |
+
or holding the 81-frame window, and eased sweeps. The student was distilled at 73, 90, and 124 frames,
|
| 20 |
+
with 243-frame holds also reported. Training-time temporal augmentation is not a promise that every
|
| 21 |
+
time mapping or reverse-playback path is supported by the released interfaces.
|
| 22 |
+
|
| 23 |
+
## Distillation and checkpoint design
|
| 24 |
+
|
| 25 |
+
The release has two learned components:
|
| 26 |
+
|
| 27 |
+
| Component | Role |
|
| 28 |
+
|---|---|
|
| 29 |
+
| `transformer/` | Fully finetuned MiniMax-H3 teacher: stock `fl2va` architecture, 50 layers, hidden size 5376; reported weight size 61.7 GiB in bf16. |
|
| 30 |
+
| `lora/` | Rank-128 DMD student adapter on **that finetuned teacher**, reported size 2.5 GiB. It is not an adapter for the unmodified base transformer. |
|
| 31 |
+
|
| 32 |
+
| Mode | CLI settings | Transformer evaluations |
|
| 33 |
+
|---|---|---|
|
| 34 |
+
| Student, default | `--steps 4 --flow-shift 3` with the LoRA loaded | 3 |
|
| 35 |
+
| Teacher | `--no-lora --steps 50 --flow-shift 12` | 49 |
|
| 36 |
+
|
| 37 |
+
The H3 scheduler counts the terminal zero-noise point in `--steps`. That endpoint does not require a
|
| 38 |
+
model evaluation, hence four grid points produce three forwards. Reducing the teacher's step count
|
| 39 |
+
is not equivalent to using the distilled student. Forward counts also do not directly translate to
|
| 40 |
+
end-to-end speedups: reconstruction, warping, VAE work, and file writing still take time.
|
| 41 |
+
|
| 42 |
+
The source and point-cloud-rendered references share the selected source timeline. Synchronized
|
| 43 |
+
multi-camera supervision is followed by temporal and camera-path augmentation and student distillation.
|
| 44 |
+
The training footage is synthetic; real-world performance depends on the scene.
|
| 45 |
+
|
| 46 |
+
For weight provenance and modification notices, see [`MODIFICATIONS.md`](../MODIFICATIONS.md).
|
examples/CREDITS.md
ADDED
|
@@ -0,0 +1,13 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Sample clips
|
| 2 |
+
|
| 3 |
+
Both clips in `media/` are from Wikimedia Commons and were released by their uploaders under
|
| 4 |
+
[CC0 1.0](https://creativecommons.org/publicdomain/zero/1.0/) (public domain dedication). We modified
|
| 5 |
+
them: cut to a 73-frame window, scaled to 1280 × 720, re-encoded as H.264, soundtrack removed.
|
| 6 |
+
|
| 7 |
+
| file | source | uploader | window |
|
| 8 |
+
|---|---|---|---|
|
| 9 |
+
| `sp_bouldering_hang.mp4` | [2020-11-28 - IFSC Euros - Combined M-B - Alex Khazanov - Video 3.webm](https://commons.wikimedia.org/wiki/File:2020-11-28_-_IFSC_Euros_-_Combined_M-B_-_Alex_Khazanov_-_Video_3.webm) | Voltmetro | from 9.5 s |
|
| 10 |
+
| `sp_bouldering_reach.mp4` | [Anna Stohr JMM 2013 Annecy Bloc.webm](https://commons.wikimedia.org/wiki/File:Anna_Stohr_JMM_2013_Annecy_Bloc.webm) | Shev123 | from 13.75 s |
|
| 11 |
+
|
| 12 |
+
Both show identifiable athletes at public competitions. The CC0 dedication covers the uploader's
|
| 13 |
+
copyright, not the athletes' personality rights; the clips are here as technical demo inputs only.
|
examples/media/sp_bouldering_hang.mp4
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:6e79aa0bf6f57695c05c5d46dd057b35fb18b1a50f266de0426d087733710fe7
|
| 3 |
+
size 2426274
|