
Model card, examples and sampling recipes
Browse files- .gitattributes +2 -0
- README.md +133 -0
- media/examples.jpg +3 -0
- media/recipes.jpg +3 -0
.gitattributes
CHANGED
|
@@ -34,3 +34,5 @@ saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
processor/tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
processor/tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
| 37 |
+
media/examples.jpg filter=lfs diff=lfs merge=lfs -text
|
| 38 |
+
media/recipes.jpg filter=lfs diff=lfs merge=lfs -text
|
README.md
ADDED
|
@@ -0,0 +1,133 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
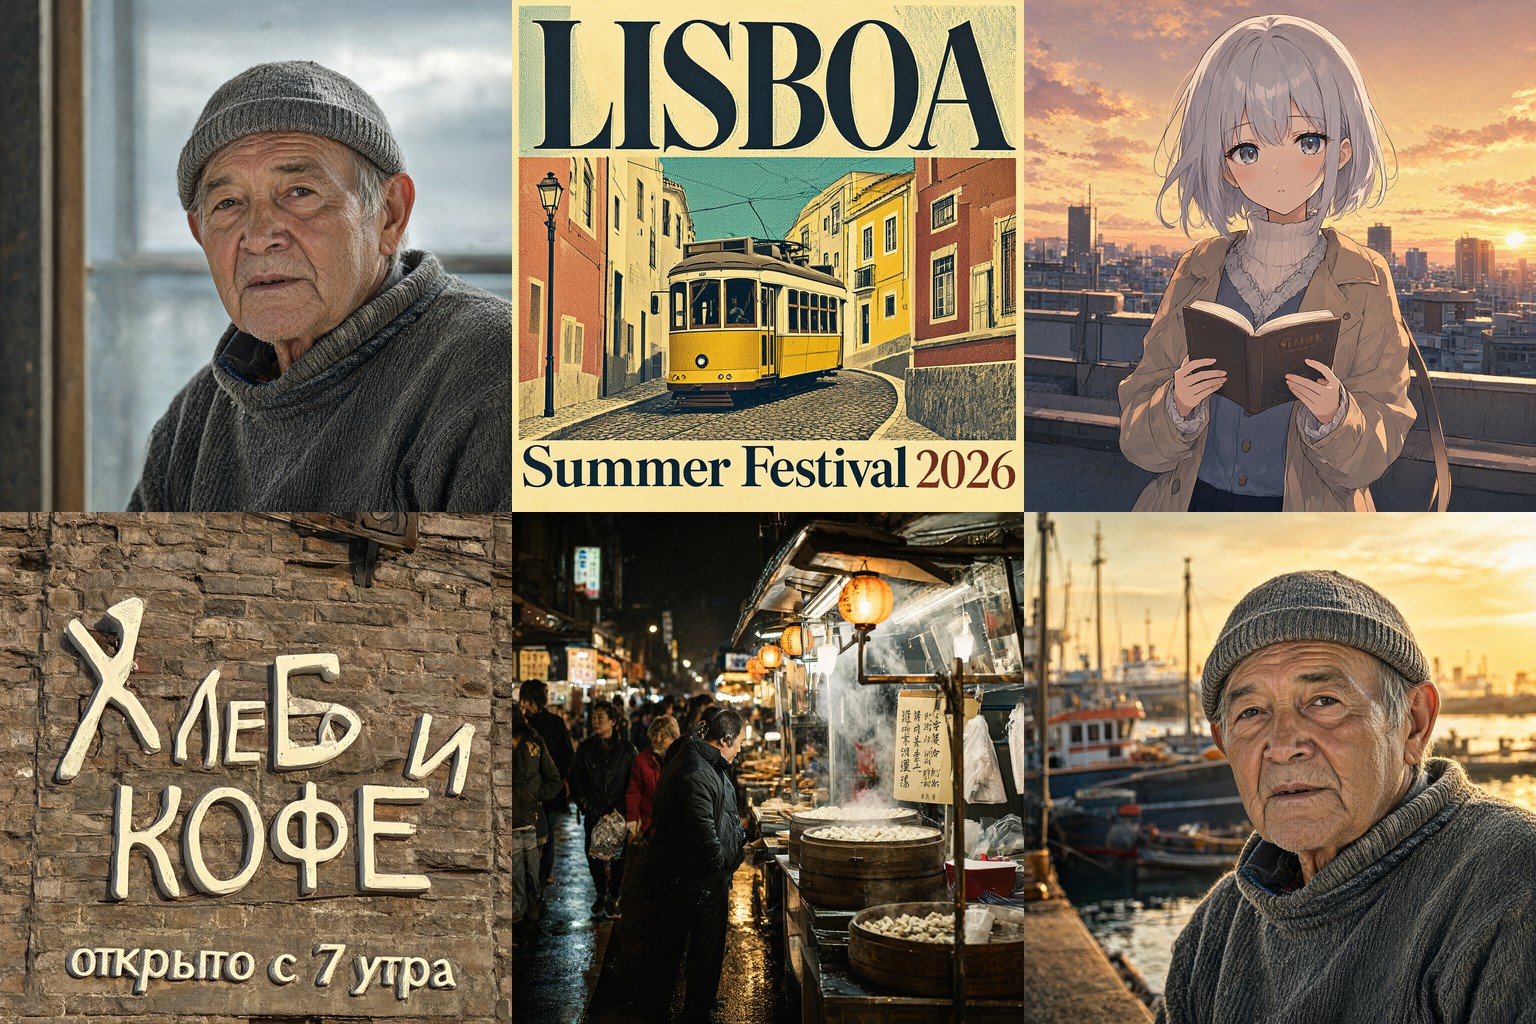
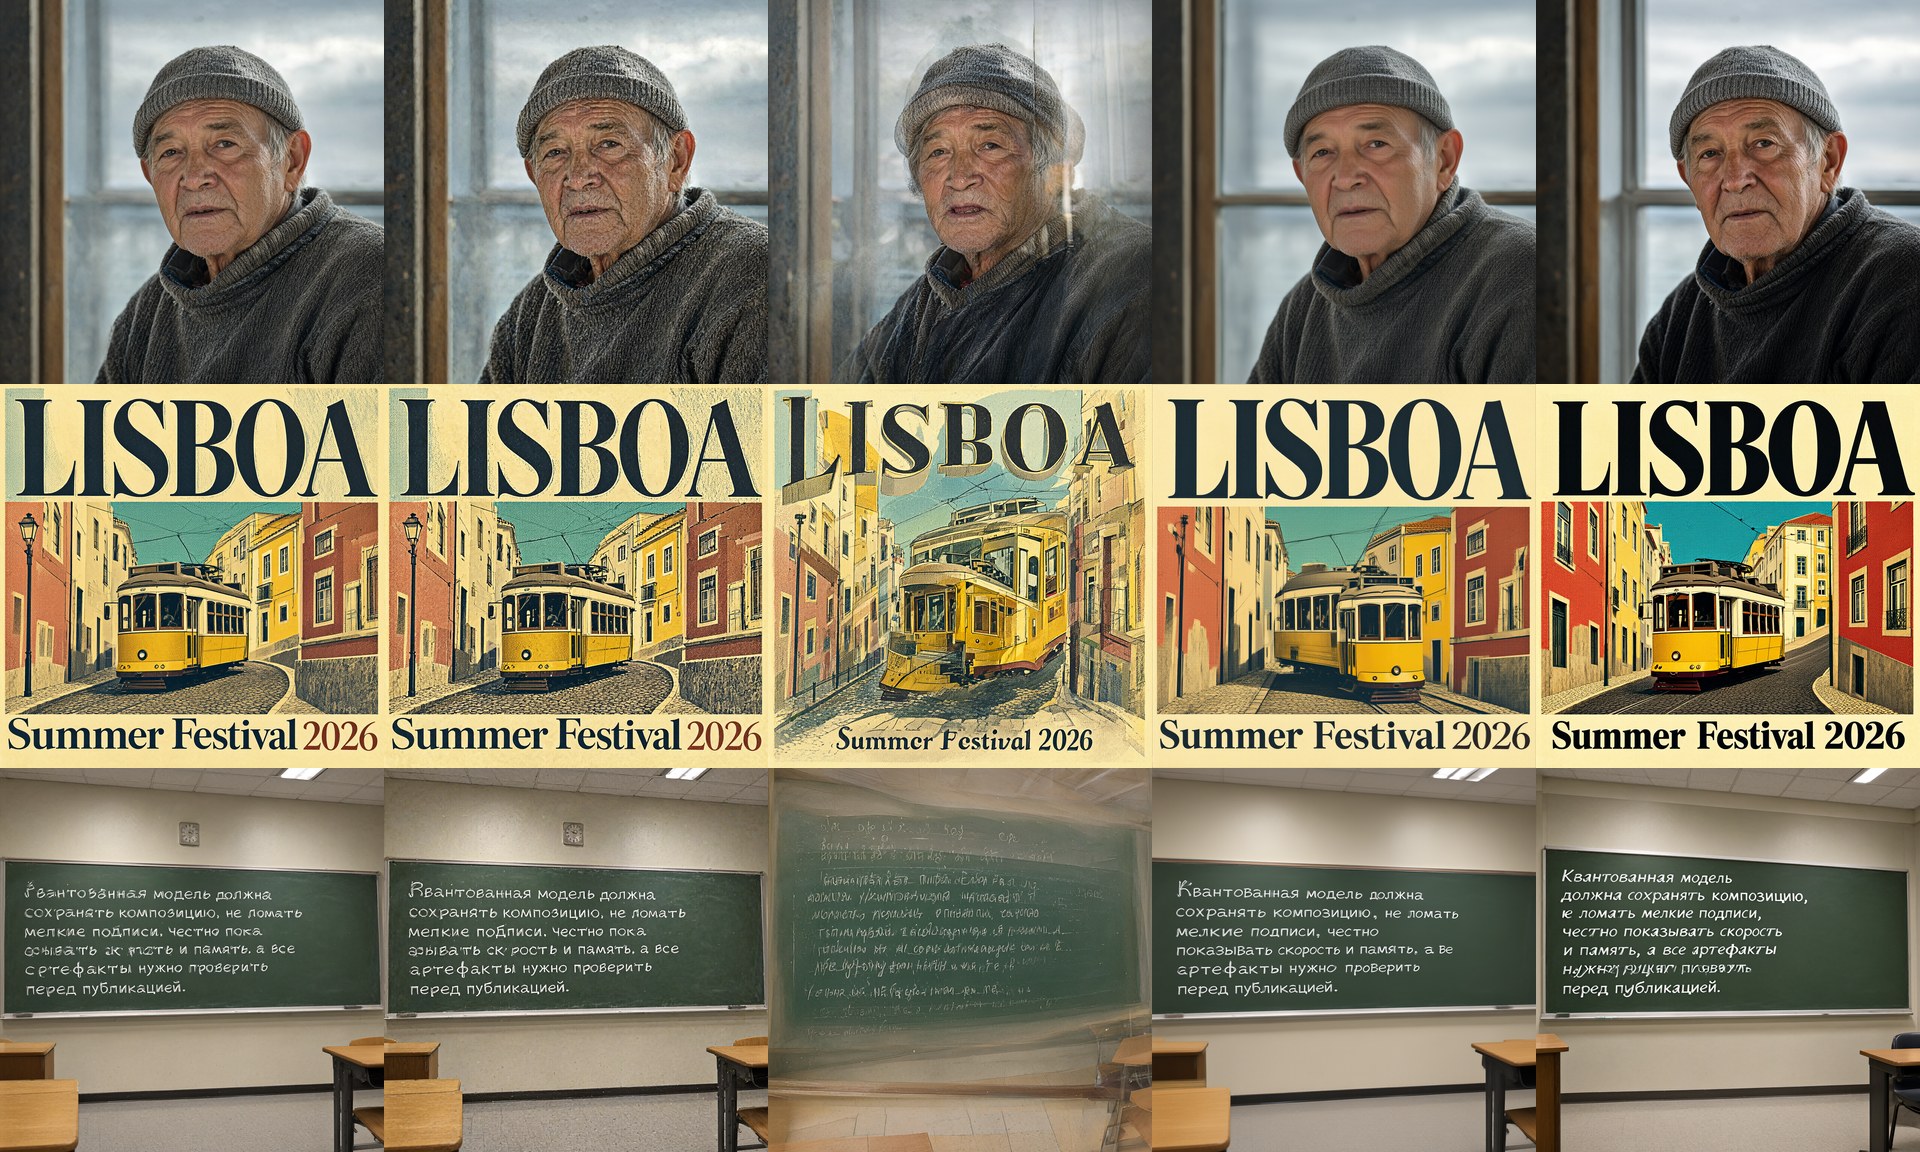
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
language:
|
| 3 |
+
- en
|
| 4 |
+
- zh
|
| 5 |
+
- ru
|
| 6 |
+
license: other
|
| 7 |
+
license_name: qwen-research
|
| 8 |
+
license_link: LICENSE
|
| 9 |
+
base_model:
|
| 10 |
+
- Qwen/Qwen-Image-2.1
|
| 11 |
+
- Viggle/Qwen-Image-2.1-viggle-turbo
|
| 12 |
+
- madebyollin/texture-fix-vae-for-qwen-image-2.1
|
| 13 |
+
base_model_relation: merge
|
| 14 |
+
library_name: diffusers
|
| 15 |
+
pipeline_tag: text-to-image
|
| 16 |
+
tags:
|
| 17 |
+
- diffusers
|
| 18 |
+
- text-to-image
|
| 19 |
+
- image-editing
|
| 20 |
+
- qwen-image
|
| 21 |
+
- turbo
|
| 22 |
+
- few-step
|
| 23 |
+
- distillation
|
| 24 |
+
---
|
| 25 |
+
|
| 26 |
+
# Image21 Turbo
|
| 27 |
+
|
| 28 |
+
[Qwen-Image-2.1](https://huggingface.co/Qwen/Qwen-Image-2.1) with the
|
| 29 |
+
[Viggle turbo v0.2.1](https://huggingface.co/Viggle/Qwen-Image-2.1-viggle-turbo) distillation LoRA merged into the
|
| 30 |
+
transformer and the [Texture-Fix VAE](https://huggingface.co/madebyollin/texture-fix-vae-for-qwen-image-2.1) in place
|
| 31 |
+
of the stock decoder. Text-to-image and editing with reference images in **6 steps without guidance**, loaded by the
|
| 32 |
+
stock `QwenImage21Pipeline`. Built with Qwen.
|
| 33 |
+
|
| 34 |
+
A 4-bit build with a quantized text encoder is published as
|
| 35 |
+
[WaveCut/Image21-Turbo-OrbitQuant-W4A4](https://huggingface.co/WaveCut/Image21-Turbo-OrbitQuant-W4A4).
|
| 36 |
+
|
| 37 |
+

|
| 38 |
+
|
| 39 |
+
| Component | Contents | Size |
|
| 40 |
+
| --- | --- | ---: |
|
| 41 |
+
| `transformer/` | Qwen-Image-2.1 DiT, Viggle turbo v0.2.1 (rank 256) merged in fp32 and stored in fp16 | 14.2 GB |
|
| 42 |
+
| `text_encoder/` | Qwen3-VL-8B, unchanged | 17.5 GB |
|
| 43 |
+
| `vae/` | Texture-Fix VAE, fp32 | 1.35 GB |
|
| 44 |
+
| `scheduler/` | Viggle turbo config: dynamic shift, `shift_terminal` null | |
|
| 45 |
+
|
| 46 |
+
## Run
|
| 47 |
+
|
| 48 |
+
```bash
|
| 49 |
+
pip install -U torch "transformers>=5.17,<6" accelerate safetensors pillow
|
| 50 |
+
pip install "git+https://github.com/huggingface/diffusers.git@80c7ed262aeffbeb43ef13ae04baeb9b84515a69"
|
| 51 |
+
```
|
| 52 |
+
|
| 53 |
+
```python
|
| 54 |
+
import torch
|
| 55 |
+
from diffusers import QwenImage21Pipeline
|
| 56 |
+
|
| 57 |
+
pipe = QwenImage21Pipeline.from_pretrained("WaveCut/Image21-Turbo", torch_dtype=torch.float16)
|
| 58 |
+
pipe.enable_model_cpu_offload()
|
| 59 |
+
|
| 60 |
+
SIGMAS = [1.0, 0.9375, 0.875, 0.75, 0.5, 0.25]
|
| 61 |
+
image = pipe(
|
| 62 |
+
prompt="A studio portrait of an old fisherman mending a net, warm rim light, 85mm",
|
| 63 |
+
width=1024, height=1024,
|
| 64 |
+
num_inference_steps=6, sigmas=SIGMAS,
|
| 65 |
+
generator=torch.Generator("cuda").manual_seed(0),
|
| 66 |
+
).images[0]
|
| 67 |
+
|
| 68 |
+
edited = pipe(
|
| 69 |
+
prompt="Replace the background of <image1> with a sunset beach; keep the man unchanged.",
|
| 70 |
+
image=[image], output_resolution=1024,
|
| 71 |
+
num_inference_steps=6, sigmas=SIGMAS,
|
| 72 |
+
generator=torch.Generator("cuda").manual_seed(0),
|
| 73 |
+
).images[0]
|
| 74 |
+
```
|
| 75 |
+
|
| 76 |
+
Load the pipeline in **fp16**. The merge keeps 99.7 % of the LoRA update in fp16; loading the same weights in bf16
|
| 77 |
+
rounds away about a third of it (64 % kept). The text encoder and the VAE work in fp16 as well: text embeddings match
|
| 78 |
+
bf16 at cosine 0.998–0.9997, VAE decodes match fp32 at 58–64 dB PSNR.
|
| 79 |
+
|
| 80 |
+
All weights together are 33 GB, so a 32 GB card needs `enable_model_cpu_offload()` (≈22 s per 1024² image on an
|
| 81 |
+
RTX 5090, most of it host transfers). Encoding a batch of prompts first and then running the transformer and the VAE
|
| 82 |
+
takes 2.69 s per 1024² image hot (6 steps, peak 22.5 GB) and 17.9 s at 2048². The
|
| 83 |
+
[OrbitQuant build](https://huggingface.co/WaveCut/Image21-Turbo-OrbitQuant-W4A4) keeps every component resident in
|
| 84 |
+
13.6 GB and needs 2.25 s.
|
| 85 |
+
|
| 86 |
+
Keep the VAE untiled in fp16. Tiled decoding in fp16 produces non-finite pixels; for 2048² text-to-image cast it
|
| 87 |
+
first: `pipe.vae.to(torch.bfloat16); pipe.vae.enable_tiling()` (54 dB PSNR against fp32).
|
| 88 |
+
|
| 89 |
+
## Sampling recipes
|
| 90 |
+
|
| 91 |
+
Tested at 1024² on 8 prompts (photo, poster, anime, product, night scene, two Russian-text prompts) with fixed
|
| 92 |
+
seeds, plus 4 edits. Times are transformer + VAE on an RTX 5090.
|
| 93 |
+
|
| 94 |
+

|
| 95 |
+
|
| 96 |
+
*Columns: default, 8 steps, 4 steps, static shift 3, CFG 2.*
|
| 97 |
+
|
| 98 |
+
| Recipe | Settings | Result | Time |
|
| 99 |
+
| --- | --- | --- | ---: |
|
| 100 |
+
| **Default** | 6 steps, `sigmas=[1, 0.9375, 0.875, 0.75, 0.5, 0.25]`, shipped scheduler, no CFG | Sharpest detail and textures; Latin and Cyrillic text mostly right | 2.9 s |
|
| 101 |
+
| **Text, posters, natural skin** | the same 6 sigmas with a static shift of 3: `pipe.scheduler = FlowMatchEulerDiscreteScheduler.from_config(pipe.scheduler.config, use_dynamic_shifting=False, shift=3.0)` | Cleanest lettering in the set (long Russian paragraph almost error-free), smoother skin, calmer micro-texture | 2.9 s |
|
| 102 |
+
| Dense text | 8 steps, `sigmas=[1, 0.9375, 0.875, 0.75, 0.625, 0.5, 0.25, 0.125]` | Same composition as the default, small print slightly cleaner | 3.8 s |
|
| 103 |
+
| Guidance | 6 steps, `true_cfg_scale=2` with a negative prompt | Higher contrast and saturation, bolder type | 5.8 s |
|
| 104 |
+
| Avoid | 4 steps `[1, 0.75, 0.5, 0.25]` | Ghosted double contours, garbled text | 2.0 s |
|
| 105 |
+
| Avoid | static shift 5 | Soft, smeared detail | |
|
| 106 |
+
|
| 107 |
+
Editing: reference images are `<image1>`, `<image2>`, … in the prompt, in the order passed; the canvas follows the last
|
| 108 |
+
reference unless `width`/`height` are given; references are encoded at `output_resolution`² area.
|
| 109 |
+
|
| 110 |
+
## Merge
|
| 111 |
+
|
| 112 |
+
| | Value |
|
| 113 |
+
| --- | --- |
|
| 114 |
+
| LoRA | Viggle turbo v0.2.1, rank 256, alpha 256, 227 projections (attention, image MLP, modulation, timestep embedder) |
|
| 115 |
+
| Factors | F32 from `peft_v0.2.1/` |
|
| 116 |
+
| Update size | median 0.11 % of the weight norm, max 1.6 % |
|
| 117 |
+
| Kept after rounding | fp16 99.7 % (rounding noise 18.7 % of the update); bf16 would keep 64 % |
|
| 118 |
+
| Output vs runtime LoRA | 0.4–2.8 % latent difference at the same precision and seed |
|
| 119 |
+
|
| 120 |
+
Everything outside the 227 projections is the upstream bf16 value stored in fp16.
|
| 121 |
+
|
| 122 |
+
## Files
|
| 123 |
+
|
| 124 |
+
`transformer/`, `text_encoder/`, `processor/`, `vae/`, `scheduler/`, `model_index.json` — the diffusers pipeline;
|
| 125 |
+
`media/` — example images; `LICENSE`, `NOTICE` — license and attribution.
|
| 126 |
+
|
| 127 |
+
## License
|
| 128 |
+
|
| 129 |
+
Derivative of Qwen-Image-2.1 under the Qwen RESEARCH LICENSE AGREEMENT (`LICENSE`): non-commercial research and
|
| 130 |
+
evaluation only. `NOTICE` lists the modified files and the upstream notices of Viggle and madebyollin.
|
| 131 |
+
|
| 132 |
+
> Qwen is licensed under the Qwen RESEARCH LICENSE AGREEMENT, Copyright (c) 2026 Hangzhou Tongyi Laboratory Technology
|
| 133 |
+
> Co., Ltd. All Rights Reserved.
|
media/examples.jpg
ADDED
|
Git LFS Details
|
media/recipes.jpg
ADDED
|
Git LFS Details
|