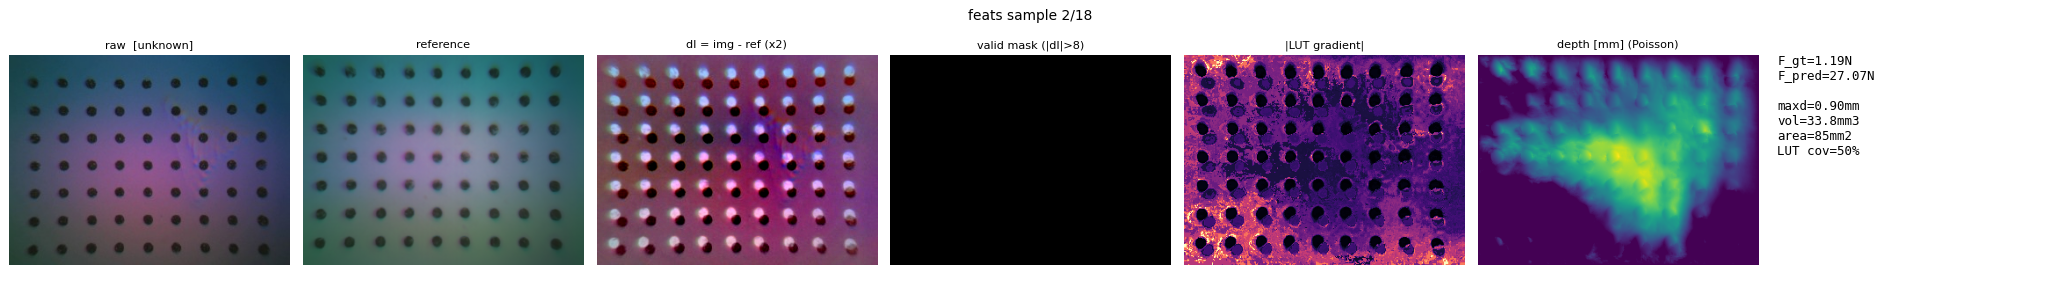
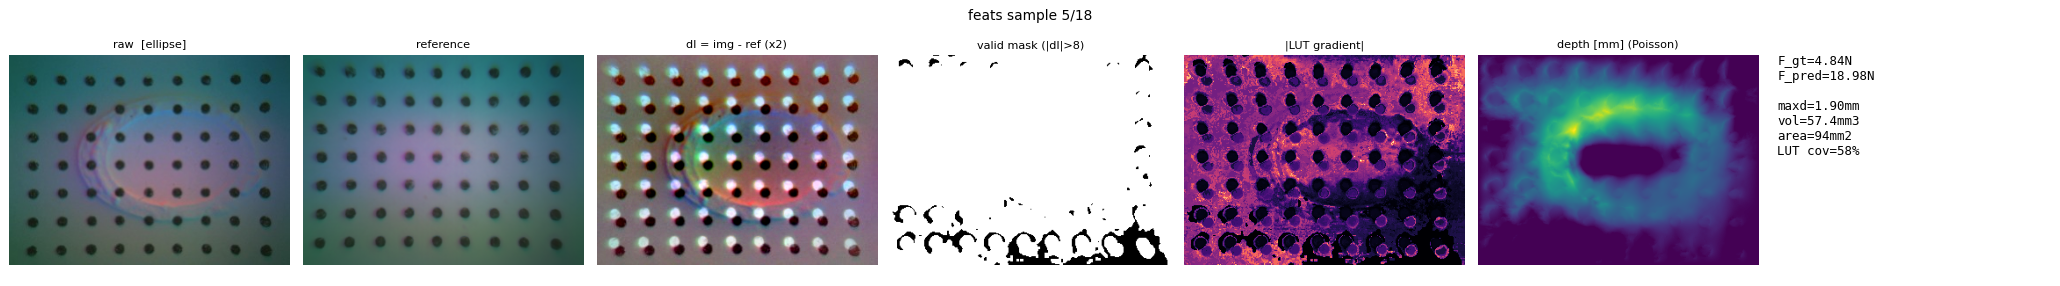
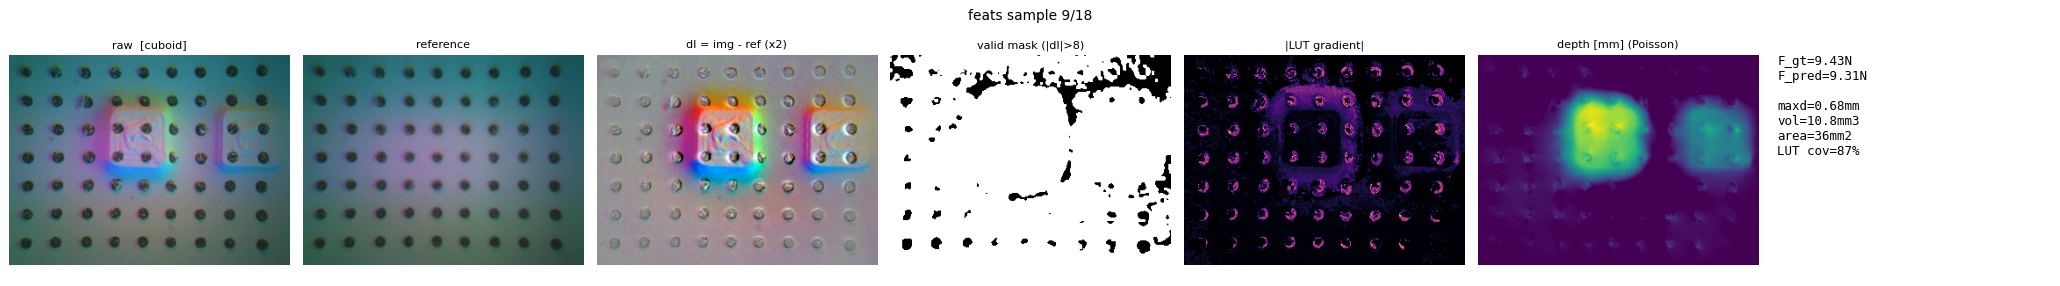
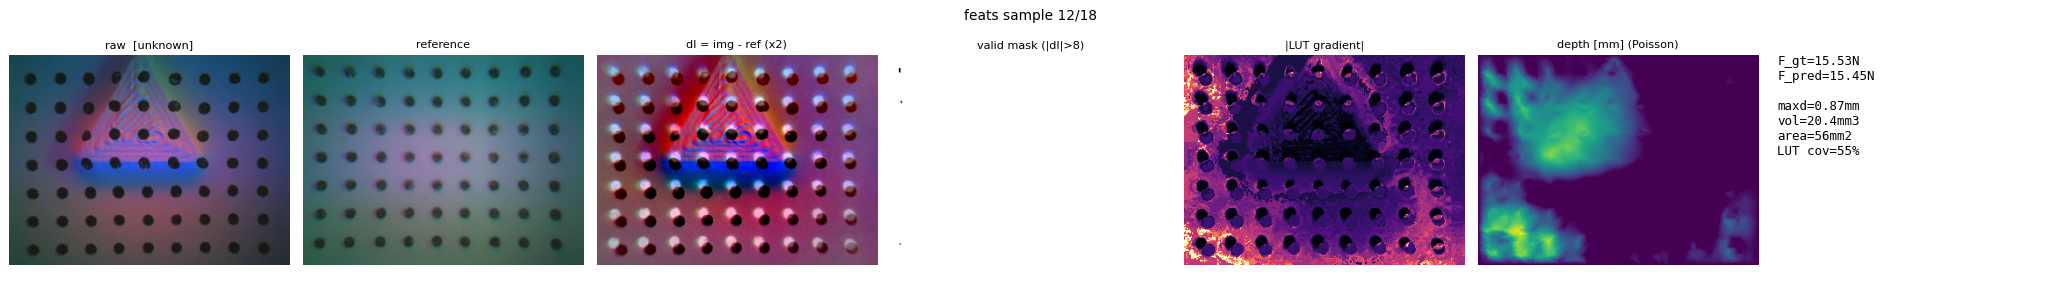
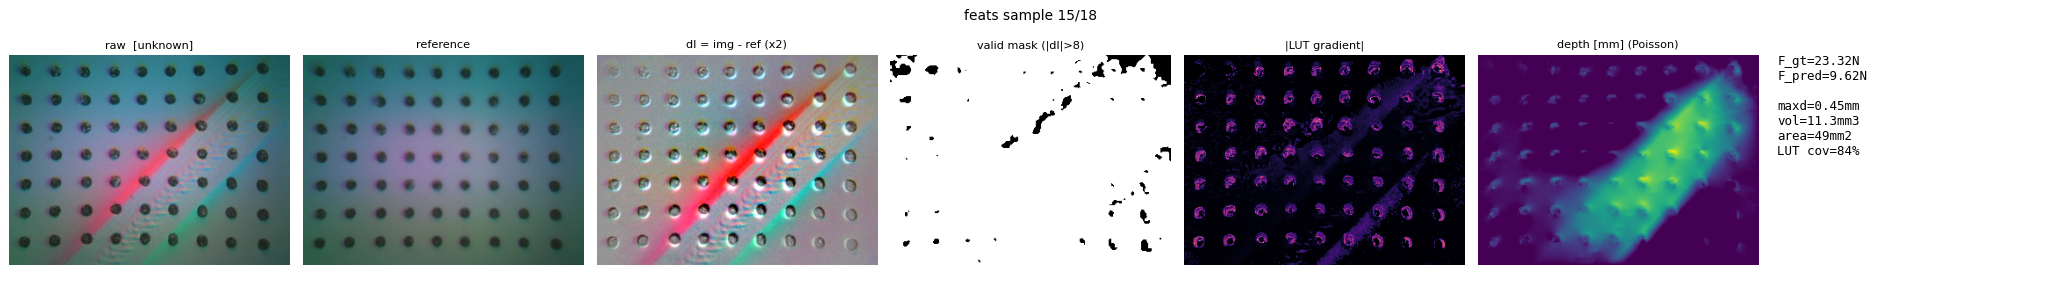
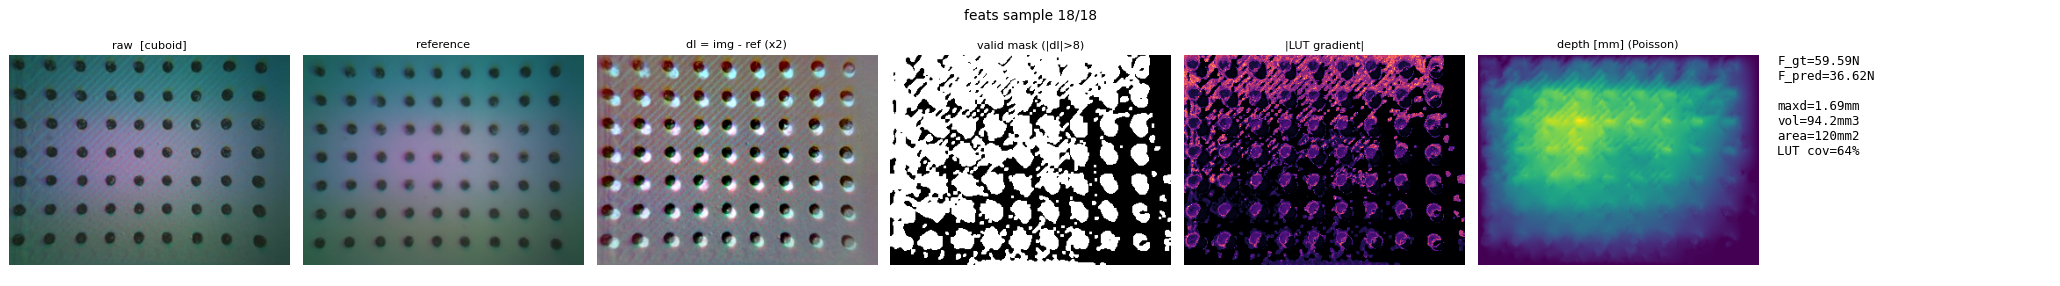
From raw image to force, step by step
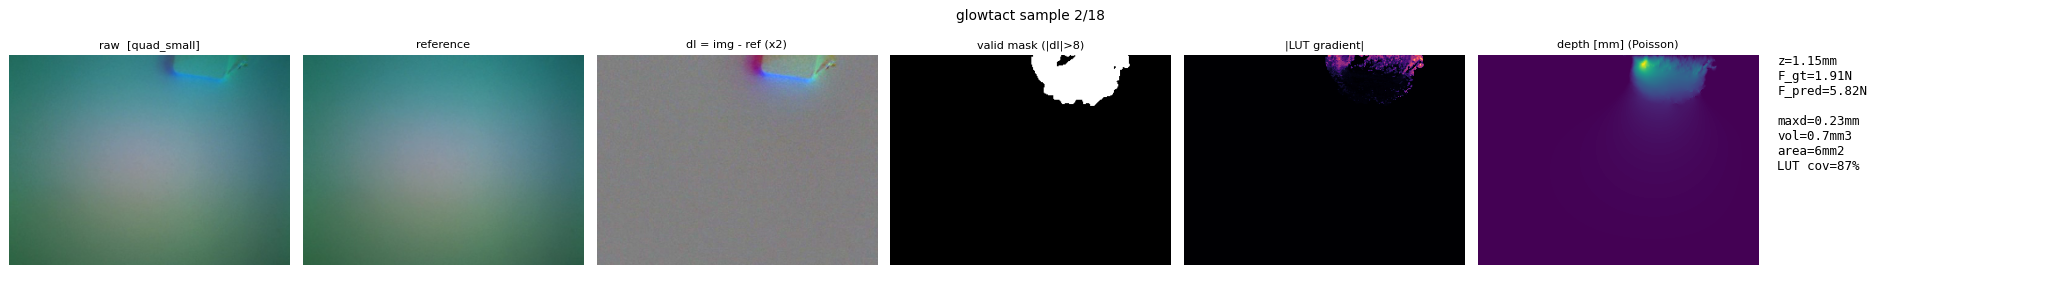
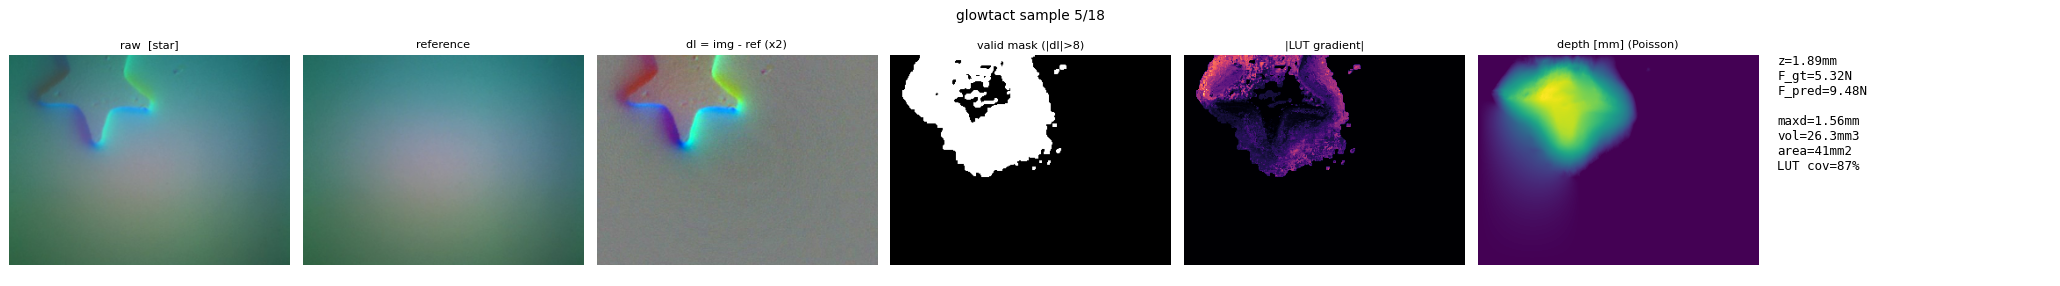
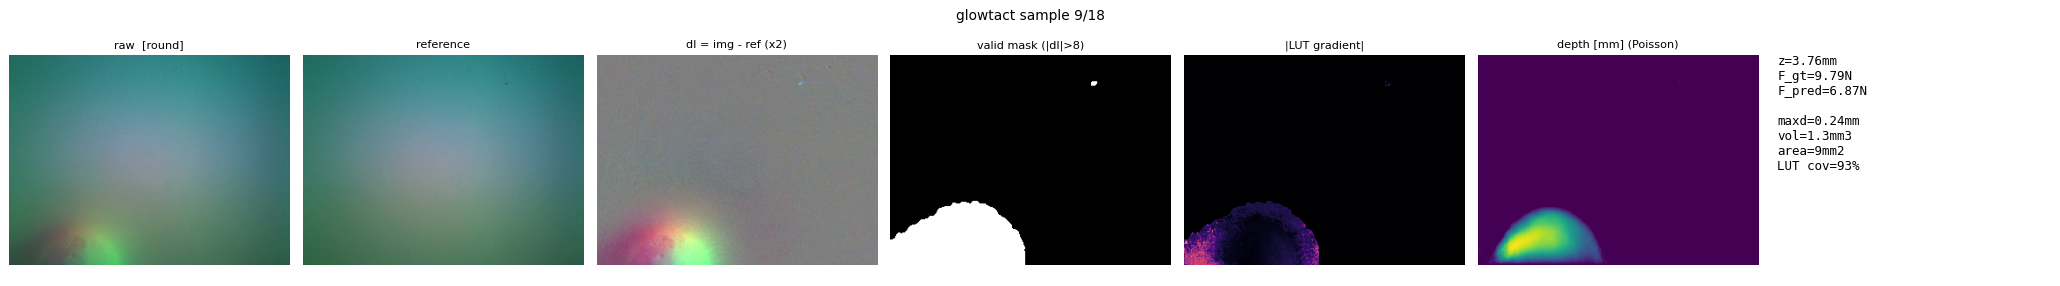
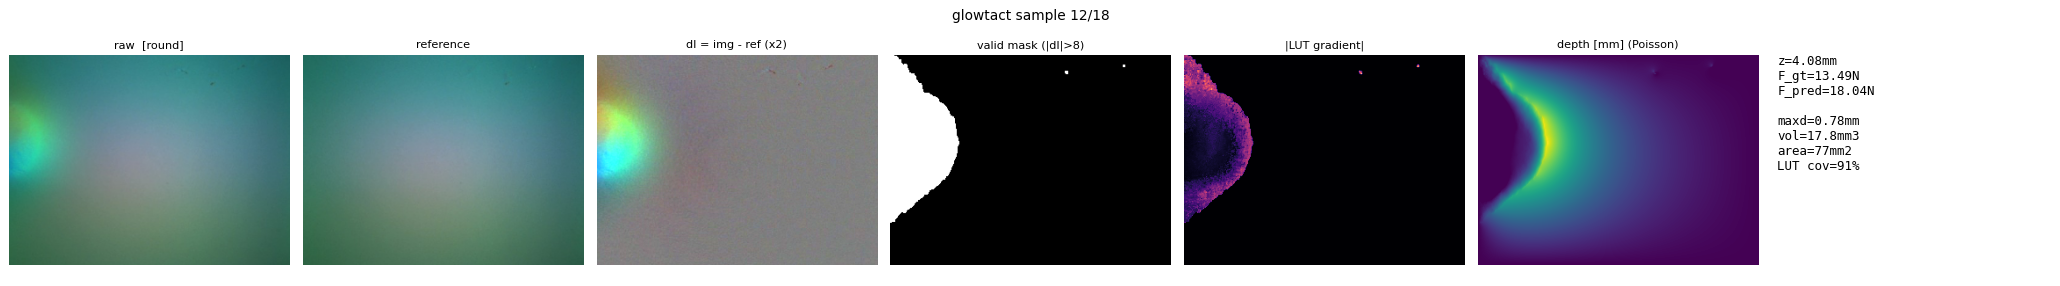
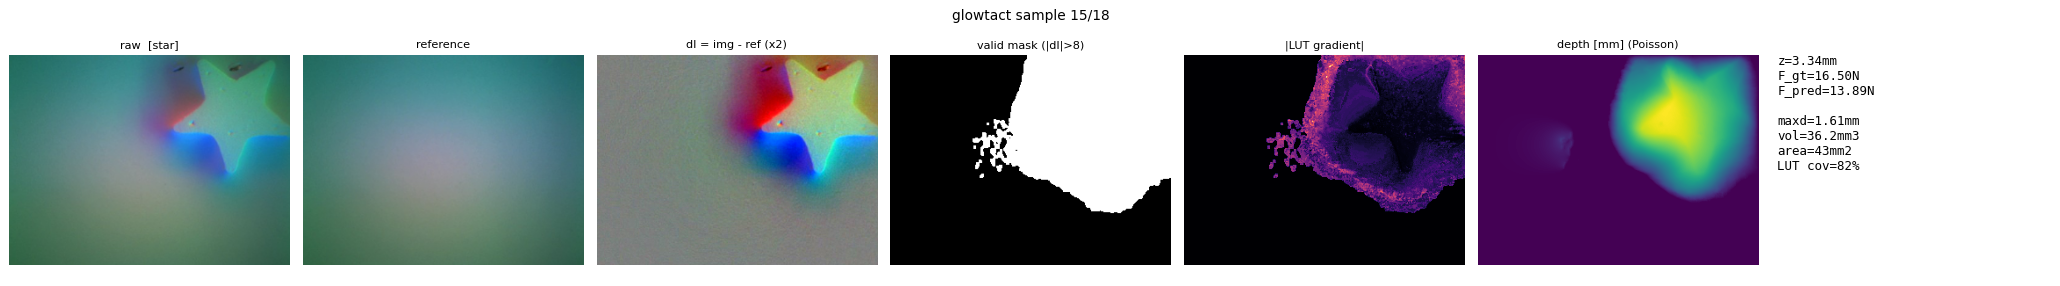
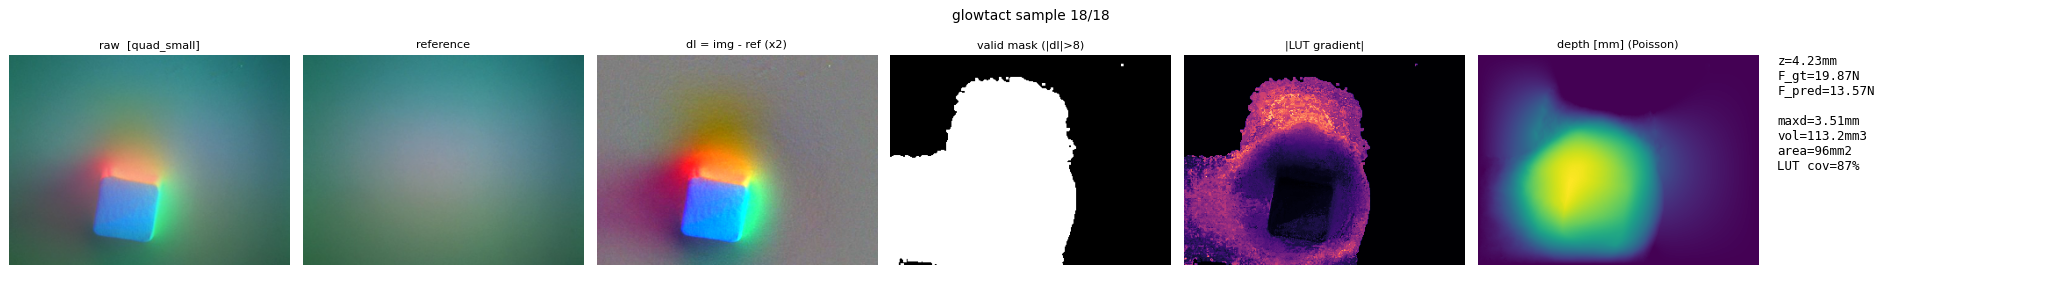
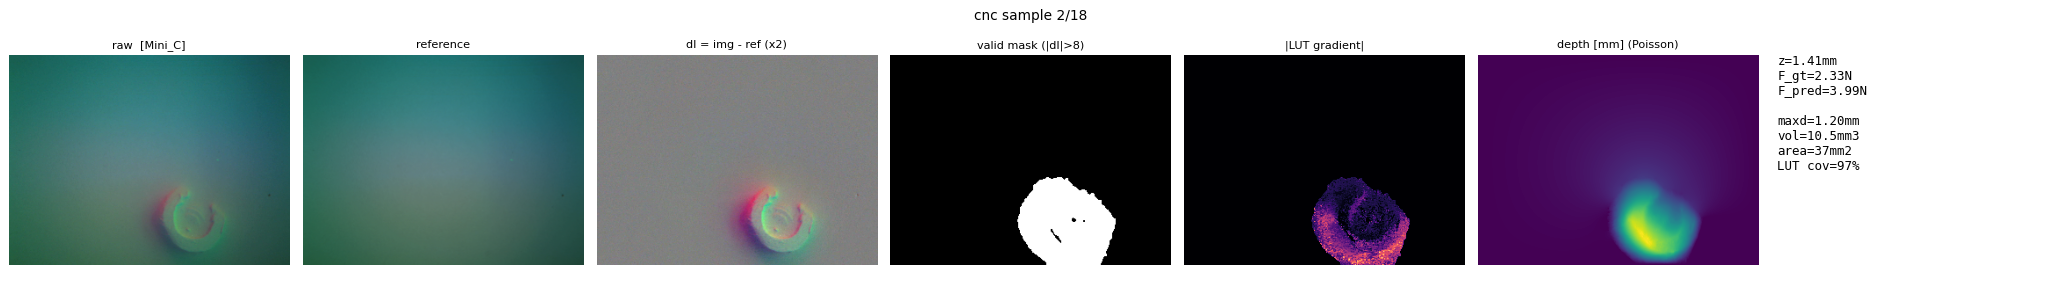
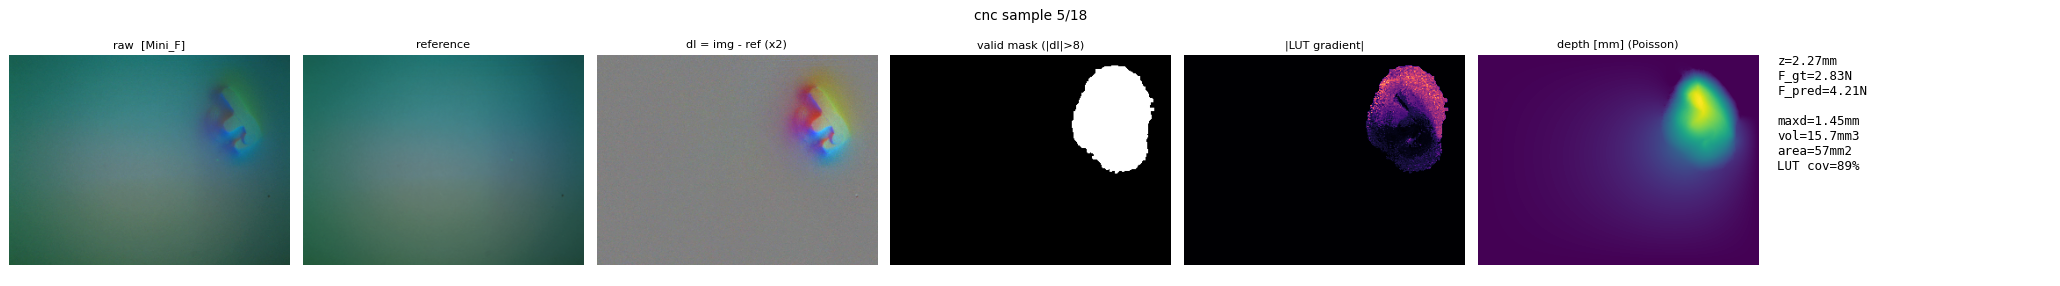
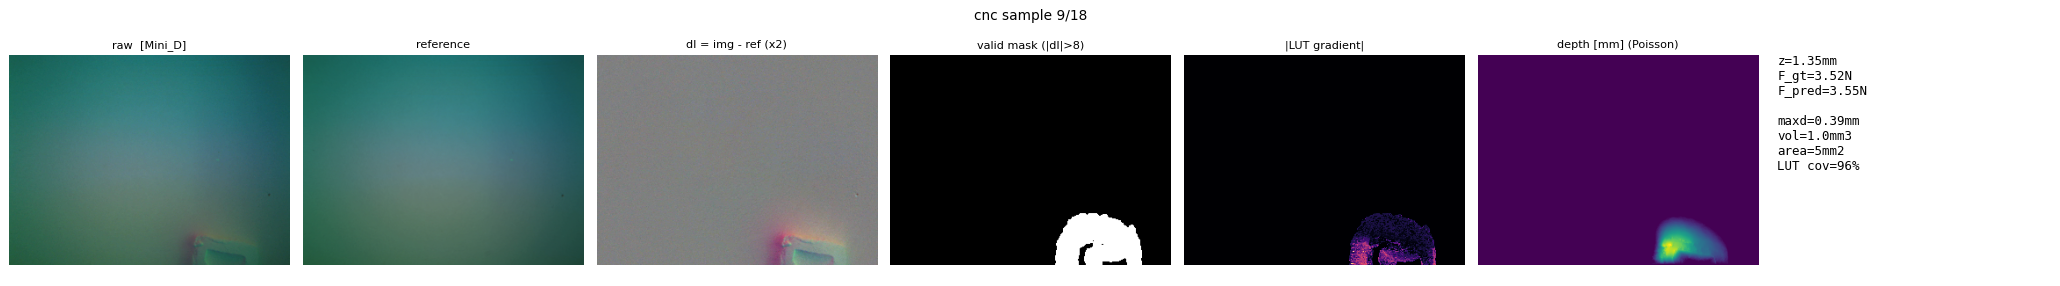
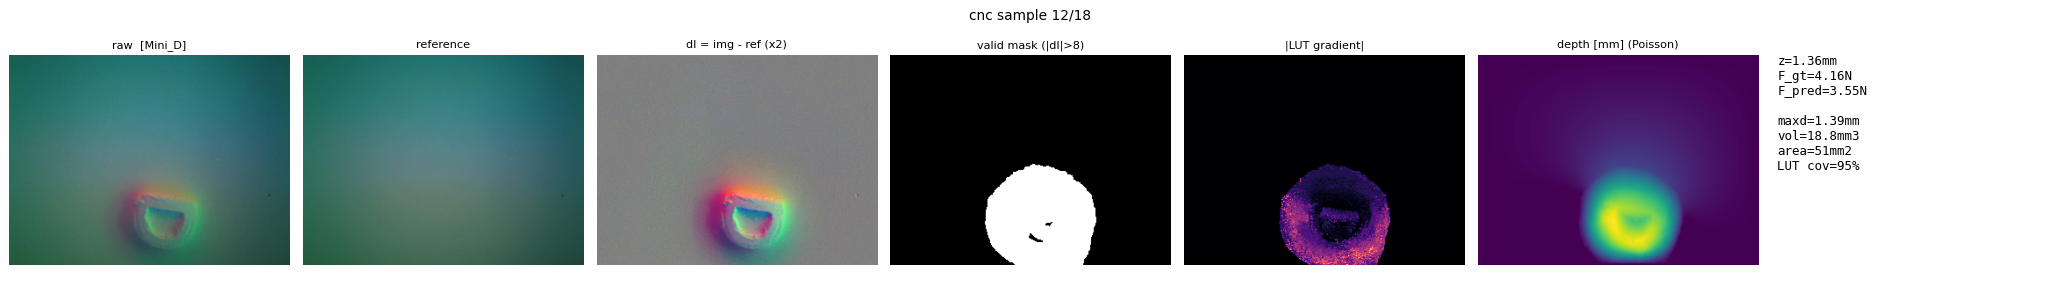
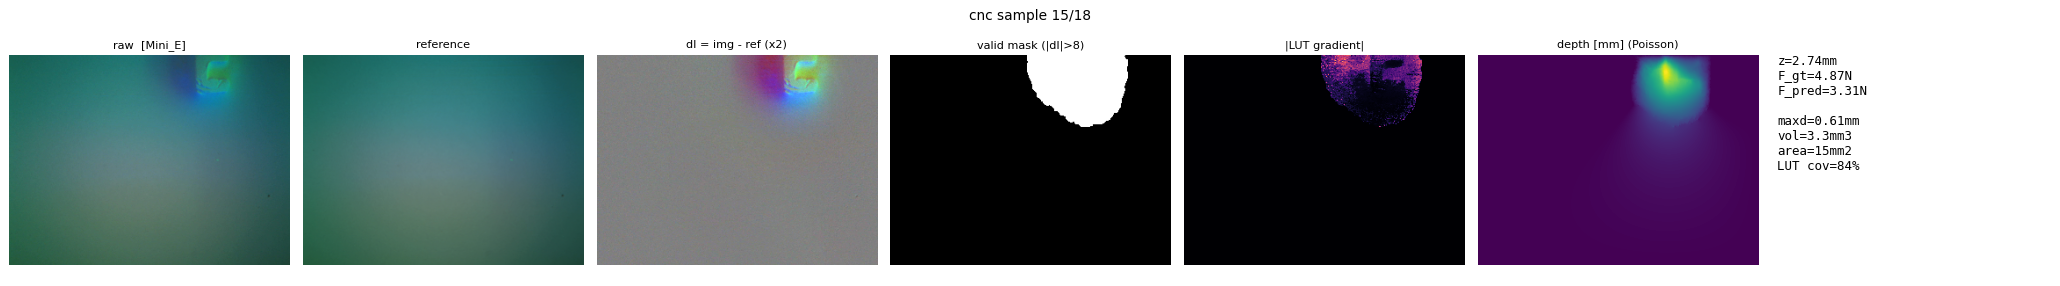
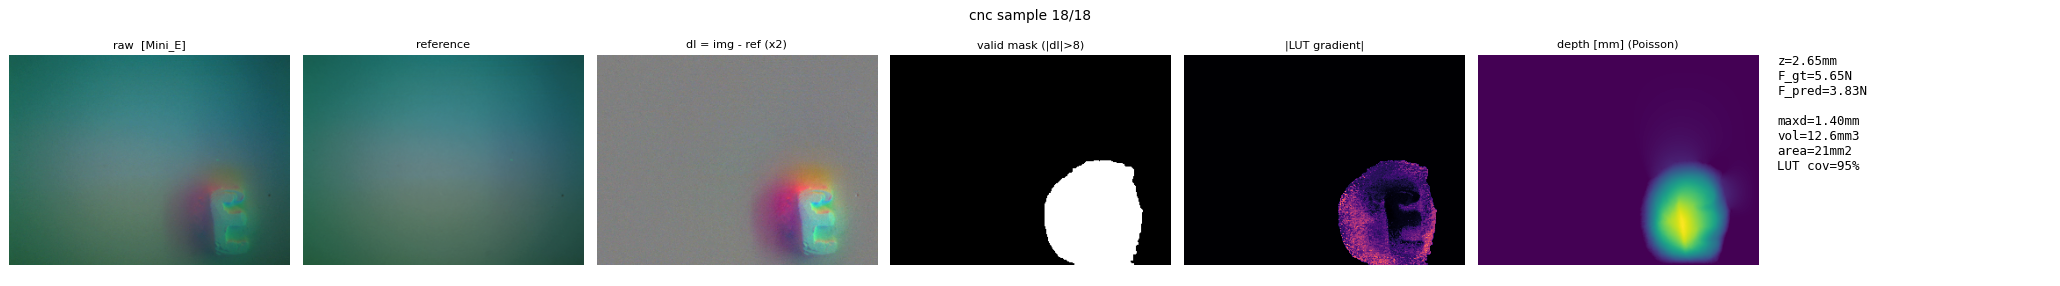
Each row: raw → reference → dI=img−ref → valid mask → |LUT gradient| → Poisson depth → features and predicted vs ground-truth force. Same pipeline, three datasets.
Why cnc_Mini looked broken — and what it actually was
Neither bad labels nor a broken reconstruction: the cnc press grid spans the full 20×16 mm pad while the cropped camera view sees only ≈13×10 mm, so two thirds of the presses are partially outside the image and their contact features are systematically underestimated. Restricted to presses fully in view, the same reconstruction reaches GlowTact-level accuracy. Label quality is fine (force CV 4.5% at fixed probe/position/depth). This retracts our earlier “dataset ceiling” argument: in-view ρ=0.94 exceeds the commanded-depth proxy (0.78–0.88) that argument relied on.
| scope (cnc, 3351 frames) | n | per-probe ρ (A–F) | median ρ | MAE |
|---|---|---|---|---|
| all press positions | 3351 | 0.09–0.16 | 0.113 | 0.74 N |
| interior x∈[3.5,14.5] | 1232 | 0.79–0.85 | 0.835 | 0.39 N |
| strictly in view x∈[5,13] | 671 | 0.94 0.94 0.93 0.91 0.95 0.95 | 0.941 | 0.26 N |
Per-probe half/half fit, 7 seeds, LUT pipeline with z-supervised gain field. Dot-type control: FEATS presses are always centered, so the raw pipeline already gives ρ=0.72 there, vs 0.46 raw on GlowTact — the gain field and scope, not markers, are the binding factors.
GlowTact — markerless, the LUT's home sensor (control)
FoTa cnc_Mini — markerless, foreign sensor, press grid larger than the field of view
FEATS — dot/marker type; difference imaging cancels static markers