GelSight image → normal force, in one page
Markerless gel, no F/T sensor, no training data from our rig. A physics pipeline with exactly one fitted number.
↖ results matrix overview action transform 中文The pipeline — six steps
nnmini): three-color illumination makes color→normal invertiblePost-processing: a 3-tap median over fresh tactile frames only (duplicated rows would let a row-wise filter count bad values three times). Cuts single-frame spikes from 4–8% to ≈0.
Photometric overhaul — classic per-sensor calibration (v2)
Ground-truth depth supervision (commanded press depth in GlowTact) exposed that the generic depth MLP recovers only ~25% of true indentation and saturates (peak-depth ρ = 0.39) — and, deeper, that the gsrobotics SDK's Poisson solver returns 39% of the amplitude even on a perfect synthetic gradient field (line-integral proved the gradients were correct at 105%). Rebuilt on the classic Dong/Yuan calibration: difference image → per-sensor RGB lookup table, self-calibrated from GlowTact's spherical presses via the exact relation a² = d(2R−d) (R = 3.35 mm, no external data) → exact Poisson (Dong's fast_poisson, 100.7% on the same benchmark) → sphere-supervised spatial gain field → Drake-style stiffening foundation p = k₁δ + k₂δ² with imprint-derived shape conditioning.
| stage (held-out, GlowTact 0–20 N) | ρ | MAE |
|---|---|---|
| MLP + linear Winkler (v1) | 0.63 | 4.4 N |
| LUT + solver fix + gain field + nonlinear foundation | 0.80 | 2.75 N |
| + imprint shape self-conditioning | 0.82 | 2.46 N |
| spheres only (geometry exact — the method's ceiling) | 0.91–0.94 | 1.5–1.9 N |
| spheres × 0–8 N (React's operating range; 7-seed median, +isotonic) | 0.95 (0.93–0.96) | 0.78 N (0.73–0.84) |
Ceiling context: the CNC's own commanded depth predicts force at ρ = 0.975. The remaining pooled gap is object-dependent contact mechanics; sub-newton MAE on 0–20 N exceeds what geometry alone carries (the 200K-frame supervised network reaches 2.1 N on the same range). A new sensor needs one 2-minute ball-press pass — a calibration the React rig can adopt.
Validation (LUT-v2 pipeline)
The LUT-v2 pipeline is validated on three force-labeled datasets (FEATS, FoTa cnc_Mini, GlowTact) and cross-checked against two neural estimators on identical frames — every predicted-vs-ground-truth scatter, per dataset, lives on the results page. Short version: physics 0.74-0.99 everywhere (GlowTact 0.98, cnc_Mini in-view 0.94, FEATS 0.77); each network 0.90+ in its own gel domain and collapsing outside it.
Per-dataset calibration
Worth stating plainly, because it bounds what those ρ mean: the pipeline holds no hardness or elastic-modulus constant anywhere. Nothing in the code knows a gel's Shore hardness or Young's modulus. Stiffness enters only implicitly — absorbed into the per-group least-squares weights and the isotonic calibration stacked on them — and those are refit per dataset and per indenter/probe group: every cnc_Mini probe, every GlowTact indenter family, every FEATS capture group gets its own fit, half the group fitting and half held out.
The only physical constants shared across datasets are the sphere-calibrated
RGB lookup table and MM_PER_PIXEL. Everything downstream of depth
is refit. The reported ρ are therefore per-group rank correlations —
evidence that the geometry recovered from the image is monotone in force
within a group. They do not demonstrate a transferable
absolute-newton model across gels; the one pooled multi-object fit we tried was
much worse (ρ 0.47), which is why the sphere, with known geometry, is the
calibration object.
The reconstruction underneath is not the noise source it appears to be, and that is measured, not assumed: high-frequency content in the depth field is 0.3% of peak depth (6.5 µm on a 1.9 mm press), while in the gradient field it is 22.2% — LUT bin quantisation, with 9.8% of contact pixels landing in bins the sphere calibration never observed (nearest-filled). Poisson integration is a low-pass, so the LUT noise is gone by the time depth exists; the speckle visible in gradient-domain debug panels never reaches the force features.
Optimizing against ground truth
The cnc_Mini force labels turned the pipeline's weak spots into measurable defects, fixed in order (each step verified on held-out data):
| step | evidence that drove it | ρ (held-out val) |
|---|---|---|
| baseline (volume, per-episode zeroing) | — | 0.34 pooled |
| + median zero map over scattered presses | only 4 of 2686 frames are truly contact-free; lowest-force references carried 1.7 N of baked-in contact | ≈ same (zero map wasn't the bottleneck) |
| + flat-field illumination normalization | force-fit residuals correlated with contact position (|ρ| up to 0.6); probe×quadrant conditioning raised ρ 0.45→0.55 — the vignette modulates the depth MLP's gain | 0.44 pooled |
| + edge filtering (contact centroid > 3 mm from border) | border presses sit where the vignette is steepest and imprints clip the sensor edge | 0.65 (probe-median 0.64) |
Volume or max depth? Settled empirically: the volume family wins (vol1.5-weighted 0.65, plain volume 0.63) over max depth (0.63) and clearly over contact area (0.35); a tiny 3-feature linear model matches ρ but halves MAE (0.61 N). The ceiling matters too: even the CNC's own commanded press depth only reaches ρ 0.78–0.88 within a probe — force at equal depth genuinely varies with texture and position.
Gallery
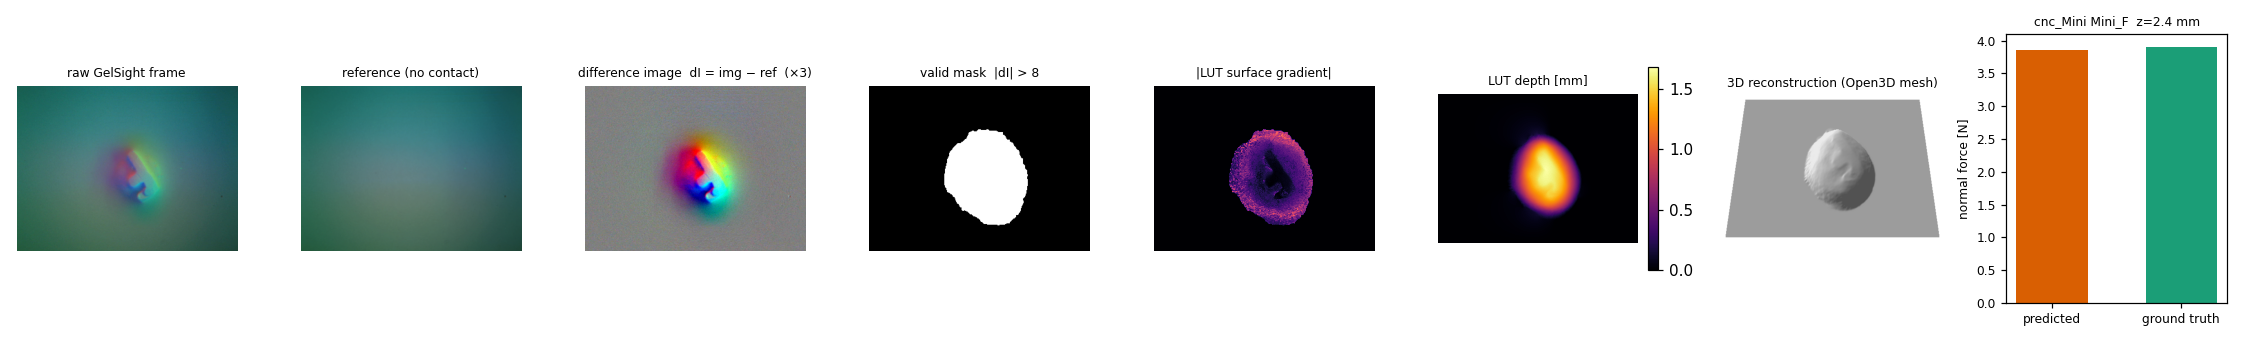
20 image samples (raw | indentation | Open3D mesh of the reconstruction | predicted vs ground-truth force) and 10 React episode clips (tactile | live depth | live Open3D mesh | force trace): browse the full gallery. The mesh panel re-renders on every fresh tactile frame.
NN vs model-based on the GelSight Mini — who has compared them?
No published head-to-head that we could find. The literature runs in two camps that cite but don't benchmark each other. Model-based: marker displacement × elasticity (Yuan 2017), photometric-stereo height + polynomial fit, inverse FEM (GelSlim, Ma 2019). Learned, on the Mini specifically: CANFnet (F/T-labeled, normal only), FEATS (FEA-labeled, 3D distributions), FeelAnyForce (200K ATI-labeled). Each motivates NN over physics qualitatively — FEA too slow for real time, linear elasticity misses elastomer nonlinearity — but their reported baselines are other networks, not the physics pipeline.
Our FEATS experiment is therefore one of the few direct data points: the model-based pipeline reaches ρ 0.70–0.85 with one fitted scalar and zero training frames, where the NNs earn sub-newton MAE in-domain but die outside their gel (FEATS on our markerless gel: no response at all). The trade is portability vs in-domain accuracy — and which one you need depends on whether you can collect labels on your own sensor.
Where it can still improve — and does learning help?
Five candidate improvements, each with a control that could have killed it.
Two survived. Reproduce with
python -m force_recovery.improvement_study all.
| idea | result | verdict |
|---|---|---|
| Extract shear-sensitive features residual correlates with shear at ρ 0.31–0.40 |
feeding the true shear in as an oracle moves ρ 0.9749 → 0.9757 (MAE 0.0360 → 0.0345) | closed — the correlation was confounded; both track force magnitude |
| Small neural nets on the same features | MLP 32×16 0.967 · MLP 64×64 0.972 · gradient boosting 0.972, vs 0.974 for linear+isotonic | no — with ~400 in-view frames per pad, flexible models overfit |
| Log features (error is multiplicative) | ρ 0.9735 → 0.9822, MAE 0.0361 → 0.0310 (−14%) | adopted |
| “PINN-lite” dimensionless contact law F/A = g(δ/√A) | looked decisive on sphere→flat (MAE 0.426 → 0.150 N, beating an MLP's 0.297) — then F = g(volume) reached 0.0736 N | rejected — the gain was one monotone feature instead of five, not the physics form |
| Match model complexity to the transfer regime | see below | adopted |
The one real structural finding: a single monotone volume feature generalises to unseen indenter shapes better than the five-feature model, while five features stay better once the shape is calibrated. On GlowTact leave-one-indenter-out — the model never sees the held-out shape — this repairs exactly the two weak spots we reported earlier:
| held-out indenter | 5-feature ρ | volume-only ρ |
|---|---|---|
| round | 0.958 | 0.993 |
| star | 0.977 | 0.991 |
| quad_small | 0.989 | 0.997 |
| B / quad / triangle | 0.981–0.995 | 0.986–0.996 |
Every held-out indenter now lands at ρ ≥ 0.986 without the model ever seeing that shape — a stronger claim than the per-indenter calibrated numbers on the results page, which are fitted within each family. The cost is absolute newtons: five features still win MAE when the shape is known (Sparsh cross-pad 0.0372 vs 0.0443 N), so the rule is volume-only for unseen shapes, five features once calibrated. A learned g inside the physics law collapses entirely (ρ −0.249): isotonic clips monotonically outside the training range, a network extrapolates freely.