


Verify vLLM usage on GPU and update latency and effort charts
Browse files- README.md +36 -13
- README.zh-CN.md +20 -11
- assets/effort-tradeoff.svg +1 -0
- assets/latency-vllm.svg +1 -0
- bundle-manifest.json +29 -5
- effort-tradeoff-data.json +32 -0
- latency-vllm-data.json +47 -0
README.md
CHANGED
|
@@ -37,7 +37,7 @@ We introduce **APUS-OpenJev-v1**, a family of decision models for browser agents
|
|
| 37 |
|
| 38 |
**Decision-oriented inference.** The runtime scores candidate labels and maps them back to application actions. This removes the need to generate a structured answer token by token for bounded-choice tasks. Choose `effort="low"` or `effort="high"` to balance compute cost and decision quality.
|
| 39 |
|
| 40 |
-
On our frozen 80-question development panel, **APUS-OpenJev 9B achieves 85.0% accuracy**, compared with **82.5% for the Jev API**.
|
| 41 |
|
| 42 |

|
| 43 |
|
|
@@ -66,18 +66,29 @@ The 4B model leads this panel's Browser subset, while 9B's gains come from princ
|
|
| 66 |
|
| 67 |
### Response latency
|
| 68 |
|
| 69 |
-
![
|
| 70 |
|
| 71 |
-
*Figure 3.
|
| 72 |
|
| 73 |
-
|
|
| 74 |
-
| --- | ---: |
|
| 75 |
-
|
|
| 76 |
-
|
|
| 77 |
-
|
|
| 78 |
-
|
|
|
|
|
| 79 |
|
| 80 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 81 |
|
| 82 |
## 3. Evaluation Set
|
| 83 |
|
|
@@ -137,14 +148,21 @@ On Linux with Python 3.12 and an NVIDIA GPU with sufficient memory (the existing
|
|
| 137 |
```bash
|
| 138 |
python3.12 -m venv .venv
|
| 139 |
source .venv/bin/activate
|
| 140 |
-
pip install vllm==0.29.0 huggingface-hub openai ninja
|
| 141 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 142 |
CUDA_VISIBLE_DEVICES=0 python serve_vllm.py
|
| 143 |
# Optional: --revision <40-character-commit-SHA>
|
| 144 |
# Inspect the command without downloading or using a GPU:
|
| 145 |
# python serve_vllm.py --dry-run
|
| 146 |
```
|
| 147 |
|
|
|
|
|
|
|
| 148 |
In a second terminal using the same environment:
|
| 149 |
|
| 150 |
```python
|
|
@@ -159,10 +177,15 @@ response = client.chat.completions.create(
|
|
| 159 |
"Reply with only A, B, or C."}],
|
| 160 |
temperature=0,
|
| 161 |
max_tokens=16,
|
|
|
|
| 162 |
)
|
| 163 |
-
print(response.choices[0].message.content)
|
| 164 |
```
|
| 165 |
|
|
|
|
|
|
|
|
|
|
|
|
|
| 166 |
This example returns standard chat-completion text through `choices[0].message.content`. It demonstrates **full-depth text serving**, not the specialized candidate-probability `/decide` gateway or `effort` routing. It does not enforce the three candidate labels; application-specific decision serving requires the corresponding prompt/compiler and output constraints. The server binds to localhost by default. Blackwell JIT compilation requires a compatible CUDA toolchain; the launcher disables the FlashInfer sampler as in the tested engine configuration.
|
| 167 |
|
| 168 |
## 6. Reproducing the Evaluation
|
|
|
|
| 37 |
|
| 38 |
**Decision-oriented inference.** The runtime scores candidate labels and maps them back to application actions. This removes the need to generate a structured answer token by token for bounded-choice tasks. Choose `effort="low"` or `effort="high"` to balance compute cost and decision quality.
|
| 39 |
|
| 40 |
+
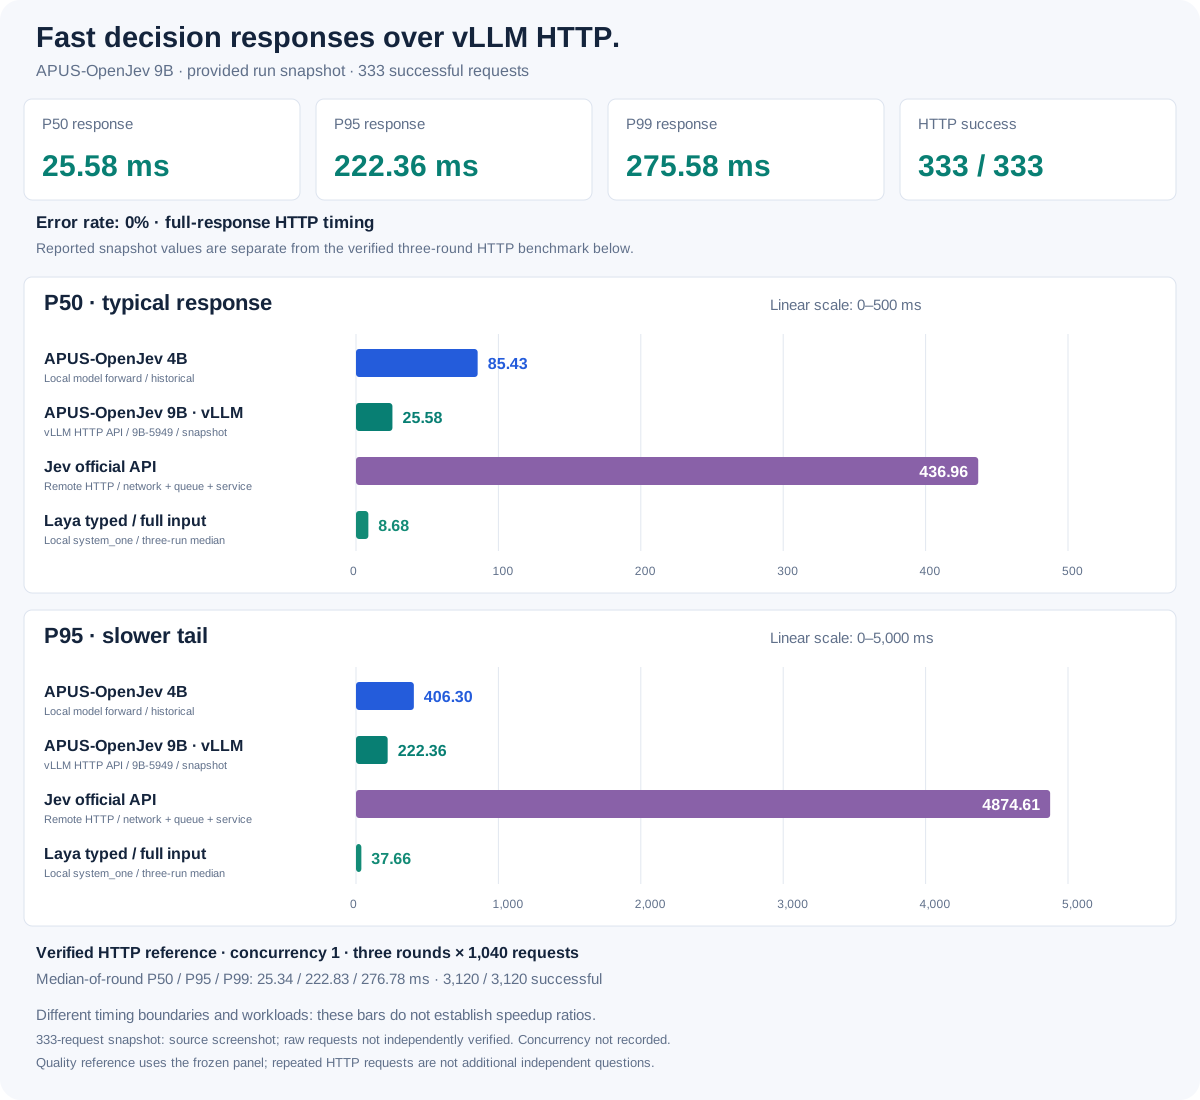
On our frozen 80-question development panel, **APUS-OpenJev 9B achieves 85.0% accuracy**, compared with **82.5% for the Jev API**. The optimized 9B decision service reports **25.58 ms median HTTP latency** in the run snapshot below. The 85.0% result uses `9B-3000`; the optimized latency measurement uses `9B-5949`. Accuracy and latency are reported with their evaluation settings below.
|
| 41 |
|
| 42 |

|
| 43 |
|
|
|
|
| 66 |
|
| 67 |
### Response latency
|
| 68 |
|
| 69 |
+

|
| 70 |
|
| 71 |
+
*Figure 3. vLLM HTTP API full-response latency for the optimized decision service. The supplied run snapshot reports 333/333 successful requests and 0% errors. This is full-response latency, not streaming first-token latency.*
|
| 72 |
|
| 73 |
+
| Decision API metric | Run snapshot |
|
| 74 |
+
| --- | ---: |
|
| 75 |
+
| **P50 latency** | **25.58 ms** |
|
| 76 |
+
| P95 latency | 222.36 ms |
|
| 77 |
+
| P99 latency | 275.58 ms |
|
| 78 |
+
| Successful requests | 333 /333 |
|
| 79 |
+
| Error rate | 0% |
|
| 80 |
|
| 81 |
+
The chart distinguishes the supplied 333-request snapshot from the independently archived three-run C1 validation: **25.34 / 222.83 / 276.78 ms** median per-run P50/P95/P99, with **3,120/3,120** successful serial requests on an RTX PRO 6000 96GB. The exact 333-request raw trace is not part of that archive. Accuracy uses 80 fixed questions; replay counts do not increase the number of independent questions.
|
| 82 |
+
|
| 83 |
+
The optimized path is the candidate-scoring `/decide` service. The standard Chat Completions launcher below has a separate generation path. Historical 4B model-forward, Laya local-pipeline and Jev public-API measurements remain labeled in the chart; different network and processing boundaries do not establish a model speedup ratio. See [measurement sources](latency-vllm-data.json).
|
| 84 |
+
|
| 85 |
+
### Selectable effort: measured quality–latency trade-off
|
| 86 |
+
|
| 87 |
+

|
| 88 |
+
|
| 89 |
+
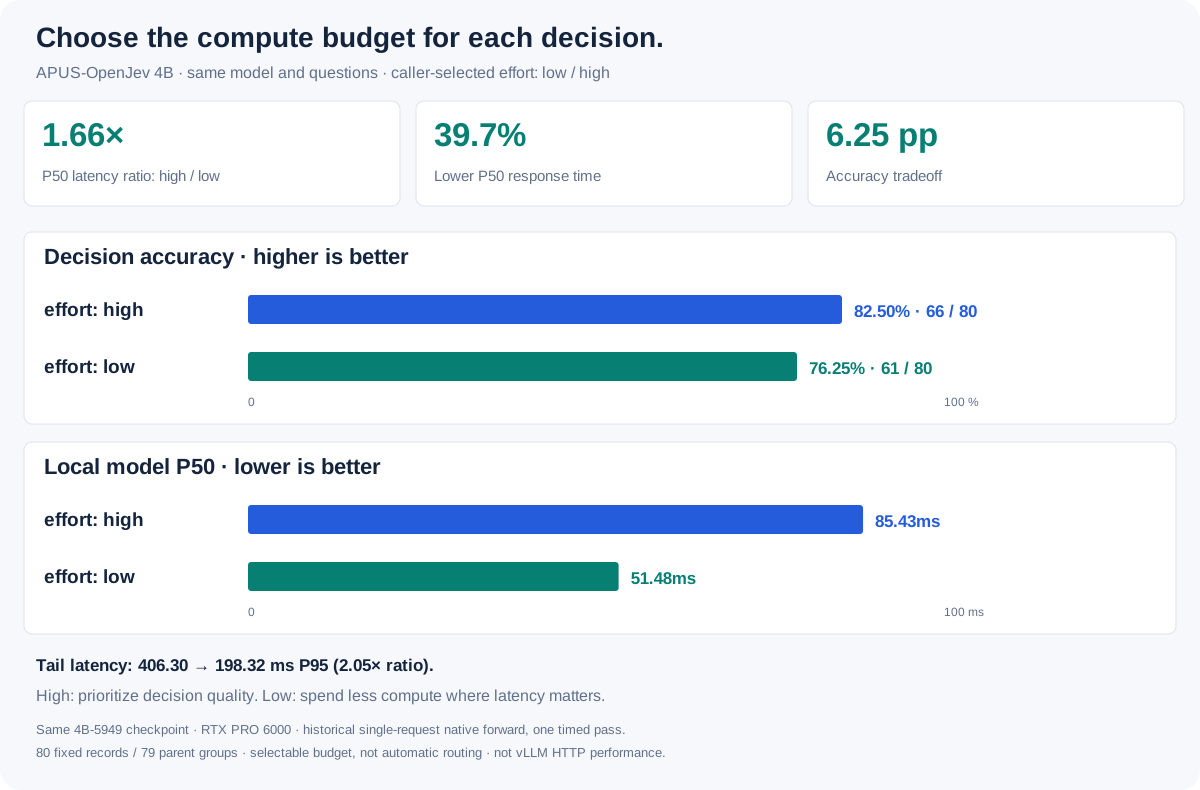
**Around 2× faster at P95, with less than 8% relative accuracy reduction.** On the same 4B checkpoint and frozen panel, selecting `effort="low"` reduces P95 model-forward latency from **406.30 to 198.32 ms**. Accuracy changes from **82.50% to 76.25%**: **6.25 percentage points**, or **7.58% relative**. P50 changes from **85.43 to 51.48 ms**, a **1.66×** speed ratio.
|
| 90 |
+
|
| 91 |
+
These paired measurements use the native effort runtime. They are separate from the full-depth vLLM Chat API measurements and do not imply a measured vLLM low-effort endpoint. Deployment-specific low/high performance must be measured using the same serving path. See [effort measurement data](effort-tradeoff-data.json).
|
| 92 |
|
| 93 |
## 3. Evaluation Set
|
| 94 |
|
|
|
|
| 148 |
```bash
|
| 149 |
python3.12 -m venv .venv
|
| 150 |
source .venv/bin/activate
|
| 151 |
+
pip install vllm==0.29.0 transformers==5.17.0 huggingface-hub==1.32.0 openai==3.16.2 ninja==1.13.2
|
| 152 |
+
# Blackwell: use the CUDA 13 compiler used in the GPU verification.
|
| 153 |
+
pip install nvidia-cuda-nvcc==13.4.92 nvidia-cuda-crt==13.4.92 nvidia-cuda-cccl==13.3.4.3.1
|
| 154 |
+
export CUDA_HOME="$(python -c 'import sysconfig; print(sysconfig.get_path("purelib") + "/nvidia/cu13")')"
|
| 155 |
+
export PATH="$CUDA_HOME/bin:$PATH"
|
| 156 |
+
"$CUDA_HOME/bin/nvcc" --version
|
| 157 |
+
curl -fL https://huggingface.co/apus-ailab/APUS-OpenJev-v1/resolve/main/deployment/serve_vllm.py -o serve_vllm.py
|
| 158 |
CUDA_VISIBLE_DEVICES=0 python serve_vllm.py
|
| 159 |
# Optional: --revision <40-character-commit-SHA>
|
| 160 |
# Inspect the command without downloading or using a GPU:
|
| 161 |
# python serve_vllm.py --dry-run
|
| 162 |
```
|
| 163 |
|
| 164 |
+
The first launch downloads approximately 18 GB and compiles GPU kernels; allow several minutes before sending requests. Check readiness with `curl -f http://127.0.0.1:8000/health`.
|
| 165 |
+
|
| 166 |
In a second terminal using the same environment:
|
| 167 |
|
| 168 |
```python
|
|
|
|
| 177 |
"Reply with only A, B, or C."}],
|
| 178 |
temperature=0,
|
| 179 |
max_tokens=16,
|
| 180 |
+
extra_body={"chat_template_kwargs": {"enable_thinking": False}},
|
| 181 |
)
|
| 182 |
+
print(response.choices[0].message.content) # A
|
| 183 |
```
|
| 184 |
|
| 185 |
+
Keep `enable_thinking=False` for these short decision outputs. The original example without this setting reached its 16-token limit before producing a decision; the corrected example returned `A` in the real GPU check.
|
| 186 |
+
|
| 187 |
+
**GPU verification:** anonymous download from this public repository into a fresh cache, followed by 240/240 successful Chat Completions requests (80 fixed questions replayed three times), with no invalid answers or truncated completions. Local HTTP P50/P95/P99: **45.47 / 191.36 / 232.29 ms**. Test environment: Linux, Python 3.12.3, RTX PRO 6000 Blackwell 96GB, vLLM 0.29.0, PyTorch 2.13.0, Transformers 5.17.0, and the CUDA 13 compiler specified above. This reused an installed Python environment; a clean OS installation was not tested.
|
| 188 |
+
|
| 189 |
This example returns standard chat-completion text through `choices[0].message.content`. It demonstrates **full-depth text serving**, not the specialized candidate-probability `/decide` gateway or `effort` routing. It does not enforce the three candidate labels; application-specific decision serving requires the corresponding prompt/compiler and output constraints. The server binds to localhost by default. Blackwell JIT compilation requires a compatible CUDA toolchain; the launcher disables the FlashInfer sampler as in the tested engine configuration.
|
| 190 |
|
| 191 |
## 6. Reproducing the Evaluation
|
README.zh-CN.md
CHANGED
|
@@ -39,7 +39,7 @@ tags:
|
|
| 39 |
|
| 40 |
**面向决策的推理。** runtime对候选标签评分,再映射回应用动作。对于有界选择任务,无需逐token生成结构化答案。通过选择`effort="low"`或`effort="high"`,在计算成本与决策质量之间取得平衡。
|
| 41 |
|
| 42 |
-
在冻结的80题开发回归面板上,**APUS-OpenJev 9B的准确率为85.0%**,**Jev API为82.5%**。
|
| 43 |
|
| 44 |

|
| 45 |
|
|
@@ -68,18 +68,27 @@ tags:
|
|
| 68 |
|
| 69 |
### 响应延迟
|
| 70 |
|
| 71 |
-
,从 `apus-ailab/APUS-OpenJev-v1` 下载 `9B-5949` 完整权重并启动 vLLM 0.29.0。安装、启动及 OpenAI 调用示例见[英文说明](README.md#deploy-with-vllm)。该入口提供完整深度的标准文本生成;决策网关 `/decide` 和动态深度选择使用各自的运行路径。
|
| 136 |
|
| 137 |
## 6. 复现评测
|
| 138 |
|
|
|
|
| 39 |
|
| 40 |
**面向决策的推理。** runtime对候选标签评分,再映射回应用动作。对于有界选择任务,无需逐token生成结构化答案。通过选择`effort="low"`或`effort="high"`,在计算成本与决策质量之间取得平衡。
|
| 41 |
|
| 42 |
+
在冻结的80题开发回归面板上,**APUS-OpenJev 9B的准确率为85.0%**,**Jev API为82.5%**。优化后的9B决策服务在下方运行快照中达到 **25.58 ms HTTP中位延迟**。85.0%对应`9B-3000`;优化延迟对应`9B-5949`。下文分别说明准确率和延迟的评测条件。
|
| 43 |
|
| 44 |

|
| 45 |
|
|
|
|
| 68 |
|
| 69 |
### 响应延迟
|
| 70 |
|
| 71 |
+

|
| 72 |
|
| 73 |
+
| 决策接口指标 | 提供的运行快照 |
|
| 74 |
+
| --- | ---: |
|
| 75 |
+
| **P50延迟** | **25.58 ms** |
|
| 76 |
+
| P95延迟 | 222.36 ms |
|
| 77 |
+
| P99延迟 | 275.58 ms |
|
| 78 |
+
| 成功请求 | 333 /333 |
|
| 79 |
+
| 错误率 | 0% |
|
| 80 |
|
| 81 |
+
333次请求数据来自提供的运行截图。独立归档可核验的C1三轮结果为:各轮P50/P95/P99的中位数 **25.34 / 222.83 / 276.78 ms**,成功 **3,120/3,120**,硬件为RTX PRO 6000 96GB;归档不含这333次请求的精确原始明细。准确率对应80道固定题,重复请求不增加独立题数。
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 82 |
|
| 83 |
+
这是候选打分`/decide`服务的完整HTTP响应耗时,非流式首token。下方标准Chat Completions脚本走独立生成路径。图中4B本地forward、Laya本地流程与Jev公网API保留各自计时边界,不直接相除宣称模型加速倍数。[数据来源](latency-vllm-data.json)。
|
| 84 |
+
|
| 85 |
+
### 可选 effort:准确率与延迟的实测取舍
|
| 86 |
+
|
| 87 |
+

|
| 88 |
+
|
| 89 |
+
**P95约2倍提速,准确率相对下降不到8%。** 同一4B版本、同一冻结面板上,`effort="low"`将P95模型前向延迟从 **406.30 ms降到198.32 ms**;准确率从 **82.50%降到76.25%**,下降 **6.25个百分点 / 相对7.58%**。P50从 **85.43 ms降到51.48 ms**,提速 **1.66倍**。
|
| 90 |
+
|
| 91 |
+
这组数据来自原生effort runtime,与完整深度vLLM Chat API分开记录;不能把Chat API的实测延迟除以二当作low实测。相同部署路径的low/high需另行测试。[成对测量来源](effort-tradeoff-data.json)。
|
| 92 |
|
| 93 |
## 3. 评测集
|
| 94 |
|
|
|
|
| 141 |
|
| 142 |
### vLLM 部署
|
| 143 |
|
| 144 |
+
提供[单文件启动脚本](deployment/serve_vllm.py),从 `apus-ailab/APUS-OpenJev-v1` 下载 `9B-5949` 完整权重并启动 vLLM 0.29.0。安装、启动及 OpenAI 调用示例见[英文说明](README.md#deploy-with-vllm)。已完成公开仓库匿名下载和真实GPU验证:标准Chat API三轮共240/240次成功、无截断,P50/P95/P99为45.47/191.36/232.29 ms。短标签请求必须设置`chat_template_kwargs.enable_thinking=False`,否则16-token示例会在思考阶段截断。复用了已安装的Python环境,未验证全新系统安装。该入口提供完整深度的标准文本生成;决策网关 `/decide` 和动态深度选择使用各自的运行路径。
|
| 145 |
|
| 146 |
## 6. 复现评测
|
| 147 |
|
assets/effort-tradeoff.svg
ADDED
|
assets/latency-vllm.svg
ADDED
|
bundle-manifest.json
CHANGED
|
@@ -17,7 +17,11 @@
|
|
| 17 |
"ARCHITECTURE.md",
|
| 18 |
"README.md",
|
| 19 |
"README.zh-CN.md",
|
| 20 |
-
"
|
|
|
|
|
|
|
|
|
|
|
|
|
| 21 |
],
|
| 22 |
"files": [
|
| 23 |
{
|
|
@@ -577,13 +581,13 @@
|
|
| 577 |
},
|
| 578 |
{
|
| 579 |
"path": "README.md",
|
| 580 |
-
"bytes":
|
| 581 |
-
"sha256": "
|
| 582 |
},
|
| 583 |
{
|
| 584 |
"path": "README.zh-CN.md",
|
| 585 |
-
"bytes":
|
| 586 |
-
"sha256": "
|
| 587 |
},
|
| 588 |
{
|
| 589 |
"path": "TECHNICAL_REPORT.md",
|
|
@@ -610,6 +614,16 @@
|
|
| 610 |
"bytes": 6425,
|
| 611 |
"sha256": "b3198ec01536b6efff1c8f89402d3b45112c21471d613ed69f9a5c1a5fb94762"
|
| 612 |
},
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 613 |
{
|
| 614 |
"path": "assets/latency.svg",
|
| 615 |
"bytes": 6956,
|
|
@@ -635,6 +649,16 @@
|
|
| 635 |
"bytes": 3535,
|
| 636 |
"sha256": "7d8fac3021a9f9949e73364013989d861dcb6fd4c44ee338239822584d32ecf8"
|
| 637 |
},
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 638 |
{
|
| 639 |
"path": "subset-chart-data.json",
|
| 640 |
"bytes": 58611,
|
|
|
|
| 17 |
"ARCHITECTURE.md",
|
| 18 |
"README.md",
|
| 19 |
"README.zh-CN.md",
|
| 20 |
+
"assets/effort-tradeoff.svg",
|
| 21 |
+
"assets/latency-vllm.svg",
|
| 22 |
+
"deployment/serve_vllm.py",
|
| 23 |
+
"effort-tradeoff-data.json",
|
| 24 |
+
"latency-vllm-data.json"
|
| 25 |
],
|
| 26 |
"files": [
|
| 27 |
{
|
|
|
|
| 581 |
},
|
| 582 |
{
|
| 583 |
"path": "README.md",
|
| 584 |
+
"bytes": 15514,
|
| 585 |
+
"sha256": "ea8782dac0afeff883a49d5c6c3751eb064f37a3838bd55c7b221ac5752d43a3"
|
| 586 |
},
|
| 587 |
{
|
| 588 |
"path": "README.zh-CN.md",
|
| 589 |
+
"bytes": 11222,
|
| 590 |
+
"sha256": "a6f352a67cc955f7321891978a710bec017fcbe385b0e0c8f4c9c0f09c36d555"
|
| 591 |
},
|
| 592 |
{
|
| 593 |
"path": "TECHNICAL_REPORT.md",
|
|
|
|
| 614 |
"bytes": 6425,
|
| 615 |
"sha256": "b3198ec01536b6efff1c8f89402d3b45112c21471d613ed69f9a5c1a5fb94762"
|
| 616 |
},
|
| 617 |
+
{
|
| 618 |
+
"path": "assets/effort-tradeoff.svg",
|
| 619 |
+
"bytes": 4092,
|
| 620 |
+
"sha256": "3c0c2354e04593d431db293a1e3153cc8bbf9c9c0b0c5a3ad59a68ce005592eb"
|
| 621 |
+
},
|
| 622 |
+
{
|
| 623 |
+
"path": "assets/latency-vllm.svg",
|
| 624 |
+
"bytes": 8391,
|
| 625 |
+
"sha256": "d6cbb29a693be1f5f4c4810b06b5277e279358c91283c3bd045c706ae32b0bae"
|
| 626 |
+
},
|
| 627 |
{
|
| 628 |
"path": "assets/latency.svg",
|
| 629 |
"bytes": 6956,
|
|
|
|
| 649 |
"bytes": 3535,
|
| 650 |
"sha256": "7d8fac3021a9f9949e73364013989d861dcb6fd4c44ee338239822584d32ecf8"
|
| 651 |
},
|
| 652 |
+
{
|
| 653 |
+
"path": "effort-tradeoff-data.json",
|
| 654 |
+
"bytes": 1201,
|
| 655 |
+
"sha256": "c2b2efb1b4aa1f25730b0f7605f87f5fef0662af30e809a79c70d3a2ce176e5a"
|
| 656 |
+
},
|
| 657 |
+
{
|
| 658 |
+
"path": "latency-vllm-data.json",
|
| 659 |
+
"bytes": 1337,
|
| 660 |
+
"sha256": "d04c85c1b75a209c0cc857ae9961d3651cde1c62b9cbf28dfadb3a5f6f2215a8"
|
| 661 |
+
},
|
| 662 |
{
|
| 663 |
"path": "subset-chart-data.json",
|
| 664 |
"bytes": 58611,
|
effort-tradeoff-data.json
ADDED
|
@@ -0,0 +1,32 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"selected_model": "4B-5949",
|
| 3 |
+
"source_path": "evidence/official-vs-final5949-80/report.json",
|
| 4 |
+
"source_sha256": "b3542b7268a675a48c64ee0dad067bbb609c0e3c99bc6f7926e0241a56a27597",
|
| 5 |
+
"low": {
|
| 6 |
+
"n": 80,
|
| 7 |
+
"correct": 61,
|
| 8 |
+
"accuracy": 0.7625,
|
| 9 |
+
"nll_epsilon_1e-12": 1.0545613467438772,
|
| 10 |
+
"brier": 0.3943826629642137,
|
| 11 |
+
"latency_p50_seconds": 0.05147563456557691,
|
| 12 |
+
"latency_p95_seconds_nearest_rank": 0.19832013035193086
|
| 13 |
+
},
|
| 14 |
+
"high": {
|
| 15 |
+
"n": 80,
|
| 16 |
+
"correct": 66,
|
| 17 |
+
"accuracy": 0.825,
|
| 18 |
+
"nll_epsilon_1e-12": 0.6519612054580076,
|
| 19 |
+
"brier": 0.27633044836807164,
|
| 20 |
+
"latency_p50_seconds": 0.08542586304247379,
|
| 21 |
+
"latency_p95_seconds_nearest_rank": 0.40630325907841325
|
| 22 |
+
},
|
| 23 |
+
"p50_ratio_high_over_low": 1.6595397757291617,
|
| 24 |
+
"p95_ratio_high_over_low": 2.048724243763878,
|
| 25 |
+
"p50_latency_reduction_percent": 39.74233009506361,
|
| 26 |
+
"accuracy_drop_percentage_points": 6.25,
|
| 27 |
+
"accuracy_relative_drop_percent": 7.575757575757576,
|
| 28 |
+
"timing": "Historical single-request native forward; same checkpoint and frozen panel, not vLLM HTTP or merged latency retest",
|
| 29 |
+
"routing": "Caller-selected effort; not automatic per-question routing",
|
| 30 |
+
"n_records": 80,
|
| 31 |
+
"n_parent_groups": 79
|
| 32 |
+
}
|
latency-vllm-data.json
ADDED
|
@@ -0,0 +1,47 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"provided_snapshot": {
|
| 3 |
+
"source": "User-provided screenshot",
|
| 4 |
+
"raw_requests_independently_verified": false,
|
| 5 |
+
"concurrency": null,
|
| 6 |
+
"reported_model": "APUS-OpenJev 9B-5949",
|
| 7 |
+
"p50_ms": 25.58,
|
| 8 |
+
"p95_ms": 222.36,
|
| 9 |
+
"p99_ms": 275.58,
|
| 10 |
+
"successful": 333,
|
| 11 |
+
"requests": 333,
|
| 12 |
+
"error_rate": 0
|
| 13 |
+
},
|
| 14 |
+
"verified_reference": {
|
| 15 |
+
"source": "feat-jev-scale-9b-35b/docs/feat-jev-scale-9b-35b/evidence/vllm-merged-http-20260921/local-verification.json",
|
| 16 |
+
"aggregation": "Median of three per-round percentiles",
|
| 17 |
+
"concurrency": 1,
|
| 18 |
+
"rounds": 3,
|
| 19 |
+
"requests_per_round": 1040,
|
| 20 |
+
"p50_ms": 25.34,
|
| 21 |
+
"p95_ms": 222.83,
|
| 22 |
+
"p99_ms": 276.78,
|
| 23 |
+
"correct": 67,
|
| 24 |
+
"quality_records": 80
|
| 25 |
+
},
|
| 26 |
+
"historical_rows": [
|
| 27 |
+
{
|
| 28 |
+
"name": "APUS-OpenJev 4B",
|
| 29 |
+
"scope": "Local model forward / historical",
|
| 30 |
+
"p50_ms": 85.43,
|
| 31 |
+
"p95_ms": 406.3
|
| 32 |
+
},
|
| 33 |
+
{
|
| 34 |
+
"name": "Jev official API",
|
| 35 |
+
"scope": "Remote HTTP / network + queue + service",
|
| 36 |
+
"p50_ms": 436.96,
|
| 37 |
+
"p95_ms": 4874.61
|
| 38 |
+
},
|
| 39 |
+
{
|
| 40 |
+
"name": "Laya typed / full input",
|
| 41 |
+
"scope": "Local system_one / three-run median",
|
| 42 |
+
"p50_ms": 8.68,
|
| 43 |
+
"p95_ms": 37.66
|
| 44 |
+
}
|
| 45 |
+
],
|
| 46 |
+
"source_search": "No exact 333-request run found in local scale evidence, combined release, or archived loopback/diagnostic-load reports."
|
| 47 |
+
}
|