---
base_model:
- Qwen/Qwen3.5-4B
- Qwen/Qwen3.5-9B
library_name: transformers
language:
- en
- zh
tags:
- decision-model
- dynamic-depth
- structured-output
---
# APUS-OpenJev-v1
Technical Report
**Decision models with selectable compute depth.**
[Model weights](https://huggingface.co/apus-ailab/APUS-OpenJev-v1/tree/main) · [Architecture](ARCHITECTURE.md) · [Evaluation data](https://huggingface.co/datasets/apus-ailab/APUS-OpenJev-Eval-Frozen80)
## 1. Introduction
We introduce **APUS-OpenJev-v1**, a family of decision models for browser agents and business workflows. Given a task, context, and candidate actions, the model returns a scored choice that an application can execute. The family provides 4B and 9B variants with a common decision interface.
**Architecture.** A shared language-model backbone supports multiple compute budgets. Task definitions and candidate meanings arrive through natural language, allowing the same model to handle different decision spaces. Applications select `effort="low"` or `effort="high"` through the included runtime.
**Joint post-training.** Decision learning is coordinated across computation depths. Both execution paths learn from reference decisions, while the complete path supplies a distribution-level learning signal for the shorter path. This trains useful early decisions rather than relying on an untrained intermediate representation. The [architecture guide](ARCHITECTURE.md) explains the design and its trade-offs.
**Decision-oriented inference.** The runtime scores candidate labels and maps them back to application actions. This removes the need to generate a structured answer token by token for bounded-choice tasks. Choose `effort="low"` or `effort="high"` to balance compute cost and decision quality.
On our frozen 80-question development panel, **APUS-OpenJev 9B achieves 85.0% accuracy**, compared with **82.5% for the Jev API**. The optimized 9B decision service reports **25.58 ms median HTTP latency** in the run snapshot below. The 85.0% result uses `9B-3000`; the optimized latency measurement uses `9B-5949`. Accuracy and latency are reported with their evaluation settings below.
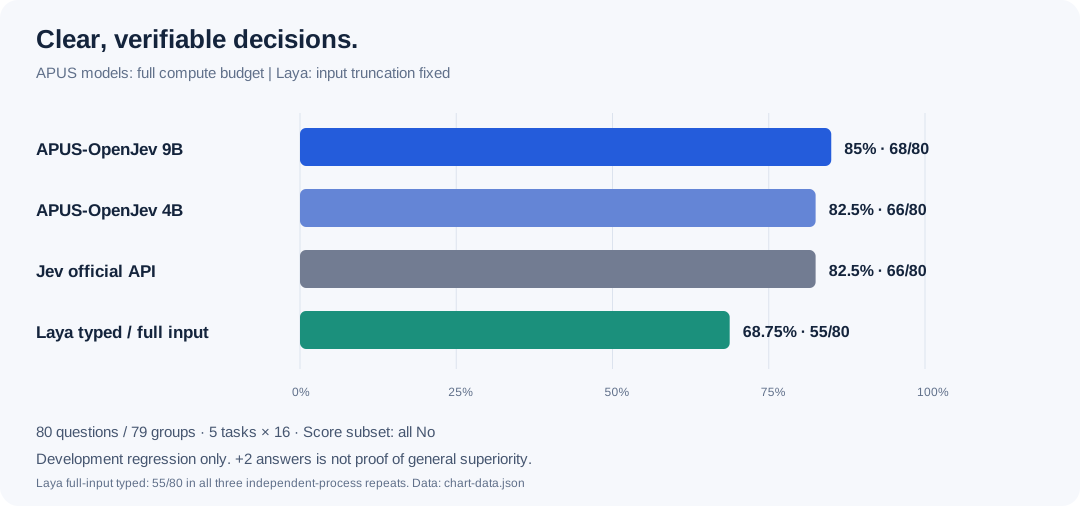
*Figure 1. Same-panel decision accuracy. APUS results use the full compute budget; Laya uses its higher-scoring complete-input configuration after truncation was corrected.*
## 2. Evaluation Results
### Decision quality
| Model | Correct / total | Accuracy |
| --- | ---: | ---: |
| **APUS-OpenJev 9B** | **68 /80** | **85.00%** |
| APUS-OpenJev 4B | 66 /80 | 82.50% |
| Jev API | 66 /80 | 82.50% |
| Laya · typed configuration, complete input | 55 /80 | 68.75% |
All models are compared on the same frozen question identities and reference labels. Laya's complete-input typed configuration reproduces 55/80 across three runs; its complete-input English configuration scores 54/80. Repetition establishes consistency on these questions, not additional independent evidence. The two-question advantage over Jev is a panel result and does not establish broad or statistically significant superiority.
### Results by task
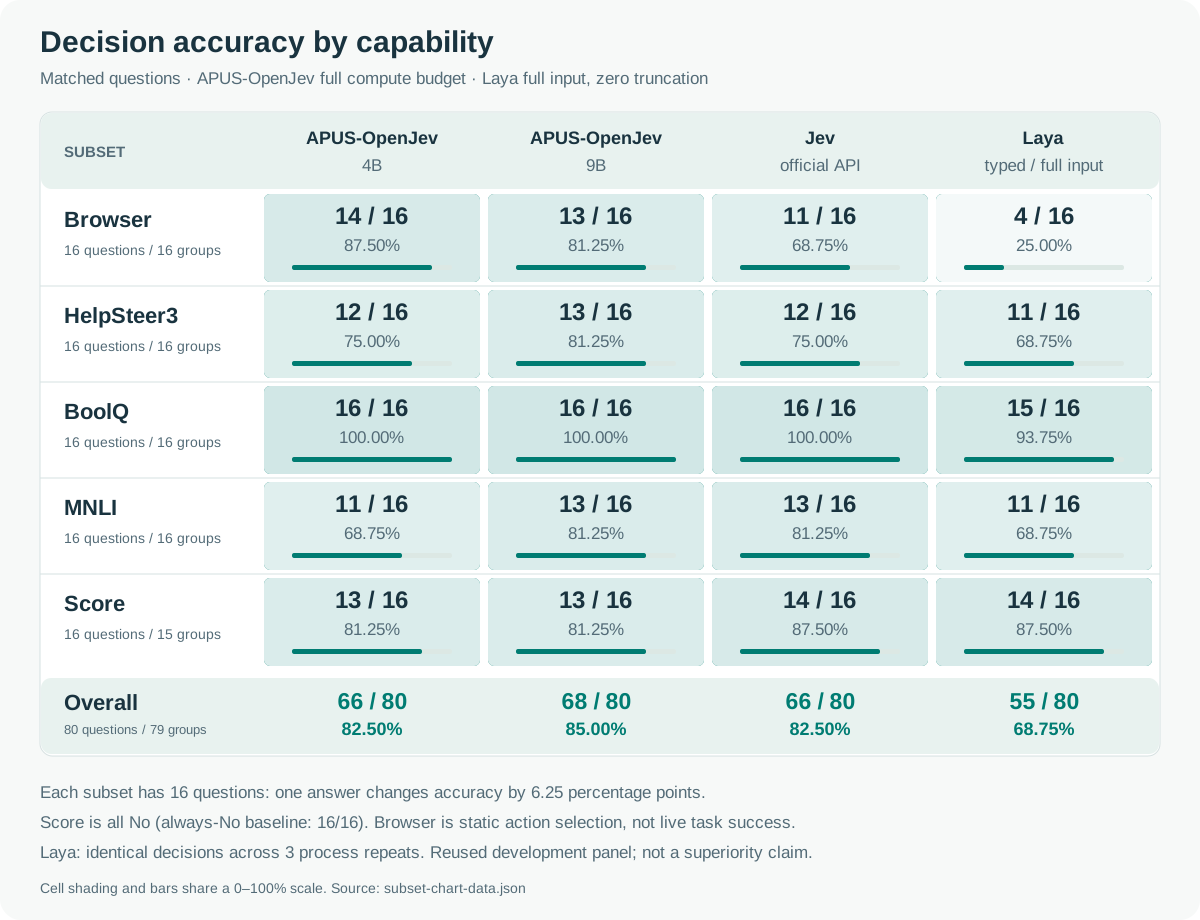
*Figure 2. Correct answers and accuracy for each task family. APUS models use the full compute budget; Laya uses the complete-input typed configuration. Each family contains 16 questions, so one answer changes accuracy by 6.25 percentage points.*
The 4B model leads this panel's Browser subset, while 9B's gains come from principle-based judgments and natural language inference. Laya's corrected Browser result is 4/16. The task breakdown and source hashes are recorded in [subset-chart-data.json](subset-chart-data.json).
### Response latency
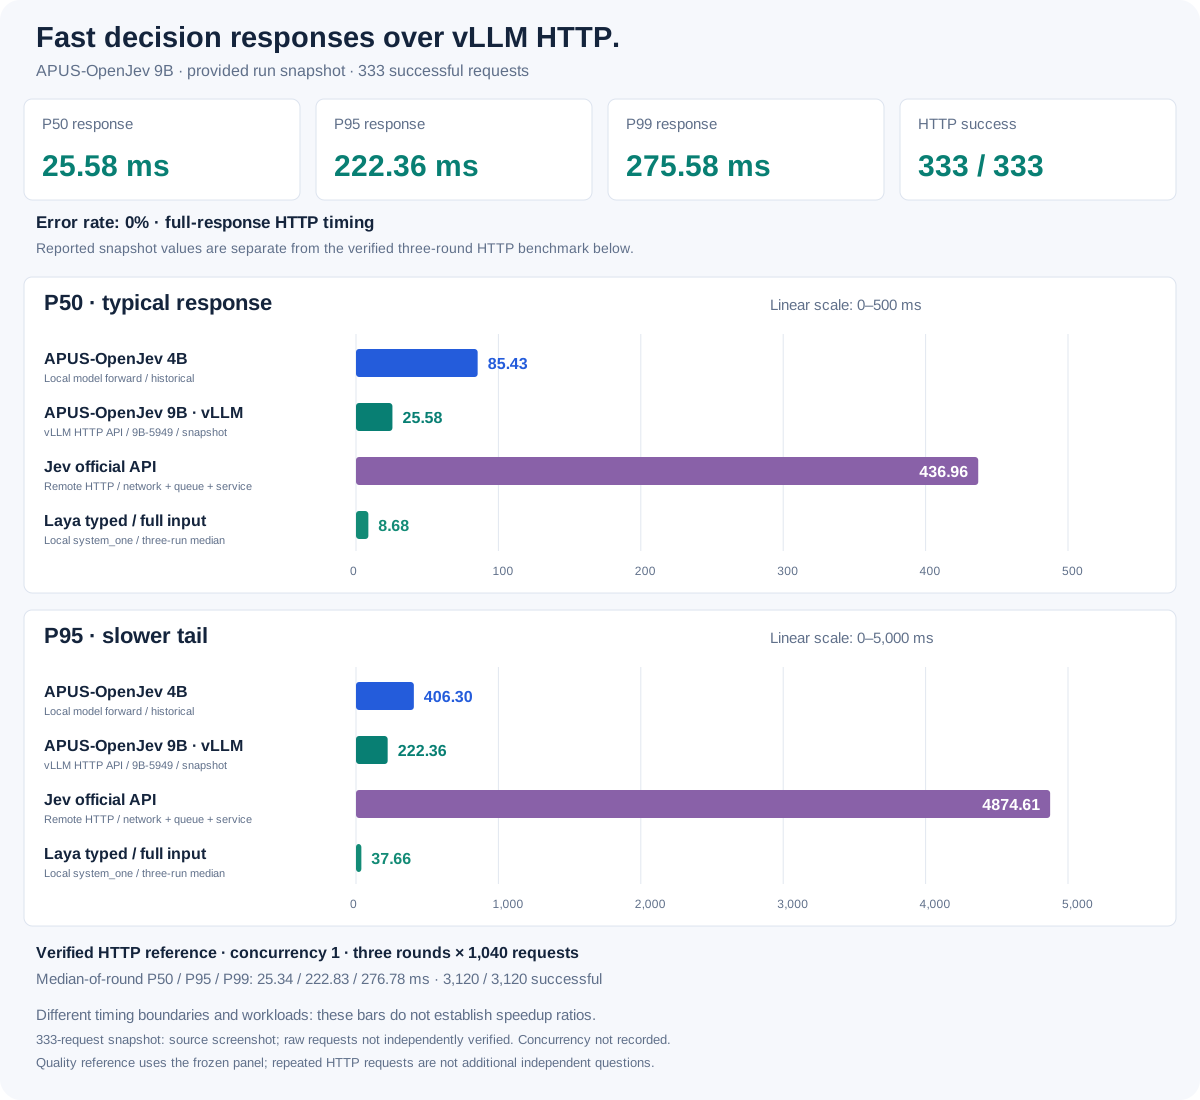
*Figure 3. vLLM HTTP API full-response latency for the optimized decision service. The supplied run snapshot reports 333/333 successful requests and 0% errors. This is full-response latency, not streaming first-token latency.*
| Decision API metric | Run snapshot |
| --- | ---: |
| **P50 latency** | **25.58 ms** |
| P95 latency | 222.36 ms |
| P99 latency | 275.58 ms |
| Successful requests | 333 /333 |
| Error rate | 0% |
The chart distinguishes the supplied 333-request snapshot from the independently archived three-run C1 validation: **25.34 / 222.83 / 276.78 ms** median per-run P50/P95/P99, with **3,120/3,120** successful serial requests on an RTX PRO 6000 96GB. The exact 333-request raw trace is not part of that archive. Accuracy uses 80 fixed questions; replay counts do not increase the number of independent questions.
The optimized path is the candidate-scoring `/decide` service. The standard Chat Completions launcher below has a separate generation path. Historical 4B model-forward, Laya local-pipeline and Jev public-API measurements remain labeled in the chart; different network and processing boundaries do not establish a model speedup ratio. See [measurement sources](latency-vllm-data.json).
### Selectable effort: measured quality–latency trade-off
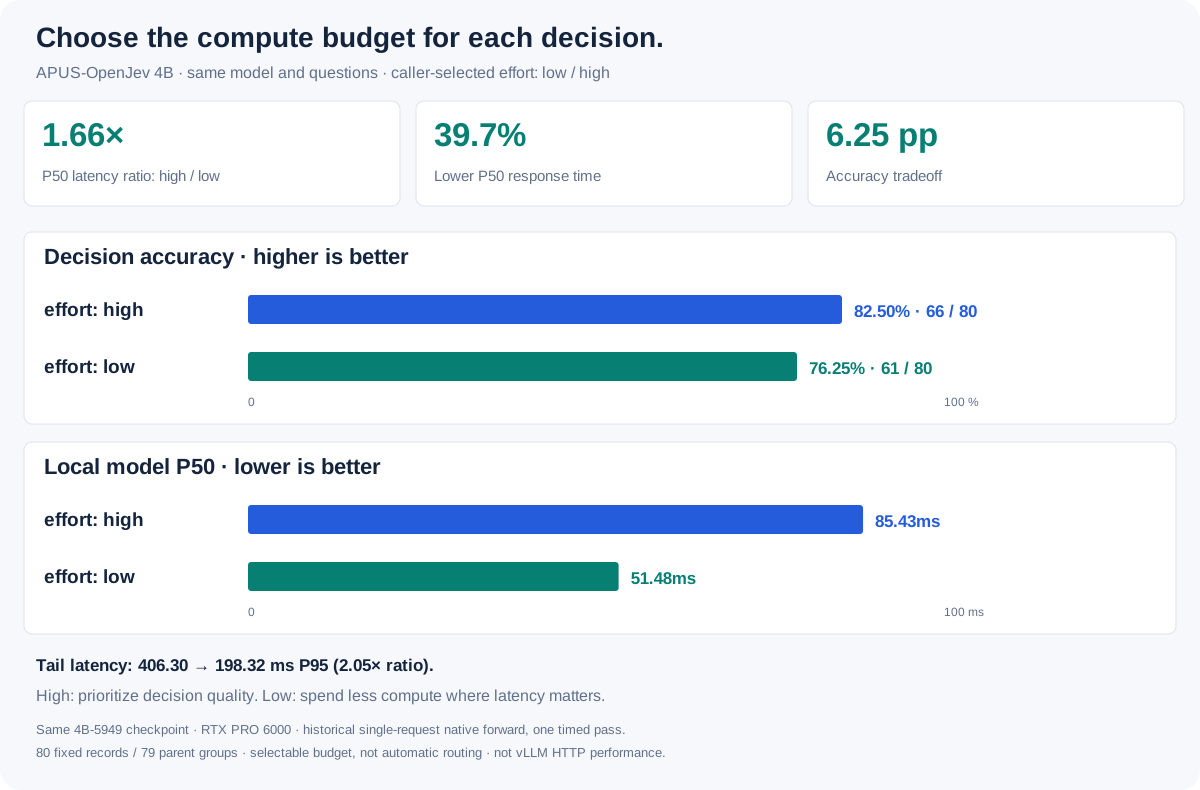
**Around 2× faster at P95, with less than 8% relative accuracy reduction.** On the same 4B checkpoint and frozen panel, selecting `effort="low"` reduces P95 model-forward latency from **406.30 to 198.32 ms**. Accuracy changes from **82.50% to 76.25%**: **6.25 percentage points**, or **7.58% relative**. P50 changes from **85.43 to 51.48 ms**, a **1.66×** speed ratio.
These paired measurements use the native effort runtime. They are separate from the full-depth vLLM Chat API measurements and do not imply a measured vLLM low-effort endpoint. Deployment-specific low/high performance must be measured using the same serving path. See [effort measurement data](effort-tradeoff-data.json).
## 3. Evaluation Set
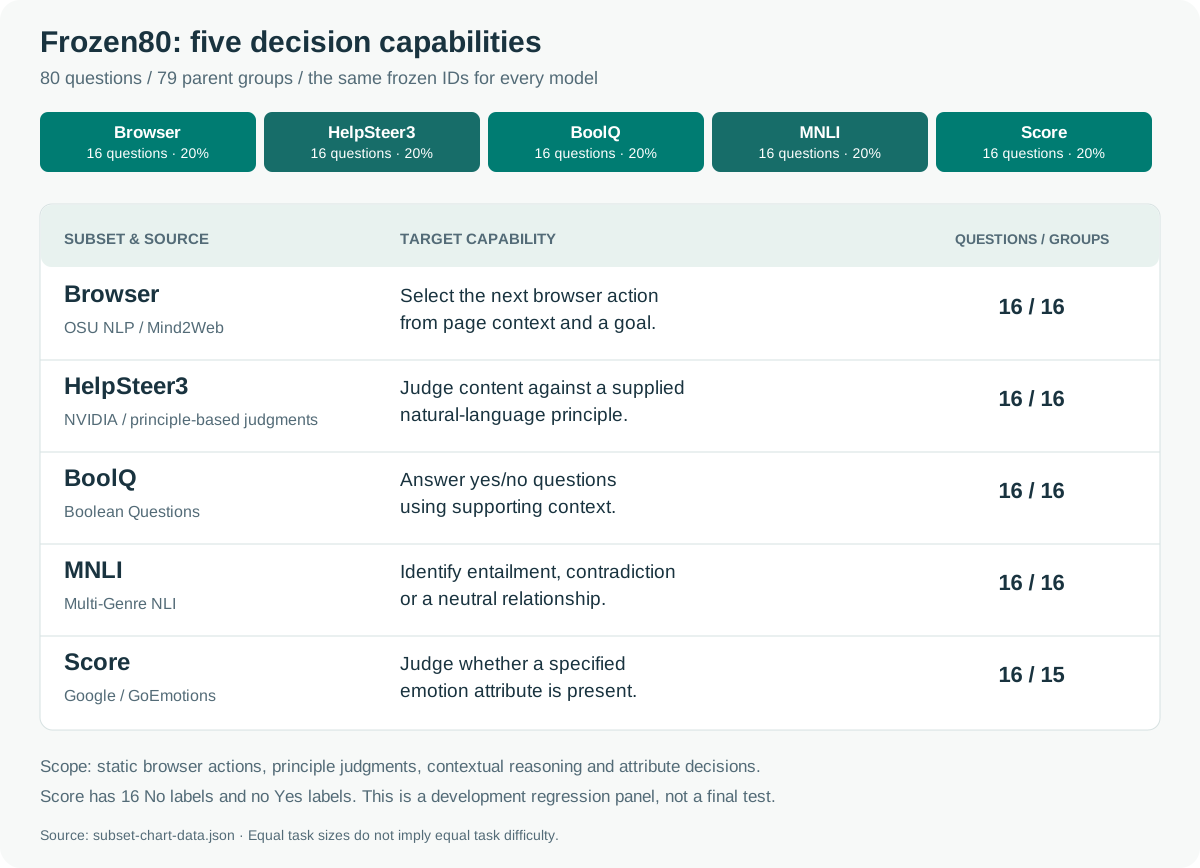
*Figure 4. Dataset composition, source datasets, and target capabilities. Parent groups identify related examples; equal question counts do not imply equal task difficulty or production traffic.*
| Task family | Questions | Decision evaluated |
| --- | ---: | --- |
| Browser / Mind2Web | 16 | Select an action from a static page state |
| HelpSteer3 | 16 | Check a response against a supplied principle |
| BoolQ | 16 | Answer a binary question from evidence |
| MNLI | 16 | Distinguish entailment, neutral, and contradiction |
| Score / GoEmotions | 16 | Judge whether an individual attribute applies |
The panel contains **80 questions from 79 parent groups** and is released as `validation`. It has informed development and model selection. All 16 Score labels are No, so an always-No strategy scores 100% on that subset; these results cannot establish positive-case Score performance. Browser evaluation covers offline action selection, not complete website tasks.
The [dataset](https://huggingface.co/datasets/apus-ailab/APUS-OpenJev-Eval-Frozen80) includes JSONL/Parquet, frozen identifiers, provenance, schema documentation, and verification code. It is a separate private repository with its own access permissions.
## 4. Decision Encoding
A request carries the task, supporting context, and 2–16 candidate descriptions. The runtime assigns request-local short labels, evaluates the legal candidate set, and returns the selected candidate ID with relative scores. Application code assembles the response. Candidate meanings can change between requests without adding a fixed business-category classifier.
A legal output can still be the wrong decision. Candidate probabilities are not calibrated confidence, and business thresholds require validation. See the [runtime contract](9B-3000/RUNTIME.md) for the supported request format.
## 5. Minimal Inference
The repository is a model-family bundle. Choose a subdirectory containing complete BF16 weights and the reference runtime:
| Variant | Model directory | Suggested use |
| --- | --- | --- |
| **9B** | `9B-3000/` | Quality-focused evaluation |
| **4B** | `4B-5949/` | Smaller parameter footprint |
An additional 9B research variant is listed in the [artifact manifest](bundle-manifest.json). Load a model subdirectory, not the repository root.
Use a CUDA-capable PyTorch environment. Select the model directory to download:
```bash
python -m pip install huggingface_hub
hf auth login
hf download apus-ailab/APUS-OpenJev-v1 \
--include "9B-3000/*" --local-dir ./APUS-OpenJev-v1
cd ./APUS-OpenJev-v1/9B-3000
python -m pip install -r requirements.txt
python examples.py . --device cuda:0 --effort high
```
For 4B, download `4B-5949/*` and enter that directory. The included runtime implements the budget control; ordinary Transformers loading does not enable it automatically. Text generation should use `high`. See [inference documentation](9B-3000/RUNTIME.md) and [examples](9B-3000/examples.py).
### Deploy with vLLM
The [single-file launcher](deployment/serve_vllm.py) downloads the merged **9B-5949** weights from **`apus-ailab/APUS-OpenJev-v1`** and starts a standard OpenAI-compatible vLLM server. It resolves the requested revision to a fixed commit before downloading and prints the resolved model identity.
On Linux with Python 3.12 and an NVIDIA GPU with sufficient memory (the existing 9B serving configuration was tested on RTX PRO 6000 96GB):
```bash
python3.12 -m venv .venv
source .venv/bin/activate
pip install vllm==0.29.0 transformers==5.17.0 huggingface-hub==1.32.0 openai==3.16.2 ninja==1.13.2
# Blackwell: use the CUDA 13 compiler used in the GPU verification.
pip install nvidia-cuda-nvcc==13.4.92 nvidia-cuda-crt==13.4.92 nvidia-cuda-cccl==13.3.4.3.1
export CUDA_HOME="$(python -c 'import sysconfig; print(sysconfig.get_path("purelib") + "/nvidia/cu13")')"
export PATH="$CUDA_HOME/bin:$PATH"
"$CUDA_HOME/bin/nvcc" --version
curl -fL https://huggingface.co/apus-ailab/APUS-OpenJev-v1/resolve/main/deployment/serve_vllm.py -o serve_vllm.py
CUDA_VISIBLE_DEVICES=0 python serve_vllm.py
# Optional: --revision <40-character-commit-SHA>
# Inspect the command without downloading or using a GPU:
# python serve_vllm.py --dry-run
```
The first launch downloads approximately 18 GB and compiles GPU kernels; allow several minutes before sending requests. Check readiness with `curl -f http://127.0.0.1:8000/health`.
In a second terminal using the same environment:
```python
from openai import OpenAI
client = OpenAI(base_url="http://127.0.0.1:8000/v1", api_key="local")
response = client.chat.completions.create(
model="APUS-OpenJev-v1-9B",
messages=[{"role": "user", "content":
"Task: find the shipping policy. Choose one visible link: "
"A: Shipping and returns. B: Add to cart. C: Sign in. "
"Reply with only A, B, or C."}],
temperature=0,
max_tokens=16,
extra_body={"chat_template_kwargs": {"enable_thinking": False}},
)
print(response.choices[0].message.content) # A
```
Keep `enable_thinking=False` for these short decision outputs. The original example without this setting reached its 16-token limit before producing a decision; the corrected example returned `A` in the real GPU check.
**GPU verification:** anonymous download from this public repository into a fresh cache, followed by 240/240 successful Chat Completions requests (80 fixed questions replayed three times), with no invalid answers or truncated completions. Local HTTP P50/P95/P99: **45.47 / 191.36 / 232.29 ms**. Test environment: Linux, Python 3.12.3, RTX PRO 6000 Blackwell 96GB, vLLM 0.29.0, PyTorch 2.13.0, Transformers 5.17.0, and the CUDA 13 compiler specified above. This reused an installed Python environment; a clean OS installation was not tested.
This example returns standard chat-completion text through `choices[0].message.content`. It demonstrates **full-depth text serving**, not the specialized candidate-probability `/decide` gateway or `effort` routing. It does not enforce the three candidate labels; application-specific decision serving requires the corresponding prompt/compiler and output constraints. The server binds to localhost by default. Blackwell JIT compilation requires a compatible CUDA toolchain; the launcher disables the FlashInfer sampler as in the tested engine configuration.
## 6. Reproducing the Evaluation
Use the fixed dataset revision `7e85bf96455a3be04c5570a4801e9531b1bc5274`, preserve question and candidate order, and record the model revision, runtime, dtype, and compute budget. Keep reference labels out of the model input. Report decision accuracy separately from latency, and state precisely where timing starts and ends.
The release records fixed source revisions and per-file hashes. Model files were downloaded and verified, with GPU checks on the source packages; this family bundle preserves those model bytes. Subsequent model-card changes do not represent new training or evaluation. Detailed merge results and diagnostic examples remain in the [9B evaluation records](9B-3000/merged-evaluation.json) and [4B evaluation records](4B-5949/merged-evaluation.json). BF16 merging changed some candidate probabilities, so calibration and routing thresholds must be revalidated.
## 7. License
Original APUS-OpenJev-v1 code and documentation contributed in this release are licensed under the [MIT License](LICENSE). Qwen-derived model weights and inherited code retain their applicable [Apache 2.0 license and notices](9B-3000/LICENSE); see the [license scope](LICENSE_NOTICES.md) for all variants. Dataset licenses are documented separately.
## 8. Citation
```bibtex
@misc{apusopenjev2026,
title = {APUS-OpenJev-v1: Decision Models with Selectable Compute Depth},
author = {gumpcheng and zhangxu and {APUS AI-LAB}},
year = {2026},
url = {https://huggingface.co/apus-ailab/APUS-OpenJev-v1}
}
```
## 9. Contact
Visit the [APUS official website](https://www.apusai.com) or [APUS AI Lab on Hugging Face](https://huggingface.co/apus-ailab). For model questions and feedback, open a discussion in this model repository's [Community tab](https://huggingface.co/apus-ailab/APUS-OpenJev-v1/discussions).
**Authors:** gumpcheng ([https://huggingface.co/xDAN2099](https://huggingface.co/xDAN2099)), zhangxu, [APUS AI-LAB](https://github.com/APUS-AI-Lab).