

Release Jev-Style-0.8B-Decision-v3
Browse files- .gitattributes +6 -0
- Jev-Style-0.8B-Decision-v3-F16.gguf +3 -0
- Jev-Style-0.8B-Decision-v3-Q4_K_M.gguf +3 -0
- Jev-Style-0.8B-Decision-v3-Q8_0.gguf +3 -0
- LICENSE +202 -0
- NOTICE +35 -0
- README.md +138 -0
- build_jev_score.sh +27 -0
- figures/latency.data.json +51 -0
- figures/latency.png +3 -0
- figures/latency.svg +447 -0
- figures/quantization.data.json +151 -0
- figures/quantization.png +3 -0
- figures/quantization.svg +471 -0
- jev_score.cpp +367 -0
- jev_style_decision_gguf.py +552 -0
- manifest.json +89 -0
- readout_config.json +247 -0
- release_config.json +425 -0
- requirements.txt +4 -0
- tokenizer/tokenizer.json +3 -0
- tokenizer/tokenizer_config.json +32 -0
.gitattributes
CHANGED
|
@@ -33,3 +33,9 @@ saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
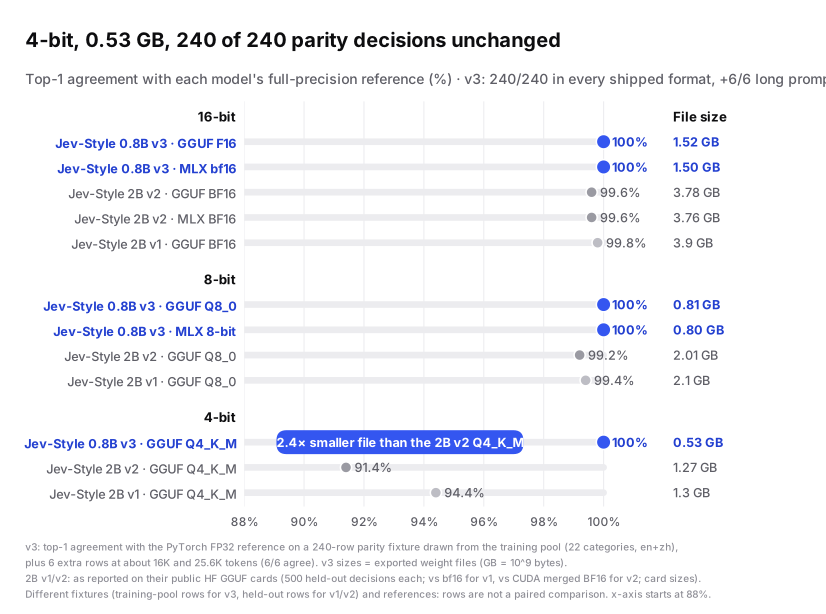
|
|
|
|
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
Jev-Style-0.8B-Decision-v3-F16.gguf filter=lfs diff=lfs merge=lfs -text
|
| 37 |
+
Jev-Style-0.8B-Decision-v3-Q4_K_M.gguf filter=lfs diff=lfs merge=lfs -text
|
| 38 |
+
Jev-Style-0.8B-Decision-v3-Q8_0.gguf filter=lfs diff=lfs merge=lfs -text
|
| 39 |
+
figures/latency.png filter=lfs diff=lfs merge=lfs -text
|
| 40 |
+
figures/quantization.png filter=lfs diff=lfs merge=lfs -text
|
| 41 |
+
tokenizer/tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
Jev-Style-0.8B-Decision-v3-F16.gguf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:a33f709e10009c3fe182b51e4945d440288b137a35ad5d481e4ac1f2800b1a27
|
| 3 |
+
size 1516744160
|
Jev-Style-0.8B-Decision-v3-Q4_K_M.gguf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:0a19bc29bacc33e0d871146c8612b24dd14c2ed2e61cedeb7a928b0852628bac
|
| 3 |
+
size 529296864
|
Jev-Style-0.8B-Decision-v3-Q8_0.gguf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:cd87d284c4ee355cb0b3fce7391db57ba3ad108e45b3a41b058d529931a2bd5e
|
| 3 |
+
size 811843040
|
LICENSE
ADDED
|
@@ -0,0 +1,202 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
|
| 2 |
+
Apache License
|
| 3 |
+
Version 2.0, January 2004
|
| 4 |
+
http://www.apache.org/licenses/
|
| 5 |
+
|
| 6 |
+
TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
|
| 7 |
+
|
| 8 |
+
1. Definitions.
|
| 9 |
+
|
| 10 |
+
"License" shall mean the terms and conditions for use, reproduction,
|
| 11 |
+
and distribution as defined by Sections 1 through 9 of this document.
|
| 12 |
+
|
| 13 |
+
"Licensor" shall mean the copyright owner or entity authorized by
|
| 14 |
+
the copyright owner that is granting the License.
|
| 15 |
+
|
| 16 |
+
"Legal Entity" shall mean the union of the acting entity and all
|
| 17 |
+
other entities that control, are controlled by, or are under common
|
| 18 |
+
control with that entity. For the purposes of this definition,
|
| 19 |
+
"control" means (i) the power, direct or indirect, to cause the
|
| 20 |
+
direction or management of such entity, whether by contract or
|
| 21 |
+
otherwise, or (ii) ownership of fifty percent (50%) or more of the
|
| 22 |
+
outstanding shares, or (iii) beneficial ownership of such entity.
|
| 23 |
+
|
| 24 |
+
"You" (or "Your") shall mean an individual or Legal Entity
|
| 25 |
+
exercising permissions granted by this License.
|
| 26 |
+
|
| 27 |
+
"Source" form shall mean the preferred form for making modifications,
|
| 28 |
+
including but not limited to software source code, documentation
|
| 29 |
+
source, and configuration files.
|
| 30 |
+
|
| 31 |
+
"Object" form shall mean any form resulting from mechanical
|
| 32 |
+
transformation or translation of a Source form, including but
|
| 33 |
+
not limited to compiled object code, generated documentation,
|
| 34 |
+
and conversions to other media types.
|
| 35 |
+
|
| 36 |
+
"Work" shall mean the work of authorship, whether in Source or
|
| 37 |
+
Object form, made available under the License, as indicated by a
|
| 38 |
+
copyright notice that is included in or attached to the work
|
| 39 |
+
(an example is provided in the Appendix below).
|
| 40 |
+
|
| 41 |
+
"Derivative Works" shall mean any work, whether in Source or Object
|
| 42 |
+
form, that is based on (or derived from) the Work and for which the
|
| 43 |
+
editorial revisions, annotations, elaborations, or other modifications
|
| 44 |
+
represent, as a whole, an original work of authorship. For the purposes
|
| 45 |
+
of this License, Derivative Works shall not include works that remain
|
| 46 |
+
separable from, or merely link (or bind by name) to the interfaces of,
|
| 47 |
+
the Work and Derivative Works thereof.
|
| 48 |
+
|
| 49 |
+
"Contribution" shall mean any work of authorship, including
|
| 50 |
+
the original version of the Work and any modifications or additions
|
| 51 |
+
to that Work or Derivative Works thereof, that is intentionally
|
| 52 |
+
submitted to Licensor for inclusion in the Work by the copyright owner
|
| 53 |
+
or by an individual or Legal Entity authorized to submit on behalf of
|
| 54 |
+
the copyright owner. For the purposes of this definition, "submitted"
|
| 55 |
+
means any form of electronic, verbal, or written communication sent
|
| 56 |
+
to the Licensor or its representatives, including but not limited to
|
| 57 |
+
communication on electronic mailing lists, source code control systems,
|
| 58 |
+
and issue tracking systems that are managed by, or on behalf of, the
|
| 59 |
+
Licensor for the purpose of discussing and improving the Work, but
|
| 60 |
+
excluding communication that is conspicuously marked or otherwise
|
| 61 |
+
designated in writing by the copyright owner as "Not a Contribution."
|
| 62 |
+
|
| 63 |
+
"Contributor" shall mean Licensor and any individual or Legal Entity
|
| 64 |
+
on behalf of whom a Contribution has been received by Licensor and
|
| 65 |
+
subsequently incorporated within the Work.
|
| 66 |
+
|
| 67 |
+
2. Grant of Copyright License. Subject to the terms and conditions of
|
| 68 |
+
this License, each Contributor hereby grants to You a perpetual,
|
| 69 |
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
| 70 |
+
copyright license to reproduce, prepare Derivative Works of,
|
| 71 |
+
publicly display, publicly perform, sublicense, and distribute the
|
| 72 |
+
Work and such Derivative Works in Source or Object form.
|
| 73 |
+
|
| 74 |
+
3. Grant of Patent License. Subject to the terms and conditions of
|
| 75 |
+
this License, each Contributor hereby grants to You a perpetual,
|
| 76 |
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
| 77 |
+
(except as stated in this section) patent license to make, have made,
|
| 78 |
+
use, offer to sell, sell, import, and otherwise transfer the Work,
|
| 79 |
+
where such license applies only to those patent claims licensable
|
| 80 |
+
by such Contributor that are necessarily infringed by their
|
| 81 |
+
Contribution(s) alone or by combination of their Contribution(s)
|
| 82 |
+
with the Work to which such Contribution(s) was submitted. If You
|
| 83 |
+
institute patent litigation against any entity (including a
|
| 84 |
+
cross-claim or counterclaim in a lawsuit) alleging that the Work
|
| 85 |
+
or a Contribution incorporated within the Work constitutes direct
|
| 86 |
+
or contributory patent infringement, then any patent licenses
|
| 87 |
+
granted to You under this License for that Work shall terminate
|
| 88 |
+
as of the date such litigation is filed.
|
| 89 |
+
|
| 90 |
+
4. Redistribution. You may reproduce and distribute copies of the
|
| 91 |
+
Work or Derivative Works thereof in any medium, with or without
|
| 92 |
+
modifications, and in Source or Object form, provided that You
|
| 93 |
+
meet the following conditions:
|
| 94 |
+
|
| 95 |
+
(a) You must give any other recipients of the Work or
|
| 96 |
+
Derivative Works a copy of this License; and
|
| 97 |
+
|
| 98 |
+
(b) You must cause any modified files to carry prominent notices
|
| 99 |
+
stating that You changed the files; and
|
| 100 |
+
|
| 101 |
+
(c) You must retain, in the Source form of any Derivative Works
|
| 102 |
+
that You distribute, all copyright, patent, trademark, and
|
| 103 |
+
attribution notices from the Source form of the Work,
|
| 104 |
+
excluding those notices that do not pertain to any part of
|
| 105 |
+
the Derivative Works; and
|
| 106 |
+
|
| 107 |
+
(d) If the Work includes a "NOTICE" text file as part of its
|
| 108 |
+
distribution, then any Derivative Works that You distribute must
|
| 109 |
+
include a readable copy of the attribution notices contained
|
| 110 |
+
within such NOTICE file, excluding those notices that do not
|
| 111 |
+
pertain to any part of the Derivative Works, in at least one
|
| 112 |
+
of the following places: within a NOTICE text file distributed
|
| 113 |
+
as part of the Derivative Works; within the Source form or
|
| 114 |
+
documentation, if provided along with the Derivative Works; or,
|
| 115 |
+
within a display generated by the Derivative Works, if and
|
| 116 |
+
wherever such third-party notices normally appear. The contents
|
| 117 |
+
of the NOTICE file are for informational purposes only and
|
| 118 |
+
do not modify the License. You may add Your own attribution
|
| 119 |
+
notices within Derivative Works that You distribute, alongside
|
| 120 |
+
or as an addendum to the NOTICE text from the Work, provided
|
| 121 |
+
that such additional attribution notices cannot be construed
|
| 122 |
+
as modifying the License.
|
| 123 |
+
|
| 124 |
+
You may add Your own copyright statement to Your modifications and
|
| 125 |
+
may provide additional or different license terms and conditions
|
| 126 |
+
for use, reproduction, or distribution of Your modifications, or
|
| 127 |
+
for any such Derivative Works as a whole, provided Your use,
|
| 128 |
+
reproduction, and distribution of the Work otherwise complies with
|
| 129 |
+
the conditions stated in this License.
|
| 130 |
+
|
| 131 |
+
5. Submission of Contributions. Unless You explicitly state otherwise,
|
| 132 |
+
any Contribution intentionally submitted for inclusion in the Work
|
| 133 |
+
by You to the Licensor shall be under the terms and conditions of
|
| 134 |
+
this License, without any additional terms or conditions.
|
| 135 |
+
Notwithstanding the above, nothing herein shall supersede or modify
|
| 136 |
+
the terms of any separate license agreement you may have executed
|
| 137 |
+
with Licensor regarding such Contributions.
|
| 138 |
+
|
| 139 |
+
6. Trademarks. This License does not grant permission to use the trade
|
| 140 |
+
names, trademarks, service marks, or product names of the Licensor,
|
| 141 |
+
except as required for reasonable and customary use in describing the
|
| 142 |
+
origin of the Work and reproducing the content of the NOTICE file.
|
| 143 |
+
|
| 144 |
+
7. Disclaimer of Warranty. Unless required by applicable law or
|
| 145 |
+
agreed to in writing, Licensor provides the Work (and each
|
| 146 |
+
Contributor provides its Contributions) on an "AS IS" BASIS,
|
| 147 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
|
| 148 |
+
implied, including, without limitation, any warranties or conditions
|
| 149 |
+
of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
|
| 150 |
+
PARTICULAR PURPOSE. You are solely responsible for determining the
|
| 151 |
+
appropriateness of using or redistributing the Work and assume any
|
| 152 |
+
risks associated with Your exercise of permissions under this License.
|
| 153 |
+
|
| 154 |
+
8. Limitation of Liability. In no event and under no legal theory,
|
| 155 |
+
whether in tort (including negligence), contract, or otherwise,
|
| 156 |
+
unless required by applicable law (such as deliberate and grossly
|
| 157 |
+
negligent acts) or agreed to in writing, shall any Contributor be
|
| 158 |
+
liable to You for damages, including any direct, indirect, special,
|
| 159 |
+
incidental, or consequential damages of any character arising as a
|
| 160 |
+
result of this License or out of the use or inability to use the
|
| 161 |
+
Work (including but not limited to damages for loss of goodwill,
|
| 162 |
+
work stoppage, computer failure or malfunction, or any and all
|
| 163 |
+
other commercial damages or losses), even if such Contributor
|
| 164 |
+
has been advised of the possibility of such damages.
|
| 165 |
+
|
| 166 |
+
9. Accepting Warranty or Additional Liability. While redistributing
|
| 167 |
+
the Work or Derivative Works thereof, You may choose to offer,
|
| 168 |
+
and charge a fee for, acceptance of support, warranty, indemnity,
|
| 169 |
+
or other liability obligations and/or rights consistent with this
|
| 170 |
+
License. However, in accepting such obligations, You may act only
|
| 171 |
+
on Your own behalf and on Your sole responsibility, not on behalf
|
| 172 |
+
of any other Contributor, and only if You agree to indemnify,
|
| 173 |
+
defend, and hold each Contributor harmless for any liability
|
| 174 |
+
incurred by, or claims asserted against, such Contributor by reason
|
| 175 |
+
of your accepting any such warranty or additional liability.
|
| 176 |
+
|
| 177 |
+
END OF TERMS AND CONDITIONS
|
| 178 |
+
|
| 179 |
+
APPENDIX: How to apply the Apache License to your work.
|
| 180 |
+
|
| 181 |
+
To apply the Apache License to your work, attach the following
|
| 182 |
+
boilerplate notice, with the fields enclosed by brackets "[]"
|
| 183 |
+
replaced with your own identifying information. (Don't include
|
| 184 |
+
the brackets!) The text should be enclosed in the appropriate
|
| 185 |
+
comment syntax for the file format. We also recommend that a
|
| 186 |
+
file or class name and description of purpose be included on the
|
| 187 |
+
same "printed page" as the copyright notice for easier
|
| 188 |
+
identification within third-party archives.
|
| 189 |
+
|
| 190 |
+
Copyright 2026 Alibaba Cloud
|
| 191 |
+
|
| 192 |
+
Licensed under the Apache License, Version 2.0 (the "License");
|
| 193 |
+
you may not use this file except in compliance with the License.
|
| 194 |
+
You may obtain a copy of the License at
|
| 195 |
+
|
| 196 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 197 |
+
|
| 198 |
+
Unless required by applicable law or agreed to in writing, software
|
| 199 |
+
distributed under the License is distributed on an "AS IS" BASIS,
|
| 200 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 201 |
+
See the License for the specific language governing permissions and
|
| 202 |
+
limitations under the License.
|
NOTICE
ADDED
|
@@ -0,0 +1,35 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
chaoliangUNSW/Jev-Style-0.8B-Decision-v3-GGUF
|
| 2 |
+
Copyright 2026 chaoliangUNSW. Licensed under the Apache License, Version 2.0 (see LICENSE).
|
| 3 |
+
|
| 4 |
+
This model is a fine-tuned derivative of Qwen3.5-0.8B (https://huggingface.co/Qwen/Qwen3.5-0.8B,
|
| 5 |
+
revision 2fc06364715b967f1860aea9cf38778875588b17), Copyright 2026 Alibaba Cloud, licensed under the Apache
|
| 6 |
+
License, Version 2.0. The LICENSE file in this repository is the license file distributed with Qwen3.5-0.8B.
|
| 7 |
+
|
| 8 |
+
Modifications relative to Qwen3.5-0.8B:
|
| 9 |
+
- all text-model weights were fine-tuned (full fine-tuning, bf16 training) to score typed decision questions
|
| 10 |
+
(choice / score / true-false) with a verdict readout: logit(" yes") - logit(" no") at one " ->" slot per
|
| 11 |
+
option; calibration temperatures were fitted afterwards (readout_config.json);
|
| 12 |
+
- the vision tower (model.visual.*) and the multi-token-prediction head (mtp.*) were removed; the checkpoint
|
| 13 |
+
is a text-only Qwen3_5ForCausalLM with tied input/output embeddings;
|
| 14 |
+
- converted to GGUF (F16) and quantised (Q8_0, Q4_K_M) with the unmodified llama.cpp tools
|
| 15 |
+
(https://github.com/ggml-org/llama.cpp, MIT License, Copyright The ggml authors), commit 441df11f65ea0b6d0c72965aaf70c8241070ddcb;
|
| 16 |
+
- the GGUF metadata field general.name was set to "Jev-Style-0.8B-Decision-v3" with gguf-py (llama.cpp,
|
| 17 |
+
gguf_new_metadata.py); tensor data unchanged;
|
| 18 |
+
- added the runtime script, readout/release configuration files, the integrity manifest and this NOTICE.
|
| 19 |
+
|
| 20 |
+
jev_score.cpp is original code of this project released under Apache-2.0. It is compiled against
|
| 21 |
+
libllama and uses nlohmann/json (MIT) from llama.cpp's vendor directory at build time; neither
|
| 22 |
+
library is redistributed in this repository.
|
| 23 |
+
|
| 24 |
+
The question types (choice / score / noul) follow the typed-decision convention of Laya
|
| 25 |
+
(https://github.com/NandhaKishorM/laya, Apache-2.0) so both models can be evaluated on the same
|
| 26 |
+
inputs. No Laya code or weights are included.
|
| 27 |
+
|
| 28 |
+
Third generation (v3) of the Jev-Style decision series. Earlier generations: v1 =
|
| 29 |
+
chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision (public GGUF release: chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision-GGUF) and
|
| 30 |
+
v2 = chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision-v2, both 2B models built on Qwen3.5-2B-Base. v3 is fine-tuned from
|
| 31 |
+
Qwen3.5-0.8B; no weights of v1 or v2 were reused.
|
| 32 |
+
|
| 33 |
+
Not affiliated with, endorsed by or connected to TypeSafe or Jev. "Jev-Style" only describes the kind
|
| 34 |
+
of model (a small typed-decision model in a similar style); no Jev weights, code or outputs are included.
|
| 35 |
+
Not affiliated with or endorsed by Alibaba Cloud / the Qwen team or the Laya authors.
|
README.md
ADDED
|
@@ -0,0 +1,138 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: apache-2.0
|
| 3 |
+
base_model: chaoliangUNSW/Jev-Style-0.8B-Decision-v3
|
| 4 |
+
base_model_relation: quantized
|
| 5 |
+
library_name: gguf
|
| 6 |
+
pipeline_tag: text-classification
|
| 7 |
+
language:
|
| 8 |
+
- en
|
| 9 |
+
- zh
|
| 10 |
+
- ar
|
| 11 |
+
- bg
|
| 12 |
+
- de
|
| 13 |
+
- el
|
| 14 |
+
- es
|
| 15 |
+
- fr
|
| 16 |
+
- hi
|
| 17 |
+
- ja
|
| 18 |
+
- ko
|
| 19 |
+
- pt
|
| 20 |
+
- ru
|
| 21 |
+
- sw
|
| 22 |
+
- ta
|
| 23 |
+
- th
|
| 24 |
+
- tr
|
| 25 |
+
- ur
|
| 26 |
+
- vi
|
| 27 |
+
tags:
|
| 28 |
+
- decision-model
|
| 29 |
+
- jev-style
|
| 30 |
+
- system-one
|
| 31 |
+
- calibration
|
| 32 |
+
- long-context
|
| 33 |
+
- multilingual
|
| 34 |
+
- qwen3.5
|
| 35 |
+
- gguf
|
| 36 |
+
- llama.cpp
|
| 37 |
+
---
|
| 38 |
+
|
| 39 |
+
# Jev-Style-0.8B-Decision-v3-GGUF
|
| 40 |
+
|
| 41 |
+
**Jev-Style decision series:** [v1 · 2B](https://huggingface.co/chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision-GGUF) → [v2 · 2B](https://huggingface.co/chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision-v2-GGUF) → **v3 · 0.8B** · **Website:** [jevstyle.com](https://jevstyle.com)
|
| 42 |
+
|
| 43 |
+
These are the GGUF builds of [Jev-Style-0.8B-Decision-v3](https://huggingface.co/chaoliangUNSW/Jev-Style-0.8B-Decision-v3).
|
| 44 |
+
**One state. One pass. Every option scored.** The model takes up to 25,600 tokens of input, reads the state once and returns a calibrated
|
| 45 |
+
probability for every option of every question, with no letter cap. **Full results, protocols, training data and
|
| 46 |
+
licences are on the [main model card](https://huggingface.co/chaoliangUNSW/Jev-Style-0.8B-Decision-v3).**
|
| 47 |
+
|
| 48 |
+
## Files
|
| 49 |
+
|
| 50 |
+
| File | Quantization | Size | Same decision as PyTorch FP32 (240 parity rows) | Prompts of about 16K / 25.6K tokens |
|
| 51 |
+
|---|---|---:|---:|---:|
|
| 52 |
+
| `Jev-Style-0.8B-Decision-v3-F16.gguf` | F16 | 1.52 GB | **240 / 240** | **6 / 6** |
|
| 53 |
+
| `Jev-Style-0.8B-Decision-v3-Q8_0.gguf` | Q8_0 | 0.81 GB | **240 / 240** | **6 / 6** |
|
| 54 |
+
| `Jev-Style-0.8B-Decision-v3-Q4_K_M.gguf` | Q4_K_M | 0.53 GB | **240 / 240** | **6 / 6** |
|
| 55 |
+
|
| 56 |
+
<sub>Top-1 agreement with the PyTorch FP32 reference on a 240-row mixed parity fixture (training-pool rows, 22 categories, English and Chinese) plus 6 extra long prompts. These rows test agreement between formats, not accuracy. Sizes are the exported files (GB = 10^9 bytes). F16 is the runtime's default and the backend used for the latency figures.</sub>
|
| 57 |
+
|
| 58 |
+
## Highlights
|
| 59 |
+
|
| 60 |
+
- **4-bit, 0.53 GB, same calls.** The Q4_K_M file matches PyTorch FP32 on 240 of 240 parity rows, plus 6 of 6
|
| 61 |
+
prompts at about 16K and 25.6K tokens, and it is about 2.4× smaller than the 2B v2's Q4_K_M (1.27 GB).
|
| 62 |
+
- **Up to 4.6× faster than a Laya-architecture engine when 10 questions share one 4K-token state** (1,381 ms vs
|
| 63 |
+
6,364 ms with `many_mode="batched"`; the engine is our round-1 MacLaya-4K, one call per question, not an official
|
| 64 |
+
Laya checkpoint), because in that mode the bundled scorer reads the state once. It also answers questions about 8K-token states in 2.3 to 2.6 s.
|
| 65 |
+
- **79.2% on 2,000 typed decisions**, +6.4 points over Jev and +5.7 over the 2B v2, with a 3.2× lower Brier score
|
| 66 |
+
than Jev (in-domain for v3, zero-shot for Jev).
|
| 67 |
+
|
| 68 |
+

|
| 69 |
+
|
| 70 |
+

|
| 71 |
+
|
| 72 |
+
<sub>Latency: untrained identical-architecture Qwen3.5-0.8B export on llama.cpp GGUF F16, one call per state with all questions scored together (`many_mode="batched"`); comparison engine = round-1 MacLaya-4K, our own fine-tune of the Laya multilingual architecture (FP32 on Apple MPS, 4,096-token budget, one call per question), not an official Laya checkpoint; Apple M1 Max 64 GB, warm p50, idle run 2026-09-23. v3 parity rows are drawn from the training pool; 2B v1/v2 quantization numbers and sizes are as reported on their public GGUF cards (their own 500 held-out decisions), so no agreement gap is claimed. More protocol detail is on the main card.</sub>
|
| 73 |
+
|
| 74 |
+
## Quick start
|
| 75 |
+
|
| 76 |
+
The files are standard Qwen3.5 text models, so any recent llama.cpp loads them. Chat or text generation does
|
| 77 |
+
**not** give you the model's decisions, though. Decisions are read at one verdict slot per option, and the bundled
|
| 78 |
+
scorer does exactly that.
|
| 79 |
+
|
| 80 |
+
```bash
|
| 81 |
+
pip install -U huggingface_hub
|
| 82 |
+
hf download chaoliangUNSW/Jev-Style-0.8B-Decision-v3-GGUF --local-dir jev-v3-gguf
|
| 83 |
+
cd jev-v3-gguf
|
| 84 |
+
pip install -r requirements.txt # tokenizers, numpy
|
| 85 |
+
|
| 86 |
+
# Build the scorer against llama.cpp (tested at commit 441df11f65ea0b6d0c72965aaf70c8241070ddcb or later).
|
| 87 |
+
git clone https://github.com/ggml-org/llama.cpp
|
| 88 |
+
git -C llama.cpp checkout 441df11f65ea0b6d0c72965aaf70c8241070ddcb
|
| 89 |
+
sh build_jev_score.sh llama.cpp # -> ./build/jev-score (Metal on macOS)
|
| 90 |
+
# Linux + CUDA: LLAMA_CMAKE_FLAGS="-DGGML_CUDA=ON" sh build_jev_score.sh llama.cpp
|
| 91 |
+
|
| 92 |
+
python jev_style_decision_gguf.py --quant Q4_K_M \
|
| 93 |
+
--state "The film was excellent." \
|
| 94 |
+
--question "What is the sentiment of this review?" \
|
| 95 |
+
--options '["negative", "positive"]' --category general_sentiment
|
| 96 |
+
```
|
| 97 |
+
|
| 98 |
+
From Python, the API is the same as the main repository's runtime:
|
| 99 |
+
|
| 100 |
+
```python
|
| 101 |
+
from jev_style_decision_gguf import JevStyleDecisionGGUF
|
| 102 |
+
|
| 103 |
+
m = JevStyleDecisionGGUF(".", quant="F16") # or "Q8_0", "Q4_K_M"
|
| 104 |
+
r = m.decide(
|
| 105 |
+
{"ticket": "I was charged twice for my subscription this month.", "customer_tier": "pro"},
|
| 106 |
+
"Which team should handle this ticket?",
|
| 107 |
+
options={"billing": "payments, invoices, refunds", "technical": "bugs and outages", "sales": "new purchases"},
|
| 108 |
+
category="theme_routing",
|
| 109 |
+
)
|
| 110 |
+
print(r["answer"], r["probabilities"])
|
| 111 |
+
m.close()
|
| 112 |
+
```
|
| 113 |
+
|
| 114 |
+
- `jev-score` (`jev_score.cpp`) is a small libllama program that runs as a JSON-lines process. It requests logits
|
| 115 |
+
only at the slot positions. With a shared prefix it decodes the state once and scores several questions on
|
| 116 |
+
copies of it.
|
| 117 |
+
- `decide_many` sends all questions about one state in one request. The default, `many_mode="exact"`, returns
|
| 118 |
+
exactly what one `decide` call per question returns; it shares the state in whole 1,024-token blocks, so it
|
| 119 |
+
saves time from 1,024-token states on. `many_mode="batched"` reads the whole state once and scores all questions
|
| 120 |
+
together (the setting of the latency chart); its probabilities differed from `decide` by at most 0.002 in our
|
| 121 |
+
tests, and a near-tied top answer can change.
|
| 122 |
+
- The runtime opens a 32,768-token context, which covers the 25,600-token input limit plus the question part.
|
| 123 |
+
The whole input may be up to 25,600 tokens, and the question, options and readout up to 2,048. Over-budget
|
| 124 |
+
inputs raise an error, and nothing is truncated.
|
| 125 |
+
- The input format, the readout and the calibration temperatures are described on the
|
| 126 |
+
[main card](https://huggingface.co/chaoliangUNSW/Jev-Style-0.8B-Decision-v3#input-format-and-readout).
|
| 127 |
+
|
| 128 |
+
## Licence
|
| 129 |
+
|
| 130 |
+
Apache-2.0. Built on Qwen/Qwen3.5-0.8B (Apache-2.0). Some training data has restrictive or unclear terms, and some
|
| 131 |
+
training rows are outputs of OpenAI and Anthropic models. See "Training data and licences" on the main card.
|
| 132 |
+
Not affiliated with TypeSafe AI, Jev, the Laya authors or the Qwen team.
|
| 133 |
+
|
| 134 |
+
## Contact
|
| 135 |
+
|
| 136 |
+
I welcome internship, employment, and research collaboration opportunities. Please contact me at [**yanchaoliang369@gmail.com**](mailto:yanchaoliang369@gmail.com).
|
| 137 |
+
|
| 138 |
+
欢迎提供实习、工作及科研合作机会,请邮件联系:[yanchaoliang369@gmail.com](mailto:yanchaoliang369@gmail.com)。
|
build_jev_score.sh
ADDED
|
@@ -0,0 +1,27 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
#!/bin/sh
|
| 2 |
+
# Build jev-score (jev_score.cpp) against a llama.cpp checkout.
|
| 3 |
+
# sh build_jev_score.sh /path/to/llama.cpp -> ./build/jev-score
|
| 4 |
+
# Tested with llama.cpp commit 441df11f65ea0b6d0c72965aaf70c8241070ddcb (2026-09-23), macOS/Metal.
|
| 5 |
+
# If llama.cpp has no shared-library build yet, it is configured and built first (Metal on macOS;
|
| 6 |
+
# pass extra CMake flags in LLAMA_CMAKE_FLAGS, e.g. "-DGGML_CUDA=ON" on Linux/CUDA).
|
| 7 |
+
# OUT=/some/path/jev-score overrides the output file.
|
| 8 |
+
set -eu
|
| 9 |
+
LC=${1:?usage: sh build_jev_score.sh /path/to/llama.cpp}
|
| 10 |
+
LC=$(cd "$LC" && pwd)
|
| 11 |
+
HERE=$(cd "$(dirname "$0")" && pwd)
|
| 12 |
+
OUT=${OUT:-"$HERE/build/jev-score"}
|
| 13 |
+
LIBDIR="$LC/build/bin"
|
| 14 |
+
if [ ! -f "$LIBDIR/libllama.dylib" ] && [ ! -f "$LIBDIR/libllama.so" ]; then
|
| 15 |
+
cmake -S "$LC" -B "$LC/build" -DCMAKE_BUILD_TYPE=Release -DBUILD_SHARED_LIBS=ON \
|
| 16 |
+
-DLLAMA_BUILD_TESTS=OFF -DLLAMA_BUILD_SERVER=OFF -DLLAMA_CURL=OFF ${LLAMA_CMAKE_FLAGS:-}
|
| 17 |
+
cmake --build "$LC/build" -j 8 --target llama
|
| 18 |
+
fi
|
| 19 |
+
if [ ! -f "$LIBDIR/libllama.dylib" ] && [ ! -f "$LIBDIR/libllama.so" ]; then
|
| 20 |
+
LIBDIR=$(dirname "$(find "$LC/build" -name 'libllama.so' -o -name 'libllama.dylib' | head -n 1)")
|
| 21 |
+
fi
|
| 22 |
+
mkdir -p "$(dirname "$OUT")"
|
| 23 |
+
c++ -std=c++17 -O2 -Wall -Wno-unused-function \
|
| 24 |
+
-I"$LC/include" -I"$LC/ggml/include" -I"$LC/vendor" \
|
| 25 |
+
"$HERE/jev_score.cpp" -o "$OUT" \
|
| 26 |
+
-L"$LIBDIR" -lllama -lggml -lggml-base -Wl,-rpath,"$LIBDIR"
|
| 27 |
+
echo "$OUT"
|
figures/latency.data.json
ADDED
|
@@ -0,0 +1,51 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"chart": "latency",
|
| 3 |
+
"from_chart_data_entry": "latency.idle",
|
| 4 |
+
"source_path": "runs/macjev/latency/m1max_untrained_base_2026-09-23_review_idle/latency.json",
|
| 5 |
+
"field": "results['llamacpp-f16'|'laya-multilingual-mps-fp32'][cell].p50_ms",
|
| 6 |
+
"protocol_label": "M1 Max 64 GB, warm end-to-end p50 ms, idle run 2026-09-23 (load avg 3-8); untrained identical-architecture Qwen3.5-0.8B export (latency does not depend on weights); v3 = llama.cpp GGUF F16, one call per state; comparison engine = round-1 MacLaya-4K (our Laya-multilingual fine-tune, FP32/MPS, 4,096-token budget), one decide() per question; prefix reuse off",
|
| 7 |
+
"plotted": [
|
| 8 |
+
{
|
| 9 |
+
"cell": "1024x5",
|
| 10 |
+
"v3_p50_ms": 394,
|
| 11 |
+
"maclaya4k_p50_ms": 543,
|
| 12 |
+
"speedup_label": "1.4x"
|
| 13 |
+
},
|
| 14 |
+
{
|
| 15 |
+
"cell": "1024x10",
|
| 16 |
+
"v3_p50_ms": 525,
|
| 17 |
+
"maclaya4k_p50_ms": 1019,
|
| 18 |
+
"speedup_label": "1.9x"
|
| 19 |
+
},
|
| 20 |
+
{
|
| 21 |
+
"cell": "4096x5",
|
| 22 |
+
"v3_p50_ms": 1212,
|
| 23 |
+
"maclaya4k_p50_ms": 3204,
|
| 24 |
+
"speedup_label": "2.6x"
|
| 25 |
+
},
|
| 26 |
+
{
|
| 27 |
+
"cell": "4096x10",
|
| 28 |
+
"v3_p50_ms": 1381,
|
| 29 |
+
"maclaya4k_p50_ms": 6364,
|
| 30 |
+
"speedup_label": "4.6x"
|
| 31 |
+
},
|
| 32 |
+
{
|
| 33 |
+
"cell": "8192x1",
|
| 34 |
+
"v3_p50_ms": 2295,
|
| 35 |
+
"maclaya4k_p50_ms": null,
|
| 36 |
+
"speedup_label": "v3 only"
|
| 37 |
+
},
|
| 38 |
+
{
|
| 39 |
+
"cell": "8192x5",
|
| 40 |
+
"v3_p50_ms": 2424,
|
| 41 |
+
"maclaya4k_p50_ms": null,
|
| 42 |
+
"speedup_label": "v3 only"
|
| 43 |
+
},
|
| 44 |
+
{
|
| 45 |
+
"cell": "8192x10",
|
| 46 |
+
"v3_p50_ms": 2613,
|
| 47 |
+
"maclaya4k_p50_ms": null,
|
| 48 |
+
"speedup_label": "v3 only"
|
| 49 |
+
}
|
| 50 |
+
]
|
| 51 |
+
}
|
figures/latency.png
ADDED

|
Git LFS Details
|
figures/latency.svg
ADDED

|
figures/quantization.data.json
ADDED
|
@@ -0,0 +1,151 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"chart": "quantization",
|
| 3 |
+
"metric": "top-1 agreement with the full-precision reference (%), plus file size (GB = bytes/1e9)",
|
| 4 |
+
"rows": [
|
| 5 |
+
{
|
| 6 |
+
"tier": "16-bit",
|
| 7 |
+
"model": "v3",
|
| 8 |
+
"label": "Jev-Style 0.8B v3 \u00b7 GGUF F16",
|
| 9 |
+
"agree": 100.0,
|
| 10 |
+
"n": 240,
|
| 11 |
+
"agree_count": 240,
|
| 12 |
+
"size_gb": 1.516744128,
|
| 13 |
+
"size_note": "local export file (bytes / 1e9)",
|
| 14 |
+
"reference": "torch FP32",
|
| 15 |
+
"source": "runs/macjev/export_r2/main/parity/report.json; sizes: chart_data.json export.sizes"
|
| 16 |
+
},
|
| 17 |
+
{
|
| 18 |
+
"tier": "16-bit",
|
| 19 |
+
"model": "v3",
|
| 20 |
+
"label": "Jev-Style 0.8B v3 \u00b7 MLX bf16",
|
| 21 |
+
"agree": 100.0,
|
| 22 |
+
"n": 240,
|
| 23 |
+
"agree_count": 240,
|
| 24 |
+
"size_gb": 1.504827355,
|
| 25 |
+
"size_note": "local export file (bytes / 1e9)",
|
| 26 |
+
"reference": "torch FP32",
|
| 27 |
+
"source": "runs/macjev/export_r2/main/parity/report.json; sizes: chart_data.json export.sizes"
|
| 28 |
+
},
|
| 29 |
+
{
|
| 30 |
+
"tier": "16-bit",
|
| 31 |
+
"model": "v2",
|
| 32 |
+
"label": "Jev-Style 2B v2 \u00b7 GGUF BF16",
|
| 33 |
+
"agree": 99.6,
|
| 34 |
+
"n": 500,
|
| 35 |
+
"size_gb": 3.78,
|
| 36 |
+
"size_note": "as reported on card",
|
| 37 |
+
"reference": "CUDA merged BF16",
|
| 38 |
+
"source": "https://huggingface.co/chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision-v2-GGUF/raw/main/README.md"
|
| 39 |
+
},
|
| 40 |
+
{
|
| 41 |
+
"tier": "16-bit",
|
| 42 |
+
"model": "v2",
|
| 43 |
+
"label": "Jev-Style 2B v2 \u00b7 MLX BF16",
|
| 44 |
+
"agree": 99.6,
|
| 45 |
+
"n": 500,
|
| 46 |
+
"size_gb": 3.76,
|
| 47 |
+
"size_note": "as reported on card",
|
| 48 |
+
"reference": "CUDA merged BF16",
|
| 49 |
+
"source": "https://huggingface.co/chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision-v2-GGUF/raw/main/README.md (table: 'Native MLX BF16 | 3.76 GB | 99.6% choice agreement')"
|
| 50 |
+
},
|
| 51 |
+
{
|
| 52 |
+
"tier": "16-bit",
|
| 53 |
+
"model": "v1",
|
| 54 |
+
"label": "Jev-Style 2B v1 \u00b7 GGUF BF16",
|
| 55 |
+
"agree": 99.8,
|
| 56 |
+
"n": 500,
|
| 57 |
+
"size_gb": 3.9,
|
| 58 |
+
"size_note": "as reported on card",
|
| 59 |
+
"reference": "bf16",
|
| 60 |
+
"source": "https://huggingface.co/chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision-GGUF/raw/main/README.md"
|
| 61 |
+
},
|
| 62 |
+
{
|
| 63 |
+
"tier": "8-bit",
|
| 64 |
+
"model": "v3",
|
| 65 |
+
"label": "Jev-Style 0.8B v3 \u00b7 GGUF Q8_0",
|
| 66 |
+
"agree": 100.0,
|
| 67 |
+
"n": 240,
|
| 68 |
+
"agree_count": 240,
|
| 69 |
+
"size_gb": 0.811843008,
|
| 70 |
+
"size_note": "local export file (bytes / 1e9)",
|
| 71 |
+
"reference": "torch FP32",
|
| 72 |
+
"source": "runs/macjev/export_r2/main/parity/report.json; sizes: chart_data.json export.sizes"
|
| 73 |
+
},
|
| 74 |
+
{
|
| 75 |
+
"tier": "8-bit",
|
| 76 |
+
"model": "v3",
|
| 77 |
+
"label": "Jev-Style 0.8B v3 \u00b7 MLX 8-bit",
|
| 78 |
+
"agree": 100.0,
|
| 79 |
+
"n": 240,
|
| 80 |
+
"agree_count": 240,
|
| 81 |
+
"size_gb": 0.799973748,
|
| 82 |
+
"size_note": "local export file (bytes / 1e9)",
|
| 83 |
+
"reference": "torch FP32",
|
| 84 |
+
"source": "runs/macjev/export_r2/main/parity/report.json; sizes: chart_data.json export.sizes"
|
| 85 |
+
},
|
| 86 |
+
{
|
| 87 |
+
"tier": "8-bit",
|
| 88 |
+
"model": "v2",
|
| 89 |
+
"label": "Jev-Style 2B v2 \u00b7 GGUF Q8_0",
|
| 90 |
+
"agree": 99.2,
|
| 91 |
+
"n": 500,
|
| 92 |
+
"size_gb": 2.01,
|
| 93 |
+
"size_note": "as reported on card",
|
| 94 |
+
"reference": "CUDA merged BF16",
|
| 95 |
+
"source": "https://huggingface.co/chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision-v2-GGUF/raw/main/README.md"
|
| 96 |
+
},
|
| 97 |
+
{
|
| 98 |
+
"tier": "8-bit",
|
| 99 |
+
"model": "v1",
|
| 100 |
+
"label": "Jev-Style 2B v1 \u00b7 GGUF Q8_0",
|
| 101 |
+
"agree": 99.4,
|
| 102 |
+
"n": 500,
|
| 103 |
+
"size_gb": 2.1,
|
| 104 |
+
"size_note": "as reported on card",
|
| 105 |
+
"reference": "bf16",
|
| 106 |
+
"source": "https://huggingface.co/chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision-GGUF/raw/main/README.md"
|
| 107 |
+
},
|
| 108 |
+
{
|
| 109 |
+
"tier": "4-bit",
|
| 110 |
+
"model": "v3",
|
| 111 |
+
"label": "Jev-Style 0.8B v3 \u00b7 GGUF Q4_K_M",
|
| 112 |
+
"agree": 100.0,
|
| 113 |
+
"n": 240,
|
| 114 |
+
"agree_count": 240,
|
| 115 |
+
"size_gb": 0.529296832,
|
| 116 |
+
"size_note": "local export file (bytes / 1e9)",
|
| 117 |
+
"reference": "torch FP32",
|
| 118 |
+
"source": "runs/macjev/export_r2/main/parity/report.json; sizes: chart_data.json export.sizes"
|
| 119 |
+
},
|
| 120 |
+
{
|
| 121 |
+
"tier": "4-bit",
|
| 122 |
+
"model": "v2",
|
| 123 |
+
"label": "Jev-Style 2B v2 \u00b7 GGUF Q4_K_M",
|
| 124 |
+
"agree": 91.4,
|
| 125 |
+
"n": 500,
|
| 126 |
+
"size_gb": 1.27,
|
| 127 |
+
"size_note": "as reported on card",
|
| 128 |
+
"reference": "CUDA merged BF16",
|
| 129 |
+
"source": "https://huggingface.co/chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision-v2-GGUF/raw/main/README.md"
|
| 130 |
+
},
|
| 131 |
+
{
|
| 132 |
+
"tier": "4-bit",
|
| 133 |
+
"model": "v1",
|
| 134 |
+
"label": "Jev-Style 2B v1 \u00b7 GGUF Q4_K_M",
|
| 135 |
+
"agree": 94.39999999999999,
|
| 136 |
+
"n": 500,
|
| 137 |
+
"size_gb": 1.3,
|
| 138 |
+
"size_note": "as reported on card",
|
| 139 |
+
"reference": "bf16",
|
| 140 |
+
"source": "https://huggingface.co/chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision-GGUF/raw/main/README.md"
|
| 141 |
+
}
|
| 142 |
+
],
|
| 143 |
+
"deltas": {
|
| 144 |
+
"v2 Q4_K_M size / v3 Q4_K_M size": 2.4
|
| 145 |
+
},
|
| 146 |
+
"no_agreement_delta_claimed": "v3 parity rows are training-pool rows; v1/v2 used 500 held-out decisions, so no agreement gap is claimed",
|
| 147 |
+
"long_points": "v3 formats also 100% top-1 at 16,384 and 25,600 tokens (3 rows each), parity report long_points",
|
| 148 |
+
"not_plotted": "mlx-4bit (98.75%, 237/240) is not a published format and is omitted",
|
| 149 |
+
"footnote": "v3: top-1 agreement with the PyTorch FP32 reference on a 240-row parity fixture drawn from the training pool (22 categories, en+zh), plus 6 extra rows at about 16K and 25.6K tokens (6/6 agree). v3 sizes = exported weight files (GB = 10^9 bytes). 2B v1/v2: as reported on their public HF GGUF cards (500 held-out decisions each; vs bf16 for v1, vs CUDA merged BF16 for v2; card sizes). Different fixtures (training-pool rows for v3, held-out rows for v1/v2) and references: rows are not a paired comparison. x-axis starts at 88%.",
|
| 150 |
+
"protocol_label": "v3 G5 parity: 240-row mixed fixture (drawn from training-pool rows, 22 categories, en+zh) vs torch FP32; plus 16K and 25.6K long points (3 rows each). 2B numbers are from their cards on different fixtures (500 decisions vs bf16)"
|
| 151 |
+
}
|
figures/quantization.png
ADDED

|
Git LFS Details
|
figures/quantization.svg
ADDED
|
jev_score.cpp
ADDED
|
@@ -0,0 +1,367 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
// Part of Jev-Style-0.8B-Decision-v3 (Apache-2.0). Tested against llama.cpp commit
|
| 2 |
+
// 441df11f65ea0b6d0c72965aaf70c8241070ddcb (2026-09-23); needs a llama.cpp with qwen35 support and
|
| 3 |
+
// llama_context_params.n_outputs_max. Build: sh build_jev_score.sh /path/to/llama.cpp
|
| 4 |
+
//
|
| 5 |
+
// jev-score: score Jev-Style typed decisions with libllama, reading logits only at slot positions.
|
| 6 |
+
//
|
| 7 |
+
// Persistent JSON-lines server. Start:
|
| 8 |
+
// jev-score --model model.gguf [--n-ctx 32768] [--n-ubatch 1024] [--ngl 999] [--threads 8]
|
| 9 |
+
// [--flash-attn auto|on|off] [--n-outputs-max 256] [--n-seq-max 17]
|
| 10 |
+
// It prints one line {"ready":true,...}. Then each stdin line is one request:
|
| 11 |
+
// {"prefix":[ids], "questions":[{"ids":[ids], "slots":[abs positions], "rows":[token ids]}],
|
| 12 |
+
// "share_prefix":true, "keep_prefix":true}
|
| 13 |
+
// Positions in "slots" are absolute in prefix+question ids and must lie inside the question part.
|
| 14 |
+
// For every slot the response returns the logits of the requested token ids only:
|
| 15 |
+
// {"results":[{"scores":[[...len(rows)] per slot], "finite":true}], "prefix_reused":false,
|
| 16 |
+
// "n_prefix":N, "timing":{"prefix_ms":..,"question_ms":[..],"total_ms":..}}
|
| 17 |
+
//
|
| 18 |
+
// Mechanics: only slot positions get batch.logits[i] = 1 (never all-token output). With
|
| 19 |
+
// share_prefix the prefix is decoded once into sequence 0 and each question is decoded in
|
| 20 |
+
// sequence 1 after llama_memory_seq_cp(0 -> 1) (attention KV cells are shared; the recurrent
|
| 21 |
+
// GDN state is copied on write by llama.cpp), then sequence 1 is removed. With keep_prefix the
|
| 22 |
+
// prefix stays in sequence 0 and an identical prefix in the next request is reused without
|
| 23 |
+
// recomputation (recurrent state cannot be rolled back, so only exact matches are reused).
|
| 24 |
+
// share_prefix=false decodes prefix+question from scratch per question (reference path).
|
| 25 |
+
// "mode" (default "auto"): with share_prefix, "sequential" = one question at a time as above;
|
| 26 |
+
// "batched" = questions k=1..G get sequences k (seq_cp 0 -> k) and ALL their tokens go into one
|
| 27 |
+
// llama_decode (groups bounded by --n-seq-max - 1 questions, by free KV cells and by
|
| 28 |
+
// --n-outputs-max slots per decode: libllama aborts the process on a larger output request);
|
| 29 |
+
// "auto" = "fused" for a single question whose prefix is not cached (one decode of
|
| 30 |
+
// prefix+question into sequence 0, prefix not kept), "batched" for several questions.
|
| 31 |
+
// {"cmd":"reset"} clears the memory; {"cmd":"quit"} exits.
|
| 32 |
+
|
| 33 |
+
#include "llama.h"
|
| 34 |
+
#include "nlohmann/json.hpp"
|
| 35 |
+
|
| 36 |
+
#include <algorithm>
|
| 37 |
+
#include <chrono>
|
| 38 |
+
#include <cmath>
|
| 39 |
+
#include <cstdio>
|
| 40 |
+
#include <cstring>
|
| 41 |
+
#include <iostream>
|
| 42 |
+
#include <string>
|
| 43 |
+
#include <vector>
|
| 44 |
+
|
| 45 |
+
using json = nlohmann::json;
|
| 46 |
+
using clk = std::chrono::steady_clock;
|
| 47 |
+
|
| 48 |
+
static double ms_since(clk::time_point t0) {
|
| 49 |
+
return std::chrono::duration<double, std::milli>(clk::now() - t0).count();
|
| 50 |
+
}
|
| 51 |
+
|
| 52 |
+
struct Scorer {
|
| 53 |
+
llama_model * model = nullptr;
|
| 54 |
+
llama_context * ctx = nullptr;
|
| 55 |
+
int n_ctx = 0, n_batch = 0, n_vocab = 0, n_seq_max = 2;
|
| 56 |
+
// Max logits rows one llama_decode may request. libllama GGML_ASSERTs (process abort) when a
|
| 57 |
+
// batch asks for more, so every decode is kept within it: a single question with more slots
|
| 58 |
+
// is rejected with an error, batched groups are split by their total slot count.
|
| 59 |
+
int n_outputs_max = 256;
|
| 60 |
+
std::vector<llama_token> cached_prefix; // content of sequence 0
|
| 61 |
+
bool cached_valid = false;
|
| 62 |
+
|
| 63 |
+
void clear() {
|
| 64 |
+
llama_memory_clear(llama_get_memory(ctx), true);
|
| 65 |
+
cached_prefix.clear();
|
| 66 |
+
cached_valid = false;
|
| 67 |
+
}
|
| 68 |
+
|
| 69 |
+
// Decode ids at positions [pos0, pos0+n) into seq; request logits at the given absolute positions.
|
| 70 |
+
// Returns the batch index of every requested position (same order as `want`).
|
| 71 |
+
std::vector<int> decode(const std::vector<llama_token> & ids, int pos0, llama_seq_id seq,
|
| 72 |
+
const std::vector<int> & want) {
|
| 73 |
+
std::vector<int> idx(want.size(), -1);
|
| 74 |
+
const int n = (int) ids.size();
|
| 75 |
+
if (n == 0) return idx;
|
| 76 |
+
// Chunk by n_batch (only the last chunk can hold slots because slots lie in the question).
|
| 77 |
+
for (int start = 0; start < n; start += n_batch) {
|
| 78 |
+
const int len = std::min(n_batch, n - start);
|
| 79 |
+
llama_batch batch = llama_batch_init(len, 0, 1);
|
| 80 |
+
batch.n_tokens = len;
|
| 81 |
+
for (int j = 0; j < len; ++j) {
|
| 82 |
+
batch.token[j] = ids[start + j];
|
| 83 |
+
batch.pos[j] = pos0 + start + j;
|
| 84 |
+
batch.n_seq_id[j] = 1;
|
| 85 |
+
batch.seq_id[j][0] = seq;
|
| 86 |
+
batch.logits[j] = 0;
|
| 87 |
+
}
|
| 88 |
+
for (size_t w = 0; w < want.size(); ++w) {
|
| 89 |
+
const int rel = want[w] - pos0 - start;
|
| 90 |
+
if (rel >= 0 && rel < len) {
|
| 91 |
+
batch.logits[rel] = 1;
|
| 92 |
+
idx[w] = rel;
|
| 93 |
+
}
|
| 94 |
+
}
|
| 95 |
+
const int rc = llama_decode(ctx, batch);
|
| 96 |
+
llama_batch_free(batch);
|
| 97 |
+
if (rc != 0) throw std::runtime_error("llama_decode failed with code " + std::to_string(rc));
|
| 98 |
+
for (size_t w = 0; w < want.size(); ++w) {
|
| 99 |
+
const int rel = want[w] - pos0 - start;
|
| 100 |
+
if ((rel >= 0 && rel < len) && start + len < n) {
|
| 101 |
+
throw std::runtime_error("slot inside a non-final chunk; question longer than n_batch");
|
| 102 |
+
}
|
| 103 |
+
}
|
| 104 |
+
}
|
| 105 |
+
return idx;
|
| 106 |
+
}
|
| 107 |
+
|
| 108 |
+
// Decode several questions at once: question k goes to sequence seqs[k] at positions
|
| 109 |
+
// n_prefix.. . Returns per question the batch indices of its slots.
|
| 110 |
+
std::vector<std::vector<int>> decode_group(const std::vector<std::vector<llama_token>> & ids,
|
| 111 |
+
const std::vector<std::vector<int>> & slots,
|
| 112 |
+
const std::vector<llama_seq_id> & seqs, int n_prefix) {
|
| 113 |
+
int total = 0;
|
| 114 |
+
for (const auto & v : ids) total += (int) v.size();
|
| 115 |
+
if (total > n_batch) throw std::runtime_error("question group larger than n_batch");
|
| 116 |
+
llama_batch batch = llama_batch_init(total, 0, 1);
|
| 117 |
+
batch.n_tokens = total;
|
| 118 |
+
std::vector<std::vector<int>> idx(ids.size());
|
| 119 |
+
int j = 0;
|
| 120 |
+
for (size_t k = 0; k < ids.size(); ++k) {
|
| 121 |
+
std::vector<int> want = slots[k];
|
| 122 |
+
idx[k].assign(want.size(), -1);
|
| 123 |
+
for (size_t t = 0; t < ids[k].size(); ++t, ++j) {
|
| 124 |
+
batch.token[j] = ids[k][t];
|
| 125 |
+
batch.pos[j] = n_prefix + (int) t;
|
| 126 |
+
batch.n_seq_id[j] = 1;
|
| 127 |
+
batch.seq_id[j][0] = seqs[k];
|
| 128 |
+
batch.logits[j] = 0;
|
| 129 |
+
for (size_t w = 0; w < want.size(); ++w) {
|
| 130 |
+
if (want[w] == n_prefix + (int) t) { batch.logits[j] = 1; idx[k][w] = j; }
|
| 131 |
+
}
|
| 132 |
+
}
|
| 133 |
+
}
|
| 134 |
+
const int rc = llama_decode(ctx, batch);
|
| 135 |
+
llama_batch_free(batch);
|
| 136 |
+
if (rc != 0) throw std::runtime_error("llama_decode (question group) failed with code " + std::to_string(rc));
|
| 137 |
+
return idx;
|
| 138 |
+
}
|
| 139 |
+
|
| 140 |
+
json read_slots(const std::vector<int> & idx, const std::vector<llama_token> & rows, bool & finite) {
|
| 141 |
+
json scores = json::array();
|
| 142 |
+
for (int i : idx) {
|
| 143 |
+
const float * lg = llama_get_logits_ith(ctx, i);
|
| 144 |
+
if (!lg) throw std::runtime_error("no logits at requested slot");
|
| 145 |
+
json r = json::array();
|
| 146 |
+
for (llama_token t : rows) {
|
| 147 |
+
if (t < 0 || t >= n_vocab) throw std::runtime_error("row token id out of range");
|
| 148 |
+
const float v = lg[t];
|
| 149 |
+
if (!std::isfinite(v)) finite = false;
|
| 150 |
+
r.push_back(std::isfinite(v) ? json(v) : json(nullptr));
|
| 151 |
+
}
|
| 152 |
+
scores.push_back(r);
|
| 153 |
+
}
|
| 154 |
+
return scores;
|
| 155 |
+
}
|
| 156 |
+
|
| 157 |
+
json handle(const json & req) {
|
| 158 |
+
const auto t_total = clk::now();
|
| 159 |
+
std::vector<llama_token> prefix = req.value("prefix", std::vector<llama_token>{});
|
| 160 |
+
const bool share = req.value("share_prefix", true);
|
| 161 |
+
const bool keep = req.value("keep_prefix", true);
|
| 162 |
+
const json & qs = req.at("questions");
|
| 163 |
+
llama_memory_t mem = llama_get_memory(ctx);
|
| 164 |
+
const int n_prefix = (int) prefix.size();
|
| 165 |
+
json out;
|
| 166 |
+
json results = json::array();
|
| 167 |
+
json q_ms = json::array();
|
| 168 |
+
double prefix_ms = 0.0;
|
| 169 |
+
bool reused = false;
|
| 170 |
+
|
| 171 |
+
for (const auto & q : qs) {
|
| 172 |
+
std::vector<llama_token> ids = q.at("ids").get<std::vector<llama_token>>();
|
| 173 |
+
if (n_prefix + (int) ids.size() > n_ctx) {
|
| 174 |
+
throw std::runtime_error("input of " + std::to_string(n_prefix + ids.size()) +
|
| 175 |
+
" tokens exceeds n_ctx=" + std::to_string(n_ctx) + "; nothing truncated");
|
| 176 |
+
}
|
| 177 |
+
const std::vector<int> qslots = q.at("slots").get<std::vector<int>>();
|
| 178 |
+
if ((int) qslots.size() > n_outputs_max) {
|
| 179 |
+
throw std::runtime_error("question has " + std::to_string(qslots.size()) + " slots; n_outputs_max=" +
|
| 180 |
+
std::to_string(n_outputs_max) + " (restart with a larger --n-outputs-max)");
|
| 181 |
+
}
|
| 182 |
+
for (int s : qslots) {
|
| 183 |
+
if (s < n_prefix || s >= n_prefix + (int) ids.size())
|
| 184 |
+
throw std::runtime_error("slot position outside the question part");
|
| 185 |
+
}
|
| 186 |
+
}
|
| 187 |
+
|
| 188 |
+
if (share && n_prefix > 0 && keep && cached_valid && cached_prefix == prefix) reused = true;
|
| 189 |
+
std::string mode = req.value("mode", std::string("auto"));
|
| 190 |
+
if (mode == "auto") mode = qs.size() > 1 ? "batched" : "fused";
|
| 191 |
+
if (!share) mode = "sequential";
|
| 192 |
+
if (mode == "fused" && (qs.size() != 1 || reused)) mode = qs.size() > 1 ? "batched" : "sequential";
|
| 193 |
+
if (mode == "batched" && n_seq_max < 3) mode = "sequential";
|
| 194 |
+
std::vector<json> res_by_q(qs.size());
|
| 195 |
+
std::vector<double> ms_by_q(qs.size(), 0.0);
|
| 196 |
+
|
| 197 |
+
if (mode == "fused") {
|
| 198 |
+
// one decode of prefix + question into sequence 0; the prefix is not kept afterwards
|
| 199 |
+
const auto t0 = clk::now();
|
| 200 |
+
const auto & q = qs[0];
|
| 201 |
+
std::vector<llama_token> all(prefix);
|
| 202 |
+
std::vector<llama_token> ids = q.at("ids").get<std::vector<llama_token>>();
|
| 203 |
+
all.insert(all.end(), ids.begin(), ids.end());
|
| 204 |
+
clear();
|
| 205 |
+
std::vector<int> idx = decode(all, 0, 0, q.at("slots").get<std::vector<int>>());
|
| 206 |
+
bool finite = true;
|
| 207 |
+
json scores = read_slots(idx, q.at("rows").get<std::vector<llama_token>>(), finite);
|
| 208 |
+
clear();
|
| 209 |
+
ms_by_q[0] = ms_since(t0);
|
| 210 |
+
res_by_q[0] = {{"scores", scores}, {"finite", finite}};
|
| 211 |
+
} else {
|
| 212 |
+
if (share && n_prefix > 0 && !reused) {
|
| 213 |
+
const auto t0 = clk::now();
|
| 214 |
+
clear();
|
| 215 |
+
decode(prefix, 0, 0, {});
|
| 216 |
+
llama_synchronize(ctx);
|
| 217 |
+
prefix_ms = ms_since(t0);
|
| 218 |
+
cached_prefix = prefix;
|
| 219 |
+
cached_valid = true;
|
| 220 |
+
}
|
| 221 |
+
size_t i = 0;
|
| 222 |
+
while (i < qs.size()) {
|
| 223 |
+
const auto t0 = clk::now();
|
| 224 |
+
// group: up to n_seq_max-1 questions whose tokens fit the free KV cells and n_batch
|
| 225 |
+
// and whose slots together stay within n_outputs_max (one llama_decode)
|
| 226 |
+
std::vector<size_t> grp;
|
| 227 |
+
int used = 0, outs = 0;
|
| 228 |
+
const int cap = mode == "batched" ? n_seq_max - 1 : 1;
|
| 229 |
+
while (i < qs.size() && (int) grp.size() < cap) {
|
| 230 |
+
const int len = (int) qs[i].at("ids").size();
|
| 231 |
+
const int ns = (int) qs[i].at("slots").size();
|
| 232 |
+
if (!grp.empty() && (n_prefix + used + len > n_ctx || used + len > n_batch ||
|
| 233 |
+
outs + ns > n_outputs_max)) break;
|
| 234 |
+
grp.push_back(i++);
|
| 235 |
+
used += len;
|
| 236 |
+
outs += ns;
|
| 237 |
+
}
|
| 238 |
+
std::vector<std::vector<llama_token>> ids;
|
| 239 |
+
std::vector<std::vector<int>> slots;
|
| 240 |
+
std::vector<llama_seq_id> seqs;
|
| 241 |
+
for (size_t k = 0; k < grp.size(); ++k) {
|
| 242 |
+
const llama_seq_id sq = (llama_seq_id) (k + 1);
|
| 243 |
+
llama_memory_seq_rm(mem, sq, -1, -1);
|
| 244 |
+
if (share && n_prefix > 0) llama_memory_seq_cp(mem, 0, sq, -1, -1);
|
| 245 |
+
ids.push_back(qs[grp[k]].at("ids").get<std::vector<llama_token>>());
|
| 246 |
+
slots.push_back(qs[grp[k]].at("slots").get<std::vector<int>>());
|
| 247 |
+
seqs.push_back(sq);
|
| 248 |
+
}
|
| 249 |
+
std::vector<std::vector<int>> idx;
|
| 250 |
+
if (share) {
|
| 251 |
+
idx = decode_group(ids, slots, seqs, n_prefix);
|
| 252 |
+
} else { // reference path: prefix + question from scratch
|
| 253 |
+
clear();
|
| 254 |
+
std::vector<llama_token> all(prefix);
|
| 255 |
+
all.insert(all.end(), ids[0].begin(), ids[0].end());
|
| 256 |
+
idx.push_back(decode(all, 0, 1, slots[0]));
|
| 257 |
+
}
|
| 258 |
+
for (size_t k = 0; k < grp.size(); ++k) {
|
| 259 |
+
bool finite = true;
|
| 260 |
+
json scores = read_slots(idx[k], qs[grp[k]].at("rows").get<std::vector<llama_token>>(), finite);
|
| 261 |
+
res_by_q[grp[k]] = {{"scores", scores}, {"finite", finite}};
|
| 262 |
+
}
|
| 263 |
+
for (auto sq : seqs) llama_memory_seq_rm(mem, sq, -1, -1);
|
| 264 |
+
const double per = ms_since(t0) / (double) grp.size();
|
| 265 |
+
for (size_t k : grp) ms_by_q[k] = per;
|
| 266 |
+
}
|
| 267 |
+
}
|
| 268 |
+
for (size_t k = 0; k < qs.size(); ++k) {
|
| 269 |
+
results.push_back(res_by_q[k]);
|
| 270 |
+
q_ms.push_back(ms_by_q[k]);
|
| 271 |
+
}
|
| 272 |
+
out["mode"] = mode;
|
| 273 |
+
if (!share || !keep) clear();
|
| 274 |
+
out["results"] = results;
|
| 275 |
+
out["prefix_reused"] = reused;
|
| 276 |
+
out["n_prefix"] = n_prefix;
|
| 277 |
+
out["timing"] = {{"prefix_ms", prefix_ms}, {"question_ms", q_ms}, {"total_ms", ms_since(t_total)}};
|
| 278 |
+
return out;
|
| 279 |
+
}
|
| 280 |
+
};
|
| 281 |
+
|
| 282 |
+
static void usage() {
|
| 283 |
+
fprintf(stderr, "usage: jev-score --model PATH [--n-ctx N] [--n-ubatch N] [--ngl N] [--threads N] "
|
| 284 |
+
"[--flash-attn auto|on|off] [--n-outputs-max N] [--n-seq-max N]\n");
|
| 285 |
+
}
|
| 286 |
+
|
| 287 |
+
int main(int argc, char ** argv) {
|
| 288 |
+
std::string model_path, fa = "auto";
|
| 289 |
+
int n_ctx = 32768, n_ubatch = 1024, ngl = 999, threads = 8, n_out = 256, n_seq = 17; // 25,600-token context + question room
|
| 290 |
+
for (int i = 1; i < argc; ++i) {
|
| 291 |
+
std::string a = argv[i];
|
| 292 |
+
auto next = [&]() -> std::string {
|
| 293 |
+
if (i + 1 >= argc) { usage(); exit(2); }
|
| 294 |
+
return argv[++i];
|
| 295 |
+
};
|
| 296 |
+
if (a == "--model") model_path = next();
|
| 297 |
+
else if (a == "--n-ctx") n_ctx = std::stoi(next());
|
| 298 |
+
else if (a == "--n-ubatch") n_ubatch = std::stoi(next());
|
| 299 |
+
else if (a == "--ngl") ngl = std::stoi(next());
|
| 300 |
+
else if (a == "--threads") threads = std::stoi(next());
|
| 301 |
+
else if (a == "--flash-attn") fa = next();
|
| 302 |
+
else if (a == "--n-outputs-max") n_out = std::stoi(next());
|
| 303 |
+
else if (a == "--n-seq-max") n_seq = std::stoi(next());
|
| 304 |
+
else { usage(); return 2; }
|
| 305 |
+
}
|
| 306 |
+
if (model_path.empty()) { usage(); return 2; }
|
| 307 |
+
if (n_out < std::max(2, n_seq)) { // libllama reserves max(n_outputs, n_seq_max) rows and asserts on it
|
| 308 |
+
std::cout << json{{"ready", false}, {"error", "--n-outputs-max must be >= --n-seq-max"}}.dump() << std::endl;
|
| 309 |
+
return 2;
|
| 310 |
+
}
|
| 311 |
+
|
| 312 |
+
const auto t0 = clk::now();
|
| 313 |
+
llama_log_set([](enum ggml_log_level level, const char * text, void *) {
|
| 314 |
+
if (level >= GGML_LOG_LEVEL_WARN) fputs(text, stderr);
|
| 315 |
+
}, nullptr);
|
| 316 |
+
llama_backend_init();
|
| 317 |
+
llama_model_params mp = llama_model_default_params();
|
| 318 |
+
mp.n_gpu_layers = ngl;
|
| 319 |
+
Scorer S;
|
| 320 |
+
S.model = llama_model_load_from_file(model_path.c_str(), mp);
|
| 321 |
+
if (!S.model) { std::cout << json{{"ready", false}, {"error", "model load failed"}}.dump() << std::endl; return 1; }
|
| 322 |
+
llama_context_params cp = llama_context_default_params();
|
| 323 |
+
cp.n_ctx = n_ctx;
|
| 324 |
+
cp.n_batch = n_ctx;
|
| 325 |
+
cp.n_ubatch = std::min(n_ubatch, n_ctx);
|
| 326 |
+
cp.n_seq_max = std::max(2, n_seq);
|
| 327 |
+
cp.n_outputs_max = n_out;
|
| 328 |
+
cp.n_threads = threads;
|
| 329 |
+
cp.n_threads_batch = threads;
|
| 330 |
+
cp.kv_unified = true;
|
| 331 |
+
cp.no_perf = true;
|
| 332 |
+
cp.flash_attn_type = fa == "on" ? LLAMA_FLASH_ATTN_TYPE_ENABLED
|
| 333 |
+
: fa == "off" ? LLAMA_FLASH_ATTN_TYPE_DISABLED : LLAMA_FLASH_ATTN_TYPE_AUTO;
|
| 334 |
+
S.ctx = llama_init_from_model(S.model, cp);
|
| 335 |
+
if (!S.ctx) { std::cout << json{{"ready", false}, {"error", "context init failed"}}.dump() << std::endl; return 1; }
|
| 336 |
+
S.n_ctx = (int) llama_n_ctx(S.ctx);
|
| 337 |
+
S.n_batch = (int) llama_n_batch(S.ctx);
|
| 338 |
+
S.n_seq_max = (int) llama_n_seq_max(S.ctx);
|
| 339 |
+
S.n_outputs_max = (int) cp.n_outputs_max;
|
| 340 |
+
S.n_vocab = llama_vocab_n_tokens(llama_model_get_vocab(S.model));
|
| 341 |
+
char desc[256];
|
| 342 |
+
llama_model_desc(S.model, desc, sizeof(desc));
|
| 343 |
+
std::cout << json{{"ready", true}, {"n_ctx", S.n_ctx}, {"n_batch", S.n_batch}, {"n_ubatch", cp.n_ubatch}, {"n_seq_max", S.n_seq_max}, {"n_outputs_max", S.n_outputs_max},
|
| 344 |
+
{"n_vocab", S.n_vocab}, {"desc", desc}, {"load_ms", ms_since(t0)},
|
| 345 |
+
{"system_info", llama_print_system_info()}}.dump() << std::endl;
|
| 346 |
+
|
| 347 |
+
std::string line;
|
| 348 |
+
while (std::getline(std::cin, line)) {
|
| 349 |
+
if (line.empty()) continue;
|
| 350 |
+
json resp;
|
| 351 |
+
try {
|
| 352 |
+
json req = json::parse(line);
|
| 353 |
+
const std::string cmd = req.value("cmd", "");
|
| 354 |
+
if (cmd == "quit") break;
|
| 355 |
+
if (cmd == "reset") { S.clear(); resp = {{"ok", true}}; }
|
| 356 |
+
else resp = S.handle(req);
|
| 357 |
+
} catch (const std::exception & e) {
|
| 358 |
+
try { S.clear(); } catch (...) {}
|
| 359 |
+
resp = {{"error", e.what()}};
|
| 360 |
+
}
|
| 361 |
+
std::cout << resp.dump() << std::endl;
|
| 362 |
+
}
|
| 363 |
+
llama_free(S.ctx);
|
| 364 |
+
llama_model_free(S.model);
|
| 365 |
+
llama_backend_free();
|
| 366 |
+
return 0;
|
| 367 |
+
}
|
jev_style_decision_gguf.py
ADDED
|
@@ -0,0 +1,552 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Jev-Style-0.8B-Decision-v3: typed decisions with llama.cpp (GGUF F16 / Q8_0 / Q4_K_M).
|
| 2 |
+
|
| 3 |
+
Self-contained runtime for chaoliangUNSW/Jev-Style-0.8B-Decision-v3 (Apache-2.0). No dependency on any training code:
|
| 4 |
+
rendering, verdict readout and calibration are implemented below and reproduce the reference
|
| 5 |
+
implementation used for evaluation (see release_config.json -> "runtime_parity").
|
| 6 |
+
|
| 7 |
+
Calibration temperature: with no category (the default) probabilities use the global temperature of
|
| 8 |
+
readout_config.json (temperatures.global = 0.880); pass category=... (CLI --category, JSONL "category")
|
| 9 |
+
for the fitted group temperature of that category's family x question type x option-count bucket, or
|
| 10 |
+
temperature=... to override (1.0 = uncalibrated scores).
|
| 11 |
+
"""
|
| 12 |
+
# ----------------------------------------------------------------------------------------------
|
| 13 |
+
# Shared core (identical in jev_style_decision.py, jev_style_decision_gguf.py and
|
| 14 |
+
# jev_style_decision_mlx.py): input rendering, verdict readout, calibrated probabilities.
|
| 15 |
+
#
|
| 16 |
+
# Input layout ("macjev-render-v1"; token segments are encoded separately and concatenated):
|
| 17 |
+
#
|
| 18 |
+
# State:\n<state>\n\n
|
| 19 |
+
# Question [<type>]: <question>\nOptions:\n
|
| 20 |
+
# - <option 1>\n ... - <option K>\n
|
| 21 |
+
# Judge each option:\n
|
| 22 |
+
# <option 1> ->\n ... <option K> ->\n
|
| 23 |
+
#
|
| 24 |
+
# Score of option k = logit(" yes") - logit(" no") at the k-th " ->" token (computed from the final
|
| 25 |
+
# hidden state and the tied embedding rows, float32). Probabilities = softmax(scores / T), where T is
|
| 26 |
+
# the calibration temperature shipped in readout_config.json:
|
| 27 |
+
# * no category given (the default): T = temperatures.global (the file's global temperature);
|
| 28 |
+
# * category="..." given: T = the fitted group temperature of (family of that category x question
|
| 29 |
+
# type x option-count bucket), or temperatures.global when that group was not fitted;
|
| 30 |
+
# * temperature=... given: that value (1.0 = uncalibrated scores).
|
| 31 |
+
# T is clamped to temperatures.clamp. Text inside the state or options is tokenised with special
|
| 32 |
+
# tokens disabled, so e.g. "<|im_end|>" in user text can never act as a control token.
|
| 33 |
+
#
|
| 34 |
+
# Budgets: whole input <= 25,600 tokens; question + options + readout ("head") <= 2,048 tokens.
|
| 35 |
+
# Larger inputs raise InputBudgetError. Nothing is ever truncated.
|
| 36 |
+
# ----------------------------------------------------------------------------------------------
|
| 37 |
+
import argparse
|
| 38 |
+
import hashlib
|
| 39 |
+
import json
|
| 40 |
+
import math
|
| 41 |
+
import sys
|
| 42 |
+
from pathlib import Path
|
| 43 |
+
|
| 44 |
+
import numpy as np
|
| 45 |
+
|
| 46 |
+
MODEL_NAME = "Jev-Style-0.8B-Decision-v3"
|
| 47 |
+
TEMPLATE_VERSION = "macjev-render-v1"
|
| 48 |
+
READOUT_FORMAT = "macjev-readout-v1"
|
| 49 |
+
CONTEXT_LIMIT = 25_600 # state + question + options + readout
|
| 50 |
+
HARD_HEAD_MAX = 2048 # question + options + readout
|
| 51 |
+
QTYPES = ("choice", "score", "noul")
|
| 52 |
+
HERE = Path(__file__).resolve().parent
|
| 53 |
+
|
| 54 |
+
# calibration families (category prefix -> family), same table the temperatures were fitted with
|
| 55 |
+
FAMILY_BY_CATEGORY_PREFIX = (("typed_official", "typed"), ("typed_synthetic", "typed_synth"), ("general_", "general"),
|
| 56 |
+
("intent", "intent"), ("nli", "nli"), ("theme_", "theme"), ("mac_", "mac"),
|
| 57 |
+
("long_", "long"))
|
| 58 |
+
|
| 59 |
+
|
| 60 |
+
class InputBudgetError(ValueError):
|
| 61 |
+
"""The rendered input exceeds a token budget. Nothing was truncated."""
|
| 62 |
+
|
| 63 |
+
|
| 64 |
+
class QuestionError(ValueError):
|
| 65 |
+
"""The question/options are malformed."""
|
| 66 |
+
|
| 67 |
+
|
| 68 |
+
# -- questions ------------------------------------------------------------------------------------
|
| 69 |
+
def option_names(question):
|
| 70 |
+
"""Canonical option identifiers, in the order the probabilities are returned."""
|
| 71 |
+
if not isinstance(question, dict):
|
| 72 |
+
raise QuestionError("question must be a dict {'t', 'ins', 'crit'}")
|
| 73 |
+
t, crit = question.get("t"), question.get("crit")
|
| 74 |
+
if not isinstance(question.get("ins"), str) or not question["ins"].strip():
|
| 75 |
+
raise QuestionError("question text ('ins') must be a non-empty string")
|
| 76 |
+
if t == "choice":
|
| 77 |
+
if not isinstance(crit, dict) or not crit:
|
| 78 |
+
raise QuestionError("choice needs a non-empty dict {option name: description or None}")
|
| 79 |
+
return [str(k) for k in crit]
|
| 80 |
+
if t == "score":
|
| 81 |
+
if not isinstance(crit, list) or not 2 <= len(crit) <= 10:
|
| 82 |
+
raise QuestionError("score needs a list of 2..10 level descriptions")
|
| 83 |
+
return [str(i) for i in range(len(crit))]
|
| 84 |
+
if t == "noul":
|
| 85 |
+
if crit is not None and not isinstance(crit, dict):
|
| 86 |
+
raise QuestionError("noul criteria must be None or {'false': ..., 'true': ...}")
|
| 87 |
+
return ["false", "true"]
|
| 88 |
+
raise QuestionError(f"unknown question type {t!r} (expected one of {QTYPES})")
|
| 89 |
+
|
| 90 |
+
|
| 91 |
+
def make_question(question, options=None, qtype=None):
|
| 92 |
+
"""Build a typed question.
|
| 93 |
+
|
| 94 |
+
* ``question`` already a dict {"t", "ins", "crit"}: validated and returned.
|
| 95 |
+
* ``qtype="choice"`` (default when ``options`` is given): ``options`` = {name: description or None}
|
| 96 |
+
or a list of names.
|
| 97 |
+
* ``qtype="score"``: ``options`` = list of 2..10 level descriptions (level 0 first).
|
| 98 |
+
* ``qtype="noul"`` (default when no options): a true/false statement; ``options`` may be
|
| 99 |
+
{"false": "...", "true": "..."} to describe the two outcomes.
|
| 100 |
+
"""
|
| 101 |
+
if isinstance(question, dict):
|
| 102 |
+
q = dict(question)
|
| 103 |
+
else:
|
| 104 |
+
if qtype is None:
|
| 105 |
+
qtype = "choice" if options is not None else "noul"
|
| 106 |
+
if qtype == "choice":
|
| 107 |
+
if isinstance(options, (list, tuple)):
|
| 108 |
+
if len(set(map(str, options))) != len(options):
|
| 109 |
+
raise QuestionError("duplicate option names")
|
| 110 |
+
crit = {str(o): None for o in options}
|
| 111 |
+
else:
|
| 112 |
+
crit = options
|
| 113 |
+
elif qtype == "score":
|
| 114 |
+
crit = list(options) if options is not None else None
|
| 115 |
+
else:
|
| 116 |
+
crit = options
|
| 117 |
+
q = {"t": qtype, "ins": question, "crit": crit}
|
| 118 |
+
option_names(q)
|
| 119 |
+
return q
|
| 120 |
+
|
| 121 |
+
|
| 122 |
+
def serialize_state(state):
|
| 123 |
+
"""Strings pass through unchanged; any other JSON value is serialised (ensure_ascii=False)."""
|
| 124 |
+
if isinstance(state, str):
|
| 125 |
+
return state
|
| 126 |
+
return json.dumps(state, ensure_ascii=False)
|
| 127 |
+
|
| 128 |
+
|
| 129 |
+
def _criterion(value):
|
| 130 |
+
if isinstance(value, str):
|
| 131 |
+
return value
|
| 132 |
+
return json.dumps(value, ensure_ascii=False, separators=(", ", ": "), default=str)
|
| 133 |
+
|
| 134 |
+
|
| 135 |
+
def render_options(question):
|
| 136 |
+
t, crit = question["t"], question.get("crit")
|
| 137 |
+
if t == "choice":
|
| 138 |
+
return [k if v is None or v == "" else f"{k}: {_criterion(v)}" for k, v in crit.items()]
|
| 139 |
+
if t == "score":
|
| 140 |
+
return [f"level {i}: {_criterion(c)}" for i, c in enumerate(crit)]
|
| 141 |
+
crit = crit or {}
|
| 142 |
+
false_c, true_c = crit.get("false"), crit.get("true")
|
| 143 |
+
return ["false: " + (_criterion(false_c) if false_c not in (None, "") else "no, the statement does not hold"),
|
| 144 |
+
"true: " + (_criterion(true_c) if true_c not in (None, "") else "yes, the statement holds")]
|
| 145 |
+
|
| 146 |
+
|
| 147 |
+
# -- tokenizer + renderer -----------------------------------------------------------------------
|
| 148 |
+
class TextEncoder:
|
| 149 |
+
"""HF ``tokenizers`` tokenizer.json; no BOS/EOS, special tokens in text are split (never control tokens)."""
|
| 150 |
+
|
| 151 |
+
def __init__(self, tokenizer_json):
|
| 152 |
+
from tokenizers import Tokenizer
|
| 153 |
+
self.tk = Tokenizer.from_file(str(tokenizer_json))
|
| 154 |
+
self.tk.encode_special_tokens = True
|
| 155 |
+
|
| 156 |
+
def __call__(self, text):
|
| 157 |
+
return self.tk.encode(text, add_special_tokens=False).ids
|
| 158 |
+
|
| 159 |
+
|
| 160 |
+
class Rendered:
|
| 161 |
+
__slots__ = ("ids", "prefix_len", "slots", "names", "head_tokens")
|
| 162 |
+
|
| 163 |
+
def __init__(self, ids, prefix_len, slots, names, head_tokens):
|
| 164 |
+
self.ids, self.prefix_len, self.slots, self.names, self.head_tokens = ids, prefix_len, slots, names, head_tokens
|
| 165 |
+
|
| 166 |
+
|
| 167 |
+
class Renderer:
|
| 168 |
+
def __init__(self, encode, readout_cfg, max_len=CONTEXT_LIMIT, head_max=HARD_HEAD_MAX):
|
| 169 |
+
if readout_cfg.get("format") != READOUT_FORMAT or readout_cfg.get("template") != TEMPLATE_VERSION:
|
| 170 |
+
raise ValueError("readout_config.json is not a macjev-readout-v1 / macjev-render-v1 config")
|
| 171 |
+
if readout_cfg.get("readout") != "verdict":
|
| 172 |
+
raise ValueError("this runtime implements the verdict readout only")
|
| 173 |
+
if not 0 < int(max_len) <= CONTEXT_LIMIT:
|
| 174 |
+
raise ValueError(f"max_len must be in 1..{CONTEXT_LIMIT}")
|
| 175 |
+
if not 0 < int(head_max) <= HARD_HEAD_MAX:
|
| 176 |
+
raise ValueError(f"head_max must be in 1..{HARD_HEAD_MAX}")
|
| 177 |
+
self.enc, self.max_len, self.head_max = encode, int(max_len), int(head_max)
|
| 178 |
+
st = readout_cfg["slot_tokens"]
|
| 179 |
+
self.yes, self.no, arrow = int(st["yes"]["id"]), int(st["no"]["id"]), int(st["verdict_slot"]["id"])
|
| 180 |
+
for text, want in ((" yes", self.yes), (" no", self.no), (" ->", arrow)):
|
| 181 |
+
got = self.enc(text)
|
| 182 |
+
if got != [want]:
|
| 183 |
+
raise ValueError(f"tokenizer mismatch: {text!r} -> {got}, readout_config expects [{want}]")
|
| 184 |
+
self.arrow = [arrow]
|
| 185 |
+
self.newline = self.enc("\n")
|
| 186 |
+
self.dash = self.enc("- ")
|
| 187 |
+
self.judge = self.enc("Judge each option:\n")
|
| 188 |
+
|
| 189 |
+
def prefix_ids(self, state):
|
| 190 |
+
return self.enc("State:\n") + self.enc(serialize_state(state)) + self.enc("\n\n")
|
| 191 |
+
|
| 192 |
+
def render(self, state, question, head_max=None, max_len=None):
|
| 193 |
+
head_max = self.head_max if head_max is None else int(head_max)
|
| 194 |
+
max_len = self.max_len if max_len is None else min(int(max_len), self.max_len)
|
| 195 |
+
if head_max > HARD_HEAD_MAX:
|
| 196 |
+
raise InputBudgetError(f"head_max may not exceed {HARD_HEAD_MAX}")
|
| 197 |
+
names = option_names(question)
|
| 198 |
+
opts = [self.enc(o) for o in render_options(question)]
|
| 199 |
+
suffix = self.enc(f"Question [{question['t']}]: {question['ins']}\nOptions:\n")
|
| 200 |
+
for o in opts:
|
| 201 |
+
suffix += self.dash + o + self.newline
|
| 202 |
+
suffix += self.judge
|
| 203 |
+
rel = []
|
| 204 |
+
for o in opts:
|
| 205 |
+
suffix += o + self.arrow
|
| 206 |
+
rel.append(len(suffix) - 1)
|
| 207 |
+
suffix += self.newline
|
| 208 |
+
if len(suffix) > head_max:
|
| 209 |
+
raise InputBudgetError(f"question + options + readout need {len(suffix)} tokens; the head budget is "
|
| 210 |
+
f"{head_max} (hard cap {HARD_HEAD_MAX}). Nothing was truncated: shorten the "
|
| 211 |
+
f"question/options or split the options over several questions.")
|
| 212 |
+
prefix = self.prefix_ids(state)
|
| 213 |
+
ids = prefix + suffix
|
| 214 |
+
if len(ids) > max_len:
|
| 215 |
+
raise InputBudgetError(f"input needs {len(ids)} tokens (state {len(prefix)} + head {len(suffix)}); the "
|
| 216 |
+
f"limit is {max_len} (model maximum {CONTEXT_LIMIT}). Nothing was truncated: "
|
| 217 |
+
f"shorten the state.")
|
| 218 |
+
return Rendered(ids, len(prefix), [len(prefix) + s for s in rel], names, len(suffix))
|
| 219 |
+
|
| 220 |
+
|
| 221 |
+
# -- calibration ----------------------------------------------------------------------------------
|
| 222 |
+
def family(category):
|
| 223 |
+
for prefix, fam in FAMILY_BY_CATEGORY_PREFIX:
|
| 224 |
+
if category.startswith(prefix):
|
| 225 |
+
return fam
|
| 226 |
+
return "other"
|
| 227 |
+
|
| 228 |
+
|
| 229 |
+
def option_bucket(k):
|
| 230 |
+
return "2" if k <= 2 else "3-5" if k <= 5 else "6-10" if k <= 10 else "11-20" if k <= 20 else "21+"
|
| 231 |
+
|
| 232 |
+
|
| 233 |
+
def lookup_temperature(temps, category, qtype, n_options):
|
| 234 |
+
"""Calibration temperature. ``category`` None/"" -> the global temperature; otherwise the fitted
|
| 235 |
+
group (family(category) x qtype x option bucket), falling back to the global temperature."""
|
| 236 |
+
g = None
|
| 237 |
+
if category:
|
| 238 |
+
g = (temps.get("groups") or {}).get(f"{family(category)}|{qtype}|{option_bucket(n_options)}")
|
| 239 |
+
t = g["T"] if g else temps.get("global", 1.0)
|
| 240 |
+
lo, hi = temps.get("clamp", [0.3, 5.0])
|
| 241 |
+
return float(min(hi, max(lo, t)))
|
| 242 |
+
|
| 243 |
+
|
| 244 |
+
def concentration(p):
|
| 245 |
+
k = len(p)
|
| 246 |
+
if k < 2:
|
| 247 |
+
return 1.0
|
| 248 |
+
ent = -(p * np.log(np.clip(p, 1e-12, 1.0))).sum()
|
| 249 |
+
return float(np.clip(1.0 - ent / math.log(k), 0.0, 1.0))
|
| 250 |
+
|
| 251 |
+
|
| 252 |
+
def _sha256(path):
|
| 253 |
+
h = hashlib.sha256()
|
| 254 |
+
with open(path, "rb") as f:
|
| 255 |
+
for b in iter(lambda: f.read(1 << 22), b""):
|
| 256 |
+
h.update(b)
|
| 257 |
+
return h.hexdigest()
|
| 258 |
+
|
| 259 |
+
|
| 260 |
+
def verify_manifest(model_dir, only=None):
|
| 261 |
+
"""Re-hash the files listed in manifest.json (all, or those whose path starts with one of ``only``).
|
| 262 |
+
Documentation (README.md, figures/, assets/) is recorded in the manifest but not checked here, so
|
| 263 |
+
a card edit never makes the runtime refuse to load."""
|
| 264 |
+
model_dir = Path(model_dir)
|
| 265 |
+
man = json.loads((model_dir / "manifest.json").read_text())
|
| 266 |
+
bad, missing, checked = [], [], 0
|
| 267 |
+
for name, rec in man["files"].items():
|
| 268 |
+
if name == "README.md" or name.startswith(("assets/", "figures/")):
|
| 269 |
+
continue
|
| 270 |
+
if only and not any(name == o or name.startswith(o.rstrip("/") + "/") for o in only):
|
| 271 |
+
continue
|
| 272 |
+
p = model_dir / name
|
| 273 |
+
if not p.exists():
|
| 274 |
+
missing.append(name)
|
| 275 |
+
elif _sha256(p) != rec["sha256"]:
|
| 276 |
+
bad.append(name)
|
| 277 |
+
checked += 1
|
| 278 |
+
return {"ok": not bad and not missing, "checked": checked, "bad": bad, "missing": missing}
|
| 279 |
+
|
| 280 |
+
|
| 281 |
+
class DecisionBase:
|
| 282 |
+
"""Backend-independent part. Subclasses implement ``_scores(rendered) -> list[float]`` and may
|
| 283 |
+
override ``_scores_many(list of rendered) -> list of list[float]`` (several questions, one state).
|
| 284 |
+
|
| 285 |
+
Calibration: ``category`` (constructor default or per call) selects the fitted group temperature
|
| 286 |
+
of that category's family; with no category anywhere, the global temperature of
|
| 287 |
+
readout_config.json (temperatures.global) is used."""
|
| 288 |
+
backend = "base"
|
| 289 |
+
|
| 290 |
+
def _setup(self, model_dir, tokenizer_json, category=None, head_max=HARD_HEAD_MAX, max_len=CONTEXT_LIMIT):
|
| 291 |
+
self.model_dir = Path(model_dir)
|
| 292 |
+
self.readout_config = json.loads((self.model_dir / "readout_config.json").read_text())
|
| 293 |
+
self.temperatures = self.readout_config["temperatures"]
|
| 294 |
+
self.default_category = category or None # None -> temperatures.global
|
| 295 |
+
self.encode = TextEncoder(tokenizer_json)
|
| 296 |
+
self.renderer = Renderer(self.encode, self.readout_config, max_len=max_len, head_max=head_max)
|
| 297 |
+
|
| 298 |
+
def temperature(self, question, category=None):
|
| 299 |
+
"""T for ``question``: group temperature of ``category`` (or the constructor's default category);
|
| 300 |
+
the global temperature when neither is given."""
|
| 301 |
+
return lookup_temperature(self.temperatures, category or self.default_category, question["t"],
|
| 302 |
+
len(option_names(question)))
|
| 303 |
+
|
| 304 |
+
def _scores_many(self, rendered):
|
| 305 |
+
return [self._scores(r) for r in rendered]
|
| 306 |
+
|
| 307 |
+
def _result(self, r, q, scores, category=None, temperature=None):
|
| 308 |
+
scores = [float(x) for x in scores]
|
| 309 |
+
t = float(temperature) if temperature is not None else self.temperature(q, category)
|
| 310 |
+
z = np.asarray(scores, float) / t
|
| 311 |
+
if not np.all(np.isfinite(z)):
|
| 312 |
+
raise FloatingPointError("non-finite decision scores")
|
| 313 |
+
p = np.exp(z - z.max())
|
| 314 |
+
p /= p.sum()
|
| 315 |
+
i = int(p.argmax())
|
| 316 |
+
return {"answer": r.names[i], "probabilities": dict(zip(r.names, p.tolist())),
|
| 317 |
+
"scores": dict(zip(r.names, scores)), "temperature": t, "top_probability": float(p[i]),
|
| 318 |
+
"entropy_concentration": concentration(p), "input_tokens": len(r.ids), "head_tokens": r.head_tokens,
|
| 319 |
+
"model": MODEL_NAME, "backend": self.backend}
|
| 320 |
+
|
| 321 |
+
def decide(self, state, question, options=None, qtype=None, category=None, temperature=None, head_max=None):
|
| 322 |
+
"""Score one question about ``state``.
|
| 323 |
+
|
| 324 |
+
Returns {"answer", "probabilities" {option: p}, "scores" {option: logit(yes)-logit(no)},
|
| 325 |
+
"temperature", "top_probability", "entropy_concentration", "input_tokens", "head_tokens"}.
|
| 326 |
+
Temperature: with no ``category`` (here or in the constructor) the global temperature of
|
| 327 |
+
readout_config.json is used; ``category`` picks the fitted group temperature of its family
|
| 328 |
+
(e.g. "mac_gate", "general_topic", "theme_routing", "intent", "typed_official");
|
| 329 |
+
``temperature`` overrides both (1.0 = uncalibrated scores).
|
| 330 |
+
Raises InputBudgetError (never truncates) or QuestionError.
|
| 331 |
+
"""
|
| 332 |
+
q = make_question(question, options, qtype)
|
| 333 |
+
r = self.renderer.render(state, q, head_max=head_max)
|
| 334 |
+
return self._result(r, q, self._scores(r), category, temperature)
|
| 335 |
+
|
| 336 |
+
def decide_many(self, state, questions, category=None, temperature=None, head_max=None):
|
| 337 |
+
"""Several questions about the same state (each a dict {"t","ins","crit"}); results in order.
|
| 338 |
+
Same outputs as calling decide() per question. The llama.cpp runtime sends all questions in one
|
| 339 |
+
request and shares the state in whole 1,024-token ubatches (see JevStyleDecisionGGUF, also for
|
| 340 |
+
its faster, not bit-identical many_mode="batched"). All questions are rendered and
|
| 341 |
+
budget-checked before any scoring."""
|
| 342 |
+
qs = [make_question(q) for q in questions]
|
| 343 |
+
rs = [self.renderer.render(state, q, head_max=head_max) for q in qs]
|
| 344 |
+
if not rs:
|
| 345 |
+
return []
|
| 346 |
+
return [self._result(r, q, sc, category, temperature) for r, q, sc in zip(rs, qs, self._scores_many(rs))]
|
| 347 |
+
|
| 348 |
+
|
| 349 |
+
def base_arg_parser(description):
|
| 350 |
+
ap = argparse.ArgumentParser(description=description)
|
| 351 |
+
ap.add_argument("--model-dir", default=str(HERE), help="folder with the weights and readout_config.json")
|
| 352 |
+
ap.add_argument("--state", help="state as plain text")
|
| 353 |
+
ap.add_argument("--state-json", help="state as a JSON value")
|
| 354 |
+
ap.add_argument("--question", help="question text (or a JSON question {'t','ins','crit'})")
|
| 355 |
+
ap.add_argument("--options", help="JSON: {name: description} or [names] (choice); [levels] (score)")
|
| 356 |
+
ap.add_argument("--qtype", choices=QTYPES)
|
| 357 |
+
ap.add_argument("--category", help="calibration family key, e.g. mac_gate, general_topic, theme_routing, intent "
|
| 358 |
+
"(default: none -> the global temperature of readout_config.json)")
|
| 359 |
+
ap.add_argument("--temperature", type=float, help="override the calibrated temperature")
|
| 360 |
+
ap.add_argument("--head-max", type=int, default=HARD_HEAD_MAX)
|
| 361 |
+
ap.add_argument("--max-len", type=int, default=CONTEXT_LIMIT)
|
| 362 |
+
ap.add_argument("--jsonl", help="batch mode: input JSON lines {id?, state, question, options?, qtype?, "
|
| 363 |
+
"category?}; one JSON result per line on stdout")
|
| 364 |
+
ap.add_argument("--verify", action="store_true", help="check sha256 of the files in manifest.json first")
|
| 365 |
+
return ap
|
| 366 |
+
|
| 367 |
+
|
| 368 |
+
def run_cli(args, engine):
|
| 369 |
+
def one(rec):
|
| 370 |
+
q = rec["question"]
|
| 371 |
+
return engine.decide(rec.get("state", ""), q, options=rec.get("options"), qtype=rec.get("qtype"),
|
| 372 |
+
category=rec.get("category"), temperature=rec.get("temperature", args.temperature))
|
| 373 |
+
if args.jsonl:
|
| 374 |
+
src = sys.stdin if args.jsonl == "-" else open(args.jsonl, encoding="utf-8")
|
| 375 |
+
for n, line in enumerate(src):
|
| 376 |
+
if not line.strip():
|
| 377 |
+
continue
|
| 378 |
+
rec = json.loads(line)
|
| 379 |
+
rid = rec.get("id", n)
|
| 380 |
+
try:
|
| 381 |
+
out = {"id": rid, **one(rec)}
|
| 382 |
+
except (InputBudgetError, QuestionError) as e:
|
| 383 |
+
out = {"id": rid, "error": f"{type(e).__name__}: {e}"}
|
| 384 |
+
print(json.dumps(out, ensure_ascii=False), flush=True)
|
| 385 |
+
return 0
|
| 386 |
+
if args.question is None:
|
| 387 |
+
raise SystemExit("--question (or --jsonl) is required")
|
| 388 |
+
state = json.loads(args.state_json) if args.state_json is not None else (args.state or "")
|
| 389 |
+
question = args.question
|
| 390 |
+
if question.lstrip().startswith("{"):
|
| 391 |
+
question = json.loads(question)
|
| 392 |
+
rec = {"state": state, "question": question, "options": json.loads(args.options) if args.options else None,
|
| 393 |
+
"qtype": args.qtype, "category": args.category}
|
| 394 |
+
print(json.dumps(one(rec), ensure_ascii=False, indent=2))
|
| 395 |
+
return 0
|
| 396 |
+
# ---------------------------------------------------------------------------- end of shared core
|
| 397 |
+
|
| 398 |
+
|
| 399 |
+
# ---------------------------------------------------------------------------- llama.cpp backend
|
| 400 |
+
import os
|
| 401 |
+
import shutil
|
| 402 |
+
import subprocess
|
| 403 |
+
import threading
|
| 404 |
+
|
| 405 |
+
GGUF_FILES = {q: f"{MODEL_NAME}-{q}.gguf" for q in ("F16", "Q8_0", "Q4_K_M")}
|
| 406 |
+
LLAMA_N_CTX = 32768 # >= 25,600-token context + room for question suffixes
|
| 407 |
+
assert LLAMA_N_CTX >= CONTEXT_LIMIT + 3 * HARD_HEAD_MAX
|
| 408 |
+
MANY_MODES = ("exact", "batched")
|
| 409 |
+
|
| 410 |
+
|
| 411 |
+
def find_scorer(binary=None):
|
| 412 |
+
"""jev-score binary: argument, $JEV_SCORE_BIN, ./build/jev-score, or on PATH."""
|
| 413 |
+
for cand in (binary, os.environ.get("JEV_SCORE_BIN"), HERE / "build" / "jev-score", shutil.which("jev-score")):
|
| 414 |
+
if cand and Path(cand).is_file():
|
| 415 |
+
return Path(cand)
|
| 416 |
+
raise FileNotFoundError("jev-score binary not found: build it with `sh build_jev_score.sh /path/to/llama.cpp` "
|
| 417 |
+
"(see the header of jev_score.cpp), or pass --jev-score / set JEV_SCORE_BIN")
|
| 418 |
+
|
| 419 |
+
|
| 420 |
+
class JevStyleDecisionGGUF(DecisionBase):
|
| 421 |
+
"""llama.cpp runtime. The GGUF is run by ``jev-score`` (jev_score.cpp, a ~350-line libllama
|
| 422 |
+
program shipped in this repo), which reads the " yes" / " no" logits only at the slot positions;
|
| 423 |
+
this class renders inputs with the shipped tokenizer and applies the readout + calibration.
|
| 424 |
+
|
| 425 |
+
quant: "F16" (validated default), "Q8_0" or "Q4_K_M".
|
| 426 |
+
|
| 427 |
+
``decide`` sends one request per question: state + question in one decode ("fused"), the
|
| 428 |
+
validated path.
|
| 429 |
+
|
| 430 |
+
``decide_many`` sends all questions about one state in ONE jev-score request.
|
| 431 |
+
many_mode="exact" (default): results are bit-identical to calling ``decide`` per question
|
| 432 |
+
(and do not depend on which other questions are in the request). llama.cpp decodes in
|
| 433 |
+
ubatches of n_ubatch (1,024) tokens, and the Gated DeltaNet state and the kernel choice depend
|
| 434 |
+
on how the input is split, so only whole ubatches of the state can be shared: the first
|
| 435 |
+
floor(state_tokens / 1024) * 1024 tokens are decoded once and kept, and the rest of the state
|
| 436 |
+
plus each question is decoded on a copy of it, exactly as ``decide`` splits them. States
|
| 437 |
+
shorter than 1,024 tokens share nothing (each question recomputes the state, still in one
|
| 438 |
+
request); the saving grows with the state length.
|
| 439 |
+
many_mode="batched": the whole state is decoded once and all questions go into one decode
|
| 440 |
+
(jev-score "batched" mode, the mode of the published latency figures). It is the fastest
|
| 441 |
+
option but not bit-identical to ``decide``: in our tests probabilities differed by up to 4.4e-4
|
| 442 |
+
(F16, Q8_0) and 1.7e-3 (Q4_K_M), and a near-tied top answer can change (1 of 201 test pairs on
|
| 443 |
+
F16 and on Q8_0); see release_config.json -> runtime_parity -> decide_many.
|
| 444 |
+
"""
|
| 445 |
+
backend = "llama.cpp"
|
| 446 |
+
|
| 447 |
+
def __init__(self, model_dir=HERE, quant="F16", gguf=None, binary=None, category=None, head_max=HARD_HEAD_MAX,
|
| 448 |
+
max_len=CONTEXT_LIMIT, n_gpu_layers=999, threads=None, flash_attn="auto", n_ubatch=1024,
|
| 449 |
+
many_mode="exact", verify=False, stderr=None):
|
| 450 |
+
if many_mode not in MANY_MODES:
|
| 451 |
+
raise ValueError(f"many_mode must be one of {MANY_MODES}, got {many_mode!r}")
|
| 452 |
+
self.many_mode = many_mode
|
| 453 |
+
model_dir = Path(model_dir)
|
| 454 |
+
self.gguf = Path(gguf) if gguf else model_dir / GGUF_FILES[quant.upper()]
|
| 455 |
+
if verify:
|
| 456 |
+
res = verify_manifest(model_dir, only=["tokenizer", "readout_config.json", self.gguf.name])
|
| 457 |
+
if not res["ok"]:
|
| 458 |
+
raise RuntimeError(f"integrity check failed: {res}")
|
| 459 |
+
self._setup(model_dir, model_dir / "tokenizer" / "tokenizer.json", category, head_max, max_len)
|
| 460 |
+
self.binary = find_scorer(binary)
|
| 461 |
+
cmd = [str(self.binary), "--model", str(self.gguf), "--n-ctx", str(LLAMA_N_CTX), "--n-ubatch", str(n_ubatch),
|
| 462 |
+
"--ngl", str(n_gpu_layers), "--flash-attn", flash_attn, "--n-seq-max", "17", "--n-outputs-max", "256"]
|
| 463 |
+
if threads:
|
| 464 |
+
cmd += ["--threads", str(threads)]
|
| 465 |
+
self.proc = subprocess.Popen(cmd, stdin=subprocess.PIPE, stdout=subprocess.PIPE,
|
| 466 |
+
stderr=stderr if stderr is not None else subprocess.DEVNULL, text=True, bufsize=1)
|
| 467 |
+
self._lock = threading.Lock()
|
| 468 |
+
line = self.proc.stdout.readline()
|
| 469 |
+
ready = json.loads(line) if line else {"ready": False, "error": "no output (see stderr)"}
|
| 470 |
+
if not ready.get("ready"):
|
| 471 |
+
raise RuntimeError(f"jev-score failed to start: {ready}")
|
| 472 |
+
self.info = ready
|
| 473 |
+
|
| 474 |
+
def _request(self, req):
|
| 475 |
+
with self._lock:
|
| 476 |
+
self.proc.stdin.write(json.dumps(req) + "\n")
|
| 477 |
+
self.proc.stdin.flush()
|
| 478 |
+
line = self.proc.stdout.readline()
|
| 479 |
+
if not line:
|
| 480 |
+
raise RuntimeError("jev-score exited")
|
| 481 |
+
resp = json.loads(line)
|
| 482 |
+
if "error" in resp:
|
| 483 |
+
raise RuntimeError(f"jev-score: {resp['error']}")
|
| 484 |
+
return resp
|
| 485 |
+
|
| 486 |
+
def _scores(self, r):
|
| 487 |
+
rows = [self.renderer.yes, self.renderer.no]
|
| 488 |
+
resp = self._request({"prefix": r.ids[:r.prefix_len], "share_prefix": True, "keep_prefix": False,
|
| 489 |
+
"mode": "fused",
|
| 490 |
+
"questions": [{"ids": r.ids[r.prefix_len:], "slots": r.slots, "rows": rows}]})
|
| 491 |
+
return [float("nan") if (y is None or n is None) else y - n for y, n in resp["results"][0]["scores"]]
|
| 492 |
+
|
| 493 |
+
def _shared_len(self, n_prefix):
|
| 494 |
+
"""State tokens decoded once in many_mode="exact": whole ubatches only, so that every ubatch
|
| 495 |
+
(and with it the Gated DeltaNet chunking and the llama.cpp kernel choice) is exactly the one
|
| 496 |
+
``decide`` uses; any other split can change the scores by ~1e-3."""
|
| 497 |
+
u = int(self.info.get("n_ubatch") or 1024)
|
| 498 |
+
return (n_prefix // u) * u
|
| 499 |
+
|
| 500 |
+
def _scores_many(self, rendered):
|
| 501 |
+
"""All questions of one state in ONE jev-score request (see the class docstring for many_mode)."""
|
| 502 |
+
if len(rendered) == 1:
|
| 503 |
+
return [self._scores(rendered[0])]
|
| 504 |
+
n_prefix = rendered[0].prefix_len
|
| 505 |
+
prefix = rendered[0].ids[:n_prefix]
|
| 506 |
+
if any(r.prefix_len != n_prefix or r.ids[:n_prefix] != prefix for r in rendered):
|
| 507 |
+
return [self._scores(r) for r in rendered] # not one state: one by one
|
| 508 |
+
batched = self.many_mode == "batched"
|
| 509 |
+
s = n_prefix if batched else self._shared_len(n_prefix)
|
| 510 |
+
rows = [self.renderer.yes, self.renderer.no]
|
| 511 |
+
resp = self._request({"prefix": prefix[:s], "share_prefix": s > 0, "keep_prefix": s > 0,
|
| 512 |
+
"mode": "batched" if batched else "sequential",
|
| 513 |
+
"questions": [{"ids": r.ids[s:], "slots": r.slots, "rows": rows} for r in rendered]})
|
| 514 |
+
self.last_timing = dict(resp.get("timing") or {}, shared_tokens=s, mode=resp.get("mode"))
|
| 515 |
+
return [[float("nan") if (y is None or n is None) else y - n for y, n in res["scores"]]
|
| 516 |
+
for res in resp["results"]]
|
| 517 |
+
|
| 518 |
+
def close(self):
|
| 519 |
+
if getattr(self, "proc", None) and self.proc.poll() is None:
|
| 520 |
+
try:
|
| 521 |
+
self.proc.stdin.write('{"cmd":"quit"}\n')
|
| 522 |
+
self.proc.stdin.flush()
|
| 523 |
+
self.proc.wait(timeout=10)
|
| 524 |
+
except Exception:
|
| 525 |
+
self.proc.kill()
|
| 526 |
+
|
| 527 |
+
def __del__(self):
|
| 528 |
+
try:
|
| 529 |
+
self.close()
|
| 530 |
+
except Exception:
|
| 531 |
+
pass
|
| 532 |
+
|
| 533 |
+
|
| 534 |
+
def main(argv=None):
|
| 535 |
+
ap = base_arg_parser(f"{MODEL_NAME}: typed decisions with llama.cpp (GGUF)")
|
| 536 |
+
ap.add_argument("--quant", default="F16", choices=sorted(GGUF_FILES))
|
| 537 |
+
ap.add_argument("--gguf", help="explicit GGUF path (overrides --quant)")
|
| 538 |
+
ap.add_argument("--jev-score", help="path to the jev-score binary (default: $JEV_SCORE_BIN, ./build/jev-score)")
|
| 539 |
+
ap.add_argument("--ngl", type=int, default=999, help="layers offloaded to the GPU")
|
| 540 |
+
ap.add_argument("--threads", type=int)
|
| 541 |
+
args = ap.parse_args(argv)
|
| 542 |
+
engine = JevStyleDecisionGGUF(args.model_dir, quant=args.quant, gguf=args.gguf, binary=args.jev_score,
|
| 543 |
+
category=args.category, head_max=args.head_max, max_len=args.max_len,
|
| 544 |
+
n_gpu_layers=args.ngl, threads=args.threads, verify=args.verify)
|
| 545 |
+
try:
|
| 546 |
+
return run_cli(args, engine)
|
| 547 |
+
finally:
|
| 548 |
+
engine.close()
|
| 549 |
+
|
| 550 |
+
|
| 551 |
+
if __name__ == "__main__":
|
| 552 |
+
raise SystemExit(main())
|
manifest.json
ADDED
|
@@ -0,0 +1,89 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"format": "jev-style-manifest-v1",
|
| 3 |
+
"repo": "chaoliangUNSW/Jev-Style-0.8B-Decision-v3-GGUF",
|
| 4 |
+
"created_unix": 1790261967.451401,
|
| 5 |
+
"files": {
|
| 6 |
+
"Jev-Style-0.8B-Decision-v3-F16.gguf": {
|
| 7 |
+
"sha256": "a33f709e10009c3fe182b51e4945d440288b137a35ad5d481e4ac1f2800b1a27",
|
| 8 |
+
"bytes": 1516744160
|
| 9 |
+
},
|
| 10 |
+
"Jev-Style-0.8B-Decision-v3-Q4_K_M.gguf": {
|
| 11 |
+
"sha256": "0a19bc29bacc33e0d871146c8612b24dd14c2ed2e61cedeb7a928b0852628bac",
|
| 12 |
+
"bytes": 529296864
|
| 13 |
+
},
|
| 14 |
+
"Jev-Style-0.8B-Decision-v3-Q8_0.gguf": {
|
| 15 |
+
"sha256": "cd87d284c4ee355cb0b3fce7391db57ba3ad108e45b3a41b058d529931a2bd5e",
|
| 16 |
+
"bytes": 811843040
|
| 17 |
+
},
|
| 18 |
+
"LICENSE": {
|
| 19 |
+
"sha256": "bbedc3fda3305820b977265f01b8619d87570a6739de3a5582c3464840f1e57a",
|
| 20 |
+
"bytes": 11544
|
| 21 |
+
},
|
| 22 |
+
"NOTICE": {
|
| 23 |
+
"sha256": "5b20e266b5b9b9c12df4cb53db6801bc08fe8f1471355aaec15c1a9f9aa0b201",
|
| 24 |
+
"bytes": 2585
|
| 25 |
+
},
|
| 26 |
+
"README.md": {
|
| 27 |
+
"sha256": "f39d3a008a7d9285119489551d1993524a9a5083001dd6b65dd2115af9938402",
|
| 28 |
+
"bytes": 7080
|
| 29 |
+
},
|
| 30 |
+
"build_jev_score.sh": {
|
| 31 |
+
"sha256": "5789a1585c51fbc4a03b423099a451e05cb66b9db49bc6c9361f326aca170fda",
|
| 32 |
+
"bytes": 1399
|
| 33 |
+
},
|
| 34 |
+
"figures/latency.data.json": {
|
| 35 |
+
"sha256": "c0eb510a69dfe1b1cd85beca6ba3c354be4984d588b4aae2672331606a119cbc",
|
| 36 |
+
"bytes": 1402
|
| 37 |
+
},
|
| 38 |
+
"figures/latency.png": {
|
| 39 |
+
"sha256": "d6d0d34b875997b8a733d4776dc34a1b564ddc64b48cea9d0def7f72a34af79e",
|
| 40 |
+
"bytes": 203081
|
| 41 |
+
},
|
| 42 |
+
"figures/latency.svg": {
|
| 43 |
+
"sha256": "c7bdf011eec488aae7197d653cb8486dfd8ccbd1a58f5ba222873de7410aca30",
|
| 44 |
+
"bytes": 24079
|
| 45 |
+
},
|
| 46 |
+
"figures/quantization.data.json": {
|
| 47 |
+
"sha256": "a140816ef145a6dd096ef471e4afbff1cecd33adb663c6cb856e19845349fc2d",
|
| 48 |
+
"bytes": 5473
|
| 49 |
+
},
|
| 50 |
+
"figures/quantization.png": {
|
| 51 |
+
"sha256": "bc75c212caa11008ca929a685d3085040c2b4698afb58d04a0ad692b815be230",
|
| 52 |
+
"bytes": 253992
|
| 53 |
+
},
|
| 54 |
+
"figures/quantization.svg": {
|
| 55 |
+
"sha256": "70720bb46ec1e718dcbfac9a83d3b5d11d50b3a5cc3356915465d70d95f3d43b",
|
| 56 |
+
"bytes": 28756
|
| 57 |
+
},
|
| 58 |
+
"jev_score.cpp": {
|
| 59 |
+
"sha256": "90d848a61546286c74e484f61126f572b79c6f77f835450d8fc970b8547ce603",
|
| 60 |
+
"bytes": 18088
|
| 61 |
+
},
|
| 62 |
+
"jev_style_decision_gguf.py": {
|
| 63 |
+
"sha256": "2db954a8a0792668c2d6c051fc8149e695675968cf32c52003f95820fdd95c5a",
|
| 64 |
+
"bytes": 28332
|
| 65 |
+
},
|
| 66 |
+
"readout_config.json": {
|
| 67 |
+
"sha256": "01de9bcce7effbfd1ae0a3fa13e52d7fa9aa4dd1cd1e47977d6bbdcd5e63054a",
|
| 68 |
+
"bytes": 6236
|
| 69 |
+
},
|
| 70 |
+
"release_config.json": {
|
| 71 |
+
"sha256": "5e2abbf2cf2e2e6d5b1a33bc299d779933bd1e3eef46321938e10f687d41585a",
|
| 72 |
+
"bytes": 17114
|
| 73 |
+
},
|
| 74 |
+
"requirements.txt": {
|
| 75 |
+
"sha256": "632dbfd22eefe09f9008e6437f2849c674c067080473eb5e9d7d3f5910f425eb",
|
| 76 |
+
"bytes": 204
|
| 77 |
+
},
|
| 78 |
+
"tokenizer/tokenizer.json": {
|
| 79 |
+
"sha256": "06b9509352d2af50381ab2247e083b80d32d5c0aba91c272ca9ff729b6a0e523",
|
| 80 |
+
"bytes": 19989325
|
| 81 |
+
},
|
| 82 |
+
"tokenizer/tokenizer_config.json": {
|
| 83 |
+
"sha256": "66e427c470fe580fe8c7b5725d857af23d8417e37fae62667ec698306a19987b",
|
| 84 |
+
"bytes": 1124
|
| 85 |
+
}
|
| 86 |
+
},
|
| 87 |
+
"readme_hashed": true,
|
| 88 |
+
"note": "manifest.json hashes every file of the repo except itself, README.md and figures/ included. The runtime --verify check skips the documentation (README.md, figures/, assets/) and checks every other file."
|
| 89 |
+
}
|
readout_config.json
ADDED
|
@@ -0,0 +1,247 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"format": "macjev-readout-v1",
|
| 3 |
+
"model_name": "Jev-Style-0.8B-Decision-v3",
|
| 4 |
+
"readout": "verdict",
|
| 5 |
+
"template": "macjev-render-v1",
|
| 6 |
+
"slot_tokens": {
|
| 7 |
+
"yes": {
|
| 8 |
+
"text": " yes",
|
| 9 |
+
"id": 9542
|
| 10 |
+
},
|
| 11 |
+
"no": {
|
| 12 |
+
"text": " no",
|
| 13 |
+
"id": 874
|
| 14 |
+
},
|
| 15 |
+
"verdict_slot": {
|
| 16 |
+
"text": " ->",
|
| 17 |
+
"id": 1411
|
| 18 |
+
},
|
| 19 |
+
"letters": {
|
| 20 |
+
"A": 357,
|
| 21 |
+
"B": 417,
|
| 22 |
+
"C": 351,
|
| 23 |
+
"D": 414,
|
| 24 |
+
"E": 458,
|
| 25 |
+
"F": 426,
|
| 26 |
+
"G": 469,
|
| 27 |
+
"H": 462,
|
| 28 |
+
"I": 353,
|
| 29 |
+
"J": 604,
|
| 30 |
+
"K": 710,
|
| 31 |
+
"L": 436,
|
| 32 |
+
"M": 380,
|
| 33 |
+
"N": 443,
|
| 34 |
+
"O": 496,
|
| 35 |
+
"P": 387,
|
| 36 |
+
"Q": 1167,
|
| 37 |
+
"R": 423,
|
| 38 |
+
"S": 326,
|
| 39 |
+
"T": 345,
|
| 40 |
+
"U": 533,
|
| 41 |
+
"V": 629,
|
| 42 |
+
"W": 457,
|
| 43 |
+
"X": 1543,
|
| 44 |
+
"Y": 783,
|
| 45 |
+
"Z": 1799,
|
| 46 |
+
"a": 264,
|
| 47 |
+
"b": 292,
|
| 48 |
+
"c": 272,
|
| 49 |
+
"d": 293,
|
| 50 |
+
"e": 378,
|
| 51 |
+
"f": 281,
|
| 52 |
+
"g": 338,
|
| 53 |
+
"h": 304,
|
| 54 |
+
"i": 585,
|
| 55 |
+
"j": 492,
|
| 56 |
+
"k": 580,
|
| 57 |
+
"l": 324,
|
| 58 |
+
"m": 295,
|
| 59 |
+
"n": 307,
|
| 60 |
+
"o": 296,
|
| 61 |
+
"p": 280,
|
| 62 |
+
"q": 2715,
|
| 63 |
+
"r": 427,
|
| 64 |
+
"s": 274,
|
| 65 |
+
"t": 259,
|
| 66 |
+
"u": 560,
|
| 67 |
+
"v": 343,
|
| 68 |
+
"w": 288,
|
| 69 |
+
"x": 830,
|
| 70 |
+
"y": 374,
|
| 71 |
+
"z": 1110
|
| 72 |
+
}
|
| 73 |
+
},
|
| 74 |
+
"score": "per option k: logit[' yes'] - logit[' no'] at the k-th ' ->' slot, computed as h_slot . (w_yes - w_no) from the final normed hidden state and the tied embedding rows (float32)",
|
| 75 |
+
"probabilities": "softmax(scores / T); T = temperatures.groups['<family>|<qtype>|<option bucket>'].T (else temperatures.global), clamped to temperatures.clamp",
|
| 76 |
+
"families": {
|
| 77 |
+
"typed_official*": "typed",
|
| 78 |
+
"typed_synthetic*": "typed_synth",
|
| 79 |
+
"general_*": "general",
|
| 80 |
+
"intent*": "intent",
|
| 81 |
+
"nli*": "nli",
|
| 82 |
+
"theme_*": "theme",
|
| 83 |
+
"mac_*": "mac",
|
| 84 |
+
"long_*": "long",
|
| 85 |
+
"anything else": "other (global T)"
|
| 86 |
+
},
|
| 87 |
+
"option_buckets": [
|
| 88 |
+
"2",
|
| 89 |
+
"3-5",
|
| 90 |
+
"6-10",
|
| 91 |
+
"11-20",
|
| 92 |
+
"21+"
|
| 93 |
+
],
|
| 94 |
+
"default_category": null,
|
| 95 |
+
"default_category_note": "no category given -> temperatures.global (the global temperature); pass category=... for the fitted group temperature of that category's family",
|
| 96 |
+
"tokenizer_sha256": "06b9509352d2af50381ab2247e083b80d32d5c0aba91c272ca9ff729b6a0e523",
|
| 97 |
+
"budgets": {
|
| 98 |
+
"max_len": 25600,
|
| 99 |
+
"head_max": 2048,
|
| 100 |
+
"hard_head_max": 2048,
|
| 101 |
+
"note": "whole input <= max_len tokens, question+options+readout <= head_max; larger inputs raise InputBudgetError, nothing is truncated"
|
| 102 |
+
},
|
| 103 |
+
"temperatures": {
|
| 104 |
+
"version": "macjev-temperatures-v1",
|
| 105 |
+
"global": 0.8800546821789332,
|
| 106 |
+
"groups": {
|
| 107 |
+
"general|choice|3-5": {
|
| 108 |
+
"T": 0.8563796906101172,
|
| 109 |
+
"T_raw": 0.8524962478467872,
|
| 110 |
+
"n": 600,
|
| 111 |
+
"weight": 0.8571428571428571
|
| 112 |
+
},
|
| 113 |
+
"general|choice|6-10": {
|
| 114 |
+
"T": 0.7883347591845132,
|
| 115 |
+
"T_raw": 0.7797058230459033,
|
| 116 |
+
"n": 1000,
|
| 117 |
+
"weight": 0.9090909090909091
|
| 118 |
+
},
|
| 119 |
+
"general|noul|2": {
|
| 120 |
+
"T": 0.9702474579038656,
|
| 121 |
+
"T_raw": 1.0023209290239254,
|
| 122 |
+
"n": 300,
|
| 123 |
+
"weight": 0.75
|
| 124 |
+
},
|
| 125 |
+
"general|score|3-5": {
|
| 126 |
+
"T": 0.9583320444900012,
|
| 127 |
+
"T_raw": 0.9748039508642105,
|
| 128 |
+
"n": 500,
|
| 129 |
+
"weight": 0.8333333333333334
|
| 130 |
+
},
|
| 131 |
+
"intent|choice|11-20": {
|
| 132 |
+
"T": 0.8536586990515279,
|
| 133 |
+
"T_raw": 0.8530447902066461,
|
| 134 |
+
"n": 4233,
|
| 135 |
+
"weight": 0.9769213016385876
|
| 136 |
+
},
|
| 137 |
+
"intent|choice|21+": {
|
| 138 |
+
"T": 0.7508751181814466,
|
| 139 |
+
"T_raw": 0.737974406022733,
|
| 140 |
+
"n": 916,
|
| 141 |
+
"weight": 0.9015748031496063
|
| 142 |
+
},
|
| 143 |
+
"long|choice|2": {
|
| 144 |
+
"T": 1.0101601686032944,
|
| 145 |
+
"T_raw": 2.5327604766936602,
|
| 146 |
+
"n": 15,
|
| 147 |
+
"weight": 0.13043478260869565
|
| 148 |
+
},
|
| 149 |
+
"long|choice|3-5": {
|
| 150 |
+
"T": 0.9789458925825579,
|
| 151 |
+
"T_raw": 0.9984431087771811,
|
| 152 |
+
"n": 540,
|
| 153 |
+
"weight": 0.84375
|
| 154 |
+
},
|
| 155 |
+
"long|choice|6-10": {
|
| 156 |
+
"T": 0.6918332634850016,
|
| 157 |
+
"T_raw": 0.6260903832047418,
|
| 158 |
+
"n": 241,
|
| 159 |
+
"weight": 0.7067448680351907
|
| 160 |
+
},
|
| 161 |
+
"long|noul|2": {
|
| 162 |
+
"T": 0.8183260460233314,
|
| 163 |
+
"T_raw": 0.7857458244621078,
|
| 164 |
+
"n": 179,
|
| 165 |
+
"weight": 0.6415770609318996
|
| 166 |
+
},
|
| 167 |
+
"long|score|3-5": {
|
| 168 |
+
"T": 0.8412851094005789,
|
| 169 |
+
"T_raw": 0.7952160414763221,
|
| 170 |
+
"n": 80,
|
| 171 |
+
"weight": 0.4444444444444444
|
| 172 |
+
},
|
| 173 |
+
"mac|choice|3-5": {
|
| 174 |
+
"T": 0.7640449061346866,
|
| 175 |
+
"T_raw": 0.753267027600698,
|
| 176 |
+
"n": 995,
|
| 177 |
+
"weight": 0.908675799086758
|
| 178 |
+
},
|
| 179 |
+
"mac|noul|2": {
|
| 180 |
+
"T": 0.922463080251143,
|
| 181 |
+
"T_raw": 0.9300179680535603,
|
| 182 |
+
"n": 577,
|
| 183 |
+
"weight": 0.8522895125553914
|
| 184 |
+
},
|
| 185 |
+
"mac|score|3-5": {
|
| 186 |
+
"T": 2.729450780811877,
|
| 187 |
+
"T_raw": 4.999707266277221,
|
| 188 |
+
"n": 187,
|
| 189 |
+
"weight": 0.6515679442508711
|
| 190 |
+
},
|
| 191 |
+
"nli|choice|3-5": {
|
| 192 |
+
"T": 1.003611674961589,
|
| 193 |
+
"T_raw": 1.0108425661039413,
|
| 194 |
+
"n": 1830,
|
| 195 |
+
"weight": 0.9481865284974094
|
| 196 |
+
},
|
| 197 |
+
"theme|choice|6-10": {
|
| 198 |
+
"T": 0.9848729122522978,
|
| 199 |
+
"T_raw": 0.9981552921230235,
|
| 200 |
+
"n": 840,
|
| 201 |
+
"weight": 0.8936170212765957
|
| 202 |
+
},
|
| 203 |
+
"theme|noul|2": {
|
| 204 |
+
"T": 0.896799495386032,
|
| 205 |
+
"T_raw": 0.89763584528285,
|
| 206 |
+
"n": 2022,
|
| 207 |
+
"weight": 0.9528746465598492
|
| 208 |
+
},
|
| 209 |
+
"typed|choice|3-5": {
|
| 210 |
+
"T": 0.9751541851571508,
|
| 211 |
+
"T_raw": 1.0336976619219436,
|
| 212 |
+
"n": 176,
|
| 213 |
+
"weight": 0.6376811594202898
|
| 214 |
+
},
|
| 215 |
+
"typed|noul|2": {
|
| 216 |
+
"T": 0.9892589014450378,
|
| 217 |
+
"T_raw": 1.054189849787923,
|
| 218 |
+
"n": 184,
|
| 219 |
+
"weight": 0.647887323943662
|
| 220 |
+
},
|
| 221 |
+
"typed|score|3-5": {
|
| 222 |
+
"T": 1.0056628114581752,
|
| 223 |
+
"T_raw": 1.0631515969968885,
|
| 224 |
+
"n": 240,
|
| 225 |
+
"weight": 0.7058823529411765
|
| 226 |
+
}
|
| 227 |
+
},
|
| 228 |
+
"clamp": [
|
| 229 |
+
0.3,
|
| 230 |
+
5.0
|
| 231 |
+
],
|
| 232 |
+
"shrinkage_k": 100.0,
|
| 233 |
+
"key": "family|qtype|option_bucket",
|
| 234 |
+
"n_rows": 15655,
|
| 235 |
+
"fitted_on": [
|
| 236 |
+
"pool_cal.jsonl:dfb7e9beff96c6c5"
|
| 237 |
+
],
|
| 238 |
+
"fit_quality": {
|
| 239 |
+
"nll_before": 0.37752055301970966,
|
| 240 |
+
"nll_after": 0.36671188108641545,
|
| 241 |
+
"ece_before": 0.03289307373502533,
|
| 242 |
+
"ece_after": 0.011376234101433989,
|
| 243 |
+
"n": 15655
|
| 244 |
+
}
|
| 245 |
+
},
|
| 246 |
+
"temperatures_sha256": "39ad8f6633934ff67770725993d7354ebebd6e7a08f73e50cab04df24715f2ce"
|
| 247 |
+
}
|
release_config.json
ADDED
|
@@ -0,0 +1,425 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"format": "jev-style-release-v1",
|
| 3 |
+
"model_name": "Jev-Style-0.8B-Decision-v3",
|
| 4 |
+
"repo": "chaoliangUNSW/Jev-Style-0.8B-Decision-v3-GGUF",
|
| 5 |
+
"generation": "v3 (third generation of the Jev-Style decision series)",
|
| 6 |
+
"lineage": {
|
| 7 |
+
"v1": "chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision",
|
| 8 |
+
"v1_public_gguf": "chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision-GGUF",
|
| 9 |
+
"v2": "chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision-v2",
|
| 10 |
+
"v3": "chaoliangUNSW/Jev-Style-0.8B-Decision-v3"
|
| 11 |
+
},
|
| 12 |
+
"base_model": "Qwen/Qwen3.5-0.8B",
|
| 13 |
+
"base_model_revision": "2fc06364715b967f1860aea9cf38778875588b17",
|
| 14 |
+
"base_model_relation": "finetune",
|
| 15 |
+
"architecture": "Qwen3_5ForCausalLM (text only, 24 layers: 18 Gated DeltaNet + 6 full attention, hidden 1024, tied embeddings, 752,393,024 parameters)",
|
| 16 |
+
"readout": "verdict",
|
| 17 |
+
"template": "macjev-render-v1",
|
| 18 |
+
"readout_config": "readout_config.json",
|
| 19 |
+
"budgets": {
|
| 20 |
+
"max_len": 25600,
|
| 21 |
+
"head_max": 2048
|
| 22 |
+
},
|
| 23 |
+
"source": {
|
| 24 |
+
"checkpoint_sha256": {
|
| 25 |
+
"best-0.safetensors": "b10d249adfa3e1475f0f633ab961130c06f16c898db23c846b035d24bdc5c945"
|
| 26 |
+
},
|
| 27 |
+
"text_only_model_safetensors_sha256": "0f8c861605dcdfb356a63e056baa2106e81042e8981e8d0d26fe50b34599541e",
|
| 28 |
+
"release_manifest_sha256": "4bc9f89795ccf2d749008de7739bc5294f3ec543404ca2db9cac6a3914cfb84a",
|
| 29 |
+
"llama_cpp_commit": "441df11f65ea0b6d0c72965aaf70c8241070ddcb",
|
| 30 |
+
"mlx": "0.32.2",
|
| 31 |
+
"mlx_lm": "0.31.3"
|
| 32 |
+
},
|
| 33 |
+
"calibration": {
|
| 34 |
+
"version": "macjev-temperatures-v1",
|
| 35 |
+
"global_T": 0.8800546821789332,
|
| 36 |
+
"groups": 20,
|
| 37 |
+
"n_rows": 15655,
|
| 38 |
+
"fit_quality": {
|
| 39 |
+
"nll_before": 0.37752055301970966,
|
| 40 |
+
"nll_after": 0.36671188108641545,
|
| 41 |
+
"ece_before": 0.03289307373502533,
|
| 42 |
+
"ece_after": 0.011376234101433989,
|
| 43 |
+
"n": 15655
|
| 44 |
+
},
|
| 45 |
+
"fitted_on": "calibration pool (dev/cal rows, never test rows)"
|
| 46 |
+
},
|
| 47 |
+
"g5_parity": {
|
| 48 |
+
"reference": "PyTorch float32 (same weights, same rendered inputs)",
|
| 49 |
+
"rows": 240,
|
| 50 |
+
"rows_note": "non-sealed training-distribution rows, 22 categories, en 215 / zh 25",
|
| 51 |
+
"report_sha256": "056dc3a3d1de5616f97dab3f8b5ec1f7e2c6c85258aa03f2a57b9fd65a71022b",
|
| 52 |
+
"g5_pass": true,
|
| 53 |
+
"verdict_readout": {
|
| 54 |
+
"gguf-f16": {
|
| 55 |
+
"top1_agreement": 1.0,
|
| 56 |
+
"dnll": 2.436279701012456e-05,
|
| 57 |
+
"n": 240,
|
| 58 |
+
"nan_rows": 0,
|
| 59 |
+
"gate": "top1>=0.99, |dNLL|<=0.02, no NaN, every reference row scored",
|
| 60 |
+
"pass": true
|
| 61 |
+
},
|
| 62 |
+
"gguf-q8_0": {
|
| 63 |
+
"top1_agreement": 1.0,
|
| 64 |
+
"dnll": -3.093173930673876e-05,
|
| 65 |
+
"n": 240,
|
| 66 |
+
"nan_rows": 0,
|
| 67 |
+
"gate": "top1>=0.98, |dNLL|<=0.02, no NaN, every reference row scored",
|
| 68 |
+
"pass": true
|
| 69 |
+
},
|
| 70 |
+
"gguf-q4_k_m": {
|
| 71 |
+
"top1_agreement": 1.0,
|
| 72 |
+
"dnll": 0.006187511546346225,
|
| 73 |
+
"n": 240,
|
| 74 |
+
"nan_rows": 0,
|
| 75 |
+
"gate": "report_only",
|
| 76 |
+
"pass": true
|
| 77 |
+
},
|
| 78 |
+
"mlx-bf16": {
|
| 79 |
+
"top1_agreement": 1.0,
|
| 80 |
+
"dnll": 0.00031018251516545803,
|
| 81 |
+
"n": 240,
|
| 82 |
+
"nan_rows": 0,
|
| 83 |
+
"gate": "top1>=0.99, |dNLL|<=0.02, no NaN, every reference row scored",
|
| 84 |
+
"pass": true
|
| 85 |
+
},
|
| 86 |
+
"mlx-bf16-f32act": {
|
| 87 |
+
"top1_agreement": 1.0,
|
| 88 |
+
"dnll": 0.00015659911501769708,
|
| 89 |
+
"n": 240,
|
| 90 |
+
"nan_rows": 0,
|
| 91 |
+
"gate": "top1>=0.99, |dNLL|<=0.02, no NaN, every reference row scored",
|
| 92 |
+
"pass": true
|
| 93 |
+
},
|
| 94 |
+
"mlx-8bit": {
|
| 95 |
+
"top1_agreement": 1.0,
|
| 96 |
+
"dnll": 0.00023178691602621093,
|
| 97 |
+
"n": 240,
|
| 98 |
+
"nan_rows": 0,
|
| 99 |
+
"gate": "top1>=0.98, |dNLL|<=0.02, no NaN, every reference row scored",
|
| 100 |
+
"pass": true
|
| 101 |
+
},
|
| 102 |
+
"mlx-4bit": {
|
| 103 |
+
"top1_agreement": 0.9875,
|
| 104 |
+
"dnll": 0.010326217052955111,
|
| 105 |
+
"n": 240,
|
| 106 |
+
"nan_rows": 0,
|
| 107 |
+
"gate": "report_only",
|
| 108 |
+
"pass": true
|
| 109 |
+
}
|
| 110 |
+
},
|
| 111 |
+
"gates": "top-1 >= 0.99 (16-bit) / >= 0.98 (8-bit), |dNLL| <= 0.02, no NaN; 4-bit report-only"
|
| 112 |
+
},
|
| 113 |
+
"decision_index": "not run for this release (optional follow-up)",
|
| 114 |
+
"related_repos": {
|
| 115 |
+
"main": "chaoliangUNSW/Jev-Style-0.8B-Decision-v3",
|
| 116 |
+
"gguf": "chaoliangUNSW/Jev-Style-0.8B-Decision-v3-GGUF",
|
| 117 |
+
"mlx-bf16": "chaoliangUNSW/Jev-Style-0.8B-Decision-v3-MLX-bf16",
|
| 118 |
+
"mlx-8bit": "chaoliangUNSW/Jev-Style-0.8B-Decision-v3-MLX-8bit"
|
| 119 |
+
},
|
| 120 |
+
"not_released": {
|
| 121 |
+
"mlx-4bit": "affine4-g64 reported only (G5 top-1 0.9875, report-only gate); not released"
|
| 122 |
+
},
|
| 123 |
+
"tested_with": {
|
| 124 |
+
"python": "3.12",
|
| 125 |
+
"torch": "2.14.0",
|
| 126 |
+
"transformers": "5.17.0",
|
| 127 |
+
"tokenizers": "0.23.2",
|
| 128 |
+
"numpy": "2.5.3",
|
| 129 |
+
"mlx": "0.32.2",
|
| 130 |
+
"mlx-lm": "0.31.3",
|
| 131 |
+
"llama.cpp": "441df11f65ea0b6d0c72965aaf70c8241070ddcb"
|
| 132 |
+
},
|
| 133 |
+
"weights": {
|
| 134 |
+
"Jev-Style-0.8B-Decision-v3-F16.gguf": "F16",
|
| 135 |
+
"Jev-Style-0.8B-Decision-v3-Q8_0.gguf": "Q8_0",
|
| 136 |
+
"Jev-Style-0.8B-Decision-v3-Q4_K_M.gguf": "Q4_K_M"
|
| 137 |
+
},
|
| 138 |
+
"runtime": {
|
| 139 |
+
"script": "jev_style_decision_gguf.py",
|
| 140 |
+
"class": "JevStyleDecisionGGUF",
|
| 141 |
+
"engine": "jev-score (jev_score.cpp, libllama; slot-only logits)",
|
| 142 |
+
"default_quant": "F16",
|
| 143 |
+
"n_ctx": 32768
|
| 144 |
+
},
|
| 145 |
+
"gguf_metadata_edit": {
|
| 146 |
+
"what": "general.name set to 'Jev-Style-0.8B-Decision-v3' (metadata only; the exported files had 'Text Only'); tensor data byte-identical",
|
| 147 |
+
"tool": "gguf-py scripts/gguf_new_metadata.py, llama.cpp 441df11f65ea0b6d0c72965aaf70c8241070ddcb",
|
| 148 |
+
"files": {
|
| 149 |
+
"Jev-Style-0.8B-Decision-v3-F16.gguf": {
|
| 150 |
+
"general.name": {
|
| 151 |
+
"source": "Text Only",
|
| 152 |
+
"staged": "Jev-Style-0.8B-Decision-v3"
|
| 153 |
+
},
|
| 154 |
+
"source_file_sha256": "7d75f4925716ca94e1da3e73c239ecbe58fc712fa07c153b3550f59b626aa0e6",
|
| 155 |
+
"source_file_bytes": 1516744128,
|
| 156 |
+
"staged_file_bytes": 1516744160,
|
| 157 |
+
"tensor_count": 320,
|
| 158 |
+
"tensor_data_sha256": "7975b3b7cc4ae95d3a2b651b760ccf8c86ac78b81643c6cea150e1d0bcec231a",
|
| 159 |
+
"tensor_data_offset": {
|
| 160 |
+
"source": 10961088,
|
| 161 |
+
"staged": 10961120
|
| 162 |
+
},
|
| 163 |
+
"checks": {
|
| 164 |
+
"general_name": true,
|
| 165 |
+
"other_kv_identical": true,
|
| 166 |
+
"tensor_table_identical": true,
|
| 167 |
+
"tensor_data_identical": true,
|
| 168 |
+
"source_inode_distinct": true
|
| 169 |
+
}
|
| 170 |
+
},
|
| 171 |
+
"Jev-Style-0.8B-Decision-v3-Q8_0.gguf": {
|
| 172 |
+
"general.name": {
|
| 173 |
+
"source": "Text Only",
|
| 174 |
+
"staged": "Jev-Style-0.8B-Decision-v3"
|
| 175 |
+
},
|
| 176 |
+
"source_file_sha256": "70b3f1fe71bc560374ed4054898da80f0227c40ad12e9edda4c9a2e5c5912a05",
|
| 177 |
+
"source_file_bytes": 811843008,
|
| 178 |
+
"staged_file_bytes": 811843040,
|
| 179 |
+
"tensor_count": 320,
|
| 180 |
+
"tensor_data_sha256": "3f268d647972c13945e05d6c2449d7ad0bcb29ca78fcd546e20eaad92b10e3fe",
|
| 181 |
+
"tensor_data_offset": {
|
| 182 |
+
"source": 10961088,
|
| 183 |
+
"staged": 10961120
|
| 184 |
+
},
|
| 185 |
+
"checks": {
|
| 186 |
+
"general_name": true,
|
| 187 |
+
"other_kv_identical": true,
|
| 188 |
+
"tensor_table_identical": true,
|
| 189 |
+
"tensor_data_identical": true,
|
| 190 |
+
"source_inode_distinct": true
|
| 191 |
+
}
|
| 192 |
+
},
|
| 193 |
+
"Jev-Style-0.8B-Decision-v3-Q4_K_M.gguf": {
|
| 194 |
+
"general.name": {
|
| 195 |
+
"source": "Text Only",
|
| 196 |
+
"staged": "Jev-Style-0.8B-Decision-v3"
|
| 197 |
+
},
|
| 198 |
+
"source_file_sha256": "c5d76500d861ad1127eb1ae4e5d43e59c61a5babf4a845b316b7c82f78ef9396",
|
| 199 |
+
"source_file_bytes": 529296832,
|
| 200 |
+
"staged_file_bytes": 529296864,
|
| 201 |
+
"tensor_count": 320,
|
| 202 |
+
"tensor_data_sha256": "ecc2589e70d943e6c5111db0957af786538675fff27e807d548233b0ccb93101",
|
| 203 |
+
"tensor_data_offset": {
|
| 204 |
+
"source": 10961088,
|
| 205 |
+
"staged": 10961120
|
| 206 |
+
},
|
| 207 |
+
"checks": {
|
| 208 |
+
"general_name": true,
|
| 209 |
+
"other_kv_identical": true,
|
| 210 |
+
"tensor_table_identical": true,
|
| 211 |
+
"tensor_data_identical": true,
|
| 212 |
+
"source_inode_distinct": true
|
| 213 |
+
}
|
| 214 |
+
}
|
| 215 |
+
}
|
| 216 |
+
},
|
| 217 |
+
"runtime_parity": {
|
| 218 |
+
"protocol": "2026-09-24: each runtime script run in a clean subprocess (cwd = repo folder, empty PYTHONPATH, HF_HUB_OFFLINE=1, --verify) on 24 fixed parity-fixture rows (every 10th of the 240 G5 rows; 12 categories families, choice/score/noul, 92-8156 tokens) and compared with the reference (training-code) scorer of the same format on the same inputs, probabilities with the same calibration temperature; plus 2 synthetic long states (16,381 and 25,582 tokens). Rendered token ids identical to the reference renderer on 244/244 rows (240 fixture rows + 4 adversarial special-token/unicode rows). Re-run 2026-09-24 after the rename to Jev-Style-0.8B-Decision-v3, the no-category = global-temperature default and the GGUF general.name metadata edit: all six formats again identical to the reference scorer run on the original (pre-edit) files (max |prob diff| 0.0 same backend, 0 top-1 changes). Re-run 2026-09-25 after the GGUF decide_many fix (runtime code change in decide_many only, docstrings in all scripts): all six formats gave outputs identical (0.0) to the 2026-09-24 run on the 24 rows.",
|
| 219 |
+
"results": {
|
| 220 |
+
"F16": {
|
| 221 |
+
"rows": 24,
|
| 222 |
+
"errors": 0,
|
| 223 |
+
"vs_reference_same_backend": {
|
| 224 |
+
"max_abs_prob_diff": 0.0,
|
| 225 |
+
"max_abs_score_diff": 0.0,
|
| 226 |
+
"top1_changes": 0,
|
| 227 |
+
"top1_agreement": 1.0
|
| 228 |
+
},
|
| 229 |
+
"vs_reference_torch_fp32": {
|
| 230 |
+
"max_abs_prob_diff": 0.00021979985324915852,
|
| 231 |
+
"max_abs_score_diff": 0.0029196739196777344,
|
| 232 |
+
"top1_changes": 0,
|
| 233 |
+
"top1_agreement": 1.0
|
| 234 |
+
}
|
| 235 |
+
},
|
| 236 |
+
"Q8_0": {
|
| 237 |
+
"rows": 24,
|
| 238 |
+
"errors": 0,
|
| 239 |
+
"vs_reference_same_backend": {
|
| 240 |
+
"max_abs_prob_diff": 0.0,
|
| 241 |
+
"max_abs_score_diff": 0.0,
|
| 242 |
+
"top1_changes": 0,
|
| 243 |
+
"top1_agreement": 1.0
|
| 244 |
+
},
|
| 245 |
+
"vs_reference_torch_fp32": {
|
| 246 |
+
"max_abs_prob_diff": 0.002699855778938831,
|
| 247 |
+
"max_abs_score_diff": 0.03364121913909912,
|
| 248 |
+
"top1_changes": 0,
|
| 249 |
+
"top1_agreement": 1.0
|
| 250 |
+
}
|
| 251 |
+
},
|
| 252 |
+
"Q4_K_M": {
|
| 253 |
+
"rows": 24,
|
| 254 |
+
"errors": 0,
|
| 255 |
+
"vs_reference_same_backend": {
|
| 256 |
+
"max_abs_prob_diff": 0.0,
|
| 257 |
+
"max_abs_score_diff": 0.0,
|
| 258 |
+
"top1_changes": 0,
|
| 259 |
+
"top1_agreement": 1.0
|
| 260 |
+
},
|
| 261 |
+
"vs_reference_torch_fp32": {
|
| 262 |
+
"max_abs_prob_diff": 0.03184545218113055,
|
| 263 |
+
"max_abs_score_diff": 0.30671894550323486,
|
| 264 |
+
"top1_changes": 0,
|
| 265 |
+
"top1_agreement": 1.0
|
| 266 |
+
}
|
| 267 |
+
},
|
| 268 |
+
"F16-long": {
|
| 269 |
+
"long16384:gguf": {
|
| 270 |
+
"tokens": 16381,
|
| 271 |
+
"max_abs_score_diff_vs_macjev": 0.0,
|
| 272 |
+
"top1_same": true
|
| 273 |
+
},
|
| 274 |
+
"long25600:gguf": {
|
| 275 |
+
"tokens": 25582,
|
| 276 |
+
"max_abs_score_diff_vs_macjev": 0.0,
|
| 277 |
+
"top1_same": true
|
| 278 |
+
}
|
| 279 |
+
},
|
| 280 |
+
"render_token_identity": {
|
| 281 |
+
"rows": 244,
|
| 282 |
+
"identical": 244,
|
| 283 |
+
"different": 0,
|
| 284 |
+
"bad": []
|
| 285 |
+
},
|
| 286 |
+
"decide_many": {
|
| 287 |
+
"protocol": "2026-09-25 re-run after a fix: decide_many vs decide() per question, both many_modes. many_mode='exact' (default) shares only whole 1,024-token ubatches of the state (floor(state_tokens/1024)*1024 tokens decoded once; the rest of the state plus each question decoded on a copy, split exactly as decide() splits it; states < 1,024 tokens share nothing but still go in one request). The earlier rule (share the whole state when every ubatch piece is >= 32 tokens) differed from decide() by up to 1.3e-3 in score / 8.2e-5 in probability when a long question head (12 described options, 40 options) crossed a ubatch boundary; it was replaced. many_mode='batched' = whole state once, all questions in one decode (jev-score batched mode). Test set: 5 fixture states (14-612 state tokens) x 5 questions (incl. a 12-option described head) + 44 synthetic states (5-8,200 state tokens, incl. 1,023/1,024/1,025, 2,047/2,048/2,049, 3,072 and the previously failing 500/600/700/1,700/2,600) x 4 questions (short noul, 12 described options, 40 options, 4-level score; heads up to 575 tokens); plus a reordered 2-question subset per state.",
|
| 288 |
+
"pairs_per_quant": 201,
|
| 289 |
+
"exact": {
|
| 290 |
+
"F16": {
|
| 291 |
+
"pairs": 201,
|
| 292 |
+
"max_abs_prob_diff": 0.0,
|
| 293 |
+
"max_abs_score_diff": 0.0,
|
| 294 |
+
"answer_changes": 0,
|
| 295 |
+
"pairs_with_nonzero_diff": 0,
|
| 296 |
+
"subset_reorder_max_abs_score_diff": 0.0
|
| 297 |
+
},
|
| 298 |
+
"Q8_0": {
|
| 299 |
+
"pairs": 201,
|
| 300 |
+
"max_abs_prob_diff": 0.0,
|
| 301 |
+
"max_abs_score_diff": 0.0,
|
| 302 |
+
"answer_changes": 0,
|
| 303 |
+
"pairs_with_nonzero_diff": 0,
|
| 304 |
+
"subset_reorder_max_abs_score_diff": 0.0
|
| 305 |
+
},
|
| 306 |
+
"Q4_K_M": {
|
| 307 |
+
"pairs": 201,
|
| 308 |
+
"max_abs_prob_diff": 0.0,
|
| 309 |
+
"max_abs_score_diff": 0.0,
|
| 310 |
+
"answer_changes": 0,
|
| 311 |
+
"pairs_with_nonzero_diff": 0,
|
| 312 |
+
"subset_reorder_max_abs_score_diff": 0.0
|
| 313 |
+
},
|
| 314 |
+
"gate": "bit-identical to decide(): max |prob diff| == 0.0 and 0 answer changes",
|
| 315 |
+
"gate_pass": true,
|
| 316 |
+
"independent_recheck": "independent second test script (32 synthetic states, 5-7,000 state tokens x 4 questions + a reordered subset per state): F16 128 pairs and Q4_K_M 128 pairs, max diff 0.0, 0 answer changes"
|
| 317 |
+
},
|
| 318 |
+
"batched": {
|
| 319 |
+
"F16": {
|
| 320 |
+
"pairs": 201,
|
| 321 |
+
"max_abs_prob_diff": 0.00044065521011987796,
|
| 322 |
+
"max_abs_score_diff": 0.0031585693359375,
|
| 323 |
+
"answer_changes": 1,
|
| 324 |
+
"pairs_with_nonzero_diff": 190,
|
| 325 |
+
"subset_reorder_max_abs_score_diff": 0.0022974014282226562
|
| 326 |
+
},
|
| 327 |
+
"Q8_0": {
|
| 328 |
+
"pairs": 201,
|
| 329 |
+
"max_abs_prob_diff": 0.0004022755000451794,
|
| 330 |
+
"max_abs_score_diff": 0.003612518310546875,
|
| 331 |
+
"answer_changes": 1,
|
| 332 |
+
"pairs_with_nonzero_diff": 188,
|
| 333 |
+
"subset_reorder_max_abs_score_diff": 0.001926422119140625
|
| 334 |
+
},
|
| 335 |
+
"Q4_K_M": {
|
| 336 |
+
"pairs": 201,
|
| 337 |
+
"max_abs_prob_diff": 0.001676735283422881,
|
| 338 |
+
"max_abs_score_diff": 0.012386322021484375,
|
| 339 |
+
"answer_changes": 0,
|
| 340 |
+
"pairs_with_nonzero_diff": 165,
|
| 341 |
+
"subset_reorder_max_abs_score_diff": 0.012037277221679688
|
| 342 |
+
},
|
| 343 |
+
"note": "opt-in (many_mode='batched'); not bit-identical, report only"
|
| 344 |
+
},
|
| 345 |
+
"timing_f16_informational": {
|
| 346 |
+
"protocol": "GGUF F16, states and questions of the latency chart (2026-09-23 inputs), warm, jev-score memory reset before every timed call (no prefix reuse), median of 5; Apple M1 Max 64 GB, Metal",
|
| 347 |
+
"cells": [
|
| 348 |
+
{
|
| 349 |
+
"cell": "1024x5",
|
| 350 |
+
"state_tokens": 985,
|
| 351 |
+
"exact_shared_tokens": 0,
|
| 352 |
+
"loop_ms": 1382.4,
|
| 353 |
+
"exact_ms": 1324.3,
|
| 354 |
+
"batched_ms": 365.1,
|
| 355 |
+
"exact_speedup_vs_loop": 1.04,
|
| 356 |
+
"batched_speedup_vs_loop": 3.79,
|
| 357 |
+
"exact_max_abs_prob_diff": 0.0,
|
| 358 |
+
"batched_max_abs_prob_diff": 0.00015860293574876394
|
| 359 |
+
},
|
| 360 |
+
{
|
| 361 |
+
"cell": "1024x10",
|
| 362 |
+
"state_tokens": 985,
|
| 363 |
+
"exact_shared_tokens": 0,
|
| 364 |
+
"loop_ms": 2752.3,
|
| 365 |
+
"exact_ms": 2614.5,
|
| 366 |
+
"batched_ms": 489.0,
|
| 367 |
+
"exact_speedup_vs_loop": 1.05,
|
| 368 |
+
"batched_speedup_vs_loop": 5.63,
|
| 369 |
+
"exact_max_abs_prob_diff": 0.0,
|
| 370 |
+
"batched_max_abs_prob_diff": 0.0003301056018537585
|
| 371 |
+
},
|
| 372 |
+
{
|
| 373 |
+
"cell": "4096x5",
|
| 374 |
+
"state_tokens": 4055,
|
| 375 |
+
"exact_shared_tokens": 3072,
|
| 376 |
+
"loop_ms": 5313.1,
|
| 377 |
+
"exact_ms": 2257.2,
|
| 378 |
+
"batched_ms": 1198.3,
|
| 379 |
+
"exact_speedup_vs_loop": 2.35,
|
| 380 |
+
"batched_speedup_vs_loop": 4.43,
|
| 381 |
+
"exact_max_abs_prob_diff": 0.0,
|
| 382 |
+
"batched_max_abs_prob_diff": 0.00023034970614133066
|
| 383 |
+
},
|
| 384 |
+
{
|
| 385 |
+
"cell": "4096x10",
|
| 386 |
+
"state_tokens": 4055,
|
| 387 |
+
"exact_shared_tokens": 3072,
|
| 388 |
+
"loop_ms": 10648.8,
|
| 389 |
+
"exact_ms": 3701.4,
|
| 390 |
+
"batched_ms": 1350.7,
|
| 391 |
+
"exact_speedup_vs_loop": 2.88,
|
| 392 |
+
"batched_speedup_vs_loop": 7.88,
|
| 393 |
+
"exact_max_abs_prob_diff": 0.0,
|
| 394 |
+
"batched_max_abs_prob_diff": 0.00014278970038722472
|
| 395 |
+
},
|
| 396 |
+
{
|
| 397 |
+
"cell": "8192x5",
|
| 398 |
+
"state_tokens": 8093,
|
| 399 |
+
"exact_shared_tokens": 7168,
|
| 400 |
+
"loop_ms": 11328.1,
|
| 401 |
+
"exact_ms": 3562.6,
|
| 402 |
+
"batched_ms": 2431.5,
|
| 403 |
+
"exact_speedup_vs_loop": 3.18,
|
| 404 |
+
"batched_speedup_vs_loop": 4.66,
|
| 405 |
+
"exact_max_abs_prob_diff": 0.0,
|
| 406 |
+
"batched_max_abs_prob_diff": 0.00021432728430226256
|
| 407 |
+
},
|
| 408 |
+
{
|
| 409 |
+
"cell": "8192x10",
|
| 410 |
+
"state_tokens": 8093,
|
| 411 |
+
"exact_shared_tokens": 7168,
|
| 412 |
+
"loop_ms": 22612.8,
|
| 413 |
+
"exact_ms": 5269.7,
|
| 414 |
+
"batched_ms": 2668.4,
|
| 415 |
+
"exact_speedup_vs_loop": 4.29,
|
| 416 |
+
"batched_speedup_vs_loop": 8.47,
|
| 417 |
+
"exact_max_abs_prob_diff": 0.0,
|
| 418 |
+
"batched_max_abs_prob_diff": 0.0003231294396546236
|
| 419 |
+
}
|
| 420 |
+
]
|
| 421 |
+
}
|
| 422 |
+
}
|
| 423 |
+
}
|
| 424 |
+
}
|
| 425 |
+
}
|
requirements.txt
ADDED
|
@@ -0,0 +1,4 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# tested with: python 3.12, tokenizers 0.23.2, numpy 2.5.3, llama.cpp 441df11f65ea0b6d0c72965aaf70c8241070ddcb
|
| 2 |
+
# plus the jev-score binary: sh build_jev_score.sh /path/to/llama.cpp
|
| 3 |
+
tokenizers>=0.21
|
| 4 |
+
numpy
|
tokenizer/tokenizer.json
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:06b9509352d2af50381ab2247e083b80d32d5c0aba91c272ca9ff729b6a0e523
|
| 3 |
+
size 19989325
|
tokenizer/tokenizer_config.json
ADDED
|
@@ -0,0 +1,32 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"add_prefix_space": false,
|
| 3 |
+
"audio_bos_token": "<|audio_start|>",
|
| 4 |
+
"audio_eos_token": "<|audio_end|>",
|
| 5 |
+
"audio_token": "<|audio_pad|>",
|
| 6 |
+
"backend": "tokenizers",
|
| 7 |
+
"bos_token": null,
|
| 8 |
+
"clean_up_tokenization_spaces": false,
|
| 9 |
+
"eos_token": "<|im_end|>",
|
| 10 |
+
"errors": "replace",
|
| 11 |
+
"image_token": "<|image_pad|>",
|
| 12 |
+
"is_local": true,
|
| 13 |
+
"local_files_only": false,
|
| 14 |
+
"model_max_length": 262144,
|
| 15 |
+
"model_specific_special_tokens": {
|
| 16 |
+
"audio_bos_token": "<|audio_start|>",
|
| 17 |
+
"audio_eos_token": "<|audio_end|>",
|
| 18 |
+
"audio_token": "<|audio_pad|>",
|
| 19 |
+
"image_token": "<|image_pad|>",
|
| 20 |
+
"video_token": "<|video_pad|>",
|
| 21 |
+
"vision_bos_token": "<|vision_start|>",
|
| 22 |
+
"vision_eos_token": "<|vision_end|>"
|
| 23 |
+
},
|
| 24 |
+
"pad_token": "<|endoftext|>",
|
| 25 |
+
"pretokenize_regex": "(?i:'s|'t|'re|'ve|'m|'ll|'d)|[^\\r\\n\\p{L}\\p{N}]?[\\p{L}\\p{M}]+|\\p{N}| ?[^\\s\\p{L}\\p{M}\\p{N}]+[\\r\\n]*|\\s*[\\r\\n]+|\\s+(?!\\S)|\\s+",
|
| 26 |
+
"split_special_tokens": false,
|
| 27 |
+
"tokenizer_class": "Qwen2Tokenizer",
|
| 28 |
+
"unk_token": null,
|
| 29 |
+
"video_token": "<|video_pad|>",
|
| 30 |
+
"vision_bos_token": "<|vision_start|>",
|
| 31 |
+
"vision_eos_token": "<|vision_end|>"
|
| 32 |
+
}
|