

Card: lead with results beyond the training data; typed decisions vs Laya typed only, with teacher-noise reference
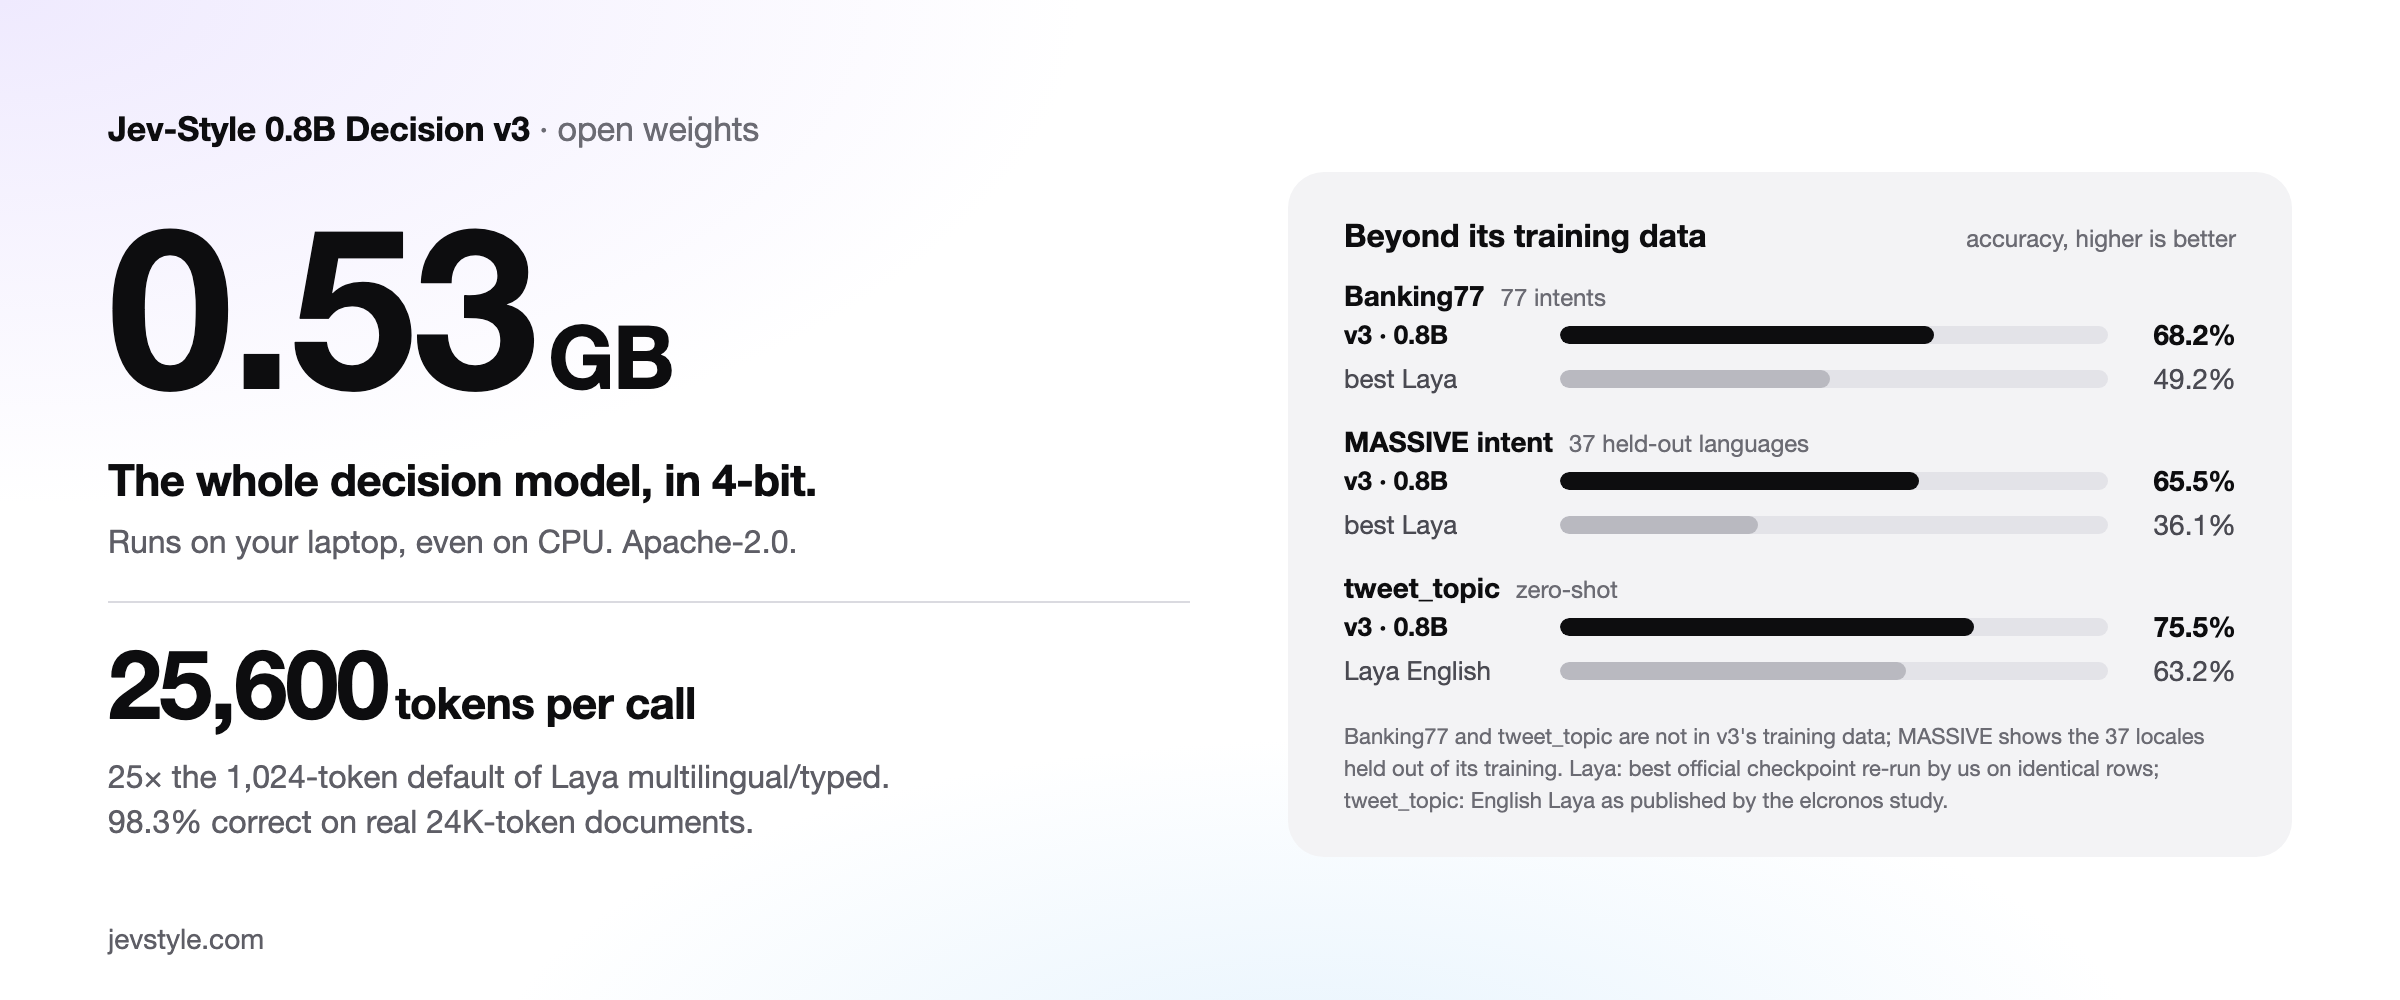
Browse filesTyped-decisions gold comes from one teacher, so the in-domain number is now compared only with Laya's typed checkpoint (same train split) and shown next to a teacher-noise reference and a teacher-margin split. The +6.4-over-Jev and Brier-vs-Jev claims are removed; the first screen now shows Banking77, held-out MASSIVE languages, tweet_topic and JevBench.
- README.md +96 -56
- figures/banner.data.json +30 -0
- figures/banner.png +2 -2
- figures/headline_typed.data.json +38 -50
- figures/headline_typed.png +2 -2
- figures/headline_typed.svg +255 -218
- figures/typed_teacher_noise.json +93 -0
- manifest.json +23 -11
README.md
CHANGED
|
@@ -44,20 +44,22 @@ tags:
|
|
| 44 |
|
| 45 |
**Jev-style decisions on your laptop.** Give it any text and a question; it returns a calibrated probability for every option in one forward pass. 0.8B parameters, open weights, Apache-2.0.
|
| 46 |
|
| 47 |
-
**
|
| 63 |
|
|
@@ -84,7 +86,7 @@ Other builds: [GGUF for llama.cpp](https://huggingface.co/chaoliangUNSW/Jev-Styl
|
|
| 84 |
|
| 85 |
## What's new in v3
|
| 86 |
|
| 87 |
-
- **Smaller and stronger.** 0.8B instead of 2B, and 79.2% vs 73.5% for our 2B v2 on the same 2,000 typed decisions.
|
| 88 |
- **No letter cap.** v1 and v2 read one option-letter token, so a question could have at most 26 options. v3
|
| 89 |
scores a verdict slot per option, so the options are whatever you pass. Banking77 was run with all 77 intents
|
| 90 |
in one pass.
|
|
@@ -128,14 +130,70 @@ Other builds: [GGUF for llama.cpp](https://huggingface.co/chaoliangUNSW/Jev-Styl
|
|
| 128 |
|
| 129 |
## Results
|
| 130 |
|
| 131 |
-
|
| 132 |
|
| 133 |
-
|
| 134 |
|
| 135 |
-
|
| 136 |
-
|
|
|
|
|
|
|
| 137 |
|
| 138 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 139 |
|
| 140 |
**Head-to-head against Laya's typed checkpoint.** Both models trained on this dataset's train split, and v3 wins on all four
|
| 141 |
metrics, each with a paired 95% CI that excludes zero:
|
|
@@ -149,30 +207,34 @@ metrics, each with a paired 95% CI that excludes zero:
|
|
| 149 |
|
| 150 |
<sub>Both in-domain; v3 also trained on 27,300 synthetic typed items from other workflows. Laya: official checkpoint re-run by us on identical rows with its shipped temperature. Paired case-cluster bootstrap within suites, 2,000 resamples.</sub>
|
| 151 |
|
| 152 |
-
<details>
|
| 153 |
-
<summary><strong>More results:</strong> +30 points over Laya · 51 languages · calibration · 24K-token documents · JevBench · zero-shot topics · speed · 4-bit parity</summary>
|
| 154 |
-
|
| 155 |
-
### Beyond Laya: up to +30 points
|
| 156 |
|
| 157 |
-
|
| 158 |
|
| 159 |
-
**
|
| 160 |
-
|
| 161 |
-
|
|
|
|
|
|
|
| 162 |
|
| 163 |
-
|
|
|
|
|
|
|
| 164 |
|
| 165 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
| 166 |
|
| 167 |
-
|
|
|
|
|
|
|
|
|
|
| 168 |
|
| 169 |
-
|
| 170 |
-
**71.7%** across 51 languages, against 40.1% for the official Laya multilingual checkpoint (+31.7 points). It
|
| 171 |
-
beats Laya multilingual in every one of the 51 languages, by at least 11 points, and stays above 3× chance in all
|
| 172 |
-
of them. That includes the 37 locales held out of MASSIVE training (65.5% vs 36.1%), 32 of them outside the 19
|
| 173 |
-
fine-tuning languages.
|
| 174 |
|
| 175 |
-
<
|
|
|
|
| 176 |
|
| 177 |
### Probabilities you can act on
|
| 178 |
|
|
@@ -202,29 +264,6 @@ at 24K), so the answers cannot be recovered from the question alone.
|
|
| 202 |
|
| 203 |
<sub>v3 only. Laya's default input budget is 512 tokens (English) / 1,024 (multilingual, typed) per the Laya README, so Laya is not plotted. Suite long_grid_plus, English and Chinese documents: preregistered 2026-09-24 and amended before any model was scored (+96 items per 24K depth decile, thresholds unchanged); 320 items per bin, 1,280 at 24K. Controlled accuracy = the real item is correct AND its question-only and state-swap controls pass; both controls are at chance in every length bin. 25K claim rule: |24K − 2K–4K reference| ≤ 5 points and every 24K evidence-depth decile within 10 points of it.</sub>
|
| 204 |
|
| 205 |
-
### JevBench: ahead of Laya and every Qwen3.5-0.8B-based system
|
| 206 |
-
|
| 207 |
-

|
| 208 |
-
|
| 209 |
-
**On the 231 public JevBench v1.4.1 items, v3 scores 64.1% zero-shot**: 5.6 points above Laya, and ahead of every
|
| 210 |
-
Qwen3.5-0.8B-based system on the board, including a dedicated 0.8B decision fine-tune (+4.8 points) and
|
| 211 |
-
SimpleJev on the same base (+9.5 points). Every answer is a valid option (231 of 231), because v3 can only score
|
| 212 |
-
the options it is given.
|
| 213 |
-
|
| 214 |
-
<sub>JevBench v1.4.1, public items only (231). v3: self-run zero-shot with the vendored official harness (commit 24b9b5c), 148 / 231 correct, 95% CI 57.7–70.0% (Wilson); training-pool contamination scan: 0 hits; not an official leaderboard entry. Other rows: public accuracy as published in the board's [v1.4.1 results file](https://github.com/fstandhartinger/jevbench). Shown: Laya plus every Qwen3.5-0.8B-based system on the board; other board systems are not shown. Laya's and M. Ghafiri's scores lie inside v3's 95% CI, so those two leads are point estimates, not significant at n = 231.</sub>
|
| 215 |
-
|
| 216 |
-
### Zero-shot topics: +12 points over English Laya
|
| 217 |
-
|
| 218 |
-

|
| 219 |
-
|
| 220 |
-
**On two topic sets it never trained on, v3 leads English Laya by +12.3 points on tweet_topic** (75.5% vs 63.2%)
|
| 221 |
-
**and +12.5 points on the 20-way fin_topic** (46.7% vs 34.2%). On tweet_topic it lands **within 4 points of Jev**
|
| 222 |
-
(75.5% vs 79.3%). Macro-F1 leads over English Laya are +13.8 points (59.9% vs 46.1%) and +8.9 points (45.2% vs 36.2%).
|
| 223 |
-
With its shipped temperature, its probabilities are also better calibrated than Jev's on both sets: ECE 0.027 vs
|
| 224 |
-
0.063 on tweet_topic and 0.046 vs 0.166 on fin_topic.
|
| 225 |
-
|
| 226 |
-
<sub>Zero-shot for every system: neither set is in v3's training pool; accuracy over every row of the pinned test files (n = 1,693 and 4,117). Jev (1.13, API) and English Laya: numbers published by the [elcronos jev-vs-open-decision-models study](https://github.com/elcronos/jev-vs-open-decision-models) with its own prompt (results/cross_dataset_summary.json @ a1901bc), not re-run by us. v3: scored by us on the identical rows, label sets and instruction, in v3's own input format; tweet_topic accuracy 95% CI 73.4–77.5%. ECE: 15 equal-width bins as in the study; v3 with its shipped global temperature (0.880, fitted on v3's own calibration split, never on these sets), Jev's ECE as published (raw API probabilities).</sub>
|
| 227 |
-
|
| 228 |
### Speed: many questions, one read
|
| 229 |
|
| 230 |

|
|
@@ -431,7 +470,8 @@ Judge each option:
|
|
| 431 |
[multilingual](figures/multilingual.data.json), [calibration](figures/calibration.data.json),
|
| 432 |
[long_context](figures/long_context.json), [jevbench](figures/jevbench.data.json),
|
| 433 |
[zeroshot](figures/zeroshot.json), [latency](figures/latency.data.json),
|
| 434 |
-
[quantization](figures/quantization.data.json), [design_table](figures/design_table.data.json)
|
|
|
|
| 435 |
- Every v3 and re-run Laya number comes from prediction files that were each scored once. Paired differences use
|
| 436 |
a case-cluster bootstrap within suites (2,000 resamples). A win is only claimed when the 95% CI excludes zero,
|
| 437 |
except where a chart or note says otherwise (JevBench leads over Laya and M. Ghafiri, and per-language MASSIVE
|
|
|
|
| 44 |
|
| 45 |
**Jev-style decisions on your laptop.** Give it any text and a question; it returns a calibrated probability for every option in one forward pass. 0.8B parameters, open weights, Apache-2.0.
|
| 46 |
|
| 47 |
+

|
| 48 |
|
| 49 |
+
| Beyond its training data | **Jev-Style v3 · 0.8B** | Best official Laya |
|
| 50 |
+
|---|:---:|:---:|
|
| 51 |
+
| Banking77, 77 intents (never trained) ↑ | **68.2%** | 49.2% |
|
| 52 |
+
| MASSIVE intent, 37 held-out languages ↑ | **65.5%** | 36.1% |
|
| 53 |
+
| tweet_topic, zero-shot ↑ | **75.5%** | 63.2%¹ |
|
| 54 |
+
| JevBench v1.4.1, 231 public items, zero-shot ↑ | **64.1%** | 58.4%² |
|
| 55 |
+
| Runs on your own machine | **Yes, 0.53 GB (4-bit GGUF)** | Yes |
|
| 56 |
+
| Longest input per call | **25,600 tokens** | 1,024 by default³ |
|
| 57 |
|
| 58 |
+
<sub>Laya: the best of its three official checkpoints, re-run by us on identical rows with their shipped temperatures; paired 95% CIs exclude zero for Banking77 and MASSIVE. ¹ English Laya, as published by the elcronos study. ² Laya's score as published on the JevBench board; it lies inside v3's 95% CI, so this lead is a point estimate. ³ Default input budget in the Laya README: 1,024 tokens for the multilingual and typed checkpoints, 512 for English. Jev (API) has higher accuracy than v3 on each of these sets where its accuracy is published. Details: [Results](#results).</sub>
|
| 59 |
|
| 60 |
**Reads long documents in one call.** Up to 25,600 tokens of input, 25× Laya's 1,024-token default and 25× our 2B v2's prompt. On 1,280 real 24K-token items v3 answers **98.3%** correctly, and accuracy stays flat from 1K to 24K tokens (preregistered claim, passed).
|
| 61 |
|
| 62 |
+
**Also:** ahead of Laya multilingual in 51 of 51 languages · +2.6 points over Laya's typed checkpoint on typed decisions, trained on the same split ([how to read that number](#reading-the-typed-number)).
|
| 63 |
|
| 64 |
**[Try it in your browser →](https://huggingface.co/spaces/chaoliangUNSW/jev-style-v3)**
|
| 65 |
|
|
|
|
| 86 |
|
| 87 |
## What's new in v3
|
| 88 |
|
| 89 |
+
- **Smaller and stronger.** 0.8B instead of 2B, and 79.2% vs 73.5% teacher agreement for our 2B v2 on the same 2,000 typed decisions.
|
| 90 |
- **No letter cap.** v1 and v2 read one option-letter token, so a question could have at most 26 options. v3
|
| 91 |
scores a verdict slot per option, so the options are whatever you pass. Banking77 was run with all 77 intents
|
| 92 |
in one pass.
|
|
|
|
| 130 |
|
| 131 |
## Results
|
| 132 |
|
| 133 |
+
<a id="beyond-its-training-data"></a>
|
| 134 |
|
| 135 |
+
### Beyond its training data
|
| 136 |
|
| 137 |
+
Results on rows that v3 never trained on (the MASSIVE chart also shows the 14 locales it did train on; each note
|
| 138 |
+
states the protocol). Laya numbers are its official checkpoints re-run by us on
|
| 139 |
+
identical rows unless a note says otherwise. Jev (API) has higher accuracy than v3 on each of these sets where its
|
| 140 |
+
accuracy is published.
|
| 141 |
|
| 142 |
+
#### Beyond Laya: up to +30 points
|
| 143 |
+
|
| 144 |
+

|
| 145 |
+
|
| 146 |
+
**On five decision tasks scored on identical rows, the 0.8B v3 beats the best official Laya checkpoint on every
|
| 147 |
+
one:** +19.0 points on 77-way Banking77, +7.2 balanced accuracy on jailbreak detection, +29.5 macro-F1 on
|
| 148 |
+
toxicity, +30.3 on model routing and +29.4 across the 37 locales held out of MASSIVE training.
|
| 149 |
+
|
| 150 |
+
<sub>Laya numbers: official checkpoints (English, typed-decisions, multilingual) re-run by us on identical rows with their shipped temperatures and default token budgets; the best of the three is shown per task. v3 trained on tasks of the same kind from other datasets, never on these evaluation rows: intent (CLINC150/HWU64; Banking77 never trained), jailbreak (other permissive sets plus teacher data), toxicity (civil_comments plus teacher data; toxic-chat is evaluation-only), routing (teacher-written; the gsm8k/mbpp/AG rows are evaluation-only), MASSIVE in 14 other locales (no MASSIVE rows in these 37). n = 400 / 400 / 400 / 399 / 3,700 (37 × 100). Every gap's paired 95% bootstrap CI excludes zero.</sub>
|
| 151 |
+
|
| 152 |
+
#### Zero-shot topics: +12 points over English Laya
|
| 153 |
+
|
| 154 |
+

|
| 155 |
+
|
| 156 |
+
**On two topic sets it never trained on, v3 leads English Laya by +12.3 points on tweet_topic** (75.5% vs 63.2%)
|
| 157 |
+
**and +12.5 points on the 20-way fin_topic** (46.7% vs 34.2%). On tweet_topic it lands **within 4 points of Jev**
|
| 158 |
+
(75.5% vs 79.3%). Macro-F1 leads over English Laya are +13.8 points (59.9% vs 46.1%) and +8.9 points (45.2% vs 36.2%).
|
| 159 |
+
With its shipped temperature, its probabilities are also better calibrated than Jev's on both sets: ECE 0.027 vs
|
| 160 |
+
0.063 on tweet_topic and 0.046 vs 0.166 on fin_topic.
|
| 161 |
+
|
| 162 |
+
<sub>Zero-shot for every system: neither set is in v3's training pool; accuracy over every row of the pinned test files (n = 1,693 and 4,117). Jev (1.13, API) and English Laya: numbers published by the [elcronos jev-vs-open-decision-models study](https://github.com/elcronos/jev-vs-open-decision-models) with its own prompt (results/cross_dataset_summary.json @ a1901bc), not re-run by us. v3: scored by us on the identical rows, label sets and instruction, in v3's own input format; tweet_topic accuracy 95% CI 73.4–77.5%. ECE: 15 equal-width bins as in the study; v3 with its shipped global temperature (0.880, fitted on v3's own calibration split, never on these sets), Jev's ECE as published (raw API probabilities).</sub>
|
| 163 |
+
|
| 164 |
+
#### JevBench: ahead of Laya and every Qwen3.5-0.8B-based system
|
| 165 |
+
|
| 166 |
+

|
| 167 |
+
|
| 168 |
+
**On the 231 public JevBench v1.4.1 items, v3 scores 64.1% zero-shot**: 5.6 points above Laya, and ahead of every
|
| 169 |
+
Qwen3.5-0.8B-based system on the board, including a dedicated 0.8B decision fine-tune (+4.8 points) and
|
| 170 |
+
SimpleJev on the same base (+9.5 points). Every answer is a valid option (231 of 231), because v3 can only score
|
| 171 |
+
the options it is given.
|
| 172 |
+
|
| 173 |
+
<sub>JevBench v1.4.1, public items only (231). v3: self-run zero-shot with the vendored official harness (commit 24b9b5c), 148 / 231 correct, 95% CI 57.7–70.0% (Wilson); training-pool contamination scan: 0 hits; not an official leaderboard entry. Other rows: public accuracy as published in the board's [v1.4.1 results file](https://github.com/fstandhartinger/jevbench). Shown: Laya plus every Qwen3.5-0.8B-based system on the board; other board systems are not shown. Laya's and M. Ghafiri's scores lie inside v3's 95% CI, so those two leads are point estimates, not significant at n = 231.</sub>
|
| 174 |
+
|
| 175 |
+
#### 51 languages, 51 wins
|
| 176 |
+
|
| 177 |
+

|
| 178 |
+
|
| 179 |
+
**One 0.8B model, 51 languages, 51 wins over Laya.** On MASSIVE intent (20 options per question) v3 averages
|
| 180 |
+
**71.7%** across 51 languages, against 40.1% for the official Laya multilingual checkpoint (+31.7 points). It
|
| 181 |
+
beats Laya multilingual in every one of the 51 languages, by at least 11 points, and stays above 3× chance in all
|
| 182 |
+
of them. That includes the 37 locales held out of MASSIVE training (65.5% vs 36.1%), 32 of them outside the 19
|
| 183 |
+
fine-tuning languages.
|
| 184 |
+
|
| 185 |
+
<sub>MASSIVE intent (mteb/amazon_massive_intent) test rows, 100 per language, 20 candidate intents per row (chance 5%, 3× chance 15%); accuracy = top-scored option. v3: in-domain for the 14 trained locales, held out for the other 37 (vi/th/el/ur had about 1.3K translated-NLI training rows each; zh-TW shares Chinese with zh-CN; a 69-row multilingual jailbreak set in training may include a few prompts in other held-out languages). Laya: official multilingual checkpoint re-run by us on identical rows with its shipped temperature and default token budget (held-out for Laya). v3 is also ahead of the best of the three official Laya checkpoints in all 51 languages (per-language point estimates on 100 rows each, smallest gap 10 points). Paired 95% CI of the 51-language macro difference: +30.1 to +33.1 points.</sub>
|
| 186 |
+
|
| 187 |
+
<a id="typed-decisions"></a>
|
| 188 |
+
|
| 189 |
+
### Typed decisions: ahead of Laya's typed checkpoint on the same train split
|
| 190 |
+
|
| 191 |
+

|
| 192 |
+
|
| 193 |
+
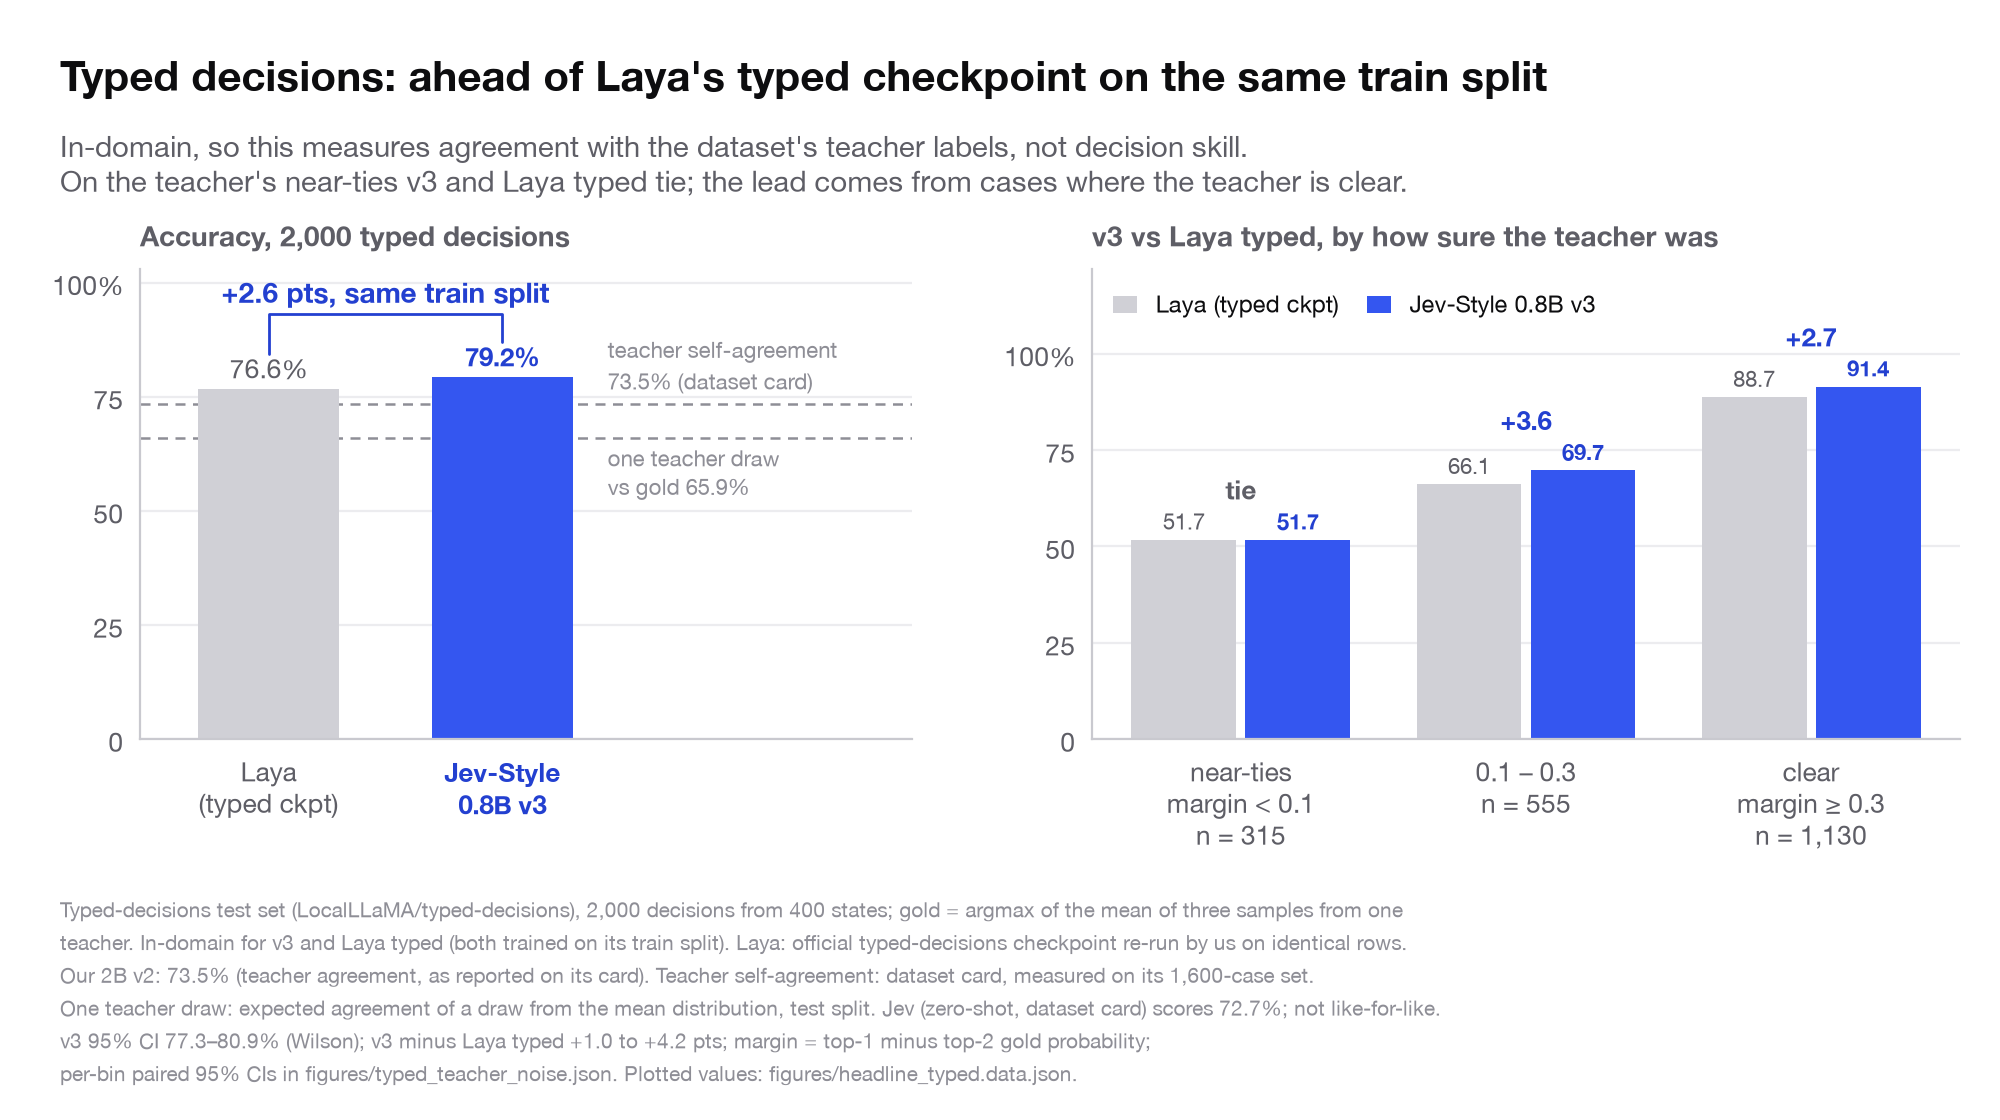
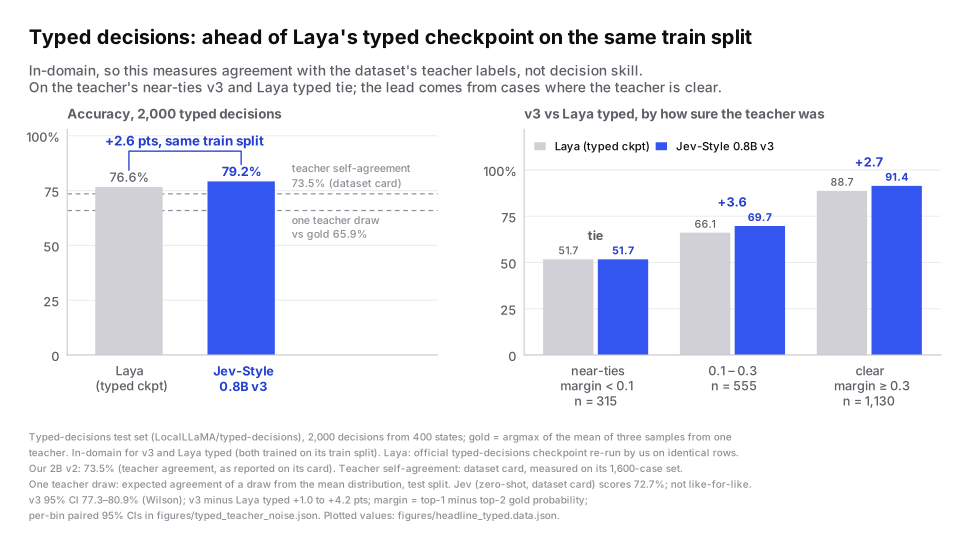
v3 scores **79.2%** on the 2,000 typed decisions, **+2.6 points over Laya's typed checkpoint**, which was trained on
|
| 194 |
+
the same split, and +5.7 over our 2B v2.
|
| 195 |
+
|
| 196 |
+
<sub>Typed-decisions test set (LocalLLaMA/typed-decisions), 2,000 decisions from 400 states. In-domain for v3 and Laya typed (both trained on its train split). Laya: official typed-decisions checkpoint re-run by us on identical rows with its shipped temperature. 2B v2: teacher agreement as reported on its card (same 2,000 decisions, scored by that card's harness; its training pool included typed workflow decisions). v3: 1,583 / 2,000 correct, 95% CI 77.3–80.9% (Wilson); v3 minus Laya typed, paired bootstrap 95% CI +1.0 to +4.2 points. Jev (zero-shot, dataset card) scores 72.7%; that is not a like-for-like comparison (see below).</sub>
|
| 197 |
|
| 198 |
**Head-to-head against Laya's typed checkpoint.** Both models trained on this dataset's train split, and v3 wins on all four
|
| 199 |
metrics, each with a paired 95% CI that excludes zero:
|
|
|
|
| 207 |
|
| 208 |
<sub>Both in-domain; v3 also trained on 27,300 synthetic typed items from other workflows. Laya: official checkpoint re-run by us on identical rows with its shipped temperature. Paired case-cluster bootstrap within suites, 2,000 resamples.</sub>
|
| 209 |
|
|
|
|
|
|
|
|
|
|
|
|
|
| 210 |
|
| 211 |
+
<a id="reading-the-typed-number"></a>
|
| 212 |
|
| 213 |
+
**Reading the typed number.** The gold labels come from one ~4B teacher: each is the argmax of the mean of three
|
| 214 |
+
teacher samples. In-domain accuracy therefore measures agreement with that teacher, and the dataset card notes that
|
| 215 |
+
scores well above ~0.75 partly reflect the teacher's quirks rather than the task. The test split does not release the
|
| 216 |
+
individual samples, so the card's teacher self-agreement (73.5%, measured on its 1,600-case set) cannot be recomputed
|
| 217 |
+
here. What the released data does allow:
|
| 218 |
|
| 219 |
+
- One draw from the teacher's mean distribution matches the gold argmax **65.9%** of the time on the test split.
|
| 220 |
+
- Split by how sure the teacher was, v3 and Laya typed **tie on the teacher's near-ties**; v3's lead comes from cases
|
| 221 |
+
where the teacher is clear.
|
| 222 |
|
| 223 |
+
| Teacher margin (top-1 − top-2 probability) | Decisions | Laya typed | **v3** | Difference, paired 95% CI |
|
| 224 |
+
|---|---:|---:|---:|---|
|
| 225 |
+
| Below 0.1 (near-ties) | 315 | 51.7% | 51.7% | +0.0 pts [−4.4, +4.5] |
|
| 226 |
+
| 0.1 to 0.3 | 555 | 66.1% | **69.7%** | +3.6 pts [+0.2, +7.3] |
|
| 227 |
+
| 0.3 and above (teacher is clear) | 1,130 | 88.7% | **91.4%** | +2.7 pts [+0.8, +4.6] |
|
| 228 |
|
| 229 |
+
This rules out fitting the teacher's noise as the source of the gap to Laya typed. It cannot separate task skill from
|
| 230 |
+
the teacher's consistent biases, because both models trained on its labels; the [results beyond the training
|
| 231 |
+
data](#beyond-its-training-data) are the check for that. Jev's 72.7% on this set is zero-shot, so it is not a
|
| 232 |
+
like-for-like comparison with either in-domain model.
|
| 233 |
|
| 234 |
+
<sub>Gold labels and label_agreement flags: LocalLLaMA/typed-decisions test split. One teacher draw = mean over decisions of the gold's top probability. Paired bootstrap resampling the 400 states, 2,000 resamples per row. Values and script: [typed_teacher_noise.json](figures/typed_teacher_noise.json).</sub>
|
|
|
|
|
|
|
|
|
|
|
|
|
| 235 |
|
| 236 |
+
<details>
|
| 237 |
+
<summary><strong>More results:</strong> calibration · 24K-token documents · speed · 4-bit parity</summary>
|
| 238 |
|
| 239 |
### Probabilities you can act on
|
| 240 |
|
|
|
|
| 264 |
|
| 265 |
<sub>v3 only. Laya's default input budget is 512 tokens (English) / 1,024 (multilingual, typed) per the Laya README, so Laya is not plotted. Suite long_grid_plus, English and Chinese documents: preregistered 2026-09-24 and amended before any model was scored (+96 items per 24K depth decile, thresholds unchanged); 320 items per bin, 1,280 at 24K. Controlled accuracy = the real item is correct AND its question-only and state-swap controls pass; both controls are at chance in every length bin. 25K claim rule: |24K − 2K–4K reference| ≤ 5 points and every 24K evidence-depth decile within 10 points of it.</sub>
|
| 266 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 267 |
### Speed: many questions, one read
|
| 268 |
|
| 269 |

|
|
|
|
| 470 |
[multilingual](figures/multilingual.data.json), [calibration](figures/calibration.data.json),
|
| 471 |
[long_context](figures/long_context.json), [jevbench](figures/jevbench.data.json),
|
| 472 |
[zeroshot](figures/zeroshot.json), [latency](figures/latency.data.json),
|
| 473 |
+
[quantization](figures/quantization.data.json), [design_table](figures/design_table.data.json),
|
| 474 |
+
[typed_teacher_noise](figures/typed_teacher_noise.json), [banner](figures/banner.data.json).
|
| 475 |
- Every v3 and re-run Laya number comes from prediction files that were each scored once. Paired differences use
|
| 476 |
a case-cluster bootstrap within suites (2,000 resamples). A win is only claimed when the 95% CI excludes zero,
|
| 477 |
except where a chart or note says otherwise (JevBench leads over Laya and M. Ghafiri, and per-language MASSIVE
|
figures/banner.data.json
ADDED
|
@@ -0,0 +1,30 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"rows": [
|
| 3 |
+
{
|
| 4 |
+
"task": "Banking77",
|
| 5 |
+
"subset": "77 intents",
|
| 6 |
+
"v3_pct": 68.2,
|
| 7 |
+
"laya_pct": 49.2,
|
| 8 |
+
"laya": "best Laya"
|
| 9 |
+
},
|
| 10 |
+
{
|
| 11 |
+
"task": "MASSIVE intent",
|
| 12 |
+
"subset": "37 held-out languages",
|
| 13 |
+
"v3_pct": 65.5,
|
| 14 |
+
"laya_pct": 36.1,
|
| 15 |
+
"laya": "best Laya"
|
| 16 |
+
},
|
| 17 |
+
{
|
| 18 |
+
"task": "tweet_topic",
|
| 19 |
+
"subset": "zero-shot",
|
| 20 |
+
"v3_pct": 75.5,
|
| 21 |
+
"laya_pct": 63.2,
|
| 22 |
+
"laya": "Laya English"
|
| 23 |
+
}
|
| 24 |
+
],
|
| 25 |
+
"note": "Banking77 and tweet_topic are not in v3's training data; MASSIVE shows the 37 locales held out of its training. Laya: best official checkpoint re-run by us on identical rows; tweet_topic: English Laya as published by the elcronos study.",
|
| 26 |
+
"sources": [
|
| 27 |
+
"figures/beyond_laya.json",
|
| 28 |
+
"figures/zeroshot.json"
|
| 29 |
+
]
|
| 30 |
+
}
|
figures/banner.png
CHANGED

|
Git LFS Details
|
|
Git LFS Details
|
figures/headline_typed.data.json
CHANGED
|
@@ -2,30 +2,6 @@
|
|
| 2 |
"figure": "headline_typed",
|
| 3 |
"panels": {
|
| 4 |
"accuracy_pct": [
|
| 5 |
-
{
|
| 6 |
-
"label": "Jev-Style 2B v1",
|
| 7 |
-
"entry": "typed.teacher_agreement.v1",
|
| 8 |
-
"raw": 0.5335,
|
| 9 |
-
"plotted": 53.4,
|
| 10 |
-
"source": "https://huggingface.co/chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision-v2/raw/main/README.md",
|
| 11 |
-
"field": "card text: 'The separate typed-decisions group contains 2,000 teacher-reference decisions from 400 states. Teacher agreement is 53.35% for v1, 37.55% for English Laya and 73.45% for v2'"
|
| 12 |
-
},
|
| 13 |
-
{
|
| 14 |
-
"label": "Jev",
|
| 15 |
-
"entry": "typed.accuracy.jev",
|
| 16 |
-
"raw": 0.727,
|
| 17 |
-
"plotted": 72.7,
|
| 18 |
-
"source": "docs/round2_audit/track_jev_results.json",
|
| 19 |
-
"field": "string 'Jev typed-decisions (zero-shot)': '0.727 acc; KL 1.442; Brier 0.148; ECE 0.144; soft-acc 0.580' (from LocalLLaMA/typed-decisions dataset card / Laya HF card)"
|
| 20 |
-
},
|
| 21 |
-
{
|
| 22 |
-
"label": "Jev-Style 2B v2",
|
| 23 |
-
"entry": "typed.teacher_agreement.v2",
|
| 24 |
-
"raw": 0.7345,
|
| 25 |
-
"plotted": 73.5,
|
| 26 |
-
"source": "https://huggingface.co/chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision-v2/raw/main/README.md",
|
| 27 |
-
"field": "card text: 'The separate typed-decisions group contains 2,000 teacher-reference decisions from 400 states. Teacher agreement is 53.35% for v1, 37.55% for English Laya and 73.45% for v2'"
|
| 28 |
-
},
|
| 29 |
{
|
| 30 |
"label": "Laya (typed ckpt)",
|
| 31 |
"entry": "typed.accuracy.laya_typed",
|
|
@@ -43,39 +19,46 @@
|
|
| 43 |
"field": "metrics['typed.accuracy'].ours_value"
|
| 44 |
}
|
| 45 |
],
|
| 46 |
-
"
|
|
|
|
|
|
|
|
|
|
|
|
|
| 47 |
{
|
| 48 |
-
"
|
| 49 |
-
"
|
| 50 |
-
"
|
| 51 |
-
"
|
| 52 |
-
"
|
| 53 |
-
|
|
|
|
|
|
|
| 54 |
},
|
| 55 |
{
|
| 56 |
-
"
|
| 57 |
-
"
|
| 58 |
-
"
|
| 59 |
-
"
|
| 60 |
-
"
|
| 61 |
-
|
|
|
|
|
|
|
| 62 |
},
|
| 63 |
{
|
| 64 |
-
"
|
| 65 |
-
"
|
| 66 |
-
"
|
| 67 |
-
"
|
| 68 |
-
"
|
| 69 |
-
|
|
|
|
|
|
|
| 70 |
}
|
| 71 |
]
|
| 72 |
},
|
| 73 |
"annotations": {
|
| 74 |
-
"delta_vs_jev_pts": 6.4,
|
| 75 |
-
"delta_vs_v2_pts": 5.7,
|
| 76 |
"delta_vs_laya_typed_pts": 2.6,
|
| 77 |
-
"
|
| 78 |
-
"brier_pct_lower_than_laya_typed": 25.4,
|
| 79 |
"v3_acc_ci95_wilson": [
|
| 80 |
0.7731,
|
| 81 |
0.8087
|
|
@@ -83,8 +66,13 @@
|
|
| 83 |
"v3_minus_laya_typed_paired_ci95": [
|
| 84 |
0.010499999999999954,
|
| 85 |
0.04249999999999998
|
| 86 |
-
]
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 87 |
},
|
| 88 |
-
"
|
| 89 |
-
"footnote": "Typed-decisions test set (LocalLLaMA/typed-decisions), 2,000 decisions from 400 states. In-domain for v3 and Laya typed (both trained on its\ntrain split); zero-shot for Jev (dataset-card numbers, Jev API, all 2,000 decisions). Laya: official typed-decisions checkpoint re-run by us on\nidentical rows with its shipped temperature. 2B v1/v2: teacher agreement as reported on the v2 card (same 2,000 decisions, that card's harness;\nv1 was not trained on typed decisions, v2's pool included typed workflow decisions). v3 95% CI 77.3\u201380.9% (Wilson);\nv3 minus Laya typed, paired bootstrap 95% CI +1.0 to +4.2 pts. Plotted values: figures/headline_typed.data.json."
|
| 90 |
}
|
|
|
|
| 2 |
"figure": "headline_typed",
|
| 3 |
"panels": {
|
| 4 |
"accuracy_pct": [
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 5 |
{
|
| 6 |
"label": "Laya (typed ckpt)",
|
| 7 |
"entry": "typed.accuracy.laya_typed",
|
|
|
|
| 19 |
"field": "metrics['typed.accuracy'].ours_value"
|
| 20 |
}
|
| 21 |
],
|
| 22 |
+
"reference_lines_pct": {
|
| 23 |
+
"teacher_self_agreement_dataset_card": 73.5,
|
| 24 |
+
"one_teacher_draw_vs_gold_test_split": 65.9
|
| 25 |
+
},
|
| 26 |
+
"by_teacher_margin_pct": [
|
| 27 |
{
|
| 28 |
+
"bin": "near-ties margin < 0.1",
|
| 29 |
+
"n": 315,
|
| 30 |
+
"v3": 51.7,
|
| 31 |
+
"laya_typed": 51.7,
|
| 32 |
+
"diff_ci95_pts": [
|
| 33 |
+
-4.36,
|
| 34 |
+
4.52
|
| 35 |
+
]
|
| 36 |
},
|
| 37 |
{
|
| 38 |
+
"bin": "0.1 \u2013 0.3",
|
| 39 |
+
"n": 555,
|
| 40 |
+
"v3": 69.7,
|
| 41 |
+
"laya_typed": 66.1,
|
| 42 |
+
"diff_ci95_pts": [
|
| 43 |
+
0.18,
|
| 44 |
+
7.27
|
| 45 |
+
]
|
| 46 |
},
|
| 47 |
{
|
| 48 |
+
"bin": "clear margin \u2265 0.3",
|
| 49 |
+
"n": 1130,
|
| 50 |
+
"v3": 91.4,
|
| 51 |
+
"laya_typed": 88.7,
|
| 52 |
+
"diff_ci95_pts": [
|
| 53 |
+
0.82,
|
| 54 |
+
4.61
|
| 55 |
+
]
|
| 56 |
}
|
| 57 |
]
|
| 58 |
},
|
| 59 |
"annotations": {
|
|
|
|
|
|
|
| 60 |
"delta_vs_laya_typed_pts": 2.6,
|
| 61 |
+
"delta_vs_v2_pts": 5.7,
|
|
|
|
| 62 |
"v3_acc_ci95_wilson": [
|
| 63 |
0.7731,
|
| 64 |
0.8087
|
|
|
|
| 66 |
"v3_minus_laya_typed_paired_ci95": [
|
| 67 |
0.010499999999999954,
|
| 68 |
0.04249999999999998
|
| 69 |
+
],
|
| 70 |
+
"jev_zero_shot_pct_footnote_only": 72.7
|
| 71 |
+
},
|
| 72 |
+
"protocol": "in-domain for v3 and Laya typed; 2B v1/v2 as reported on the v2 card; Jev named in the footnote only",
|
| 73 |
+
"sources": {
|
| 74 |
+
"chart_data": "v3_card/chart_data.json",
|
| 75 |
+
"teacher_noise": "figures/typed_teacher_noise.json"
|
| 76 |
},
|
| 77 |
+
"footnote": "Typed-decisions test set (LocalLLaMA/typed-decisions), 2,000 decisions from 400 states; gold = argmax of the mean of three samples from one\nteacher. In-domain for v3 and Laya typed (both trained on its train split). Laya: official typed-decisions checkpoint re-run by us on identical rows.\nOur 2B v2: 73.5% (teacher agreement, as reported on its card). Teacher self-agreement: dataset card, measured on its 1,600-case set.\nOne teacher draw: expected agreement of a draw from the mean distribution, test split. Jev (zero-shot, dataset card) scores 72.7%; not like-for-like.\nv3 95% CI 77.3\u201380.9% (Wilson); v3 minus Laya typed +1.0 to +4.2 pts; margin = top-1 minus top-2 gold probability;\nper-bin paired 95% CIs in figures/typed_teacher_noise.json. Plotted values: figures/headline_typed.data.json."
|
|
|
|
| 78 |
}
|
figures/headline_typed.png
CHANGED

|
Git LFS Details
|
|
Git LFS Details
|
figures/headline_typed.svg
CHANGED

|
|
figures/typed_teacher_noise.json
ADDED
|
@@ -0,0 +1,93 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"what": "typed-decisions test split, 2,000 decisions / 400 states; v3 vs Laya typed (official checkpoint, re-run by us); both trained on the train split",
|
| 3 |
+
"gold": "argmax of the mean of three teacher samples; individual samples not released",
|
| 4 |
+
"single_draw_reference": 0.6589,
|
| 5 |
+
"dataset_card_references": {
|
| 6 |
+
"teacher_self_agreement": 0.735,
|
| 7 |
+
"factor_model": 0.704,
|
| 8 |
+
"majority": 0.52,
|
| 9 |
+
"note": "from the LocalLLaMA/typed-decisions card, measured on its 1,600-case set"
|
| 10 |
+
},
|
| 11 |
+
"argmax_agree_rate": 0.594,
|
| 12 |
+
"bootstrap": "paired, resampling states (clusters), 2000 resamples per subset, one generator seeded 0",
|
| 13 |
+
"by_margin": [
|
| 14 |
+
{
|
| 15 |
+
"subset": "all",
|
| 16 |
+
"n": 2000,
|
| 17 |
+
"v3": 0.7915,
|
| 18 |
+
"laya_typed": 0.766,
|
| 19 |
+
"diff_pts": 2.55,
|
| 20 |
+
"diff_ci95_pts": [
|
| 21 |
+
1.05,
|
| 22 |
+
4.25
|
| 23 |
+
],
|
| 24 |
+
"mean_gold_max_prob": 0.6589
|
| 25 |
+
},
|
| 26 |
+
{
|
| 27 |
+
"subset": "margin < 0.1",
|
| 28 |
+
"n": 315,
|
| 29 |
+
"v3": 0.51746,
|
| 30 |
+
"laya_typed": 0.51746,
|
| 31 |
+
"diff_pts": 0.0,
|
| 32 |
+
"diff_ci95_pts": [
|
| 33 |
+
-4.36,
|
| 34 |
+
4.52
|
| 35 |
+
],
|
| 36 |
+
"mean_gold_max_prob": 0.4481
|
| 37 |
+
},
|
| 38 |
+
{
|
| 39 |
+
"subset": "0.1 <= margin < 0.3",
|
| 40 |
+
"n": 555,
|
| 41 |
+
"v3": 0.697297,
|
| 42 |
+
"laya_typed": 0.661261,
|
| 43 |
+
"diff_pts": 3.6,
|
| 44 |
+
"diff_ci95_pts": [
|
| 45 |
+
0.18,
|
| 46 |
+
7.27
|
| 47 |
+
],
|
| 48 |
+
"mean_gold_max_prob": 0.5337
|
| 49 |
+
},
|
| 50 |
+
{
|
| 51 |
+
"subset": "margin >= 0.3",
|
| 52 |
+
"n": 1130,
|
| 53 |
+
"v3": 0.914159,
|
| 54 |
+
"laya_typed": 0.886726,
|
| 55 |
+
"diff_pts": 2.74,
|
| 56 |
+
"diff_ci95_pts": [
|
| 57 |
+
0.82,
|
| 58 |
+
4.61
|
| 59 |
+
],
|
| 60 |
+
"mean_gold_max_prob": 0.7792
|
| 61 |
+
}
|
| 62 |
+
],
|
| 63 |
+
"by_argmax_agree": [
|
| 64 |
+
{
|
| 65 |
+
"subset": "argmax_agree",
|
| 66 |
+
"n": 1188,
|
| 67 |
+
"v3": 0.906566,
|
| 68 |
+
"laya_typed": 0.877104,
|
| 69 |
+
"diff_pts": 2.95,
|
| 70 |
+
"diff_ci95_pts": [
|
| 71 |
+
1.18,
|
| 72 |
+
4.71
|
| 73 |
+
],
|
| 74 |
+
"mean_gold_max_prob": 0.7581
|
| 75 |
+
},
|
| 76 |
+
{
|
| 77 |
+
"subset": "not argmax_agree",
|
| 78 |
+
"n": 812,
|
| 79 |
+
"v3": 0.623153,
|
| 80 |
+
"laya_typed": 0.603448,
|
| 81 |
+
"diff_pts": 1.97,
|
| 82 |
+
"diff_ci95_pts": [
|
| 83 |
+
-0.99,
|
| 84 |
+
4.83
|
| 85 |
+
],
|
| 86 |
+
"mean_gold_max_prob": 0.5139
|
| 87 |
+
}
|
| 88 |
+
],
|
| 89 |
+
"sources": {
|
| 90 |
+
"v3": "runs/macjev/received/20260924-0313/evals/main/test/typed_test.jsonl",
|
| 91 |
+
"laya_typed": "runs/macjev/laya_baselines/typed/typed_test.jsonl"
|
| 92 |
+
}
|
| 93 |
+
}
|
manifest.json
CHANGED
|
@@ -1,7 +1,7 @@
|
|
| 1 |
{
|
| 2 |
"format": "jev-style-manifest-v1",
|
| 3 |
"repo": "chaoliangUNSW/Jev-Style-0.8B-Decision-v3",
|
| 4 |
-
"created_unix":
|
| 5 |
"files": {
|
| 6 |
"LICENSE": {
|
| 7 |
"sha256": "bbedc3fda3305820b977265f01b8619d87570a6739de3a5582c3464840f1e57a",
|
|
@@ -12,8 +12,12 @@
|
|
| 12 |
"bytes": 1966
|
| 13 |
},
|
| 14 |
"README.md": {
|
| 15 |
-
"sha256": "
|
| 16 |
-
"bytes":
|
|
|
|
|
|
|
|
|
|
|
|
|
| 17 |
},
|
| 18 |
"chat_template.jinja": {
|
| 19 |
"sha256": "273d8e0e683b885071fb17e08d71e5f2a5ddfb5309756181681de4f5a1822d80",
|
|
@@ -23,9 +27,13 @@
|
|
| 23 |
"sha256": "3f56b6210db3c52e0bafb50da005eb52b6d340ab4ad980091879b397743675fc",
|
| 24 |
"bytes": 1790
|
| 25 |
},
|
|
|
|
|
|
|
|
|
|
|
|
|
| 26 |
"figures/banner.png": {
|
| 27 |
-
"sha256": "
|
| 28 |
-
"bytes":
|
| 29 |
},
|
| 30 |
"figures/beyond_laya.json": {
|
| 31 |
"sha256": "a6dfd582fe3aca32bcd67cf01b85190d92084a0790f7744dd03180df5923f946",
|
|
@@ -64,16 +72,16 @@
|
|
| 64 |
"bytes": 26655
|
| 65 |
},
|
| 66 |
"figures/headline_typed.data.json": {
|
| 67 |
-
"sha256": "
|
| 68 |
-
"bytes":
|
| 69 |
},
|
| 70 |
"figures/headline_typed.png": {
|
| 71 |
-
"sha256": "
|
| 72 |
-
"bytes":
|
| 73 |
},
|
| 74 |
"figures/headline_typed.svg": {
|
| 75 |
-
"sha256": "
|
| 76 |
-
"bytes":
|
| 77 |
},
|
| 78 |
"figures/jevbench.data.json": {
|
| 79 |
"sha256": "f9173e65f5cd1fe9fadad8c93a8d00dbe5181e7314d49f18c6f547a0ed168543",
|
|
@@ -135,6 +143,10 @@
|
|
| 135 |
"sha256": "70720bb46ec1e718dcbfac9a83d3b5d11d50b3a5cc3356915465d70d95f3d43b",
|
| 136 |
"bytes": 28756
|
| 137 |
},
|
|
|
|
|
|
|
|
|
|
|
|
|
| 138 |
"figures/zeroshot.json": {
|
| 139 |
"sha256": "003c087074b876efab789fadf94f51d134c604d5f2efce417557732de2272e9d",
|
| 140 |
"bytes": 1867
|
|
|
|
| 1 |
{
|
| 2 |
"format": "jev-style-manifest-v1",
|
| 3 |
"repo": "chaoliangUNSW/Jev-Style-0.8B-Decision-v3",
|
| 4 |
+
"created_unix": 1790293524.81474,
|
| 5 |
"files": {
|
| 6 |
"LICENSE": {
|
| 7 |
"sha256": "bbedc3fda3305820b977265f01b8619d87570a6739de3a5582c3464840f1e57a",
|
|
|
|
| 12 |
"bytes": 1966
|
| 13 |
},
|
| 14 |
"README.md": {
|
| 15 |
+
"sha256": "de01bf84f05dcfe340e9bd08ade9fd904553fa5eb0db736d109fcbb39a868f77",
|
| 16 |
+
"bytes": 35644
|
| 17 |
+
},
|
| 18 |
+
"__pycache__/jev_style_decision.cpython-312.pyc": {
|
| 19 |
+
"sha256": "4e68d51a447aa64877128431a50b7fdca85f57eb7558754cb76f65858339e528",
|
| 20 |
+
"bytes": 35081
|
| 21 |
},
|
| 22 |
"chat_template.jinja": {
|
| 23 |
"sha256": "273d8e0e683b885071fb17e08d71e5f2a5ddfb5309756181681de4f5a1822d80",
|
|
|
|
| 27 |
"sha256": "3f56b6210db3c52e0bafb50da005eb52b6d340ab4ad980091879b397743675fc",
|
| 28 |
"bytes": 1790
|
| 29 |
},
|
| 30 |
+
"figures/banner.data.json": {
|
| 31 |
+
"sha256": "b9d992327c8d9db777cef1d53a49226f19d45c4ce5c16c3e284f525405c41e20",
|
| 32 |
+
"bytes": 728
|
| 33 |
+
},
|
| 34 |
"figures/banner.png": {
|
| 35 |
+
"sha256": "43d8ca0c7ce6fc140558e57a0196c8d69d6dc61ce597f9186a0a286ba8cace58",
|
| 36 |
+
"bytes": 385876
|
| 37 |
},
|
| 38 |
"figures/beyond_laya.json": {
|
| 39 |
"sha256": "a6dfd582fe3aca32bcd67cf01b85190d92084a0790f7744dd03180df5923f946",
|
|
|
|
| 72 |
"bytes": 26655
|
| 73 |
},
|
| 74 |
"figures/headline_typed.data.json": {
|
| 75 |
+
"sha256": "13f18eb866d87d21057478cc40d8180b054258d733996b9b0a98fa846bcc0ae1",
|
| 76 |
+
"bytes": 2492
|
| 77 |
},
|
| 78 |
"figures/headline_typed.png": {
|
| 79 |
+
"sha256": "0f4a50b91df02593f177b5154f57621ff5d7450b2812f303488545d2d55255be",
|
| 80 |
+
"bytes": 216728
|
| 81 |
},
|
| 82 |
"figures/headline_typed.svg": {
|
| 83 |
+
"sha256": "345d8bf7fefdbdf26890ce9c30d74b3df2a4642d19768168f10d0fc1821d7f6b",
|
| 84 |
+
"bytes": 23730
|
| 85 |
},
|
| 86 |
"figures/jevbench.data.json": {
|
| 87 |
"sha256": "f9173e65f5cd1fe9fadad8c93a8d00dbe5181e7314d49f18c6f547a0ed168543",
|
|
|
|
| 143 |
"sha256": "70720bb46ec1e718dcbfac9a83d3b5d11d50b3a5cc3356915465d70d95f3d43b",
|
| 144 |
"bytes": 28756
|
| 145 |
},
|
| 146 |
+
"figures/typed_teacher_noise.json": {
|
| 147 |
+
"sha256": "08ac501f990c889d72cba4b7909de5129860159f28a95fee19ce82cc0bd36dbe",
|
| 148 |
+
"bytes": 2004
|
| 149 |
+
},
|
| 150 |
"figures/zeroshot.json": {
|
| 151 |
"sha256": "003c087074b876efab789fadf94f51d134c604d5f2efce417557732de2272e9d",
|
| 152 |
"bytes": 1867
|