

Jev-Style-2B-Decision-v3: release
Browse files- .gitattributes +5 -0
- 8bit/chat_template.jinja +154 -0
- 8bit/config.json +85 -0
- 8bit/generation_config.json +6 -0
- 8bit/macjev_norms_fp32.safetensors +3 -0
- 8bit/model.safetensors +3 -0
- 8bit/model.safetensors.index.json +702 -0
- 8bit/tokenizer.json +3 -0
- 8bit/tokenizer_config.json +33 -0
- LICENSE +202 -0
- NOTICE +35 -0
- README.md +194 -0
- THIRD_PARTY_NOTICES.md +41 -0
- bf16/chat_template.jinja +154 -0
- bf16/config.json +75 -0
- bf16/generation_config.json +6 -0
- bf16/macjev_norms_fp32.safetensors +3 -0
- bf16/model.safetensors +3 -0
- bf16/model.safetensors.index.json +328 -0
- bf16/tokenizer.json +3 -0
- bf16/tokenizer_config.json +33 -0
- config.json +75 -0
- figures/banner.data.json +44 -0
- figures/banner.png +3 -0
- figures/jevbench.data.json +49 -0
- figures/jevbench.png +3 -0
- figures/jevbench.svg +245 -0
- figures/zeroshot.data.json +40 -0
- figures/zeroshot.png +3 -0
- figures/zeroshot.svg +253 -0
- jev_style_decision_mlx.py +1059 -0
- manifest.json +190 -0
- readout_config.json +47 -0
- release_config.json +422 -0
- requirements.txt +8 -0
- validation/SOURCES.json +60 -0
- validation/latency_2b.json +1568 -0
- validation/parity/PREDECLARED_RELEASE_GATES_2B.md +29 -0
- validation/parity/compare_mlx_affine8-g64_base_vs_block.json +276 -0
- validation/parity/compare_mlx_affine8-g64_gate_vs_block.json +228 -0
- validation/parity/compare_mlx_bf16_base_vs_block.json +269 -0
- validation/parity/compare_mlx_bf16_gate_vs_block.json +221 -0
- validation/parity/cross_format_dp.json +68 -0
- validation/runtime/fixture_verify_8bit.json +319 -0
- validation/runtime/fixture_verify_bf16.json +319 -0
- validation/runtime/render_verify.json +88 -0
- validation/runtime/reverify_mlx.json +23 -0
.gitattributes
CHANGED
|
@@ -33,3 +33,8 @@ saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
8bit/tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
| 37 |
+
bf16/tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
| 38 |
+
figures/banner.png filter=lfs diff=lfs merge=lfs -text
|
| 39 |
+
figures/jevbench.png filter=lfs diff=lfs merge=lfs -text
|
| 40 |
+
figures/zeroshot.png filter=lfs diff=lfs merge=lfs -text
|
8bit/chat_template.jinja
ADDED
|
@@ -0,0 +1,154 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{%- set image_count = namespace(value=0) %}
|
| 2 |
+
{%- set video_count = namespace(value=0) %}
|
| 3 |
+
{%- macro render_content(content, do_vision_count, is_system_content=false) %}
|
| 4 |
+
{%- if content is string %}
|
| 5 |
+
{{- content }}
|
| 6 |
+
{%- elif content is iterable and content is not mapping %}
|
| 7 |
+
{%- for item in content %}
|
| 8 |
+
{%- if 'image' in item or 'image_url' in item or item.type == 'image' %}
|
| 9 |
+
{%- if is_system_content %}
|
| 10 |
+
{{- raise_exception('System message cannot contain images.') }}
|
| 11 |
+
{%- endif %}
|
| 12 |
+
{%- if do_vision_count %}
|
| 13 |
+
{%- set image_count.value = image_count.value + 1 %}
|
| 14 |
+
{%- endif %}
|
| 15 |
+
{%- if add_vision_id %}
|
| 16 |
+
{{- 'Picture ' ~ image_count.value ~ ': ' }}
|
| 17 |
+
{%- endif %}
|
| 18 |
+
{{- '<|vision_start|><|image_pad|><|vision_end|>' }}
|
| 19 |
+
{%- elif 'video' in item or item.type == 'video' %}
|
| 20 |
+
{%- if is_system_content %}
|
| 21 |
+
{{- raise_exception('System message cannot contain videos.') }}
|
| 22 |
+
{%- endif %}
|
| 23 |
+
{%- if do_vision_count %}
|
| 24 |
+
{%- set video_count.value = video_count.value + 1 %}
|
| 25 |
+
{%- endif %}
|
| 26 |
+
{%- if add_vision_id %}
|
| 27 |
+
{{- 'Video ' ~ video_count.value ~ ': ' }}
|
| 28 |
+
{%- endif %}
|
| 29 |
+
{{- '<|vision_start|><|video_pad|><|vision_end|>' }}
|
| 30 |
+
{%- elif 'text' in item %}
|
| 31 |
+
{{- item.text }}
|
| 32 |
+
{%- else %}
|
| 33 |
+
{{- raise_exception('Unexpected item type in content.') }}
|
| 34 |
+
{%- endif %}
|
| 35 |
+
{%- endfor %}
|
| 36 |
+
{%- elif content is none or content is undefined %}
|
| 37 |
+
{{- '' }}
|
| 38 |
+
{%- else %}
|
| 39 |
+
{{- raise_exception('Unexpected content type.') }}
|
| 40 |
+
{%- endif %}
|
| 41 |
+
{%- endmacro %}
|
| 42 |
+
{%- if not messages %}
|
| 43 |
+
{{- raise_exception('No messages provided.') }}
|
| 44 |
+
{%- endif %}
|
| 45 |
+
{%- if tools and tools is iterable and tools is not mapping %}
|
| 46 |
+
{{- '<|im_start|>system\n' }}
|
| 47 |
+
{{- "# Tools\n\nYou have access to the following functions:\n\n<tools>" }}
|
| 48 |
+
{%- for tool in tools %}
|
| 49 |
+
{{- "\n" }}
|
| 50 |
+
{{- tool | tojson }}
|
| 51 |
+
{%- endfor %}
|
| 52 |
+
{{- "\n</tools>" }}
|
| 53 |
+
{{- '\n\nIf you choose to call a function ONLY reply in the following format with NO suffix:\n\n<tool_call>\n<function=example_function_name>\n<parameter=example_parameter_1>\nvalue_1\n</parameter>\n<parameter=example_parameter_2>\nThis is the value for the second parameter\nthat can span\nmultiple lines\n</parameter>\n</function>\n</tool_call>\n\n<IMPORTANT>\nReminder:\n- Function calls MUST follow the specified format: an inner <function=...></function> block must be nested within <tool_call></tool_call> XML tags\n- Required parameters MUST be specified\n- You may provide optional reasoning for your function call in natural language BEFORE the function call, but NOT after\n- If there is no function call available, answer the question like normal with your current knowledge and do not tell the user about function calls\n</IMPORTANT>' }}
|
| 54 |
+
{%- if messages[0].role == 'system' %}
|
| 55 |
+
{%- set content = render_content(messages[0].content, false, true)|trim %}
|
| 56 |
+
{%- if content %}
|
| 57 |
+
{{- '\n\n' + content }}
|
| 58 |
+
{%- endif %}
|
| 59 |
+
{%- endif %}
|
| 60 |
+
{{- '<|im_end|>\n' }}
|
| 61 |
+
{%- else %}
|
| 62 |
+
{%- if messages[0].role == 'system' %}
|
| 63 |
+
{%- set content = render_content(messages[0].content, false, true)|trim %}
|
| 64 |
+
{{- '<|im_start|>system\n' + content + '<|im_end|>\n' }}
|
| 65 |
+
{%- endif %}
|
| 66 |
+
{%- endif %}
|
| 67 |
+
{%- set ns = namespace(multi_step_tool=true, last_query_index=messages|length - 1) %}
|
| 68 |
+
{%- for message in messages[::-1] %}
|
| 69 |
+
{%- set index = (messages|length - 1) - loop.index0 %}
|
| 70 |
+
{%- if ns.multi_step_tool and message.role == "user" %}
|
| 71 |
+
{%- set content = render_content(message.content, false)|trim %}
|
| 72 |
+
{%- if not(content.startswith('<tool_response>') and content.endswith('</tool_response>')) %}
|
| 73 |
+
{%- set ns.multi_step_tool = false %}
|
| 74 |
+
{%- set ns.last_query_index = index %}
|
| 75 |
+
{%- endif %}
|
| 76 |
+
{%- endif %}
|
| 77 |
+
{%- endfor %}
|
| 78 |
+
{%- if ns.multi_step_tool %}
|
| 79 |
+
{{- raise_exception('No user query found in messages.') }}
|
| 80 |
+
{%- endif %}
|
| 81 |
+
{%- for message in messages %}
|
| 82 |
+
{%- set content = render_content(message.content, true)|trim %}
|
| 83 |
+
{%- if message.role == "system" %}
|
| 84 |
+
{%- if not loop.first %}
|
| 85 |
+
{{- raise_exception('System message must be at the beginning.') }}
|
| 86 |
+
{%- endif %}
|
| 87 |
+
{%- elif message.role == "user" %}
|
| 88 |
+
{{- '<|im_start|>' + message.role + '\n' + content + '<|im_end|>' + '\n' }}
|
| 89 |
+
{%- elif message.role == "assistant" %}
|
| 90 |
+
{%- set reasoning_content = '' %}
|
| 91 |
+
{%- if message.reasoning_content is string %}
|
| 92 |
+
{%- set reasoning_content = message.reasoning_content %}
|
| 93 |
+
{%- else %}
|
| 94 |
+
{%- if '</think>' in content %}
|
| 95 |
+
{%- set reasoning_content = content.split('</think>')[0].rstrip('\n').split('<think>')[-1].lstrip('\n') %}
|
| 96 |
+
{%- set content = content.split('</think>')[-1].lstrip('\n') %}
|
| 97 |
+
{%- endif %}
|
| 98 |
+
{%- endif %}
|
| 99 |
+
{%- set reasoning_content = reasoning_content|trim %}
|
| 100 |
+
{%- if loop.index0 > ns.last_query_index %}
|
| 101 |
+
{{- '<|im_start|>' + message.role + '\n<think>\n' + reasoning_content + '\n</think>\n\n' + content }}
|
| 102 |
+
{%- else %}
|
| 103 |
+
{{- '<|im_start|>' + message.role + '\n' + content }}
|
| 104 |
+
{%- endif %}
|
| 105 |
+
{%- if message.tool_calls and message.tool_calls is iterable and message.tool_calls is not mapping %}
|
| 106 |
+
{%- for tool_call in message.tool_calls %}
|
| 107 |
+
{%- if tool_call.function is defined %}
|
| 108 |
+
{%- set tool_call = tool_call.function %}
|
| 109 |
+
{%- endif %}
|
| 110 |
+
{%- if loop.first %}
|
| 111 |
+
{%- if content|trim %}
|
| 112 |
+
{{- '\n\n<tool_call>\n<function=' + tool_call.name + '>\n' }}
|
| 113 |
+
{%- else %}
|
| 114 |
+
{{- '<tool_call>\n<function=' + tool_call.name + '>\n' }}
|
| 115 |
+
{%- endif %}
|
| 116 |
+
{%- else %}
|
| 117 |
+
{{- '\n<tool_call>\n<function=' + tool_call.name + '>\n' }}
|
| 118 |
+
{%- endif %}
|
| 119 |
+
{%- if tool_call.arguments is defined %}
|
| 120 |
+
{%- for args_name, args_value in tool_call.arguments|items %}
|
| 121 |
+
{{- '<parameter=' + args_name + '>\n' }}
|
| 122 |
+
{%- set args_value = args_value | tojson | safe if args_value is mapping or (args_value is sequence and args_value is not string) else args_value | string %}
|
| 123 |
+
{{- args_value }}
|
| 124 |
+
{{- '\n</parameter>\n' }}
|
| 125 |
+
{%- endfor %}
|
| 126 |
+
{%- endif %}
|
| 127 |
+
{{- '</function>\n</tool_call>' }}
|
| 128 |
+
{%- endfor %}
|
| 129 |
+
{%- endif %}
|
| 130 |
+
{{- '<|im_end|>\n' }}
|
| 131 |
+
{%- elif message.role == "tool" %}
|
| 132 |
+
{%- if loop.previtem and loop.previtem.role != "tool" %}
|
| 133 |
+
{{- '<|im_start|>user' }}
|
| 134 |
+
{%- endif %}
|
| 135 |
+
{{- '\n<tool_response>\n' }}
|
| 136 |
+
{{- content }}
|
| 137 |
+
{{- '\n</tool_response>' }}
|
| 138 |
+
{%- if not loop.last and loop.nextitem.role != "tool" %}
|
| 139 |
+
{{- '<|im_end|>\n' }}
|
| 140 |
+
{%- elif loop.last %}
|
| 141 |
+
{{- '<|im_end|>\n' }}
|
| 142 |
+
{%- endif %}
|
| 143 |
+
{%- else %}
|
| 144 |
+
{{- raise_exception('Unexpected message role.') }}
|
| 145 |
+
{%- endif %}
|
| 146 |
+
{%- endfor %}
|
| 147 |
+
{%- if add_generation_prompt %}
|
| 148 |
+
{{- '<|im_start|>assistant\n' }}
|
| 149 |
+
{%- if enable_thinking is defined and enable_thinking is true %}
|
| 150 |
+
{{- '<think>\n' }}
|
| 151 |
+
{%- else %}
|
| 152 |
+
{{- '<think>\n\n</think>\n\n' }}
|
| 153 |
+
{%- endif %}
|
| 154 |
+
{%- endif %}
|
8bit/config.json
ADDED
|
@@ -0,0 +1,85 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"architectures": [
|
| 3 |
+
"Qwen3_5ForCausalLM"
|
| 4 |
+
],
|
| 5 |
+
"attention_bias": false,
|
| 6 |
+
"attention_dropout": 0.0,
|
| 7 |
+
"attn_output_gate": true,
|
| 8 |
+
"bos_token_id": null,
|
| 9 |
+
"dtype": "bfloat16",
|
| 10 |
+
"eos_token_id": 248044,
|
| 11 |
+
"full_attention_interval": 4,
|
| 12 |
+
"head_dim": 256,
|
| 13 |
+
"hidden_act": "silu",
|
| 14 |
+
"hidden_size": 2048,
|
| 15 |
+
"initializer_range": 0.02,
|
| 16 |
+
"intermediate_size": 6144,
|
| 17 |
+
"layer_types": [
|
| 18 |
+
"linear_attention",
|
| 19 |
+
"linear_attention",
|
| 20 |
+
"linear_attention",
|
| 21 |
+
"full_attention",
|
| 22 |
+
"linear_attention",
|
| 23 |
+
"linear_attention",
|
| 24 |
+
"linear_attention",
|
| 25 |
+
"full_attention",
|
| 26 |
+
"linear_attention",
|
| 27 |
+
"linear_attention",
|
| 28 |
+
"linear_attention",
|
| 29 |
+
"full_attention",
|
| 30 |
+
"linear_attention",
|
| 31 |
+
"linear_attention",
|
| 32 |
+
"linear_attention",
|
| 33 |
+
"full_attention",
|
| 34 |
+
"linear_attention",
|
| 35 |
+
"linear_attention",
|
| 36 |
+
"linear_attention",
|
| 37 |
+
"full_attention",
|
| 38 |
+
"linear_attention",
|
| 39 |
+
"linear_attention",
|
| 40 |
+
"linear_attention",
|
| 41 |
+
"full_attention"
|
| 42 |
+
],
|
| 43 |
+
"linear_conv_kernel_dim": 4,
|
| 44 |
+
"linear_key_head_dim": 128,
|
| 45 |
+
"linear_num_key_heads": 16,
|
| 46 |
+
"linear_num_value_heads": 16,
|
| 47 |
+
"linear_value_head_dim": 128,
|
| 48 |
+
"mamba_ssm_dtype": "float32",
|
| 49 |
+
"max_position_embeddings": 262144,
|
| 50 |
+
"mlp_only_layers": [],
|
| 51 |
+
"model_type": "qwen3_5",
|
| 52 |
+
"mtp_num_hidden_layers": 1,
|
| 53 |
+
"mtp_use_dedicated_embeddings": false,
|
| 54 |
+
"num_attention_heads": 8,
|
| 55 |
+
"num_hidden_layers": 24,
|
| 56 |
+
"num_key_value_heads": 2,
|
| 57 |
+
"pad_token_id": null,
|
| 58 |
+
"partial_rotary_factor": 0.25,
|
| 59 |
+
"quantization": {
|
| 60 |
+
"group_size": 64,
|
| 61 |
+
"bits": 8,
|
| 62 |
+
"mode": "affine"
|
| 63 |
+
},
|
| 64 |
+
"quantization_config": {
|
| 65 |
+
"group_size": 64,
|
| 66 |
+
"bits": 8,
|
| 67 |
+
"mode": "affine"
|
| 68 |
+
},
|
| 69 |
+
"rms_norm_eps": 1e-06,
|
| 70 |
+
"rope_parameters": {
|
| 71 |
+
"mrope_interleaved": true,
|
| 72 |
+
"mrope_section": [
|
| 73 |
+
11,
|
| 74 |
+
11,
|
| 75 |
+
10
|
| 76 |
+
],
|
| 77 |
+
"partial_rotary_factor": 0.25,
|
| 78 |
+
"rope_theta": 10000000,
|
| 79 |
+
"type": "default"
|
| 80 |
+
},
|
| 81 |
+
"tie_word_embeddings": true,
|
| 82 |
+
"transformers_version": "5.17.0",
|
| 83 |
+
"use_cache": false,
|
| 84 |
+
"vocab_size": 248320
|
| 85 |
+
}
|
8bit/generation_config.json
ADDED
|
@@ -0,0 +1,6 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"_from_model_config": true,
|
| 3 |
+
"eos_token_id": 248044,
|
| 4 |
+
"transformers_version": "5.17.0",
|
| 5 |
+
"use_cache": true
|
| 6 |
+
}
|
8bit/macjev_norms_fp32.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:02f08c422228929c44dd84856678ea95d41401138aa56b1b771a654376d3e51c
|
| 3 |
+
size 420112
|
8bit/model.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:184b4dda2f1285fe95a00a6271b364c861d370fbf913030f0259b2423f88a740
|
| 3 |
+
size 2000043057
|
8bit/model.safetensors.index.json
ADDED
|
@@ -0,0 +1,702 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"metadata": {
|
| 3 |
+
"total_size": 1999953536,
|
| 4 |
+
"total_parameters": 1881824512
|
| 5 |
+
},
|
| 6 |
+
"weight_map": {
|
| 7 |
+
"language_model.model.embed_tokens.biases": "model.safetensors",
|
| 8 |
+
"language_model.model.embed_tokens.scales": "model.safetensors",
|
| 9 |
+
"language_model.model.embed_tokens.weight": "model.safetensors",
|
| 10 |
+
"language_model.model.layers.0.input_layernorm.weight": "model.safetensors",
|
| 11 |
+
"language_model.model.layers.0.linear_attn.A_log": "model.safetensors",
|
| 12 |
+
"language_model.model.layers.0.linear_attn.conv1d.weight": "model.safetensors",
|
| 13 |
+
"language_model.model.layers.0.linear_attn.dt_bias": "model.safetensors",
|
| 14 |
+
"language_model.model.layers.0.linear_attn.in_proj_a.biases": "model.safetensors",
|
| 15 |
+
"language_model.model.layers.0.linear_attn.in_proj_a.scales": "model.safetensors",
|
| 16 |
+
"language_model.model.layers.0.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 17 |
+
"language_model.model.layers.0.linear_attn.in_proj_b.biases": "model.safetensors",
|
| 18 |
+
"language_model.model.layers.0.linear_attn.in_proj_b.scales": "model.safetensors",
|
| 19 |
+
"language_model.model.layers.0.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 20 |
+
"language_model.model.layers.0.linear_attn.in_proj_qkv.biases": "model.safetensors",
|
| 21 |
+
"language_model.model.layers.0.linear_attn.in_proj_qkv.scales": "model.safetensors",
|
| 22 |
+
"language_model.model.layers.0.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 23 |
+
"language_model.model.layers.0.linear_attn.in_proj_z.biases": "model.safetensors",
|
| 24 |
+
"language_model.model.layers.0.linear_attn.in_proj_z.scales": "model.safetensors",
|
| 25 |
+
"language_model.model.layers.0.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 26 |
+
"language_model.model.layers.0.linear_attn.norm.weight": "model.safetensors",
|
| 27 |
+
"language_model.model.layers.0.linear_attn.out_proj.biases": "model.safetensors",
|
| 28 |
+
"language_model.model.layers.0.linear_attn.out_proj.scales": "model.safetensors",
|
| 29 |
+
"language_model.model.layers.0.linear_attn.out_proj.weight": "model.safetensors",
|
| 30 |
+
"language_model.model.layers.0.mlp.down_proj.biases": "model.safetensors",
|
| 31 |
+
"language_model.model.layers.0.mlp.down_proj.scales": "model.safetensors",
|
| 32 |
+
"language_model.model.layers.0.mlp.down_proj.weight": "model.safetensors",
|
| 33 |
+
"language_model.model.layers.0.mlp.gate_proj.biases": "model.safetensors",
|
| 34 |
+
"language_model.model.layers.0.mlp.gate_proj.scales": "model.safetensors",
|
| 35 |
+
"language_model.model.layers.0.mlp.gate_proj.weight": "model.safetensors",
|
| 36 |
+
"language_model.model.layers.0.mlp.up_proj.biases": "model.safetensors",
|
| 37 |
+
"language_model.model.layers.0.mlp.up_proj.scales": "model.safetensors",
|
| 38 |
+
"language_model.model.layers.0.mlp.up_proj.weight": "model.safetensors",
|
| 39 |
+
"language_model.model.layers.0.post_attention_layernorm.weight": "model.safetensors",
|
| 40 |
+
"language_model.model.layers.1.input_layernorm.weight": "model.safetensors",
|
| 41 |
+
"language_model.model.layers.1.linear_attn.A_log": "model.safetensors",
|
| 42 |
+
"language_model.model.layers.1.linear_attn.conv1d.weight": "model.safetensors",
|
| 43 |
+
"language_model.model.layers.1.linear_attn.dt_bias": "model.safetensors",
|
| 44 |
+
"language_model.model.layers.1.linear_attn.in_proj_a.biases": "model.safetensors",
|
| 45 |
+
"language_model.model.layers.1.linear_attn.in_proj_a.scales": "model.safetensors",
|
| 46 |
+
"language_model.model.layers.1.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 47 |
+
"language_model.model.layers.1.linear_attn.in_proj_b.biases": "model.safetensors",
|
| 48 |
+
"language_model.model.layers.1.linear_attn.in_proj_b.scales": "model.safetensors",
|
| 49 |
+
"language_model.model.layers.1.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 50 |
+
"language_model.model.layers.1.linear_attn.in_proj_qkv.biases": "model.safetensors",
|
| 51 |
+
"language_model.model.layers.1.linear_attn.in_proj_qkv.scales": "model.safetensors",
|
| 52 |
+
"language_model.model.layers.1.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 53 |
+
"language_model.model.layers.1.linear_attn.in_proj_z.biases": "model.safetensors",
|
| 54 |
+
"language_model.model.layers.1.linear_attn.in_proj_z.scales": "model.safetensors",
|
| 55 |
+
"language_model.model.layers.1.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 56 |
+
"language_model.model.layers.1.linear_attn.norm.weight": "model.safetensors",
|
| 57 |
+
"language_model.model.layers.1.linear_attn.out_proj.biases": "model.safetensors",
|
| 58 |
+
"language_model.model.layers.1.linear_attn.out_proj.scales": "model.safetensors",
|
| 59 |
+
"language_model.model.layers.1.linear_attn.out_proj.weight": "model.safetensors",
|
| 60 |
+
"language_model.model.layers.1.mlp.down_proj.biases": "model.safetensors",
|
| 61 |
+
"language_model.model.layers.1.mlp.down_proj.scales": "model.safetensors",
|
| 62 |
+
"language_model.model.layers.1.mlp.down_proj.weight": "model.safetensors",
|
| 63 |
+
"language_model.model.layers.1.mlp.gate_proj.biases": "model.safetensors",
|
| 64 |
+
"language_model.model.layers.1.mlp.gate_proj.scales": "model.safetensors",
|
| 65 |
+
"language_model.model.layers.1.mlp.gate_proj.weight": "model.safetensors",
|
| 66 |
+
"language_model.model.layers.1.mlp.up_proj.biases": "model.safetensors",
|
| 67 |
+
"language_model.model.layers.1.mlp.up_proj.scales": "model.safetensors",
|
| 68 |
+
"language_model.model.layers.1.mlp.up_proj.weight": "model.safetensors",
|
| 69 |
+
"language_model.model.layers.1.post_attention_layernorm.weight": "model.safetensors",
|
| 70 |
+
"language_model.model.layers.10.input_layernorm.weight": "model.safetensors",
|
| 71 |
+
"language_model.model.layers.10.linear_attn.A_log": "model.safetensors",
|
| 72 |
+
"language_model.model.layers.10.linear_attn.conv1d.weight": "model.safetensors",
|
| 73 |
+
"language_model.model.layers.10.linear_attn.dt_bias": "model.safetensors",
|
| 74 |
+
"language_model.model.layers.10.linear_attn.in_proj_a.biases": "model.safetensors",
|
| 75 |
+
"language_model.model.layers.10.linear_attn.in_proj_a.scales": "model.safetensors",
|
| 76 |
+
"language_model.model.layers.10.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 77 |
+
"language_model.model.layers.10.linear_attn.in_proj_b.biases": "model.safetensors",
|
| 78 |
+
"language_model.model.layers.10.linear_attn.in_proj_b.scales": "model.safetensors",
|
| 79 |
+
"language_model.model.layers.10.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 80 |
+
"language_model.model.layers.10.linear_attn.in_proj_qkv.biases": "model.safetensors",
|
| 81 |
+
"language_model.model.layers.10.linear_attn.in_proj_qkv.scales": "model.safetensors",
|
| 82 |
+
"language_model.model.layers.10.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 83 |
+
"language_model.model.layers.10.linear_attn.in_proj_z.biases": "model.safetensors",
|
| 84 |
+
"language_model.model.layers.10.linear_attn.in_proj_z.scales": "model.safetensors",
|
| 85 |
+
"language_model.model.layers.10.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 86 |
+
"language_model.model.layers.10.linear_attn.norm.weight": "model.safetensors",
|
| 87 |
+
"language_model.model.layers.10.linear_attn.out_proj.biases": "model.safetensors",
|
| 88 |
+
"language_model.model.layers.10.linear_attn.out_proj.scales": "model.safetensors",
|
| 89 |
+
"language_model.model.layers.10.linear_attn.out_proj.weight": "model.safetensors",
|
| 90 |
+
"language_model.model.layers.10.mlp.down_proj.biases": "model.safetensors",
|
| 91 |
+
"language_model.model.layers.10.mlp.down_proj.scales": "model.safetensors",
|
| 92 |
+
"language_model.model.layers.10.mlp.down_proj.weight": "model.safetensors",
|
| 93 |
+
"language_model.model.layers.10.mlp.gate_proj.biases": "model.safetensors",
|
| 94 |
+
"language_model.model.layers.10.mlp.gate_proj.scales": "model.safetensors",
|
| 95 |
+
"language_model.model.layers.10.mlp.gate_proj.weight": "model.safetensors",
|
| 96 |
+
"language_model.model.layers.10.mlp.up_proj.biases": "model.safetensors",
|
| 97 |
+
"language_model.model.layers.10.mlp.up_proj.scales": "model.safetensors",
|
| 98 |
+
"language_model.model.layers.10.mlp.up_proj.weight": "model.safetensors",
|
| 99 |
+
"language_model.model.layers.10.post_attention_layernorm.weight": "model.safetensors",
|
| 100 |
+
"language_model.model.layers.11.input_layernorm.weight": "model.safetensors",
|
| 101 |
+
"language_model.model.layers.11.mlp.down_proj.biases": "model.safetensors",
|
| 102 |
+
"language_model.model.layers.11.mlp.down_proj.scales": "model.safetensors",
|
| 103 |
+
"language_model.model.layers.11.mlp.down_proj.weight": "model.safetensors",
|
| 104 |
+
"language_model.model.layers.11.mlp.gate_proj.biases": "model.safetensors",
|
| 105 |
+
"language_model.model.layers.11.mlp.gate_proj.scales": "model.safetensors",
|
| 106 |
+
"language_model.model.layers.11.mlp.gate_proj.weight": "model.safetensors",
|
| 107 |
+
"language_model.model.layers.11.mlp.up_proj.biases": "model.safetensors",
|
| 108 |
+
"language_model.model.layers.11.mlp.up_proj.scales": "model.safetensors",
|
| 109 |
+
"language_model.model.layers.11.mlp.up_proj.weight": "model.safetensors",
|
| 110 |
+
"language_model.model.layers.11.post_attention_layernorm.weight": "model.safetensors",
|
| 111 |
+
"language_model.model.layers.11.self_attn.k_norm.weight": "model.safetensors",
|
| 112 |
+
"language_model.model.layers.11.self_attn.k_proj.biases": "model.safetensors",
|
| 113 |
+
"language_model.model.layers.11.self_attn.k_proj.scales": "model.safetensors",
|
| 114 |
+
"language_model.model.layers.11.self_attn.k_proj.weight": "model.safetensors",
|
| 115 |
+
"language_model.model.layers.11.self_attn.o_proj.biases": "model.safetensors",
|
| 116 |
+
"language_model.model.layers.11.self_attn.o_proj.scales": "model.safetensors",
|
| 117 |
+
"language_model.model.layers.11.self_attn.o_proj.weight": "model.safetensors",
|
| 118 |
+
"language_model.model.layers.11.self_attn.q_norm.weight": "model.safetensors",
|
| 119 |
+
"language_model.model.layers.11.self_attn.q_proj.biases": "model.safetensors",
|
| 120 |
+
"language_model.model.layers.11.self_attn.q_proj.scales": "model.safetensors",
|
| 121 |
+
"language_model.model.layers.11.self_attn.q_proj.weight": "model.safetensors",
|
| 122 |
+
"language_model.model.layers.11.self_attn.v_proj.biases": "model.safetensors",
|
| 123 |
+
"language_model.model.layers.11.self_attn.v_proj.scales": "model.safetensors",
|
| 124 |
+
"language_model.model.layers.11.self_attn.v_proj.weight": "model.safetensors",
|
| 125 |
+
"language_model.model.layers.12.input_layernorm.weight": "model.safetensors",
|
| 126 |
+
"language_model.model.layers.12.linear_attn.A_log": "model.safetensors",
|
| 127 |
+
"language_model.model.layers.12.linear_attn.conv1d.weight": "model.safetensors",
|
| 128 |
+
"language_model.model.layers.12.linear_attn.dt_bias": "model.safetensors",
|
| 129 |
+
"language_model.model.layers.12.linear_attn.in_proj_a.biases": "model.safetensors",
|
| 130 |
+
"language_model.model.layers.12.linear_attn.in_proj_a.scales": "model.safetensors",
|
| 131 |
+
"language_model.model.layers.12.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 132 |
+
"language_model.model.layers.12.linear_attn.in_proj_b.biases": "model.safetensors",
|
| 133 |
+
"language_model.model.layers.12.linear_attn.in_proj_b.scales": "model.safetensors",
|
| 134 |
+
"language_model.model.layers.12.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 135 |
+
"language_model.model.layers.12.linear_attn.in_proj_qkv.biases": "model.safetensors",
|
| 136 |
+
"language_model.model.layers.12.linear_attn.in_proj_qkv.scales": "model.safetensors",
|
| 137 |
+
"language_model.model.layers.12.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 138 |
+
"language_model.model.layers.12.linear_attn.in_proj_z.biases": "model.safetensors",
|
| 139 |
+
"language_model.model.layers.12.linear_attn.in_proj_z.scales": "model.safetensors",
|
| 140 |
+
"language_model.model.layers.12.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 141 |
+
"language_model.model.layers.12.linear_attn.norm.weight": "model.safetensors",
|
| 142 |
+
"language_model.model.layers.12.linear_attn.out_proj.biases": "model.safetensors",
|
| 143 |
+
"language_model.model.layers.12.linear_attn.out_proj.scales": "model.safetensors",
|
| 144 |
+
"language_model.model.layers.12.linear_attn.out_proj.weight": "model.safetensors",
|
| 145 |
+
"language_model.model.layers.12.mlp.down_proj.biases": "model.safetensors",
|
| 146 |
+
"language_model.model.layers.12.mlp.down_proj.scales": "model.safetensors",
|
| 147 |
+
"language_model.model.layers.12.mlp.down_proj.weight": "model.safetensors",
|
| 148 |
+
"language_model.model.layers.12.mlp.gate_proj.biases": "model.safetensors",
|
| 149 |
+
"language_model.model.layers.12.mlp.gate_proj.scales": "model.safetensors",
|
| 150 |
+
"language_model.model.layers.12.mlp.gate_proj.weight": "model.safetensors",
|
| 151 |
+
"language_model.model.layers.12.mlp.up_proj.biases": "model.safetensors",
|
| 152 |
+
"language_model.model.layers.12.mlp.up_proj.scales": "model.safetensors",
|
| 153 |
+
"language_model.model.layers.12.mlp.up_proj.weight": "model.safetensors",
|
| 154 |
+
"language_model.model.layers.12.post_attention_layernorm.weight": "model.safetensors",
|
| 155 |
+
"language_model.model.layers.13.input_layernorm.weight": "model.safetensors",
|
| 156 |
+
"language_model.model.layers.13.linear_attn.A_log": "model.safetensors",
|
| 157 |
+
"language_model.model.layers.13.linear_attn.conv1d.weight": "model.safetensors",
|
| 158 |
+
"language_model.model.layers.13.linear_attn.dt_bias": "model.safetensors",
|
| 159 |
+
"language_model.model.layers.13.linear_attn.in_proj_a.biases": "model.safetensors",
|
| 160 |
+
"language_model.model.layers.13.linear_attn.in_proj_a.scales": "model.safetensors",
|
| 161 |
+
"language_model.model.layers.13.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 162 |
+
"language_model.model.layers.13.linear_attn.in_proj_b.biases": "model.safetensors",
|
| 163 |
+
"language_model.model.layers.13.linear_attn.in_proj_b.scales": "model.safetensors",
|
| 164 |
+
"language_model.model.layers.13.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 165 |
+
"language_model.model.layers.13.linear_attn.in_proj_qkv.biases": "model.safetensors",
|
| 166 |
+
"language_model.model.layers.13.linear_attn.in_proj_qkv.scales": "model.safetensors",
|
| 167 |
+
"language_model.model.layers.13.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 168 |
+
"language_model.model.layers.13.linear_attn.in_proj_z.biases": "model.safetensors",
|
| 169 |
+
"language_model.model.layers.13.linear_attn.in_proj_z.scales": "model.safetensors",
|
| 170 |
+
"language_model.model.layers.13.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 171 |
+
"language_model.model.layers.13.linear_attn.norm.weight": "model.safetensors",
|
| 172 |
+
"language_model.model.layers.13.linear_attn.out_proj.biases": "model.safetensors",
|
| 173 |
+
"language_model.model.layers.13.linear_attn.out_proj.scales": "model.safetensors",
|
| 174 |
+
"language_model.model.layers.13.linear_attn.out_proj.weight": "model.safetensors",
|
| 175 |
+
"language_model.model.layers.13.mlp.down_proj.biases": "model.safetensors",
|
| 176 |
+
"language_model.model.layers.13.mlp.down_proj.scales": "model.safetensors",
|
| 177 |
+
"language_model.model.layers.13.mlp.down_proj.weight": "model.safetensors",
|
| 178 |
+
"language_model.model.layers.13.mlp.gate_proj.biases": "model.safetensors",
|
| 179 |
+
"language_model.model.layers.13.mlp.gate_proj.scales": "model.safetensors",
|
| 180 |
+
"language_model.model.layers.13.mlp.gate_proj.weight": "model.safetensors",
|
| 181 |
+
"language_model.model.layers.13.mlp.up_proj.biases": "model.safetensors",
|
| 182 |
+
"language_model.model.layers.13.mlp.up_proj.scales": "model.safetensors",
|
| 183 |
+
"language_model.model.layers.13.mlp.up_proj.weight": "model.safetensors",
|
| 184 |
+
"language_model.model.layers.13.post_attention_layernorm.weight": "model.safetensors",
|
| 185 |
+
"language_model.model.layers.14.input_layernorm.weight": "model.safetensors",
|
| 186 |
+
"language_model.model.layers.14.linear_attn.A_log": "model.safetensors",
|
| 187 |
+
"language_model.model.layers.14.linear_attn.conv1d.weight": "model.safetensors",
|
| 188 |
+
"language_model.model.layers.14.linear_attn.dt_bias": "model.safetensors",
|
| 189 |
+
"language_model.model.layers.14.linear_attn.in_proj_a.biases": "model.safetensors",
|
| 190 |
+
"language_model.model.layers.14.linear_attn.in_proj_a.scales": "model.safetensors",
|
| 191 |
+
"language_model.model.layers.14.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 192 |
+
"language_model.model.layers.14.linear_attn.in_proj_b.biases": "model.safetensors",
|
| 193 |
+
"language_model.model.layers.14.linear_attn.in_proj_b.scales": "model.safetensors",
|
| 194 |
+
"language_model.model.layers.14.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 195 |
+
"language_model.model.layers.14.linear_attn.in_proj_qkv.biases": "model.safetensors",
|
| 196 |
+
"language_model.model.layers.14.linear_attn.in_proj_qkv.scales": "model.safetensors",
|
| 197 |
+
"language_model.model.layers.14.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 198 |
+
"language_model.model.layers.14.linear_attn.in_proj_z.biases": "model.safetensors",
|
| 199 |
+
"language_model.model.layers.14.linear_attn.in_proj_z.scales": "model.safetensors",
|
| 200 |
+
"language_model.model.layers.14.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 201 |
+
"language_model.model.layers.14.linear_attn.norm.weight": "model.safetensors",
|
| 202 |
+
"language_model.model.layers.14.linear_attn.out_proj.biases": "model.safetensors",
|
| 203 |
+
"language_model.model.layers.14.linear_attn.out_proj.scales": "model.safetensors",
|
| 204 |
+
"language_model.model.layers.14.linear_attn.out_proj.weight": "model.safetensors",
|
| 205 |
+
"language_model.model.layers.14.mlp.down_proj.biases": "model.safetensors",
|
| 206 |
+
"language_model.model.layers.14.mlp.down_proj.scales": "model.safetensors",
|
| 207 |
+
"language_model.model.layers.14.mlp.down_proj.weight": "model.safetensors",
|
| 208 |
+
"language_model.model.layers.14.mlp.gate_proj.biases": "model.safetensors",
|
| 209 |
+
"language_model.model.layers.14.mlp.gate_proj.scales": "model.safetensors",
|
| 210 |
+
"language_model.model.layers.14.mlp.gate_proj.weight": "model.safetensors",
|
| 211 |
+
"language_model.model.layers.14.mlp.up_proj.biases": "model.safetensors",
|
| 212 |
+
"language_model.model.layers.14.mlp.up_proj.scales": "model.safetensors",
|
| 213 |
+
"language_model.model.layers.14.mlp.up_proj.weight": "model.safetensors",
|
| 214 |
+
"language_model.model.layers.14.post_attention_layernorm.weight": "model.safetensors",
|
| 215 |
+
"language_model.model.layers.15.input_layernorm.weight": "model.safetensors",
|
| 216 |
+
"language_model.model.layers.15.mlp.down_proj.biases": "model.safetensors",
|
| 217 |
+
"language_model.model.layers.15.mlp.down_proj.scales": "model.safetensors",
|
| 218 |
+
"language_model.model.layers.15.mlp.down_proj.weight": "model.safetensors",
|
| 219 |
+
"language_model.model.layers.15.mlp.gate_proj.biases": "model.safetensors",
|
| 220 |
+
"language_model.model.layers.15.mlp.gate_proj.scales": "model.safetensors",
|
| 221 |
+
"language_model.model.layers.15.mlp.gate_proj.weight": "model.safetensors",
|
| 222 |
+
"language_model.model.layers.15.mlp.up_proj.biases": "model.safetensors",
|
| 223 |
+
"language_model.model.layers.15.mlp.up_proj.scales": "model.safetensors",
|
| 224 |
+
"language_model.model.layers.15.mlp.up_proj.weight": "model.safetensors",
|
| 225 |
+
"language_model.model.layers.15.post_attention_layernorm.weight": "model.safetensors",
|
| 226 |
+
"language_model.model.layers.15.self_attn.k_norm.weight": "model.safetensors",
|
| 227 |
+
"language_model.model.layers.15.self_attn.k_proj.biases": "model.safetensors",
|
| 228 |
+
"language_model.model.layers.15.self_attn.k_proj.scales": "model.safetensors",
|
| 229 |
+
"language_model.model.layers.15.self_attn.k_proj.weight": "model.safetensors",
|
| 230 |
+
"language_model.model.layers.15.self_attn.o_proj.biases": "model.safetensors",
|
| 231 |
+
"language_model.model.layers.15.self_attn.o_proj.scales": "model.safetensors",
|
| 232 |
+
"language_model.model.layers.15.self_attn.o_proj.weight": "model.safetensors",
|
| 233 |
+
"language_model.model.layers.15.self_attn.q_norm.weight": "model.safetensors",
|
| 234 |
+
"language_model.model.layers.15.self_attn.q_proj.biases": "model.safetensors",
|
| 235 |
+
"language_model.model.layers.15.self_attn.q_proj.scales": "model.safetensors",
|
| 236 |
+
"language_model.model.layers.15.self_attn.q_proj.weight": "model.safetensors",
|
| 237 |
+
"language_model.model.layers.15.self_attn.v_proj.biases": "model.safetensors",
|
| 238 |
+
"language_model.model.layers.15.self_attn.v_proj.scales": "model.safetensors",
|
| 239 |
+
"language_model.model.layers.15.self_attn.v_proj.weight": "model.safetensors",
|
| 240 |
+
"language_model.model.layers.16.input_layernorm.weight": "model.safetensors",
|
| 241 |
+
"language_model.model.layers.16.linear_attn.A_log": "model.safetensors",
|
| 242 |
+
"language_model.model.layers.16.linear_attn.conv1d.weight": "model.safetensors",
|
| 243 |
+
"language_model.model.layers.16.linear_attn.dt_bias": "model.safetensors",
|
| 244 |
+
"language_model.model.layers.16.linear_attn.in_proj_a.biases": "model.safetensors",
|
| 245 |
+
"language_model.model.layers.16.linear_attn.in_proj_a.scales": "model.safetensors",
|
| 246 |
+
"language_model.model.layers.16.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 247 |
+
"language_model.model.layers.16.linear_attn.in_proj_b.biases": "model.safetensors",
|
| 248 |
+
"language_model.model.layers.16.linear_attn.in_proj_b.scales": "model.safetensors",
|
| 249 |
+
"language_model.model.layers.16.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 250 |
+
"language_model.model.layers.16.linear_attn.in_proj_qkv.biases": "model.safetensors",
|
| 251 |
+
"language_model.model.layers.16.linear_attn.in_proj_qkv.scales": "model.safetensors",
|
| 252 |
+
"language_model.model.layers.16.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 253 |
+
"language_model.model.layers.16.linear_attn.in_proj_z.biases": "model.safetensors",
|
| 254 |
+
"language_model.model.layers.16.linear_attn.in_proj_z.scales": "model.safetensors",
|
| 255 |
+
"language_model.model.layers.16.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 256 |
+
"language_model.model.layers.16.linear_attn.norm.weight": "model.safetensors",
|
| 257 |
+
"language_model.model.layers.16.linear_attn.out_proj.biases": "model.safetensors",
|
| 258 |
+
"language_model.model.layers.16.linear_attn.out_proj.scales": "model.safetensors",
|
| 259 |
+
"language_model.model.layers.16.linear_attn.out_proj.weight": "model.safetensors",
|
| 260 |
+
"language_model.model.layers.16.mlp.down_proj.biases": "model.safetensors",
|
| 261 |
+
"language_model.model.layers.16.mlp.down_proj.scales": "model.safetensors",
|
| 262 |
+
"language_model.model.layers.16.mlp.down_proj.weight": "model.safetensors",
|
| 263 |
+
"language_model.model.layers.16.mlp.gate_proj.biases": "model.safetensors",
|
| 264 |
+
"language_model.model.layers.16.mlp.gate_proj.scales": "model.safetensors",
|
| 265 |
+
"language_model.model.layers.16.mlp.gate_proj.weight": "model.safetensors",
|
| 266 |
+
"language_model.model.layers.16.mlp.up_proj.biases": "model.safetensors",
|
| 267 |
+
"language_model.model.layers.16.mlp.up_proj.scales": "model.safetensors",
|
| 268 |
+
"language_model.model.layers.16.mlp.up_proj.weight": "model.safetensors",
|
| 269 |
+
"language_model.model.layers.16.post_attention_layernorm.weight": "model.safetensors",
|
| 270 |
+
"language_model.model.layers.17.input_layernorm.weight": "model.safetensors",
|
| 271 |
+
"language_model.model.layers.17.linear_attn.A_log": "model.safetensors",
|
| 272 |
+
"language_model.model.layers.17.linear_attn.conv1d.weight": "model.safetensors",
|
| 273 |
+
"language_model.model.layers.17.linear_attn.dt_bias": "model.safetensors",
|
| 274 |
+
"language_model.model.layers.17.linear_attn.in_proj_a.biases": "model.safetensors",
|
| 275 |
+
"language_model.model.layers.17.linear_attn.in_proj_a.scales": "model.safetensors",
|
| 276 |
+
"language_model.model.layers.17.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 277 |
+
"language_model.model.layers.17.linear_attn.in_proj_b.biases": "model.safetensors",
|
| 278 |
+
"language_model.model.layers.17.linear_attn.in_proj_b.scales": "model.safetensors",
|
| 279 |
+
"language_model.model.layers.17.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 280 |
+
"language_model.model.layers.17.linear_attn.in_proj_qkv.biases": "model.safetensors",
|
| 281 |
+
"language_model.model.layers.17.linear_attn.in_proj_qkv.scales": "model.safetensors",
|
| 282 |
+
"language_model.model.layers.17.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 283 |
+
"language_model.model.layers.17.linear_attn.in_proj_z.biases": "model.safetensors",
|
| 284 |
+
"language_model.model.layers.17.linear_attn.in_proj_z.scales": "model.safetensors",
|
| 285 |
+
"language_model.model.layers.17.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 286 |
+
"language_model.model.layers.17.linear_attn.norm.weight": "model.safetensors",
|
| 287 |
+
"language_model.model.layers.17.linear_attn.out_proj.biases": "model.safetensors",
|
| 288 |
+
"language_model.model.layers.17.linear_attn.out_proj.scales": "model.safetensors",
|
| 289 |
+
"language_model.model.layers.17.linear_attn.out_proj.weight": "model.safetensors",
|
| 290 |
+
"language_model.model.layers.17.mlp.down_proj.biases": "model.safetensors",
|
| 291 |
+
"language_model.model.layers.17.mlp.down_proj.scales": "model.safetensors",
|
| 292 |
+
"language_model.model.layers.17.mlp.down_proj.weight": "model.safetensors",
|
| 293 |
+
"language_model.model.layers.17.mlp.gate_proj.biases": "model.safetensors",
|
| 294 |
+
"language_model.model.layers.17.mlp.gate_proj.scales": "model.safetensors",
|
| 295 |
+
"language_model.model.layers.17.mlp.gate_proj.weight": "model.safetensors",
|
| 296 |
+
"language_model.model.layers.17.mlp.up_proj.biases": "model.safetensors",
|
| 297 |
+
"language_model.model.layers.17.mlp.up_proj.scales": "model.safetensors",
|
| 298 |
+
"language_model.model.layers.17.mlp.up_proj.weight": "model.safetensors",
|
| 299 |
+
"language_model.model.layers.17.post_attention_layernorm.weight": "model.safetensors",
|
| 300 |
+
"language_model.model.layers.18.input_layernorm.weight": "model.safetensors",
|
| 301 |
+
"language_model.model.layers.18.linear_attn.A_log": "model.safetensors",
|
| 302 |
+
"language_model.model.layers.18.linear_attn.conv1d.weight": "model.safetensors",
|
| 303 |
+
"language_model.model.layers.18.linear_attn.dt_bias": "model.safetensors",
|
| 304 |
+
"language_model.model.layers.18.linear_attn.in_proj_a.biases": "model.safetensors",
|
| 305 |
+
"language_model.model.layers.18.linear_attn.in_proj_a.scales": "model.safetensors",
|
| 306 |
+
"language_model.model.layers.18.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 307 |
+
"language_model.model.layers.18.linear_attn.in_proj_b.biases": "model.safetensors",
|
| 308 |
+
"language_model.model.layers.18.linear_attn.in_proj_b.scales": "model.safetensors",
|
| 309 |
+
"language_model.model.layers.18.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 310 |
+
"language_model.model.layers.18.linear_attn.in_proj_qkv.biases": "model.safetensors",
|
| 311 |
+
"language_model.model.layers.18.linear_attn.in_proj_qkv.scales": "model.safetensors",
|
| 312 |
+
"language_model.model.layers.18.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 313 |
+
"language_model.model.layers.18.linear_attn.in_proj_z.biases": "model.safetensors",
|
| 314 |
+
"language_model.model.layers.18.linear_attn.in_proj_z.scales": "model.safetensors",
|
| 315 |
+
"language_model.model.layers.18.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 316 |
+
"language_model.model.layers.18.linear_attn.norm.weight": "model.safetensors",
|
| 317 |
+
"language_model.model.layers.18.linear_attn.out_proj.biases": "model.safetensors",
|
| 318 |
+
"language_model.model.layers.18.linear_attn.out_proj.scales": "model.safetensors",
|
| 319 |
+
"language_model.model.layers.18.linear_attn.out_proj.weight": "model.safetensors",
|
| 320 |
+
"language_model.model.layers.18.mlp.down_proj.biases": "model.safetensors",
|
| 321 |
+
"language_model.model.layers.18.mlp.down_proj.scales": "model.safetensors",
|
| 322 |
+
"language_model.model.layers.18.mlp.down_proj.weight": "model.safetensors",
|
| 323 |
+
"language_model.model.layers.18.mlp.gate_proj.biases": "model.safetensors",
|
| 324 |
+
"language_model.model.layers.18.mlp.gate_proj.scales": "model.safetensors",
|
| 325 |
+
"language_model.model.layers.18.mlp.gate_proj.weight": "model.safetensors",
|
| 326 |
+
"language_model.model.layers.18.mlp.up_proj.biases": "model.safetensors",
|
| 327 |
+
"language_model.model.layers.18.mlp.up_proj.scales": "model.safetensors",
|
| 328 |
+
"language_model.model.layers.18.mlp.up_proj.weight": "model.safetensors",
|
| 329 |
+
"language_model.model.layers.18.post_attention_layernorm.weight": "model.safetensors",
|
| 330 |
+
"language_model.model.layers.19.input_layernorm.weight": "model.safetensors",
|
| 331 |
+
"language_model.model.layers.19.mlp.down_proj.biases": "model.safetensors",
|
| 332 |
+
"language_model.model.layers.19.mlp.down_proj.scales": "model.safetensors",
|
| 333 |
+
"language_model.model.layers.19.mlp.down_proj.weight": "model.safetensors",
|
| 334 |
+
"language_model.model.layers.19.mlp.gate_proj.biases": "model.safetensors",
|
| 335 |
+
"language_model.model.layers.19.mlp.gate_proj.scales": "model.safetensors",
|
| 336 |
+
"language_model.model.layers.19.mlp.gate_proj.weight": "model.safetensors",
|
| 337 |
+
"language_model.model.layers.19.mlp.up_proj.biases": "model.safetensors",
|
| 338 |
+
"language_model.model.layers.19.mlp.up_proj.scales": "model.safetensors",
|
| 339 |
+
"language_model.model.layers.19.mlp.up_proj.weight": "model.safetensors",
|
| 340 |
+
"language_model.model.layers.19.post_attention_layernorm.weight": "model.safetensors",
|
| 341 |
+
"language_model.model.layers.19.self_attn.k_norm.weight": "model.safetensors",
|
| 342 |
+
"language_model.model.layers.19.self_attn.k_proj.biases": "model.safetensors",
|
| 343 |
+
"language_model.model.layers.19.self_attn.k_proj.scales": "model.safetensors",
|
| 344 |
+
"language_model.model.layers.19.self_attn.k_proj.weight": "model.safetensors",
|
| 345 |
+
"language_model.model.layers.19.self_attn.o_proj.biases": "model.safetensors",
|
| 346 |
+
"language_model.model.layers.19.self_attn.o_proj.scales": "model.safetensors",
|
| 347 |
+
"language_model.model.layers.19.self_attn.o_proj.weight": "model.safetensors",
|
| 348 |
+
"language_model.model.layers.19.self_attn.q_norm.weight": "model.safetensors",
|
| 349 |
+
"language_model.model.layers.19.self_attn.q_proj.biases": "model.safetensors",
|
| 350 |
+
"language_model.model.layers.19.self_attn.q_proj.scales": "model.safetensors",
|
| 351 |
+
"language_model.model.layers.19.self_attn.q_proj.weight": "model.safetensors",
|
| 352 |
+
"language_model.model.layers.19.self_attn.v_proj.biases": "model.safetensors",
|
| 353 |
+
"language_model.model.layers.19.self_attn.v_proj.scales": "model.safetensors",
|
| 354 |
+
"language_model.model.layers.19.self_attn.v_proj.weight": "model.safetensors",
|
| 355 |
+
"language_model.model.layers.2.input_layernorm.weight": "model.safetensors",
|
| 356 |
+
"language_model.model.layers.2.linear_attn.A_log": "model.safetensors",
|
| 357 |
+
"language_model.model.layers.2.linear_attn.conv1d.weight": "model.safetensors",
|
| 358 |
+
"language_model.model.layers.2.linear_attn.dt_bias": "model.safetensors",
|
| 359 |
+
"language_model.model.layers.2.linear_attn.in_proj_a.biases": "model.safetensors",
|
| 360 |
+
"language_model.model.layers.2.linear_attn.in_proj_a.scales": "model.safetensors",
|
| 361 |
+
"language_model.model.layers.2.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 362 |
+
"language_model.model.layers.2.linear_attn.in_proj_b.biases": "model.safetensors",
|
| 363 |
+
"language_model.model.layers.2.linear_attn.in_proj_b.scales": "model.safetensors",
|
| 364 |
+
"language_model.model.layers.2.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 365 |
+
"language_model.model.layers.2.linear_attn.in_proj_qkv.biases": "model.safetensors",
|
| 366 |
+
"language_model.model.layers.2.linear_attn.in_proj_qkv.scales": "model.safetensors",
|
| 367 |
+
"language_model.model.layers.2.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 368 |
+
"language_model.model.layers.2.linear_attn.in_proj_z.biases": "model.safetensors",
|
| 369 |
+
"language_model.model.layers.2.linear_attn.in_proj_z.scales": "model.safetensors",
|
| 370 |
+
"language_model.model.layers.2.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 371 |
+
"language_model.model.layers.2.linear_attn.norm.weight": "model.safetensors",
|
| 372 |
+
"language_model.model.layers.2.linear_attn.out_proj.biases": "model.safetensors",
|
| 373 |
+
"language_model.model.layers.2.linear_attn.out_proj.scales": "model.safetensors",
|
| 374 |
+
"language_model.model.layers.2.linear_attn.out_proj.weight": "model.safetensors",
|
| 375 |
+
"language_model.model.layers.2.mlp.down_proj.biases": "model.safetensors",
|
| 376 |
+
"language_model.model.layers.2.mlp.down_proj.scales": "model.safetensors",
|
| 377 |
+
"language_model.model.layers.2.mlp.down_proj.weight": "model.safetensors",
|
| 378 |
+
"language_model.model.layers.2.mlp.gate_proj.biases": "model.safetensors",
|
| 379 |
+
"language_model.model.layers.2.mlp.gate_proj.scales": "model.safetensors",
|
| 380 |
+
"language_model.model.layers.2.mlp.gate_proj.weight": "model.safetensors",
|
| 381 |
+
"language_model.model.layers.2.mlp.up_proj.biases": "model.safetensors",
|
| 382 |
+
"language_model.model.layers.2.mlp.up_proj.scales": "model.safetensors",
|
| 383 |
+
"language_model.model.layers.2.mlp.up_proj.weight": "model.safetensors",
|
| 384 |
+
"language_model.model.layers.2.post_attention_layernorm.weight": "model.safetensors",
|
| 385 |
+
"language_model.model.layers.20.input_layernorm.weight": "model.safetensors",
|
| 386 |
+
"language_model.model.layers.20.linear_attn.A_log": "model.safetensors",
|
| 387 |
+
"language_model.model.layers.20.linear_attn.conv1d.weight": "model.safetensors",
|
| 388 |
+
"language_model.model.layers.20.linear_attn.dt_bias": "model.safetensors",
|
| 389 |
+
"language_model.model.layers.20.linear_attn.in_proj_a.biases": "model.safetensors",
|
| 390 |
+
"language_model.model.layers.20.linear_attn.in_proj_a.scales": "model.safetensors",
|
| 391 |
+
"language_model.model.layers.20.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 392 |
+
"language_model.model.layers.20.linear_attn.in_proj_b.biases": "model.safetensors",
|
| 393 |
+
"language_model.model.layers.20.linear_attn.in_proj_b.scales": "model.safetensors",
|
| 394 |
+
"language_model.model.layers.20.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 395 |
+
"language_model.model.layers.20.linear_attn.in_proj_qkv.biases": "model.safetensors",
|
| 396 |
+
"language_model.model.layers.20.linear_attn.in_proj_qkv.scales": "model.safetensors",
|
| 397 |
+
"language_model.model.layers.20.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 398 |
+
"language_model.model.layers.20.linear_attn.in_proj_z.biases": "model.safetensors",
|
| 399 |
+
"language_model.model.layers.20.linear_attn.in_proj_z.scales": "model.safetensors",
|
| 400 |
+
"language_model.model.layers.20.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 401 |
+
"language_model.model.layers.20.linear_attn.norm.weight": "model.safetensors",
|
| 402 |
+
"language_model.model.layers.20.linear_attn.out_proj.biases": "model.safetensors",
|
| 403 |
+
"language_model.model.layers.20.linear_attn.out_proj.scales": "model.safetensors",
|
| 404 |
+
"language_model.model.layers.20.linear_attn.out_proj.weight": "model.safetensors",
|
| 405 |
+
"language_model.model.layers.20.mlp.down_proj.biases": "model.safetensors",
|
| 406 |
+
"language_model.model.layers.20.mlp.down_proj.scales": "model.safetensors",
|
| 407 |
+
"language_model.model.layers.20.mlp.down_proj.weight": "model.safetensors",
|
| 408 |
+
"language_model.model.layers.20.mlp.gate_proj.biases": "model.safetensors",
|
| 409 |
+
"language_model.model.layers.20.mlp.gate_proj.scales": "model.safetensors",
|
| 410 |
+
"language_model.model.layers.20.mlp.gate_proj.weight": "model.safetensors",
|
| 411 |
+
"language_model.model.layers.20.mlp.up_proj.biases": "model.safetensors",
|
| 412 |
+
"language_model.model.layers.20.mlp.up_proj.scales": "model.safetensors",
|
| 413 |
+
"language_model.model.layers.20.mlp.up_proj.weight": "model.safetensors",
|
| 414 |
+
"language_model.model.layers.20.post_attention_layernorm.weight": "model.safetensors",
|
| 415 |
+
"language_model.model.layers.21.input_layernorm.weight": "model.safetensors",
|
| 416 |
+
"language_model.model.layers.21.linear_attn.A_log": "model.safetensors",
|
| 417 |
+
"language_model.model.layers.21.linear_attn.conv1d.weight": "model.safetensors",
|
| 418 |
+
"language_model.model.layers.21.linear_attn.dt_bias": "model.safetensors",
|
| 419 |
+
"language_model.model.layers.21.linear_attn.in_proj_a.biases": "model.safetensors",
|
| 420 |
+
"language_model.model.layers.21.linear_attn.in_proj_a.scales": "model.safetensors",
|
| 421 |
+
"language_model.model.layers.21.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 422 |
+
"language_model.model.layers.21.linear_attn.in_proj_b.biases": "model.safetensors",
|
| 423 |
+
"language_model.model.layers.21.linear_attn.in_proj_b.scales": "model.safetensors",
|
| 424 |
+
"language_model.model.layers.21.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 425 |
+
"language_model.model.layers.21.linear_attn.in_proj_qkv.biases": "model.safetensors",
|
| 426 |
+
"language_model.model.layers.21.linear_attn.in_proj_qkv.scales": "model.safetensors",
|
| 427 |
+
"language_model.model.layers.21.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 428 |
+
"language_model.model.layers.21.linear_attn.in_proj_z.biases": "model.safetensors",
|
| 429 |
+
"language_model.model.layers.21.linear_attn.in_proj_z.scales": "model.safetensors",
|
| 430 |
+
"language_model.model.layers.21.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 431 |
+
"language_model.model.layers.21.linear_attn.norm.weight": "model.safetensors",
|
| 432 |
+
"language_model.model.layers.21.linear_attn.out_proj.biases": "model.safetensors",
|
| 433 |
+
"language_model.model.layers.21.linear_attn.out_proj.scales": "model.safetensors",
|
| 434 |
+
"language_model.model.layers.21.linear_attn.out_proj.weight": "model.safetensors",
|
| 435 |
+
"language_model.model.layers.21.mlp.down_proj.biases": "model.safetensors",
|
| 436 |
+
"language_model.model.layers.21.mlp.down_proj.scales": "model.safetensors",
|
| 437 |
+
"language_model.model.layers.21.mlp.down_proj.weight": "model.safetensors",
|
| 438 |
+
"language_model.model.layers.21.mlp.gate_proj.biases": "model.safetensors",
|
| 439 |
+
"language_model.model.layers.21.mlp.gate_proj.scales": "model.safetensors",
|
| 440 |
+
"language_model.model.layers.21.mlp.gate_proj.weight": "model.safetensors",
|
| 441 |
+
"language_model.model.layers.21.mlp.up_proj.biases": "model.safetensors",
|
| 442 |
+
"language_model.model.layers.21.mlp.up_proj.scales": "model.safetensors",
|
| 443 |
+
"language_model.model.layers.21.mlp.up_proj.weight": "model.safetensors",
|
| 444 |
+
"language_model.model.layers.21.post_attention_layernorm.weight": "model.safetensors",
|
| 445 |
+
"language_model.model.layers.22.input_layernorm.weight": "model.safetensors",
|
| 446 |
+
"language_model.model.layers.22.linear_attn.A_log": "model.safetensors",
|
| 447 |
+
"language_model.model.layers.22.linear_attn.conv1d.weight": "model.safetensors",
|
| 448 |
+
"language_model.model.layers.22.linear_attn.dt_bias": "model.safetensors",
|
| 449 |
+
"language_model.model.layers.22.linear_attn.in_proj_a.biases": "model.safetensors",
|
| 450 |
+
"language_model.model.layers.22.linear_attn.in_proj_a.scales": "model.safetensors",
|
| 451 |
+
"language_model.model.layers.22.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 452 |
+
"language_model.model.layers.22.linear_attn.in_proj_b.biases": "model.safetensors",
|
| 453 |
+
"language_model.model.layers.22.linear_attn.in_proj_b.scales": "model.safetensors",
|
| 454 |
+
"language_model.model.layers.22.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 455 |
+
"language_model.model.layers.22.linear_attn.in_proj_qkv.biases": "model.safetensors",
|
| 456 |
+
"language_model.model.layers.22.linear_attn.in_proj_qkv.scales": "model.safetensors",
|
| 457 |
+
"language_model.model.layers.22.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 458 |
+
"language_model.model.layers.22.linear_attn.in_proj_z.biases": "model.safetensors",
|
| 459 |
+
"language_model.model.layers.22.linear_attn.in_proj_z.scales": "model.safetensors",
|
| 460 |
+
"language_model.model.layers.22.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 461 |
+
"language_model.model.layers.22.linear_attn.norm.weight": "model.safetensors",
|
| 462 |
+
"language_model.model.layers.22.linear_attn.out_proj.biases": "model.safetensors",
|
| 463 |
+
"language_model.model.layers.22.linear_attn.out_proj.scales": "model.safetensors",
|
| 464 |
+
"language_model.model.layers.22.linear_attn.out_proj.weight": "model.safetensors",
|
| 465 |
+
"language_model.model.layers.22.mlp.down_proj.biases": "model.safetensors",
|
| 466 |
+
"language_model.model.layers.22.mlp.down_proj.scales": "model.safetensors",
|
| 467 |
+
"language_model.model.layers.22.mlp.down_proj.weight": "model.safetensors",
|
| 468 |
+
"language_model.model.layers.22.mlp.gate_proj.biases": "model.safetensors",
|
| 469 |
+
"language_model.model.layers.22.mlp.gate_proj.scales": "model.safetensors",
|
| 470 |
+
"language_model.model.layers.22.mlp.gate_proj.weight": "model.safetensors",
|
| 471 |
+
"language_model.model.layers.22.mlp.up_proj.biases": "model.safetensors",
|
| 472 |
+
"language_model.model.layers.22.mlp.up_proj.scales": "model.safetensors",
|
| 473 |
+
"language_model.model.layers.22.mlp.up_proj.weight": "model.safetensors",
|
| 474 |
+
"language_model.model.layers.22.post_attention_layernorm.weight": "model.safetensors",
|
| 475 |
+
"language_model.model.layers.23.input_layernorm.weight": "model.safetensors",
|
| 476 |
+
"language_model.model.layers.23.mlp.down_proj.biases": "model.safetensors",
|
| 477 |
+
"language_model.model.layers.23.mlp.down_proj.scales": "model.safetensors",
|
| 478 |
+
"language_model.model.layers.23.mlp.down_proj.weight": "model.safetensors",
|
| 479 |
+
"language_model.model.layers.23.mlp.gate_proj.biases": "model.safetensors",
|
| 480 |
+
"language_model.model.layers.23.mlp.gate_proj.scales": "model.safetensors",
|
| 481 |
+
"language_model.model.layers.23.mlp.gate_proj.weight": "model.safetensors",
|
| 482 |
+
"language_model.model.layers.23.mlp.up_proj.biases": "model.safetensors",
|
| 483 |
+
"language_model.model.layers.23.mlp.up_proj.scales": "model.safetensors",
|
| 484 |
+
"language_model.model.layers.23.mlp.up_proj.weight": "model.safetensors",
|
| 485 |
+
"language_model.model.layers.23.post_attention_layernorm.weight": "model.safetensors",
|
| 486 |
+
"language_model.model.layers.23.self_attn.k_norm.weight": "model.safetensors",
|
| 487 |
+
"language_model.model.layers.23.self_attn.k_proj.biases": "model.safetensors",
|
| 488 |
+
"language_model.model.layers.23.self_attn.k_proj.scales": "model.safetensors",
|
| 489 |
+
"language_model.model.layers.23.self_attn.k_proj.weight": "model.safetensors",
|
| 490 |
+
"language_model.model.layers.23.self_attn.o_proj.biases": "model.safetensors",
|
| 491 |
+
"language_model.model.layers.23.self_attn.o_proj.scales": "model.safetensors",
|
| 492 |
+
"language_model.model.layers.23.self_attn.o_proj.weight": "model.safetensors",
|
| 493 |
+
"language_model.model.layers.23.self_attn.q_norm.weight": "model.safetensors",
|
| 494 |
+
"language_model.model.layers.23.self_attn.q_proj.biases": "model.safetensors",
|
| 495 |
+
"language_model.model.layers.23.self_attn.q_proj.scales": "model.safetensors",
|
| 496 |
+
"language_model.model.layers.23.self_attn.q_proj.weight": "model.safetensors",
|
| 497 |
+
"language_model.model.layers.23.self_attn.v_proj.biases": "model.safetensors",
|
| 498 |
+
"language_model.model.layers.23.self_attn.v_proj.scales": "model.safetensors",
|
| 499 |
+
"language_model.model.layers.23.self_attn.v_proj.weight": "model.safetensors",
|
| 500 |
+
"language_model.model.layers.3.input_layernorm.weight": "model.safetensors",
|
| 501 |
+
"language_model.model.layers.3.mlp.down_proj.biases": "model.safetensors",
|
| 502 |
+
"language_model.model.layers.3.mlp.down_proj.scales": "model.safetensors",
|
| 503 |
+
"language_model.model.layers.3.mlp.down_proj.weight": "model.safetensors",
|
| 504 |
+
"language_model.model.layers.3.mlp.gate_proj.biases": "model.safetensors",
|
| 505 |
+
"language_model.model.layers.3.mlp.gate_proj.scales": "model.safetensors",
|
| 506 |
+
"language_model.model.layers.3.mlp.gate_proj.weight": "model.safetensors",
|
| 507 |
+
"language_model.model.layers.3.mlp.up_proj.biases": "model.safetensors",
|
| 508 |
+
"language_model.model.layers.3.mlp.up_proj.scales": "model.safetensors",
|
| 509 |
+
"language_model.model.layers.3.mlp.up_proj.weight": "model.safetensors",
|
| 510 |
+
"language_model.model.layers.3.post_attention_layernorm.weight": "model.safetensors",
|
| 511 |
+
"language_model.model.layers.3.self_attn.k_norm.weight": "model.safetensors",
|
| 512 |
+
"language_model.model.layers.3.self_attn.k_proj.biases": "model.safetensors",
|
| 513 |
+
"language_model.model.layers.3.self_attn.k_proj.scales": "model.safetensors",
|
| 514 |
+
"language_model.model.layers.3.self_attn.k_proj.weight": "model.safetensors",
|
| 515 |
+
"language_model.model.layers.3.self_attn.o_proj.biases": "model.safetensors",
|
| 516 |
+
"language_model.model.layers.3.self_attn.o_proj.scales": "model.safetensors",
|
| 517 |
+
"language_model.model.layers.3.self_attn.o_proj.weight": "model.safetensors",
|
| 518 |
+
"language_model.model.layers.3.self_attn.q_norm.weight": "model.safetensors",
|
| 519 |
+
"language_model.model.layers.3.self_attn.q_proj.biases": "model.safetensors",
|
| 520 |
+
"language_model.model.layers.3.self_attn.q_proj.scales": "model.safetensors",
|
| 521 |
+
"language_model.model.layers.3.self_attn.q_proj.weight": "model.safetensors",
|
| 522 |
+
"language_model.model.layers.3.self_attn.v_proj.biases": "model.safetensors",
|
| 523 |
+
"language_model.model.layers.3.self_attn.v_proj.scales": "model.safetensors",
|
| 524 |
+
"language_model.model.layers.3.self_attn.v_proj.weight": "model.safetensors",
|
| 525 |
+
"language_model.model.layers.4.input_layernorm.weight": "model.safetensors",
|
| 526 |
+
"language_model.model.layers.4.linear_attn.A_log": "model.safetensors",
|
| 527 |
+
"language_model.model.layers.4.linear_attn.conv1d.weight": "model.safetensors",
|
| 528 |
+
"language_model.model.layers.4.linear_attn.dt_bias": "model.safetensors",
|
| 529 |
+
"language_model.model.layers.4.linear_attn.in_proj_a.biases": "model.safetensors",
|
| 530 |
+
"language_model.model.layers.4.linear_attn.in_proj_a.scales": "model.safetensors",
|
| 531 |
+
"language_model.model.layers.4.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 532 |
+
"language_model.model.layers.4.linear_attn.in_proj_b.biases": "model.safetensors",
|
| 533 |
+
"language_model.model.layers.4.linear_attn.in_proj_b.scales": "model.safetensors",
|
| 534 |
+
"language_model.model.layers.4.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 535 |
+
"language_model.model.layers.4.linear_attn.in_proj_qkv.biases": "model.safetensors",
|
| 536 |
+
"language_model.model.layers.4.linear_attn.in_proj_qkv.scales": "model.safetensors",
|
| 537 |
+
"language_model.model.layers.4.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 538 |
+
"language_model.model.layers.4.linear_attn.in_proj_z.biases": "model.safetensors",
|
| 539 |
+
"language_model.model.layers.4.linear_attn.in_proj_z.scales": "model.safetensors",
|
| 540 |
+
"language_model.model.layers.4.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 541 |
+
"language_model.model.layers.4.linear_attn.norm.weight": "model.safetensors",
|
| 542 |
+
"language_model.model.layers.4.linear_attn.out_proj.biases": "model.safetensors",
|
| 543 |
+
"language_model.model.layers.4.linear_attn.out_proj.scales": "model.safetensors",
|
| 544 |
+
"language_model.model.layers.4.linear_attn.out_proj.weight": "model.safetensors",
|
| 545 |
+
"language_model.model.layers.4.mlp.down_proj.biases": "model.safetensors",
|
| 546 |
+
"language_model.model.layers.4.mlp.down_proj.scales": "model.safetensors",
|
| 547 |
+
"language_model.model.layers.4.mlp.down_proj.weight": "model.safetensors",
|
| 548 |
+
"language_model.model.layers.4.mlp.gate_proj.biases": "model.safetensors",
|
| 549 |
+
"language_model.model.layers.4.mlp.gate_proj.scales": "model.safetensors",
|
| 550 |
+
"language_model.model.layers.4.mlp.gate_proj.weight": "model.safetensors",
|
| 551 |
+
"language_model.model.layers.4.mlp.up_proj.biases": "model.safetensors",
|
| 552 |
+
"language_model.model.layers.4.mlp.up_proj.scales": "model.safetensors",
|
| 553 |
+
"language_model.model.layers.4.mlp.up_proj.weight": "model.safetensors",
|
| 554 |
+
"language_model.model.layers.4.post_attention_layernorm.weight": "model.safetensors",
|
| 555 |
+
"language_model.model.layers.5.input_layernorm.weight": "model.safetensors",
|
| 556 |
+
"language_model.model.layers.5.linear_attn.A_log": "model.safetensors",
|
| 557 |
+
"language_model.model.layers.5.linear_attn.conv1d.weight": "model.safetensors",
|
| 558 |
+
"language_model.model.layers.5.linear_attn.dt_bias": "model.safetensors",
|
| 559 |
+
"language_model.model.layers.5.linear_attn.in_proj_a.biases": "model.safetensors",
|
| 560 |
+
"language_model.model.layers.5.linear_attn.in_proj_a.scales": "model.safetensors",
|
| 561 |
+
"language_model.model.layers.5.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 562 |
+
"language_model.model.layers.5.linear_attn.in_proj_b.biases": "model.safetensors",
|
| 563 |
+
"language_model.model.layers.5.linear_attn.in_proj_b.scales": "model.safetensors",
|
| 564 |
+
"language_model.model.layers.5.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 565 |
+
"language_model.model.layers.5.linear_attn.in_proj_qkv.biases": "model.safetensors",
|
| 566 |
+
"language_model.model.layers.5.linear_attn.in_proj_qkv.scales": "model.safetensors",
|
| 567 |
+
"language_model.model.layers.5.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 568 |
+
"language_model.model.layers.5.linear_attn.in_proj_z.biases": "model.safetensors",
|
| 569 |
+
"language_model.model.layers.5.linear_attn.in_proj_z.scales": "model.safetensors",
|
| 570 |
+
"language_model.model.layers.5.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 571 |
+
"language_model.model.layers.5.linear_attn.norm.weight": "model.safetensors",
|
| 572 |
+
"language_model.model.layers.5.linear_attn.out_proj.biases": "model.safetensors",
|
| 573 |
+
"language_model.model.layers.5.linear_attn.out_proj.scales": "model.safetensors",
|
| 574 |
+
"language_model.model.layers.5.linear_attn.out_proj.weight": "model.safetensors",
|
| 575 |
+
"language_model.model.layers.5.mlp.down_proj.biases": "model.safetensors",
|
| 576 |
+
"language_model.model.layers.5.mlp.down_proj.scales": "model.safetensors",
|
| 577 |
+
"language_model.model.layers.5.mlp.down_proj.weight": "model.safetensors",
|
| 578 |
+
"language_model.model.layers.5.mlp.gate_proj.biases": "model.safetensors",
|
| 579 |
+
"language_model.model.layers.5.mlp.gate_proj.scales": "model.safetensors",
|
| 580 |
+
"language_model.model.layers.5.mlp.gate_proj.weight": "model.safetensors",
|
| 581 |
+
"language_model.model.layers.5.mlp.up_proj.biases": "model.safetensors",
|
| 582 |
+
"language_model.model.layers.5.mlp.up_proj.scales": "model.safetensors",
|
| 583 |
+
"language_model.model.layers.5.mlp.up_proj.weight": "model.safetensors",
|
| 584 |
+
"language_model.model.layers.5.post_attention_layernorm.weight": "model.safetensors",
|
| 585 |
+
"language_model.model.layers.6.input_layernorm.weight": "model.safetensors",
|
| 586 |
+
"language_model.model.layers.6.linear_attn.A_log": "model.safetensors",
|
| 587 |
+
"language_model.model.layers.6.linear_attn.conv1d.weight": "model.safetensors",
|
| 588 |
+
"language_model.model.layers.6.linear_attn.dt_bias": "model.safetensors",
|
| 589 |
+
"language_model.model.layers.6.linear_attn.in_proj_a.biases": "model.safetensors",
|
| 590 |
+
"language_model.model.layers.6.linear_attn.in_proj_a.scales": "model.safetensors",
|
| 591 |
+
"language_model.model.layers.6.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 592 |
+
"language_model.model.layers.6.linear_attn.in_proj_b.biases": "model.safetensors",
|
| 593 |
+
"language_model.model.layers.6.linear_attn.in_proj_b.scales": "model.safetensors",
|
| 594 |
+
"language_model.model.layers.6.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 595 |
+
"language_model.model.layers.6.linear_attn.in_proj_qkv.biases": "model.safetensors",
|
| 596 |
+
"language_model.model.layers.6.linear_attn.in_proj_qkv.scales": "model.safetensors",
|
| 597 |
+
"language_model.model.layers.6.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 598 |
+
"language_model.model.layers.6.linear_attn.in_proj_z.biases": "model.safetensors",
|
| 599 |
+
"language_model.model.layers.6.linear_attn.in_proj_z.scales": "model.safetensors",
|
| 600 |
+
"language_model.model.layers.6.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 601 |
+
"language_model.model.layers.6.linear_attn.norm.weight": "model.safetensors",
|
| 602 |
+
"language_model.model.layers.6.linear_attn.out_proj.biases": "model.safetensors",
|
| 603 |
+
"language_model.model.layers.6.linear_attn.out_proj.scales": "model.safetensors",
|
| 604 |
+
"language_model.model.layers.6.linear_attn.out_proj.weight": "model.safetensors",
|
| 605 |
+
"language_model.model.layers.6.mlp.down_proj.biases": "model.safetensors",
|
| 606 |
+
"language_model.model.layers.6.mlp.down_proj.scales": "model.safetensors",
|
| 607 |
+
"language_model.model.layers.6.mlp.down_proj.weight": "model.safetensors",
|
| 608 |
+
"language_model.model.layers.6.mlp.gate_proj.biases": "model.safetensors",
|
| 609 |
+
"language_model.model.layers.6.mlp.gate_proj.scales": "model.safetensors",
|
| 610 |
+
"language_model.model.layers.6.mlp.gate_proj.weight": "model.safetensors",
|
| 611 |
+
"language_model.model.layers.6.mlp.up_proj.biases": "model.safetensors",
|
| 612 |
+
"language_model.model.layers.6.mlp.up_proj.scales": "model.safetensors",
|
| 613 |
+
"language_model.model.layers.6.mlp.up_proj.weight": "model.safetensors",
|
| 614 |
+
"language_model.model.layers.6.post_attention_layernorm.weight": "model.safetensors",
|
| 615 |
+
"language_model.model.layers.7.input_layernorm.weight": "model.safetensors",
|
| 616 |
+
"language_model.model.layers.7.mlp.down_proj.biases": "model.safetensors",
|
| 617 |
+
"language_model.model.layers.7.mlp.down_proj.scales": "model.safetensors",
|
| 618 |
+
"language_model.model.layers.7.mlp.down_proj.weight": "model.safetensors",
|
| 619 |
+
"language_model.model.layers.7.mlp.gate_proj.biases": "model.safetensors",
|
| 620 |
+
"language_model.model.layers.7.mlp.gate_proj.scales": "model.safetensors",
|
| 621 |
+
"language_model.model.layers.7.mlp.gate_proj.weight": "model.safetensors",
|
| 622 |
+
"language_model.model.layers.7.mlp.up_proj.biases": "model.safetensors",
|
| 623 |
+
"language_model.model.layers.7.mlp.up_proj.scales": "model.safetensors",
|
| 624 |
+
"language_model.model.layers.7.mlp.up_proj.weight": "model.safetensors",
|
| 625 |
+
"language_model.model.layers.7.post_attention_layernorm.weight": "model.safetensors",
|
| 626 |
+
"language_model.model.layers.7.self_attn.k_norm.weight": "model.safetensors",
|
| 627 |
+
"language_model.model.layers.7.self_attn.k_proj.biases": "model.safetensors",
|
| 628 |
+
"language_model.model.layers.7.self_attn.k_proj.scales": "model.safetensors",
|
| 629 |
+
"language_model.model.layers.7.self_attn.k_proj.weight": "model.safetensors",
|
| 630 |
+
"language_model.model.layers.7.self_attn.o_proj.biases": "model.safetensors",
|
| 631 |
+
"language_model.model.layers.7.self_attn.o_proj.scales": "model.safetensors",
|
| 632 |
+
"language_model.model.layers.7.self_attn.o_proj.weight": "model.safetensors",
|
| 633 |
+
"language_model.model.layers.7.self_attn.q_norm.weight": "model.safetensors",
|
| 634 |
+
"language_model.model.layers.7.self_attn.q_proj.biases": "model.safetensors",
|
| 635 |
+
"language_model.model.layers.7.self_attn.q_proj.scales": "model.safetensors",
|
| 636 |
+
"language_model.model.layers.7.self_attn.q_proj.weight": "model.safetensors",
|
| 637 |
+
"language_model.model.layers.7.self_attn.v_proj.biases": "model.safetensors",
|
| 638 |
+
"language_model.model.layers.7.self_attn.v_proj.scales": "model.safetensors",
|
| 639 |
+
"language_model.model.layers.7.self_attn.v_proj.weight": "model.safetensors",
|
| 640 |
+
"language_model.model.layers.8.input_layernorm.weight": "model.safetensors",
|
| 641 |
+
"language_model.model.layers.8.linear_attn.A_log": "model.safetensors",
|
| 642 |
+
"language_model.model.layers.8.linear_attn.conv1d.weight": "model.safetensors",
|
| 643 |
+
"language_model.model.layers.8.linear_attn.dt_bias": "model.safetensors",
|
| 644 |
+
"language_model.model.layers.8.linear_attn.in_proj_a.biases": "model.safetensors",
|
| 645 |
+
"language_model.model.layers.8.linear_attn.in_proj_a.scales": "model.safetensors",
|
| 646 |
+
"language_model.model.layers.8.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 647 |
+
"language_model.model.layers.8.linear_attn.in_proj_b.biases": "model.safetensors",
|
| 648 |
+
"language_model.model.layers.8.linear_attn.in_proj_b.scales": "model.safetensors",
|
| 649 |
+
"language_model.model.layers.8.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 650 |
+
"language_model.model.layers.8.linear_attn.in_proj_qkv.biases": "model.safetensors",
|
| 651 |
+
"language_model.model.layers.8.linear_attn.in_proj_qkv.scales": "model.safetensors",
|
| 652 |
+
"language_model.model.layers.8.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 653 |
+
"language_model.model.layers.8.linear_attn.in_proj_z.biases": "model.safetensors",
|
| 654 |
+
"language_model.model.layers.8.linear_attn.in_proj_z.scales": "model.safetensors",
|
| 655 |
+
"language_model.model.layers.8.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 656 |
+
"language_model.model.layers.8.linear_attn.norm.weight": "model.safetensors",
|
| 657 |
+
"language_model.model.layers.8.linear_attn.out_proj.biases": "model.safetensors",
|
| 658 |
+
"language_model.model.layers.8.linear_attn.out_proj.scales": "model.safetensors",
|
| 659 |
+
"language_model.model.layers.8.linear_attn.out_proj.weight": "model.safetensors",
|
| 660 |
+
"language_model.model.layers.8.mlp.down_proj.biases": "model.safetensors",
|
| 661 |
+
"language_model.model.layers.8.mlp.down_proj.scales": "model.safetensors",
|
| 662 |
+
"language_model.model.layers.8.mlp.down_proj.weight": "model.safetensors",
|
| 663 |
+
"language_model.model.layers.8.mlp.gate_proj.biases": "model.safetensors",
|
| 664 |
+
"language_model.model.layers.8.mlp.gate_proj.scales": "model.safetensors",
|
| 665 |
+
"language_model.model.layers.8.mlp.gate_proj.weight": "model.safetensors",
|
| 666 |
+
"language_model.model.layers.8.mlp.up_proj.biases": "model.safetensors",
|
| 667 |
+
"language_model.model.layers.8.mlp.up_proj.scales": "model.safetensors",
|
| 668 |
+
"language_model.model.layers.8.mlp.up_proj.weight": "model.safetensors",
|
| 669 |
+
"language_model.model.layers.8.post_attention_layernorm.weight": "model.safetensors",
|
| 670 |
+
"language_model.model.layers.9.input_layernorm.weight": "model.safetensors",
|
| 671 |
+
"language_model.model.layers.9.linear_attn.A_log": "model.safetensors",
|
| 672 |
+
"language_model.model.layers.9.linear_attn.conv1d.weight": "model.safetensors",
|
| 673 |
+
"language_model.model.layers.9.linear_attn.dt_bias": "model.safetensors",
|
| 674 |
+
"language_model.model.layers.9.linear_attn.in_proj_a.biases": "model.safetensors",
|
| 675 |
+
"language_model.model.layers.9.linear_attn.in_proj_a.scales": "model.safetensors",
|
| 676 |
+
"language_model.model.layers.9.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 677 |
+
"language_model.model.layers.9.linear_attn.in_proj_b.biases": "model.safetensors",
|
| 678 |
+
"language_model.model.layers.9.linear_attn.in_proj_b.scales": "model.safetensors",
|
| 679 |
+
"language_model.model.layers.9.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 680 |
+
"language_model.model.layers.9.linear_attn.in_proj_qkv.biases": "model.safetensors",
|
| 681 |
+
"language_model.model.layers.9.linear_attn.in_proj_qkv.scales": "model.safetensors",
|
| 682 |
+
"language_model.model.layers.9.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 683 |
+
"language_model.model.layers.9.linear_attn.in_proj_z.biases": "model.safetensors",
|
| 684 |
+
"language_model.model.layers.9.linear_attn.in_proj_z.scales": "model.safetensors",
|
| 685 |
+
"language_model.model.layers.9.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 686 |
+
"language_model.model.layers.9.linear_attn.norm.weight": "model.safetensors",
|
| 687 |
+
"language_model.model.layers.9.linear_attn.out_proj.biases": "model.safetensors",
|
| 688 |
+
"language_model.model.layers.9.linear_attn.out_proj.scales": "model.safetensors",
|
| 689 |
+
"language_model.model.layers.9.linear_attn.out_proj.weight": "model.safetensors",
|
| 690 |
+
"language_model.model.layers.9.mlp.down_proj.biases": "model.safetensors",
|
| 691 |
+
"language_model.model.layers.9.mlp.down_proj.scales": "model.safetensors",
|
| 692 |
+
"language_model.model.layers.9.mlp.down_proj.weight": "model.safetensors",
|
| 693 |
+
"language_model.model.layers.9.mlp.gate_proj.biases": "model.safetensors",
|
| 694 |
+
"language_model.model.layers.9.mlp.gate_proj.scales": "model.safetensors",
|
| 695 |
+
"language_model.model.layers.9.mlp.gate_proj.weight": "model.safetensors",
|
| 696 |
+
"language_model.model.layers.9.mlp.up_proj.biases": "model.safetensors",
|
| 697 |
+
"language_model.model.layers.9.mlp.up_proj.scales": "model.safetensors",
|
| 698 |
+
"language_model.model.layers.9.mlp.up_proj.weight": "model.safetensors",
|
| 699 |
+
"language_model.model.layers.9.post_attention_layernorm.weight": "model.safetensors",
|
| 700 |
+
"language_model.model.norm.weight": "model.safetensors"
|
| 701 |
+
}
|
| 702 |
+
}
|
8bit/tokenizer.json
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:06b9509352d2af50381ab2247e083b80d32d5c0aba91c272ca9ff729b6a0e523
|
| 3 |
+
size 19989325
|
8bit/tokenizer_config.json
ADDED
|
@@ -0,0 +1,33 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"add_prefix_space": false,
|
| 3 |
+
"audio_bos_token": "<|audio_start|>",
|
| 4 |
+
"audio_eos_token": "<|audio_end|>",
|
| 5 |
+
"audio_token": "<|audio_pad|>",
|
| 6 |
+
"backend": "tokenizers",
|
| 7 |
+
"bos_token": null,
|
| 8 |
+
"clean_up_tokenization_spaces": false,
|
| 9 |
+
"eos_token": "<|im_end|>",
|
| 10 |
+
"errors": "replace",
|
| 11 |
+
"image_token": "<|image_pad|>",
|
| 12 |
+
"is_local": true,
|
| 13 |
+
"local_files_only": false,
|
| 14 |
+
"model_max_length": 262144,
|
| 15 |
+
"model_specific_special_tokens": {
|
| 16 |
+
"audio_bos_token": "<|audio_start|>",
|
| 17 |
+
"audio_eos_token": "<|audio_end|>",
|
| 18 |
+
"audio_token": "<|audio_pad|>",
|
| 19 |
+
"image_token": "<|image_pad|>",
|
| 20 |
+
"video_token": "<|video_pad|>",
|
| 21 |
+
"vision_bos_token": "<|vision_start|>",
|
| 22 |
+
"vision_eos_token": "<|vision_end|>"
|
| 23 |
+
},
|
| 24 |
+
"pad_token": "<|endoftext|>",
|
| 25 |
+
"pretokenize_regex": "(?i:'s|'t|'re|'ve|'m|'ll|'d)|[^\\r\\n\\p{L}\\p{N}]?[\\p{L}\\p{M}]+|\\p{N}| ?[^\\s\\p{L}\\p{M}\\p{N}]+[\\r\\n]*|\\s*[\\r\\n]+|\\s+(?!\\S)|\\s+",
|
| 26 |
+
"split_special_tokens": false,
|
| 27 |
+
"tokenizer_class": "Qwen2Tokenizer",
|
| 28 |
+
"tool_parser_type": "qwen3_coder",
|
| 29 |
+
"unk_token": null,
|
| 30 |
+
"video_token": "<|video_pad|>",
|
| 31 |
+
"vision_bos_token": "<|vision_start|>",
|
| 32 |
+
"vision_eos_token": "<|vision_end|>"
|
| 33 |
+
}
|
LICENSE
ADDED
|
@@ -0,0 +1,202 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
|
| 2 |
+
Apache License
|
| 3 |
+
Version 2.0, January 2004
|
| 4 |
+
http://www.apache.org/licenses/
|
| 5 |
+
|
| 6 |
+
TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
|
| 7 |
+
|
| 8 |
+
1. Definitions.
|
| 9 |
+
|
| 10 |
+
"License" shall mean the terms and conditions for use, reproduction,
|
| 11 |
+
and distribution as defined by Sections 1 through 9 of this document.
|
| 12 |
+
|
| 13 |
+
"Licensor" shall mean the copyright owner or entity authorized by
|
| 14 |
+
the copyright owner that is granting the License.
|
| 15 |
+
|
| 16 |
+
"Legal Entity" shall mean the union of the acting entity and all
|
| 17 |
+
other entities that control, are controlled by, or are under common
|
| 18 |
+
control with that entity. For the purposes of this definition,
|
| 19 |
+
"control" means (i) the power, direct or indirect, to cause the
|
| 20 |
+
direction or management of such entity, whether by contract or
|
| 21 |
+
otherwise, or (ii) ownership of fifty percent (50%) or more of the
|
| 22 |
+
outstanding shares, or (iii) beneficial ownership of such entity.
|
| 23 |
+
|
| 24 |
+
"You" (or "Your") shall mean an individual or Legal Entity
|
| 25 |
+
exercising permissions granted by this License.
|
| 26 |
+
|
| 27 |
+
"Source" form shall mean the preferred form for making modifications,
|
| 28 |
+
including but not limited to software source code, documentation
|
| 29 |
+
source, and configuration files.
|
| 30 |
+
|
| 31 |
+
"Object" form shall mean any form resulting from mechanical
|
| 32 |
+
transformation or translation of a Source form, including but
|
| 33 |
+
not limited to compiled object code, generated documentation,
|
| 34 |
+
and conversions to other media types.
|
| 35 |
+
|
| 36 |
+
"Work" shall mean the work of authorship, whether in Source or
|
| 37 |
+
Object form, made available under the License, as indicated by a
|
| 38 |
+
copyright notice that is included in or attached to the work
|
| 39 |
+
(an example is provided in the Appendix below).
|
| 40 |
+
|
| 41 |
+
"Derivative Works" shall mean any work, whether in Source or Object
|
| 42 |
+
form, that is based on (or derived from) the Work and for which the
|
| 43 |
+
editorial revisions, annotations, elaborations, or other modifications
|
| 44 |
+
represent, as a whole, an original work of authorship. For the purposes
|
| 45 |
+
of this License, Derivative Works shall not include works that remain
|
| 46 |
+
separable from, or merely link (or bind by name) to the interfaces of,
|
| 47 |
+
the Work and Derivative Works thereof.
|
| 48 |
+
|
| 49 |
+
"Contribution" shall mean any work of authorship, including
|
| 50 |
+
the original version of the Work and any modifications or additions
|
| 51 |
+
to that Work or Derivative Works thereof, that is intentionally
|
| 52 |
+
submitted to Licensor for inclusion in the Work by the copyright owner
|
| 53 |
+
or by an individual or Legal Entity authorized to submit on behalf of
|
| 54 |
+
the copyright owner. For the purposes of this definition, "submitted"
|
| 55 |
+
means any form of electronic, verbal, or written communication sent
|
| 56 |
+
to the Licensor or its representatives, including but not limited to
|
| 57 |
+
communication on electronic mailing lists, source code control systems,
|
| 58 |
+
and issue tracking systems that are managed by, or on behalf of, the
|
| 59 |
+
Licensor for the purpose of discussing and improving the Work, but
|
| 60 |
+
excluding communication that is conspicuously marked or otherwise
|
| 61 |
+
designated in writing by the copyright owner as "Not a Contribution."
|
| 62 |
+
|
| 63 |
+
"Contributor" shall mean Licensor and any individual or Legal Entity
|
| 64 |
+
on behalf of whom a Contribution has been received by Licensor and
|
| 65 |
+
subsequently incorporated within the Work.
|
| 66 |
+
|
| 67 |
+
2. Grant of Copyright License. Subject to the terms and conditions of
|
| 68 |
+
this License, each Contributor hereby grants to You a perpetual,
|
| 69 |
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
| 70 |
+
copyright license to reproduce, prepare Derivative Works of,
|
| 71 |
+
publicly display, publicly perform, sublicense, and distribute the
|
| 72 |
+
Work and such Derivative Works in Source or Object form.
|
| 73 |
+
|
| 74 |
+
3. Grant of Patent License. Subject to the terms and conditions of
|
| 75 |
+
this License, each Contributor hereby grants to You a perpetual,
|
| 76 |
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
| 77 |
+
(except as stated in this section) patent license to make, have made,
|
| 78 |
+
use, offer to sell, sell, import, and otherwise transfer the Work,
|
| 79 |
+
where such license applies only to those patent claims licensable
|
| 80 |
+
by such Contributor that are necessarily infringed by their
|
| 81 |
+
Contribution(s) alone or by combination of their Contribution(s)
|
| 82 |
+
with the Work to which such Contribution(s) was submitted. If You
|
| 83 |
+
institute patent litigation against any entity (including a
|
| 84 |
+
cross-claim or counterclaim in a lawsuit) alleging that the Work
|
| 85 |
+
or a Contribution incorporated within the Work constitutes direct
|
| 86 |
+
or contributory patent infringement, then any patent licenses
|
| 87 |
+
granted to You under this License for that Work shall terminate
|
| 88 |
+
as of the date such litigation is filed.
|
| 89 |
+
|
| 90 |
+
4. Redistribution. You may reproduce and distribute copies of the
|
| 91 |
+
Work or Derivative Works thereof in any medium, with or without
|
| 92 |
+
modifications, and in Source or Object form, provided that You
|
| 93 |
+
meet the following conditions:
|
| 94 |
+
|
| 95 |
+
(a) You must give any other recipients of the Work or
|
| 96 |
+
Derivative Works a copy of this License; and
|
| 97 |
+
|
| 98 |
+
(b) You must cause any modified files to carry prominent notices
|
| 99 |
+
stating that You changed the files; and
|
| 100 |
+
|
| 101 |
+
(c) You must retain, in the Source form of any Derivative Works
|
| 102 |
+
that You distribute, all copyright, patent, trademark, and
|
| 103 |
+
attribution notices from the Source form of the Work,
|
| 104 |
+
excluding those notices that do not pertain to any part of
|
| 105 |
+
the Derivative Works; and
|
| 106 |
+
|
| 107 |
+
(d) If the Work includes a "NOTICE" text file as part of its
|
| 108 |
+
distribution, then any Derivative Works that You distribute must
|
| 109 |
+
include a readable copy of the attribution notices contained
|
| 110 |
+
within such NOTICE file, excluding those notices that do not
|
| 111 |
+
pertain to any part of the Derivative Works, in at least one
|
| 112 |
+
of the following places: within a NOTICE text file distributed
|
| 113 |
+
as part of the Derivative Works; within the Source form or
|
| 114 |
+
documentation, if provided along with the Derivative Works; or,
|
| 115 |
+
within a display generated by the Derivative Works, if and
|
| 116 |
+
wherever such third-party notices normally appear. The contents
|
| 117 |
+
of the NOTICE file are for informational purposes only and
|
| 118 |
+
do not modify the License. You may add Your own attribution
|
| 119 |
+
notices within Derivative Works that You distribute, alongside
|
| 120 |
+
or as an addendum to the NOTICE text from the Work, provided
|
| 121 |
+
that such additional attribution notices cannot be construed
|
| 122 |
+
as modifying the License.
|
| 123 |
+
|
| 124 |
+
You may add Your own copyright statement to Your modifications and
|
| 125 |
+
may provide additional or different license terms and conditions
|
| 126 |
+
for use, reproduction, or distribution of Your modifications, or
|
| 127 |
+
for any such Derivative Works as a whole, provided Your use,
|
| 128 |
+
reproduction, and distribution of the Work otherwise complies with
|
| 129 |
+
the conditions stated in this License.
|
| 130 |
+
|
| 131 |
+
5. Submission of Contributions. Unless You explicitly state otherwise,
|
| 132 |
+
any Contribution intentionally submitted for inclusion in the Work
|
| 133 |
+
by You to the Licensor shall be under the terms and conditions of
|
| 134 |
+
this License, without any additional terms or conditions.
|
| 135 |
+
Notwithstanding the above, nothing herein shall supersede or modify
|
| 136 |
+
the terms of any separate license agreement you may have executed
|
| 137 |
+
with Licensor regarding such Contributions.
|
| 138 |
+
|
| 139 |
+
6. Trademarks. This License does not grant permission to use the trade
|
| 140 |
+
names, trademarks, service marks, or product names of the Licensor,
|
| 141 |
+
except as required for reasonable and customary use in describing the
|
| 142 |
+
origin of the Work and reproducing the content of the NOTICE file.
|
| 143 |
+
|
| 144 |
+
7. Disclaimer of Warranty. Unless required by applicable law or
|
| 145 |
+
agreed to in writing, Licensor provides the Work (and each
|
| 146 |
+
Contributor provides its Contributions) on an "AS IS" BASIS,
|
| 147 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
|
| 148 |
+
implied, including, without limitation, any warranties or conditions
|
| 149 |
+
of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
|
| 150 |
+
PARTICULAR PURPOSE. You are solely responsible for determining the
|
| 151 |
+
appropriateness of using or redistributing the Work and assume any
|
| 152 |
+
risks associated with Your exercise of permissions under this License.
|
| 153 |
+
|
| 154 |
+
8. Limitation of Liability. In no event and under no legal theory,
|
| 155 |
+
whether in tort (including negligence), contract, or otherwise,
|
| 156 |
+
unless required by applicable law (such as deliberate and grossly
|
| 157 |
+
negligent acts) or agreed to in writing, shall any Contributor be
|
| 158 |
+
liable to You for damages, including any direct, indirect, special,
|
| 159 |
+
incidental, or consequential damages of any character arising as a
|
| 160 |
+
result of this License or out of the use or inability to use the
|
| 161 |
+
Work (including but not limited to damages for loss of goodwill,
|
| 162 |
+
work stoppage, computer failure or malfunction, or any and all
|
| 163 |
+
other commercial damages or losses), even if such Contributor
|
| 164 |
+
has been advised of the possibility of such damages.
|
| 165 |
+
|
| 166 |
+
9. Accepting Warranty or Additional Liability. While redistributing
|
| 167 |
+
the Work or Derivative Works thereof, You may choose to offer,
|
| 168 |
+
and charge a fee for, acceptance of support, warranty, indemnity,
|
| 169 |
+
or other liability obligations and/or rights consistent with this
|
| 170 |
+
License. However, in accepting such obligations, You may act only
|
| 171 |
+
on Your own behalf and on Your sole responsibility, not on behalf
|
| 172 |
+
of any other Contributor, and only if You agree to indemnify,
|
| 173 |
+
defend, and hold each Contributor harmless for any liability
|
| 174 |
+
incurred by, or claims asserted against, such Contributor by reason
|
| 175 |
+
of your accepting any such warranty or additional liability.
|
| 176 |
+
|
| 177 |
+
END OF TERMS AND CONDITIONS
|
| 178 |
+
|
| 179 |
+
APPENDIX: How to apply the Apache License to your work.
|
| 180 |
+
|
| 181 |
+
To apply the Apache License to your work, attach the following
|
| 182 |
+
boilerplate notice, with the fields enclosed by brackets "[]"
|
| 183 |
+
replaced with your own identifying information. (Don't include
|
| 184 |
+
the brackets!) The text should be enclosed in the appropriate
|
| 185 |
+
comment syntax for the file format. We also recommend that a
|
| 186 |
+
file or class name and description of purpose be included on the
|
| 187 |
+
same "printed page" as the copyright notice for easier
|
| 188 |
+
identification within third-party archives.
|
| 189 |
+
|
| 190 |
+
Copyright 2026 Alibaba Cloud
|
| 191 |
+
|
| 192 |
+
Licensed under the Apache License, Version 2.0 (the "License");
|
| 193 |
+
you may not use this file except in compliance with the License.
|
| 194 |
+
You may obtain a copy of the License at
|
| 195 |
+
|
| 196 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 197 |
+
|
| 198 |
+
Unless required by applicable law or agreed to in writing, software
|
| 199 |
+
distributed under the License is distributed on an "AS IS" BASIS,
|
| 200 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 201 |
+
See the License for the specific language governing permissions and
|
| 202 |
+
limitations under the License.
|
NOTICE
ADDED
|
@@ -0,0 +1,35 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
chaoliangUNSW/Jev-Style-2B-Decision-v3-MLX
|
| 2 |
+
Copyright 2026 chaoliangUNSW. Licensed under the Apache License, Version 2.0 (see LICENSE).
|
| 3 |
+
|
| 4 |
+
This model is a fine-tuned derivative of Qwen3.5-2B (https://huggingface.co/Qwen/Qwen3.5-2B,
|
| 5 |
+
revision 15852e8c16360a2fea060d615a32b45270f8a8fc), Copyright 2026 Alibaba Cloud, licensed under the Apache
|
| 6 |
+
License, Version 2.0. The LICENSE file in this repository is the license file distributed with Qwen3.5-2B.
|
| 7 |
+
|
| 8 |
+
Modifications relative to Qwen3.5-2B:
|
| 9 |
+
- all text-model weights were fine-tuned (full fine-tuning) to score typed decision questions
|
| 10 |
+
(choice / score / true-false) with a verdict readout: logit(" yes") - logit(" no") at one " ->" slot per
|
| 11 |
+
option, under a block-causal attention protocol (2,048-token blocks); one global calibration temperature was
|
| 12 |
+
fitted afterwards (readout_config.json);
|
| 13 |
+
- the vision tower (model.visual.*) and the multi-token-prediction head (mtp.*) were removed; the checkpoint
|
| 14 |
+
is a text-only Qwen3_5ForCausalLM with tied input/output embeddings;
|
| 15 |
+
- converted to MLX format with mlx-lm 0.31.3 / mlx 0.32.2 (https://github.com/ml-explore/mlx-lm,
|
| 16 |
+
MIT License, Copyright Apple Inc.): bf16/ = bfloat16, 8bit/ = affine 8-bit quantisation, group size 64;
|
| 17 |
+
each folder also holds macjev_norms_fp32.safetensors (the exact FP32 (1 + w) RMSNorm weights);
|
| 18 |
+
- the runtime script contains a modified copy of mlx-lm 0.31.3's qwen3_5 GatedDeltaNet.__call__ (MIT License,
|
| 19 |
+
Copyright Apple Inc.; the q/k normalisation epsilon changed and the sharding branches removed); the MIT
|
| 20 |
+
copyright and permission notice is reproduced in THIRD_PARTY_NOTICES.md;
|
| 21 |
+
- added the runtime script, readout/release configuration files, the integrity manifest and this NOTICE.
|
| 22 |
+
|
| 23 |
+
The question types (choice / score / noul) follow the typed-decision convention of Laya
|
| 24 |
+
(https://github.com/NandhaKishorM/laya, Apache-2.0) so both models can be evaluated on the same
|
| 25 |
+
inputs. No Laya code or weights are included.
|
| 26 |
+
|
| 27 |
+
Part of the third generation (v3) of the Jev-Style decision series (v3 also includes
|
| 28 |
+
chaoliangUNSW/Jev-Style-0.8B-Decision-v3). Earlier generations: v1 = chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision
|
| 29 |
+
(public GGUF release: chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision-GGUF) and v2 =
|
| 30 |
+
chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision-v2, both built on Qwen3.5-2B-Base. Jev-Style-2B-Decision-v3 is
|
| 31 |
+
a full fine-tune of Qwen/Qwen3.5-2B.
|
| 32 |
+
|
| 33 |
+
Not affiliated with, endorsed by or connected to TypeSafe or Jev. "Jev-Style" only describes the kind
|
| 34 |
+
of model (a small typed-decision model in a similar style); no Jev weights, code or outputs are included.
|
| 35 |
+
Not affiliated with or endorsed by Alibaba Cloud / the Qwen team or the Laya authors.
|
README.md
ADDED
|
@@ -0,0 +1,194 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: apache-2.0
|
| 3 |
+
base_model: chaoliangUNSW/Jev-Style-2B-Decision-v3
|
| 4 |
+
base_model_relation: quantized
|
| 5 |
+
library_name: mlx
|
| 6 |
+
pipeline_tag: text-classification
|
| 7 |
+
tags:
|
| 8 |
+
- decision-model
|
| 9 |
+
- decision-making
|
| 10 |
+
- jev-style
|
| 11 |
+
- system-one
|
| 12 |
+
- calibration
|
| 13 |
+
- long-context
|
| 14 |
+
- qwen3.5
|
| 15 |
+
- mlx
|
| 16 |
+
- apple-silicon
|
| 17 |
+
- on-device
|
| 18 |
+
- llm-routing
|
| 19 |
+
- guardrails
|
| 20 |
+
---
|
| 21 |
+
|
| 22 |
+
# Jev-Style-2B-Decision-v3-MLX
|
| 23 |
+
|
| 24 |
+
**[Try it in your browser →](https://huggingface.co/spaces/chaoliangUNSW/jev-style-2b)**
|
| 25 |
+
|
| 26 |
+
**Website:** [jevstyle.com](https://jevstyle.com/#v3-2b) · **GitHub:** [jev-style](https://github.com/lawrence3699/jev-style) · **Collection:** [all v3 builds and demos](https://huggingface.co/collections/chaoliangUNSW/jev-style-decision-v3-08b-2b-6ab87f32380cbd8c03b608b9)
|
| 27 |
+
|
| 28 |
+
**Jev-Style decision series:** [v1 · 2B](https://huggingface.co/chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision-MLX-bf16) → [v2 · 2B](https://huggingface.co/chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision-v2-MLX-bf16) → [v3 · 0.8B](https://huggingface.co/chaoliangUNSW/Jev-Style-0.8B-Decision-v3-MLX) → **v3 · 2B**
|
| 29 |
+
|
| 30 |
+
<!-- PIP_SNIPPET_AFTER_0.3.0 -->
|
| 31 |
+
|
| 32 |
+
**Jev-style decisions, now at 2B, native on Apple silicon.** These are the MLX builds of
|
| 33 |
+
[Jev-Style-2B-Decision-v3](https://huggingface.co/chaoliangUNSW/Jev-Style-2B-Decision-v3): bf16 (3.76 GB) and
|
| 34 |
+
8-bit (2.00 GB) in one repository, with one runtime (`jev_style_decision_mlx.py`; choose the folder with `--model-dir bf16` or `--model-dir 8bit`). Full
|
| 35 |
+
results, protocols, training data and licences are on the
|
| 36 |
+
[main model card](https://huggingface.co/chaoliangUNSW/Jev-Style-2B-Decision-v3).
|
| 37 |
+
|
| 38 |
+

|
| 39 |
+
|
| 40 |
+
| Public benchmark | **Jev-Style v3 · 2B** | Jev-Style v3 · 0.8B | Jev 1.13 (API) |
|
| 41 |
+
|---|:---:|:---:|:---:|
|
| 42 |
+
| JevBench v1.4.1, 231 public items ↑ | 73.6% | 64.1% | 86.6% |
|
| 43 |
+
| tweet_topic, zero-shot, accuracy ↑ | 82.2% | 75.5% | 79.3%¹ |
|
| 44 |
+
| fin_topic, zero-shot, accuracy ↑ | 61.1% | 46.7% | 67.0%¹ |
|
| 45 |
+
| Longest input per call | 25,600 tokens, no option cap | 25,600 tokens | |
|
| 46 |
+
|
| 47 |
+
<sub>Benchmark numbers of the model, measured with its GGUF F16 build (the pre-declared engine; one global temperature; each benchmark run once). The MLX builds were checked against the same FP32 reference (table below). JevBench: self-run with the official harness, not an official board entry; 95% CI 67.6–78.9% (Wilson). 73.6% is the highest JevBench public accuracy among the Qwen3.5-2B-family systems on the v1.4.1 board (decider-2b 71.0%, open-jev-zefan-2b 64.5%); decider-2b lies inside the CI. Jev is well ahead on JevBench and ahead on fin_topic. ¹ Jev numbers from the elcronos study (raw API), not re-run by us; on tweet_topic the 2B's macro-F1 (67.8%) is below Jev's (69.4%). Details: [main card](https://huggingface.co/chaoliangUNSW/Jev-Style-2B-Decision-v3#results).</sub>
|
| 48 |
+
|
| 49 |
+
**25,600 tokens, no option cap.** State, questions and every option share one 25,600-token budget; question and
|
| 50 |
+
options over 2,048 tokens use a numbered-option catalogue. Nothing is truncated.
|
| 51 |
+
|
| 52 |
+
## Precisions and parity
|
| 53 |
+
|
| 54 |
+
| Precision | Folder | Weights | Same top-1 as PyTorch FP32 (1,000 rows) | Max abs Δp | Accuracy (FP32: 80.8%) | Long fixture (43 questions) | Gate |
|
| 55 |
+
|---|---|---:|---:|---:|---:|---:|:---:|
|
| 56 |
+
| **bf16** (default) | `bf16/` | 3.76 GB | **99.7%** | 0.035 | 80.5% | **43 / 43** | PASS |
|
| 57 |
+
| **8-bit** (affine, group size 64) | `8bit/` | 2.00 GB | **99.6%** | 0.162 | 80.8% | **43 / 43** | PASS |
|
| 58 |
+
|
| 59 |
+
- Each folder holds `model.safetensors`, its `config.json`, the tokenizer and `macjev_norms_fp32.safetensors`
|
| 60 |
+
(FP32 norm weights, 0.42 MB, required). The top level holds the shared runtime `jev_style_decision_mlx.py`,
|
| 61 |
+
`readout_config.json`, `release_config.json`, the sha256 `manifest.json`, `LICENSE`, `NOTICE`,
|
| 62 |
+
`THIRD_PARTY_NOTICES.md` and a copy of `bf16/config.json` (for the Hub's download counter). Converted with mlx
|
| 63 |
+
0.32.2 and mlx-lm 0.31.3.
|
| 64 |
+
- The 8-bit build makes the same call as full precision on 99.6% of the 1,000 rows at about half the size.
|
| 65 |
+
- **Which folder:** `bf16/` for closeness to the FP32 reference (max abs Δp 0.035 vs 0.162); `8bit/` when memory is
|
| 66 |
+
tight.
|
| 67 |
+
|
| 68 |
+
<sub>Reference: HF FP32 on CPU, exact block attention, on the released bf16 checkpoint; gates declared before any format was scored. 1,000 real development rows (≤4,096 tokens) test agreement between formats. Long fixture: 35 requests / 43 questions up to 25,600 tokens, including catalogue-overflow questions and up to 151 options. Sizes are the weight files (GB = 10^9 bytes).</sub>
|
| 69 |
+
|
| 70 |
+
<!-- LATENCY:BEGIN generated from latency_2b.json (validation/latency_2b.json in the main repository); do not edit by hand -->
|
| 71 |
+
|
| 72 |
+
## Speed
|
| 73 |
+
|
| 74 |
+
**Read once, then ask.** On an Apple M1 Max (MLX bf16), the first question about a 24,501-token input took 15.5 s; a further question about the same state took 0.15 s, because the state is computed once and reused (medians). Ten questions about that state in one call took 16.2 s.
|
| 75 |
+
|
| 76 |
+
| State | Questions per call | MLX bf16 | MLX 8-bit |
|
| 77 |
+
|---|---:|---:|---:|
|
| 78 |
+
| 878 tokens | 1 | 0.57 s | 0.72 s |
|
| 79 |
+
| 878 tokens | 10 | 1.07 s | 1.27 s |
|
| 80 |
+
| 3,950 tokens | 1 | 2.26 s | 2.96 s |
|
| 81 |
+
| 3,950 tokens | 10 | 2.80 s | 3.54 s |
|
| 82 |
+
| 24,436 tokens | 1 | 15.5 s | 19.9 s |
|
| 83 |
+
| 24,436 tokens | 10 | 16.2 s | 20.8 s |
|
| 84 |
+
| 24,436 tokens, already computed | 1 | 0.15 s | 0.16 s |
|
| 85 |
+
|
| 86 |
+
- Pick a precision folder by size and closeness to FP32 (Precisions table above). bf16 and 8-bit were timed one after another on the same shared machine; in these runs 8-bit was the slower folder in every row (indicative only).
|
| 87 |
+
|
| 88 |
+
<sub>Apple M1 Max, 64 GB, macOS 15.7.5. Wall time around one `decide` / `score_many` call (tokenisation included), median of 3 calls with the state recomputed each time; the model was loaded beforehand (loading took 3.1–3.7 s here, not included). States: English documentation and source code of 878, 3,950, 24,436 tokens plus the question; 10 questions = 4 choice, 4 true/false and 2 score questions about the same state in one call; with the question and options each input was up to 943, 4,015 and 24,501 tokens. MLX: mlx 0.32.2 / mlx-lm 0.31.3. Results were identical with and without a precomputed state. Other jobs shared the machine during these runs (1-minute load average 5.5–8.6 at the end of each run), so treat the numbers as indicative. All rows here were measured in one session (2026-09-27 03:21–03:28 AEST); an earlier run of the same rows (00:37–00:45 AEST, load average 11.8–27.5) was discarded because other jobs had slowed it (its times were up to 2.1× longer).</sub>
|
| 89 |
+
|
| 90 |
+
<!-- LATENCY:END -->
|
| 91 |
+
|
| 92 |
+
## Quick start
|
| 93 |
+
|
| 94 |
+
```bash
|
| 95 |
+
pip install -U huggingface_hub
|
| 96 |
+
hf download chaoliangUNSW/Jev-Style-2B-Decision-v3-MLX --local-dir Jev-Style-2B-Decision-v3-MLX
|
| 97 |
+
cd Jev-Style-2B-Decision-v3-MLX
|
| 98 |
+
pip install -r requirements.txt # mlx 0.32.2, mlx-lm 0.31.3 (exactly), transformers 5.17.0, tokenizers, numpy
|
| 99 |
+
```
|
| 100 |
+
|
| 101 |
+
Only one precision is needed: add `--exclude "8bit/*"` to the download for bf16 only, or `--exclude "bf16/*"` for
|
| 102 |
+
8-bit only. Pass the precision folder to the runtime with `--model-dir bf16` or `--model-dir 8bit` (in Python,
|
| 103 |
+
`JevStyleDecisionMLX("bf16")` or `JevStyleDecisionMLX("8bit")`).
|
| 104 |
+
|
| 105 |
+
```bash
|
| 106 |
+
# choice question, bf16 weights
|
| 107 |
+
python jev_style_decision_mlx.py --model-dir bf16 --state "Finder is open on ~/Reports. The user asked: email report.pdf to Ana." \
|
| 108 |
+
--question "What should the agent do next?" \
|
| 109 |
+
--options '{"attach_report": "attach report.pdf to a new email to Ana", "rename_report": null, "close_finder": "close the Finder window"}'
|
| 110 |
+
|
| 111 |
+
# true/false question about a JSON state, 8-bit weights
|
| 112 |
+
python jev_style_decision_mlx.py --model-dir 8bit \
|
| 113 |
+
--state-json '{"app": "Mail", "draft": {"to": "ana@example.com", "attachments": []}}' \
|
| 114 |
+
--question "Is the report attached?" --qtype noul
|
| 115 |
+
|
| 116 |
+
# score (ordinal) question, uncalibrated probabilities (T = 1.0)
|
| 117 |
+
python jev_style_decision_mlx.py --model-dir 8bit --state "The deploy failed twice with the same migration error." \
|
| 118 |
+
--question "How risky is retrying now?" --qtype score --options '["no risk", "some risk", "high risk"]' --temperature 1.0
|
| 119 |
+
|
| 120 |
+
# full typed question as JSON, first checking the sha256 of the runtime files and the chosen precision folder (manifest.json)
|
| 121 |
+
python jev_style_decision_mlx.py --model-dir bf16 --verify --state "cart: 3 items" \
|
| 122 |
+
--question '{"t": "choice", "ins": "Next step?", "crit": {"checkout": null, "keep_shopping": null}}'
|
| 123 |
+
```
|
| 124 |
+
|
| 125 |
+
The output has `answer`, `probabilities` and raw `scores` per option, `temperature` (0.8279, the calibrated global
|
| 126 |
+
temperature), `top_probability`, `entropy_concentration`, `input_tokens`, `state_tokens`, `head_tokens`, `blocks`
|
| 127 |
+
and `catalogue_overflow`.
|
| 128 |
+
|
| 129 |
+
```python
|
| 130 |
+
from jev_style_decision_mlx import JevStyleDecisionMLX
|
| 131 |
+
m = JevStyleDecisionMLX("8bit") # the 8-bit precision folder
|
| 132 |
+
state = {"screen": "Settings > Wi-Fi", "goal": "join the network Office-5G"}
|
| 133 |
+
qs = [{"t": "choice", "ins": "Next action?", "crit": {"tap_office_5g": None, "toggle_wifi_off": None, "go_back": None}},
|
| 134 |
+
{"t": "noul", "ins": "Is Wi-Fi turned on?", "crit": None}]
|
| 135 |
+
for r in m.score_many(state, qs): # the state is computed once and reused for every question
|
| 136 |
+
print(r["answer"], round(r["top_probability"], 4))
|
| 137 |
+
m.decide(state, qs[0]) # same state again: reused (m.last_timing["state_reused"] is True)
|
| 138 |
+
m.close()
|
| 139 |
+
```
|
| 140 |
+
|
| 141 |
+
- Batch mode: `--jsonl requests.jsonl` (or `-` for stdin), rows `{"id"?, "state", "question", "options"?, "qtype"?,
|
| 142 |
+
"temperature"?}`; consecutive rows with an identical state share one state computation, and a malformed row gets
|
| 143 |
+
an `"error"` field while the batch continues.
|
| 144 |
+
- **Long inputs.** The complete input can be up to 25,600 tokens, with no separate question/options cap. In our
|
| 145 |
+
smoke test a 22,005-token state with 100 described options ran as 25,393 tokens in 14 blocks, using the
|
| 146 |
+
catalogue layout. A larger input raises `InputBudgetError` (CLI exit status 2); nothing is truncated.
|
| 147 |
+
- **mlx-lm must be exactly 0.31.3.** The runtime corrects two Qwen3.5 numerics inside mlx-lm and checks the source
|
| 148 |
+
it patches; other versions are refused with the install command. It also refuses to run without
|
| 149 |
+
`macjev_norms_fp32.safetensors` or `readout_config.json`, and never falls back to stock norms or T = 1.
|
| 150 |
+
- The input format, block attention and the readout are described on the
|
| 151 |
+
[main card](https://huggingface.co/chaoliangUNSW/Jev-Style-2B-Decision-v3#input-format-and-readout).
|
| 152 |
+
|
| 153 |
+
## Scope and limits
|
| 154 |
+
|
| 155 |
+
- **Runtime required.** `mlx_lm.generate` can load the weights in `bf16/` or `8bit/` (the
|
| 156 |
+
repository root holds no weights) but still cannot produce the decision scores, and it would run causal attention.
|
| 157 |
+
Use `jev_style_decision_mlx.py`.
|
| 158 |
+
- **25,600 tokens** is the limit for the whole input (state + question + options + readout).
|
| 159 |
+
- **Reduced-data training.** The model was trained on a reduced data pool (60M tokens).
|
| 160 |
+
- **Decision Index.** Not run by us. The training pool includes the train splits of 7 of its benchmarks and
|
| 161 |
+
format-imitating data for 7 more, so results on these are not zero-shot; the 14 benchmarks that are not zero-shot
|
| 162 |
+
for this model are named on the [main card](https://huggingface.co/chaoliangUNSW/Jev-Style-2B-Decision-v3#scope-and-limits).
|
| 163 |
+
|
| 164 |
+
<details>
|
| 165 |
+
<summary><strong>Results charts</strong></summary>
|
| 166 |
+
|
| 167 |
+

|
| 168 |
+
|
| 169 |
+

|
| 170 |
+
|
| 171 |
+
<sub>Protocol notes are under each chart and on the main card. Plotted values and sources: [jevbench.data.json](figures/jevbench.data.json), [zeroshot.data.json](figures/zeroshot.data.json).</sub>
|
| 172 |
+
|
| 173 |
+
</details>
|
| 174 |
+
|
| 175 |
+
## Disclaimers and licence
|
| 176 |
+
|
| 177 |
+
Apache-2.0. Built on Qwen/Qwen3.5-2B (Apache-2.0); `NOTICE` lists the modifications. Some training data has
|
| 178 |
+
restrictive or unclear terms (for example research-only jailbreak prompts and share-alike CC BY-SA sources), and some
|
| 179 |
+
training rows are outputs of OpenAI GPT and Anthropic Claude models, whose providers' terms of use may restrict how
|
| 180 |
+
models trained on them may be used. See [Training data and
|
| 181 |
+
licences](https://huggingface.co/chaoliangUNSW/Jev-Style-2B-Decision-v3#training-data-and-licences) on the main card.
|
| 182 |
+
The runtime contains a modified copy of one mlx-lm 0.31.3 function (the Qwen3.5 `GatedDeltaNet.__call__`; MIT License,
|
| 183 |
+
Copyright Apple Inc.); its copyright and permission notice is in `THIRD_PARTY_NOTICES.md`. Not affiliated with,
|
| 184 |
+
endorsed by or connected to TypeSafe AI or Jev (no Jev weights, code or outputs are used), the Laya authors or the
|
| 185 |
+
Qwen team.
|
| 186 |
+
|
| 187 |
+
**AI disclosure:** code written with AI coding assistants (Claude Code) under my direction; I designed the project,
|
| 188 |
+
trained the models and verified the results.
|
| 189 |
+
|
| 190 |
+
## Contact
|
| 191 |
+
|
| 192 |
+
I welcome internship, employment, and research collaboration opportunities. Please contact me at [**yanchaoliang369@gmail.com**](mailto:yanchaoliang369@gmail.com).
|
| 193 |
+
|
| 194 |
+
欢迎提供实习、工作及科研合作机会,请邮件联系:[yanchaoliang369@gmail.com](mailto:yanchaoliang369@gmail.com)。
|
THIRD_PARTY_NOTICES.md
ADDED
|
@@ -0,0 +1,41 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Third-party notices
|
| 2 |
+
|
| 3 |
+
This file covers third-party code that is **contained in** this repository. Libraries that are only imported at
|
| 4 |
+
run time (mlx, mlx-lm, tokenizers, numpy) are not redistributed here and keep their own licences.
|
| 5 |
+
|
| 6 |
+
## mlx-lm 0.31.3 (MIT License)
|
| 7 |
+
|
| 8 |
+
`jev_style_decision_mlx.py` contains a modified copy of `GatedDeltaNet.__call__` from
|
| 9 |
+
`mlx_lm/models/qwen3_5.py` of mlx-lm 0.31.3 (https://github.com/ml-explore/mlx-lm; that source file carries the
|
| 10 |
+
header "Copyright © 2026 Apple Inc."). In the runtime it is the function `_gdn_hf_call`. Changes made:
|
| 11 |
+
|
| 12 |
+
- the q/k normalisation epsilon: `mx.fast.rms_norm(x, None, 1e-6)` became `mx.fast.rms_norm(x, None, 1e-6 / Dk)`,
|
| 13 |
+
so that q/k are l2-normalised with eps 1e-6 as in Hugging Face transformers / llama.cpp;
|
| 14 |
+
- the tensor-parallel (sharding) branches were removed: a sharded layer is refused with an error;
|
| 15 |
+
- rewritten as a module-level function (installed per model instance, never globally) and reformatted.
|
| 16 |
+
|
| 17 |
+
The mlx-lm licence (the LICENSE file distributed with mlx-lm 0.31.3), reproduced verbatim:
|
| 18 |
+
|
| 19 |
+
```text
|
| 20 |
+
MIT License
|
| 21 |
+
|
| 22 |
+
Copyright © 2023 Apple Inc.
|
| 23 |
+
|
| 24 |
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
| 25 |
+
of this software and associated documentation files (the "Software"), to deal
|
| 26 |
+
in the Software without restriction, including without limitation the rights
|
| 27 |
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
| 28 |
+
copies of the Software, and to permit persons to whom the Software is
|
| 29 |
+
furnished to do so, subject to the following conditions:
|
| 30 |
+
|
| 31 |
+
The above copyright notice and this permission notice shall be included in all
|
| 32 |
+
copies or substantial portions of the Software.
|
| 33 |
+
|
| 34 |
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
| 35 |
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
| 36 |
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
| 37 |
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
| 38 |
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
| 39 |
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
| 40 |
+
SOFTWARE.
|
| 41 |
+
```
|
bf16/chat_template.jinja
ADDED
|
@@ -0,0 +1,154 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{%- set image_count = namespace(value=0) %}
|
| 2 |
+
{%- set video_count = namespace(value=0) %}
|
| 3 |
+
{%- macro render_content(content, do_vision_count, is_system_content=false) %}
|
| 4 |
+
{%- if content is string %}
|
| 5 |
+
{{- content }}
|
| 6 |
+
{%- elif content is iterable and content is not mapping %}
|
| 7 |
+
{%- for item in content %}
|
| 8 |
+
{%- if 'image' in item or 'image_url' in item or item.type == 'image' %}
|
| 9 |
+
{%- if is_system_content %}
|
| 10 |
+
{{- raise_exception('System message cannot contain images.') }}
|
| 11 |
+
{%- endif %}
|
| 12 |
+
{%- if do_vision_count %}
|
| 13 |
+
{%- set image_count.value = image_count.value + 1 %}
|
| 14 |
+
{%- endif %}
|
| 15 |
+
{%- if add_vision_id %}
|
| 16 |
+
{{- 'Picture ' ~ image_count.value ~ ': ' }}
|
| 17 |
+
{%- endif %}
|
| 18 |
+
{{- '<|vision_start|><|image_pad|><|vision_end|>' }}
|
| 19 |
+
{%- elif 'video' in item or item.type == 'video' %}
|
| 20 |
+
{%- if is_system_content %}
|
| 21 |
+
{{- raise_exception('System message cannot contain videos.') }}
|
| 22 |
+
{%- endif %}
|
| 23 |
+
{%- if do_vision_count %}
|
| 24 |
+
{%- set video_count.value = video_count.value + 1 %}
|
| 25 |
+
{%- endif %}
|
| 26 |
+
{%- if add_vision_id %}
|
| 27 |
+
{{- 'Video ' ~ video_count.value ~ ': ' }}
|
| 28 |
+
{%- endif %}
|
| 29 |
+
{{- '<|vision_start|><|video_pad|><|vision_end|>' }}
|
| 30 |
+
{%- elif 'text' in item %}
|
| 31 |
+
{{- item.text }}
|
| 32 |
+
{%- else %}
|
| 33 |
+
{{- raise_exception('Unexpected item type in content.') }}
|
| 34 |
+
{%- endif %}
|
| 35 |
+
{%- endfor %}
|
| 36 |
+
{%- elif content is none or content is undefined %}
|
| 37 |
+
{{- '' }}
|
| 38 |
+
{%- else %}
|
| 39 |
+
{{- raise_exception('Unexpected content type.') }}
|
| 40 |
+
{%- endif %}
|
| 41 |
+
{%- endmacro %}
|
| 42 |
+
{%- if not messages %}
|
| 43 |
+
{{- raise_exception('No messages provided.') }}
|
| 44 |
+
{%- endif %}
|
| 45 |
+
{%- if tools and tools is iterable and tools is not mapping %}
|
| 46 |
+
{{- '<|im_start|>system\n' }}
|
| 47 |
+
{{- "# Tools\n\nYou have access to the following functions:\n\n<tools>" }}
|
| 48 |
+
{%- for tool in tools %}
|
| 49 |
+
{{- "\n" }}
|
| 50 |
+
{{- tool | tojson }}
|
| 51 |
+
{%- endfor %}
|
| 52 |
+
{{- "\n</tools>" }}
|
| 53 |
+
{{- '\n\nIf you choose to call a function ONLY reply in the following format with NO suffix:\n\n<tool_call>\n<function=example_function_name>\n<parameter=example_parameter_1>\nvalue_1\n</parameter>\n<parameter=example_parameter_2>\nThis is the value for the second parameter\nthat can span\nmultiple lines\n</parameter>\n</function>\n</tool_call>\n\n<IMPORTANT>\nReminder:\n- Function calls MUST follow the specified format: an inner <function=...></function> block must be nested within <tool_call></tool_call> XML tags\n- Required parameters MUST be specified\n- You may provide optional reasoning for your function call in natural language BEFORE the function call, but NOT after\n- If there is no function call available, answer the question like normal with your current knowledge and do not tell the user about function calls\n</IMPORTANT>' }}
|
| 54 |
+
{%- if messages[0].role == 'system' %}
|
| 55 |
+
{%- set content = render_content(messages[0].content, false, true)|trim %}
|
| 56 |
+
{%- if content %}
|
| 57 |
+
{{- '\n\n' + content }}
|
| 58 |
+
{%- endif %}
|
| 59 |
+
{%- endif %}
|
| 60 |
+
{{- '<|im_end|>\n' }}
|
| 61 |
+
{%- else %}
|
| 62 |
+
{%- if messages[0].role == 'system' %}
|
| 63 |
+
{%- set content = render_content(messages[0].content, false, true)|trim %}
|
| 64 |
+
{{- '<|im_start|>system\n' + content + '<|im_end|>\n' }}
|
| 65 |
+
{%- endif %}
|
| 66 |
+
{%- endif %}
|
| 67 |
+
{%- set ns = namespace(multi_step_tool=true, last_query_index=messages|length - 1) %}
|
| 68 |
+
{%- for message in messages[::-1] %}
|
| 69 |
+
{%- set index = (messages|length - 1) - loop.index0 %}
|
| 70 |
+
{%- if ns.multi_step_tool and message.role == "user" %}
|
| 71 |
+
{%- set content = render_content(message.content, false)|trim %}
|
| 72 |
+
{%- if not(content.startswith('<tool_response>') and content.endswith('</tool_response>')) %}
|
| 73 |
+
{%- set ns.multi_step_tool = false %}
|
| 74 |
+
{%- set ns.last_query_index = index %}
|
| 75 |
+
{%- endif %}
|
| 76 |
+
{%- endif %}
|
| 77 |
+
{%- endfor %}
|
| 78 |
+
{%- if ns.multi_step_tool %}
|
| 79 |
+
{{- raise_exception('No user query found in messages.') }}
|
| 80 |
+
{%- endif %}
|
| 81 |
+
{%- for message in messages %}
|
| 82 |
+
{%- set content = render_content(message.content, true)|trim %}
|
| 83 |
+
{%- if message.role == "system" %}
|
| 84 |
+
{%- if not loop.first %}
|
| 85 |
+
{{- raise_exception('System message must be at the beginning.') }}
|
| 86 |
+
{%- endif %}
|
| 87 |
+
{%- elif message.role == "user" %}
|
| 88 |
+
{{- '<|im_start|>' + message.role + '\n' + content + '<|im_end|>' + '\n' }}
|
| 89 |
+
{%- elif message.role == "assistant" %}
|
| 90 |
+
{%- set reasoning_content = '' %}
|
| 91 |
+
{%- if message.reasoning_content is string %}
|
| 92 |
+
{%- set reasoning_content = message.reasoning_content %}
|
| 93 |
+
{%- else %}
|
| 94 |
+
{%- if '</think>' in content %}
|
| 95 |
+
{%- set reasoning_content = content.split('</think>')[0].rstrip('\n').split('<think>')[-1].lstrip('\n') %}
|
| 96 |
+
{%- set content = content.split('</think>')[-1].lstrip('\n') %}
|
| 97 |
+
{%- endif %}
|
| 98 |
+
{%- endif %}
|
| 99 |
+
{%- set reasoning_content = reasoning_content|trim %}
|
| 100 |
+
{%- if loop.index0 > ns.last_query_index %}
|
| 101 |
+
{{- '<|im_start|>' + message.role + '\n<think>\n' + reasoning_content + '\n</think>\n\n' + content }}
|
| 102 |
+
{%- else %}
|
| 103 |
+
{{- '<|im_start|>' + message.role + '\n' + content }}
|
| 104 |
+
{%- endif %}
|
| 105 |
+
{%- if message.tool_calls and message.tool_calls is iterable and message.tool_calls is not mapping %}
|
| 106 |
+
{%- for tool_call in message.tool_calls %}
|
| 107 |
+
{%- if tool_call.function is defined %}
|
| 108 |
+
{%- set tool_call = tool_call.function %}
|
| 109 |
+
{%- endif %}
|
| 110 |
+
{%- if loop.first %}
|
| 111 |
+
{%- if content|trim %}
|
| 112 |
+
{{- '\n\n<tool_call>\n<function=' + tool_call.name + '>\n' }}
|
| 113 |
+
{%- else %}
|
| 114 |
+
{{- '<tool_call>\n<function=' + tool_call.name + '>\n' }}
|
| 115 |
+
{%- endif %}
|
| 116 |
+
{%- else %}
|
| 117 |
+
{{- '\n<tool_call>\n<function=' + tool_call.name + '>\n' }}
|
| 118 |
+
{%- endif %}
|
| 119 |
+
{%- if tool_call.arguments is defined %}
|
| 120 |
+
{%- for args_name, args_value in tool_call.arguments|items %}
|
| 121 |
+
{{- '<parameter=' + args_name + '>\n' }}
|
| 122 |
+
{%- set args_value = args_value | tojson | safe if args_value is mapping or (args_value is sequence and args_value is not string) else args_value | string %}
|
| 123 |
+
{{- args_value }}
|
| 124 |
+
{{- '\n</parameter>\n' }}
|
| 125 |
+
{%- endfor %}
|
| 126 |
+
{%- endif %}
|
| 127 |
+
{{- '</function>\n</tool_call>' }}
|
| 128 |
+
{%- endfor %}
|
| 129 |
+
{%- endif %}
|
| 130 |
+
{{- '<|im_end|>\n' }}
|
| 131 |
+
{%- elif message.role == "tool" %}
|
| 132 |
+
{%- if loop.previtem and loop.previtem.role != "tool" %}
|
| 133 |
+
{{- '<|im_start|>user' }}
|
| 134 |
+
{%- endif %}
|
| 135 |
+
{{- '\n<tool_response>\n' }}
|
| 136 |
+
{{- content }}
|
| 137 |
+
{{- '\n</tool_response>' }}
|
| 138 |
+
{%- if not loop.last and loop.nextitem.role != "tool" %}
|
| 139 |
+
{{- '<|im_end|>\n' }}
|
| 140 |
+
{%- elif loop.last %}
|
| 141 |
+
{{- '<|im_end|>\n' }}
|
| 142 |
+
{%- endif %}
|
| 143 |
+
{%- else %}
|
| 144 |
+
{{- raise_exception('Unexpected message role.') }}
|
| 145 |
+
{%- endif %}
|
| 146 |
+
{%- endfor %}
|
| 147 |
+
{%- if add_generation_prompt %}
|
| 148 |
+
{{- '<|im_start|>assistant\n' }}
|
| 149 |
+
{%- if enable_thinking is defined and enable_thinking is true %}
|
| 150 |
+
{{- '<think>\n' }}
|
| 151 |
+
{%- else %}
|
| 152 |
+
{{- '<think>\n\n</think>\n\n' }}
|
| 153 |
+
{%- endif %}
|
| 154 |
+
{%- endif %}
|
bf16/config.json
ADDED
|
@@ -0,0 +1,75 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"architectures": [
|
| 3 |
+
"Qwen3_5ForCausalLM"
|
| 4 |
+
],
|
| 5 |
+
"attention_bias": false,
|
| 6 |
+
"attention_dropout": 0.0,
|
| 7 |
+
"attn_output_gate": true,
|
| 8 |
+
"bos_token_id": null,
|
| 9 |
+
"dtype": "bfloat16",
|
| 10 |
+
"eos_token_id": 248044,
|
| 11 |
+
"full_attention_interval": 4,
|
| 12 |
+
"head_dim": 256,
|
| 13 |
+
"hidden_act": "silu",
|
| 14 |
+
"hidden_size": 2048,
|
| 15 |
+
"initializer_range": 0.02,
|
| 16 |
+
"intermediate_size": 6144,
|
| 17 |
+
"layer_types": [
|
| 18 |
+
"linear_attention",
|
| 19 |
+
"linear_attention",
|
| 20 |
+
"linear_attention",
|
| 21 |
+
"full_attention",
|
| 22 |
+
"linear_attention",
|
| 23 |
+
"linear_attention",
|
| 24 |
+
"linear_attention",
|
| 25 |
+
"full_attention",
|
| 26 |
+
"linear_attention",
|
| 27 |
+
"linear_attention",
|
| 28 |
+
"linear_attention",
|
| 29 |
+
"full_attention",
|
| 30 |
+
"linear_attention",
|
| 31 |
+
"linear_attention",
|
| 32 |
+
"linear_attention",
|
| 33 |
+
"full_attention",
|
| 34 |
+
"linear_attention",
|
| 35 |
+
"linear_attention",
|
| 36 |
+
"linear_attention",
|
| 37 |
+
"full_attention",
|
| 38 |
+
"linear_attention",
|
| 39 |
+
"linear_attention",
|
| 40 |
+
"linear_attention",
|
| 41 |
+
"full_attention"
|
| 42 |
+
],
|
| 43 |
+
"linear_conv_kernel_dim": 4,
|
| 44 |
+
"linear_key_head_dim": 128,
|
| 45 |
+
"linear_num_key_heads": 16,
|
| 46 |
+
"linear_num_value_heads": 16,
|
| 47 |
+
"linear_value_head_dim": 128,
|
| 48 |
+
"mamba_ssm_dtype": "float32",
|
| 49 |
+
"max_position_embeddings": 262144,
|
| 50 |
+
"mlp_only_layers": [],
|
| 51 |
+
"model_type": "qwen3_5",
|
| 52 |
+
"mtp_num_hidden_layers": 1,
|
| 53 |
+
"mtp_use_dedicated_embeddings": false,
|
| 54 |
+
"num_attention_heads": 8,
|
| 55 |
+
"num_hidden_layers": 24,
|
| 56 |
+
"num_key_value_heads": 2,
|
| 57 |
+
"pad_token_id": null,
|
| 58 |
+
"partial_rotary_factor": 0.25,
|
| 59 |
+
"rms_norm_eps": 1e-06,
|
| 60 |
+
"rope_parameters": {
|
| 61 |
+
"mrope_interleaved": true,
|
| 62 |
+
"mrope_section": [
|
| 63 |
+
11,
|
| 64 |
+
11,
|
| 65 |
+
10
|
| 66 |
+
],
|
| 67 |
+
"partial_rotary_factor": 0.25,
|
| 68 |
+
"rope_theta": 10000000,
|
| 69 |
+
"type": "default"
|
| 70 |
+
},
|
| 71 |
+
"tie_word_embeddings": true,
|
| 72 |
+
"transformers_version": "5.17.0",
|
| 73 |
+
"use_cache": false,
|
| 74 |
+
"vocab_size": 248320
|
| 75 |
+
}
|
bf16/generation_config.json
ADDED
|
@@ -0,0 +1,6 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"_from_model_config": true,
|
| 3 |
+
"eos_token_id": 248044,
|
| 4 |
+
"transformers_version": "5.17.0",
|
| 5 |
+
"use_cache": true
|
| 6 |
+
}
|
bf16/macjev_norms_fp32.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:a30e1a72d02598b405978c0eff08c3bfca3b523fa0b3d4b4c80d2a185e0b8081
|
| 3 |
+
size 420112
|
bf16/model.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:00629c8d17ea115c21c3fc0d6ddc5d4aa02887343a8ff3b3cf79ab197624d574
|
| 3 |
+
size 3763691755
|
bf16/model.safetensors.index.json
ADDED
|
@@ -0,0 +1,328 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"metadata": {
|
| 3 |
+
"total_size": 3763650176,
|
| 4 |
+
"total_parameters": 1881824512
|
| 5 |
+
},
|
| 6 |
+
"weight_map": {
|
| 7 |
+
"language_model.model.embed_tokens.weight": "model.safetensors",
|
| 8 |
+
"language_model.model.layers.0.input_layernorm.weight": "model.safetensors",
|
| 9 |
+
"language_model.model.layers.0.linear_attn.A_log": "model.safetensors",
|
| 10 |
+
"language_model.model.layers.0.linear_attn.conv1d.weight": "model.safetensors",
|
| 11 |
+
"language_model.model.layers.0.linear_attn.dt_bias": "model.safetensors",
|
| 12 |
+
"language_model.model.layers.0.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 13 |
+
"language_model.model.layers.0.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 14 |
+
"language_model.model.layers.0.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 15 |
+
"language_model.model.layers.0.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 16 |
+
"language_model.model.layers.0.linear_attn.norm.weight": "model.safetensors",
|
| 17 |
+
"language_model.model.layers.0.linear_attn.out_proj.weight": "model.safetensors",
|
| 18 |
+
"language_model.model.layers.0.mlp.down_proj.weight": "model.safetensors",
|
| 19 |
+
"language_model.model.layers.0.mlp.gate_proj.weight": "model.safetensors",
|
| 20 |
+
"language_model.model.layers.0.mlp.up_proj.weight": "model.safetensors",
|
| 21 |
+
"language_model.model.layers.0.post_attention_layernorm.weight": "model.safetensors",
|
| 22 |
+
"language_model.model.layers.1.input_layernorm.weight": "model.safetensors",
|
| 23 |
+
"language_model.model.layers.1.linear_attn.A_log": "model.safetensors",
|
| 24 |
+
"language_model.model.layers.1.linear_attn.conv1d.weight": "model.safetensors",
|
| 25 |
+
"language_model.model.layers.1.linear_attn.dt_bias": "model.safetensors",
|
| 26 |
+
"language_model.model.layers.1.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 27 |
+
"language_model.model.layers.1.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 28 |
+
"language_model.model.layers.1.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 29 |
+
"language_model.model.layers.1.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 30 |
+
"language_model.model.layers.1.linear_attn.norm.weight": "model.safetensors",
|
| 31 |
+
"language_model.model.layers.1.linear_attn.out_proj.weight": "model.safetensors",
|
| 32 |
+
"language_model.model.layers.1.mlp.down_proj.weight": "model.safetensors",
|
| 33 |
+
"language_model.model.layers.1.mlp.gate_proj.weight": "model.safetensors",
|
| 34 |
+
"language_model.model.layers.1.mlp.up_proj.weight": "model.safetensors",
|
| 35 |
+
"language_model.model.layers.1.post_attention_layernorm.weight": "model.safetensors",
|
| 36 |
+
"language_model.model.layers.10.input_layernorm.weight": "model.safetensors",
|
| 37 |
+
"language_model.model.layers.10.linear_attn.A_log": "model.safetensors",
|
| 38 |
+
"language_model.model.layers.10.linear_attn.conv1d.weight": "model.safetensors",
|
| 39 |
+
"language_model.model.layers.10.linear_attn.dt_bias": "model.safetensors",
|
| 40 |
+
"language_model.model.layers.10.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 41 |
+
"language_model.model.layers.10.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 42 |
+
"language_model.model.layers.10.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 43 |
+
"language_model.model.layers.10.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 44 |
+
"language_model.model.layers.10.linear_attn.norm.weight": "model.safetensors",
|
| 45 |
+
"language_model.model.layers.10.linear_attn.out_proj.weight": "model.safetensors",
|
| 46 |
+
"language_model.model.layers.10.mlp.down_proj.weight": "model.safetensors",
|
| 47 |
+
"language_model.model.layers.10.mlp.gate_proj.weight": "model.safetensors",
|
| 48 |
+
"language_model.model.layers.10.mlp.up_proj.weight": "model.safetensors",
|
| 49 |
+
"language_model.model.layers.10.post_attention_layernorm.weight": "model.safetensors",
|
| 50 |
+
"language_model.model.layers.11.input_layernorm.weight": "model.safetensors",
|
| 51 |
+
"language_model.model.layers.11.mlp.down_proj.weight": "model.safetensors",
|
| 52 |
+
"language_model.model.layers.11.mlp.gate_proj.weight": "model.safetensors",
|
| 53 |
+
"language_model.model.layers.11.mlp.up_proj.weight": "model.safetensors",
|
| 54 |
+
"language_model.model.layers.11.post_attention_layernorm.weight": "model.safetensors",
|
| 55 |
+
"language_model.model.layers.11.self_attn.k_norm.weight": "model.safetensors",
|
| 56 |
+
"language_model.model.layers.11.self_attn.k_proj.weight": "model.safetensors",
|
| 57 |
+
"language_model.model.layers.11.self_attn.o_proj.weight": "model.safetensors",
|
| 58 |
+
"language_model.model.layers.11.self_attn.q_norm.weight": "model.safetensors",
|
| 59 |
+
"language_model.model.layers.11.self_attn.q_proj.weight": "model.safetensors",
|
| 60 |
+
"language_model.model.layers.11.self_attn.v_proj.weight": "model.safetensors",
|
| 61 |
+
"language_model.model.layers.12.input_layernorm.weight": "model.safetensors",
|
| 62 |
+
"language_model.model.layers.12.linear_attn.A_log": "model.safetensors",
|
| 63 |
+
"language_model.model.layers.12.linear_attn.conv1d.weight": "model.safetensors",
|
| 64 |
+
"language_model.model.layers.12.linear_attn.dt_bias": "model.safetensors",
|
| 65 |
+
"language_model.model.layers.12.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 66 |
+
"language_model.model.layers.12.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 67 |
+
"language_model.model.layers.12.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 68 |
+
"language_model.model.layers.12.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 69 |
+
"language_model.model.layers.12.linear_attn.norm.weight": "model.safetensors",
|
| 70 |
+
"language_model.model.layers.12.linear_attn.out_proj.weight": "model.safetensors",
|
| 71 |
+
"language_model.model.layers.12.mlp.down_proj.weight": "model.safetensors",
|
| 72 |
+
"language_model.model.layers.12.mlp.gate_proj.weight": "model.safetensors",
|
| 73 |
+
"language_model.model.layers.12.mlp.up_proj.weight": "model.safetensors",
|
| 74 |
+
"language_model.model.layers.12.post_attention_layernorm.weight": "model.safetensors",
|
| 75 |
+
"language_model.model.layers.13.input_layernorm.weight": "model.safetensors",
|
| 76 |
+
"language_model.model.layers.13.linear_attn.A_log": "model.safetensors",
|
| 77 |
+
"language_model.model.layers.13.linear_attn.conv1d.weight": "model.safetensors",
|
| 78 |
+
"language_model.model.layers.13.linear_attn.dt_bias": "model.safetensors",
|
| 79 |
+
"language_model.model.layers.13.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 80 |
+
"language_model.model.layers.13.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 81 |
+
"language_model.model.layers.13.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 82 |
+
"language_model.model.layers.13.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 83 |
+
"language_model.model.layers.13.linear_attn.norm.weight": "model.safetensors",
|
| 84 |
+
"language_model.model.layers.13.linear_attn.out_proj.weight": "model.safetensors",
|
| 85 |
+
"language_model.model.layers.13.mlp.down_proj.weight": "model.safetensors",
|
| 86 |
+
"language_model.model.layers.13.mlp.gate_proj.weight": "model.safetensors",
|
| 87 |
+
"language_model.model.layers.13.mlp.up_proj.weight": "model.safetensors",
|
| 88 |
+
"language_model.model.layers.13.post_attention_layernorm.weight": "model.safetensors",
|
| 89 |
+
"language_model.model.layers.14.input_layernorm.weight": "model.safetensors",
|
| 90 |
+
"language_model.model.layers.14.linear_attn.A_log": "model.safetensors",
|
| 91 |
+
"language_model.model.layers.14.linear_attn.conv1d.weight": "model.safetensors",
|
| 92 |
+
"language_model.model.layers.14.linear_attn.dt_bias": "model.safetensors",
|
| 93 |
+
"language_model.model.layers.14.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 94 |
+
"language_model.model.layers.14.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 95 |
+
"language_model.model.layers.14.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 96 |
+
"language_model.model.layers.14.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 97 |
+
"language_model.model.layers.14.linear_attn.norm.weight": "model.safetensors",
|
| 98 |
+
"language_model.model.layers.14.linear_attn.out_proj.weight": "model.safetensors",
|
| 99 |
+
"language_model.model.layers.14.mlp.down_proj.weight": "model.safetensors",
|
| 100 |
+
"language_model.model.layers.14.mlp.gate_proj.weight": "model.safetensors",
|
| 101 |
+
"language_model.model.layers.14.mlp.up_proj.weight": "model.safetensors",
|
| 102 |
+
"language_model.model.layers.14.post_attention_layernorm.weight": "model.safetensors",
|
| 103 |
+
"language_model.model.layers.15.input_layernorm.weight": "model.safetensors",
|
| 104 |
+
"language_model.model.layers.15.mlp.down_proj.weight": "model.safetensors",
|
| 105 |
+
"language_model.model.layers.15.mlp.gate_proj.weight": "model.safetensors",
|
| 106 |
+
"language_model.model.layers.15.mlp.up_proj.weight": "model.safetensors",
|
| 107 |
+
"language_model.model.layers.15.post_attention_layernorm.weight": "model.safetensors",
|
| 108 |
+
"language_model.model.layers.15.self_attn.k_norm.weight": "model.safetensors",
|
| 109 |
+
"language_model.model.layers.15.self_attn.k_proj.weight": "model.safetensors",
|
| 110 |
+
"language_model.model.layers.15.self_attn.o_proj.weight": "model.safetensors",
|
| 111 |
+
"language_model.model.layers.15.self_attn.q_norm.weight": "model.safetensors",
|
| 112 |
+
"language_model.model.layers.15.self_attn.q_proj.weight": "model.safetensors",
|
| 113 |
+
"language_model.model.layers.15.self_attn.v_proj.weight": "model.safetensors",
|
| 114 |
+
"language_model.model.layers.16.input_layernorm.weight": "model.safetensors",
|
| 115 |
+
"language_model.model.layers.16.linear_attn.A_log": "model.safetensors",
|
| 116 |
+
"language_model.model.layers.16.linear_attn.conv1d.weight": "model.safetensors",
|
| 117 |
+
"language_model.model.layers.16.linear_attn.dt_bias": "model.safetensors",
|
| 118 |
+
"language_model.model.layers.16.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 119 |
+
"language_model.model.layers.16.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 120 |
+
"language_model.model.layers.16.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 121 |
+
"language_model.model.layers.16.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 122 |
+
"language_model.model.layers.16.linear_attn.norm.weight": "model.safetensors",
|
| 123 |
+
"language_model.model.layers.16.linear_attn.out_proj.weight": "model.safetensors",
|
| 124 |
+
"language_model.model.layers.16.mlp.down_proj.weight": "model.safetensors",
|
| 125 |
+
"language_model.model.layers.16.mlp.gate_proj.weight": "model.safetensors",
|
| 126 |
+
"language_model.model.layers.16.mlp.up_proj.weight": "model.safetensors",
|
| 127 |
+
"language_model.model.layers.16.post_attention_layernorm.weight": "model.safetensors",
|
| 128 |
+
"language_model.model.layers.17.input_layernorm.weight": "model.safetensors",
|
| 129 |
+
"language_model.model.layers.17.linear_attn.A_log": "model.safetensors",
|
| 130 |
+
"language_model.model.layers.17.linear_attn.conv1d.weight": "model.safetensors",
|
| 131 |
+
"language_model.model.layers.17.linear_attn.dt_bias": "model.safetensors",
|
| 132 |
+
"language_model.model.layers.17.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 133 |
+
"language_model.model.layers.17.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 134 |
+
"language_model.model.layers.17.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 135 |
+
"language_model.model.layers.17.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 136 |
+
"language_model.model.layers.17.linear_attn.norm.weight": "model.safetensors",
|
| 137 |
+
"language_model.model.layers.17.linear_attn.out_proj.weight": "model.safetensors",
|
| 138 |
+
"language_model.model.layers.17.mlp.down_proj.weight": "model.safetensors",
|
| 139 |
+
"language_model.model.layers.17.mlp.gate_proj.weight": "model.safetensors",
|
| 140 |
+
"language_model.model.layers.17.mlp.up_proj.weight": "model.safetensors",
|
| 141 |
+
"language_model.model.layers.17.post_attention_layernorm.weight": "model.safetensors",
|
| 142 |
+
"language_model.model.layers.18.input_layernorm.weight": "model.safetensors",
|
| 143 |
+
"language_model.model.layers.18.linear_attn.A_log": "model.safetensors",
|
| 144 |
+
"language_model.model.layers.18.linear_attn.conv1d.weight": "model.safetensors",
|
| 145 |
+
"language_model.model.layers.18.linear_attn.dt_bias": "model.safetensors",
|
| 146 |
+
"language_model.model.layers.18.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 147 |
+
"language_model.model.layers.18.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 148 |
+
"language_model.model.layers.18.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 149 |
+
"language_model.model.layers.18.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 150 |
+
"language_model.model.layers.18.linear_attn.norm.weight": "model.safetensors",
|
| 151 |
+
"language_model.model.layers.18.linear_attn.out_proj.weight": "model.safetensors",
|
| 152 |
+
"language_model.model.layers.18.mlp.down_proj.weight": "model.safetensors",
|
| 153 |
+
"language_model.model.layers.18.mlp.gate_proj.weight": "model.safetensors",
|
| 154 |
+
"language_model.model.layers.18.mlp.up_proj.weight": "model.safetensors",
|
| 155 |
+
"language_model.model.layers.18.post_attention_layernorm.weight": "model.safetensors",
|
| 156 |
+
"language_model.model.layers.19.input_layernorm.weight": "model.safetensors",
|
| 157 |
+
"language_model.model.layers.19.mlp.down_proj.weight": "model.safetensors",
|
| 158 |
+
"language_model.model.layers.19.mlp.gate_proj.weight": "model.safetensors",
|
| 159 |
+
"language_model.model.layers.19.mlp.up_proj.weight": "model.safetensors",
|
| 160 |
+
"language_model.model.layers.19.post_attention_layernorm.weight": "model.safetensors",
|
| 161 |
+
"language_model.model.layers.19.self_attn.k_norm.weight": "model.safetensors",
|
| 162 |
+
"language_model.model.layers.19.self_attn.k_proj.weight": "model.safetensors",
|
| 163 |
+
"language_model.model.layers.19.self_attn.o_proj.weight": "model.safetensors",
|
| 164 |
+
"language_model.model.layers.19.self_attn.q_norm.weight": "model.safetensors",
|
| 165 |
+
"language_model.model.layers.19.self_attn.q_proj.weight": "model.safetensors",
|
| 166 |
+
"language_model.model.layers.19.self_attn.v_proj.weight": "model.safetensors",
|
| 167 |
+
"language_model.model.layers.2.input_layernorm.weight": "model.safetensors",
|
| 168 |
+
"language_model.model.layers.2.linear_attn.A_log": "model.safetensors",
|
| 169 |
+
"language_model.model.layers.2.linear_attn.conv1d.weight": "model.safetensors",
|
| 170 |
+
"language_model.model.layers.2.linear_attn.dt_bias": "model.safetensors",
|
| 171 |
+
"language_model.model.layers.2.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 172 |
+
"language_model.model.layers.2.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 173 |
+
"language_model.model.layers.2.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 174 |
+
"language_model.model.layers.2.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 175 |
+
"language_model.model.layers.2.linear_attn.norm.weight": "model.safetensors",
|
| 176 |
+
"language_model.model.layers.2.linear_attn.out_proj.weight": "model.safetensors",
|
| 177 |
+
"language_model.model.layers.2.mlp.down_proj.weight": "model.safetensors",
|
| 178 |
+
"language_model.model.layers.2.mlp.gate_proj.weight": "model.safetensors",
|
| 179 |
+
"language_model.model.layers.2.mlp.up_proj.weight": "model.safetensors",
|
| 180 |
+
"language_model.model.layers.2.post_attention_layernorm.weight": "model.safetensors",
|
| 181 |
+
"language_model.model.layers.20.input_layernorm.weight": "model.safetensors",
|
| 182 |
+
"language_model.model.layers.20.linear_attn.A_log": "model.safetensors",
|
| 183 |
+
"language_model.model.layers.20.linear_attn.conv1d.weight": "model.safetensors",
|
| 184 |
+
"language_model.model.layers.20.linear_attn.dt_bias": "model.safetensors",
|
| 185 |
+
"language_model.model.layers.20.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 186 |
+
"language_model.model.layers.20.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 187 |
+
"language_model.model.layers.20.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 188 |
+
"language_model.model.layers.20.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 189 |
+
"language_model.model.layers.20.linear_attn.norm.weight": "model.safetensors",
|
| 190 |
+
"language_model.model.layers.20.linear_attn.out_proj.weight": "model.safetensors",
|
| 191 |
+
"language_model.model.layers.20.mlp.down_proj.weight": "model.safetensors",
|
| 192 |
+
"language_model.model.layers.20.mlp.gate_proj.weight": "model.safetensors",
|
| 193 |
+
"language_model.model.layers.20.mlp.up_proj.weight": "model.safetensors",
|
| 194 |
+
"language_model.model.layers.20.post_attention_layernorm.weight": "model.safetensors",
|
| 195 |
+
"language_model.model.layers.21.input_layernorm.weight": "model.safetensors",
|
| 196 |
+
"language_model.model.layers.21.linear_attn.A_log": "model.safetensors",
|
| 197 |
+
"language_model.model.layers.21.linear_attn.conv1d.weight": "model.safetensors",
|
| 198 |
+
"language_model.model.layers.21.linear_attn.dt_bias": "model.safetensors",
|
| 199 |
+
"language_model.model.layers.21.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 200 |
+
"language_model.model.layers.21.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 201 |
+
"language_model.model.layers.21.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 202 |
+
"language_model.model.layers.21.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 203 |
+
"language_model.model.layers.21.linear_attn.norm.weight": "model.safetensors",
|
| 204 |
+
"language_model.model.layers.21.linear_attn.out_proj.weight": "model.safetensors",
|
| 205 |
+
"language_model.model.layers.21.mlp.down_proj.weight": "model.safetensors",
|
| 206 |
+
"language_model.model.layers.21.mlp.gate_proj.weight": "model.safetensors",
|
| 207 |
+
"language_model.model.layers.21.mlp.up_proj.weight": "model.safetensors",
|
| 208 |
+
"language_model.model.layers.21.post_attention_layernorm.weight": "model.safetensors",
|
| 209 |
+
"language_model.model.layers.22.input_layernorm.weight": "model.safetensors",
|
| 210 |
+
"language_model.model.layers.22.linear_attn.A_log": "model.safetensors",
|
| 211 |
+
"language_model.model.layers.22.linear_attn.conv1d.weight": "model.safetensors",
|
| 212 |
+
"language_model.model.layers.22.linear_attn.dt_bias": "model.safetensors",
|
| 213 |
+
"language_model.model.layers.22.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 214 |
+
"language_model.model.layers.22.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 215 |
+
"language_model.model.layers.22.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 216 |
+
"language_model.model.layers.22.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 217 |
+
"language_model.model.layers.22.linear_attn.norm.weight": "model.safetensors",
|
| 218 |
+
"language_model.model.layers.22.linear_attn.out_proj.weight": "model.safetensors",
|
| 219 |
+
"language_model.model.layers.22.mlp.down_proj.weight": "model.safetensors",
|
| 220 |
+
"language_model.model.layers.22.mlp.gate_proj.weight": "model.safetensors",
|
| 221 |
+
"language_model.model.layers.22.mlp.up_proj.weight": "model.safetensors",
|
| 222 |
+
"language_model.model.layers.22.post_attention_layernorm.weight": "model.safetensors",
|
| 223 |
+
"language_model.model.layers.23.input_layernorm.weight": "model.safetensors",
|
| 224 |
+
"language_model.model.layers.23.mlp.down_proj.weight": "model.safetensors",
|
| 225 |
+
"language_model.model.layers.23.mlp.gate_proj.weight": "model.safetensors",
|
| 226 |
+
"language_model.model.layers.23.mlp.up_proj.weight": "model.safetensors",
|
| 227 |
+
"language_model.model.layers.23.post_attention_layernorm.weight": "model.safetensors",
|
| 228 |
+
"language_model.model.layers.23.self_attn.k_norm.weight": "model.safetensors",
|
| 229 |
+
"language_model.model.layers.23.self_attn.k_proj.weight": "model.safetensors",
|
| 230 |
+
"language_model.model.layers.23.self_attn.o_proj.weight": "model.safetensors",
|
| 231 |
+
"language_model.model.layers.23.self_attn.q_norm.weight": "model.safetensors",
|
| 232 |
+
"language_model.model.layers.23.self_attn.q_proj.weight": "model.safetensors",
|
| 233 |
+
"language_model.model.layers.23.self_attn.v_proj.weight": "model.safetensors",
|
| 234 |
+
"language_model.model.layers.3.input_layernorm.weight": "model.safetensors",
|
| 235 |
+
"language_model.model.layers.3.mlp.down_proj.weight": "model.safetensors",
|
| 236 |
+
"language_model.model.layers.3.mlp.gate_proj.weight": "model.safetensors",
|
| 237 |
+
"language_model.model.layers.3.mlp.up_proj.weight": "model.safetensors",
|
| 238 |
+
"language_model.model.layers.3.post_attention_layernorm.weight": "model.safetensors",
|
| 239 |
+
"language_model.model.layers.3.self_attn.k_norm.weight": "model.safetensors",
|
| 240 |
+
"language_model.model.layers.3.self_attn.k_proj.weight": "model.safetensors",
|
| 241 |
+
"language_model.model.layers.3.self_attn.o_proj.weight": "model.safetensors",
|
| 242 |
+
"language_model.model.layers.3.self_attn.q_norm.weight": "model.safetensors",
|
| 243 |
+
"language_model.model.layers.3.self_attn.q_proj.weight": "model.safetensors",
|
| 244 |
+
"language_model.model.layers.3.self_attn.v_proj.weight": "model.safetensors",
|
| 245 |
+
"language_model.model.layers.4.input_layernorm.weight": "model.safetensors",
|
| 246 |
+
"language_model.model.layers.4.linear_attn.A_log": "model.safetensors",
|
| 247 |
+
"language_model.model.layers.4.linear_attn.conv1d.weight": "model.safetensors",
|
| 248 |
+
"language_model.model.layers.4.linear_attn.dt_bias": "model.safetensors",
|
| 249 |
+
"language_model.model.layers.4.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 250 |
+
"language_model.model.layers.4.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 251 |
+
"language_model.model.layers.4.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 252 |
+
"language_model.model.layers.4.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 253 |
+
"language_model.model.layers.4.linear_attn.norm.weight": "model.safetensors",
|
| 254 |
+
"language_model.model.layers.4.linear_attn.out_proj.weight": "model.safetensors",
|
| 255 |
+
"language_model.model.layers.4.mlp.down_proj.weight": "model.safetensors",
|
| 256 |
+
"language_model.model.layers.4.mlp.gate_proj.weight": "model.safetensors",
|
| 257 |
+
"language_model.model.layers.4.mlp.up_proj.weight": "model.safetensors",
|
| 258 |
+
"language_model.model.layers.4.post_attention_layernorm.weight": "model.safetensors",
|
| 259 |
+
"language_model.model.layers.5.input_layernorm.weight": "model.safetensors",
|
| 260 |
+
"language_model.model.layers.5.linear_attn.A_log": "model.safetensors",
|
| 261 |
+
"language_model.model.layers.5.linear_attn.conv1d.weight": "model.safetensors",
|
| 262 |
+
"language_model.model.layers.5.linear_attn.dt_bias": "model.safetensors",
|
| 263 |
+
"language_model.model.layers.5.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 264 |
+
"language_model.model.layers.5.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 265 |
+
"language_model.model.layers.5.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 266 |
+
"language_model.model.layers.5.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 267 |
+
"language_model.model.layers.5.linear_attn.norm.weight": "model.safetensors",
|
| 268 |
+
"language_model.model.layers.5.linear_attn.out_proj.weight": "model.safetensors",
|
| 269 |
+
"language_model.model.layers.5.mlp.down_proj.weight": "model.safetensors",
|
| 270 |
+
"language_model.model.layers.5.mlp.gate_proj.weight": "model.safetensors",
|
| 271 |
+
"language_model.model.layers.5.mlp.up_proj.weight": "model.safetensors",
|
| 272 |
+
"language_model.model.layers.5.post_attention_layernorm.weight": "model.safetensors",
|
| 273 |
+
"language_model.model.layers.6.input_layernorm.weight": "model.safetensors",
|
| 274 |
+
"language_model.model.layers.6.linear_attn.A_log": "model.safetensors",
|
| 275 |
+
"language_model.model.layers.6.linear_attn.conv1d.weight": "model.safetensors",
|
| 276 |
+
"language_model.model.layers.6.linear_attn.dt_bias": "model.safetensors",
|
| 277 |
+
"language_model.model.layers.6.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 278 |
+
"language_model.model.layers.6.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 279 |
+
"language_model.model.layers.6.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 280 |
+
"language_model.model.layers.6.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 281 |
+
"language_model.model.layers.6.linear_attn.norm.weight": "model.safetensors",
|
| 282 |
+
"language_model.model.layers.6.linear_attn.out_proj.weight": "model.safetensors",
|
| 283 |
+
"language_model.model.layers.6.mlp.down_proj.weight": "model.safetensors",
|
| 284 |
+
"language_model.model.layers.6.mlp.gate_proj.weight": "model.safetensors",
|
| 285 |
+
"language_model.model.layers.6.mlp.up_proj.weight": "model.safetensors",
|
| 286 |
+
"language_model.model.layers.6.post_attention_layernorm.weight": "model.safetensors",
|
| 287 |
+
"language_model.model.layers.7.input_layernorm.weight": "model.safetensors",
|
| 288 |
+
"language_model.model.layers.7.mlp.down_proj.weight": "model.safetensors",
|
| 289 |
+
"language_model.model.layers.7.mlp.gate_proj.weight": "model.safetensors",
|
| 290 |
+
"language_model.model.layers.7.mlp.up_proj.weight": "model.safetensors",
|
| 291 |
+
"language_model.model.layers.7.post_attention_layernorm.weight": "model.safetensors",
|
| 292 |
+
"language_model.model.layers.7.self_attn.k_norm.weight": "model.safetensors",
|
| 293 |
+
"language_model.model.layers.7.self_attn.k_proj.weight": "model.safetensors",
|
| 294 |
+
"language_model.model.layers.7.self_attn.o_proj.weight": "model.safetensors",
|
| 295 |
+
"language_model.model.layers.7.self_attn.q_norm.weight": "model.safetensors",
|
| 296 |
+
"language_model.model.layers.7.self_attn.q_proj.weight": "model.safetensors",
|
| 297 |
+
"language_model.model.layers.7.self_attn.v_proj.weight": "model.safetensors",
|
| 298 |
+
"language_model.model.layers.8.input_layernorm.weight": "model.safetensors",
|
| 299 |
+
"language_model.model.layers.8.linear_attn.A_log": "model.safetensors",
|
| 300 |
+
"language_model.model.layers.8.linear_attn.conv1d.weight": "model.safetensors",
|
| 301 |
+
"language_model.model.layers.8.linear_attn.dt_bias": "model.safetensors",
|
| 302 |
+
"language_model.model.layers.8.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 303 |
+
"language_model.model.layers.8.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 304 |
+
"language_model.model.layers.8.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 305 |
+
"language_model.model.layers.8.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 306 |
+
"language_model.model.layers.8.linear_attn.norm.weight": "model.safetensors",
|
| 307 |
+
"language_model.model.layers.8.linear_attn.out_proj.weight": "model.safetensors",
|
| 308 |
+
"language_model.model.layers.8.mlp.down_proj.weight": "model.safetensors",
|
| 309 |
+
"language_model.model.layers.8.mlp.gate_proj.weight": "model.safetensors",
|
| 310 |
+
"language_model.model.layers.8.mlp.up_proj.weight": "model.safetensors",
|
| 311 |
+
"language_model.model.layers.8.post_attention_layernorm.weight": "model.safetensors",
|
| 312 |
+
"language_model.model.layers.9.input_layernorm.weight": "model.safetensors",
|
| 313 |
+
"language_model.model.layers.9.linear_attn.A_log": "model.safetensors",
|
| 314 |
+
"language_model.model.layers.9.linear_attn.conv1d.weight": "model.safetensors",
|
| 315 |
+
"language_model.model.layers.9.linear_attn.dt_bias": "model.safetensors",
|
| 316 |
+
"language_model.model.layers.9.linear_attn.in_proj_a.weight": "model.safetensors",
|
| 317 |
+
"language_model.model.layers.9.linear_attn.in_proj_b.weight": "model.safetensors",
|
| 318 |
+
"language_model.model.layers.9.linear_attn.in_proj_qkv.weight": "model.safetensors",
|
| 319 |
+
"language_model.model.layers.9.linear_attn.in_proj_z.weight": "model.safetensors",
|
| 320 |
+
"language_model.model.layers.9.linear_attn.norm.weight": "model.safetensors",
|
| 321 |
+
"language_model.model.layers.9.linear_attn.out_proj.weight": "model.safetensors",
|
| 322 |
+
"language_model.model.layers.9.mlp.down_proj.weight": "model.safetensors",
|
| 323 |
+
"language_model.model.layers.9.mlp.gate_proj.weight": "model.safetensors",
|
| 324 |
+
"language_model.model.layers.9.mlp.up_proj.weight": "model.safetensors",
|
| 325 |
+
"language_model.model.layers.9.post_attention_layernorm.weight": "model.safetensors",
|
| 326 |
+
"language_model.model.norm.weight": "model.safetensors"
|
| 327 |
+
}
|
| 328 |
+
}
|
bf16/tokenizer.json
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:06b9509352d2af50381ab2247e083b80d32d5c0aba91c272ca9ff729b6a0e523
|
| 3 |
+
size 19989325
|
bf16/tokenizer_config.json
ADDED
|
@@ -0,0 +1,33 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"add_prefix_space": false,
|
| 3 |
+
"audio_bos_token": "<|audio_start|>",
|
| 4 |
+
"audio_eos_token": "<|audio_end|>",
|
| 5 |
+
"audio_token": "<|audio_pad|>",
|
| 6 |
+
"backend": "tokenizers",
|
| 7 |
+
"bos_token": null,
|
| 8 |
+
"clean_up_tokenization_spaces": false,
|
| 9 |
+
"eos_token": "<|im_end|>",
|
| 10 |
+
"errors": "replace",
|
| 11 |
+
"image_token": "<|image_pad|>",
|
| 12 |
+
"is_local": true,
|
| 13 |
+
"local_files_only": false,
|
| 14 |
+
"model_max_length": 262144,
|
| 15 |
+
"model_specific_special_tokens": {
|
| 16 |
+
"audio_bos_token": "<|audio_start|>",
|
| 17 |
+
"audio_eos_token": "<|audio_end|>",
|
| 18 |
+
"audio_token": "<|audio_pad|>",
|
| 19 |
+
"image_token": "<|image_pad|>",
|
| 20 |
+
"video_token": "<|video_pad|>",
|
| 21 |
+
"vision_bos_token": "<|vision_start|>",
|
| 22 |
+
"vision_eos_token": "<|vision_end|>"
|
| 23 |
+
},
|
| 24 |
+
"pad_token": "<|endoftext|>",
|
| 25 |
+
"pretokenize_regex": "(?i:'s|'t|'re|'ve|'m|'ll|'d)|[^\\r\\n\\p{L}\\p{N}]?[\\p{L}\\p{M}]+|\\p{N}| ?[^\\s\\p{L}\\p{M}\\p{N}]+[\\r\\n]*|\\s*[\\r\\n]+|\\s+(?!\\S)|\\s+",
|
| 26 |
+
"split_special_tokens": false,
|
| 27 |
+
"tokenizer_class": "Qwen2Tokenizer",
|
| 28 |
+
"tool_parser_type": "qwen3_coder",
|
| 29 |
+
"unk_token": null,
|
| 30 |
+
"video_token": "<|video_pad|>",
|
| 31 |
+
"vision_bos_token": "<|vision_start|>",
|
| 32 |
+
"vision_eos_token": "<|vision_end|>"
|
| 33 |
+
}
|
config.json
ADDED
|
@@ -0,0 +1,75 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"architectures": [
|
| 3 |
+
"Qwen3_5ForCausalLM"
|
| 4 |
+
],
|
| 5 |
+
"attention_bias": false,
|
| 6 |
+
"attention_dropout": 0.0,
|
| 7 |
+
"attn_output_gate": true,
|
| 8 |
+
"bos_token_id": null,
|
| 9 |
+
"dtype": "bfloat16",
|
| 10 |
+
"eos_token_id": 248044,
|
| 11 |
+
"full_attention_interval": 4,
|
| 12 |
+
"head_dim": 256,
|
| 13 |
+
"hidden_act": "silu",
|
| 14 |
+
"hidden_size": 2048,
|
| 15 |
+
"initializer_range": 0.02,
|
| 16 |
+
"intermediate_size": 6144,
|
| 17 |
+
"layer_types": [
|
| 18 |
+
"linear_attention",
|
| 19 |
+
"linear_attention",
|
| 20 |
+
"linear_attention",
|
| 21 |
+
"full_attention",
|
| 22 |
+
"linear_attention",
|
| 23 |
+
"linear_attention",
|
| 24 |
+
"linear_attention",
|
| 25 |
+
"full_attention",
|
| 26 |
+
"linear_attention",
|
| 27 |
+
"linear_attention",
|
| 28 |
+
"linear_attention",
|
| 29 |
+
"full_attention",
|
| 30 |
+
"linear_attention",
|
| 31 |
+
"linear_attention",
|
| 32 |
+
"linear_attention",
|
| 33 |
+
"full_attention",
|
| 34 |
+
"linear_attention",
|
| 35 |
+
"linear_attention",
|
| 36 |
+
"linear_attention",
|
| 37 |
+
"full_attention",
|
| 38 |
+
"linear_attention",
|
| 39 |
+
"linear_attention",
|
| 40 |
+
"linear_attention",
|
| 41 |
+
"full_attention"
|
| 42 |
+
],
|
| 43 |
+
"linear_conv_kernel_dim": 4,
|
| 44 |
+
"linear_key_head_dim": 128,
|
| 45 |
+
"linear_num_key_heads": 16,
|
| 46 |
+
"linear_num_value_heads": 16,
|
| 47 |
+
"linear_value_head_dim": 128,
|
| 48 |
+
"mamba_ssm_dtype": "float32",
|
| 49 |
+
"max_position_embeddings": 262144,
|
| 50 |
+
"mlp_only_layers": [],
|
| 51 |
+
"model_type": "qwen3_5",
|
| 52 |
+
"mtp_num_hidden_layers": 1,
|
| 53 |
+
"mtp_use_dedicated_embeddings": false,
|
| 54 |
+
"num_attention_heads": 8,
|
| 55 |
+
"num_hidden_layers": 24,
|
| 56 |
+
"num_key_value_heads": 2,
|
| 57 |
+
"pad_token_id": null,
|
| 58 |
+
"partial_rotary_factor": 0.25,
|
| 59 |
+
"rms_norm_eps": 1e-06,
|
| 60 |
+
"rope_parameters": {
|
| 61 |
+
"mrope_interleaved": true,
|
| 62 |
+
"mrope_section": [
|
| 63 |
+
11,
|
| 64 |
+
11,
|
| 65 |
+
10
|
| 66 |
+
],
|
| 67 |
+
"partial_rotary_factor": 0.25,
|
| 68 |
+
"rope_theta": 10000000,
|
| 69 |
+
"type": "default"
|
| 70 |
+
},
|
| 71 |
+
"tie_word_embeddings": true,
|
| 72 |
+
"transformers_version": "5.17.0",
|
| 73 |
+
"use_cache": false,
|
| 74 |
+
"vocab_size": 248320
|
| 75 |
+
}
|
figures/banner.data.json
ADDED
|
@@ -0,0 +1,44 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"left": {
|
| 3 |
+
"big": "73.6% on JevBench",
|
| 4 |
+
"sub": "+9.5 points over our 0.8B v3; Jev 86.6%",
|
| 5 |
+
"tokens": "25,600 tokens per call, no option cap"
|
| 6 |
+
},
|
| 7 |
+
"rows": [
|
| 8 |
+
{
|
| 9 |
+
"label": "Jev 1.13 (API)",
|
| 10 |
+
"accuracy": 0.8658008658008658,
|
| 11 |
+
"pct_1dp": 86.6
|
| 12 |
+
},
|
| 13 |
+
{
|
| 14 |
+
"label": "2B v3 \u00b7 this model",
|
| 15 |
+
"accuracy": 0.7359307359307359,
|
| 16 |
+
"pct_1dp": 73.6
|
| 17 |
+
},
|
| 18 |
+
{
|
| 19 |
+
"label": "decider-2b",
|
| 20 |
+
"accuracy": 0.70995670995671,
|
| 21 |
+
"pct_1dp": 71.0
|
| 22 |
+
},
|
| 23 |
+
{
|
| 24 |
+
"label": "Open-Jev 2B",
|
| 25 |
+
"accuracy": 0.645021645021645,
|
| 26 |
+
"pct_1dp": 64.5
|
| 27 |
+
},
|
| 28 |
+
{
|
| 29 |
+
"label": "0.8B v3",
|
| 30 |
+
"accuracy": 0.6406926406926406,
|
| 31 |
+
"pct_1dp": 64.1
|
| 32 |
+
},
|
| 33 |
+
{
|
| 34 |
+
"label": "Laya",
|
| 35 |
+
"accuracy": 0.5844155844155844,
|
| 36 |
+
"pct_1dp": 58.4
|
| 37 |
+
}
|
| 38 |
+
],
|
| 39 |
+
"shown": "Shown: Qwen3.5-2B-family systems, our 0.8B v3, Laya and Jev \u00b7 42 of 82 board systems score higher than 73.6%",
|
| 40 |
+
"note": "231 public items. 2B v3: self-run with the official harness (GGUF F16), not an official board entry; 95% CI 67.6\u201378.9%, so the lead over decider-2b is inside the CI. Other rows as published on the v1.4.1 board.",
|
| 41 |
+
"sources": [
|
| 42 |
+
"figures/jevbench.data.json"
|
| 43 |
+
]
|
| 44 |
+
}
|
figures/banner.png
ADDED

|
Git LFS Details
|
figures/jevbench.data.json
ADDED
|
@@ -0,0 +1,49 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"chart": "jevbench",
|
| 3 |
+
"metric": "JevBench v1.4.1 public accuracy (231 items)",
|
| 4 |
+
"rows": [
|
| 5 |
+
{
|
| 6 |
+
"label": "Jev-Style 2B v3 (this model)",
|
| 7 |
+
"accuracy": 0.7359307359307359,
|
| 8 |
+
"accuracy_pct_1dp": 73.6,
|
| 9 |
+
"source": "https://huggingface.co/chaoliangUNSW/Jev-Style-2B-Decision-v3/blob/main/validation/benchmarks/jevbench_v1.4.1_results.json :: public_accuracy (170/231)"
|
| 10 |
+
},
|
| 11 |
+
{
|
| 12 |
+
"label": "decider-2b (Mapika, Qwen3.5-2B-Base)",
|
| 13 |
+
"accuracy": 0.70995670995671,
|
| 14 |
+
"accuracy_pct_1dp": 71.0,
|
| 15 |
+
"source": "https://github.com/fstandhartinger/jevbench/blob/v1.4.1/results/v1.4.1/jevbench-v1.4.1-results.json :: systems[decider-2b]"
|
| 16 |
+
},
|
| 17 |
+
{
|
| 18 |
+
"label": "Open-Jev 2B (Zefan Cai, Qwen3.5-2B + LoRA)",
|
| 19 |
+
"accuracy": 0.645021645021645,
|
| 20 |
+
"accuracy_pct_1dp": 64.5,
|
| 21 |
+
"source": "https://github.com/fstandhartinger/jevbench/blob/v1.4.1/results/v1.4.1/jevbench-v1.4.1-results.json :: systems[open-jev-zefan-2b]"
|
| 22 |
+
},
|
| 23 |
+
{
|
| 24 |
+
"label": "Jev-Style 0.8B v3",
|
| 25 |
+
"accuracy": 0.6406926406926406,
|
| 26 |
+
"accuracy_pct_1dp": 64.1,
|
| 27 |
+
"source": "https://huggingface.co/chaoliangUNSW/Jev-Style-0.8B-Decision-v3/blob/main/figures/jevbench.data.json (0.8B v3 card; row Jev-Style 0.8B v3, 148/231)"
|
| 28 |
+
},
|
| 29 |
+
{
|
| 30 |
+
"label": "Laya (ModernBERT-large, 421M)",
|
| 31 |
+
"accuracy": 0.5844155844155844,
|
| 32 |
+
"accuracy_pct_1dp": 58.4,
|
| 33 |
+
"source": "https://github.com/fstandhartinger/jevbench/blob/v1.4.1/results/v1.4.1/jevbench-v1.4.1-results.json :: systems[laya]"
|
| 34 |
+
}
|
| 35 |
+
],
|
| 36 |
+
"reference_line": {
|
| 37 |
+
"label": "Jev 1.13.0",
|
| 38 |
+
"accuracy": 0.8658008658008658,
|
| 39 |
+
"source": "https://github.com/fstandhartinger/jevbench/blob/v1.4.1/results/v1.4.1/jevbench-v1.4.1-results.json :: systems[jev-1.13.0]"
|
| 40 |
+
},
|
| 41 |
+
"ci95_wilson_2b": [
|
| 42 |
+
0.6755578394149232,
|
| 43 |
+
0.7885850787366094
|
| 44 |
+
],
|
| 45 |
+
"board_systems_higher_than_2b": 42,
|
| 46 |
+
"board_systems": 82,
|
| 47 |
+
"board_sha256": "e6754863056503fe2b010410fc7111df884ac1f9ce4449aa369aab61d98092cd",
|
| 48 |
+
"footnote": "JevBench v1.4.1, 231 public items. 2B v3: self-run once with the official harness (commit 24b9b5c), GGUF F16 engine, one global temperature, not an official board entry; 95% CI 67.6-78.9% (Wilson), so its lead over decider-2b (164/231) is inside the CI; training-pool contamination scan: 0 hits. Other rows: public accuracy as published in the board's v1.4.1 results file. Shown: the Qwen3.5-2B-family systems on the board, our 0.8B v3, Laya and Jev; 42 of the 82 board systems score higher than 73.6%."
|
| 49 |
+
}
|
figures/jevbench.png
ADDED
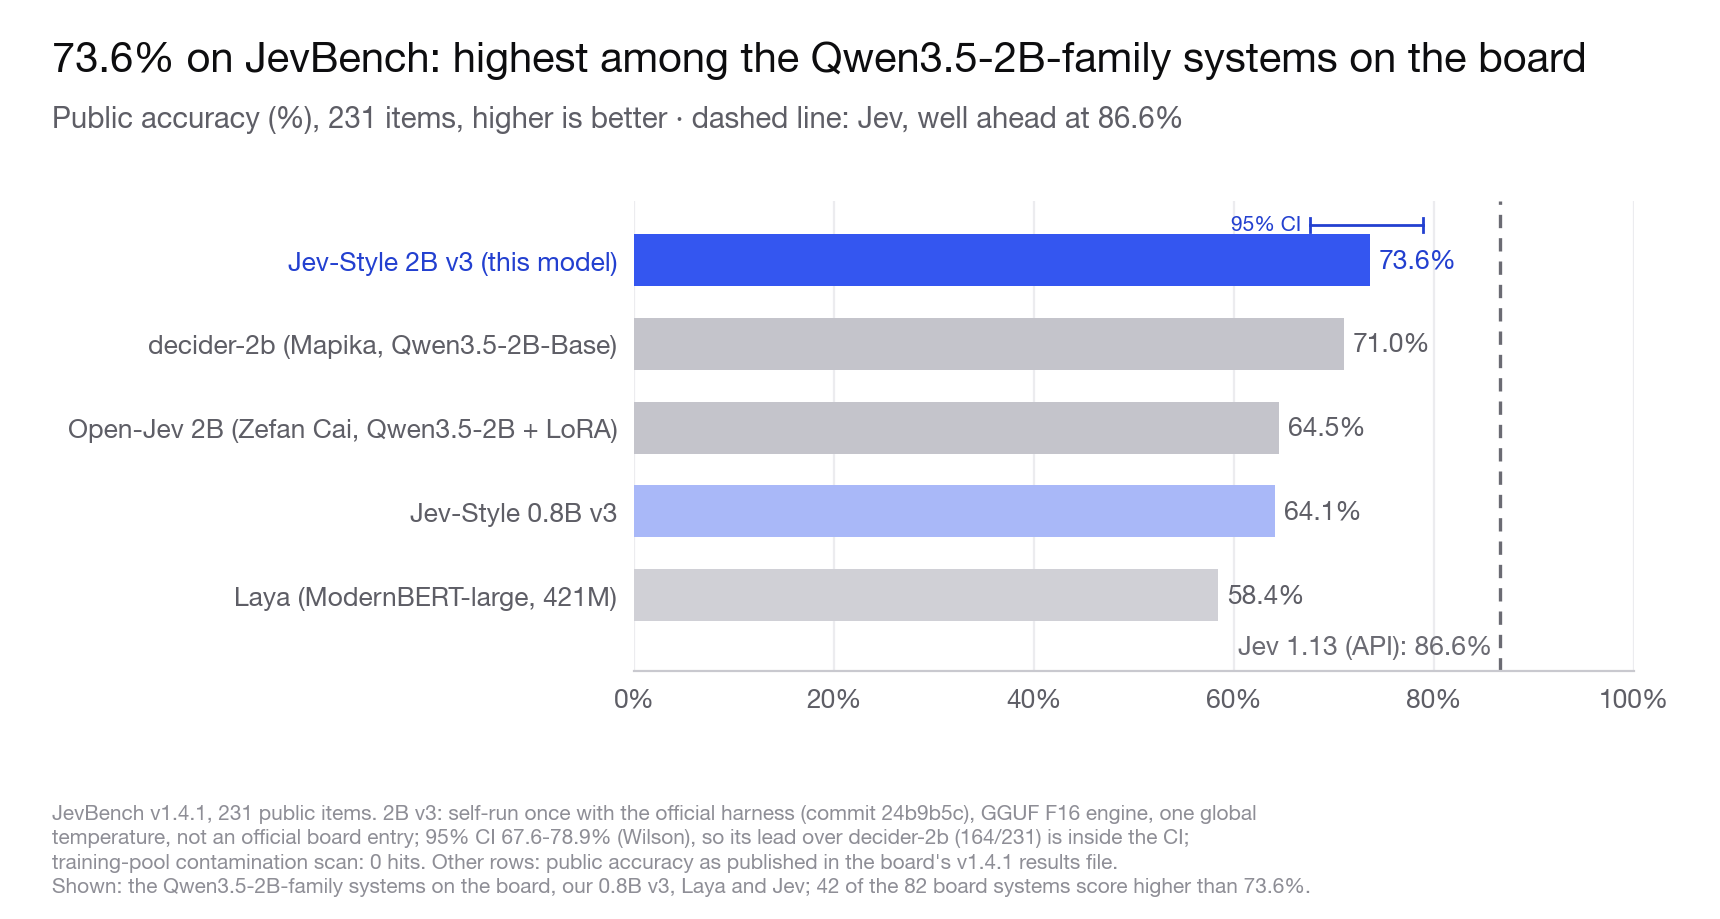
|
Git LFS Details
|
figures/jevbench.svg
ADDED
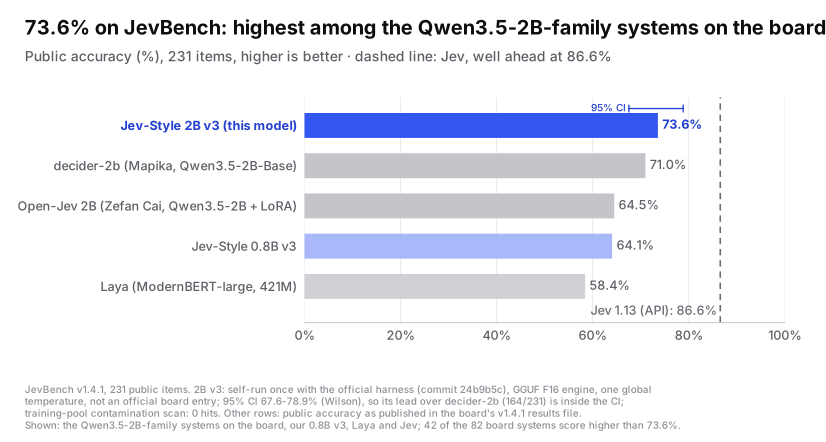
|
figures/zeroshot.data.json
ADDED
|
@@ -0,0 +1,40 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"chart": "zeroshot",
|
| 3 |
+
"metric": "accuracy over every row of the pinned test files",
|
| 4 |
+
"values": {
|
| 5 |
+
"tweet_topic": {
|
| 6 |
+
"2b": 0.822209096278795,
|
| 7 |
+
"2b_ci95": [
|
| 8 |
+
0.8038984051978736,
|
| 9 |
+
0.8399438865918486
|
| 10 |
+
],
|
| 11 |
+
"2b_macro_f1": 0.677897069437572,
|
| 12 |
+
"2b_ece15": 0.027919883880813873,
|
| 13 |
+
"08b": 0.754873006497342,
|
| 14 |
+
"jev": 0.7932663910218547,
|
| 15 |
+
"jev_macro_f1": 0.6936,
|
| 16 |
+
"jev_ece15": 0.0631,
|
| 17 |
+
"n": 1693
|
| 18 |
+
},
|
| 19 |
+
"fin_topic": {
|
| 20 |
+
"2b": 0.6111246052951178,
|
| 21 |
+
"2b_ci95": [
|
| 22 |
+
0.5960650959436483,
|
| 23 |
+
0.6259412193344669
|
| 24 |
+
],
|
| 25 |
+
"2b_macro_f1": 0.5897964463354406,
|
| 26 |
+
"2b_ece15": 0.06460657860002232,
|
| 27 |
+
"08b": 0.4670876852076755,
|
| 28 |
+
"jev": 0.669905270828273,
|
| 29 |
+
"jev_macro_f1": 0.6298,
|
| 30 |
+
"jev_ece15": 0.1664,
|
| 31 |
+
"n": 4117
|
| 32 |
+
}
|
| 33 |
+
},
|
| 34 |
+
"sources": {
|
| 35 |
+
"2b": "https://huggingface.co/chaoliangUNSW/Jev-Style-2B-Decision-v3/blob/main/validation/benchmarks/zeroshot_metrics.json",
|
| 36 |
+
"0.8b": "https://huggingface.co/chaoliangUNSW/Jev-Style-0.8B-Decision-v3/blob/main/figures/zeroshot.json (0.8B v3 card; v3_recomputed: tweet_topic 1278/1693, fin_topic 1923/4117)",
|
| 37 |
+
"jev": "https://github.com/elcronos/jev-vs-open-decision-models/blob/a1901bc3d520e73936de8d4326545c0cdcf742fb/results/cross_dataset_summary.json (as copied in https://huggingface.co/chaoliangUNSW/Jev-Style-2B-Decision-v3/blob/main/validation/benchmarks/zeroshot_metrics.json :: comparison)"
|
| 38 |
+
},
|
| 39 |
+
"footnote": "Zero-shot: none of these test sets is in the 2B or 0.8B training pool; accuracy over every row of the pinned test files (n = 1,693 and 4,117). 2B v3: GGUF F16 engine, one global temperature, run once; tweet_topic 95% CI 80.4-84.0%. Jev (1.13, API): numbers published by the elcronos jev-vs-open-decision-models study (cross_dataset_summary.json @ a1901bc), not re-run by us. Macro-F1 is below Jev on both sets (tweet_topic 67.8% vs 69.4%; fin_topic 59.0% vs 63.0%)."
|
| 40 |
+
}
|
figures/zeroshot.png
ADDED

|
Git LFS Details
|
figures/zeroshot.svg
ADDED

|
jev_style_decision_mlx.py
ADDED
|
@@ -0,0 +1,1059 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Jev-Style-2B-Decision-v3: typed decisions with MLX on Apple silicon (bf16 / 8-bit, --precision).
|
| 2 |
+
|
| 3 |
+
Self-contained runtime for chaoliangUNSW/Jev-Style-2B-Decision-v3 (Apache-2.0). No dependency on any training
|
| 4 |
+
code: rendering (protocol "macjev-render-v2-long-options"), block-causal attention, the verdict readout and
|
| 5 |
+
calibration are implemented below and reproduce the reference implementation used for evaluation (see
|
| 6 |
+
release_config.json -> "runtime_parity"). Needs mlx, mlx-lm==0.31.3 (pinned, see the MLX backend section),
|
| 7 |
+
tokenizers and numpy.
|
| 8 |
+
|
| 9 |
+
Calibration: probabilities use the ONE global temperature of readout_config.json (temperatures.global);
|
| 10 |
+
temperature=... (CLI --temperature, JSONL "temperature") overrides it (1.0 = uncalibrated scores). Unlike the
|
| 11 |
+
0.8B v3 runtime there is no --category (no group temperatures) and no --head-max (no question/options cap:
|
| 12 |
+
only the 25,600-token total budget applies).
|
| 13 |
+
|
| 14 |
+
Python:
|
| 15 |
+
from jev_style_decision_mlx import JevStyleDecisionMLX
|
| 16 |
+
m = JevStyleDecisionMLX(".", precision="bf16") # or "8bit"
|
| 17 |
+
m.decide("<state>", "Which action?", options={"click": "press it", "wait": None})
|
| 18 |
+
m.score_many("<state>", [q1, q2, ...]) # state computed once, reused for every question
|
| 19 |
+
"""
|
| 20 |
+
# ----------------------------------------------------------------------------------------------
|
| 21 |
+
# Shared core (byte-identical in jev_style_decision.py, jev_style_decision_gguf.py and jev_style_decision_mlx.py):
|
| 22 |
+
# input rendering (v2), verdict readout, calibration, budgets, errors, manifest check, CLI/JSONL.
|
| 23 |
+
#
|
| 24 |
+
# Input layout ("macjev-render-v2-long-options", layout "sb"; token segments are encoded separately
|
| 25 |
+
# and concatenated, so slot positions are exact):
|
| 26 |
+
#
|
| 27 |
+
# state prefix State:\n<state>\n\n
|
| 28 |
+
# short form Question [<type>]: <question>\nOptions:\n
|
| 29 |
+
# (question + - <option 1> ->\n ... - <option K> ->\n
|
| 30 |
+
# options + slots <= 2,048 tokens)
|
| 31 |
+
# overflow form Question [<type>]: <question>\nOptions:\n
|
| 32 |
+
# (otherwise) Option 1: <option 1>\n ... Option K: <option K>\n (the catalogue)
|
| 33 |
+
# Judge each numbered option in the complete catalogue above:\n
|
| 34 |
+
# Option 1 ->\n ... Option K ->\n (the rubric)
|
| 35 |
+
#
|
| 36 |
+
# Attention blocks ([start, stop) token ranges): the state is cut into consecutive 2,048-token
|
| 37 |
+
# blocks; the short form is one block; in the overflow form the catalogue and the rubric are each cut
|
| 38 |
+
# into 2,048-token blocks. In the 6 full-attention layers every block attends to all earlier tokens
|
| 39 |
+
# and to itself with NO causal mask inside the block (block-causal); the Gated-DeltaNet layers are
|
| 40 |
+
# ordinary recurrent layers. A backend must compute exactly these blocks (never merged, never re-split).
|
| 41 |
+
#
|
| 42 |
+
# Score of option k = logit(" yes") - logit(" no") at its " ->" slot = h_slot . (W_yes - W_no) in
|
| 43 |
+
# float32 (final normed hidden state, tied embedding rows). Probabilities = softmax(scores / T) in
|
| 44 |
+
# canonical option order. T = the ONE global temperature of readout_config.json
|
| 45 |
+
# (temperatures.global, fitted on 2,000 calibration rows) unless temperature=... overrides it
|
| 46 |
+
# (1.0 = uncalibrated scores). This model has no category / group temperatures and no separate
|
| 47 |
+
# question/options budget, so the 0.8B v3 runtime's --category and --head-max options do not exist here.
|
| 48 |
+
#
|
| 49 |
+
# Budget: the complete input (state + question + options + readout) <= 25,600 tokens. Larger inputs
|
| 50 |
+
# raise InputBudgetError; nothing is ever truncated. Text inside the state, question and options is
|
| 51 |
+
# tokenised with special tokens disabled, so e.g. "<|im_end|>" in user text can never act as a
|
| 52 |
+
# control token. A non-finite score (NaN / inf) raises NonFiniteScoreError: no probabilities are made.
|
| 53 |
+
# ----------------------------------------------------------------------------------------------
|
| 54 |
+
import argparse
|
| 55 |
+
import hashlib
|
| 56 |
+
import json
|
| 57 |
+
import math
|
| 58 |
+
import sys
|
| 59 |
+
from pathlib import Path
|
| 60 |
+
|
| 61 |
+
import numpy as np
|
| 62 |
+
|
| 63 |
+
MODEL_NAME = "Jev-Style-2B-Decision-v3"
|
| 64 |
+
TEMPLATE_VERSION = "macjev-render-v2-long-options"
|
| 65 |
+
READOUT_FORMAT = "macjev-readout-v2"
|
| 66 |
+
LAYOUT = "sb"
|
| 67 |
+
BLOCK = 2048 # attention block size (a processing unit, not a content limit)
|
| 68 |
+
CONTEXT_LIMIT = 25_600 # state + question + options + readout, all included
|
| 69 |
+
QTYPES = ("choice", "score", "noul")
|
| 70 |
+
JSONL_GROUP_MAX = 256 # consecutive JSONL rows with one state scored in one backend call
|
| 71 |
+
HERE = Path(__file__).resolve().parent
|
| 72 |
+
|
| 73 |
+
|
| 74 |
+
class InputBudgetError(ValueError):
|
| 75 |
+
"""The rendered input exceeds the token budget. Nothing was truncated."""
|
| 76 |
+
|
| 77 |
+
|
| 78 |
+
class QuestionError(ValueError):
|
| 79 |
+
"""The question/options are malformed."""
|
| 80 |
+
|
| 81 |
+
|
| 82 |
+
class NonFiniteScoreError(FloatingPointError):
|
| 83 |
+
"""The model produced a non-finite decision score (NaN or inf). No probabilities are returned."""
|
| 84 |
+
|
| 85 |
+
|
| 86 |
+
# -- questions ------------------------------------------------------------------------------------
|
| 87 |
+
def option_names(question):
|
| 88 |
+
"""Canonical option identifiers, in the order the probabilities are returned."""
|
| 89 |
+
if not isinstance(question, dict):
|
| 90 |
+
raise QuestionError("question must be a dict {'t', 'ins', 'crit'}")
|
| 91 |
+
t, crit = question.get("t"), question.get("crit")
|
| 92 |
+
if not isinstance(question.get("ins"), str) or not question["ins"].strip():
|
| 93 |
+
raise QuestionError("question text ('ins') must be a non-empty string")
|
| 94 |
+
if t == "choice":
|
| 95 |
+
if not isinstance(crit, dict) or not crit:
|
| 96 |
+
raise QuestionError("choice needs a non-empty dict {option name: description or None}")
|
| 97 |
+
return [str(k) for k in crit]
|
| 98 |
+
if t == "score":
|
| 99 |
+
if not isinstance(crit, list) or not 2 <= len(crit) <= 10:
|
| 100 |
+
raise QuestionError("score needs a list of 2..10 level descriptions")
|
| 101 |
+
return [str(i) for i in range(len(crit))]
|
| 102 |
+
if t == "noul":
|
| 103 |
+
if crit is not None and not isinstance(crit, dict):
|
| 104 |
+
raise QuestionError("noul criteria must be None or {'false': ..., 'true': ...}")
|
| 105 |
+
return ["false", "true"]
|
| 106 |
+
raise QuestionError(f"unknown question type {t!r} (expected one of {QTYPES})")
|
| 107 |
+
|
| 108 |
+
|
| 109 |
+
def make_question(question, options=None, qtype=None):
|
| 110 |
+
"""Build a typed question.
|
| 111 |
+
|
| 112 |
+
* ``question`` already a dict {"t", "ins", "crit"}: validated and returned.
|
| 113 |
+
* ``qtype="choice"`` (default when ``options`` is given): ``options`` = {name: description or None}
|
| 114 |
+
or a list of names.
|
| 115 |
+
* ``qtype="score"``: ``options`` = list of 2..10 level descriptions (level 0 first).
|
| 116 |
+
* ``qtype="noul"`` (default when no options): a true/false statement; ``options`` may be
|
| 117 |
+
{"false": "...", "true": "..."} to describe the two outcomes.
|
| 118 |
+
"""
|
| 119 |
+
if isinstance(question, dict):
|
| 120 |
+
q = dict(question)
|
| 121 |
+
else:
|
| 122 |
+
if qtype is None:
|
| 123 |
+
qtype = "choice" if options is not None else "noul"
|
| 124 |
+
if qtype == "choice":
|
| 125 |
+
if isinstance(options, (list, tuple)):
|
| 126 |
+
if len(set(map(str, options))) != len(options):
|
| 127 |
+
raise QuestionError("duplicate option names")
|
| 128 |
+
crit = {str(o): None for o in options}
|
| 129 |
+
else:
|
| 130 |
+
crit = options
|
| 131 |
+
elif qtype == "score":
|
| 132 |
+
crit = list(options) if options is not None else None
|
| 133 |
+
else:
|
| 134 |
+
crit = options
|
| 135 |
+
q = {"t": qtype, "ins": question, "crit": crit}
|
| 136 |
+
option_names(q)
|
| 137 |
+
return q
|
| 138 |
+
|
| 139 |
+
|
| 140 |
+
def serialize_state(state):
|
| 141 |
+
"""Strings pass through unchanged; any other JSON value is serialised (ensure_ascii=False)."""
|
| 142 |
+
if isinstance(state, str):
|
| 143 |
+
return state
|
| 144 |
+
return json.dumps(state, ensure_ascii=False)
|
| 145 |
+
|
| 146 |
+
|
| 147 |
+
def _criterion(value):
|
| 148 |
+
if isinstance(value, str):
|
| 149 |
+
return value
|
| 150 |
+
return json.dumps(value, ensure_ascii=False, separators=(", ", ": "), default=str)
|
| 151 |
+
|
| 152 |
+
|
| 153 |
+
def render_options(question):
|
| 154 |
+
t, crit = question["t"], question.get("crit")
|
| 155 |
+
if t == "choice":
|
| 156 |
+
return [k if v is None or v == "" else f"{k}: {_criterion(v)}" for k, v in crit.items()]
|
| 157 |
+
if t == "score":
|
| 158 |
+
return [f"level {i}: {_criterion(c)}" for i, c in enumerate(crit)]
|
| 159 |
+
crit = crit or {}
|
| 160 |
+
false_c, true_c = crit.get("false"), crit.get("true")
|
| 161 |
+
return ["false: " + (_criterion(false_c) if false_c not in (None, "") else "no, the statement does not hold"),
|
| 162 |
+
"true: " + (_criterion(true_c) if true_c not in (None, "") else "yes, the statement holds")]
|
| 163 |
+
|
| 164 |
+
|
| 165 |
+
# -- tokenizer + renderer -----------------------------------------------------------------------
|
| 166 |
+
class TextEncoder:
|
| 167 |
+
"""HF ``tokenizers`` tokenizer.json; no BOS/EOS, special tokens in text are split (never control tokens)."""
|
| 168 |
+
|
| 169 |
+
def __init__(self, tokenizer_json):
|
| 170 |
+
from tokenizers import Tokenizer
|
| 171 |
+
self.tk = Tokenizer.from_file(str(tokenizer_json))
|
| 172 |
+
self.tk.encode_special_tokens = True
|
| 173 |
+
|
| 174 |
+
def __call__(self, text):
|
| 175 |
+
return self.tk.encode(text, add_special_tokens=False).ids
|
| 176 |
+
|
| 177 |
+
def id_to_token(self, i):
|
| 178 |
+
return self.tk.id_to_token(int(i))
|
| 179 |
+
|
| 180 |
+
def vocab_size(self):
|
| 181 |
+
return self.tk.get_vocab_size(with_added_tokens=True)
|
| 182 |
+
|
| 183 |
+
|
| 184 |
+
def _blocks(start, stop):
|
| 185 |
+
return [(s, min(s + BLOCK, stop)) for s in range(start, stop, BLOCK)]
|
| 186 |
+
|
| 187 |
+
|
| 188 |
+
class Rendered:
|
| 189 |
+
"""One rendered question: token ids, the verdict slots (one per option, canonical order), the
|
| 190 |
+
attention blocks ([start, stop) pairs tiling [0, len(ids))) and the state prefix length."""
|
| 191 |
+
__slots__ = ("ids", "prefix_len", "slots", "blocks", "names", "qtype", "catalogue_overflow")
|
| 192 |
+
|
| 193 |
+
def __init__(self, ids, prefix_len, slots, blocks, names, qtype, catalogue_overflow):
|
| 194 |
+
self.ids, self.prefix_len, self.slots, self.blocks = ids, prefix_len, slots, blocks
|
| 195 |
+
self.names, self.qtype, self.catalogue_overflow = names, qtype, catalogue_overflow
|
| 196 |
+
|
| 197 |
+
@property
|
| 198 |
+
def state_blocks(self):
|
| 199 |
+
return [b for b in self.blocks if b[1] <= self.prefix_len]
|
| 200 |
+
|
| 201 |
+
@property
|
| 202 |
+
def question_blocks(self):
|
| 203 |
+
return [b for b in self.blocks if b[0] >= self.prefix_len]
|
| 204 |
+
|
| 205 |
+
@property
|
| 206 |
+
def input_tokens(self):
|
| 207 |
+
return len(self.ids)
|
| 208 |
+
|
| 209 |
+
@property
|
| 210 |
+
def head_tokens(self):
|
| 211 |
+
"""question + options + readout tokens (everything after the state prefix)"""
|
| 212 |
+
return len(self.ids) - self.prefix_len
|
| 213 |
+
|
| 214 |
+
|
| 215 |
+
class Renderer:
|
| 216 |
+
def __init__(self, encode, readout_cfg, max_len=CONTEXT_LIMIT):
|
| 217 |
+
want = {"format": READOUT_FORMAT, "template": TEMPLATE_VERSION, "layout": LAYOUT, "readout": "verdict",
|
| 218 |
+
"block_size": BLOCK, "total_context_limit": CONTEXT_LIMIT}
|
| 219 |
+
bad = {k: readout_cfg.get(k) for k, v in want.items() if readout_cfg.get(k) != v}
|
| 220 |
+
if bad:
|
| 221 |
+
raise ValueError(f"readout_config.json does not describe this runtime's protocol {want}; got {bad}")
|
| 222 |
+
if not 0 < int(max_len) <= CONTEXT_LIMIT:
|
| 223 |
+
raise ValueError(f"max_len must be in 1..{CONTEXT_LIMIT}")
|
| 224 |
+
self.enc, self.max_len = encode, int(max_len)
|
| 225 |
+
self.head_max = self.max_len # no separate question/options cap (field kept for the 0.8B / jev-style API)
|
| 226 |
+
st = readout_cfg["slot_tokens"]
|
| 227 |
+
self.yes, self.no, arrow = int(st["yes"]["id"]), int(st["no"]["id"]), int(st["verdict_slot"]["id"])
|
| 228 |
+
for text, want_id in ((" yes", self.yes), (" no", self.no), (" ->", arrow)):
|
| 229 |
+
got = self.enc(text)
|
| 230 |
+
if got != [want_id]:
|
| 231 |
+
raise ValueError(f"tokenizer mismatch: {text!r} -> {got}, readout_config expects [{want_id}]")
|
| 232 |
+
self.arrow = [arrow]
|
| 233 |
+
self.newline = self.enc("\n")
|
| 234 |
+
self.dash = self.enc("- ")
|
| 235 |
+
self.rubric_head = self.enc("Judge each numbered option in the complete catalogue above:\n")
|
| 236 |
+
self._numbered = {}
|
| 237 |
+
|
| 238 |
+
def _option_label(self, pos, catalogue):
|
| 239 |
+
key = (pos, catalogue)
|
| 240 |
+
if key not in self._numbered:
|
| 241 |
+
self._numbered[key] = self.enc(f"Option {pos + 1}: " if catalogue else f"Option {pos + 1}")
|
| 242 |
+
return self._numbered[key]
|
| 243 |
+
|
| 244 |
+
def prefix_ids(self, state):
|
| 245 |
+
return self.enc("State:\n") + self.enc(serialize_state(state)) + self.enc("\n\n")
|
| 246 |
+
|
| 247 |
+
def pieces(self, state, question, prefix=None):
|
| 248 |
+
"""Tokenised segments of one question (``prefix``: already tokenised state, to tokenise it once)."""
|
| 249 |
+
names = option_names(question)
|
| 250 |
+
return {"prefix": self.prefix_ids(state) if prefix is None else list(prefix),
|
| 251 |
+
"head": self.enc(f"Question [{question['t']}]: {question['ins']}\nOptions:\n"),
|
| 252 |
+
"opts": [self.enc(o) for o in render_options(question)], "names": names, "qtype": question["t"]}
|
| 253 |
+
|
| 254 |
+
def assemble(self, pieces, max_len=None):
|
| 255 |
+
maximum = self.max_len if max_len is None else min(self.max_len, int(max_len))
|
| 256 |
+
prefix, head, opts = list(pieces["prefix"]), list(pieces["head"]), pieces["opts"]
|
| 257 |
+
k = len(opts)
|
| 258 |
+
if k < 1:
|
| 259 |
+
raise QuestionError("at least one option is required")
|
| 260 |
+
short, rel = list(head), []
|
| 261 |
+
for o in opts:
|
| 262 |
+
short += self.dash + list(o) + self.arrow
|
| 263 |
+
rel.append(len(short) - 1)
|
| 264 |
+
short += self.newline
|
| 265 |
+
overflow = len(short) > BLOCK
|
| 266 |
+
if not overflow:
|
| 267 |
+
ids = prefix + short
|
| 268 |
+
slots = [len(prefix) + s for s in rel]
|
| 269 |
+
blocks = _blocks(0, len(prefix)) + [(len(prefix), len(ids))]
|
| 270 |
+
else:
|
| 271 |
+
catalogue = list(head)
|
| 272 |
+
for pos, o in enumerate(opts):
|
| 273 |
+
catalogue += self._option_label(pos, True) + list(o) + self.newline
|
| 274 |
+
doc_end = len(prefix) + len(catalogue)
|
| 275 |
+
rubric, rel = list(self.rubric_head), []
|
| 276 |
+
for pos in range(k):
|
| 277 |
+
rubric += self._option_label(pos, False) + self.arrow
|
| 278 |
+
rel.append(len(rubric) - 1)
|
| 279 |
+
rubric += self.newline
|
| 280 |
+
ids = prefix + catalogue + rubric
|
| 281 |
+
slots = [doc_end + s for s in rel]
|
| 282 |
+
blocks = _blocks(0, len(prefix)) + _blocks(len(prefix), doc_end) + _blocks(doc_end, len(ids))
|
| 283 |
+
if len(ids) > maximum:
|
| 284 |
+
raise InputBudgetError(f"the complete input needs {len(ids)} tokens (state {len(prefix)} + question/"
|
| 285 |
+
f"options/readout {len(ids) - len(prefix)}); the limit is {maximum} tokens (model "
|
| 286 |
+
f"maximum {CONTEXT_LIMIT}). Nothing was truncated: shorten the state, the "
|
| 287 |
+
f"question or the options.")
|
| 288 |
+
return Rendered(ids, len(prefix), slots, blocks, list(pieces["names"]), pieces["qtype"], overflow)
|
| 289 |
+
|
| 290 |
+
def render(self, state, question, max_len=None, prefix=None):
|
| 291 |
+
return self.assemble(self.pieces(state, question, prefix), max_len)
|
| 292 |
+
|
| 293 |
+
|
| 294 |
+
# -- calibration ----------------------------------------------------------------------------------
|
| 295 |
+
def check_temperature(t):
|
| 296 |
+
try:
|
| 297 |
+
t = float(t)
|
| 298 |
+
except (TypeError, ValueError):
|
| 299 |
+
raise ValueError(f"temperature must be a number, got {t!r}") from None
|
| 300 |
+
if not (math.isfinite(t) and t > 0):
|
| 301 |
+
raise ValueError(f"temperature must be finite and > 0, got {t!r}")
|
| 302 |
+
return t
|
| 303 |
+
|
| 304 |
+
|
| 305 |
+
def softmax_probabilities(scores, temperature):
|
| 306 |
+
"""softmax(scores / T) in float64 (the reference computation)."""
|
| 307 |
+
z = np.asarray(scores, float) / float(temperature)
|
| 308 |
+
z = np.exp(z - z.max())
|
| 309 |
+
return z / z.sum()
|
| 310 |
+
|
| 311 |
+
|
| 312 |
+
def concentration(p):
|
| 313 |
+
k = len(p)
|
| 314 |
+
if k < 2:
|
| 315 |
+
return 1.0
|
| 316 |
+
ent = -(p * np.log(np.clip(p, 1e-12, 1.0))).sum()
|
| 317 |
+
return float(np.clip(1.0 - ent / math.log(k), 0.0, 1.0))
|
| 318 |
+
|
| 319 |
+
|
| 320 |
+
def _sha256(path):
|
| 321 |
+
h = hashlib.sha256()
|
| 322 |
+
with open(path, "rb") as f:
|
| 323 |
+
for b in iter(lambda: f.read(1 << 22), b""):
|
| 324 |
+
h.update(b)
|
| 325 |
+
return h.hexdigest()
|
| 326 |
+
|
| 327 |
+
|
| 328 |
+
NOT_VERIFIED = ("README.md", "eval_results.json") # documentation / records: in manifest.json, not checked
|
| 329 |
+
NOT_VERIFIED_DIRS = ("assets/", "figures/", "validation/")
|
| 330 |
+
|
| 331 |
+
|
| 332 |
+
def verify_manifest(model_dir, only=None):
|
| 333 |
+
"""Re-hash the files listed in manifest.json (all, or those whose path starts with one of ``only``).
|
| 334 |
+
Documentation and evaluation records (README.md, eval_results.json, assets/, figures/, validation/) are
|
| 335 |
+
recorded in the manifest but not checked here (not even when named in ``only``), so a card edit never
|
| 336 |
+
makes the runtime refuse to load and a download without them still verifies."""
|
| 337 |
+
model_dir = Path(model_dir)
|
| 338 |
+
man = json.loads((model_dir / "manifest.json").read_text())
|
| 339 |
+
bad, missing, checked = [], [], 0
|
| 340 |
+
for name, rec in man["files"].items():
|
| 341 |
+
if name in NOT_VERIFIED or name.startswith(NOT_VERIFIED_DIRS):
|
| 342 |
+
continue
|
| 343 |
+
if only and not any(name == o or name.startswith(o.rstrip("/") + "/") for o in only):
|
| 344 |
+
continue
|
| 345 |
+
p = model_dir / name
|
| 346 |
+
if not p.exists():
|
| 347 |
+
missing.append(name)
|
| 348 |
+
elif _sha256(p) != rec["sha256"]:
|
| 349 |
+
bad.append(name)
|
| 350 |
+
checked += 1
|
| 351 |
+
return {"ok": not bad and not missing, "checked": checked, "bad": bad, "missing": missing}
|
| 352 |
+
|
| 353 |
+
|
| 354 |
+
class DecisionBase:
|
| 355 |
+
"""Backend-independent part. A backend implements ``_scores_many(rendered) -> list of list[float]``:
|
| 356 |
+
``rendered`` is a non-empty list of Rendered that all share ONE state (identical prefix ids and
|
| 357 |
+
state blocks); it returns the raw float32 scores of every slot of every Rendered (slot order =
|
| 358 |
+
canonical option order), computing the state blocks once per call. Backends keep the most recent
|
| 359 |
+
state for the next call (exact prefix match only), so consecutive calls about the same state (e.g.
|
| 360 |
+
JSONL rows read from stdin) reuse it."""
|
| 361 |
+
backend = "base"
|
| 362 |
+
|
| 363 |
+
def _setup(self, model_dir, tokenizer_json, max_len=CONTEXT_LIMIT, temperature=None):
|
| 364 |
+
self.model_dir = Path(model_dir)
|
| 365 |
+
self.readout_config = json.loads((self.model_dir / "readout_config.json").read_text())
|
| 366 |
+
self.calibrated_temperature = check_temperature(self.readout_config["temperatures"]["global"])
|
| 367 |
+
self.default_temperature = self.calibrated_temperature if temperature is None else check_temperature(temperature)
|
| 368 |
+
self.encode = TextEncoder(tokenizer_json)
|
| 369 |
+
self.renderer = Renderer(self.encode, self.readout_config, max_len=max_len)
|
| 370 |
+
|
| 371 |
+
def _scores_many(self, rendered):
|
| 372 |
+
raise NotImplementedError
|
| 373 |
+
|
| 374 |
+
def close(self):
|
| 375 |
+
pass
|
| 376 |
+
|
| 377 |
+
def __enter__(self):
|
| 378 |
+
return self
|
| 379 |
+
|
| 380 |
+
def __exit__(self, *exc):
|
| 381 |
+
self.close()
|
| 382 |
+
|
| 383 |
+
def _score_all(self, rendered):
|
| 384 |
+
"""Raw scores (lists of floats, canonical order) for Rendered sharing one state; one backend call."""
|
| 385 |
+
if not rendered:
|
| 386 |
+
return []
|
| 387 |
+
p = rendered[0].prefix_len
|
| 388 |
+
prefix, sblocks = rendered[0].ids[:p], rendered[0].state_blocks
|
| 389 |
+
for r in rendered[1:]:
|
| 390 |
+
if r.prefix_len != p or r.ids[:p] != prefix or r.state_blocks != sblocks:
|
| 391 |
+
raise ValueError("all questions of one backend call must share the same state")
|
| 392 |
+
scores = self._scores_many(rendered)
|
| 393 |
+
if len(scores) != len(rendered) or any(len(s) != len(r.slots) for s, r in zip(scores, rendered)):
|
| 394 |
+
raise RuntimeError("backend returned a wrong number of scores")
|
| 395 |
+
return [[float(x) for x in s] for s in scores]
|
| 396 |
+
|
| 397 |
+
def score_pieces(self, pieces_list, max_len=None):
|
| 398 |
+
"""Raw scores for pre-tokenised questions sharing one state: dicts {"prefix", "head", "opts",
|
| 399 |
+
"names", "qtype"} of token ids (see Renderer.pieces). For parity checks; no temperature."""
|
| 400 |
+
return self._score_all([self.renderer.assemble(p, max_len) for p in pieces_list])
|
| 401 |
+
|
| 402 |
+
def _result(self, r, scores, temperature):
|
| 403 |
+
t = self.default_temperature if temperature is None else check_temperature(temperature)
|
| 404 |
+
bad = [n for n, x in zip(r.names, scores) if not math.isfinite(x)]
|
| 405 |
+
if bad:
|
| 406 |
+
raise NonFiniteScoreError(f"non-finite decision scores for option(s) {bad} ({len(r.ids)} input tokens); "
|
| 407 |
+
f"refusing to return probabilities. Check the weights file / engine build.")
|
| 408 |
+
p = softmax_probabilities(scores, t)
|
| 409 |
+
if not np.all(np.isfinite(p)):
|
| 410 |
+
raise NonFiniteScoreError("non-finite probabilities")
|
| 411 |
+
i = int(p.argmax())
|
| 412 |
+
return {"answer": r.names[i], "probabilities": dict(zip(r.names, p.tolist())),
|
| 413 |
+
"scores": dict(zip(r.names, scores)), "temperature": t, "top_probability": float(p[i]),
|
| 414 |
+
"entropy_concentration": concentration(p), "input_tokens": len(r.ids),
|
| 415 |
+
"state_tokens": r.prefix_len, "head_tokens": r.head_tokens, "blocks": len(r.blocks),
|
| 416 |
+
"catalogue_overflow": r.catalogue_overflow, "model": MODEL_NAME, "backend": self.backend}
|
| 417 |
+
|
| 418 |
+
def decide(self, state, question, options=None, qtype=None, category=None, temperature=None, head_max=None,
|
| 419 |
+
max_len=None):
|
| 420 |
+
"""Score one question about ``state``.
|
| 421 |
+
|
| 422 |
+
Returns {"answer", "probabilities" {option: p}, "scores" {option: logit(yes)-logit(no)},
|
| 423 |
+
"temperature", "top_probability", "entropy_concentration", "input_tokens", "state_tokens",
|
| 424 |
+
"head_tokens", "blocks", "catalogue_overflow", "model", "backend"}. ``temperature`` overrides
|
| 425 |
+
the calibrated global temperature (1.0 = uncalibrated scores). ``category`` and ``head_max`` are
|
| 426 |
+
accepted for compatibility with the 0.8B v3 runtime and the jev-style package, and ignored: this
|
| 427 |
+
model has one global temperature and no separate question/options budget. Raises InputBudgetError
|
| 428 |
+
(never truncates), QuestionError or NonFiniteScoreError."""
|
| 429 |
+
q = make_question(question, options, qtype)
|
| 430 |
+
r = self.renderer.render(state, q, max_len)
|
| 431 |
+
return self._result(r, self._score_all([r])[0], temperature)
|
| 432 |
+
|
| 433 |
+
def score_many(self, state, questions, category=None, temperature=None, head_max=None, max_len=None):
|
| 434 |
+
"""Several questions about ONE state: the state is tokenised and computed once and reused for
|
| 435 |
+
every question (one backend call). ``questions``: dicts {"t","ins","crit"} (or anything
|
| 436 |
+
make_question accepts). Results in order, identical to calling decide() per question. All
|
| 437 |
+
questions are rendered and budget-checked before any scoring. ``category`` / ``head_max``: see
|
| 438 |
+
decide() (accepted and ignored)."""
|
| 439 |
+
qs = [make_question(q) for q in questions]
|
| 440 |
+
if not qs:
|
| 441 |
+
return []
|
| 442 |
+
prefix = self.renderer.prefix_ids(state)
|
| 443 |
+
rs = [self.renderer.render(state, q, max_len, prefix=prefix) for q in qs]
|
| 444 |
+
return [self._result(r, sc, temperature) for r, sc in zip(rs, self._score_all(rs))]
|
| 445 |
+
|
| 446 |
+
decide_many = score_many
|
| 447 |
+
|
| 448 |
+
|
| 449 |
+
def base_arg_parser(description):
|
| 450 |
+
ap = argparse.ArgumentParser(description=description)
|
| 451 |
+
ap.add_argument("--model-dir", default=str(HERE), help="folder with the weights and readout_config.json")
|
| 452 |
+
ap.add_argument("--state", help="state as plain text")
|
| 453 |
+
ap.add_argument("--state-json", help="state as a JSON value")
|
| 454 |
+
ap.add_argument("--question", help="question text (or a JSON question {'t','ins','crit'})")
|
| 455 |
+
ap.add_argument("--options", help="JSON: {name: description} or [names] (choice); [levels] (score)")
|
| 456 |
+
ap.add_argument("--qtype", choices=QTYPES)
|
| 457 |
+
ap.add_argument("--temperature", type=float,
|
| 458 |
+
help="override the calibrated global temperature of readout_config.json (1.0 = raw scores)")
|
| 459 |
+
ap.add_argument("--max-len", type=int, default=CONTEXT_LIMIT,
|
| 460 |
+
help=f"total token budget (state + question + options + readout), at most {CONTEXT_LIMIT}")
|
| 461 |
+
ap.add_argument("--jsonl", help="batch mode: input JSON lines {id?, state, question, options?, qtype?, "
|
| 462 |
+
"temperature?} ('-' = stdin); one JSON result per line on stdout. Consecutive "
|
| 463 |
+
"rows with an identical state share one state computation")
|
| 464 |
+
ap.add_argument("--verify", action="store_true", help="check sha256 of the files in manifest.json first")
|
| 465 |
+
return ap
|
| 466 |
+
|
| 467 |
+
|
| 468 |
+
def _jsonl_groups(src, streaming):
|
| 469 |
+
"""(line number, record or error text) grouped into runs of consecutive rows with one state. From a
|
| 470 |
+
file up to JSONL_GROUP_MAX rows are grouped; from stdin every row is its own group (answered at once;
|
| 471 |
+
the backend's kept state still makes consecutive identical states cheap)."""
|
| 472 |
+
group, key = [], None
|
| 473 |
+
for n, line in enumerate(src):
|
| 474 |
+
if not line.strip():
|
| 475 |
+
continue
|
| 476 |
+
try:
|
| 477 |
+
rec = json.loads(line)
|
| 478 |
+
if not isinstance(rec, dict):
|
| 479 |
+
raise ValueError("a JSONL row must be a JSON object")
|
| 480 |
+
k = serialize_state(rec.get("state", ""))
|
| 481 |
+
except ValueError as e:
|
| 482 |
+
if group:
|
| 483 |
+
yield group
|
| 484 |
+
group, key = [], None
|
| 485 |
+
yield [(n, f"{type(e).__name__}: {e}")]
|
| 486 |
+
continue
|
| 487 |
+
if group and (k != key or len(group) >= JSONL_GROUP_MAX):
|
| 488 |
+
yield group
|
| 489 |
+
group = []
|
| 490 |
+
group.append((n, rec))
|
| 491 |
+
key = k
|
| 492 |
+
if streaming:
|
| 493 |
+
yield group
|
| 494 |
+
group, key = [], None
|
| 495 |
+
if group:
|
| 496 |
+
yield group
|
| 497 |
+
|
| 498 |
+
|
| 499 |
+
def _run_group(engine, group, args):
|
| 500 |
+
"""Score one group of JSONL rows sharing a state. Returns (output rows, non-finite count)."""
|
| 501 |
+
out, todo = {}, []
|
| 502 |
+
prefix = None
|
| 503 |
+
for n, rec in group:
|
| 504 |
+
if isinstance(rec, str):
|
| 505 |
+
out[n] = {"id": n, "error": rec}
|
| 506 |
+
continue
|
| 507 |
+
rid = rec.get("id", n)
|
| 508 |
+
try:
|
| 509 |
+
if "question" not in rec:
|
| 510 |
+
raise QuestionError("row has no 'question'")
|
| 511 |
+
q = make_question(rec["question"], options=rec.get("options"), qtype=rec.get("qtype"))
|
| 512 |
+
t = rec.get("temperature", args.temperature)
|
| 513 |
+
t = None if t is None else check_temperature(t)
|
| 514 |
+
if prefix is None:
|
| 515 |
+
prefix = engine.renderer.prefix_ids(rec.get("state", ""))
|
| 516 |
+
todo.append((n, rid, engine.renderer.render(rec.get("state", ""), q, prefix=prefix), t))
|
| 517 |
+
except (InputBudgetError, QuestionError, ValueError, TypeError, AttributeError) as e:
|
| 518 |
+
out[n] = {"id": rid, "error": f"{type(e).__name__}: {e}"}
|
| 519 |
+
nonfinite = 0
|
| 520 |
+
if todo:
|
| 521 |
+
scores = engine._score_all([r for _, _, r, _ in todo])
|
| 522 |
+
for (n, rid, r, t), sc in zip(todo, scores):
|
| 523 |
+
try:
|
| 524 |
+
out[n] = {"id": rid, **engine._result(r, sc, t)}
|
| 525 |
+
except NonFiniteScoreError as e:
|
| 526 |
+
nonfinite += 1
|
| 527 |
+
print(f"ERROR row {rid}: NonFiniteScoreError: {e}", file=sys.stderr, flush=True)
|
| 528 |
+
out[n] = {"id": rid, "error": f"NonFiniteScoreError: {e}"}
|
| 529 |
+
return [out[n] for n, _ in group], nonfinite
|
| 530 |
+
|
| 531 |
+
|
| 532 |
+
def run_cli(args, engine):
|
| 533 |
+
"""Exit status: 0 = ok (JSONL rows with input errors carry an "error" field), 2 = input error
|
| 534 |
+
(single question), 3 = at least one non-finite score (refused, see stderr)."""
|
| 535 |
+
if args.jsonl:
|
| 536 |
+
streaming = args.jsonl == "-"
|
| 537 |
+
src = sys.stdin if streaming else open(args.jsonl, encoding="utf-8")
|
| 538 |
+
nonfinite = 0
|
| 539 |
+
try:
|
| 540 |
+
for group in _jsonl_groups(src, streaming):
|
| 541 |
+
rows, bad = _run_group(engine, group, args)
|
| 542 |
+
nonfinite += bad
|
| 543 |
+
for row in rows:
|
| 544 |
+
print(json.dumps(row, ensure_ascii=False), flush=True)
|
| 545 |
+
finally:
|
| 546 |
+
if not streaming:
|
| 547 |
+
src.close()
|
| 548 |
+
return 3 if nonfinite else 0
|
| 549 |
+
if args.question is None:
|
| 550 |
+
raise SystemExit("--question (or --jsonl) is required")
|
| 551 |
+
try:
|
| 552 |
+
state = json.loads(args.state_json) if args.state_json is not None else (args.state or "")
|
| 553 |
+
question = args.question
|
| 554 |
+
if question.lstrip().startswith("{"):
|
| 555 |
+
try: # a JSON question {'t','ins','crit'}; else plain text
|
| 556 |
+
parsed = json.loads(question)
|
| 557 |
+
except ValueError:
|
| 558 |
+
parsed = None
|
| 559 |
+
if isinstance(parsed, dict):
|
| 560 |
+
question = parsed
|
| 561 |
+
options = json.loads(args.options) if args.options else None
|
| 562 |
+
res = engine.decide(state, question, options=options, qtype=args.qtype, temperature=args.temperature)
|
| 563 |
+
except (InputBudgetError, QuestionError, ValueError, TypeError) as e: # NonFiniteScoreError is not a ValueError
|
| 564 |
+
print(f"error: {type(e).__name__}: {e}", file=sys.stderr)
|
| 565 |
+
return 2
|
| 566 |
+
except NonFiniteScoreError as e:
|
| 567 |
+
print(f"ERROR: NonFiniteScoreError: {e}", file=sys.stderr)
|
| 568 |
+
return 3
|
| 569 |
+
print(json.dumps(res, ensure_ascii=False, indent=2))
|
| 570 |
+
return 0
|
| 571 |
+
# ---------------------------------------------------------------------------- end of shared core
|
| 572 |
+
|
| 573 |
+
|
| 574 |
+
# ---------------------------------------------------------------------------------- MLX backend
|
| 575 |
+
# Repository layout (one runtime, two precisions):
|
| 576 |
+
#
|
| 577 |
+
# jev_style_decision_mlx.py, readout_config.json, release_config.json, manifest.json, ... shared
|
| 578 |
+
# bf16/ config.json, model.safetensors (bfloat16), macjev_norms_fp32.safetensors, tokenizer ...
|
| 579 |
+
# 8bit/ config.json, model.safetensors (affine 8-bit, group 64), macjev_norms_fp32.safetensors, tokenizer ...
|
| 580 |
+
#
|
| 581 |
+
# Either folder may be downloaded alone (plus the shared top-level files).
|
| 582 |
+
#
|
| 583 |
+
# Block-causal attention on mlx-lm: the input is fed to the model ONE protocol block per call on an mlx-lm
|
| 584 |
+
# prompt cache. The 6 full-attention layers use BlockKVCache, whose make_mask returns None, so the queries of
|
| 585 |
+
# the current block attend to every cached key plus every key of the block itself, with no causal mask inside
|
| 586 |
+
# the block. The 18 Gated-DeltaNet layers keep their recurrent cache (conv + recurrent state), causal by
|
| 587 |
+
# construction. The state blocks are computed once; each question then runs its block(s) on an independent
|
| 588 |
+
# copy of that cache, so questions never see each other and the state is reused (score_many, JSONL rows).
|
| 589 |
+
#
|
| 590 |
+
# Two corrections to stock mlx-lm 0.31.3 (both needed to match the HF / training numerics):
|
| 591 |
+
# 1. Gated-DeltaNet q/k normalisation: mlx-lm uses rms_norm(x, eps=1e-6) (= l2norm with eps Dk*1e-6); HF / fla /
|
| 592 |
+
# llama.cpp use l2norm(x, eps=1e-6). A copy of mlx-lm's GatedDeltaNet.__call__ with only that eps changed is
|
| 593 |
+
# swapped in per instance (never globally).
|
| 594 |
+
# 2. Qwen3.5 RMSNorm is x_hat * (1 + w). mlx-lm's converter adds the 1 in bf16, so the export stores bf16(1 + w).
|
| 595 |
+
# The exact FP32 (1 + w) ships as the sidecar macjev_norms_fp32.safetensors (ignored by stock mlx-lm); the
|
| 596 |
+
# runtime installs it and computes those norms in FP32 (cast back to the input dtype, as HF does).
|
| 597 |
+
# Both depend on mlx-lm internals, so the runtime checks the sha256 of the mlx-lm source it patches or relies on
|
| 598 |
+
# and refuses to run on any other mlx-lm version (install mlx-lm==0.31.3). The sidecar and readout_config.json are
|
| 599 |
+
# mandatory: the runtime never falls back to stock norms or to T = 1.
|
| 600 |
+
REPO_ID = "chaoliangUNSW/Jev-Style-2B-Decision-v3-MLX"
|
| 601 |
+
PRECISIONS = ("bf16", "8bit")
|
| 602 |
+
DEFAULT_PRECISION = "bf16"
|
| 603 |
+
# activation dtype per precision: None = the checkpoint's native activations (bf16 residual stream), the
|
| 604 |
+
# setting the release scoring used for both precisions (release_config.json -> runtime.precisions overrides)
|
| 605 |
+
VALIDATED_COMPUTE_DTYPE = {"bf16": None, "8bit": None}
|
| 606 |
+
MLX_CACHE_LIMIT_GIB = 2.0
|
| 607 |
+
MLX_LM_VERSION = "0.31.3"
|
| 608 |
+
NORM_SIDECAR = "macjev_norms_fp32.safetensors"
|
| 609 |
+
NORM_SIDECAR_FORMAT = "macjev-norms-fp32-v1"
|
| 610 |
+
SHIFTED_NORMS = ("input_layernorm", "post_attention_layernorm", "q_norm", "k_norm")
|
| 611 |
+
# sha256 of inspect.getsource(...) in mlx-lm 0.31.3 for every function the MLX path patches (GatedDeltaNet) or relies
|
| 612 |
+
# on for the block mask (a None mask from BlockKVCache must reach scaled_dot_product_attention unchanged)
|
| 613 |
+
MLX_LM_SOURCE_SHA256 = {
|
| 614 |
+
"qwen3_5.GatedDeltaNet.__call__": "9f27bdc613912fa9b3b0509d8e3f684ac672810bf45e29831f5815a1c3b43091",
|
| 615 |
+
"qwen3_5.Qwen3_5TextModel.__call__": "45fd379f8885e93b4ba685c3d6c2aa1b891d535bb00fd042c6b1e56613345b6d",
|
| 616 |
+
"base.create_attention_mask": "a8ebacf963b3f96e9ad838a7a870d1ef6da33aec5233b133b0d0c744c3b33e5e",
|
| 617 |
+
"qwen3_5.Attention.__call__": "a938424855f1b919d1bcfd62b105e10723f7de295f5ee51a19924b502ddc86a6",
|
| 618 |
+
"base.scaled_dot_product_attention": "8deba4a8a8fb4e29f1e69ea81701da68f08f90656e1421a1e7a82332aadc41c1",
|
| 619 |
+
}
|
| 620 |
+
|
| 621 |
+
|
| 622 |
+
class MLXVersionError(RuntimeError):
|
| 623 |
+
"""The installed mlx-lm is not the version whose internals the runtime was validated against."""
|
| 624 |
+
|
| 625 |
+
|
| 626 |
+
def check_mlx_lm():
|
| 627 |
+
"""Raise MLXVersionError unless the mlx-lm source this runtime patches is byte-identical to mlx-lm 0.31.3."""
|
| 628 |
+
import inspect
|
| 629 |
+
import mlx_lm
|
| 630 |
+
from mlx_lm.models import base, qwen3_5
|
| 631 |
+
objs = {"qwen3_5.GatedDeltaNet.__call__": qwen3_5.GatedDeltaNet.__call__,
|
| 632 |
+
"qwen3_5.Qwen3_5TextModel.__call__": qwen3_5.Qwen3_5TextModel.__call__,
|
| 633 |
+
"base.create_attention_mask": base.create_attention_mask,
|
| 634 |
+
"qwen3_5.Attention.__call__": qwen3_5.Attention.__call__,
|
| 635 |
+
"base.scaled_dot_product_attention": base.scaled_dot_product_attention}
|
| 636 |
+
changed = [k for k, f in objs.items()
|
| 637 |
+
if hashlib.sha256(inspect.getsource(f).encode()).hexdigest() != MLX_LM_SOURCE_SHA256[k]]
|
| 638 |
+
if changed:
|
| 639 |
+
raise MLXVersionError(
|
| 640 |
+
f"this runtime needs mlx-lm=={MLX_LM_VERSION} (installed: {getattr(mlx_lm, '__version__', '?')}): it "
|
| 641 |
+
f"corrects the Qwen3.5 Gated-DeltaNet q/k norm and the (1 + w) RMSNorm weights inside mlx-lm, and the "
|
| 642 |
+
f"source it patches differs ({', '.join(changed)}). Install the tested version with: "
|
| 643 |
+
f"pip install 'mlx-lm=={MLX_LM_VERSION}'")
|
| 644 |
+
|
| 645 |
+
|
| 646 |
+
# Third-party code: _gdn_hf_call below is a modified copy of GatedDeltaNet.__call__ from mlx_lm/models/qwen3_5.py,
|
| 647 |
+
# mlx-lm 0.31.3 (https://github.com/ml-explore/mlx-lm), MIT License (mlx-lm LICENSE: "Copyright © 2023 Apple Inc.";
|
| 648 |
+
# qwen3_5.py header: "Copyright © 2026 Apple Inc."). Changes:
|
| 649 |
+
# q/k rms_norm eps 1e-6 -> 1e-6 / Dk (HF-exact l2norm), sharding branches removed (refused), module-level function.
|
| 650 |
+
# The MIT copyright and permission notice is reproduced in THIRD_PARTY_NOTICES.md of this repository.
|
| 651 |
+
def _gdn_hf_call(self, inputs, mask=None, cache=None):
|
| 652 |
+
"""mlx-lm 0.31.3 qwen3_5.GatedDeltaNet.__call__ with HF-exact q/k l2norm (eps 1e-6). No sharding."""
|
| 653 |
+
import mlx.core as mx
|
| 654 |
+
import mlx.nn as nn
|
| 655 |
+
from mlx_lm.models.gated_delta import gated_delta_update
|
| 656 |
+
if self.sharding_group is not None:
|
| 657 |
+
raise ValueError("sharded Gated-DeltaNet is not supported by this runtime")
|
| 658 |
+
B, S, _ = inputs.shape
|
| 659 |
+
qkv = self.in_proj_qkv(inputs)
|
| 660 |
+
z = self.in_proj_z(inputs).reshape(B, S, self.num_v_heads, self.head_v_dim)
|
| 661 |
+
b = self.in_proj_b(inputs)
|
| 662 |
+
a = self.in_proj_a(inputs)
|
| 663 |
+
if cache is not None and cache[0] is not None:
|
| 664 |
+
conv_state = cache[0]
|
| 665 |
+
else:
|
| 666 |
+
conv_state = mx.zeros((B, self.conv_kernel_size - 1, self.conv_dim), dtype=inputs.dtype)
|
| 667 |
+
if mask is not None:
|
| 668 |
+
qkv = mx.where(mask[..., None], qkv, 0)
|
| 669 |
+
conv_input = mx.concatenate([conv_state, qkv], axis=1)
|
| 670 |
+
if cache is not None:
|
| 671 |
+
n_keep = self.conv_kernel_size - 1
|
| 672 |
+
if cache.lengths is not None:
|
| 673 |
+
ends = mx.clip(cache.lengths, 0, S)
|
| 674 |
+
positions = (ends[:, None] + mx.arange(n_keep))[..., None]
|
| 675 |
+
cache[0] = mx.take_along_axis(conv_input, positions, axis=1)
|
| 676 |
+
else:
|
| 677 |
+
cache[0] = mx.contiguous(conv_input[:, -n_keep:, :])
|
| 678 |
+
conv_out = nn.silu(self.conv1d(conv_input))
|
| 679 |
+
q, k, v = [t.reshape(B, S, h, d) for t, h, d in zip(
|
| 680 |
+
mx.split(conv_out, [self.key_dim, 2 * self.key_dim], -1),
|
| 681 |
+
[self.num_k_heads, self.num_k_heads, self.num_v_heads],
|
| 682 |
+
[self.head_k_dim, self.head_k_dim, self.head_v_dim])]
|
| 683 |
+
state = cache[1] if cache else None
|
| 684 |
+
dk = k.shape[-1]
|
| 685 |
+
inv_scale = dk ** -0.5
|
| 686 |
+
# l2norm(x, 1e-6) == rms_norm(x, eps=1e-6/Dk) / sqrt(Dk); q additionally carries the 1/sqrt(Dk) scale
|
| 687 |
+
q = (inv_scale ** 2) * mx.fast.rms_norm(q, None, 1e-6 / dk)
|
| 688 |
+
k = inv_scale * mx.fast.rms_norm(k, None, 1e-6 / dk)
|
| 689 |
+
out, state = gated_delta_update(q, k, v, a, b, self.A_log, self.dt_bias, state, mask,
|
| 690 |
+
use_kernel=not self.training)
|
| 691 |
+
if cache is not None:
|
| 692 |
+
cache[1] = state
|
| 693 |
+
cache.advance(S)
|
| 694 |
+
out = self.norm(out, z)
|
| 695 |
+
return self.out_proj(out.reshape(B, S, -1))
|
| 696 |
+
|
| 697 |
+
|
| 698 |
+
def patch_gdn_l2norm(inner):
|
| 699 |
+
"""Swap every GatedDeltaNet instance of ``inner`` to the HF-exact l2norm class (per instance). -> count."""
|
| 700 |
+
from mlx_lm.models.qwen3_5 import GatedDeltaNet
|
| 701 |
+
cls = type("GatedDeltaNetHFL2", (GatedDeltaNet,), {"__call__": _gdn_hf_call})
|
| 702 |
+
n = 0
|
| 703 |
+
for layer in inner.layers:
|
| 704 |
+
if getattr(layer, "is_linear", False):
|
| 705 |
+
if type(layer.linear_attn) is not GatedDeltaNet:
|
| 706 |
+
raise TypeError(f"unexpected Gated-DeltaNet class {type(layer.linear_attn).__name__}")
|
| 707 |
+
layer.linear_attn.__class__ = cls
|
| 708 |
+
n += 1
|
| 709 |
+
return n
|
| 710 |
+
|
| 711 |
+
|
| 712 |
+
def load_norm_sidecar(path):
|
| 713 |
+
"""{mlx parameter name: FP32 (1 + w)} from macjev_norms_fp32.safetensors (format checked)."""
|
| 714 |
+
import mlx.core as mx
|
| 715 |
+
arrays, meta = mx.load(str(path), return_metadata=True)
|
| 716 |
+
if (meta or {}).get("format") != NORM_SIDECAR_FORMAT:
|
| 717 |
+
raise ValueError(f"{path} is not a {NORM_SIDECAR_FORMAT} norm sidecar (metadata {meta!r})")
|
| 718 |
+
mx.eval(arrays) # read now (mx.load is lazy)
|
| 719 |
+
return arrays
|
| 720 |
+
|
| 721 |
+
|
| 722 |
+
def apply_exact_norms(inner, norms):
|
| 723 |
+
"""Install FP32 (1 + w) into every shifted RMSNorm of ``inner`` (per-instance class swap). -> count.
|
| 724 |
+
Refuses a sidecar that misses a norm, names an unknown module or does not belong to these weights."""
|
| 725 |
+
import mlx.core as mx
|
| 726 |
+
import mlx.nn as nn
|
| 727 |
+
|
| 728 |
+
def _call(self, x):
|
| 729 |
+
return mx.fast.rms_norm(x.astype(mx.float32), self.weight, self.eps).astype(x.dtype)
|
| 730 |
+
|
| 731 |
+
cls = type("RMSNormFP32Weight", (nn.RMSNorm,), {"__call__": _call})
|
| 732 |
+
modules = dict(inner.named_modules())
|
| 733 |
+
seen = set()
|
| 734 |
+
for name, w in norms.items():
|
| 735 |
+
mod_name = name[:-len(".weight")] if name.endswith(".weight") else name
|
| 736 |
+
mod = modules.get(mod_name)
|
| 737 |
+
if mod is None or type(mod) is not nn.RMSNorm:
|
| 738 |
+
raise KeyError(f"norm sidecar entry {name} is not an RMSNorm of this model")
|
| 739 |
+
w = w.astype(mx.float32)
|
| 740 |
+
if w.shape != mod.weight.shape:
|
| 741 |
+
raise ValueError(f"norm sidecar shape mismatch at {name}")
|
| 742 |
+
# the sidecar must be the (1 + w) of THESE weights (up to the bf16 rounding it corrects)
|
| 743 |
+
if float(mx.abs(w - mod.weight.astype(mx.float32)).max()) > 2 ** -7 * float(mx.abs(w).max()) + 1e-6:
|
| 744 |
+
raise ValueError(f"norm sidecar does not match the model weights at {name}")
|
| 745 |
+
mod.weight = w
|
| 746 |
+
mod.__class__ = cls
|
| 747 |
+
seen.add(mod_name)
|
| 748 |
+
missing = [k for k, m in modules.items() if type(m) is nn.RMSNorm and k not in seen
|
| 749 |
+
and (k == "norm" or k.endswith(SHIFTED_NORMS))]
|
| 750 |
+
if missing:
|
| 751 |
+
raise KeyError(f"norm sidecar misses {missing[:3]}")
|
| 752 |
+
mx.eval(inner.parameters())
|
| 753 |
+
return len(seen)
|
| 754 |
+
|
| 755 |
+
|
| 756 |
+
def _block_kv_class():
|
| 757 |
+
from mlx_lm.models.cache import KVCache
|
| 758 |
+
|
| 759 |
+
class BlockKVCache(KVCache):
|
| 760 |
+
"""KV cache whose make_mask is None: the current block attends to all cached keys and to itself
|
| 761 |
+
(Qwen3_5TextModel builds one mask from the first full-attention layer's cache)."""
|
| 762 |
+
|
| 763 |
+
def make_mask(self, *args, **kwargs):
|
| 764 |
+
return None
|
| 765 |
+
|
| 766 |
+
return BlockKVCache
|
| 767 |
+
|
| 768 |
+
|
| 769 |
+
def copy_cache(cache):
|
| 770 |
+
"""Independent copy of a prompt cache (KV + ArraysCache). KV copies are trimmed to ``offset`` (the next
|
| 771 |
+
update re-allocates by concatenation); ArraysCache gets a new list (GDN layers assign new arrays)."""
|
| 772 |
+
import copy
|
| 773 |
+
from mlx_lm.models.cache import ArraysCache, KVCache
|
| 774 |
+
out = []
|
| 775 |
+
for c in cache:
|
| 776 |
+
n = copy.copy(c)
|
| 777 |
+
if isinstance(c, KVCache):
|
| 778 |
+
if c.keys is not None:
|
| 779 |
+
n.keys = c.keys[..., :c.offset, :]
|
| 780 |
+
n.values = c.values[..., :c.offset, :]
|
| 781 |
+
elif isinstance(c, ArraysCache):
|
| 782 |
+
n.cache = list(c.cache)
|
| 783 |
+
if c.lengths is not None or c.left_padding is not None:
|
| 784 |
+
raise ValueError("batched ArraysCache state is not supported")
|
| 785 |
+
else:
|
| 786 |
+
raise TypeError(f"unsupported cache type {type(c).__name__}")
|
| 787 |
+
out.append(n)
|
| 788 |
+
return out
|
| 789 |
+
|
| 790 |
+
|
| 791 |
+
def _set_mlx_cache_limit(mx, gib):
|
| 792 |
+
"""Bound MLX's freed-buffer cache (process-wide); never raises a lower limit set by the host."""
|
| 793 |
+
if gib is None:
|
| 794 |
+
return None
|
| 795 |
+
want = int(float(gib) * (1 << 30))
|
| 796 |
+
prev = mx.set_cache_limit(want)
|
| 797 |
+
if prev is not None and prev < want:
|
| 798 |
+
mx.set_cache_limit(prev)
|
| 799 |
+
return int(prev)
|
| 800 |
+
return want
|
| 801 |
+
|
| 802 |
+
|
| 803 |
+
def _weights_precision(weights_dir):
|
| 804 |
+
"""'bf16' or '8bit' (or '<n>bit') from the MLX config.json of a weights folder."""
|
| 805 |
+
cfg = json.loads((Path(weights_dir) / "config.json").read_text())
|
| 806 |
+
q = cfg.get("quantization") or cfg.get("quantization_config")
|
| 807 |
+
return f"{int(q['bits'])}bit" if q else "bf16"
|
| 808 |
+
|
| 809 |
+
|
| 810 |
+
def _require_weights(w, precision, repo):
|
| 811 |
+
need = ["config.json", "model.safetensors", "tokenizer.json", NORM_SIDECAR]
|
| 812 |
+
miss = [n for n in need if not (w / n).is_file()]
|
| 813 |
+
if miss:
|
| 814 |
+
extra = (f" {NORM_SIDECAR} holds the exact FP32 (1 + w) RMSNorm weights; without it mlx-lm would use "
|
| 815 |
+
f"bf16-rounded norms, so the runtime refuses to load." if NORM_SIDECAR in miss else "")
|
| 816 |
+
raise FileNotFoundError(f"{w} is missing {', '.join(miss)}.{extra} Download the folder with: "
|
| 817 |
+
f"hf download {REPO_ID} --include \"{precision}/*\" --local-dir {repo}")
|
| 818 |
+
|
| 819 |
+
|
| 820 |
+
def resolve_model_dirs(model_dir=HERE, precision=None):
|
| 821 |
+
"""-> (repo_dir, weights_dir, precision).
|
| 822 |
+
|
| 823 |
+
``model_dir`` is the repository folder (holding bf16/ and/or 8bit/ next to readout_config.json),
|
| 824 |
+
or one precision folder itself (then ``precision`` defaults to the precision stored there).
|
| 825 |
+
``precision`` None means "bf16" for a repository folder."""
|
| 826 |
+
if precision is not None and precision not in PRECISIONS:
|
| 827 |
+
raise ValueError(f"precision must be one of {PRECISIONS}, got {precision!r}")
|
| 828 |
+
d = Path(model_dir).resolve()
|
| 829 |
+
# a precision folder given directly (the repository root also holds a config.json, a copy of bf16/config.json,
|
| 830 |
+
# so a folder counts as a precision folder only if it has its own weights or no bf16/ / 8bit/ subfolder)
|
| 831 |
+
if (d / "config.json").is_file() and ((d / "model.safetensors").is_file()
|
| 832 |
+
or not any((d / p).is_dir() for p in PRECISIONS)):
|
| 833 |
+
found = _weights_precision(d)
|
| 834 |
+
if precision is not None and precision != found:
|
| 835 |
+
raise ValueError(f"{d} holds {found} weights, not {precision}")
|
| 836 |
+
repo = d if (d / "readout_config.json").is_file() else d.parent
|
| 837 |
+
_require_weights(d, found, repo)
|
| 838 |
+
return repo, d, found
|
| 839 |
+
precision = precision or DEFAULT_PRECISION
|
| 840 |
+
w = d / precision
|
| 841 |
+
if not ((w / "config.json").is_file() and (w / "model.safetensors").is_file()):
|
| 842 |
+
have = [p for p in PRECISIONS if (d / p / "config.json").is_file() and (d / p / "model.safetensors").is_file()]
|
| 843 |
+
msg = f"the {precision} weights are not in {d} (expected {precision}/config.json and {precision}/model.safetensors)."
|
| 844 |
+
if have:
|
| 845 |
+
msg += f" This folder has only: {', '.join(p + '/' for p in have)}; use --precision {have[0]} (precision=\"{have[0]}\"), or"
|
| 846 |
+
msg += f" download them with: hf download {REPO_ID} --include \"{precision}/*\" --local-dir {d}"
|
| 847 |
+
raise FileNotFoundError(msg)
|
| 848 |
+
found = _weights_precision(w)
|
| 849 |
+
if found != precision:
|
| 850 |
+
raise ValueError(f"{w} holds {found} weights, not {precision}")
|
| 851 |
+
_require_weights(w, precision, d)
|
| 852 |
+
return d, w, precision
|
| 853 |
+
|
| 854 |
+
|
| 855 |
+
def verify_repo(repo_dir, weights_dir):
|
| 856 |
+
"""manifest check of the shared top-level files and of the selected precision folder only (the other
|
| 857 |
+
precision may be absent). Documentation and records (README.md, figures/, validation/) are skipped as in
|
| 858 |
+
verify_manifest."""
|
| 859 |
+
repo_dir, weights_dir = Path(repo_dir), Path(weights_dir)
|
| 860 |
+
if weights_dir == repo_dir:
|
| 861 |
+
return verify_manifest(repo_dir)
|
| 862 |
+
sub = weights_dir.relative_to(repo_dir).as_posix()
|
| 863 |
+
names = json.loads((repo_dir / "manifest.json").read_text())["files"]
|
| 864 |
+
if not any(n.startswith(sub + "/") for n in names):
|
| 865 |
+
return {"ok": False, "checked": 0, "bad": [], "missing": [f"{sub}/ (not listed in manifest.json)"]}
|
| 866 |
+
res = verify_manifest(repo_dir, only=[n for n in names if "/" not in n] + [sub + "/"])
|
| 867 |
+
res["precision_folder"] = sub + "/"
|
| 868 |
+
return res
|
| 869 |
+
|
| 870 |
+
|
| 871 |
+
def release_compute_dtype(repo_dir, precision):
|
| 872 |
+
"""Activation dtype of ``precision`` (release_config.json -> runtime.precisions, else the built-in default)."""
|
| 873 |
+
p = Path(repo_dir) / "release_config.json"
|
| 874 |
+
if p.is_file():
|
| 875 |
+
per = (json.loads(p.read_text()).get("runtime", {}).get("precisions") or {}).get(precision)
|
| 876 |
+
if per is not None and "mlx_compute_dtype" in per:
|
| 877 |
+
return per["mlx_compute_dtype"]
|
| 878 |
+
return VALIDATED_COMPUTE_DTYPE[precision]
|
| 879 |
+
|
| 880 |
+
|
| 881 |
+
class _MLXEngine:
|
| 882 |
+
"""Block-causal v2 scoring on mlx-lm (see the MLX backend comment above). Stateless apart from the last
|
| 883 |
+
state cache (kept so consecutive requests with the same state reuse it)."""
|
| 884 |
+
|
| 885 |
+
def __init__(self, weights_dir, yes_id, no_id, compute_dtype=None, cache_limit_gib=MLX_CACHE_LIMIT_GIB):
|
| 886 |
+
import mlx.core as mx
|
| 887 |
+
check_mlx_lm()
|
| 888 |
+
from mlx_lm.utils import load_model
|
| 889 |
+
self.mx = mx
|
| 890 |
+
self.cache_limit_bytes = _set_mlx_cache_limit(mx, cache_limit_gib)
|
| 891 |
+
norms = load_norm_sidecar(Path(weights_dir) / NORM_SIDECAR)
|
| 892 |
+
self.model, self.config = load_model(Path(weights_dir))
|
| 893 |
+
if compute_dtype:
|
| 894 |
+
self.model.set_dtype(getattr(mx, compute_dtype))
|
| 895 |
+
self.compute_dtype = compute_dtype
|
| 896 |
+
lm = getattr(self.model, "language_model", self.model)
|
| 897 |
+
self.inner = lm.model
|
| 898 |
+
args = getattr(lm, "args", None) or getattr(self.model, "args", None)
|
| 899 |
+
if not bool(getattr(args, "tie_word_embeddings", True)) or hasattr(lm, "lm_head"):
|
| 900 |
+
raise ValueError("expected tied input/output embeddings")
|
| 901 |
+
self.n_gdn_patched = patch_gdn_l2norm(self.inner)
|
| 902 |
+
self.n_norms_exact = apply_exact_norms(self.inner, norms)
|
| 903 |
+
self.n_full_attention = sum(1 for layer in self.inner.layers if not layer.is_linear)
|
| 904 |
+
w = self.inner.embed_tokens(mx.array([int(yes_id), int(no_id)])) # dequantised rows if quantised
|
| 905 |
+
w = w.astype(mx.float32)
|
| 906 |
+
self.direction = w[0] - w[1]
|
| 907 |
+
mx.eval(self.direction)
|
| 908 |
+
self._state = None # (tuple(prefix ids), cache) of the last state
|
| 909 |
+
|
| 910 |
+
def _make_cache(self):
|
| 911 |
+
from mlx_lm.models.cache import ArraysCache
|
| 912 |
+
kv = _block_kv_class()
|
| 913 |
+
return [ArraysCache(size=2) if layer.is_linear else kv() for layer in self.inner.layers]
|
| 914 |
+
|
| 915 |
+
def _eval_cache(self, cache):
|
| 916 |
+
arrays = []
|
| 917 |
+
for c in cache:
|
| 918 |
+
if hasattr(c, "keys"):
|
| 919 |
+
if c.keys is not None:
|
| 920 |
+
arrays += [c.keys, c.values]
|
| 921 |
+
else:
|
| 922 |
+
arrays += [a for a in c.cache if a is not None]
|
| 923 |
+
self.mx.eval(arrays)
|
| 924 |
+
|
| 925 |
+
def state_cache(self, prefix, blocks):
|
| 926 |
+
"""Cache after the state blocks (computed once; reused while the state is unchanged). -> (cache, reused)"""
|
| 927 |
+
key = tuple(prefix)
|
| 928 |
+
if self._state is not None and self._state[0] == key:
|
| 929 |
+
return self._state[1], True
|
| 930 |
+
self._state = None
|
| 931 |
+
cache = self._make_cache()
|
| 932 |
+
for a, b in blocks:
|
| 933 |
+
self.inner(self.mx.array(prefix[a:b])[None], cache=cache)
|
| 934 |
+
self._eval_cache(cache)
|
| 935 |
+
self._state = (key, cache)
|
| 936 |
+
return cache, False
|
| 937 |
+
|
| 938 |
+
def question_scores(self, ids, slots, qblocks, state_cache):
|
| 939 |
+
"""Question block(s) on a copy of the state cache -> raw FP32 scores, one per slot (rendered order)."""
|
| 940 |
+
mx = self.mx
|
| 941 |
+
cache = copy_cache(state_cache)
|
| 942 |
+
found = {}
|
| 943 |
+
for i, (a, b) in enumerate(qblocks):
|
| 944 |
+
h = self.inner(mx.array(ids[a:b])[None], cache=cache)[0]
|
| 945 |
+
inside = [(j, s) for j, s in enumerate(slots) if a <= s < b]
|
| 946 |
+
if inside:
|
| 947 |
+
hs = h[mx.array([s - a for _, s in inside])].astype(mx.float32)
|
| 948 |
+
v = hs @ self.direction
|
| 949 |
+
mx.eval(v)
|
| 950 |
+
for (j, _), x in zip(inside, v.tolist()):
|
| 951 |
+
found[j] = x
|
| 952 |
+
if i + 1 < len(qblocks):
|
| 953 |
+
self._eval_cache(cache)
|
| 954 |
+
if len(found) != len(slots):
|
| 955 |
+
raise RuntimeError("a verdict slot lies outside the question blocks")
|
| 956 |
+
return [float(found[j]) for j in range(len(slots))]
|
| 957 |
+
|
| 958 |
+
def reset(self):
|
| 959 |
+
self._state = None
|
| 960 |
+
|
| 961 |
+
def close(self):
|
| 962 |
+
self._state = None
|
| 963 |
+
self.mx.clear_cache()
|
| 964 |
+
|
| 965 |
+
|
| 966 |
+
def _check_blocks(r):
|
| 967 |
+
"""The protocol invariants a backend relies on: blocks tile [0, n) in order, each <= BLOCK tokens, the
|
| 968 |
+
state ends on a block boundary, every slot lies in a question block."""
|
| 969 |
+
n, p, end = len(r.ids), r.prefix_len, 0
|
| 970 |
+
for a, b in r.blocks:
|
| 971 |
+
if a != end or not a < b <= n or b - a > BLOCK:
|
| 972 |
+
raise ValueError(f"invalid block layout {r.blocks}")
|
| 973 |
+
end = b
|
| 974 |
+
sb, qb = r.state_blocks, r.question_blocks
|
| 975 |
+
if end != n or len(sb) + len(qb) != len(r.blocks) or (sb and sb[-1][1] != p) or not qb:
|
| 976 |
+
raise ValueError(f"invalid block layout {r.blocks} (prefix {p}, {n} tokens)")
|
| 977 |
+
if any(not qb[0][0] <= s < n for s in r.slots):
|
| 978 |
+
raise ValueError("verdict slots must lie in the question blocks")
|
| 979 |
+
|
| 980 |
+
|
| 981 |
+
class JevStyleDecisionMLX(DecisionBase):
|
| 982 |
+
"""Apple-silicon runtime on mlx / mlx-lm 0.31.3 (qwen3_5 model code, two numerics corrections).
|
| 983 |
+
|
| 984 |
+
``model_dir``: the repository folder (default: the folder of this script) holding bf16/ and/or 8bit/ next to
|
| 985 |
+
readout_config.json, or one precision folder. ``precision``: "bf16" (default) or "8bit".
|
| 986 |
+
``temperature``: overrides the calibrated global temperature for every call (default: readout_config.json).
|
| 987 |
+
``compute_dtype``: "release" (default) = the activation dtype of the chosen precision in release_config.json
|
| 988 |
+
(native bf16 activations for both precisions); "float32" or None (native) override it.
|
| 989 |
+
``max_len``: total token budget (<= 25,600). ``verify``: re-hash the files in manifest.json before loading.
|
| 990 |
+
|
| 991 |
+
The most recent state stays computed: score_many() and consecutive calls / JSONL rows with an identical
|
| 992 |
+
state reuse it (``last_timing["state_reused"]``)."""
|
| 993 |
+
backend = "mlx"
|
| 994 |
+
|
| 995 |
+
def __init__(self, model_dir=HERE, precision=None, temperature=None, max_len=CONTEXT_LIMIT,
|
| 996 |
+
compute_dtype="release", cache_limit_gib=MLX_CACHE_LIMIT_GIB, verify=False):
|
| 997 |
+
repo_dir, weights_dir, precision = resolve_model_dirs(model_dir, precision)
|
| 998 |
+
self.repo_dir, self.weights_dir, self.precision = repo_dir, weights_dir, precision
|
| 999 |
+
if not (repo_dir / "readout_config.json").is_file():
|
| 1000 |
+
raise FileNotFoundError(f"readout_config.json (readout + calibration temperature) is not in {repo_dir}; "
|
| 1001 |
+
f"the runtime does not guess a temperature. Download it with: hf download "
|
| 1002 |
+
f"{REPO_ID} readout_config.json release_config.json --local-dir {repo_dir}")
|
| 1003 |
+
if verify:
|
| 1004 |
+
res = verify_repo(repo_dir, weights_dir)
|
| 1005 |
+
if not res["ok"]:
|
| 1006 |
+
raise RuntimeError(f"integrity check failed: {res}")
|
| 1007 |
+
self._setup(repo_dir, weights_dir / "tokenizer.json", max_len, temperature)
|
| 1008 |
+
if compute_dtype == "release":
|
| 1009 |
+
compute_dtype = release_compute_dtype(repo_dir, precision)
|
| 1010 |
+
if compute_dtype not in (None, "float32", "bfloat16", "float16"):
|
| 1011 |
+
raise ValueError(f"unsupported compute_dtype {compute_dtype!r}")
|
| 1012 |
+
self.engine = _MLXEngine(weights_dir, self.renderer.yes, self.renderer.no, compute_dtype, cache_limit_gib)
|
| 1013 |
+
self.compute_dtype = compute_dtype
|
| 1014 |
+
self.last_timing = {}
|
| 1015 |
+
|
| 1016 |
+
def _scores_many(self, rendered):
|
| 1017 |
+
import time
|
| 1018 |
+
for r in rendered:
|
| 1019 |
+
_check_blocks(r)
|
| 1020 |
+
r0 = rendered[0]
|
| 1021 |
+
t0 = time.perf_counter()
|
| 1022 |
+
cache, reused = self.engine.state_cache(r0.ids[:r0.prefix_len], r0.state_blocks)
|
| 1023 |
+
t1 = time.perf_counter()
|
| 1024 |
+
out = [self.engine.question_scores(r.ids, r.slots, r.question_blocks, cache) for r in rendered]
|
| 1025 |
+
self.last_timing = {"state_tokens": r0.prefix_len, "state_reused": reused, "state_ms": (t1 - t0) * 1000,
|
| 1026 |
+
"questions": len(rendered), "questions_ms": (time.perf_counter() - t1) * 1000}
|
| 1027 |
+
return out
|
| 1028 |
+
|
| 1029 |
+
def close(self):
|
| 1030 |
+
self.engine.close()
|
| 1031 |
+
|
| 1032 |
+
|
| 1033 |
+
def main(argv=None):
|
| 1034 |
+
ap = base_arg_parser(f"{MODEL_NAME}: typed decisions with MLX (Apple silicon)")
|
| 1035 |
+
for a in ap._actions:
|
| 1036 |
+
if a.dest == "model_dir":
|
| 1037 |
+
a.help = ("repository folder holding bf16/ and/or 8bit/ next to readout_config.json (default: the "
|
| 1038 |
+
"folder of this script), or one precision folder")
|
| 1039 |
+
ap.add_argument("--precision", choices=PRECISIONS, default=None,
|
| 1040 |
+
help="weights to load: bf16 (default) or 8bit (affine 8-bit, group 64)")
|
| 1041 |
+
ap.add_argument("--compute-dtype", default="release", choices=["release", "float32", "native"],
|
| 1042 |
+
help="activation dtype: the release setting of the precision (release = native), float32, or "
|
| 1043 |
+
"the checkpoint's native dtype")
|
| 1044 |
+
ap.add_argument("--cache-limit-gib", type=float, default=MLX_CACHE_LIMIT_GIB)
|
| 1045 |
+
args = ap.parse_args(argv)
|
| 1046 |
+
cdt = None if args.compute_dtype == "native" else args.compute_dtype
|
| 1047 |
+
try:
|
| 1048 |
+
engine = JevStyleDecisionMLX(args.model_dir, precision=args.precision, max_len=args.max_len,
|
| 1049 |
+
compute_dtype=cdt, cache_limit_gib=args.cache_limit_gib, verify=args.verify)
|
| 1050 |
+
except (FileNotFoundError, ValueError, MLXVersionError, RuntimeError, ImportError) as e:
|
| 1051 |
+
raise SystemExit(f"error: {e}")
|
| 1052 |
+
try:
|
| 1053 |
+
return run_cli(args, engine)
|
| 1054 |
+
finally:
|
| 1055 |
+
engine.close()
|
| 1056 |
+
|
| 1057 |
+
|
| 1058 |
+
if __name__ == "__main__":
|
| 1059 |
+
raise SystemExit(main())
|
manifest.json
ADDED
|
@@ -0,0 +1,190 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"format": "jev-style-manifest-v1",
|
| 3 |
+
"repo": "chaoliangUNSW/Jev-Style-2B-Decision-v3-MLX",
|
| 4 |
+
"created_unix": 1790476271.175225,
|
| 5 |
+
"files": {
|
| 6 |
+
"8bit/chat_template.jinja": {
|
| 7 |
+
"sha256": "273d8e0e683b885071fb17e08d71e5f2a5ddfb5309756181681de4f5a1822d80",
|
| 8 |
+
"bytes": 7755
|
| 9 |
+
},
|
| 10 |
+
"8bit/config.json": {
|
| 11 |
+
"sha256": "8865dd86a4e561e6b036667cd0d5c1c39ad12527b3feda7c585cf116d890477a",
|
| 12 |
+
"bytes": 2205
|
| 13 |
+
},
|
| 14 |
+
"8bit/generation_config.json": {
|
| 15 |
+
"sha256": "62153eb6c69f2e1f426beaa8002b7186437e949c7588167085df14e10e9c0a73",
|
| 16 |
+
"bytes": 116
|
| 17 |
+
},
|
| 18 |
+
"8bit/macjev_norms_fp32.safetensors": {
|
| 19 |
+
"sha256": "02f08c422228929c44dd84856678ea95d41401138aa56b1b771a654376d3e51c",
|
| 20 |
+
"bytes": 420112
|
| 21 |
+
},
|
| 22 |
+
"8bit/model.safetensors": {
|
| 23 |
+
"sha256": "184b4dda2f1285fe95a00a6271b364c861d370fbf913030f0259b2423f88a740",
|
| 24 |
+
"bytes": 2000043057
|
| 25 |
+
},
|
| 26 |
+
"8bit/model.safetensors.index.json": {
|
| 27 |
+
"sha256": "54d94d008c07e39846c0b454f68055622bb635a0623b51bce86d724e18733aab",
|
| 28 |
+
"bytes": 60786
|
| 29 |
+
},
|
| 30 |
+
"8bit/tokenizer.json": {
|
| 31 |
+
"sha256": "06b9509352d2af50381ab2247e083b80d32d5c0aba91c272ca9ff729b6a0e523",
|
| 32 |
+
"bytes": 19989325
|
| 33 |
+
},
|
| 34 |
+
"8bit/tokenizer_config.json": {
|
| 35 |
+
"sha256": "95c557768e6b88a7128befc7bfd3c7de50e5d51af9b8b33a9f4dee0e04f99679",
|
| 36 |
+
"bytes": 1161
|
| 37 |
+
},
|
| 38 |
+
"LICENSE": {
|
| 39 |
+
"sha256": "bbedc3fda3305820b977265f01b8619d87570a6739de3a5582c3464840f1e57a",
|
| 40 |
+
"bytes": 11544
|
| 41 |
+
},
|
| 42 |
+
"NOTICE": {
|
| 43 |
+
"sha256": "39ce15275bd1433d18dd09066e9045529a3c7f1a8c3e761d3f318041167e9fed",
|
| 44 |
+
"bytes": 2664
|
| 45 |
+
},
|
| 46 |
+
"README.md": {
|
| 47 |
+
"sha256": "965607319a7721d4eb497128179a740b2c9ca9516761c028c44fa8c6b4d20733",
|
| 48 |
+
"bytes": 13399
|
| 49 |
+
},
|
| 50 |
+
"THIRD_PARTY_NOTICES.md": {
|
| 51 |
+
"sha256": "55ade7a70bb6bfcb8f0a8e9f4aef9222cde16c8bb44b6135aab6f929c706cbc5",
|
| 52 |
+
"bytes": 2146
|
| 53 |
+
},
|
| 54 |
+
"bf16/chat_template.jinja": {
|
| 55 |
+
"sha256": "273d8e0e683b885071fb17e08d71e5f2a5ddfb5309756181681de4f5a1822d80",
|
| 56 |
+
"bytes": 7755
|
| 57 |
+
},
|
| 58 |
+
"bf16/config.json": {
|
| 59 |
+
"sha256": "1dd31077b37706dc40e1bbddedf5eeba3e50e1d3c85d1fe34bfd5957a8d6ad14",
|
| 60 |
+
"bytes": 2000
|
| 61 |
+
},
|
| 62 |
+
"bf16/generation_config.json": {
|
| 63 |
+
"sha256": "62153eb6c69f2e1f426beaa8002b7186437e949c7588167085df14e10e9c0a73",
|
| 64 |
+
"bytes": 116
|
| 65 |
+
},
|
| 66 |
+
"bf16/macjev_norms_fp32.safetensors": {
|
| 67 |
+
"sha256": "a30e1a72d02598b405978c0eff08c3bfca3b523fa0b3d4b4c80d2a185e0b8081",
|
| 68 |
+
"bytes": 420112
|
| 69 |
+
},
|
| 70 |
+
"bf16/model.safetensors": {
|
| 71 |
+
"sha256": "00629c8d17ea115c21c3fc0d6ddc5d4aa02887343a8ff3b3cf79ab197624d574",
|
| 72 |
+
"bytes": 3763691755
|
| 73 |
+
},
|
| 74 |
+
"bf16/model.safetensors.index.json": {
|
| 75 |
+
"sha256": "d49d69fd9257879080337533c6051a14ff4f561a79b9f70d8bdb74e47444a306",
|
| 76 |
+
"bytes": 28024
|
| 77 |
+
},
|
| 78 |
+
"bf16/tokenizer.json": {
|
| 79 |
+
"sha256": "06b9509352d2af50381ab2247e083b80d32d5c0aba91c272ca9ff729b6a0e523",
|
| 80 |
+
"bytes": 19989325
|
| 81 |
+
},
|
| 82 |
+
"bf16/tokenizer_config.json": {
|
| 83 |
+
"sha256": "95c557768e6b88a7128befc7bfd3c7de50e5d51af9b8b33a9f4dee0e04f99679",
|
| 84 |
+
"bytes": 1161
|
| 85 |
+
},
|
| 86 |
+
"config.json": {
|
| 87 |
+
"sha256": "1dd31077b37706dc40e1bbddedf5eeba3e50e1d3c85d1fe34bfd5957a8d6ad14",
|
| 88 |
+
"bytes": 2000
|
| 89 |
+
},
|
| 90 |
+
"figures/banner.data.json": {
|
| 91 |
+
"sha256": "397cbfb222986f8d59a65143f2fec5a11170385c661a86c5e54d890a24d7d89e",
|
| 92 |
+
"bytes": 1109
|
| 93 |
+
},
|
| 94 |
+
"figures/banner.png": {
|
| 95 |
+
"sha256": "2623e4afad36239aaa007c34350d6f2fbacb33430ffd3c36ce2f7ee7db849b47",
|
| 96 |
+
"bytes": 447467
|
| 97 |
+
},
|
| 98 |
+
"figures/jevbench.data.json": {
|
| 99 |
+
"sha256": "508994afea8d8b1bc33e25c675621a9b3b55b01f900daa688c240c8356dffe3b",
|
| 100 |
+
"bytes": 2387
|
| 101 |
+
},
|
| 102 |
+
"figures/jevbench.png": {
|
| 103 |
+
"sha256": "c8542dba9ecc1bd2a4ea3bda844cbc3fbd661c40d6eb9254098b279a92a74ce8",
|
| 104 |
+
"bytes": 167843
|
| 105 |
+
},
|
| 106 |
+
"figures/jevbench.svg": {
|
| 107 |
+
"sha256": "13193f8d636ad5e6685cbc58863f27bced87c0ead94c252917839c7c6eed837e",
|
| 108 |
+
"bytes": 12280
|
| 109 |
+
},
|
| 110 |
+
"figures/zeroshot.data.json": {
|
| 111 |
+
"sha256": "3ad81c3dc926c988db5c339eec4991c2e2cce46faafb89db99cc47d6d8737538",
|
| 112 |
+
"bytes": 1841
|
| 113 |
+
},
|
| 114 |
+
"figures/zeroshot.png": {
|
| 115 |
+
"sha256": "d51f9a7bc46b88d8dcf5ba46f15d479c781302ca531208ff0838106da8aae755",
|
| 116 |
+
"bytes": 137714
|
| 117 |
+
},
|
| 118 |
+
"figures/zeroshot.svg": {
|
| 119 |
+
"sha256": "f3234ba4715b0d87e081ec9fc52c0b409010612f54db7aa39307a9eda3b7545f",
|
| 120 |
+
"bytes": 13874
|
| 121 |
+
},
|
| 122 |
+
"jev_style_decision_mlx.py": {
|
| 123 |
+
"sha256": "025daab9b374d740e743c519bd3aa3385791e08c81f4515b2ae525af57788030",
|
| 124 |
+
"bytes": 54020
|
| 125 |
+
},
|
| 126 |
+
"readout_config.json": {
|
| 127 |
+
"sha256": "4af0d578c9126d4eb1a545b6e576e0a49a967243a47b8e99e3555f081fdaa1de",
|
| 128 |
+
"bytes": 2031
|
| 129 |
+
},
|
| 130 |
+
"release_config.json": {
|
| 131 |
+
"sha256": "eddb00c6bf6682f3f62d0c69ffa3ef3820454abd8bea092c7ecddece55f5b551",
|
| 132 |
+
"bytes": 17829
|
| 133 |
+
},
|
| 134 |
+
"requirements.txt": {
|
| 135 |
+
"sha256": "2dd1d057db2c4f0d906e3665745e85d4647be032e1ffd2cc94cea2db2104c329",
|
| 136 |
+
"bytes": 479
|
| 137 |
+
},
|
| 138 |
+
"validation/SOURCES.json": {
|
| 139 |
+
"sha256": "fa8510c5c1f3afbdb01a3da6f26500cfa3117b8f4e26ceaf788fbf1eca9a5639",
|
| 140 |
+
"bytes": 3165
|
| 141 |
+
},
|
| 142 |
+
"validation/latency_2b.json": {
|
| 143 |
+
"sha256": "458d00e0c81b3165072b8547278e6039b9ae0d45d54b7421008ef24c1d24ca3d",
|
| 144 |
+
"bytes": 40294
|
| 145 |
+
},
|
| 146 |
+
"validation/parity/PREDECLARED_RELEASE_GATES_2B.md": {
|
| 147 |
+
"sha256": "783aec77300779582911cdc57c71cf8b101b0cd5ca040073f7e1fa3ac20af08e",
|
| 148 |
+
"bytes": 2619
|
| 149 |
+
},
|
| 150 |
+
"validation/parity/compare_mlx_affine8-g64_base_vs_block.json": {
|
| 151 |
+
"sha256": "e1911f21ce73dd42d6c57e8349e2ec3221386a2b44ca461a3e50b9a69057ec34",
|
| 152 |
+
"bytes": 7697
|
| 153 |
+
},
|
| 154 |
+
"validation/parity/compare_mlx_affine8-g64_gate_vs_block.json": {
|
| 155 |
+
"sha256": "f0e2f44498df00945901c2a9bd5bff6f742d11ab243495c8089eaf0448fda782",
|
| 156 |
+
"bytes": 6494
|
| 157 |
+
},
|
| 158 |
+
"validation/parity/compare_mlx_bf16_base_vs_block.json": {
|
| 159 |
+
"sha256": "ca16e5281debaf1bc601b4a8c93cf6c1106f7b032f35c5833baa4fc8178def7c",
|
| 160 |
+
"bytes": 7408
|
| 161 |
+
},
|
| 162 |
+
"validation/parity/compare_mlx_bf16_gate_vs_block.json": {
|
| 163 |
+
"sha256": "7fa30fa414a4ffc12a7aa6371e77579845c3b816b90da3a813a70fec10ccd9fb",
|
| 164 |
+
"bytes": 6410
|
| 165 |
+
},
|
| 166 |
+
"validation/parity/cross_format_dp.json": {
|
| 167 |
+
"sha256": "c7332df0f02244416b01e49ecb037c76d4bf2643a2b42505ff1dfe896879e533",
|
| 168 |
+
"bytes": 1550
|
| 169 |
+
},
|
| 170 |
+
"validation/runtime/fixture_verify_8bit.json": {
|
| 171 |
+
"sha256": "305cc657c5ebd539ce92e3fbe7db36c594e40a0566d185b36dc858e338025d01",
|
| 172 |
+
"bytes": 3078
|
| 173 |
+
},
|
| 174 |
+
"validation/runtime/fixture_verify_bf16.json": {
|
| 175 |
+
"sha256": "87766f14dfdf9ac1d6d97692e523e3942329b4431615a46322992d1dbf315c63",
|
| 176 |
+
"bytes": 3077
|
| 177 |
+
},
|
| 178 |
+
"validation/runtime/render_verify.json": {
|
| 179 |
+
"sha256": "5333dd7e4083de7e80bd98b4da4d0965c2835782a37e836d55d0e09a26c4f8c1",
|
| 180 |
+
"bytes": 1550
|
| 181 |
+
},
|
| 182 |
+
"validation/runtime/reverify_mlx.json": {
|
| 183 |
+
"sha256": "1f6f62c8b66e8df2f738acfd96667ef746f9504328e603bdeaa848156ddf22bf",
|
| 184 |
+
"bytes": 963
|
| 185 |
+
}
|
| 186 |
+
},
|
| 187 |
+
"readme_hashed": true,
|
| 188 |
+
"readme_placeholder": false,
|
| 189 |
+
"note": "manifest.json hashes every file of the repo except itself, README.md, figures/ and validation/ included. The runtime --verify check (jev_style_decision_mlx.py) checks the top-level files (except README.md) and the selected precision folder (bf16/ or 8bit/), so either folder may be downloaded alone; README.md, figures/ and validation/ are not checked."
|
| 190 |
+
}
|
readout_config.json
ADDED
|
@@ -0,0 +1,47 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"format": "macjev-readout-v2",
|
| 3 |
+
"model_name": "Jev-Style-2B-Decision-v3",
|
| 4 |
+
"readout": "verdict",
|
| 5 |
+
"template": "macjev-render-v2-long-options",
|
| 6 |
+
"layout": "sb",
|
| 7 |
+
"block_size": 2048,
|
| 8 |
+
"total_context_limit": 25600,
|
| 9 |
+
"question_option_limit": null,
|
| 10 |
+
"slot_tokens": {
|
| 11 |
+
"yes": {
|
| 12 |
+
"text": " yes",
|
| 13 |
+
"id": 9542
|
| 14 |
+
},
|
| 15 |
+
"no": {
|
| 16 |
+
"text": " no",
|
| 17 |
+
"id": 874
|
| 18 |
+
},
|
| 19 |
+
"verdict_slot": {
|
| 20 |
+
"text": " ->",
|
| 21 |
+
"id": 1411
|
| 22 |
+
}
|
| 23 |
+
},
|
| 24 |
+
"attention": "block-causal in the 6 full-attention layers: the input is cut into [start, stop) blocks of at most block_size tokens (state blocks; one short question block, or catalogue blocks + rubric blocks when question + options + slots exceed block_size); every block attends to all earlier tokens and to itself with no causal mask inside the block. Gated-DeltaNet layers are ordinary recurrent layers.",
|
| 25 |
+
"score": "per option k: logit[' yes'] - logit[' no'] at the k-th ' ->' slot, computed as h_slot . (w_yes - w_no) from the final normed hidden state and the tied embedding rows (float32)",
|
| 26 |
+
"probabilities": "softmax(scores / T) in canonical option order; T = temperatures.global (one global temperature)",
|
| 27 |
+
"tokenizer_sha256": "06b9509352d2af50381ab2247e083b80d32d5c0aba91c272ca9ff729b6a0e523",
|
| 28 |
+
"budgets": {
|
| 29 |
+
"max_len": 25600,
|
| 30 |
+
"question_option_limit": null,
|
| 31 |
+
"note": "the complete input (state + question + options + readout) <= max_len tokens; there is no separate question/options cap; larger inputs raise InputBudgetError, nothing is truncated"
|
| 32 |
+
},
|
| 33 |
+
"temperatures": {
|
| 34 |
+
"version": "macjev-temperature-v2-global",
|
| 35 |
+
"global": 0.8278650620942867,
|
| 36 |
+
"groups": null,
|
| 37 |
+
"groups_note": "none: this model has one global temperature (no category / family / option-count temperatures)",
|
| 38 |
+
"fitted_on": "2,000 independent calibration rows (not dev, not test)",
|
| 39 |
+
"n_rows": 2000,
|
| 40 |
+
"fit_quality": {
|
| 41 |
+
"nll_before": 0.3002617012172898,
|
| 42 |
+
"nll_after": 0.2900580002426921,
|
| 43 |
+
"n": 2000
|
| 44 |
+
},
|
| 45 |
+
"selected_weights": "ema"
|
| 46 |
+
}
|
| 47 |
+
}
|
release_config.json
ADDED
|
@@ -0,0 +1,422 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"format": "jev-style-release-v1",
|
| 3 |
+
"model_name": "Jev-Style-2B-Decision-v3",
|
| 4 |
+
"repo": "chaoliangUNSW/Jev-Style-2B-Decision-v3-MLX",
|
| 5 |
+
"generation": "v3 (third generation of the Jev-Style decision series)",
|
| 6 |
+
"lineage": {
|
| 7 |
+
"v1": "chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision",
|
| 8 |
+
"v1_public_gguf": "chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision-GGUF",
|
| 9 |
+
"v2": "chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision-v2",
|
| 10 |
+
"v3_0.8b": "chaoliangUNSW/Jev-Style-0.8B-Decision-v3",
|
| 11 |
+
"v3_2b": "chaoliangUNSW/Jev-Style-2B-Decision-v3"
|
| 12 |
+
},
|
| 13 |
+
"base_model": "Qwen/Qwen3.5-2B",
|
| 14 |
+
"base_model_revision": "15852e8c16360a2fea060d615a32b45270f8a8fc",
|
| 15 |
+
"base_model_relation": "finetune",
|
| 16 |
+
"architecture": "Qwen3_5ForCausalLM (text only, 24 layers: 18 Gated DeltaNet + 6 full attention, hidden 2048, tied embeddings)",
|
| 17 |
+
"readout": "verdict",
|
| 18 |
+
"template": "macjev-render-v2-long-options",
|
| 19 |
+
"layout": "sb",
|
| 20 |
+
"attention": "block-causal (2,048-token blocks) in the full-attention layers; see readout_config.json -> attention",
|
| 21 |
+
"readout_config": "readout_config.json",
|
| 22 |
+
"budgets": {
|
| 23 |
+
"max_len": 25600,
|
| 24 |
+
"block_size": 2048,
|
| 25 |
+
"question_option_limit": null
|
| 26 |
+
},
|
| 27 |
+
"source": {
|
| 28 |
+
"checkpoint_sha256": {
|
| 29 |
+
"model-00001-of-00002.safetensors": "df592f869cb1232226d31491b783bfa9406ffb3c795eae44a3b7452e1044a8fb",
|
| 30 |
+
"model-00002-of-00002.safetensors": "c6ff77a32a8cf36767e51c1282bb345a873db6509847f6c75baadd8fb17eeb70"
|
| 31 |
+
},
|
| 32 |
+
"selected_weights": "ema",
|
| 33 |
+
"mlx": "0.32.2",
|
| 34 |
+
"mlx_lm": "0.31.3",
|
| 35 |
+
"exports_manifest": {
|
| 36 |
+
"file": "runs/macjev/release_2b/exports_manifest.json",
|
| 37 |
+
"sha256": "11c549e479c7022c960c546730d6a3c42957c1c40b1b8901a183a893917d96a5",
|
| 38 |
+
"note": "sha256 / bytes of the exported GGUF and MLX files (release_2b/build_exports.py)"
|
| 39 |
+
},
|
| 40 |
+
"candidate_sha256sums": {
|
| 41 |
+
"file": "runs/macjev/candidate_2b/hf-candidate/SHA256SUMS.json",
|
| 42 |
+
"sha256": "7549ed3fe6239b2862998798d8da1457fdced25cd424aa4442557ae852d6e696"
|
| 43 |
+
}
|
| 44 |
+
},
|
| 45 |
+
"calibration": {
|
| 46 |
+
"version": "macjev-temperature-v2-global",
|
| 47 |
+
"global_T": 0.8278650620942867,
|
| 48 |
+
"groups": null,
|
| 49 |
+
"n_rows": 2000,
|
| 50 |
+
"fit_quality": {
|
| 51 |
+
"nll_before": 0.3002617012172898,
|
| 52 |
+
"nll_after": 0.2900580002426921,
|
| 53 |
+
"n": 2000
|
| 54 |
+
},
|
| 55 |
+
"fitted_on": "2,000 independent calibration rows (not dev, not test)"
|
| 56 |
+
},
|
| 57 |
+
"related_repos": {
|
| 58 |
+
"main": "chaoliangUNSW/Jev-Style-2B-Decision-v3",
|
| 59 |
+
"gguf": "chaoliangUNSW/Jev-Style-2B-Decision-v3-GGUF",
|
| 60 |
+
"mlx": "chaoliangUNSW/Jev-Style-2B-Decision-v3-MLX"
|
| 61 |
+
},
|
| 62 |
+
"tested_with": {
|
| 63 |
+
"python": "3.12",
|
| 64 |
+
"mlx": "0.32.2",
|
| 65 |
+
"mlx-lm": "0.31.3",
|
| 66 |
+
"tokenizers": "0.23.2",
|
| 67 |
+
"numpy": "2.5.3"
|
| 68 |
+
},
|
| 69 |
+
"weights": {
|
| 70 |
+
"bf16/model.safetensors": "bfloat16",
|
| 71 |
+
"8bit/model.safetensors": "mlx affine 8-bit, group 64",
|
| 72 |
+
"*/macjev_norms_fp32.safetensors": "exact FP32 (1 + w) of the 61 shifted Qwen3.5 RMSNorms (format macjev-norms-fp32-v1); required by the runtime"
|
| 73 |
+
},
|
| 74 |
+
"runtime": {
|
| 75 |
+
"script": "jev_style_decision_mlx.py",
|
| 76 |
+
"class": "JevStyleDecisionMLX",
|
| 77 |
+
"precision_argument": "--precision bf16|8bit (Python: precision=...)",
|
| 78 |
+
"default_precision": "bf16",
|
| 79 |
+
"mlx_cache_limit_gib": 2.0,
|
| 80 |
+
"mlx_lm_required": "0.31.3 (exact; the runtime checks the sha256 of the mlx-lm source it patches and refuses other versions)",
|
| 81 |
+
"mlx_lm_corrections": {
|
| 82 |
+
"gdn_qk_l2norm": "Gated-DeltaNet q/k normalised with l2norm eps 1e-6 (HF / fla / llama.cpp) instead of mlx-lm's rms_norm eps 1e-6 (= l2norm eps Dk*1e-6); per-instance class swap",
|
| 83 |
+
"rmsnorm_fp32_shift": "Qwen3.5 (1 + w) RMSNorm weights taken in FP32 from macjev_norms_fp32.safetensors instead of the bf16-rounded (1 + w) stored by mlx-lm's converter; norms computed in FP32 and cast back"
|
| 84 |
+
},
|
| 85 |
+
"state_reuse": "score_many(state, questions) computes the state blocks once and runs every question on a copy of that cache; the last state is kept, so consecutive calls / JSONL rows with an identical state reuse it",
|
| 86 |
+
"shared_files": "readout_config.json (readout + calibration temperature), release_config.json and manifest.json are shared by both precisions; each precision folder has its own config.json, tokenizer, weights and norm sidecar",
|
| 87 |
+
"precisions": {
|
| 88 |
+
"bf16": {
|
| 89 |
+
"folder": "bf16/",
|
| 90 |
+
"weights": "bfloat16",
|
| 91 |
+
"mlx_compute_dtype": null,
|
| 92 |
+
"mlx_compute_dtype_note": "native activations (bf16 residual stream; norms and readout in FP32), the setting the release scoring used"
|
| 93 |
+
},
|
| 94 |
+
"8bit": {
|
| 95 |
+
"folder": "8bit/",
|
| 96 |
+
"weights": "mlx affine 8-bit, group 64",
|
| 97 |
+
"mlx_compute_dtype": null,
|
| 98 |
+
"mlx_compute_dtype_note": "native activations, the setting the release scoring used"
|
| 99 |
+
}
|
| 100 |
+
},
|
| 101 |
+
"removed_vs_0.8b_runtime": {
|
| 102 |
+
"--category": "no group temperatures: one global temperature",
|
| 103 |
+
"--head-max": "no question/options cap: only the 25,600-token total budget; long question+options use the catalogue-overflow layout",
|
| 104 |
+
"option chunking": "not needed: all options are always scored in one input"
|
| 105 |
+
}
|
| 106 |
+
},
|
| 107 |
+
"format_gates": {
|
| 108 |
+
"predeclared": {
|
| 109 |
+
"file": "runs/macjev/runtime_v2_dev/PREDECLARED_RELEASE_GATES_2B.md",
|
| 110 |
+
"sha256": "783aec77300779582911cdc57c71cf8b101b0cd5ca040073f7e1fa3ac20af08e",
|
| 111 |
+
"gates": "F16/bf16 top-1 >= 0.99; 8-bit top-1 >= 0.98; |dNLL| <= 0.02; accuracy drop Q8_0 / MLX-8bit <= 0.3 pp, Q4_K_M <= 1.0 pp (4-bit top-1 / NLL report-only); no non-finite scores"
|
| 112 |
+
},
|
| 113 |
+
"reference": {
|
| 114 |
+
"what": "HF transformers FP32 on CPU, exact v2 block attention, released bf16 checkpoint (runs/macjev/candidate_2b/hf-candidate)",
|
| 115 |
+
"temperature": 0.8278650620942867
|
| 116 |
+
},
|
| 117 |
+
"fixtures": {
|
| 118 |
+
"gate": {
|
| 119 |
+
"what": "1,000 real dev rows (<= 4,096 tokens); decides the release gates",
|
| 120 |
+
"file": "runs/macjev/runtime_v2_dev/reference/gate_fixture_n1000.jsonl",
|
| 121 |
+
"sha256": "1c03b8c570b988b0c83ca1f79e7fd37e6196239a0836f348300c3f23ae667b68"
|
| 122 |
+
},
|
| 123 |
+
"long": {
|
| 124 |
+
"what": "35 requests / 43 questions up to 25,600 tokens incl. catalogue overflow and K <= 151; accuracy gate unresolvable on 43 questions (verdict INCONCLUSIVE means only that), top-1 / dNLL reported",
|
| 125 |
+
"file": "runs/macjev/runtime_v2_dev/reference_base/fixture.jsonl",
|
| 126 |
+
"sha256": "2b16d25eafa70c00a1106ba51b94890821b51ecb4fa393abb12403c8739ef314"
|
| 127 |
+
}
|
| 128 |
+
},
|
| 129 |
+
"cross_format_dp": {
|
| 130 |
+
"file": "runs/macjev/release_2b/parity/cross_format_dp.json",
|
| 131 |
+
"sha256": "c7332df0f02244416b01e49ecb037c76d4bf2643a2b42505ff1dfe896879e533"
|
| 132 |
+
},
|
| 133 |
+
"formats": {
|
| 134 |
+
"mlx-bf16": {
|
| 135 |
+
"gate_fixture": {
|
| 136 |
+
"n": 1000,
|
| 137 |
+
"top1_agreement": 0.997,
|
| 138 |
+
"top1_flips": 3,
|
| 139 |
+
"max_abs_dscore": 0.13961565494537354,
|
| 140 |
+
"mean_abs_dscore": 0.012822698334419146,
|
| 141 |
+
"dnll": 0.0001265220422789204,
|
| 142 |
+
"nll_ref": 0.4436679457518203,
|
| 143 |
+
"nll_cand": 0.4437944677940992,
|
| 144 |
+
"acc_ref": 0.808,
|
| 145 |
+
"acc_cand": 0.805,
|
| 146 |
+
"acc_drop_pp": 0.30000000000000027,
|
| 147 |
+
"max_abs_dp": 0.03549758339084519,
|
| 148 |
+
"mean_max_abs_dp": 0.0025865935031305484,
|
| 149 |
+
"gates": {
|
| 150 |
+
"coverage_finite_tokens": {
|
| 151 |
+
"pass": true,
|
| 152 |
+
"problems": {},
|
| 153 |
+
"reference_missing_requests": 0
|
| 154 |
+
},
|
| 155 |
+
"top1": {
|
| 156 |
+
"threshold": 0.99,
|
| 157 |
+
"value": 0.997,
|
| 158 |
+
"pass": true
|
| 159 |
+
},
|
| 160 |
+
"dnll": {
|
| 161 |
+
"threshold": 0.02,
|
| 162 |
+
"value": 0.0001265220422789204,
|
| 163 |
+
"pass": true
|
| 164 |
+
}
|
| 165 |
+
},
|
| 166 |
+
"verdict": "PASS",
|
| 167 |
+
"note": "small fixtures cannot resolve 0.3pp accuracy gates; accuracy on a parity fixture is only indicative (synthetic long rows carry the base row's gold label).",
|
| 168 |
+
"source": {
|
| 169 |
+
"file": "runs/macjev/release_2b/parity/compare_mlx_bf16_gate_vs_block.json",
|
| 170 |
+
"sha256": "7fa30fa414a4ffc12a7aa6371e77579845c3b816b90da3a813a70fec10ccd9fb"
|
| 171 |
+
}
|
| 172 |
+
},
|
| 173 |
+
"long_fixture": {
|
| 174 |
+
"n": 43,
|
| 175 |
+
"top1_agreement": 1.0,
|
| 176 |
+
"top1_flips": 0,
|
| 177 |
+
"max_abs_dscore": 0.08836114406585693,
|
| 178 |
+
"mean_abs_dscore": 0.01365492056503762,
|
| 179 |
+
"dnll": -0.0026943261000204055,
|
| 180 |
+
"nll_ref": 0.670433307194272,
|
| 181 |
+
"nll_cand": 0.6677389810942516,
|
| 182 |
+
"acc_ref": 0.7209302325581395,
|
| 183 |
+
"acc_cand": 0.7209302325581395,
|
| 184 |
+
"acc_drop_pp": 0.0,
|
| 185 |
+
"max_abs_dp": 0.010765431767972844,
|
| 186 |
+
"mean_max_abs_dp": 0.003890125022245109,
|
| 187 |
+
"gates": {
|
| 188 |
+
"coverage_finite_tokens": {
|
| 189 |
+
"pass": true,
|
| 190 |
+
"problems": {},
|
| 191 |
+
"reference_missing_requests": 0
|
| 192 |
+
},
|
| 193 |
+
"top1": {
|
| 194 |
+
"threshold": 0.99,
|
| 195 |
+
"value": 1.0,
|
| 196 |
+
"pass": true
|
| 197 |
+
},
|
| 198 |
+
"dnll": {
|
| 199 |
+
"threshold": 0.02,
|
| 200 |
+
"value": -0.0026943261000204055,
|
| 201 |
+
"pass": true
|
| 202 |
+
}
|
| 203 |
+
},
|
| 204 |
+
"verdict": "PASS",
|
| 205 |
+
"note": "small fixtures cannot resolve 0.3pp accuracy gates; accuracy on a parity fixture is only indicative (synthetic long rows carry the base row's gold label).",
|
| 206 |
+
"source": {
|
| 207 |
+
"file": "runs/macjev/release_2b/parity/compare_mlx_bf16_base_vs_block.json",
|
| 208 |
+
"sha256": "ca16e5281debaf1bc601b4a8c93cf6c1106f7b032f35c5833baa4fc8178def7c"
|
| 209 |
+
}
|
| 210 |
+
},
|
| 211 |
+
"release_verdict": "PASS"
|
| 212 |
+
},
|
| 213 |
+
"mlx-8bit": {
|
| 214 |
+
"gate_fixture": {
|
| 215 |
+
"n": 1000,
|
| 216 |
+
"top1_agreement": 0.996,
|
| 217 |
+
"top1_flips": 4,
|
| 218 |
+
"max_abs_dscore": 0.3184394836425781,
|
| 219 |
+
"mean_abs_dscore": 0.016680597170951345,
|
| 220 |
+
"dnll": 0.0005035682350758575,
|
| 221 |
+
"nll_ref": 0.4436679457518203,
|
| 222 |
+
"nll_cand": 0.44417151398689614,
|
| 223 |
+
"acc_ref": 0.808,
|
| 224 |
+
"acc_cand": 0.808,
|
| 225 |
+
"acc_drop_pp": 0.0,
|
| 226 |
+
"max_abs_dp": 0.1623697296878569,
|
| 227 |
+
"mean_max_abs_dp": 0.0039011049015487734,
|
| 228 |
+
"gates": {
|
| 229 |
+
"coverage_finite_tokens": {
|
| 230 |
+
"pass": true,
|
| 231 |
+
"problems": {},
|
| 232 |
+
"reference_missing_requests": 0
|
| 233 |
+
},
|
| 234 |
+
"top1": {
|
| 235 |
+
"threshold": 0.98,
|
| 236 |
+
"value": 0.996,
|
| 237 |
+
"pass": true
|
| 238 |
+
},
|
| 239 |
+
"dnll": {
|
| 240 |
+
"threshold": 0.02,
|
| 241 |
+
"value": 0.0005035682350758575,
|
| 242 |
+
"pass": true
|
| 243 |
+
},
|
| 244 |
+
"acc_drop_pp": {
|
| 245 |
+
"threshold": 0.3,
|
| 246 |
+
"value": 0.0,
|
| 247 |
+
"resolution_pp": 0.1,
|
| 248 |
+
"pass": true,
|
| 249 |
+
"note": null
|
| 250 |
+
}
|
| 251 |
+
},
|
| 252 |
+
"verdict": "PASS",
|
| 253 |
+
"note": "small fixtures cannot resolve 0.3pp accuracy gates; accuracy on a parity fixture is only indicative (synthetic long rows carry the base row's gold label).",
|
| 254 |
+
"source": {
|
| 255 |
+
"file": "runs/macjev/release_2b/parity/compare_mlx_affine8-g64_gate_vs_block.json",
|
| 256 |
+
"sha256": "f0e2f44498df00945901c2a9bd5bff6f742d11ab243495c8089eaf0448fda782"
|
| 257 |
+
}
|
| 258 |
+
},
|
| 259 |
+
"long_fixture": {
|
| 260 |
+
"n": 43,
|
| 261 |
+
"top1_agreement": 1.0,
|
| 262 |
+
"top1_flips": 0,
|
| 263 |
+
"max_abs_dscore": 0.4653351306915283,
|
| 264 |
+
"mean_abs_dscore": 0.023077200647273945,
|
| 265 |
+
"dnll": 0.01638063705636561,
|
| 266 |
+
"nll_ref": 0.670433307194272,
|
| 267 |
+
"nll_cand": 0.6868139442506376,
|
| 268 |
+
"acc_ref": 0.7209302325581395,
|
| 269 |
+
"acc_cand": 0.7209302325581395,
|
| 270 |
+
"acc_drop_pp": 0.0,
|
| 271 |
+
"max_abs_dp": 0.04628699142360499,
|
| 272 |
+
"mean_max_abs_dp": 0.007026009064181663,
|
| 273 |
+
"gates": {
|
| 274 |
+
"coverage_finite_tokens": {
|
| 275 |
+
"pass": true,
|
| 276 |
+
"problems": {},
|
| 277 |
+
"reference_missing_requests": 0
|
| 278 |
+
},
|
| 279 |
+
"top1": {
|
| 280 |
+
"threshold": 0.98,
|
| 281 |
+
"value": 1.0,
|
| 282 |
+
"pass": true
|
| 283 |
+
},
|
| 284 |
+
"dnll": {
|
| 285 |
+
"threshold": 0.02,
|
| 286 |
+
"value": 0.01638063705636561,
|
| 287 |
+
"pass": true
|
| 288 |
+
},
|
| 289 |
+
"acc_drop_pp": {
|
| 290 |
+
"threshold": 0.3,
|
| 291 |
+
"value": 0.0,
|
| 292 |
+
"resolution_pp": 2.3255813953488373,
|
| 293 |
+
"pass": null,
|
| 294 |
+
"note": "UNRESOLVED: 43 gold questions -> one flip = 2.33pp > 0.3pp; this fixture cannot resolve the gate (use the gate fixture with >= 334 rows; statistical power needs far more)"
|
| 295 |
+
}
|
| 296 |
+
},
|
| 297 |
+
"verdict": "INCONCLUSIVE",
|
| 298 |
+
"note": "small fixtures cannot resolve 0.3pp accuracy gates; accuracy on a parity fixture is only indicative (synthetic long rows carry the base row's gold label).",
|
| 299 |
+
"source": {
|
| 300 |
+
"file": "runs/macjev/release_2b/parity/compare_mlx_affine8-g64_base_vs_block.json",
|
| 301 |
+
"sha256": "e1911f21ce73dd42d6c57e8349e2ec3221386a2b44ca461a3e50b9a69057ec34"
|
| 302 |
+
}
|
| 303 |
+
},
|
| 304 |
+
"release_verdict": "PASS"
|
| 305 |
+
}
|
| 306 |
+
}
|
| 307 |
+
},
|
| 308 |
+
"decision_index": "requested from the maintainer after release (not run by us)",
|
| 309 |
+
"runtime_parity": {
|
| 310 |
+
"protocol": "the staged runtime scores the long fixture from text/ids through its own renderer; raw scores compared with the development MLX engine that produced the release parity (release_2b/parity/pred_mlx_*_base.jsonl)",
|
| 311 |
+
"fixture": {
|
| 312 |
+
"file": "runs/macjev/runtime_v2_dev/reference_base/fixture.jsonl",
|
| 313 |
+
"sha256": "2b16d25eafa70c00a1106ba51b94890821b51ecb4fa393abb12403c8739ef314"
|
| 314 |
+
},
|
| 315 |
+
"bf16": {
|
| 316 |
+
"precision": "bf16",
|
| 317 |
+
"dev_seconds": 415.6,
|
| 318 |
+
"default_T": 0.8278650620942867,
|
| 319 |
+
"fixture_requests": 35,
|
| 320 |
+
"fixture_questions": 43,
|
| 321 |
+
"fixture_tokens": 214700,
|
| 322 |
+
"overflow_q": 5,
|
| 323 |
+
"max_abs_dscore": 0.0,
|
| 324 |
+
"max_abs_dprob_vs_softmax_dev_over_T": 0.0,
|
| 325 |
+
"text_e2e_max_abs_dscore_vs_dev": 0.0,
|
| 326 |
+
"text_ids_equal_dev": true,
|
| 327 |
+
"score_many_vs_separate_fresh_decide_max_abs": 0.0,
|
| 328 |
+
"order_invariance_max_abs": 0.0,
|
| 329 |
+
"runtime_seconds": 293.1,
|
| 330 |
+
"source": {
|
| 331 |
+
"file": "runs/macjev/runtime_v2_dev/verify_release_mlx/fixture_verify_bf16.json",
|
| 332 |
+
"sha256": "87766f14dfdf9ac1d6d97692e523e3942329b4431615a46322992d1dbf315c63"
|
| 333 |
+
}
|
| 334 |
+
},
|
| 335 |
+
"8bit": {
|
| 336 |
+
"precision": "8bit",
|
| 337 |
+
"dev_seconds": 1324.8,
|
| 338 |
+
"default_T": 0.8278650620942867,
|
| 339 |
+
"fixture_requests": 35,
|
| 340 |
+
"fixture_questions": 43,
|
| 341 |
+
"fixture_tokens": 214700,
|
| 342 |
+
"overflow_q": 5,
|
| 343 |
+
"max_abs_dscore": 0.0,
|
| 344 |
+
"max_abs_dprob_vs_softmax_dev_over_T": 0.0,
|
| 345 |
+
"text_e2e_max_abs_dscore_vs_dev": 0.0,
|
| 346 |
+
"text_ids_equal_dev": true,
|
| 347 |
+
"score_many_vs_separate_fresh_decide_max_abs": 0.0,
|
| 348 |
+
"order_invariance_max_abs": 0.0,
|
| 349 |
+
"runtime_seconds": 286.5,
|
| 350 |
+
"source": {
|
| 351 |
+
"file": "runs/macjev/runtime_v2_dev/verify_release_mlx/fixture_verify_8bit.json",
|
| 352 |
+
"sha256": "305cc657c5ebd539ce92e3fbe7db36c594e40a0566d185b36dc858e338025d01"
|
| 353 |
+
}
|
| 354 |
+
},
|
| 355 |
+
"render_token_identity": {
|
| 356 |
+
"requests": 463,
|
| 357 |
+
"questions": 756,
|
| 358 |
+
"ok_identical": 743,
|
| 359 |
+
"budget_both": 6,
|
| 360 |
+
"error_both": 6,
|
| 361 |
+
"mismatch_count": 1,
|
| 362 |
+
"source": {
|
| 363 |
+
"file": "runs/macjev/runtime_v2_dev/verify_release_mlx/render_verify.json",
|
| 364 |
+
"sha256": "5333dd7e4083de7e80bd98b4da4d0965c2835782a37e836d55d0e09a26c4f8c1"
|
| 365 |
+
}
|
| 366 |
+
},
|
| 367 |
+
"runtime_file": {
|
| 368 |
+
"file": "jev_style_decision_mlx.py",
|
| 369 |
+
"sha256_now": "025daab9b374d740e743c519bd3aa3385791e08c81f4515b2ae525af57788030",
|
| 370 |
+
"mtime_unix": 1790448336.812169
|
| 371 |
+
},
|
| 372 |
+
"original_records_predate_last_runtime_edit": true,
|
| 373 |
+
"reverified_on_current_runtime": true,
|
| 374 |
+
"recorded_before_last_runtime_edit": false,
|
| 375 |
+
"note": "the records above were written before the last edit of the runtime file; the runtime as staged now (sha256 runtime_file.sha256_now) was re-verified on the long fixture, see 'reverified' (reverified.runtime_sha256 == runtime_file.sha256_now).",
|
| 376 |
+
"reverified": {
|
| 377 |
+
"runtime_file": "jev_style_decision_mlx.py",
|
| 378 |
+
"runtime_sha256": "025daab9b374d740e743c519bd3aa3385791e08c81f4515b2ae525af57788030",
|
| 379 |
+
"shared_core_sha256": "56deae095206fc59b9a30d8626ac5d27cacddcd94d7c7f08f6f4bc53d326a002",
|
| 380 |
+
"what": "MLX bf16 (loaded from the repository root, precision bf16), runtime defaults",
|
| 381 |
+
"loaded_from": "runs/macjev/hf_staging/Jev-Style-2B-Decision-v3-MLX",
|
| 382 |
+
"verify_manifest": true,
|
| 383 |
+
"compared_with": {
|
| 384 |
+
"file": "runs/macjev/release_2b/parity/pred_mlx_bf16_base.jsonl",
|
| 385 |
+
"sha256": "c42232870ab8c5410b4f45dc85729249d467b9c0bd5d24213d085e4479a3a60e"
|
| 386 |
+
},
|
| 387 |
+
"fixture": {
|
| 388 |
+
"file": "runs/macjev/runtime_v2_dev/reference_base/fixture.jsonl",
|
| 389 |
+
"sha256": "2b16d25eafa70c00a1106ba51b94890821b51ecb4fa393abb12403c8739ef314"
|
| 390 |
+
},
|
| 391 |
+
"questions": 43,
|
| 392 |
+
"skipped_questions": 0,
|
| 393 |
+
"max_abs_score_diff": 0.0,
|
| 394 |
+
"top1_same": "43/43",
|
| 395 |
+
"token_or_overflow_mismatches": [],
|
| 396 |
+
"seconds": 137.2,
|
| 397 |
+
"finished_unix": 1790449492.3913028,
|
| 398 |
+
"source": {
|
| 399 |
+
"file": "runs/macjev/hf_staging/_2b_tools/reverify_mlx.json",
|
| 400 |
+
"sha256": "1f6f62c8b66e8df2f738acfd96667ef746f9504328e603bdeaa848156ddf22bf"
|
| 401 |
+
}
|
| 402 |
+
}
|
| 403 |
+
},
|
| 404 |
+
"latency": {
|
| 405 |
+
"file": "validation/latency_2b.json",
|
| 406 |
+
"sha256": "458d00e0c81b3165072b8547278e6039b9ae0d45d54b7421008ef24c1d24ca3d",
|
| 407 |
+
"machine": {
|
| 408 |
+
"chip": "Apple M1 Max",
|
| 409 |
+
"memory_bytes": 68719476736,
|
| 410 |
+
"macos": "15.7.5",
|
| 411 |
+
"python": "3.12.13"
|
| 412 |
+
},
|
| 413 |
+
"backends_shown_on_card": [
|
| 414 |
+
"mlx-bf16",
|
| 415 |
+
"mlx-8bit"
|
| 416 |
+
],
|
| 417 |
+
"rows": 12,
|
| 418 |
+
"rows_in_file": 36,
|
| 419 |
+
"card_generator": "runs/macjev/release_2b/cards/_build/latency_tables.py"
|
| 420 |
+
},
|
| 421 |
+
"root_config_json": "copy of bf16/config.json at the repository root so the Hub counts downloads; the runtime treats the root as the repository folder (it has bf16/ and 8bit/ but no model.safetensors) and loads bf16/ or 8bit/"
|
| 422 |
+
}
|
requirements.txt
ADDED
|
@@ -0,0 +1,8 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# tested with: python 3.12, mlx 0.32.2, mlx-lm 0.31.3, transformers 5.17.0, tokenizers 0.23.2, numpy 2.5.3 (Apple silicon, macOS 15)
|
| 2 |
+
# mlx-lm is pinned: the runtime corrects two Qwen3.5 numerics inside mlx-lm (Gated-DeltaNet q/k l2norm eps,
|
| 3 |
+
# FP32 (1 + w) RMSNorm weights) and checks the sha256 of the mlx-lm source it patches; other versions are refused.
|
| 4 |
+
mlx==0.32.2
|
| 5 |
+
mlx-lm==0.31.3
|
| 6 |
+
transformers==5.17.0 # imported by mlx-lm when the model loads
|
| 7 |
+
tokenizers==0.23.2
|
| 8 |
+
numpy==2.5.3
|
validation/SOURCES.json
ADDED
|
@@ -0,0 +1,60 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"note": "copies of the verification / benchmark records behind release_config.json and the model card; local absolute paths replaced by repository-relative ones (local_paths_scrubbed); source_sha256 = the unmodified file (equal to the published copy when local_paths_scrubbed is false)",
|
| 3 |
+
"files": {
|
| 4 |
+
"parity/compare_mlx_bf16_gate_vs_block.json": {
|
| 5 |
+
"source": "runs/macjev/release_2b/parity/compare_mlx_bf16_gate_vs_block.json",
|
| 6 |
+
"source_sha256": "7fa30fa414a4ffc12a7aa6371e77579845c3b816b90da3a813a70fec10ccd9fb",
|
| 7 |
+
"local_paths_scrubbed": false
|
| 8 |
+
},
|
| 9 |
+
"parity/compare_mlx_bf16_base_vs_block.json": {
|
| 10 |
+
"source": "runs/macjev/release_2b/parity/compare_mlx_bf16_base_vs_block.json",
|
| 11 |
+
"source_sha256": "ca16e5281debaf1bc601b4a8c93cf6c1106f7b032f35c5833baa4fc8178def7c",
|
| 12 |
+
"local_paths_scrubbed": false
|
| 13 |
+
},
|
| 14 |
+
"parity/compare_mlx_affine8-g64_gate_vs_block.json": {
|
| 15 |
+
"source": "runs/macjev/release_2b/parity/compare_mlx_affine8-g64_gate_vs_block.json",
|
| 16 |
+
"source_sha256": "f0e2f44498df00945901c2a9bd5bff6f742d11ab243495c8089eaf0448fda782",
|
| 17 |
+
"local_paths_scrubbed": false
|
| 18 |
+
},
|
| 19 |
+
"parity/compare_mlx_affine8-g64_base_vs_block.json": {
|
| 20 |
+
"source": "runs/macjev/release_2b/parity/compare_mlx_affine8-g64_base_vs_block.json",
|
| 21 |
+
"source_sha256": "e1911f21ce73dd42d6c57e8349e2ec3221386a2b44ca461a3e50b9a69057ec34",
|
| 22 |
+
"local_paths_scrubbed": false
|
| 23 |
+
},
|
| 24 |
+
"parity/cross_format_dp.json": {
|
| 25 |
+
"source": "runs/macjev/release_2b/parity/cross_format_dp.json",
|
| 26 |
+
"source_sha256": "c7332df0f02244416b01e49ecb037c76d4bf2643a2b42505ff1dfe896879e533",
|
| 27 |
+
"local_paths_scrubbed": false
|
| 28 |
+
},
|
| 29 |
+
"parity/PREDECLARED_RELEASE_GATES_2B.md": {
|
| 30 |
+
"source": "runs/macjev/runtime_v2_dev/PREDECLARED_RELEASE_GATES_2B.md",
|
| 31 |
+
"source_sha256": "783aec77300779582911cdc57c71cf8b101b0cd5ca040073f7e1fa3ac20af08e",
|
| 32 |
+
"local_paths_scrubbed": false
|
| 33 |
+
},
|
| 34 |
+
"runtime/fixture_verify_bf16.json": {
|
| 35 |
+
"source": "runs/macjev/runtime_v2_dev/verify_release_mlx/fixture_verify_bf16.json",
|
| 36 |
+
"source_sha256": "87766f14dfdf9ac1d6d97692e523e3942329b4431615a46322992d1dbf315c63",
|
| 37 |
+
"local_paths_scrubbed": false
|
| 38 |
+
},
|
| 39 |
+
"runtime/fixture_verify_8bit.json": {
|
| 40 |
+
"source": "runs/macjev/runtime_v2_dev/verify_release_mlx/fixture_verify_8bit.json",
|
| 41 |
+
"source_sha256": "305cc657c5ebd539ce92e3fbe7db36c594e40a0566d185b36dc858e338025d01",
|
| 42 |
+
"local_paths_scrubbed": false
|
| 43 |
+
},
|
| 44 |
+
"runtime/render_verify.json": {
|
| 45 |
+
"source": "runs/macjev/runtime_v2_dev/verify_release_mlx/render_verify.json",
|
| 46 |
+
"source_sha256": "5333dd7e4083de7e80bd98b4da4d0965c2835782a37e836d55d0e09a26c4f8c1",
|
| 47 |
+
"local_paths_scrubbed": false
|
| 48 |
+
},
|
| 49 |
+
"runtime/reverify_mlx.json": {
|
| 50 |
+
"source": "runs/macjev/hf_staging/_2b_tools/reverify_mlx.json",
|
| 51 |
+
"source_sha256": "1f6f62c8b66e8df2f738acfd96667ef746f9504328e603bdeaa848156ddf22bf",
|
| 52 |
+
"local_paths_scrubbed": false
|
| 53 |
+
},
|
| 54 |
+
"latency_2b.json": {
|
| 55 |
+
"source": "runs/macjev/release_2b/latency_2b.json",
|
| 56 |
+
"source_sha256": "458d00e0c81b3165072b8547278e6039b9ae0d45d54b7421008ef24c1d24ca3d",
|
| 57 |
+
"local_paths_scrubbed": false
|
| 58 |
+
}
|
| 59 |
+
}
|
| 60 |
+
}
|
validation/latency_2b.json
ADDED
|
@@ -0,0 +1,1568 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"format": "jev-style-latency-v1",
|
| 3 |
+
"model": "Jev-Style-2B-Decision-v3",
|
| 4 |
+
"machine": {
|
| 5 |
+
"chip": "Apple M1 Max",
|
| 6 |
+
"memory_bytes": 68719476736,
|
| 7 |
+
"macos": "15.7.5",
|
| 8 |
+
"python": "3.12.13"
|
| 9 |
+
},
|
| 10 |
+
"shared_machine_note": "measured while other agents' jobs ran on the same Mac (among them a CPU-heavy PyTorch parity job using ~3.5 cores and ~16 GB); load averages at the end of each run are recorded per row. Treat the numbers as indicative, not as a clean benchmark.",
|
| 11 |
+
"protocol": {
|
| 12 |
+
"runtimes": "the staged runtimes of the three repos (jev_style_decision_gguf.py + jev-score-v2 built with build_jev_score.sh against llama.cpp 441df11f, Metal, all layers on the GPU; jev_style_decision_mlx.py, mlx 0.32.2 / mlx-lm 0.31.3; jev_style_decision.py on MPS, float32)",
|
| 13 |
+
"weights": "trained release weights: release_2b/gguf/model-*.gguf (tensor data identical to the named repo files), release_2b/mlx/{bf16,affine8-g64}, candidate_2b/hf-candidate (torch)",
|
| 14 |
+
"state": "plain text (repository documentation + source code, English) cut to target-150 tokens; the total input per question is recorded in input_tokens_per_question",
|
| 15 |
+
"questions": "n_questions=1: one 4-option choice question (decide); n_questions=10: 10 mixed questions (4 choice, 4 true/false, 2 score) about the same state in one score_many call",
|
| 16 |
+
"one_process_per_row": true,
|
| 17 |
+
"cold_s": "first scoring call after loading (state + questions; includes GPU warm-up)",
|
| 18 |
+
"warm_median_s": "median of 3 further calls, cached state dropped before each (state recomputed)",
|
| 19 |
+
"state_cached_median_s": "median of 3 calls with the state already computed (only the question blocks run)",
|
| 20 |
+
"load_s": "runtime construction (weights from the OS file cache in most rows)",
|
| 21 |
+
"wall_time": "time.perf_counter around decide()/score_many(), incl. tokenisation and rendering",
|
| 22 |
+
"peak_rss_bytes": "ru_maxrss of the Python process (and of the jev-score-v2 child for GGUF); includes memory-mapped weight pages",
|
| 23 |
+
"peak_phys_footprint_bytes": "macOS lifetime-max physical footprint (proc_pid_rusage v4): memory the process owns, incl. Metal / MLX buffers it allocates. It does NOT count clean memory-mapped file pages, so for GGUF (jev-score-v2 maps the .gguf file) it excludes the weights and is not a memory requirement; use peak_rss_bytes.jev_score_v2 (which includes the mapped weight pages) as the upper bound for GGUF"
|
| 24 |
+
},
|
| 25 |
+
"reruns": {
|
| 26 |
+
"gguf_and_mlx_rows": "all 18 GGUF rows and all 12 MLX rows were re-measured on 2026-09-27 03:11-03:28 (fix round, same script, same state text, same answers) because an independent re-run of the first session's GGUF Q8_0 / Q4_K_M 10-question rows was ~2.4x faster (contention during the first session). The first-session rows are kept in latency/runs_superseded_2026-09-27/ and are not used here. The 6 torch MPS rows are from the first session (not re-measured).",
|
| 27 |
+
"superseded_dir": "latency/runs_superseded_2026-09-27/"
|
| 28 |
+
},
|
| 29 |
+
"complete": true,
|
| 30 |
+
"missing_runs": [],
|
| 31 |
+
"rows": [
|
| 32 |
+
{
|
| 33 |
+
"backend": "gguf-f16",
|
| 34 |
+
"n_questions": 1,
|
| 35 |
+
"state_tokens": 878,
|
| 36 |
+
"input_tokens_per_question": [
|
| 37 |
+
943
|
| 38 |
+
],
|
| 39 |
+
"load_s": 2.6054,
|
| 40 |
+
"cold_s": 0.5624,
|
| 41 |
+
"warm_median_s": 0.5242,
|
| 42 |
+
"warm_s": [
|
| 43 |
+
0.5203,
|
| 44 |
+
0.5345,
|
| 45 |
+
0.5242
|
| 46 |
+
],
|
| 47 |
+
"state_cached_median_s": 0.0653,
|
| 48 |
+
"peak_rss_bytes": {
|
| 49 |
+
"python": 352616448,
|
| 50 |
+
"jev_score_v2": 4451008512
|
| 51 |
+
},
|
| 52 |
+
"peak_phys_footprint_bytes": {
|
| 53 |
+
"python": 252413696,
|
| 54 |
+
"jev_score_v2": 660384576
|
| 55 |
+
},
|
| 56 |
+
"results_identical_cold_vs_state_cached": true,
|
| 57 |
+
"loadavg_at_end": [
|
| 58 |
+
9.59,
|
| 59 |
+
9.9,
|
| 60 |
+
10.98
|
| 61 |
+
],
|
| 62 |
+
"measured_unix": 1790442718.8146281,
|
| 63 |
+
"settings": {
|
| 64 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 65 |
+
"n_gpu_layers": 999,
|
| 66 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 67 |
+
"gguf": "release_2b/gguf/model-f16.gguf"
|
| 68 |
+
},
|
| 69 |
+
"raw": "latency/runs/gguf-f16_1024_1q.json"
|
| 70 |
+
},
|
| 71 |
+
{
|
| 72 |
+
"backend": "gguf-f16",
|
| 73 |
+
"n_questions": 10,
|
| 74 |
+
"state_tokens": 878,
|
| 75 |
+
"input_tokens_per_question": [
|
| 76 |
+
943,
|
| 77 |
+
918,
|
| 78 |
+
925,
|
| 79 |
+
911,
|
| 80 |
+
918,
|
| 81 |
+
921,
|
| 82 |
+
943,
|
| 83 |
+
917,
|
| 84 |
+
912,
|
| 85 |
+
919
|
| 86 |
+
],
|
| 87 |
+
"load_s": 1.1941,
|
| 88 |
+
"cold_s": 0.994,
|
| 89 |
+
"warm_median_s": 0.968,
|
| 90 |
+
"warm_s": [
|
| 91 |
+
0.968,
|
| 92 |
+
0.9464,
|
| 93 |
+
0.9713
|
| 94 |
+
],
|
| 95 |
+
"state_cached_median_s": 0.4965,
|
| 96 |
+
"peak_rss_bytes": {
|
| 97 |
+
"python": 328564736,
|
| 98 |
+
"jev_score_v2": 4516610048
|
| 99 |
+
},
|
| 100 |
+
"peak_phys_footprint_bytes": {
|
| 101 |
+
"python": 254527296,
|
| 102 |
+
"jev_score_v2": 676899648
|
| 103 |
+
},
|
| 104 |
+
"results_identical_cold_vs_state_cached": true,
|
| 105 |
+
"loadavg_at_end": [
|
| 106 |
+
10.0,
|
| 107 |
+
9.97,
|
| 108 |
+
10.99
|
| 109 |
+
],
|
| 110 |
+
"measured_unix": 1790442726.19508,
|
| 111 |
+
"settings": {
|
| 112 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 113 |
+
"n_gpu_layers": 999,
|
| 114 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 115 |
+
"gguf": "release_2b/gguf/model-f16.gguf"
|
| 116 |
+
},
|
| 117 |
+
"raw": "latency/runs/gguf-f16_1024_10q.json"
|
| 118 |
+
},
|
| 119 |
+
{
|
| 120 |
+
"backend": "gguf-f16",
|
| 121 |
+
"n_questions": 1,
|
| 122 |
+
"state_tokens": 3950,
|
| 123 |
+
"input_tokens_per_question": [
|
| 124 |
+
4015
|
| 125 |
+
],
|
| 126 |
+
"load_s": 1.1659,
|
| 127 |
+
"cold_s": 2.2122,
|
| 128 |
+
"warm_median_s": 2.1753,
|
| 129 |
+
"warm_s": [
|
| 130 |
+
2.1909,
|
| 131 |
+
2.1753,
|
| 132 |
+
2.1733
|
| 133 |
+
],
|
| 134 |
+
"state_cached_median_s": 0.078,
|
| 135 |
+
"peak_rss_bytes": {
|
| 136 |
+
"python": 354697216,
|
| 137 |
+
"jev_score_v2": 4568334336
|
| 138 |
+
},
|
| 139 |
+
"peak_phys_footprint_bytes": {
|
| 140 |
+
"python": 257705600,
|
| 141 |
+
"jev_score_v2": 722676736
|
| 142 |
+
},
|
| 143 |
+
"results_identical_cold_vs_state_cached": true,
|
| 144 |
+
"loadavg_at_end": [
|
| 145 |
+
9.01,
|
| 146 |
+
9.76,
|
| 147 |
+
10.9
|
| 148 |
+
],
|
| 149 |
+
"measured_unix": 1790442737.183161,
|
| 150 |
+
"settings": {
|
| 151 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 152 |
+
"n_gpu_layers": 999,
|
| 153 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 154 |
+
"gguf": "release_2b/gguf/model-f16.gguf"
|
| 155 |
+
},
|
| 156 |
+
"raw": "latency/runs/gguf-f16_4096_1q.json"
|
| 157 |
+
},
|
| 158 |
+
{
|
| 159 |
+
"backend": "gguf-f16",
|
| 160 |
+
"n_questions": 10,
|
| 161 |
+
"state_tokens": 3950,
|
| 162 |
+
"input_tokens_per_question": [
|
| 163 |
+
4015,
|
| 164 |
+
3990,
|
| 165 |
+
3997,
|
| 166 |
+
3983,
|
| 167 |
+
3990,
|
| 168 |
+
3993,
|
| 169 |
+
4015,
|
| 170 |
+
3989,
|
| 171 |
+
3984,
|
| 172 |
+
3991
|
| 173 |
+
],
|
| 174 |
+
"load_s": 1.2112,
|
| 175 |
+
"cold_s": 2.6904,
|
| 176 |
+
"warm_median_s": 2.6583,
|
| 177 |
+
"warm_s": [
|
| 178 |
+
2.6583,
|
| 179 |
+
2.6665,
|
| 180 |
+
2.6378
|
| 181 |
+
],
|
| 182 |
+
"state_cached_median_s": 0.5467,
|
| 183 |
+
"peak_rss_bytes": {
|
| 184 |
+
"python": 331694080,
|
| 185 |
+
"jev_score_v2": 4564172800
|
| 186 |
+
},
|
| 187 |
+
"peak_phys_footprint_bytes": {
|
| 188 |
+
"python": 248334016,
|
| 189 |
+
"jev_score_v2": 720382976
|
| 190 |
+
},
|
| 191 |
+
"results_identical_cold_vs_state_cached": true,
|
| 192 |
+
"loadavg_at_end": [
|
| 193 |
+
8.62,
|
| 194 |
+
9.62,
|
| 195 |
+
10.83
|
| 196 |
+
],
|
| 197 |
+
"measured_unix": 1790442751.5065348,
|
| 198 |
+
"settings": {
|
| 199 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 200 |
+
"n_gpu_layers": 999,
|
| 201 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 202 |
+
"gguf": "release_2b/gguf/model-f16.gguf"
|
| 203 |
+
},
|
| 204 |
+
"raw": "latency/runs/gguf-f16_4096_10q.json"
|
| 205 |
+
},
|
| 206 |
+
{
|
| 207 |
+
"backend": "gguf-f16",
|
| 208 |
+
"n_questions": 1,
|
| 209 |
+
"state_tokens": 24436,
|
| 210 |
+
"input_tokens_per_question": [
|
| 211 |
+
24501
|
| 212 |
+
],
|
| 213 |
+
"load_s": 1.1784,
|
| 214 |
+
"cold_s": 16.2299,
|
| 215 |
+
"warm_median_s": 16.1651,
|
| 216 |
+
"warm_s": [
|
| 217 |
+
16.1645,
|
| 218 |
+
16.1651,
|
| 219 |
+
16.2375
|
| 220 |
+
],
|
| 221 |
+
"state_cached_median_s": 0.1677,
|
| 222 |
+
"peak_rss_bytes": {
|
| 223 |
+
"python": 349683712,
|
| 224 |
+
"jev_score_v2": 4734812160
|
| 225 |
+
},
|
| 226 |
+
"peak_phys_footprint_bytes": {
|
| 227 |
+
"python": 239191744,
|
| 228 |
+
"jev_score_v2": 882732352
|
| 229 |
+
},
|
| 230 |
+
"results_identical_cold_vs_state_cached": true,
|
| 231 |
+
"loadavg_at_end": [
|
| 232 |
+
9.74,
|
| 233 |
+
9.66,
|
| 234 |
+
10.75
|
| 235 |
+
],
|
| 236 |
+
"measured_unix": 1790442818.798799,
|
| 237 |
+
"settings": {
|
| 238 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 239 |
+
"n_gpu_layers": 999,
|
| 240 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 241 |
+
"gguf": "release_2b/gguf/model-f16.gguf"
|
| 242 |
+
},
|
| 243 |
+
"raw": "latency/runs/gguf-f16_24576_1q.json"
|
| 244 |
+
},
|
| 245 |
+
{
|
| 246 |
+
"backend": "gguf-f16",
|
| 247 |
+
"n_questions": 10,
|
| 248 |
+
"state_tokens": 24436,
|
| 249 |
+
"input_tokens_per_question": [
|
| 250 |
+
24501,
|
| 251 |
+
24476,
|
| 252 |
+
24483,
|
| 253 |
+
24469,
|
| 254 |
+
24476,
|
| 255 |
+
24479,
|
| 256 |
+
24501,
|
| 257 |
+
24475,
|
| 258 |
+
24470,
|
| 259 |
+
24477
|
| 260 |
+
],
|
| 261 |
+
"load_s": 1.225,
|
| 262 |
+
"cold_s": 16.9884,
|
| 263 |
+
"warm_median_s": 16.8115,
|
| 264 |
+
"warm_s": [
|
| 265 |
+
16.8115,
|
| 266 |
+
16.675,
|
| 267 |
+
16.8156
|
| 268 |
+
],
|
| 269 |
+
"state_cached_median_s": 0.8643,
|
| 270 |
+
"peak_rss_bytes": {
|
| 271 |
+
"python": 367919104,
|
| 272 |
+
"jev_score_v2": 4738170880
|
| 273 |
+
},
|
| 274 |
+
"peak_phys_footprint_bytes": {
|
| 275 |
+
"python": 242992832,
|
| 276 |
+
"jev_score_v2": 887975168
|
| 277 |
+
},
|
| 278 |
+
"results_identical_cold_vs_state_cached": true,
|
| 279 |
+
"loadavg_at_end": [
|
| 280 |
+
8.02,
|
| 281 |
+
9.14,
|
| 282 |
+
10.46
|
| 283 |
+
],
|
| 284 |
+
"measured_unix": 1790442890.769493,
|
| 285 |
+
"settings": {
|
| 286 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 287 |
+
"n_gpu_layers": 999,
|
| 288 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 289 |
+
"gguf": "release_2b/gguf/model-f16.gguf"
|
| 290 |
+
},
|
| 291 |
+
"raw": "latency/runs/gguf-f16_24576_10q.json"
|
| 292 |
+
},
|
| 293 |
+
{
|
| 294 |
+
"backend": "gguf-q8_0",
|
| 295 |
+
"n_questions": 1,
|
| 296 |
+
"state_tokens": 878,
|
| 297 |
+
"input_tokens_per_question": [
|
| 298 |
+
943
|
| 299 |
+
],
|
| 300 |
+
"load_s": 1.7934,
|
| 301 |
+
"cold_s": 0.6136,
|
| 302 |
+
"warm_median_s": 0.5663,
|
| 303 |
+
"warm_s": [
|
| 304 |
+
0.5678,
|
| 305 |
+
0.5663,
|
| 306 |
+
0.5663
|
| 307 |
+
],
|
| 308 |
+
"state_cached_median_s": 0.0682,
|
| 309 |
+
"peak_rss_bytes": {
|
| 310 |
+
"python": 328974336,
|
| 311 |
+
"jev_score_v2": 2721579008
|
| 312 |
+
},
|
| 313 |
+
"peak_phys_footprint_bytes": {
|
| 314 |
+
"python": 248874624,
|
| 315 |
+
"jev_score_v2": 668163520
|
| 316 |
+
},
|
| 317 |
+
"results_identical_cold_vs_state_cached": true,
|
| 318 |
+
"loadavg_at_end": [
|
| 319 |
+
7.69,
|
| 320 |
+
9.05,
|
| 321 |
+
10.42
|
| 322 |
+
],
|
| 323 |
+
"measured_unix": 1790442895.894016,
|
| 324 |
+
"settings": {
|
| 325 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 326 |
+
"n_gpu_layers": 999,
|
| 327 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 328 |
+
"gguf": "release_2b/gguf/model-q8_0.gguf"
|
| 329 |
+
},
|
| 330 |
+
"raw": "latency/runs/gguf-q8_0_1024_1q.json"
|
| 331 |
+
},
|
| 332 |
+
{
|
| 333 |
+
"backend": "gguf-q8_0",
|
| 334 |
+
"n_questions": 10,
|
| 335 |
+
"state_tokens": 878,
|
| 336 |
+
"input_tokens_per_question": [
|
| 337 |
+
943,
|
| 338 |
+
918,
|
| 339 |
+
925,
|
| 340 |
+
911,
|
| 341 |
+
918,
|
| 342 |
+
921,
|
| 343 |
+
943,
|
| 344 |
+
917,
|
| 345 |
+
912,
|
| 346 |
+
919
|
| 347 |
+
],
|
| 348 |
+
"load_s": 1.0682,
|
| 349 |
+
"cold_s": 1.073,
|
| 350 |
+
"warm_median_s": 1.0243,
|
| 351 |
+
"warm_s": [
|
| 352 |
+
1.0244,
|
| 353 |
+
1.0243,
|
| 354 |
+
1.0231
|
| 355 |
+
],
|
| 356 |
+
"state_cached_median_s": 0.5268,
|
| 357 |
+
"peak_rss_bytes": {
|
| 358 |
+
"python": 347635712,
|
| 359 |
+
"jev_score_v2": 2757804032
|
| 360 |
+
},
|
| 361 |
+
"peak_phys_footprint_bytes": {
|
| 362 |
+
"python": 258377344,
|
| 363 |
+
"jev_score_v2": 674569792
|
| 364 |
+
},
|
| 365 |
+
"results_identical_cold_vs_state_cached": true,
|
| 366 |
+
"loadavg_at_end": [
|
| 367 |
+
7.24,
|
| 368 |
+
8.94,
|
| 369 |
+
10.37
|
| 370 |
+
],
|
| 371 |
+
"measured_unix": 1790442903.5177228,
|
| 372 |
+
"settings": {
|
| 373 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 374 |
+
"n_gpu_layers": 999,
|
| 375 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 376 |
+
"gguf": "release_2b/gguf/model-q8_0.gguf"
|
| 377 |
+
},
|
| 378 |
+
"raw": "latency/runs/gguf-q8_0_1024_10q.json"
|
| 379 |
+
},
|
| 380 |
+
{
|
| 381 |
+
"backend": "gguf-q8_0",
|
| 382 |
+
"n_questions": 1,
|
| 383 |
+
"state_tokens": 3950,
|
| 384 |
+
"input_tokens_per_question": [
|
| 385 |
+
4015
|
| 386 |
+
],
|
| 387 |
+
"load_s": 1.0689,
|
| 388 |
+
"cold_s": 2.3987,
|
| 389 |
+
"warm_median_s": 2.3345,
|
| 390 |
+
"warm_s": [
|
| 391 |
+
2.3333,
|
| 392 |
+
2.3488,
|
| 393 |
+
2.3345
|
| 394 |
+
],
|
| 395 |
+
"state_cached_median_s": 0.082,
|
| 396 |
+
"peak_rss_bytes": {
|
| 397 |
+
"python": 354189312,
|
| 398 |
+
"jev_score_v2": 2807808000
|
| 399 |
+
},
|
| 400 |
+
"peak_phys_footprint_bytes": {
|
| 401 |
+
"python": 247596736,
|
| 402 |
+
"jev_score_v2": 719183680
|
| 403 |
+
},
|
| 404 |
+
"results_identical_cold_vs_state_cached": true,
|
| 405 |
+
"loadavg_at_end": [
|
| 406 |
+
6.58,
|
| 407 |
+
8.74,
|
| 408 |
+
10.28
|
| 409 |
+
],
|
| 410 |
+
"measured_unix": 1790442915.085064,
|
| 411 |
+
"settings": {
|
| 412 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 413 |
+
"n_gpu_layers": 999,
|
| 414 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 415 |
+
"gguf": "release_2b/gguf/model-q8_0.gguf"
|
| 416 |
+
},
|
| 417 |
+
"raw": "latency/runs/gguf-q8_0_4096_1q.json"
|
| 418 |
+
},
|
| 419 |
+
{
|
| 420 |
+
"backend": "gguf-q8_0",
|
| 421 |
+
"n_questions": 10,
|
| 422 |
+
"state_tokens": 3950,
|
| 423 |
+
"input_tokens_per_question": [
|
| 424 |
+
4015,
|
| 425 |
+
3990,
|
| 426 |
+
3997,
|
| 427 |
+
3983,
|
| 428 |
+
3990,
|
| 429 |
+
3993,
|
| 430 |
+
4015,
|
| 431 |
+
3989,
|
| 432 |
+
3984,
|
| 433 |
+
3991
|
| 434 |
+
],
|
| 435 |
+
"load_s": 1.0684,
|
| 436 |
+
"cold_s": 2.8854,
|
| 437 |
+
"warm_median_s": 2.8178,
|
| 438 |
+
"warm_s": [
|
| 439 |
+
2.8178,
|
| 440 |
+
2.8439,
|
| 441 |
+
2.816
|
| 442 |
+
],
|
| 443 |
+
"state_cached_median_s": 0.5719,
|
| 444 |
+
"peak_rss_bytes": {
|
| 445 |
+
"python": 319045632,
|
| 446 |
+
"jev_score_v2": 2799091712
|
| 447 |
+
},
|
| 448 |
+
"peak_phys_footprint_bytes": {
|
| 449 |
+
"python": 243910336,
|
| 450 |
+
"jev_score_v2": 716169152
|
| 451 |
+
},
|
| 452 |
+
"results_identical_cold_vs_state_cached": true,
|
| 453 |
+
"loadavg_at_end": [
|
| 454 |
+
7.36,
|
| 455 |
+
8.8,
|
| 456 |
+
10.28
|
| 457 |
+
],
|
| 458 |
+
"measured_unix": 1790442930.063521,
|
| 459 |
+
"settings": {
|
| 460 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 461 |
+
"n_gpu_layers": 999,
|
| 462 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 463 |
+
"gguf": "release_2b/gguf/model-q8_0.gguf"
|
| 464 |
+
},
|
| 465 |
+
"raw": "latency/runs/gguf-q8_0_4096_10q.json"
|
| 466 |
+
},
|
| 467 |
+
{
|
| 468 |
+
"backend": "gguf-q8_0",
|
| 469 |
+
"n_questions": 1,
|
| 470 |
+
"state_tokens": 24436,
|
| 471 |
+
"input_tokens_per_question": [
|
| 472 |
+
24501
|
| 473 |
+
],
|
| 474 |
+
"load_s": 1.0589,
|
| 475 |
+
"cold_s": 17.0922,
|
| 476 |
+
"warm_median_s": 17.0489,
|
| 477 |
+
"warm_s": [
|
| 478 |
+
17.0489,
|
| 479 |
+
17.0376,
|
| 480 |
+
17.0539
|
| 481 |
+
],
|
| 482 |
+
"state_cached_median_s": 0.1679,
|
| 483 |
+
"peak_rss_bytes": {
|
| 484 |
+
"python": 364937216,
|
| 485 |
+
"jev_score_v2": 2966470656
|
| 486 |
+
},
|
| 487 |
+
"peak_phys_footprint_bytes": {
|
| 488 |
+
"python": 267110080,
|
| 489 |
+
"jev_score_v2": 875831168
|
| 490 |
+
},
|
| 491 |
+
"results_identical_cold_vs_state_cached": true,
|
| 492 |
+
"loadavg_at_end": [
|
| 493 |
+
6.7,
|
| 494 |
+
8.25,
|
| 495 |
+
9.94
|
| 496 |
+
],
|
| 497 |
+
"measured_unix": 1790443000.691691,
|
| 498 |
+
"settings": {
|
| 499 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 500 |
+
"n_gpu_layers": 999,
|
| 501 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 502 |
+
"gguf": "release_2b/gguf/model-q8_0.gguf"
|
| 503 |
+
},
|
| 504 |
+
"raw": "latency/runs/gguf-q8_0_24576_1q.json"
|
| 505 |
+
},
|
| 506 |
+
{
|
| 507 |
+
"backend": "gguf-q8_0",
|
| 508 |
+
"n_questions": 10,
|
| 509 |
+
"state_tokens": 24436,
|
| 510 |
+
"input_tokens_per_question": [
|
| 511 |
+
24501,
|
| 512 |
+
24476,
|
| 513 |
+
24483,
|
| 514 |
+
24469,
|
| 515 |
+
24476,
|
| 516 |
+
24479,
|
| 517 |
+
24501,
|
| 518 |
+
24475,
|
| 519 |
+
24470,
|
| 520 |
+
24477
|
| 521 |
+
],
|
| 522 |
+
"load_s": 1.0501,
|
| 523 |
+
"cold_s": 17.8244,
|
| 524 |
+
"warm_median_s": 17.7424,
|
| 525 |
+
"warm_s": [
|
| 526 |
+
17.7424,
|
| 527 |
+
17.7312,
|
| 528 |
+
17.7793
|
| 529 |
+
],
|
| 530 |
+
"state_cached_median_s": 0.8902,
|
| 531 |
+
"peak_rss_bytes": {
|
| 532 |
+
"python": 348651520,
|
| 533 |
+
"jev_score_v2": 2967109632
|
| 534 |
+
},
|
| 535 |
+
"peak_phys_footprint_bytes": {
|
| 536 |
+
"python": 260425536,
|
| 537 |
+
"jev_score_v2": 878698496
|
| 538 |
+
},
|
| 539 |
+
"results_identical_cold_vs_state_cached": true,
|
| 540 |
+
"loadavg_at_end": [
|
| 541 |
+
11.28,
|
| 542 |
+
9.17,
|
| 543 |
+
10.13
|
| 544 |
+
],
|
| 545 |
+
"measured_unix": 1790443076.341974,
|
| 546 |
+
"settings": {
|
| 547 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 548 |
+
"n_gpu_layers": 999,
|
| 549 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 550 |
+
"gguf": "release_2b/gguf/model-q8_0.gguf"
|
| 551 |
+
},
|
| 552 |
+
"raw": "latency/runs/gguf-q8_0_24576_10q.json"
|
| 553 |
+
},
|
| 554 |
+
{
|
| 555 |
+
"backend": "gguf-q4_k_m",
|
| 556 |
+
"n_questions": 1,
|
| 557 |
+
"state_tokens": 878,
|
| 558 |
+
"input_tokens_per_question": [
|
| 559 |
+
943
|
| 560 |
+
],
|
| 561 |
+
"load_s": 1.4512,
|
| 562 |
+
"cold_s": 0.6738,
|
| 563 |
+
"warm_median_s": 0.6391,
|
| 564 |
+
"warm_s": [
|
| 565 |
+
0.6418,
|
| 566 |
+
0.6391,
|
| 567 |
+
0.6334
|
| 568 |
+
],
|
| 569 |
+
"state_cached_median_s": 0.0782,
|
| 570 |
+
"peak_rss_bytes": {
|
| 571 |
+
"python": 334921728,
|
| 572 |
+
"jev_score_v2": 1988542464
|
| 573 |
+
},
|
| 574 |
+
"peak_phys_footprint_bytes": {
|
| 575 |
+
"python": 245073728,
|
| 576 |
+
"jev_score_v2": 669308992
|
| 577 |
+
},
|
| 578 |
+
"results_identical_cold_vs_state_cached": true,
|
| 579 |
+
"loadavg_at_end": [
|
| 580 |
+
12.77,
|
| 581 |
+
9.51,
|
| 582 |
+
10.25
|
| 583 |
+
],
|
| 584 |
+
"measured_unix": 1790443081.420589,
|
| 585 |
+
"settings": {
|
| 586 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 587 |
+
"n_gpu_layers": 999,
|
| 588 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 589 |
+
"gguf": "release_2b/gguf/model-q4_k_m.gguf"
|
| 590 |
+
},
|
| 591 |
+
"raw": "latency/runs/gguf-q4_k_m_1024_1q.json"
|
| 592 |
+
},
|
| 593 |
+
{
|
| 594 |
+
"backend": "gguf-q4_k_m",
|
| 595 |
+
"n_questions": 10,
|
| 596 |
+
"state_tokens": 878,
|
| 597 |
+
"input_tokens_per_question": [
|
| 598 |
+
943,
|
| 599 |
+
918,
|
| 600 |
+
925,
|
| 601 |
+
911,
|
| 602 |
+
918,
|
| 603 |
+
921,
|
| 604 |
+
943,
|
| 605 |
+
917,
|
| 606 |
+
912,
|
| 607 |
+
919
|
| 608 |
+
],
|
| 609 |
+
"load_s": 0.9937,
|
| 610 |
+
"cold_s": 1.2045,
|
| 611 |
+
"warm_median_s": 1.157,
|
| 612 |
+
"warm_s": [
|
| 613 |
+
1.1544,
|
| 614 |
+
1.1643,
|
| 615 |
+
1.157
|
| 616 |
+
],
|
| 617 |
+
"state_cached_median_s": 0.6009,
|
| 618 |
+
"peak_rss_bytes": {
|
| 619 |
+
"python": 352059392,
|
| 620 |
+
"jev_score_v2": 2018754560
|
| 621 |
+
},
|
| 622 |
+
"peak_phys_footprint_bytes": {
|
| 623 |
+
"python": 256673344,
|
| 624 |
+
"jev_score_v2": 665065728
|
| 625 |
+
},
|
| 626 |
+
"results_identical_cold_vs_state_cached": true,
|
| 627 |
+
"loadavg_at_end": [
|
| 628 |
+
13.83,
|
| 629 |
+
9.78,
|
| 630 |
+
10.34
|
| 631 |
+
],
|
| 632 |
+
"measured_unix": 1790443089.6937559,
|
| 633 |
+
"settings": {
|
| 634 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 635 |
+
"n_gpu_layers": 999,
|
| 636 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 637 |
+
"gguf": "release_2b/gguf/model-q4_k_m.gguf"
|
| 638 |
+
},
|
| 639 |
+
"raw": "latency/runs/gguf-q4_k_m_1024_10q.json"
|
| 640 |
+
},
|
| 641 |
+
{
|
| 642 |
+
"backend": "gguf-q4_k_m",
|
| 643 |
+
"n_questions": 1,
|
| 644 |
+
"state_tokens": 3950,
|
| 645 |
+
"input_tokens_per_question": [
|
| 646 |
+
4015
|
| 647 |
+
],
|
| 648 |
+
"load_s": 0.9922,
|
| 649 |
+
"cold_s": 2.6608,
|
| 650 |
+
"warm_median_s": 2.6006,
|
| 651 |
+
"warm_s": [
|
| 652 |
+
2.6006,
|
| 653 |
+
2.6206,
|
| 654 |
+
2.5977
|
| 655 |
+
],
|
| 656 |
+
"state_cached_median_s": 0.0908,
|
| 657 |
+
"peak_rss_bytes": {
|
| 658 |
+
"python": 327221248,
|
| 659 |
+
"jev_score_v2": 2062483456
|
| 660 |
+
},
|
| 661 |
+
"peak_phys_footprint_bytes": {
|
| 662 |
+
"python": 259393408,
|
| 663 |
+
"jev_score_v2": 714692992
|
| 664 |
+
},
|
| 665 |
+
"results_identical_cold_vs_state_cached": true,
|
| 666 |
+
"loadavg_at_end": [
|
| 667 |
+
11.99,
|
| 668 |
+
9.57,
|
| 669 |
+
10.25
|
| 670 |
+
],
|
| 671 |
+
"measured_unix": 1790443102.1980171,
|
| 672 |
+
"settings": {
|
| 673 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 674 |
+
"n_gpu_layers": 999,
|
| 675 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 676 |
+
"gguf": "release_2b/gguf/model-q4_k_m.gguf"
|
| 677 |
+
},
|
| 678 |
+
"raw": "latency/runs/gguf-q4_k_m_4096_1q.json"
|
| 679 |
+
},
|
| 680 |
+
{
|
| 681 |
+
"backend": "gguf-q4_k_m",
|
| 682 |
+
"n_questions": 10,
|
| 683 |
+
"state_tokens": 3950,
|
| 684 |
+
"input_tokens_per_question": [
|
| 685 |
+
4015,
|
| 686 |
+
3990,
|
| 687 |
+
3997,
|
| 688 |
+
3983,
|
| 689 |
+
3990,
|
| 690 |
+
3993,
|
| 691 |
+
4015,
|
| 692 |
+
3989,
|
| 693 |
+
3984,
|
| 694 |
+
3991
|
| 695 |
+
],
|
| 696 |
+
"load_s": 0.9859,
|
| 697 |
+
"cold_s": 3.2053,
|
| 698 |
+
"warm_median_s": 3.1651,
|
| 699 |
+
"warm_s": [
|
| 700 |
+
3.1651,
|
| 701 |
+
3.1579,
|
| 702 |
+
3.1711
|
| 703 |
+
],
|
| 704 |
+
"state_cached_median_s": 0.6462,
|
| 705 |
+
"peak_rss_bytes": {
|
| 706 |
+
"python": 326434816,
|
| 707 |
+
"jev_score_v2": 2073214976
|
| 708 |
+
},
|
| 709 |
+
"peak_phys_footprint_bytes": {
|
| 710 |
+
"python": 245614208,
|
| 711 |
+
"jev_score_v2": 716806400
|
| 712 |
+
},
|
| 713 |
+
"results_identical_cold_vs_state_cached": true,
|
| 714 |
+
"loadavg_at_end": [
|
| 715 |
+
10.28,
|
| 716 |
+
9.31,
|
| 717 |
+
10.15
|
| 718 |
+
],
|
| 719 |
+
"measured_unix": 1790443118.634955,
|
| 720 |
+
"settings": {
|
| 721 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 722 |
+
"n_gpu_layers": 999,
|
| 723 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 724 |
+
"gguf": "release_2b/gguf/model-q4_k_m.gguf"
|
| 725 |
+
},
|
| 726 |
+
"raw": "latency/runs/gguf-q4_k_m_4096_10q.json"
|
| 727 |
+
},
|
| 728 |
+
{
|
| 729 |
+
"backend": "gguf-q4_k_m",
|
| 730 |
+
"n_questions": 1,
|
| 731 |
+
"state_tokens": 24436,
|
| 732 |
+
"input_tokens_per_question": [
|
| 733 |
+
24501
|
| 734 |
+
],
|
| 735 |
+
"load_s": 1.0041,
|
| 736 |
+
"cold_s": 18.6914,
|
| 737 |
+
"warm_median_s": 18.6165,
|
| 738 |
+
"warm_s": [
|
| 739 |
+
18.6165,
|
| 740 |
+
18.6059,
|
| 741 |
+
18.624
|
| 742 |
+
],
|
| 743 |
+
"state_cached_median_s": 0.1755,
|
| 744 |
+
"peak_rss_bytes": {
|
| 745 |
+
"python": 345686016,
|
| 746 |
+
"jev_score_v2": 2233663488
|
| 747 |
+
},
|
| 748 |
+
"peak_phys_footprint_bytes": {
|
| 749 |
+
"python": 260048576,
|
| 750 |
+
"jev_score_v2": 880335552
|
| 751 |
+
},
|
| 752 |
+
"results_identical_cold_vs_state_cached": true,
|
| 753 |
+
"loadavg_at_end": [
|
| 754 |
+
8.43,
|
| 755 |
+
9.22,
|
| 756 |
+
10.05
|
| 757 |
+
],
|
| 758 |
+
"measured_unix": 1790443195.534742,
|
| 759 |
+
"settings": {
|
| 760 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 761 |
+
"n_gpu_layers": 999,
|
| 762 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 763 |
+
"gguf": "release_2b/gguf/model-q4_k_m.gguf"
|
| 764 |
+
},
|
| 765 |
+
"raw": "latency/runs/gguf-q4_k_m_24576_1q.json"
|
| 766 |
+
},
|
| 767 |
+
{
|
| 768 |
+
"backend": "gguf-q4_k_m",
|
| 769 |
+
"n_questions": 10,
|
| 770 |
+
"state_tokens": 24436,
|
| 771 |
+
"input_tokens_per_question": [
|
| 772 |
+
24501,
|
| 773 |
+
24476,
|
| 774 |
+
24483,
|
| 775 |
+
24469,
|
| 776 |
+
24476,
|
| 777 |
+
24479,
|
| 778 |
+
24501,
|
| 779 |
+
24475,
|
| 780 |
+
24470,
|
| 781 |
+
24477
|
| 782 |
+
],
|
| 783 |
+
"load_s": 0.9967,
|
| 784 |
+
"cold_s": 19.4776,
|
| 785 |
+
"warm_median_s": 19.4309,
|
| 786 |
+
"warm_s": [
|
| 787 |
+
19.4309,
|
| 788 |
+
19.4251,
|
| 789 |
+
19.5057
|
| 790 |
+
],
|
| 791 |
+
"state_cached_median_s": 0.9616,
|
| 792 |
+
"peak_rss_bytes": {
|
| 793 |
+
"python": 354992128,
|
| 794 |
+
"jev_score_v2": 2226913280
|
| 795 |
+
},
|
| 796 |
+
"peak_phys_footprint_bytes": {
|
| 797 |
+
"python": 250791552,
|
| 798 |
+
"jev_score_v2": 870128320
|
| 799 |
+
},
|
| 800 |
+
"results_identical_cold_vs_state_cached": true,
|
| 801 |
+
"loadavg_at_end": [
|
| 802 |
+
5.63,
|
| 803 |
+
8.19,
|
| 804 |
+
9.59
|
| 805 |
+
],
|
| 806 |
+
"measured_unix": 1790443278.075001,
|
| 807 |
+
"settings": {
|
| 808 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 809 |
+
"n_gpu_layers": 999,
|
| 810 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 811 |
+
"gguf": "release_2b/gguf/model-q4_k_m.gguf"
|
| 812 |
+
},
|
| 813 |
+
"raw": "latency/runs/gguf-q4_k_m_24576_10q.json"
|
| 814 |
+
},
|
| 815 |
+
{
|
| 816 |
+
"backend": "mlx-bf16",
|
| 817 |
+
"n_questions": 1,
|
| 818 |
+
"state_tokens": 878,
|
| 819 |
+
"input_tokens_per_question": [
|
| 820 |
+
943
|
| 821 |
+
],
|
| 822 |
+
"load_s": 3.6602,
|
| 823 |
+
"cold_s": 0.64,
|
| 824 |
+
"warm_median_s": 0.5658,
|
| 825 |
+
"warm_s": [
|
| 826 |
+
0.5615,
|
| 827 |
+
0.5665,
|
| 828 |
+
0.5658
|
| 829 |
+
],
|
| 830 |
+
"state_cached_median_s": 0.0796,
|
| 831 |
+
"peak_rss_bytes": {
|
| 832 |
+
"python": 4401463296
|
| 833 |
+
},
|
| 834 |
+
"peak_phys_footprint_bytes": {
|
| 835 |
+
"python": 5205486080
|
| 836 |
+
},
|
| 837 |
+
"mlx_peak_memory_bytes": 4536436474,
|
| 838 |
+
"results_identical_cold_vs_state_cached": true,
|
| 839 |
+
"loadavg_at_end": [
|
| 840 |
+
6.5,
|
| 841 |
+
8.17,
|
| 842 |
+
9.53
|
| 843 |
+
],
|
| 844 |
+
"measured_unix": 1790443305.918901,
|
| 845 |
+
"settings": {
|
| 846 |
+
"engine": "mlx 0.32.2 / mlx-lm 0.31.3 (staged runtime)",
|
| 847 |
+
"precision": "bf16",
|
| 848 |
+
"compute_dtype": null
|
| 849 |
+
},
|
| 850 |
+
"raw": "latency/runs/mlx-bf16_1024_1q.json"
|
| 851 |
+
},
|
| 852 |
+
{
|
| 853 |
+
"backend": "mlx-bf16",
|
| 854 |
+
"n_questions": 10,
|
| 855 |
+
"state_tokens": 878,
|
| 856 |
+
"input_tokens_per_question": [
|
| 857 |
+
943,
|
| 858 |
+
918,
|
| 859 |
+
925,
|
| 860 |
+
911,
|
| 861 |
+
918,
|
| 862 |
+
921,
|
| 863 |
+
943,
|
| 864 |
+
917,
|
| 865 |
+
912,
|
| 866 |
+
919
|
| 867 |
+
],
|
| 868 |
+
"load_s": 3.3114,
|
| 869 |
+
"cold_s": 1.1022,
|
| 870 |
+
"warm_median_s": 1.0651,
|
| 871 |
+
"warm_s": [
|
| 872 |
+
1.0651,
|
| 873 |
+
1.0647,
|
| 874 |
+
1.0714
|
| 875 |
+
],
|
| 876 |
+
"state_cached_median_s": 0.5726,
|
| 877 |
+
"peak_rss_bytes": {
|
| 878 |
+
"python": 4416684032
|
| 879 |
+
},
|
| 880 |
+
"peak_phys_footprint_bytes": {
|
| 881 |
+
"python": 5575518912
|
| 882 |
+
},
|
| 883 |
+
"mlx_peak_memory_bytes": 4536436474,
|
| 884 |
+
"results_identical_cold_vs_state_cached": true,
|
| 885 |
+
"loadavg_at_end": [
|
| 886 |
+
6.03,
|
| 887 |
+
8.01,
|
| 888 |
+
9.46
|
| 889 |
+
],
|
| 890 |
+
"measured_unix": 1790443316.3707972,
|
| 891 |
+
"settings": {
|
| 892 |
+
"engine": "mlx 0.32.2 / mlx-lm 0.31.3 (staged runtime)",
|
| 893 |
+
"precision": "bf16",
|
| 894 |
+
"compute_dtype": null
|
| 895 |
+
},
|
| 896 |
+
"raw": "latency/runs/mlx-bf16_1024_10q.json"
|
| 897 |
+
},
|
| 898 |
+
{
|
| 899 |
+
"backend": "mlx-bf16",
|
| 900 |
+
"n_questions": 1,
|
| 901 |
+
"state_tokens": 3950,
|
| 902 |
+
"input_tokens_per_question": [
|
| 903 |
+
4015
|
| 904 |
+
],
|
| 905 |
+
"load_s": 3.2848,
|
| 906 |
+
"cold_s": 2.265,
|
| 907 |
+
"warm_median_s": 2.2579,
|
| 908 |
+
"warm_s": [
|
| 909 |
+
2.2462,
|
| 910 |
+
2.2579,
|
| 911 |
+
2.2701
|
| 912 |
+
],
|
| 913 |
+
"state_cached_median_s": 0.0903,
|
| 914 |
+
"peak_rss_bytes": {
|
| 915 |
+
"python": 4408279040
|
| 916 |
+
},
|
| 917 |
+
"peak_phys_footprint_bytes": {
|
| 918 |
+
"python": 6899099712
|
| 919 |
+
},
|
| 920 |
+
"mlx_peak_memory_bytes": 5062198966,
|
| 921 |
+
"results_identical_cold_vs_state_cached": true,
|
| 922 |
+
"loadavg_at_end": [
|
| 923 |
+
5.78,
|
| 924 |
+
7.9,
|
| 925 |
+
9.4
|
| 926 |
+
],
|
| 927 |
+
"measured_unix": 1790443330.072621,
|
| 928 |
+
"settings": {
|
| 929 |
+
"engine": "mlx 0.32.2 / mlx-lm 0.31.3 (staged runtime)",
|
| 930 |
+
"precision": "bf16",
|
| 931 |
+
"compute_dtype": null
|
| 932 |
+
},
|
| 933 |
+
"raw": "latency/runs/mlx-bf16_4096_1q.json"
|
| 934 |
+
},
|
| 935 |
+
{
|
| 936 |
+
"backend": "mlx-bf16",
|
| 937 |
+
"n_questions": 10,
|
| 938 |
+
"state_tokens": 3950,
|
| 939 |
+
"input_tokens_per_question": [
|
| 940 |
+
4015,
|
| 941 |
+
3990,
|
| 942 |
+
3997,
|
| 943 |
+
3983,
|
| 944 |
+
3990,
|
| 945 |
+
3993,
|
| 946 |
+
4015,
|
| 947 |
+
3989,
|
| 948 |
+
3984,
|
| 949 |
+
3991
|
| 950 |
+
],
|
| 951 |
+
"load_s": 3.3381,
|
| 952 |
+
"cold_s": 2.8286,
|
| 953 |
+
"warm_median_s": 2.7998,
|
| 954 |
+
"warm_s": [
|
| 955 |
+
2.832,
|
| 956 |
+
2.7968,
|
| 957 |
+
2.7998
|
| 958 |
+
],
|
| 959 |
+
"state_cached_median_s": 0.622,
|
| 960 |
+
"peak_rss_bytes": {
|
| 961 |
+
"python": 4406149120
|
| 962 |
+
},
|
| 963 |
+
"peak_phys_footprint_bytes": {
|
| 964 |
+
"python": 6943402624
|
| 965 |
+
},
|
| 966 |
+
"mlx_peak_memory_bytes": 5062395574,
|
| 967 |
+
"results_identical_cold_vs_state_cached": true,
|
| 968 |
+
"loadavg_at_end": [
|
| 969 |
+
5.53,
|
| 970 |
+
7.71,
|
| 971 |
+
9.3
|
| 972 |
+
],
|
| 973 |
+
"measured_unix": 1790443347.640775,
|
| 974 |
+
"settings": {
|
| 975 |
+
"engine": "mlx 0.32.2 / mlx-lm 0.31.3 (staged runtime)",
|
| 976 |
+
"precision": "bf16",
|
| 977 |
+
"compute_dtype": null
|
| 978 |
+
},
|
| 979 |
+
"raw": "latency/runs/mlx-bf16_4096_10q.json"
|
| 980 |
+
},
|
| 981 |
+
{
|
| 982 |
+
"backend": "mlx-bf16",
|
| 983 |
+
"n_questions": 1,
|
| 984 |
+
"state_tokens": 24436,
|
| 985 |
+
"input_tokens_per_question": [
|
| 986 |
+
24501
|
| 987 |
+
],
|
| 988 |
+
"load_s": 3.2657,
|
| 989 |
+
"cold_s": 15.472,
|
| 990 |
+
"warm_median_s": 15.5073,
|
| 991 |
+
"warm_s": [
|
| 992 |
+
15.5202,
|
| 993 |
+
15.5073,
|
| 994 |
+
15.4734
|
| 995 |
+
],
|
| 996 |
+
"state_cached_median_s": 0.1546,
|
| 997 |
+
"peak_rss_bytes": {
|
| 998 |
+
"python": 4403707904
|
| 999 |
+
},
|
| 1000 |
+
"peak_phys_footprint_bytes": {
|
| 1001 |
+
"python": 7889725824
|
| 1002 |
+
},
|
| 1003 |
+
"mlx_peak_memory_bytes": 5942822582,
|
| 1004 |
+
"results_identical_cold_vs_state_cached": true,
|
| 1005 |
+
"loadavg_at_end": [
|
| 1006 |
+
6.15,
|
| 1007 |
+
7.49,
|
| 1008 |
+
9.1
|
| 1009 |
+
],
|
| 1010 |
+
"measured_unix": 1790443414.47198,
|
| 1011 |
+
"settings": {
|
| 1012 |
+
"engine": "mlx 0.32.2 / mlx-lm 0.31.3 (staged runtime)",
|
| 1013 |
+
"precision": "bf16",
|
| 1014 |
+
"compute_dtype": null
|
| 1015 |
+
},
|
| 1016 |
+
"raw": "latency/runs/mlx-bf16_24576_1q.json"
|
| 1017 |
+
},
|
| 1018 |
+
{
|
| 1019 |
+
"backend": "mlx-bf16",
|
| 1020 |
+
"n_questions": 10,
|
| 1021 |
+
"state_tokens": 24436,
|
| 1022 |
+
"input_tokens_per_question": [
|
| 1023 |
+
24501,
|
| 1024 |
+
24476,
|
| 1025 |
+
24483,
|
| 1026 |
+
24469,
|
| 1027 |
+
24476,
|
| 1028 |
+
24479,
|
| 1029 |
+
24501,
|
| 1030 |
+
24475,
|
| 1031 |
+
24470,
|
| 1032 |
+
24477
|
| 1033 |
+
],
|
| 1034 |
+
"load_s": 3.278,
|
| 1035 |
+
"cold_s": 16.2813,
|
| 1036 |
+
"warm_median_s": 16.2351,
|
| 1037 |
+
"warm_s": [
|
| 1038 |
+
16.2243,
|
| 1039 |
+
16.2351,
|
| 1040 |
+
16.2657
|
| 1041 |
+
],
|
| 1042 |
+
"state_cached_median_s": 0.8797,
|
| 1043 |
+
"peak_rss_bytes": {
|
| 1044 |
+
"python": 4405805056
|
| 1045 |
+
},
|
| 1046 |
+
"peak_phys_footprint_bytes": {
|
| 1047 |
+
"python": 7863035904
|
| 1048 |
+
},
|
| 1049 |
+
"mlx_peak_memory_bytes": 5942806198,
|
| 1050 |
+
"results_identical_cold_vs_state_cached": true,
|
| 1051 |
+
"loadavg_at_end": [
|
| 1052 |
+
8.07,
|
| 1053 |
+
7.75,
|
| 1054 |
+
9.06
|
| 1055 |
+
],
|
| 1056 |
+
"measured_unix": 1790443486.522902,
|
| 1057 |
+
"settings": {
|
| 1058 |
+
"engine": "mlx 0.32.2 / mlx-lm 0.31.3 (staged runtime)",
|
| 1059 |
+
"precision": "bf16",
|
| 1060 |
+
"compute_dtype": null
|
| 1061 |
+
},
|
| 1062 |
+
"raw": "latency/runs/mlx-bf16_24576_10q.json"
|
| 1063 |
+
},
|
| 1064 |
+
{
|
| 1065 |
+
"backend": "mlx-8bit",
|
| 1066 |
+
"n_questions": 1,
|
| 1067 |
+
"state_tokens": 878,
|
| 1068 |
+
"input_tokens_per_question": [
|
| 1069 |
+
943
|
| 1070 |
+
],
|
| 1071 |
+
"load_s": 3.3345,
|
| 1072 |
+
"cold_s": 0.7573,
|
| 1073 |
+
"warm_median_s": 0.72,
|
| 1074 |
+
"warm_s": [
|
| 1075 |
+
0.7177,
|
| 1076 |
+
0.72,
|
| 1077 |
+
0.7228
|
| 1078 |
+
],
|
| 1079 |
+
"state_cached_median_s": 0.0834,
|
| 1080 |
+
"peak_rss_bytes": {
|
| 1081 |
+
"python": 2640986112
|
| 1082 |
+
},
|
| 1083 |
+
"peak_phys_footprint_bytes": {
|
| 1084 |
+
"python": 3772211392
|
| 1085 |
+
},
|
| 1086 |
+
"mlx_peak_memory_bytes": 3074287404,
|
| 1087 |
+
"results_identical_cold_vs_state_cached": true,
|
| 1088 |
+
"loadavg_at_end": [
|
| 1089 |
+
8.14,
|
| 1090 |
+
7.77,
|
| 1091 |
+
9.06
|
| 1092 |
+
],
|
| 1093 |
+
"measured_unix": 1790443494.139926,
|
| 1094 |
+
"settings": {
|
| 1095 |
+
"engine": "mlx 0.32.2 / mlx-lm 0.31.3 (staged runtime)",
|
| 1096 |
+
"precision": "8bit",
|
| 1097 |
+
"compute_dtype": null
|
| 1098 |
+
},
|
| 1099 |
+
"raw": "latency/runs/mlx-8bit_1024_1q.json"
|
| 1100 |
+
},
|
| 1101 |
+
{
|
| 1102 |
+
"backend": "mlx-8bit",
|
| 1103 |
+
"n_questions": 10,
|
| 1104 |
+
"state_tokens": 878,
|
| 1105 |
+
"input_tokens_per_question": [
|
| 1106 |
+
943,
|
| 1107 |
+
918,
|
| 1108 |
+
925,
|
| 1109 |
+
911,
|
| 1110 |
+
918,
|
| 1111 |
+
921,
|
| 1112 |
+
943,
|
| 1113 |
+
917,
|
| 1114 |
+
912,
|
| 1115 |
+
919
|
| 1116 |
+
],
|
| 1117 |
+
"load_s": 3.1502,
|
| 1118 |
+
"cold_s": 1.3124,
|
| 1119 |
+
"warm_median_s": 1.2657,
|
| 1120 |
+
"warm_s": [
|
| 1121 |
+
1.2719,
|
| 1122 |
+
1.2657,
|
| 1123 |
+
1.2621
|
| 1124 |
+
],
|
| 1125 |
+
"state_cached_median_s": 0.6288,
|
| 1126 |
+
"peak_rss_bytes": {
|
| 1127 |
+
"python": 2635268096
|
| 1128 |
+
},
|
| 1129 |
+
"peak_phys_footprint_bytes": {
|
| 1130 |
+
"python": 4171391040
|
| 1131 |
+
},
|
| 1132 |
+
"mlx_peak_memory_bytes": 3074287404,
|
| 1133 |
+
"results_identical_cold_vs_state_cached": true,
|
| 1134 |
+
"loadavg_at_end": [
|
| 1135 |
+
7.51,
|
| 1136 |
+
7.65,
|
| 1137 |
+
9.0
|
| 1138 |
+
],
|
| 1139 |
+
"measured_unix": 1790443505.379929,
|
| 1140 |
+
"settings": {
|
| 1141 |
+
"engine": "mlx 0.32.2 / mlx-lm 0.31.3 (staged runtime)",
|
| 1142 |
+
"precision": "8bit",
|
| 1143 |
+
"compute_dtype": null
|
| 1144 |
+
},
|
| 1145 |
+
"raw": "latency/runs/mlx-8bit_1024_10q.json"
|
| 1146 |
+
},
|
| 1147 |
+
{
|
| 1148 |
+
"backend": "mlx-8bit",
|
| 1149 |
+
"n_questions": 1,
|
| 1150 |
+
"state_tokens": 3950,
|
| 1151 |
+
"input_tokens_per_question": [
|
| 1152 |
+
4015
|
| 1153 |
+
],
|
| 1154 |
+
"load_s": 3.1569,
|
| 1155 |
+
"cold_s": 2.9904,
|
| 1156 |
+
"warm_median_s": 2.9581,
|
| 1157 |
+
"warm_s": [
|
| 1158 |
+
2.9525,
|
| 1159 |
+
2.9624,
|
| 1160 |
+
2.9581
|
| 1161 |
+
],
|
| 1162 |
+
"state_cached_median_s": 0.0922,
|
| 1163 |
+
"peak_rss_bytes": {
|
| 1164 |
+
"python": 2639839232
|
| 1165 |
+
},
|
| 1166 |
+
"peak_phys_footprint_bytes": {
|
| 1167 |
+
"python": 5536832896
|
| 1168 |
+
},
|
| 1169 |
+
"mlx_peak_memory_bytes": 3471550184,
|
| 1170 |
+
"results_identical_cold_vs_state_cached": true,
|
| 1171 |
+
"loadavg_at_end": [
|
| 1172 |
+
8.57,
|
| 1173 |
+
7.86,
|
| 1174 |
+
9.04
|
| 1175 |
+
],
|
| 1176 |
+
"measured_unix": 1790443521.78049,
|
| 1177 |
+
"settings": {
|
| 1178 |
+
"engine": "mlx 0.32.2 / mlx-lm 0.31.3 (staged runtime)",
|
| 1179 |
+
"precision": "8bit",
|
| 1180 |
+
"compute_dtype": null
|
| 1181 |
+
},
|
| 1182 |
+
"raw": "latency/runs/mlx-8bit_4096_1q.json"
|
| 1183 |
+
},
|
| 1184 |
+
{
|
| 1185 |
+
"backend": "mlx-8bit",
|
| 1186 |
+
"n_questions": 10,
|
| 1187 |
+
"state_tokens": 3950,
|
| 1188 |
+
"input_tokens_per_question": [
|
| 1189 |
+
4015,
|
| 1190 |
+
3990,
|
| 1191 |
+
3997,
|
| 1192 |
+
3983,
|
| 1193 |
+
3990,
|
| 1194 |
+
3993,
|
| 1195 |
+
4015,
|
| 1196 |
+
3989,
|
| 1197 |
+
3984,
|
| 1198 |
+
3991
|
| 1199 |
+
],
|
| 1200 |
+
"load_s": 3.1665,
|
| 1201 |
+
"cold_s": 3.572,
|
| 1202 |
+
"warm_median_s": 3.5432,
|
| 1203 |
+
"warm_s": [
|
| 1204 |
+
3.5584,
|
| 1205 |
+
3.5432,
|
| 1206 |
+
3.5354
|
| 1207 |
+
],
|
| 1208 |
+
"state_cached_median_s": 0.6768,
|
| 1209 |
+
"peak_rss_bytes": {
|
| 1210 |
+
"python": 2624536576
|
| 1211 |
+
},
|
| 1212 |
+
"peak_phys_footprint_bytes": {
|
| 1213 |
+
"python": 5698149760
|
| 1214 |
+
},
|
| 1215 |
+
"mlx_peak_memory_bytes": 3471615720,
|
| 1216 |
+
"results_identical_cold_vs_state_cached": true,
|
| 1217 |
+
"loadavg_at_end": [
|
| 1218 |
+
7.82,
|
| 1219 |
+
7.73,
|
| 1220 |
+
8.97
|
| 1221 |
+
],
|
| 1222 |
+
"measured_unix": 1790443542.268524,
|
| 1223 |
+
"settings": {
|
| 1224 |
+
"engine": "mlx 0.32.2 / mlx-lm 0.31.3 (staged runtime)",
|
| 1225 |
+
"precision": "8bit",
|
| 1226 |
+
"compute_dtype": null
|
| 1227 |
+
},
|
| 1228 |
+
"raw": "latency/runs/mlx-8bit_4096_10q.json"
|
| 1229 |
+
},
|
| 1230 |
+
{
|
| 1231 |
+
"backend": "mlx-8bit",
|
| 1232 |
+
"n_questions": 1,
|
| 1233 |
+
"state_tokens": 24436,
|
| 1234 |
+
"input_tokens_per_question": [
|
| 1235 |
+
24501
|
| 1236 |
+
],
|
| 1237 |
+
"load_s": 3.1447,
|
| 1238 |
+
"cold_s": 19.75,
|
| 1239 |
+
"warm_median_s": 19.8614,
|
| 1240 |
+
"warm_s": [
|
| 1241 |
+
19.8005,
|
| 1242 |
+
19.8614,
|
| 1243 |
+
19.9115
|
| 1244 |
+
],
|
| 1245 |
+
"state_cached_median_s": 0.1562,
|
| 1246 |
+
"peak_rss_bytes": {
|
| 1247 |
+
"python": 2643197952
|
| 1248 |
+
},
|
| 1249 |
+
"peak_phys_footprint_bytes": {
|
| 1250 |
+
"python": 6518807424
|
| 1251 |
+
},
|
| 1252 |
+
"mlx_peak_memory_bytes": 4350994102,
|
| 1253 |
+
"results_identical_cold_vs_state_cached": true,
|
| 1254 |
+
"loadavg_at_end": [
|
| 1255 |
+
6.7,
|
| 1256 |
+
7.34,
|
| 1257 |
+
8.69
|
| 1258 |
+
],
|
| 1259 |
+
"measured_unix": 1790443626.3357399,
|
| 1260 |
+
"settings": {
|
| 1261 |
+
"engine": "mlx 0.32.2 / mlx-lm 0.31.3 (staged runtime)",
|
| 1262 |
+
"precision": "8bit",
|
| 1263 |
+
"compute_dtype": null
|
| 1264 |
+
},
|
| 1265 |
+
"raw": "latency/runs/mlx-8bit_24576_1q.json"
|
| 1266 |
+
},
|
| 1267 |
+
{
|
| 1268 |
+
"backend": "mlx-8bit",
|
| 1269 |
+
"n_questions": 10,
|
| 1270 |
+
"state_tokens": 24436,
|
| 1271 |
+
"input_tokens_per_question": [
|
| 1272 |
+
24501,
|
| 1273 |
+
24476,
|
| 1274 |
+
24483,
|
| 1275 |
+
24469,
|
| 1276 |
+
24476,
|
| 1277 |
+
24479,
|
| 1278 |
+
24501,
|
| 1279 |
+
24475,
|
| 1280 |
+
24470,
|
| 1281 |
+
24477
|
| 1282 |
+
],
|
| 1283 |
+
"load_s": 3.1668,
|
| 1284 |
+
"cold_s": 20.7629,
|
| 1285 |
+
"warm_median_s": 20.7793,
|
| 1286 |
+
"warm_s": [
|
| 1287 |
+
20.6782,
|
| 1288 |
+
20.7793,
|
| 1289 |
+
21.8013
|
| 1290 |
+
],
|
| 1291 |
+
"state_cached_median_s": 0.9543,
|
| 1292 |
+
"peak_rss_bytes": {
|
| 1293 |
+
"python": 2643705856
|
| 1294 |
+
},
|
| 1295 |
+
"peak_phys_footprint_bytes": {
|
| 1296 |
+
"python": 6522985664
|
| 1297 |
+
},
|
| 1298 |
+
"mlx_peak_memory_bytes": 4350944950,
|
| 1299 |
+
"results_identical_cold_vs_state_cached": true,
|
| 1300 |
+
"loadavg_at_end": [
|
| 1301 |
+
8.26,
|
| 1302 |
+
8.35,
|
| 1303 |
+
8.99
|
| 1304 |
+
],
|
| 1305 |
+
"measured_unix": 1790443717.49426,
|
| 1306 |
+
"settings": {
|
| 1307 |
+
"engine": "mlx 0.32.2 / mlx-lm 0.31.3 (staged runtime)",
|
| 1308 |
+
"precision": "8bit",
|
| 1309 |
+
"compute_dtype": null
|
| 1310 |
+
},
|
| 1311 |
+
"raw": "latency/runs/mlx-8bit_24576_10q.json"
|
| 1312 |
+
},
|
| 1313 |
+
{
|
| 1314 |
+
"backend": "torch-mps-fp32",
|
| 1315 |
+
"n_questions": 1,
|
| 1316 |
+
"state_tokens": 878,
|
| 1317 |
+
"input_tokens_per_question": [
|
| 1318 |
+
943
|
| 1319 |
+
],
|
| 1320 |
+
"load_s": 7.2396,
|
| 1321 |
+
"cold_s": 2.0776,
|
| 1322 |
+
"warm_median_s": 1.82,
|
| 1323 |
+
"warm_s": [
|
| 1324 |
+
1.82,
|
| 1325 |
+
1.8185,
|
| 1326 |
+
1.8657
|
| 1327 |
+
],
|
| 1328 |
+
"state_cached_median_s": 0.2243,
|
| 1329 |
+
"peak_rss_bytes": {
|
| 1330 |
+
"python": 11777310720
|
| 1331 |
+
},
|
| 1332 |
+
"peak_phys_footprint_bytes": {
|
| 1333 |
+
"python": 9488876864
|
| 1334 |
+
},
|
| 1335 |
+
"results_identical_cold_vs_state_cached": true,
|
| 1336 |
+
"loadavg_at_end": [
|
| 1337 |
+
11.08,
|
| 1338 |
+
15.97,
|
| 1339 |
+
14.21
|
| 1340 |
+
],
|
| 1341 |
+
"measured_unix": 1790433935.3785548,
|
| 1342 |
+
"settings": {
|
| 1343 |
+
"engine": "transformers 5.17 / torch 2.14 (staged runtime)",
|
| 1344 |
+
"device": "mps",
|
| 1345 |
+
"dtype": "float32",
|
| 1346 |
+
"attn_chunk": 1024
|
| 1347 |
+
},
|
| 1348 |
+
"raw": "latency/runs/torch-mps-fp32_1024_1q.json"
|
| 1349 |
+
},
|
| 1350 |
+
{
|
| 1351 |
+
"backend": "torch-mps-fp32",
|
| 1352 |
+
"n_questions": 10,
|
| 1353 |
+
"state_tokens": 878,
|
| 1354 |
+
"input_tokens_per_question": [
|
| 1355 |
+
943,
|
| 1356 |
+
918,
|
| 1357 |
+
925,
|
| 1358 |
+
911,
|
| 1359 |
+
918,
|
| 1360 |
+
921,
|
| 1361 |
+
943,
|
| 1362 |
+
917,
|
| 1363 |
+
912,
|
| 1364 |
+
919
|
| 1365 |
+
],
|
| 1366 |
+
"load_s": 5.8844,
|
| 1367 |
+
"cold_s": 3.487,
|
| 1368 |
+
"warm_median_s": 3.126,
|
| 1369 |
+
"warm_s": [
|
| 1370 |
+
3.126,
|
| 1371 |
+
3.124,
|
| 1372 |
+
3.1357
|
| 1373 |
+
],
|
| 1374 |
+
"state_cached_median_s": 1.534,
|
| 1375 |
+
"peak_rss_bytes": {
|
| 1376 |
+
"python": 11766398976
|
| 1377 |
+
},
|
| 1378 |
+
"peak_phys_footprint_bytes": {
|
| 1379 |
+
"python": 9348826496
|
| 1380 |
+
},
|
| 1381 |
+
"results_identical_cold_vs_state_cached": true,
|
| 1382 |
+
"loadavg_at_end": [
|
| 1383 |
+
10.92,
|
| 1384 |
+
15.56,
|
| 1385 |
+
14.11
|
| 1386 |
+
],
|
| 1387 |
+
"measured_unix": 1790433960.3376808,
|
| 1388 |
+
"settings": {
|
| 1389 |
+
"engine": "transformers 5.17 / torch 2.14 (staged runtime)",
|
| 1390 |
+
"device": "mps",
|
| 1391 |
+
"dtype": "float32",
|
| 1392 |
+
"attn_chunk": 1024
|
| 1393 |
+
},
|
| 1394 |
+
"raw": "latency/runs/torch-mps-fp32_1024_10q.json"
|
| 1395 |
+
},
|
| 1396 |
+
{
|
| 1397 |
+
"backend": "torch-mps-fp32",
|
| 1398 |
+
"n_questions": 1,
|
| 1399 |
+
"state_tokens": 3950,
|
| 1400 |
+
"input_tokens_per_question": [
|
| 1401 |
+
4015
|
| 1402 |
+
],
|
| 1403 |
+
"load_s": 6.6133,
|
| 1404 |
+
"cold_s": 7.9626,
|
| 1405 |
+
"warm_median_s": 7.7385,
|
| 1406 |
+
"warm_s": [
|
| 1407 |
+
7.7135,
|
| 1408 |
+
7.7385,
|
| 1409 |
+
7.7569
|
| 1410 |
+
],
|
| 1411 |
+
"state_cached_median_s": 0.2508,
|
| 1412 |
+
"peak_rss_bytes": {
|
| 1413 |
+
"python": 11774099456
|
| 1414 |
+
},
|
| 1415 |
+
"peak_phys_footprint_bytes": {
|
| 1416 |
+
"python": 9830892736
|
| 1417 |
+
},
|
| 1418 |
+
"results_identical_cold_vs_state_cached": true,
|
| 1419 |
+
"loadavg_at_end": [
|
| 1420 |
+
8.41,
|
| 1421 |
+
7.52,
|
| 1422 |
+
7.06
|
| 1423 |
+
],
|
| 1424 |
+
"measured_unix": 1790438685.325036,
|
| 1425 |
+
"settings": {
|
| 1426 |
+
"engine": "transformers 5.17 / torch 2.14 (staged runtime)",
|
| 1427 |
+
"device": "mps",
|
| 1428 |
+
"dtype": "float32",
|
| 1429 |
+
"attn_chunk": 1024
|
| 1430 |
+
},
|
| 1431 |
+
"raw": "latency/runs/torch-mps-fp32_4096_1q.json"
|
| 1432 |
+
},
|
| 1433 |
+
{
|
| 1434 |
+
"backend": "torch-mps-fp32",
|
| 1435 |
+
"n_questions": 10,
|
| 1436 |
+
"state_tokens": 3950,
|
| 1437 |
+
"input_tokens_per_question": [
|
| 1438 |
+
4015,
|
| 1439 |
+
3990,
|
| 1440 |
+
3997,
|
| 1441 |
+
3983,
|
| 1442 |
+
3990,
|
| 1443 |
+
3993,
|
| 1444 |
+
4015,
|
| 1445 |
+
3989,
|
| 1446 |
+
3984,
|
| 1447 |
+
3991
|
| 1448 |
+
],
|
| 1449 |
+
"load_s": 5.8354,
|
| 1450 |
+
"cold_s": 9.4943,
|
| 1451 |
+
"warm_median_s": 9.2321,
|
| 1452 |
+
"warm_s": [
|
| 1453 |
+
9.1731,
|
| 1454 |
+
9.2321,
|
| 1455 |
+
9.2805
|
| 1456 |
+
],
|
| 1457 |
+
"state_cached_median_s": 1.7373,
|
| 1458 |
+
"peak_rss_bytes": {
|
| 1459 |
+
"python": 11766579200
|
| 1460 |
+
},
|
| 1461 |
+
"peak_phys_footprint_bytes": {
|
| 1462 |
+
"python": 9740780928
|
| 1463 |
+
},
|
| 1464 |
+
"results_identical_cold_vs_state_cached": true,
|
| 1465 |
+
"loadavg_at_end": [
|
| 1466 |
+
10.4,
|
| 1467 |
+
8.12,
|
| 1468 |
+
7.31
|
| 1469 |
+
],
|
| 1470 |
+
"measured_unix": 1790438734.979529,
|
| 1471 |
+
"settings": {
|
| 1472 |
+
"engine": "transformers 5.17 / torch 2.14 (staged runtime)",
|
| 1473 |
+
"device": "mps",
|
| 1474 |
+
"dtype": "float32",
|
| 1475 |
+
"attn_chunk": 1024
|
| 1476 |
+
},
|
| 1477 |
+
"raw": "latency/runs/torch-mps-fp32_4096_10q.json"
|
| 1478 |
+
},
|
| 1479 |
+
{
|
| 1480 |
+
"backend": "torch-mps-fp32",
|
| 1481 |
+
"n_questions": 1,
|
| 1482 |
+
"state_tokens": 24436,
|
| 1483 |
+
"input_tokens_per_question": [
|
| 1484 |
+
24501
|
| 1485 |
+
],
|
| 1486 |
+
"load_s": 7.5475,
|
| 1487 |
+
"cold_s": 56.4354,
|
| 1488 |
+
"warm_median_s": 61.9146,
|
| 1489 |
+
"warm_s": [
|
| 1490 |
+
55.156,
|
| 1491 |
+
61.9146,
|
| 1492 |
+
80.3434
|
| 1493 |
+
],
|
| 1494 |
+
"state_cached_median_s": 0.6,
|
| 1495 |
+
"peak_rss_bytes": {
|
| 1496 |
+
"python": 11774935040
|
| 1497 |
+
},
|
| 1498 |
+
"peak_phys_footprint_bytes": {
|
| 1499 |
+
"python": 13703111296
|
| 1500 |
+
},
|
| 1501 |
+
"results_identical_cold_vs_state_cached": true,
|
| 1502 |
+
"loadavg_at_end": [
|
| 1503 |
+
7.27,
|
| 1504 |
+
7.84,
|
| 1505 |
+
7.44
|
| 1506 |
+
],
|
| 1507 |
+
"measured_unix": 1790438999.6904268,
|
| 1508 |
+
"settings": {
|
| 1509 |
+
"engine": "transformers 5.17 / torch 2.14 (staged runtime)",
|
| 1510 |
+
"device": "mps",
|
| 1511 |
+
"dtype": "float32",
|
| 1512 |
+
"attn_chunk": 1024
|
| 1513 |
+
},
|
| 1514 |
+
"raw": "latency/runs/torch-mps-fp32_24576_1q.json"
|
| 1515 |
+
},
|
| 1516 |
+
{
|
| 1517 |
+
"backend": "torch-mps-fp32",
|
| 1518 |
+
"n_questions": 10,
|
| 1519 |
+
"state_tokens": 24436,
|
| 1520 |
+
"input_tokens_per_question": [
|
| 1521 |
+
24501,
|
| 1522 |
+
24476,
|
| 1523 |
+
24483,
|
| 1524 |
+
24469,
|
| 1525 |
+
24476,
|
| 1526 |
+
24479,
|
| 1527 |
+
24501,
|
| 1528 |
+
24475,
|
| 1529 |
+
24470,
|
| 1530 |
+
24477
|
| 1531 |
+
],
|
| 1532 |
+
"load_s": 7.9699,
|
| 1533 |
+
"cold_s": 72.6584,
|
| 1534 |
+
"warm_median_s": 72.3035,
|
| 1535 |
+
"warm_s": [
|
| 1536 |
+
83.2192,
|
| 1537 |
+
72.3035,
|
| 1538 |
+
58.3757
|
| 1539 |
+
],
|
| 1540 |
+
"state_cached_median_s": 2.7217,
|
| 1541 |
+
"peak_rss_bytes": {
|
| 1542 |
+
"python": 11775229952
|
| 1543 |
+
},
|
| 1544 |
+
"peak_phys_footprint_bytes": {
|
| 1545 |
+
"python": 13640000128
|
| 1546 |
+
},
|
| 1547 |
+
"results_identical_cold_vs_state_cached": true,
|
| 1548 |
+
"loadavg_at_end": [
|
| 1549 |
+
9.6,
|
| 1550 |
+
8.35,
|
| 1551 |
+
7.72
|
| 1552 |
+
],
|
| 1553 |
+
"measured_unix": 1790439304.235886,
|
| 1554 |
+
"settings": {
|
| 1555 |
+
"engine": "transformers 5.17 / torch 2.14 (staged runtime)",
|
| 1556 |
+
"device": "mps",
|
| 1557 |
+
"dtype": "float32",
|
| 1558 |
+
"attn_chunk": 1024
|
| 1559 |
+
},
|
| 1560 |
+
"raw": "latency/runs/torch-mps-fp32_24576_10q.json"
|
| 1561 |
+
}
|
| 1562 |
+
],
|
| 1563 |
+
"scripts": [
|
| 1564 |
+
"release_2b/latency/latency_run.py",
|
| 1565 |
+
"release_2b/latency/run_all.sh",
|
| 1566 |
+
"release_2b/latency/aggregate.py"
|
| 1567 |
+
]
|
| 1568 |
+
}
|
validation/parity/PREDECLARED_RELEASE_GATES_2B.md
ADDED
|
@@ -0,0 +1,29 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Jev-Style-2B-Decision-v3 — release format gates (pre-declared 2026-09-26, BEFORE any trained-weight format was scored)
|
| 2 |
+
|
| 3 |
+
Reference: HF FP32 CPU, exact v2 block attention, on the released bf16 text-only checkpoint
|
| 4 |
+
runs/macjev/candidate_2b/hf-candidate (SHA256SUMS 279/279 verified). Temperature T = 0.8278650621 (macjev_readout.json).
|
| 5 |
+
|
| 6 |
+
Fixtures (frozen, sha256 in their .stats/.README):
|
| 7 |
+
- base fixture: runs/macjev/runtime_v2_dev/reference_base/fixture.jsonl (35 req / 43 q, 214,700 tok, up to 25,600 tok, overflow, K<=151)
|
| 8 |
+
- gate fixture: runs/macjev/runtime_v2_dev/reference/gate_fixture_n1000.jsonl (1,000 real dev rows, <=4,096 tok)
|
| 9 |
+
|
| 10 |
+
Gates (training plan §11.2, unchanged): F16/bf16 top-1 >= .99; 8-bit top-1 >= .98; |dNLL| <= .02 (fp/16/8-bit);
|
| 11 |
+
accuracy drop Q8_0/MLX-8bit <= 0.3 pp, Q4_K_M <= 1.0 pp (measured on the gate fixture; n=1000 => 0.1 pp per flip).
|
| 12 |
+
Block-mask proof on the base fixture: every question closer to the block reference than to the causal and prefix-causal controls.
|
| 13 |
+
|
| 14 |
+
Release set (user choice): GGUF F16 / Q8_0 / Q4_K_M; MLX bf16 / 8bit (affine g64).
|
| 15 |
+
Recipe 1 (primary): stock llama-quantize defaults; mlx_lm.convert defaults + FP32 norm sidecar + MLXScorerV2.
|
| 16 |
+
Recipe 2 (declared fallback, used ONLY if recipe 1 fails a gate): keep the tied embedding / readout rows at f16
|
| 17 |
+
(llama-quantize --token-embedding-type f16; MLX: quant predicate excluding embed_tokens). Same gates, same fixtures.
|
| 18 |
+
If recipe 2 also fails, that format is NOT shipped. Gates are not relaxed after seeing results.
|
| 19 |
+
|
| 20 |
+
## Public benchmarks (pre-declared 2026-09-26 22:01:49 AEST, before any 2B benchmark item was scored)
|
| 21 |
+
Timing (erratum added 2026-09-27 03:35 AEST): this section was appended by the same shell command that launched the
|
| 22 |
+
benchmark runs, immediately before the first item (file mtime 22:01:49; run log `runs/macjev/bench_2b/run_trained.log`
|
| 23 |
+
first line `[2026-09-26 22:01:49] START jevbench`; first result seen 22:06:28). The heading originally said
|
| 24 |
+
"22:10" by mistake. The format-gate section above was written when the file was created (21:46:03), before any
|
| 25 |
+
trained-weight format was scored (first format score started 21:53:00).
|
| 26 |
+
- Reported engine: GGUF F16 (runs/macjev/release_2b/gguf/model-f16.gguf, jev-score-v2, Metal), global T = 0.8278650621 only.
|
| 27 |
+
- JevBench v1.4.1 public (231) and elcronos zero-shot sets (tweet_topic / fin_topic / daily_dialog), each run ONCE,
|
| 28 |
+
same metric code as the 0.8B v3 card. No per-benchmark temperatures, no reruns, no prompt changes after seeing scores.
|
| 29 |
+
- Decision Index 0.2: not run locally; requested from the maintainer after release (user decision 2026-09-26).
|
validation/parity/compare_mlx_affine8-g64_base_vs_block.json
ADDED
|
@@ -0,0 +1,276 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"format": "8bit",
|
| 3 |
+
"temperature": 0.8278650620942867,
|
| 4 |
+
"overall": {
|
| 5 |
+
"n": 43,
|
| 6 |
+
"top1_agreement": 1.0,
|
| 7 |
+
"top1_flips": 0,
|
| 8 |
+
"max_abs_dscore": 0.4653351306915283,
|
| 9 |
+
"mean_abs_dscore": 0.023077200647273945,
|
| 10 |
+
"mean_kl": 0.0006975644872166873,
|
| 11 |
+
"n_gold": 43,
|
| 12 |
+
"nll_ref": 0.670433307194272,
|
| 13 |
+
"nll_cand": 0.6868139442506376,
|
| 14 |
+
"dnll": 0.01638063705636561,
|
| 15 |
+
"mean_abs_row_dnll": 0.030139399526949388,
|
| 16 |
+
"acc_ref": 0.7209302325581395,
|
| 17 |
+
"acc_cand": 0.7209302325581395,
|
| 18 |
+
"acc_drop_pp": 0.0
|
| 19 |
+
},
|
| 20 |
+
"per_category": {
|
| 21 |
+
"catalogue_overflow": {
|
| 22 |
+
"n": 3,
|
| 23 |
+
"top1_agreement": 1.0,
|
| 24 |
+
"top1_flips": 0,
|
| 25 |
+
"max_abs_dscore": 0.2735496163368225,
|
| 26 |
+
"mean_abs_dscore": 0.019241230377298316,
|
| 27 |
+
"mean_kl": 0.0012829640019479873,
|
| 28 |
+
"n_gold": 3,
|
| 29 |
+
"nll_ref": 0.5023960827418966,
|
| 30 |
+
"nll_cand": 0.46349011750257935,
|
| 31 |
+
"dnll": -0.038905965239317275,
|
| 32 |
+
"mean_abs_row_dnll": 0.039379824994875905,
|
| 33 |
+
"acc_ref": 0.6666666666666666,
|
| 34 |
+
"acc_cand": 0.6666666666666666,
|
| 35 |
+
"acc_drop_pp": 0.0
|
| 36 |
+
},
|
| 37 |
+
"catalogue_overflow_long_state": {
|
| 38 |
+
"n": 1,
|
| 39 |
+
"top1_agreement": 1.0,
|
| 40 |
+
"top1_flips": 0,
|
| 41 |
+
"max_abs_dscore": 0.09829854965209961,
|
| 42 |
+
"mean_abs_dscore": 0.02608197888001701,
|
| 43 |
+
"mean_kl": 0.00037418306666026774,
|
| 44 |
+
"n_gold": 1,
|
| 45 |
+
"nll_ref": 1.868953922917252,
|
| 46 |
+
"nll_cand": 1.8305656122814864,
|
| 47 |
+
"dnll": -0.03838831063576564,
|
| 48 |
+
"mean_abs_row_dnll": 0.03838831063576564,
|
| 49 |
+
"acc_ref": 0.0,
|
| 50 |
+
"acc_cand": 0.0,
|
| 51 |
+
"acc_drop_pp": 0.0
|
| 52 |
+
},
|
| 53 |
+
"long_16k": {
|
| 54 |
+
"n": 3,
|
| 55 |
+
"top1_agreement": 1.0,
|
| 56 |
+
"top1_flips": 0,
|
| 57 |
+
"max_abs_dscore": 0.4653351306915283,
|
| 58 |
+
"mean_abs_dscore": 0.04898447410160343,
|
| 59 |
+
"mean_kl": 0.005652873428140343,
|
| 60 |
+
"n_gold": 3,
|
| 61 |
+
"nll_ref": 1.098996986024778,
|
| 62 |
+
"nll_cand": 1.3040987437659517,
|
| 63 |
+
"dnll": 0.20510175774117378,
|
| 64 |
+
"mean_abs_row_dnll": 0.2051017577411738,
|
| 65 |
+
"acc_ref": 0.6666666666666666,
|
| 66 |
+
"acc_cand": 0.6666666666666666,
|
| 67 |
+
"acc_drop_pp": 0.0
|
| 68 |
+
},
|
| 69 |
+
"long_24k": {
|
| 70 |
+
"n": 2,
|
| 71 |
+
"top1_agreement": 1.0,
|
| 72 |
+
"top1_flips": 0,
|
| 73 |
+
"max_abs_dscore": 0.068747878074646,
|
| 74 |
+
"mean_abs_dscore": 0.03896120687325796,
|
| 75 |
+
"mean_kl": 0.0007690578648421433,
|
| 76 |
+
"n_gold": 2,
|
| 77 |
+
"nll_ref": 0.43411292245601785,
|
| 78 |
+
"nll_cand": 0.43100727732191557,
|
| 79 |
+
"dnll": -0.003105645134102275,
|
| 80 |
+
"mean_abs_row_dnll": 0.019953016950989222,
|
| 81 |
+
"acc_ref": 1.0,
|
| 82 |
+
"acc_cand": 1.0,
|
| 83 |
+
"acc_drop_pp": 0.0
|
| 84 |
+
},
|
| 85 |
+
"many_options": {
|
| 86 |
+
"n": 2,
|
| 87 |
+
"top1_agreement": 1.0,
|
| 88 |
+
"top1_flips": 0,
|
| 89 |
+
"max_abs_dscore": 0.06005406379699707,
|
| 90 |
+
"mean_abs_dscore": 0.01609148249030113,
|
| 91 |
+
"mean_kl": 3.102768330017338e-06,
|
| 92 |
+
"n_gold": 2,
|
| 93 |
+
"nll_ref": 0.012124599411053285,
|
| 94 |
+
"nll_cand": 0.012000711496263293,
|
| 95 |
+
"dnll": -0.00012388791478999163,
|
| 96 |
+
"mean_abs_row_dnll": 0.00012388791478999076,
|
| 97 |
+
"acc_ref": 1.0,
|
| 98 |
+
"acc_cand": 1.0,
|
| 99 |
+
"acc_drop_pp": 0.0
|
| 100 |
+
},
|
| 101 |
+
"multi_block_3k": {
|
| 102 |
+
"n": 2,
|
| 103 |
+
"top1_agreement": 1.0,
|
| 104 |
+
"top1_flips": 0,
|
| 105 |
+
"max_abs_dscore": 0.037885069847106934,
|
| 106 |
+
"mean_abs_dscore": 0.015739992260932922,
|
| 107 |
+
"mean_kl": 0.00011035902286322221,
|
| 108 |
+
"n_gold": 2,
|
| 109 |
+
"nll_ref": 0.10264503770560551,
|
| 110 |
+
"nll_cand": 0.09882922575086513,
|
| 111 |
+
"dnll": -0.0038158119547403863,
|
| 112 |
+
"mean_abs_row_dnll": 0.00429795147361977,
|
| 113 |
+
"acc_ref": 1.0,
|
| 114 |
+
"acc_cand": 1.0,
|
| 115 |
+
"acc_drop_pp": 0.0
|
| 116 |
+
},
|
| 117 |
+
"multi_block_5k": {
|
| 118 |
+
"n": 2,
|
| 119 |
+
"top1_agreement": 1.0,
|
| 120 |
+
"top1_flips": 0,
|
| 121 |
+
"max_abs_dscore": 0.0428202748298645,
|
| 122 |
+
"mean_abs_dscore": 0.02182019054889679,
|
| 123 |
+
"mean_kl": 4.99818269133305e-05,
|
| 124 |
+
"n_gold": 2,
|
| 125 |
+
"nll_ref": 0.41414880456154163,
|
| 126 |
+
"nll_cand": 0.40767085022183286,
|
| 127 |
+
"dnll": -0.006477954339708769,
|
| 128 |
+
"mean_abs_row_dnll": 0.006477954339708783,
|
| 129 |
+
"acc_ref": 1.0,
|
| 130 |
+
"acc_cand": 1.0,
|
| 131 |
+
"acc_drop_pp": 0.0
|
| 132 |
+
},
|
| 133 |
+
"multi_block_9k": {
|
| 134 |
+
"n": 2,
|
| 135 |
+
"top1_agreement": 1.0,
|
| 136 |
+
"top1_flips": 0,
|
| 137 |
+
"max_abs_dscore": 0.02951335906982422,
|
| 138 |
+
"mean_abs_dscore": 0.02005617693066597,
|
| 139 |
+
"mean_kl": 6.540709706121381e-06,
|
| 140 |
+
"n_gold": 2,
|
| 141 |
+
"nll_ref": 1.387121106483142,
|
| 142 |
+
"nll_cand": 1.3792866299819007,
|
| 143 |
+
"dnll": -0.00783447650124125,
|
| 144 |
+
"mean_abs_row_dnll": 0.00783447650124136,
|
| 145 |
+
"acc_ref": 0.5,
|
| 146 |
+
"acc_cand": 0.5,
|
| 147 |
+
"acc_drop_pp": 0.0
|
| 148 |
+
},
|
| 149 |
+
"multi_question": {
|
| 150 |
+
"n": 10,
|
| 151 |
+
"top1_agreement": 1.0,
|
| 152 |
+
"top1_flips": 0,
|
| 153 |
+
"max_abs_dscore": 0.06343865394592285,
|
| 154 |
+
"mean_abs_dscore": 0.018984448437889417,
|
| 155 |
+
"mean_kl": 0.00014264548450480086,
|
| 156 |
+
"n_gold": 10,
|
| 157 |
+
"nll_ref": 0.7606667410227165,
|
| 158 |
+
"nll_cand": 0.7742217565907421,
|
| 159 |
+
"dnll": 0.01355501556802563,
|
| 160 |
+
"mean_abs_row_dnll": 0.016602018627922027,
|
| 161 |
+
"acc_ref": 0.7,
|
| 162 |
+
"acc_cand": 0.7,
|
| 163 |
+
"acc_drop_pp": 0.0
|
| 164 |
+
},
|
| 165 |
+
"prefix_boundary": {
|
| 166 |
+
"n": 7,
|
| 167 |
+
"top1_agreement": 1.0,
|
| 168 |
+
"top1_flips": 0,
|
| 169 |
+
"max_abs_dscore": 0.07407116889953613,
|
| 170 |
+
"mean_abs_dscore": 0.02506211300690969,
|
| 171 |
+
"mean_kl": 0.000275167227242767,
|
| 172 |
+
"n_gold": 7,
|
| 173 |
+
"nll_ref": 0.9445710499909146,
|
| 174 |
+
"nll_cand": 0.9592024225354618,
|
| 175 |
+
"dnll": 0.014631372544547272,
|
| 176 |
+
"mean_abs_row_dnll": 0.026803385065686018,
|
| 177 |
+
"acc_ref": 0.5714285714285714,
|
| 178 |
+
"acc_cand": 0.5714285714285714,
|
| 179 |
+
"acc_drop_pp": 0.0
|
| 180 |
+
},
|
| 181 |
+
"qtype_choice": {
|
| 182 |
+
"n": 1,
|
| 183 |
+
"top1_agreement": 1.0,
|
| 184 |
+
"top1_flips": 0,
|
| 185 |
+
"max_abs_dscore": 0.039629340171813965,
|
| 186 |
+
"mean_abs_dscore": 0.01868373155593872,
|
| 187 |
+
"mean_kl": 9.758721027128357e-05,
|
| 188 |
+
"n_gold": 1,
|
| 189 |
+
"nll_ref": 1.2471588298811915,
|
| 190 |
+
"nll_cand": 1.2644290223938441,
|
| 191 |
+
"dnll": 0.017270192512652605,
|
| 192 |
+
"mean_abs_row_dnll": 0.017270192512652605,
|
| 193 |
+
"acc_ref": 0.0,
|
| 194 |
+
"acc_cand": 0.0,
|
| 195 |
+
"acc_drop_pp": 0.0
|
| 196 |
+
},
|
| 197 |
+
"qtype_noul": {
|
| 198 |
+
"n": 1,
|
| 199 |
+
"top1_agreement": 1.0,
|
| 200 |
+
"top1_flips": 0,
|
| 201 |
+
"max_abs_dscore": 0.04642695188522339,
|
| 202 |
+
"mean_abs_dscore": 0.02744242548942566,
|
| 203 |
+
"mean_kl": 0.00046207429765575576,
|
| 204 |
+
"n_gold": 1,
|
| 205 |
+
"nll_ref": 0.3643240477162341,
|
| 206 |
+
"nll_cand": 0.3445434412562239,
|
| 207 |
+
"dnll": -0.01978060646001023,
|
| 208 |
+
"mean_abs_row_dnll": 0.01978060646001023,
|
| 209 |
+
"acc_ref": 1.0,
|
| 210 |
+
"acc_cand": 1.0,
|
| 211 |
+
"acc_drop_pp": 0.0
|
| 212 |
+
},
|
| 213 |
+
"qtype_score": {
|
| 214 |
+
"n": 1,
|
| 215 |
+
"top1_agreement": 1.0,
|
| 216 |
+
"top1_flips": 0,
|
| 217 |
+
"max_abs_dscore": 0.04161477088928223,
|
| 218 |
+
"mean_abs_dscore": 0.015557724237442016,
|
| 219 |
+
"mean_kl": 1.4547309373278143e-05,
|
| 220 |
+
"n_gold": 1,
|
| 221 |
+
"nll_ref": 0.9393375234945696,
|
| 222 |
+
"nll_cand": 0.9372245712212975,
|
| 223 |
+
"dnll": -0.0021129522732720174,
|
| 224 |
+
"mean_abs_row_dnll": 0.0021129522732720174,
|
| 225 |
+
"acc_ref": 0.0,
|
| 226 |
+
"acc_cand": 0.0,
|
| 227 |
+
"acc_drop_pp": 0.0
|
| 228 |
+
},
|
| 229 |
+
"short_sb": {
|
| 230 |
+
"n": 6,
|
| 231 |
+
"top1_agreement": 1.0,
|
| 232 |
+
"top1_flips": 0,
|
| 233 |
+
"max_abs_dscore": 0.12482678890228271,
|
| 234 |
+
"mean_abs_dscore": 0.01820988009964663,
|
| 235 |
+
"mean_kl": 0.0005014431591724873,
|
| 236 |
+
"n_gold": 6,
|
| 237 |
+
"nll_ref": 0.11428482960768895,
|
| 238 |
+
"nll_cand": 0.123207743102961,
|
| 239 |
+
"dnll": 0.00892291349527205,
|
| 240 |
+
"mean_abs_row_dnll": 0.008996485578208901,
|
| 241 |
+
"acc_ref": 1.0,
|
| 242 |
+
"acc_cand": 1.0,
|
| 243 |
+
"acc_drop_pp": 0.0
|
| 244 |
+
}
|
| 245 |
+
},
|
| 246 |
+
"gates": {
|
| 247 |
+
"coverage_finite_tokens": {
|
| 248 |
+
"pass": true,
|
| 249 |
+
"problems": {},
|
| 250 |
+
"reference_missing_requests": 0
|
| 251 |
+
},
|
| 252 |
+
"top1": {
|
| 253 |
+
"threshold": 0.98,
|
| 254 |
+
"value": 1.0,
|
| 255 |
+
"pass": true
|
| 256 |
+
},
|
| 257 |
+
"dnll": {
|
| 258 |
+
"threshold": 0.02,
|
| 259 |
+
"value": 0.01638063705636561,
|
| 260 |
+
"pass": true
|
| 261 |
+
},
|
| 262 |
+
"acc_drop_pp": {
|
| 263 |
+
"threshold": 0.3,
|
| 264 |
+
"value": 0.0,
|
| 265 |
+
"resolution_pp": 2.3255813953488373,
|
| 266 |
+
"pass": null,
|
| 267 |
+
"note": "UNRESOLVED: 43 gold questions -> one flip = 2.33pp > 0.3pp; this fixture cannot resolve the gate (use the gate fixture with >= 334 rows; statistical power needs far more)"
|
| 268 |
+
}
|
| 269 |
+
},
|
| 270 |
+
"verdict": "INCONCLUSIVE",
|
| 271 |
+
"resolution_pp_per_flip": 2.3255813953488373,
|
| 272 |
+
"note": "small fixtures cannot resolve 0.3pp accuracy gates; accuracy on a parity fixture is only indicative (synthetic long rows carry the base row's gold label).",
|
| 273 |
+
"ref": "runs/macjev/runtime_v2_dev/reference_trained/ref_block_fp32.jsonl",
|
| 274 |
+
"cand": "runs/macjev/release_2b/parity/pred_mlx_affine8-g64_base.jsonl",
|
| 275 |
+
"fixture": "runs/macjev/runtime_v2_dev/reference_base/fixture.jsonl"
|
| 276 |
+
}
|
validation/parity/compare_mlx_affine8-g64_gate_vs_block.json
ADDED
|
@@ -0,0 +1,228 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"format": "8bit",
|
| 3 |
+
"temperature": 0.8278650620942867,
|
| 4 |
+
"overall": {
|
| 5 |
+
"n": 1000,
|
| 6 |
+
"top1_agreement": 0.996,
|
| 7 |
+
"top1_flips": 4,
|
| 8 |
+
"max_abs_dscore": 0.3184394836425781,
|
| 9 |
+
"mean_abs_dscore": 0.016680597170951345,
|
| 10 |
+
"mean_kl": 0.0002134925530053613,
|
| 11 |
+
"n_gold": 1000,
|
| 12 |
+
"nll_ref": 0.4436679457518203,
|
| 13 |
+
"nll_cand": 0.44417151398689614,
|
| 14 |
+
"dnll": 0.0005035682350758575,
|
| 15 |
+
"mean_abs_row_dnll": 0.008527335296640175,
|
| 16 |
+
"acc_ref": 0.808,
|
| 17 |
+
"acc_cand": 0.808,
|
| 18 |
+
"acc_drop_pp": 0.0
|
| 19 |
+
},
|
| 20 |
+
"per_category": {
|
| 21 |
+
"di_knowledge": {
|
| 22 |
+
"n": 93,
|
| 23 |
+
"top1_agreement": 0.978494623655914,
|
| 24 |
+
"top1_flips": 2,
|
| 25 |
+
"max_abs_dscore": 0.10516834259033203,
|
| 26 |
+
"mean_abs_dscore": 0.01826677256272753,
|
| 27 |
+
"mean_kl": 0.0001961899290394059,
|
| 28 |
+
"n_gold": 93,
|
| 29 |
+
"nll_ref": 0.7907936240501159,
|
| 30 |
+
"nll_cand": 0.7950259330695674,
|
| 31 |
+
"dnll": 0.004232309019451486,
|
| 32 |
+
"mean_abs_row_dnll": 0.012335049730692368,
|
| 33 |
+
"acc_ref": 0.6559139784946236,
|
| 34 |
+
"acc_cand": 0.6559139784946236,
|
| 35 |
+
"acc_drop_pp": 0.0
|
| 36 |
+
},
|
| 37 |
+
"di_language": {
|
| 38 |
+
"n": 93,
|
| 39 |
+
"top1_agreement": 1.0,
|
| 40 |
+
"top1_flips": 0,
|
| 41 |
+
"max_abs_dscore": 0.12582671642303467,
|
| 42 |
+
"mean_abs_dscore": 0.019231186946019475,
|
| 43 |
+
"mean_kl": 0.0002764365455637818,
|
| 44 |
+
"n_gold": 93,
|
| 45 |
+
"nll_ref": 0.43828192127009435,
|
| 46 |
+
"nll_cand": 0.4350339331964042,
|
| 47 |
+
"dnll": -0.0032479880736901445,
|
| 48 |
+
"mean_abs_row_dnll": 0.01105854314657161,
|
| 49 |
+
"acc_ref": 0.8494623655913979,
|
| 50 |
+
"acc_cand": 0.8494623655913979,
|
| 51 |
+
"acc_drop_pp": 0.0
|
| 52 |
+
},
|
| 53 |
+
"di_retrieval": {
|
| 54 |
+
"n": 93,
|
| 55 |
+
"top1_agreement": 1.0,
|
| 56 |
+
"top1_flips": 0,
|
| 57 |
+
"max_abs_dscore": 0.16489863395690918,
|
| 58 |
+
"mean_abs_dscore": 0.013032539303739148,
|
| 59 |
+
"mean_kl": 9.17728737128296e-05,
|
| 60 |
+
"n_gold": 93,
|
| 61 |
+
"nll_ref": 0.07565367364179643,
|
| 62 |
+
"nll_cand": 0.07596664403414172,
|
| 63 |
+
"dnll": 0.0003129703923452909,
|
| 64 |
+
"mean_abs_row_dnll": 0.0027333661229381077,
|
| 65 |
+
"acc_ref": 0.978494623655914,
|
| 66 |
+
"acc_cand": 0.978494623655914,
|
| 67 |
+
"acc_drop_pp": 0.0
|
| 68 |
+
},
|
| 69 |
+
"format": {
|
| 70 |
+
"n": 75,
|
| 71 |
+
"top1_agreement": 1.0,
|
| 72 |
+
"top1_flips": 0,
|
| 73 |
+
"max_abs_dscore": 0.15371152758598328,
|
| 74 |
+
"mean_abs_dscore": 0.014854268128133183,
|
| 75 |
+
"mean_kl": 8.706661370645814e-05,
|
| 76 |
+
"n_gold": 75,
|
| 77 |
+
"nll_ref": 0.09087868406020969,
|
| 78 |
+
"nll_cand": 0.09241995785860305,
|
| 79 |
+
"dnll": 0.001541273798393361,
|
| 80 |
+
"mean_abs_row_dnll": 0.003729830247715702,
|
| 81 |
+
"acc_ref": 0.9733333333333334,
|
| 82 |
+
"acc_cand": 0.9733333333333334,
|
| 83 |
+
"acc_drop_pp": 0.0
|
| 84 |
+
},
|
| 85 |
+
"general": {
|
| 86 |
+
"n": 93,
|
| 87 |
+
"top1_agreement": 1.0,
|
| 88 |
+
"top1_flips": 0,
|
| 89 |
+
"max_abs_dscore": 0.1003103256225586,
|
| 90 |
+
"mean_abs_dscore": 0.01342117658100456,
|
| 91 |
+
"mean_kl": 7.21948109281326e-05,
|
| 92 |
+
"n_gold": 93,
|
| 93 |
+
"nll_ref": 0.13061020512422436,
|
| 94 |
+
"nll_cand": 0.12993521810236933,
|
| 95 |
+
"dnll": -0.0006749870218550336,
|
| 96 |
+
"mean_abs_row_dnll": 0.003786342376918514,
|
| 97 |
+
"acc_ref": 0.967741935483871,
|
| 98 |
+
"acc_cand": 0.967741935483871,
|
| 99 |
+
"acc_drop_pp": 0.0
|
| 100 |
+
},
|
| 101 |
+
"hard_short": {
|
| 102 |
+
"n": 93,
|
| 103 |
+
"top1_agreement": 0.989247311827957,
|
| 104 |
+
"top1_flips": 1,
|
| 105 |
+
"max_abs_dscore": 0.12274712324142456,
|
| 106 |
+
"mean_abs_dscore": 0.020271506775084727,
|
| 107 |
+
"mean_kl": 0.00027143138298962177,
|
| 108 |
+
"n_gold": 93,
|
| 109 |
+
"nll_ref": 0.7835153258109905,
|
| 110 |
+
"nll_cand": 0.7861608190184016,
|
| 111 |
+
"dnll": 0.0026454932074111426,
|
| 112 |
+
"mean_abs_row_dnll": 0.014292107382686168,
|
| 113 |
+
"acc_ref": 0.6021505376344086,
|
| 114 |
+
"acc_cand": 0.5913978494623656,
|
| 115 |
+
"acc_drop_pp": 1.0752688172043001
|
| 116 |
+
},
|
| 117 |
+
"long": {
|
| 118 |
+
"n": 92,
|
| 119 |
+
"top1_agreement": 1.0,
|
| 120 |
+
"top1_flips": 0,
|
| 121 |
+
"max_abs_dscore": 0.3184394836425781,
|
| 122 |
+
"mean_abs_dscore": 0.020006766643251753,
|
| 123 |
+
"mean_kl": 0.0007467326030115854,
|
| 124 |
+
"n_gold": 92,
|
| 125 |
+
"nll_ref": 0.10827285500173092,
|
| 126 |
+
"nll_cand": 0.10447898892584594,
|
| 127 |
+
"dnll": -0.0037938660758849857,
|
| 128 |
+
"mean_abs_row_dnll": 0.008173341485227314,
|
| 129 |
+
"acc_ref": 0.967391304347826,
|
| 130 |
+
"acc_cand": 0.967391304347826,
|
| 131 |
+
"acc_drop_pp": 0.0
|
| 132 |
+
},
|
| 133 |
+
"mac": {
|
| 134 |
+
"n": 92,
|
| 135 |
+
"top1_agreement": 1.0,
|
| 136 |
+
"top1_flips": 0,
|
| 137 |
+
"max_abs_dscore": 0.05875861644744873,
|
| 138 |
+
"mean_abs_dscore": 0.013405789823635765,
|
| 139 |
+
"mean_kl": 3.8362254891210755e-05,
|
| 140 |
+
"n_gold": 92,
|
| 141 |
+
"nll_ref": 0.3262944821095264,
|
| 142 |
+
"nll_cand": 0.3269720723076003,
|
| 143 |
+
"dnll": 0.0006775901980738963,
|
| 144 |
+
"mean_abs_row_dnll": 0.0040734288260641455,
|
| 145 |
+
"acc_ref": 0.8369565217391305,
|
| 146 |
+
"acc_cand": 0.8369565217391305,
|
| 147 |
+
"acc_drop_pp": 0.0
|
| 148 |
+
},
|
| 149 |
+
"public_ingests": {
|
| 150 |
+
"n": 92,
|
| 151 |
+
"top1_agreement": 0.9891304347826086,
|
| 152 |
+
"top1_flips": 1,
|
| 153 |
+
"max_abs_dscore": 0.146925687789917,
|
| 154 |
+
"mean_abs_dscore": 0.020489049231511028,
|
| 155 |
+
"mean_kl": 0.00030913724098080613,
|
| 156 |
+
"n_gold": 92,
|
| 157 |
+
"nll_ref": 0.7667467143475788,
|
| 158 |
+
"nll_cand": 0.7701994879203283,
|
| 159 |
+
"dnll": 0.0034527735727495346,
|
| 160 |
+
"mean_abs_row_dnll": 0.016463952376233926,
|
| 161 |
+
"acc_ref": 0.6521739130434783,
|
| 162 |
+
"acc_cand": 0.6630434782608695,
|
| 163 |
+
"acc_drop_pp": -1.0869565217391242
|
| 164 |
+
},
|
| 165 |
+
"themes": {
|
| 166 |
+
"n": 92,
|
| 167 |
+
"top1_agreement": 1.0,
|
| 168 |
+
"top1_flips": 0,
|
| 169 |
+
"max_abs_dscore": 0.05321455001831055,
|
| 170 |
+
"mean_abs_dscore": 0.012158645316958427,
|
| 171 |
+
"mean_kl": 2.255066396046878e-05,
|
| 172 |
+
"n_gold": 92,
|
| 173 |
+
"nll_ref": 0.27025191463643466,
|
| 174 |
+
"nll_cand": 0.27031868131249703,
|
| 175 |
+
"dnll": 6.676667606236864e-05,
|
| 176 |
+
"mean_abs_row_dnll": 0.003036639894596646,
|
| 177 |
+
"acc_ref": 0.8695652173913043,
|
| 178 |
+
"acc_cand": 0.8695652173913043,
|
| 179 |
+
"acc_drop_pp": 0.0
|
| 180 |
+
},
|
| 181 |
+
"typed_synthetic": {
|
| 182 |
+
"n": 92,
|
| 183 |
+
"top1_agreement": 1.0,
|
| 184 |
+
"top1_flips": 0,
|
| 185 |
+
"max_abs_dscore": 0.07491475343704224,
|
| 186 |
+
"mean_abs_dscore": 0.018002478546206502,
|
| 187 |
+
"mean_kl": 0.00021491486269545232,
|
| 188 |
+
"n_gold": 92,
|
| 189 |
+
"nll_ref": 1.0338530850662833,
|
| 190 |
+
"nll_cand": 1.0343635982006703,
|
| 191 |
+
"dnll": 0.0005105131343869918,
|
| 192 |
+
"mean_abs_row_dnll": 0.0132145397374374,
|
| 193 |
+
"acc_ref": 0.5652173913043478,
|
| 194 |
+
"acc_cand": 0.5652173913043478,
|
| 195 |
+
"acc_drop_pp": 0.0
|
| 196 |
+
}
|
| 197 |
+
},
|
| 198 |
+
"gates": {
|
| 199 |
+
"coverage_finite_tokens": {
|
| 200 |
+
"pass": true,
|
| 201 |
+
"problems": {},
|
| 202 |
+
"reference_missing_requests": 0
|
| 203 |
+
},
|
| 204 |
+
"top1": {
|
| 205 |
+
"threshold": 0.98,
|
| 206 |
+
"value": 0.996,
|
| 207 |
+
"pass": true
|
| 208 |
+
},
|
| 209 |
+
"dnll": {
|
| 210 |
+
"threshold": 0.02,
|
| 211 |
+
"value": 0.0005035682350758575,
|
| 212 |
+
"pass": true
|
| 213 |
+
},
|
| 214 |
+
"acc_drop_pp": {
|
| 215 |
+
"threshold": 0.3,
|
| 216 |
+
"value": 0.0,
|
| 217 |
+
"resolution_pp": 0.1,
|
| 218 |
+
"pass": true,
|
| 219 |
+
"note": null
|
| 220 |
+
}
|
| 221 |
+
},
|
| 222 |
+
"verdict": "PASS",
|
| 223 |
+
"resolution_pp_per_flip": 0.1,
|
| 224 |
+
"note": "small fixtures cannot resolve 0.3pp accuracy gates; accuracy on a parity fixture is only indicative (synthetic long rows carry the base row's gold label).",
|
| 225 |
+
"ref": "runs/macjev/runtime_v2_dev/reference_trained/gate_ref_block_fp32.jsonl",
|
| 226 |
+
"cand": "runs/macjev/release_2b/parity/pred_mlx_affine8-g64_gate.jsonl",
|
| 227 |
+
"fixture": "runs/macjev/runtime_v2_dev/reference/gate_fixture_n1000.jsonl"
|
| 228 |
+
}
|
validation/parity/compare_mlx_bf16_base_vs_block.json
ADDED
|
@@ -0,0 +1,269 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"format": "bf16",
|
| 3 |
+
"temperature": 0.8278650620942867,
|
| 4 |
+
"overall": {
|
| 5 |
+
"n": 43,
|
| 6 |
+
"top1_agreement": 1.0,
|
| 7 |
+
"top1_flips": 0,
|
| 8 |
+
"max_abs_dscore": 0.08836114406585693,
|
| 9 |
+
"mean_abs_dscore": 0.01365492056503762,
|
| 10 |
+
"mean_kl": 9.883488035170103e-05,
|
| 11 |
+
"n_gold": 43,
|
| 12 |
+
"nll_ref": 0.670433307194272,
|
| 13 |
+
"nll_cand": 0.6677389810942516,
|
| 14 |
+
"dnll": -0.0026943261000204055,
|
| 15 |
+
"mean_abs_row_dnll": 0.009347213165255148,
|
| 16 |
+
"acc_ref": 0.7209302325581395,
|
| 17 |
+
"acc_cand": 0.7209302325581395,
|
| 18 |
+
"acc_drop_pp": 0.0
|
| 19 |
+
},
|
| 20 |
+
"per_category": {
|
| 21 |
+
"catalogue_overflow": {
|
| 22 |
+
"n": 3,
|
| 23 |
+
"top1_agreement": 1.0,
|
| 24 |
+
"top1_flips": 0,
|
| 25 |
+
"max_abs_dscore": 0.08836114406585693,
|
| 26 |
+
"mean_abs_dscore": 0.012576654652096578,
|
| 27 |
+
"mean_kl": 9.049678076068058e-05,
|
| 28 |
+
"n_gold": 3,
|
| 29 |
+
"nll_ref": 0.5023960827418966,
|
| 30 |
+
"nll_cand": 0.49688457645611867,
|
| 31 |
+
"dnll": -0.005511506285777956,
|
| 32 |
+
"mean_abs_row_dnll": 0.005740943453378988,
|
| 33 |
+
"acc_ref": 0.6666666666666666,
|
| 34 |
+
"acc_cand": 0.6666666666666666,
|
| 35 |
+
"acc_drop_pp": 0.0
|
| 36 |
+
},
|
| 37 |
+
"catalogue_overflow_long_state": {
|
| 38 |
+
"n": 1,
|
| 39 |
+
"top1_agreement": 1.0,
|
| 40 |
+
"top1_flips": 0,
|
| 41 |
+
"max_abs_dscore": 0.04151296615600586,
|
| 42 |
+
"mean_abs_dscore": 0.012695910914844235,
|
| 43 |
+
"mean_kl": 0.00019275121223053925,
|
| 44 |
+
"n_gold": 1,
|
| 45 |
+
"nll_ref": 1.868953922917252,
|
| 46 |
+
"nll_cand": 1.8621515972563385,
|
| 47 |
+
"dnll": -0.006802325660913544,
|
| 48 |
+
"mean_abs_row_dnll": 0.006802325660913544,
|
| 49 |
+
"acc_ref": 0.0,
|
| 50 |
+
"acc_cand": 0.0,
|
| 51 |
+
"acc_drop_pp": 0.0
|
| 52 |
+
},
|
| 53 |
+
"long_16k": {
|
| 54 |
+
"n": 3,
|
| 55 |
+
"top1_agreement": 1.0,
|
| 56 |
+
"top1_flips": 0,
|
| 57 |
+
"max_abs_dscore": 0.05213227868080139,
|
| 58 |
+
"mean_abs_dscore": 0.014879310828434184,
|
| 59 |
+
"mean_kl": 0.000149667886473795,
|
| 60 |
+
"n_gold": 3,
|
| 61 |
+
"nll_ref": 1.098996986024778,
|
| 62 |
+
"nll_cand": 1.0956083262917284,
|
| 63 |
+
"dnll": -0.0033886597330494705,
|
| 64 |
+
"mean_abs_row_dnll": 0.006144886758009865,
|
| 65 |
+
"acc_ref": 0.6666666666666666,
|
| 66 |
+
"acc_cand": 0.6666666666666666,
|
| 67 |
+
"acc_drop_pp": 0.0
|
| 68 |
+
},
|
| 69 |
+
"long_24k": {
|
| 70 |
+
"n": 2,
|
| 71 |
+
"top1_agreement": 1.0,
|
| 72 |
+
"top1_flips": 0,
|
| 73 |
+
"max_abs_dscore": 0.03363656997680664,
|
| 74 |
+
"mean_abs_dscore": 0.012938144306341806,
|
| 75 |
+
"mean_kl": 0.0001715685914165032,
|
| 76 |
+
"n_gold": 2,
|
| 77 |
+
"nll_ref": 0.43411292245601785,
|
| 78 |
+
"nll_cand": 0.42479629433910976,
|
| 79 |
+
"dnll": -0.009316628116908088,
|
| 80 |
+
"mean_abs_row_dnll": 0.00931662811690806,
|
| 81 |
+
"acc_ref": 1.0,
|
| 82 |
+
"acc_cand": 1.0,
|
| 83 |
+
"acc_drop_pp": 0.0
|
| 84 |
+
},
|
| 85 |
+
"many_options": {
|
| 86 |
+
"n": 2,
|
| 87 |
+
"top1_agreement": 1.0,
|
| 88 |
+
"top1_flips": 0,
|
| 89 |
+
"max_abs_dscore": 0.03784656524658203,
|
| 90 |
+
"mean_abs_dscore": 0.0131730338682731,
|
| 91 |
+
"mean_kl": 4.283448514828303e-06,
|
| 92 |
+
"n_gold": 2,
|
| 93 |
+
"nll_ref": 0.012124599411053285,
|
| 94 |
+
"nll_cand": 0.01233819862308103,
|
| 95 |
+
"dnll": 0.0002135992120277444,
|
| 96 |
+
"mean_abs_row_dnll": 0.00021359921202774614,
|
| 97 |
+
"acc_ref": 1.0,
|
| 98 |
+
"acc_cand": 1.0,
|
| 99 |
+
"acc_drop_pp": 0.0
|
| 100 |
+
},
|
| 101 |
+
"multi_block_3k": {
|
| 102 |
+
"n": 2,
|
| 103 |
+
"top1_agreement": 1.0,
|
| 104 |
+
"top1_flips": 0,
|
| 105 |
+
"max_abs_dscore": 0.053168416023254395,
|
| 106 |
+
"mean_abs_dscore": 0.011156398057937621,
|
| 107 |
+
"mean_kl": 0.00020998625581104233,
|
| 108 |
+
"n_gold": 2,
|
| 109 |
+
"nll_ref": 0.10264503770560551,
|
| 110 |
+
"nll_cand": 0.09699945875175084,
|
| 111 |
+
"dnll": -0.005645578953854674,
|
| 112 |
+
"mean_abs_row_dnll": 0.005792563090663002,
|
| 113 |
+
"acc_ref": 1.0,
|
| 114 |
+
"acc_cand": 1.0,
|
| 115 |
+
"acc_drop_pp": 0.0
|
| 116 |
+
},
|
| 117 |
+
"multi_block_5k": {
|
| 118 |
+
"n": 2,
|
| 119 |
+
"top1_agreement": 1.0,
|
| 120 |
+
"top1_flips": 0,
|
| 121 |
+
"max_abs_dscore": 0.018996506929397583,
|
| 122 |
+
"mean_abs_dscore": 0.010537676513195038,
|
| 123 |
+
"mean_kl": 7.5737981061909e-05,
|
| 124 |
+
"n_gold": 2,
|
| 125 |
+
"nll_ref": 0.41414880456154163,
|
| 126 |
+
"nll_cand": 0.40761999179423464,
|
| 127 |
+
"dnll": -0.006528812767306991,
|
| 128 |
+
"mean_abs_row_dnll": 0.0065288127673070045,
|
| 129 |
+
"acc_ref": 1.0,
|
| 130 |
+
"acc_cand": 1.0,
|
| 131 |
+
"acc_drop_pp": 0.0
|
| 132 |
+
},
|
| 133 |
+
"multi_block_9k": {
|
| 134 |
+
"n": 2,
|
| 135 |
+
"top1_agreement": 1.0,
|
| 136 |
+
"top1_flips": 0,
|
| 137 |
+
"max_abs_dscore": 0.033649444580078125,
|
| 138 |
+
"mean_abs_dscore": 0.00982309877872467,
|
| 139 |
+
"mean_kl": 8.772959532626077e-05,
|
| 140 |
+
"n_gold": 2,
|
| 141 |
+
"nll_ref": 1.387121106483142,
|
| 142 |
+
"nll_cand": 1.389387240331538,
|
| 143 |
+
"dnll": 0.0022661338483960236,
|
| 144 |
+
"mean_abs_row_dnll": 0.009883718382939666,
|
| 145 |
+
"acc_ref": 0.5,
|
| 146 |
+
"acc_cand": 0.5,
|
| 147 |
+
"acc_drop_pp": 0.0
|
| 148 |
+
},
|
| 149 |
+
"multi_question": {
|
| 150 |
+
"n": 10,
|
| 151 |
+
"top1_agreement": 1.0,
|
| 152 |
+
"top1_flips": 0,
|
| 153 |
+
"max_abs_dscore": 0.06624865531921387,
|
| 154 |
+
"mean_abs_dscore": 0.014526768724123637,
|
| 155 |
+
"mean_kl": 8.529135561399713e-05,
|
| 156 |
+
"n_gold": 10,
|
| 157 |
+
"nll_ref": 0.7606667410227165,
|
| 158 |
+
"nll_cand": 0.7570780864187747,
|
| 159 |
+
"dnll": -0.0035886546039417544,
|
| 160 |
+
"mean_abs_row_dnll": 0.010879836749203488,
|
| 161 |
+
"acc_ref": 0.7,
|
| 162 |
+
"acc_cand": 0.7,
|
| 163 |
+
"acc_drop_pp": 0.0
|
| 164 |
+
},
|
| 165 |
+
"prefix_boundary": {
|
| 166 |
+
"n": 7,
|
| 167 |
+
"top1_agreement": 1.0,
|
| 168 |
+
"top1_flips": 0,
|
| 169 |
+
"max_abs_dscore": 0.047842979431152344,
|
| 170 |
+
"mean_abs_dscore": 0.014937927183650791,
|
| 171 |
+
"mean_kl": 0.00011731551621384146,
|
| 172 |
+
"n_gold": 7,
|
| 173 |
+
"nll_ref": 0.9445710499909146,
|
| 174 |
+
"nll_cand": 0.9344505690212561,
|
| 175 |
+
"dnll": -0.010120480969658452,
|
| 176 |
+
"mean_abs_row_dnll": 0.01758201360584486,
|
| 177 |
+
"acc_ref": 0.5714285714285714,
|
| 178 |
+
"acc_cand": 0.5714285714285714,
|
| 179 |
+
"acc_drop_pp": 0.0
|
| 180 |
+
},
|
| 181 |
+
"qtype_choice": {
|
| 182 |
+
"n": 1,
|
| 183 |
+
"top1_agreement": 1.0,
|
| 184 |
+
"top1_flips": 0,
|
| 185 |
+
"max_abs_dscore": 0.02133503556251526,
|
| 186 |
+
"mean_abs_dscore": 0.013152092695236206,
|
| 187 |
+
"mean_kl": 8.789457820938037e-05,
|
| 188 |
+
"n_gold": 1,
|
| 189 |
+
"nll_ref": 1.2471588298811915,
|
| 190 |
+
"nll_cand": 1.267813737179954,
|
| 191 |
+
"dnll": 0.020654907298762515,
|
| 192 |
+
"mean_abs_row_dnll": 0.020654907298762515,
|
| 193 |
+
"acc_ref": 0.0,
|
| 194 |
+
"acc_cand": 0.0,
|
| 195 |
+
"acc_drop_pp": 0.0
|
| 196 |
+
},
|
| 197 |
+
"qtype_noul": {
|
| 198 |
+
"n": 1,
|
| 199 |
+
"top1_agreement": 1.0,
|
| 200 |
+
"top1_flips": 0,
|
| 201 |
+
"max_abs_dscore": 0.010687410831451416,
|
| 202 |
+
"mean_abs_dscore": 0.006474539637565613,
|
| 203 |
+
"mean_kl": 2.599908743399675e-05,
|
| 204 |
+
"n_gold": 1,
|
| 205 |
+
"nll_ref": 0.3643240477162341,
|
| 206 |
+
"nll_cand": 0.3691259380231449,
|
| 207 |
+
"dnll": 0.004801890306910805,
|
| 208 |
+
"mean_abs_row_dnll": 0.004801890306910805,
|
| 209 |
+
"acc_ref": 1.0,
|
| 210 |
+
"acc_cand": 1.0,
|
| 211 |
+
"acc_drop_pp": 0.0
|
| 212 |
+
},
|
| 213 |
+
"qtype_score": {
|
| 214 |
+
"n": 1,
|
| 215 |
+
"top1_agreement": 1.0,
|
| 216 |
+
"top1_flips": 0,
|
| 217 |
+
"max_abs_dscore": 0.03596752882003784,
|
| 218 |
+
"mean_abs_dscore": 0.013961112499237061,
|
| 219 |
+
"mean_kl": 0.0002653113090994117,
|
| 220 |
+
"n_gold": 1,
|
| 221 |
+
"nll_ref": 0.9393375234945696,
|
| 222 |
+
"nll_cand": 0.9660497441698873,
|
| 223 |
+
"dnll": 0.026712220675317755,
|
| 224 |
+
"mean_abs_row_dnll": 0.026712220675317755,
|
| 225 |
+
"acc_ref": 0.0,
|
| 226 |
+
"acc_cand": 0.0,
|
| 227 |
+
"acc_drop_pp": 0.0
|
| 228 |
+
},
|
| 229 |
+
"short_sb": {
|
| 230 |
+
"n": 6,
|
| 231 |
+
"top1_agreement": 1.0,
|
| 232 |
+
"top1_flips": 0,
|
| 233 |
+
"max_abs_dscore": 0.04204094409942627,
|
| 234 |
+
"mean_abs_dscore": 0.015570025255400981,
|
| 235 |
+
"mean_kl": 3.078595875807344e-05,
|
| 236 |
+
"n_gold": 6,
|
| 237 |
+
"nll_ref": 0.11428482960768895,
|
| 238 |
+
"nll_cand": 0.11598987452733013,
|
| 239 |
+
"dnll": 0.0017050449196411854,
|
| 240 |
+
"mean_abs_row_dnll": 0.0019930376095433936,
|
| 241 |
+
"acc_ref": 1.0,
|
| 242 |
+
"acc_cand": 1.0,
|
| 243 |
+
"acc_drop_pp": 0.0
|
| 244 |
+
}
|
| 245 |
+
},
|
| 246 |
+
"gates": {
|
| 247 |
+
"coverage_finite_tokens": {
|
| 248 |
+
"pass": true,
|
| 249 |
+
"problems": {},
|
| 250 |
+
"reference_missing_requests": 0
|
| 251 |
+
},
|
| 252 |
+
"top1": {
|
| 253 |
+
"threshold": 0.99,
|
| 254 |
+
"value": 1.0,
|
| 255 |
+
"pass": true
|
| 256 |
+
},
|
| 257 |
+
"dnll": {
|
| 258 |
+
"threshold": 0.02,
|
| 259 |
+
"value": -0.0026943261000204055,
|
| 260 |
+
"pass": true
|
| 261 |
+
}
|
| 262 |
+
},
|
| 263 |
+
"verdict": "PASS",
|
| 264 |
+
"resolution_pp_per_flip": 2.3255813953488373,
|
| 265 |
+
"note": "small fixtures cannot resolve 0.3pp accuracy gates; accuracy on a parity fixture is only indicative (synthetic long rows carry the base row's gold label).",
|
| 266 |
+
"ref": "runs/macjev/runtime_v2_dev/reference_trained/ref_block_fp32.jsonl",
|
| 267 |
+
"cand": "runs/macjev/release_2b/parity/pred_mlx_bf16_base.jsonl",
|
| 268 |
+
"fixture": "runs/macjev/runtime_v2_dev/reference_base/fixture.jsonl"
|
| 269 |
+
}
|
validation/parity/compare_mlx_bf16_gate_vs_block.json
ADDED
|
@@ -0,0 +1,221 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"format": "bf16",
|
| 3 |
+
"temperature": 0.8278650620942867,
|
| 4 |
+
"overall": {
|
| 5 |
+
"n": 1000,
|
| 6 |
+
"top1_agreement": 0.997,
|
| 7 |
+
"top1_flips": 3,
|
| 8 |
+
"max_abs_dscore": 0.13961565494537354,
|
| 9 |
+
"mean_abs_dscore": 0.012822698334419146,
|
| 10 |
+
"mean_kl": 7.013363207503902e-05,
|
| 11 |
+
"n_gold": 1000,
|
| 12 |
+
"nll_ref": 0.4436679457518203,
|
| 13 |
+
"nll_cand": 0.4437944677940992,
|
| 14 |
+
"dnll": 0.0001265220422789204,
|
| 15 |
+
"mean_abs_row_dnll": 0.005641898326944814,
|
| 16 |
+
"acc_ref": 0.808,
|
| 17 |
+
"acc_cand": 0.805,
|
| 18 |
+
"acc_drop_pp": 0.30000000000000027
|
| 19 |
+
},
|
| 20 |
+
"per_category": {
|
| 21 |
+
"di_knowledge": {
|
| 22 |
+
"n": 93,
|
| 23 |
+
"top1_agreement": 1.0,
|
| 24 |
+
"top1_flips": 0,
|
| 25 |
+
"max_abs_dscore": 0.07215514779090881,
|
| 26 |
+
"mean_abs_dscore": 0.014889913475799058,
|
| 27 |
+
"mean_kl": 0.00013722336018850683,
|
| 28 |
+
"n_gold": 93,
|
| 29 |
+
"nll_ref": 0.7907936240501159,
|
| 30 |
+
"nll_cand": 0.7927041608827371,
|
| 31 |
+
"dnll": 0.0019105368326212124,
|
| 32 |
+
"mean_abs_row_dnll": 0.01039648465267476,
|
| 33 |
+
"acc_ref": 0.6559139784946236,
|
| 34 |
+
"acc_cand": 0.6559139784946236,
|
| 35 |
+
"acc_drop_pp": 0.0
|
| 36 |
+
},
|
| 37 |
+
"di_language": {
|
| 38 |
+
"n": 93,
|
| 39 |
+
"top1_agreement": 1.0,
|
| 40 |
+
"top1_flips": 0,
|
| 41 |
+
"max_abs_dscore": 0.0584871768951416,
|
| 42 |
+
"mean_abs_dscore": 0.013199496934170362,
|
| 43 |
+
"mean_kl": 4.376886766709004e-05,
|
| 44 |
+
"n_gold": 93,
|
| 45 |
+
"nll_ref": 0.43828192127009435,
|
| 46 |
+
"nll_cand": 0.43613660599650544,
|
| 47 |
+
"dnll": -0.0021453152735889103,
|
| 48 |
+
"mean_abs_row_dnll": 0.005769073926221885,
|
| 49 |
+
"acc_ref": 0.8494623655913979,
|
| 50 |
+
"acc_cand": 0.8494623655913979,
|
| 51 |
+
"acc_drop_pp": 0.0
|
| 52 |
+
},
|
| 53 |
+
"di_retrieval": {
|
| 54 |
+
"n": 93,
|
| 55 |
+
"top1_agreement": 1.0,
|
| 56 |
+
"top1_flips": 0,
|
| 57 |
+
"max_abs_dscore": 0.13961565494537354,
|
| 58 |
+
"mean_abs_dscore": 0.011278054842327665,
|
| 59 |
+
"mean_kl": 6.320183776936612e-05,
|
| 60 |
+
"n_gold": 93,
|
| 61 |
+
"nll_ref": 0.07565367364179643,
|
| 62 |
+
"nll_cand": 0.07529180302084762,
|
| 63 |
+
"dnll": -0.0003618706209488065,
|
| 64 |
+
"mean_abs_row_dnll": 0.0018865181948961214,
|
| 65 |
+
"acc_ref": 0.978494623655914,
|
| 66 |
+
"acc_cand": 0.978494623655914,
|
| 67 |
+
"acc_drop_pp": 0.0
|
| 68 |
+
},
|
| 69 |
+
"format": {
|
| 70 |
+
"n": 75,
|
| 71 |
+
"top1_agreement": 1.0,
|
| 72 |
+
"top1_flips": 0,
|
| 73 |
+
"max_abs_dscore": 0.07049310207366943,
|
| 74 |
+
"mean_abs_dscore": 0.012186950511526283,
|
| 75 |
+
"mean_kl": 1.866440251394625e-05,
|
| 76 |
+
"n_gold": 75,
|
| 77 |
+
"nll_ref": 0.09087868406020969,
|
| 78 |
+
"nll_cand": 0.09027726831006917,
|
| 79 |
+
"dnll": -0.0006014157501405132,
|
| 80 |
+
"mean_abs_row_dnll": 0.0017343322558420642,
|
| 81 |
+
"acc_ref": 0.9733333333333334,
|
| 82 |
+
"acc_cand": 0.9733333333333334,
|
| 83 |
+
"acc_drop_pp": 0.0
|
| 84 |
+
},
|
| 85 |
+
"general": {
|
| 86 |
+
"n": 93,
|
| 87 |
+
"top1_agreement": 1.0,
|
| 88 |
+
"top1_flips": 0,
|
| 89 |
+
"max_abs_dscore": 0.053872108459472656,
|
| 90 |
+
"mean_abs_dscore": 0.011199172480311083,
|
| 91 |
+
"mean_kl": 8.964417186979084e-06,
|
| 92 |
+
"n_gold": 93,
|
| 93 |
+
"nll_ref": 0.13061020512422436,
|
| 94 |
+
"nll_cand": 0.12994049456566417,
|
| 95 |
+
"dnll": -0.0006697105585601881,
|
| 96 |
+
"mean_abs_row_dnll": 0.0015611860129022736,
|
| 97 |
+
"acc_ref": 0.967741935483871,
|
| 98 |
+
"acc_cand": 0.967741935483871,
|
| 99 |
+
"acc_drop_pp": 0.0
|
| 100 |
+
},
|
| 101 |
+
"hard_short": {
|
| 102 |
+
"n": 93,
|
| 103 |
+
"top1_agreement": 0.989247311827957,
|
| 104 |
+
"top1_flips": 1,
|
| 105 |
+
"max_abs_dscore": 0.06802543997764587,
|
| 106 |
+
"mean_abs_dscore": 0.014637837174057167,
|
| 107 |
+
"mean_kl": 0.00013160361749015227,
|
| 108 |
+
"n_gold": 93,
|
| 109 |
+
"nll_ref": 0.7835153258109905,
|
| 110 |
+
"nll_cand": 0.782783474188176,
|
| 111 |
+
"dnll": -0.0007318516228145278,
|
| 112 |
+
"mean_abs_row_dnll": 0.01093632719811279,
|
| 113 |
+
"acc_ref": 0.6021505376344086,
|
| 114 |
+
"acc_cand": 0.5913978494623656,
|
| 115 |
+
"acc_drop_pp": 1.0752688172043001
|
| 116 |
+
},
|
| 117 |
+
"long": {
|
| 118 |
+
"n": 92,
|
| 119 |
+
"top1_agreement": 1.0,
|
| 120 |
+
"top1_flips": 0,
|
| 121 |
+
"max_abs_dscore": 0.1342533826828003,
|
| 122 |
+
"mean_abs_dscore": 0.013823732117665294,
|
| 123 |
+
"mean_kl": 6.168921301697641e-05,
|
| 124 |
+
"n_gold": 92,
|
| 125 |
+
"nll_ref": 0.10827285500173092,
|
| 126 |
+
"nll_cand": 0.10768749311257943,
|
| 127 |
+
"dnll": -0.000585361889151495,
|
| 128 |
+
"mean_abs_row_dnll": 0.002564256755867923,
|
| 129 |
+
"acc_ref": 0.967391304347826,
|
| 130 |
+
"acc_cand": 0.967391304347826,
|
| 131 |
+
"acc_drop_pp": 0.0
|
| 132 |
+
},
|
| 133 |
+
"mac": {
|
| 134 |
+
"n": 92,
|
| 135 |
+
"top1_agreement": 1.0,
|
| 136 |
+
"top1_flips": 0,
|
| 137 |
+
"max_abs_dscore": 0.04618799686431885,
|
| 138 |
+
"mean_abs_dscore": 0.01143809092109618,
|
| 139 |
+
"mean_kl": 2.6581458539860547e-05,
|
| 140 |
+
"n_gold": 92,
|
| 141 |
+
"nll_ref": 0.3262944821095264,
|
| 142 |
+
"nll_cand": 0.3269180887247012,
|
| 143 |
+
"dnll": 0.0006236066151747988,
|
| 144 |
+
"mean_abs_row_dnll": 0.003772370527716574,
|
| 145 |
+
"acc_ref": 0.8369565217391305,
|
| 146 |
+
"acc_cand": 0.8369565217391305,
|
| 147 |
+
"acc_drop_pp": 0.0
|
| 148 |
+
},
|
| 149 |
+
"public_ingests": {
|
| 150 |
+
"n": 92,
|
| 151 |
+
"top1_agreement": 1.0,
|
| 152 |
+
"top1_flips": 0,
|
| 153 |
+
"max_abs_dscore": 0.10585364699363708,
|
| 154 |
+
"mean_abs_dscore": 0.015097456673118565,
|
| 155 |
+
"mean_kl": 0.00015103258358910773,
|
| 156 |
+
"n_gold": 92,
|
| 157 |
+
"nll_ref": 0.7667467143475788,
|
| 158 |
+
"nll_cand": 0.7682457652594957,
|
| 159 |
+
"dnll": 0.0014990509119169326,
|
| 160 |
+
"mean_abs_row_dnll": 0.010491535553020102,
|
| 161 |
+
"acc_ref": 0.6521739130434783,
|
| 162 |
+
"acc_cand": 0.6521739130434783,
|
| 163 |
+
"acc_drop_pp": 0.0
|
| 164 |
+
},
|
| 165 |
+
"themes": {
|
| 166 |
+
"n": 92,
|
| 167 |
+
"top1_agreement": 0.9891304347826086,
|
| 168 |
+
"top1_flips": 1,
|
| 169 |
+
"max_abs_dscore": 0.04355478286743164,
|
| 170 |
+
"mean_abs_dscore": 0.010605669458923132,
|
| 171 |
+
"mean_kl": 2.4907957260022938e-05,
|
| 172 |
+
"n_gold": 92,
|
| 173 |
+
"nll_ref": 0.27025191463643466,
|
| 174 |
+
"nll_cand": 0.2710970978349834,
|
| 175 |
+
"dnll": 0.0008451831985487601,
|
| 176 |
+
"mean_abs_row_dnll": 0.0033373064356656897,
|
| 177 |
+
"acc_ref": 0.8695652173913043,
|
| 178 |
+
"acc_cand": 0.8586956521739131,
|
| 179 |
+
"acc_drop_pp": 1.0869565217391242
|
| 180 |
+
},
|
| 181 |
+
"typed_synthetic": {
|
| 182 |
+
"n": 92,
|
| 183 |
+
"top1_agreement": 0.9891304347826086,
|
| 184 |
+
"top1_flips": 1,
|
| 185 |
+
"max_abs_dscore": 0.04864954948425293,
|
| 186 |
+
"mean_abs_dscore": 0.01256397343500986,
|
| 187 |
+
"mean_kl": 9.395103279401365e-05,
|
| 188 |
+
"n_gold": 92,
|
| 189 |
+
"nll_ref": 1.0338530850662833,
|
| 190 |
+
"nll_cand": 1.0353560613294195,
|
| 191 |
+
"dnll": 0.0015029762631362242,
|
| 192 |
+
"mean_abs_row_dnll": 0.008864003979572451,
|
| 193 |
+
"acc_ref": 0.5652173913043478,
|
| 194 |
+
"acc_cand": 0.5543478260869565,
|
| 195 |
+
"acc_drop_pp": 1.0869565217391242
|
| 196 |
+
}
|
| 197 |
+
},
|
| 198 |
+
"gates": {
|
| 199 |
+
"coverage_finite_tokens": {
|
| 200 |
+
"pass": true,
|
| 201 |
+
"problems": {},
|
| 202 |
+
"reference_missing_requests": 0
|
| 203 |
+
},
|
| 204 |
+
"top1": {
|
| 205 |
+
"threshold": 0.99,
|
| 206 |
+
"value": 0.997,
|
| 207 |
+
"pass": true
|
| 208 |
+
},
|
| 209 |
+
"dnll": {
|
| 210 |
+
"threshold": 0.02,
|
| 211 |
+
"value": 0.0001265220422789204,
|
| 212 |
+
"pass": true
|
| 213 |
+
}
|
| 214 |
+
},
|
| 215 |
+
"verdict": "PASS",
|
| 216 |
+
"resolution_pp_per_flip": 0.1,
|
| 217 |
+
"note": "small fixtures cannot resolve 0.3pp accuracy gates; accuracy on a parity fixture is only indicative (synthetic long rows carry the base row's gold label).",
|
| 218 |
+
"ref": "runs/macjev/runtime_v2_dev/reference_trained/gate_ref_block_fp32.jsonl",
|
| 219 |
+
"cand": "runs/macjev/release_2b/parity/pred_mlx_bf16_gate.jsonl",
|
| 220 |
+
"fixture": "runs/macjev/runtime_v2_dev/reference/gate_fixture_n1000.jsonl"
|
| 221 |
+
}
|
validation/parity/cross_format_dp.json
ADDED
|
@@ -0,0 +1,68 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"base:torch_fp32_cpu": {
|
| 3 |
+
"n": 43,
|
| 4 |
+
"top1_agree": 1.0,
|
| 5 |
+
"max_abs_dp": 4.782633115096857e-06,
|
| 6 |
+
"mean_max_abs_dp": 6.972375795818997e-07
|
| 7 |
+
},
|
| 8 |
+
"base:gguf_f16": {
|
| 9 |
+
"n": 43,
|
| 10 |
+
"top1_agree": 1.0,
|
| 11 |
+
"max_abs_dp": 0.0006297677378335198,
|
| 12 |
+
"mean_max_abs_dp": 0.00017737997866918594
|
| 13 |
+
},
|
| 14 |
+
"base:gguf_q8_0": {
|
| 15 |
+
"n": 43,
|
| 16 |
+
"top1_agree": 1.0,
|
| 17 |
+
"max_abs_dp": 0.021289327356281362,
|
| 18 |
+
"mean_max_abs_dp": 0.0044768677260933745
|
| 19 |
+
},
|
| 20 |
+
"base:gguf_q4_k_m": {
|
| 21 |
+
"n": 43,
|
| 22 |
+
"top1_agree": 0.9767441860465116,
|
| 23 |
+
"max_abs_dp": 0.15778925110927658,
|
| 24 |
+
"mean_max_abs_dp": 0.047022506153486646
|
| 25 |
+
},
|
| 26 |
+
"base:mlx_bf16": {
|
| 27 |
+
"n": 43,
|
| 28 |
+
"top1_agree": 1.0,
|
| 29 |
+
"max_abs_dp": 0.010765431767972844,
|
| 30 |
+
"mean_max_abs_dp": 0.003890125022245109
|
| 31 |
+
},
|
| 32 |
+
"base:mlx_8bit": {
|
| 33 |
+
"n": 43,
|
| 34 |
+
"top1_agree": 1.0,
|
| 35 |
+
"max_abs_dp": 0.04628699142360499,
|
| 36 |
+
"mean_max_abs_dp": 0.007026009064181663
|
| 37 |
+
},
|
| 38 |
+
"gate:gguf_f16": {
|
| 39 |
+
"n": 1000,
|
| 40 |
+
"top1_agree": 1.0,
|
| 41 |
+
"max_abs_dp": 0.0013728371250730786,
|
| 42 |
+
"mean_max_abs_dp": 0.00012138780447113503
|
| 43 |
+
},
|
| 44 |
+
"gate:gguf_q8_0": {
|
| 45 |
+
"n": 1000,
|
| 46 |
+
"top1_agree": 0.997,
|
| 47 |
+
"max_abs_dp": 0.033479594816581415,
|
| 48 |
+
"mean_max_abs_dp": 0.0020247272188215755
|
| 49 |
+
},
|
| 50 |
+
"gate:gguf_q4_k_m": {
|
| 51 |
+
"n": 1000,
|
| 52 |
+
"top1_agree": 0.957,
|
| 53 |
+
"max_abs_dp": 0.34599917206983777,
|
| 54 |
+
"mean_max_abs_dp": 0.02317308476687987
|
| 55 |
+
},
|
| 56 |
+
"gate:mlx_bf16": {
|
| 57 |
+
"n": 1000,
|
| 58 |
+
"top1_agree": 0.997,
|
| 59 |
+
"max_abs_dp": 0.03549758339084519,
|
| 60 |
+
"mean_max_abs_dp": 0.0025865935031305484
|
| 61 |
+
},
|
| 62 |
+
"gate:mlx_8bit": {
|
| 63 |
+
"n": 1000,
|
| 64 |
+
"top1_agree": 0.996,
|
| 65 |
+
"max_abs_dp": 0.1623697296878569,
|
| 66 |
+
"mean_max_abs_dp": 0.0039011049015487734
|
| 67 |
+
}
|
| 68 |
+
}
|
validation/runtime/fixture_verify_8bit.json
ADDED
|
@@ -0,0 +1,319 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"precision": "8bit",
|
| 3 |
+
"dev_seconds": 1324.8,
|
| 4 |
+
"default_T": 0.8278650620942867,
|
| 5 |
+
"fixture_requests": 35,
|
| 6 |
+
"fixture_questions": 43,
|
| 7 |
+
"fixture_tokens": 214700,
|
| 8 |
+
"overflow_q": 5,
|
| 9 |
+
"max_abs_dscore": 0.0,
|
| 10 |
+
"max_abs_dprob_vs_softmax_dev_over_T": 0.0,
|
| 11 |
+
"text_e2e_max_abs_dscore_vs_dev": 0.0,
|
| 12 |
+
"text_ids_equal_dev": true,
|
| 13 |
+
"score_many_vs_separate_fresh_decide_max_abs": 0.0,
|
| 14 |
+
"order_invariance_max_abs": 0.0,
|
| 15 |
+
"runtime_seconds": 286.5,
|
| 16 |
+
"per_question": [
|
| 17 |
+
[
|
| 18 |
+
"multi_question-0",
|
| 19 |
+
0,
|
| 20 |
+
450,
|
| 21 |
+
5,
|
| 22 |
+
0.0
|
| 23 |
+
],
|
| 24 |
+
[
|
| 25 |
+
"multi_question-0",
|
| 26 |
+
1,
|
| 27 |
+
364,
|
| 28 |
+
4,
|
| 29 |
+
0.0
|
| 30 |
+
],
|
| 31 |
+
[
|
| 32 |
+
"multi_question-0",
|
| 33 |
+
2,
|
| 34 |
+
356,
|
| 35 |
+
2,
|
| 36 |
+
0.0
|
| 37 |
+
],
|
| 38 |
+
[
|
| 39 |
+
"multi_question-0",
|
| 40 |
+
3,
|
| 41 |
+
345,
|
| 42 |
+
4,
|
| 43 |
+
0.0
|
| 44 |
+
],
|
| 45 |
+
[
|
| 46 |
+
"multi_question-0",
|
| 47 |
+
4,
|
| 48 |
+
319,
|
| 49 |
+
2,
|
| 50 |
+
0.0
|
| 51 |
+
],
|
| 52 |
+
[
|
| 53 |
+
"multi_question-1",
|
| 54 |
+
0,
|
| 55 |
+
5416,
|
| 56 |
+
2,
|
| 57 |
+
0.0
|
| 58 |
+
],
|
| 59 |
+
[
|
| 60 |
+
"multi_question-1",
|
| 61 |
+
1,
|
| 62 |
+
5471,
|
| 63 |
+
2,
|
| 64 |
+
0.0
|
| 65 |
+
],
|
| 66 |
+
[
|
| 67 |
+
"multi_question-1",
|
| 68 |
+
2,
|
| 69 |
+
5425,
|
| 70 |
+
2,
|
| 71 |
+
0.0
|
| 72 |
+
],
|
| 73 |
+
[
|
| 74 |
+
"multi_question-1",
|
| 75 |
+
3,
|
| 76 |
+
5517,
|
| 77 |
+
6,
|
| 78 |
+
0.0
|
| 79 |
+
],
|
| 80 |
+
[
|
| 81 |
+
"multi_question-1",
|
| 82 |
+
4,
|
| 83 |
+
5428,
|
| 84 |
+
2,
|
| 85 |
+
0.0
|
| 86 |
+
],
|
| 87 |
+
[
|
| 88 |
+
"short_sb-themes-0",
|
| 89 |
+
0,
|
| 90 |
+
105,
|
| 91 |
+
2,
|
| 92 |
+
0.0
|
| 93 |
+
],
|
| 94 |
+
[
|
| 95 |
+
"short_sb-public_ingests-0",
|
| 96 |
+
0,
|
| 97 |
+
382,
|
| 98 |
+
16,
|
| 99 |
+
0.0
|
| 100 |
+
],
|
| 101 |
+
[
|
| 102 |
+
"short_sb-di_retrieval-0",
|
| 103 |
+
0,
|
| 104 |
+
197,
|
| 105 |
+
2,
|
| 106 |
+
0.0
|
| 107 |
+
],
|
| 108 |
+
[
|
| 109 |
+
"short_sb-di_knowledge-0",
|
| 110 |
+
0,
|
| 111 |
+
72,
|
| 112 |
+
4,
|
| 113 |
+
0.0
|
| 114 |
+
],
|
| 115 |
+
[
|
| 116 |
+
"short_sb-hard_short-0",
|
| 117 |
+
0,
|
| 118 |
+
517,
|
| 119 |
+
3,
|
| 120 |
+
0.0
|
| 121 |
+
],
|
| 122 |
+
[
|
| 123 |
+
"short_sb-format-0",
|
| 124 |
+
0,
|
| 125 |
+
166,
|
| 126 |
+
21,
|
| 127 |
+
0.0
|
| 128 |
+
],
|
| 129 |
+
[
|
| 130 |
+
"qtype_choice-0",
|
| 131 |
+
0,
|
| 132 |
+
594,
|
| 133 |
+
3,
|
| 134 |
+
0.0
|
| 135 |
+
],
|
| 136 |
+
[
|
| 137 |
+
"qtype_noul-0",
|
| 138 |
+
0,
|
| 139 |
+
246,
|
| 140 |
+
2,
|
| 141 |
+
0.0
|
| 142 |
+
],
|
| 143 |
+
[
|
| 144 |
+
"qtype_score-0",
|
| 145 |
+
0,
|
| 146 |
+
873,
|
| 147 |
+
5,
|
| 148 |
+
0.0
|
| 149 |
+
],
|
| 150 |
+
[
|
| 151 |
+
"multi_block_3k-0",
|
| 152 |
+
0,
|
| 153 |
+
2927,
|
| 154 |
+
5,
|
| 155 |
+
0.0
|
| 156 |
+
],
|
| 157 |
+
[
|
| 158 |
+
"multi_block_3k-1",
|
| 159 |
+
0,
|
| 160 |
+
2932,
|
| 161 |
+
2,
|
| 162 |
+
0.0
|
| 163 |
+
],
|
| 164 |
+
[
|
| 165 |
+
"multi_block_5k-0",
|
| 166 |
+
0,
|
| 167 |
+
5011,
|
| 168 |
+
5,
|
| 169 |
+
0.0
|
| 170 |
+
],
|
| 171 |
+
[
|
| 172 |
+
"multi_block_5k-1",
|
| 173 |
+
0,
|
| 174 |
+
4767,
|
| 175 |
+
2,
|
| 176 |
+
0.0
|
| 177 |
+
],
|
| 178 |
+
[
|
| 179 |
+
"multi_block_9k-s0",
|
| 180 |
+
0,
|
| 181 |
+
9083,
|
| 182 |
+
3,
|
| 183 |
+
0.0
|
| 184 |
+
],
|
| 185 |
+
[
|
| 186 |
+
"multi_block_9k-s1",
|
| 187 |
+
0,
|
| 188 |
+
9568,
|
| 189 |
+
2,
|
| 190 |
+
0.0
|
| 191 |
+
],
|
| 192 |
+
[
|
| 193 |
+
"prefix_boundary-2047",
|
| 194 |
+
0,
|
| 195 |
+
2178,
|
| 196 |
+
2,
|
| 197 |
+
0.0
|
| 198 |
+
],
|
| 199 |
+
[
|
| 200 |
+
"prefix_boundary-2048",
|
| 201 |
+
0,
|
| 202 |
+
2203,
|
| 203 |
+
3,
|
| 204 |
+
0.0
|
| 205 |
+
],
|
| 206 |
+
[
|
| 207 |
+
"prefix_boundary-2049",
|
| 208 |
+
0,
|
| 209 |
+
2289,
|
| 210 |
+
6,
|
| 211 |
+
0.0
|
| 212 |
+
],
|
| 213 |
+
[
|
| 214 |
+
"prefix_boundary-4095",
|
| 215 |
+
0,
|
| 216 |
+
4163,
|
| 217 |
+
4,
|
| 218 |
+
0.0
|
| 219 |
+
],
|
| 220 |
+
[
|
| 221 |
+
"prefix_boundary-4096",
|
| 222 |
+
0,
|
| 223 |
+
4312,
|
| 224 |
+
5,
|
| 225 |
+
0.0
|
| 226 |
+
],
|
| 227 |
+
[
|
| 228 |
+
"prefix_boundary-4097",
|
| 229 |
+
0,
|
| 230 |
+
4180,
|
| 231 |
+
2,
|
| 232 |
+
0.0
|
| 233 |
+
],
|
| 234 |
+
[
|
| 235 |
+
"prefix_boundary-6144",
|
| 236 |
+
0,
|
| 237 |
+
6259,
|
| 238 |
+
3,
|
| 239 |
+
0.0
|
| 240 |
+
],
|
| 241 |
+
[
|
| 242 |
+
"catalogue_overflow-0",
|
| 243 |
+
0,
|
| 244 |
+
4722,
|
| 245 |
+
151,
|
| 246 |
+
0.0
|
| 247 |
+
],
|
| 248 |
+
[
|
| 249 |
+
"catalogue_overflow-1",
|
| 250 |
+
0,
|
| 251 |
+
4721,
|
| 252 |
+
151,
|
| 253 |
+
0.0
|
| 254 |
+
],
|
| 255 |
+
[
|
| 256 |
+
"catalogue_overflow-2",
|
| 257 |
+
0,
|
| 258 |
+
4729,
|
| 259 |
+
151,
|
| 260 |
+
0.0
|
| 261 |
+
],
|
| 262 |
+
[
|
| 263 |
+
"catalogue_overflow_long_state-0",
|
| 264 |
+
0,
|
| 265 |
+
8806,
|
| 266 |
+
151,
|
| 267 |
+
0.0
|
| 268 |
+
],
|
| 269 |
+
[
|
| 270 |
+
"many_options-0",
|
| 271 |
+
0,
|
| 272 |
+
500,
|
| 273 |
+
75,
|
| 274 |
+
0.0
|
| 275 |
+
],
|
| 276 |
+
[
|
| 277 |
+
"many_options-1",
|
| 278 |
+
0,
|
| 279 |
+
423,
|
| 280 |
+
64,
|
| 281 |
+
0.0
|
| 282 |
+
],
|
| 283 |
+
[
|
| 284 |
+
"long_16k-0",
|
| 285 |
+
0,
|
| 286 |
+
15900,
|
| 287 |
+
6,
|
| 288 |
+
0.0
|
| 289 |
+
],
|
| 290 |
+
[
|
| 291 |
+
"long_16k-1",
|
| 292 |
+
0,
|
| 293 |
+
16384,
|
| 294 |
+
2,
|
| 295 |
+
0.0
|
| 296 |
+
],
|
| 297 |
+
[
|
| 298 |
+
"long_16k-2",
|
| 299 |
+
0,
|
| 300 |
+
16800,
|
| 301 |
+
151,
|
| 302 |
+
0.0
|
| 303 |
+
],
|
| 304 |
+
[
|
| 305 |
+
"long_24k-0",
|
| 306 |
+
0,
|
| 307 |
+
24000,
|
| 308 |
+
2,
|
| 309 |
+
0.0
|
| 310 |
+
],
|
| 311 |
+
[
|
| 312 |
+
"long_24k-1",
|
| 313 |
+
0,
|
| 314 |
+
25600,
|
| 315 |
+
6,
|
| 316 |
+
0.0
|
| 317 |
+
]
|
| 318 |
+
]
|
| 319 |
+
}
|
validation/runtime/fixture_verify_bf16.json
ADDED
|
@@ -0,0 +1,319 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"precision": "bf16",
|
| 3 |
+
"dev_seconds": 415.6,
|
| 4 |
+
"default_T": 0.8278650620942867,
|
| 5 |
+
"fixture_requests": 35,
|
| 6 |
+
"fixture_questions": 43,
|
| 7 |
+
"fixture_tokens": 214700,
|
| 8 |
+
"overflow_q": 5,
|
| 9 |
+
"max_abs_dscore": 0.0,
|
| 10 |
+
"max_abs_dprob_vs_softmax_dev_over_T": 0.0,
|
| 11 |
+
"text_e2e_max_abs_dscore_vs_dev": 0.0,
|
| 12 |
+
"text_ids_equal_dev": true,
|
| 13 |
+
"score_many_vs_separate_fresh_decide_max_abs": 0.0,
|
| 14 |
+
"order_invariance_max_abs": 0.0,
|
| 15 |
+
"runtime_seconds": 293.1,
|
| 16 |
+
"per_question": [
|
| 17 |
+
[
|
| 18 |
+
"multi_question-0",
|
| 19 |
+
0,
|
| 20 |
+
450,
|
| 21 |
+
5,
|
| 22 |
+
0.0
|
| 23 |
+
],
|
| 24 |
+
[
|
| 25 |
+
"multi_question-0",
|
| 26 |
+
1,
|
| 27 |
+
364,
|
| 28 |
+
4,
|
| 29 |
+
0.0
|
| 30 |
+
],
|
| 31 |
+
[
|
| 32 |
+
"multi_question-0",
|
| 33 |
+
2,
|
| 34 |
+
356,
|
| 35 |
+
2,
|
| 36 |
+
0.0
|
| 37 |
+
],
|
| 38 |
+
[
|
| 39 |
+
"multi_question-0",
|
| 40 |
+
3,
|
| 41 |
+
345,
|
| 42 |
+
4,
|
| 43 |
+
0.0
|
| 44 |
+
],
|
| 45 |
+
[
|
| 46 |
+
"multi_question-0",
|
| 47 |
+
4,
|
| 48 |
+
319,
|
| 49 |
+
2,
|
| 50 |
+
0.0
|
| 51 |
+
],
|
| 52 |
+
[
|
| 53 |
+
"multi_question-1",
|
| 54 |
+
0,
|
| 55 |
+
5416,
|
| 56 |
+
2,
|
| 57 |
+
0.0
|
| 58 |
+
],
|
| 59 |
+
[
|
| 60 |
+
"multi_question-1",
|
| 61 |
+
1,
|
| 62 |
+
5471,
|
| 63 |
+
2,
|
| 64 |
+
0.0
|
| 65 |
+
],
|
| 66 |
+
[
|
| 67 |
+
"multi_question-1",
|
| 68 |
+
2,
|
| 69 |
+
5425,
|
| 70 |
+
2,
|
| 71 |
+
0.0
|
| 72 |
+
],
|
| 73 |
+
[
|
| 74 |
+
"multi_question-1",
|
| 75 |
+
3,
|
| 76 |
+
5517,
|
| 77 |
+
6,
|
| 78 |
+
0.0
|
| 79 |
+
],
|
| 80 |
+
[
|
| 81 |
+
"multi_question-1",
|
| 82 |
+
4,
|
| 83 |
+
5428,
|
| 84 |
+
2,
|
| 85 |
+
0.0
|
| 86 |
+
],
|
| 87 |
+
[
|
| 88 |
+
"short_sb-themes-0",
|
| 89 |
+
0,
|
| 90 |
+
105,
|
| 91 |
+
2,
|
| 92 |
+
0.0
|
| 93 |
+
],
|
| 94 |
+
[
|
| 95 |
+
"short_sb-public_ingests-0",
|
| 96 |
+
0,
|
| 97 |
+
382,
|
| 98 |
+
16,
|
| 99 |
+
0.0
|
| 100 |
+
],
|
| 101 |
+
[
|
| 102 |
+
"short_sb-di_retrieval-0",
|
| 103 |
+
0,
|
| 104 |
+
197,
|
| 105 |
+
2,
|
| 106 |
+
0.0
|
| 107 |
+
],
|
| 108 |
+
[
|
| 109 |
+
"short_sb-di_knowledge-0",
|
| 110 |
+
0,
|
| 111 |
+
72,
|
| 112 |
+
4,
|
| 113 |
+
0.0
|
| 114 |
+
],
|
| 115 |
+
[
|
| 116 |
+
"short_sb-hard_short-0",
|
| 117 |
+
0,
|
| 118 |
+
517,
|
| 119 |
+
3,
|
| 120 |
+
0.0
|
| 121 |
+
],
|
| 122 |
+
[
|
| 123 |
+
"short_sb-format-0",
|
| 124 |
+
0,
|
| 125 |
+
166,
|
| 126 |
+
21,
|
| 127 |
+
0.0
|
| 128 |
+
],
|
| 129 |
+
[
|
| 130 |
+
"qtype_choice-0",
|
| 131 |
+
0,
|
| 132 |
+
594,
|
| 133 |
+
3,
|
| 134 |
+
0.0
|
| 135 |
+
],
|
| 136 |
+
[
|
| 137 |
+
"qtype_noul-0",
|
| 138 |
+
0,
|
| 139 |
+
246,
|
| 140 |
+
2,
|
| 141 |
+
0.0
|
| 142 |
+
],
|
| 143 |
+
[
|
| 144 |
+
"qtype_score-0",
|
| 145 |
+
0,
|
| 146 |
+
873,
|
| 147 |
+
5,
|
| 148 |
+
0.0
|
| 149 |
+
],
|
| 150 |
+
[
|
| 151 |
+
"multi_block_3k-0",
|
| 152 |
+
0,
|
| 153 |
+
2927,
|
| 154 |
+
5,
|
| 155 |
+
0.0
|
| 156 |
+
],
|
| 157 |
+
[
|
| 158 |
+
"multi_block_3k-1",
|
| 159 |
+
0,
|
| 160 |
+
2932,
|
| 161 |
+
2,
|
| 162 |
+
0.0
|
| 163 |
+
],
|
| 164 |
+
[
|
| 165 |
+
"multi_block_5k-0",
|
| 166 |
+
0,
|
| 167 |
+
5011,
|
| 168 |
+
5,
|
| 169 |
+
0.0
|
| 170 |
+
],
|
| 171 |
+
[
|
| 172 |
+
"multi_block_5k-1",
|
| 173 |
+
0,
|
| 174 |
+
4767,
|
| 175 |
+
2,
|
| 176 |
+
0.0
|
| 177 |
+
],
|
| 178 |
+
[
|
| 179 |
+
"multi_block_9k-s0",
|
| 180 |
+
0,
|
| 181 |
+
9083,
|
| 182 |
+
3,
|
| 183 |
+
0.0
|
| 184 |
+
],
|
| 185 |
+
[
|
| 186 |
+
"multi_block_9k-s1",
|
| 187 |
+
0,
|
| 188 |
+
9568,
|
| 189 |
+
2,
|
| 190 |
+
0.0
|
| 191 |
+
],
|
| 192 |
+
[
|
| 193 |
+
"prefix_boundary-2047",
|
| 194 |
+
0,
|
| 195 |
+
2178,
|
| 196 |
+
2,
|
| 197 |
+
0.0
|
| 198 |
+
],
|
| 199 |
+
[
|
| 200 |
+
"prefix_boundary-2048",
|
| 201 |
+
0,
|
| 202 |
+
2203,
|
| 203 |
+
3,
|
| 204 |
+
0.0
|
| 205 |
+
],
|
| 206 |
+
[
|
| 207 |
+
"prefix_boundary-2049",
|
| 208 |
+
0,
|
| 209 |
+
2289,
|
| 210 |
+
6,
|
| 211 |
+
0.0
|
| 212 |
+
],
|
| 213 |
+
[
|
| 214 |
+
"prefix_boundary-4095",
|
| 215 |
+
0,
|
| 216 |
+
4163,
|
| 217 |
+
4,
|
| 218 |
+
0.0
|
| 219 |
+
],
|
| 220 |
+
[
|
| 221 |
+
"prefix_boundary-4096",
|
| 222 |
+
0,
|
| 223 |
+
4312,
|
| 224 |
+
5,
|
| 225 |
+
0.0
|
| 226 |
+
],
|
| 227 |
+
[
|
| 228 |
+
"prefix_boundary-4097",
|
| 229 |
+
0,
|
| 230 |
+
4180,
|
| 231 |
+
2,
|
| 232 |
+
0.0
|
| 233 |
+
],
|
| 234 |
+
[
|
| 235 |
+
"prefix_boundary-6144",
|
| 236 |
+
0,
|
| 237 |
+
6259,
|
| 238 |
+
3,
|
| 239 |
+
0.0
|
| 240 |
+
],
|
| 241 |
+
[
|
| 242 |
+
"catalogue_overflow-0",
|
| 243 |
+
0,
|
| 244 |
+
4722,
|
| 245 |
+
151,
|
| 246 |
+
0.0
|
| 247 |
+
],
|
| 248 |
+
[
|
| 249 |
+
"catalogue_overflow-1",
|
| 250 |
+
0,
|
| 251 |
+
4721,
|
| 252 |
+
151,
|
| 253 |
+
0.0
|
| 254 |
+
],
|
| 255 |
+
[
|
| 256 |
+
"catalogue_overflow-2",
|
| 257 |
+
0,
|
| 258 |
+
4729,
|
| 259 |
+
151,
|
| 260 |
+
0.0
|
| 261 |
+
],
|
| 262 |
+
[
|
| 263 |
+
"catalogue_overflow_long_state-0",
|
| 264 |
+
0,
|
| 265 |
+
8806,
|
| 266 |
+
151,
|
| 267 |
+
0.0
|
| 268 |
+
],
|
| 269 |
+
[
|
| 270 |
+
"many_options-0",
|
| 271 |
+
0,
|
| 272 |
+
500,
|
| 273 |
+
75,
|
| 274 |
+
0.0
|
| 275 |
+
],
|
| 276 |
+
[
|
| 277 |
+
"many_options-1",
|
| 278 |
+
0,
|
| 279 |
+
423,
|
| 280 |
+
64,
|
| 281 |
+
0.0
|
| 282 |
+
],
|
| 283 |
+
[
|
| 284 |
+
"long_16k-0",
|
| 285 |
+
0,
|
| 286 |
+
15900,
|
| 287 |
+
6,
|
| 288 |
+
0.0
|
| 289 |
+
],
|
| 290 |
+
[
|
| 291 |
+
"long_16k-1",
|
| 292 |
+
0,
|
| 293 |
+
16384,
|
| 294 |
+
2,
|
| 295 |
+
0.0
|
| 296 |
+
],
|
| 297 |
+
[
|
| 298 |
+
"long_16k-2",
|
| 299 |
+
0,
|
| 300 |
+
16800,
|
| 301 |
+
151,
|
| 302 |
+
0.0
|
| 303 |
+
],
|
| 304 |
+
[
|
| 305 |
+
"long_24k-0",
|
| 306 |
+
0,
|
| 307 |
+
24000,
|
| 308 |
+
2,
|
| 309 |
+
0.0
|
| 310 |
+
],
|
| 311 |
+
[
|
| 312 |
+
"long_24k-1",
|
| 313 |
+
0,
|
| 314 |
+
25600,
|
| 315 |
+
6,
|
| 316 |
+
0.0
|
| 317 |
+
]
|
| 318 |
+
]
|
| 319 |
+
}
|
validation/runtime/render_verify.json
ADDED
|
@@ -0,0 +1,88 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"requests": 463,
|
| 3 |
+
"questions": 756,
|
| 4 |
+
"ok_identical": 743,
|
| 5 |
+
"budget_both": 6,
|
| 6 |
+
"error_both": 6,
|
| 7 |
+
"mismatch": [
|
| 8 |
+
{
|
| 9 |
+
"q_repr": "{'t': 'score', 'ins': '\\n', 'crit': [' <tool_response>', '\\n<tool_response>->', '<|box_start|>\\nOptions:\\nOption 2: ', '<tool_response> -> yesabc', '<|endoftext|><|endoftext|>Option 1 ->', '', '<|video_pad|>\ud83d\ude42Option 2: ', '<tool_call>Judge each numbered option in the complete catalogue above:\\n<think",
|
| 10 |
+
"state_repr": "'abc<|im_start|><|vision_pad|>Judge each numbered option in the complete catalogue above:\\n<think>\\n",
|
| 11 |
+
"id": "special:16",
|
| 12 |
+
"q": 0,
|
| 13 |
+
"ref": [
|
| 14 |
+
"ok",
|
| 15 |
+
245
|
| 16 |
+
],
|
| 17 |
+
"rt": "error",
|
| 18 |
+
"ref_err": null,
|
| 19 |
+
"rt_err": [
|
| 20 |
+
"QuestionError"
|
| 21 |
+
]
|
| 22 |
+
}
|
| 23 |
+
],
|
| 24 |
+
"overflow_q": 17,
|
| 25 |
+
"max_tokens": 25600,
|
| 26 |
+
"max_k": 1000,
|
| 27 |
+
"prefix_path_mismatch": 0,
|
| 28 |
+
"boundary_head_lens": [
|
| 29 |
+
2046,
|
| 30 |
+
2047,
|
| 31 |
+
2048,
|
| 32 |
+
2095,
|
| 33 |
+
2096
|
| 34 |
+
],
|
| 35 |
+
"state_prefix_lens": [
|
| 36 |
+
2047,
|
| 37 |
+
2048,
|
| 38 |
+
2049,
|
| 39 |
+
4095,
|
| 40 |
+
4096,
|
| 41 |
+
4097,
|
| 42 |
+
20479,
|
| 43 |
+
20480,
|
| 44 |
+
20481
|
| 45 |
+
],
|
| 46 |
+
"overflow_budget_edge_total": 25600,
|
| 47 |
+
"budget_ids": [
|
| 48 |
+
"total_edge:18657",
|
| 49 |
+
"total_edge:18658",
|
| 50 |
+
"bigk:1500",
|
| 51 |
+
"maxlen:64",
|
| 52 |
+
"maxlen:300",
|
| 53 |
+
"huge_question"
|
| 54 |
+
],
|
| 55 |
+
"error_ids": [
|
| 56 |
+
[
|
| 57 |
+
"ctrl:1",
|
| 58 |
+
"TypeError",
|
| 59 |
+
"TypeError"
|
| 60 |
+
],
|
| 61 |
+
[
|
| 62 |
+
"score_11",
|
| 63 |
+
"RecordError",
|
| 64 |
+
"QuestionError"
|
| 65 |
+
],
|
| 66 |
+
[
|
| 67 |
+
"score_1",
|
| 68 |
+
"RecordError",
|
| 69 |
+
"QuestionError"
|
| 70 |
+
],
|
| 71 |
+
[
|
| 72 |
+
"choice_empty",
|
| 73 |
+
"RecordError",
|
| 74 |
+
"QuestionError"
|
| 75 |
+
],
|
| 76 |
+
[
|
| 77 |
+
"choice_numkeys",
|
| 78 |
+
"ValueError",
|
| 79 |
+
"TypeError"
|
| 80 |
+
],
|
| 81 |
+
[
|
| 82 |
+
"bad_type",
|
| 83 |
+
"RecordError",
|
| 84 |
+
"QuestionError"
|
| 85 |
+
]
|
| 86 |
+
],
|
| 87 |
+
"n_mismatch": 1
|
| 88 |
+
}
|
validation/runtime/reverify_mlx.json
ADDED
|
@@ -0,0 +1,23 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"runtime_file": "jev_style_decision_mlx.py",
|
| 3 |
+
"runtime_sha256": "025daab9b374d740e743c519bd3aa3385791e08c81f4515b2ae525af57788030",
|
| 4 |
+
"shared_core_sha256": "56deae095206fc59b9a30d8626ac5d27cacddcd94d7c7f08f6f4bc53d326a002",
|
| 5 |
+
"what": "MLX bf16 (loaded from the repository root, precision bf16), runtime defaults",
|
| 6 |
+
"loaded_from": "runs/macjev/hf_staging/Jev-Style-2B-Decision-v3-MLX",
|
| 7 |
+
"verify_manifest": true,
|
| 8 |
+
"compared_with": {
|
| 9 |
+
"file": "runs/macjev/release_2b/parity/pred_mlx_bf16_base.jsonl",
|
| 10 |
+
"sha256": "c42232870ab8c5410b4f45dc85729249d467b9c0bd5d24213d085e4479a3a60e"
|
| 11 |
+
},
|
| 12 |
+
"fixture": {
|
| 13 |
+
"file": "runs/macjev/runtime_v2_dev/reference_base/fixture.jsonl",
|
| 14 |
+
"sha256": "2b16d25eafa70c00a1106ba51b94890821b51ecb4fa393abb12403c8739ef314"
|
| 15 |
+
},
|
| 16 |
+
"questions": 43,
|
| 17 |
+
"skipped_questions": 0,
|
| 18 |
+
"max_abs_score_diff": 0.0,
|
| 19 |
+
"top1_same": "43/43",
|
| 20 |
+
"token_or_overflow_mismatches": [],
|
| 21 |
+
"seconds": 137.2,
|
| 22 |
+
"finished_unix": 1790449492.3913028
|
| 23 |
+
}
|