

Jev-Style-2B-Decision-v3: release
Browse files- .gitattributes +4 -0
- LICENSE +202 -0
- NOTICE +32 -0
- README.md +371 -0
- chat_template.jinja +154 -0
- config.json +75 -0
- eval_results.json +262 -0
- figures/banner.data.json +44 -0
- figures/banner.png +3 -0
- figures/jevbench.data.json +49 -0
- figures/jevbench.png +3 -0
- figures/jevbench.svg +245 -0
- figures/zeroshot.data.json +40 -0
- figures/zeroshot.png +3 -0
- figures/zeroshot.svg +253 -0
- generation_config.json +6 -0
- jev_style_decision.py +806 -0
- manifest.json +170 -0
- model-00001-of-00002.safetensors +3 -0
- model-00002-of-00002.safetensors +3 -0
- model.safetensors.index.json +328 -0
- readout_config.json +47 -0
- release_config.json +804 -0
- requirements.txt +5 -0
- tokenizer.json +3 -0
- tokenizer_config.json +32 -0
- validation/SOURCES.json +81 -0
- validation/benchmarks/contamination.json +110 -0
- validation/benchmarks/jevbench_v1.4.1_results.json +511 -0
- validation/benchmarks/jevbench_v1.4.1_results.md +18 -0
- validation/benchmarks/zeroshot_comparison.md +11 -0
- validation/benchmarks/zeroshot_metrics.json +304 -0
- validation/data_sources.json +641 -0
- validation/latency_2b.json +1568 -0
- validation/parity/PREDECLARED_RELEASE_GATES_2B.md +29 -0
- validation/parity/cross_format_dp.json +68 -0
- validation/runtime/parity_cpu_fp32_t4.log +56 -0
- validation/runtime/parity_mps_fp32_long.log +9 -0
- validation/runtime/reverify_main.json +23 -0
- validation/runtime/reverify_main_mps_long.log +9 -0
- validation/runtime/v_jevstyle_e2e.json +80 -0
- validation/runtime/v_tiny_and_render.json +24 -0
.gitattributes
CHANGED
|
@@ -33,3 +33,7 @@ saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
figures/banner.png filter=lfs diff=lfs merge=lfs -text
|
| 37 |
+
figures/jevbench.png filter=lfs diff=lfs merge=lfs -text
|
| 38 |
+
figures/zeroshot.png filter=lfs diff=lfs merge=lfs -text
|
| 39 |
+
tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
LICENSE
ADDED
|
@@ -0,0 +1,202 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
|
| 2 |
+
Apache License
|
| 3 |
+
Version 2.0, January 2004
|
| 4 |
+
http://www.apache.org/licenses/
|
| 5 |
+
|
| 6 |
+
TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
|
| 7 |
+
|
| 8 |
+
1. Definitions.
|
| 9 |
+
|
| 10 |
+
"License" shall mean the terms and conditions for use, reproduction,
|
| 11 |
+
and distribution as defined by Sections 1 through 9 of this document.
|
| 12 |
+
|
| 13 |
+
"Licensor" shall mean the copyright owner or entity authorized by
|
| 14 |
+
the copyright owner that is granting the License.
|
| 15 |
+
|
| 16 |
+
"Legal Entity" shall mean the union of the acting entity and all
|
| 17 |
+
other entities that control, are controlled by, or are under common
|
| 18 |
+
control with that entity. For the purposes of this definition,
|
| 19 |
+
"control" means (i) the power, direct or indirect, to cause the
|
| 20 |
+
direction or management of such entity, whether by contract or
|
| 21 |
+
otherwise, or (ii) ownership of fifty percent (50%) or more of the
|
| 22 |
+
outstanding shares, or (iii) beneficial ownership of such entity.
|
| 23 |
+
|
| 24 |
+
"You" (or "Your") shall mean an individual or Legal Entity
|
| 25 |
+
exercising permissions granted by this License.
|
| 26 |
+
|
| 27 |
+
"Source" form shall mean the preferred form for making modifications,
|
| 28 |
+
including but not limited to software source code, documentation
|
| 29 |
+
source, and configuration files.
|
| 30 |
+
|
| 31 |
+
"Object" form shall mean any form resulting from mechanical
|
| 32 |
+
transformation or translation of a Source form, including but
|
| 33 |
+
not limited to compiled object code, generated documentation,
|
| 34 |
+
and conversions to other media types.
|
| 35 |
+
|
| 36 |
+
"Work" shall mean the work of authorship, whether in Source or
|
| 37 |
+
Object form, made available under the License, as indicated by a
|
| 38 |
+
copyright notice that is included in or attached to the work
|
| 39 |
+
(an example is provided in the Appendix below).
|
| 40 |
+
|
| 41 |
+
"Derivative Works" shall mean any work, whether in Source or Object
|
| 42 |
+
form, that is based on (or derived from) the Work and for which the
|
| 43 |
+
editorial revisions, annotations, elaborations, or other modifications
|
| 44 |
+
represent, as a whole, an original work of authorship. For the purposes
|
| 45 |
+
of this License, Derivative Works shall not include works that remain
|
| 46 |
+
separable from, or merely link (or bind by name) to the interfaces of,
|
| 47 |
+
the Work and Derivative Works thereof.
|
| 48 |
+
|
| 49 |
+
"Contribution" shall mean any work of authorship, including
|
| 50 |
+
the original version of the Work and any modifications or additions
|
| 51 |
+
to that Work or Derivative Works thereof, that is intentionally
|
| 52 |
+
submitted to Licensor for inclusion in the Work by the copyright owner
|
| 53 |
+
or by an individual or Legal Entity authorized to submit on behalf of
|
| 54 |
+
the copyright owner. For the purposes of this definition, "submitted"
|
| 55 |
+
means any form of electronic, verbal, or written communication sent
|
| 56 |
+
to the Licensor or its representatives, including but not limited to
|
| 57 |
+
communication on electronic mailing lists, source code control systems,
|
| 58 |
+
and issue tracking systems that are managed by, or on behalf of, the
|
| 59 |
+
Licensor for the purpose of discussing and improving the Work, but
|
| 60 |
+
excluding communication that is conspicuously marked or otherwise
|
| 61 |
+
designated in writing by the copyright owner as "Not a Contribution."
|
| 62 |
+
|
| 63 |
+
"Contributor" shall mean Licensor and any individual or Legal Entity
|
| 64 |
+
on behalf of whom a Contribution has been received by Licensor and
|
| 65 |
+
subsequently incorporated within the Work.
|
| 66 |
+
|
| 67 |
+
2. Grant of Copyright License. Subject to the terms and conditions of
|
| 68 |
+
this License, each Contributor hereby grants to You a perpetual,
|
| 69 |
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
| 70 |
+
copyright license to reproduce, prepare Derivative Works of,
|
| 71 |
+
publicly display, publicly perform, sublicense, and distribute the
|
| 72 |
+
Work and such Derivative Works in Source or Object form.
|
| 73 |
+
|
| 74 |
+
3. Grant of Patent License. Subject to the terms and conditions of
|
| 75 |
+
this License, each Contributor hereby grants to You a perpetual,
|
| 76 |
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
| 77 |
+
(except as stated in this section) patent license to make, have made,
|
| 78 |
+
use, offer to sell, sell, import, and otherwise transfer the Work,
|
| 79 |
+
where such license applies only to those patent claims licensable
|
| 80 |
+
by such Contributor that are necessarily infringed by their
|
| 81 |
+
Contribution(s) alone or by combination of their Contribution(s)
|
| 82 |
+
with the Work to which such Contribution(s) was submitted. If You
|
| 83 |
+
institute patent litigation against any entity (including a
|
| 84 |
+
cross-claim or counterclaim in a lawsuit) alleging that the Work
|
| 85 |
+
or a Contribution incorporated within the Work constitutes direct
|
| 86 |
+
or contributory patent infringement, then any patent licenses
|
| 87 |
+
granted to You under this License for that Work shall terminate
|
| 88 |
+
as of the date such litigation is filed.
|
| 89 |
+
|
| 90 |
+
4. Redistribution. You may reproduce and distribute copies of the
|
| 91 |
+
Work or Derivative Works thereof in any medium, with or without
|
| 92 |
+
modifications, and in Source or Object form, provided that You
|
| 93 |
+
meet the following conditions:
|
| 94 |
+
|
| 95 |
+
(a) You must give any other recipients of the Work or
|
| 96 |
+
Derivative Works a copy of this License; and
|
| 97 |
+
|
| 98 |
+
(b) You must cause any modified files to carry prominent notices
|
| 99 |
+
stating that You changed the files; and
|
| 100 |
+
|
| 101 |
+
(c) You must retain, in the Source form of any Derivative Works
|
| 102 |
+
that You distribute, all copyright, patent, trademark, and
|
| 103 |
+
attribution notices from the Source form of the Work,
|
| 104 |
+
excluding those notices that do not pertain to any part of
|
| 105 |
+
the Derivative Works; and
|
| 106 |
+
|
| 107 |
+
(d) If the Work includes a "NOTICE" text file as part of its
|
| 108 |
+
distribution, then any Derivative Works that You distribute must
|
| 109 |
+
include a readable copy of the attribution notices contained
|
| 110 |
+
within such NOTICE file, excluding those notices that do not
|
| 111 |
+
pertain to any part of the Derivative Works, in at least one
|
| 112 |
+
of the following places: within a NOTICE text file distributed
|
| 113 |
+
as part of the Derivative Works; within the Source form or
|
| 114 |
+
documentation, if provided along with the Derivative Works; or,
|
| 115 |
+
within a display generated by the Derivative Works, if and
|
| 116 |
+
wherever such third-party notices normally appear. The contents
|
| 117 |
+
of the NOTICE file are for informational purposes only and
|
| 118 |
+
do not modify the License. You may add Your own attribution
|
| 119 |
+
notices within Derivative Works that You distribute, alongside
|
| 120 |
+
or as an addendum to the NOTICE text from the Work, provided
|
| 121 |
+
that such additional attribution notices cannot be construed
|
| 122 |
+
as modifying the License.
|
| 123 |
+
|
| 124 |
+
You may add Your own copyright statement to Your modifications and
|
| 125 |
+
may provide additional or different license terms and conditions
|
| 126 |
+
for use, reproduction, or distribution of Your modifications, or
|
| 127 |
+
for any such Derivative Works as a whole, provided Your use,
|
| 128 |
+
reproduction, and distribution of the Work otherwise complies with
|
| 129 |
+
the conditions stated in this License.
|
| 130 |
+
|
| 131 |
+
5. Submission of Contributions. Unless You explicitly state otherwise,
|
| 132 |
+
any Contribution intentionally submitted for inclusion in the Work
|
| 133 |
+
by You to the Licensor shall be under the terms and conditions of
|
| 134 |
+
this License, without any additional terms or conditions.
|
| 135 |
+
Notwithstanding the above, nothing herein shall supersede or modify
|
| 136 |
+
the terms of any separate license agreement you may have executed
|
| 137 |
+
with Licensor regarding such Contributions.
|
| 138 |
+
|
| 139 |
+
6. Trademarks. This License does not grant permission to use the trade
|
| 140 |
+
names, trademarks, service marks, or product names of the Licensor,
|
| 141 |
+
except as required for reasonable and customary use in describing the
|
| 142 |
+
origin of the Work and reproducing the content of the NOTICE file.
|
| 143 |
+
|
| 144 |
+
7. Disclaimer of Warranty. Unless required by applicable law or
|
| 145 |
+
agreed to in writing, Licensor provides the Work (and each
|
| 146 |
+
Contributor provides its Contributions) on an "AS IS" BASIS,
|
| 147 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
|
| 148 |
+
implied, including, without limitation, any warranties or conditions
|
| 149 |
+
of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
|
| 150 |
+
PARTICULAR PURPOSE. You are solely responsible for determining the
|
| 151 |
+
appropriateness of using or redistributing the Work and assume any
|
| 152 |
+
risks associated with Your exercise of permissions under this License.
|
| 153 |
+
|
| 154 |
+
8. Limitation of Liability. In no event and under no legal theory,
|
| 155 |
+
whether in tort (including negligence), contract, or otherwise,
|
| 156 |
+
unless required by applicable law (such as deliberate and grossly
|
| 157 |
+
negligent acts) or agreed to in writing, shall any Contributor be
|
| 158 |
+
liable to You for damages, including any direct, indirect, special,
|
| 159 |
+
incidental, or consequential damages of any character arising as a
|
| 160 |
+
result of this License or out of the use or inability to use the
|
| 161 |
+
Work (including but not limited to damages for loss of goodwill,
|
| 162 |
+
work stoppage, computer failure or malfunction, or any and all
|
| 163 |
+
other commercial damages or losses), even if such Contributor
|
| 164 |
+
has been advised of the possibility of such damages.
|
| 165 |
+
|
| 166 |
+
9. Accepting Warranty or Additional Liability. While redistributing
|
| 167 |
+
the Work or Derivative Works thereof, You may choose to offer,
|
| 168 |
+
and charge a fee for, acceptance of support, warranty, indemnity,
|
| 169 |
+
or other liability obligations and/or rights consistent with this
|
| 170 |
+
License. However, in accepting such obligations, You may act only
|
| 171 |
+
on Your own behalf and on Your sole responsibility, not on behalf
|
| 172 |
+
of any other Contributor, and only if You agree to indemnify,
|
| 173 |
+
defend, and hold each Contributor harmless for any liability
|
| 174 |
+
incurred by, or claims asserted against, such Contributor by reason
|
| 175 |
+
of your accepting any such warranty or additional liability.
|
| 176 |
+
|
| 177 |
+
END OF TERMS AND CONDITIONS
|
| 178 |
+
|
| 179 |
+
APPENDIX: How to apply the Apache License to your work.
|
| 180 |
+
|
| 181 |
+
To apply the Apache License to your work, attach the following
|
| 182 |
+
boilerplate notice, with the fields enclosed by brackets "[]"
|
| 183 |
+
replaced with your own identifying information. (Don't include
|
| 184 |
+
the brackets!) The text should be enclosed in the appropriate
|
| 185 |
+
comment syntax for the file format. We also recommend that a
|
| 186 |
+
file or class name and description of purpose be included on the
|
| 187 |
+
same "printed page" as the copyright notice for easier
|
| 188 |
+
identification within third-party archives.
|
| 189 |
+
|
| 190 |
+
Copyright 2026 Alibaba Cloud
|
| 191 |
+
|
| 192 |
+
Licensed under the Apache License, Version 2.0 (the "License");
|
| 193 |
+
you may not use this file except in compliance with the License.
|
| 194 |
+
You may obtain a copy of the License at
|
| 195 |
+
|
| 196 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 197 |
+
|
| 198 |
+
Unless required by applicable law or agreed to in writing, software
|
| 199 |
+
distributed under the License is distributed on an "AS IS" BASIS,
|
| 200 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 201 |
+
See the License for the specific language governing permissions and
|
| 202 |
+
limitations under the License.
|
NOTICE
ADDED
|
@@ -0,0 +1,32 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
chaoliangUNSW/Jev-Style-2B-Decision-v3
|
| 2 |
+
Copyright 2026 chaoliangUNSW. Licensed under the Apache License, Version 2.0 (see LICENSE).
|
| 3 |
+
|
| 4 |
+
This model is a fine-tuned derivative of Qwen3.5-2B (https://huggingface.co/Qwen/Qwen3.5-2B,
|
| 5 |
+
revision 15852e8c16360a2fea060d615a32b45270f8a8fc), Copyright 2026 Alibaba Cloud, licensed under the Apache
|
| 6 |
+
License, Version 2.0. The LICENSE file in this repository is the license file distributed with Qwen3.5-2B.
|
| 7 |
+
|
| 8 |
+
Modifications relative to Qwen3.5-2B:
|
| 9 |
+
- all text-model weights were fine-tuned (full fine-tuning, bf16 training; the EMA weights were selected) to
|
| 10 |
+
score typed decision questions (choice / score / true-false) with a verdict readout: logit(" yes") -
|
| 11 |
+
logit(" no") at one " ->" slot per option, using the v2 input protocol (render v2 with long-option
|
| 12 |
+
catalogues; block-causal attention in the full-attention layers over 2,048-token blocks); one global
|
| 13 |
+
calibration temperature was fitted afterwards (readout_config.json);
|
| 14 |
+
- the vision tower and the multi-token-prediction head were removed; the checkpoint is a text-only
|
| 15 |
+
Qwen3_5ForCausalLM with tied input/output embeddings;
|
| 16 |
+
- added the runtime script, readout/release configuration files, the integrity manifest and this NOTICE.
|
| 17 |
+
|
| 18 |
+
The question types (choice / score / noul) follow the typed-decision convention of Laya
|
| 19 |
+
(https://github.com/NandhaKishorM/laya, Apache-2.0) so both models can be evaluated on the same
|
| 20 |
+
inputs. No Laya code or weights are included.
|
| 21 |
+
|
| 22 |
+
Part of the third generation (v3) of the Jev-Style decision series. Earlier generations: v1 =
|
| 23 |
+
chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision (public GGUF release:
|
| 24 |
+
chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision-GGUF) and v2 = chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision-v2
|
| 25 |
+
(both built on Qwen3.5-2B-Base); the v3 series also contains chaoliangUNSW/Jev-Style-0.8B-Decision-v3 (fine-tuned from
|
| 26 |
+
Qwen3.5-0.8B, v1 input protocol). This model was fine-tuned from Qwen/Qwen3.5-2B; no weights of the earlier
|
| 27 |
+
models were used. Its input protocol (render v2 + block attention) differs from the 0.8B v3 models: use the
|
| 28 |
+
runtime of this repository (jev_style_decision.py).
|
| 29 |
+
|
| 30 |
+
Not affiliated with, endorsed by or connected to TypeSafe or Jev. "Jev-Style" only describes the kind
|
| 31 |
+
of model (a small typed-decision model in a similar style); no Jev weights, code or outputs are included.
|
| 32 |
+
Not affiliated with or endorsed by Alibaba Cloud / the Qwen team or the Laya authors.
|
README.md
ADDED
|
@@ -0,0 +1,371 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: apache-2.0
|
| 3 |
+
base_model: Qwen/Qwen3.5-2B
|
| 4 |
+
base_model_relation: finetune
|
| 5 |
+
library_name: jev-style
|
| 6 |
+
pipeline_tag: text-classification
|
| 7 |
+
tags:
|
| 8 |
+
- decision-model
|
| 9 |
+
- decision-making
|
| 10 |
+
- transformers
|
| 11 |
+
- jev-style
|
| 12 |
+
- system-one
|
| 13 |
+
- calibration
|
| 14 |
+
- classification
|
| 15 |
+
- long-context
|
| 16 |
+
- qwen3.5
|
| 17 |
+
- on-device
|
| 18 |
+
- llm-routing
|
| 19 |
+
- guardrails
|
| 20 |
+
---
|
| 21 |
+
|
| 22 |
+
# Jev-Style-2B-Decision-v3
|
| 23 |
+
|
| 24 |
+
**[Try it in your browser →](https://huggingface.co/spaces/chaoliangUNSW/jev-style-2b)**
|
| 25 |
+
|
| 26 |
+
**Website:** [jevstyle.com](https://jevstyle.com/#v3-2b) · **GitHub:** [jev-style](https://github.com/lawrence3699/jev-style) · **Collection:** [all v3 builds and demos](https://huggingface.co/collections/chaoliangUNSW/jev-style-decision-v3-08b-2b-6ab87f32380cbd8c03b608b9)
|
| 27 |
+
|
| 28 |
+
**Jev-Style decision series:** [v1 · 2B](https://huggingface.co/chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision-GGUF) → [v2 · 2B](https://huggingface.co/chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision-v2) → [v3 · 0.8B](https://huggingface.co/chaoliangUNSW/Jev-Style-0.8B-Decision-v3) → **v3 · 2B (this model)**
|
| 29 |
+
|
| 30 |
+
<!-- PIP_SNIPPET_AFTER_0.3.0 -->
|
| 31 |
+
|
| 32 |
+
**Jev-style decisions, now at 2B.** Give it a state and typed questions; it returns a calibrated probability for
|
| 33 |
+
every option in one pass. 1.88B parameters (text-only Qwen3.5-2B), open weights, Apache-2.0.
|
| 34 |
+
|
| 35 |
+

|
| 36 |
+
|
| 37 |
+
| Public benchmark | **Jev-Style v3 · 2B** | Jev-Style v3 · 0.8B | Jev 1.13 (API) |
|
| 38 |
+
|---|:---:|:---:|:---:|
|
| 39 |
+
| JevBench v1.4.1, 231 public items ↑ | 73.6% | 64.1% | 86.6% |
|
| 40 |
+
| tweet_topic, zero-shot, accuracy ↑ | 82.2% | 75.5% | 79.3%¹ |
|
| 41 |
+
| fin_topic, zero-shot, accuracy ↑ | 61.1% | 46.7% | 67.0%¹ |
|
| 42 |
+
| Longest input per call | 25,600 tokens, no option cap | 25,600 tokens | |
|
| 43 |
+
|
| 44 |
+
<sub>2B v3: GGUF F16 engine, one global temperature, each benchmark run once as pre-declared. JevBench: self-run with the official harness, not an official board entry; 95% CI 67.6–78.9% (Wilson). Jev is well ahead of the 2B on JevBench and ahead on fin_topic. ¹ Jev numbers from the elcronos study (raw API), not re-run by us. On tweet_topic the 2B's macro-F1 (67.8%) is below Jev's (69.4%). Details: [Results](#results).</sub>
|
| 45 |
+
|
| 46 |
+
**73.6% on JevBench.** On the 231 public items of JevBench v1.4.1 this is the highest JevBench public accuracy
|
| 47 |
+
among the Qwen3.5-2B-family systems on the v1.4.1 board (decider-2b 71.0%, open-jev-zefan-2b 64.5%), and
|
| 48 |
+
+9.5 points over our 0.8B v3. The 95% CI (67.6–78.9%) includes decider-2b's 71.0%, so that lead is a point
|
| 49 |
+
estimate. Jev (86.6%) is well ahead.
|
| 50 |
+
|
| 51 |
+
**25,600 tokens, no option cap.** State, questions and every option share one 25,600-token budget. There is no
|
| 52 |
+
separate question/options limit: when the question and its options exceed 2,048 tokens, the runtime switches to a
|
| 53 |
+
numbered-option catalogue. Nothing is ever truncated; an input over budget raises `InputBudgetError`.
|
| 54 |
+
|
| 55 |
+
## What it does
|
| 56 |
+
|
| 57 |
+
A state (text or JSON) and a typed question go in; a probability for every option comes out. The model never
|
| 58 |
+
generates text and cannot answer outside the options it is given.
|
| 59 |
+
|
| 60 |
+
- **choice**: pick one of N named options;
|
| 61 |
+
- **noul** (yes/no): the probability that a statement about the state is true;
|
| 62 |
+
- **score**: a distribution over 2 to 10 ordered levels.
|
| 63 |
+
|
| 64 |
+
One example, run with this repository's runtime (`jev_style_decision.py`) on the released weights, CPU, float32:
|
| 65 |
+
|
| 66 |
+
```python
|
| 67 |
+
from jev_style_decision import JevStyleDecision
|
| 68 |
+
|
| 69 |
+
m = JevStyleDecision(".", device="cpu", threads=4)
|
| 70 |
+
r = m.decide({"ticket": "I was charged twice for my subscription this month.", "customer_tier": "pro"},
|
| 71 |
+
"Which team should handle this ticket?",
|
| 72 |
+
options={"billing": "payments, invoices, refunds", "technical": "bugs and outages", "sales": "new purchases"})
|
| 73 |
+
print(r["answer"], r["probabilities"])
|
| 74 |
+
# billing {'billing': 0.976, 'technical': 0.007, 'sales': 0.017} (rounded)
|
| 75 |
+
```
|
| 76 |
+
|
| 77 |
+
Several questions about one state are scored in one call; the state is computed once and reused:
|
| 78 |
+
|
| 79 |
+
```python
|
| 80 |
+
state = "Order #1182: paid, packed, handed to the courier on Monday. Tracking shows 'delivered' on Wednesday."
|
| 81 |
+
m.decide_many(state, [
|
| 82 |
+
{"t": "noul", "ins": "Has the order been delivered?", "crit": None},
|
| 83 |
+
{"t": "choice", "ins": "Which step is the order at?", "crit": {"packing": None, "in transit": None, "delivered": None}},
|
| 84 |
+
{"t": "score", "ins": "How urgent is a follow-up?", "crit": ["not urgent", "somewhat urgent", "urgent", "critical"]},
|
| 85 |
+
])
|
| 86 |
+
# -> true 0.976 · delivered 0.686 (in transit 0.294) · level "1" 0.439 (level "0" 0.412) (rounded)
|
| 87 |
+
```
|
| 88 |
+
|
| 89 |
+
## Quick start
|
| 90 |
+
|
| 91 |
+
```bash
|
| 92 |
+
pip install -U huggingface_hub
|
| 93 |
+
hf download chaoliangUNSW/Jev-Style-2B-Decision-v3 --local-dir jev-v3-2b && cd jev-v3-2b
|
| 94 |
+
pip install -r requirements.txt # torch 2.14.0, transformers 5.17.0, tokenizers 0.23.2, numpy 2.5.3
|
| 95 |
+
|
| 96 |
+
python jev_style_decision.py --model-dir . --device cpu --threads 4 \
|
| 97 |
+
--state "The user asked to cancel the order" \
|
| 98 |
+
--question "What should happen?" \
|
| 99 |
+
--options '{"cancel": "cancel the order", "ship": "ship it"}'
|
| 100 |
+
# -> "answer": "cancel", probability 0.993 (CPU, float32)
|
| 101 |
+
```
|
| 102 |
+
|
| 103 |
+
`decide` returns `answer`, `probabilities`, the raw `scores`, the `temperature` used, `top_probability`,
|
| 104 |
+
`entropy_concentration`, token counts (`input_tokens`, `state_tokens`, `head_tokens`), `blocks`,
|
| 105 |
+
`catalogue_overflow`, `model` and `backend`. Batch mode reads JSON lines (`--jsonl file|-`); consecutive rows with
|
| 106 |
+
the same state share one state computation. `--verify` first checks the weights, tokenizer, configs and runtime against the sha256
|
| 107 |
+
manifest (documentation and evaluation records — `README.md`, `figures/`, `validation/` and `eval_results.json` —
|
| 108 |
+
are listed there but not checked).
|
| 109 |
+
A true/false question returns `{"false": p, "true": p}`; a score question returns the level indices `"0"`,
|
| 110 |
+
`"1"`, ... as option names.
|
| 111 |
+
|
| 112 |
+
```bash
|
| 113 |
+
python jev_style_decision.py --model-dir . --device cpu --threads 4 --jsonl rows.jsonl
|
| 114 |
+
```
|
| 115 |
+
|
| 116 |
+
Devices (`--device`): CPU and Apple MPS were run for this card; CUDA is supported by the runtime but was not run
|
| 117 |
+
for this release. float32 is the default (the format checks below used float32 on CPU); `--dtype bfloat16` (CUDA
|
| 118 |
+
only) was not parity-checked. `category=` is accepted for compatibility with the 0.8B v3 runtime and ignored: this model has one
|
| 119 |
+
global temperature.
|
| 120 |
+
|
| 121 |
+
### Other builds
|
| 122 |
+
|
| 123 |
+
| Build | Size | Runtime |
|
| 124 |
+
|---|---:|---|
|
| 125 |
+
| **Transformers safetensors (bf16) · this repository** | 3.76 GB (2 shards) | PyTorch on CPU, Apple MPS or CUDA (`jev_style_decision.py`) |
|
| 126 |
+
| [GGUF F16 / Q8_0 / Q4_K_M](https://huggingface.co/chaoliangUNSW/Jev-Style-2B-Decision-v3-GGUF) | 3.78 / 2.01 / 1.27 GB | llama.cpp (libllama) + the bundled `jev-score-v2` scorer |
|
| 127 |
+
| [MLX bf16 / 8-bit](https://huggingface.co/chaoliangUNSW/Jev-Style-2B-Decision-v3-MLX) (one repository) | 3.76 / 2.00 GB | Apple silicon, mlx-lm 0.31.3 (`--model-dir bf16\|8bit`) |
|
| 128 |
+
|
| 129 |
+
## Which file to pick
|
| 130 |
+
|
| 131 |
+
Every format was checked against the PyTorch FP32 reference on the released checkpoint, with gates declared before
|
| 132 |
+
any format was scored. All five pass.
|
| 133 |
+
|
| 134 |
+
| Format | Size | Same top-1 as FP32 (1,000 rows) | Max abs Δp (1,000 rows) | Accuracy (FP32: 80.8%) | Long fixture (43 questions, up to 25,600 tokens) | Gate |
|
| 135 |
+
|---|---:|---:|---:|---:|---:|:---:|
|
| 136 |
+
| PyTorch (this repository) | 3.76 GB | reference | | 80.8% | reference | |
|
| 137 |
+
| GGUF F16 | 3.78 GB | 100% | 0.0014 | 80.8% | 43 / 43 | PASS |
|
| 138 |
+
| GGUF Q8_0 | 2.01 GB | 99.7% | 0.033 | 80.7% | 43 / 43 | PASS |
|
| 139 |
+
| GGUF Q4_K_M | 1.27 GB | 95.7% | 0.346 | 81.1% | 42 / 43 | PASS¹ |
|
| 140 |
+
| MLX bf16 | 3.76 GB | 99.7% | 0.035 | 80.5% | 43 / 43 | PASS |
|
| 141 |
+
| MLX 8-bit (affine, group 64) | 2.00 GB | 99.6% | 0.162 | 80.8% | 43 / 43 | PASS |
|
| 142 |
+
|
| 143 |
+
- **Long documents: use GGUF Q8_0 or F16.** Q4_K_M is noticeably noisier on long inputs.
|
| 144 |
+
- **Apple silicon:** MLX bf16 (3.76 GB) for closeness to FP32: its scores are the closer of the two MLX builds to the
|
| 145 |
+
FP32 reference (max abs Δp 0.035 vs 0.162 for 8-bit). MLX 8-bit (2.00 GB) when memory is tight.
|
| 146 |
+
- **Smallest file:** GGUF Q4_K_M, 1.27 GB.
|
| 147 |
+
|
| 148 |
+
<sub>Reference: HF FP32 on CPU, exact block attention, on the released bf16 checkpoint. Gate fixture: 1,000 real development rows (≤4,096 tokens); these rows test agreement between formats. Long fixture: 35 requests / 43 questions up to 25,600 tokens, including catalogue-overflow questions and up to 151 options. ¹ For 4-bit the pre-declared gate is the accuracy drop (≤1.0 point); top-1 agreement is reported only. Sizes are the weight files (GB = 10^9 bytes); MLX adds a 0.42 MB FP32 norm file.</sub>
|
| 149 |
+
|
| 150 |
+
<!-- LATENCY:BEGIN generated from latency_2b.json (validation/latency_2b.json in the main repository); do not edit by hand -->
|
| 151 |
+
|
| 152 |
+
## Speed
|
| 153 |
+
|
| 154 |
+
**Read once, then ask.** On an Apple M1 Max (GGUF F16), the first question about a 24,501-token input took 16.2 s; a further question about the same state took 0.17 s, because the state is computed once and reused (medians). Ten questions about that state in one call took 16.8 s.
|
| 155 |
+
|
| 156 |
+
| State | Questions per call | GGUF F16 | MLX bf16 | PyTorch (MPS, float32) |
|
| 157 |
+
|---|---:|---:|---:|---:|
|
| 158 |
+
| 878 tokens | 1 | 0.52 s | 0.57 s | 1.82 s |
|
| 159 |
+
| 878 tokens | 10 | 0.97 s | 1.07 s | 3.13 s |
|
| 160 |
+
| 3,950 tokens | 1 | 2.18 s | 2.26 s | 7.74 s |
|
| 161 |
+
| 3,950 tokens | 10 | 2.66 s | 2.80 s | 9.23 s |
|
| 162 |
+
| 24,436 tokens | 1 | 16.2 s | 15.5 s | 61.9 s |
|
| 163 |
+
| 24,436 tokens | 10 | 16.8 s | 16.2 s | 72.3 s |
|
| 164 |
+
| 24,436 tokens, already computed | 1 | 0.17 s | 0.15 s | 0.60 s |
|
| 165 |
+
|
| 166 |
+
<sub>Apple M1 Max, 64 GB, macOS 15.7.5. Wall time around one `decide` / `score_many` call (tokenisation included), median of 3 calls with the state recomputed each time; the model was loaded beforehand (loading took 1.2–8.0 s here, not included). States: English documentation and source code of 878, 3,950, 24,436 tokens plus the question; 10 questions = 4 choice, 4 true/false and 2 score questions about the same state in one call; with the question and options each input was up to 943, 4,015 and 24,501 tokens. GGUF: `jev-score-v2` on llama.cpp 441df11f, Metal, all layers on the GPU. MLX: mlx 0.32.2 / mlx-lm 0.31.3. PyTorch: this repository's runtime, float32 on Apple MPS. Results were identical with and without a precomputed state. Other jobs shared the machine during these runs (1-minute load average 5.5–11.1 at the end of each run), so treat the numbers as indicative. The PyTorch rows were measured in an earlier session (2026-09-27 00:45–02:15 AEST, load average 7.3–11.1); the GGUF and MLX rows were re-measured later (03:11–03:24 AEST, load average 5.5–10.0) because other jobs had slowed the earlier session (the re-measured GGUF and MLX rows shown here were up to 2.1× faster), so the PyTorch times may be pessimistic.</sub>
|
| 167 |
+
|
| 168 |
+
<!-- LATENCY:END -->
|
| 169 |
+
|
| 170 |
+
## Results
|
| 171 |
+
|
| 172 |
+
All public benchmarks were pre-declared: GGUF F16 engine, each benchmark run once, one global temperature fitted
|
| 173 |
+
on our own calibration rows (never on benchmark items).
|
| 174 |
+
|
| 175 |
+
### JevBench v1.4.1: 73.6% on the public items
|
| 176 |
+
|
| 177 |
+

|
| 178 |
+
|
| 179 |
+
**73.6% (170 / 231)**, the highest JevBench public accuracy among the Qwen3.5-2B-family systems on the v1.4.1
|
| 180 |
+
board (decider-2b 71.0%, open-jev-zefan-2b 64.5%), and +9.5 points over the 0.8B v3. Jev (86.6%) is well ahead.
|
| 181 |
+
|
| 182 |
+
| System | Public accuracy (231) | Easy (48) | Standard (72) | Hard (111) | Hard-tier ECE |
|
| 183 |
+
|---|---:|---:|---:|---:|---:|
|
| 184 |
+
| **Jev-Style 2B v3** (this model, self-run) | 73.6% (170) | 100% | 95.8% | 47.7% | 0.153² |
|
| 185 |
+
| Jev-Style 0.8B v3 (self-run) | 64.1% (148) | 100% | 81.9% | 36.9% | 0.200² |
|
| 186 |
+
| Jev 1.13.0 (TypeSafe AI, API) | 86.6% | | | | |
|
| 187 |
+
| Decision 2B (FlyMy.AI, MiniCPM5-2B + LoRA, evaluation-only weights) | 75.3% | | | | |
|
| 188 |
+
| decider-2b (Mapika, Qwen3.5-2B-Base) | 71.0% | | | | |
|
| 189 |
+
| Raw Qwen3-4B-Instruct-2507 logits | 69.7% | | | | |
|
| 190 |
+
| kev 0.6B | 66.7% | | | | |
|
| 191 |
+
| Open-Jev 2B (Zefan Cai, Qwen3.5-2B + LoRA) | 64.5% | | | | |
|
| 192 |
+
| Laya (ModernBERT-large, 421M) | 58.4% | | | | |
|
| 193 |
+
|
| 194 |
+
<sub>JevBench v1.4.1 (github.com/fstandhartinger/jevbench, tag v1.4.1, commit 24b9b5c), public items only. 2B v3: self-run once with the vendored official harness, GGUF F16, zero-shot, one global temperature; 95% CI 67.6–78.9% (Wilson), which includes decider-2b (164 / 231), so that lead is a point estimate; not an official leaderboard entry. Other rows: public accuracy as published in the board's v1.4.1 results file; 42 of the 82 board systems score higher than 73.6%, almost all of them 4B or larger, or large API models. ² ECE over the 111 public hard items; the board's ECE uses all 220 hard items, so it is only an approximate comparison. Training-pool contamination scan (state hash, instruction hash, text fields of 32+ characters, 13-word spans): 0 hits.</sub>
|
| 195 |
+
|
| 196 |
+
### Zero-shot topics: 82.2% on tweet_topic
|
| 197 |
+
|
| 198 |
+

|
| 199 |
+
|
| 200 |
+
**On tweet_topic the 2B scores 82.2% accuracy, above Jev's 79.3%**, which lies outside the 2B's 95% CI
|
| 201 |
+
(80.4–84.0%). Its macro-F1 is below Jev's (67.8% vs 69.4%). **On the 20-way fin_topic it scores 61.1%, +14.4
|
| 202 |
+
points over the 0.8B v3**; Jev is higher there (67.0%).
|
| 203 |
+
|
| 204 |
+
| Set | n | **2B v3 accuracy** [95% CI] | 2B v3 macro-F1 | 2B v3 ECE (calibrated) | Jev accuracy / macro-F1 / ECE (raw API) | 0.8B v3 accuracy |
|
| 205 |
+
|---|---:|---:|---:|---:|---:|---:|
|
| 206 |
+
| tweet_topic | 1,693 | 82.2% [80.4, 84.0] | 67.8% | 0.028 | 79.3% / 69.4% / 0.063 | 75.5% |
|
| 207 |
+
| fin_topic | 4,117 | 61.1% [59.6, 62.6] | 59.0% | 0.065 | 67.0% / 63.0% / 0.166 | 46.7% |
|
| 208 |
+
|
| 209 |
+
<sub>Zero-shot: none of these test sets is in the training pool (0 exact overlaps, 0 near-duplicates). Accuracy over every row of the pinned test files; CIs are percentile bootstrap (10,000 resamples). Jev (1.13, API): numbers published by the [elcronos jev-vs-open-decision-models study](https://github.com/elcronos/jev-vs-open-decision-models) (results/cross_dataset_summary.json @ a1901bc), not re-run by us. ECE: 15 equal-width bins; ours uses the model's one global temperature (fitted on our own calibration rows, never on these sets), Jev's is from its raw API probabilities, so the two ECE columns are not like-for-like. The temperature is fitted once for all tasks, not per test set: without it (T = 1) the 2B's ECE is 0.087 on tweet_topic and 0.038 on fin_topic.</sub>
|
| 210 |
+
|
| 211 |
+
## How it differs from the 0.8B v3
|
| 212 |
+
|
| 213 |
+
Both v3 models read 25,600 tokens and score every option at its own verdict slot. The 2B is a separate full
|
| 214 |
+
fine-tune with a different input protocol, so each size needs its own runtime.
|
| 215 |
+
|
| 216 |
+
| | [Jev-Style 0.8B v3](https://huggingface.co/chaoliangUNSW/Jev-Style-0.8B-Decision-v3) | **Jev-Style 2B v3 (this model)** |
|
| 217 |
+
|---|---|---|
|
| 218 |
+
| Base | Qwen/Qwen3.5-0.8B | **Qwen/Qwen3.5-2B** (post-trained, not -Base) |
|
| 219 |
+
| Parameters | 752,393,024 | **1,881,825,088** (24 layers: 18 Gated DeltaNet + 6 full attention, hidden 2,048) |
|
| 220 |
+
| Input protocol | v1: causal attention | **v2: block attention**. Each 2,048-token block sees everything before it plus itself |
|
| 221 |
+
| Question/options limit | 2,048-token head; longer option lists are split into option chunks | **None**: one 25,600-token budget; a numbered catalogue when question + options exceed 2,048 tokens |
|
| 222 |
+
| Calibration | 20 group temperatures + a global one | **One global temperature** (T = 0.828) |
|
| 223 |
+
| JevBench v1.4.1 public | 64.1% | **73.6%** |
|
| 224 |
+
| tweet_topic / fin_topic accuracy | 75.5% / 46.7% | **82.2% / 61.1%** |
|
| 225 |
+
| Smallest file | 0.53 GB (Q4_K_M) | 1.27 GB (Q4_K_M) |
|
| 226 |
+
|
| 227 |
+
### Input format and readout
|
| 228 |
+
|
| 229 |
+
<details>
|
| 230 |
+
<summary><strong>Prompt layout, block attention and the score</strong></summary>
|
| 231 |
+
|
| 232 |
+
Each segment is tokenised on its own and the pieces are concatenated, so slot positions are exact. Text inside the
|
| 233 |
+
state, question and options is tokenised with special tokens disabled: `<|im_end|>` in user text stays plain text.
|
| 234 |
+
Non-special added tokens such as `<think>` encode as their single ids, as in training.
|
| 235 |
+
|
| 236 |
+
```text
|
| 237 |
+
State:
|
| 238 |
+
<state: plain text, or any JSON value>
|
| 239 |
+
|
| 240 |
+
Question [<choice|noul|score>]: <question>
|
| 241 |
+
Options:
|
| 242 |
+
- <option 1> ->
|
| 243 |
+
- <option 2> ->
|
| 244 |
+
```
|
| 245 |
+
|
| 246 |
+
When the question, options and slots together exceed 2,048 tokens, the options are written once as a numbered
|
| 247 |
+
catalogue (`Option 1: <option 1>` ...), followed by `Judge each numbered option in the complete catalogue above:` and
|
| 248 |
+
one `Option k ->` slot per option.
|
| 249 |
+
|
| 250 |
+
- **Block attention.** The input is cut into blocks of at most 2,048 tokens (state blocks, then the question block,
|
| 251 |
+
or catalogue and rubric blocks). In the 6 full-attention layers each block attends to everything before it and to
|
| 252 |
+
itself, with no causal mask inside the block. The Gated DeltaNet layers are ordinary recurrent layers. This is
|
| 253 |
+
why the shipped runtimes are required.
|
| 254 |
+
- **Score.** Option k's score is `logit(" yes") − logit(" no")` at its ` ->` slot, computed in float32 from the
|
| 255 |
+
final normalised hidden state and the tied embedding rows. No parameters are added.
|
| 256 |
+
- **Probabilities.** `softmax(scores / T)` with one global `T = 0.8278650621`, fitted on 2,000 independent
|
| 257 |
+
calibration rows (NLL 0.3003 → 0.2901). `temperature=1.0` gives the raw scores.
|
| 258 |
+
|
| 259 |
+
</details>
|
| 260 |
+
|
| 261 |
+
## Scope and limits
|
| 262 |
+
|
| 263 |
+
- **Runtime required.** Decisions come from the runtimes shipped in the three repositories (PyTorch, GGUF +
|
| 264 |
+
`jev-score-v2`, MLX). Stock llama.cpp, Ollama, LM Studio or `mlx_lm.generate` can load the weights but cannot
|
| 265 |
+
produce the decision scores, and they would run causal attention. The 0.8B v3 runtimes are not valid for this model.
|
| 266 |
+
- **25,600 tokens** is the limit for the whole input (state + question + options + readout).
|
| 267 |
+
- **Reduced-data training.** This model was trained on a reduced data pool (60M tokens); the planned full recipe
|
| 268 |
+
was not run.
|
| 269 |
+
- **Decision Index.** We have not run Decision Index 0.2 and report no score for it. The training pool includes the
|
| 270 |
+
train splits of BANKING77, CLINC150 (+OOS), SGD, HellaSwag, GSM8K, ARC-Easy and ARC-Challenge (licences under
|
| 271 |
+
[Training data and licences](#training-data-and-licences)), and format-imitating data for SATA-Bench, BRIGHT,
|
| 272 |
+
NLI4CT, CRUXEval, CLadder, PhishNChips and BBH, so results on these 14 benchmarks are not zero-shot.
|
| 273 |
+
- **Decisions only.** The model scores the options you give it. It does not generate text and takes no actions.
|
| 274 |
+
|
| 275 |
+
## Training
|
| 276 |
+
|
| 277 |
+
- **Base:** [Qwen/Qwen3.5-2B](https://huggingface.co/Qwen/Qwen3.5-2B) (revision `15852e8c`), Apache-2.0. The
|
| 278 |
+
vision tower and the multi-token-prediction head were removed; the checkpoint is a text-only
|
| 279 |
+
`Qwen3_5ForCausalLM` with tied embeddings.
|
| 280 |
+
- **Run:** full fine-tune on one Colab A100 40GB, 458 steps, 1 epoch, 60,032,377 training tokens (181,449
|
| 281 |
+
logical rows). Trained on a reduced data pool (60M tokens).
|
| 282 |
+
- **Checkpoint:** EMA vs raw weights chosen by a pre-declared rule (lowest component-macro NLL on a fixed
|
| 283 |
+
development sample of 1,556 rows): EMA.
|
| 284 |
+
- **Calibration:** one global temperature fitted on 2,000 independent calibration rows (NLL 0.3003 → 0.2901).
|
| 285 |
+
|
| 286 |
+
<!-- BEGIN DATA_LICENCES -->
|
| 287 |
+
## Training data and licences
|
| 288 |
+
|
| 289 |
+
- **Base model:** Qwen/Qwen3.5-2B (Qwen team, Alibaba Cloud), Apache-2.0; see `LICENSE` and `NOTICE`.
|
| 290 |
+
- **Mixture:** 181,449 training rows (60,032,377 tokens; repeats counted) from 58 sources. English is 77.7% of the
|
| 291 |
+
tokens and Chinese 17.0%; MASSIVE adds nine more languages.
|
| 292 |
+
|
| 293 |
+
| Component | Rows | Share of tokens | Sources |
|
| 294 |
+
|---|---:|---:|---|
|
| 295 |
+
| Typed decisions | 34,008 | 19.2% | model-written business workflows (27,300 unique items) |
|
| 296 |
+
| Intents and yes/no QA | 32,123 | 16.2% | MASSIVE, CLINC150, BoolQ |
|
| 297 |
+
| Knowledge and reasoning | 32,724 | 10.6% | ARC, CommonsenseQA, MedMCQA, QASC, GSM8K, MBPP, chess puzzles; code-generated items |
|
| 298 |
+
| Themes | 38,290 | 10.3% | Civil Comments, SQuAD v2, five jailbreak and prompt-injection sets, model-written prompts |
|
| 299 |
+
| Long tables | 3,292 | 8.6% | code-generated tables |
|
| 300 |
+
| Retrieval and routing | 13,697 | 7.6% | BANKING77, SGD; code-generated link-safety and relevance items |
|
| 301 |
+
| Mac agent checks | 7,787 | 7.5% | the project's own simulators |
|
| 302 |
+
| Public reading tasks | 5,597 | 7.0% | 14 sets, incl. WANLI, TabFact, DROP, HelpSteer2, FinQA, MAUD |
|
| 303 |
+
| Hard cases | 2,281 | 6.8% | five generated families (policy, multi-hop, numeric, abstention, judging) |
|
| 304 |
+
| Language | 11,012 | 3.6% | HellaSwag, SNLI, code-generated clinical-trial reports |
|
| 305 |
+
| Option-format views | 638 | 2.6% | alternative option layouts of rows above |
|
| 306 |
+
|
| 307 |
+
- **Benchmark train splits** (official train splits only, no test split; results on these benchmarks are not
|
| 308 |
+
zero-shot, see Benchmarks below): BANKING77 by PolyAI (CC BY 4.0 upstream at PolyAI/banking77; rows taken from the MTEB mirror mteb/banking77, whose card says MIT), CLINC150 with its out-of-scope queries (CC BY 3.0),
|
| 309 |
+
Schema-Guided Dialogue (SGD; CC BY-SA 4.0), GSM8K (MIT), ARC-Easy and ARC-Challenge (CC BY-SA 4.0), and HellaSwag
|
| 310 |
+
(MIT; see below). Each one's repository is linked in the per-source list.
|
| 311 |
+
- **Full per-source list:** [validation/data_sources.json](validation/data_sources.json) (all 58 sources with the
|
| 312 |
+
licence recorded for each, the mixture rows they feed and a link where available).
|
| 313 |
+
- **Datasets with restrictive or unclear terms** (kept in the pool; check each source's terms before commercial use):
|
| 314 |
+
- Jailbreak prompts from the jailbreak_llms collection, which states it is for research purposes only:
|
| 315 |
+
In-the-Wild Jailbreak Prompts (TrustAIRLab, MIT; 1,604 rows) and the jailbreak prompts in
|
| 316 |
+
jackhhao/jailbreak-classification (Apache-2.0; 1,410 rows in total).
|
| 317 |
+
- HellaSwag: its card gives MIT only in the text (no licence field), and the original GitHub repository is blocked
|
| 318 |
+
after a DMCA notice from wikiHow. Only the ActivityNet-caption items were used.
|
| 319 |
+
- neuralchemy Prompt-injection-dataset (2,133 rows): the upstream rows its card marks research-only were removed.
|
| 320 |
+
- Share-alike (CC BY-SA): SQuAD v2, BoolQ, DROP, SNLI, ARC, SGD, ShARC, TempReason.
|
| 321 |
+
- **Outputs of other models:**
|
| 322 |
+
- OpenAI GPT and Anthropic Claude models designed the typed-decision workflows (34,008 rows); Claude models
|
| 323 |
+
labelled them. A Claude model wrote and labelled 1,243 jailbreak and toxicity prompt rows.
|
| 324 |
+
- OpenAI GPT models wrote two hard-case families (1,132 rows) and paraphrased the goal wording of 2,012 of the
|
| 325 |
+
3,999 unique Mac goal-done items. Hard-case labels are computed by code.
|
| 326 |
+
- Third-party data with model-written text: WANLI (506 rows; GPT-3, revised by crowdworkers), part of the
|
| 327 |
+
jackhhao benign prompts (from GPTeacher, generated by GPT-4) and the HelpSteer2 responses (490 rows; mostly
|
| 328 |
+
NVIDIA Nemotron models and Mixtral-8x7B-Instruct).
|
| 329 |
+
- The providers' terms of use may restrict how models trained on such outputs may be used, so check them for
|
| 330 |
+
your use case. No outputs of Jev or any other TypeSafe model were used.
|
| 331 |
+
- **Benchmarks:** no test split was used. The train splits and format-imitating generators named under
|
| 332 |
+
[Scope and limits](#scope-and-limits) are in the mixture, so results on those 14 benchmarks are not zero-shot.
|
| 333 |
+
- **Evaluation-only data** (0 training rows): the JevBench items, tweet_topic, fin_topic and daily_dialog. The
|
| 334 |
+
contamination scan found no JevBench hit and no exact or near-duplicate overlap with tweet_topic and fin_topic;
|
| 335 |
+
daily_dialog has no exact overlap apart from one generic short phrase ("Thanks a lot"), plus three
|
| 336 |
+
near-duplicate-only matches. The scan ([validation/benchmarks/contamination.json](validation/benchmarks/contamination.json))
|
| 337 |
+
covers the full reduced pool (463,208 train rows, plus the format, development and calibration files), a superset
|
| 338 |
+
of the rows actually trained on (181,449 drawn, repeats counted).
|
| 339 |
+
<!-- END DATA_LICENCES -->
|
| 340 |
+
|
| 341 |
+
## Disclaimers
|
| 342 |
+
|
| 343 |
+
> **Independent project.** Jev-Style is not affiliated with, endorsed by or connected to TypeSafe AI or Jev, and no
|
| 344 |
+
> Jev weights, code or outputs are used. It is also not affiliated with the Laya authors or the Qwen team. Jev and
|
| 345 |
+
> other board numbers on this card come from the sources named under each result.
|
| 346 |
+
|
| 347 |
+
**AI disclosure:** code written with AI coding assistants (Claude Code) under my direction; I designed the project,
|
| 348 |
+
trained the models and verified the results.
|
| 349 |
+
|
| 350 |
+
## Licence
|
| 351 |
+
|
| 352 |
+
Apache-2.0. Built on Qwen/Qwen3.5-2B (Apache-2.0); the Apache License 2.0 text is in `LICENSE`, and `NOTICE` lists
|
| 353 |
+
the modifications.
|
| 354 |
+
|
| 355 |
+
## Citation
|
| 356 |
+
|
| 357 |
+
```bibtex
|
| 358 |
+
@misc{jevstyle2026v3_2b,
|
| 359 |
+
title = {Jev-Style-2B-Decision-v3: a 2B decision model with calibrated probabilities for every option},
|
| 360 |
+
author = {chaoliangUNSW},
|
| 361 |
+
year = {2026},
|
| 362 |
+
howpublished = {\url{https://huggingface.co/chaoliangUNSW/Jev-Style-2B-Decision-v3}},
|
| 363 |
+
note = {Fine-tuned from Qwen/Qwen3.5-2B}
|
| 364 |
+
}
|
| 365 |
+
```
|
| 366 |
+
|
| 367 |
+
## Contact
|
| 368 |
+
|
| 369 |
+
I welcome internship, employment, and research collaboration opportunities. Please contact me at [**yanchaoliang369@gmail.com**](mailto:yanchaoliang369@gmail.com).
|
| 370 |
+
|
| 371 |
+
欢迎提供实习、工作及科研合作机会,请邮件联系:[yanchaoliang369@gmail.com](mailto:yanchaoliang369@gmail.com)。
|
chat_template.jinja
ADDED
|
@@ -0,0 +1,154 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{%- set image_count = namespace(value=0) %}
|
| 2 |
+
{%- set video_count = namespace(value=0) %}
|
| 3 |
+
{%- macro render_content(content, do_vision_count, is_system_content=false) %}
|
| 4 |
+
{%- if content is string %}
|
| 5 |
+
{{- content }}
|
| 6 |
+
{%- elif content is iterable and content is not mapping %}
|
| 7 |
+
{%- for item in content %}
|
| 8 |
+
{%- if 'image' in item or 'image_url' in item or item.type == 'image' %}
|
| 9 |
+
{%- if is_system_content %}
|
| 10 |
+
{{- raise_exception('System message cannot contain images.') }}
|
| 11 |
+
{%- endif %}
|
| 12 |
+
{%- if do_vision_count %}
|
| 13 |
+
{%- set image_count.value = image_count.value + 1 %}
|
| 14 |
+
{%- endif %}
|
| 15 |
+
{%- if add_vision_id %}
|
| 16 |
+
{{- 'Picture ' ~ image_count.value ~ ': ' }}
|
| 17 |
+
{%- endif %}
|
| 18 |
+
{{- '<|vision_start|><|image_pad|><|vision_end|>' }}
|
| 19 |
+
{%- elif 'video' in item or item.type == 'video' %}
|
| 20 |
+
{%- if is_system_content %}
|
| 21 |
+
{{- raise_exception('System message cannot contain videos.') }}
|
| 22 |
+
{%- endif %}
|
| 23 |
+
{%- if do_vision_count %}
|
| 24 |
+
{%- set video_count.value = video_count.value + 1 %}
|
| 25 |
+
{%- endif %}
|
| 26 |
+
{%- if add_vision_id %}
|
| 27 |
+
{{- 'Video ' ~ video_count.value ~ ': ' }}
|
| 28 |
+
{%- endif %}
|
| 29 |
+
{{- '<|vision_start|><|video_pad|><|vision_end|>' }}
|
| 30 |
+
{%- elif 'text' in item %}
|
| 31 |
+
{{- item.text }}
|
| 32 |
+
{%- else %}
|
| 33 |
+
{{- raise_exception('Unexpected item type in content.') }}
|
| 34 |
+
{%- endif %}
|
| 35 |
+
{%- endfor %}
|
| 36 |
+
{%- elif content is none or content is undefined %}
|
| 37 |
+
{{- '' }}
|
| 38 |
+
{%- else %}
|
| 39 |
+
{{- raise_exception('Unexpected content type.') }}
|
| 40 |
+
{%- endif %}
|
| 41 |
+
{%- endmacro %}
|
| 42 |
+
{%- if not messages %}
|
| 43 |
+
{{- raise_exception('No messages provided.') }}
|
| 44 |
+
{%- endif %}
|
| 45 |
+
{%- if tools and tools is iterable and tools is not mapping %}
|
| 46 |
+
{{- '<|im_start|>system\n' }}
|
| 47 |
+
{{- "# Tools\n\nYou have access to the following functions:\n\n<tools>" }}
|
| 48 |
+
{%- for tool in tools %}
|
| 49 |
+
{{- "\n" }}
|
| 50 |
+
{{- tool | tojson }}
|
| 51 |
+
{%- endfor %}
|
| 52 |
+
{{- "\n</tools>" }}
|
| 53 |
+
{{- '\n\nIf you choose to call a function ONLY reply in the following format with NO suffix:\n\n<tool_call>\n<function=example_function_name>\n<parameter=example_parameter_1>\nvalue_1\n</parameter>\n<parameter=example_parameter_2>\nThis is the value for the second parameter\nthat can span\nmultiple lines\n</parameter>\n</function>\n</tool_call>\n\n<IMPORTANT>\nReminder:\n- Function calls MUST follow the specified format: an inner <function=...></function> block must be nested within <tool_call></tool_call> XML tags\n- Required parameters MUST be specified\n- You may provide optional reasoning for your function call in natural language BEFORE the function call, but NOT after\n- If there is no function call available, answer the question like normal with your current knowledge and do not tell the user about function calls\n</IMPORTANT>' }}
|
| 54 |
+
{%- if messages[0].role == 'system' %}
|
| 55 |
+
{%- set content = render_content(messages[0].content, false, true)|trim %}
|
| 56 |
+
{%- if content %}
|
| 57 |
+
{{- '\n\n' + content }}
|
| 58 |
+
{%- endif %}
|
| 59 |
+
{%- endif %}
|
| 60 |
+
{{- '<|im_end|>\n' }}
|
| 61 |
+
{%- else %}
|
| 62 |
+
{%- if messages[0].role == 'system' %}
|
| 63 |
+
{%- set content = render_content(messages[0].content, false, true)|trim %}
|
| 64 |
+
{{- '<|im_start|>system\n' + content + '<|im_end|>\n' }}
|
| 65 |
+
{%- endif %}
|
| 66 |
+
{%- endif %}
|
| 67 |
+
{%- set ns = namespace(multi_step_tool=true, last_query_index=messages|length - 1) %}
|
| 68 |
+
{%- for message in messages[::-1] %}
|
| 69 |
+
{%- set index = (messages|length - 1) - loop.index0 %}
|
| 70 |
+
{%- if ns.multi_step_tool and message.role == "user" %}
|
| 71 |
+
{%- set content = render_content(message.content, false)|trim %}
|
| 72 |
+
{%- if not(content.startswith('<tool_response>') and content.endswith('</tool_response>')) %}
|
| 73 |
+
{%- set ns.multi_step_tool = false %}
|
| 74 |
+
{%- set ns.last_query_index = index %}
|
| 75 |
+
{%- endif %}
|
| 76 |
+
{%- endif %}
|
| 77 |
+
{%- endfor %}
|
| 78 |
+
{%- if ns.multi_step_tool %}
|
| 79 |
+
{{- raise_exception('No user query found in messages.') }}
|
| 80 |
+
{%- endif %}
|
| 81 |
+
{%- for message in messages %}
|
| 82 |
+
{%- set content = render_content(message.content, true)|trim %}
|
| 83 |
+
{%- if message.role == "system" %}
|
| 84 |
+
{%- if not loop.first %}
|
| 85 |
+
{{- raise_exception('System message must be at the beginning.') }}
|
| 86 |
+
{%- endif %}
|
| 87 |
+
{%- elif message.role == "user" %}
|
| 88 |
+
{{- '<|im_start|>' + message.role + '\n' + content + '<|im_end|>' + '\n' }}
|
| 89 |
+
{%- elif message.role == "assistant" %}
|
| 90 |
+
{%- set reasoning_content = '' %}
|
| 91 |
+
{%- if message.reasoning_content is string %}
|
| 92 |
+
{%- set reasoning_content = message.reasoning_content %}
|
| 93 |
+
{%- else %}
|
| 94 |
+
{%- if '</think>' in content %}
|
| 95 |
+
{%- set reasoning_content = content.split('</think>')[0].rstrip('\n').split('<think>')[-1].lstrip('\n') %}
|
| 96 |
+
{%- set content = content.split('</think>')[-1].lstrip('\n') %}
|
| 97 |
+
{%- endif %}
|
| 98 |
+
{%- endif %}
|
| 99 |
+
{%- set reasoning_content = reasoning_content|trim %}
|
| 100 |
+
{%- if loop.index0 > ns.last_query_index %}
|
| 101 |
+
{{- '<|im_start|>' + message.role + '\n<think>\n' + reasoning_content + '\n</think>\n\n' + content }}
|
| 102 |
+
{%- else %}
|
| 103 |
+
{{- '<|im_start|>' + message.role + '\n' + content }}
|
| 104 |
+
{%- endif %}
|
| 105 |
+
{%- if message.tool_calls and message.tool_calls is iterable and message.tool_calls is not mapping %}
|
| 106 |
+
{%- for tool_call in message.tool_calls %}
|
| 107 |
+
{%- if tool_call.function is defined %}
|
| 108 |
+
{%- set tool_call = tool_call.function %}
|
| 109 |
+
{%- endif %}
|
| 110 |
+
{%- if loop.first %}
|
| 111 |
+
{%- if content|trim %}
|
| 112 |
+
{{- '\n\n<tool_call>\n<function=' + tool_call.name + '>\n' }}
|
| 113 |
+
{%- else %}
|
| 114 |
+
{{- '<tool_call>\n<function=' + tool_call.name + '>\n' }}
|
| 115 |
+
{%- endif %}
|
| 116 |
+
{%- else %}
|
| 117 |
+
{{- '\n<tool_call>\n<function=' + tool_call.name + '>\n' }}
|
| 118 |
+
{%- endif %}
|
| 119 |
+
{%- if tool_call.arguments is defined %}
|
| 120 |
+
{%- for args_name, args_value in tool_call.arguments|items %}
|
| 121 |
+
{{- '<parameter=' + args_name + '>\n' }}
|
| 122 |
+
{%- set args_value = args_value | tojson | safe if args_value is mapping or (args_value is sequence and args_value is not string) else args_value | string %}
|
| 123 |
+
{{- args_value }}
|
| 124 |
+
{{- '\n</parameter>\n' }}
|
| 125 |
+
{%- endfor %}
|
| 126 |
+
{%- endif %}
|
| 127 |
+
{{- '</function>\n</tool_call>' }}
|
| 128 |
+
{%- endfor %}
|
| 129 |
+
{%- endif %}
|
| 130 |
+
{{- '<|im_end|>\n' }}
|
| 131 |
+
{%- elif message.role == "tool" %}
|
| 132 |
+
{%- if loop.previtem and loop.previtem.role != "tool" %}
|
| 133 |
+
{{- '<|im_start|>user' }}
|
| 134 |
+
{%- endif %}
|
| 135 |
+
{{- '\n<tool_response>\n' }}
|
| 136 |
+
{{- content }}
|
| 137 |
+
{{- '\n</tool_response>' }}
|
| 138 |
+
{%- if not loop.last and loop.nextitem.role != "tool" %}
|
| 139 |
+
{{- '<|im_end|>\n' }}
|
| 140 |
+
{%- elif loop.last %}
|
| 141 |
+
{{- '<|im_end|>\n' }}
|
| 142 |
+
{%- endif %}
|
| 143 |
+
{%- else %}
|
| 144 |
+
{{- raise_exception('Unexpected message role.') }}
|
| 145 |
+
{%- endif %}
|
| 146 |
+
{%- endfor %}
|
| 147 |
+
{%- if add_generation_prompt %}
|
| 148 |
+
{{- '<|im_start|>assistant\n' }}
|
| 149 |
+
{%- if enable_thinking is defined and enable_thinking is true %}
|
| 150 |
+
{{- '<think>\n' }}
|
| 151 |
+
{%- else %}
|
| 152 |
+
{{- '<think>\n\n</think>\n\n' }}
|
| 153 |
+
{%- endif %}
|
| 154 |
+
{%- endif %}
|
config.json
ADDED
|
@@ -0,0 +1,75 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"architectures": [
|
| 3 |
+
"Qwen3_5ForCausalLM"
|
| 4 |
+
],
|
| 5 |
+
"attention_bias": false,
|
| 6 |
+
"attention_dropout": 0.0,
|
| 7 |
+
"attn_output_gate": true,
|
| 8 |
+
"bos_token_id": null,
|
| 9 |
+
"dtype": "bfloat16",
|
| 10 |
+
"eos_token_id": 248044,
|
| 11 |
+
"full_attention_interval": 4,
|
| 12 |
+
"head_dim": 256,
|
| 13 |
+
"hidden_act": "silu",
|
| 14 |
+
"hidden_size": 2048,
|
| 15 |
+
"initializer_range": 0.02,
|
| 16 |
+
"intermediate_size": 6144,
|
| 17 |
+
"layer_types": [
|
| 18 |
+
"linear_attention",
|
| 19 |
+
"linear_attention",
|
| 20 |
+
"linear_attention",
|
| 21 |
+
"full_attention",
|
| 22 |
+
"linear_attention",
|
| 23 |
+
"linear_attention",
|
| 24 |
+
"linear_attention",
|
| 25 |
+
"full_attention",
|
| 26 |
+
"linear_attention",
|
| 27 |
+
"linear_attention",
|
| 28 |
+
"linear_attention",
|
| 29 |
+
"full_attention",
|
| 30 |
+
"linear_attention",
|
| 31 |
+
"linear_attention",
|
| 32 |
+
"linear_attention",
|
| 33 |
+
"full_attention",
|
| 34 |
+
"linear_attention",
|
| 35 |
+
"linear_attention",
|
| 36 |
+
"linear_attention",
|
| 37 |
+
"full_attention",
|
| 38 |
+
"linear_attention",
|
| 39 |
+
"linear_attention",
|
| 40 |
+
"linear_attention",
|
| 41 |
+
"full_attention"
|
| 42 |
+
],
|
| 43 |
+
"linear_conv_kernel_dim": 4,
|
| 44 |
+
"linear_key_head_dim": 128,
|
| 45 |
+
"linear_num_key_heads": 16,
|
| 46 |
+
"linear_num_value_heads": 16,
|
| 47 |
+
"linear_value_head_dim": 128,
|
| 48 |
+
"mamba_ssm_dtype": "float32",
|
| 49 |
+
"max_position_embeddings": 262144,
|
| 50 |
+
"mlp_only_layers": [],
|
| 51 |
+
"model_type": "qwen3_5_text",
|
| 52 |
+
"mtp_num_hidden_layers": 1,
|
| 53 |
+
"mtp_use_dedicated_embeddings": false,
|
| 54 |
+
"num_attention_heads": 8,
|
| 55 |
+
"num_hidden_layers": 24,
|
| 56 |
+
"num_key_value_heads": 2,
|
| 57 |
+
"pad_token_id": null,
|
| 58 |
+
"partial_rotary_factor": 0.25,
|
| 59 |
+
"rms_norm_eps": 1e-06,
|
| 60 |
+
"rope_parameters": {
|
| 61 |
+
"mrope_interleaved": true,
|
| 62 |
+
"mrope_section": [
|
| 63 |
+
11,
|
| 64 |
+
11,
|
| 65 |
+
10
|
| 66 |
+
],
|
| 67 |
+
"partial_rotary_factor": 0.25,
|
| 68 |
+
"rope_theta": 10000000,
|
| 69 |
+
"rope_type": "default"
|
| 70 |
+
},
|
| 71 |
+
"tie_word_embeddings": true,
|
| 72 |
+
"transformers_version": "5.17.0",
|
| 73 |
+
"use_cache": false,
|
| 74 |
+
"vocab_size": 248320
|
| 75 |
+
}
|
eval_results.json
ADDED
|
@@ -0,0 +1,262 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"format": "jev-style-eval-results-v1",
|
| 3 |
+
"model": "chaoliangUNSW/Jev-Style-2B-Decision-v3",
|
| 4 |
+
"evaluated_format": {
|
| 5 |
+
"engine": "GGUF F16 via jev-score-v2 (llama.cpp 441df11f, Metal), render v2 + block attention",
|
| 6 |
+
"weights": {
|
| 7 |
+
"file": "release_2b/gguf/model-f16.gguf (= Jev-Style-2B-Decision-v3-F16.gguf, tensor data identical)",
|
| 8 |
+
"sha256": "fe18cf4f524e0d59e92a11ee3c012c0b4b03b4e2109e8a35497737e2e55d33dd"
|
| 9 |
+
},
|
| 10 |
+
"temperature": {
|
| 11 |
+
"mode": "global",
|
| 12 |
+
"value": 0.8278650620942867,
|
| 13 |
+
"fitted_on_benchmark_items": false
|
| 14 |
+
},
|
| 15 |
+
"truncation": "never",
|
| 16 |
+
"run_policy": "pre-declared, run once (runtime_v2_dev/PREDECLARED_RELEASE_GATES_2B.md)"
|
| 17 |
+
},
|
| 18 |
+
"jevbench": {
|
| 19 |
+
"benchmark": "jevbench-v1.4.1",
|
| 20 |
+
"repo": "https://github.com/fstandhartinger/jevbench",
|
| 21 |
+
"commit": "24b9b5c1609a7a9e8fa14f49e5985a836c9dc842",
|
| 22 |
+
"split": "public",
|
| 23 |
+
"n_items": 231,
|
| 24 |
+
"correct": 170,
|
| 25 |
+
"public_accuracy": 0.7359307359307359,
|
| 26 |
+
"public_accuracy_wilson_ci95": [
|
| 27 |
+
0.6755578394149232,
|
| 28 |
+
0.7885850787366094
|
| 29 |
+
],
|
| 30 |
+
"tiers": {
|
| 31 |
+
"easy": {
|
| 32 |
+
"n": 48,
|
| 33 |
+
"correct": 48,
|
| 34 |
+
"accuracy": 1.0,
|
| 35 |
+
"ece_top_label_10bin": 0.01884318271512942
|
| 36 |
+
},
|
| 37 |
+
"standard": {
|
| 38 |
+
"n": 72,
|
| 39 |
+
"correct": 69,
|
| 40 |
+
"accuracy": 0.9583333333333334,
|
| 41 |
+
"ece_top_label_10bin": 0.09887602156622965
|
| 42 |
+
},
|
| 43 |
+
"hard": {
|
| 44 |
+
"n": 111,
|
| 45 |
+
"correct": 53,
|
| 46 |
+
"accuracy": 0.4774774774774775,
|
| 47 |
+
"ece_top_label_10bin": 0.15324274416807362
|
| 48 |
+
}
|
| 49 |
+
},
|
| 50 |
+
"hard_tier_ece_public111": 0.15324274416807362,
|
| 51 |
+
"hard_tier_ece_note": "board ECE uses all 220 hard items; ours uses the 111 public hard items (approximate comparison)",
|
| 52 |
+
"unsupported": 0,
|
| 53 |
+
"protocol": {
|
| 54 |
+
"template": "macjev-render-v2-long-options",
|
| 55 |
+
"layout": "sb",
|
| 56 |
+
"block": 2048,
|
| 57 |
+
"total_budget_tokens": 25600,
|
| 58 |
+
"truncation": "never",
|
| 59 |
+
"question_options_cap": null,
|
| 60 |
+
"over_budget_rule": "complete rendering > 25,600 tokens -> status unsupported (InputBudgetError), counted per benchmark and scored as wrong",
|
| 61 |
+
"catalogue_overflow_rule": "question+options over one 2,048-token block -> numbered catalogue in prefix blocks + numbered-option rubric (RendererV2); counted per benchmark",
|
| 62 |
+
"readout": "FP32 h_slot . (W_yes - W_no) at each option slot; p = softmax(scores / T_global)"
|
| 63 |
+
},
|
| 64 |
+
"board": {
|
| 65 |
+
"file": "results/v1.4.1/jevbench-v1.4.1-results.json",
|
| 66 |
+
"sha256": "e6754863056503fe2b010410fc7111df884ac1f9ce4449aa369aab61d98092cd",
|
| 67 |
+
"commit": "24b9b5c1609a7a9e8fa14f49e5985a836c9dc842",
|
| 68 |
+
"revision": "v1.4.1",
|
| 69 |
+
"n_systems": 82,
|
| 70 |
+
"systems_with_higher_public_accuracy": 42,
|
| 71 |
+
"selected_rows": [
|
| 72 |
+
{
|
| 73 |
+
"key": "jev-1.13.0",
|
| 74 |
+
"name": "Jev 1.13.0 (TypeSafe AI)",
|
| 75 |
+
"public_accuracy": 0.8658008658008658,
|
| 76 |
+
"underlying": "closed"
|
| 77 |
+
},
|
| 78 |
+
{
|
| 79 |
+
"key": "raw-qwen3-4b-instruct-2507",
|
| 80 |
+
"name": "Raw Qwen3 4B Instruct 2507 direct logits",
|
| 81 |
+
"public_accuracy": 0.696969696969697,
|
| 82 |
+
"underlying": "Qwen3-4B-Instruct-2507 BF16"
|
| 83 |
+
},
|
| 84 |
+
{
|
| 85 |
+
"key": "decision-2b",
|
| 86 |
+
"name": "Decision 2B (FlyMy.AI, v59)",
|
| 87 |
+
"public_accuracy": 0.7532467532467533,
|
| 88 |
+
"underlying": "openbmb/MiniCPM5-2B with a trained LoRA adapter and pointer head (26.2M trainable parameters)"
|
| 89 |
+
},
|
| 90 |
+
{
|
| 91 |
+
"key": "decider-2b",
|
| 92 |
+
"name": "decider-2b (Mapika)",
|
| 93 |
+
"public_accuracy": 0.70995670995671,
|
| 94 |
+
"underlying": "Qwen3.5-2B-Base with a trained decision readout, 1.9B"
|
| 95 |
+
},
|
| 96 |
+
{
|
| 97 |
+
"key": "laya",
|
| 98 |
+
"name": "Laya (Convai Innovations, ModernBERT-large 421M)",
|
| 99 |
+
"public_accuracy": 0.5844155844155844,
|
| 100 |
+
"underlying": "ModernBERT-large encoder + option-marker decision head, 421M, RLCD-trained"
|
| 101 |
+
},
|
| 102 |
+
{
|
| 103 |
+
"key": "kev-0.6b",
|
| 104 |
+
"name": "kev 0.6B (research preview)",
|
| 105 |
+
"public_accuracy": 0.6666666666666666,
|
| 106 |
+
"underlying": "Qwen3-0.6B-Base + LoRA + learned pointer head; jaredpalmer/kev-0.6b"
|
| 107 |
+
},
|
| 108 |
+
{
|
| 109 |
+
"key": "open-jev-zefan-2b",
|
| 110 |
+
"name": "Open-Jev 2B (Zefan Cai)",
|
| 111 |
+
"public_accuracy": 0.645021645021645,
|
| 112 |
+
"underlying": "Qwen3.5-2B plus rank-8 LoRA and trained scalar decision head"
|
| 113 |
+
}
|
| 114 |
+
]
|
| 115 |
+
},
|
| 116 |
+
"previous_v3_0.8b": {
|
| 117 |
+
"public_accuracy": 0.6406926406926406,
|
| 118 |
+
"correct": 148,
|
| 119 |
+
"source_sha256": "6c1f94220dc8197e504827213b3567e00919740bb705929bed88535812f2a033"
|
| 120 |
+
},
|
| 121 |
+
"source": {
|
| 122 |
+
"file": "runs/macjev/bench_2b/jevbench/gguf_f16/results.json",
|
| 123 |
+
"sha256": "9a467fb4ddcc9a42f9d82ff8f8cf1ce5cfafd51d27b8d4dca2b9c1a681f67a9c"
|
| 124 |
+
}
|
| 125 |
+
},
|
| 126 |
+
"zero_shot": {
|
| 127 |
+
"benchmark": "elcronos zero-shot sets (tweet_topic, fin_topic, daily_dialog)",
|
| 128 |
+
"elcronos_commit": "a1901bc3d520e73936de8d4326545c0cdcf742fb",
|
| 129 |
+
"sets": {
|
| 130 |
+
"tweet_topic": {
|
| 131 |
+
"n": 1693,
|
| 132 |
+
"n_unsupported": 0,
|
| 133 |
+
"n_classes": 6,
|
| 134 |
+
"accuracy": 0.822209096278795,
|
| 135 |
+
"accuracy_ci95": [
|
| 136 |
+
0.8038984051978736,
|
| 137 |
+
0.8399438865918486
|
| 138 |
+
],
|
| 139 |
+
"macro_f1": 0.677897069437572,
|
| 140 |
+
"macro_f1_ci95": [
|
| 141 |
+
0.6455020683998111,
|
| 142 |
+
0.7085891187789015
|
| 143 |
+
],
|
| 144 |
+
"ece15_temperature_calibrated": 0.027919883880813873,
|
| 145 |
+
"ece15_raw_T1": 0.08661185749227743,
|
| 146 |
+
"nll": 0.5282712172517265,
|
| 147 |
+
"brier": 0.262576013332696,
|
| 148 |
+
"majority_class_accuracy": 0.3963378617838157,
|
| 149 |
+
"ci_method": "percentile bootstrap, 10000 resamples, default_rng(0), rows resampled i.i.d.",
|
| 150 |
+
"in_training_pool": false
|
| 151 |
+
},
|
| 152 |
+
"fin_topic": {
|
| 153 |
+
"n": 4117,
|
| 154 |
+
"n_unsupported": 0,
|
| 155 |
+
"n_classes": 20,
|
| 156 |
+
"accuracy": 0.6111246052951178,
|
| 157 |
+
"accuracy_ci95": [
|
| 158 |
+
0.5960650959436483,
|
| 159 |
+
0.6259412193344669
|
| 160 |
+
],
|
| 161 |
+
"macro_f1": 0.5897964463354406,
|
| 162 |
+
"macro_f1_ci95": [
|
| 163 |
+
0.5694510128995812,
|
| 164 |
+
0.6071880523494645
|
| 165 |
+
],
|
| 166 |
+
"ece15_temperature_calibrated": 0.06460657860002232,
|
| 167 |
+
"ece15_raw_T1": 0.03822893519578447,
|
| 168 |
+
"nll": 1.159706614583174,
|
| 169 |
+
"brier": 0.5285731205072254,
|
| 170 |
+
"majority_class_accuracy": 0.2069468059266456,
|
| 171 |
+
"ci_method": "percentile bootstrap, 10000 resamples, default_rng(0), rows resampled i.i.d.",
|
| 172 |
+
"in_training_pool": false
|
| 173 |
+
},
|
| 174 |
+
"daily_dialog": {
|
| 175 |
+
"n": 7740,
|
| 176 |
+
"n_unsupported": 0,
|
| 177 |
+
"n_classes": 7,
|
| 178 |
+
"accuracy": 0.7744186046511627,
|
| 179 |
+
"accuracy_ci95": [
|
| 180 |
+
0.7649870801033591,
|
| 181 |
+
0.7835917312661499
|
| 182 |
+
],
|
| 183 |
+
"macro_f1": 0.3724097968832693,
|
| 184 |
+
"macro_f1_ci95": [
|
| 185 |
+
0.3480292808769088,
|
| 186 |
+
0.3955194464258293
|
| 187 |
+
],
|
| 188 |
+
"ece15_temperature_calibrated": 0.03934861337502408,
|
| 189 |
+
"ece15_raw_T1": 0.027480647988479354,
|
| 190 |
+
"nll": 0.6778540478231467,
|
| 191 |
+
"brier": 0.3382397818519505,
|
| 192 |
+
"majority_class_accuracy": 0.8166666666666667,
|
| 193 |
+
"ci_method": "percentile bootstrap, 10000 resamples, default_rng(0), rows resampled i.i.d.",
|
| 194 |
+
"in_training_pool": false
|
| 195 |
+
}
|
| 196 |
+
},
|
| 197 |
+
"jev_reference": {
|
| 198 |
+
"values": {
|
| 199 |
+
"tweet_topic": {
|
| 200 |
+
"accuracy": 0.7932663910218547,
|
| 201 |
+
"macro_f1": 0.6936,
|
| 202 |
+
"ece15": 0.0631
|
| 203 |
+
},
|
| 204 |
+
"fin_topic": {
|
| 205 |
+
"accuracy": 0.669905270828273,
|
| 206 |
+
"macro_f1": 0.6298,
|
| 207 |
+
"ece15": 0.1664
|
| 208 |
+
},
|
| 209 |
+
"daily_dialog": {
|
| 210 |
+
"accuracy": 0.7099483204134367,
|
| 211 |
+
"macro_f1": 0.3847,
|
| 212 |
+
"ece15": 0.1563
|
| 213 |
+
}
|
| 214 |
+
},
|
| 215 |
+
"source": "https://github.com/elcronos/jev-vs-open-decision-models/blob/a1901bc3d520e73936de8d4326545c0cdcf742fb/results/cross_dataset_summary.json",
|
| 216 |
+
"source_sha256": "5380d3a45395bfdf5340d75e7e18ecdb4b636734295d234839c7113efae608d0",
|
| 217 |
+
"note": "Jev numbers as published by elcronos (raw API probabilities, no temperature); sha256 recorded by the 0.8B adapter, not re-verified locally"
|
| 218 |
+
},
|
| 219 |
+
"previous_v3_0.8b": {
|
| 220 |
+
"tweet_topic": {
|
| 221 |
+
"accuracy": 0.754873006497342,
|
| 222 |
+
"macro_f1": 0.5993905130101003
|
| 223 |
+
},
|
| 224 |
+
"fin_topic": {
|
| 225 |
+
"accuracy": 0.4670876852076755,
|
| 226 |
+
"macro_f1": 0.45174530293977544
|
| 227 |
+
},
|
| 228 |
+
"daily_dialog": {
|
| 229 |
+
"accuracy": 0.32493540051679587,
|
| 230 |
+
"macro_f1": 0.2331496717992918
|
| 231 |
+
}
|
| 232 |
+
},
|
| 233 |
+
"protocol": {
|
| 234 |
+
"template": "macjev-render-v2-long-options",
|
| 235 |
+
"layout": "sb",
|
| 236 |
+
"block": 2048,
|
| 237 |
+
"total_budget_tokens": 25600,
|
| 238 |
+
"truncation": "never",
|
| 239 |
+
"question_options_cap": null,
|
| 240 |
+
"over_budget_rule": "complete rendering > 25,600 tokens -> status unsupported (InputBudgetError), counted per benchmark and scored as wrong",
|
| 241 |
+
"catalogue_overflow_rule": "question+options over one 2,048-token block -> numbered catalogue in prefix blocks + numbered-option rubric (RendererV2); counted per benchmark",
|
| 242 |
+
"readout": "FP32 h_slot . (W_yes - W_no) at each option slot; p = softmax(scores / T_global)"
|
| 243 |
+
},
|
| 244 |
+
"source": {
|
| 245 |
+
"file": "runs/macjev/bench_2b/zeroshot/gguf_f16/metrics.json",
|
| 246 |
+
"sha256": "f80c80ae55678cce974927df0c6a33a5bf5e2ba85e9b14a181e6e5d16bcee3c5"
|
| 247 |
+
},
|
| 248 |
+
"run": {
|
| 249 |
+
"file": "runs/macjev/bench_2b/zeroshot/gguf_f16/run.json",
|
| 250 |
+
"sha256": "0361c42dc3247387b8325aedc872de644b9c0eca80f6e6db9fd68629c27fd389"
|
| 251 |
+
}
|
| 252 |
+
},
|
| 253 |
+
"contamination": {
|
| 254 |
+
"source": {
|
| 255 |
+
"file": "validation/benchmarks/contamination.json",
|
| 256 |
+
"sha256": "87f7f645b950b4cd626ff248b1899578c078db74d4c74bc944b017badc06a8e8",
|
| 257 |
+
"generated_from": "runs/macjev/release_2b/cards/_build/contamination_public.json"
|
| 258 |
+
},
|
| 259 |
+
"note": "JevBench public items vs the whole 2B training pool: state hash, instruction hash, 32+ character text fields, 13-word spans"
|
| 260 |
+
},
|
| 261 |
+
"decision_index": "requested from the maintainer after release (not run by us)"
|
| 262 |
+
}
|
figures/banner.data.json
ADDED
|
@@ -0,0 +1,44 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"left": {
|
| 3 |
+
"big": "73.6% on JevBench",
|
| 4 |
+
"sub": "+9.5 points over our 0.8B v3; Jev 86.6%",
|
| 5 |
+
"tokens": "25,600 tokens per call, no option cap"
|
| 6 |
+
},
|
| 7 |
+
"rows": [
|
| 8 |
+
{
|
| 9 |
+
"label": "Jev 1.13 (API)",
|
| 10 |
+
"accuracy": 0.8658008658008658,
|
| 11 |
+
"pct_1dp": 86.6
|
| 12 |
+
},
|
| 13 |
+
{
|
| 14 |
+
"label": "2B v3 \u00b7 this model",
|
| 15 |
+
"accuracy": 0.7359307359307359,
|
| 16 |
+
"pct_1dp": 73.6
|
| 17 |
+
},
|
| 18 |
+
{
|
| 19 |
+
"label": "decider-2b",
|
| 20 |
+
"accuracy": 0.70995670995671,
|
| 21 |
+
"pct_1dp": 71.0
|
| 22 |
+
},
|
| 23 |
+
{
|
| 24 |
+
"label": "Open-Jev 2B",
|
| 25 |
+
"accuracy": 0.645021645021645,
|
| 26 |
+
"pct_1dp": 64.5
|
| 27 |
+
},
|
| 28 |
+
{
|
| 29 |
+
"label": "0.8B v3",
|
| 30 |
+
"accuracy": 0.6406926406926406,
|
| 31 |
+
"pct_1dp": 64.1
|
| 32 |
+
},
|
| 33 |
+
{
|
| 34 |
+
"label": "Laya",
|
| 35 |
+
"accuracy": 0.5844155844155844,
|
| 36 |
+
"pct_1dp": 58.4
|
| 37 |
+
}
|
| 38 |
+
],
|
| 39 |
+
"shown": "Shown: Qwen3.5-2B-family systems, our 0.8B v3, Laya and Jev \u00b7 42 of 82 board systems score higher than 73.6%",
|
| 40 |
+
"note": "231 public items. 2B v3: self-run with the official harness (GGUF F16), not an official board entry; 95% CI 67.6\u201378.9%, so the lead over decider-2b is inside the CI. Other rows as published on the v1.4.1 board.",
|
| 41 |
+
"sources": [
|
| 42 |
+
"figures/jevbench.data.json"
|
| 43 |
+
]
|
| 44 |
+
}
|
figures/banner.png
ADDED

|
Git LFS Details
|
figures/jevbench.data.json
ADDED
|
@@ -0,0 +1,49 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"chart": "jevbench",
|
| 3 |
+
"metric": "JevBench v1.4.1 public accuracy (231 items)",
|
| 4 |
+
"rows": [
|
| 5 |
+
{
|
| 6 |
+
"label": "Jev-Style 2B v3 (this model)",
|
| 7 |
+
"accuracy": 0.7359307359307359,
|
| 8 |
+
"accuracy_pct_1dp": 73.6,
|
| 9 |
+
"source": "https://huggingface.co/chaoliangUNSW/Jev-Style-2B-Decision-v3/blob/main/validation/benchmarks/jevbench_v1.4.1_results.json :: public_accuracy (170/231)"
|
| 10 |
+
},
|
| 11 |
+
{
|
| 12 |
+
"label": "decider-2b (Mapika, Qwen3.5-2B-Base)",
|
| 13 |
+
"accuracy": 0.70995670995671,
|
| 14 |
+
"accuracy_pct_1dp": 71.0,
|
| 15 |
+
"source": "https://github.com/fstandhartinger/jevbench/blob/v1.4.1/results/v1.4.1/jevbench-v1.4.1-results.json :: systems[decider-2b]"
|
| 16 |
+
},
|
| 17 |
+
{
|
| 18 |
+
"label": "Open-Jev 2B (Zefan Cai, Qwen3.5-2B + LoRA)",
|
| 19 |
+
"accuracy": 0.645021645021645,
|
| 20 |
+
"accuracy_pct_1dp": 64.5,
|
| 21 |
+
"source": "https://github.com/fstandhartinger/jevbench/blob/v1.4.1/results/v1.4.1/jevbench-v1.4.1-results.json :: systems[open-jev-zefan-2b]"
|
| 22 |
+
},
|
| 23 |
+
{
|
| 24 |
+
"label": "Jev-Style 0.8B v3",
|
| 25 |
+
"accuracy": 0.6406926406926406,
|
| 26 |
+
"accuracy_pct_1dp": 64.1,
|
| 27 |
+
"source": "https://huggingface.co/chaoliangUNSW/Jev-Style-0.8B-Decision-v3/blob/main/figures/jevbench.data.json (0.8B v3 card; row Jev-Style 0.8B v3, 148/231)"
|
| 28 |
+
},
|
| 29 |
+
{
|
| 30 |
+
"label": "Laya (ModernBERT-large, 421M)",
|
| 31 |
+
"accuracy": 0.5844155844155844,
|
| 32 |
+
"accuracy_pct_1dp": 58.4,
|
| 33 |
+
"source": "https://github.com/fstandhartinger/jevbench/blob/v1.4.1/results/v1.4.1/jevbench-v1.4.1-results.json :: systems[laya]"
|
| 34 |
+
}
|
| 35 |
+
],
|
| 36 |
+
"reference_line": {
|
| 37 |
+
"label": "Jev 1.13.0",
|
| 38 |
+
"accuracy": 0.8658008658008658,
|
| 39 |
+
"source": "https://github.com/fstandhartinger/jevbench/blob/v1.4.1/results/v1.4.1/jevbench-v1.4.1-results.json :: systems[jev-1.13.0]"
|
| 40 |
+
},
|
| 41 |
+
"ci95_wilson_2b": [
|
| 42 |
+
0.6755578394149232,
|
| 43 |
+
0.7885850787366094
|
| 44 |
+
],
|
| 45 |
+
"board_systems_higher_than_2b": 42,
|
| 46 |
+
"board_systems": 82,
|
| 47 |
+
"board_sha256": "e6754863056503fe2b010410fc7111df884ac1f9ce4449aa369aab61d98092cd",
|
| 48 |
+
"footnote": "JevBench v1.4.1, 231 public items. 2B v3: self-run once with the official harness (commit 24b9b5c), GGUF F16 engine, one global temperature, not an official board entry; 95% CI 67.6-78.9% (Wilson), so its lead over decider-2b (164/231) is inside the CI; training-pool contamination scan: 0 hits. Other rows: public accuracy as published in the board's v1.4.1 results file. Shown: the Qwen3.5-2B-family systems on the board, our 0.8B v3, Laya and Jev; 42 of the 82 board systems score higher than 73.6%."
|
| 49 |
+
}
|
figures/jevbench.png
ADDED

|
Git LFS Details
|
figures/jevbench.svg
ADDED
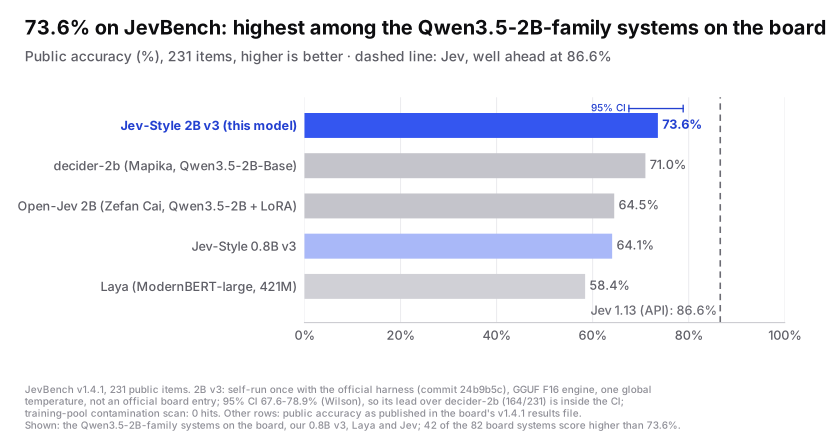
|
figures/zeroshot.data.json
ADDED
|
@@ -0,0 +1,40 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"chart": "zeroshot",
|
| 3 |
+
"metric": "accuracy over every row of the pinned test files",
|
| 4 |
+
"values": {
|
| 5 |
+
"tweet_topic": {
|
| 6 |
+
"2b": 0.822209096278795,
|
| 7 |
+
"2b_ci95": [
|
| 8 |
+
0.8038984051978736,
|
| 9 |
+
0.8399438865918486
|
| 10 |
+
],
|
| 11 |
+
"2b_macro_f1": 0.677897069437572,
|
| 12 |
+
"2b_ece15": 0.027919883880813873,
|
| 13 |
+
"08b": 0.754873006497342,
|
| 14 |
+
"jev": 0.7932663910218547,
|
| 15 |
+
"jev_macro_f1": 0.6936,
|
| 16 |
+
"jev_ece15": 0.0631,
|
| 17 |
+
"n": 1693
|
| 18 |
+
},
|
| 19 |
+
"fin_topic": {
|
| 20 |
+
"2b": 0.6111246052951178,
|
| 21 |
+
"2b_ci95": [
|
| 22 |
+
0.5960650959436483,
|
| 23 |
+
0.6259412193344669
|
| 24 |
+
],
|
| 25 |
+
"2b_macro_f1": 0.5897964463354406,
|
| 26 |
+
"2b_ece15": 0.06460657860002232,
|
| 27 |
+
"08b": 0.4670876852076755,
|
| 28 |
+
"jev": 0.669905270828273,
|
| 29 |
+
"jev_macro_f1": 0.6298,
|
| 30 |
+
"jev_ece15": 0.1664,
|
| 31 |
+
"n": 4117
|
| 32 |
+
}
|
| 33 |
+
},
|
| 34 |
+
"sources": {
|
| 35 |
+
"2b": "https://huggingface.co/chaoliangUNSW/Jev-Style-2B-Decision-v3/blob/main/validation/benchmarks/zeroshot_metrics.json",
|
| 36 |
+
"0.8b": "https://huggingface.co/chaoliangUNSW/Jev-Style-0.8B-Decision-v3/blob/main/figures/zeroshot.json (0.8B v3 card; v3_recomputed: tweet_topic 1278/1693, fin_topic 1923/4117)",
|
| 37 |
+
"jev": "https://github.com/elcronos/jev-vs-open-decision-models/blob/a1901bc3d520e73936de8d4326545c0cdcf742fb/results/cross_dataset_summary.json (as copied in https://huggingface.co/chaoliangUNSW/Jev-Style-2B-Decision-v3/blob/main/validation/benchmarks/zeroshot_metrics.json :: comparison)"
|
| 38 |
+
},
|
| 39 |
+
"footnote": "Zero-shot: none of these test sets is in the 2B or 0.8B training pool; accuracy over every row of the pinned test files (n = 1,693 and 4,117). 2B v3: GGUF F16 engine, one global temperature, run once; tweet_topic 95% CI 80.4-84.0%. Jev (1.13, API): numbers published by the elcronos jev-vs-open-decision-models study (cross_dataset_summary.json @ a1901bc), not re-run by us. Macro-F1 is below Jev on both sets (tweet_topic 67.8% vs 69.4%; fin_topic 59.0% vs 63.0%)."
|
| 40 |
+
}
|
figures/zeroshot.png
ADDED

|
Git LFS Details
|
figures/zeroshot.svg
ADDED

|
generation_config.json
ADDED
|
@@ -0,0 +1,6 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"_from_model_config": true,
|
| 3 |
+
"eos_token_id": 248044,
|
| 4 |
+
"transformers_version": "5.17.0",
|
| 5 |
+
"use_cache": true
|
| 6 |
+
}
|
jev_style_decision.py
ADDED
|
@@ -0,0 +1,806 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Jev-Style-2B-Decision-v3: typed decisions with transformers / PyTorch (CUDA, MPS, CPU).
|
| 2 |
+
|
| 3 |
+
Self-contained runtime for chaoliangUNSW/Jev-Style-2B-Decision-v3 (Apache-2.0). No dependency on any training
|
| 4 |
+
code: rendering (render v2 + attention blocks), block-causal attention, verdict readout and calibration are
|
| 5 |
+
implemented below and reproduce the reference implementation used for evaluation (see release_config.json ->
|
| 6 |
+
"runtime_parity"). Needs torch, transformers (with Qwen3.5 support), tokenizers and numpy.
|
| 7 |
+
|
| 8 |
+
python jev_style_decision.py --state "..." --question "Which option?" --options '["a", "b"]'
|
| 9 |
+
|
| 10 |
+
from jev_style_decision import JevStyleDecision
|
| 11 |
+
m = JevStyleDecision(".") # float32, best available device
|
| 12 |
+
m.decide(state, "Is the task finished?") # true/false question
|
| 13 |
+
m.decide_many(state, [q1, q2, q3]) # one state, computed once
|
| 14 |
+
|
| 15 |
+
Probabilities use the ONE calibrated global temperature of readout_config.json (temperatures.global
|
| 16 |
+
= 0.828) unless temperature=... is given (1.0 = uncalibrated scores). ``category=...`` is accepted
|
| 17 |
+
for compatibility with the 0.8B v3 runtime and ignored: this model has no category temperatures.
|
| 18 |
+
|
| 19 |
+
NOTE: this model uses a different input protocol (render v2 + block attention) from the 0.8B v3
|
| 20 |
+
models; the 0.8B runtimes must not be used with these weights (they would run ordinary causal
|
| 21 |
+
attention over a different layout and give wrong answers).
|
| 22 |
+
"""
|
| 23 |
+
# ----------------------------------------------------------------------------------------------
|
| 24 |
+
# Shared core (byte-identical in jev_style_decision.py, jev_style_decision_gguf.py and jev_style_decision_mlx.py):
|
| 25 |
+
# input rendering (v2), verdict readout, calibration, budgets, errors, manifest check, CLI/JSONL.
|
| 26 |
+
#
|
| 27 |
+
# Input layout ("macjev-render-v2-long-options", layout "sb"; token segments are encoded separately
|
| 28 |
+
# and concatenated, so slot positions are exact):
|
| 29 |
+
#
|
| 30 |
+
# state prefix State:\n<state>\n\n
|
| 31 |
+
# short form Question [<type>]: <question>\nOptions:\n
|
| 32 |
+
# (question + - <option 1> ->\n ... - <option K> ->\n
|
| 33 |
+
# options + slots <= 2,048 tokens)
|
| 34 |
+
# overflow form Question [<type>]: <question>\nOptions:\n
|
| 35 |
+
# (otherwise) Option 1: <option 1>\n ... Option K: <option K>\n (the catalogue)
|
| 36 |
+
# Judge each numbered option in the complete catalogue above:\n
|
| 37 |
+
# Option 1 ->\n ... Option K ->\n (the rubric)
|
| 38 |
+
#
|
| 39 |
+
# Attention blocks ([start, stop) token ranges): the state is cut into consecutive 2,048-token
|
| 40 |
+
# blocks; the short form is one block; in the overflow form the catalogue and the rubric are each cut
|
| 41 |
+
# into 2,048-token blocks. In the 6 full-attention layers every block attends to all earlier tokens
|
| 42 |
+
# and to itself with NO causal mask inside the block (block-causal); the Gated-DeltaNet layers are
|
| 43 |
+
# ordinary recurrent layers. A backend must compute exactly these blocks (never merged, never re-split).
|
| 44 |
+
#
|
| 45 |
+
# Score of option k = logit(" yes") - logit(" no") at its " ->" slot = h_slot . (W_yes - W_no) in
|
| 46 |
+
# float32 (final normed hidden state, tied embedding rows). Probabilities = softmax(scores / T) in
|
| 47 |
+
# canonical option order. T = the ONE global temperature of readout_config.json
|
| 48 |
+
# (temperatures.global, fitted on 2,000 calibration rows) unless temperature=... overrides it
|
| 49 |
+
# (1.0 = uncalibrated scores). This model has no category / group temperatures and no separate
|
| 50 |
+
# question/options budget, so the 0.8B v3 runtime's --category and --head-max options do not exist here.
|
| 51 |
+
#
|
| 52 |
+
# Budget: the complete input (state + question + options + readout) <= 25,600 tokens. Larger inputs
|
| 53 |
+
# raise InputBudgetError; nothing is ever truncated. Text inside the state, question and options is
|
| 54 |
+
# tokenised with special tokens disabled, so e.g. "<|im_end|>" in user text can never act as a
|
| 55 |
+
# control token. A non-finite score (NaN / inf) raises NonFiniteScoreError: no probabilities are made.
|
| 56 |
+
# ----------------------------------------------------------------------------------------------
|
| 57 |
+
import argparse
|
| 58 |
+
import hashlib
|
| 59 |
+
import json
|
| 60 |
+
import math
|
| 61 |
+
import sys
|
| 62 |
+
from pathlib import Path
|
| 63 |
+
|
| 64 |
+
import numpy as np
|
| 65 |
+
|
| 66 |
+
MODEL_NAME = "Jev-Style-2B-Decision-v3"
|
| 67 |
+
TEMPLATE_VERSION = "macjev-render-v2-long-options"
|
| 68 |
+
READOUT_FORMAT = "macjev-readout-v2"
|
| 69 |
+
LAYOUT = "sb"
|
| 70 |
+
BLOCK = 2048 # attention block size (a processing unit, not a content limit)
|
| 71 |
+
CONTEXT_LIMIT = 25_600 # state + question + options + readout, all included
|
| 72 |
+
QTYPES = ("choice", "score", "noul")
|
| 73 |
+
JSONL_GROUP_MAX = 256 # consecutive JSONL rows with one state scored in one backend call
|
| 74 |
+
HERE = Path(__file__).resolve().parent
|
| 75 |
+
|
| 76 |
+
|
| 77 |
+
class InputBudgetError(ValueError):
|
| 78 |
+
"""The rendered input exceeds the token budget. Nothing was truncated."""
|
| 79 |
+
|
| 80 |
+
|
| 81 |
+
class QuestionError(ValueError):
|
| 82 |
+
"""The question/options are malformed."""
|
| 83 |
+
|
| 84 |
+
|
| 85 |
+
class NonFiniteScoreError(FloatingPointError):
|
| 86 |
+
"""The model produced a non-finite decision score (NaN or inf). No probabilities are returned."""
|
| 87 |
+
|
| 88 |
+
|
| 89 |
+
# -- questions ------------------------------------------------------------------------------------
|
| 90 |
+
def option_names(question):
|
| 91 |
+
"""Canonical option identifiers, in the order the probabilities are returned."""
|
| 92 |
+
if not isinstance(question, dict):
|
| 93 |
+
raise QuestionError("question must be a dict {'t', 'ins', 'crit'}")
|
| 94 |
+
t, crit = question.get("t"), question.get("crit")
|
| 95 |
+
if not isinstance(question.get("ins"), str) or not question["ins"].strip():
|
| 96 |
+
raise QuestionError("question text ('ins') must be a non-empty string")
|
| 97 |
+
if t == "choice":
|
| 98 |
+
if not isinstance(crit, dict) or not crit:
|
| 99 |
+
raise QuestionError("choice needs a non-empty dict {option name: description or None}")
|
| 100 |
+
return [str(k) for k in crit]
|
| 101 |
+
if t == "score":
|
| 102 |
+
if not isinstance(crit, list) or not 2 <= len(crit) <= 10:
|
| 103 |
+
raise QuestionError("score needs a list of 2..10 level descriptions")
|
| 104 |
+
return [str(i) for i in range(len(crit))]
|
| 105 |
+
if t == "noul":
|
| 106 |
+
if crit is not None and not isinstance(crit, dict):
|
| 107 |
+
raise QuestionError("noul criteria must be None or {'false': ..., 'true': ...}")
|
| 108 |
+
return ["false", "true"]
|
| 109 |
+
raise QuestionError(f"unknown question type {t!r} (expected one of {QTYPES})")
|
| 110 |
+
|
| 111 |
+
|
| 112 |
+
def make_question(question, options=None, qtype=None):
|
| 113 |
+
"""Build a typed question.
|
| 114 |
+
|
| 115 |
+
* ``question`` already a dict {"t", "ins", "crit"}: validated and returned.
|
| 116 |
+
* ``qtype="choice"`` (default when ``options`` is given): ``options`` = {name: description or None}
|
| 117 |
+
or a list of names.
|
| 118 |
+
* ``qtype="score"``: ``options`` = list of 2..10 level descriptions (level 0 first).
|
| 119 |
+
* ``qtype="noul"`` (default when no options): a true/false statement; ``options`` may be
|
| 120 |
+
{"false": "...", "true": "..."} to describe the two outcomes.
|
| 121 |
+
"""
|
| 122 |
+
if isinstance(question, dict):
|
| 123 |
+
q = dict(question)
|
| 124 |
+
else:
|
| 125 |
+
if qtype is None:
|
| 126 |
+
qtype = "choice" if options is not None else "noul"
|
| 127 |
+
if qtype == "choice":
|
| 128 |
+
if isinstance(options, (list, tuple)):
|
| 129 |
+
if len(set(map(str, options))) != len(options):
|
| 130 |
+
raise QuestionError("duplicate option names")
|
| 131 |
+
crit = {str(o): None for o in options}
|
| 132 |
+
else:
|
| 133 |
+
crit = options
|
| 134 |
+
elif qtype == "score":
|
| 135 |
+
crit = list(options) if options is not None else None
|
| 136 |
+
else:
|
| 137 |
+
crit = options
|
| 138 |
+
q = {"t": qtype, "ins": question, "crit": crit}
|
| 139 |
+
option_names(q)
|
| 140 |
+
return q
|
| 141 |
+
|
| 142 |
+
|
| 143 |
+
def serialize_state(state):
|
| 144 |
+
"""Strings pass through unchanged; any other JSON value is serialised (ensure_ascii=False)."""
|
| 145 |
+
if isinstance(state, str):
|
| 146 |
+
return state
|
| 147 |
+
return json.dumps(state, ensure_ascii=False)
|
| 148 |
+
|
| 149 |
+
|
| 150 |
+
def _criterion(value):
|
| 151 |
+
if isinstance(value, str):
|
| 152 |
+
return value
|
| 153 |
+
return json.dumps(value, ensure_ascii=False, separators=(", ", ": "), default=str)
|
| 154 |
+
|
| 155 |
+
|
| 156 |
+
def render_options(question):
|
| 157 |
+
t, crit = question["t"], question.get("crit")
|
| 158 |
+
if t == "choice":
|
| 159 |
+
return [k if v is None or v == "" else f"{k}: {_criterion(v)}" for k, v in crit.items()]
|
| 160 |
+
if t == "score":
|
| 161 |
+
return [f"level {i}: {_criterion(c)}" for i, c in enumerate(crit)]
|
| 162 |
+
crit = crit or {}
|
| 163 |
+
false_c, true_c = crit.get("false"), crit.get("true")
|
| 164 |
+
return ["false: " + (_criterion(false_c) if false_c not in (None, "") else "no, the statement does not hold"),
|
| 165 |
+
"true: " + (_criterion(true_c) if true_c not in (None, "") else "yes, the statement holds")]
|
| 166 |
+
|
| 167 |
+
|
| 168 |
+
# -- tokenizer + renderer -----------------------------------------------------------------------
|
| 169 |
+
class TextEncoder:
|
| 170 |
+
"""HF ``tokenizers`` tokenizer.json; no BOS/EOS, special tokens in text are split (never control tokens)."""
|
| 171 |
+
|
| 172 |
+
def __init__(self, tokenizer_json):
|
| 173 |
+
from tokenizers import Tokenizer
|
| 174 |
+
self.tk = Tokenizer.from_file(str(tokenizer_json))
|
| 175 |
+
self.tk.encode_special_tokens = True
|
| 176 |
+
|
| 177 |
+
def __call__(self, text):
|
| 178 |
+
return self.tk.encode(text, add_special_tokens=False).ids
|
| 179 |
+
|
| 180 |
+
def id_to_token(self, i):
|
| 181 |
+
return self.tk.id_to_token(int(i))
|
| 182 |
+
|
| 183 |
+
def vocab_size(self):
|
| 184 |
+
return self.tk.get_vocab_size(with_added_tokens=True)
|
| 185 |
+
|
| 186 |
+
|
| 187 |
+
def _blocks(start, stop):
|
| 188 |
+
return [(s, min(s + BLOCK, stop)) for s in range(start, stop, BLOCK)]
|
| 189 |
+
|
| 190 |
+
|
| 191 |
+
class Rendered:
|
| 192 |
+
"""One rendered question: token ids, the verdict slots (one per option, canonical order), the
|
| 193 |
+
attention blocks ([start, stop) pairs tiling [0, len(ids))) and the state prefix length."""
|
| 194 |
+
__slots__ = ("ids", "prefix_len", "slots", "blocks", "names", "qtype", "catalogue_overflow")
|
| 195 |
+
|
| 196 |
+
def __init__(self, ids, prefix_len, slots, blocks, names, qtype, catalogue_overflow):
|
| 197 |
+
self.ids, self.prefix_len, self.slots, self.blocks = ids, prefix_len, slots, blocks
|
| 198 |
+
self.names, self.qtype, self.catalogue_overflow = names, qtype, catalogue_overflow
|
| 199 |
+
|
| 200 |
+
@property
|
| 201 |
+
def state_blocks(self):
|
| 202 |
+
return [b for b in self.blocks if b[1] <= self.prefix_len]
|
| 203 |
+
|
| 204 |
+
@property
|
| 205 |
+
def question_blocks(self):
|
| 206 |
+
return [b for b in self.blocks if b[0] >= self.prefix_len]
|
| 207 |
+
|
| 208 |
+
@property
|
| 209 |
+
def input_tokens(self):
|
| 210 |
+
return len(self.ids)
|
| 211 |
+
|
| 212 |
+
@property
|
| 213 |
+
def head_tokens(self):
|
| 214 |
+
"""question + options + readout tokens (everything after the state prefix)"""
|
| 215 |
+
return len(self.ids) - self.prefix_len
|
| 216 |
+
|
| 217 |
+
|
| 218 |
+
class Renderer:
|
| 219 |
+
def __init__(self, encode, readout_cfg, max_len=CONTEXT_LIMIT):
|
| 220 |
+
want = {"format": READOUT_FORMAT, "template": TEMPLATE_VERSION, "layout": LAYOUT, "readout": "verdict",
|
| 221 |
+
"block_size": BLOCK, "total_context_limit": CONTEXT_LIMIT}
|
| 222 |
+
bad = {k: readout_cfg.get(k) for k, v in want.items() if readout_cfg.get(k) != v}
|
| 223 |
+
if bad:
|
| 224 |
+
raise ValueError(f"readout_config.json does not describe this runtime's protocol {want}; got {bad}")
|
| 225 |
+
if not 0 < int(max_len) <= CONTEXT_LIMIT:
|
| 226 |
+
raise ValueError(f"max_len must be in 1..{CONTEXT_LIMIT}")
|
| 227 |
+
self.enc, self.max_len = encode, int(max_len)
|
| 228 |
+
self.head_max = self.max_len # no separate question/options cap (field kept for the 0.8B / jev-style API)
|
| 229 |
+
st = readout_cfg["slot_tokens"]
|
| 230 |
+
self.yes, self.no, arrow = int(st["yes"]["id"]), int(st["no"]["id"]), int(st["verdict_slot"]["id"])
|
| 231 |
+
for text, want_id in ((" yes", self.yes), (" no", self.no), (" ->", arrow)):
|
| 232 |
+
got = self.enc(text)
|
| 233 |
+
if got != [want_id]:
|
| 234 |
+
raise ValueError(f"tokenizer mismatch: {text!r} -> {got}, readout_config expects [{want_id}]")
|
| 235 |
+
self.arrow = [arrow]
|
| 236 |
+
self.newline = self.enc("\n")
|
| 237 |
+
self.dash = self.enc("- ")
|
| 238 |
+
self.rubric_head = self.enc("Judge each numbered option in the complete catalogue above:\n")
|
| 239 |
+
self._numbered = {}
|
| 240 |
+
|
| 241 |
+
def _option_label(self, pos, catalogue):
|
| 242 |
+
key = (pos, catalogue)
|
| 243 |
+
if key not in self._numbered:
|
| 244 |
+
self._numbered[key] = self.enc(f"Option {pos + 1}: " if catalogue else f"Option {pos + 1}")
|
| 245 |
+
return self._numbered[key]
|
| 246 |
+
|
| 247 |
+
def prefix_ids(self, state):
|
| 248 |
+
return self.enc("State:\n") + self.enc(serialize_state(state)) + self.enc("\n\n")
|
| 249 |
+
|
| 250 |
+
def pieces(self, state, question, prefix=None):
|
| 251 |
+
"""Tokenised segments of one question (``prefix``: already tokenised state, to tokenise it once)."""
|
| 252 |
+
names = option_names(question)
|
| 253 |
+
return {"prefix": self.prefix_ids(state) if prefix is None else list(prefix),
|
| 254 |
+
"head": self.enc(f"Question [{question['t']}]: {question['ins']}\nOptions:\n"),
|
| 255 |
+
"opts": [self.enc(o) for o in render_options(question)], "names": names, "qtype": question["t"]}
|
| 256 |
+
|
| 257 |
+
def assemble(self, pieces, max_len=None):
|
| 258 |
+
maximum = self.max_len if max_len is None else min(self.max_len, int(max_len))
|
| 259 |
+
prefix, head, opts = list(pieces["prefix"]), list(pieces["head"]), pieces["opts"]
|
| 260 |
+
k = len(opts)
|
| 261 |
+
if k < 1:
|
| 262 |
+
raise QuestionError("at least one option is required")
|
| 263 |
+
short, rel = list(head), []
|
| 264 |
+
for o in opts:
|
| 265 |
+
short += self.dash + list(o) + self.arrow
|
| 266 |
+
rel.append(len(short) - 1)
|
| 267 |
+
short += self.newline
|
| 268 |
+
overflow = len(short) > BLOCK
|
| 269 |
+
if not overflow:
|
| 270 |
+
ids = prefix + short
|
| 271 |
+
slots = [len(prefix) + s for s in rel]
|
| 272 |
+
blocks = _blocks(0, len(prefix)) + [(len(prefix), len(ids))]
|
| 273 |
+
else:
|
| 274 |
+
catalogue = list(head)
|
| 275 |
+
for pos, o in enumerate(opts):
|
| 276 |
+
catalogue += self._option_label(pos, True) + list(o) + self.newline
|
| 277 |
+
doc_end = len(prefix) + len(catalogue)
|
| 278 |
+
rubric, rel = list(self.rubric_head), []
|
| 279 |
+
for pos in range(k):
|
| 280 |
+
rubric += self._option_label(pos, False) + self.arrow
|
| 281 |
+
rel.append(len(rubric) - 1)
|
| 282 |
+
rubric += self.newline
|
| 283 |
+
ids = prefix + catalogue + rubric
|
| 284 |
+
slots = [doc_end + s for s in rel]
|
| 285 |
+
blocks = _blocks(0, len(prefix)) + _blocks(len(prefix), doc_end) + _blocks(doc_end, len(ids))
|
| 286 |
+
if len(ids) > maximum:
|
| 287 |
+
raise InputBudgetError(f"the complete input needs {len(ids)} tokens (state {len(prefix)} + question/"
|
| 288 |
+
f"options/readout {len(ids) - len(prefix)}); the limit is {maximum} tokens (model "
|
| 289 |
+
f"maximum {CONTEXT_LIMIT}). Nothing was truncated: shorten the state, the "
|
| 290 |
+
f"question or the options.")
|
| 291 |
+
return Rendered(ids, len(prefix), slots, blocks, list(pieces["names"]), pieces["qtype"], overflow)
|
| 292 |
+
|
| 293 |
+
def render(self, state, question, max_len=None, prefix=None):
|
| 294 |
+
return self.assemble(self.pieces(state, question, prefix), max_len)
|
| 295 |
+
|
| 296 |
+
|
| 297 |
+
# -- calibration ----------------------------------------------------------------------------------
|
| 298 |
+
def check_temperature(t):
|
| 299 |
+
try:
|
| 300 |
+
t = float(t)
|
| 301 |
+
except (TypeError, ValueError):
|
| 302 |
+
raise ValueError(f"temperature must be a number, got {t!r}") from None
|
| 303 |
+
if not (math.isfinite(t) and t > 0):
|
| 304 |
+
raise ValueError(f"temperature must be finite and > 0, got {t!r}")
|
| 305 |
+
return t
|
| 306 |
+
|
| 307 |
+
|
| 308 |
+
def softmax_probabilities(scores, temperature):
|
| 309 |
+
"""softmax(scores / T) in float64 (the reference computation)."""
|
| 310 |
+
z = np.asarray(scores, float) / float(temperature)
|
| 311 |
+
z = np.exp(z - z.max())
|
| 312 |
+
return z / z.sum()
|
| 313 |
+
|
| 314 |
+
|
| 315 |
+
def concentration(p):
|
| 316 |
+
k = len(p)
|
| 317 |
+
if k < 2:
|
| 318 |
+
return 1.0
|
| 319 |
+
ent = -(p * np.log(np.clip(p, 1e-12, 1.0))).sum()
|
| 320 |
+
return float(np.clip(1.0 - ent / math.log(k), 0.0, 1.0))
|
| 321 |
+
|
| 322 |
+
|
| 323 |
+
def _sha256(path):
|
| 324 |
+
h = hashlib.sha256()
|
| 325 |
+
with open(path, "rb") as f:
|
| 326 |
+
for b in iter(lambda: f.read(1 << 22), b""):
|
| 327 |
+
h.update(b)
|
| 328 |
+
return h.hexdigest()
|
| 329 |
+
|
| 330 |
+
|
| 331 |
+
NOT_VERIFIED = ("README.md", "eval_results.json") # documentation / records: in manifest.json, not checked
|
| 332 |
+
NOT_VERIFIED_DIRS = ("assets/", "figures/", "validation/")
|
| 333 |
+
|
| 334 |
+
|
| 335 |
+
def verify_manifest(model_dir, only=None):
|
| 336 |
+
"""Re-hash the files listed in manifest.json (all, or those whose path starts with one of ``only``).
|
| 337 |
+
Documentation and evaluation records (README.md, eval_results.json, assets/, figures/, validation/) are
|
| 338 |
+
recorded in the manifest but not checked here (not even when named in ``only``), so a card edit never
|
| 339 |
+
makes the runtime refuse to load and a download without them still verifies."""
|
| 340 |
+
model_dir = Path(model_dir)
|
| 341 |
+
man = json.loads((model_dir / "manifest.json").read_text())
|
| 342 |
+
bad, missing, checked = [], [], 0
|
| 343 |
+
for name, rec in man["files"].items():
|
| 344 |
+
if name in NOT_VERIFIED or name.startswith(NOT_VERIFIED_DIRS):
|
| 345 |
+
continue
|
| 346 |
+
if only and not any(name == o or name.startswith(o.rstrip("/") + "/") for o in only):
|
| 347 |
+
continue
|
| 348 |
+
p = model_dir / name
|
| 349 |
+
if not p.exists():
|
| 350 |
+
missing.append(name)
|
| 351 |
+
elif _sha256(p) != rec["sha256"]:
|
| 352 |
+
bad.append(name)
|
| 353 |
+
checked += 1
|
| 354 |
+
return {"ok": not bad and not missing, "checked": checked, "bad": bad, "missing": missing}
|
| 355 |
+
|
| 356 |
+
|
| 357 |
+
class DecisionBase:
|
| 358 |
+
"""Backend-independent part. A backend implements ``_scores_many(rendered) -> list of list[float]``:
|
| 359 |
+
``rendered`` is a non-empty list of Rendered that all share ONE state (identical prefix ids and
|
| 360 |
+
state blocks); it returns the raw float32 scores of every slot of every Rendered (slot order =
|
| 361 |
+
canonical option order), computing the state blocks once per call. Backends keep the most recent
|
| 362 |
+
state for the next call (exact prefix match only), so consecutive calls about the same state (e.g.
|
| 363 |
+
JSONL rows read from stdin) reuse it."""
|
| 364 |
+
backend = "base"
|
| 365 |
+
|
| 366 |
+
def _setup(self, model_dir, tokenizer_json, max_len=CONTEXT_LIMIT, temperature=None):
|
| 367 |
+
self.model_dir = Path(model_dir)
|
| 368 |
+
self.readout_config = json.loads((self.model_dir / "readout_config.json").read_text())
|
| 369 |
+
self.calibrated_temperature = check_temperature(self.readout_config["temperatures"]["global"])
|
| 370 |
+
self.default_temperature = self.calibrated_temperature if temperature is None else check_temperature(temperature)
|
| 371 |
+
self.encode = TextEncoder(tokenizer_json)
|
| 372 |
+
self.renderer = Renderer(self.encode, self.readout_config, max_len=max_len)
|
| 373 |
+
|
| 374 |
+
def _scores_many(self, rendered):
|
| 375 |
+
raise NotImplementedError
|
| 376 |
+
|
| 377 |
+
def close(self):
|
| 378 |
+
pass
|
| 379 |
+
|
| 380 |
+
def __enter__(self):
|
| 381 |
+
return self
|
| 382 |
+
|
| 383 |
+
def __exit__(self, *exc):
|
| 384 |
+
self.close()
|
| 385 |
+
|
| 386 |
+
def _score_all(self, rendered):
|
| 387 |
+
"""Raw scores (lists of floats, canonical order) for Rendered sharing one state; one backend call."""
|
| 388 |
+
if not rendered:
|
| 389 |
+
return []
|
| 390 |
+
p = rendered[0].prefix_len
|
| 391 |
+
prefix, sblocks = rendered[0].ids[:p], rendered[0].state_blocks
|
| 392 |
+
for r in rendered[1:]:
|
| 393 |
+
if r.prefix_len != p or r.ids[:p] != prefix or r.state_blocks != sblocks:
|
| 394 |
+
raise ValueError("all questions of one backend call must share the same state")
|
| 395 |
+
scores = self._scores_many(rendered)
|
| 396 |
+
if len(scores) != len(rendered) or any(len(s) != len(r.slots) for s, r in zip(scores, rendered)):
|
| 397 |
+
raise RuntimeError("backend returned a wrong number of scores")
|
| 398 |
+
return [[float(x) for x in s] for s in scores]
|
| 399 |
+
|
| 400 |
+
def score_pieces(self, pieces_list, max_len=None):
|
| 401 |
+
"""Raw scores for pre-tokenised questions sharing one state: dicts {"prefix", "head", "opts",
|
| 402 |
+
"names", "qtype"} of token ids (see Renderer.pieces). For parity checks; no temperature."""
|
| 403 |
+
return self._score_all([self.renderer.assemble(p, max_len) for p in pieces_list])
|
| 404 |
+
|
| 405 |
+
def _result(self, r, scores, temperature):
|
| 406 |
+
t = self.default_temperature if temperature is None else check_temperature(temperature)
|
| 407 |
+
bad = [n for n, x in zip(r.names, scores) if not math.isfinite(x)]
|
| 408 |
+
if bad:
|
| 409 |
+
raise NonFiniteScoreError(f"non-finite decision scores for option(s) {bad} ({len(r.ids)} input tokens); "
|
| 410 |
+
f"refusing to return probabilities. Check the weights file / engine build.")
|
| 411 |
+
p = softmax_probabilities(scores, t)
|
| 412 |
+
if not np.all(np.isfinite(p)):
|
| 413 |
+
raise NonFiniteScoreError("non-finite probabilities")
|
| 414 |
+
i = int(p.argmax())
|
| 415 |
+
return {"answer": r.names[i], "probabilities": dict(zip(r.names, p.tolist())),
|
| 416 |
+
"scores": dict(zip(r.names, scores)), "temperature": t, "top_probability": float(p[i]),
|
| 417 |
+
"entropy_concentration": concentration(p), "input_tokens": len(r.ids),
|
| 418 |
+
"state_tokens": r.prefix_len, "head_tokens": r.head_tokens, "blocks": len(r.blocks),
|
| 419 |
+
"catalogue_overflow": r.catalogue_overflow, "model": MODEL_NAME, "backend": self.backend}
|
| 420 |
+
|
| 421 |
+
def decide(self, state, question, options=None, qtype=None, category=None, temperature=None, head_max=None,
|
| 422 |
+
max_len=None):
|
| 423 |
+
"""Score one question about ``state``.
|
| 424 |
+
|
| 425 |
+
Returns {"answer", "probabilities" {option: p}, "scores" {option: logit(yes)-logit(no)},
|
| 426 |
+
"temperature", "top_probability", "entropy_concentration", "input_tokens", "state_tokens",
|
| 427 |
+
"head_tokens", "blocks", "catalogue_overflow", "model", "backend"}. ``temperature`` overrides
|
| 428 |
+
the calibrated global temperature (1.0 = uncalibrated scores). ``category`` and ``head_max`` are
|
| 429 |
+
accepted for compatibility with the 0.8B v3 runtime and the jev-style package, and ignored: this
|
| 430 |
+
model has one global temperature and no separate question/options budget. Raises InputBudgetError
|
| 431 |
+
(never truncates), QuestionError or NonFiniteScoreError."""
|
| 432 |
+
q = make_question(question, options, qtype)
|
| 433 |
+
r = self.renderer.render(state, q, max_len)
|
| 434 |
+
return self._result(r, self._score_all([r])[0], temperature)
|
| 435 |
+
|
| 436 |
+
def score_many(self, state, questions, category=None, temperature=None, head_max=None, max_len=None):
|
| 437 |
+
"""Several questions about ONE state: the state is tokenised and computed once and reused for
|
| 438 |
+
every question (one backend call). ``questions``: dicts {"t","ins","crit"} (or anything
|
| 439 |
+
make_question accepts). Results in order, identical to calling decide() per question. All
|
| 440 |
+
questions are rendered and budget-checked before any scoring. ``category`` / ``head_max``: see
|
| 441 |
+
decide() (accepted and ignored)."""
|
| 442 |
+
qs = [make_question(q) for q in questions]
|
| 443 |
+
if not qs:
|
| 444 |
+
return []
|
| 445 |
+
prefix = self.renderer.prefix_ids(state)
|
| 446 |
+
rs = [self.renderer.render(state, q, max_len, prefix=prefix) for q in qs]
|
| 447 |
+
return [self._result(r, sc, temperature) for r, sc in zip(rs, self._score_all(rs))]
|
| 448 |
+
|
| 449 |
+
decide_many = score_many
|
| 450 |
+
|
| 451 |
+
|
| 452 |
+
def base_arg_parser(description):
|
| 453 |
+
ap = argparse.ArgumentParser(description=description)
|
| 454 |
+
ap.add_argument("--model-dir", default=str(HERE), help="folder with the weights and readout_config.json")
|
| 455 |
+
ap.add_argument("--state", help="state as plain text")
|
| 456 |
+
ap.add_argument("--state-json", help="state as a JSON value")
|
| 457 |
+
ap.add_argument("--question", help="question text (or a JSON question {'t','ins','crit'})")
|
| 458 |
+
ap.add_argument("--options", help="JSON: {name: description} or [names] (choice); [levels] (score)")
|
| 459 |
+
ap.add_argument("--qtype", choices=QTYPES)
|
| 460 |
+
ap.add_argument("--temperature", type=float,
|
| 461 |
+
help="override the calibrated global temperature of readout_config.json (1.0 = raw scores)")
|
| 462 |
+
ap.add_argument("--max-len", type=int, default=CONTEXT_LIMIT,
|
| 463 |
+
help=f"total token budget (state + question + options + readout), at most {CONTEXT_LIMIT}")
|
| 464 |
+
ap.add_argument("--jsonl", help="batch mode: input JSON lines {id?, state, question, options?, qtype?, "
|
| 465 |
+
"temperature?} ('-' = stdin); one JSON result per line on stdout. Consecutive "
|
| 466 |
+
"rows with an identical state share one state computation")
|
| 467 |
+
ap.add_argument("--verify", action="store_true", help="check sha256 of the files in manifest.json first")
|
| 468 |
+
return ap
|
| 469 |
+
|
| 470 |
+
|
| 471 |
+
def _jsonl_groups(src, streaming):
|
| 472 |
+
"""(line number, record or error text) grouped into runs of consecutive rows with one state. From a
|
| 473 |
+
file up to JSONL_GROUP_MAX rows are grouped; from stdin every row is its own group (answered at once;
|
| 474 |
+
the backend's kept state still makes consecutive identical states cheap)."""
|
| 475 |
+
group, key = [], None
|
| 476 |
+
for n, line in enumerate(src):
|
| 477 |
+
if not line.strip():
|
| 478 |
+
continue
|
| 479 |
+
try:
|
| 480 |
+
rec = json.loads(line)
|
| 481 |
+
if not isinstance(rec, dict):
|
| 482 |
+
raise ValueError("a JSONL row must be a JSON object")
|
| 483 |
+
k = serialize_state(rec.get("state", ""))
|
| 484 |
+
except ValueError as e:
|
| 485 |
+
if group:
|
| 486 |
+
yield group
|
| 487 |
+
group, key = [], None
|
| 488 |
+
yield [(n, f"{type(e).__name__}: {e}")]
|
| 489 |
+
continue
|
| 490 |
+
if group and (k != key or len(group) >= JSONL_GROUP_MAX):
|
| 491 |
+
yield group
|
| 492 |
+
group = []
|
| 493 |
+
group.append((n, rec))
|
| 494 |
+
key = k
|
| 495 |
+
if streaming:
|
| 496 |
+
yield group
|
| 497 |
+
group, key = [], None
|
| 498 |
+
if group:
|
| 499 |
+
yield group
|
| 500 |
+
|
| 501 |
+
|
| 502 |
+
def _run_group(engine, group, args):
|
| 503 |
+
"""Score one group of JSONL rows sharing a state. Returns (output rows, non-finite count)."""
|
| 504 |
+
out, todo = {}, []
|
| 505 |
+
prefix = None
|
| 506 |
+
for n, rec in group:
|
| 507 |
+
if isinstance(rec, str):
|
| 508 |
+
out[n] = {"id": n, "error": rec}
|
| 509 |
+
continue
|
| 510 |
+
rid = rec.get("id", n)
|
| 511 |
+
try:
|
| 512 |
+
if "question" not in rec:
|
| 513 |
+
raise QuestionError("row has no 'question'")
|
| 514 |
+
q = make_question(rec["question"], options=rec.get("options"), qtype=rec.get("qtype"))
|
| 515 |
+
t = rec.get("temperature", args.temperature)
|
| 516 |
+
t = None if t is None else check_temperature(t)
|
| 517 |
+
if prefix is None:
|
| 518 |
+
prefix = engine.renderer.prefix_ids(rec.get("state", ""))
|
| 519 |
+
todo.append((n, rid, engine.renderer.render(rec.get("state", ""), q, prefix=prefix), t))
|
| 520 |
+
except (InputBudgetError, QuestionError, ValueError, TypeError, AttributeError) as e:
|
| 521 |
+
out[n] = {"id": rid, "error": f"{type(e).__name__}: {e}"}
|
| 522 |
+
nonfinite = 0
|
| 523 |
+
if todo:
|
| 524 |
+
scores = engine._score_all([r for _, _, r, _ in todo])
|
| 525 |
+
for (n, rid, r, t), sc in zip(todo, scores):
|
| 526 |
+
try:
|
| 527 |
+
out[n] = {"id": rid, **engine._result(r, sc, t)}
|
| 528 |
+
except NonFiniteScoreError as e:
|
| 529 |
+
nonfinite += 1
|
| 530 |
+
print(f"ERROR row {rid}: NonFiniteScoreError: {e}", file=sys.stderr, flush=True)
|
| 531 |
+
out[n] = {"id": rid, "error": f"NonFiniteScoreError: {e}"}
|
| 532 |
+
return [out[n] for n, _ in group], nonfinite
|
| 533 |
+
|
| 534 |
+
|
| 535 |
+
def run_cli(args, engine):
|
| 536 |
+
"""Exit status: 0 = ok (JSONL rows with input errors carry an "error" field), 2 = input error
|
| 537 |
+
(single question), 3 = at least one non-finite score (refused, see stderr)."""
|
| 538 |
+
if args.jsonl:
|
| 539 |
+
streaming = args.jsonl == "-"
|
| 540 |
+
src = sys.stdin if streaming else open(args.jsonl, encoding="utf-8")
|
| 541 |
+
nonfinite = 0
|
| 542 |
+
try:
|
| 543 |
+
for group in _jsonl_groups(src, streaming):
|
| 544 |
+
rows, bad = _run_group(engine, group, args)
|
| 545 |
+
nonfinite += bad
|
| 546 |
+
for row in rows:
|
| 547 |
+
print(json.dumps(row, ensure_ascii=False), flush=True)
|
| 548 |
+
finally:
|
| 549 |
+
if not streaming:
|
| 550 |
+
src.close()
|
| 551 |
+
return 3 if nonfinite else 0
|
| 552 |
+
if args.question is None:
|
| 553 |
+
raise SystemExit("--question (or --jsonl) is required")
|
| 554 |
+
try:
|
| 555 |
+
state = json.loads(args.state_json) if args.state_json is not None else (args.state or "")
|
| 556 |
+
question = args.question
|
| 557 |
+
if question.lstrip().startswith("{"):
|
| 558 |
+
try: # a JSON question {'t','ins','crit'}; else plain text
|
| 559 |
+
parsed = json.loads(question)
|
| 560 |
+
except ValueError:
|
| 561 |
+
parsed = None
|
| 562 |
+
if isinstance(parsed, dict):
|
| 563 |
+
question = parsed
|
| 564 |
+
options = json.loads(args.options) if args.options else None
|
| 565 |
+
res = engine.decide(state, question, options=options, qtype=args.qtype, temperature=args.temperature)
|
| 566 |
+
except (InputBudgetError, QuestionError, ValueError, TypeError) as e: # NonFiniteScoreError is not a ValueError
|
| 567 |
+
print(f"error: {type(e).__name__}: {e}", file=sys.stderr)
|
| 568 |
+
return 2
|
| 569 |
+
except NonFiniteScoreError as e:
|
| 570 |
+
print(f"ERROR: NonFiniteScoreError: {e}", file=sys.stderr)
|
| 571 |
+
return 3
|
| 572 |
+
print(json.dumps(res, ensure_ascii=False, indent=2))
|
| 573 |
+
return 0
|
| 574 |
+
# ---------------------------------------------------------------------------- end of shared core
|
| 575 |
+
|
| 576 |
+
|
| 577 |
+
# ------------------------------------------------------------------------------ PyTorch backend
|
| 578 |
+
# How the block-causal attention is computed exactly:
|
| 579 |
+
#
|
| 580 |
+
# The input is fed to the model ONE renderer block per forward call, in order, with a transformers
|
| 581 |
+
# cache: when block [a, b) runs, the cache holds tokens [0, a). In the 6 full-attention layers the
|
| 582 |
+
# queries are the block's own tokens and the keys/values are the cached [0, a) plus [a, b); attention
|
| 583 |
+
# over all of them WITHOUT any mask is then exactly "every block attends to all earlier tokens and to
|
| 584 |
+
# itself, no causal mask inside the block". The Gated-DeltaNet layers continue their conv / recurrent
|
| 585 |
+
# state from the cache, i.e. they run as ordinary causal recurrent layers over the whole input.
|
| 586 |
+
#
|
| 587 |
+
# State reuse: the state blocks are computed once per call (and kept for the next call when the next
|
| 588 |
+
# state is identical); every question continues from its own copy of that cache, so a question never
|
| 589 |
+
# sees another question's tokens. Because nothing after the state can influence the state blocks
|
| 590 |
+
# (block-causal), this equals recomputing state + question for each question.
|
| 591 |
+
import copy
|
| 592 |
+
|
| 593 |
+
ATTN_NAME = "jev_style_block_sdpa"
|
| 594 |
+
MPS_ATTN_CHUNK = 1024 # MPS: queries per SDPA call (row-wise identical, bounds the score matrix)
|
| 595 |
+
_ATTN_REGISTERED = False
|
| 596 |
+
|
| 597 |
+
|
| 598 |
+
def _block_sdpa(module, query, key, value, attention_mask=None, dropout=0.0, scaling=None, **kwargs):
|
| 599 |
+
"""Attention of ONE renderer block (see above): no mask; queries = the block, keys = all tokens so far.
|
| 600 |
+
|
| 601 |
+
The backend announces each call's geometry on the attention module (``jev_expect`` = (block length,
|
| 602 |
+
tokens so far)). Any other use, e.g. an ordinary whole-sequence ``model(...)`` call, is refused, so
|
| 603 |
+
this function can never silently act as non-causal attention over a wrong span."""
|
| 604 |
+
import torch
|
| 605 |
+
import torch.nn.functional as F
|
| 606 |
+
q_len, kv_len = query.shape[2], key.shape[2]
|
| 607 |
+
expect = getattr(module, "jev_expect", None)
|
| 608 |
+
if expect is None or tuple(expect) != (q_len, kv_len):
|
| 609 |
+
raise RuntimeError(f"block attention called with {q_len} queries / {kv_len} keys, expected {expect}: this "
|
| 610 |
+
f"model must be run through JevStyleDecision (one renderer block per forward call)")
|
| 611 |
+
if attention_mask is not None:
|
| 612 |
+
raise RuntimeError("block attention does not take an attention mask")
|
| 613 |
+
if query.shape[1] % key.shape[1]:
|
| 614 |
+
raise ValueError("invalid grouped-query head counts")
|
| 615 |
+
rep = query.shape[1] // key.shape[1]
|
| 616 |
+
if rep > 1:
|
| 617 |
+
key, value = key.repeat_interleave(rep, 1), value.repeat_interleave(rep, 1)
|
| 618 |
+
chunk = getattr(module, "jev_attn_chunk", None)
|
| 619 |
+
if not chunk or q_len <= chunk:
|
| 620 |
+
out = F.scaled_dot_product_attention(query, key, value, is_causal=False, scale=scaling)
|
| 621 |
+
else:
|
| 622 |
+
out = torch.cat([F.scaled_dot_product_attention(query[:, :, s:s + chunk], key, value, is_causal=False,
|
| 623 |
+
scale=scaling) for s in range(0, q_len, chunk)], dim=2)
|
| 624 |
+
return out.transpose(1, 2).contiguous(), None
|
| 625 |
+
|
| 626 |
+
|
| 627 |
+
def _no_mask(*args, **kwargs):
|
| 628 |
+
return None
|
| 629 |
+
|
| 630 |
+
|
| 631 |
+
def _register_attention():
|
| 632 |
+
global _ATTN_REGISTERED
|
| 633 |
+
if not _ATTN_REGISTERED:
|
| 634 |
+
from transformers import AttentionInterface
|
| 635 |
+
from transformers.masking_utils import AttentionMaskInterface
|
| 636 |
+
AttentionInterface.register(ATTN_NAME, _block_sdpa)
|
| 637 |
+
AttentionMaskInterface.register(ATTN_NAME, _no_mask)
|
| 638 |
+
_ATTN_REGISTERED = True
|
| 639 |
+
return ATTN_NAME
|
| 640 |
+
|
| 641 |
+
|
| 642 |
+
def _pick_device(torch, device):
|
| 643 |
+
if device is None:
|
| 644 |
+
if torch.cuda.is_available():
|
| 645 |
+
return "cuda"
|
| 646 |
+
mps = getattr(torch.backends, "mps", None)
|
| 647 |
+
return "mps" if mps is not None and mps.is_available() else "cpu"
|
| 648 |
+
kind = torch.device(device).type
|
| 649 |
+
if kind == "cuda" and not torch.cuda.is_available():
|
| 650 |
+
raise RuntimeError("device='cuda' was requested but CUDA is not available (no implicit fallback)")
|
| 651 |
+
if kind == "mps" and not (getattr(torch.backends, "mps", None) and torch.backends.mps.is_available()):
|
| 652 |
+
raise RuntimeError("device='mps' was requested but MPS is not available (no implicit fallback)")
|
| 653 |
+
if kind not in ("cuda", "mps", "cpu"):
|
| 654 |
+
raise ValueError(f"unsupported device {device!r} (cuda, mps or cpu)")
|
| 655 |
+
return str(device)
|
| 656 |
+
|
| 657 |
+
|
| 658 |
+
class JevStyleDecision(DecisionBase):
|
| 659 |
+
"""Transformers / PyTorch runtime (CUDA, Apple MPS or CPU).
|
| 660 |
+
|
| 661 |
+
>>> m = JevStyleDecision(".") # float32 on the best available device
|
| 662 |
+
>>> m.decide({"messages": ["Refund still missing after 3 weeks"]},
|
| 663 |
+
... "Which team should handle this ticket?",
|
| 664 |
+
... options={"billing": "payments, refunds", "tech": "bugs, crashes", "sales": "pricing, plans"})
|
| 665 |
+
|
| 666 |
+
device: None = cuda > mps > cpu; "cuda" / "mps" / "cpu" explicitly (never an implicit fallback).
|
| 667 |
+
dtype: "float32" (default; the parity-tested setting on every device) or "bfloat16" (CUDA only).
|
| 668 |
+
The readout h_slot . (w_yes - w_no) is always computed in float32.
|
| 669 |
+
temperature: None = the calibrated global temperature of readout_config.json.
|
| 670 |
+
threads: torch CPU threads (torch.set_num_threads; process-wide).
|
| 671 |
+
attn_chunk: queries per SDPA call inside a block (default: 1,024 on MPS, whole block elsewhere).
|
| 672 |
+
keep_state: keep the last state's cache for the next call with the identical state (exact match).
|
| 673 |
+
category: accepted for compatibility with the 0.8B v3 runtime and ignored (one global temperature).
|
| 674 |
+
|
| 675 |
+
decide(state, question, options=None, qtype=None, category=None, temperature=None, head_max=None, max_len=None)
|
| 676 |
+
decide_many(state, questions, category=None, temperature=None, head_max=None, max_len=None) (= score_many)
|
| 677 |
+
(the same signatures as the 0.8B v3 runtime; category and head_max are accepted and ignored)
|
| 678 |
+
Every result has "answer", "probabilities" (by option name; true/false questions: "false" / "true"),
|
| 679 |
+
"scores", "temperature", "top_probability", "entropy_concentration", "input_tokens",
|
| 680 |
+
"state_tokens", "head_tokens", "blocks", "catalogue_overflow", "model", "backend".
|
| 681 |
+
"""
|
| 682 |
+
backend = "torch"
|
| 683 |
+
|
| 684 |
+
def __init__(self, model_dir=HERE, device=None, dtype="float32", *, max_len=CONTEXT_LIMIT, temperature=None,
|
| 685 |
+
threads=None, attn_chunk=None, keep_state=True, verify=False, category=None):
|
| 686 |
+
import torch
|
| 687 |
+
self.torch = torch
|
| 688 |
+
model_dir = Path(model_dir)
|
| 689 |
+
if verify:
|
| 690 |
+
res = verify_manifest(model_dir)
|
| 691 |
+
if not res["ok"]:
|
| 692 |
+
raise RuntimeError(f"integrity check failed: {res}")
|
| 693 |
+
self.verified = res
|
| 694 |
+
self._setup(model_dir, model_dir / "tokenizer.json", max_len, temperature)
|
| 695 |
+
if threads:
|
| 696 |
+
torch.set_num_threads(int(threads))
|
| 697 |
+
self.device = _pick_device(torch, device)
|
| 698 |
+
kind = torch.device(self.device).type
|
| 699 |
+
dt = getattr(torch, dtype) if isinstance(dtype, str) else dtype
|
| 700 |
+
if dt not in (torch.float32, torch.bfloat16):
|
| 701 |
+
raise ValueError(f"dtype must be float32 or bfloat16, got {dtype!r}")
|
| 702 |
+
if dt == torch.bfloat16 and kind != "cuda":
|
| 703 |
+
raise ValueError("bfloat16 is supported on CUDA only; use float32 on MPS / CPU")
|
| 704 |
+
cfg = json.loads((model_dir / "config.json").read_text())
|
| 705 |
+
layer_types = cfg.get("layer_types") or []
|
| 706 |
+
if cfg.get("model_type") not in ("qwen3_5_text", "qwen3_5") or "full_attention" not in layer_types:
|
| 707 |
+
raise ValueError(f"{model_dir / 'config.json'} is not the text-only Qwen3.5 checkpoint of {MODEL_NAME}")
|
| 708 |
+
try:
|
| 709 |
+
from transformers.models.qwen3_5.modeling_qwen3_5 import Qwen3_5ForCausalLM as cls
|
| 710 |
+
except ImportError as e:
|
| 711 |
+
raise ImportError("this model needs a transformers version with Qwen3.5 support "
|
| 712 |
+
"(transformers.models.qwen3_5)") from e
|
| 713 |
+
from transformers import DynamicCache
|
| 714 |
+
self._cache_cls = DynamicCache
|
| 715 |
+
name = _register_attention()
|
| 716 |
+
try:
|
| 717 |
+
model = cls.from_pretrained(str(model_dir), dtype=dt, attn_implementation=name)
|
| 718 |
+
except TypeError: # transformers 4.x keyword
|
| 719 |
+
model = cls.from_pretrained(str(model_dir), torch_dtype=dt, attn_implementation=name)
|
| 720 |
+
if getattr(model.config, "_attn_implementation", None) != name:
|
| 721 |
+
model.set_attn_implementation(name)
|
| 722 |
+
self.model = model.to(self.device).eval()
|
| 723 |
+
self.dtype = dt
|
| 724 |
+
types = list(self.model.config.layer_types)
|
| 725 |
+
self._attn = [layer.self_attn for layer, t in zip(self.model.model.layers, types) if t == "full_attention"]
|
| 726 |
+
if len(self._attn) != types.count("full_attention") or not self._attn:
|
| 727 |
+
raise RuntimeError("could not find the full-attention layers")
|
| 728 |
+
chunk = attn_chunk if attn_chunk is not None else (MPS_ATTN_CHUNK if kind == "mps" else None)
|
| 729 |
+
for m in self._attn:
|
| 730 |
+
m.jev_expect, m.jev_attn_chunk = None, (int(chunk) if chunk else None)
|
| 731 |
+
w = self.model.get_output_embeddings().weight
|
| 732 |
+
if not getattr(self.model.config, "tie_word_embeddings", False) and w is not self.model.get_input_embeddings().weight:
|
| 733 |
+
raise ValueError("expected tied input/output embeddings")
|
| 734 |
+
self.direction = (w[self.renderer.yes].float() - w[self.renderer.no].float()).detach()
|
| 735 |
+
self.keep_state = bool(keep_state)
|
| 736 |
+
self._kept = None # (state token ids, cache after the state blocks)
|
| 737 |
+
|
| 738 |
+
# -- model calls
|
| 739 |
+
def _block(self, ids, start, stop, cache):
|
| 740 |
+
"""Run renderer block [start, stop) on top of ``cache`` (which holds tokens [0, start)); returns
|
| 741 |
+
the final normed hidden states of the block's tokens."""
|
| 742 |
+
torch = self.torch
|
| 743 |
+
x = torch.tensor([ids[start:stop]], dtype=torch.long, device=self.device)
|
| 744 |
+
pos = torch.arange(start, stop, dtype=torch.long, device=self.device)[None]
|
| 745 |
+
for m in self._attn:
|
| 746 |
+
m.jev_expect = (stop - start, stop)
|
| 747 |
+
try:
|
| 748 |
+
out = self.model.model(input_ids=x, position_ids=pos, past_key_values=cache, use_cache=True)
|
| 749 |
+
finally:
|
| 750 |
+
for m in self._attn:
|
| 751 |
+
m.jev_expect = None
|
| 752 |
+
return out.last_hidden_state[0]
|
| 753 |
+
|
| 754 |
+
def _state_cache(self, r):
|
| 755 |
+
key = r.ids[:r.prefix_len]
|
| 756 |
+
if self._kept is not None and self._kept[0] == key:
|
| 757 |
+
return self._kept[1]
|
| 758 |
+
self._kept = None # free the old state first
|
| 759 |
+
cache = self._cache_cls(config=self.model.config)
|
| 760 |
+
for s, e in r.state_blocks:
|
| 761 |
+
self._block(r.ids, s, e, cache)
|
| 762 |
+
if self.keep_state:
|
| 763 |
+
self._kept = (key, cache)
|
| 764 |
+
return cache
|
| 765 |
+
|
| 766 |
+
def _scores_many(self, rendered):
|
| 767 |
+
torch = self.torch
|
| 768 |
+
out = []
|
| 769 |
+
with torch.inference_mode():
|
| 770 |
+
for r in rendered:
|
| 771 |
+
if r.state_blocks + r.question_blocks != r.blocks or r.slots != sorted(r.slots):
|
| 772 |
+
raise RuntimeError("renderer blocks do not tile the input")
|
| 773 |
+
base = self._state_cache(rendered[0])
|
| 774 |
+
for r in rendered:
|
| 775 |
+
cache = copy.deepcopy(base) # the shared state cache itself is never modified
|
| 776 |
+
hs = []
|
| 777 |
+
for s, e in r.question_blocks:
|
| 778 |
+
h = self._block(r.ids, s, e, cache)
|
| 779 |
+
rel = [p - s for p in r.slots if s <= p < e]
|
| 780 |
+
if rel:
|
| 781 |
+
hs.append(h[torch.tensor(rel, device=h.device)])
|
| 782 |
+
del cache
|
| 783 |
+
h = torch.cat(hs).float()
|
| 784 |
+
if h.shape[0] != len(r.slots):
|
| 785 |
+
raise RuntimeError("slot count mismatch")
|
| 786 |
+
out.append((h @ self.direction).cpu().tolist())
|
| 787 |
+
return out
|
| 788 |
+
|
| 789 |
+
def close(self):
|
| 790 |
+
self._kept = None
|
| 791 |
+
|
| 792 |
+
|
| 793 |
+
def main(argv=None):
|
| 794 |
+
ap = base_arg_parser(f"{MODEL_NAME}: typed decisions with transformers / PyTorch")
|
| 795 |
+
ap.add_argument("--device", choices=["cuda", "mps", "cpu"], help="default: cuda > mps > cpu")
|
| 796 |
+
ap.add_argument("--dtype", default="float32", choices=["float32", "bfloat16"],
|
| 797 |
+
help="bfloat16 on CUDA only; the readout is float32 either way")
|
| 798 |
+
ap.add_argument("--threads", type=int, help="torch CPU threads")
|
| 799 |
+
args = ap.parse_args(argv)
|
| 800 |
+
engine = JevStyleDecision(args.model_dir, device=args.device, dtype=args.dtype, max_len=args.max_len,
|
| 801 |
+
threads=args.threads, verify=args.verify)
|
| 802 |
+
return run_cli(args, engine)
|
| 803 |
+
|
| 804 |
+
|
| 805 |
+
if __name__ == "__main__":
|
| 806 |
+
raise SystemExit(main())
|
manifest.json
ADDED
|
@@ -0,0 +1,170 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"format": "jev-style-manifest-v1",
|
| 3 |
+
"repo": "chaoliangUNSW/Jev-Style-2B-Decision-v3",
|
| 4 |
+
"created_unix": 1790476262.791195,
|
| 5 |
+
"files": {
|
| 6 |
+
"LICENSE": {
|
| 7 |
+
"sha256": "bbedc3fda3305820b977265f01b8619d87570a6739de3a5582c3464840f1e57a",
|
| 8 |
+
"bytes": 11544
|
| 9 |
+
},
|
| 10 |
+
"NOTICE": {
|
| 11 |
+
"sha256": "937fb1f4a643708c77dbe48cd483cb0998874feadbb107f1ca536a3ec654a0c4",
|
| 12 |
+
"bytes": 2406
|
| 13 |
+
},
|
| 14 |
+
"README.md": {
|
| 15 |
+
"sha256": "b3d39950f74a583ec0e4e89afd779c99ccfe93da8f4d0d453fd423e84b561f6a",
|
| 16 |
+
"bytes": 25217
|
| 17 |
+
},
|
| 18 |
+
"chat_template.jinja": {
|
| 19 |
+
"sha256": "273d8e0e683b885071fb17e08d71e5f2a5ddfb5309756181681de4f5a1822d80",
|
| 20 |
+
"bytes": 7755
|
| 21 |
+
},
|
| 22 |
+
"config.json": {
|
| 23 |
+
"sha256": "88bf86c270d616198909ed1eefef8d8c21ac1fa13f62e947f20f8e1ebd02c211",
|
| 24 |
+
"bytes": 1791
|
| 25 |
+
},
|
| 26 |
+
"eval_results.json": {
|
| 27 |
+
"sha256": "8cecf3a823603300d6fb2c94b4d87239a6c7e88b31c89f381e1fdb581a0a36fb",
|
| 28 |
+
"bytes": 9901
|
| 29 |
+
},
|
| 30 |
+
"figures/banner.data.json": {
|
| 31 |
+
"sha256": "397cbfb222986f8d59a65143f2fec5a11170385c661a86c5e54d890a24d7d89e",
|
| 32 |
+
"bytes": 1109
|
| 33 |
+
},
|
| 34 |
+
"figures/banner.png": {
|
| 35 |
+
"sha256": "2623e4afad36239aaa007c34350d6f2fbacb33430ffd3c36ce2f7ee7db849b47",
|
| 36 |
+
"bytes": 447467
|
| 37 |
+
},
|
| 38 |
+
"figures/jevbench.data.json": {
|
| 39 |
+
"sha256": "508994afea8d8b1bc33e25c675621a9b3b55b01f900daa688c240c8356dffe3b",
|
| 40 |
+
"bytes": 2387
|
| 41 |
+
},
|
| 42 |
+
"figures/jevbench.png": {
|
| 43 |
+
"sha256": "c8542dba9ecc1bd2a4ea3bda844cbc3fbd661c40d6eb9254098b279a92a74ce8",
|
| 44 |
+
"bytes": 167843
|
| 45 |
+
},
|
| 46 |
+
"figures/jevbench.svg": {
|
| 47 |
+
"sha256": "13193f8d636ad5e6685cbc58863f27bced87c0ead94c252917839c7c6eed837e",
|
| 48 |
+
"bytes": 12280
|
| 49 |
+
},
|
| 50 |
+
"figures/zeroshot.data.json": {
|
| 51 |
+
"sha256": "3ad81c3dc926c988db5c339eec4991c2e2cce46faafb89db99cc47d6d8737538",
|
| 52 |
+
"bytes": 1841
|
| 53 |
+
},
|
| 54 |
+
"figures/zeroshot.png": {
|
| 55 |
+
"sha256": "d51f9a7bc46b88d8dcf5ba46f15d479c781302ca531208ff0838106da8aae755",
|
| 56 |
+
"bytes": 137714
|
| 57 |
+
},
|
| 58 |
+
"figures/zeroshot.svg": {
|
| 59 |
+
"sha256": "f3234ba4715b0d87e081ec9fc52c0b409010612f54db7aa39307a9eda3b7545f",
|
| 60 |
+
"bytes": 13874
|
| 61 |
+
},
|
| 62 |
+
"generation_config.json": {
|
| 63 |
+
"sha256": "62153eb6c69f2e1f426beaa8002b7186437e949c7588167085df14e10e9c0a73",
|
| 64 |
+
"bytes": 116
|
| 65 |
+
},
|
| 66 |
+
"jev_style_decision.py": {
|
| 67 |
+
"sha256": "5ecba24cdfff4f0e043c2ea48c9c7f514907c6804f265906e21dec0f1b20dbd6",
|
| 68 |
+
"bytes": 41304
|
| 69 |
+
},
|
| 70 |
+
"model-00001-of-00002.safetensors": {
|
| 71 |
+
"sha256": "df592f869cb1232226d31491b783bfa9406ffb3c795eae44a3b7452e1044a8fb",
|
| 72 |
+
"bytes": 1999936744
|
| 73 |
+
},
|
| 74 |
+
"model-00002-of-00002.safetensors": {
|
| 75 |
+
"sha256": "c6ff77a32a8cf36767e51c1282bb345a873db6509847f6c75baadd8fb17eeb70",
|
| 76 |
+
"bytes": 1763755048
|
| 77 |
+
},
|
| 78 |
+
"model.safetensors.index.json": {
|
| 79 |
+
"sha256": "f60ba6dc3c3cfb32baf76fbb5f851b1a35616ba04543c35640aa973bd3947c52",
|
| 80 |
+
"bytes": 31529
|
| 81 |
+
},
|
| 82 |
+
"readout_config.json": {
|
| 83 |
+
"sha256": "4af0d578c9126d4eb1a545b6e576e0a49a967243a47b8e99e3555f081fdaa1de",
|
| 84 |
+
"bytes": 2031
|
| 85 |
+
},
|
| 86 |
+
"release_config.json": {
|
| 87 |
+
"sha256": "1c4c6917b43773fdaa7eb5ccfe4c2ed790f0c2fba6bcc2977e20701940ebb03e",
|
| 88 |
+
"bytes": 30558
|
| 89 |
+
},
|
| 90 |
+
"requirements.txt": {
|
| 91 |
+
"sha256": "d653173d284907c39856430cf264acf73b24d3350a04b0d31da8739e7f801651",
|
| 92 |
+
"bytes": 272
|
| 93 |
+
},
|
| 94 |
+
"tokenizer.json": {
|
| 95 |
+
"sha256": "06b9509352d2af50381ab2247e083b80d32d5c0aba91c272ca9ff729b6a0e523",
|
| 96 |
+
"bytes": 19989325
|
| 97 |
+
},
|
| 98 |
+
"tokenizer_config.json": {
|
| 99 |
+
"sha256": "66e427c470fe580fe8c7b5725d857af23d8417e37fae62667ec698306a19987b",
|
| 100 |
+
"bytes": 1124
|
| 101 |
+
},
|
| 102 |
+
"validation/SOURCES.json": {
|
| 103 |
+
"sha256": "5e35ae9eac7fc9e081693806bbf30b0bcd701d36f0807c3d29cad54c26ed2518",
|
| 104 |
+
"bytes": 4161
|
| 105 |
+
},
|
| 106 |
+
"validation/benchmarks/contamination.json": {
|
| 107 |
+
"sha256": "87f7f645b950b4cd626ff248b1899578c078db74d4c74bc944b017badc06a8e8",
|
| 108 |
+
"bytes": 3345
|
| 109 |
+
},
|
| 110 |
+
"validation/benchmarks/jevbench_v1.4.1_results.json": {
|
| 111 |
+
"sha256": "9a467fb4ddcc9a42f9d82ff8f8cf1ce5cfafd51d27b8d4dca2b9c1a681f67a9c",
|
| 112 |
+
"bytes": 15051
|
| 113 |
+
},
|
| 114 |
+
"validation/benchmarks/jevbench_v1.4.1_results.md": {
|
| 115 |
+
"sha256": "824ffa6ae920595e9277c9d6c41770bf6b2d9fc2e71ff7de9afe6ee635b69ae8",
|
| 116 |
+
"bytes": 1587
|
| 117 |
+
},
|
| 118 |
+
"validation/benchmarks/zeroshot_comparison.md": {
|
| 119 |
+
"sha256": "34828fa9375ea717c866b1e749d3fe902f0b52303c807289a769934760f6dad0",
|
| 120 |
+
"bytes": 1174
|
| 121 |
+
},
|
| 122 |
+
"validation/benchmarks/zeroshot_metrics.json": {
|
| 123 |
+
"sha256": "479ddbaa101f843487471500061906e78ce28f9af09c65eaadc3cee4b5ebdb4a",
|
| 124 |
+
"bytes": 8732
|
| 125 |
+
},
|
| 126 |
+
"validation/data_sources.json": {
|
| 127 |
+
"sha256": "415fa9dcb893dc71d97d76652fbf03600a72681c15f7248ef46035d85ea56d7c",
|
| 128 |
+
"bytes": 16696
|
| 129 |
+
},
|
| 130 |
+
"validation/latency_2b.json": {
|
| 131 |
+
"sha256": "458d00e0c81b3165072b8547278e6039b9ae0d45d54b7421008ef24c1d24ca3d",
|
| 132 |
+
"bytes": 40294
|
| 133 |
+
},
|
| 134 |
+
"validation/parity/PREDECLARED_RELEASE_GATES_2B.md": {
|
| 135 |
+
"sha256": "783aec77300779582911cdc57c71cf8b101b0cd5ca040073f7e1fa3ac20af08e",
|
| 136 |
+
"bytes": 2619
|
| 137 |
+
},
|
| 138 |
+
"validation/parity/cross_format_dp.json": {
|
| 139 |
+
"sha256": "c7332df0f02244416b01e49ecb037c76d4bf2643a2b42505ff1dfe896879e533",
|
| 140 |
+
"bytes": 1550
|
| 141 |
+
},
|
| 142 |
+
"validation/runtime/parity_cpu_fp32_t4.log": {
|
| 143 |
+
"sha256": "616618ec2b61c472137ea4cb418dc0b79019b699e7fa6f044bf06c166cb970ba",
|
| 144 |
+
"bytes": 4486
|
| 145 |
+
},
|
| 146 |
+
"validation/runtime/parity_mps_fp32_long.log": {
|
| 147 |
+
"sha256": "04e40ead1c8694fb3bbda9714074701777ea48d8d2cb3489df738ad902f351d8",
|
| 148 |
+
"bytes": 1008
|
| 149 |
+
},
|
| 150 |
+
"validation/runtime/reverify_main.json": {
|
| 151 |
+
"sha256": "3b8e573deb626385ce469b289e8e753d60c499ce21efcdeefd20a8e44b4d6c0a",
|
| 152 |
+
"bytes": 968
|
| 153 |
+
},
|
| 154 |
+
"validation/runtime/reverify_main_mps_long.log": {
|
| 155 |
+
"sha256": "98720ecc5f12d24f7a12add39a7cf332f12c300c8177eed2665a3077d0e0f0b1",
|
| 156 |
+
"bytes": 1007
|
| 157 |
+
},
|
| 158 |
+
"validation/runtime/v_jevstyle_e2e.json": {
|
| 159 |
+
"sha256": "812cbee4d6c8b0af5cd81b6b5aaa8b24f55c07c0ec934cc81c8f61c634e734a6",
|
| 160 |
+
"bytes": 1622
|
| 161 |
+
},
|
| 162 |
+
"validation/runtime/v_tiny_and_render.json": {
|
| 163 |
+
"sha256": "d3ff75211cfac2f26f0f7763ee937dee8d1e01eceae43e37f16f9ec5d0bb02bf",
|
| 164 |
+
"bytes": 406
|
| 165 |
+
}
|
| 166 |
+
},
|
| 167 |
+
"readme_hashed": true,
|
| 168 |
+
"readme_placeholder": false,
|
| 169 |
+
"note": "manifest.json hashes every file of the repo except itself, README.md, figures/ and validation/ included. The runtime --verify check (jev_style_decision.py) skips the documentation and evaluation records (README.md, figures/, assets/, validation/, eval_results.json) and checks every other listed file."
|
| 170 |
+
}
|
model-00001-of-00002.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:df592f869cb1232226d31491b783bfa9406ffb3c795eae44a3b7452e1044a8fb
|
| 3 |
+
size 1999936744
|
model-00002-of-00002.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:c6ff77a32a8cf36767e51c1282bb345a873db6509847f6c75baadd8fb17eeb70
|
| 3 |
+
size 1763755048
|
model.safetensors.index.json
ADDED
|
@@ -0,0 +1,328 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"metadata": {
|
| 3 |
+
"total_parameters": 1881825088,
|
| 4 |
+
"total_size": 3763650176
|
| 5 |
+
},
|
| 6 |
+
"weight_map": {
|
| 7 |
+
"model.language_model.embed_tokens.weight": "model-00001-of-00002.safetensors",
|
| 8 |
+
"model.language_model.layers.0.input_layernorm.weight": "model-00001-of-00002.safetensors",
|
| 9 |
+
"model.language_model.layers.0.linear_attn.A_log": "model-00001-of-00002.safetensors",
|
| 10 |
+
"model.language_model.layers.0.linear_attn.conv1d.weight": "model-00001-of-00002.safetensors",
|
| 11 |
+
"model.language_model.layers.0.linear_attn.dt_bias": "model-00001-of-00002.safetensors",
|
| 12 |
+
"model.language_model.layers.0.linear_attn.in_proj_a.weight": "model-00001-of-00002.safetensors",
|
| 13 |
+
"model.language_model.layers.0.linear_attn.in_proj_b.weight": "model-00001-of-00002.safetensors",
|
| 14 |
+
"model.language_model.layers.0.linear_attn.in_proj_qkv.weight": "model-00001-of-00002.safetensors",
|
| 15 |
+
"model.language_model.layers.0.linear_attn.in_proj_z.weight": "model-00001-of-00002.safetensors",
|
| 16 |
+
"model.language_model.layers.0.linear_attn.norm.weight": "model-00001-of-00002.safetensors",
|
| 17 |
+
"model.language_model.layers.0.linear_attn.out_proj.weight": "model-00001-of-00002.safetensors",
|
| 18 |
+
"model.language_model.layers.0.mlp.down_proj.weight": "model-00001-of-00002.safetensors",
|
| 19 |
+
"model.language_model.layers.0.mlp.gate_proj.weight": "model-00001-of-00002.safetensors",
|
| 20 |
+
"model.language_model.layers.0.mlp.up_proj.weight": "model-00001-of-00002.safetensors",
|
| 21 |
+
"model.language_model.layers.0.post_attention_layernorm.weight": "model-00001-of-00002.safetensors",
|
| 22 |
+
"model.language_model.layers.1.input_layernorm.weight": "model-00001-of-00002.safetensors",
|
| 23 |
+
"model.language_model.layers.1.linear_attn.A_log": "model-00001-of-00002.safetensors",
|
| 24 |
+
"model.language_model.layers.1.linear_attn.conv1d.weight": "model-00001-of-00002.safetensors",
|
| 25 |
+
"model.language_model.layers.1.linear_attn.dt_bias": "model-00001-of-00002.safetensors",
|
| 26 |
+
"model.language_model.layers.1.linear_attn.in_proj_a.weight": "model-00001-of-00002.safetensors",
|
| 27 |
+
"model.language_model.layers.1.linear_attn.in_proj_b.weight": "model-00001-of-00002.safetensors",
|
| 28 |
+
"model.language_model.layers.1.linear_attn.in_proj_qkv.weight": "model-00001-of-00002.safetensors",
|
| 29 |
+
"model.language_model.layers.1.linear_attn.in_proj_z.weight": "model-00001-of-00002.safetensors",
|
| 30 |
+
"model.language_model.layers.1.linear_attn.norm.weight": "model-00001-of-00002.safetensors",
|
| 31 |
+
"model.language_model.layers.1.linear_attn.out_proj.weight": "model-00001-of-00002.safetensors",
|
| 32 |
+
"model.language_model.layers.1.mlp.down_proj.weight": "model-00001-of-00002.safetensors",
|
| 33 |
+
"model.language_model.layers.1.mlp.gate_proj.weight": "model-00001-of-00002.safetensors",
|
| 34 |
+
"model.language_model.layers.1.mlp.up_proj.weight": "model-00001-of-00002.safetensors",
|
| 35 |
+
"model.language_model.layers.1.post_attention_layernorm.weight": "model-00001-of-00002.safetensors",
|
| 36 |
+
"model.language_model.layers.10.input_layernorm.weight": "model-00002-of-00002.safetensors",
|
| 37 |
+
"model.language_model.layers.10.linear_attn.A_log": "model-00002-of-00002.safetensors",
|
| 38 |
+
"model.language_model.layers.10.linear_attn.conv1d.weight": "model-00002-of-00002.safetensors",
|
| 39 |
+
"model.language_model.layers.10.linear_attn.dt_bias": "model-00002-of-00002.safetensors",
|
| 40 |
+
"model.language_model.layers.10.linear_attn.in_proj_a.weight": "model-00002-of-00002.safetensors",
|
| 41 |
+
"model.language_model.layers.10.linear_attn.in_proj_b.weight": "model-00002-of-00002.safetensors",
|
| 42 |
+
"model.language_model.layers.10.linear_attn.in_proj_qkv.weight": "model-00002-of-00002.safetensors",
|
| 43 |
+
"model.language_model.layers.10.linear_attn.in_proj_z.weight": "model-00002-of-00002.safetensors",
|
| 44 |
+
"model.language_model.layers.10.linear_attn.norm.weight": "model-00002-of-00002.safetensors",
|
| 45 |
+
"model.language_model.layers.10.linear_attn.out_proj.weight": "model-00002-of-00002.safetensors",
|
| 46 |
+
"model.language_model.layers.10.mlp.down_proj.weight": "model-00002-of-00002.safetensors",
|
| 47 |
+
"model.language_model.layers.10.mlp.gate_proj.weight": "model-00002-of-00002.safetensors",
|
| 48 |
+
"model.language_model.layers.10.mlp.up_proj.weight": "model-00002-of-00002.safetensors",
|
| 49 |
+
"model.language_model.layers.10.post_attention_layernorm.weight": "model-00002-of-00002.safetensors",
|
| 50 |
+
"model.language_model.layers.11.input_layernorm.weight": "model-00002-of-00002.safetensors",
|
| 51 |
+
"model.language_model.layers.11.mlp.down_proj.weight": "model-00002-of-00002.safetensors",
|
| 52 |
+
"model.language_model.layers.11.mlp.gate_proj.weight": "model-00002-of-00002.safetensors",
|
| 53 |
+
"model.language_model.layers.11.mlp.up_proj.weight": "model-00002-of-00002.safetensors",
|
| 54 |
+
"model.language_model.layers.11.post_attention_layernorm.weight": "model-00002-of-00002.safetensors",
|
| 55 |
+
"model.language_model.layers.11.self_attn.k_norm.weight": "model-00002-of-00002.safetensors",
|
| 56 |
+
"model.language_model.layers.11.self_attn.k_proj.weight": "model-00002-of-00002.safetensors",
|
| 57 |
+
"model.language_model.layers.11.self_attn.o_proj.weight": "model-00002-of-00002.safetensors",
|
| 58 |
+
"model.language_model.layers.11.self_attn.q_norm.weight": "model-00002-of-00002.safetensors",
|
| 59 |
+
"model.language_model.layers.11.self_attn.q_proj.weight": "model-00002-of-00002.safetensors",
|
| 60 |
+
"model.language_model.layers.11.self_attn.v_proj.weight": "model-00002-of-00002.safetensors",
|
| 61 |
+
"model.language_model.layers.12.input_layernorm.weight": "model-00002-of-00002.safetensors",
|
| 62 |
+
"model.language_model.layers.12.linear_attn.A_log": "model-00002-of-00002.safetensors",
|
| 63 |
+
"model.language_model.layers.12.linear_attn.conv1d.weight": "model-00002-of-00002.safetensors",
|
| 64 |
+
"model.language_model.layers.12.linear_attn.dt_bias": "model-00002-of-00002.safetensors",
|
| 65 |
+
"model.language_model.layers.12.linear_attn.in_proj_a.weight": "model-00002-of-00002.safetensors",
|
| 66 |
+
"model.language_model.layers.12.linear_attn.in_proj_b.weight": "model-00002-of-00002.safetensors",
|
| 67 |
+
"model.language_model.layers.12.linear_attn.in_proj_qkv.weight": "model-00002-of-00002.safetensors",
|
| 68 |
+
"model.language_model.layers.12.linear_attn.in_proj_z.weight": "model-00002-of-00002.safetensors",
|
| 69 |
+
"model.language_model.layers.12.linear_attn.norm.weight": "model-00002-of-00002.safetensors",
|
| 70 |
+
"model.language_model.layers.12.linear_attn.out_proj.weight": "model-00002-of-00002.safetensors",
|
| 71 |
+
"model.language_model.layers.12.mlp.down_proj.weight": "model-00002-of-00002.safetensors",
|
| 72 |
+
"model.language_model.layers.12.mlp.gate_proj.weight": "model-00002-of-00002.safetensors",
|
| 73 |
+
"model.language_model.layers.12.mlp.up_proj.weight": "model-00002-of-00002.safetensors",
|
| 74 |
+
"model.language_model.layers.12.post_attention_layernorm.weight": "model-00002-of-00002.safetensors",
|
| 75 |
+
"model.language_model.layers.13.input_layernorm.weight": "model-00002-of-00002.safetensors",
|
| 76 |
+
"model.language_model.layers.13.linear_attn.A_log": "model-00002-of-00002.safetensors",
|
| 77 |
+
"model.language_model.layers.13.linear_attn.conv1d.weight": "model-00002-of-00002.safetensors",
|
| 78 |
+
"model.language_model.layers.13.linear_attn.dt_bias": "model-00002-of-00002.safetensors",
|
| 79 |
+
"model.language_model.layers.13.linear_attn.in_proj_a.weight": "model-00002-of-00002.safetensors",
|
| 80 |
+
"model.language_model.layers.13.linear_attn.in_proj_b.weight": "model-00002-of-00002.safetensors",
|
| 81 |
+
"model.language_model.layers.13.linear_attn.in_proj_qkv.weight": "model-00002-of-00002.safetensors",
|
| 82 |
+
"model.language_model.layers.13.linear_attn.in_proj_z.weight": "model-00002-of-00002.safetensors",
|
| 83 |
+
"model.language_model.layers.13.linear_attn.norm.weight": "model-00002-of-00002.safetensors",
|
| 84 |
+
"model.language_model.layers.13.linear_attn.out_proj.weight": "model-00002-of-00002.safetensors",
|
| 85 |
+
"model.language_model.layers.13.mlp.down_proj.weight": "model-00002-of-00002.safetensors",
|
| 86 |
+
"model.language_model.layers.13.mlp.gate_proj.weight": "model-00002-of-00002.safetensors",
|
| 87 |
+
"model.language_model.layers.13.mlp.up_proj.weight": "model-00002-of-00002.safetensors",
|
| 88 |
+
"model.language_model.layers.13.post_attention_layernorm.weight": "model-00002-of-00002.safetensors",
|
| 89 |
+
"model.language_model.layers.14.input_layernorm.weight": "model-00002-of-00002.safetensors",
|
| 90 |
+
"model.language_model.layers.14.linear_attn.A_log": "model-00002-of-00002.safetensors",
|
| 91 |
+
"model.language_model.layers.14.linear_attn.conv1d.weight": "model-00002-of-00002.safetensors",
|
| 92 |
+
"model.language_model.layers.14.linear_attn.dt_bias": "model-00002-of-00002.safetensors",
|
| 93 |
+
"model.language_model.layers.14.linear_attn.in_proj_a.weight": "model-00002-of-00002.safetensors",
|
| 94 |
+
"model.language_model.layers.14.linear_attn.in_proj_b.weight": "model-00002-of-00002.safetensors",
|
| 95 |
+
"model.language_model.layers.14.linear_attn.in_proj_qkv.weight": "model-00002-of-00002.safetensors",
|
| 96 |
+
"model.language_model.layers.14.linear_attn.in_proj_z.weight": "model-00002-of-00002.safetensors",
|
| 97 |
+
"model.language_model.layers.14.linear_attn.norm.weight": "model-00002-of-00002.safetensors",
|
| 98 |
+
"model.language_model.layers.14.linear_attn.out_proj.weight": "model-00002-of-00002.safetensors",
|
| 99 |
+
"model.language_model.layers.14.mlp.down_proj.weight": "model-00002-of-00002.safetensors",
|
| 100 |
+
"model.language_model.layers.14.mlp.gate_proj.weight": "model-00002-of-00002.safetensors",
|
| 101 |
+
"model.language_model.layers.14.mlp.up_proj.weight": "model-00002-of-00002.safetensors",
|
| 102 |
+
"model.language_model.layers.14.post_attention_layernorm.weight": "model-00002-of-00002.safetensors",
|
| 103 |
+
"model.language_model.layers.15.input_layernorm.weight": "model-00002-of-00002.safetensors",
|
| 104 |
+
"model.language_model.layers.15.mlp.down_proj.weight": "model-00002-of-00002.safetensors",
|
| 105 |
+
"model.language_model.layers.15.mlp.gate_proj.weight": "model-00002-of-00002.safetensors",
|
| 106 |
+
"model.language_model.layers.15.mlp.up_proj.weight": "model-00002-of-00002.safetensors",
|
| 107 |
+
"model.language_model.layers.15.post_attention_layernorm.weight": "model-00002-of-00002.safetensors",
|
| 108 |
+
"model.language_model.layers.15.self_attn.k_norm.weight": "model-00002-of-00002.safetensors",
|
| 109 |
+
"model.language_model.layers.15.self_attn.k_proj.weight": "model-00002-of-00002.safetensors",
|
| 110 |
+
"model.language_model.layers.15.self_attn.o_proj.weight": "model-00002-of-00002.safetensors",
|
| 111 |
+
"model.language_model.layers.15.self_attn.q_norm.weight": "model-00002-of-00002.safetensors",
|
| 112 |
+
"model.language_model.layers.15.self_attn.q_proj.weight": "model-00002-of-00002.safetensors",
|
| 113 |
+
"model.language_model.layers.15.self_attn.v_proj.weight": "model-00002-of-00002.safetensors",
|
| 114 |
+
"model.language_model.layers.16.input_layernorm.weight": "model-00002-of-00002.safetensors",
|
| 115 |
+
"model.language_model.layers.16.linear_attn.A_log": "model-00002-of-00002.safetensors",
|
| 116 |
+
"model.language_model.layers.16.linear_attn.conv1d.weight": "model-00002-of-00002.safetensors",
|
| 117 |
+
"model.language_model.layers.16.linear_attn.dt_bias": "model-00002-of-00002.safetensors",
|
| 118 |
+
"model.language_model.layers.16.linear_attn.in_proj_a.weight": "model-00002-of-00002.safetensors",
|
| 119 |
+
"model.language_model.layers.16.linear_attn.in_proj_b.weight": "model-00002-of-00002.safetensors",
|
| 120 |
+
"model.language_model.layers.16.linear_attn.in_proj_qkv.weight": "model-00002-of-00002.safetensors",
|
| 121 |
+
"model.language_model.layers.16.linear_attn.in_proj_z.weight": "model-00002-of-00002.safetensors",
|
| 122 |
+
"model.language_model.layers.16.linear_attn.norm.weight": "model-00002-of-00002.safetensors",
|
| 123 |
+
"model.language_model.layers.16.linear_attn.out_proj.weight": "model-00002-of-00002.safetensors",
|
| 124 |
+
"model.language_model.layers.16.mlp.down_proj.weight": "model-00002-of-00002.safetensors",
|
| 125 |
+
"model.language_model.layers.16.mlp.gate_proj.weight": "model-00002-of-00002.safetensors",
|
| 126 |
+
"model.language_model.layers.16.mlp.up_proj.weight": "model-00002-of-00002.safetensors",
|
| 127 |
+
"model.language_model.layers.16.post_attention_layernorm.weight": "model-00002-of-00002.safetensors",
|
| 128 |
+
"model.language_model.layers.17.input_layernorm.weight": "model-00002-of-00002.safetensors",
|
| 129 |
+
"model.language_model.layers.17.linear_attn.A_log": "model-00002-of-00002.safetensors",
|
| 130 |
+
"model.language_model.layers.17.linear_attn.conv1d.weight": "model-00002-of-00002.safetensors",
|
| 131 |
+
"model.language_model.layers.17.linear_attn.dt_bias": "model-00002-of-00002.safetensors",
|
| 132 |
+
"model.language_model.layers.17.linear_attn.in_proj_a.weight": "model-00002-of-00002.safetensors",
|
| 133 |
+
"model.language_model.layers.17.linear_attn.in_proj_b.weight": "model-00002-of-00002.safetensors",
|
| 134 |
+
"model.language_model.layers.17.linear_attn.in_proj_qkv.weight": "model-00002-of-00002.safetensors",
|
| 135 |
+
"model.language_model.layers.17.linear_attn.in_proj_z.weight": "model-00002-of-00002.safetensors",
|
| 136 |
+
"model.language_model.layers.17.linear_attn.norm.weight": "model-00002-of-00002.safetensors",
|
| 137 |
+
"model.language_model.layers.17.linear_attn.out_proj.weight": "model-00002-of-00002.safetensors",
|
| 138 |
+
"model.language_model.layers.17.mlp.down_proj.weight": "model-00002-of-00002.safetensors",
|
| 139 |
+
"model.language_model.layers.17.mlp.gate_proj.weight": "model-00002-of-00002.safetensors",
|
| 140 |
+
"model.language_model.layers.17.mlp.up_proj.weight": "model-00002-of-00002.safetensors",
|
| 141 |
+
"model.language_model.layers.17.post_attention_layernorm.weight": "model-00002-of-00002.safetensors",
|
| 142 |
+
"model.language_model.layers.18.input_layernorm.weight": "model-00002-of-00002.safetensors",
|
| 143 |
+
"model.language_model.layers.18.linear_attn.A_log": "model-00002-of-00002.safetensors",
|
| 144 |
+
"model.language_model.layers.18.linear_attn.conv1d.weight": "model-00002-of-00002.safetensors",
|
| 145 |
+
"model.language_model.layers.18.linear_attn.dt_bias": "model-00002-of-00002.safetensors",
|
| 146 |
+
"model.language_model.layers.18.linear_attn.in_proj_a.weight": "model-00002-of-00002.safetensors",
|
| 147 |
+
"model.language_model.layers.18.linear_attn.in_proj_b.weight": "model-00002-of-00002.safetensors",
|
| 148 |
+
"model.language_model.layers.18.linear_attn.in_proj_qkv.weight": "model-00002-of-00002.safetensors",
|
| 149 |
+
"model.language_model.layers.18.linear_attn.in_proj_z.weight": "model-00002-of-00002.safetensors",
|
| 150 |
+
"model.language_model.layers.18.linear_attn.norm.weight": "model-00002-of-00002.safetensors",
|
| 151 |
+
"model.language_model.layers.18.linear_attn.out_proj.weight": "model-00002-of-00002.safetensors",
|
| 152 |
+
"model.language_model.layers.18.mlp.down_proj.weight": "model-00002-of-00002.safetensors",
|
| 153 |
+
"model.language_model.layers.18.mlp.gate_proj.weight": "model-00002-of-00002.safetensors",
|
| 154 |
+
"model.language_model.layers.18.mlp.up_proj.weight": "model-00002-of-00002.safetensors",
|
| 155 |
+
"model.language_model.layers.18.post_attention_layernorm.weight": "model-00002-of-00002.safetensors",
|
| 156 |
+
"model.language_model.layers.19.input_layernorm.weight": "model-00002-of-00002.safetensors",
|
| 157 |
+
"model.language_model.layers.19.mlp.down_proj.weight": "model-00002-of-00002.safetensors",
|
| 158 |
+
"model.language_model.layers.19.mlp.gate_proj.weight": "model-00002-of-00002.safetensors",
|
| 159 |
+
"model.language_model.layers.19.mlp.up_proj.weight": "model-00002-of-00002.safetensors",
|
| 160 |
+
"model.language_model.layers.19.post_attention_layernorm.weight": "model-00002-of-00002.safetensors",
|
| 161 |
+
"model.language_model.layers.19.self_attn.k_norm.weight": "model-00002-of-00002.safetensors",
|
| 162 |
+
"model.language_model.layers.19.self_attn.k_proj.weight": "model-00002-of-00002.safetensors",
|
| 163 |
+
"model.language_model.layers.19.self_attn.o_proj.weight": "model-00002-of-00002.safetensors",
|
| 164 |
+
"model.language_model.layers.19.self_attn.q_norm.weight": "model-00002-of-00002.safetensors",
|
| 165 |
+
"model.language_model.layers.19.self_attn.q_proj.weight": "model-00002-of-00002.safetensors",
|
| 166 |
+
"model.language_model.layers.19.self_attn.v_proj.weight": "model-00002-of-00002.safetensors",
|
| 167 |
+
"model.language_model.layers.2.input_layernorm.weight": "model-00001-of-00002.safetensors",
|
| 168 |
+
"model.language_model.layers.2.linear_attn.A_log": "model-00001-of-00002.safetensors",
|
| 169 |
+
"model.language_model.layers.2.linear_attn.conv1d.weight": "model-00001-of-00002.safetensors",
|
| 170 |
+
"model.language_model.layers.2.linear_attn.dt_bias": "model-00001-of-00002.safetensors",
|
| 171 |
+
"model.language_model.layers.2.linear_attn.in_proj_a.weight": "model-00001-of-00002.safetensors",
|
| 172 |
+
"model.language_model.layers.2.linear_attn.in_proj_b.weight": "model-00001-of-00002.safetensors",
|
| 173 |
+
"model.language_model.layers.2.linear_attn.in_proj_qkv.weight": "model-00001-of-00002.safetensors",
|
| 174 |
+
"model.language_model.layers.2.linear_attn.in_proj_z.weight": "model-00001-of-00002.safetensors",
|
| 175 |
+
"model.language_model.layers.2.linear_attn.norm.weight": "model-00001-of-00002.safetensors",
|
| 176 |
+
"model.language_model.layers.2.linear_attn.out_proj.weight": "model-00001-of-00002.safetensors",
|
| 177 |
+
"model.language_model.layers.2.mlp.down_proj.weight": "model-00001-of-00002.safetensors",
|
| 178 |
+
"model.language_model.layers.2.mlp.gate_proj.weight": "model-00001-of-00002.safetensors",
|
| 179 |
+
"model.language_model.layers.2.mlp.up_proj.weight": "model-00001-of-00002.safetensors",
|
| 180 |
+
"model.language_model.layers.2.post_attention_layernorm.weight": "model-00001-of-00002.safetensors",
|
| 181 |
+
"model.language_model.layers.20.input_layernorm.weight": "model-00002-of-00002.safetensors",
|
| 182 |
+
"model.language_model.layers.20.linear_attn.A_log": "model-00002-of-00002.safetensors",
|
| 183 |
+
"model.language_model.layers.20.linear_attn.conv1d.weight": "model-00002-of-00002.safetensors",
|
| 184 |
+
"model.language_model.layers.20.linear_attn.dt_bias": "model-00002-of-00002.safetensors",
|
| 185 |
+
"model.language_model.layers.20.linear_attn.in_proj_a.weight": "model-00002-of-00002.safetensors",
|
| 186 |
+
"model.language_model.layers.20.linear_attn.in_proj_b.weight": "model-00002-of-00002.safetensors",
|
| 187 |
+
"model.language_model.layers.20.linear_attn.in_proj_qkv.weight": "model-00002-of-00002.safetensors",
|
| 188 |
+
"model.language_model.layers.20.linear_attn.in_proj_z.weight": "model-00002-of-00002.safetensors",
|
| 189 |
+
"model.language_model.layers.20.linear_attn.norm.weight": "model-00002-of-00002.safetensors",
|
| 190 |
+
"model.language_model.layers.20.linear_attn.out_proj.weight": "model-00002-of-00002.safetensors",
|
| 191 |
+
"model.language_model.layers.20.mlp.down_proj.weight": "model-00002-of-00002.safetensors",
|
| 192 |
+
"model.language_model.layers.20.mlp.gate_proj.weight": "model-00002-of-00002.safetensors",
|
| 193 |
+
"model.language_model.layers.20.mlp.up_proj.weight": "model-00002-of-00002.safetensors",
|
| 194 |
+
"model.language_model.layers.20.post_attention_layernorm.weight": "model-00002-of-00002.safetensors",
|
| 195 |
+
"model.language_model.layers.21.input_layernorm.weight": "model-00002-of-00002.safetensors",
|
| 196 |
+
"model.language_model.layers.21.linear_attn.A_log": "model-00002-of-00002.safetensors",
|
| 197 |
+
"model.language_model.layers.21.linear_attn.conv1d.weight": "model-00002-of-00002.safetensors",
|
| 198 |
+
"model.language_model.layers.21.linear_attn.dt_bias": "model-00002-of-00002.safetensors",
|
| 199 |
+
"model.language_model.layers.21.linear_attn.in_proj_a.weight": "model-00002-of-00002.safetensors",
|
| 200 |
+
"model.language_model.layers.21.linear_attn.in_proj_b.weight": "model-00002-of-00002.safetensors",
|
| 201 |
+
"model.language_model.layers.21.linear_attn.in_proj_qkv.weight": "model-00002-of-00002.safetensors",
|
| 202 |
+
"model.language_model.layers.21.linear_attn.in_proj_z.weight": "model-00002-of-00002.safetensors",
|
| 203 |
+
"model.language_model.layers.21.linear_attn.norm.weight": "model-00002-of-00002.safetensors",
|
| 204 |
+
"model.language_model.layers.21.linear_attn.out_proj.weight": "model-00002-of-00002.safetensors",
|
| 205 |
+
"model.language_model.layers.21.mlp.down_proj.weight": "model-00002-of-00002.safetensors",
|
| 206 |
+
"model.language_model.layers.21.mlp.gate_proj.weight": "model-00002-of-00002.safetensors",
|
| 207 |
+
"model.language_model.layers.21.mlp.up_proj.weight": "model-00002-of-00002.safetensors",
|
| 208 |
+
"model.language_model.layers.21.post_attention_layernorm.weight": "model-00002-of-00002.safetensors",
|
| 209 |
+
"model.language_model.layers.22.input_layernorm.weight": "model-00002-of-00002.safetensors",
|
| 210 |
+
"model.language_model.layers.22.linear_attn.A_log": "model-00002-of-00002.safetensors",
|
| 211 |
+
"model.language_model.layers.22.linear_attn.conv1d.weight": "model-00002-of-00002.safetensors",
|
| 212 |
+
"model.language_model.layers.22.linear_attn.dt_bias": "model-00002-of-00002.safetensors",
|
| 213 |
+
"model.language_model.layers.22.linear_attn.in_proj_a.weight": "model-00002-of-00002.safetensors",
|
| 214 |
+
"model.language_model.layers.22.linear_attn.in_proj_b.weight": "model-00002-of-00002.safetensors",
|
| 215 |
+
"model.language_model.layers.22.linear_attn.in_proj_qkv.weight": "model-00002-of-00002.safetensors",
|
| 216 |
+
"model.language_model.layers.22.linear_attn.in_proj_z.weight": "model-00002-of-00002.safetensors",
|
| 217 |
+
"model.language_model.layers.22.linear_attn.norm.weight": "model-00002-of-00002.safetensors",
|
| 218 |
+
"model.language_model.layers.22.linear_attn.out_proj.weight": "model-00002-of-00002.safetensors",
|
| 219 |
+
"model.language_model.layers.22.mlp.down_proj.weight": "model-00002-of-00002.safetensors",
|
| 220 |
+
"model.language_model.layers.22.mlp.gate_proj.weight": "model-00002-of-00002.safetensors",
|
| 221 |
+
"model.language_model.layers.22.mlp.up_proj.weight": "model-00002-of-00002.safetensors",
|
| 222 |
+
"model.language_model.layers.22.post_attention_layernorm.weight": "model-00002-of-00002.safetensors",
|
| 223 |
+
"model.language_model.layers.23.input_layernorm.weight": "model-00002-of-00002.safetensors",
|
| 224 |
+
"model.language_model.layers.23.mlp.down_proj.weight": "model-00002-of-00002.safetensors",
|
| 225 |
+
"model.language_model.layers.23.mlp.gate_proj.weight": "model-00002-of-00002.safetensors",
|
| 226 |
+
"model.language_model.layers.23.mlp.up_proj.weight": "model-00002-of-00002.safetensors",
|
| 227 |
+
"model.language_model.layers.23.post_attention_layernorm.weight": "model-00002-of-00002.safetensors",
|
| 228 |
+
"model.language_model.layers.23.self_attn.k_norm.weight": "model-00002-of-00002.safetensors",
|
| 229 |
+
"model.language_model.layers.23.self_attn.k_proj.weight": "model-00002-of-00002.safetensors",
|
| 230 |
+
"model.language_model.layers.23.self_attn.o_proj.weight": "model-00002-of-00002.safetensors",
|
| 231 |
+
"model.language_model.layers.23.self_attn.q_norm.weight": "model-00002-of-00002.safetensors",
|
| 232 |
+
"model.language_model.layers.23.self_attn.q_proj.weight": "model-00002-of-00002.safetensors",
|
| 233 |
+
"model.language_model.layers.23.self_attn.v_proj.weight": "model-00002-of-00002.safetensors",
|
| 234 |
+
"model.language_model.layers.3.input_layernorm.weight": "model-00001-of-00002.safetensors",
|
| 235 |
+
"model.language_model.layers.3.mlp.down_proj.weight": "model-00001-of-00002.safetensors",
|
| 236 |
+
"model.language_model.layers.3.mlp.gate_proj.weight": "model-00001-of-00002.safetensors",
|
| 237 |
+
"model.language_model.layers.3.mlp.up_proj.weight": "model-00001-of-00002.safetensors",
|
| 238 |
+
"model.language_model.layers.3.post_attention_layernorm.weight": "model-00001-of-00002.safetensors",
|
| 239 |
+
"model.language_model.layers.3.self_attn.k_norm.weight": "model-00001-of-00002.safetensors",
|
| 240 |
+
"model.language_model.layers.3.self_attn.k_proj.weight": "model-00001-of-00002.safetensors",
|
| 241 |
+
"model.language_model.layers.3.self_attn.o_proj.weight": "model-00001-of-00002.safetensors",
|
| 242 |
+
"model.language_model.layers.3.self_attn.q_norm.weight": "model-00001-of-00002.safetensors",
|
| 243 |
+
"model.language_model.layers.3.self_attn.q_proj.weight": "model-00001-of-00002.safetensors",
|
| 244 |
+
"model.language_model.layers.3.self_attn.v_proj.weight": "model-00001-of-00002.safetensors",
|
| 245 |
+
"model.language_model.layers.4.input_layernorm.weight": "model-00001-of-00002.safetensors",
|
| 246 |
+
"model.language_model.layers.4.linear_attn.A_log": "model-00001-of-00002.safetensors",
|
| 247 |
+
"model.language_model.layers.4.linear_attn.conv1d.weight": "model-00001-of-00002.safetensors",
|
| 248 |
+
"model.language_model.layers.4.linear_attn.dt_bias": "model-00001-of-00002.safetensors",
|
| 249 |
+
"model.language_model.layers.4.linear_attn.in_proj_a.weight": "model-00001-of-00002.safetensors",
|
| 250 |
+
"model.language_model.layers.4.linear_attn.in_proj_b.weight": "model-00001-of-00002.safetensors",
|
| 251 |
+
"model.language_model.layers.4.linear_attn.in_proj_qkv.weight": "model-00001-of-00002.safetensors",
|
| 252 |
+
"model.language_model.layers.4.linear_attn.in_proj_z.weight": "model-00001-of-00002.safetensors",
|
| 253 |
+
"model.language_model.layers.4.linear_attn.norm.weight": "model-00001-of-00002.safetensors",
|
| 254 |
+
"model.language_model.layers.4.linear_attn.out_proj.weight": "model-00001-of-00002.safetensors",
|
| 255 |
+
"model.language_model.layers.4.mlp.down_proj.weight": "model-00001-of-00002.safetensors",
|
| 256 |
+
"model.language_model.layers.4.mlp.gate_proj.weight": "model-00001-of-00002.safetensors",
|
| 257 |
+
"model.language_model.layers.4.mlp.up_proj.weight": "model-00001-of-00002.safetensors",
|
| 258 |
+
"model.language_model.layers.4.post_attention_layernorm.weight": "model-00001-of-00002.safetensors",
|
| 259 |
+
"model.language_model.layers.5.input_layernorm.weight": "model-00001-of-00002.safetensors",
|
| 260 |
+
"model.language_model.layers.5.linear_attn.A_log": "model-00001-of-00002.safetensors",
|
| 261 |
+
"model.language_model.layers.5.linear_attn.conv1d.weight": "model-00001-of-00002.safetensors",
|
| 262 |
+
"model.language_model.layers.5.linear_attn.dt_bias": "model-00001-of-00002.safetensors",
|
| 263 |
+
"model.language_model.layers.5.linear_attn.in_proj_a.weight": "model-00001-of-00002.safetensors",
|
| 264 |
+
"model.language_model.layers.5.linear_attn.in_proj_b.weight": "model-00001-of-00002.safetensors",
|
| 265 |
+
"model.language_model.layers.5.linear_attn.in_proj_qkv.weight": "model-00001-of-00002.safetensors",
|
| 266 |
+
"model.language_model.layers.5.linear_attn.in_proj_z.weight": "model-00001-of-00002.safetensors",
|
| 267 |
+
"model.language_model.layers.5.linear_attn.norm.weight": "model-00001-of-00002.safetensors",
|
| 268 |
+
"model.language_model.layers.5.linear_attn.out_proj.weight": "model-00001-of-00002.safetensors",
|
| 269 |
+
"model.language_model.layers.5.mlp.down_proj.weight": "model-00001-of-00002.safetensors",
|
| 270 |
+
"model.language_model.layers.5.mlp.gate_proj.weight": "model-00001-of-00002.safetensors",
|
| 271 |
+
"model.language_model.layers.5.mlp.up_proj.weight": "model-00001-of-00002.safetensors",
|
| 272 |
+
"model.language_model.layers.5.post_attention_layernorm.weight": "model-00001-of-00002.safetensors",
|
| 273 |
+
"model.language_model.layers.6.input_layernorm.weight": "model-00001-of-00002.safetensors",
|
| 274 |
+
"model.language_model.layers.6.linear_attn.A_log": "model-00001-of-00002.safetensors",
|
| 275 |
+
"model.language_model.layers.6.linear_attn.conv1d.weight": "model-00001-of-00002.safetensors",
|
| 276 |
+
"model.language_model.layers.6.linear_attn.dt_bias": "model-00001-of-00002.safetensors",
|
| 277 |
+
"model.language_model.layers.6.linear_attn.in_proj_a.weight": "model-00001-of-00002.safetensors",
|
| 278 |
+
"model.language_model.layers.6.linear_attn.in_proj_b.weight": "model-00001-of-00002.safetensors",
|
| 279 |
+
"model.language_model.layers.6.linear_attn.in_proj_qkv.weight": "model-00001-of-00002.safetensors",
|
| 280 |
+
"model.language_model.layers.6.linear_attn.in_proj_z.weight": "model-00001-of-00002.safetensors",
|
| 281 |
+
"model.language_model.layers.6.linear_attn.norm.weight": "model-00001-of-00002.safetensors",
|
| 282 |
+
"model.language_model.layers.6.linear_attn.out_proj.weight": "model-00001-of-00002.safetensors",
|
| 283 |
+
"model.language_model.layers.6.mlp.down_proj.weight": "model-00001-of-00002.safetensors",
|
| 284 |
+
"model.language_model.layers.6.mlp.gate_proj.weight": "model-00001-of-00002.safetensors",
|
| 285 |
+
"model.language_model.layers.6.mlp.up_proj.weight": "model-00001-of-00002.safetensors",
|
| 286 |
+
"model.language_model.layers.6.post_attention_layernorm.weight": "model-00001-of-00002.safetensors",
|
| 287 |
+
"model.language_model.layers.7.input_layernorm.weight": "model-00001-of-00002.safetensors",
|
| 288 |
+
"model.language_model.layers.7.mlp.down_proj.weight": "model-00001-of-00002.safetensors",
|
| 289 |
+
"model.language_model.layers.7.mlp.gate_proj.weight": "model-00001-of-00002.safetensors",
|
| 290 |
+
"model.language_model.layers.7.mlp.up_proj.weight": "model-00001-of-00002.safetensors",
|
| 291 |
+
"model.language_model.layers.7.post_attention_layernorm.weight": "model-00001-of-00002.safetensors",
|
| 292 |
+
"model.language_model.layers.7.self_attn.k_norm.weight": "model-00001-of-00002.safetensors",
|
| 293 |
+
"model.language_model.layers.7.self_attn.k_proj.weight": "model-00001-of-00002.safetensors",
|
| 294 |
+
"model.language_model.layers.7.self_attn.o_proj.weight": "model-00001-of-00002.safetensors",
|
| 295 |
+
"model.language_model.layers.7.self_attn.q_norm.weight": "model-00001-of-00002.safetensors",
|
| 296 |
+
"model.language_model.layers.7.self_attn.q_proj.weight": "model-00001-of-00002.safetensors",
|
| 297 |
+
"model.language_model.layers.7.self_attn.v_proj.weight": "model-00001-of-00002.safetensors",
|
| 298 |
+
"model.language_model.layers.8.input_layernorm.weight": "model-00001-of-00002.safetensors",
|
| 299 |
+
"model.language_model.layers.8.linear_attn.A_log": "model-00001-of-00002.safetensors",
|
| 300 |
+
"model.language_model.layers.8.linear_attn.conv1d.weight": "model-00001-of-00002.safetensors",
|
| 301 |
+
"model.language_model.layers.8.linear_attn.dt_bias": "model-00001-of-00002.safetensors",
|
| 302 |
+
"model.language_model.layers.8.linear_attn.in_proj_a.weight": "model-00001-of-00002.safetensors",
|
| 303 |
+
"model.language_model.layers.8.linear_attn.in_proj_b.weight": "model-00001-of-00002.safetensors",
|
| 304 |
+
"model.language_model.layers.8.linear_attn.in_proj_qkv.weight": "model-00001-of-00002.safetensors",
|
| 305 |
+
"model.language_model.layers.8.linear_attn.in_proj_z.weight": "model-00001-of-00002.safetensors",
|
| 306 |
+
"model.language_model.layers.8.linear_attn.norm.weight": "model-00001-of-00002.safetensors",
|
| 307 |
+
"model.language_model.layers.8.linear_attn.out_proj.weight": "model-00001-of-00002.safetensors",
|
| 308 |
+
"model.language_model.layers.8.mlp.down_proj.weight": "model-00001-of-00002.safetensors",
|
| 309 |
+
"model.language_model.layers.8.mlp.gate_proj.weight": "model-00002-of-00002.safetensors",
|
| 310 |
+
"model.language_model.layers.8.mlp.up_proj.weight": "model-00002-of-00002.safetensors",
|
| 311 |
+
"model.language_model.layers.8.post_attention_layernorm.weight": "model-00002-of-00002.safetensors",
|
| 312 |
+
"model.language_model.layers.9.input_layernorm.weight": "model-00002-of-00002.safetensors",
|
| 313 |
+
"model.language_model.layers.9.linear_attn.A_log": "model-00002-of-00002.safetensors",
|
| 314 |
+
"model.language_model.layers.9.linear_attn.conv1d.weight": "model-00002-of-00002.safetensors",
|
| 315 |
+
"model.language_model.layers.9.linear_attn.dt_bias": "model-00002-of-00002.safetensors",
|
| 316 |
+
"model.language_model.layers.9.linear_attn.in_proj_a.weight": "model-00002-of-00002.safetensors",
|
| 317 |
+
"model.language_model.layers.9.linear_attn.in_proj_b.weight": "model-00002-of-00002.safetensors",
|
| 318 |
+
"model.language_model.layers.9.linear_attn.in_proj_qkv.weight": "model-00002-of-00002.safetensors",
|
| 319 |
+
"model.language_model.layers.9.linear_attn.in_proj_z.weight": "model-00002-of-00002.safetensors",
|
| 320 |
+
"model.language_model.layers.9.linear_attn.norm.weight": "model-00002-of-00002.safetensors",
|
| 321 |
+
"model.language_model.layers.9.linear_attn.out_proj.weight": "model-00002-of-00002.safetensors",
|
| 322 |
+
"model.language_model.layers.9.mlp.down_proj.weight": "model-00002-of-00002.safetensors",
|
| 323 |
+
"model.language_model.layers.9.mlp.gate_proj.weight": "model-00002-of-00002.safetensors",
|
| 324 |
+
"model.language_model.layers.9.mlp.up_proj.weight": "model-00002-of-00002.safetensors",
|
| 325 |
+
"model.language_model.layers.9.post_attention_layernorm.weight": "model-00002-of-00002.safetensors",
|
| 326 |
+
"model.language_model.norm.weight": "model-00002-of-00002.safetensors"
|
| 327 |
+
}
|
| 328 |
+
}
|
readout_config.json
ADDED
|
@@ -0,0 +1,47 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"format": "macjev-readout-v2",
|
| 3 |
+
"model_name": "Jev-Style-2B-Decision-v3",
|
| 4 |
+
"readout": "verdict",
|
| 5 |
+
"template": "macjev-render-v2-long-options",
|
| 6 |
+
"layout": "sb",
|
| 7 |
+
"block_size": 2048,
|
| 8 |
+
"total_context_limit": 25600,
|
| 9 |
+
"question_option_limit": null,
|
| 10 |
+
"slot_tokens": {
|
| 11 |
+
"yes": {
|
| 12 |
+
"text": " yes",
|
| 13 |
+
"id": 9542
|
| 14 |
+
},
|
| 15 |
+
"no": {
|
| 16 |
+
"text": " no",
|
| 17 |
+
"id": 874
|
| 18 |
+
},
|
| 19 |
+
"verdict_slot": {
|
| 20 |
+
"text": " ->",
|
| 21 |
+
"id": 1411
|
| 22 |
+
}
|
| 23 |
+
},
|
| 24 |
+
"attention": "block-causal in the 6 full-attention layers: the input is cut into [start, stop) blocks of at most block_size tokens (state blocks; one short question block, or catalogue blocks + rubric blocks when question + options + slots exceed block_size); every block attends to all earlier tokens and to itself with no causal mask inside the block. Gated-DeltaNet layers are ordinary recurrent layers.",
|
| 25 |
+
"score": "per option k: logit[' yes'] - logit[' no'] at the k-th ' ->' slot, computed as h_slot . (w_yes - w_no) from the final normed hidden state and the tied embedding rows (float32)",
|
| 26 |
+
"probabilities": "softmax(scores / T) in canonical option order; T = temperatures.global (one global temperature)",
|
| 27 |
+
"tokenizer_sha256": "06b9509352d2af50381ab2247e083b80d32d5c0aba91c272ca9ff729b6a0e523",
|
| 28 |
+
"budgets": {
|
| 29 |
+
"max_len": 25600,
|
| 30 |
+
"question_option_limit": null,
|
| 31 |
+
"note": "the complete input (state + question + options + readout) <= max_len tokens; there is no separate question/options cap; larger inputs raise InputBudgetError, nothing is truncated"
|
| 32 |
+
},
|
| 33 |
+
"temperatures": {
|
| 34 |
+
"version": "macjev-temperature-v2-global",
|
| 35 |
+
"global": 0.8278650620942867,
|
| 36 |
+
"groups": null,
|
| 37 |
+
"groups_note": "none: this model has one global temperature (no category / family / option-count temperatures)",
|
| 38 |
+
"fitted_on": "2,000 independent calibration rows (not dev, not test)",
|
| 39 |
+
"n_rows": 2000,
|
| 40 |
+
"fit_quality": {
|
| 41 |
+
"nll_before": 0.3002617012172898,
|
| 42 |
+
"nll_after": 0.2900580002426921,
|
| 43 |
+
"n": 2000
|
| 44 |
+
},
|
| 45 |
+
"selected_weights": "ema"
|
| 46 |
+
}
|
| 47 |
+
}
|
release_config.json
ADDED
|
@@ -0,0 +1,804 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"format": "jev-style-release-v1",
|
| 3 |
+
"model_name": "Jev-Style-2B-Decision-v3",
|
| 4 |
+
"repo": "chaoliangUNSW/Jev-Style-2B-Decision-v3",
|
| 5 |
+
"generation": "v3 (third generation of the Jev-Style decision series)",
|
| 6 |
+
"lineage": {
|
| 7 |
+
"v1": "chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision",
|
| 8 |
+
"v1_public_gguf": "chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision-GGUF",
|
| 9 |
+
"v2": "chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision-v2",
|
| 10 |
+
"v3_0.8b": "chaoliangUNSW/Jev-Style-0.8B-Decision-v3",
|
| 11 |
+
"v3_2b": "chaoliangUNSW/Jev-Style-2B-Decision-v3"
|
| 12 |
+
},
|
| 13 |
+
"base_model": "Qwen/Qwen3.5-2B",
|
| 14 |
+
"base_model_revision": "15852e8c16360a2fea060d615a32b45270f8a8fc",
|
| 15 |
+
"base_model_relation": "finetune",
|
| 16 |
+
"architecture": "Qwen3_5ForCausalLM (text only, 24 layers: 18 Gated DeltaNet + 6 full attention, hidden 2048, tied embeddings, 1,881,825,088 parameters)",
|
| 17 |
+
"readout": "verdict",
|
| 18 |
+
"template": "macjev-render-v2-long-options",
|
| 19 |
+
"layout": "sb",
|
| 20 |
+
"attention": "block-causal in the 6 full-attention layers (2,048-token blocks, no causal mask inside a block); Gated DeltaNet recurrent",
|
| 21 |
+
"readout_config": "readout_config.json",
|
| 22 |
+
"budgets": {
|
| 23 |
+
"max_len": 25600,
|
| 24 |
+
"question_option_limit": null,
|
| 25 |
+
"block_size": 2048
|
| 26 |
+
},
|
| 27 |
+
"source": {
|
| 28 |
+
"checkpoint": "EMA weights of the full fine-tune (text-only Qwen3_5ForCausalLM, bf16, 2 safetensors shards)",
|
| 29 |
+
"checkpoint_sha256": {
|
| 30 |
+
"model-00001-of-00002.safetensors": "df592f869cb1232226d31491b783bfa9406ffb3c795eae44a3b7452e1044a8fb",
|
| 31 |
+
"model-00002-of-00002.safetensors": "c6ff77a32a8cf36767e51c1282bb345a873db6509847f6c75baadd8fb17eeb70"
|
| 32 |
+
},
|
| 33 |
+
"exports_manifest": {
|
| 34 |
+
"file": "runs/macjev/release_2b/exports_manifest.json",
|
| 35 |
+
"sha256": "11c549e479c7022c960c546730d6a3c42957c1c40b1b8901a183a893917d96a5",
|
| 36 |
+
"note": "sha256 / bytes of the exported GGUF and MLX files (release_2b/build_exports.py)"
|
| 37 |
+
},
|
| 38 |
+
"candidate_sha256sums": {
|
| 39 |
+
"file": "runs/macjev/candidate_2b/hf-candidate/SHA256SUMS.json",
|
| 40 |
+
"sha256": "7549ed3fe6239b2862998798d8da1457fdced25cd424aa4442557ae852d6e696"
|
| 41 |
+
}
|
| 42 |
+
},
|
| 43 |
+
"calibration": {
|
| 44 |
+
"version": "macjev-temperature-v2-global",
|
| 45 |
+
"global_T": 0.8278650620942867,
|
| 46 |
+
"groups": null,
|
| 47 |
+
"n_rows": 2000,
|
| 48 |
+
"fit_quality": {
|
| 49 |
+
"nll_before": 0.3002617012172898,
|
| 50 |
+
"nll_after": 0.2900580002426921,
|
| 51 |
+
"n": 2000
|
| 52 |
+
},
|
| 53 |
+
"fitted_on": "2,000 independent calibration rows (not dev, not test rows)"
|
| 54 |
+
},
|
| 55 |
+
"related_repos": {
|
| 56 |
+
"main": "chaoliangUNSW/Jev-Style-2B-Decision-v3",
|
| 57 |
+
"gguf": "chaoliangUNSW/Jev-Style-2B-Decision-v3-GGUF",
|
| 58 |
+
"mlx": "chaoliangUNSW/Jev-Style-2B-Decision-v3-MLX"
|
| 59 |
+
},
|
| 60 |
+
"tested_with": {
|
| 61 |
+
"python": "3.12.13",
|
| 62 |
+
"torch": "2.14.0",
|
| 63 |
+
"transformers": "5.17.0",
|
| 64 |
+
"tokenizers": "0.23.2",
|
| 65 |
+
"numpy": "2.5.3"
|
| 66 |
+
},
|
| 67 |
+
"weights": {
|
| 68 |
+
"model-00001-of-00002.safetensors": "bfloat16 (text-only export of the trained checkpoint, shard 1 of 2)",
|
| 69 |
+
"model-00002-of-00002.safetensors": "bfloat16 (text-only export of the trained checkpoint, shard 2 of 2)"
|
| 70 |
+
},
|
| 71 |
+
"runtime": {
|
| 72 |
+
"script": "jev_style_decision.py",
|
| 73 |
+
"class": "JevStyleDecision",
|
| 74 |
+
"default_dtype": "float32",
|
| 75 |
+
"dtypes": {
|
| 76 |
+
"float32": "cuda, mps, cpu (the parity-tested setting)",
|
| 77 |
+
"bfloat16": "cuda only"
|
| 78 |
+
},
|
| 79 |
+
"devices": [
|
| 80 |
+
"cuda",
|
| 81 |
+
"mps",
|
| 82 |
+
"cpu"
|
| 83 |
+
],
|
| 84 |
+
"attention": "transformers AttentionInterface 'jev_style_block_sdpa': the input is fed one renderer block per forward call on top of a cache holding every earlier token; the full-attention layers run unmasked SDPA over cache + block (exactly block-causal); any other call is refused",
|
| 85 |
+
"gated_deltanet": "transformers Qwen3.5 layers (flash-linear-attention kernels when installed, otherwise the transformers torch fallback), conv / recurrent state continued from the cache",
|
| 86 |
+
"score_many": "state blocks computed once per call, each question continues from its own copy of the state cache; the last state is kept for the next call (exact match only)",
|
| 87 |
+
"mps_attn_chunk": 1024,
|
| 88 |
+
"temperature": "readout_config.json temperatures.global unless overridden",
|
| 89 |
+
"compat": {
|
| 90 |
+
"category": "accepted (keyword) and ignored: one global temperature",
|
| 91 |
+
"renderer.head_max": "= max_len (25,600): no separate question/options cap"
|
| 92 |
+
},
|
| 93 |
+
"not_supported": {
|
| 94 |
+
"--category": "no category/group temperatures (one global T)",
|
| 95 |
+
"--head-max": "no question/options cap (25,600-token total budget only)"
|
| 96 |
+
}
|
| 97 |
+
},
|
| 98 |
+
"format_gates": {
|
| 99 |
+
"predeclared": {
|
| 100 |
+
"file": "runs/macjev/runtime_v2_dev/PREDECLARED_RELEASE_GATES_2B.md",
|
| 101 |
+
"sha256": "783aec77300779582911cdc57c71cf8b101b0cd5ca040073f7e1fa3ac20af08e",
|
| 102 |
+
"gates": "F16/bf16 top-1 >= 0.99; 8-bit top-1 >= 0.98; |dNLL| <= 0.02; accuracy drop Q8_0 / MLX-8bit <= 0.3 pp, Q4_K_M <= 1.0 pp (4-bit top-1 / NLL report-only); no non-finite scores"
|
| 103 |
+
},
|
| 104 |
+
"reference": {
|
| 105 |
+
"what": "HF transformers FP32 on CPU, exact v2 block attention, released bf16 checkpoint (runs/macjev/candidate_2b/hf-candidate)",
|
| 106 |
+
"temperature": 0.8278650620942867
|
| 107 |
+
},
|
| 108 |
+
"fixtures": {
|
| 109 |
+
"gate": {
|
| 110 |
+
"what": "1,000 real dev rows (<= 4,096 tokens); decides the release gates",
|
| 111 |
+
"file": "runs/macjev/runtime_v2_dev/reference/gate_fixture_n1000.jsonl",
|
| 112 |
+
"sha256": "1c03b8c570b988b0c83ca1f79e7fd37e6196239a0836f348300c3f23ae667b68"
|
| 113 |
+
},
|
| 114 |
+
"long": {
|
| 115 |
+
"what": "35 requests / 43 questions up to 25,600 tokens incl. catalogue overflow and K <= 151; accuracy gate unresolvable on 43 questions (verdict INCONCLUSIVE means only that), top-1 / dNLL reported",
|
| 116 |
+
"file": "runs/macjev/runtime_v2_dev/reference_base/fixture.jsonl",
|
| 117 |
+
"sha256": "2b16d25eafa70c00a1106ba51b94890821b51ecb4fa393abb12403c8739ef314"
|
| 118 |
+
}
|
| 119 |
+
},
|
| 120 |
+
"cross_format_dp": {
|
| 121 |
+
"file": "runs/macjev/release_2b/parity/cross_format_dp.json",
|
| 122 |
+
"sha256": "c7332df0f02244416b01e49ecb037c76d4bf2643a2b42505ff1dfe896879e533"
|
| 123 |
+
},
|
| 124 |
+
"formats": {
|
| 125 |
+
"gguf-f16": {
|
| 126 |
+
"gate_fixture": {
|
| 127 |
+
"n": 1000,
|
| 128 |
+
"top1_agreement": 1.0,
|
| 129 |
+
"top1_flips": 0,
|
| 130 |
+
"max_abs_dscore": 0.005850315093994141,
|
| 131 |
+
"mean_abs_dscore": 0.0006183286580890569,
|
| 132 |
+
"dnll": 2.447897923035791e-05,
|
| 133 |
+
"nll_ref": 0.4436679457518203,
|
| 134 |
+
"nll_cand": 0.44369242473105064,
|
| 135 |
+
"acc_ref": 0.808,
|
| 136 |
+
"acc_cand": 0.808,
|
| 137 |
+
"acc_drop_pp": 0.0,
|
| 138 |
+
"max_abs_dp": 0.0013728371250730786,
|
| 139 |
+
"mean_max_abs_dp": 0.00012138780447113503,
|
| 140 |
+
"gates": {
|
| 141 |
+
"coverage_finite_tokens": {
|
| 142 |
+
"pass": true,
|
| 143 |
+
"problems": {},
|
| 144 |
+
"reference_missing_requests": 0
|
| 145 |
+
},
|
| 146 |
+
"top1": {
|
| 147 |
+
"threshold": 0.99,
|
| 148 |
+
"value": 1.0,
|
| 149 |
+
"pass": true
|
| 150 |
+
},
|
| 151 |
+
"dnll": {
|
| 152 |
+
"threshold": 0.02,
|
| 153 |
+
"value": 2.447897923035791e-05,
|
| 154 |
+
"pass": true
|
| 155 |
+
}
|
| 156 |
+
},
|
| 157 |
+
"verdict": "PASS",
|
| 158 |
+
"note": "small fixtures cannot resolve 0.3pp accuracy gates; accuracy on a parity fixture is only indicative (synthetic long rows carry the base row's gold label).",
|
| 159 |
+
"source": {
|
| 160 |
+
"file": "runs/macjev/release_2b/parity/compare_gguf_f16_gate_vs_block.json",
|
| 161 |
+
"sha256": "d2db48b883161cca7d9c80d51a85b3c229a3bcfb7c00086887af697aeadd4c5f"
|
| 162 |
+
}
|
| 163 |
+
},
|
| 164 |
+
"long_fixture": {
|
| 165 |
+
"n": 43,
|
| 166 |
+
"top1_agreement": 1.0,
|
| 167 |
+
"top1_flips": 0,
|
| 168 |
+
"max_abs_dscore": 0.004771709442138672,
|
| 169 |
+
"mean_abs_dscore": 0.000623485138032805,
|
| 170 |
+
"dnll": -0.00013262687499793202,
|
| 171 |
+
"nll_ref": 0.670433307194272,
|
| 172 |
+
"nll_cand": 0.670300680319274,
|
| 173 |
+
"acc_ref": 0.7209302325581395,
|
| 174 |
+
"acc_cand": 0.7209302325581395,
|
| 175 |
+
"acc_drop_pp": 0.0,
|
| 176 |
+
"max_abs_dp": 0.0006297677378335198,
|
| 177 |
+
"mean_max_abs_dp": 0.00017737997866918594,
|
| 178 |
+
"gates": {
|
| 179 |
+
"coverage_finite_tokens": {
|
| 180 |
+
"pass": true,
|
| 181 |
+
"problems": {},
|
| 182 |
+
"reference_missing_requests": 0
|
| 183 |
+
},
|
| 184 |
+
"top1": {
|
| 185 |
+
"threshold": 0.99,
|
| 186 |
+
"value": 1.0,
|
| 187 |
+
"pass": true
|
| 188 |
+
},
|
| 189 |
+
"dnll": {
|
| 190 |
+
"threshold": 0.02,
|
| 191 |
+
"value": -0.00013262687499793202,
|
| 192 |
+
"pass": true
|
| 193 |
+
}
|
| 194 |
+
},
|
| 195 |
+
"verdict": "PASS",
|
| 196 |
+
"note": "small fixtures cannot resolve 0.3pp accuracy gates; accuracy on a parity fixture is only indicative (synthetic long rows carry the base row's gold label).",
|
| 197 |
+
"source": {
|
| 198 |
+
"file": "runs/macjev/release_2b/parity/compare_gguf_f16_base_vs_block.json",
|
| 199 |
+
"sha256": "079decac551d90c59d056de5468e038209db86d240e4b31623943cae0690e2cf"
|
| 200 |
+
}
|
| 201 |
+
},
|
| 202 |
+
"release_verdict": "PASS"
|
| 203 |
+
},
|
| 204 |
+
"gguf-q8_0": {
|
| 205 |
+
"gate_fixture": {
|
| 206 |
+
"n": 1000,
|
| 207 |
+
"top1_agreement": 0.997,
|
| 208 |
+
"top1_flips": 3,
|
| 209 |
+
"max_abs_dscore": 0.10028290748596191,
|
| 210 |
+
"mean_abs_dscore": 0.017663478106852353,
|
| 211 |
+
"dnll": -0.0005833314057068772,
|
| 212 |
+
"nll_ref": 0.4436679457518203,
|
| 213 |
+
"nll_cand": 0.4430846143461134,
|
| 214 |
+
"acc_ref": 0.808,
|
| 215 |
+
"acc_cand": 0.807,
|
| 216 |
+
"acc_drop_pp": 0.10000000000000009,
|
| 217 |
+
"max_abs_dp": 0.033479594816581415,
|
| 218 |
+
"mean_max_abs_dp": 0.0020247272188215755,
|
| 219 |
+
"gates": {
|
| 220 |
+
"coverage_finite_tokens": {
|
| 221 |
+
"pass": true,
|
| 222 |
+
"problems": {},
|
| 223 |
+
"reference_missing_requests": 0
|
| 224 |
+
},
|
| 225 |
+
"top1": {
|
| 226 |
+
"threshold": 0.98,
|
| 227 |
+
"value": 0.997,
|
| 228 |
+
"pass": true
|
| 229 |
+
},
|
| 230 |
+
"dnll": {
|
| 231 |
+
"threshold": 0.02,
|
| 232 |
+
"value": -0.0005833314057068772,
|
| 233 |
+
"pass": true
|
| 234 |
+
},
|
| 235 |
+
"acc_drop_pp": {
|
| 236 |
+
"threshold": 0.3,
|
| 237 |
+
"value": 0.10000000000000009,
|
| 238 |
+
"resolution_pp": 0.1,
|
| 239 |
+
"pass": true,
|
| 240 |
+
"note": null
|
| 241 |
+
}
|
| 242 |
+
},
|
| 243 |
+
"verdict": "PASS",
|
| 244 |
+
"note": "small fixtures cannot resolve 0.3pp accuracy gates; accuracy on a parity fixture is only indicative (synthetic long rows carry the base row's gold label).",
|
| 245 |
+
"source": {
|
| 246 |
+
"file": "runs/macjev/release_2b/parity/compare_gguf_q8_0_gate_vs_block.json",
|
| 247 |
+
"sha256": "4cd6c6f9e2e340ff327cb68bc289941801c85d5216508b2318ade2b588c18a37"
|
| 248 |
+
}
|
| 249 |
+
},
|
| 250 |
+
"long_fixture": {
|
| 251 |
+
"n": 43,
|
| 252 |
+
"top1_agreement": 1.0,
|
| 253 |
+
"top1_flips": 0,
|
| 254 |
+
"max_abs_dscore": 0.12648522853851318,
|
| 255 |
+
"mean_abs_dscore": 0.01955361688020088,
|
| 256 |
+
"dnll": 0.002535229353331059,
|
| 257 |
+
"nll_ref": 0.670433307194272,
|
| 258 |
+
"nll_cand": 0.672968536547603,
|
| 259 |
+
"acc_ref": 0.7209302325581395,
|
| 260 |
+
"acc_cand": 0.7209302325581395,
|
| 261 |
+
"acc_drop_pp": 0.0,
|
| 262 |
+
"max_abs_dp": 0.021289327356281362,
|
| 263 |
+
"mean_max_abs_dp": 0.0044768677260933745,
|
| 264 |
+
"gates": {
|
| 265 |
+
"coverage_finite_tokens": {
|
| 266 |
+
"pass": true,
|
| 267 |
+
"problems": {},
|
| 268 |
+
"reference_missing_requests": 0
|
| 269 |
+
},
|
| 270 |
+
"top1": {
|
| 271 |
+
"threshold": 0.98,
|
| 272 |
+
"value": 1.0,
|
| 273 |
+
"pass": true
|
| 274 |
+
},
|
| 275 |
+
"dnll": {
|
| 276 |
+
"threshold": 0.02,
|
| 277 |
+
"value": 0.002535229353331059,
|
| 278 |
+
"pass": true
|
| 279 |
+
},
|
| 280 |
+
"acc_drop_pp": {
|
| 281 |
+
"threshold": 0.3,
|
| 282 |
+
"value": 0.0,
|
| 283 |
+
"resolution_pp": 2.3255813953488373,
|
| 284 |
+
"pass": null,
|
| 285 |
+
"note": "UNRESOLVED: 43 gold questions -> one flip = 2.33pp > 0.3pp; this fixture cannot resolve the gate (use the gate fixture with >= 334 rows; statistical power needs far more)"
|
| 286 |
+
}
|
| 287 |
+
},
|
| 288 |
+
"verdict": "INCONCLUSIVE",
|
| 289 |
+
"note": "small fixtures cannot resolve 0.3pp accuracy gates; accuracy on a parity fixture is only indicative (synthetic long rows carry the base row's gold label).",
|
| 290 |
+
"source": {
|
| 291 |
+
"file": "runs/macjev/release_2b/parity/compare_gguf_q8_0_base_vs_block.json",
|
| 292 |
+
"sha256": "79c5564ff7f85af5976082ad003e7a84f96f020abe75c127dc9f31649bd168b8"
|
| 293 |
+
}
|
| 294 |
+
},
|
| 295 |
+
"release_verdict": "PASS"
|
| 296 |
+
},
|
| 297 |
+
"gguf-q4_k_m": {
|
| 298 |
+
"gate_fixture": {
|
| 299 |
+
"n": 1000,
|
| 300 |
+
"top1_agreement": 0.957,
|
| 301 |
+
"top1_flips": 43,
|
| 302 |
+
"max_abs_dscore": 1.5673165321350098,
|
| 303 |
+
"mean_abs_dscore": 0.1311025019278954,
|
| 304 |
+
"dnll": 0.007028574074388894,
|
| 305 |
+
"nll_ref": 0.4436679457518203,
|
| 306 |
+
"nll_cand": 0.4506965198262092,
|
| 307 |
+
"acc_ref": 0.808,
|
| 308 |
+
"acc_cand": 0.811,
|
| 309 |
+
"acc_drop_pp": -0.30000000000000027,
|
| 310 |
+
"max_abs_dp": 0.34599917206983777,
|
| 311 |
+
"mean_max_abs_dp": 0.02317308476687987,
|
| 312 |
+
"gates": {
|
| 313 |
+
"coverage_finite_tokens": {
|
| 314 |
+
"pass": true,
|
| 315 |
+
"problems": {},
|
| 316 |
+
"reference_missing_requests": 0
|
| 317 |
+
},
|
| 318 |
+
"top1": {
|
| 319 |
+
"threshold": null,
|
| 320 |
+
"value": 0.957,
|
| 321 |
+
"pass": null,
|
| 322 |
+
"note": "report only"
|
| 323 |
+
},
|
| 324 |
+
"dnll": {
|
| 325 |
+
"threshold": null,
|
| 326 |
+
"value": 0.007028574074388894,
|
| 327 |
+
"pass": null,
|
| 328 |
+
"note": "report only for 4-bit (as in the pre-registered G5)"
|
| 329 |
+
},
|
| 330 |
+
"acc_drop_pp": {
|
| 331 |
+
"threshold": 1.0,
|
| 332 |
+
"value": -0.30000000000000027,
|
| 333 |
+
"resolution_pp": 0.1,
|
| 334 |
+
"pass": true,
|
| 335 |
+
"note": null
|
| 336 |
+
}
|
| 337 |
+
},
|
| 338 |
+
"verdict": "PASS",
|
| 339 |
+
"note": "small fixtures cannot resolve 0.3pp accuracy gates; accuracy on a parity fixture is only indicative (synthetic long rows carry the base row's gold label).",
|
| 340 |
+
"source": {
|
| 341 |
+
"file": "runs/macjev/release_2b/parity/compare_gguf_q4_k_m_gate_vs_block.json",
|
| 342 |
+
"sha256": "fa6f4bbde3f8dc97c144d94ee604c6ea0386558ac4d03ee803de9650e815c275"
|
| 343 |
+
}
|
| 344 |
+
},
|
| 345 |
+
"long_fixture": {
|
| 346 |
+
"n": 43,
|
| 347 |
+
"top1_agreement": 0.9767441860465116,
|
| 348 |
+
"top1_flips": 1,
|
| 349 |
+
"max_abs_dscore": 1.6832613945007324,
|
| 350 |
+
"mean_abs_dscore": 0.15424594652319,
|
| 351 |
+
"dnll": 0.11204286860779777,
|
| 352 |
+
"nll_ref": 0.670433307194272,
|
| 353 |
+
"nll_cand": 0.7824761758020697,
|
| 354 |
+
"acc_ref": 0.7209302325581395,
|
| 355 |
+
"acc_cand": 0.6976744186046512,
|
| 356 |
+
"acc_drop_pp": 2.3255813953488302,
|
| 357 |
+
"max_abs_dp": 0.15778925110927658,
|
| 358 |
+
"mean_max_abs_dp": 0.047022506153486646,
|
| 359 |
+
"gates": {
|
| 360 |
+
"coverage_finite_tokens": {
|
| 361 |
+
"pass": true,
|
| 362 |
+
"problems": {},
|
| 363 |
+
"reference_missing_requests": 0
|
| 364 |
+
},
|
| 365 |
+
"top1": {
|
| 366 |
+
"threshold": null,
|
| 367 |
+
"value": 0.9767441860465116,
|
| 368 |
+
"pass": null,
|
| 369 |
+
"note": "report only"
|
| 370 |
+
},
|
| 371 |
+
"dnll": {
|
| 372 |
+
"threshold": null,
|
| 373 |
+
"value": 0.11204286860779777,
|
| 374 |
+
"pass": null,
|
| 375 |
+
"note": "report only for 4-bit (as in the pre-registered G5)"
|
| 376 |
+
},
|
| 377 |
+
"acc_drop_pp": {
|
| 378 |
+
"threshold": 1.0,
|
| 379 |
+
"value": 2.3255813953488302,
|
| 380 |
+
"resolution_pp": 2.3255813953488373,
|
| 381 |
+
"pass": null,
|
| 382 |
+
"note": "UNRESOLVED: 43 gold questions -> one flip = 2.33pp > 1.0pp; this fixture cannot resolve the gate (use the gate fixture with >= 100 rows; statistical power needs far more)"
|
| 383 |
+
}
|
| 384 |
+
},
|
| 385 |
+
"verdict": "INCONCLUSIVE",
|
| 386 |
+
"note": "small fixtures cannot resolve 0.3pp accuracy gates; accuracy on a parity fixture is only indicative (synthetic long rows carry the base row's gold label).",
|
| 387 |
+
"source": {
|
| 388 |
+
"file": "runs/macjev/release_2b/parity/compare_gguf_q4_k_m_base_vs_block.json",
|
| 389 |
+
"sha256": "cca6700d953c15c45ef55b443d963d6d955263a2858bf713d9ba73762d78b182"
|
| 390 |
+
}
|
| 391 |
+
},
|
| 392 |
+
"release_verdict": "PASS",
|
| 393 |
+
"note": "4-bit: top-1 / dNLL are report-only by pre-declaration; accuracy-drop gate <= 1.0 pp"
|
| 394 |
+
},
|
| 395 |
+
"mlx-bf16": {
|
| 396 |
+
"gate_fixture": {
|
| 397 |
+
"n": 1000,
|
| 398 |
+
"top1_agreement": 0.997,
|
| 399 |
+
"top1_flips": 3,
|
| 400 |
+
"max_abs_dscore": 0.13961565494537354,
|
| 401 |
+
"mean_abs_dscore": 0.012822698334419146,
|
| 402 |
+
"dnll": 0.0001265220422789204,
|
| 403 |
+
"nll_ref": 0.4436679457518203,
|
| 404 |
+
"nll_cand": 0.4437944677940992,
|
| 405 |
+
"acc_ref": 0.808,
|
| 406 |
+
"acc_cand": 0.805,
|
| 407 |
+
"acc_drop_pp": 0.30000000000000027,
|
| 408 |
+
"max_abs_dp": 0.03549758339084519,
|
| 409 |
+
"mean_max_abs_dp": 0.0025865935031305484,
|
| 410 |
+
"gates": {
|
| 411 |
+
"coverage_finite_tokens": {
|
| 412 |
+
"pass": true,
|
| 413 |
+
"problems": {},
|
| 414 |
+
"reference_missing_requests": 0
|
| 415 |
+
},
|
| 416 |
+
"top1": {
|
| 417 |
+
"threshold": 0.99,
|
| 418 |
+
"value": 0.997,
|
| 419 |
+
"pass": true
|
| 420 |
+
},
|
| 421 |
+
"dnll": {
|
| 422 |
+
"threshold": 0.02,
|
| 423 |
+
"value": 0.0001265220422789204,
|
| 424 |
+
"pass": true
|
| 425 |
+
}
|
| 426 |
+
},
|
| 427 |
+
"verdict": "PASS",
|
| 428 |
+
"note": "small fixtures cannot resolve 0.3pp accuracy gates; accuracy on a parity fixture is only indicative (synthetic long rows carry the base row's gold label).",
|
| 429 |
+
"source": {
|
| 430 |
+
"file": "runs/macjev/release_2b/parity/compare_mlx_bf16_gate_vs_block.json",
|
| 431 |
+
"sha256": "7fa30fa414a4ffc12a7aa6371e77579845c3b816b90da3a813a70fec10ccd9fb"
|
| 432 |
+
}
|
| 433 |
+
},
|
| 434 |
+
"long_fixture": {
|
| 435 |
+
"n": 43,
|
| 436 |
+
"top1_agreement": 1.0,
|
| 437 |
+
"top1_flips": 0,
|
| 438 |
+
"max_abs_dscore": 0.08836114406585693,
|
| 439 |
+
"mean_abs_dscore": 0.01365492056503762,
|
| 440 |
+
"dnll": -0.0026943261000204055,
|
| 441 |
+
"nll_ref": 0.670433307194272,
|
| 442 |
+
"nll_cand": 0.6677389810942516,
|
| 443 |
+
"acc_ref": 0.7209302325581395,
|
| 444 |
+
"acc_cand": 0.7209302325581395,
|
| 445 |
+
"acc_drop_pp": 0.0,
|
| 446 |
+
"max_abs_dp": 0.010765431767972844,
|
| 447 |
+
"mean_max_abs_dp": 0.003890125022245109,
|
| 448 |
+
"gates": {
|
| 449 |
+
"coverage_finite_tokens": {
|
| 450 |
+
"pass": true,
|
| 451 |
+
"problems": {},
|
| 452 |
+
"reference_missing_requests": 0
|
| 453 |
+
},
|
| 454 |
+
"top1": {
|
| 455 |
+
"threshold": 0.99,
|
| 456 |
+
"value": 1.0,
|
| 457 |
+
"pass": true
|
| 458 |
+
},
|
| 459 |
+
"dnll": {
|
| 460 |
+
"threshold": 0.02,
|
| 461 |
+
"value": -0.0026943261000204055,
|
| 462 |
+
"pass": true
|
| 463 |
+
}
|
| 464 |
+
},
|
| 465 |
+
"verdict": "PASS",
|
| 466 |
+
"note": "small fixtures cannot resolve 0.3pp accuracy gates; accuracy on a parity fixture is only indicative (synthetic long rows carry the base row's gold label).",
|
| 467 |
+
"source": {
|
| 468 |
+
"file": "runs/macjev/release_2b/parity/compare_mlx_bf16_base_vs_block.json",
|
| 469 |
+
"sha256": "ca16e5281debaf1bc601b4a8c93cf6c1106f7b032f35c5833baa4fc8178def7c"
|
| 470 |
+
}
|
| 471 |
+
},
|
| 472 |
+
"release_verdict": "PASS"
|
| 473 |
+
},
|
| 474 |
+
"mlx-8bit": {
|
| 475 |
+
"gate_fixture": {
|
| 476 |
+
"n": 1000,
|
| 477 |
+
"top1_agreement": 0.996,
|
| 478 |
+
"top1_flips": 4,
|
| 479 |
+
"max_abs_dscore": 0.3184394836425781,
|
| 480 |
+
"mean_abs_dscore": 0.016680597170951345,
|
| 481 |
+
"dnll": 0.0005035682350758575,
|
| 482 |
+
"nll_ref": 0.4436679457518203,
|
| 483 |
+
"nll_cand": 0.44417151398689614,
|
| 484 |
+
"acc_ref": 0.808,
|
| 485 |
+
"acc_cand": 0.808,
|
| 486 |
+
"acc_drop_pp": 0.0,
|
| 487 |
+
"max_abs_dp": 0.1623697296878569,
|
| 488 |
+
"mean_max_abs_dp": 0.0039011049015487734,
|
| 489 |
+
"gates": {
|
| 490 |
+
"coverage_finite_tokens": {
|
| 491 |
+
"pass": true,
|
| 492 |
+
"problems": {},
|
| 493 |
+
"reference_missing_requests": 0
|
| 494 |
+
},
|
| 495 |
+
"top1": {
|
| 496 |
+
"threshold": 0.98,
|
| 497 |
+
"value": 0.996,
|
| 498 |
+
"pass": true
|
| 499 |
+
},
|
| 500 |
+
"dnll": {
|
| 501 |
+
"threshold": 0.02,
|
| 502 |
+
"value": 0.0005035682350758575,
|
| 503 |
+
"pass": true
|
| 504 |
+
},
|
| 505 |
+
"acc_drop_pp": {
|
| 506 |
+
"threshold": 0.3,
|
| 507 |
+
"value": 0.0,
|
| 508 |
+
"resolution_pp": 0.1,
|
| 509 |
+
"pass": true,
|
| 510 |
+
"note": null
|
| 511 |
+
}
|
| 512 |
+
},
|
| 513 |
+
"verdict": "PASS",
|
| 514 |
+
"note": "small fixtures cannot resolve 0.3pp accuracy gates; accuracy on a parity fixture is only indicative (synthetic long rows carry the base row's gold label).",
|
| 515 |
+
"source": {
|
| 516 |
+
"file": "runs/macjev/release_2b/parity/compare_mlx_affine8-g64_gate_vs_block.json",
|
| 517 |
+
"sha256": "f0e2f44498df00945901c2a9bd5bff6f742d11ab243495c8089eaf0448fda782"
|
| 518 |
+
}
|
| 519 |
+
},
|
| 520 |
+
"long_fixture": {
|
| 521 |
+
"n": 43,
|
| 522 |
+
"top1_agreement": 1.0,
|
| 523 |
+
"top1_flips": 0,
|
| 524 |
+
"max_abs_dscore": 0.4653351306915283,
|
| 525 |
+
"mean_abs_dscore": 0.023077200647273945,
|
| 526 |
+
"dnll": 0.01638063705636561,
|
| 527 |
+
"nll_ref": 0.670433307194272,
|
| 528 |
+
"nll_cand": 0.6868139442506376,
|
| 529 |
+
"acc_ref": 0.7209302325581395,
|
| 530 |
+
"acc_cand": 0.7209302325581395,
|
| 531 |
+
"acc_drop_pp": 0.0,
|
| 532 |
+
"max_abs_dp": 0.04628699142360499,
|
| 533 |
+
"mean_max_abs_dp": 0.007026009064181663,
|
| 534 |
+
"gates": {
|
| 535 |
+
"coverage_finite_tokens": {
|
| 536 |
+
"pass": true,
|
| 537 |
+
"problems": {},
|
| 538 |
+
"reference_missing_requests": 0
|
| 539 |
+
},
|
| 540 |
+
"top1": {
|
| 541 |
+
"threshold": 0.98,
|
| 542 |
+
"value": 1.0,
|
| 543 |
+
"pass": true
|
| 544 |
+
},
|
| 545 |
+
"dnll": {
|
| 546 |
+
"threshold": 0.02,
|
| 547 |
+
"value": 0.01638063705636561,
|
| 548 |
+
"pass": true
|
| 549 |
+
},
|
| 550 |
+
"acc_drop_pp": {
|
| 551 |
+
"threshold": 0.3,
|
| 552 |
+
"value": 0.0,
|
| 553 |
+
"resolution_pp": 2.3255813953488373,
|
| 554 |
+
"pass": null,
|
| 555 |
+
"note": "UNRESOLVED: 43 gold questions -> one flip = 2.33pp > 0.3pp; this fixture cannot resolve the gate (use the gate fixture with >= 334 rows; statistical power needs far more)"
|
| 556 |
+
}
|
| 557 |
+
},
|
| 558 |
+
"verdict": "INCONCLUSIVE",
|
| 559 |
+
"note": "small fixtures cannot resolve 0.3pp accuracy gates; accuracy on a parity fixture is only indicative (synthetic long rows carry the base row's gold label).",
|
| 560 |
+
"source": {
|
| 561 |
+
"file": "runs/macjev/release_2b/parity/compare_mlx_affine8-g64_base_vs_block.json",
|
| 562 |
+
"sha256": "e1911f21ce73dd42d6c57e8349e2ec3221386a2b44ca461a3e50b9a69057ec34"
|
| 563 |
+
}
|
| 564 |
+
},
|
| 565 |
+
"release_verdict": "PASS"
|
| 566 |
+
}
|
| 567 |
+
},
|
| 568 |
+
"torch_runtime_vs_reference_long_fixture": {
|
| 569 |
+
"n": 43,
|
| 570 |
+
"top1_agree": 1.0,
|
| 571 |
+
"max_abs_dp": 4.782633115096857e-06,
|
| 572 |
+
"mean_max_abs_dp": 6.972375795818997e-07
|
| 573 |
+
}
|
| 574 |
+
},
|
| 575 |
+
"decision_index": "requested from the maintainer after release (not run by us)",
|
| 576 |
+
"runtime_parity": {
|
| 577 |
+
"protocol": "the staged runtime scores the long fixture (35 requests / 43 questions, up to 25,600 tokens) from text/ids through its own renderer; raw scores compared with the HF FP32 CPU reference (runs/macjev/runtime_v2_dev/reference_trained/ref_block_fp32.jsonl)",
|
| 578 |
+
"fixture": {
|
| 579 |
+
"file": "runs/macjev/runtime_v2_dev/reference_base/fixture.jsonl",
|
| 580 |
+
"sha256": "2b16d25eafa70c00a1106ba51b94890821b51ecb4fa393abb12403c8739ef314"
|
| 581 |
+
},
|
| 582 |
+
"cpu_fp32_threads4": {
|
| 583 |
+
"requests": 35,
|
| 584 |
+
"questions": 43,
|
| 585 |
+
"max_abs_dscore": 1.502e-05,
|
| 586 |
+
"top1_flips": 0,
|
| 587 |
+
"meta_ok_all": true,
|
| 588 |
+
"per_category": {
|
| 589 |
+
"catalogue_overflow": {
|
| 590 |
+
"n": 3,
|
| 591 |
+
"max_abs_dscore": 1.502e-05,
|
| 592 |
+
"top1_flips": 0
|
| 593 |
+
},
|
| 594 |
+
"catalogue_overflow_long_state": {
|
| 595 |
+
"n": 1,
|
| 596 |
+
"max_abs_dscore": 6.437e-06,
|
| 597 |
+
"top1_flips": 0
|
| 598 |
+
},
|
| 599 |
+
"long_16k": {
|
| 600 |
+
"n": 3,
|
| 601 |
+
"max_abs_dscore": 6.676e-06,
|
| 602 |
+
"top1_flips": 0
|
| 603 |
+
},
|
| 604 |
+
"long_24k": {
|
| 605 |
+
"n": 2,
|
| 606 |
+
"max_abs_dscore": 4.053e-06,
|
| 607 |
+
"top1_flips": 0
|
| 608 |
+
},
|
| 609 |
+
"many_options": {
|
| 610 |
+
"n": 2,
|
| 611 |
+
"max_abs_dscore": 5.96e-06,
|
| 612 |
+
"top1_flips": 0
|
| 613 |
+
},
|
| 614 |
+
"multi_block_3k": {
|
| 615 |
+
"n": 2,
|
| 616 |
+
"max_abs_dscore": 1.132e-05,
|
| 617 |
+
"top1_flips": 0
|
| 618 |
+
},
|
| 619 |
+
"multi_block_5k": {
|
| 620 |
+
"n": 2,
|
| 621 |
+
"max_abs_dscore": 5.364e-06,
|
| 622 |
+
"top1_flips": 0
|
| 623 |
+
},
|
| 624 |
+
"multi_block_9k": {
|
| 625 |
+
"n": 2,
|
| 626 |
+
"max_abs_dscore": 2.384e-06,
|
| 627 |
+
"top1_flips": 0
|
| 628 |
+
},
|
| 629 |
+
"multi_question": {
|
| 630 |
+
"n": 10,
|
| 631 |
+
"max_abs_dscore": 7.391e-06,
|
| 632 |
+
"top1_flips": 0
|
| 633 |
+
},
|
| 634 |
+
"prefix_boundary": {
|
| 635 |
+
"n": 7,
|
| 636 |
+
"max_abs_dscore": 9.179e-06,
|
| 637 |
+
"top1_flips": 0
|
| 638 |
+
},
|
| 639 |
+
"qtype_choice": {
|
| 640 |
+
"n": 1,
|
| 641 |
+
"max_abs_dscore": 5.841e-06,
|
| 642 |
+
"top1_flips": 0
|
| 643 |
+
},
|
| 644 |
+
"qtype_noul": {
|
| 645 |
+
"n": 1,
|
| 646 |
+
"max_abs_dscore": 1.609e-06,
|
| 647 |
+
"top1_flips": 0
|
| 648 |
+
},
|
| 649 |
+
"qtype_score": {
|
| 650 |
+
"n": 1,
|
| 651 |
+
"max_abs_dscore": 3.934e-06,
|
| 652 |
+
"top1_flips": 0
|
| 653 |
+
},
|
| 654 |
+
"short_sb": {
|
| 655 |
+
"n": 6,
|
| 656 |
+
"max_abs_dscore": 6.02e-06,
|
| 657 |
+
"top1_flips": 0
|
| 658 |
+
}
|
| 659 |
+
},
|
| 660 |
+
"source": {
|
| 661 |
+
"file": "runs/macjev/runtime_v2_dev/verify_release_torch/parity_cpu_fp32_t4.log",
|
| 662 |
+
"sha256": "616618ec2b61c472137ea4cb418dc0b79019b699e7fa6f044bf06c166cb970ba"
|
| 663 |
+
}
|
| 664 |
+
},
|
| 665 |
+
"mps_fp32_long_16k_24k": {
|
| 666 |
+
"requests": 2,
|
| 667 |
+
"questions": 2,
|
| 668 |
+
"max_abs_dscore": 8.821e-06,
|
| 669 |
+
"top1_flips": 0,
|
| 670 |
+
"meta_ok_all": true,
|
| 671 |
+
"per_category": {
|
| 672 |
+
"long_16k": {
|
| 673 |
+
"n": 1,
|
| 674 |
+
"max_abs_dscore": 2.742e-06,
|
| 675 |
+
"top1_flips": 0
|
| 676 |
+
},
|
| 677 |
+
"long_24k": {
|
| 678 |
+
"n": 1,
|
| 679 |
+
"max_abs_dscore": 8.821e-06,
|
| 680 |
+
"top1_flips": 0
|
| 681 |
+
}
|
| 682 |
+
},
|
| 683 |
+
"source": {
|
| 684 |
+
"file": "runs/macjev/runtime_v2_dev/verify_release_torch/parity_mps_fp32_long.log",
|
| 685 |
+
"sha256": "04e40ead1c8694fb3bbda9714074701777ea48d8d2cb3489df738ad902f351d8"
|
| 686 |
+
}
|
| 687 |
+
},
|
| 688 |
+
"render_and_tiny_model": {
|
| 689 |
+
"render": {
|
| 690 |
+
"question_errors": 2,
|
| 691 |
+
"qerr_kinds": [
|
| 692 |
+
"question text ('ins') must be a non-empty string"
|
| 693 |
+
],
|
| 694 |
+
"n_rendered_equal": 406,
|
| 695 |
+
"catalogue_overflow": 43,
|
| 696 |
+
"both_rejected": 2,
|
| 697 |
+
"edges": {
|
| 698 |
+
"short_2048": 2014,
|
| 699 |
+
"short_2049": [
|
| 700 |
+
2015,
|
| 701 |
+
2074
|
| 702 |
+
]
|
| 703 |
+
},
|
| 704 |
+
"big_k_blocks": 14,
|
| 705 |
+
"big_k_tokens": 23102
|
| 706 |
+
},
|
| 707 |
+
"tiny": {
|
| 708 |
+
"cases": 24,
|
| 709 |
+
"max_abs_d_vs_dev_ref": 2.1457672119140625e-06
|
| 710 |
+
},
|
| 711 |
+
"source": {
|
| 712 |
+
"file": "runs/macjev/runtime_v2_dev/verify_release_torch/v_tiny_and_render.json",
|
| 713 |
+
"sha256": "d3ff75211cfac2f26f0f7763ee937dee8d1e01eceae43e37f16f9ec5d0bb02bf"
|
| 714 |
+
}
|
| 715 |
+
},
|
| 716 |
+
"jev_style_package_e2e": {
|
| 717 |
+
"source": {
|
| 718 |
+
"file": "runs/macjev/runtime_v2_dev/verify_release_torch/v_jevstyle_e2e.json",
|
| 719 |
+
"sha256": "812cbee4d6c8b0af5cd81b6b5aaa8b24f55c07c0ec934cc81c8f61c634e734a6"
|
| 720 |
+
},
|
| 721 |
+
"note": "systemone request through the jev-style package adapter (torch CPU)"
|
| 722 |
+
},
|
| 723 |
+
"runtime_file": {
|
| 724 |
+
"file": "jev_style_decision.py",
|
| 725 |
+
"sha256_now": "5ecba24cdfff4f0e043c2ea48c9c7f514907c6804f265906e21dec0f1b20dbd6",
|
| 726 |
+
"mtime_unix": 1790448336.7685351
|
| 727 |
+
},
|
| 728 |
+
"original_records_predate_last_runtime_edit": true,
|
| 729 |
+
"reverified_on_current_runtime": true,
|
| 730 |
+
"recorded_before_last_runtime_edit": false,
|
| 731 |
+
"note": "the records above were written before the last edit of the runtime file; the runtime as staged now (sha256 runtime_file.sha256_now) was re-verified on the long fixture, see 'reverified' (reverified.runtime_sha256 == runtime_file.sha256_now).",
|
| 732 |
+
"reverified": {
|
| 733 |
+
"runtime_file": "jev_style_decision.py",
|
| 734 |
+
"runtime_sha256": "5ecba24cdfff4f0e043c2ea48c9c7f514907c6804f265906e21dec0f1b20dbd6",
|
| 735 |
+
"shared_core_sha256": "56deae095206fc59b9a30d8626ac5d27cacddcd94d7c7f08f6f4bc53d326a002",
|
| 736 |
+
"what": "PyTorch FP32 CPU, requests with <= 6000 tokens per question",
|
| 737 |
+
"loaded_from": "runs/macjev/hf_staging/Jev-Style-2B-Decision-v3",
|
| 738 |
+
"verify_manifest": true,
|
| 739 |
+
"compared_with": {
|
| 740 |
+
"file": "runs/macjev/runtime_v2_dev/reference_trained/ref_block_fp32.jsonl",
|
| 741 |
+
"sha256": "09ff7d4fdd97c52c28429139a4f8d53dd224a5e0bcc69b1a318978abad5e136c"
|
| 742 |
+
},
|
| 743 |
+
"fixture": {
|
| 744 |
+
"file": "runs/macjev/runtime_v2_dev/reference_base/fixture.jsonl",
|
| 745 |
+
"sha256": "2b16d25eafa70c00a1106ba51b94890821b51ecb4fa393abb12403c8739ef314"
|
| 746 |
+
},
|
| 747 |
+
"questions": 34,
|
| 748 |
+
"skipped_questions": 9,
|
| 749 |
+
"max_abs_score_diff": 1.5020370483398438e-05,
|
| 750 |
+
"top1_same": "34/34",
|
| 751 |
+
"token_or_overflow_mismatches": [],
|
| 752 |
+
"seconds": 411.6,
|
| 753 |
+
"finished_unix": 1790449904.6816142,
|
| 754 |
+
"source": {
|
| 755 |
+
"file": "runs/macjev/hf_staging/_2b_tools/reverify_main.json",
|
| 756 |
+
"sha256": "3b8e573deb626385ce469b289e8e753d60c499ce21efcdeefd20a8e44b4d6c0a"
|
| 757 |
+
}
|
| 758 |
+
},
|
| 759 |
+
"reverified_mps_fp32_long_16k_24k": {
|
| 760 |
+
"what": "the staged jev_style_decision.py on MPS float32, fixture requests long_16k-1 and long_24k-1, raw scores vs the HF FP32 CPU reference (runtime_v2_dev/verify_release_torch/vparity.py, run on this folder)",
|
| 761 |
+
"runtime_sha256": "5ecba24cdfff4f0e043c2ea48c9c7f514907c6804f265906e21dec0f1b20dbd6",
|
| 762 |
+
"runtime_edited_after_this_record": false,
|
| 763 |
+
"requests": 2,
|
| 764 |
+
"questions": 2,
|
| 765 |
+
"max_abs_dscore": 8.821e-06,
|
| 766 |
+
"top1_flips": 0,
|
| 767 |
+
"meta_ok_all": true,
|
| 768 |
+
"per_category": {
|
| 769 |
+
"long_16k": {
|
| 770 |
+
"n": 1,
|
| 771 |
+
"max_abs_dscore": 2.742e-06,
|
| 772 |
+
"top1_flips": 0
|
| 773 |
+
},
|
| 774 |
+
"long_24k": {
|
| 775 |
+
"n": 1,
|
| 776 |
+
"max_abs_dscore": 8.821e-06,
|
| 777 |
+
"top1_flips": 0
|
| 778 |
+
}
|
| 779 |
+
},
|
| 780 |
+
"source": {
|
| 781 |
+
"file": "runs/macjev/hf_staging/_2b_tools/reverify_main_mps_long.log",
|
| 782 |
+
"sha256": "98720ecc5f12d24f7a12add39a7cf332f12c300c8177eed2665a3077d0e0f0b1"
|
| 783 |
+
}
|
| 784 |
+
}
|
| 785 |
+
},
|
| 786 |
+
"latency": {
|
| 787 |
+
"file": "validation/latency_2b.json",
|
| 788 |
+
"sha256": "458d00e0c81b3165072b8547278e6039b9ae0d45d54b7421008ef24c1d24ca3d",
|
| 789 |
+
"machine": {
|
| 790 |
+
"chip": "Apple M1 Max",
|
| 791 |
+
"memory_bytes": 68719476736,
|
| 792 |
+
"macos": "15.7.5",
|
| 793 |
+
"python": "3.12.13"
|
| 794 |
+
},
|
| 795 |
+
"backends_shown_on_card": [
|
| 796 |
+
"gguf-f16",
|
| 797 |
+
"mlx-bf16",
|
| 798 |
+
"torch-mps-fp32"
|
| 799 |
+
],
|
| 800 |
+
"rows": 18,
|
| 801 |
+
"rows_in_file": 36,
|
| 802 |
+
"card_generator": "runs/macjev/release_2b/cards/_build/latency_tables.py"
|
| 803 |
+
}
|
| 804 |
+
}
|
requirements.txt
ADDED
|
@@ -0,0 +1,5 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# tested with: python 3.12.13, torch 2.14.0, transformers 5.17.0, tokenizers 0.23.2, numpy 2.5.3
|
| 2 |
+
torch==2.14.0
|
| 3 |
+
transformers==5.17.0 # needs Qwen3.5 support (transformers.models.qwen3_5) and multi-token cache continuation in Gated DeltaNet
|
| 4 |
+
tokenizers==0.23.2
|
| 5 |
+
numpy==2.5.3
|
tokenizer.json
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:06b9509352d2af50381ab2247e083b80d32d5c0aba91c272ca9ff729b6a0e523
|
| 3 |
+
size 19989325
|
tokenizer_config.json
ADDED
|
@@ -0,0 +1,32 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"add_prefix_space": false,
|
| 3 |
+
"audio_bos_token": "<|audio_start|>",
|
| 4 |
+
"audio_eos_token": "<|audio_end|>",
|
| 5 |
+
"audio_token": "<|audio_pad|>",
|
| 6 |
+
"backend": "tokenizers",
|
| 7 |
+
"bos_token": null,
|
| 8 |
+
"clean_up_tokenization_spaces": false,
|
| 9 |
+
"eos_token": "<|im_end|>",
|
| 10 |
+
"errors": "replace",
|
| 11 |
+
"image_token": "<|image_pad|>",
|
| 12 |
+
"is_local": true,
|
| 13 |
+
"local_files_only": false,
|
| 14 |
+
"model_max_length": 262144,
|
| 15 |
+
"model_specific_special_tokens": {
|
| 16 |
+
"audio_bos_token": "<|audio_start|>",
|
| 17 |
+
"audio_eos_token": "<|audio_end|>",
|
| 18 |
+
"audio_token": "<|audio_pad|>",
|
| 19 |
+
"image_token": "<|image_pad|>",
|
| 20 |
+
"video_token": "<|video_pad|>",
|
| 21 |
+
"vision_bos_token": "<|vision_start|>",
|
| 22 |
+
"vision_eos_token": "<|vision_end|>"
|
| 23 |
+
},
|
| 24 |
+
"pad_token": "<|endoftext|>",
|
| 25 |
+
"pretokenize_regex": "(?i:'s|'t|'re|'ve|'m|'ll|'d)|[^\\r\\n\\p{L}\\p{N}]?[\\p{L}\\p{M}]+|\\p{N}| ?[^\\s\\p{L}\\p{M}\\p{N}]+[\\r\\n]*|\\s*[\\r\\n]+|\\s+(?!\\S)|\\s+",
|
| 26 |
+
"split_special_tokens": false,
|
| 27 |
+
"tokenizer_class": "Qwen2Tokenizer",
|
| 28 |
+
"unk_token": null,
|
| 29 |
+
"video_token": "<|video_pad|>",
|
| 30 |
+
"vision_bos_token": "<|vision_start|>",
|
| 31 |
+
"vision_eos_token": "<|vision_end|>"
|
| 32 |
+
}
|
validation/SOURCES.json
ADDED
|
@@ -0,0 +1,81 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"note": "copies of the verification / benchmark records behind release_config.json and the model card; local absolute paths replaced by repository-relative ones (local_paths_scrubbed); source_sha256 = the unmodified file (equal to the published copy when local_paths_scrubbed is false)",
|
| 3 |
+
"files": {
|
| 4 |
+
"parity/cross_format_dp.json": {
|
| 5 |
+
"source": "runs/macjev/release_2b/parity/cross_format_dp.json",
|
| 6 |
+
"source_sha256": "c7332df0f02244416b01e49ecb037c76d4bf2643a2b42505ff1dfe896879e533",
|
| 7 |
+
"local_paths_scrubbed": false
|
| 8 |
+
},
|
| 9 |
+
"parity/PREDECLARED_RELEASE_GATES_2B.md": {
|
| 10 |
+
"source": "runs/macjev/runtime_v2_dev/PREDECLARED_RELEASE_GATES_2B.md",
|
| 11 |
+
"source_sha256": "783aec77300779582911cdc57c71cf8b101b0cd5ca040073f7e1fa3ac20af08e",
|
| 12 |
+
"local_paths_scrubbed": false
|
| 13 |
+
},
|
| 14 |
+
"runtime/parity_cpu_fp32_t4.log": {
|
| 15 |
+
"source": "runs/macjev/runtime_v2_dev/verify_release_torch/parity_cpu_fp32_t4.log",
|
| 16 |
+
"source_sha256": "616618ec2b61c472137ea4cb418dc0b79019b699e7fa6f044bf06c166cb970ba",
|
| 17 |
+
"local_paths_scrubbed": false
|
| 18 |
+
},
|
| 19 |
+
"runtime/parity_mps_fp32_long.log": {
|
| 20 |
+
"source": "runs/macjev/runtime_v2_dev/verify_release_torch/parity_mps_fp32_long.log",
|
| 21 |
+
"source_sha256": "04e40ead1c8694fb3bbda9714074701777ea48d8d2cb3489df738ad902f351d8",
|
| 22 |
+
"local_paths_scrubbed": false
|
| 23 |
+
},
|
| 24 |
+
"runtime/v_tiny_and_render.json": {
|
| 25 |
+
"source": "runs/macjev/runtime_v2_dev/verify_release_torch/v_tiny_and_render.json",
|
| 26 |
+
"source_sha256": "d3ff75211cfac2f26f0f7763ee937dee8d1e01eceae43e37f16f9ec5d0bb02bf",
|
| 27 |
+
"local_paths_scrubbed": false
|
| 28 |
+
},
|
| 29 |
+
"runtime/v_jevstyle_e2e.json": {
|
| 30 |
+
"source": "runs/macjev/runtime_v2_dev/verify_release_torch/v_jevstyle_e2e.json",
|
| 31 |
+
"source_sha256": "812cbee4d6c8b0af5cd81b6b5aaa8b24f55c07c0ec934cc81c8f61c634e734a6",
|
| 32 |
+
"local_paths_scrubbed": false
|
| 33 |
+
},
|
| 34 |
+
"runtime/reverify_main.json": {
|
| 35 |
+
"source": "runs/macjev/hf_staging/_2b_tools/reverify_main.json",
|
| 36 |
+
"source_sha256": "3b8e573deb626385ce469b289e8e753d60c499ce21efcdeefd20a8e44b4d6c0a",
|
| 37 |
+
"local_paths_scrubbed": false
|
| 38 |
+
},
|
| 39 |
+
"runtime/reverify_main_mps_long.log": {
|
| 40 |
+
"source": "runs/macjev/hf_staging/_2b_tools/reverify_main_mps_long.log",
|
| 41 |
+
"source_sha256": "98720ecc5f12d24f7a12add39a7cf332f12c300c8177eed2665a3077d0e0f0b1",
|
| 42 |
+
"local_paths_scrubbed": false
|
| 43 |
+
},
|
| 44 |
+
"benchmarks/jevbench_v1.4.1_results.json": {
|
| 45 |
+
"source": "runs/macjev/bench_2b/jevbench/gguf_f16/results.json",
|
| 46 |
+
"source_sha256": "9a467fb4ddcc9a42f9d82ff8f8cf1ce5cfafd51d27b8d4dca2b9c1a681f67a9c",
|
| 47 |
+
"local_paths_scrubbed": false
|
| 48 |
+
},
|
| 49 |
+
"benchmarks/jevbench_v1.4.1_results.md": {
|
| 50 |
+
"source": "runs/macjev/bench_2b/jevbench/gguf_f16/results.md",
|
| 51 |
+
"source_sha256": "824ffa6ae920595e9277c9d6c41770bf6b2d9fc2e71ff7de9afe6ee635b69ae8",
|
| 52 |
+
"local_paths_scrubbed": false
|
| 53 |
+
},
|
| 54 |
+
"benchmarks/zeroshot_metrics.json": {
|
| 55 |
+
"source": "runs/macjev/bench_2b/zeroshot/gguf_f16/metrics.json",
|
| 56 |
+
"source_sha256": "f80c80ae55678cce974927df0c6a33a5bf5e2ba85e9b14a181e6e5d16bcee3c5",
|
| 57 |
+
"local_paths_scrubbed": true,
|
| 58 |
+
"published_sha256": "479ddbaa101f843487471500061906e78ce28f9af09c65eaadc3cee4b5ebdb4a"
|
| 59 |
+
},
|
| 60 |
+
"benchmarks/zeroshot_comparison.md": {
|
| 61 |
+
"source": "runs/macjev/bench_2b/zeroshot/gguf_f16/comparison.md",
|
| 62 |
+
"source_sha256": "34828fa9375ea717c866b1e749d3fe902f0b52303c807289a769934760f6dad0",
|
| 63 |
+
"local_paths_scrubbed": false
|
| 64 |
+
},
|
| 65 |
+
"benchmarks/contamination.json": {
|
| 66 |
+
"source": "runs/macjev/release_2b/cards/_build/contamination_public.json",
|
| 67 |
+
"source_sha256": "87f7f645b950b4cd626ff248b1899578c078db74d4c74bc944b017badc06a8e8",
|
| 68 |
+
"local_paths_scrubbed": false
|
| 69 |
+
},
|
| 70 |
+
"latency_2b.json": {
|
| 71 |
+
"source": "runs/macjev/release_2b/latency_2b.json",
|
| 72 |
+
"source_sha256": "458d00e0c81b3165072b8547278e6039b9ae0d45d54b7421008ef24c1d24ca3d",
|
| 73 |
+
"local_paths_scrubbed": false
|
| 74 |
+
},
|
| 75 |
+
"data_sources.json": {
|
| 76 |
+
"source": "runs/macjev/release_2b/cards/_build/data_sources.json",
|
| 77 |
+
"source_sha256": "415fa9dcb893dc71d97d76652fbf03600a72681c15f7248ef46035d85ea56d7c",
|
| 78 |
+
"local_paths_scrubbed": false
|
| 79 |
+
}
|
| 80 |
+
}
|
| 81 |
+
}
|
validation/benchmarks/contamination.json
ADDED
|
@@ -0,0 +1,110 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"note": "Public copy of the contamination scan of the 2B training pool. Matched pool rows are given by their dataset id (pool_row_sources); per-source pool row counts and internal records are not included. zeroshot.sets lists the three zero-shot sets this model was evaluated on (tweet_topic, fin_topic, daily_dialog).",
|
| 3 |
+
"pool": "reduced-v1/main",
|
| 4 |
+
"files": [
|
| 5 |
+
"train.jsonl",
|
| 6 |
+
"format_train.jsonl",
|
| 7 |
+
"dev.jsonl",
|
| 8 |
+
"cal.jsonl"
|
| 9 |
+
],
|
| 10 |
+
"rows_scanned": {
|
| 11 |
+
"train.jsonl": 463208,
|
| 12 |
+
"format_train.jsonl": 500,
|
| 13 |
+
"dev.jsonl": 27109,
|
| 14 |
+
"cal.jsonl": 3325
|
| 15 |
+
},
|
| 16 |
+
"decode": {
|
| 17 |
+
"prefix_exact": 494142,
|
| 18 |
+
"head_parsed": 493642
|
| 19 |
+
},
|
| 20 |
+
"tokenizer": "Qwen/Qwen3.5-2B@15852e8c16360a2fea060d615a32b45270f8a8fc",
|
| 21 |
+
"seconds": 318.62241888046265,
|
| 22 |
+
"jevbench": {
|
| 23 |
+
"n_items": 231,
|
| 24 |
+
"hits_state": [],
|
| 25 |
+
"hits_ins": [],
|
| 26 |
+
"hits_leaf": [],
|
| 27 |
+
"hits_ngram_state": {},
|
| 28 |
+
"hits_ngram_ins_extension": {},
|
| 29 |
+
"n_items_with_ngram_hits_state": 0,
|
| 30 |
+
"n_items_with_ngram_hits_ins": 0,
|
| 31 |
+
"method": {
|
| 32 |
+
"state": "content_hash of the whole serialized state",
|
| 33 |
+
"ins": "content_hash of the instruction",
|
| 34 |
+
"leaf": "content_hash of every state string leaf >= 32 chars",
|
| 35 |
+
"ngram": "13-word shingles of the normalized state (pool stride 4); extension: same on the pool instruction"
|
| 36 |
+
}
|
| 37 |
+
},
|
| 38 |
+
"zeroshot": {
|
| 39 |
+
"shingle": 8,
|
| 40 |
+
"near_dup_fraction": 0.5,
|
| 41 |
+
"sets": {
|
| 42 |
+
"tweet_topic": {
|
| 43 |
+
"n": 1693,
|
| 44 |
+
"exact_overlap": 0,
|
| 45 |
+
"exact_overlap_generic_short": 0,
|
| 46 |
+
"near_duplicate_only": 0,
|
| 47 |
+
"exact_pool_rows_by_file": {},
|
| 48 |
+
"near_pool_rows_by_file": {},
|
| 49 |
+
"examples": [],
|
| 50 |
+
"generic_examples": [],
|
| 51 |
+
"near_examples": []
|
| 52 |
+
},
|
| 53 |
+
"fin_topic": {
|
| 54 |
+
"n": 4117,
|
| 55 |
+
"exact_overlap": 0,
|
| 56 |
+
"exact_overlap_generic_short": 0,
|
| 57 |
+
"near_duplicate_only": 0,
|
| 58 |
+
"exact_pool_rows_by_file": {},
|
| 59 |
+
"near_pool_rows_by_file": {},
|
| 60 |
+
"examples": [],
|
| 61 |
+
"generic_examples": [],
|
| 62 |
+
"near_examples": []
|
| 63 |
+
},
|
| 64 |
+
"daily_dialog": {
|
| 65 |
+
"n": 7740,
|
| 66 |
+
"exact_overlap": 0,
|
| 67 |
+
"exact_overlap_generic_short": 1,
|
| 68 |
+
"near_duplicate_only": 3,
|
| 69 |
+
"exact_pool_rows_by_file": {},
|
| 70 |
+
"near_pool_rows_by_file": {
|
| 71 |
+
"train.jsonl": 5
|
| 72 |
+
},
|
| 73 |
+
"examples": [],
|
| 74 |
+
"generic_examples": [
|
| 75 |
+
{
|
| 76 |
+
"dataset_index": 3850,
|
| 77 |
+
"text": " Thanks a lot ",
|
| 78 |
+
"pool_row_sources": [
|
| 79 |
+
"train.jsonl:google-research-datasets/schema_guided_dstc8",
|
| 80 |
+
"train.jsonl:clinc150"
|
| 81 |
+
]
|
| 82 |
+
}
|
| 83 |
+
],
|
| 84 |
+
"near_examples": [
|
| 85 |
+
{
|
| 86 |
+
"dataset_index": 3522,
|
| 87 |
+
"text": " What do you like to do in your spare time ? ",
|
| 88 |
+
"pool_row_sources": [
|
| 89 |
+
"train.jsonl:clinc150"
|
| 90 |
+
]
|
| 91 |
+
},
|
| 92 |
+
{
|
| 93 |
+
"dataset_index": 1034,
|
| 94 |
+
"text": " Is there anything else I can do for you ? ",
|
| 95 |
+
"pool_row_sources": [
|
| 96 |
+
"train.jsonl:google-research-datasets/schema_guided_dstc8"
|
| 97 |
+
]
|
| 98 |
+
},
|
| 99 |
+
{
|
| 100 |
+
"dataset_index": 1604,
|
| 101 |
+
"text": " What was the score at the end of the game ? ",
|
| 102 |
+
"pool_row_sources": [
|
| 103 |
+
"train.jsonl:ucinlp/drop"
|
| 104 |
+
]
|
| 105 |
+
}
|
| 106 |
+
]
|
| 107 |
+
}
|
| 108 |
+
}
|
| 109 |
+
}
|
| 110 |
+
}
|
validation/benchmarks/jevbench_v1.4.1_results.json
ADDED
|
@@ -0,0 +1,511 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"benchmark": "jevbench-v1.4.1",
|
| 3 |
+
"repo": "https://github.com/fstandhartinger/jevbench",
|
| 4 |
+
"commit": "24b9b5c1609a7a9e8fa14f49e5985a836c9dc842",
|
| 5 |
+
"adapter": "macjev-ext-jevbench-v2 (metrics: macjev-ext-jevbench-v1)",
|
| 6 |
+
"vendor_verify": {
|
| 7 |
+
"ok": true,
|
| 8 |
+
"commit": "24b9b5c1609a7a9e8fa14f49e5985a836c9dc842",
|
| 9 |
+
"files": 13,
|
| 10 |
+
"source_json_sha256": "75b86955079a063422c79f5c31e8c74203609b9a492227855e2a9399c937b693"
|
| 11 |
+
},
|
| 12 |
+
"scorer": {
|
| 13 |
+
"scorer": "macjev-v2-gguf",
|
| 14 |
+
"readout": "verdict",
|
| 15 |
+
"kind": "gguf",
|
| 16 |
+
"engine_class": "macjev.export.gguf_v2.GGUFScorerV2",
|
| 17 |
+
"arch": "qwen3_5",
|
| 18 |
+
"template": "macjev-render-v2-long-options",
|
| 19 |
+
"layout": "sb",
|
| 20 |
+
"block": 2048,
|
| 21 |
+
"max_len": 25600,
|
| 22 |
+
"head_max": null,
|
| 23 |
+
"dtype": "gguf",
|
| 24 |
+
"base": "runs/macjev/release_2b/gguf/model-f16.gguf",
|
| 25 |
+
"sha256": "c1948e55d3a498292b818451b7726aca540c96f70c95352554f27a965ef3304b"
|
| 26 |
+
},
|
| 27 |
+
"model_name": "Jev-Style-2B-Decision-v3-GGUF-F16",
|
| 28 |
+
"n_items": 231,
|
| 29 |
+
"seconds": 262.2442800998688,
|
| 30 |
+
"timing": {
|
| 31 |
+
"n_items": 231,
|
| 32 |
+
"tokens": 144044,
|
| 33 |
+
"seconds": 261.91108745516976,
|
| 34 |
+
"tokens_per_second": 549.9728988168758,
|
| 35 |
+
"seconds_per_item": 1.1338142314076614
|
| 36 |
+
},
|
| 37 |
+
"files_sha256": {
|
| 38 |
+
"predictions.jsonl": "3168be473c97b93d75fa691686623ada8a2f9540fd1aceffeaf9e206608ef8ee",
|
| 39 |
+
"answers.jsonl": "e3bbb96c40a48fdd28e96aa9e8c34ce1c3fc2d2715f0a777ca35849e38fe5638",
|
| 40 |
+
"harness_records.jsonl": "b44d4b5389082af91330dc9d328f86ba5e3e599b3c69036c0ec6f1d98b946004",
|
| 41 |
+
"timings.jsonl": "73795be0585930e2a1b6b24d91b8349b434e58ef2a82144f679797e9e4f3775e"
|
| 42 |
+
},
|
| 43 |
+
"protocol": {
|
| 44 |
+
"template": "macjev-render-v2-long-options",
|
| 45 |
+
"layout": "sb",
|
| 46 |
+
"block": 2048,
|
| 47 |
+
"total_budget_tokens": 25600,
|
| 48 |
+
"truncation": "never",
|
| 49 |
+
"question_options_cap": null,
|
| 50 |
+
"over_budget_rule": "complete rendering > 25,600 tokens -> status unsupported (InputBudgetError), counted per benchmark and scored as wrong",
|
| 51 |
+
"catalogue_overflow_rule": "question+options over one 2,048-token block -> numbered catalogue in prefix blocks + numbered-option rubric (RendererV2); counted per benchmark",
|
| 52 |
+
"readout": "FP32 h_slot . (W_yes - W_no) at each option slot; p = softmax(scores / T_global)"
|
| 53 |
+
},
|
| 54 |
+
"catalogue_overflow": {},
|
| 55 |
+
"utc": "2026-09-26T12:06:27Z",
|
| 56 |
+
"public_accuracy": 0.7359307359307359,
|
| 57 |
+
"public_accuracy_counts": {
|
| 58 |
+
"correct": 170,
|
| 59 |
+
"scorable": 231
|
| 60 |
+
},
|
| 61 |
+
"public_accuracy_independent_check": 0.7359307359307359,
|
| 62 |
+
"tiers": {
|
| 63 |
+
"easy": {
|
| 64 |
+
"n": 48,
|
| 65 |
+
"n_scorable": 48,
|
| 66 |
+
"n_correct": 48,
|
| 67 |
+
"accuracy": 1.0,
|
| 68 |
+
"schema_validity": 1.0,
|
| 69 |
+
"schema_validity_strict": 1.0,
|
| 70 |
+
"operational_success": 1.0,
|
| 71 |
+
"brier_mean": 0.0016946904719700839,
|
| 72 |
+
"ece_top_label_10bin": 0.01884318271512942,
|
| 73 |
+
"calibration_n": 48,
|
| 74 |
+
"ordinal_mae": null,
|
| 75 |
+
"per_family": {
|
| 76 |
+
"extraction": {
|
| 77 |
+
"n": 12,
|
| 78 |
+
"accuracy": 1.0
|
| 79 |
+
},
|
| 80 |
+
"fact": {
|
| 81 |
+
"n": 12,
|
| 82 |
+
"accuracy": 1.0
|
| 83 |
+
},
|
| 84 |
+
"intent": {
|
| 85 |
+
"n": 12,
|
| 86 |
+
"accuracy": 1.0
|
| 87 |
+
},
|
| 88 |
+
"tool_selection": {
|
| 89 |
+
"n": 12,
|
| 90 |
+
"accuracy": 1.0
|
| 91 |
+
}
|
| 92 |
+
}
|
| 93 |
+
},
|
| 94 |
+
"standard": {
|
| 95 |
+
"n": 72,
|
| 96 |
+
"n_scorable": 72,
|
| 97 |
+
"n_correct": 69,
|
| 98 |
+
"accuracy": 0.9583333333333334,
|
| 99 |
+
"schema_validity": 1.0,
|
| 100 |
+
"schema_validity_strict": 1.0,
|
| 101 |
+
"operational_success": 1.0,
|
| 102 |
+
"brier_mean": 0.07269926087469171,
|
| 103 |
+
"ece_top_label_10bin": 0.09887602156622965,
|
| 104 |
+
"calibration_n": 72,
|
| 105 |
+
"ordinal_mae": 0.10494098738063083,
|
| 106 |
+
"per_family": {
|
| 107 |
+
"adequacy": {
|
| 108 |
+
"n": 12,
|
| 109 |
+
"accuracy": 0.8333333333333334
|
| 110 |
+
},
|
| 111 |
+
"extraction": {
|
| 112 |
+
"n": 12,
|
| 113 |
+
"accuracy": 1.0
|
| 114 |
+
},
|
| 115 |
+
"intent": {
|
| 116 |
+
"n": 12,
|
| 117 |
+
"accuracy": 1.0
|
| 118 |
+
},
|
| 119 |
+
"ordinal": {
|
| 120 |
+
"n": 12,
|
| 121 |
+
"accuracy": 1.0
|
| 122 |
+
},
|
| 123 |
+
"policy": {
|
| 124 |
+
"n": 12,
|
| 125 |
+
"accuracy": 1.0
|
| 126 |
+
},
|
| 127 |
+
"routing": {
|
| 128 |
+
"n": 12,
|
| 129 |
+
"accuracy": 0.9166666666666666
|
| 130 |
+
}
|
| 131 |
+
}
|
| 132 |
+
},
|
| 133 |
+
"hard": {
|
| 134 |
+
"n": 111,
|
| 135 |
+
"n_scorable": 111,
|
| 136 |
+
"n_correct": 53,
|
| 137 |
+
"accuracy": 0.4774774774774775,
|
| 138 |
+
"schema_validity": 1.0,
|
| 139 |
+
"schema_validity_strict": 1.0,
|
| 140 |
+
"operational_success": 1.0,
|
| 141 |
+
"brier_mean": 0.6071787802170037,
|
| 142 |
+
"ece_top_label_10bin": 0.15324274416807362,
|
| 143 |
+
"calibration_n": 111,
|
| 144 |
+
"ordinal_mae": 0.6837138642214399,
|
| 145 |
+
"per_family": {
|
| 146 |
+
"adversarial": {
|
| 147 |
+
"n": 6,
|
| 148 |
+
"accuracy": 0.6666666666666666
|
| 149 |
+
},
|
| 150 |
+
"ambiguous": {
|
| 151 |
+
"n": 7,
|
| 152 |
+
"accuracy": 0.42857142857142855
|
| 153 |
+
},
|
| 154 |
+
"judge_hard": {
|
| 155 |
+
"n": 17,
|
| 156 |
+
"accuracy": 0.47058823529411764
|
| 157 |
+
},
|
| 158 |
+
"long_policy": {
|
| 159 |
+
"n": 19,
|
| 160 |
+
"accuracy": 0.3157894736842105
|
| 161 |
+
},
|
| 162 |
+
"multi_hop": {
|
| 163 |
+
"n": 18,
|
| 164 |
+
"accuracy": 0.7222222222222222
|
| 165 |
+
},
|
| 166 |
+
"probability": {
|
| 167 |
+
"n": 10,
|
| 168 |
+
"accuracy": 0.4
|
| 169 |
+
},
|
| 170 |
+
"routing_hard": {
|
| 171 |
+
"n": 5,
|
| 172 |
+
"accuracy": 1.0
|
| 173 |
+
},
|
| 174 |
+
"temporal_numeric": {
|
| 175 |
+
"n": 15,
|
| 176 |
+
"accuracy": 0.13333333333333333
|
| 177 |
+
},
|
| 178 |
+
"tradeoff": {
|
| 179 |
+
"n": 6,
|
| 180 |
+
"accuracy": 0.16666666666666666
|
| 181 |
+
},
|
| 182 |
+
"trap": {
|
| 183 |
+
"n": 8,
|
| 184 |
+
"accuracy": 0.875
|
| 185 |
+
}
|
| 186 |
+
}
|
| 187 |
+
}
|
| 188 |
+
},
|
| 189 |
+
"hard_tier_ece_public111": 0.15324274416807362,
|
| 190 |
+
"hard_tier_ece_bins": [
|
| 191 |
+
{
|
| 192 |
+
"lo": 0.0,
|
| 193 |
+
"hi": 0.1,
|
| 194 |
+
"n": 0,
|
| 195 |
+
"mean_confidence": null,
|
| 196 |
+
"accuracy": null
|
| 197 |
+
},
|
| 198 |
+
{
|
| 199 |
+
"lo": 0.1,
|
| 200 |
+
"hi": 0.2,
|
| 201 |
+
"n": 0,
|
| 202 |
+
"mean_confidence": null,
|
| 203 |
+
"accuracy": null
|
| 204 |
+
},
|
| 205 |
+
{
|
| 206 |
+
"lo": 0.2,
|
| 207 |
+
"hi": 0.3,
|
| 208 |
+
"n": 1,
|
| 209 |
+
"mean_confidence": 0.21388788145283613,
|
| 210 |
+
"accuracy": 0.0
|
| 211 |
+
},
|
| 212 |
+
{
|
| 213 |
+
"lo": 0.3,
|
| 214 |
+
"hi": 0.4,
|
| 215 |
+
"n": 13,
|
| 216 |
+
"mean_confidence": 0.3512620124154394,
|
| 217 |
+
"accuracy": 0.23076923076923078
|
| 218 |
+
},
|
| 219 |
+
{
|
| 220 |
+
"lo": 0.4,
|
| 221 |
+
"hi": 0.5,
|
| 222 |
+
"n": 19,
|
| 223 |
+
"mean_confidence": 0.4498371724402195,
|
| 224 |
+
"accuracy": 0.42105263157894735
|
| 225 |
+
},
|
| 226 |
+
{
|
| 227 |
+
"lo": 0.5,
|
| 228 |
+
"hi": 0.6,
|
| 229 |
+
"n": 18,
|
| 230 |
+
"mean_confidence": 0.5561807791811684,
|
| 231 |
+
"accuracy": 0.3888888888888889
|
| 232 |
+
},
|
| 233 |
+
{
|
| 234 |
+
"lo": 0.6,
|
| 235 |
+
"hi": 0.7,
|
| 236 |
+
"n": 17,
|
| 237 |
+
"mean_confidence": 0.6470557809575238,
|
| 238 |
+
"accuracy": 0.35294117647058826
|
| 239 |
+
},
|
| 240 |
+
{
|
| 241 |
+
"lo": 0.7,
|
| 242 |
+
"hi": 0.8,
|
| 243 |
+
"n": 18,
|
| 244 |
+
"mean_confidence": 0.7435771863244336,
|
| 245 |
+
"accuracy": 0.5
|
| 246 |
+
},
|
| 247 |
+
{
|
| 248 |
+
"lo": 0.8,
|
| 249 |
+
"hi": 0.9,
|
| 250 |
+
"n": 13,
|
| 251 |
+
"mean_confidence": 0.8404461860278016,
|
| 252 |
+
"accuracy": 0.6923076923076923
|
| 253 |
+
},
|
| 254 |
+
{
|
| 255 |
+
"lo": 0.9,
|
| 256 |
+
"hi": 1.0,
|
| 257 |
+
"n": 12,
|
| 258 |
+
"mean_confidence": 0.9467793508081911,
|
| 259 |
+
"accuracy": 0.9166666666666666
|
| 260 |
+
}
|
| 261 |
+
],
|
| 262 |
+
"ordinal_mae_all_score_items": 0.29786527966090054,
|
| 263 |
+
"n_score_items": 18,
|
| 264 |
+
"brier_mean_all": 0.3147728854100423,
|
| 265 |
+
"probability_items_mean_tvd": 0.33663270227830244,
|
| 266 |
+
"probability_items_n": 10,
|
| 267 |
+
"calibration_axis_proxy_public_hard": 67.84409046927752,
|
| 268 |
+
"unsupported": {
|
| 269 |
+
"total": 0,
|
| 270 |
+
"by_tier": {},
|
| 271 |
+
"by_reason": {},
|
| 272 |
+
"rule": "over the 25,600-token TOTAL budget: counted as incorrect; never truncated"
|
| 273 |
+
},
|
| 274 |
+
"accuracy_on_supported_only": 0.7359307359307359,
|
| 275 |
+
"schema_validity": 1.0,
|
| 276 |
+
"schema_validity_strict": 1.0,
|
| 277 |
+
"paraphrase_consistency": {
|
| 278 |
+
"pairs": 36,
|
| 279 |
+
"both_valid": 36,
|
| 280 |
+
"agree": 35,
|
| 281 |
+
"agreement": 0.9722222222222222,
|
| 282 |
+
"both_correct_rate_all_pairs": 0.9444444444444444
|
| 283 |
+
},
|
| 284 |
+
"temperature": {
|
| 285 |
+
"mode": "global",
|
| 286 |
+
"file": "explicit --temperature",
|
| 287 |
+
"sha256": null,
|
| 288 |
+
"value": 0.8278650620942867,
|
| 289 |
+
"groups_used": {
|
| 290 |
+
"global": {
|
| 291 |
+
"T": 0.8278650620942867,
|
| 292 |
+
"n_items": 231
|
| 293 |
+
}
|
| 294 |
+
},
|
| 295 |
+
"fitted_on_benchmark_items": false
|
| 296 |
+
},
|
| 297 |
+
"harness_summary_all": {
|
| 298 |
+
"n_planned": 231,
|
| 299 |
+
"n_attempted": 231,
|
| 300 |
+
"n_scorable": 231,
|
| 301 |
+
"n_valid": 231,
|
| 302 |
+
"n_correct": 170,
|
| 303 |
+
"accuracy": 0.7359307359307359,
|
| 304 |
+
"coverage": 1.0,
|
| 305 |
+
"macro_accuracy": 0.7182687792465914
|
| 306 |
+
},
|
| 307 |
+
"comparison": {
|
| 308 |
+
"source_file": "results/v1.4.1/jevbench-v1.4.1-results.json",
|
| 309 |
+
"source_sha256": "e6754863056503fe2b010410fc7111df884ac1f9ce4449aa369aab61d98092cd",
|
| 310 |
+
"revision": "v1.4.1",
|
| 311 |
+
"n_systems": 82,
|
| 312 |
+
"commit": "24b9b5c1609a7a9e8fa14f49e5985a836c9dc842",
|
| 313 |
+
"rows": [
|
| 314 |
+
{
|
| 315 |
+
"key": "jev-1.13.0",
|
| 316 |
+
"label": "Jev 1.13.0",
|
| 317 |
+
"display": "Jev 1.13.0 (TypeSafe AI)",
|
| 318 |
+
"repo": "https://docs.typesafe.ai",
|
| 319 |
+
"underlying": "closed",
|
| 320 |
+
"public_accuracy": 0.8658008658008658,
|
| 321 |
+
"public_correct_of_231": 200,
|
| 322 |
+
"intelligence": 53.05904597275748,
|
| 323 |
+
"calibration": 76.3389831504074,
|
| 324 |
+
"sealed_accuracy": 0.36688311688311687,
|
| 325 |
+
"jevbench_score": 63.29205745601932,
|
| 326 |
+
"rank": 1,
|
| 327 |
+
"ece_hard_220": 0.06061111111111118,
|
| 328 |
+
"tiers_v12_full": {
|
| 329 |
+
"easy": 1.0,
|
| 330 |
+
"standard": 0.9895833333333334,
|
| 331 |
+
"judge": 0.9452054794520548,
|
| 332 |
+
"hard": 0.740909090909091
|
| 333 |
+
},
|
| 334 |
+
"source": "results/v1.4.1/jevbench-v1.4.1-results.json systems[0] (key 'jev-1.13.0') @ 24b9b5c1609a"
|
| 335 |
+
},
|
| 336 |
+
{
|
| 337 |
+
"key": "laya",
|
| 338 |
+
"label": "Laya",
|
| 339 |
+
"display": "Laya (Convai Innovations, ModernBERT-large 421M)",
|
| 340 |
+
"repo": "https://huggingface.co/convaiinnovations/laya",
|
| 341 |
+
"underlying": "ModernBERT-large encoder + option-marker decision head, 421M, RLCD-trained",
|
| 342 |
+
"public_accuracy": 0.5844155844155844,
|
| 343 |
+
"public_correct_of_231": 135,
|
| 344 |
+
"intelligence": 36.132988467190394,
|
| 345 |
+
"calibration": 63.67551046176046,
|
| 346 |
+
"sealed_accuracy": 0.30844155844155846,
|
| 347 |
+
"jevbench_score": 30.251281619829957,
|
| 348 |
+
"rank": 36,
|
| 349 |
+
"ece_hard_220": 0.20550909090909092,
|
| 350 |
+
"tiers_v12_full": {
|
| 351 |
+
"easy": 0.9444444444444444,
|
| 352 |
+
"standard": 0.7291666666666666,
|
| 353 |
+
"judge": 0.6917808219178082,
|
| 354 |
+
"hard": 0.3409090909090909
|
| 355 |
+
},
|
| 356 |
+
"source": "results/v1.4.1/jevbench-v1.4.1-results.json systems[35] (key 'laya') @ 24b9b5c1609a"
|
| 357 |
+
},
|
| 358 |
+
{
|
| 359 |
+
"key": "mghafiri-qwen3.5-0.8b-decision-model",
|
| 360 |
+
"label": "same backbone: Qwen3.5-0.8B Decision Model (mghafiri)",
|
| 361 |
+
"display": "Qwen3.5-0.8B Decision Model (Mourad Ghafiri)",
|
| 362 |
+
"repo": "https://huggingface.co/mghafiri/qwen3.5-0.8B-decision-model",
|
| 363 |
+
"underlying": "Qwen3.5-0.8B-Base fine-tuned as a JevLite decision model with per-question calibration",
|
| 364 |
+
"public_accuracy": 0.5930735930735931,
|
| 365 |
+
"public_correct_of_231": 137,
|
| 366 |
+
"intelligence": 28.073004486611502,
|
| 367 |
+
"calibration": 68.22744227994228,
|
| 368 |
+
"sealed_accuracy": 0.3474025974025974,
|
| 369 |
+
"jevbench_score": 14.540627482985634,
|
| 370 |
+
"rank": 60,
|
| 371 |
+
"ece_hard_220": null,
|
| 372 |
+
"tiers_v12_full": {
|
| 373 |
+
"easy": 0.9861111111111112,
|
| 374 |
+
"standard": 0.5520833333333334,
|
| 375 |
+
"judge": 0.3424657534246575,
|
| 376 |
+
"hard": 0.509090909090909
|
| 377 |
+
},
|
| 378 |
+
"source": "results/v1.4.1/jevbench-v1.4.1-results.json systems[59] (key 'mghafiri-qwen3.5-0.8b-decision-model') @ 24b9b5c1609a"
|
| 379 |
+
},
|
| 380 |
+
{
|
| 381 |
+
"key": "simplejev-qwen3.5-0.8b",
|
| 382 |
+
"label": "same backbone, untrained: SimpleJev Qwen3.5-0.8B",
|
| 383 |
+
"display": "SimpleJev (Qwen3.5-0.8B, CPU)",
|
| 384 |
+
"repo": "https://github.com/featherless-ai/simple-jev",
|
| 385 |
+
"underlying": "Qwen3.5-0.8B through SimpleJev native assistant-prefill option-logit scorer",
|
| 386 |
+
"public_accuracy": 0.5454545454545454,
|
| 387 |
+
"public_correct_of_231": 126,
|
| 388 |
+
"intelligence": 21.482479668016303,
|
| 389 |
+
"calibration": 49.07354475109724,
|
| 390 |
+
"sealed_accuracy": 0.3474025974025974,
|
| 391 |
+
"jevbench_score": 7.459762136724042,
|
| 392 |
+
"rank": 68,
|
| 393 |
+
"ece_hard_220": 0.3060342388575625,
|
| 394 |
+
"tiers_v12_full": {
|
| 395 |
+
"easy": 0.875,
|
| 396 |
+
"standard": 0.5729166666666666,
|
| 397 |
+
"judge": 0.1917808219178082,
|
| 398 |
+
"hard": 0.4
|
| 399 |
+
},
|
| 400 |
+
"source": "results/v1.4.1/jevbench-v1.4.1-results.json systems[67] (key 'simplejev-qwen3.5-0.8b') @ 24b9b5c1609a"
|
| 401 |
+
},
|
| 402 |
+
{
|
| 403 |
+
"key": "decider-2b",
|
| 404 |
+
"label": "decider-2b",
|
| 405 |
+
"display": "decider-2b (Mapika)",
|
| 406 |
+
"repo": "https://huggingface.co/Mapika/decider-2b",
|
| 407 |
+
"underlying": "Qwen3.5-2B-Base with a trained decision readout, 1.9B",
|
| 408 |
+
"public_accuracy": 0.70995670995671,
|
| 409 |
+
"public_correct_of_231": 164,
|
| 410 |
+
"intelligence": 38.54932735543702,
|
| 411 |
+
"calibration": 43.48691774891777,
|
| 412 |
+
"sealed_accuracy": 0.24675324675324675,
|
| 413 |
+
"jevbench_score": 30.7375448157181,
|
| 414 |
+
"rank": 34,
|
| 415 |
+
"ece_hard_220": 0.3221518181818179,
|
| 416 |
+
"tiers_v12_full": {
|
| 417 |
+
"easy": 1.0,
|
| 418 |
+
"standard": 0.8541666666666666,
|
| 419 |
+
"judge": 0.773972602739726,
|
| 420 |
+
"hard": 0.4727272727272727
|
| 421 |
+
},
|
| 422 |
+
"source": "results/v1.4.1/jevbench-v1.4.1-results.json systems[33] (key 'decider-2b') @ 24b9b5c1609a"
|
| 423 |
+
},
|
| 424 |
+
{
|
| 425 |
+
"key": "kev-0.6b",
|
| 426 |
+
"label": "kev 0.6B",
|
| 427 |
+
"display": "kev 0.6B (research preview)",
|
| 428 |
+
"repo": "https://github.com/jaredpalmer/kev",
|
| 429 |
+
"underlying": "Qwen3-0.6B-Base + LoRA + learned pointer head; jaredpalmer/kev-0.6b",
|
| 430 |
+
"public_accuracy": 0.6666666666666666,
|
| 431 |
+
"public_correct_of_231": 154,
|
| 432 |
+
"intelligence": 34.20432736698408,
|
| 433 |
+
"calibration": 49.957886527801605,
|
| 434 |
+
"sealed_accuracy": 0.24025974025974026,
|
| 435 |
+
"jevbench_score": 24.750427849352384,
|
| 436 |
+
"rank": 45,
|
| 437 |
+
"ece_hard_220": 0.26937623307785324,
|
| 438 |
+
"tiers_v12_full": {
|
| 439 |
+
"easy": 1.0,
|
| 440 |
+
"standard": 0.8125,
|
| 441 |
+
"judge": 0.6643835616438356,
|
| 442 |
+
"hard": 0.4
|
| 443 |
+
},
|
| 444 |
+
"source": "results/v1.4.1/jevbench-v1.4.1-results.json systems[44] (key 'kev-0.6b') @ 24b9b5c1609a"
|
| 445 |
+
},
|
| 446 |
+
{
|
| 447 |
+
"key": "lev-350m",
|
| 448 |
+
"label": "lev-350m",
|
| 449 |
+
"display": "lev-350m (Franck Verrot, LFM2.5-350M)",
|
| 450 |
+
"repo": "https://github.com/franckverrot/lev",
|
| 451 |
+
"underlying": "LiquidAI/LFM2.5-350M with a LoRA and a 6.5M-parameter pointer head (a kev clone)",
|
| 452 |
+
"public_accuracy": 0.5844155844155844,
|
| 453 |
+
"public_correct_of_231": 135,
|
| 454 |
+
"intelligence": 34.75234376694234,
|
| 455 |
+
"calibration": 70.61387806637806,
|
| 456 |
+
"sealed_accuracy": 0.25,
|
| 457 |
+
"jevbench_score": 28.501129766483672,
|
| 458 |
+
"rank": 37,
|
| 459 |
+
"ece_hard_220": 0.12270454545454548,
|
| 460 |
+
"tiers_v12_full": {
|
| 461 |
+
"easy": 0.9861111111111112,
|
| 462 |
+
"standard": 0.71875,
|
| 463 |
+
"judge": 0.6917808219178082,
|
| 464 |
+
"hard": 0.36818181818181817
|
| 465 |
+
},
|
| 466 |
+
"source": "results/v1.4.1/jevbench-v1.4.1-results.json systems[36] (key 'lev-350m') @ 24b9b5c1609a"
|
| 467 |
+
},
|
| 468 |
+
{
|
| 469 |
+
"key": "decision-fast",
|
| 470 |
+
"label": "Decision Fast (Qwen3-0.6B)",
|
| 471 |
+
"display": "Decision Fast (FlyMy.AI, v53a)",
|
| 472 |
+
"repo": "https://huggingface.co/flymy-ai/decision-fast-preview",
|
| 473 |
+
"underlying": "Qwen/Qwen3-0.6B-Base with a trained LoRA adapter and pointer head (10.6M trainable parameters)",
|
| 474 |
+
"public_accuracy": 0.6320346320346321,
|
| 475 |
+
"public_correct_of_231": 146,
|
| 476 |
+
"intelligence": 37.074471307080934,
|
| 477 |
+
"calibration": 65.30757379702415,
|
| 478 |
+
"sealed_accuracy": 0.2564935064935065,
|
| 479 |
+
"jevbench_score": 32.492203456270644,
|
| 480 |
+
"rank": 33,
|
| 481 |
+
"ece_hard_220": 0.17070899271518503,
|
| 482 |
+
"tiers_v12_full": {
|
| 483 |
+
"easy": 0.9861111111111112,
|
| 484 |
+
"standard": 0.78125,
|
| 485 |
+
"judge": 0.7465753424657534,
|
| 486 |
+
"hard": 0.38636363636363635
|
| 487 |
+
},
|
| 488 |
+
"source": "results/v1.4.1/jevbench-v1.4.1-results.json systems[32] (key 'decision-fast') @ 24b9b5c1609a"
|
| 489 |
+
}
|
| 490 |
+
],
|
| 491 |
+
"notes": [
|
| 492 |
+
"public_accuracy = accuracy on the 231 public items (docs/METHOD-v1.4.md, variable p).",
|
| 493 |
+
"intelligence / calibration are the official v1.4 axes (0-100): they blend held-out, judge and 308 sealed items that are not public, so a public-only run cannot reproduce them.",
|
| 494 |
+
"tiers_v12_full are accuracies on the full v1.2 tiers (public + held-out), not the public subsets; ece_hard_220 is over all 220 hard items."
|
| 495 |
+
]
|
| 496 |
+
},
|
| 497 |
+
"ours_0.8b_v3": {
|
| 498 |
+
"label": "Jev-Style-0.8B-Decision-v3 (ours, v1 protocol)",
|
| 499 |
+
"public_accuracy": 0.6406926406926406,
|
| 500 |
+
"correct": 148,
|
| 501 |
+
"tiers": {
|
| 502 |
+
"easy": 1.0,
|
| 503 |
+
"standard": 0.8194444444444444,
|
| 504 |
+
"hard": 0.36936936936936937
|
| 505 |
+
},
|
| 506 |
+
"hard_tier_ece_public111": 0.19980380205815876,
|
| 507 |
+
"ordinal_mae": 0.4283973452495316,
|
| 508 |
+
"source": "runs/macjev/received/ext_evals/main/jevbench/results.json",
|
| 509 |
+
"source_sha256": "6c1f94220dc8197e504827213b3567e00919740bb705929bed88535812f2a033"
|
| 510 |
+
}
|
| 511 |
+
}
|
validation/benchmarks/jevbench_v1.4.1_results.md
ADDED
|
@@ -0,0 +1,18 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
## JevBench v1.4.1 -- public items (231)
|
| 2 |
+
|
| 3 |
+
| System | Public acc. (231) | Correct | Easy (48) | Standard (72) | Hard (111) | Hard ECE |
|
| 4 |
+
|---|---:|---:|---:|---:|---:|---:|
|
| 5 |
+
| **Jev-Style-2B-Decision-v3-GGUF-F16** (this run, v2 protocol) | **73.6%** | 170 | 100.0% | 95.8% | 47.7% | 0.153 (public 111) |
|
| 6 |
+
| Jev-Style-0.8B-Decision-v3 (ours, v1 protocol) | 64.1% | 148 | 100.0% | 81.9% | 36.9% | 0.200 (public 111) |
|
| 7 |
+
| Jev 1.13.0 | 86.6% | 200 | -- | -- | -- | 0.061 (all 220) |
|
| 8 |
+
| Laya | 58.4% | 135 | -- | -- | -- | 0.206 (all 220) |
|
| 9 |
+
| same backbone: Qwen3.5-0.8B Decision Model (mghafiri) | 59.3% | 137 | -- | -- | -- | n/a (all 220) |
|
| 10 |
+
| same backbone, untrained: SimpleJev Qwen3.5-0.8B | 54.5% | 126 | -- | -- | -- | 0.306 (all 220) |
|
| 11 |
+
| decider-2b | 71.0% | 164 | -- | -- | -- | 0.322 (all 220) |
|
| 12 |
+
| kev 0.6B | 66.7% | 154 | -- | -- | -- | 0.269 (all 220) |
|
| 13 |
+
| lev-350m | 58.4% | 135 | -- | -- | -- | 0.123 (all 220) |
|
| 14 |
+
| Decision Fast (Qwen3-0.6B) | 63.2% | 146 | -- | -- | -- | 0.171 (all 220) |
|
| 15 |
+
|
| 16 |
+
Published rows: `results/v1.4.1/jevbench-v1.4.1-results.json` sha256 `e6754863056503fe2b010410fc7111df884ac1f9ce4449aa369aab61d98092cd` (https://github.com/fstandhartinger/jevbench @ 24b9b5c1609a, tag v1.4.1).
|
| 17 |
+
0.8B v3 row: `runs/macjev/received/ext_evals/main/jevbench/results.json` sha256 `6c1f94220dc8197e504827213b3567e00919740bb705929bed88535812f2a033`.
|
| 18 |
+
Unsupported (over the 25,600-token total budget; counted wrong, never truncated): 0 {}. Catalogue-overflow renderings: {}. Temperature: one global T = 0.8278650620942867 from `explicit --temperature`; nothing fitted on JevBench items.
|
validation/benchmarks/zeroshot_comparison.md
ADDED
|
@@ -0,0 +1,11 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
**Zero-shot sets outside our training pool**
|
| 2 |
+
|
| 3 |
+
| set | n | majority | Jev-Style-2B-Decision-v3-GGUF-F16 acc | F1 | ECE | Jev acc | F1 | ECE | Laya(en) acc | F1 | ECE |
|
| 4 |
+
|---|---|---|---|---|---|---|---|---|---|---|---|
|
| 5 |
+
| tweet_topic | 1693 | 0.396 | 0.822 | 0.678 | 0.028 | 0.793 | 0.694 | 0.063 | 0.632 | 0.461 | 0.130 |
|
| 6 |
+
| fin_topic | 4117 | 0.207 | 0.611 | 0.590 | 0.065 | 0.670 | 0.630 | 0.166 | 0.342 | 0.362 | 0.610 |
|
| 7 |
+
| daily_dialog | 7740 | 0.817 | 0.774 | 0.372 | 0.039 | 0.710 | 0.385 | 0.156 | 0.614 | 0.275 | 0.208 |
|
| 8 |
+
|
| 9 |
+
Jev / Laya: published by elcronos (https://github.com/elcronos/jev-vs-open-decision-models/blob/a1901bc3d520e73936de8d4326545c0cdcf742fb/results/cross_dataset_summary.json); Jev's ECE is raw (API probabilities, no temperature), Laya's uses its own shipped per-option-count temperature (not fitted by the study); ours uses our one cal-fitted temperature (T=1 ECE in metrics.json).
|
| 10 |
+
|
| 11 |
+
0.8B v3 (v1 protocol): tweet_topic acc 0.755 / F1 0.599, fin_topic acc 0.467 / F1 0.452, daily_dialog acc 0.325 / F1 0.233 (`runs/macjev/received/ext_evals/main/zeroshot_topics/metrics.json` sha256 `6c265318088f719a763a1919103632a247a8834c554d4b44326ea0c502cc0cf6`).
|
validation/benchmarks/zeroshot_metrics.json
ADDED
|
@@ -0,0 +1,304 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"temperature": {
|
| 3 |
+
"mode": "global",
|
| 4 |
+
"source": "explicit --temperature",
|
| 5 |
+
"sha256": null,
|
| 6 |
+
"value": 0.8278650620942867,
|
| 7 |
+
"expected_2b_v3": 0.8278650621,
|
| 8 |
+
"fitted_on_benchmark_items": false
|
| 9 |
+
},
|
| 10 |
+
"sets": {
|
| 11 |
+
"tweet_topic": {
|
| 12 |
+
"n": 1693,
|
| 13 |
+
"n_ok": 1693,
|
| 14 |
+
"n_unsupported": 0,
|
| 15 |
+
"n_classes": 6,
|
| 16 |
+
"temperature": 0.8278650620942867,
|
| 17 |
+
"majority_class_accuracy": 0.3963378617838157,
|
| 18 |
+
"accuracy_ok_rows": 0.822209096278795,
|
| 19 |
+
"ece15": 0.027919883880813873,
|
| 20 |
+
"ece15_raw_T1": 0.08661185749227743,
|
| 21 |
+
"brier": 0.262576013332696,
|
| 22 |
+
"brier_raw_T1": 0.27079026328321404,
|
| 23 |
+
"nll": 0.5282712172517265,
|
| 24 |
+
"nll_raw_T1": 0.5629566855388951,
|
| 25 |
+
"mean_confidence": 0.7947445890391743,
|
| 26 |
+
"accuracy": 0.822209096278795,
|
| 27 |
+
"macro_f1": 0.677897069437572,
|
| 28 |
+
"balanced_accuracy": 0.7070231758410981,
|
| 29 |
+
"pred_share": {
|
| 30 |
+
"arts & culture": 0.045481393975191964,
|
| 31 |
+
"business & entrepreneurs": 0.040756054341405785,
|
| 32 |
+
"pop culture": 0.33786178381571175,
|
| 33 |
+
"daily life": 0.15416420555227406,
|
| 34 |
+
"sports & gaming": 0.36207914943886593,
|
| 35 |
+
"science & technology": 0.0596574128765505
|
| 36 |
+
},
|
| 37 |
+
"accuracy_ci95": [
|
| 38 |
+
0.8038984051978736,
|
| 39 |
+
0.8399438865918486
|
| 40 |
+
],
|
| 41 |
+
"macro_f1_ci95": [
|
| 42 |
+
0.6455020683998111,
|
| 43 |
+
0.7085891187789015
|
| 44 |
+
],
|
| 45 |
+
"ci": "percentile bootstrap, 10000 resamples, default_rng(0), rows resampled i.i.d.",
|
| 46 |
+
"tokens_mean": 106.1246308328411,
|
| 47 |
+
"tokens_max": 173,
|
| 48 |
+
"in_domain": false,
|
| 49 |
+
"catalogue_overflow": 0
|
| 50 |
+
},
|
| 51 |
+
"fin_topic": {
|
| 52 |
+
"n": 4117,
|
| 53 |
+
"n_ok": 4117,
|
| 54 |
+
"n_unsupported": 0,
|
| 55 |
+
"n_classes": 20,
|
| 56 |
+
"temperature": 0.8278650620942867,
|
| 57 |
+
"majority_class_accuracy": 0.2069468059266456,
|
| 58 |
+
"accuracy_ok_rows": 0.6111246052951178,
|
| 59 |
+
"ece15": 0.06460657860002232,
|
| 60 |
+
"ece15_raw_T1": 0.03822893519578447,
|
| 61 |
+
"brier": 0.5285731205072254,
|
| 62 |
+
"brier_raw_T1": 0.5230611042844824,
|
| 63 |
+
"nll": 1.159706614583174,
|
| 64 |
+
"nll_raw_T1": 1.1731574665843,
|
| 65 |
+
"mean_confidence": 0.6685232597080648,
|
| 66 |
+
"accuracy": 0.6111246052951178,
|
| 67 |
+
"macro_f1": 0.5897964463354406,
|
| 68 |
+
"balanced_accuracy": 0.6945435859869323,
|
| 69 |
+
"pred_share": {
|
| 70 |
+
"Analyst Update": 0.030604809327179985,
|
| 71 |
+
"Fed | Central Banks": 0.037891668690794265,
|
| 72 |
+
"Company | Product News": 0.1736701481661404,
|
| 73 |
+
"Treasuries | Corporate Debt": 0.014330823415108088,
|
| 74 |
+
"Dividend": 0.026961379645372846,
|
| 75 |
+
"Earnings": 0.09181442798153995,
|
| 76 |
+
"Energy | Oil": 0.050522224921059025,
|
| 77 |
+
"Financials": 0.013116346854505708,
|
| 78 |
+
"Currencies": 0.014087928102987613,
|
| 79 |
+
"General News | Opinion": 0.1034734029633228,
|
| 80 |
+
"Gold | Metals | Materials": 0.009230021860578091,
|
| 81 |
+
"IPO": 0.011416079669662375,
|
| 82 |
+
"Legal | Regulation": 0.030604809327179985,
|
| 83 |
+
"M&A | Investments": 0.04930774836045664,
|
| 84 |
+
"Macro": 0.056594607724070926,
|
| 85 |
+
"Markets": 0.060480932717998544,
|
| 86 |
+
"Politics": 0.05926645615739616,
|
| 87 |
+
"Personnel Change": 0.0456643186786495,
|
| 88 |
+
"Stock Commentary": 0.07189701238766091,
|
| 89 |
+
"Stock Movement": 0.04906485304833617
|
| 90 |
+
},
|
| 91 |
+
"accuracy_ci95": [
|
| 92 |
+
0.5960650959436483,
|
| 93 |
+
0.6259412193344669
|
| 94 |
+
],
|
| 95 |
+
"macro_f1_ci95": [
|
| 96 |
+
0.5694510128995812,
|
| 97 |
+
0.6071880523494645
|
| 98 |
+
],
|
| 99 |
+
"ci": "percentile bootstrap, 10000 resamples, default_rng(0), rows resampled i.i.d.",
|
| 100 |
+
"tokens_mean": 199.59825115375273,
|
| 101 |
+
"tokens_max": 301,
|
| 102 |
+
"in_domain": false,
|
| 103 |
+
"catalogue_overflow": 0
|
| 104 |
+
},
|
| 105 |
+
"daily_dialog": {
|
| 106 |
+
"n": 7740,
|
| 107 |
+
"n_ok": 7740,
|
| 108 |
+
"n_unsupported": 0,
|
| 109 |
+
"n_classes": 7,
|
| 110 |
+
"temperature": 0.8278650620942867,
|
| 111 |
+
"majority_class_accuracy": 0.8166666666666667,
|
| 112 |
+
"accuracy_ok_rows": 0.7744186046511627,
|
| 113 |
+
"ece15": 0.03934861337502408,
|
| 114 |
+
"ece15_raw_T1": 0.027480647988479354,
|
| 115 |
+
"brier": 0.3382397818519505,
|
| 116 |
+
"brier_raw_T1": 0.33726329383754494,
|
| 117 |
+
"nll": 0.6778540478231467,
|
| 118 |
+
"nll_raw_T1": 0.6808418072965744,
|
| 119 |
+
"mean_confidence": 0.807695045520859,
|
| 120 |
+
"accuracy": 0.7744186046511627,
|
| 121 |
+
"macro_f1": 0.3724097968832693,
|
| 122 |
+
"balanced_accuracy": 0.51014991333418,
|
| 123 |
+
"pred_share": {
|
| 124 |
+
"no emotion": 0.7905684754521963,
|
| 125 |
+
"anger": 0.01744186046511628,
|
| 126 |
+
"disgust": 0.013565891472868217,
|
| 127 |
+
"fear": 0.020284237726098192,
|
| 128 |
+
"happiness": 0.09056847545219639,
|
| 129 |
+
"sadness": 0.033850129198966405,
|
| 130 |
+
"surprise": 0.03372093023255814
|
| 131 |
+
},
|
| 132 |
+
"accuracy_ci95": [
|
| 133 |
+
0.7649870801033591,
|
| 134 |
+
0.7835917312661499
|
| 135 |
+
],
|
| 136 |
+
"macro_f1_ci95": [
|
| 137 |
+
0.3480292808769088,
|
| 138 |
+
0.3955194464258293
|
| 139 |
+
],
|
| 140 |
+
"ci": "percentile bootstrap, 10000 resamples, default_rng(0), rows resampled i.i.d.",
|
| 141 |
+
"tokens_mean": 79.59651162790698,
|
| 142 |
+
"tokens_max": 285,
|
| 143 |
+
"in_domain": false,
|
| 144 |
+
"catalogue_overflow": 0
|
| 145 |
+
}
|
| 146 |
+
},
|
| 147 |
+
"comparison": {
|
| 148 |
+
"source": "https://github.com/elcronos/jev-vs-open-decision-models/blob/a1901bc3d520e73936de8d4326545c0cdcf742fb/results/cross_dataset_summary.json",
|
| 149 |
+
"source_sha256": "5380d3a45395bfdf5340d75e7e18ecdb4b636734295d234839c7113efae608d0",
|
| 150 |
+
"note": "repository has no licence file: only its published numbers and the public datasets it names are used; no code was copied",
|
| 151 |
+
"clean": [
|
| 152 |
+
{
|
| 153 |
+
"set": "tweet_topic",
|
| 154 |
+
"n": 1693,
|
| 155 |
+
"majority": 0.3963378617838157,
|
| 156 |
+
"Jev-Style-2B-Decision-v3-GGUF-F16": {
|
| 157 |
+
"accuracy": 0.822209096278795,
|
| 158 |
+
"macro_f1": 0.677897069437572,
|
| 159 |
+
"ece15": 0.027919883880813873,
|
| 160 |
+
"ece15_raw_T1": 0.08661185749227743,
|
| 161 |
+
"brier": 0.262576013332696,
|
| 162 |
+
"n_unsupported": 0,
|
| 163 |
+
"accuracy_ci95": [
|
| 164 |
+
0.8038984051978736,
|
| 165 |
+
0.8399438865918486
|
| 166 |
+
]
|
| 167 |
+
},
|
| 168 |
+
"jev": {
|
| 169 |
+
"accuracy": 0.7932663910218547,
|
| 170 |
+
"macro_f1": 0.6936,
|
| 171 |
+
"ece15": 0.0631,
|
| 172 |
+
"brier": 0.2935
|
| 173 |
+
},
|
| 174 |
+
"laya_en": {
|
| 175 |
+
"accuracy": 0.6320141760189013,
|
| 176 |
+
"macro_f1": 0.4611,
|
| 177 |
+
"ece15": 0.1295,
|
| 178 |
+
"brier": 0.5049
|
| 179 |
+
},
|
| 180 |
+
"prismnli": {
|
| 181 |
+
"accuracy": 0.6326048434731246,
|
| 182 |
+
"macro_f1": 0.5444,
|
| 183 |
+
"ece15": 0.181,
|
| 184 |
+
"brier": 0.5374
|
| 185 |
+
}
|
| 186 |
+
},
|
| 187 |
+
{
|
| 188 |
+
"set": "fin_topic",
|
| 189 |
+
"n": 4117,
|
| 190 |
+
"majority": 0.2069468059266456,
|
| 191 |
+
"Jev-Style-2B-Decision-v3-GGUF-F16": {
|
| 192 |
+
"accuracy": 0.6111246052951178,
|
| 193 |
+
"macro_f1": 0.5897964463354406,
|
| 194 |
+
"ece15": 0.06460657860002232,
|
| 195 |
+
"ece15_raw_T1": 0.03822893519578447,
|
| 196 |
+
"brier": 0.5285731205072254,
|
| 197 |
+
"n_unsupported": 0,
|
| 198 |
+
"accuracy_ci95": [
|
| 199 |
+
0.5960650959436483,
|
| 200 |
+
0.6259412193344669
|
| 201 |
+
]
|
| 202 |
+
},
|
| 203 |
+
"jev": {
|
| 204 |
+
"accuracy": 0.669905270828273,
|
| 205 |
+
"macro_f1": 0.6298,
|
| 206 |
+
"ece15": 0.1664,
|
| 207 |
+
"brier": 0.5085
|
| 208 |
+
},
|
| 209 |
+
"laya_en": {
|
| 210 |
+
"accuracy": 0.3419965994656303,
|
| 211 |
+
"macro_f1": 0.3623,
|
| 212 |
+
"ece15": 0.6096,
|
| 213 |
+
"brier": 1.2494
|
| 214 |
+
},
|
| 215 |
+
"prismnli": {
|
| 216 |
+
"accuracy": 0.3524410978868108,
|
| 217 |
+
"macro_f1": 0.2558,
|
| 218 |
+
"ece15": 0.1986,
|
| 219 |
+
"brier": 0.8057
|
| 220 |
+
}
|
| 221 |
+
},
|
| 222 |
+
{
|
| 223 |
+
"set": "daily_dialog",
|
| 224 |
+
"n": 7740,
|
| 225 |
+
"majority": 0.8166666666666667,
|
| 226 |
+
"Jev-Style-2B-Decision-v3-GGUF-F16": {
|
| 227 |
+
"accuracy": 0.7744186046511627,
|
| 228 |
+
"macro_f1": 0.3724097968832693,
|
| 229 |
+
"ece15": 0.03934861337502408,
|
| 230 |
+
"ece15_raw_T1": 0.027480647988479354,
|
| 231 |
+
"brier": 0.3382397818519505,
|
| 232 |
+
"n_unsupported": 0,
|
| 233 |
+
"accuracy_ci95": [
|
| 234 |
+
0.7649870801033591,
|
| 235 |
+
0.7835917312661499
|
| 236 |
+
]
|
| 237 |
+
},
|
| 238 |
+
"jev": {
|
| 239 |
+
"accuracy": 0.7099483204134367,
|
| 240 |
+
"macro_f1": 0.3847,
|
| 241 |
+
"ece15": 0.1563,
|
| 242 |
+
"brier": 0.4603
|
| 243 |
+
},
|
| 244 |
+
"laya_en": {
|
| 245 |
+
"accuracy": 0.6143410852713178,
|
| 246 |
+
"macro_f1": 0.2748,
|
| 247 |
+
"ece15": 0.208,
|
| 248 |
+
"brier": 0.6008
|
| 249 |
+
},
|
| 250 |
+
"prismnli": {
|
| 251 |
+
"accuracy": 0.7652454780361757,
|
| 252 |
+
"macro_f1": 0.3454,
|
| 253 |
+
"ece15": 0.1756,
|
| 254 |
+
"brier": 0.4091
|
| 255 |
+
}
|
| 256 |
+
}
|
| 257 |
+
],
|
| 258 |
+
"in_domain": []
|
| 259 |
+
},
|
| 260 |
+
"ours_0.8b_v3": {
|
| 261 |
+
"label": "Jev-Style-0.8B-Decision-v3 (ours, v1 protocol)",
|
| 262 |
+
"sets": {
|
| 263 |
+
"tweet_topic": {
|
| 264 |
+
"accuracy": 0.754873006497342,
|
| 265 |
+
"macro_f1": 0.5993905130101003,
|
| 266 |
+
"ece15": 0.027434099256085594,
|
| 267 |
+
"ece15_raw_T1": 0.06193629176695822,
|
| 268 |
+
"brier": 0.3422167077233273,
|
| 269 |
+
"n": 1693,
|
| 270 |
+
"n_unsupported": 0
|
| 271 |
+
},
|
| 272 |
+
"fin_topic": {
|
| 273 |
+
"accuracy": 0.4670876852076755,
|
| 274 |
+
"macro_f1": 0.45174530293977544,
|
| 275 |
+
"ece15": 0.04596390350720937,
|
| 276 |
+
"ece15_raw_T1": 0.05647184359290005,
|
| 277 |
+
"brier": 0.6470044850625658,
|
| 278 |
+
"n": 4117,
|
| 279 |
+
"n_unsupported": 0
|
| 280 |
+
},
|
| 281 |
+
"daily_dialog": {
|
| 282 |
+
"accuracy": 0.32493540051679587,
|
| 283 |
+
"macro_f1": 0.2331496717992918,
|
| 284 |
+
"ece15": 0.4225022513967012,
|
| 285 |
+
"ece15_raw_T1": 0.3871480738216389,
|
| 286 |
+
"brier": 1.0441535348512228,
|
| 287 |
+
"n": 7740,
|
| 288 |
+
"n_unsupported": 0
|
| 289 |
+
}
|
| 290 |
+
},
|
| 291 |
+
"temperature": {
|
| 292 |
+
"policy": "global temperature of a family|qtype|option_bucket file",
|
| 293 |
+
"path": "runs/macjev/h100/evals/main/temperatures.json",
|
| 294 |
+
"sha256": "39ad8f6633934ff67770725993d7354ebebd6e7a08f73e50cab04df24715f2ce",
|
| 295 |
+
"version": "macjev-temperatures-v1",
|
| 296 |
+
"fitted_on": [
|
| 297 |
+
"pool_cal.jsonl:dfb7e9beff96c6c5"
|
| 298 |
+
],
|
| 299 |
+
"T": 0.8800546821789332
|
| 300 |
+
},
|
| 301 |
+
"source": "runs/macjev/received/ext_evals/main/zeroshot_topics/metrics.json",
|
| 302 |
+
"source_sha256": "6c265318088f719a763a1919103632a247a8834c554d4b44326ea0c502cc0cf6"
|
| 303 |
+
}
|
| 304 |
+
}
|
validation/data_sources.json
ADDED
|
@@ -0,0 +1,641 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"model": "chaoliangUNSW/Jev-Style-2B-Decision-v3",
|
| 3 |
+
"note": "Every source in the training rows of this model (58 sources). licence_recorded = the licence field stored with the rows in the training pool (one entry per distinct value; 'generated...' = generated for this project). components = the mixture-table rows of the model card. link = the dataset repository the rows were built from, where one exists (null for the 22 sources generated for this project). totals = rows and tokens actually drawn during training, repeats counted (the run's exposure record); per-source counts are not listed in this file. Check each source's own terms before use; see 'Training data and licences' on the model card.",
|
| 4 |
+
"totals": {
|
| 5 |
+
"sources": 58,
|
| 6 |
+
"trained_logical_rows": 181449,
|
| 7 |
+
"trained_tokens": 60032377
|
| 8 |
+
},
|
| 9 |
+
"sources": [
|
| 10 |
+
{
|
| 11 |
+
"id": "alisawuffles/WANLI",
|
| 12 |
+
"components": [
|
| 13 |
+
"Public reading tasks"
|
| 14 |
+
],
|
| 15 |
+
"licence_recorded": [
|
| 16 |
+
"cc-by-4.0"
|
| 17 |
+
],
|
| 18 |
+
"link": "https://huggingface.co/datasets/alisawuffles/WANLI",
|
| 19 |
+
"note": "written by GPT-3 and revised by crowdworkers"
|
| 20 |
+
},
|
| 21 |
+
{
|
| 22 |
+
"id": "allenai/ai2_arc",
|
| 23 |
+
"components": [
|
| 24 |
+
"Knowledge and reasoning"
|
| 25 |
+
],
|
| 26 |
+
"licence_recorded": [
|
| 27 |
+
"cc-by-sa-4.0"
|
| 28 |
+
],
|
| 29 |
+
"link": "https://huggingface.co/datasets/allenai/ai2_arc",
|
| 30 |
+
"share_alike": true
|
| 31 |
+
},
|
| 32 |
+
{
|
| 33 |
+
"id": "allenai/qasc",
|
| 34 |
+
"components": [
|
| 35 |
+
"Knowledge and reasoning"
|
| 36 |
+
],
|
| 37 |
+
"licence_recorded": [
|
| 38 |
+
"cc-by-4.0"
|
| 39 |
+
],
|
| 40 |
+
"link": "https://huggingface.co/datasets/allenai/qasc"
|
| 41 |
+
},
|
| 42 |
+
{
|
| 43 |
+
"id": "allenai/qasper",
|
| 44 |
+
"components": [
|
| 45 |
+
"Public reading tasks"
|
| 46 |
+
],
|
| 47 |
+
"licence_recorded": [
|
| 48 |
+
"cc-by-4.0"
|
| 49 |
+
],
|
| 50 |
+
"link": "https://huggingface.co/datasets/allenai/qasper"
|
| 51 |
+
},
|
| 52 |
+
{
|
| 53 |
+
"id": "allenai/ropes",
|
| 54 |
+
"components": [
|
| 55 |
+
"Public reading tasks"
|
| 56 |
+
],
|
| 57 |
+
"licence_recorded": [
|
| 58 |
+
"cc-by-4.0"
|
| 59 |
+
],
|
| 60 |
+
"link": "https://huggingface.co/datasets/allenai/ropes"
|
| 61 |
+
},
|
| 62 |
+
{
|
| 63 |
+
"id": "clinc/clinc_oos",
|
| 64 |
+
"components": [
|
| 65 |
+
"Option-format views"
|
| 66 |
+
],
|
| 67 |
+
"licence_recorded": [
|
| 68 |
+
"cc-by-3.0"
|
| 69 |
+
],
|
| 70 |
+
"link": "https://huggingface.co/datasets/clinc/clinc_oos"
|
| 71 |
+
},
|
| 72 |
+
{
|
| 73 |
+
"id": "clinc150",
|
| 74 |
+
"components": [
|
| 75 |
+
"Intents and yes/no QA"
|
| 76 |
+
],
|
| 77 |
+
"licence_recorded": [
|
| 78 |
+
"cc-by-3.0"
|
| 79 |
+
],
|
| 80 |
+
"link": "https://huggingface.co/datasets/clinc/clinc_oos"
|
| 81 |
+
},
|
| 82 |
+
{
|
| 83 |
+
"id": "coastalcph/lex_glue",
|
| 84 |
+
"components": [
|
| 85 |
+
"Public reading tasks"
|
| 86 |
+
],
|
| 87 |
+
"licence_recorded": [
|
| 88 |
+
"cc-by-4.0"
|
| 89 |
+
],
|
| 90 |
+
"link": "https://huggingface.co/datasets/coastalcph/lex_glue"
|
| 91 |
+
},
|
| 92 |
+
{
|
| 93 |
+
"id": "czyssrs/FinQA",
|
| 94 |
+
"components": [
|
| 95 |
+
"Public reading tasks",
|
| 96 |
+
"Option-format views"
|
| 97 |
+
],
|
| 98 |
+
"licence_recorded": [
|
| 99 |
+
"mit"
|
| 100 |
+
],
|
| 101 |
+
"link": "https://github.com/czyssrs/FinQA"
|
| 102 |
+
},
|
| 103 |
+
{
|
| 104 |
+
"id": "deepmind/aqua_rat",
|
| 105 |
+
"components": [
|
| 106 |
+
"Public reading tasks"
|
| 107 |
+
],
|
| 108 |
+
"licence_recorded": [
|
| 109 |
+
"apache-2.0"
|
| 110 |
+
],
|
| 111 |
+
"link": "https://huggingface.co/datasets/deepmind/aqua_rat"
|
| 112 |
+
},
|
| 113 |
+
{
|
| 114 |
+
"id": "generated:crux_type_synth",
|
| 115 |
+
"components": [
|
| 116 |
+
"Knowledge and reasoning"
|
| 117 |
+
],
|
| 118 |
+
"licence_recorded": [
|
| 119 |
+
"generated"
|
| 120 |
+
],
|
| 121 |
+
"link": null,
|
| 122 |
+
"note": "generated for this project"
|
| 123 |
+
},
|
| 124 |
+
{
|
| 125 |
+
"id": "google-research-datasets/mbpp",
|
| 126 |
+
"components": [
|
| 127 |
+
"Knowledge and reasoning"
|
| 128 |
+
],
|
| 129 |
+
"licence_recorded": [
|
| 130 |
+
"cc-by-4.0"
|
| 131 |
+
],
|
| 132 |
+
"link": "https://huggingface.co/datasets/google-research-datasets/mbpp"
|
| 133 |
+
},
|
| 134 |
+
{
|
| 135 |
+
"id": "google-research-datasets/schema_guided_dstc8",
|
| 136 |
+
"components": [
|
| 137 |
+
"Retrieval and routing"
|
| 138 |
+
],
|
| 139 |
+
"licence_recorded": [
|
| 140 |
+
"cc-by-sa-4.0"
|
| 141 |
+
],
|
| 142 |
+
"link": "https://huggingface.co/datasets/google-research-datasets/schema_guided_dstc8",
|
| 143 |
+
"share_alike": true
|
| 144 |
+
},
|
| 145 |
+
{
|
| 146 |
+
"id": "google/boolq",
|
| 147 |
+
"components": [
|
| 148 |
+
"Intents and yes/no QA"
|
| 149 |
+
],
|
| 150 |
+
"licence_recorded": [
|
| 151 |
+
"cc-by-sa-3.0"
|
| 152 |
+
],
|
| 153 |
+
"link": "https://huggingface.co/datasets/google/boolq",
|
| 154 |
+
"share_alike": true
|
| 155 |
+
},
|
| 156 |
+
{
|
| 157 |
+
"id": "google/civil_comments",
|
| 158 |
+
"components": [
|
| 159 |
+
"Themes"
|
| 160 |
+
],
|
| 161 |
+
"licence_recorded": [
|
| 162 |
+
"cc0-1.0"
|
| 163 |
+
],
|
| 164 |
+
"link": "https://huggingface.co/datasets/google/civil_comments"
|
| 165 |
+
},
|
| 166 |
+
{
|
| 167 |
+
"id": "hardfam:F1",
|
| 168 |
+
"components": [
|
| 169 |
+
"Hard cases"
|
| 170 |
+
],
|
| 171 |
+
"licence_recorded": [
|
| 172 |
+
"generated"
|
| 173 |
+
],
|
| 174 |
+
"link": null,
|
| 175 |
+
"note": "hard-case family written by an OpenAI GPT model; labels computed by code"
|
| 176 |
+
},
|
| 177 |
+
{
|
| 178 |
+
"id": "hardfam:F2",
|
| 179 |
+
"components": [
|
| 180 |
+
"Hard cases"
|
| 181 |
+
],
|
| 182 |
+
"licence_recorded": [
|
| 183 |
+
"generated"
|
| 184 |
+
],
|
| 185 |
+
"link": null,
|
| 186 |
+
"note": "hard-case family generated by code"
|
| 187 |
+
},
|
| 188 |
+
{
|
| 189 |
+
"id": "hardfam:F3",
|
| 190 |
+
"components": [
|
| 191 |
+
"Hard cases"
|
| 192 |
+
],
|
| 193 |
+
"licence_recorded": [
|
| 194 |
+
"generated"
|
| 195 |
+
],
|
| 196 |
+
"link": null,
|
| 197 |
+
"note": "hard-case family generated by code"
|
| 198 |
+
},
|
| 199 |
+
{
|
| 200 |
+
"id": "hardfam:F6",
|
| 201 |
+
"components": [
|
| 202 |
+
"Hard cases"
|
| 203 |
+
],
|
| 204 |
+
"licence_recorded": [
|
| 205 |
+
"generated"
|
| 206 |
+
],
|
| 207 |
+
"link": null,
|
| 208 |
+
"note": "hard-case family written by an OpenAI GPT model; labels computed by code"
|
| 209 |
+
},
|
| 210 |
+
{
|
| 211 |
+
"id": "hardfam:F9",
|
| 212 |
+
"components": [
|
| 213 |
+
"Hard cases"
|
| 214 |
+
],
|
| 215 |
+
"licence_recorded": [
|
| 216 |
+
"generated"
|
| 217 |
+
],
|
| 218 |
+
"link": null,
|
| 219 |
+
"note": "hard-case family generated by code"
|
| 220 |
+
},
|
| 221 |
+
{
|
| 222 |
+
"id": "hugosousa/TimeQA",
|
| 223 |
+
"components": [
|
| 224 |
+
"Public reading tasks"
|
| 225 |
+
],
|
| 226 |
+
"licence_recorded": [
|
| 227 |
+
"bsd-3-clause-clear"
|
| 228 |
+
],
|
| 229 |
+
"link": "https://huggingface.co/datasets/hugosousa/TimeQA"
|
| 230 |
+
},
|
| 231 |
+
{
|
| 232 |
+
"id": "jackhhao/jailbreak-classification",
|
| 233 |
+
"components": [
|
| 234 |
+
"Themes"
|
| 235 |
+
],
|
| 236 |
+
"licence_recorded": [
|
| 237 |
+
"apache-2.0"
|
| 238 |
+
],
|
| 239 |
+
"link": "https://huggingface.co/datasets/jackhhao/jailbreak-classification",
|
| 240 |
+
"note": "its jailbreak prompts come from the jailbreak_llms collection (research purposes only); part of the benign prompts come from GPTeacher (generated by GPT-4)"
|
| 241 |
+
},
|
| 242 |
+
{
|
| 243 |
+
"id": "Lakera/gandalf_ignore_instructions",
|
| 244 |
+
"components": [
|
| 245 |
+
"Themes"
|
| 246 |
+
],
|
| 247 |
+
"licence_recorded": [
|
| 248 |
+
"mit"
|
| 249 |
+
],
|
| 250 |
+
"link": "https://huggingface.co/datasets/Lakera/gandalf_ignore_instructions"
|
| 251 |
+
},
|
| 252 |
+
{
|
| 253 |
+
"id": "lasha-nlp/CONDAQA",
|
| 254 |
+
"components": [
|
| 255 |
+
"Public reading tasks"
|
| 256 |
+
],
|
| 257 |
+
"licence_recorded": [
|
| 258 |
+
"apache-2.0"
|
| 259 |
+
],
|
| 260 |
+
"link": "https://huggingface.co/datasets/lasha-nlp/CONDAQA"
|
| 261 |
+
},
|
| 262 |
+
{
|
| 263 |
+
"id": "legacy:generated_rules:approved_earliest",
|
| 264 |
+
"components": [
|
| 265 |
+
"Mac agent checks",
|
| 266 |
+
"Option-format views"
|
| 267 |
+
],
|
| 268 |
+
"licence_recorded": [
|
| 269 |
+
"generated:round-1 project collectors and rule generator (mac_laya.tasks / trajectory_v2); no third-party text"
|
| 270 |
+
],
|
| 271 |
+
"link": null,
|
| 272 |
+
"note": "generated for this project"
|
| 273 |
+
},
|
| 274 |
+
{
|
| 275 |
+
"id": "legacy:generated_rules:cost_under_limit",
|
| 276 |
+
"components": [
|
| 277 |
+
"Mac agent checks",
|
| 278 |
+
"Option-format views"
|
| 279 |
+
],
|
| 280 |
+
"licence_recorded": [
|
| 281 |
+
"generated:round-1 project collectors and rule generator (mac_laya.tasks / trajectory_v2); no third-party text"
|
| 282 |
+
],
|
| 283 |
+
"link": null,
|
| 284 |
+
"note": "generated for this project"
|
| 285 |
+
},
|
| 286 |
+
{
|
| 287 |
+
"id": "legacy:generated_rules:priority_max",
|
| 288 |
+
"components": [
|
| 289 |
+
"Mac agent checks",
|
| 290 |
+
"Option-format views"
|
| 291 |
+
],
|
| 292 |
+
"licence_recorded": [
|
| 293 |
+
"generated:round-1 project collectors and rule generator (mac_laya.tasks / trajectory_v2); no third-party text"
|
| 294 |
+
],
|
| 295 |
+
"link": null,
|
| 296 |
+
"note": "generated for this project"
|
| 297 |
+
},
|
| 298 |
+
{
|
| 299 |
+
"id": "legacy:generated_rules:team_min_amount",
|
| 300 |
+
"components": [
|
| 301 |
+
"Mac agent checks",
|
| 302 |
+
"Option-format views"
|
| 303 |
+
],
|
| 304 |
+
"licence_recorded": [
|
| 305 |
+
"generated:round-1 project collectors and rule generator (mac_laya.tasks / trajectory_v2); no third-party text"
|
| 306 |
+
],
|
| 307 |
+
"link": null,
|
| 308 |
+
"note": "generated for this project"
|
| 309 |
+
},
|
| 310 |
+
{
|
| 311 |
+
"id": "legacy:mac_v2:filesystem_policy",
|
| 312 |
+
"components": [
|
| 313 |
+
"Mac agent checks"
|
| 314 |
+
],
|
| 315 |
+
"licence_recorded": [
|
| 316 |
+
"generated:round-1 project collectors and rule generator (mac_laya.tasks / trajectory_v2); no third-party text"
|
| 317 |
+
],
|
| 318 |
+
"link": null,
|
| 319 |
+
"note": "generated for this project"
|
| 320 |
+
},
|
| 321 |
+
{
|
| 322 |
+
"id": "Lichess/chess-puzzles",
|
| 323 |
+
"components": [
|
| 324 |
+
"Knowledge and reasoning"
|
| 325 |
+
],
|
| 326 |
+
"licence_recorded": [
|
| 327 |
+
"cc0-1.0"
|
| 328 |
+
],
|
| 329 |
+
"link": "https://huggingface.co/datasets/Lichess/chess-puzzles"
|
| 330 |
+
},
|
| 331 |
+
{
|
| 332 |
+
"id": "macjev-synth:gsm_templates",
|
| 333 |
+
"components": [
|
| 334 |
+
"Knowledge and reasoning"
|
| 335 |
+
],
|
| 336 |
+
"licence_recorded": [
|
| 337 |
+
"generated"
|
| 338 |
+
],
|
| 339 |
+
"link": null,
|
| 340 |
+
"note": "generated for this project"
|
| 341 |
+
},
|
| 342 |
+
{
|
| 343 |
+
"id": "macjev-synth:link_safety",
|
| 344 |
+
"components": [
|
| 345 |
+
"Retrieval and routing"
|
| 346 |
+
],
|
| 347 |
+
"licence_recorded": [
|
| 348 |
+
"generated"
|
| 349 |
+
],
|
| 350 |
+
"link": null,
|
| 351 |
+
"note": "generated for this project"
|
| 352 |
+
},
|
| 353 |
+
{
|
| 354 |
+
"id": "macjev-synth:sata_type",
|
| 355 |
+
"components": [
|
| 356 |
+
"Knowledge and reasoning"
|
| 357 |
+
],
|
| 358 |
+
"licence_recorded": [
|
| 359 |
+
"generated"
|
| 360 |
+
],
|
| 361 |
+
"link": null,
|
| 362 |
+
"note": "generated for this project"
|
| 363 |
+
},
|
| 364 |
+
{
|
| 365 |
+
"id": "macjev/long_table",
|
| 366 |
+
"components": [
|
| 367 |
+
"Long tables",
|
| 368 |
+
"Option-format views"
|
| 369 |
+
],
|
| 370 |
+
"licence_recorded": [
|
| 371 |
+
"generated:cc0 (programmatic synthetic tables)"
|
| 372 |
+
],
|
| 373 |
+
"link": null,
|
| 374 |
+
"note": "generated for this project"
|
| 375 |
+
},
|
| 376 |
+
{
|
| 377 |
+
"id": "macjev_sim:goal_done",
|
| 378 |
+
"components": [
|
| 379 |
+
"Mac agent checks"
|
| 380 |
+
],
|
| 381 |
+
"licence_recorded": [
|
| 382 |
+
"generated:macjev-sim (synthetic states written by project code; no third-party text)"
|
| 383 |
+
],
|
| 384 |
+
"link": null,
|
| 385 |
+
"note": "the project's own simulator; part of the goal wording was paraphrased by an OpenAI GPT model"
|
| 386 |
+
},
|
| 387 |
+
{
|
| 388 |
+
"id": "massive-1.1:intent",
|
| 389 |
+
"components": [
|
| 390 |
+
"Intents and yes/no QA"
|
| 391 |
+
],
|
| 392 |
+
"licence_recorded": [
|
| 393 |
+
"cc-by-4.0"
|
| 394 |
+
],
|
| 395 |
+
"link": "https://huggingface.co/datasets/AmazonScience/massive"
|
| 396 |
+
},
|
| 397 |
+
{
|
| 398 |
+
"id": "mteb/banking77",
|
| 399 |
+
"components": [
|
| 400 |
+
"Retrieval and routing"
|
| 401 |
+
],
|
| 402 |
+
"licence_recorded": [
|
| 403 |
+
"cc-by-4.0"
|
| 404 |
+
],
|
| 405 |
+
"link": "https://huggingface.co/datasets/mteb/banking77",
|
| 406 |
+
"note": "BANKING77 by PolyAI: CC BY 4.0 upstream (https://huggingface.co/datasets/PolyAI/banking77); rows taken from the MTEB mirror, whose card says MIT"
|
| 407 |
+
},
|
| 408 |
+
{
|
| 409 |
+
"id": "neuralchemy/Prompt-injection-dataset",
|
| 410 |
+
"components": [
|
| 411 |
+
"Themes",
|
| 412 |
+
"Option-format views"
|
| 413 |
+
],
|
| 414 |
+
"licence_recorded": [
|
| 415 |
+
"apache-2.0",
|
| 416 |
+
"cc-by-4.0",
|
| 417 |
+
"mit"
|
| 418 |
+
],
|
| 419 |
+
"link": "https://huggingface.co/datasets/neuralchemy/Prompt-injection-dataset",
|
| 420 |
+
"note": "the upstream rows its card marks research-only were removed"
|
| 421 |
+
},
|
| 422 |
+
{
|
| 423 |
+
"id": "nvidia/HelpSteer2",
|
| 424 |
+
"components": [
|
| 425 |
+
"Public reading tasks",
|
| 426 |
+
"Option-format views"
|
| 427 |
+
],
|
| 428 |
+
"licence_recorded": [
|
| 429 |
+
"cc-by-4.0"
|
| 430 |
+
],
|
| 431 |
+
"link": "https://huggingface.co/datasets/nvidia/HelpSteer2",
|
| 432 |
+
"note": "responses mostly written by NVIDIA Nemotron models and Mixtral-8x7B-Instruct"
|
| 433 |
+
},
|
| 434 |
+
{
|
| 435 |
+
"id": "openai/gsm8k",
|
| 436 |
+
"components": [
|
| 437 |
+
"Knowledge and reasoning"
|
| 438 |
+
],
|
| 439 |
+
"licence_recorded": [
|
| 440 |
+
"mit"
|
| 441 |
+
],
|
| 442 |
+
"link": "https://huggingface.co/datasets/openai/gsm8k"
|
| 443 |
+
},
|
| 444 |
+
{
|
| 445 |
+
"id": "openlifescienceai/medmcqa",
|
| 446 |
+
"components": [
|
| 447 |
+
"Knowledge and reasoning"
|
| 448 |
+
],
|
| 449 |
+
"licence_recorded": [
|
| 450 |
+
"apache-2.0"
|
| 451 |
+
],
|
| 452 |
+
"link": "https://huggingface.co/datasets/openlifescienceai/medmcqa"
|
| 453 |
+
},
|
| 454 |
+
{
|
| 455 |
+
"id": "rajpurkar/squad_v2",
|
| 456 |
+
"components": [
|
| 457 |
+
"Themes"
|
| 458 |
+
],
|
| 459 |
+
"licence_recorded": [
|
| 460 |
+
"cc-by-sa-4.0"
|
| 461 |
+
],
|
| 462 |
+
"link": "https://huggingface.co/datasets/rajpurkar/squad_v2",
|
| 463 |
+
"share_alike": true
|
| 464 |
+
},
|
| 465 |
+
{
|
| 466 |
+
"id": "Rowan/hellaswag",
|
| 467 |
+
"components": [
|
| 468 |
+
"Language"
|
| 469 |
+
],
|
| 470 |
+
"licence_recorded": [
|
| 471 |
+
"mit"
|
| 472 |
+
],
|
| 473 |
+
"link": "https://huggingface.co/datasets/Rowan/hellaswag",
|
| 474 |
+
"note": "MIT only in the card text (no licence field); the original GitHub repository is blocked after a DMCA notice from wikiHow; only the ActivityNet-caption items were used"
|
| 475 |
+
},
|
| 476 |
+
{
|
| 477 |
+
"id": "stanfordnlp/snli",
|
| 478 |
+
"components": [
|
| 479 |
+
"Language"
|
| 480 |
+
],
|
| 481 |
+
"licence_recorded": [
|
| 482 |
+
"cc-by-sa-4.0"
|
| 483 |
+
],
|
| 484 |
+
"link": "https://huggingface.co/datasets/stanfordnlp/snli",
|
| 485 |
+
"share_alike": true
|
| 486 |
+
},
|
| 487 |
+
{
|
| 488 |
+
"id": "synth-v4:algo_reasoning",
|
| 489 |
+
"components": [
|
| 490 |
+
"Knowledge and reasoning"
|
| 491 |
+
],
|
| 492 |
+
"licence_recorded": [
|
| 493 |
+
"generated"
|
| 494 |
+
],
|
| 495 |
+
"link": null,
|
| 496 |
+
"note": "generated for this project"
|
| 497 |
+
},
|
| 498 |
+
{
|
| 499 |
+
"id": "synth:causal_graph_scm",
|
| 500 |
+
"components": [
|
| 501 |
+
"Knowledge and reasoning"
|
| 502 |
+
],
|
| 503 |
+
"licence_recorded": [
|
| 504 |
+
"generated"
|
| 505 |
+
],
|
| 506 |
+
"link": null,
|
| 507 |
+
"note": "generated for this project"
|
| 508 |
+
},
|
| 509 |
+
{
|
| 510 |
+
"id": "synth:clinical_trial_reports",
|
| 511 |
+
"components": [
|
| 512 |
+
"Language"
|
| 513 |
+
],
|
| 514 |
+
"licence_recorded": [
|
| 515 |
+
"generated"
|
| 516 |
+
],
|
| 517 |
+
"link": null,
|
| 518 |
+
"note": "generated for this project"
|
| 519 |
+
},
|
| 520 |
+
{
|
| 521 |
+
"id": "synth:reasoning_relevance",
|
| 522 |
+
"components": [
|
| 523 |
+
"Retrieval and routing"
|
| 524 |
+
],
|
| 525 |
+
"licence_recorded": [
|
| 526 |
+
"generated"
|
| 527 |
+
],
|
| 528 |
+
"link": null,
|
| 529 |
+
"note": "generated for this project"
|
| 530 |
+
},
|
| 531 |
+
{
|
| 532 |
+
"id": "tau/commonsense_qa",
|
| 533 |
+
"components": [
|
| 534 |
+
"Knowledge and reasoning"
|
| 535 |
+
],
|
| 536 |
+
"licence_recorded": [
|
| 537 |
+
"mit"
|
| 538 |
+
],
|
| 539 |
+
"link": "https://huggingface.co/datasets/tau/commonsense_qa"
|
| 540 |
+
},
|
| 541 |
+
{
|
| 542 |
+
"id": "teacher:themes_jailbreak",
|
| 543 |
+
"components": [
|
| 544 |
+
"Themes"
|
| 545 |
+
],
|
| 546 |
+
"licence_recorded": [
|
| 547 |
+
"generated:claude-opus-5.5"
|
| 548 |
+
],
|
| 549 |
+
"link": null,
|
| 550 |
+
"note": "jailbreak and toxicity prompts written and labelled by an Anthropic Claude model"
|
| 551 |
+
},
|
| 552 |
+
{
|
| 553 |
+
"id": "theatticusproject/maud",
|
| 554 |
+
"components": [
|
| 555 |
+
"Public reading tasks",
|
| 556 |
+
"Option-format views"
|
| 557 |
+
],
|
| 558 |
+
"licence_recorded": [
|
| 559 |
+
"cc-by-4.0"
|
| 560 |
+
],
|
| 561 |
+
"link": "https://huggingface.co/datasets/theatticusproject/maud"
|
| 562 |
+
},
|
| 563 |
+
{
|
| 564 |
+
"id": "tonytan48/TempReason",
|
| 565 |
+
"components": [
|
| 566 |
+
"Public reading tasks"
|
| 567 |
+
],
|
| 568 |
+
"licence_recorded": [
|
| 569 |
+
"cc-by-sa-3.0"
|
| 570 |
+
],
|
| 571 |
+
"link": "https://huggingface.co/datasets/tonytan48/TempReason",
|
| 572 |
+
"share_alike": true
|
| 573 |
+
},
|
| 574 |
+
{
|
| 575 |
+
"id": "TrustAIRLab/in-the-wild-jailbreak-prompts",
|
| 576 |
+
"components": [
|
| 577 |
+
"Themes",
|
| 578 |
+
"Option-format views"
|
| 579 |
+
],
|
| 580 |
+
"licence_recorded": [
|
| 581 |
+
"mit"
|
| 582 |
+
],
|
| 583 |
+
"link": "https://huggingface.co/datasets/TrustAIRLab/in-the-wild-jailbreak-prompts",
|
| 584 |
+
"note": "prompts from the jailbreak_llms collection, which states it is for research purposes only"
|
| 585 |
+
},
|
| 586 |
+
{
|
| 587 |
+
"id": "typed_synthetic",
|
| 588 |
+
"components": [
|
| 589 |
+
"Typed decisions"
|
| 590 |
+
],
|
| 591 |
+
"licence_recorded": [
|
| 592 |
+
"generated"
|
| 593 |
+
],
|
| 594 |
+
"link": null,
|
| 595 |
+
"note": "model-written business workflows: designed by OpenAI GPT and Anthropic Claude models, labelled by Claude models"
|
| 596 |
+
},
|
| 597 |
+
{
|
| 598 |
+
"id": "ucinlp/drop",
|
| 599 |
+
"components": [
|
| 600 |
+
"Public reading tasks",
|
| 601 |
+
"Option-format views"
|
| 602 |
+
],
|
| 603 |
+
"licence_recorded": [
|
| 604 |
+
"cc-by-sa-4.0"
|
| 605 |
+
],
|
| 606 |
+
"link": "https://huggingface.co/datasets/ucinlp/drop",
|
| 607 |
+
"share_alike": true
|
| 608 |
+
},
|
| 609 |
+
{
|
| 610 |
+
"id": "UCLNLP/sharc",
|
| 611 |
+
"components": [
|
| 612 |
+
"Public reading tasks"
|
| 613 |
+
],
|
| 614 |
+
"licence_recorded": [
|
| 615 |
+
"cc-by-sa-3.0"
|
| 616 |
+
],
|
| 617 |
+
"link": "https://huggingface.co/datasets/UCLNLP/sharc",
|
| 618 |
+
"share_alike": true
|
| 619 |
+
},
|
| 620 |
+
{
|
| 621 |
+
"id": "wenhu/tab_fact",
|
| 622 |
+
"components": [
|
| 623 |
+
"Public reading tasks"
|
| 624 |
+
],
|
| 625 |
+
"licence_recorded": [
|
| 626 |
+
"cc-by-4.0"
|
| 627 |
+
],
|
| 628 |
+
"link": "https://huggingface.co/datasets/wenhu/tab_fact"
|
| 629 |
+
},
|
| 630 |
+
{
|
| 631 |
+
"id": "yanismiraoui/prompt_injections",
|
| 632 |
+
"components": [
|
| 633 |
+
"Themes"
|
| 634 |
+
],
|
| 635 |
+
"licence_recorded": [
|
| 636 |
+
"apache-2.0"
|
| 637 |
+
],
|
| 638 |
+
"link": "https://huggingface.co/datasets/yanismiraoui/prompt_injections"
|
| 639 |
+
}
|
| 640 |
+
]
|
| 641 |
+
}
|
validation/latency_2b.json
ADDED
|
@@ -0,0 +1,1568 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"format": "jev-style-latency-v1",
|
| 3 |
+
"model": "Jev-Style-2B-Decision-v3",
|
| 4 |
+
"machine": {
|
| 5 |
+
"chip": "Apple M1 Max",
|
| 6 |
+
"memory_bytes": 68719476736,
|
| 7 |
+
"macos": "15.7.5",
|
| 8 |
+
"python": "3.12.13"
|
| 9 |
+
},
|
| 10 |
+
"shared_machine_note": "measured while other agents' jobs ran on the same Mac (among them a CPU-heavy PyTorch parity job using ~3.5 cores and ~16 GB); load averages at the end of each run are recorded per row. Treat the numbers as indicative, not as a clean benchmark.",
|
| 11 |
+
"protocol": {
|
| 12 |
+
"runtimes": "the staged runtimes of the three repos (jev_style_decision_gguf.py + jev-score-v2 built with build_jev_score.sh against llama.cpp 441df11f, Metal, all layers on the GPU; jev_style_decision_mlx.py, mlx 0.32.2 / mlx-lm 0.31.3; jev_style_decision.py on MPS, float32)",
|
| 13 |
+
"weights": "trained release weights: release_2b/gguf/model-*.gguf (tensor data identical to the named repo files), release_2b/mlx/{bf16,affine8-g64}, candidate_2b/hf-candidate (torch)",
|
| 14 |
+
"state": "plain text (repository documentation + source code, English) cut to target-150 tokens; the total input per question is recorded in input_tokens_per_question",
|
| 15 |
+
"questions": "n_questions=1: one 4-option choice question (decide); n_questions=10: 10 mixed questions (4 choice, 4 true/false, 2 score) about the same state in one score_many call",
|
| 16 |
+
"one_process_per_row": true,
|
| 17 |
+
"cold_s": "first scoring call after loading (state + questions; includes GPU warm-up)",
|
| 18 |
+
"warm_median_s": "median of 3 further calls, cached state dropped before each (state recomputed)",
|
| 19 |
+
"state_cached_median_s": "median of 3 calls with the state already computed (only the question blocks run)",
|
| 20 |
+
"load_s": "runtime construction (weights from the OS file cache in most rows)",
|
| 21 |
+
"wall_time": "time.perf_counter around decide()/score_many(), incl. tokenisation and rendering",
|
| 22 |
+
"peak_rss_bytes": "ru_maxrss of the Python process (and of the jev-score-v2 child for GGUF); includes memory-mapped weight pages",
|
| 23 |
+
"peak_phys_footprint_bytes": "macOS lifetime-max physical footprint (proc_pid_rusage v4): memory the process owns, incl. Metal / MLX buffers it allocates. It does NOT count clean memory-mapped file pages, so for GGUF (jev-score-v2 maps the .gguf file) it excludes the weights and is not a memory requirement; use peak_rss_bytes.jev_score_v2 (which includes the mapped weight pages) as the upper bound for GGUF"
|
| 24 |
+
},
|
| 25 |
+
"reruns": {
|
| 26 |
+
"gguf_and_mlx_rows": "all 18 GGUF rows and all 12 MLX rows were re-measured on 2026-09-27 03:11-03:28 (fix round, same script, same state text, same answers) because an independent re-run of the first session's GGUF Q8_0 / Q4_K_M 10-question rows was ~2.4x faster (contention during the first session). The first-session rows are kept in latency/runs_superseded_2026-09-27/ and are not used here. The 6 torch MPS rows are from the first session (not re-measured).",
|
| 27 |
+
"superseded_dir": "latency/runs_superseded_2026-09-27/"
|
| 28 |
+
},
|
| 29 |
+
"complete": true,
|
| 30 |
+
"missing_runs": [],
|
| 31 |
+
"rows": [
|
| 32 |
+
{
|
| 33 |
+
"backend": "gguf-f16",
|
| 34 |
+
"n_questions": 1,
|
| 35 |
+
"state_tokens": 878,
|
| 36 |
+
"input_tokens_per_question": [
|
| 37 |
+
943
|
| 38 |
+
],
|
| 39 |
+
"load_s": 2.6054,
|
| 40 |
+
"cold_s": 0.5624,
|
| 41 |
+
"warm_median_s": 0.5242,
|
| 42 |
+
"warm_s": [
|
| 43 |
+
0.5203,
|
| 44 |
+
0.5345,
|
| 45 |
+
0.5242
|
| 46 |
+
],
|
| 47 |
+
"state_cached_median_s": 0.0653,
|
| 48 |
+
"peak_rss_bytes": {
|
| 49 |
+
"python": 352616448,
|
| 50 |
+
"jev_score_v2": 4451008512
|
| 51 |
+
},
|
| 52 |
+
"peak_phys_footprint_bytes": {
|
| 53 |
+
"python": 252413696,
|
| 54 |
+
"jev_score_v2": 660384576
|
| 55 |
+
},
|
| 56 |
+
"results_identical_cold_vs_state_cached": true,
|
| 57 |
+
"loadavg_at_end": [
|
| 58 |
+
9.59,
|
| 59 |
+
9.9,
|
| 60 |
+
10.98
|
| 61 |
+
],
|
| 62 |
+
"measured_unix": 1790442718.8146281,
|
| 63 |
+
"settings": {
|
| 64 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 65 |
+
"n_gpu_layers": 999,
|
| 66 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 67 |
+
"gguf": "release_2b/gguf/model-f16.gguf"
|
| 68 |
+
},
|
| 69 |
+
"raw": "latency/runs/gguf-f16_1024_1q.json"
|
| 70 |
+
},
|
| 71 |
+
{
|
| 72 |
+
"backend": "gguf-f16",
|
| 73 |
+
"n_questions": 10,
|
| 74 |
+
"state_tokens": 878,
|
| 75 |
+
"input_tokens_per_question": [
|
| 76 |
+
943,
|
| 77 |
+
918,
|
| 78 |
+
925,
|
| 79 |
+
911,
|
| 80 |
+
918,
|
| 81 |
+
921,
|
| 82 |
+
943,
|
| 83 |
+
917,
|
| 84 |
+
912,
|
| 85 |
+
919
|
| 86 |
+
],
|
| 87 |
+
"load_s": 1.1941,
|
| 88 |
+
"cold_s": 0.994,
|
| 89 |
+
"warm_median_s": 0.968,
|
| 90 |
+
"warm_s": [
|
| 91 |
+
0.968,
|
| 92 |
+
0.9464,
|
| 93 |
+
0.9713
|
| 94 |
+
],
|
| 95 |
+
"state_cached_median_s": 0.4965,
|
| 96 |
+
"peak_rss_bytes": {
|
| 97 |
+
"python": 328564736,
|
| 98 |
+
"jev_score_v2": 4516610048
|
| 99 |
+
},
|
| 100 |
+
"peak_phys_footprint_bytes": {
|
| 101 |
+
"python": 254527296,
|
| 102 |
+
"jev_score_v2": 676899648
|
| 103 |
+
},
|
| 104 |
+
"results_identical_cold_vs_state_cached": true,
|
| 105 |
+
"loadavg_at_end": [
|
| 106 |
+
10.0,
|
| 107 |
+
9.97,
|
| 108 |
+
10.99
|
| 109 |
+
],
|
| 110 |
+
"measured_unix": 1790442726.19508,
|
| 111 |
+
"settings": {
|
| 112 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 113 |
+
"n_gpu_layers": 999,
|
| 114 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 115 |
+
"gguf": "release_2b/gguf/model-f16.gguf"
|
| 116 |
+
},
|
| 117 |
+
"raw": "latency/runs/gguf-f16_1024_10q.json"
|
| 118 |
+
},
|
| 119 |
+
{
|
| 120 |
+
"backend": "gguf-f16",
|
| 121 |
+
"n_questions": 1,
|
| 122 |
+
"state_tokens": 3950,
|
| 123 |
+
"input_tokens_per_question": [
|
| 124 |
+
4015
|
| 125 |
+
],
|
| 126 |
+
"load_s": 1.1659,
|
| 127 |
+
"cold_s": 2.2122,
|
| 128 |
+
"warm_median_s": 2.1753,
|
| 129 |
+
"warm_s": [
|
| 130 |
+
2.1909,
|
| 131 |
+
2.1753,
|
| 132 |
+
2.1733
|
| 133 |
+
],
|
| 134 |
+
"state_cached_median_s": 0.078,
|
| 135 |
+
"peak_rss_bytes": {
|
| 136 |
+
"python": 354697216,
|
| 137 |
+
"jev_score_v2": 4568334336
|
| 138 |
+
},
|
| 139 |
+
"peak_phys_footprint_bytes": {
|
| 140 |
+
"python": 257705600,
|
| 141 |
+
"jev_score_v2": 722676736
|
| 142 |
+
},
|
| 143 |
+
"results_identical_cold_vs_state_cached": true,
|
| 144 |
+
"loadavg_at_end": [
|
| 145 |
+
9.01,
|
| 146 |
+
9.76,
|
| 147 |
+
10.9
|
| 148 |
+
],
|
| 149 |
+
"measured_unix": 1790442737.183161,
|
| 150 |
+
"settings": {
|
| 151 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 152 |
+
"n_gpu_layers": 999,
|
| 153 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 154 |
+
"gguf": "release_2b/gguf/model-f16.gguf"
|
| 155 |
+
},
|
| 156 |
+
"raw": "latency/runs/gguf-f16_4096_1q.json"
|
| 157 |
+
},
|
| 158 |
+
{
|
| 159 |
+
"backend": "gguf-f16",
|
| 160 |
+
"n_questions": 10,
|
| 161 |
+
"state_tokens": 3950,
|
| 162 |
+
"input_tokens_per_question": [
|
| 163 |
+
4015,
|
| 164 |
+
3990,
|
| 165 |
+
3997,
|
| 166 |
+
3983,
|
| 167 |
+
3990,
|
| 168 |
+
3993,
|
| 169 |
+
4015,
|
| 170 |
+
3989,
|
| 171 |
+
3984,
|
| 172 |
+
3991
|
| 173 |
+
],
|
| 174 |
+
"load_s": 1.2112,
|
| 175 |
+
"cold_s": 2.6904,
|
| 176 |
+
"warm_median_s": 2.6583,
|
| 177 |
+
"warm_s": [
|
| 178 |
+
2.6583,
|
| 179 |
+
2.6665,
|
| 180 |
+
2.6378
|
| 181 |
+
],
|
| 182 |
+
"state_cached_median_s": 0.5467,
|
| 183 |
+
"peak_rss_bytes": {
|
| 184 |
+
"python": 331694080,
|
| 185 |
+
"jev_score_v2": 4564172800
|
| 186 |
+
},
|
| 187 |
+
"peak_phys_footprint_bytes": {
|
| 188 |
+
"python": 248334016,
|
| 189 |
+
"jev_score_v2": 720382976
|
| 190 |
+
},
|
| 191 |
+
"results_identical_cold_vs_state_cached": true,
|
| 192 |
+
"loadavg_at_end": [
|
| 193 |
+
8.62,
|
| 194 |
+
9.62,
|
| 195 |
+
10.83
|
| 196 |
+
],
|
| 197 |
+
"measured_unix": 1790442751.5065348,
|
| 198 |
+
"settings": {
|
| 199 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 200 |
+
"n_gpu_layers": 999,
|
| 201 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 202 |
+
"gguf": "release_2b/gguf/model-f16.gguf"
|
| 203 |
+
},
|
| 204 |
+
"raw": "latency/runs/gguf-f16_4096_10q.json"
|
| 205 |
+
},
|
| 206 |
+
{
|
| 207 |
+
"backend": "gguf-f16",
|
| 208 |
+
"n_questions": 1,
|
| 209 |
+
"state_tokens": 24436,
|
| 210 |
+
"input_tokens_per_question": [
|
| 211 |
+
24501
|
| 212 |
+
],
|
| 213 |
+
"load_s": 1.1784,
|
| 214 |
+
"cold_s": 16.2299,
|
| 215 |
+
"warm_median_s": 16.1651,
|
| 216 |
+
"warm_s": [
|
| 217 |
+
16.1645,
|
| 218 |
+
16.1651,
|
| 219 |
+
16.2375
|
| 220 |
+
],
|
| 221 |
+
"state_cached_median_s": 0.1677,
|
| 222 |
+
"peak_rss_bytes": {
|
| 223 |
+
"python": 349683712,
|
| 224 |
+
"jev_score_v2": 4734812160
|
| 225 |
+
},
|
| 226 |
+
"peak_phys_footprint_bytes": {
|
| 227 |
+
"python": 239191744,
|
| 228 |
+
"jev_score_v2": 882732352
|
| 229 |
+
},
|
| 230 |
+
"results_identical_cold_vs_state_cached": true,
|
| 231 |
+
"loadavg_at_end": [
|
| 232 |
+
9.74,
|
| 233 |
+
9.66,
|
| 234 |
+
10.75
|
| 235 |
+
],
|
| 236 |
+
"measured_unix": 1790442818.798799,
|
| 237 |
+
"settings": {
|
| 238 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 239 |
+
"n_gpu_layers": 999,
|
| 240 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 241 |
+
"gguf": "release_2b/gguf/model-f16.gguf"
|
| 242 |
+
},
|
| 243 |
+
"raw": "latency/runs/gguf-f16_24576_1q.json"
|
| 244 |
+
},
|
| 245 |
+
{
|
| 246 |
+
"backend": "gguf-f16",
|
| 247 |
+
"n_questions": 10,
|
| 248 |
+
"state_tokens": 24436,
|
| 249 |
+
"input_tokens_per_question": [
|
| 250 |
+
24501,
|
| 251 |
+
24476,
|
| 252 |
+
24483,
|
| 253 |
+
24469,
|
| 254 |
+
24476,
|
| 255 |
+
24479,
|
| 256 |
+
24501,
|
| 257 |
+
24475,
|
| 258 |
+
24470,
|
| 259 |
+
24477
|
| 260 |
+
],
|
| 261 |
+
"load_s": 1.225,
|
| 262 |
+
"cold_s": 16.9884,
|
| 263 |
+
"warm_median_s": 16.8115,
|
| 264 |
+
"warm_s": [
|
| 265 |
+
16.8115,
|
| 266 |
+
16.675,
|
| 267 |
+
16.8156
|
| 268 |
+
],
|
| 269 |
+
"state_cached_median_s": 0.8643,
|
| 270 |
+
"peak_rss_bytes": {
|
| 271 |
+
"python": 367919104,
|
| 272 |
+
"jev_score_v2": 4738170880
|
| 273 |
+
},
|
| 274 |
+
"peak_phys_footprint_bytes": {
|
| 275 |
+
"python": 242992832,
|
| 276 |
+
"jev_score_v2": 887975168
|
| 277 |
+
},
|
| 278 |
+
"results_identical_cold_vs_state_cached": true,
|
| 279 |
+
"loadavg_at_end": [
|
| 280 |
+
8.02,
|
| 281 |
+
9.14,
|
| 282 |
+
10.46
|
| 283 |
+
],
|
| 284 |
+
"measured_unix": 1790442890.769493,
|
| 285 |
+
"settings": {
|
| 286 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 287 |
+
"n_gpu_layers": 999,
|
| 288 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 289 |
+
"gguf": "release_2b/gguf/model-f16.gguf"
|
| 290 |
+
},
|
| 291 |
+
"raw": "latency/runs/gguf-f16_24576_10q.json"
|
| 292 |
+
},
|
| 293 |
+
{
|
| 294 |
+
"backend": "gguf-q8_0",
|
| 295 |
+
"n_questions": 1,
|
| 296 |
+
"state_tokens": 878,
|
| 297 |
+
"input_tokens_per_question": [
|
| 298 |
+
943
|
| 299 |
+
],
|
| 300 |
+
"load_s": 1.7934,
|
| 301 |
+
"cold_s": 0.6136,
|
| 302 |
+
"warm_median_s": 0.5663,
|
| 303 |
+
"warm_s": [
|
| 304 |
+
0.5678,
|
| 305 |
+
0.5663,
|
| 306 |
+
0.5663
|
| 307 |
+
],
|
| 308 |
+
"state_cached_median_s": 0.0682,
|
| 309 |
+
"peak_rss_bytes": {
|
| 310 |
+
"python": 328974336,
|
| 311 |
+
"jev_score_v2": 2721579008
|
| 312 |
+
},
|
| 313 |
+
"peak_phys_footprint_bytes": {
|
| 314 |
+
"python": 248874624,
|
| 315 |
+
"jev_score_v2": 668163520
|
| 316 |
+
},
|
| 317 |
+
"results_identical_cold_vs_state_cached": true,
|
| 318 |
+
"loadavg_at_end": [
|
| 319 |
+
7.69,
|
| 320 |
+
9.05,
|
| 321 |
+
10.42
|
| 322 |
+
],
|
| 323 |
+
"measured_unix": 1790442895.894016,
|
| 324 |
+
"settings": {
|
| 325 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 326 |
+
"n_gpu_layers": 999,
|
| 327 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 328 |
+
"gguf": "release_2b/gguf/model-q8_0.gguf"
|
| 329 |
+
},
|
| 330 |
+
"raw": "latency/runs/gguf-q8_0_1024_1q.json"
|
| 331 |
+
},
|
| 332 |
+
{
|
| 333 |
+
"backend": "gguf-q8_0",
|
| 334 |
+
"n_questions": 10,
|
| 335 |
+
"state_tokens": 878,
|
| 336 |
+
"input_tokens_per_question": [
|
| 337 |
+
943,
|
| 338 |
+
918,
|
| 339 |
+
925,
|
| 340 |
+
911,
|
| 341 |
+
918,
|
| 342 |
+
921,
|
| 343 |
+
943,
|
| 344 |
+
917,
|
| 345 |
+
912,
|
| 346 |
+
919
|
| 347 |
+
],
|
| 348 |
+
"load_s": 1.0682,
|
| 349 |
+
"cold_s": 1.073,
|
| 350 |
+
"warm_median_s": 1.0243,
|
| 351 |
+
"warm_s": [
|
| 352 |
+
1.0244,
|
| 353 |
+
1.0243,
|
| 354 |
+
1.0231
|
| 355 |
+
],
|
| 356 |
+
"state_cached_median_s": 0.5268,
|
| 357 |
+
"peak_rss_bytes": {
|
| 358 |
+
"python": 347635712,
|
| 359 |
+
"jev_score_v2": 2757804032
|
| 360 |
+
},
|
| 361 |
+
"peak_phys_footprint_bytes": {
|
| 362 |
+
"python": 258377344,
|
| 363 |
+
"jev_score_v2": 674569792
|
| 364 |
+
},
|
| 365 |
+
"results_identical_cold_vs_state_cached": true,
|
| 366 |
+
"loadavg_at_end": [
|
| 367 |
+
7.24,
|
| 368 |
+
8.94,
|
| 369 |
+
10.37
|
| 370 |
+
],
|
| 371 |
+
"measured_unix": 1790442903.5177228,
|
| 372 |
+
"settings": {
|
| 373 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 374 |
+
"n_gpu_layers": 999,
|
| 375 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 376 |
+
"gguf": "release_2b/gguf/model-q8_0.gguf"
|
| 377 |
+
},
|
| 378 |
+
"raw": "latency/runs/gguf-q8_0_1024_10q.json"
|
| 379 |
+
},
|
| 380 |
+
{
|
| 381 |
+
"backend": "gguf-q8_0",
|
| 382 |
+
"n_questions": 1,
|
| 383 |
+
"state_tokens": 3950,
|
| 384 |
+
"input_tokens_per_question": [
|
| 385 |
+
4015
|
| 386 |
+
],
|
| 387 |
+
"load_s": 1.0689,
|
| 388 |
+
"cold_s": 2.3987,
|
| 389 |
+
"warm_median_s": 2.3345,
|
| 390 |
+
"warm_s": [
|
| 391 |
+
2.3333,
|
| 392 |
+
2.3488,
|
| 393 |
+
2.3345
|
| 394 |
+
],
|
| 395 |
+
"state_cached_median_s": 0.082,
|
| 396 |
+
"peak_rss_bytes": {
|
| 397 |
+
"python": 354189312,
|
| 398 |
+
"jev_score_v2": 2807808000
|
| 399 |
+
},
|
| 400 |
+
"peak_phys_footprint_bytes": {
|
| 401 |
+
"python": 247596736,
|
| 402 |
+
"jev_score_v2": 719183680
|
| 403 |
+
},
|
| 404 |
+
"results_identical_cold_vs_state_cached": true,
|
| 405 |
+
"loadavg_at_end": [
|
| 406 |
+
6.58,
|
| 407 |
+
8.74,
|
| 408 |
+
10.28
|
| 409 |
+
],
|
| 410 |
+
"measured_unix": 1790442915.085064,
|
| 411 |
+
"settings": {
|
| 412 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 413 |
+
"n_gpu_layers": 999,
|
| 414 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 415 |
+
"gguf": "release_2b/gguf/model-q8_0.gguf"
|
| 416 |
+
},
|
| 417 |
+
"raw": "latency/runs/gguf-q8_0_4096_1q.json"
|
| 418 |
+
},
|
| 419 |
+
{
|
| 420 |
+
"backend": "gguf-q8_0",
|
| 421 |
+
"n_questions": 10,
|
| 422 |
+
"state_tokens": 3950,
|
| 423 |
+
"input_tokens_per_question": [
|
| 424 |
+
4015,
|
| 425 |
+
3990,
|
| 426 |
+
3997,
|
| 427 |
+
3983,
|
| 428 |
+
3990,
|
| 429 |
+
3993,
|
| 430 |
+
4015,
|
| 431 |
+
3989,
|
| 432 |
+
3984,
|
| 433 |
+
3991
|
| 434 |
+
],
|
| 435 |
+
"load_s": 1.0684,
|
| 436 |
+
"cold_s": 2.8854,
|
| 437 |
+
"warm_median_s": 2.8178,
|
| 438 |
+
"warm_s": [
|
| 439 |
+
2.8178,
|
| 440 |
+
2.8439,
|
| 441 |
+
2.816
|
| 442 |
+
],
|
| 443 |
+
"state_cached_median_s": 0.5719,
|
| 444 |
+
"peak_rss_bytes": {
|
| 445 |
+
"python": 319045632,
|
| 446 |
+
"jev_score_v2": 2799091712
|
| 447 |
+
},
|
| 448 |
+
"peak_phys_footprint_bytes": {
|
| 449 |
+
"python": 243910336,
|
| 450 |
+
"jev_score_v2": 716169152
|
| 451 |
+
},
|
| 452 |
+
"results_identical_cold_vs_state_cached": true,
|
| 453 |
+
"loadavg_at_end": [
|
| 454 |
+
7.36,
|
| 455 |
+
8.8,
|
| 456 |
+
10.28
|
| 457 |
+
],
|
| 458 |
+
"measured_unix": 1790442930.063521,
|
| 459 |
+
"settings": {
|
| 460 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 461 |
+
"n_gpu_layers": 999,
|
| 462 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 463 |
+
"gguf": "release_2b/gguf/model-q8_0.gguf"
|
| 464 |
+
},
|
| 465 |
+
"raw": "latency/runs/gguf-q8_0_4096_10q.json"
|
| 466 |
+
},
|
| 467 |
+
{
|
| 468 |
+
"backend": "gguf-q8_0",
|
| 469 |
+
"n_questions": 1,
|
| 470 |
+
"state_tokens": 24436,
|
| 471 |
+
"input_tokens_per_question": [
|
| 472 |
+
24501
|
| 473 |
+
],
|
| 474 |
+
"load_s": 1.0589,
|
| 475 |
+
"cold_s": 17.0922,
|
| 476 |
+
"warm_median_s": 17.0489,
|
| 477 |
+
"warm_s": [
|
| 478 |
+
17.0489,
|
| 479 |
+
17.0376,
|
| 480 |
+
17.0539
|
| 481 |
+
],
|
| 482 |
+
"state_cached_median_s": 0.1679,
|
| 483 |
+
"peak_rss_bytes": {
|
| 484 |
+
"python": 364937216,
|
| 485 |
+
"jev_score_v2": 2966470656
|
| 486 |
+
},
|
| 487 |
+
"peak_phys_footprint_bytes": {
|
| 488 |
+
"python": 267110080,
|
| 489 |
+
"jev_score_v2": 875831168
|
| 490 |
+
},
|
| 491 |
+
"results_identical_cold_vs_state_cached": true,
|
| 492 |
+
"loadavg_at_end": [
|
| 493 |
+
6.7,
|
| 494 |
+
8.25,
|
| 495 |
+
9.94
|
| 496 |
+
],
|
| 497 |
+
"measured_unix": 1790443000.691691,
|
| 498 |
+
"settings": {
|
| 499 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 500 |
+
"n_gpu_layers": 999,
|
| 501 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 502 |
+
"gguf": "release_2b/gguf/model-q8_0.gguf"
|
| 503 |
+
},
|
| 504 |
+
"raw": "latency/runs/gguf-q8_0_24576_1q.json"
|
| 505 |
+
},
|
| 506 |
+
{
|
| 507 |
+
"backend": "gguf-q8_0",
|
| 508 |
+
"n_questions": 10,
|
| 509 |
+
"state_tokens": 24436,
|
| 510 |
+
"input_tokens_per_question": [
|
| 511 |
+
24501,
|
| 512 |
+
24476,
|
| 513 |
+
24483,
|
| 514 |
+
24469,
|
| 515 |
+
24476,
|
| 516 |
+
24479,
|
| 517 |
+
24501,
|
| 518 |
+
24475,
|
| 519 |
+
24470,
|
| 520 |
+
24477
|
| 521 |
+
],
|
| 522 |
+
"load_s": 1.0501,
|
| 523 |
+
"cold_s": 17.8244,
|
| 524 |
+
"warm_median_s": 17.7424,
|
| 525 |
+
"warm_s": [
|
| 526 |
+
17.7424,
|
| 527 |
+
17.7312,
|
| 528 |
+
17.7793
|
| 529 |
+
],
|
| 530 |
+
"state_cached_median_s": 0.8902,
|
| 531 |
+
"peak_rss_bytes": {
|
| 532 |
+
"python": 348651520,
|
| 533 |
+
"jev_score_v2": 2967109632
|
| 534 |
+
},
|
| 535 |
+
"peak_phys_footprint_bytes": {
|
| 536 |
+
"python": 260425536,
|
| 537 |
+
"jev_score_v2": 878698496
|
| 538 |
+
},
|
| 539 |
+
"results_identical_cold_vs_state_cached": true,
|
| 540 |
+
"loadavg_at_end": [
|
| 541 |
+
11.28,
|
| 542 |
+
9.17,
|
| 543 |
+
10.13
|
| 544 |
+
],
|
| 545 |
+
"measured_unix": 1790443076.341974,
|
| 546 |
+
"settings": {
|
| 547 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 548 |
+
"n_gpu_layers": 999,
|
| 549 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 550 |
+
"gguf": "release_2b/gguf/model-q8_0.gguf"
|
| 551 |
+
},
|
| 552 |
+
"raw": "latency/runs/gguf-q8_0_24576_10q.json"
|
| 553 |
+
},
|
| 554 |
+
{
|
| 555 |
+
"backend": "gguf-q4_k_m",
|
| 556 |
+
"n_questions": 1,
|
| 557 |
+
"state_tokens": 878,
|
| 558 |
+
"input_tokens_per_question": [
|
| 559 |
+
943
|
| 560 |
+
],
|
| 561 |
+
"load_s": 1.4512,
|
| 562 |
+
"cold_s": 0.6738,
|
| 563 |
+
"warm_median_s": 0.6391,
|
| 564 |
+
"warm_s": [
|
| 565 |
+
0.6418,
|
| 566 |
+
0.6391,
|
| 567 |
+
0.6334
|
| 568 |
+
],
|
| 569 |
+
"state_cached_median_s": 0.0782,
|
| 570 |
+
"peak_rss_bytes": {
|
| 571 |
+
"python": 334921728,
|
| 572 |
+
"jev_score_v2": 1988542464
|
| 573 |
+
},
|
| 574 |
+
"peak_phys_footprint_bytes": {
|
| 575 |
+
"python": 245073728,
|
| 576 |
+
"jev_score_v2": 669308992
|
| 577 |
+
},
|
| 578 |
+
"results_identical_cold_vs_state_cached": true,
|
| 579 |
+
"loadavg_at_end": [
|
| 580 |
+
12.77,
|
| 581 |
+
9.51,
|
| 582 |
+
10.25
|
| 583 |
+
],
|
| 584 |
+
"measured_unix": 1790443081.420589,
|
| 585 |
+
"settings": {
|
| 586 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 587 |
+
"n_gpu_layers": 999,
|
| 588 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 589 |
+
"gguf": "release_2b/gguf/model-q4_k_m.gguf"
|
| 590 |
+
},
|
| 591 |
+
"raw": "latency/runs/gguf-q4_k_m_1024_1q.json"
|
| 592 |
+
},
|
| 593 |
+
{
|
| 594 |
+
"backend": "gguf-q4_k_m",
|
| 595 |
+
"n_questions": 10,
|
| 596 |
+
"state_tokens": 878,
|
| 597 |
+
"input_tokens_per_question": [
|
| 598 |
+
943,
|
| 599 |
+
918,
|
| 600 |
+
925,
|
| 601 |
+
911,
|
| 602 |
+
918,
|
| 603 |
+
921,
|
| 604 |
+
943,
|
| 605 |
+
917,
|
| 606 |
+
912,
|
| 607 |
+
919
|
| 608 |
+
],
|
| 609 |
+
"load_s": 0.9937,
|
| 610 |
+
"cold_s": 1.2045,
|
| 611 |
+
"warm_median_s": 1.157,
|
| 612 |
+
"warm_s": [
|
| 613 |
+
1.1544,
|
| 614 |
+
1.1643,
|
| 615 |
+
1.157
|
| 616 |
+
],
|
| 617 |
+
"state_cached_median_s": 0.6009,
|
| 618 |
+
"peak_rss_bytes": {
|
| 619 |
+
"python": 352059392,
|
| 620 |
+
"jev_score_v2": 2018754560
|
| 621 |
+
},
|
| 622 |
+
"peak_phys_footprint_bytes": {
|
| 623 |
+
"python": 256673344,
|
| 624 |
+
"jev_score_v2": 665065728
|
| 625 |
+
},
|
| 626 |
+
"results_identical_cold_vs_state_cached": true,
|
| 627 |
+
"loadavg_at_end": [
|
| 628 |
+
13.83,
|
| 629 |
+
9.78,
|
| 630 |
+
10.34
|
| 631 |
+
],
|
| 632 |
+
"measured_unix": 1790443089.6937559,
|
| 633 |
+
"settings": {
|
| 634 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 635 |
+
"n_gpu_layers": 999,
|
| 636 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 637 |
+
"gguf": "release_2b/gguf/model-q4_k_m.gguf"
|
| 638 |
+
},
|
| 639 |
+
"raw": "latency/runs/gguf-q4_k_m_1024_10q.json"
|
| 640 |
+
},
|
| 641 |
+
{
|
| 642 |
+
"backend": "gguf-q4_k_m",
|
| 643 |
+
"n_questions": 1,
|
| 644 |
+
"state_tokens": 3950,
|
| 645 |
+
"input_tokens_per_question": [
|
| 646 |
+
4015
|
| 647 |
+
],
|
| 648 |
+
"load_s": 0.9922,
|
| 649 |
+
"cold_s": 2.6608,
|
| 650 |
+
"warm_median_s": 2.6006,
|
| 651 |
+
"warm_s": [
|
| 652 |
+
2.6006,
|
| 653 |
+
2.6206,
|
| 654 |
+
2.5977
|
| 655 |
+
],
|
| 656 |
+
"state_cached_median_s": 0.0908,
|
| 657 |
+
"peak_rss_bytes": {
|
| 658 |
+
"python": 327221248,
|
| 659 |
+
"jev_score_v2": 2062483456
|
| 660 |
+
},
|
| 661 |
+
"peak_phys_footprint_bytes": {
|
| 662 |
+
"python": 259393408,
|
| 663 |
+
"jev_score_v2": 714692992
|
| 664 |
+
},
|
| 665 |
+
"results_identical_cold_vs_state_cached": true,
|
| 666 |
+
"loadavg_at_end": [
|
| 667 |
+
11.99,
|
| 668 |
+
9.57,
|
| 669 |
+
10.25
|
| 670 |
+
],
|
| 671 |
+
"measured_unix": 1790443102.1980171,
|
| 672 |
+
"settings": {
|
| 673 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 674 |
+
"n_gpu_layers": 999,
|
| 675 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 676 |
+
"gguf": "release_2b/gguf/model-q4_k_m.gguf"
|
| 677 |
+
},
|
| 678 |
+
"raw": "latency/runs/gguf-q4_k_m_4096_1q.json"
|
| 679 |
+
},
|
| 680 |
+
{
|
| 681 |
+
"backend": "gguf-q4_k_m",
|
| 682 |
+
"n_questions": 10,
|
| 683 |
+
"state_tokens": 3950,
|
| 684 |
+
"input_tokens_per_question": [
|
| 685 |
+
4015,
|
| 686 |
+
3990,
|
| 687 |
+
3997,
|
| 688 |
+
3983,
|
| 689 |
+
3990,
|
| 690 |
+
3993,
|
| 691 |
+
4015,
|
| 692 |
+
3989,
|
| 693 |
+
3984,
|
| 694 |
+
3991
|
| 695 |
+
],
|
| 696 |
+
"load_s": 0.9859,
|
| 697 |
+
"cold_s": 3.2053,
|
| 698 |
+
"warm_median_s": 3.1651,
|
| 699 |
+
"warm_s": [
|
| 700 |
+
3.1651,
|
| 701 |
+
3.1579,
|
| 702 |
+
3.1711
|
| 703 |
+
],
|
| 704 |
+
"state_cached_median_s": 0.6462,
|
| 705 |
+
"peak_rss_bytes": {
|
| 706 |
+
"python": 326434816,
|
| 707 |
+
"jev_score_v2": 2073214976
|
| 708 |
+
},
|
| 709 |
+
"peak_phys_footprint_bytes": {
|
| 710 |
+
"python": 245614208,
|
| 711 |
+
"jev_score_v2": 716806400
|
| 712 |
+
},
|
| 713 |
+
"results_identical_cold_vs_state_cached": true,
|
| 714 |
+
"loadavg_at_end": [
|
| 715 |
+
10.28,
|
| 716 |
+
9.31,
|
| 717 |
+
10.15
|
| 718 |
+
],
|
| 719 |
+
"measured_unix": 1790443118.634955,
|
| 720 |
+
"settings": {
|
| 721 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 722 |
+
"n_gpu_layers": 999,
|
| 723 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 724 |
+
"gguf": "release_2b/gguf/model-q4_k_m.gguf"
|
| 725 |
+
},
|
| 726 |
+
"raw": "latency/runs/gguf-q4_k_m_4096_10q.json"
|
| 727 |
+
},
|
| 728 |
+
{
|
| 729 |
+
"backend": "gguf-q4_k_m",
|
| 730 |
+
"n_questions": 1,
|
| 731 |
+
"state_tokens": 24436,
|
| 732 |
+
"input_tokens_per_question": [
|
| 733 |
+
24501
|
| 734 |
+
],
|
| 735 |
+
"load_s": 1.0041,
|
| 736 |
+
"cold_s": 18.6914,
|
| 737 |
+
"warm_median_s": 18.6165,
|
| 738 |
+
"warm_s": [
|
| 739 |
+
18.6165,
|
| 740 |
+
18.6059,
|
| 741 |
+
18.624
|
| 742 |
+
],
|
| 743 |
+
"state_cached_median_s": 0.1755,
|
| 744 |
+
"peak_rss_bytes": {
|
| 745 |
+
"python": 345686016,
|
| 746 |
+
"jev_score_v2": 2233663488
|
| 747 |
+
},
|
| 748 |
+
"peak_phys_footprint_bytes": {
|
| 749 |
+
"python": 260048576,
|
| 750 |
+
"jev_score_v2": 880335552
|
| 751 |
+
},
|
| 752 |
+
"results_identical_cold_vs_state_cached": true,
|
| 753 |
+
"loadavg_at_end": [
|
| 754 |
+
8.43,
|
| 755 |
+
9.22,
|
| 756 |
+
10.05
|
| 757 |
+
],
|
| 758 |
+
"measured_unix": 1790443195.534742,
|
| 759 |
+
"settings": {
|
| 760 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 761 |
+
"n_gpu_layers": 999,
|
| 762 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 763 |
+
"gguf": "release_2b/gguf/model-q4_k_m.gguf"
|
| 764 |
+
},
|
| 765 |
+
"raw": "latency/runs/gguf-q4_k_m_24576_1q.json"
|
| 766 |
+
},
|
| 767 |
+
{
|
| 768 |
+
"backend": "gguf-q4_k_m",
|
| 769 |
+
"n_questions": 10,
|
| 770 |
+
"state_tokens": 24436,
|
| 771 |
+
"input_tokens_per_question": [
|
| 772 |
+
24501,
|
| 773 |
+
24476,
|
| 774 |
+
24483,
|
| 775 |
+
24469,
|
| 776 |
+
24476,
|
| 777 |
+
24479,
|
| 778 |
+
24501,
|
| 779 |
+
24475,
|
| 780 |
+
24470,
|
| 781 |
+
24477
|
| 782 |
+
],
|
| 783 |
+
"load_s": 0.9967,
|
| 784 |
+
"cold_s": 19.4776,
|
| 785 |
+
"warm_median_s": 19.4309,
|
| 786 |
+
"warm_s": [
|
| 787 |
+
19.4309,
|
| 788 |
+
19.4251,
|
| 789 |
+
19.5057
|
| 790 |
+
],
|
| 791 |
+
"state_cached_median_s": 0.9616,
|
| 792 |
+
"peak_rss_bytes": {
|
| 793 |
+
"python": 354992128,
|
| 794 |
+
"jev_score_v2": 2226913280
|
| 795 |
+
},
|
| 796 |
+
"peak_phys_footprint_bytes": {
|
| 797 |
+
"python": 250791552,
|
| 798 |
+
"jev_score_v2": 870128320
|
| 799 |
+
},
|
| 800 |
+
"results_identical_cold_vs_state_cached": true,
|
| 801 |
+
"loadavg_at_end": [
|
| 802 |
+
5.63,
|
| 803 |
+
8.19,
|
| 804 |
+
9.59
|
| 805 |
+
],
|
| 806 |
+
"measured_unix": 1790443278.075001,
|
| 807 |
+
"settings": {
|
| 808 |
+
"engine": "jev-score-v2 (staged jev_score_v2.cpp, llama.cpp 441df11f, Metal)",
|
| 809 |
+
"n_gpu_layers": 999,
|
| 810 |
+
"flash_attn": "default (llama.cpp auto on Metal)",
|
| 811 |
+
"gguf": "release_2b/gguf/model-q4_k_m.gguf"
|
| 812 |
+
},
|
| 813 |
+
"raw": "latency/runs/gguf-q4_k_m_24576_10q.json"
|
| 814 |
+
},
|
| 815 |
+
{
|
| 816 |
+
"backend": "mlx-bf16",
|
| 817 |
+
"n_questions": 1,
|
| 818 |
+
"state_tokens": 878,
|
| 819 |
+
"input_tokens_per_question": [
|
| 820 |
+
943
|
| 821 |
+
],
|
| 822 |
+
"load_s": 3.6602,
|
| 823 |
+
"cold_s": 0.64,
|
| 824 |
+
"warm_median_s": 0.5658,
|
| 825 |
+
"warm_s": [
|
| 826 |
+
0.5615,
|
| 827 |
+
0.5665,
|
| 828 |
+
0.5658
|
| 829 |
+
],
|
| 830 |
+
"state_cached_median_s": 0.0796,
|
| 831 |
+
"peak_rss_bytes": {
|
| 832 |
+
"python": 4401463296
|
| 833 |
+
},
|
| 834 |
+
"peak_phys_footprint_bytes": {
|
| 835 |
+
"python": 5205486080
|
| 836 |
+
},
|
| 837 |
+
"mlx_peak_memory_bytes": 4536436474,
|
| 838 |
+
"results_identical_cold_vs_state_cached": true,
|
| 839 |
+
"loadavg_at_end": [
|
| 840 |
+
6.5,
|
| 841 |
+
8.17,
|
| 842 |
+
9.53
|
| 843 |
+
],
|
| 844 |
+
"measured_unix": 1790443305.918901,
|
| 845 |
+
"settings": {
|
| 846 |
+
"engine": "mlx 0.32.2 / mlx-lm 0.31.3 (staged runtime)",
|
| 847 |
+
"precision": "bf16",
|
| 848 |
+
"compute_dtype": null
|
| 849 |
+
},
|
| 850 |
+
"raw": "latency/runs/mlx-bf16_1024_1q.json"
|
| 851 |
+
},
|
| 852 |
+
{
|
| 853 |
+
"backend": "mlx-bf16",
|
| 854 |
+
"n_questions": 10,
|
| 855 |
+
"state_tokens": 878,
|
| 856 |
+
"input_tokens_per_question": [
|
| 857 |
+
943,
|
| 858 |
+
918,
|
| 859 |
+
925,
|
| 860 |
+
911,
|
| 861 |
+
918,
|
| 862 |
+
921,
|
| 863 |
+
943,
|
| 864 |
+
917,
|
| 865 |
+
912,
|
| 866 |
+
919
|
| 867 |
+
],
|
| 868 |
+
"load_s": 3.3114,
|
| 869 |
+
"cold_s": 1.1022,
|
| 870 |
+
"warm_median_s": 1.0651,
|
| 871 |
+
"warm_s": [
|
| 872 |
+
1.0651,
|
| 873 |
+
1.0647,
|
| 874 |
+
1.0714
|
| 875 |
+
],
|
| 876 |
+
"state_cached_median_s": 0.5726,
|
| 877 |
+
"peak_rss_bytes": {
|
| 878 |
+
"python": 4416684032
|
| 879 |
+
},
|
| 880 |
+
"peak_phys_footprint_bytes": {
|
| 881 |
+
"python": 5575518912
|
| 882 |
+
},
|
| 883 |
+
"mlx_peak_memory_bytes": 4536436474,
|
| 884 |
+
"results_identical_cold_vs_state_cached": true,
|
| 885 |
+
"loadavg_at_end": [
|
| 886 |
+
6.03,
|
| 887 |
+
8.01,
|
| 888 |
+
9.46
|
| 889 |
+
],
|
| 890 |
+
"measured_unix": 1790443316.3707972,
|
| 891 |
+
"settings": {
|
| 892 |
+
"engine": "mlx 0.32.2 / mlx-lm 0.31.3 (staged runtime)",
|
| 893 |
+
"precision": "bf16",
|
| 894 |
+
"compute_dtype": null
|
| 895 |
+
},
|
| 896 |
+
"raw": "latency/runs/mlx-bf16_1024_10q.json"
|
| 897 |
+
},
|
| 898 |
+
{
|
| 899 |
+
"backend": "mlx-bf16",
|
| 900 |
+
"n_questions": 1,
|
| 901 |
+
"state_tokens": 3950,
|
| 902 |
+
"input_tokens_per_question": [
|
| 903 |
+
4015
|
| 904 |
+
],
|
| 905 |
+
"load_s": 3.2848,
|
| 906 |
+
"cold_s": 2.265,
|
| 907 |
+
"warm_median_s": 2.2579,
|
| 908 |
+
"warm_s": [
|
| 909 |
+
2.2462,
|
| 910 |
+
2.2579,
|
| 911 |
+
2.2701
|
| 912 |
+
],
|
| 913 |
+
"state_cached_median_s": 0.0903,
|
| 914 |
+
"peak_rss_bytes": {
|
| 915 |
+
"python": 4408279040
|
| 916 |
+
},
|
| 917 |
+
"peak_phys_footprint_bytes": {
|
| 918 |
+
"python": 6899099712
|
| 919 |
+
},
|
| 920 |
+
"mlx_peak_memory_bytes": 5062198966,
|
| 921 |
+
"results_identical_cold_vs_state_cached": true,
|
| 922 |
+
"loadavg_at_end": [
|
| 923 |
+
5.78,
|
| 924 |
+
7.9,
|
| 925 |
+
9.4
|
| 926 |
+
],
|
| 927 |
+
"measured_unix": 1790443330.072621,
|
| 928 |
+
"settings": {
|
| 929 |
+
"engine": "mlx 0.32.2 / mlx-lm 0.31.3 (staged runtime)",
|
| 930 |
+
"precision": "bf16",
|
| 931 |
+
"compute_dtype": null
|
| 932 |
+
},
|
| 933 |
+
"raw": "latency/runs/mlx-bf16_4096_1q.json"
|
| 934 |
+
},
|
| 935 |
+
{
|
| 936 |
+
"backend": "mlx-bf16",
|
| 937 |
+
"n_questions": 10,
|
| 938 |
+
"state_tokens": 3950,
|
| 939 |
+
"input_tokens_per_question": [
|
| 940 |
+
4015,
|
| 941 |
+
3990,
|
| 942 |
+
3997,
|
| 943 |
+
3983,
|
| 944 |
+
3990,
|
| 945 |
+
3993,
|
| 946 |
+
4015,
|
| 947 |
+
3989,
|
| 948 |
+
3984,
|
| 949 |
+
3991
|
| 950 |
+
],
|
| 951 |
+
"load_s": 3.3381,
|
| 952 |
+
"cold_s": 2.8286,
|
| 953 |
+
"warm_median_s": 2.7998,
|
| 954 |
+
"warm_s": [
|
| 955 |
+
2.832,
|
| 956 |
+
2.7968,
|
| 957 |
+
2.7998
|
| 958 |
+
],
|
| 959 |
+
"state_cached_median_s": 0.622,
|
| 960 |
+
"peak_rss_bytes": {
|
| 961 |
+
"python": 4406149120
|
| 962 |
+
},
|
| 963 |
+
"peak_phys_footprint_bytes": {
|
| 964 |
+
"python": 6943402624
|
| 965 |
+
},
|
| 966 |
+
"mlx_peak_memory_bytes": 5062395574,
|
| 967 |
+
"results_identical_cold_vs_state_cached": true,
|
| 968 |
+
"loadavg_at_end": [
|
| 969 |
+
5.53,
|
| 970 |
+
7.71,
|
| 971 |
+
9.3
|
| 972 |
+
],
|
| 973 |
+
"measured_unix": 1790443347.640775,
|
| 974 |
+
"settings": {
|
| 975 |
+
"engine": "mlx 0.32.2 / mlx-lm 0.31.3 (staged runtime)",
|
| 976 |
+
"precision": "bf16",
|
| 977 |
+
"compute_dtype": null
|
| 978 |
+
},
|
| 979 |
+
"raw": "latency/runs/mlx-bf16_4096_10q.json"
|
| 980 |
+
},
|
| 981 |
+
{
|
| 982 |
+
"backend": "mlx-bf16",
|
| 983 |
+
"n_questions": 1,
|
| 984 |
+
"state_tokens": 24436,
|
| 985 |
+
"input_tokens_per_question": [
|
| 986 |
+
24501
|
| 987 |
+
],
|
| 988 |
+
"load_s": 3.2657,
|
| 989 |
+
"cold_s": 15.472,
|
| 990 |
+
"warm_median_s": 15.5073,
|
| 991 |
+
"warm_s": [
|
| 992 |
+
15.5202,
|
| 993 |
+
15.5073,
|
| 994 |
+
15.4734
|
| 995 |
+
],
|
| 996 |
+
"state_cached_median_s": 0.1546,
|
| 997 |
+
"peak_rss_bytes": {
|
| 998 |
+
"python": 4403707904
|
| 999 |
+
},
|
| 1000 |
+
"peak_phys_footprint_bytes": {
|
| 1001 |
+
"python": 7889725824
|
| 1002 |
+
},
|
| 1003 |
+
"mlx_peak_memory_bytes": 5942822582,
|
| 1004 |
+
"results_identical_cold_vs_state_cached": true,
|
| 1005 |
+
"loadavg_at_end": [
|
| 1006 |
+
6.15,
|
| 1007 |
+
7.49,
|
| 1008 |
+
9.1
|
| 1009 |
+
],
|
| 1010 |
+
"measured_unix": 1790443414.47198,
|
| 1011 |
+
"settings": {
|
| 1012 |
+
"engine": "mlx 0.32.2 / mlx-lm 0.31.3 (staged runtime)",
|
| 1013 |
+
"precision": "bf16",
|
| 1014 |
+
"compute_dtype": null
|
| 1015 |
+
},
|
| 1016 |
+
"raw": "latency/runs/mlx-bf16_24576_1q.json"
|
| 1017 |
+
},
|
| 1018 |
+
{
|
| 1019 |
+
"backend": "mlx-bf16",
|
| 1020 |
+
"n_questions": 10,
|
| 1021 |
+
"state_tokens": 24436,
|
| 1022 |
+
"input_tokens_per_question": [
|
| 1023 |
+
24501,
|
| 1024 |
+
24476,
|
| 1025 |
+
24483,
|
| 1026 |
+
24469,
|
| 1027 |
+
24476,
|
| 1028 |
+
24479,
|
| 1029 |
+
24501,
|
| 1030 |
+
24475,
|
| 1031 |
+
24470,
|
| 1032 |
+
24477
|
| 1033 |
+
],
|
| 1034 |
+
"load_s": 3.278,
|
| 1035 |
+
"cold_s": 16.2813,
|
| 1036 |
+
"warm_median_s": 16.2351,
|
| 1037 |
+
"warm_s": [
|
| 1038 |
+
16.2243,
|
| 1039 |
+
16.2351,
|
| 1040 |
+
16.2657
|
| 1041 |
+
],
|
| 1042 |
+
"state_cached_median_s": 0.8797,
|
| 1043 |
+
"peak_rss_bytes": {
|
| 1044 |
+
"python": 4405805056
|
| 1045 |
+
},
|
| 1046 |
+
"peak_phys_footprint_bytes": {
|
| 1047 |
+
"python": 7863035904
|
| 1048 |
+
},
|
| 1049 |
+
"mlx_peak_memory_bytes": 5942806198,
|
| 1050 |
+
"results_identical_cold_vs_state_cached": true,
|
| 1051 |
+
"loadavg_at_end": [
|
| 1052 |
+
8.07,
|
| 1053 |
+
7.75,
|
| 1054 |
+
9.06
|
| 1055 |
+
],
|
| 1056 |
+
"measured_unix": 1790443486.522902,
|
| 1057 |
+
"settings": {
|
| 1058 |
+
"engine": "mlx 0.32.2 / mlx-lm 0.31.3 (staged runtime)",
|
| 1059 |
+
"precision": "bf16",
|
| 1060 |
+
"compute_dtype": null
|
| 1061 |
+
},
|
| 1062 |
+
"raw": "latency/runs/mlx-bf16_24576_10q.json"
|
| 1063 |
+
},
|
| 1064 |
+
{
|
| 1065 |
+
"backend": "mlx-8bit",
|
| 1066 |
+
"n_questions": 1,
|
| 1067 |
+
"state_tokens": 878,
|
| 1068 |
+
"input_tokens_per_question": [
|
| 1069 |
+
943
|
| 1070 |
+
],
|
| 1071 |
+
"load_s": 3.3345,
|
| 1072 |
+
"cold_s": 0.7573,
|
| 1073 |
+
"warm_median_s": 0.72,
|
| 1074 |
+
"warm_s": [
|
| 1075 |
+
0.7177,
|
| 1076 |
+
0.72,
|
| 1077 |
+
0.7228
|
| 1078 |
+
],
|
| 1079 |
+
"state_cached_median_s": 0.0834,
|
| 1080 |
+
"peak_rss_bytes": {
|
| 1081 |
+
"python": 2640986112
|
| 1082 |
+
},
|
| 1083 |
+
"peak_phys_footprint_bytes": {
|
| 1084 |
+
"python": 3772211392
|
| 1085 |
+
},
|
| 1086 |
+
"mlx_peak_memory_bytes": 3074287404,
|
| 1087 |
+
"results_identical_cold_vs_state_cached": true,
|
| 1088 |
+
"loadavg_at_end": [
|
| 1089 |
+
8.14,
|
| 1090 |
+
7.77,
|
| 1091 |
+
9.06
|
| 1092 |
+
],
|
| 1093 |
+
"measured_unix": 1790443494.139926,
|
| 1094 |
+
"settings": {
|
| 1095 |
+
"engine": "mlx 0.32.2 / mlx-lm 0.31.3 (staged runtime)",
|
| 1096 |
+
"precision": "8bit",
|
| 1097 |
+
"compute_dtype": null
|
| 1098 |
+
},
|
| 1099 |
+
"raw": "latency/runs/mlx-8bit_1024_1q.json"
|
| 1100 |
+
},
|
| 1101 |
+
{
|
| 1102 |
+
"backend": "mlx-8bit",
|
| 1103 |
+
"n_questions": 10,
|
| 1104 |
+
"state_tokens": 878,
|
| 1105 |
+
"input_tokens_per_question": [
|
| 1106 |
+
943,
|
| 1107 |
+
918,
|
| 1108 |
+
925,
|
| 1109 |
+
911,
|
| 1110 |
+
918,
|
| 1111 |
+
921,
|
| 1112 |
+
943,
|
| 1113 |
+
917,
|
| 1114 |
+
912,
|
| 1115 |
+
919
|
| 1116 |
+
],
|
| 1117 |
+
"load_s": 3.1502,
|
| 1118 |
+
"cold_s": 1.3124,
|
| 1119 |
+
"warm_median_s": 1.2657,
|
| 1120 |
+
"warm_s": [
|
| 1121 |
+
1.2719,
|
| 1122 |
+
1.2657,
|
| 1123 |
+
1.2621
|
| 1124 |
+
],
|
| 1125 |
+
"state_cached_median_s": 0.6288,
|
| 1126 |
+
"peak_rss_bytes": {
|
| 1127 |
+
"python": 2635268096
|
| 1128 |
+
},
|
| 1129 |
+
"peak_phys_footprint_bytes": {
|
| 1130 |
+
"python": 4171391040
|
| 1131 |
+
},
|
| 1132 |
+
"mlx_peak_memory_bytes": 3074287404,
|
| 1133 |
+
"results_identical_cold_vs_state_cached": true,
|
| 1134 |
+
"loadavg_at_end": [
|
| 1135 |
+
7.51,
|
| 1136 |
+
7.65,
|
| 1137 |
+
9.0
|
| 1138 |
+
],
|
| 1139 |
+
"measured_unix": 1790443505.379929,
|
| 1140 |
+
"settings": {
|
| 1141 |
+
"engine": "mlx 0.32.2 / mlx-lm 0.31.3 (staged runtime)",
|
| 1142 |
+
"precision": "8bit",
|
| 1143 |
+
"compute_dtype": null
|
| 1144 |
+
},
|
| 1145 |
+
"raw": "latency/runs/mlx-8bit_1024_10q.json"
|
| 1146 |
+
},
|
| 1147 |
+
{
|
| 1148 |
+
"backend": "mlx-8bit",
|
| 1149 |
+
"n_questions": 1,
|
| 1150 |
+
"state_tokens": 3950,
|
| 1151 |
+
"input_tokens_per_question": [
|
| 1152 |
+
4015
|
| 1153 |
+
],
|
| 1154 |
+
"load_s": 3.1569,
|
| 1155 |
+
"cold_s": 2.9904,
|
| 1156 |
+
"warm_median_s": 2.9581,
|
| 1157 |
+
"warm_s": [
|
| 1158 |
+
2.9525,
|
| 1159 |
+
2.9624,
|
| 1160 |
+
2.9581
|
| 1161 |
+
],
|
| 1162 |
+
"state_cached_median_s": 0.0922,
|
| 1163 |
+
"peak_rss_bytes": {
|
| 1164 |
+
"python": 2639839232
|
| 1165 |
+
},
|
| 1166 |
+
"peak_phys_footprint_bytes": {
|
| 1167 |
+
"python": 5536832896
|
| 1168 |
+
},
|
| 1169 |
+
"mlx_peak_memory_bytes": 3471550184,
|
| 1170 |
+
"results_identical_cold_vs_state_cached": true,
|
| 1171 |
+
"loadavg_at_end": [
|
| 1172 |
+
8.57,
|
| 1173 |
+
7.86,
|
| 1174 |
+
9.04
|
| 1175 |
+
],
|
| 1176 |
+
"measured_unix": 1790443521.78049,
|
| 1177 |
+
"settings": {
|
| 1178 |
+
"engine": "mlx 0.32.2 / mlx-lm 0.31.3 (staged runtime)",
|
| 1179 |
+
"precision": "8bit",
|
| 1180 |
+
"compute_dtype": null
|
| 1181 |
+
},
|
| 1182 |
+
"raw": "latency/runs/mlx-8bit_4096_1q.json"
|
| 1183 |
+
},
|
| 1184 |
+
{
|
| 1185 |
+
"backend": "mlx-8bit",
|
| 1186 |
+
"n_questions": 10,
|
| 1187 |
+
"state_tokens": 3950,
|
| 1188 |
+
"input_tokens_per_question": [
|
| 1189 |
+
4015,
|
| 1190 |
+
3990,
|
| 1191 |
+
3997,
|
| 1192 |
+
3983,
|
| 1193 |
+
3990,
|
| 1194 |
+
3993,
|
| 1195 |
+
4015,
|
| 1196 |
+
3989,
|
| 1197 |
+
3984,
|
| 1198 |
+
3991
|
| 1199 |
+
],
|
| 1200 |
+
"load_s": 3.1665,
|
| 1201 |
+
"cold_s": 3.572,
|
| 1202 |
+
"warm_median_s": 3.5432,
|
| 1203 |
+
"warm_s": [
|
| 1204 |
+
3.5584,
|
| 1205 |
+
3.5432,
|
| 1206 |
+
3.5354
|
| 1207 |
+
],
|
| 1208 |
+
"state_cached_median_s": 0.6768,
|
| 1209 |
+
"peak_rss_bytes": {
|
| 1210 |
+
"python": 2624536576
|
| 1211 |
+
},
|
| 1212 |
+
"peak_phys_footprint_bytes": {
|
| 1213 |
+
"python": 5698149760
|
| 1214 |
+
},
|
| 1215 |
+
"mlx_peak_memory_bytes": 3471615720,
|
| 1216 |
+
"results_identical_cold_vs_state_cached": true,
|
| 1217 |
+
"loadavg_at_end": [
|
| 1218 |
+
7.82,
|
| 1219 |
+
7.73,
|
| 1220 |
+
8.97
|
| 1221 |
+
],
|
| 1222 |
+
"measured_unix": 1790443542.268524,
|
| 1223 |
+
"settings": {
|
| 1224 |
+
"engine": "mlx 0.32.2 / mlx-lm 0.31.3 (staged runtime)",
|
| 1225 |
+
"precision": "8bit",
|
| 1226 |
+
"compute_dtype": null
|
| 1227 |
+
},
|
| 1228 |
+
"raw": "latency/runs/mlx-8bit_4096_10q.json"
|
| 1229 |
+
},
|
| 1230 |
+
{
|
| 1231 |
+
"backend": "mlx-8bit",
|
| 1232 |
+
"n_questions": 1,
|
| 1233 |
+
"state_tokens": 24436,
|
| 1234 |
+
"input_tokens_per_question": [
|
| 1235 |
+
24501
|
| 1236 |
+
],
|
| 1237 |
+
"load_s": 3.1447,
|
| 1238 |
+
"cold_s": 19.75,
|
| 1239 |
+
"warm_median_s": 19.8614,
|
| 1240 |
+
"warm_s": [
|
| 1241 |
+
19.8005,
|
| 1242 |
+
19.8614,
|
| 1243 |
+
19.9115
|
| 1244 |
+
],
|
| 1245 |
+
"state_cached_median_s": 0.1562,
|
| 1246 |
+
"peak_rss_bytes": {
|
| 1247 |
+
"python": 2643197952
|
| 1248 |
+
},
|
| 1249 |
+
"peak_phys_footprint_bytes": {
|
| 1250 |
+
"python": 6518807424
|
| 1251 |
+
},
|
| 1252 |
+
"mlx_peak_memory_bytes": 4350994102,
|
| 1253 |
+
"results_identical_cold_vs_state_cached": true,
|
| 1254 |
+
"loadavg_at_end": [
|
| 1255 |
+
6.7,
|
| 1256 |
+
7.34,
|
| 1257 |
+
8.69
|
| 1258 |
+
],
|
| 1259 |
+
"measured_unix": 1790443626.3357399,
|
| 1260 |
+
"settings": {
|
| 1261 |
+
"engine": "mlx 0.32.2 / mlx-lm 0.31.3 (staged runtime)",
|
| 1262 |
+
"precision": "8bit",
|
| 1263 |
+
"compute_dtype": null
|
| 1264 |
+
},
|
| 1265 |
+
"raw": "latency/runs/mlx-8bit_24576_1q.json"
|
| 1266 |
+
},
|
| 1267 |
+
{
|
| 1268 |
+
"backend": "mlx-8bit",
|
| 1269 |
+
"n_questions": 10,
|
| 1270 |
+
"state_tokens": 24436,
|
| 1271 |
+
"input_tokens_per_question": [
|
| 1272 |
+
24501,
|
| 1273 |
+
24476,
|
| 1274 |
+
24483,
|
| 1275 |
+
24469,
|
| 1276 |
+
24476,
|
| 1277 |
+
24479,
|
| 1278 |
+
24501,
|
| 1279 |
+
24475,
|
| 1280 |
+
24470,
|
| 1281 |
+
24477
|
| 1282 |
+
],
|
| 1283 |
+
"load_s": 3.1668,
|
| 1284 |
+
"cold_s": 20.7629,
|
| 1285 |
+
"warm_median_s": 20.7793,
|
| 1286 |
+
"warm_s": [
|
| 1287 |
+
20.6782,
|
| 1288 |
+
20.7793,
|
| 1289 |
+
21.8013
|
| 1290 |
+
],
|
| 1291 |
+
"state_cached_median_s": 0.9543,
|
| 1292 |
+
"peak_rss_bytes": {
|
| 1293 |
+
"python": 2643705856
|
| 1294 |
+
},
|
| 1295 |
+
"peak_phys_footprint_bytes": {
|
| 1296 |
+
"python": 6522985664
|
| 1297 |
+
},
|
| 1298 |
+
"mlx_peak_memory_bytes": 4350944950,
|
| 1299 |
+
"results_identical_cold_vs_state_cached": true,
|
| 1300 |
+
"loadavg_at_end": [
|
| 1301 |
+
8.26,
|
| 1302 |
+
8.35,
|
| 1303 |
+
8.99
|
| 1304 |
+
],
|
| 1305 |
+
"measured_unix": 1790443717.49426,
|
| 1306 |
+
"settings": {
|
| 1307 |
+
"engine": "mlx 0.32.2 / mlx-lm 0.31.3 (staged runtime)",
|
| 1308 |
+
"precision": "8bit",
|
| 1309 |
+
"compute_dtype": null
|
| 1310 |
+
},
|
| 1311 |
+
"raw": "latency/runs/mlx-8bit_24576_10q.json"
|
| 1312 |
+
},
|
| 1313 |
+
{
|
| 1314 |
+
"backend": "torch-mps-fp32",
|
| 1315 |
+
"n_questions": 1,
|
| 1316 |
+
"state_tokens": 878,
|
| 1317 |
+
"input_tokens_per_question": [
|
| 1318 |
+
943
|
| 1319 |
+
],
|
| 1320 |
+
"load_s": 7.2396,
|
| 1321 |
+
"cold_s": 2.0776,
|
| 1322 |
+
"warm_median_s": 1.82,
|
| 1323 |
+
"warm_s": [
|
| 1324 |
+
1.82,
|
| 1325 |
+
1.8185,
|
| 1326 |
+
1.8657
|
| 1327 |
+
],
|
| 1328 |
+
"state_cached_median_s": 0.2243,
|
| 1329 |
+
"peak_rss_bytes": {
|
| 1330 |
+
"python": 11777310720
|
| 1331 |
+
},
|
| 1332 |
+
"peak_phys_footprint_bytes": {
|
| 1333 |
+
"python": 9488876864
|
| 1334 |
+
},
|
| 1335 |
+
"results_identical_cold_vs_state_cached": true,
|
| 1336 |
+
"loadavg_at_end": [
|
| 1337 |
+
11.08,
|
| 1338 |
+
15.97,
|
| 1339 |
+
14.21
|
| 1340 |
+
],
|
| 1341 |
+
"measured_unix": 1790433935.3785548,
|
| 1342 |
+
"settings": {
|
| 1343 |
+
"engine": "transformers 5.17 / torch 2.14 (staged runtime)",
|
| 1344 |
+
"device": "mps",
|
| 1345 |
+
"dtype": "float32",
|
| 1346 |
+
"attn_chunk": 1024
|
| 1347 |
+
},
|
| 1348 |
+
"raw": "latency/runs/torch-mps-fp32_1024_1q.json"
|
| 1349 |
+
},
|
| 1350 |
+
{
|
| 1351 |
+
"backend": "torch-mps-fp32",
|
| 1352 |
+
"n_questions": 10,
|
| 1353 |
+
"state_tokens": 878,
|
| 1354 |
+
"input_tokens_per_question": [
|
| 1355 |
+
943,
|
| 1356 |
+
918,
|
| 1357 |
+
925,
|
| 1358 |
+
911,
|
| 1359 |
+
918,
|
| 1360 |
+
921,
|
| 1361 |
+
943,
|
| 1362 |
+
917,
|
| 1363 |
+
912,
|
| 1364 |
+
919
|
| 1365 |
+
],
|
| 1366 |
+
"load_s": 5.8844,
|
| 1367 |
+
"cold_s": 3.487,
|
| 1368 |
+
"warm_median_s": 3.126,
|
| 1369 |
+
"warm_s": [
|
| 1370 |
+
3.126,
|
| 1371 |
+
3.124,
|
| 1372 |
+
3.1357
|
| 1373 |
+
],
|
| 1374 |
+
"state_cached_median_s": 1.534,
|
| 1375 |
+
"peak_rss_bytes": {
|
| 1376 |
+
"python": 11766398976
|
| 1377 |
+
},
|
| 1378 |
+
"peak_phys_footprint_bytes": {
|
| 1379 |
+
"python": 9348826496
|
| 1380 |
+
},
|
| 1381 |
+
"results_identical_cold_vs_state_cached": true,
|
| 1382 |
+
"loadavg_at_end": [
|
| 1383 |
+
10.92,
|
| 1384 |
+
15.56,
|
| 1385 |
+
14.11
|
| 1386 |
+
],
|
| 1387 |
+
"measured_unix": 1790433960.3376808,
|
| 1388 |
+
"settings": {
|
| 1389 |
+
"engine": "transformers 5.17 / torch 2.14 (staged runtime)",
|
| 1390 |
+
"device": "mps",
|
| 1391 |
+
"dtype": "float32",
|
| 1392 |
+
"attn_chunk": 1024
|
| 1393 |
+
},
|
| 1394 |
+
"raw": "latency/runs/torch-mps-fp32_1024_10q.json"
|
| 1395 |
+
},
|
| 1396 |
+
{
|
| 1397 |
+
"backend": "torch-mps-fp32",
|
| 1398 |
+
"n_questions": 1,
|
| 1399 |
+
"state_tokens": 3950,
|
| 1400 |
+
"input_tokens_per_question": [
|
| 1401 |
+
4015
|
| 1402 |
+
],
|
| 1403 |
+
"load_s": 6.6133,
|
| 1404 |
+
"cold_s": 7.9626,
|
| 1405 |
+
"warm_median_s": 7.7385,
|
| 1406 |
+
"warm_s": [
|
| 1407 |
+
7.7135,
|
| 1408 |
+
7.7385,
|
| 1409 |
+
7.7569
|
| 1410 |
+
],
|
| 1411 |
+
"state_cached_median_s": 0.2508,
|
| 1412 |
+
"peak_rss_bytes": {
|
| 1413 |
+
"python": 11774099456
|
| 1414 |
+
},
|
| 1415 |
+
"peak_phys_footprint_bytes": {
|
| 1416 |
+
"python": 9830892736
|
| 1417 |
+
},
|
| 1418 |
+
"results_identical_cold_vs_state_cached": true,
|
| 1419 |
+
"loadavg_at_end": [
|
| 1420 |
+
8.41,
|
| 1421 |
+
7.52,
|
| 1422 |
+
7.06
|
| 1423 |
+
],
|
| 1424 |
+
"measured_unix": 1790438685.325036,
|
| 1425 |
+
"settings": {
|
| 1426 |
+
"engine": "transformers 5.17 / torch 2.14 (staged runtime)",
|
| 1427 |
+
"device": "mps",
|
| 1428 |
+
"dtype": "float32",
|
| 1429 |
+
"attn_chunk": 1024
|
| 1430 |
+
},
|
| 1431 |
+
"raw": "latency/runs/torch-mps-fp32_4096_1q.json"
|
| 1432 |
+
},
|
| 1433 |
+
{
|
| 1434 |
+
"backend": "torch-mps-fp32",
|
| 1435 |
+
"n_questions": 10,
|
| 1436 |
+
"state_tokens": 3950,
|
| 1437 |
+
"input_tokens_per_question": [
|
| 1438 |
+
4015,
|
| 1439 |
+
3990,
|
| 1440 |
+
3997,
|
| 1441 |
+
3983,
|
| 1442 |
+
3990,
|
| 1443 |
+
3993,
|
| 1444 |
+
4015,
|
| 1445 |
+
3989,
|
| 1446 |
+
3984,
|
| 1447 |
+
3991
|
| 1448 |
+
],
|
| 1449 |
+
"load_s": 5.8354,
|
| 1450 |
+
"cold_s": 9.4943,
|
| 1451 |
+
"warm_median_s": 9.2321,
|
| 1452 |
+
"warm_s": [
|
| 1453 |
+
9.1731,
|
| 1454 |
+
9.2321,
|
| 1455 |
+
9.2805
|
| 1456 |
+
],
|
| 1457 |
+
"state_cached_median_s": 1.7373,
|
| 1458 |
+
"peak_rss_bytes": {
|
| 1459 |
+
"python": 11766579200
|
| 1460 |
+
},
|
| 1461 |
+
"peak_phys_footprint_bytes": {
|
| 1462 |
+
"python": 9740780928
|
| 1463 |
+
},
|
| 1464 |
+
"results_identical_cold_vs_state_cached": true,
|
| 1465 |
+
"loadavg_at_end": [
|
| 1466 |
+
10.4,
|
| 1467 |
+
8.12,
|
| 1468 |
+
7.31
|
| 1469 |
+
],
|
| 1470 |
+
"measured_unix": 1790438734.979529,
|
| 1471 |
+
"settings": {
|
| 1472 |
+
"engine": "transformers 5.17 / torch 2.14 (staged runtime)",
|
| 1473 |
+
"device": "mps",
|
| 1474 |
+
"dtype": "float32",
|
| 1475 |
+
"attn_chunk": 1024
|
| 1476 |
+
},
|
| 1477 |
+
"raw": "latency/runs/torch-mps-fp32_4096_10q.json"
|
| 1478 |
+
},
|
| 1479 |
+
{
|
| 1480 |
+
"backend": "torch-mps-fp32",
|
| 1481 |
+
"n_questions": 1,
|
| 1482 |
+
"state_tokens": 24436,
|
| 1483 |
+
"input_tokens_per_question": [
|
| 1484 |
+
24501
|
| 1485 |
+
],
|
| 1486 |
+
"load_s": 7.5475,
|
| 1487 |
+
"cold_s": 56.4354,
|
| 1488 |
+
"warm_median_s": 61.9146,
|
| 1489 |
+
"warm_s": [
|
| 1490 |
+
55.156,
|
| 1491 |
+
61.9146,
|
| 1492 |
+
80.3434
|
| 1493 |
+
],
|
| 1494 |
+
"state_cached_median_s": 0.6,
|
| 1495 |
+
"peak_rss_bytes": {
|
| 1496 |
+
"python": 11774935040
|
| 1497 |
+
},
|
| 1498 |
+
"peak_phys_footprint_bytes": {
|
| 1499 |
+
"python": 13703111296
|
| 1500 |
+
},
|
| 1501 |
+
"results_identical_cold_vs_state_cached": true,
|
| 1502 |
+
"loadavg_at_end": [
|
| 1503 |
+
7.27,
|
| 1504 |
+
7.84,
|
| 1505 |
+
7.44
|
| 1506 |
+
],
|
| 1507 |
+
"measured_unix": 1790438999.6904268,
|
| 1508 |
+
"settings": {
|
| 1509 |
+
"engine": "transformers 5.17 / torch 2.14 (staged runtime)",
|
| 1510 |
+
"device": "mps",
|
| 1511 |
+
"dtype": "float32",
|
| 1512 |
+
"attn_chunk": 1024
|
| 1513 |
+
},
|
| 1514 |
+
"raw": "latency/runs/torch-mps-fp32_24576_1q.json"
|
| 1515 |
+
},
|
| 1516 |
+
{
|
| 1517 |
+
"backend": "torch-mps-fp32",
|
| 1518 |
+
"n_questions": 10,
|
| 1519 |
+
"state_tokens": 24436,
|
| 1520 |
+
"input_tokens_per_question": [
|
| 1521 |
+
24501,
|
| 1522 |
+
24476,
|
| 1523 |
+
24483,
|
| 1524 |
+
24469,
|
| 1525 |
+
24476,
|
| 1526 |
+
24479,
|
| 1527 |
+
24501,
|
| 1528 |
+
24475,
|
| 1529 |
+
24470,
|
| 1530 |
+
24477
|
| 1531 |
+
],
|
| 1532 |
+
"load_s": 7.9699,
|
| 1533 |
+
"cold_s": 72.6584,
|
| 1534 |
+
"warm_median_s": 72.3035,
|
| 1535 |
+
"warm_s": [
|
| 1536 |
+
83.2192,
|
| 1537 |
+
72.3035,
|
| 1538 |
+
58.3757
|
| 1539 |
+
],
|
| 1540 |
+
"state_cached_median_s": 2.7217,
|
| 1541 |
+
"peak_rss_bytes": {
|
| 1542 |
+
"python": 11775229952
|
| 1543 |
+
},
|
| 1544 |
+
"peak_phys_footprint_bytes": {
|
| 1545 |
+
"python": 13640000128
|
| 1546 |
+
},
|
| 1547 |
+
"results_identical_cold_vs_state_cached": true,
|
| 1548 |
+
"loadavg_at_end": [
|
| 1549 |
+
9.6,
|
| 1550 |
+
8.35,
|
| 1551 |
+
7.72
|
| 1552 |
+
],
|
| 1553 |
+
"measured_unix": 1790439304.235886,
|
| 1554 |
+
"settings": {
|
| 1555 |
+
"engine": "transformers 5.17 / torch 2.14 (staged runtime)",
|
| 1556 |
+
"device": "mps",
|
| 1557 |
+
"dtype": "float32",
|
| 1558 |
+
"attn_chunk": 1024
|
| 1559 |
+
},
|
| 1560 |
+
"raw": "latency/runs/torch-mps-fp32_24576_10q.json"
|
| 1561 |
+
}
|
| 1562 |
+
],
|
| 1563 |
+
"scripts": [
|
| 1564 |
+
"release_2b/latency/latency_run.py",
|
| 1565 |
+
"release_2b/latency/run_all.sh",
|
| 1566 |
+
"release_2b/latency/aggregate.py"
|
| 1567 |
+
]
|
| 1568 |
+
}
|
validation/parity/PREDECLARED_RELEASE_GATES_2B.md
ADDED
|
@@ -0,0 +1,29 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Jev-Style-2B-Decision-v3 — release format gates (pre-declared 2026-09-26, BEFORE any trained-weight format was scored)
|
| 2 |
+
|
| 3 |
+
Reference: HF FP32 CPU, exact v2 block attention, on the released bf16 text-only checkpoint
|
| 4 |
+
runs/macjev/candidate_2b/hf-candidate (SHA256SUMS 279/279 verified). Temperature T = 0.8278650621 (macjev_readout.json).
|
| 5 |
+
|
| 6 |
+
Fixtures (frozen, sha256 in their .stats/.README):
|
| 7 |
+
- base fixture: runs/macjev/runtime_v2_dev/reference_base/fixture.jsonl (35 req / 43 q, 214,700 tok, up to 25,600 tok, overflow, K<=151)
|
| 8 |
+
- gate fixture: runs/macjev/runtime_v2_dev/reference/gate_fixture_n1000.jsonl (1,000 real dev rows, <=4,096 tok)
|
| 9 |
+
|
| 10 |
+
Gates (training plan §11.2, unchanged): F16/bf16 top-1 >= .99; 8-bit top-1 >= .98; |dNLL| <= .02 (fp/16/8-bit);
|
| 11 |
+
accuracy drop Q8_0/MLX-8bit <= 0.3 pp, Q4_K_M <= 1.0 pp (measured on the gate fixture; n=1000 => 0.1 pp per flip).
|
| 12 |
+
Block-mask proof on the base fixture: every question closer to the block reference than to the causal and prefix-causal controls.
|
| 13 |
+
|
| 14 |
+
Release set (user choice): GGUF F16 / Q8_0 / Q4_K_M; MLX bf16 / 8bit (affine g64).
|
| 15 |
+
Recipe 1 (primary): stock llama-quantize defaults; mlx_lm.convert defaults + FP32 norm sidecar + MLXScorerV2.
|
| 16 |
+
Recipe 2 (declared fallback, used ONLY if recipe 1 fails a gate): keep the tied embedding / readout rows at f16
|
| 17 |
+
(llama-quantize --token-embedding-type f16; MLX: quant predicate excluding embed_tokens). Same gates, same fixtures.
|
| 18 |
+
If recipe 2 also fails, that format is NOT shipped. Gates are not relaxed after seeing results.
|
| 19 |
+
|
| 20 |
+
## Public benchmarks (pre-declared 2026-09-26 22:01:49 AEST, before any 2B benchmark item was scored)
|
| 21 |
+
Timing (erratum added 2026-09-27 03:35 AEST): this section was appended by the same shell command that launched the
|
| 22 |
+
benchmark runs, immediately before the first item (file mtime 22:01:49; run log `runs/macjev/bench_2b/run_trained.log`
|
| 23 |
+
first line `[2026-09-26 22:01:49] START jevbench`; first result seen 22:06:28). The heading originally said
|
| 24 |
+
"22:10" by mistake. The format-gate section above was written when the file was created (21:46:03), before any
|
| 25 |
+
trained-weight format was scored (first format score started 21:53:00).
|
| 26 |
+
- Reported engine: GGUF F16 (runs/macjev/release_2b/gguf/model-f16.gguf, jev-score-v2, Metal), global T = 0.8278650621 only.
|
| 27 |
+
- JevBench v1.4.1 public (231) and elcronos zero-shot sets (tweet_topic / fin_topic / daily_dialog), each run ONCE,
|
| 28 |
+
same metric code as the 0.8B v3 card. No per-benchmark temperatures, no reruns, no prompt changes after seeing scores.
|
| 29 |
+
- Decision Index 0.2: not run locally; requested from the maintainer after release (user decision 2026-09-26).
|
validation/parity/cross_format_dp.json
ADDED
|
@@ -0,0 +1,68 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"base:torch_fp32_cpu": {
|
| 3 |
+
"n": 43,
|
| 4 |
+
"top1_agree": 1.0,
|
| 5 |
+
"max_abs_dp": 4.782633115096857e-06,
|
| 6 |
+
"mean_max_abs_dp": 6.972375795818997e-07
|
| 7 |
+
},
|
| 8 |
+
"base:gguf_f16": {
|
| 9 |
+
"n": 43,
|
| 10 |
+
"top1_agree": 1.0,
|
| 11 |
+
"max_abs_dp": 0.0006297677378335198,
|
| 12 |
+
"mean_max_abs_dp": 0.00017737997866918594
|
| 13 |
+
},
|
| 14 |
+
"base:gguf_q8_0": {
|
| 15 |
+
"n": 43,
|
| 16 |
+
"top1_agree": 1.0,
|
| 17 |
+
"max_abs_dp": 0.021289327356281362,
|
| 18 |
+
"mean_max_abs_dp": 0.0044768677260933745
|
| 19 |
+
},
|
| 20 |
+
"base:gguf_q4_k_m": {
|
| 21 |
+
"n": 43,
|
| 22 |
+
"top1_agree": 0.9767441860465116,
|
| 23 |
+
"max_abs_dp": 0.15778925110927658,
|
| 24 |
+
"mean_max_abs_dp": 0.047022506153486646
|
| 25 |
+
},
|
| 26 |
+
"base:mlx_bf16": {
|
| 27 |
+
"n": 43,
|
| 28 |
+
"top1_agree": 1.0,
|
| 29 |
+
"max_abs_dp": 0.010765431767972844,
|
| 30 |
+
"mean_max_abs_dp": 0.003890125022245109
|
| 31 |
+
},
|
| 32 |
+
"base:mlx_8bit": {
|
| 33 |
+
"n": 43,
|
| 34 |
+
"top1_agree": 1.0,
|
| 35 |
+
"max_abs_dp": 0.04628699142360499,
|
| 36 |
+
"mean_max_abs_dp": 0.007026009064181663
|
| 37 |
+
},
|
| 38 |
+
"gate:gguf_f16": {
|
| 39 |
+
"n": 1000,
|
| 40 |
+
"top1_agree": 1.0,
|
| 41 |
+
"max_abs_dp": 0.0013728371250730786,
|
| 42 |
+
"mean_max_abs_dp": 0.00012138780447113503
|
| 43 |
+
},
|
| 44 |
+
"gate:gguf_q8_0": {
|
| 45 |
+
"n": 1000,
|
| 46 |
+
"top1_agree": 0.997,
|
| 47 |
+
"max_abs_dp": 0.033479594816581415,
|
| 48 |
+
"mean_max_abs_dp": 0.0020247272188215755
|
| 49 |
+
},
|
| 50 |
+
"gate:gguf_q4_k_m": {
|
| 51 |
+
"n": 1000,
|
| 52 |
+
"top1_agree": 0.957,
|
| 53 |
+
"max_abs_dp": 0.34599917206983777,
|
| 54 |
+
"mean_max_abs_dp": 0.02317308476687987
|
| 55 |
+
},
|
| 56 |
+
"gate:mlx_bf16": {
|
| 57 |
+
"n": 1000,
|
| 58 |
+
"top1_agree": 0.997,
|
| 59 |
+
"max_abs_dp": 0.03549758339084519,
|
| 60 |
+
"mean_max_abs_dp": 0.0025865935031305484
|
| 61 |
+
},
|
| 62 |
+
"gate:mlx_8bit": {
|
| 63 |
+
"n": 1000,
|
| 64 |
+
"top1_agree": 0.996,
|
| 65 |
+
"max_abs_dp": 0.1623697296878569,
|
| 66 |
+
"mean_max_abs_dp": 0.0039011049015487734
|
| 67 |
+
}
|
| 68 |
+
}
|
validation/runtime/parity_cpu_fp32_t4.log
ADDED
|
@@ -0,0 +1,56 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
|
| 2 |
+
load 4.1s device=cpu threads=4
|
| 3 |
+
[transformers] `causal_conv1d_fn` is falling back to its reference PyTorch implementation because `causal_conv1d` is not installed. This is correct but much slower; install `causal_conv1d` for the optimized kernel.
|
| 4 |
+
[transformers] `chunk_gated_delta_rule` is falling back to its reference PyTorch implementation because `flash-linear-attention` is not installed. This is correct but much slower; install `flash-linear-attention` for the optimized kernel.
|
| 5 |
+
multi_question-0 [450, 364, 356, 345, 319] d=7.391e-06 flips=0 meta_ok=True 28.5s
|
| 6 |
+
multi_question-1 [5416, 5471, 5425, 5517, 5428] d=4.530e-06 flips=0 meta_ok=True 55.1s
|
| 7 |
+
short_sb-themes-0 [105] d=2.980e-07 flips=0 meta_ok=True 8.2s
|
| 8 |
+
short_sb-public_ingests-0 [382] d=6.020e-06 flips=0 meta_ok=True 9.4s
|
| 9 |
+
short_sb-di_retrieval-0 [197] d=2.980e-07 flips=0 meta_ok=True 9.5s
|
| 10 |
+
short_sb-di_knowledge-0 [72] d=1.669e-06 flips=0 meta_ok=True 8.9s
|
| 11 |
+
short_sb-hard_short-0 [517] d=4.411e-06 flips=0 meta_ok=True 10.2s
|
| 12 |
+
short_sb-format-0 [166] d=3.576e-06 flips=0 meta_ok=True 9.3s
|
| 13 |
+
qtype_choice-0 [594] d=5.841e-06 flips=0 meta_ok=True 10.9s
|
| 14 |
+
qtype_noul-0 [246] d=1.609e-06 flips=0 meta_ok=True 10.0s
|
| 15 |
+
qtype_score-0 [873] d=3.934e-06 flips=0 meta_ok=True 12.3s
|
| 16 |
+
multi_block_3k-0 [2927] d=1.132e-05 flips=0 meta_ok=True 24.8s
|
| 17 |
+
multi_block_3k-1 [2932] d=2.146e-06 flips=0 meta_ok=True 23.2s
|
| 18 |
+
multi_block_5k-0 [5011] d=4.798e-06 flips=0 meta_ok=True 37.1s
|
| 19 |
+
multi_block_5k-1 [4767] d=5.364e-06 flips=0 meta_ok=True 36.3s
|
| 20 |
+
multi_block_9k-s0 [9083] d=2.384e-06 flips=0 meta_ok=True 69.7s
|
| 21 |
+
multi_block_9k-s1 [9568] d=2.310e-06 flips=0 meta_ok=True 77.4s
|
| 22 |
+
prefix_boundary-2047 [2178] d=2.623e-06 flips=0 meta_ok=True 19.7s
|
| 23 |
+
prefix_boundary-2048 [2203] d=3.457e-06 flips=0 meta_ok=True 20.8s
|
| 24 |
+
[transformers] `causal_conv1d_update` is falling back to its reference PyTorch implementation because `causal_conv1d` is not installed. This is correct but much slower; install `causal_conv1d` for the optimized kernel.
|
| 25 |
+
[transformers] `fused_recurrent_gated_delta_rule` is falling back to its reference PyTorch implementation because `flash-linear-attention` is not installed. This is correct but much slower; install `flash-linear-attention` for the optimized kernel.
|
| 26 |
+
prefix_boundary-2049 [2289] d=4.530e-06 flips=0 meta_ok=True 28.7s
|
| 27 |
+
prefix_boundary-4095 [4163] d=9.179e-06 flips=0 meta_ok=True 37.4s
|
| 28 |
+
prefix_boundary-4096 [4312] d=4.292e-06 flips=0 meta_ok=True 39.8s
|
| 29 |
+
prefix_boundary-4097 [4180] d=1.669e-06 flips=0 meta_ok=True 36.9s
|
| 30 |
+
prefix_boundary-6144 [6259] d=5.722e-06 flips=0 meta_ok=True 61.6s
|
| 31 |
+
catalogue_overflow-0 [4722] d=6.676e-06 flips=0 meta_ok=True 36.4s
|
| 32 |
+
catalogue_overflow-1 [4721] d=7.153e-06 flips=0 meta_ok=True 36.2s
|
| 33 |
+
catalogue_overflow-2 [4729] d=1.502e-05 flips=0 meta_ok=True 40.0s
|
| 34 |
+
catalogue_overflow_long_state-0 [8806] d=6.437e-06 flips=0 meta_ok=True 64.5s
|
| 35 |
+
many_options-0 [500] d=5.960e-06 flips=0 meta_ok=True 11.5s
|
| 36 |
+
many_options-1 [423] d=3.815e-06 flips=0 meta_ok=True 10.2s
|
| 37 |
+
long_16k-0 [15900] d=6.676e-06 flips=0 meta_ok=True 119.6s
|
| 38 |
+
long_16k-1 [16384] d=2.086e-06 flips=0 meta_ok=True 120.1s
|
| 39 |
+
long_16k-2 [16800] d=5.722e-06 flips=0 meta_ok=True 106.6s
|
| 40 |
+
long_24k-0 [24000] d=3.815e-06 flips=0 meta_ok=True 163.9s
|
| 41 |
+
long_24k-1 [25600] d=4.053e-06 flips=0 meta_ok=True 171.0s
|
| 42 |
+
catalogue_overflow n= 3 max|d|=1.502e-05 flips=0
|
| 43 |
+
catalogue_overflow_long_state n= 1 max|d|=6.437e-06 flips=0
|
| 44 |
+
long_16k n= 3 max|d|=6.676e-06 flips=0
|
| 45 |
+
long_24k n= 2 max|d|=4.053e-06 flips=0
|
| 46 |
+
many_options n= 2 max|d|=5.960e-06 flips=0
|
| 47 |
+
multi_block_3k n= 2 max|d|=1.132e-05 flips=0
|
| 48 |
+
multi_block_5k n= 2 max|d|=5.364e-06 flips=0
|
| 49 |
+
multi_block_9k n= 2 max|d|=2.384e-06 flips=0
|
| 50 |
+
multi_question n=10 max|d|=7.391e-06 flips=0
|
| 51 |
+
prefix_boundary n= 7 max|d|=9.179e-06 flips=0
|
| 52 |
+
qtype_choice n= 1 max|d|=5.841e-06 flips=0
|
| 53 |
+
qtype_noul n= 1 max|d|=1.609e-06 flips=0
|
| 54 |
+
qtype_score n= 1 max|d|=3.934e-06 flips=0
|
| 55 |
+
short_sb n= 6 max|d|=6.020e-06 flips=0
|
| 56 |
+
ALL requests=35 questions=43 max|d|=1.502e-05 flips=0 meta_ok_all=True
|
validation/runtime/parity_mps_fp32_long.log
ADDED
|
@@ -0,0 +1,9 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
|
| 2 |
+
load 4.9s device=mps threads=2
|
| 3 |
+
[transformers] `causal_conv1d_fn` is falling back to its reference PyTorch implementation because `causal_conv1d` is not installed. This is correct but much slower; install `causal_conv1d` for the optimized kernel.
|
| 4 |
+
[transformers] `chunk_gated_delta_rule` is falling back to its reference PyTorch implementation because `flash-linear-attention` is not installed. This is correct but much slower; install `flash-linear-attention` for the optimized kernel.
|
| 5 |
+
long_16k-1 [16384] d=2.742e-06 flips=0 meta_ok=True 33.9s
|
| 6 |
+
long_24k-1 [25600] d=8.821e-06 flips=0 meta_ok=True 57.5s
|
| 7 |
+
long_16k n= 1 max|d|=2.742e-06 flips=0
|
| 8 |
+
long_24k n= 1 max|d|=8.821e-06 flips=0
|
| 9 |
+
ALL requests=2 questions=2 max|d|=8.821e-06 flips=0 meta_ok_all=True
|
validation/runtime/reverify_main.json
ADDED
|
@@ -0,0 +1,23 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"runtime_file": "jev_style_decision.py",
|
| 3 |
+
"runtime_sha256": "5ecba24cdfff4f0e043c2ea48c9c7f514907c6804f265906e21dec0f1b20dbd6",
|
| 4 |
+
"shared_core_sha256": "56deae095206fc59b9a30d8626ac5d27cacddcd94d7c7f08f6f4bc53d326a002",
|
| 5 |
+
"what": "PyTorch FP32 CPU, requests with <= 6000 tokens per question",
|
| 6 |
+
"loaded_from": "runs/macjev/hf_staging/Jev-Style-2B-Decision-v3",
|
| 7 |
+
"verify_manifest": true,
|
| 8 |
+
"compared_with": {
|
| 9 |
+
"file": "runs/macjev/runtime_v2_dev/reference_trained/ref_block_fp32.jsonl",
|
| 10 |
+
"sha256": "09ff7d4fdd97c52c28429139a4f8d53dd224a5e0bcc69b1a318978abad5e136c"
|
| 11 |
+
},
|
| 12 |
+
"fixture": {
|
| 13 |
+
"file": "runs/macjev/runtime_v2_dev/reference_base/fixture.jsonl",
|
| 14 |
+
"sha256": "2b16d25eafa70c00a1106ba51b94890821b51ecb4fa393abb12403c8739ef314"
|
| 15 |
+
},
|
| 16 |
+
"questions": 34,
|
| 17 |
+
"skipped_questions": 9,
|
| 18 |
+
"max_abs_score_diff": 1.5020370483398438e-05,
|
| 19 |
+
"top1_same": "34/34",
|
| 20 |
+
"token_or_overflow_mismatches": [],
|
| 21 |
+
"seconds": 411.6,
|
| 22 |
+
"finished_unix": 1790449904.6816142
|
| 23 |
+
}
|
validation/runtime/reverify_main_mps_long.log
ADDED
|
@@ -0,0 +1,9 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
|
| 2 |
+
load 4.6s device=mps threads=2
|
| 3 |
+
[transformers] `causal_conv1d_fn` is falling back to its reference PyTorch implementation because `causal_conv1d` is not installed. This is correct but much slower; install `causal_conv1d` for the optimized kernel.
|
| 4 |
+
[transformers] `chunk_gated_delta_rule` is falling back to its reference PyTorch implementation because `flash-linear-attention` is not installed. This is correct but much slower; install `flash-linear-attention` for the optimized kernel.
|
| 5 |
+
long_16k-1 [16384] d=2.742e-06 flips=0 meta_ok=True 37.8s
|
| 6 |
+
long_24k-1 [25600] d=8.821e-06 flips=0 meta_ok=True 61.0s
|
| 7 |
+
long_16k n= 1 max|d|=2.742e-06 flips=0
|
| 8 |
+
long_24k n= 1 max|d|=8.821e-06 flips=0
|
| 9 |
+
ALL requests=2 questions=2 max|d|=8.821e-06 flips=0 meta_ok_all=True
|
validation/runtime/v_jevstyle_e2e.json
ADDED
|
@@ -0,0 +1,80 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"systemone_2b_release": {
|
| 3 |
+
"model": "jev-style-2b-decision-v3",
|
| 4 |
+
"answers": {
|
| 5 |
+
"team": {
|
| 6 |
+
"type": "choice",
|
| 7 |
+
"choice": "billing",
|
| 8 |
+
"confidence": 0.9802240272350504,
|
| 9 |
+
"probabilities": {
|
| 10 |
+
"billing": 0.9868160181567003,
|
| 11 |
+
"tech": 0.0073588517073361745,
|
| 12 |
+
"sales": 0.0058251301359634414
|
| 13 |
+
}
|
| 14 |
+
},
|
| 15 |
+
"urgent": {
|
| 16 |
+
"type": "noul",
|
| 17 |
+
"noul": 0.6980439916465264
|
| 18 |
+
},
|
| 19 |
+
"anger": {
|
| 20 |
+
"type": "score",
|
| 21 |
+
"score": 1.8349445223126968,
|
| 22 |
+
"confidence": 0.7639580848277534,
|
| 23 |
+
"legend": {
|
| 24 |
+
"0": "calm",
|
| 25 |
+
"1": "annoyed",
|
| 26 |
+
"2": "angry"
|
| 27 |
+
},
|
| 28 |
+
"probabilities": {
|
| 29 |
+
"0": 0.007694200905805288,
|
| 30 |
+
"1": 0.14966707587569247,
|
| 31 |
+
"2": 0.8426387232185022
|
| 32 |
+
}
|
| 33 |
+
}
|
| 34 |
+
},
|
| 35 |
+
"usage": {
|
| 36 |
+
"input_tokens": 168,
|
| 37 |
+
"state_tokens": 48,
|
| 38 |
+
"output_tokens": 0
|
| 39 |
+
},
|
| 40 |
+
"latency_ms": 17843.8,
|
| 41 |
+
"timing": {
|
| 42 |
+
"total_ms": 17843.8
|
| 43 |
+
},
|
| 44 |
+
"backend": "torch-cpu"
|
| 45 |
+
},
|
| 46 |
+
"models_2b_release": {
|
| 47 |
+
"object": "list",
|
| 48 |
+
"data": [
|
| 49 |
+
{
|
| 50 |
+
"id": "jev-style-2b-decision-v3",
|
| 51 |
+
"context_tokens": 25600,
|
| 52 |
+
"head_max_tokens": 25600,
|
| 53 |
+
"backend": "torch-cpu"
|
| 54 |
+
}
|
| 55 |
+
],
|
| 56 |
+
"models": [
|
| 57 |
+
{
|
| 58 |
+
"name": "jev-style-2b-decision-v3",
|
| 59 |
+
"release_date": null,
|
| 60 |
+
"description": "Jev-Style 2B Decision v3: local typed decisions (noul / choice / score)"
|
| 61 |
+
}
|
| 62 |
+
]
|
| 63 |
+
},
|
| 64 |
+
"over_budget": [
|
| 65 |
+
422,
|
| 66 |
+
"input_budget_exceeded"
|
| 67 |
+
],
|
| 68 |
+
"k60_answers": {
|
| 69 |
+
"q0": "opt1",
|
| 70 |
+
"q1": "opt1",
|
| 71 |
+
"q2": "opt2"
|
| 72 |
+
},
|
| 73 |
+
"adapter_vs_direct": [
|
| 74 |
+
2.220446049250313e-16,
|
| 75 |
+
0.0
|
| 76 |
+
],
|
| 77 |
+
"default_release_model_id": "jev-style-0.8b-decision-v3",
|
| 78 |
+
"default_release_same_answers": true,
|
| 79 |
+
"text_path_vs_dev_ref_max_abs_d": 3.4570693969726562e-06
|
| 80 |
+
}
|
validation/runtime/v_tiny_and_render.json
ADDED
|
@@ -0,0 +1,24 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"render": {
|
| 3 |
+
"question_errors": 2,
|
| 4 |
+
"qerr_kinds": [
|
| 5 |
+
"question text ('ins') must be a non-empty string"
|
| 6 |
+
],
|
| 7 |
+
"n_rendered_equal": 406,
|
| 8 |
+
"catalogue_overflow": 43,
|
| 9 |
+
"both_rejected": 2,
|
| 10 |
+
"edges": {
|
| 11 |
+
"short_2048": 2014,
|
| 12 |
+
"short_2049": [
|
| 13 |
+
2015,
|
| 14 |
+
2074
|
| 15 |
+
]
|
| 16 |
+
},
|
| 17 |
+
"big_k_blocks": 14,
|
| 18 |
+
"big_k_tokens": 23102
|
| 19 |
+
},
|
| 20 |
+
"tiny": {
|
| 21 |
+
"cases": 24,
|
| 22 |
+
"max_abs_d_vs_dev_ref": 2.1457672119140625e-06
|
| 23 |
+
}
|
| 24 |
+
}
|