

Data-Juicer: A One-Stop Data Processing System for Large Language Models
Paper • 2309.02033 • Published • 4
docker run --gpus all \
--shm-size 32g \
-p 30000:30000 \
-v ~/.cache/huggingface:/root/.cache/huggingface \
--env "HF_TOKEN=<secret>" \
--ipc=host \
lmsysorg/sglang:latest \
python3 -m sglang.launch_server \
--model-path "datajuicer/LLaMA-1B-dj-refine-100B" \
--host 0.0.0.0 \
--port 30000# Call the server using curl (OpenAI-compatible API):
curl -X POST "http://localhost:30000/v1/completions" \
-H "Content-Type: application/json" \
--data '{
"model": "datajuicer/LLaMA-1B-dj-refine-100B",
"prompt": "Once upon a time,",
"max_tokens": 512,
"temperature": 0.5
}'Our first data-centric LLM competition begins! Please visit the competition's official websites, FT-Data Ranker (1B Track, 7B Track), for more information.
This is a reference LLM from Data-Juicer.
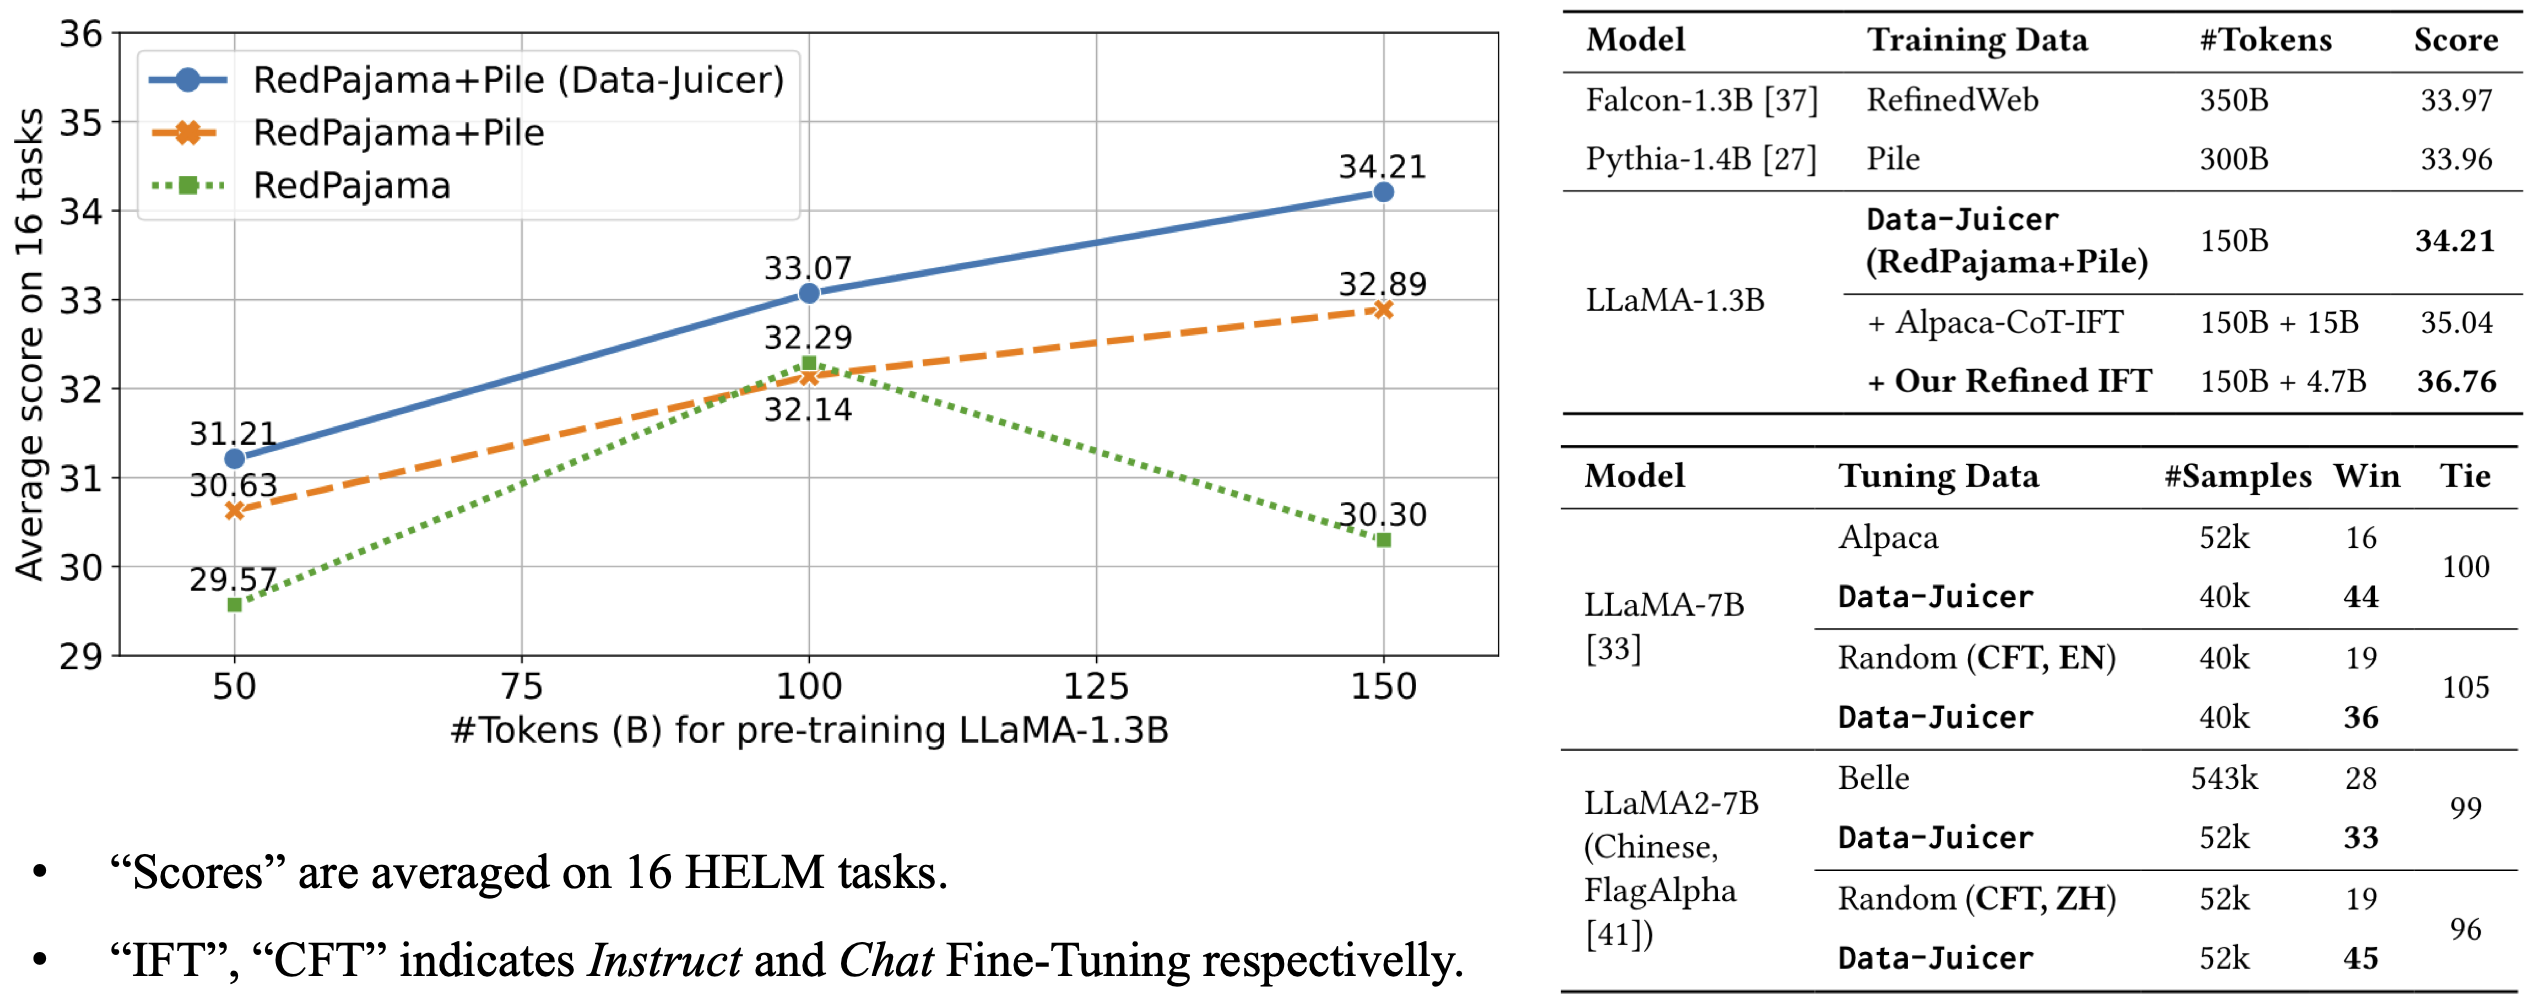
The model architecture is LLaMA-1.3B and we adopt the OpenLLaMA implementation. The model is pre-trained on 100B tokens of Data-Juicer's refined RedPajama and Pile. It achieves an average score of 33.07 over 16 HELM tasks, beating LLMs trained on original RedPajama and Pile datasets.
For more details, please refer to our paper.
Install from pip and serve model
# Install SGLang from pip: pip install sglang# Start the SGLang server: python3 -m sglang.launch_server \ --model-path "datajuicer/LLaMA-1B-dj-refine-100B" \ --host 0.0.0.0 \ --port 30000# Call the server using curl (OpenAI-compatible API): curl -X POST "http://localhost:30000/v1/completions" \ -H "Content-Type: application/json" \ --data '{ "model": "datajuicer/LLaMA-1B-dj-refine-100B", "prompt": "Once upon a time,", "max_tokens": 512, "temperature": 0.5 }'