
Datasets:


language:
  - en
pretty_name: >-
  Cross-Embodiment Bimanual Table Cleanup — Rich-Modality 10-Episode Inspection
  Sample
size_categories:
  - 10K<n<100K
task_categories:
  - robotics
configs:
  - config_name: panda
    data_files:
      - split: train
        path: viewer_data/panda/*.parquet
  - config_name: widowxai
    data_files:
      - split: train
        path: viewer_data/widowxai/*.parquet
  - config_name: episodes
    data_files:
      - split: train
        path: viewer_index/metadata.parquet
  - config_name: videos
    data_files:
      - split: train
        path: viewer_videos/train.parquet
tags:
  - lerobot
  - robot-learning
  - imitation-learning
  - manipulation
  - franka
  - panda
  - widowxai
  - bimanual-manipulation
  - dual-arm
  - table-cleanup
  - multi-view
  - video
  - depth
  - segmentation
  - object-poses
  - 6dof
  - synthetic
  - parquet
  - inspection-sample
Cross-Embodiment Bimanual Table Cleanup — Rich-Modality 10-Episode Inspection Sample
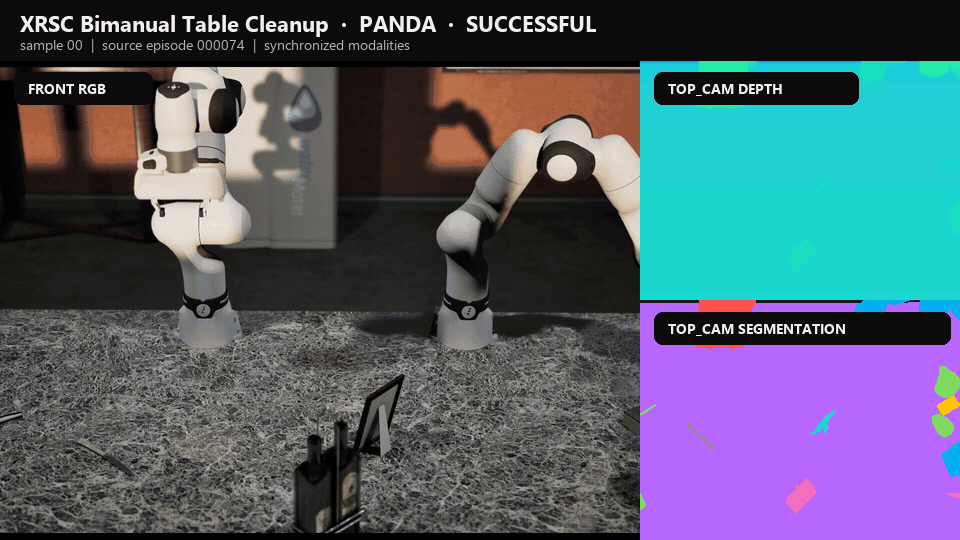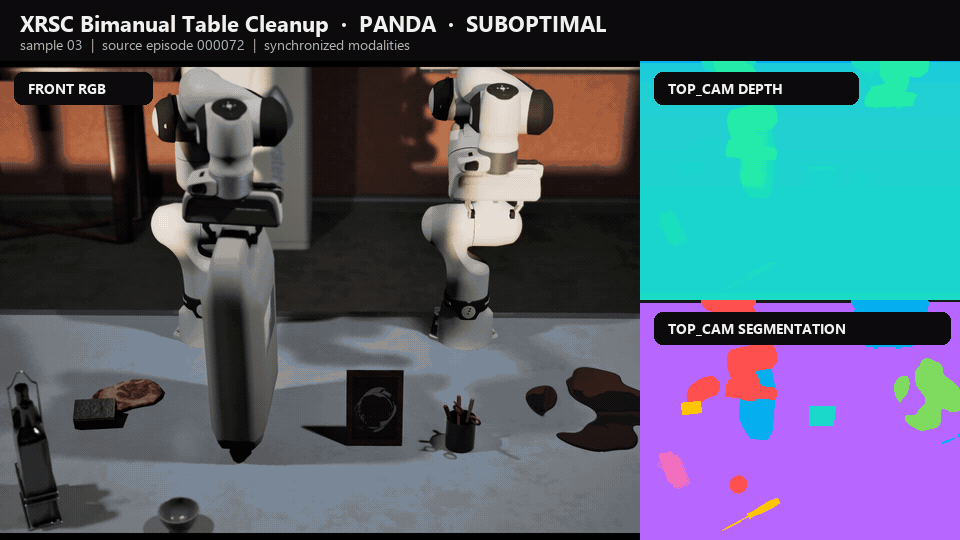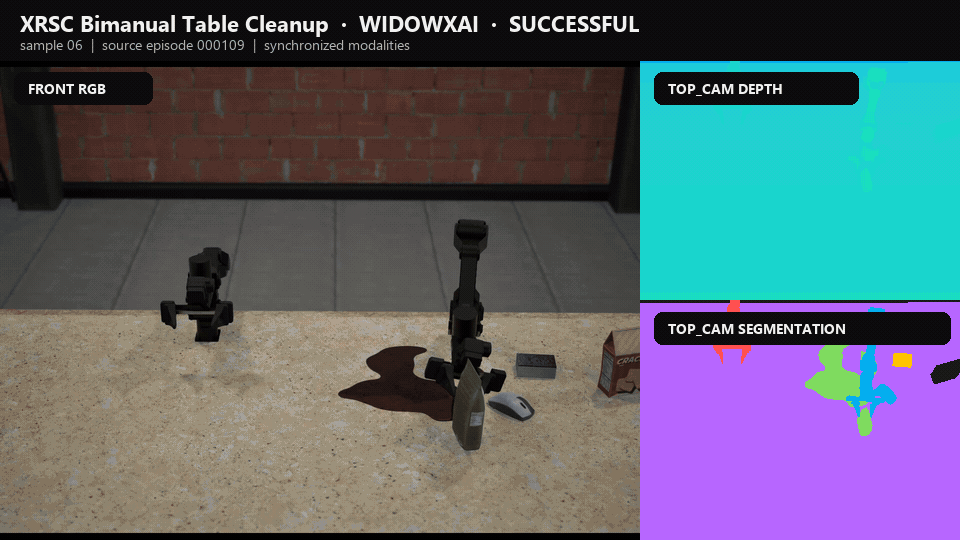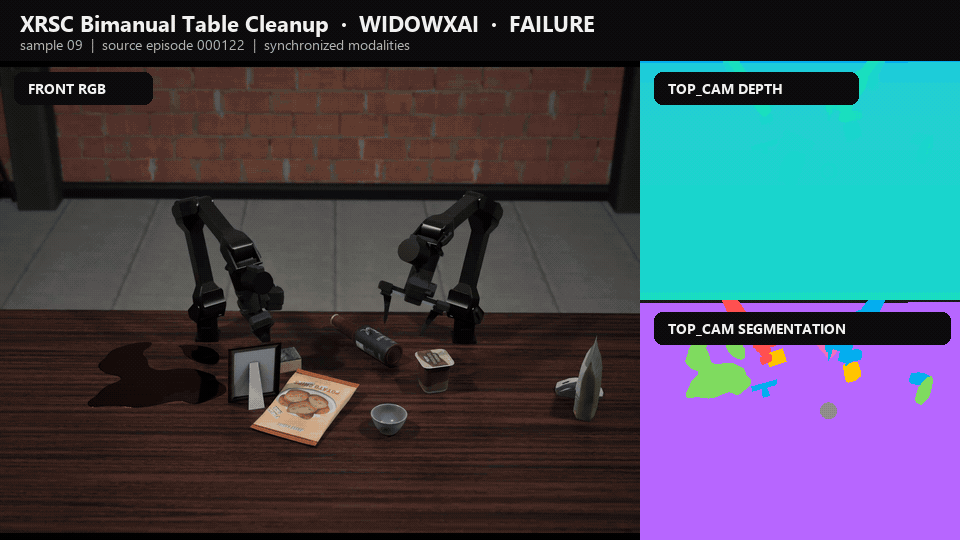
10 full-modality cross-embodiment bimanual table-cleanup episodes: 5 Franka Panda + 5 WidowXAI, 21,267 frames, 6 RGB views per robot, task-camera depth and segmentation, native robot state/action, end-effector trajectories, 6-DoF object poses, and QA annotations.
✅ Use it / ❌ Skip it
Use it for
- Inspecting loaders, schemas, camera coverage, depth, segmentation, object poses, annotations, and cross-embodiment differences before using the 150-episode sources.
- Testing visualization, filtering, QA, and preprocessing pipelines on both Panda and WidowXAI.
- Reviewing clean and deliberately suboptimal demonstrations. The cleanup sample also includes true task failures.
Skip it if you need
- A from-scratch training corpus. Ten episodes are not sufficient for policy training.
- A single shared state/action tensor across robots. Panda and WidowXAI retain different joint definitions and vector widths.
- Real-world data, force/torque, contact, tactile, point-cloud, or audio streams.
At a glance
| Episodes / frames | 10 / 21,267 (≈11.81 min @ 30 FPS) |
| Robot split | 5 Panda + 5 WidowXAI |
| Selection split | Per robot: 2 successful / 2 suboptimal / 1 cleanup-incomplete failure |
| State/action | Panda 18-D; WidowXAI 16-D joint/gripper state; achieved next-frame action, not recorded controller commands |
| Cameras | 6 RGB views per robot, 1280×960 H.264, no audio |
| Depth / segmentation | Metric depth and instance segmentation from top_cam |
| Other modalities | End-effector state/action, local/world TCP poses, 6-DoF object state, gripper semantics, phase/subtask QA |
| Format | Two robot-specific LeRobot v2.1 subsets + four Hugging Face Viewer configs |
| Repository footprint | ≈5.70 GB |
| License | Not specified in either source repository |
Additional camera modalities: Any RGB view can be supplied with additional synthetic modalities, including metric depth and instance segmentation, on request. These modalities are not included in this release unless explicitly listed above.
Load it
The robot frame schemas are intentionally separate. Select the embodiment explicitly:
from datasets import load_dataset

repo = "ExylosAi/bimanual-table-cleanup-cross-embodiment-rich-modality-sample"
panda = load_dataset(repo, name="panda", split="train")
widowxai = load_dataset(repo, name="widowxai", split="train")

print(panda[0]["observation.state"])
print(widowxai[0]["observation.state"])
print(panda[0]["selection_bucket"], panda[0]["source_episode_index"])
Use name="episodes" for the combined 10-row provenance and quality index. Use name="videos" for the combined RGB browser.
Canonical nested Parquet is stored under each robot root and is best read with PyArrow:
from huggingface_hub import hf_hub_download
import pyarrow.parquet as pq

path = hf_hub_download(
    "ExylosAi/bimanual-table-cleanup-cross-embodiment-rich-modality-sample",
    "robots/panda/data/chunk-000/episode_000000.parquet",
    repo_type="dataset",
)
episode = pq.read_table(path)
print(episode.schema)
Episode selection
| Robot | Local ep | Source | Source ep | Inspection bucket | Task success | Grade | Score |
|---|---|---|---|---|---|---|---|
| panda | 0 | xrsc-cleanup-table-bimanual-panda-150ep | 74 | successful | yes | B | 3.71 |
| panda | 1 | xrsc-cleanup-table-bimanual-panda-150ep | 89 | successful | yes | B | 3.57 |
| panda | 2 | xrsc-cleanup-table-bimanual-panda-150ep | 119 | suboptimal | yes | D | 2.14 |
| panda | 3 | xrsc-cleanup-table-bimanual-panda-150ep | 72 | suboptimal | yes | C | 3.00 |
| panda | 4 | xrsc-cleanup-table-bimanual-panda-150ep | 131 | failure | no | D | 2.00 |
| widowxai | 0 | xrsc-cleanup-table-bimanual-widowxai-150ep | 11 | successful | yes | C | 3.14 |
| widowxai | 1 | xrsc-cleanup-table-bimanual-widowxai-150ep | 109 | successful | yes | C | 3.14 |
| widowxai | 2 | xrsc-cleanup-table-bimanual-widowxai-150ep | 140 | suboptimal | yes | D | 2.14 |
| widowxai | 3 | xrsc-cleanup-table-bimanual-widowxai-150ep | 37 | suboptimal | yes | D | 2.43 |
| widowxai | 4 | xrsc-cleanup-table-bimanual-widowxai-150ep | 122 | failure | no | D | 2.29 |
Selection buckets summarize why an episode is present in this inspection sample. Detailed phase annotations, D1–D7 scores, raw measurements, confidence, and source provenance remain available in annotations.json, viewer_index/metadata.parquet, and sample_manifest.json.
Modalities
- RGB video: all source cameras for every selected episode.
- Metric depth: packed float32 NPZ, referenced frame-by-frame from canonical and Viewer Parquet.
- Instance segmentation: lossless FFV1 MKV plus per-row label maps.
- Robot state/action: native, embodiment-specific joint and gripper vectors; no padding or mixed robot tensor.
- End-effector: packed state/action plus local/world TCP poses and linear velocity.
- Objects: per-frame 6-DoF poses, orientation, velocity, and task-specific state.
- QA: task outcome, failure reason, phase ranges, execution quality, task alignment, D1–D7 metrics, composite score, confidence, and grade.
Source revisions
The sample is reproducibly derived from these immutable private snapshots:
VadRobotics/xrsc-cleanup-table-bimanual-panda-150ep@5ecbcce36d5d833449b67d2a39342e287d9be589VadRobotics/xrsc-cleanup-table-bimanual-widowxai-150ep@430e8bbedc8d18e5a7557df3ace7fcf1056ef6ee
Media payloads are byte-identical copies of the selected source files. Episode indices and paths are remapped only inside the five-episode robot subsets. sample_manifest.json preserves the complete mapping.
File layout
robots/panda/        meta · data · videos · annotations for 5 Panda episodes
robots/widowxai/     meta · data · videos · annotations for 5 WidowXAI episodes
viewer_data/         separate flattened panda and widowxai frame configs
viewer_index/        combined 10-row episode/provenance config
viewer_videos/       combined RGB Video-feature config
assets/              dataset_preview.gif showing RGB, depth, and segmentation
sample_manifest.json · annotations.json
Notes and limitations
- This is a synthetic inspection sample, not a statistically representative training or evaluation benchmark.
- Robot schemas are deliberately separate. Do not concatenate state/action vectors without an explicit embodiment adapter.
- The joint-space and Cartesian actions are derived from achieved next-frame state; no commanded target stream exists.
- RGB has no audio. Depth and segmentation are available from one task-specific camera.
- Each robot subset intentionally contains one
cleanup_incompletetask failure. successfulandsuboptimalare inspection-selection buckets; use the original annotations and scores for custom filtering.- No standalone license file or explicit license terms were present in the source repositories. Do not assume redistribution rights.
Citation
If you use this sample, cite this repository plus the exact sample commit and source revisions listed above.