

Add files using upload-large-folder tool
Browse filesThis view is limited to 50 files because it contains too many changes. See raw diff
- .gitattributes +2 -0
- README.md +253 -1
- assets/data_distribution.png +3 -0
- camera.csv +3 -0
- camlayout.csv +3 -0
- tars/annotations_camlayout.tar +3 -0
- tars/videos_camera_only_000.tar +3 -0
- tars/videos_camera_only_001.tar +3 -0
- tars/videos_camera_only_002.tar +3 -0
- tars/videos_camera_only_003.tar +3 -0
- tars/videos_camera_only_006.tar +3 -0
- tars/videos_camera_only_007.tar +3 -0
- tars/videos_camera_only_008.tar +3 -0
- tars/videos_camera_only_010.tar +3 -0
- tars/videos_camera_only_012.tar +3 -0
- tars/videos_camera_only_013.tar +3 -0
- tars/videos_camera_only_015.tar +3 -0
- tars/videos_camera_only_017.tar +3 -0
- tars/videos_camera_only_019.tar +3 -0
- tars/videos_camera_only_024.tar +3 -0
- tars/videos_camera_only_026.tar +3 -0
- tars/videos_camera_only_028.tar +3 -0
- tars/videos_camera_only_029.tar +3 -0
- tars/videos_camera_only_033.tar +3 -0
- tars/videos_camera_only_034.tar +3 -0
- tars/videos_camera_only_036.tar +3 -0
- tars/videos_camera_only_038.tar +3 -0
- tars/videos_camera_only_039.tar +3 -0
- tars/videos_camera_only_040.tar +3 -0
- tars/videos_camera_only_043.tar +3 -0
- tars/videos_camera_only_044.tar +3 -0
- tars/videos_camera_only_055.tar +3 -0
- tars/videos_camera_only_056.tar +3 -0
- tars/videos_camera_only_058.tar +3 -0
- tars/videos_camlayout_001.tar +3 -0
- tars/videos_camlayout_003.tar +3 -0
- tars/videos_camlayout_005.tar +3 -0
- tars/videos_camlayout_007.tar +3 -0
- tars/videos_camlayout_008.tar +3 -0
- tars/videos_camlayout_009.tar +3 -0
- tars/videos_camlayout_011.tar +3 -0
- tars/videos_camlayout_016.tar +3 -0
- tars/videos_camlayout_017.tar +3 -0
- tars/videos_camlayout_021.tar +3 -0
- tars/videos_camlayout_027.tar +3 -0
- tars/videos_camlayout_029.tar +3 -0
- tars/videos_camlayout_030.tar +3 -0
- tars/videos_camlayout_031.tar +3 -0
- tars/videos_camlayout_034.tar +3 -0
- tars/videos_camlayout_035.tar +3 -0
.gitattributes
CHANGED
|
@@ -58,3 +58,5 @@ saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
|
| 58 |
# Video files - compressed
|
| 59 |
*.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 60 |
*.webm filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
| 58 |
# Video files - compressed
|
| 59 |
*.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 60 |
*.webm filter=lfs diff=lfs merge=lfs -text
|
| 61 |
+
camlayout.csv filter=lfs diff=lfs merge=lfs -text
|
| 62 |
+
camera.csv filter=lfs diff=lfs merge=lfs -text
|
README.md
CHANGED
|
@@ -1,3 +1,255 @@
|
|
| 1 |
---
|
| 2 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
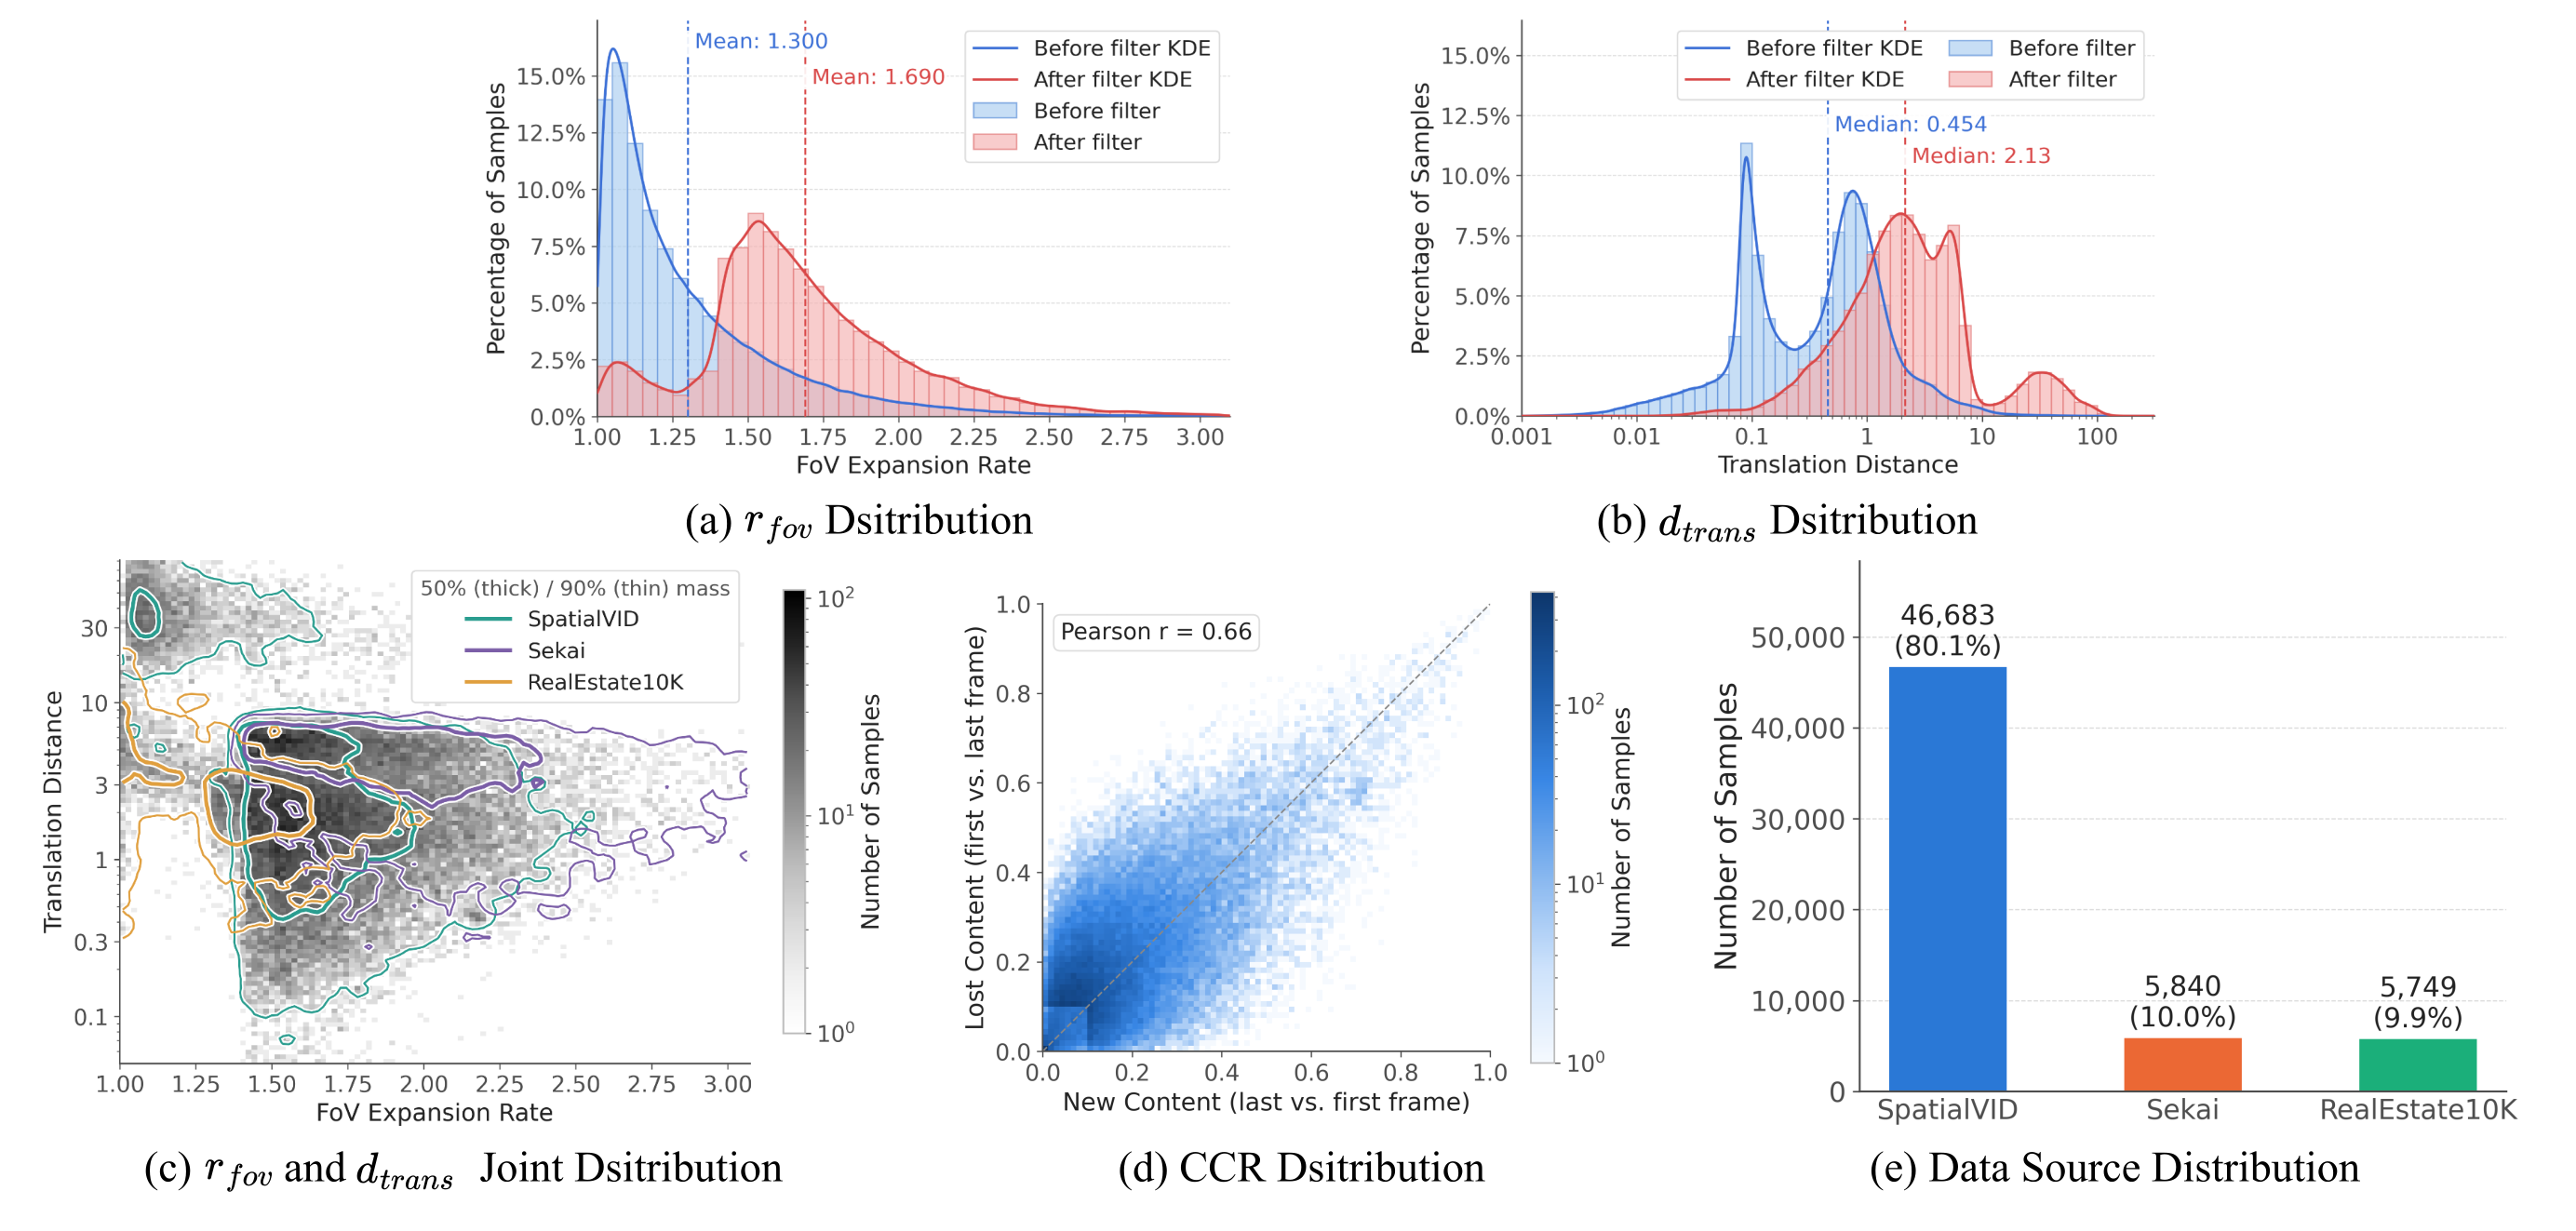
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 3 |
---
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
---
|
| 2 |
+
pretty_name: LIFT-Vista
|
| 3 |
+
license: cc-by-nc-sa-4.0
|
| 4 |
+
language:
|
| 5 |
+
- en
|
| 6 |
+
task_categories:
|
| 7 |
+
- video-generation
|
| 8 |
+
tags:
|
| 9 |
+
- video-generation
|
| 10 |
+
- camera-control
|
| 11 |
+
- layout-control
|
| 12 |
+
- bounding-box
|
| 13 |
+
- novel-view-synthesis
|
| 14 |
+
size_categories:
|
| 15 |
+
- 120,898
|
| 16 |
+
configs:
|
| 17 |
+
- config_name: camlayout
|
| 18 |
+
default: true
|
| 19 |
+
data_files:
|
| 20 |
+
- split: train
|
| 21 |
+
path: camlayout.csv
|
| 22 |
+
- config_name: camera
|
| 23 |
+
data_files:
|
| 24 |
+
- split: train
|
| 25 |
+
path: camera.csv
|
| 26 |
---
|
| 27 |
+
|
| 28 |
+
# LIFT-Vista
|
| 29 |
+
|
| 30 |
+
<p align="center">
|
| 31 |
+
<a href="https://jsxzs.github.io/LIFT"><img src="https://img.shields.io/badge/Project%20Page-LIFT-blue?logo=googlechrome&logoColor=white" alt="Project Page"></a>
|
| 32 |
+
<!-- <a href="https://arxiv.org/abs/XXXX.XXXXX"><img src="https://img.shields.io/badge/arXiv-XXXX.XXXXX-b31b1b?logo=arxiv&logoColor=white" alt="arXiv"></a> -->
|
| 33 |
+
<a href="https://github.com/jsxzs/LIFT"><img src="https://img.shields.io/badge/GitHub-Code-181717?logo=github&logoColor=white" alt="Code"></a>
|
| 34 |
+
<a href="https://huggingface.co/Overdog/LIFT"><img src="https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-Model-ffcc00" alt="Hugging Face Model"></a>
|
| 35 |
+
<a href="https://huggingface.co/datasets/Overdog/LIFT-Vista"><img src="https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-Dataset-ffcc00" alt="Hugging Face Dataset"></a>
|
| 36 |
+
</p>
|
| 37 |
+
|
| 38 |
+
LIFT-Vista is a dataset with large camera viewpoint changes and joint camera-layout annotations.
|
| 39 |
+
|
| 40 |
+
## Overview
|
| 41 |
+
|
| 42 |
+
| | `camera.csv` | `camlayout.csv` |
|
| 43 |
+
|---|---|---|
|
| 44 |
+
| Clips | 120,898 | 58,272 (a subset of the camera clips) |
|
| 45 |
+
| Annotations | camera trajectory, caption | camera trajectory, caption, last-frame layout, per-frame box tracks |
|
| 46 |
+
|
| 47 |
+
Every clip has 81 frames at 16 fps (about 5 s) at the native resolution of its source video (98% are 1280×720),
|
| 48 |
+
encoded with H.264. The release is about 413 GB, of which 407 GB are videos.
|
| 49 |
+
|
| 50 |
+
## Download
|
| 51 |
+
|
| 52 |
+
Videos and annotations are stored as tar shards in `tars/` (about 4 GB per video shard). Extracting them in the
|
| 53 |
+
dataset root restores the `videos/` and `annotations/` directories that the CSV paths point to (413 GB in total):
|
| 54 |
+
|
| 55 |
+
```bash
|
| 56 |
+
hf download Overdog/LIFT-Vista --repo-type dataset --local-dir LIFT-Vista
|
| 57 |
+
cd LIFT-Vista
|
| 58 |
+
for f in tars/*.tar; do tar -xf "$f"; done
|
| 59 |
+
```
|
| 60 |
+
|
| 61 |
+
`camlayout.csv` only needs the `camlayout` shards (179 GB):
|
| 62 |
+
|
| 63 |
+
```bash
|
| 64 |
+
hf download Overdog/LIFT-Vista --repo-type dataset --local-dir LIFT-Vista \
|
| 65 |
+
--include "*.md" --include "*.csv" --include "assets/*" \
|
| 66 |
+
--include "tars/annotations_camlayout.tar" --include "tars/videos_camlayout_*.tar"
|
| 67 |
+
cd LIFT-Vista
|
| 68 |
+
for f in tars/*.tar; do tar -xf "$f"; done
|
| 69 |
+
```
|
| 70 |
+
|
| 71 |
+
## Structure
|
| 72 |
+
|
| 73 |
+
```
|
| 74 |
+
LIFT-Vista/
|
| 75 |
+
├── camera.csv
|
| 76 |
+
├── camlayout.csv
|
| 77 |
+
├── videos/<source>/<video_id>/<window>.mp4
|
| 78 |
+
└── annotations/<source>/<video_id>/<window>/
|
| 79 |
+
├── camera_da3.npz # every clip
|
| 80 |
+
├── caption.txt # every clip
|
| 81 |
+
├── layout_lastframe.json # camlayout clips only
|
| 82 |
+
└── layout_track_<W>x<H>.json # camlayout clips only
|
| 83 |
+
```
|
| 84 |
+
|
| 85 |
+
`<source>` is `SpatialVID`, `Sekai` or `RealEstate10K`, `<video_id>` is the id of the video in the source dataset,
|
| 86 |
+
and `<window>` is the window index `w` of the 81-frame window extracted from the source video.
|
| 87 |
+
|
| 88 |
+
### CSV columns
|
| 89 |
+
|
| 90 |
+
| Column | Description |
|
| 91 |
+
|---|---|
|
| 92 |
+
| `UID` | unique clip id, `<video_id>_<window>` |
|
| 93 |
+
| `resolution` | clip resolution, `WxH` |
|
| 94 |
+
| `fps`, `num_frames` | frame rate and frame count of the **source video** the clip was cut from (every clip itself has 81 frames at 16 fps) |
|
| 95 |
+
| `Video_Path` | the clip, relative to the dataset root |
|
| 96 |
+
| `Annotation_Path` | the annotation directory, relative to the dataset root |
|
| 97 |
+
| `CameraFile` | camera file inside `Annotation_Path` |
|
| 98 |
+
| `layout_file` | last-frame layout inside `Annotation_Path` (`camlayout.csv` only) |
|
| 99 |
+
| `sam3_track_file` | box tracks inside `Annotation_Path` (`camlayout.csv` only) |
|
| 100 |
+
| `sam3_track_resolution` | pixel grid `WxH` of the track boxes; equal to `resolution` except for 183 clips whose tracks were computed at 640×352 or 832×480 (rescale x and y separately) |
|
| 101 |
+
| `caption` | text caption, identical to `caption.txt` |
|
| 102 |
+
|
| 103 |
+
### Camera (`camera_da3.npz`)
|
| 104 |
+
|
| 105 |
+
- `extrinsic`: `(81, 3, 4)` world-to-camera matrices `[R | t]`, OpenCV convention (x right, y down, z forward).
|
| 106 |
+
- `intrinsic`: `(81, 3, 3)` pinhole intrinsics in pixels of the clip resolution.
|
| 107 |
+
|
| 108 |
+
### Last-frame layout (`layout_lastframe.json`)
|
| 109 |
+
|
| 110 |
+
```
|
| 111 |
+
{
|
| 112 |
+
"instances": [
|
| 113 |
+
{
|
| 114 |
+
"id": 0,
|
| 115 |
+
"category": "chair",
|
| 116 |
+
"bbox": [0, 515, 332, 719],
|
| 117 |
+
"caption": "white upholstered chair with an orange throw pillow"
|
| 118 |
+
},
|
| 119 |
+
...
|
| 120 |
+
]
|
| 121 |
+
}
|
| 122 |
+
```
|
| 123 |
+
|
| 124 |
+
Salient foreground objects of the last frame (frame 80), with boxes `[x1, y1, x2, y2]` in pixels of the clip
|
| 125 |
+
resolution.
|
| 126 |
+
|
| 127 |
+
### Box tracks (`layout_track_<W>x<H>.json`)
|
| 128 |
+
|
| 129 |
+
```
|
| 130 |
+
{
|
| 131 |
+
"source_layout_file": "layout_lastframe.json",
|
| 132 |
+
"track_resolution": "1280x720", # pixel grid of every box in this file
|
| 133 |
+
"prompt_frame_idx": 80,
|
| 134 |
+
"num_frames": 81,
|
| 135 |
+
"tracks": {
|
| 136 |
+
"0": {"id": 0, "category": "chair", "caption": "...",
|
| 137 |
+
"bboxes": {"37": [x1, y1, x2, y2], ..., "80": [x1, y1, x2, y2]}}, # no box in frames 0..36
|
| 138 |
+
...
|
| 139 |
+
},
|
| 140 |
+
"frames": {"37": [{"id": 0, "category": "chair", "caption": "...", "bbox": [x1, y1, x2, y2]}, ...], ...}
|
| 141 |
+
}
|
| 142 |
+
```
|
| 143 |
+
|
| 144 |
+
## Statistics
|
| 145 |
+
|
| 146 |
+
`camera.csv` has **120,898** clips for camera-control training (Stage 1 in the paper) and
|
| 147 |
+
`camlayout.csv` has a subset of **58,272** clips with layouts (Stages 2 and 3).
|
| 148 |
+
The layout annotations contain **5.5 objects per clip** on average and cover **8,302 category labels**, including indoor objects (chair, window, lamp, cabinet, sofa, ...) and outdoor objects (person, building, car, boat, tree, sign, ...).
|
| 149 |
+
**84.8%** of the layout clips contain objects that are
|
| 150 |
+
not visible in the first frame and only appear in later views.
|
| 151 |
+
|
| 152 |
+

|
| 153 |
+
|
| 154 |
+
(a, b) Distributions of the FoV expansion ratio and the translation distance over all candidate windows before
|
| 155 |
+
filtering (blue) and ours (red); filtering removes the mass of near-static windows and shifts both
|
| 156 |
+
metrics toward larger viewpoint changes.
|
| 157 |
+
(c) Joint distribution of the two camera-motion metrics, with 50% and 90% mass contours per source dataset.
|
| 158 |
+
(d) Joint distribution of the two content change ratios; the two directions are correlated and complementary but not redundant.
|
| 159 |
+
(e) Number of training clips per source dataset.
|
| 160 |
+
|
| 161 |
+
**FoV expansion ratio.** We uniformly sample $K$ keyframes from each clip ($K = 8$). For the $i$-th keyframe, let
|
| 162 |
+
$\Omega_{k_i} \subseteq \mathbb{S}^2$ denote the set of visible viewing directions in a common world coordinate system;
|
| 163 |
+
its spherical area is estimated using uniformly sampled directions on the unit sphere. The FoV expansion ratio
|
| 164 |
+
|
| 165 |
+
$$
|
| 166 |
+
r_{\mathrm{FoV}} = \frac{\left| \bigcup_{i=1}^{K} \Omega_{k_i} \right|}{\left| \Omega_{k_1} \right|}
|
| 167 |
+
$$
|
| 168 |
+
|
| 169 |
+
measures the total viewing region covered by the clip relative to the first frame.
|
| 170 |
+
|
| 171 |
+
**Translation distance.** The accumulated camera translation is
|
| 172 |
+
|
| 173 |
+
$$
|
| 174 |
+
d_{\mathrm{trans}} = \sum_{i=1}^{K-1} \left\| \mathbf{o}_{k_{i+1}} - \mathbf{o}_{k_i} \right\|_2 ,
|
| 175 |
+
$$
|
| 176 |
+
|
| 177 |
+
where $\mathbf{o}_{k_i}$ denotes the camera origin of the $i$-th keyframe.
|
| 178 |
+
|
| 179 |
+
**Content change ratios (CCR).** Since camera motion alone does not directly measure changes in visible scene content,
|
| 180 |
+
we additionally compute a patch-level CCR between the first and last frames using DINOv2. Let
|
| 181 |
+
$\{\mathbf{p}_i\}_{i=1}^{N}$ and $\{\mathbf{q}_j\}_{j=1}^{N}$ denote their $\ell_2$-normalized patch embeddings. The
|
| 182 |
+
last-frame CCR is
|
| 183 |
+
|
| 184 |
+
$$
|
| 185 |
+
r_{lf\text{-}CCR} = \frac{1}{N} \sum_{j=1}^{N} \mathbb{I}\left[ \max_i \langle \mathbf{p}_i, \mathbf{q}_j \rangle < \tau \right],
|
| 186 |
+
$$
|
| 187 |
+
|
| 188 |
+
where $\mathbb{I}[\cdot]$ denotes the indicator function, $\langle \cdot, \cdot \rangle$ denotes the cosine similarity,
|
| 189 |
+
and $\tau$ is a similarity threshold ($\tau = 0.5$). $r_{lf\text{-}CCR}$ measures the fraction of last-frame patches
|
| 190 |
+
unmatched in the first frame (new content); $r_{ff\text{-}CCR}$ is computed analogously in the reverse direction to
|
| 191 |
+
measure content leaving the initial view (lost content).
|
| 192 |
+
|
| 193 |
+
## Usage
|
| 194 |
+
|
| 195 |
+
```python
|
| 196 |
+
import json, os
|
| 197 |
+
import numpy as np
|
| 198 |
+
import pandas as pd
|
| 199 |
+
|
| 200 |
+
root = "LIFT-Vista"
|
| 201 |
+
df = pd.read_csv(os.path.join(root, "camlayout.csv"))
|
| 202 |
+
row = df.iloc[0]
|
| 203 |
+
|
| 204 |
+
video_path = os.path.join(root, row.Video_Path) # 81 frames, 16 fps
|
| 205 |
+
ann_dir = os.path.join(root, row.Annotation_Path)
|
| 206 |
+
|
| 207 |
+
cam = np.load(os.path.join(ann_dir, row.CameraFile))
|
| 208 |
+
w2c, K = cam["extrinsic"], cam["intrinsic"] # (81, 3, 4), (81, 3, 3)
|
| 209 |
+
|
| 210 |
+
with open(os.path.join(ann_dir, row.sam3_track_file)) as f:
|
| 211 |
+
tracks = json.load(f)["tracks"]
|
| 212 |
+
tw, th = map(int, row.sam3_track_resolution.split("x")) # pixel grid of the boxes
|
| 213 |
+
for obj in tracks.values():
|
| 214 |
+
frames = sorted(int(k) for k in obj["bboxes"])
|
| 215 |
+
print(obj["category"], "| visible in frames", frames[0], "to", frames[-1], "|", obj["caption"])
|
| 216 |
+
```
|
| 217 |
+
|
| 218 |
+
The LIFT training code reads these CSVs directly; see the [code repository](https://github.com/jsxzs/LIFT).
|
| 219 |
+
|
| 220 |
+
|
| 221 |
+
## Citation
|
| 222 |
+
|
| 223 |
+
Coming soon.
|
| 224 |
+
|
| 225 |
+
Please also cite the source datasets:
|
| 226 |
+
|
| 227 |
+
```bibtex
|
| 228 |
+
@misc{wang2025spatialvidlargescalevideodataset,
|
| 229 |
+
title={SpatialVID: A Large-Scale Video Dataset with Spatial Annotations},
|
| 230 |
+
author={Jiahao Wang and Yufeng Yuan and Rujie Zheng and Youtian Lin and Jian Gao and Lin-Zhuo Chen and Yajie Bao and Yi Zhang and Chang Zeng and Yanxi Zhou and Xiaoxiao Long and Hao Zhu and Zhaoxiang Zhang and Xun Cao and Yao Yao},
|
| 231 |
+
year={2025},
|
| 232 |
+
eprint={2509.09676},
|
| 233 |
+
archivePrefix={arXiv},
|
| 234 |
+
primaryClass={cs.CV},
|
| 235 |
+
url={https://arxiv.org/abs/2509.09676},
|
| 236 |
+
}
|
| 237 |
+
|
| 238 |
+
@article{li2025sekai,
|
| 239 |
+
title={Sekai: A Video Dataset towards World Exploration},
|
| 240 |
+
author={Zhen Li and Chuanhao Li and Xiaofeng Mao and Shaoheng Lin and Ming Li and Shitian Zhao and Zhaopan Xu and Xinyue Li and Yukang Feng and Jianwen Sun and Zizhen Li and Fanrui Zhang and Jiaxin Ai and Zhixiang Wang and Yuwei Wu and Tong He and Jiangmiao Pang and Yu Qiao and Yunde Jia and Kaipeng Zhang},
|
| 241 |
+
journal={arXiv preprint arXiv:2506.15675},
|
| 242 |
+
year={2025}
|
| 243 |
+
}
|
| 244 |
+
|
| 245 |
+
@article{zhou2018stereo,
|
| 246 |
+
author = {Zhou, Tinghui and Tucker, Richard and Flynn, John and Fyffe, Graham and Snavely, Noah},
|
| 247 |
+
title = {Stereo Magnification: Learning View Synthesis using Multiplane Images},
|
| 248 |
+
journal = {ACM Transactions on Graphics (SIGGRAPH)},
|
| 249 |
+
volume = {37},
|
| 250 |
+
number = {4},
|
| 251 |
+
articleno = {65},
|
| 252 |
+
year = {2018},
|
| 253 |
+
url = {https://dl.acm.org/doi/10.1145/3197517.3201323}
|
| 254 |
+
}
|
| 255 |
+
```
|
assets/data_distribution.png
ADDED
|
Git LFS Details
|
camera.csv
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:250055b9925fc5e5deea9575f7a978c89d7c53587b8e32138af9922acaee43a9
|
| 3 |
+
size 78268246
|
camlayout.csv
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:835b754ca7ac91751a7832487a139076e94a9d3429f28e264f56f6c26db39959
|
| 3 |
+
size 40831118
|
tars/annotations_camlayout.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:7c968e87d65513ed119494f7867c072f31ffb384b9fdc404d073a2a5b42e2790
|
| 3 |
+
size 5579745280
|
tars/videos_camera_only_000.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:d41e5505ca5b6faa56b3cdca57394c7ba152a1992c64a84847d67bae965d8d2e
|
| 3 |
+
size 4001075200
|
tars/videos_camera_only_001.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:9ea159d7fda00435fd19b3a0fb5c7d1794ebc1576e2039f1b60ab053973e0c80
|
| 3 |
+
size 4003993600
|
tars/videos_camera_only_002.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:01807754102be1bb13e9306c58854f3b0534a6962dea5b984fc1868783692af8
|
| 3 |
+
size 4003123200
|
tars/videos_camera_only_003.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:56c42160c3a232dff11c776c5b6496aca26e36a631198798f840a72469ce99ff
|
| 3 |
+
size 4005744640
|
tars/videos_camera_only_006.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:8cd0779b71147d0d6561e88f27d24b1d05c81a502542decca04a4ba50031a18d
|
| 3 |
+
size 4002406400
|
tars/videos_camera_only_007.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:5456e6e2098ad93d491a3ef55c4b21140224d09bcae3a7ecab89aa1184c7b183
|
| 3 |
+
size 4003102720
|
tars/videos_camera_only_008.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:bb81853d95268e347980f477e20d292740ff66c07c640c665b679800ef0ff5c6
|
| 3 |
+
size 4001146880
|
tars/videos_camera_only_010.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:50c9806517d92cace7f488fea36f0397163c0f4769afb147045146ef61bf3119
|
| 3 |
+
size 4001597440
|
tars/videos_camera_only_012.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:c2892e94e8a010f3c5bb8dbe1d91fb68232e811c93df7c57be146db618445ffe
|
| 3 |
+
size 4001515520
|
tars/videos_camera_only_013.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:cf9b5109bf26c48a177de3fd3a833ae8893f3012d36588f255c5925cf3a7e9e0
|
| 3 |
+
size 4002631680
|
tars/videos_camera_only_015.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:04bb0062ec68c56e3cdaaf3903dc7af8d81b6d166039880be1e2edc454572892
|
| 3 |
+
size 4006481920
|
tars/videos_camera_only_017.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:75e4921421dae61b7da217dd7461cc231a62e320d5e00b6a07c07f1b2abc2490
|
| 3 |
+
size 4002775040
|
tars/videos_camera_only_019.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:573235733355aec6524c0f29baeb9d33aaa9d287716b4a92ff378fdd953865c2
|
| 3 |
+
size 4002037760
|
tars/videos_camera_only_024.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:2ea979134c87ea5ffbc5234dd64bf11c17fcce4b90f9ce35cfd55ea373bfbcce
|
| 3 |
+
size 4001525760
|
tars/videos_camera_only_026.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:34040c000349ba18d33f27ad5705517ba9750a90da175057d6ac550d4129adf1
|
| 3 |
+
size 4001894400
|
tars/videos_camera_only_028.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:a00fe779268887868aa7118ae3019857b9ce95b01f815a11ad2a2d10317df257
|
| 3 |
+
size 4005662720
|
tars/videos_camera_only_029.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:cecc7ea1318fe02936f26f14f32c7904abb61d23b2949f4b23b96f728694ff5d
|
| 3 |
+
size 4005140480
|
tars/videos_camera_only_033.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:b9491fc5fae6a35f8f08bcc2b42409bbec164c743e378ec06f36e6993bc51b7f
|
| 3 |
+
size 4003491840
|
tars/videos_camera_only_034.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:69b93cb7f5d0fc5e2e38049e0746c8379f4a1886451b089ea4435374f69f2791
|
| 3 |
+
size 4004085760
|
tars/videos_camera_only_036.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:95311fc67575596b62fbfeddff39093537e909dffd973a49795bc520f5d502a0
|
| 3 |
+
size 4003266560
|
tars/videos_camera_only_038.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:9814f8bcb3dcb9239f69ab7d5883713199c05d6a2c1bc411119e9bb0dc6f83a0
|
| 3 |
+
size 4001945600
|
tars/videos_camera_only_039.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:8a197d0d869668596af1b0fa42e56f7b2b5a00052d0567b65f92932bb5ae4931
|
| 3 |
+
size 4003440640
|
tars/videos_camera_only_040.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:20f8d1a1ce57a00f08bde6d32e5511773834ff8fa29908bb9f505a226869fbd5
|
| 3 |
+
size 4002191360
|
tars/videos_camera_only_043.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:c3cf5ea66e47713cb3b69077005b11d28c45a5d644402f396df2545abd6d711b
|
| 3 |
+
size 4002037760
|
tars/videos_camera_only_044.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:b252d0836d276fb4904691c3912fa2124a781abcf44b80a341e6149898cb65b8
|
| 3 |
+
size 4001966080
|
tars/videos_camera_only_055.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:6c1a1d70d1d15f37edec76dbc0adb18e36d3b3b910e353b0582843ae7d15f686
|
| 3 |
+
size 4003256320
|
tars/videos_camera_only_056.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:0d1667aef9c458c1f1c0a173a4780445114d6ea013102424a31cbd4a40e943cd
|
| 3 |
+
size 4001116160
|
tars/videos_camera_only_058.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:6367c51a07fd916659dbe9e51837a722d02d86052785a2a059c6ea0b6397729d
|
| 3 |
+
size 1146163200
|
tars/videos_camlayout_001.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:0c9445c2006a7fbdb43daf83a2bc04368c897e7fcaa5069e3ec99bc1af76695e
|
| 3 |
+
size 4004833280
|
tars/videos_camlayout_003.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:5a45b22ba561d88dde86c1b65921b7019d52399ded2e1b41f1b282245cbefc04
|
| 3 |
+
size 4002805760
|
tars/videos_camlayout_005.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:c423b582d0b3ce48ee19a4995aa2ac09a558568ab9911deffb9889dee7036d71
|
| 3 |
+
size 4000839680
|
tars/videos_camlayout_007.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:be68cfcb089db822b4de5a295d6be54f08e93be700e953e8664f065004ba0a32
|
| 3 |
+
size 4001894400
|
tars/videos_camlayout_008.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:9935b64a50680a383bce2a69d7c076da986cb64f24c80d48c2f457fc36c3057c
|
| 3 |
+
size 4005683200
|
tars/videos_camlayout_009.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:9cfc97fa3058baf42a62adecdf78e8dacd5629d4371de9a062ce1787c71e86aa
|
| 3 |
+
size 4001290240
|
tars/videos_camlayout_011.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:7353775af0759741b4ab324bc17956fc9cfb710546767966f3545663e5eb53ad
|
| 3 |
+
size 4005017600
|
tars/videos_camlayout_016.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:6d28e3a685ea89a0fad9234b92d2e3ac68a9be2544654a961d5a33f1b49cb694
|
| 3 |
+
size 4001269760
|
tars/videos_camlayout_017.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:83ef2c85f2bed90509db67b47016cfa76f8204453aa1763573bf8d4f6b5ead77
|
| 3 |
+
size 4004331520
|
tars/videos_camlayout_021.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:5cf12ddc8dd356630e43f0d309669aa5a4b5a84cb77da447ee68a772de4f09b5
|
| 3 |
+
size 4003041280
|
tars/videos_camlayout_027.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:b09ad2b76641bc0fc679d680bf50bda9d9e0c1b4101151533b234dd385747938
|
| 3 |
+
size 4003389440
|
tars/videos_camlayout_029.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:51d2e1dcd33a7ba86dc683fc59417ca946b1e860a79ca93835f3a1244e01b19f
|
| 3 |
+
size 4003225600
|
tars/videos_camlayout_030.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:145beed1dd8b7b4fd5c01ef7435ebb4558d5ebb4a6a8a98d1246e2908d798147
|
| 3 |
+
size 4001280000
|
tars/videos_camlayout_031.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:80ed4658169ea28725fdd091e629a7c2c4772b0f10adde3feb9b96f4a92eb529
|
| 3 |
+
size 4001331200
|
tars/videos_camlayout_034.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:102352edd0fd0ff8786d44fb511ab55985b0163b112150a90459a2c58aa37ec0
|
| 3 |
+
size 4002959360
|
tars/videos_camlayout_035.tar
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:dcff1143eb6bbf644f4e8f47b600ed96db4cad446173d18f6c6efb670a81a587
|
| 3 |
+
size 4001515520
|