
Datasets:


Docs refresh: merge the re-pointed v0.2.5 tag; document main since v0.2.5
Browse filesMerges f71cc09 (the commit the v0.2.5 tag now points at) so main agrees with
the published tag: v0.2.5 is 20 sources, 4,366,651 documents / 9,676,513,980
proxy tokens, with sejm_api and wiktionary_examples released.
On top of that:
- README: callout for main (36 sources, 4,094,255 docs / 8.38B tokens);
european_hplt_v3_pl marked withdrawn (dead datasheet link removed);
samorzad_gov_pl v0.2 rebuild noted; table of the 17 sources not yet
released (1,331,877 docs / 1,262.4M tokens), generated from the registry
and stats.json; contributors updated from Hub PR authors; phrase-frequency
section labelled as the v0.2.5 snapshot.
- CHANGELOG: new Unreleased section (17 sources, HPLT removal, samorzad v0.2,
tooling PRs, tag re-point). Release sections untouched.
- src/sources.py: rock_pollub_pl gets its added date; comment on the
withdrawn HPLT entry.
- AGENTS.md: two known-drift notes on regenerating the README from main.
Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
- AGENTS.md +7 -0
- CHANGELOG.md +73 -11
- README.md +107 -30
- artifacts/pattern_frequency_artykul.png +2 -2
- artifacts/pattern_frequency_dzu.png +2 -2
- artifacts/pattern_frequency_hf_snippet.md +28 -10
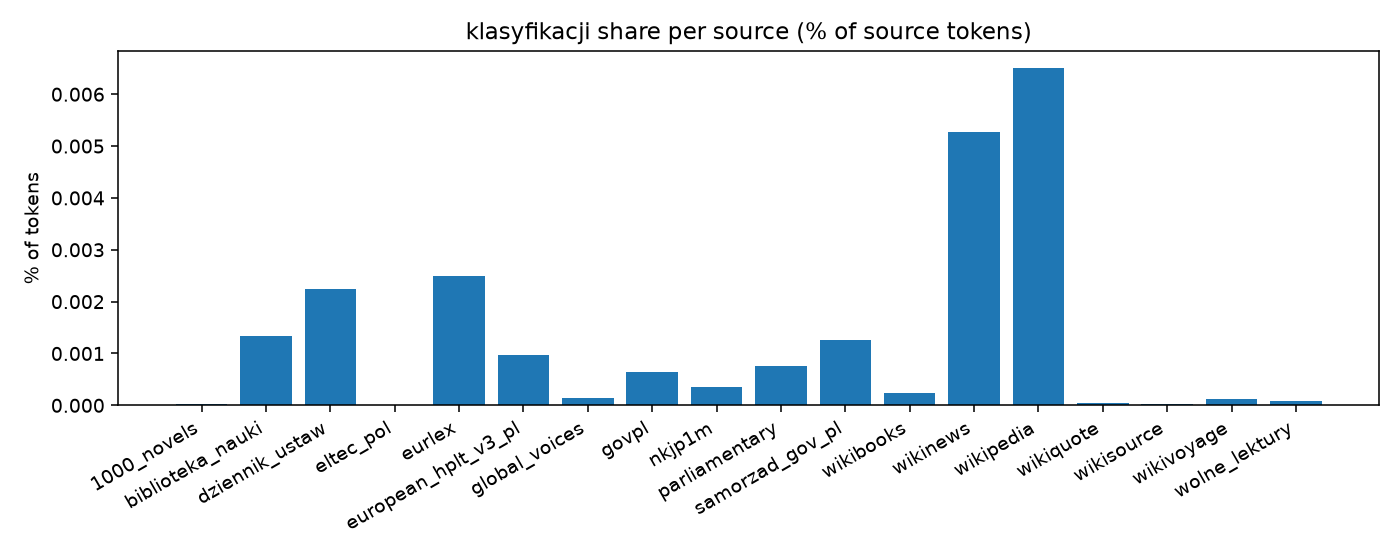
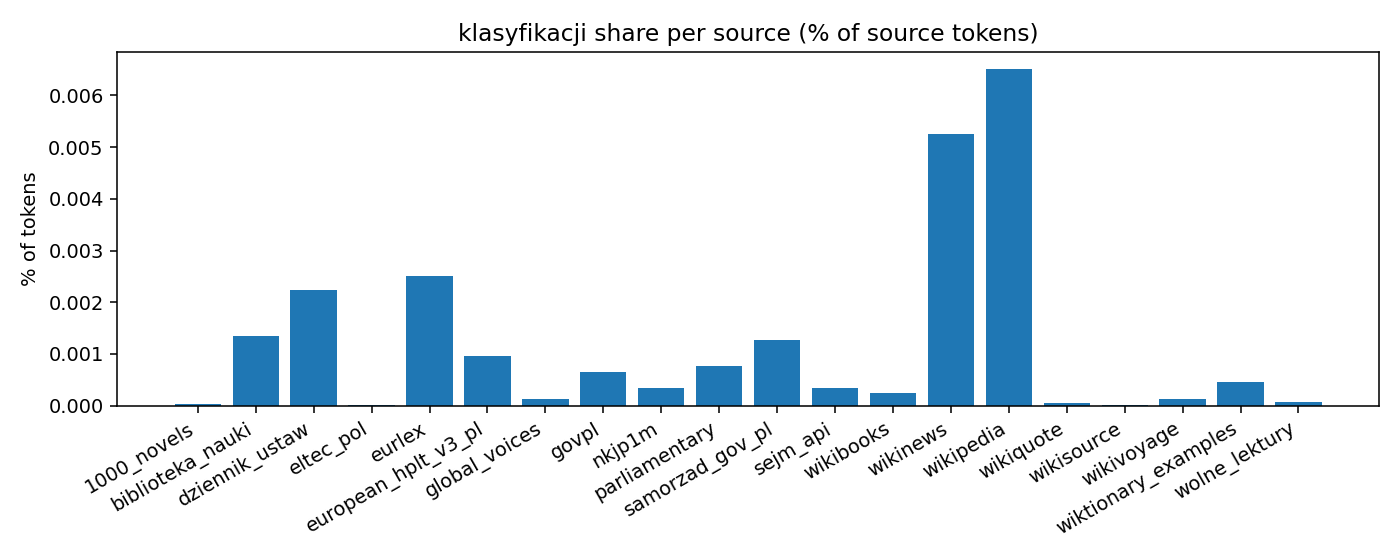
- artifacts/pattern_frequency_klasyfikacji.png +2 -2
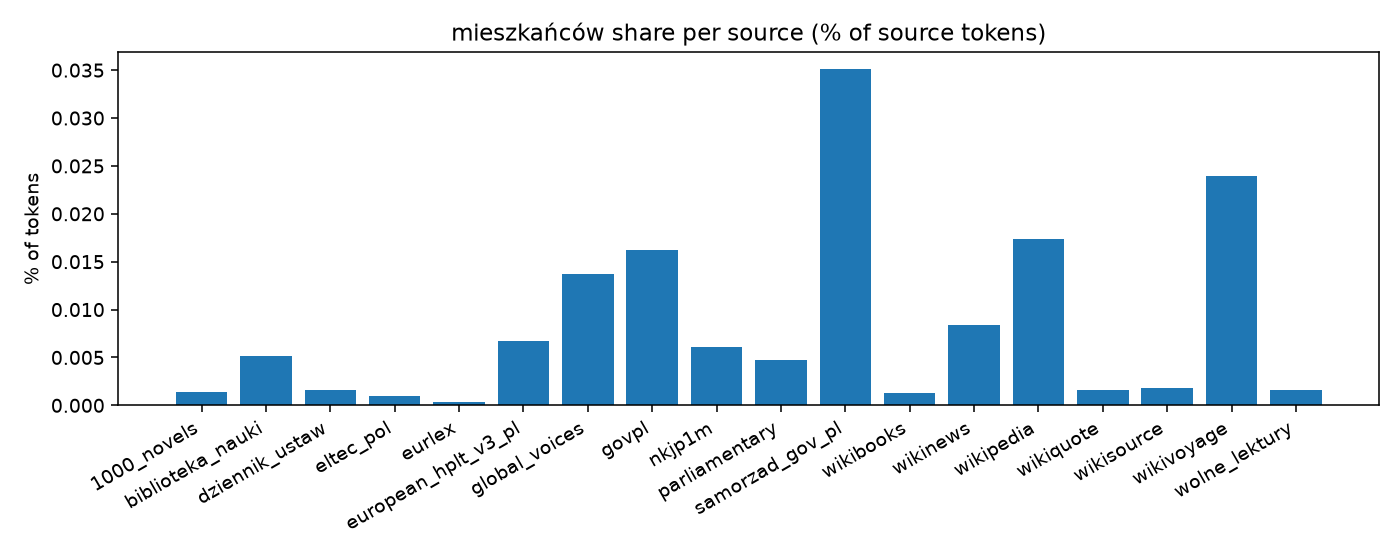
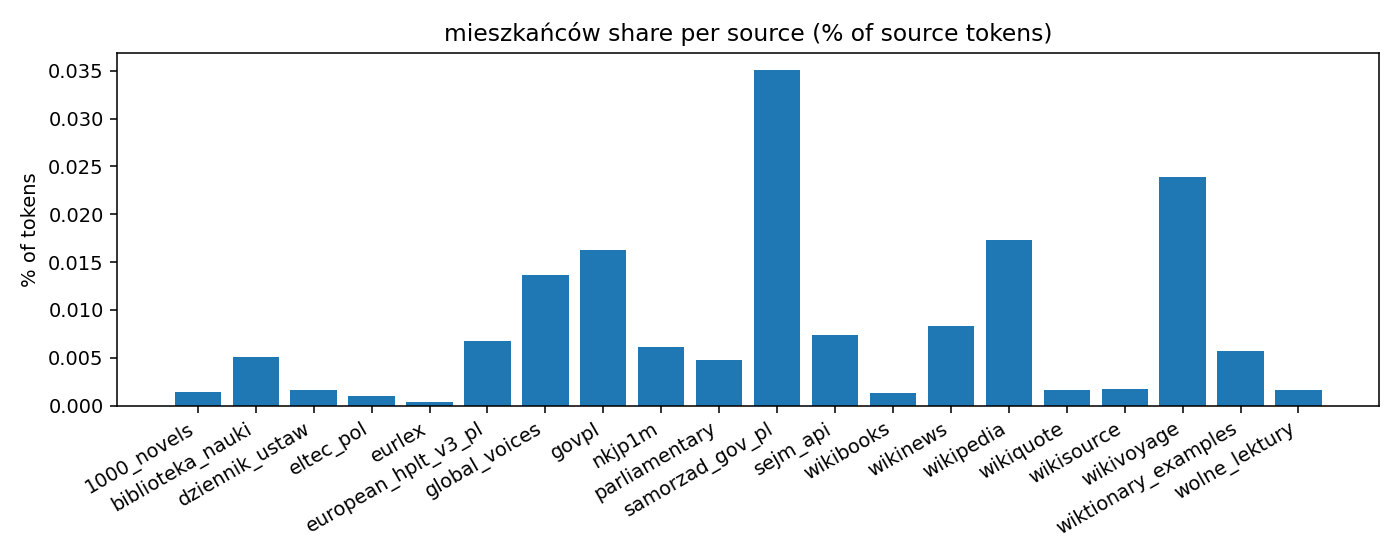
- artifacts/pattern_frequency_mieszkańców.png +2 -2
- artifacts/pattern_frequency_overall.png +2 -2
- artifacts/pattern_frequency_parlament.png +2 -2
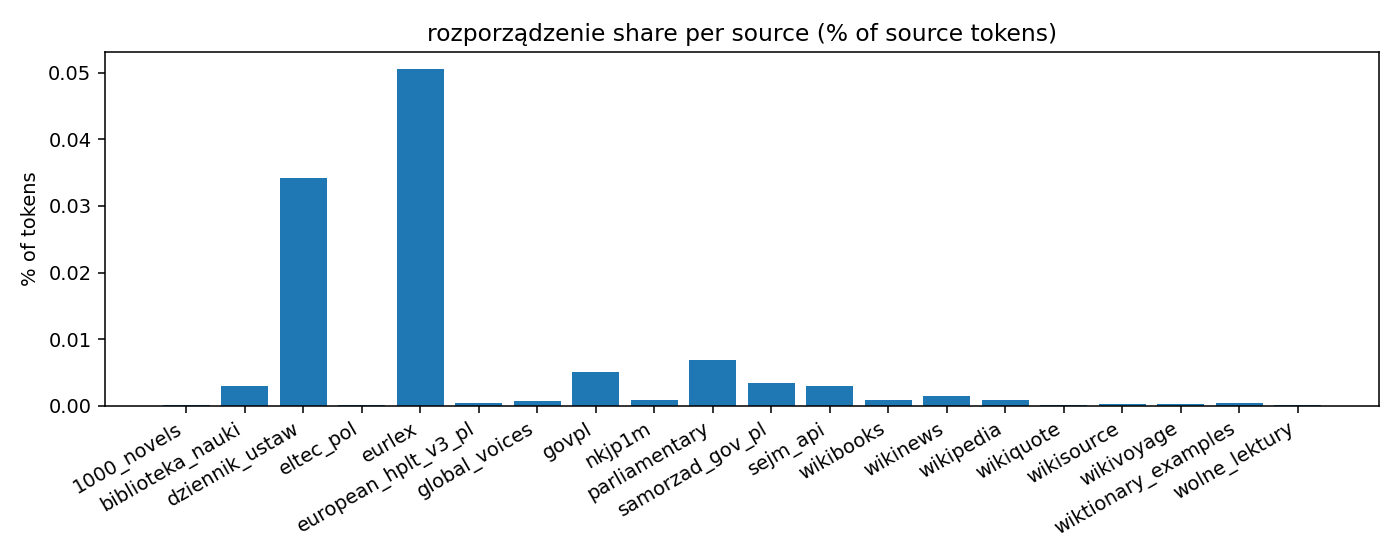
- artifacts/pattern_frequency_rozporządzenie.png +2 -2
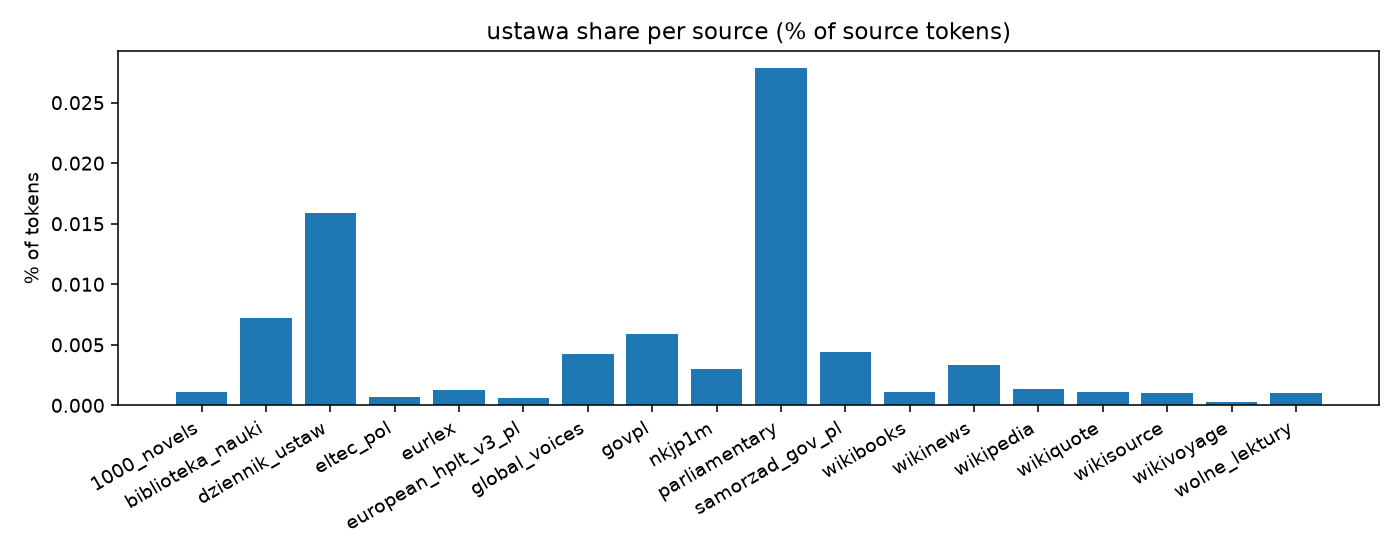
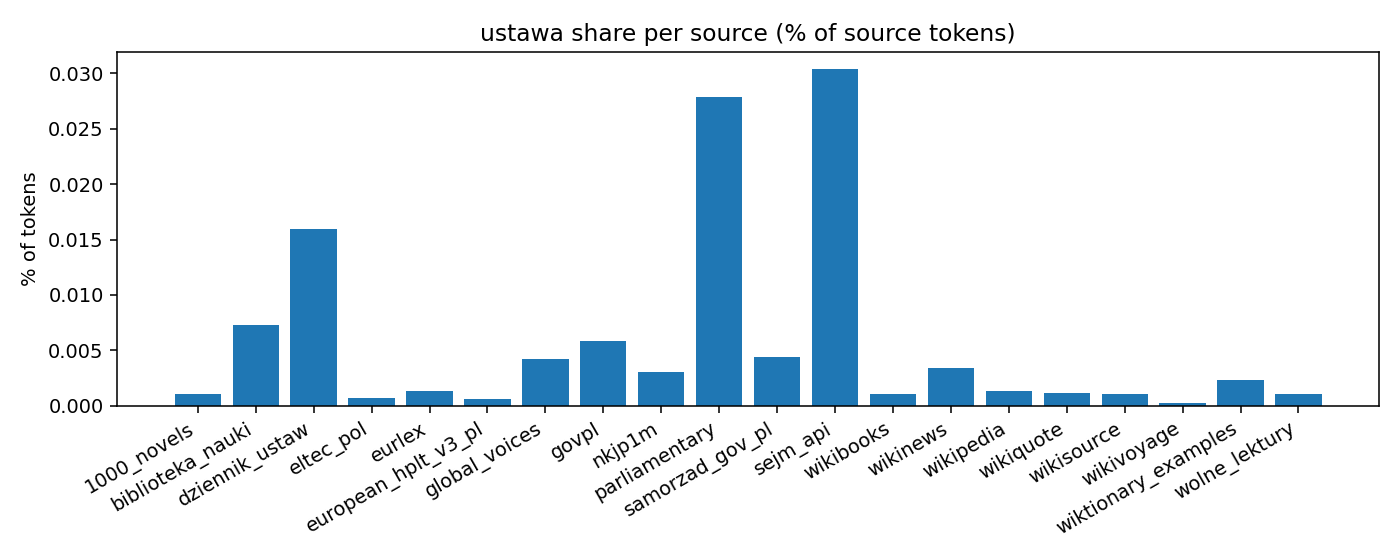
- artifacts/pattern_frequency_ustawa.png +2 -2
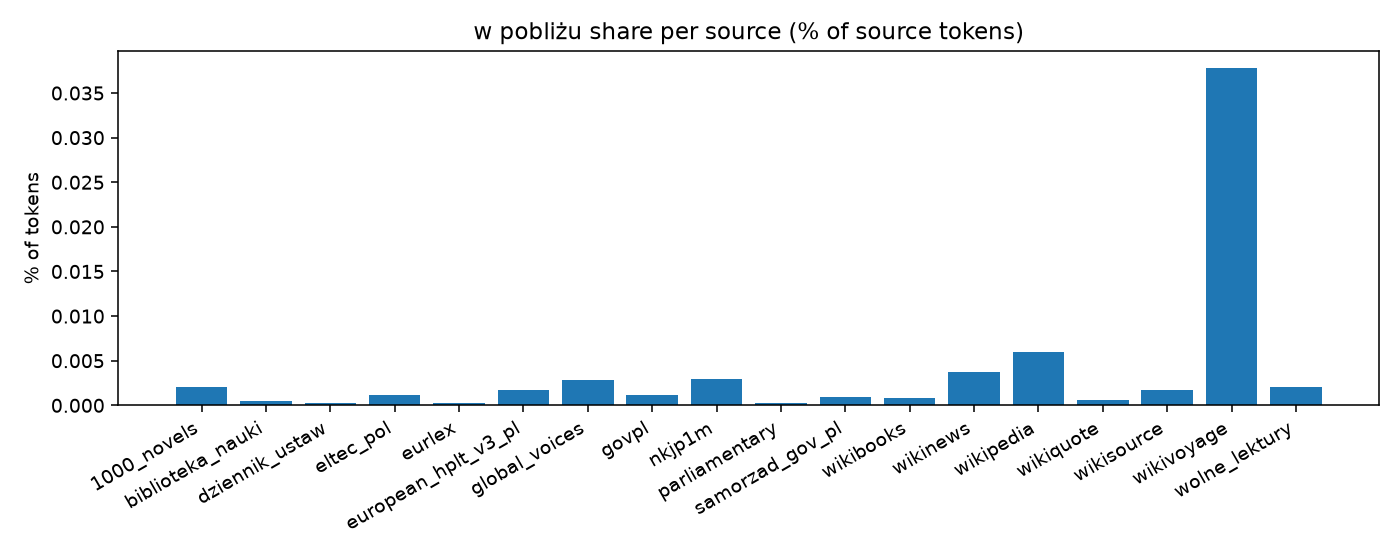
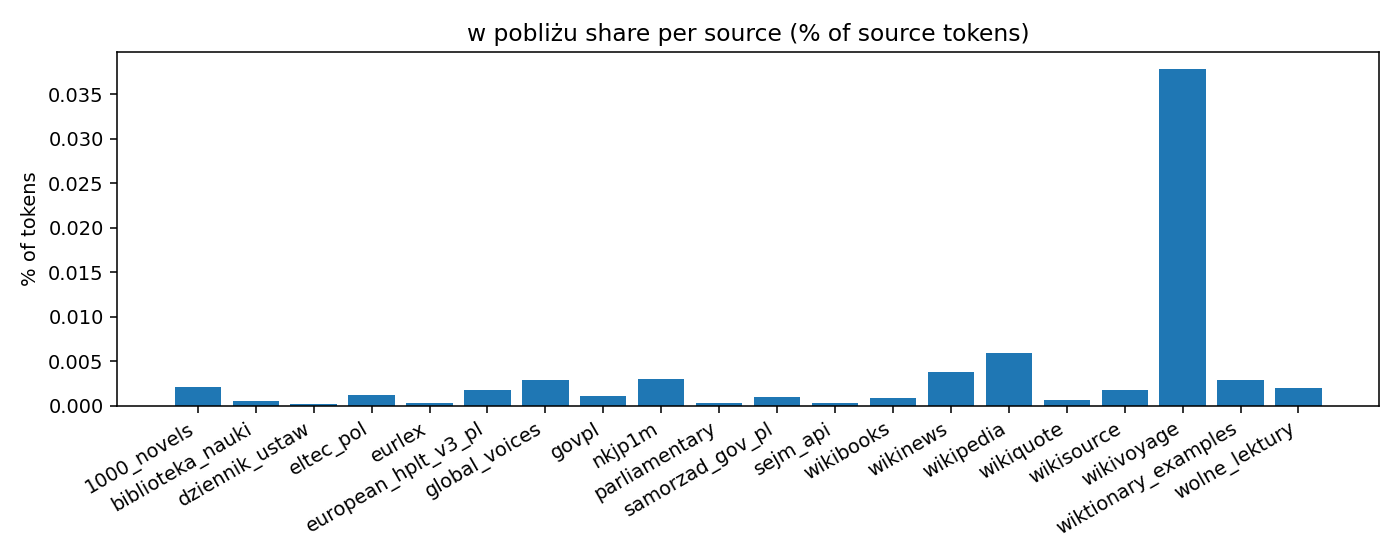
- artifacts/pattern_frequency_w_pobliżu.png +2 -2
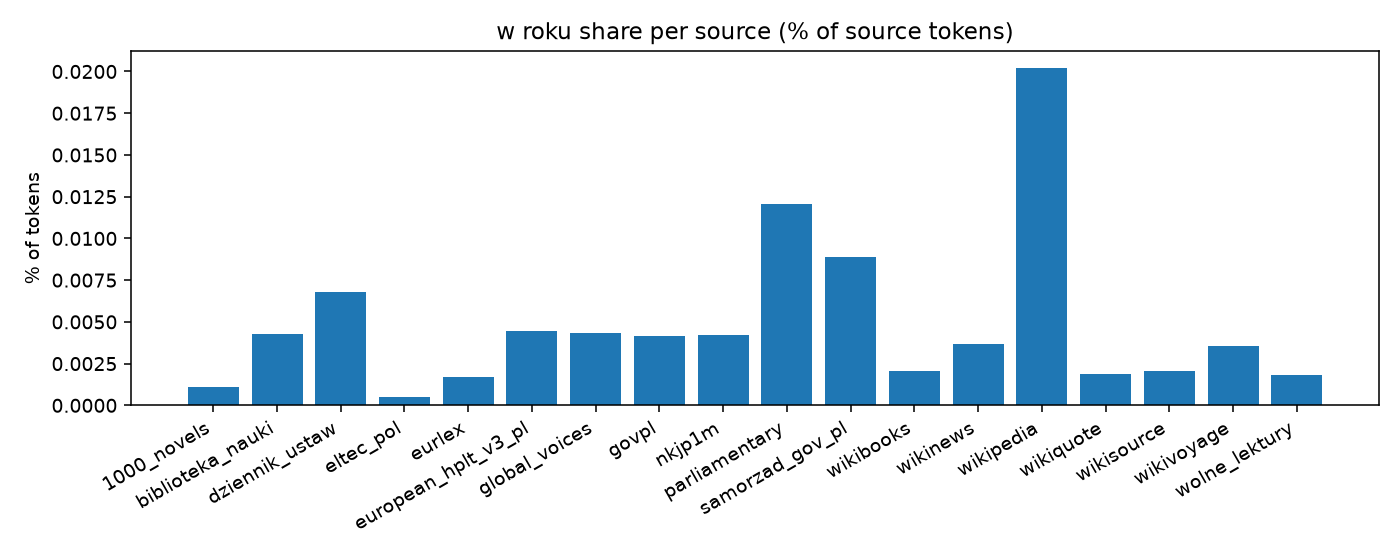
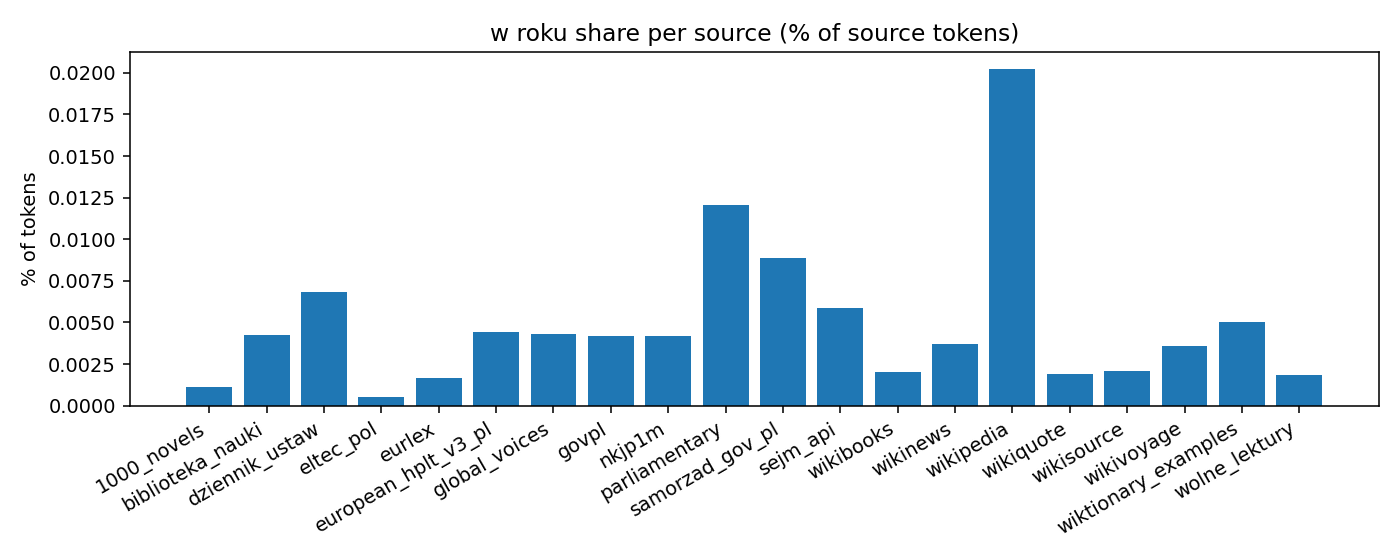
- artifacts/pattern_frequency_w_roku.png +2 -2
- pattern_frequency_report.md +28 -10
- src/make_docs.py +23 -6
- src/sources.py +6 -3
|
@@ -263,3 +263,10 @@ before staging. `*.parquet` is LFS-tracked; commit the pointer, not the blob.
|
|
| 263 |
`parlamint_pl` has one only in some working trees — it is not committed.
|
| 264 |
make_docs skips both with `! no stats`. Intentional placeholders or stale —
|
| 265 |
confirm before relying on `build_dynaword.py --all`.
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 263 |
`parlamint_pl` has one only in some working trees — it is not committed.
|
| 264 |
make_docs skips both with `! no stats`. Intentional placeholders or stale —
|
| 265 |
confirm before relying on `build_dynaword.py --all`.
|
| 266 |
+
- `european_hplt_v3_pl` keeps `release: "0.2.3"`, but its data was removed from
|
| 267 |
+
main after v0.2.5 (licence under review). make_docs skips it, so a README
|
| 268 |
+
regenerated from main undercounts every release from v0.2.3 on. Keep the
|
| 269 |
+
hand-written v0.2.5 table until the next release settles it.
|
| 270 |
+
- make_docs computes the current release's totals from main's `stats.json`, so
|
| 271 |
+
a source rebuilt after its release (`samorzad_gov_pl` v0.2, #46) shifts the
|
| 272 |
+
regenerated v0.2.5 row away from what was tagged.
|
|
@@ -2,15 +2,75 @@
|
|
| 2 |
|
| 3 |
## Unreleased (on main)
|
| 4 |
|
| 5 |
-
|
| 6 |
-
|
| 7 |
-
|
| 8 |
-
|
| 9 |
-
|
| 10 |
-
|
| 11 |
-
|
| 12 |
-
|
| 13 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 14 |
- Added the community contribution `samorzad_gov_pl` by Dawid Majewski
|
| 15 |
(`dawidmajewski`): 72,771 Polish articles / 41,154,506 cl100k-proxy tokens
|
| 16 |
from 246 local public institutions and one central platform tenant using the
|
|
@@ -27,8 +87,10 @@
|
|
| 27 |
script, contract tests, source datasheet, NOTICE and release-time license
|
| 28 |
evidence. The live shared footer script matched the audited SHA-256
|
| 29 |
`b36ec507901ed443195479d8d8009386159ae59d7486ce266bfb3308043e99aa`.
|
| 30 |
-
- Recomputed complete-corpus totals: 4,
|
| 31 |
-
cl100k-proxy tokens across
|
|
|
|
|
|
|
| 32 |
|
| 33 |
## v0.2.4 (2026-08-07)
|
| 34 |
|
|
|
|
| 2 |
|
| 3 |
## Unreleased (on main)
|
| 4 |
|
| 5 |
+
Sources on main that no release admits yet (`release: None` in
|
| 6 |
+
`src/sources.py`). None has a recorded NERGAL pass, which is required before a
|
| 7 |
+
release can admit it. Together: 17 sources, 1,331,877 documents /
|
| 8 |
+
1,262,417,311 cl100k-proxy tokens.
|
| 9 |
+
|
| 10 |
+
- `uzp_orzeczenia_pl` by Piotr Styła: 34,715 documents / 422,043,881 tokens (Hub PR #39).
|
| 11 |
+
- `plwiki_user_talk` by Piotr Styła: 380,527 documents / 381,445,111 tokens (Hub PR #40).
|
| 12 |
+
- `sejm_committee_transcripts` by Piotr Styła: 653,411 documents / 166,310,754 tokens (Hub PR #37).
|
| 13 |
+
- `sejm_api_2011_2022` by Piotr Styła: 118,902 documents / 135,072,403 tokens (Hub PR #18).
|
| 14 |
+
- `plwiki_talk` by Piotr Styła: 43,054 documents / 55,568,733 tokens (Hub PR #36).
|
| 15 |
+
- `ted_pl` by Piotr Styła: 15,544 documents / 42,475,098 tokens (Hub PR #32).
|
| 16 |
+
- `sejm_interpellations` by Paweł Puzio: 25,950 documents / 28,180,895 tokens (Hub PR #24).
|
| 17 |
+
- `nonsa` by Piotr Styła: 12,304 documents / 16,883,883 tokens (Hub PR #41).
|
| 18 |
+
- `openstax_pl` by Piotr Styła: 1,422 documents / 4,632,374 tokens (Hub PR #23).
|
| 19 |
+
- `open_icm_pl` by Piotr Styła: 85 documents / 2,358,174 tokens (Hub PR #34).
|
| 20 |
+
- `studia_bas` by gzawadzki (PR #19, landed by Piotr Styła): 112 documents / 2,256,009 tokens (Hub PR #44).
|
| 21 |
+
- `wiadomosci_statystyczne_pl` by Piotr Styła: 169 documents / 1,506,269 tokens (Hub PR #35).
|
| 22 |
+
- `rock_pollub_pl` by Piotr Styła: 8 documents / 1,177,858 tokens (Hub PR #33).
|
| 23 |
+
- `common_voice_pl` by Piotr Styła: 45,043 documents / 994,922 tokens (Hub PR #22).
|
| 24 |
+
- `edukacja_medialna_pl` by Piotr Styła: 252 documents / 728,987 tokens (Hub PR #26).
|
| 25 |
+
- `open_agh_chemistry_pl` by Piotr Styła: 370 documents / 564,028 tokens (Hub PR #25).
|
| 26 |
+
- `kultura_bez_barier_pl` by Piotr Styła: 9 documents / 217,932 tokens (Hub PR #27).
|
| 27 |
+
|
| 28 |
+
`common_voice_pl` documents are single validated sentences, all below the
|
| 29 |
+
200-character document gate; accepting sentence-level units for it is an open
|
| 30 |
+
maintainer decision (see its datasheet).
|
| 31 |
+
|
| 32 |
+
Removed from main:
|
| 33 |
+
|
| 34 |
+
- `european_hplt_v3_pl` (1,603,974 documents / 2,555,525,652 tokens in
|
| 35 |
+
v0.2.4 and v0.2.5) was removed by Arkadiusz Słota because its licence is
|
| 36 |
+
unverified; it is re-added only after review. The registry keeps its
|
| 37 |
+
`release: "0.2.3"` entry and `make_docs.py` skips it (no stats file). The
|
| 38 |
+
v0.2.4 and v0.2.5 tags still contain it.
|
| 39 |
+
|
| 40 |
+
Changed on main:
|
| 41 |
+
|
| 42 |
+
- `samorzad_gov_pl` rebuilt from the de-identified upstream v0.2 (Dawid
|
| 43 |
+
Majewski, Hub PR #15, landed as #46): 72,771 documents / 41,154,506 tokens
|
| 44 |
+
in v0.2.5 → 72,472 / 40,011,099 on main.
|
| 45 |
+
- The 19 v0.2.5 sources still on main total 2,762,378 documents /
|
| 46 |
+
7,119,844,921 tokens; all 36 sources on main total 4,094,255 documents /
|
| 47 |
+
8,382,262,232 tokens.
|
| 48 |
+
|
| 49 |
+
Tooling and process:
|
| 50 |
+
|
| 51 |
+
- PII scrubbing moved out of the repo to SlayerLab/NERGAL (#38); contextual
|
| 52 |
+
PII masking improvements (#28).
|
| 53 |
+
- Releases are tagged (#31).
|
| 54 |
+
- Source PRs are separate from releases; `src/render_sample.py` renders PR data
|
| 55 |
+
samples (#42).
|
| 56 |
+
- `build_dynaword.py` gained `preserve_id` / `preserve_created` flags (#45).
|
| 57 |
+
- The `v0.2.5` tag was re-pointed on 2026-09-29 from 02bcb0b to f71cc09, which
|
| 58 |
+
corrects the v0.2.5 documentation to 20 sources. Every file under `data/` is
|
| 59 |
+
byte-identical between the two commits.
|
| 60 |
+
|
| 61 |
+
## v0.2.5 (2026-08-14; tagged 2026-09-07)
|
| 62 |
+
|
| 63 |
+
- The v0.2.5 tag contains 20 sources: `samorzad_gov_pl`, `sejm_api` and
|
| 64 |
+
`wiktionary_examples` were added in this release. `sejm_api` and
|
| 65 |
+
`wiktionary_examples` were previously documented as built but not released
|
| 66 |
+
(`release: None` in `src/sources.py`); that was a documentation error, and
|
| 67 |
+
the registry now sets `release: "0.2.5"` for both.
|
| 68 |
+
- Added `sejm_api` by Piotr Styła: 38,812 parliamentary-speech documents
|
| 69 |
+
(2023 onward) / 36,335,587 cl100k-proxy tokens from the official Sejm API,
|
| 70 |
+
`public-domain (official documents)` (Hub PR #16).
|
| 71 |
+
- Added `wiktionary_examples` by Katarzyna Majzel-Pośpiech: 8,639 Polish
|
| 72 |
+
Wiktionary usage-example documents / 1,115,820 cl100k-proxy tokens,
|
| 73 |
+
`CC-BY-SA-3.0` (Hub PR #14).
|
| 74 |
- Added the community contribution `samorzad_gov_pl` by Dawid Majewski
|
| 75 |
(`dawidmajewski`): 72,771 Polish articles / 41,154,506 cl100k-proxy tokens
|
| 76 |
from 246 local public institutions and one central platform tenant using the
|
|
|
|
| 87 |
script, contract tests, source datasheet, NOTICE and release-time license
|
| 88 |
evidence. The live shared footer script matched the audited SHA-256
|
| 89 |
`b36ec507901ed443195479d8d8009386159ae59d7486ce266bfb3308043e99aa`.
|
| 90 |
+
- Recomputed complete-corpus totals: 4,366,651 documents and 9,676,513,980
|
| 91 |
+
cl100k-proxy tokens across 20 sources (earlier drafts of this entry gave
|
| 92 |
+
4,319,200 documents / 9,639,062,573 tokens across 18 sources, before
|
| 93 |
+
`sejm_api` and `wiktionary_examples` were counted).
|
| 94 |
|
| 95 |
## v0.2.4 (2026-08-07)
|
| 96 |
|
|
@@ -19,10 +19,15 @@ A continuously developed, **openly-licensed**, human-text Polish corpus — a Po
|
|
| 19 |
edition in the [Dynaword](https://huggingface.co/datasets/danish-foundation-models/danish-dynaword)
|
| 20 |
family (Enevoldsen et al., [arXiv:2508.02271](https://arxiv.org/abs/2508.02271)).
|
| 21 |
|
| 22 |
-
> **v0.2.5 stable** · 4,
|
| 23 |
-
> (tiktoken proxy; canonical Llama-3 count at release) ·
|
| 24 |
> Updated: **2026-08-14**
|
| 25 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 26 |
> **v0.3-dev experimental track** · quality/diversity workflow, source-gate
|
| 27 |
> validation and candidate-data audits. This is development work, not a released
|
| 28 |
> corpus version, and it does not replace the v0.2.5 stable parquets.
|
|
@@ -37,7 +42,7 @@ family (Enevoldsen et al., [arXiv:2508.02271](https://arxiv.org/abs/2508.02271))
|
|
| 37 |
|
| 38 |
| version | status | documents | tokens | notes |
|
| 39 |
|---|---|---:|---:|---|
|
| 40 |
-
| `v0.2.5` | stable release | 4,
|
| 41 |
| `v0.2.4` | previous stable | 4,246,429 | 9.60B | Expanded `european_hplt_v3_pl` to WDS bins 10-5 (+1.49M docs / 2.04B tok); phone PII-scrub hardening (independent dual-lens) + cross-source dedup (zero-overlap). |
|
| 42 |
| `v0.2.3` | previous stable | 2,710,974 | 6.88B | Adds community-contributed `european_hplt_v3_pl`, `global_voices` and `nkjp1m`. |
|
| 43 |
| `v0.2.2` | previous stable | 2,579,963 | 6.36B | Added community-contributed `govpl`: 88,190 docs / 80.7M tokens. |
|
|
@@ -57,11 +62,26 @@ family (Enevoldsen et al., [arXiv:2508.02271](https://arxiv.org/abs/2508.02271))
|
|
| 57 |
|
| 58 |
#### v0.2.5 — current stable
|
| 59 |
|
| 60 |
-
Added
|
| 61 |
-
|
| 62 |
-
|
| 63 |
-
|
| 64 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 65 |
|
| 66 |
#### v0.2.4 — previous stable
|
| 67 |
|
|
@@ -145,10 +165,13 @@ as the redistributing aggregator; this release does not claim ownership of them
|
|
| 145 |
|---|---|---|
|
| 146 |
| [Kacper Wikieł](https://huggingface.co/kacperwikiel) | Project maintainer; corpus curation, source and license review, release engineering, documentation, validation and reproducible build workflow. | all releases |
|
| 147 |
| [Bart Kobyliński](https://huggingface.co/bartoszkobylinski1) | Added `1000_novels`; expanded Biblioteka Nauki and Europeana ingestion with per-document license and author metadata. | `v0.2.1`, [PR #1](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/1) |
|
| 148 |
-
| [Paweł Puzio](https://huggingface.co/ppuzio) | Built `govpl`: subsite discovery, direct ingestion pipeline, dataset artifact, contract tests and documentation. | `v0.2.2`, [PR #9](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/9) |
|
| 149 |
| [Arkadiusz Słota](https://huggingface.co/Maggio33) | Built & expanded `european_hplt_v3_pl`: HPLT v3 WDS 10+9 (PR #5) then WDS 10-5 expansion (+1,493,384 docs / 2.04B tok), modular cleaning pipeline, phone-recall PII-scrub (v12b, independent dual-lens), cross-source dedup-vs-base (zero-overlap), validation and documentation. | `v0.2.3` (PR #5), `v0.2.4` |
|
| 150 |
-
| [Dawid Majewski](https://huggingface.co/dawidmajewski) | Added the reviewed Global Voices Polish corpus; built `samorzad_gov_pl` with direct acquisition, institution attribution, licensing evidence, release artifact and reproducible conversion. | `v0.2.3`, [PR #7](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/7); `v0.2.5` |
|
| 151 |
| [1am](https://huggingface.co/1am) | Added `nkjp1m`: the manually annotated 1-million-word NKJP subcorpus, direct fetch/build pipeline, source documentation and release artifact. | `v0.2.3`, [PR #8](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/8) |
|
|
|
|
|
|
|
|
|
|
| 152 |
|
| 153 |
Contributions are credited when they add a verifiable dataset artifact, pipeline,
|
| 154 |
validation, documentation or release work. A merged discussion with no resulting
|
|
@@ -164,7 +187,7 @@ files is not listed as a data contribution.
|
|
| 164 |
## Sources
|
| 165 |
| source | description | license | documents | tokens |
|
| 166 |
|---|---|---|---:|---:|
|
| 167 |
-
|
|
| 168 |
| [eurlex](data/eurlex/eurlex.md) | EUR-Lex (EU legal acts, Polish) | `CC-BY-4.0` | 243,060 | 2,378.1M |
|
| 169 |
| [parliamentary](data/parliamentary/parliamentary.md) | Polish Parliamentary Corpus (Sejm/Senat) | `public-domain (official documents)` | 324,622 | 1,646.8M |
|
| 170 |
| [wikisource](data/wikisource/wikisource.md) | Polish Wikisource | `CC-BY-SA-3.0` | 632,005 | 801.9M |
|
|
@@ -175,6 +198,7 @@ files is not listed as a data contribution.
|
|
| 175 |
| [govpl](data/govpl/govpl.md) | gov.pl — Polish government press releases | `CC-BY-SA-4.0` | 88,190 | 80.7M |
|
| 176 |
| [1000_novels](data/1000_novels/1000_novels.md) | 1000 Novels Corpus (CLARIN-PL) | `CC-BY-4.0` | 1,000 | 60.5M |
|
| 177 |
| [samorzad_gov_pl](data/samorzad_gov_pl/samorzad_gov_pl.md) | samorzad.gov.pl — Polish public-sector institutions | `CC-BY-SA-4.0` | 72,771 | 41.2M |
|
|
|
|
| 178 |
| [wikiquote](data/wikiquote/wikiquote.md) | Polish Wikiquote (quotations) | `CC-BY-SA-3.0` | 30,363 | 31.9M |
|
| 179 |
| [eltec_pol](data/eltec_pol/eltec_pol.md) | ELTeC-pol (European Literary Text Collection, Polish) | `CC-BY-4.0` | 100 | 21.5M |
|
| 180 |
| [wikivoyage](data/wikivoyage/wikivoyage.md) | Polish Wikivoyage (travel guides) | `CC-BY-SA-3.0` | 13,645 | 17.1M |
|
|
@@ -182,15 +206,48 @@ files is not listed as a data contribution.
|
|
| 182 |
| [wikinews](data/wikinews/wikinews.md) | Polish Wikinews | `CC-BY-2.5` | 24,386 | 12.1M |
|
| 183 |
| [global_voices](data/global_voices/global_voices.md) | Global Voices Polish | `CC-BY-3.0` | 2,040 | 3.7M |
|
| 184 |
| [nkjp1m](data/nkjp1m/nkjp1m.md) | The manually annotated 1-million word subcorpus of the National Corpus of Polish | `CC-BY` | 18,381 | 2.6M |
|
| 185 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 186 |
|
| 187 |
## Sources on main, not yet released
|
| 188 |
-
Built and documented, but **not** part of v0.2.5 and excluded from every total
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 189 |
|
| 190 |
| source | description | license | documents | tokens |
|
| 191 |
|---|---|---|---:|---:|
|
| 192 |
-
| [
|
| 193 |
-
| [
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 194 |
|
| 195 |
## Method
|
| 196 |
Only **human-authored** text — no synthetic, machine-translated, or auto-transcribed
|
|
@@ -229,10 +286,10 @@ Current v0.3 source-ingestion status:
|
|
| 229 |
- Europeana release policy: split conservatively at pre-1929 records for
|
| 230 |
US-sensitive downstream reuse, and keep later/unknown records separately
|
| 231 |
labeled or held until legal review.
|
| 232 |
-
- `european_hplt_v3_pl`: WDS bins 10-5
|
| 233 |
-
|
| 234 |
-
|
| 235 |
-
|
| 236 |
|
| 237 |
Current review artifacts:
|
| 238 |
|
|
@@ -299,21 +356,23 @@ python3 src/make_docs.py
|
|
| 299 |
|
| 300 |
### Corpus phrase frequency (normalized by tokens)
|
| 301 |
|
| 302 |
-
|
|
|
|
|
|
|
| 303 |
|
| 304 |
-
- Total token count (tiktoken proxy): **9,
|
| 305 |
|
| 306 |
| Pattern | Count | Share of all tokens |
|
| 307 |
|---|---:|---:|
|
| 308 |
-
| `w roku` |
|
| 309 |
-
| `klasyfikacji` | 164,
|
| 310 |
-
| `ustawa` |
|
| 311 |
-
| `artykuł` | 2,
|
| 312 |
-
| `parlament` | 1,
|
| 313 |
-
| `rozporządzenie` | 1,
|
| 314 |
-
| `w pobliżu` | 127,
|
| 315 |
-
| `mieszkańców` |
|
| 316 |
-
| `Dz.U.` | 987,
|
| 317 |
|
| 318 |
### Per-source shares
|
| 319 |
|
|
@@ -418,6 +477,15 @@ Raw counts and token-normalized shares are regenerated from the current Parquet
|
|
| 418 |
| `samorzad_gov_pl` | `w pobliżu` | 401 | 0.00097% |
|
| 419 |
| `samorzad_gov_pl` | `mieszkańców` | 14,450 | 0.03511% |
|
| 420 |
| `samorzad_gov_pl` | `Dz.U.` | 1,380 | 0.00335% |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 421 |
| `wikibooks` | `w roku` | 319 | 0.00205% |
|
| 422 |
| `wikibooks` | `klasyfikacji` | 37 | 0.00024% |
|
| 423 |
| `wikibooks` | `ustawa` | 165 | 0.00106% |
|
|
@@ -472,6 +540,15 @@ Raw counts and token-normalized shares are regenerated from the current Parquet
|
|
| 472 |
| `wikivoyage` | `w pobliżu` | 6,480 | 0.03783% |
|
| 473 |
| `wikivoyage` | `mieszkańców` | 4,100 | 0.02394% |
|
| 474 |
| `wikivoyage` | `Dz.U.` | 1 | 0.00001% |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 475 |
| `wolne_lektury` | `w roku` | 1,898 | 0.00184% |
|
| 476 |
| `wolne_lektury` | `klasyfikacji` | 80 | 0.00008% |
|
| 477 |
| `wolne_lektury` | `ustawa` | 1,060 | 0.00103% |
|
|
|
|
| 19 |
edition in the [Dynaword](https://huggingface.co/datasets/danish-foundation-models/danish-dynaword)
|
| 20 |
family (Enevoldsen et al., [arXiv:2508.02271](https://arxiv.org/abs/2508.02271)).
|
| 21 |
|
| 22 |
+
> **v0.2.5 stable** · 4,366,651 documents · **9.68B tokens**
|
| 23 |
+
> (tiktoken proxy; canonical Llama-3 count at release) · 20 sources
|
| 24 |
> Updated: **2026-08-14**
|
| 25 |
|
| 26 |
+
> **main, not a release (2026-09-29)** · 36 sources · 4,094,255 documents ·
|
| 27 |
+
> **8.38B tokens**: 19 of the 20 v0.2.5 sources (`european_hplt_v3_pl` withdrawn)
|
| 28 |
+
> plus 17 [sources not yet released](#sources-on-main-not-yet-released). Cite
|
| 29 |
+
> the `v0.2.5` tag, not main.
|
| 30 |
+
|
| 31 |
> **v0.3-dev experimental track** · quality/diversity workflow, source-gate
|
| 32 |
> validation and candidate-data audits. This is development work, not a released
|
| 33 |
> corpus version, and it does not replace the v0.2.5 stable parquets.
|
|
|
|
| 42 |
|
| 43 |
| version | status | documents | tokens | notes |
|
| 44 |
|---|---|---:|---:|---|
|
| 45 |
+
| `v0.2.5` | stable release | 4,366,651 | 9.68B | Adds community-contributed `samorzad_gov_pl` (institution-level author attribution and a URL-bearing attribution sidecar), `sejm_api` and `wiktionary_examples`. |
|
| 46 |
| `v0.2.4` | previous stable | 4,246,429 | 9.60B | Expanded `european_hplt_v3_pl` to WDS bins 10-5 (+1.49M docs / 2.04B tok); phone PII-scrub hardening (independent dual-lens) + cross-source dedup (zero-overlap). |
|
| 47 |
| `v0.2.3` | previous stable | 2,710,974 | 6.88B | Adds community-contributed `european_hplt_v3_pl`, `global_voices` and `nkjp1m`. |
|
| 48 |
| `v0.2.2` | previous stable | 2,579,963 | 6.36B | Added community-contributed `govpl`: 88,190 docs / 80.7M tokens. |
|
|
|
|
| 62 |
|
| 63 |
#### v0.2.5 — current stable
|
| 64 |
|
| 65 |
+
Added three sources, bringing the complete release to **20 sources,
|
| 66 |
+
4,366,651 documents / 9,676,513,980 cl100k-proxy tokens**:
|
| 67 |
+
|
| 68 |
+
- `samorzad_gov_pl`: **72,771 documents / 41,154,506 cl100k-proxy
|
| 69 |
+
tokens** from 246 Polish local public institutions and one central platform
|
| 70 |
+
tenant. The contribution preserves the publishing institution as `author`,
|
| 71 |
+
discovered and fetched article URLs in an attribution sidecar and the verified
|
| 72 |
+
platform-wide CC-BY-SA-4.0 basis.
|
| 73 |
+
- `sejm_api`: **38,812 documents / 36,335,587 cl100k-proxy tokens** of
|
| 74 |
+
parliamentary speeches (2023 onward) from the official Sejm API,
|
| 75 |
+
`public-domain (official documents)`
|
| 76 |
+
([PR #16](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/16)).
|
| 77 |
+
- `wiktionary_examples`: **8,639 documents / 1,115,820 cl100k-proxy tokens**
|
| 78 |
+
of Polish Wiktionary usage examples, one document per headword,
|
| 79 |
+
`CC-BY-SA-3.0`
|
| 80 |
+
([PR #14](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/14)).
|
| 81 |
+
|
| 82 |
+
Documentation correction: the v0.2.5 tag contains all 20 sources. Earlier
|
| 83 |
+
copies of this card counted only 18 (4,319,200 documents / 9,639,062,573
|
| 84 |
+
tokens) and listed `sejm_api` and `wiktionary_examples` as not released.
|
| 85 |
|
| 86 |
#### v0.2.4 — previous stable
|
| 87 |
|
|
|
|
| 165 |
|---|---|---|
|
| 166 |
| [Kacper Wikieł](https://huggingface.co/kacperwikiel) | Project maintainer; corpus curation, source and license review, release engineering, documentation, validation and reproducible build workflow. | all releases |
|
| 167 |
| [Bart Kobyliński](https://huggingface.co/bartoszkobylinski1) | Added `1000_novels`; expanded Biblioteka Nauki and Europeana ingestion with per-document license and author metadata. | `v0.2.1`, [PR #1](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/1) |
|
| 168 |
+
| [Paweł Puzio](https://huggingface.co/ppuzio) | Built `govpl`: subsite discovery, direct ingestion pipeline, dataset artifact, contract tests and documentation. Added `sejm_interpellations` (on main, not yet released); contributor guidance, PII scrubbing and its move to SlayerLab/NERGAL; registry-driven release totals, release tags and the source-PR/release split. | `v0.2.2`, [PR #9](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/9); [#17](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/17), [#20](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/20), [#24](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/24), [#28](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/28)–[#31](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/31), [#38](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/38), [#42](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/42) |
|
| 169 |
| [Arkadiusz Słota](https://huggingface.co/Maggio33) | Built & expanded `european_hplt_v3_pl`: HPLT v3 WDS 10+9 (PR #5) then WDS 10-5 expansion (+1,493,384 docs / 2.04B tok), modular cleaning pipeline, phone-recall PII-scrub (v12b, independent dual-lens), cross-source dedup-vs-base (zero-overlap), validation and documentation. | `v0.2.3` (PR #5), `v0.2.4` |
|
| 170 |
+
| [Dawid Majewski](https://huggingface.co/dawidmajewski) | Added the reviewed Global Voices Polish corpus; built `samorzad_gov_pl` with direct acquisition, institution attribution, licensing evidence, release artifact and reproducible conversion; prepared its de-identified upstream v0.2. | `v0.2.3`, [PR #7](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/7); `v0.2.5`, [PR #13](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/13); [PR #15](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/15) (merged via [#46](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/46)) |
|
| 171 |
| [1am](https://huggingface.co/1am) | Added `nkjp1m`: the manually annotated 1-million-word NKJP subcorpus, direct fetch/build pipeline, source documentation and release artifact. | `v0.2.3`, [PR #8](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/8) |
|
| 172 |
+
| [Piotr Styła](https://huggingface.co/PiotrSty) | Corpus preparation and contribution of `sejm_api`: parliamentary speeches from the official Sejm API with speaker attribution and immutable `PiotrSty/sejm-speeches-corpus` v1.0.1 provenance. On main, not yet released: 15 further sources (`sejm_api_2011_2022`, `common_voice_pl`, `openstax_pl`, `open_agh_chemistry_pl`, `edukacja_medialna_pl`, `kultura_bez_barier_pl`, `ted_pl`, `rock_pollub_pl`, `open_icm_pl`, `wiadomosci_statystyczne_pl`, `plwiki_talk`, `sejm_committee_transcripts`, `uzp_orzeczenia_pl`, `plwiki_user_talk`, `nonsa`); landed `studia_bas` and the `samorzad_gov_pl` v0.2 update; `build_dynaword` `preserve_id`/`preserve_created` flags. | `v0.2.5`, [PR #16](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/16); [#18](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/18), [#22](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/22), [#23](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/23), [#25](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/25)–[#27](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/27), [#32](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/32)–[#37](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/37), [#39](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/39)–[#41](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/41), [#44](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/44)–[#46](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/46) |
|
| 173 |
+
| [Katarzyna Majzel-Pośpiech](https://huggingface.co/KateMajzel) | Added `wiktionary_examples`: usage examples extracted from the Polish Wiktionary dump, one document per headword. | `v0.2.5`, [PR #14](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/14) |
|
| 174 |
+
| [gzawadzki](https://huggingface.co/gzawadzki) | Added `studia_bas`: peer-reviewed socioeconomic and public-policy articles from Studia BAS (on main, not yet released). | [PR #19](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/19) (merged via [#44](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/44)) |
|
| 175 |
|
| 176 |
Contributions are credited when they add a verifiable dataset artifact, pipeline,
|
| 177 |
validation, documentation or release work. A merged discussion with no resulting
|
|
|
|
| 187 |
## Sources
|
| 188 |
| source | description | license | documents | tokens |
|
| 189 |
|---|---|---|---:|---:|
|
| 190 |
+
| european_hplt_v3_pl *(withdrawn from main after v0.2.5, licence under review)* | HPLT v3.0 Polish (web, top WDS bins 10-5) | `CC0-1.0` | 1,603,974 | 2,555.5M |
|
| 191 |
| [eurlex](data/eurlex/eurlex.md) | EUR-Lex (EU legal acts, Polish) | `CC-BY-4.0` | 243,060 | 2,378.1M |
|
| 192 |
| [parliamentary](data/parliamentary/parliamentary.md) | Polish Parliamentary Corpus (Sejm/Senat) | `public-domain (official documents)` | 324,622 | 1,646.8M |
|
| 193 |
| [wikisource](data/wikisource/wikisource.md) | Polish Wikisource | `CC-BY-SA-3.0` | 632,005 | 801.9M |
|
|
|
|
| 198 |
| [govpl](data/govpl/govpl.md) | gov.pl — Polish government press releases | `CC-BY-SA-4.0` | 88,190 | 80.7M |
|
| 199 |
| [1000_novels](data/1000_novels/1000_novels.md) | 1000 Novels Corpus (CLARIN-PL) | `CC-BY-4.0` | 1,000 | 60.5M |
|
| 200 |
| [samorzad_gov_pl](data/samorzad_gov_pl/samorzad_gov_pl.md) | samorzad.gov.pl — Polish public-sector institutions | `CC-BY-SA-4.0` | 72,771 | 41.2M |
|
| 201 |
+
| [sejm_api](data/sejm_api/sejm_api.md) | Sejm API parliamentary speeches (2023 onward) | `public-domain (official documents)` | 38,812 | 36.3M |
|
| 202 |
| [wikiquote](data/wikiquote/wikiquote.md) | Polish Wikiquote (quotations) | `CC-BY-SA-3.0` | 30,363 | 31.9M |
|
| 203 |
| [eltec_pol](data/eltec_pol/eltec_pol.md) | ELTeC-pol (European Literary Text Collection, Polish) | `CC-BY-4.0` | 100 | 21.5M |
|
| 204 |
| [wikivoyage](data/wikivoyage/wikivoyage.md) | Polish Wikivoyage (travel guides) | `CC-BY-SA-3.0` | 13,645 | 17.1M |
|
|
|
|
| 206 |
| [wikinews](data/wikinews/wikinews.md) | Polish Wikinews | `CC-BY-2.5` | 24,386 | 12.1M |
|
| 207 |
| [global_voices](data/global_voices/global_voices.md) | Global Voices Polish | `CC-BY-3.0` | 2,040 | 3.7M |
|
| 208 |
| [nkjp1m](data/nkjp1m/nkjp1m.md) | The manually annotated 1-million word subcorpus of the National Corpus of Polish | `CC-BY` | 18,381 | 2.6M |
|
| 209 |
+
| [wiktionary_examples](data/wiktionary_examples/wiktionary_examples.md) | Polish Wiktionary usage examples | `CC-BY-SA-3.0` | 8,639 | 1.1M |
|
| 210 |
+
| **total** | | | **4,366,651** | **9,676.5M** |
|
| 211 |
+
|
| 212 |
+
This table is the v0.2.5 release as tagged (load it with `revision="v0.2.5"`).
|
| 213 |
+
Main has changed since:
|
| 214 |
+
|
| 215 |
+
- `european_hplt_v3_pl` was removed from main (licence under review; it is
|
| 216 |
+
re-added only after that review).
|
| 217 |
+
- `samorzad_gov_pl` was rebuilt from the de-identified upstream v0.2:
|
| 218 |
+
72,472 documents / 40.0M tokens
|
| 219 |
+
([PR #46](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/46), scoped from [PR #15](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/15)).
|
| 220 |
+
|
| 221 |
+
The 19 v0.2.5 sources still on main total 2,762,378 documents / 7,119.8M tokens.
|
| 222 |
|
| 223 |
## Sources on main, not yet released
|
| 224 |
+
Built and documented, but **not** part of v0.2.5 and excluded from every total
|
| 225 |
+
above. None has a recorded [NERGAL](https://huggingface.co/SlayerLab/NERGAL)
|
| 226 |
+
pass yet, which a source needs before a release can admit it (see `AGENTS.md`).
|
| 227 |
+
`common_voice_pl` documents are single validated sentences (at most 153
|
| 228 |
+
characters, below the 200-character document gate); whether sentence-level
|
| 229 |
+
units are accepted is an open maintainer decision (see its datasheet).
|
| 230 |
|
| 231 |
| source | description | license | documents | tokens |
|
| 232 |
|---|---|---|---:|---:|
|
| 233 |
+
| [uzp_orzeczenia_pl](data/uzp_orzeczenia_pl/uzp_orzeczenia_pl.md) | UZP Orzeczenia - KIO/SO/SA/SN public-procurement rulings | `public-domain (official documents)` | 34,715 | 422.0M |
|
| 234 |
+
| [plwiki_user_talk](data/plwiki_user_talk/plwiki_user_talk.md) | Polish Wikipedia user-talk pages (ns 3) | `CC BY-SA 4.0` | 380,527 | 381.4M |
|
| 235 |
+
| [sejm_committee_transcripts](data/sejm_committee_transcripts/sejm_committee_transcripts.md) | Sejm committee transcripts (terms 9-10) | `public-domain (official documents)` | 653,411 | 166.3M |
|
| 236 |
+
| [sejm_api_2011_2022](data/sejm_api_2011_2022/sejm_api_2011_2022.md) | Sejm speeches 2011-2022 (terms VII-IX, attributed) | `public-domain (official documents)` | 118,902 | 135.1M |
|
| 237 |
+
| [plwiki_talk](data/plwiki_talk/plwiki_talk.md) | Polish Wikipedia talk pages (ns 1+5) | `CC BY-SA 4.0` | 43,054 | 55.6M |
|
| 238 |
+
| [ted_pl](data/ted_pl/ted_pl.md) | TED Polish public-procurement notices | `TED notice reuse terms` | 15,544 | 42.5M |
|
| 239 |
+
| [sejm_interpellations](data/sejm_interpellations/sejm_interpellations.md) | Sejm interpellations and written questions (10th term) | `public-domain (official documents)` | 25,950 | 28.2M |
|
| 240 |
+
| [nonsa](data/nonsa/nonsa.md) | Nonsensopedia (Polish satirical wiki, content namespaces) | `CC BY-SA 3.0` | 12,304 | 16.9M |
|
| 241 |
+
| [openstax_pl](data/openstax_pl/openstax_pl.md) | OpenStax Poland - eight academic textbook volumes | `CC-BY-4.0` | 1,422 | 4.6M |
|
| 242 |
+
| [open_icm_pl](data/open_icm_pl/open_icm_pl.md) | OPEN ICM Polish open-access publications pilot | `per-record CC BY or CC BY-SA` | 85 | 2.4M |
|
| 243 |
+
| [studia_bas](data/studia_bas/studia_bas.md) | Studia BAS — peer-reviewed socioeconomic and public-policy articles | `CC-BY-3.0-PL` | 112 | 2.3M |
|
| 244 |
+
| [wiadomosci_statystyczne_pl](data/wiadomosci_statystyczne_pl/wiadomosci_statystyczne_pl.md) | Wiadomosci Statystyczne. The Polish Statistician (GUS) | `CC BY-SA 4.0` | 169 | 1.5M |
|
| 245 |
+
| [rock_pollub_pl](data/rock_pollub_pl/rock_pollub_pl.md) | ROCK Politechnika Lubelska - Polish academic books | `CC-BY-SA-4.0` | 8 | 1.2M |
|
| 246 |
+
| [common_voice_pl](data/common_voice_pl/common_voice_pl.md) | Mozilla Common Voice Polish validated sentences (v26.0) | `CC0-1.0` | 45,043 | 1.0M |
|
| 247 |
+
| [edukacja_medialna_pl](data/edukacja_medialna_pl/edukacja_medialna_pl.md) | Edukacja Medialna - Polish media-literacy lessons | `CC-BY-SA-3.0` | 252 | 0.7M |
|
| 248 |
+
| [open_agh_chemistry_pl](data/open_agh_chemistry_pl/open_agh_chemistry_pl.md) | Open AGH - four Polish chemistry textbooks | `CC-BY-SA-4.0` | 370 | 0.6M |
|
| 249 |
+
| [kultura_bez_barier_pl](data/kultura_bez_barier_pl/kultura_bez_barier_pl.md) | Kultura bez Barier PL (accessibility guides) | `CC-BY-SA-3.0` | 9 | 0.2M |
|
| 250 |
+
| **total (not released)** | | | **1,331,877** | **1,262.4M** |
|
| 251 |
|
| 252 |
## Method
|
| 253 |
Only **human-authored** text — no synthetic, machine-translated, or auto-transcribed
|
|
|
|
| 286 |
- Europeana release policy: split conservatively at pre-1929 records for
|
| 287 |
US-sensitive downstream reuse, and keep later/unknown records separately
|
| 288 |
labeled or held until legal review.
|
| 289 |
+
- `european_hplt_v3_pl`: WDS bins 10-5 shipped in v0.2.4 and v0.2.5, then the
|
| 290 |
+
data was removed from main because its licence is unverified: HPLT packaging
|
| 291 |
+
is CC0, but the underlying crawled web documents can carry independent rights.
|
| 292 |
+
It is re-added only after licence review.
|
| 293 |
|
| 294 |
Current review artifacts:
|
| 295 |
|
|
|
|
| 356 |
|
| 357 |
### Corpus phrase frequency (normalized by tokens)
|
| 358 |
|
| 359 |
+
Snapshot of the v0.2.5 release (all 20 Parquets, including
|
| 360 |
+
`european_hplt_v3_pl`), produced with `src/pattern_frequency_report.py`. It is
|
| 361 |
+
not recomputed for main; the next release regenerates it.
|
| 362 |
|
| 363 |
+
- Total token count (tiktoken proxy): **9,676,513,980**
|
| 364 |
|
| 365 |
| Pattern | Count | Share of all tokens |
|
| 366 |
|---|---:|---:|
|
| 367 |
+
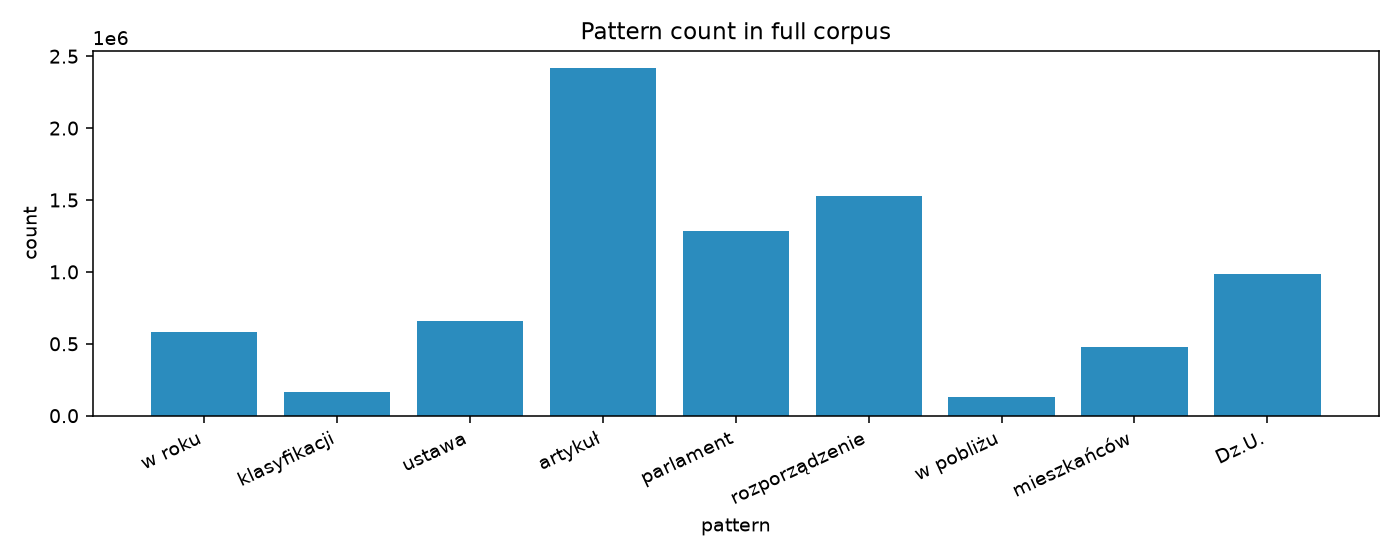
| `w roku` | 587,251 | 0.0061% |
|
| 368 |
+
| `klasyfikacji` | 164,888 | 0.0017% |
|
| 369 |
+
| `ustawa` | 670,171 | 0.0069% |
|
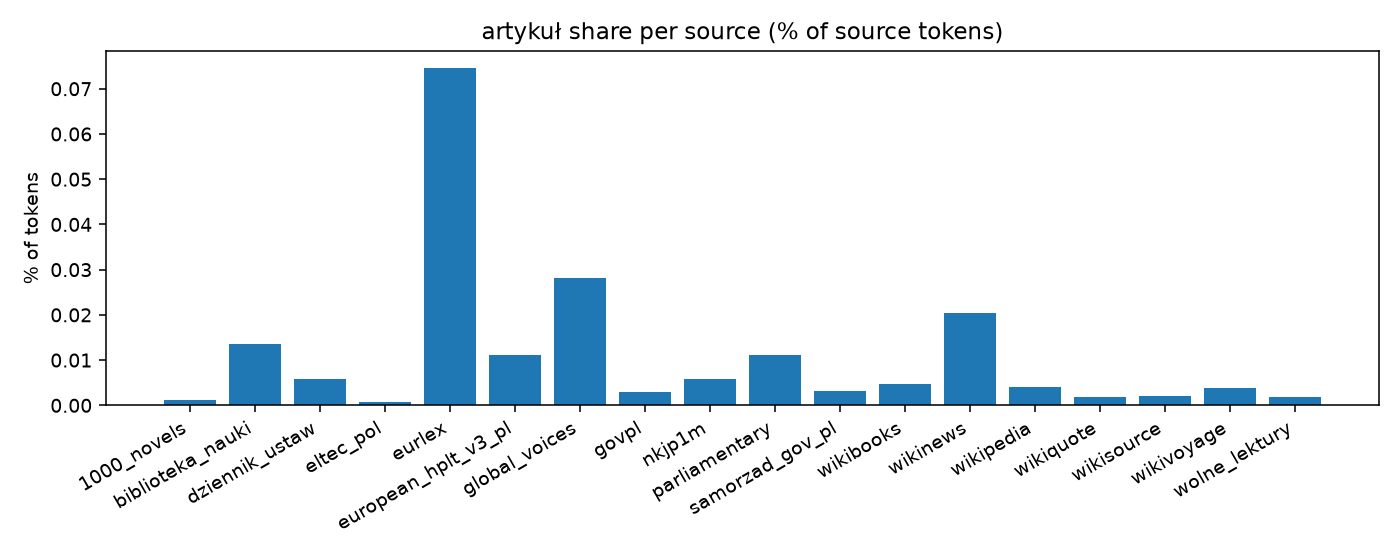
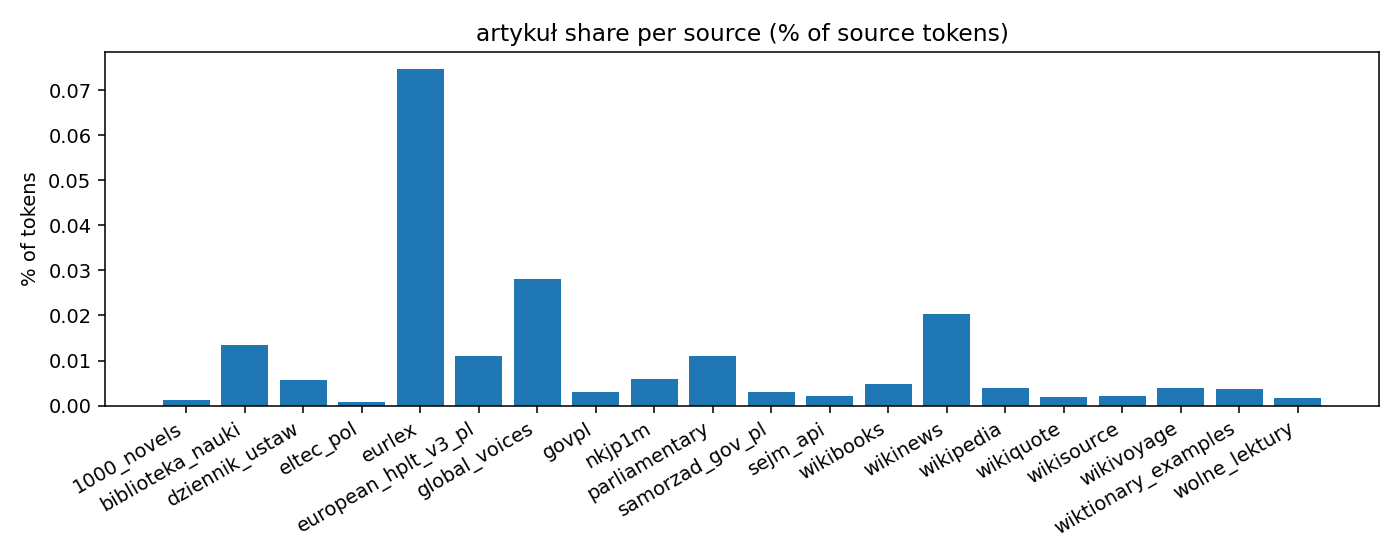
| 370 |
+
| `artykuł` | 2,417,211 | 0.0250% |
|
| 371 |
+
| `parlament` | 1,300,050 | 0.0134% |
|
| 372 |
+
| `rozporządzenie` | 1,528,556 | 0.0158% |
|
| 373 |
+
| `w pobliżu` | 127,903 | 0.0013% |
|
| 374 |
+
| `mieszkańców` | 479,471 | 0.0050% |
|
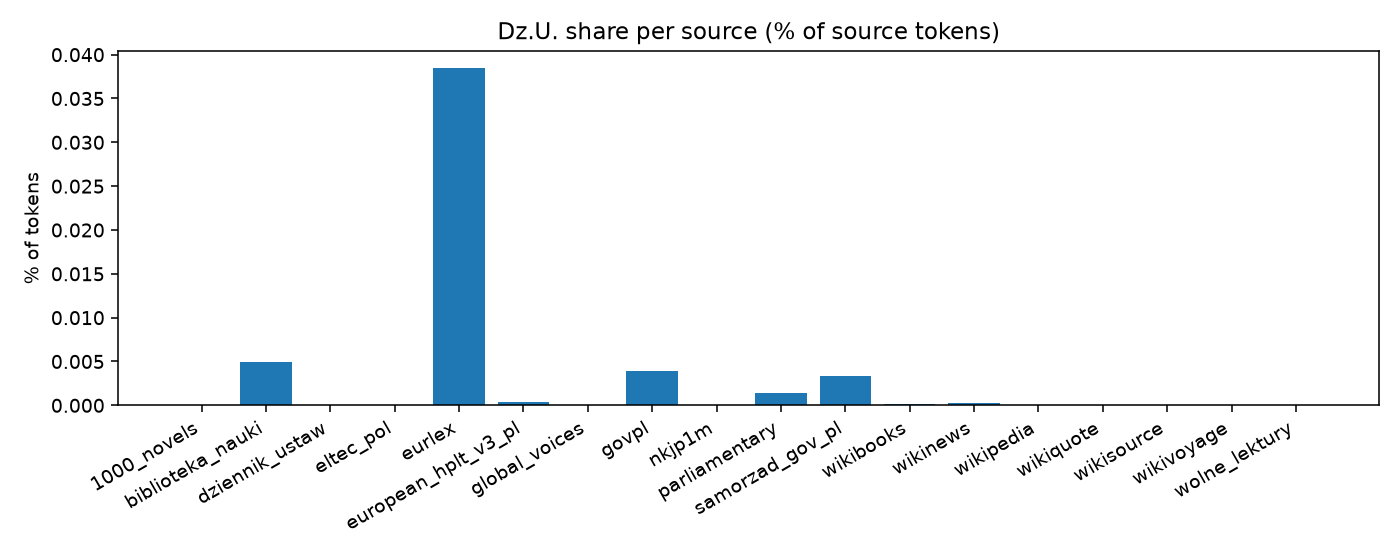
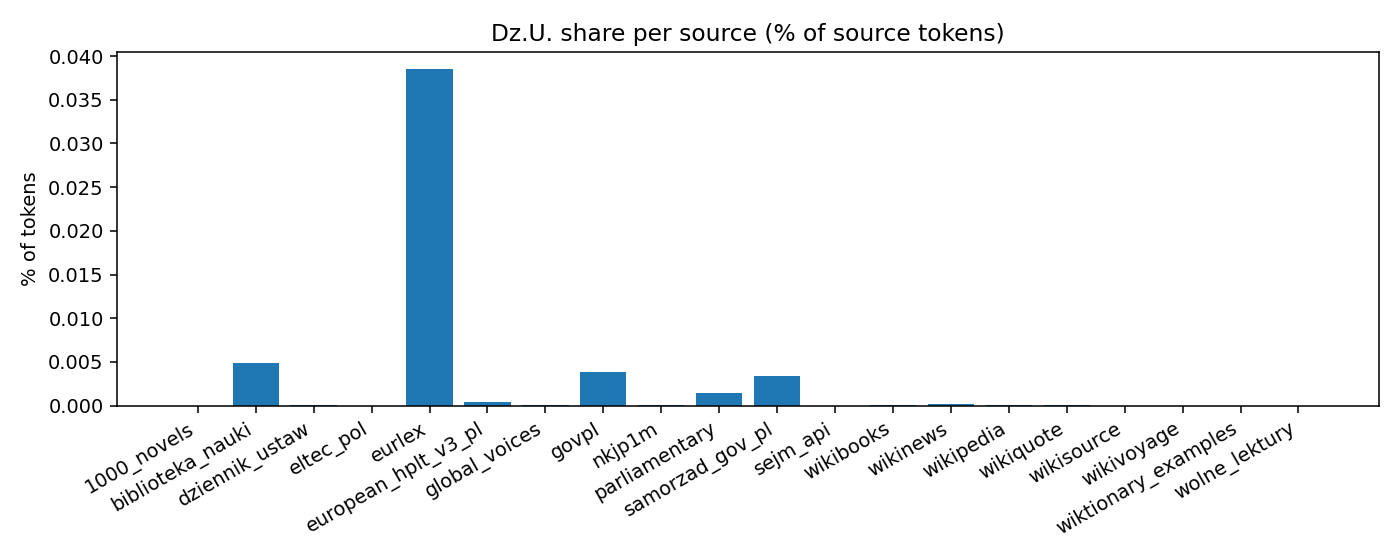
| 375 |
+
| `Dz.U.` | 987,052 | 0.0102% |
|
| 376 |
|
| 377 |
### Per-source shares
|
| 378 |
|
|
|
|
| 477 |
| `samorzad_gov_pl` | `w pobliżu` | 401 | 0.00097% |
|
| 478 |
| `samorzad_gov_pl` | `mieszkańców` | 14,450 | 0.03511% |
|
| 479 |
| `samorzad_gov_pl` | `Dz.U.` | 1,380 | 0.00335% |
|
| 480 |
+
| `sejm_api` | `w roku` | 2,123 | 0.00584% |
|
| 481 |
+
| `sejm_api` | `klasyfikacji` | 126 | 0.00035% |
|
| 482 |
+
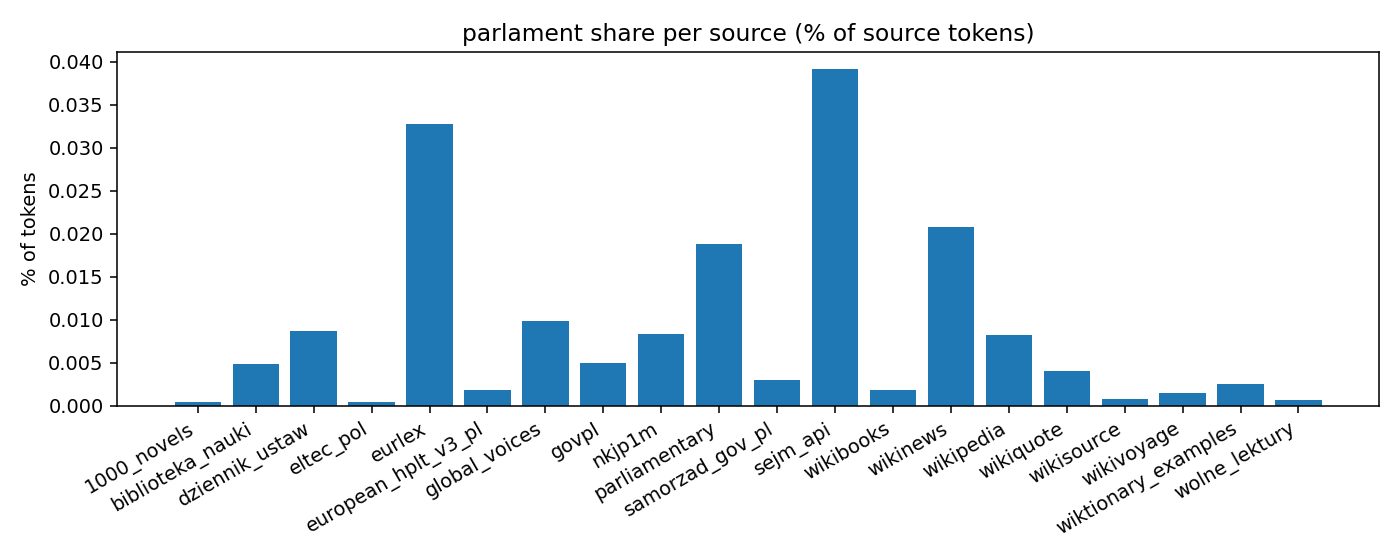
| `sejm_api` | `ustawa` | 11,042 | 0.03039% |
|
| 483 |
+
| `sejm_api` | `artykuł` | 808 | 0.00222% |
|
| 484 |
+
| `sejm_api` | `parlament` | 14,230 | 0.03916% |
|
| 485 |
+
| `sejm_api` | `rozporządzenie` | 1,095 | 0.00301% |
|
| 486 |
+
| `sejm_api` | `w pobliżu` | 87 | 0.00024% |
|
| 487 |
+
| `sejm_api` | `mieszkańców` | 2,697 | 0.00742% |
|
| 488 |
+
| `sejm_api` | `Dz.U.` | 4 | 0.00001% |
|
| 489 |
| `wikibooks` | `w roku` | 319 | 0.00205% |
|
| 490 |
| `wikibooks` | `klasyfikacji` | 37 | 0.00024% |
|
| 491 |
| `wikibooks` | `ustawa` | 165 | 0.00106% |
|
|
|
|
| 540 |
| `wikivoyage` | `w pobliżu` | 6,480 | 0.03783% |
|
| 541 |
| `wikivoyage` | `mieszkańców` | 4,100 | 0.02394% |
|
| 542 |
| `wikivoyage` | `Dz.U.` | 1 | 0.00001% |
|
| 543 |
+
| `wiktionary_examples` | `w roku` | 56 | 0.00502% |
|
| 544 |
+
| `wiktionary_examples` | `klasyfikacji` | 5 | 0.00045% |
|
| 545 |
+
| `wiktionary_examples` | `ustawa` | 26 | 0.00233% |
|
| 546 |
+
| `wiktionary_examples` | `artykuł` | 42 | 0.00376% |
|
| 547 |
+
| `wiktionary_examples` | `parlament` | 28 | 0.00251% |
|
| 548 |
+
| `wiktionary_examples` | `rozporządzenie` | 5 | 0.00045% |
|
| 549 |
+
| `wiktionary_examples` | `w pobliżu` | 32 | 0.00287% |
|
| 550 |
+
| `wiktionary_examples` | `mieszkańców` | 64 | 0.00574% |
|
| 551 |
+
| `wiktionary_examples` | `Dz.U.` | 0 | 0.00000% |
|
| 552 |
| `wolne_lektury` | `w roku` | 1,898 | 0.00184% |
|
| 553 |
| `wolne_lektury` | `klasyfikacji` | 80 | 0.00008% |
|
| 554 |
| `wolne_lektury` | `ustawa` | 1,060 | 0.00103% |
|
|
Git LFS Details
|
|
Git LFS Details
|
|
Git LFS Details
|
|
Git LFS Details
|
|
@@ -1,18 +1,18 @@
|
|
| 1 |
## Phrase frequency in corpus (token-normalized)
|
| 2 |
|
| 3 |
-
- Total token count (tiktoken proxy): **9,
|
| 4 |
|
| 5 |
| Pattern | Count | Share of all tokens |
|
| 6 |
|---|---:|---:|
|
| 7 |
-
| `w roku` |
|
| 8 |
-
| `klasyfikacji` | 164,
|
| 9 |
-
| `ustawa` |
|
| 10 |
-
| `artykuł` | 2,
|
| 11 |
-
| `parlament` | 1,
|
| 12 |
-
| `rozporządzenie` | 1,
|
| 13 |
-
| `w pobliżu` | 127,
|
| 14 |
-
| `mieszkańców` |
|
| 15 |
-
| `Dz.U.` | 987,
|
| 16 |
|
| 17 |
### Per-source shares
|
| 18 |
|
|
@@ -117,6 +117,15 @@
|
|
| 117 |
| `samorzad_gov_pl` | `w pobliżu` | 401 | 0.00097% |
|
| 118 |
| `samorzad_gov_pl` | `mieszkańców` | 14,450 | 0.03511% |
|
| 119 |
| `samorzad_gov_pl` | `Dz.U.` | 1,380 | 0.00335% |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 120 |
| `wikibooks` | `w roku` | 319 | 0.00205% |
|
| 121 |
| `wikibooks` | `klasyfikacji` | 37 | 0.00024% |
|
| 122 |
| `wikibooks` | `ustawa` | 165 | 0.00106% |
|
|
@@ -171,6 +180,15 @@
|
|
| 171 |
| `wikivoyage` | `w pobliżu` | 6,480 | 0.03783% |
|
| 172 |
| `wikivoyage` | `mieszkańców` | 4,100 | 0.02394% |
|
| 173 |
| `wikivoyage` | `Dz.U.` | 1 | 0.00001% |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 174 |
| `wolne_lektury` | `w roku` | 1,898 | 0.00184% |
|
| 175 |
| `wolne_lektury` | `klasyfikacji` | 80 | 0.00008% |
|
| 176 |
| `wolne_lektury` | `ustawa` | 1,060 | 0.00103% |
|
|
|
|
| 1 |
## Phrase frequency in corpus (token-normalized)
|
| 2 |
|
| 3 |
+
- Total token count (tiktoken proxy): **9,676,513,980**
|
| 4 |
|
| 5 |
| Pattern | Count | Share of all tokens |
|
| 6 |
|---|---:|---:|
|
| 7 |
+
| `w roku` | 587,251 | 0.0061% |
|
| 8 |
+
| `klasyfikacji` | 164,888 | 0.0017% |
|
| 9 |
+
| `ustawa` | 670,171 | 0.0069% |
|
| 10 |
+
| `artykuł` | 2,417,211 | 0.0250% |
|
| 11 |
+
| `parlament` | 1,300,050 | 0.0134% |
|
| 12 |
+
| `rozporządzenie` | 1,528,556 | 0.0158% |
|
| 13 |
+
| `w pobliżu` | 127,903 | 0.0013% |
|
| 14 |
+
| `mieszkańców` | 479,471 | 0.0050% |
|
| 15 |
+
| `Dz.U.` | 987,052 | 0.0102% |
|
| 16 |
|
| 17 |
### Per-source shares
|
| 18 |
|
|
|
|
| 117 |
| `samorzad_gov_pl` | `w pobliżu` | 401 | 0.00097% |
|
| 118 |
| `samorzad_gov_pl` | `mieszkańców` | 14,450 | 0.03511% |
|
| 119 |
| `samorzad_gov_pl` | `Dz.U.` | 1,380 | 0.00335% |
|
| 120 |
+
| `sejm_api` | `w roku` | 2,123 | 0.00584% |
|
| 121 |
+
| `sejm_api` | `klasyfikacji` | 126 | 0.00035% |
|
| 122 |
+
| `sejm_api` | `ustawa` | 11,042 | 0.03039% |
|
| 123 |
+
| `sejm_api` | `artykuł` | 808 | 0.00222% |
|
| 124 |
+
| `sejm_api` | `parlament` | 14,230 | 0.03916% |
|
| 125 |
+
| `sejm_api` | `rozporządzenie` | 1,095 | 0.00301% |
|
| 126 |
+
| `sejm_api` | `w pobliżu` | 87 | 0.00024% |
|
| 127 |
+
| `sejm_api` | `mieszkańców` | 2,697 | 0.00742% |
|
| 128 |
+
| `sejm_api` | `Dz.U.` | 4 | 0.00001% |
|
| 129 |
| `wikibooks` | `w roku` | 319 | 0.00205% |
|
| 130 |
| `wikibooks` | `klasyfikacji` | 37 | 0.00024% |
|
| 131 |
| `wikibooks` | `ustawa` | 165 | 0.00106% |
|
|
|
|
| 180 |
| `wikivoyage` | `w pobliżu` | 6,480 | 0.03783% |
|
| 181 |
| `wikivoyage` | `mieszkańców` | 4,100 | 0.02394% |
|
| 182 |
| `wikivoyage` | `Dz.U.` | 1 | 0.00001% |
|
| 183 |
+
| `wiktionary_examples` | `w roku` | 56 | 0.00502% |
|
| 184 |
+
| `wiktionary_examples` | `klasyfikacji` | 5 | 0.00045% |
|
| 185 |
+
| `wiktionary_examples` | `ustawa` | 26 | 0.00233% |
|
| 186 |
+
| `wiktionary_examples` | `artykuł` | 42 | 0.00376% |
|
| 187 |
+
| `wiktionary_examples` | `parlament` | 28 | 0.00251% |
|
| 188 |
+
| `wiktionary_examples` | `rozporządzenie` | 5 | 0.00045% |
|
| 189 |
+
| `wiktionary_examples` | `w pobliżu` | 32 | 0.00287% |
|
| 190 |
+
| `wiktionary_examples` | `mieszkańców` | 64 | 0.00574% |
|
| 191 |
+
| `wiktionary_examples` | `Dz.U.` | 0 | 0.00000% |
|
| 192 |
| `wolne_lektury` | `w roku` | 1,898 | 0.00184% |
|
| 193 |
| `wolne_lektury` | `klasyfikacji` | 80 | 0.00008% |
|
| 194 |
| `wolne_lektury` | `ustawa` | 1,060 | 0.00103% |
|
|
Git LFS Details
|
|
Git LFS Details
|
|
Git LFS Details
|
|
Git LFS Details
|
|
Git LFS Details
|
|
Git LFS Details
|
|
Git LFS Details
|
|
Git LFS Details
|

|
Git LFS Details
|
|
Git LFS Details
|
|
Git LFS Details
|
|
Git LFS Details
|
|
Git LFS Details
|
|
Git LFS Details
|
|
Git LFS Details
|
|
Git LFS Details
|
|
@@ -1,18 +1,18 @@
|
|
| 1 |
## Pattern frequency on corpus
|
| 2 |
|
| 3 |
-
- total tokens (tiktoken proxy): `9,
|
| 4 |
|
| 5 |
| pattern | count | share of all tokens |
|
| 6 |
|---|---:|---:|
|
| 7 |
-
| `w roku` |
|
| 8 |
-
| `klasyfikacji` | 164,
|
| 9 |
-
| `ustawa` |
|
| 10 |
-
| `artykuł` | 2,
|
| 11 |
-
| `parlament` | 1,
|
| 12 |
-
| `rozporządzenie` | 1,
|
| 13 |
-
| `w pobliżu` | 127,
|
| 14 |
-
| `mieszkańców` |
|
| 15 |
-
| `Dz.U.` | 987,
|
| 16 |
|
| 17 |
| source | pattern | count | per-token share |
|
| 18 |
|---|---|---:|---:|
|
|
@@ -115,6 +115,15 @@
|
|
| 115 |
| samorzad_gov_pl | `w pobliżu` | 401 | 0.00097% |
|
| 116 |
| samorzad_gov_pl | `mieszkańców` | 14,450 | 0.03511% |
|
| 117 |
| samorzad_gov_pl | `Dz.U.` | 1,380 | 0.00335% |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 118 |
| wikibooks | `w roku` | 319 | 0.00205% |
|
| 119 |
| wikibooks | `klasyfikacji` | 37 | 0.00024% |
|
| 120 |
| wikibooks | `ustawa` | 165 | 0.00106% |
|
|
@@ -169,6 +178,15 @@
|
|
| 169 |
| wikivoyage | `w pobliżu` | 6,480 | 0.03783% |
|
| 170 |
| wikivoyage | `mieszkańców` | 4,100 | 0.02394% |
|
| 171 |
| wikivoyage | `Dz.U.` | 1 | 0.00001% |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 172 |
| wolne_lektury | `w roku` | 1,898 | 0.00184% |
|
| 173 |
| wolne_lektury | `klasyfikacji` | 80 | 0.00008% |
|
| 174 |
| wolne_lektury | `ustawa` | 1,060 | 0.00103% |
|
|
|
|
| 1 |
## Pattern frequency on corpus
|
| 2 |
|
| 3 |
+
- total tokens (tiktoken proxy): `9,676,513,980`
|
| 4 |
|
| 5 |
| pattern | count | share of all tokens |
|
| 6 |
|---|---:|---:|
|
| 7 |
+
| `w roku` | 587,251 | 0.0061% |
|
| 8 |
+
| `klasyfikacji` | 164,888 | 0.0017% |
|
| 9 |
+
| `ustawa` | 670,171 | 0.0069% |
|
| 10 |
+
| `artykuł` | 2,417,211 | 0.0250% |
|
| 11 |
+
| `parlament` | 1,300,050 | 0.0134% |
|
| 12 |
+
| `rozporządzenie` | 1,528,556 | 0.0158% |
|
| 13 |
+
| `w pobliżu` | 127,903 | 0.0013% |
|
| 14 |
+
| `mieszkańców` | 479,471 | 0.0050% |
|
| 15 |
+
| `Dz.U.` | 987,052 | 0.0102% |
|
| 16 |
|
| 17 |
| source | pattern | count | per-token share |
|
| 18 |
|---|---|---:|---:|
|
|
|
|
| 115 |
| samorzad_gov_pl | `w pobliżu` | 401 | 0.00097% |
|
| 116 |
| samorzad_gov_pl | `mieszkańców` | 14,450 | 0.03511% |
|
| 117 |
| samorzad_gov_pl | `Dz.U.` | 1,380 | 0.00335% |
|
| 118 |
+
| sejm_api | `w roku` | 2,123 | 0.00584% |
|
| 119 |
+
| sejm_api | `klasyfikacji` | 126 | 0.00035% |
|
| 120 |
+
| sejm_api | `ustawa` | 11,042 | 0.03039% |
|
| 121 |
+
| sejm_api | `artykuł` | 808 | 0.00222% |
|
| 122 |
+
| sejm_api | `parlament` | 14,230 | 0.03916% |
|
| 123 |
+
| sejm_api | `rozporządzenie` | 1,095 | 0.00301% |
|
| 124 |
+
| sejm_api | `w pobliżu` | 87 | 0.00024% |
|
| 125 |
+
| sejm_api | `mieszkańców` | 2,697 | 0.00742% |
|
| 126 |
+
| sejm_api | `Dz.U.` | 4 | 0.00001% |
|
| 127 |
| wikibooks | `w roku` | 319 | 0.00205% |
|
| 128 |
| wikibooks | `klasyfikacji` | 37 | 0.00024% |
|
| 129 |
| wikibooks | `ustawa` | 165 | 0.00106% |
|
|
|
|
| 178 |
| wikivoyage | `w pobliżu` | 6,480 | 0.03783% |
|
| 179 |
| wikivoyage | `mieszkańców` | 4,100 | 0.02394% |
|
| 180 |
| wikivoyage | `Dz.U.` | 1 | 0.00001% |
|
| 181 |
+
| wiktionary_examples | `w roku` | 56 | 0.00502% |
|
| 182 |
+
| wiktionary_examples | `klasyfikacji` | 5 | 0.00045% |
|
| 183 |
+
| wiktionary_examples | `ustawa` | 26 | 0.00233% |
|
| 184 |
+
| wiktionary_examples | `artykuł` | 42 | 0.00376% |
|
| 185 |
+
| wiktionary_examples | `parlament` | 28 | 0.00251% |
|
| 186 |
+
| wiktionary_examples | `rozporządzenie` | 5 | 0.00045% |
|
| 187 |
+
| wiktionary_examples | `w pobliżu` | 32 | 0.00287% |
|
| 188 |
+
| wiktionary_examples | `mieszkańców` | 64 | 0.00574% |
|
| 189 |
+
| wiktionary_examples | `Dz.U.` | 0 | 0.00000% |
|
| 190 |
| wolne_lektury | `w roku` | 1,898 | 0.00184% |
|
| 191 |
| wolne_lektury | `klasyfikacji` | 80 | 0.00008% |
|
| 192 |
| wolne_lektury | `ustawa` | 1,060 | 0.00103% |
|
|
@@ -253,7 +253,7 @@ family (Enevoldsen et al., [arXiv:2508.02271](https://arxiv.org/abs/2508.02271))
|
|
| 253 |
|
| 254 |
| version | status | documents | tokens | notes |
|
| 255 |
|---|---|---:|---:|---|
|
| 256 |
-
| `v0.2.5` | stable release | {tot_doc:,} | {tot_tok/1e9:.2f}B | Adds community-contributed `samorzad_gov_pl`
|
| 257 |
| `v0.2.4` | previous stable | 4,246,429 | 9.60B | Expanded `european_hplt_v3_pl` to WDS bins 10-5 (+1.49M docs / 2.04B tok); phone PII-scrub hardening (independent dual-lens) + cross-source dedup (zero-overlap). |
|
| 258 |
| `v0.2.3` | previous stable | 2,710,974 | 6.88B | Adds community-contributed `european_hplt_v3_pl`, `global_voices` and `nkjp1m`. |
|
| 259 |
| `v0.2.2` | previous stable | 2,579,963 | 6.36B | Added community-contributed `govpl`: 88,190 docs / 80.7M tokens. |
|
|
@@ -273,11 +273,26 @@ family (Enevoldsen et al., [arXiv:2508.02271](https://arxiv.org/abs/2508.02271))
|
|
| 273 |
|
| 274 |
#### v0.2.5 — current stable
|
| 275 |
|
| 276 |
-
Added
|
| 277 |
-
|
| 278 |
-
|
| 279 |
-
|
| 280 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 281 |
|
| 282 |
#### v0.2.4 — previous stable
|
| 283 |
|
|
@@ -365,6 +380,8 @@ as the redistributing aggregator; this release does not claim ownership of them
|
|
| 365 |
| [Arkadiusz Słota](https://huggingface.co/Maggio33) | Built & expanded `european_hplt_v3_pl`: HPLT v3 WDS 10+9 (PR #5) then WDS 10-5 expansion (+1,493,384 docs / 2.04B tok), modular cleaning pipeline, phone-recall PII-scrub (v12b, independent dual-lens), cross-source dedup-vs-base (zero-overlap), validation and documentation. | `v0.2.3` (PR #5), `v0.2.4` |
|
| 366 |
| [Dawid Majewski](https://huggingface.co/dawidmajewski) | Added the reviewed Global Voices Polish corpus; built `samorzad_gov_pl` with direct acquisition, institution attribution, licensing evidence, release artifact and reproducible conversion. | `v0.2.3`, [PR #7](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/7); `v0.2.5` |
|
| 367 |
| [1am](https://huggingface.co/1am) | Added `nkjp1m`: the manually annotated 1-million-word NKJP subcorpus, direct fetch/build pipeline, source documentation and release artifact. | `v0.2.3`, [PR #8](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/8) |
|
|
|
|
|
|
|
| 368 |
|
| 369 |
Contributions are credited when they add a verifiable dataset artifact, pipeline,
|
| 370 |
validation, documentation or release work. A merged discussion with no resulting
|
|
|
|
| 253 |
|
| 254 |
| version | status | documents | tokens | notes |
|
| 255 |
|---|---|---:|---:|---|
|
| 256 |
+
| `v0.2.5` | stable release | {tot_doc:,} | {tot_tok/1e9:.2f}B | Adds community-contributed `samorzad_gov_pl` (institution-level author attribution and a URL-bearing attribution sidecar), `sejm_api` and `wiktionary_examples`. |
|
| 257 |
| `v0.2.4` | previous stable | 4,246,429 | 9.60B | Expanded `european_hplt_v3_pl` to WDS bins 10-5 (+1.49M docs / 2.04B tok); phone PII-scrub hardening (independent dual-lens) + cross-source dedup (zero-overlap). |
|
| 258 |
| `v0.2.3` | previous stable | 2,710,974 | 6.88B | Adds community-contributed `european_hplt_v3_pl`, `global_voices` and `nkjp1m`. |
|
| 259 |
| `v0.2.2` | previous stable | 2,579,963 | 6.36B | Added community-contributed `govpl`: 88,190 docs / 80.7M tokens. |
|
|
|
|
| 273 |
|
| 274 |
#### v0.2.5 — current stable
|
| 275 |
|
| 276 |
+
Added three sources, bringing the complete release to **20 sources,
|
| 277 |
+
4,366,651 documents / 9,676,513,980 cl100k-proxy tokens**:
|
| 278 |
+
|
| 279 |
+
- `samorzad_gov_pl`: **72,771 documents / 41,154,506 cl100k-proxy
|
| 280 |
+
tokens** from 246 Polish local public institutions and one central platform
|
| 281 |
+
tenant. The contribution preserves the publishing institution as `author`,
|
| 282 |
+
discovered and fetched article URLs in an attribution sidecar and the verified
|
| 283 |
+
platform-wide CC-BY-SA-4.0 basis.
|
| 284 |
+
- `sejm_api`: **38,812 documents / 36,335,587 cl100k-proxy tokens** of
|
| 285 |
+
parliamentary speeches (2023 onward) from the official Sejm API,
|
| 286 |
+
`public-domain (official documents)`
|
| 287 |
+
([PR #16](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/16)).
|
| 288 |
+
- `wiktionary_examples`: **8,639 documents / 1,115,820 cl100k-proxy tokens**
|
| 289 |
+
of Polish Wiktionary usage examples, one document per headword,
|
| 290 |
+
`CC-BY-SA-3.0`
|
| 291 |
+
([PR #14](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/14)).
|
| 292 |
+
|
| 293 |
+
Documentation correction: the v0.2.5 tag contains all 20 sources. Earlier
|
| 294 |
+
copies of this card counted only 18 (4,319,200 documents / 9,639,062,573
|
| 295 |
+
tokens) and listed `sejm_api` and `wiktionary_examples` as not released.
|
| 296 |
|
| 297 |
#### v0.2.4 — previous stable
|
| 298 |
|
|
|
|
| 380 |
| [Arkadiusz Słota](https://huggingface.co/Maggio33) | Built & expanded `european_hplt_v3_pl`: HPLT v3 WDS 10+9 (PR #5) then WDS 10-5 expansion (+1,493,384 docs / 2.04B tok), modular cleaning pipeline, phone-recall PII-scrub (v12b, independent dual-lens), cross-source dedup-vs-base (zero-overlap), validation and documentation. | `v0.2.3` (PR #5), `v0.2.4` |
|
| 381 |
| [Dawid Majewski](https://huggingface.co/dawidmajewski) | Added the reviewed Global Voices Polish corpus; built `samorzad_gov_pl` with direct acquisition, institution attribution, licensing evidence, release artifact and reproducible conversion. | `v0.2.3`, [PR #7](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/7); `v0.2.5` |
|
| 382 |
| [1am](https://huggingface.co/1am) | Added `nkjp1m`: the manually annotated 1-million-word NKJP subcorpus, direct fetch/build pipeline, source documentation and release artifact. | `v0.2.3`, [PR #8](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/8) |
|
| 383 |
+
| Piotr Styła (HF: `PiotrSty`) | Corpus preparation and contribution of `sejm_api`: parliamentary speeches from the official Sejm API with speaker attribution and immutable `PiotrSty/sejm-speeches-corpus` v1.0.1 provenance. | `v0.2.5`, [PR #16](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/16) |
|
| 384 |
+
| Katarzyna Majzel-Pośpiech | Added `wiktionary_examples`: usage examples extracted from the Polish Wiktionary dump, one document per headword. | `v0.2.5`, [PR #14](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/14) |
|
| 385 |
|
| 386 |
Contributions are credited when they add a verifiable dataset artifact, pipeline,
|
| 387 |
validation, documentation or release work. A merged discussion with no resulting
|
|
@@ -80,7 +80,8 @@ SOURCES = {
|
|
| 80 |
"is_ocr": False,
|
| 81 |
"custom_datasheet": True,
|
| 82 |
},
|
| 83 |
-
'rock_pollub_pl': {'
|
|
|
|
| 84 |
'pretty': 'ROCK Politechnika Lubelska - Polish academic books',
|
| 85 |
'license': 'CC-BY-SA-4.0',
|
| 86 |
'license_spdx': 'CC-BY-SA-4.0',
|
|
@@ -140,7 +141,7 @@ SOURCES = {
|
|
| 140 |
},
|
| 141 |
"wiktionary_examples": {
|
| 142 |
"added": "2026-07-19",
|
| 143 |
-
"release":
|
| 144 |
"file_key": "wiktionary_examples",
|
| 145 |
"pretty": "Polish Wiktionary usage examples",
|
| 146 |
"provenance": "Parsed directly from the official Wikimedia dump "
|
|
@@ -214,7 +215,7 @@ SOURCES = {
|
|
| 214 |
"sejm_api": {
|
| 215 |
"added": "2026-08-22",
|
| 216 |
"custom_datasheet": True,
|
| 217 |
-
"release":
|
| 218 |
"file_key": "sejm_api",
|
| 219 |
"pretty": "Sejm API parliamentary speeches (2023 onward)",
|
| 220 |
"license": "public-domain (official documents)",
|
|
@@ -647,6 +648,8 @@ SOURCES = {
|
|
| 647 |
"created": "1957-2008 (recorded for 6,581 of 18,381 documents; per-document in the created column)",
|
| 648 |
"is_ocr": False,
|
| 649 |
},
|
|
|
|
|
|
|
| 650 |
"european_hplt_v3_pl": {
|
| 651 |
"added": "2026-07-14",
|
| 652 |
"release": "0.2.3",
|
|
|
|
| 80 |
"is_ocr": False,
|
| 81 |
"custom_datasheet": True,
|
| 82 |
},
|
| 83 |
+
'rock_pollub_pl': {'added': '2026-09-08',
|
| 84 |
+
'file_key': 'rock_pollub_pl',
|
| 85 |
'pretty': 'ROCK Politechnika Lubelska - Polish academic books',
|
| 86 |
'license': 'CC-BY-SA-4.0',
|
| 87 |
'license_spdx': 'CC-BY-SA-4.0',
|
|
|
|
| 141 |
},
|
| 142 |
"wiktionary_examples": {
|
| 143 |
"added": "2026-07-19",
|
| 144 |
+
"release": "0.2.5",
|
| 145 |
"file_key": "wiktionary_examples",
|
| 146 |
"pretty": "Polish Wiktionary usage examples",
|
| 147 |
"provenance": "Parsed directly from the official Wikimedia dump "
|
|
|
|
| 215 |
"sejm_api": {
|
| 216 |
"added": "2026-08-22",
|
| 217 |
"custom_datasheet": True,
|
| 218 |
+
"release": "0.2.5",
|
| 219 |
"file_key": "sejm_api",
|
| 220 |
"pretty": "Sejm API parliamentary speeches (2023 onward)",
|
| 221 |
"license": "public-domain (official documents)",
|
|
|
|
| 648 |
"created": "1957-2008 (recorded for 6,581 of 18,381 documents; per-document in the created column)",
|
| 649 |
"is_ocr": False,
|
| 650 |
},
|
| 651 |
+
# Data removed from main after v0.2.5 (licence under review); the v0.2.4 and
|
| 652 |
+
# v0.2.5 tags still contain it. No stats file on main, so make_docs skips it.
|
| 653 |
"european_hplt_v3_pl": {
|
| 654 |
"added": "2026-07-14",
|
| 655 |
"release": "0.2.3",
|