
Datasets:


feat(data): update samorzad_gov_pl to upstream v0.2
Browse files# Update `samorzad_gov_pl` to de-identified upstream v0.2
## Summary
This PR updates the existing `samorzad_gov_pl` component from the published v0.2 release of [`dawidmajewski/samorzad-gov-pl-articles`](https://huggingface.co/datasets/dawidmajewski/samorzad-gov-pl-articles).
The rebuilt DynaWord source contains:
- 72,472 documents;
- 107,130,266 characters;
- 40,011,099 `cl100k_base` proxy tokens;
- institution-level `author` values for all retained documents;
- one-to-one attribution records with de-identified titles and canonical source URLs.
No other source Parquet is changed.
## Source update and de-identification
The converter now pins upstream revision:
`a998efea84bb0a62d94effc0b54f88b422d9898f`
and verifies the release manifest SHA-256, all 10 Parquet shards, schema, row counts, unique IDs and release-wide record-text digest before conversion.
The v0.2 source release de-identifies consumer-facing text before DynaWord filtering. It uses the pinned [`ArkadiuszPawlak/fastpdn-ner-polish-pii`](https://huggingface.co/ArkadiuszPawlak/fastpdn-ner-polish-pii) model at revision `636c57fe77b0afad8f065e7c76243dc051437035`, together with deterministic rules and checksum validation for contact data and structured identifiers. Removed values are represented by typed placeholders.
The upstream release audit scanned all 81,418 records for structured residuals, reran the PERSON model on an evenly spaced 1,000-record sample, validated placeholder structure and verified provenance against the pinned source manifest. Four corrupted source records were excluded before publication.
## DynaWord filtering
From 81,418 upstream records, the conversion removes:
- 6,932 documents shorter than 200 characters;
- 34 documents below the existing Polish-language heuristic;
- 1,980 exact-text duplicates.
The resulting source contains 72,472 documents. Retained text is an exact subset of the de-identified upstream release after trimming leading and trailing whitespace.
## Release integration
This PR prepares v0.2.6 and updates:
- the source converter, pinned release contract and contract tests;
- the Parquet artifact, attribution sidecar and statistics;
- the source datasheet and attribution notice;
- README totals, version history, changelog and contributor credit;
- complete-corpus phrase-frequency reports and plots.
New stable totals:
- 4,327,540 documents;
- 9,639,034,986 `cl100k_base` proxy tokens;
- 19 sources.
The source count now includes the already merged `wiktionary_examples` artifact in the stable release totals.
## Verification
- `15 passed` in the complete `src/` pytest suite;
- Ruff checks passed for the changed Python code, excluding two pre-existing repository-wide import/executable-bit rules;
- all 72,472 retained texts match the pinned de-identified upstream records exactly;
- all 72,472 attribution entries align one-to-one with Parquet IDs, titles and institution authors;
- zero malformed, unknown, nested or in-word de-identification placeholders;
- zero internal exact-text duplicates and zero exact-text overlap with the other 18 source Parquets;
- canonical eight-column DynaWord schema, unique deterministic IDs, positive token counts and complete institution authors;
- complete-corpus totals recomputed from all 19 source statistics and Parquets;
- a second full conversion produced identical artifact hashes;
- `git diff --check` passed and no local paths, credentials or network addresses appear in the textual diff.
Artifact SHA-256:
- Parquet: `3a683b4220b9b70698d7c524637d9ea5c1d72630b8f92ea7a871642a719cf2c0`;
- attribution sidecar: `2def7488c34e749204842bcf21d33149738b34de2515115e3f79401f7eb271c4`;
- statistics: `eb17463e79ed4ff03694f17773372311a8a576d393244b26d27486096025fd4c`;
- pinned upstream manifest: `9d349bb271033fef62a051e311115460e030740f9593bb7f3158cb1437f87639`.
- CHANGELOG.md +23 -3
- README.md +53 -35
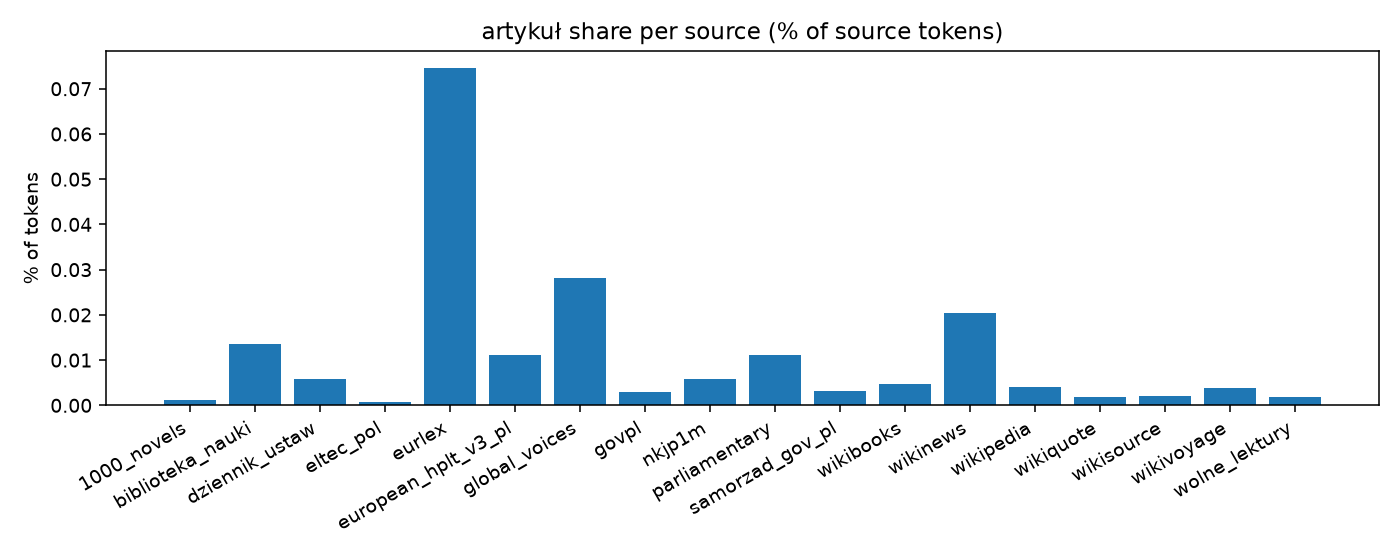
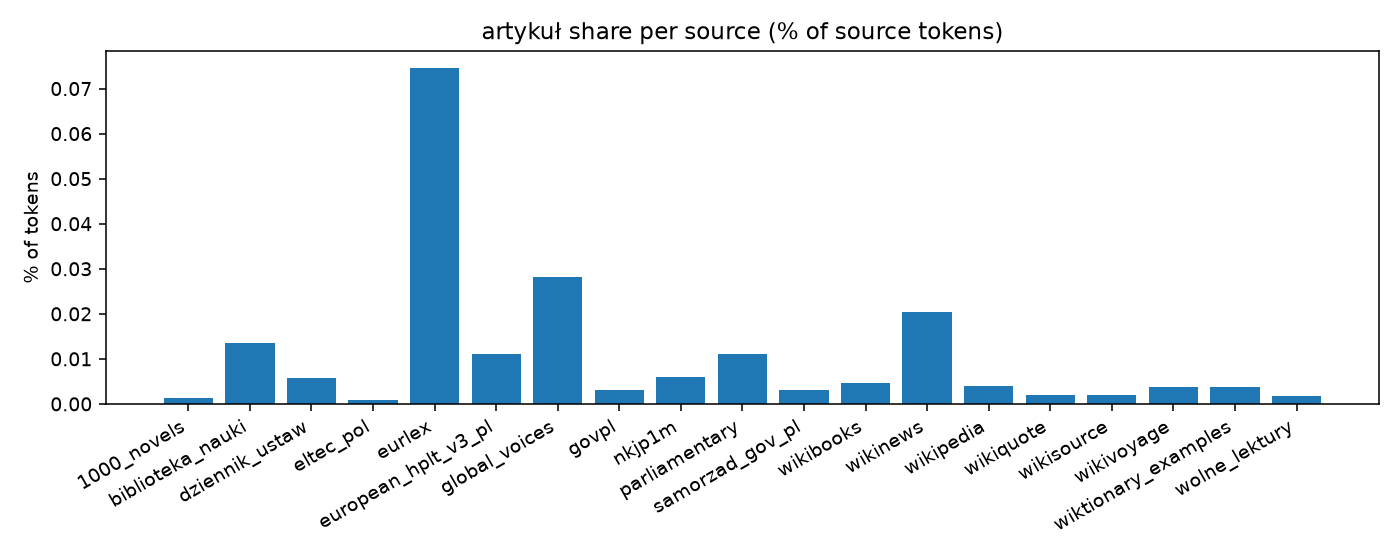
- artifacts/pattern_frequency_artykul.png +2 -2
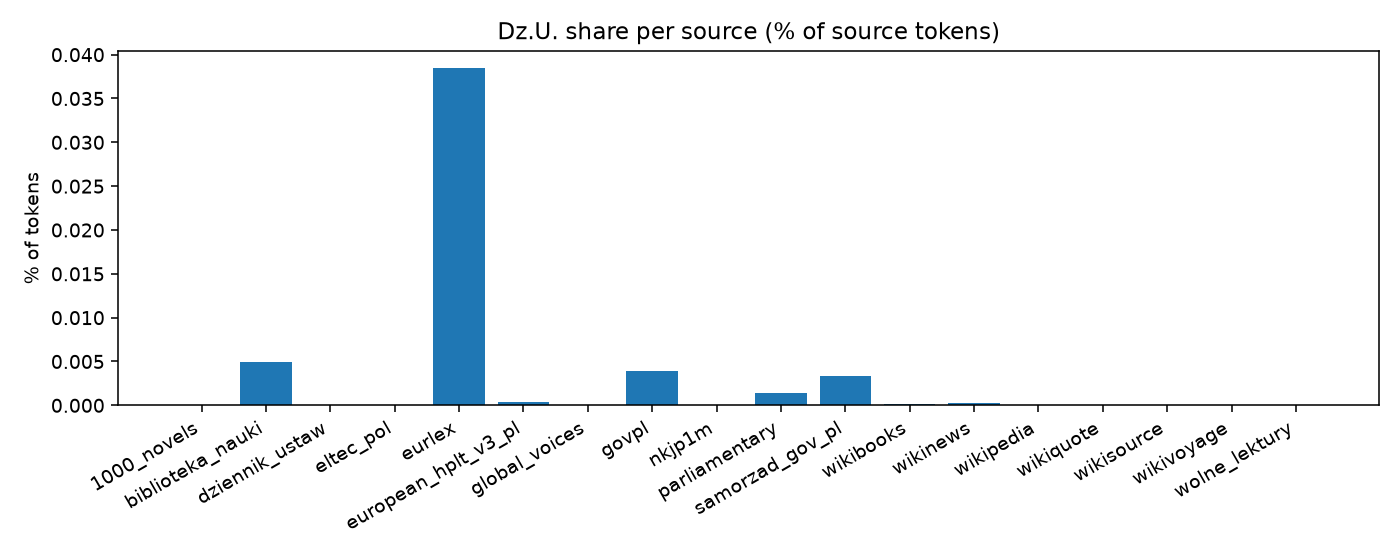
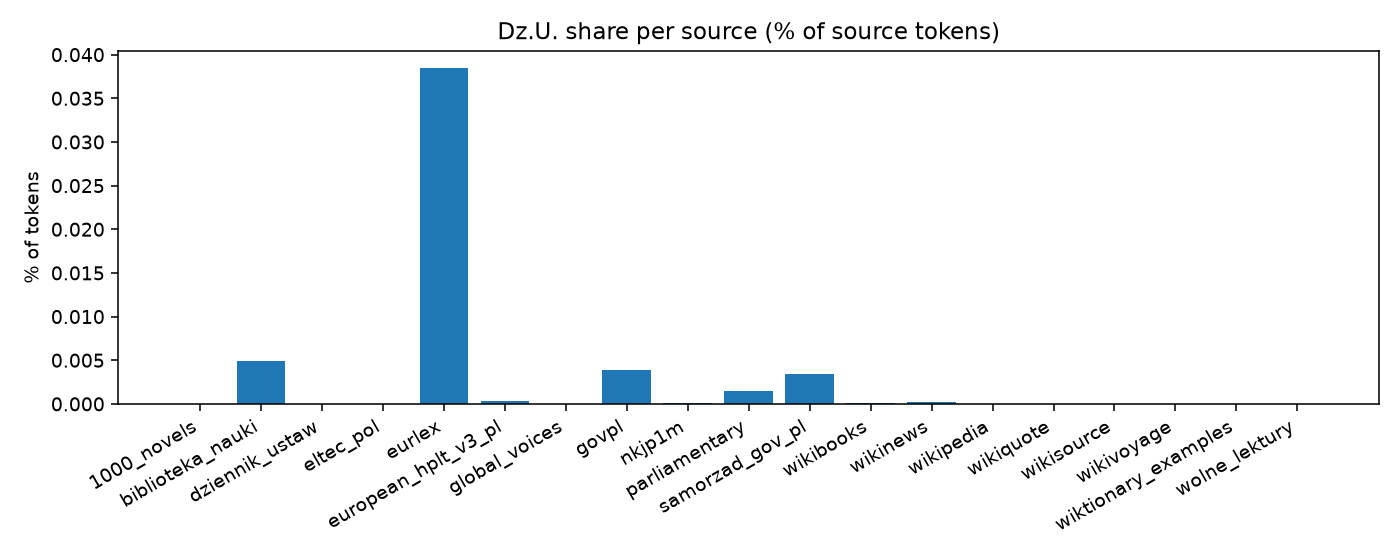
- artifacts/pattern_frequency_dzu.png +2 -2
- artifacts/pattern_frequency_hf_snippet.md +27 -18
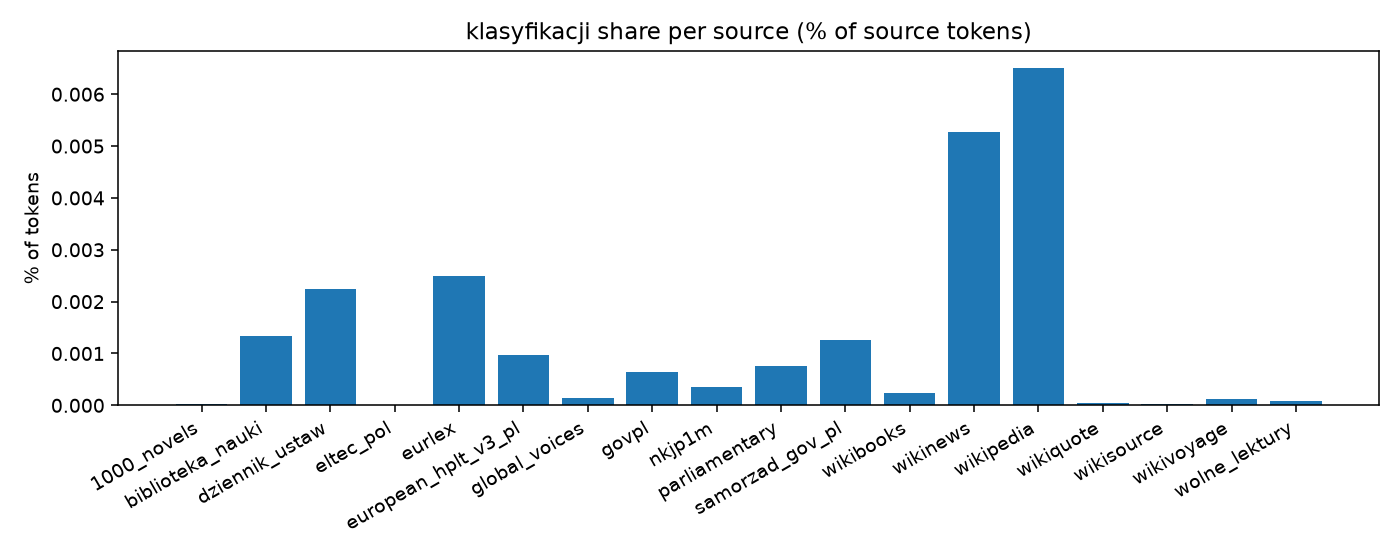
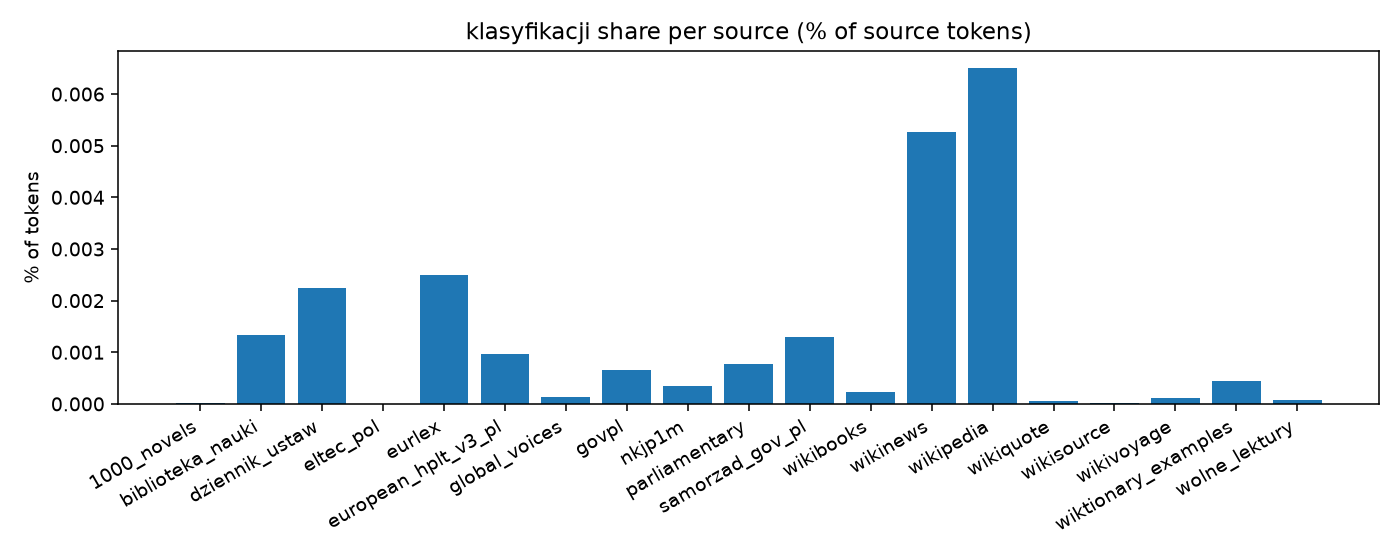
- artifacts/pattern_frequency_klasyfikacji.png +2 -2
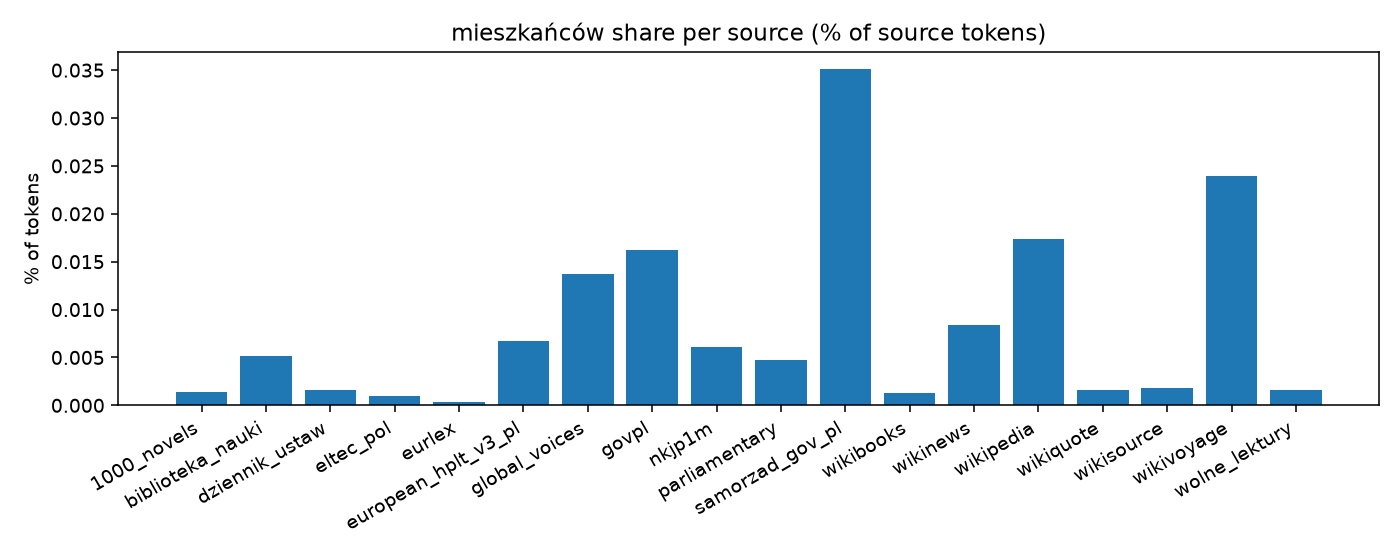
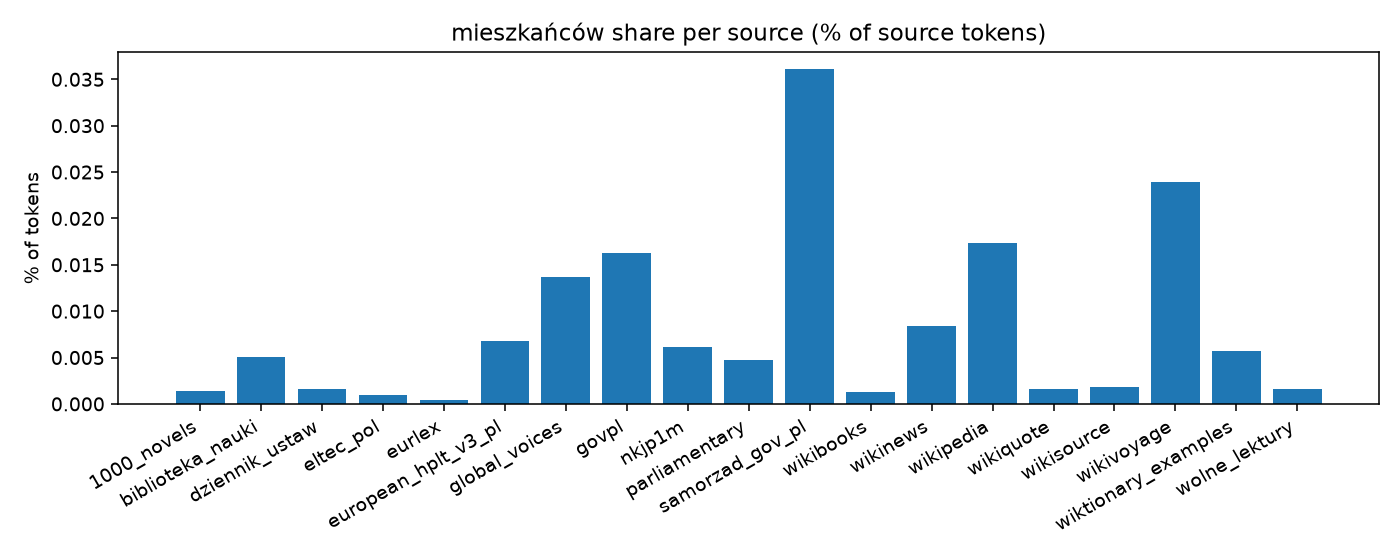
- artifacts/pattern_frequency_mieszkańców.png +2 -2
- artifacts/pattern_frequency_overall.png +2 -2
- artifacts/pattern_frequency_parlament.png +2 -2
- artifacts/pattern_frequency_rozporządzenie.png +2 -2
- artifacts/pattern_frequency_ustawa.png +2 -2
- artifacts/pattern_frequency_w_pobliżu.png +2 -2
- artifacts/pattern_frequency_w_roku.png +2 -2
- data/samorzad_gov_pl/NOTICE.md +5 -4
- data/samorzad_gov_pl/samorzad_gov_pl.attribution.jsonl +2 -2
- data/samorzad_gov_pl/samorzad_gov_pl.md +48 -29
- data/samorzad_gov_pl/samorzad_gov_pl.parquet +2 -2
- data/samorzad_gov_pl/samorzad_gov_pl.stats.json +18 -14
- pattern_frequency_report.md +27 -18
- src/clean_samorzad_gov_pl.py +17 -7
- src/make_docs.py +14 -6
- src/sources.py +5 -4
- src/test_samorzad_gov_pl_contract.py +13 -2
|
@@ -1,5 +1,25 @@
|
|
| 1 |
-
# Changelog
|
| 2 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 3 |
## v0.2.5 (2026-08-14)
|
| 4 |
|
| 5 |
- Added the community contribution `samorzad_gov_pl` by Dawid Majewski
|
|
@@ -118,4 +138,4 @@
|
|
| 118 |
- Credited Bart Kobyliński for source expansion work on Biblioteka Nauki and Europeana metadata/rebuild preparation.
|
| 119 |
- Kept raw SpeakLeash Europeana excluded unless a direct rebuild preserves per-record rights metadata.
|
| 120 |
- Sources: eurlex, parliamentary, wikisource, wikipedia, dziennik_ustaw, wolne_lektury, 1000_novels, wikiquote, eltec_pol, wikivoyage, wikibooks, wikinews.
|
| 121 |
-
- Excluded (see README): open_subtitles_corpus, europeana_eu_pl_corpus_raw_speakleash, project_gutenberg_pl_corpus.
|
|
|
|
| 1 |
+
# Changelog
|
| 2 |
+
|
| 3 |
+
## v0.2.6 (2026-08-22)
|
| 4 |
+
|
| 5 |
+
- Updated `samorzad_gov_pl` from the published, de-identified upstream v0.2
|
| 6 |
+
release at revision `a998efea84bb0a62d94effc0b54f88b422d9898f`.
|
| 7 |
+
- Rebuilt the DynaWord artifact as 72,472 documents / 40,011,099
|
| 8 |
+
cl100k-proxy tokens after dropping 6,932 short, 34 below the Polish-language
|
| 9 |
+
heuristic and 1,980 exact-duplicate records.
|
| 10 |
+
- Pinned and verified the upstream manifest, all 10 Parquet shards, record
|
| 11 |
+
counts, schema, unique IDs and release-wide record-text digest. The upstream
|
| 12 |
+
release passed its full structured-data scan, placeholder validation and a
|
| 13 |
+
1,000-record PERSON-model audit sample.
|
| 14 |
+
- Updated attribution notices and source documentation to record that retained
|
| 15 |
+
text was de-identified upstream using the pinned
|
| 16 |
+
`ArkadiuszPawlak/fastpdn-ner-polish-pii` model and deterministic rules for
|
| 17 |
+
structured identifiers and contact data.
|
| 18 |
+
- Recomputed complete-corpus documentation and phrase-frequency artifacts.
|
| 19 |
+
Stable totals are now 4,327,540 documents and 9,639,034,986 cl100k-proxy
|
| 20 |
+
tokens across 19 sources, including the previously merged
|
| 21 |
+
`wiktionary_examples` source.
|
| 22 |
+
|
| 23 |
## v0.2.5 (2026-08-14)
|
| 24 |
|
| 25 |
- Added the community contribution `samorzad_gov_pl` by Dawid Majewski
|
|
|
|
| 138 |
- Credited Bart Kobyliński for source expansion work on Biblioteka Nauki and Europeana metadata/rebuild preparation.
|
| 139 |
- Kept raw SpeakLeash Europeana excluded unless a direct rebuild preserves per-record rights metadata.
|
| 140 |
- Sources: eurlex, parliamentary, wikisource, wikipedia, dziennik_ustaw, wolne_lektury, 1000_novels, wikiquote, eltec_pol, wikivoyage, wikibooks, wikinews.
|
| 141 |
+
- Excluded (see README): open_subtitles_corpus, europeana_eu_pl_corpus_raw_speakleash, project_gutenberg_pl_corpus.
|
|
@@ -19,13 +19,13 @@ A continuously developed, **openly-licensed**, human-text Polish corpus — a Po
|
|
| 19 |
edition in the [Dynaword](https://huggingface.co/datasets/danish-foundation-models/danish-dynaword)
|
| 20 |
family (Enevoldsen et al., [arXiv:2508.02271](https://arxiv.org/abs/2508.02271)).
|
| 21 |
|
| 22 |
-
> **v0.2.
|
| 23 |
-
> (tiktoken proxy; canonical Llama-3 count at release) ·
|
| 24 |
-
> Updated: **2026-08-
|
| 25 |
|
| 26 |
> **v0.3-dev experimental track** · quality/diversity workflow, source-gate
|
| 27 |
> validation and candidate-data audits. This is development work, not a released
|
| 28 |
-
> corpus version, and it does not replace the v0.2.
|
| 29 |
|
| 30 |
> **Europeana validation artifact (2026-07-10)** · a separate reproducible
|
| 31 |
> 810-document direct-ingestion sample stored under the legacy path
|
|
@@ -37,7 +37,8 @@ family (Enevoldsen et al., [arXiv:2508.02271](https://arxiv.org/abs/2508.02271))
|
|
| 37 |
|
| 38 |
| version | status | documents | tokens | notes |
|
| 39 |
|---|---|---:|---:|---|
|
| 40 |
-
| `v0.2.
|
|
|
|
| 41 |
| `v0.2.4` | previous stable | 4,246,429 | 9.60B | Expanded `european_hplt_v3_pl` to WDS bins 10-5 (+1.49M docs / 2.04B tok); phone PII-scrub hardening (independent dual-lens) + cross-source dedup (zero-overlap). |
|
| 42 |
| `v0.2.3` | previous stable | 2,710,974 | 6.88B | Adds community-contributed `european_hplt_v3_pl`, `global_voices` and `nkjp1m`. |
|
| 43 |
| `v0.2.2` | previous stable | 2,579,963 | 6.36B | Added community-contributed `govpl`: 88,190 docs / 80.7M tokens. |
|
|
@@ -55,13 +56,20 @@ family (Enevoldsen et al., [arXiv:2508.02271](https://arxiv.org/abs/2508.02271))
|
|
| 55 |
|
| 56 |
### Version details
|
| 57 |
|
| 58 |
-
#### v0.2.
|
| 59 |
-
|
| 60 |
-
|
| 61 |
-
|
| 62 |
-
|
| 63 |
-
|
| 64 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 65 |
|
| 66 |
#### v0.2.4 — previous stable
|
| 67 |
|
|
@@ -147,7 +155,7 @@ as the redistributing aggregator; this release does not claim ownership of them
|
|
| 147 |
| [Bart Kobyliński](https://huggingface.co/bartoszkobylinski1) | Added `1000_novels`; expanded Biblioteka Nauki and Europeana ingestion with per-document license and author metadata. | `v0.2.1`, [PR #1](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/1) |
|
| 148 |
| [Paweł Puzio](https://huggingface.co/ppuzio) | Built `govpl`: subsite discovery, direct ingestion pipeline, dataset artifact, contract tests and documentation. | `v0.2.2`, [PR #9](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/9) |
|
| 149 |
| [Arkadiusz Słota](https://huggingface.co/Maggio33) | Built & expanded `european_hplt_v3_pl`: HPLT v3 WDS 10+9 (PR #5) then WDS 10-5 expansion (+1,493,384 docs / 2.04B tok), modular cleaning pipeline, phone-recall PII-scrub (v12b, independent dual-lens), cross-source dedup-vs-base (zero-overlap), validation and documentation. | `v0.2.3` (PR #5), `v0.2.4` |
|
| 150 |
-
| [Dawid Majewski](https://huggingface.co/dawidmajewski) | Added the reviewed Global Voices Polish corpus; built `samorzad_gov_pl` with direct acquisition, institution attribution, licensing evidence, release
|
| 151 |
| [1am](https://huggingface.co/1am) | Added `nkjp1m`: the manually annotated 1-million-word NKJP subcorpus, direct fetch/build pipeline, source documentation and release artifact. | `v0.2.3`, [PR #8](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/8) |
|
| 152 |
|
| 153 |
Contributions are credited when they add a verifiable dataset artifact, pipeline,
|
|
@@ -174,7 +182,7 @@ files is not listed as a data contribution.
|
|
| 174 |
| [wolne_lektury](data/wolne_lektury/wolne_lektury.md) | Wolne Lektury (school readings) | `CC-BY-SA-4.0 / Wolna Sztuka 1.3` | 6,141 | 103.0M |
|
| 175 |
| [govpl](data/govpl/govpl.md) | gov.pl — Polish government press releases | `CC-BY-SA-4.0` | 88,190 | 80.7M |
|
| 176 |
| [1000_novels](data/1000_novels/1000_novels.md) | 1000 Novels Corpus (CLARIN-PL) | `CC-BY-4.0` | 1,000 | 60.5M |
|
| 177 |
-
| [samorzad_gov_pl](data/samorzad_gov_pl/samorzad_gov_pl.md) | samorzad.gov.pl — Polish public-sector institutions | `CC-BY-SA-4.0` | 72,
|
| 178 |
| [wikiquote](data/wikiquote/wikiquote.md) | Polish Wikiquote (quotations) | `CC-BY-SA-3.0` | 30,363 | 31.9M |
|
| 179 |
| [eltec_pol](data/eltec_pol/eltec_pol.md) | ELTeC-pol (European Literary Text Collection, Polish) | `CC-BY-4.0` | 100 | 21.5M |
|
| 180 |
| [wikivoyage](data/wikivoyage/wikivoyage.md) | Polish Wikivoyage (travel guides) | `CC-BY-SA-3.0` | 13,645 | 17.1M |
|
|
@@ -182,7 +190,8 @@ files is not listed as a data contribution.
|
|
| 182 |
| [wikinews](data/wikinews/wikinews.md) | Polish Wikinews | `CC-BY-2.5` | 24,386 | 12.1M |
|
| 183 |
| [global_voices](data/global_voices/global_voices.md) | Global Voices Polish | `CC-BY-3.0` | 2,040 | 3.7M |
|
| 184 |
| [nkjp1m](data/nkjp1m/nkjp1m.md) | The manually annotated 1-million word subcorpus of the National Corpus of Polish | `CC-BY` | 18,381 | 2.6M |
|
| 185 |
-
|
|
|
|
|
| 186 |
|
| 187 |
## Method
|
| 188 |
Only **human-authored** text — no synthetic, machine-translated, or auto-transcribed
|
|
@@ -221,7 +230,7 @@ Current v0.3 source-ingestion status:
|
|
| 221 |
- Europeana release policy: split conservatively at pre-1929 records for
|
| 222 |
US-sensitive downstream reuse, and keep later/unknown records separately
|
| 223 |
labeled or held until legal review.
|
| 224 |
-
- `european_hplt_v3_pl`: WDS bins 10-5 are included in v0.2.
|
| 225 |
validation. HPLT packaging is CC0, while underlying crawled web documents can
|
| 226 |
carry independent rights; downstream near-dedup and web-content review remain
|
| 227 |
recommended before training.
|
|
@@ -291,20 +300,20 @@ python3 src/make_docs.py
|
|
| 291 |
|
| 292 |
### Corpus phrase frequency (normalized by tokens)
|
| 293 |
|
| 294 |
-
Raw counts and token-normalized shares are regenerated from the current
|
| 295 |
|
| 296 |
-
- Total token count (tiktoken proxy): **9,639,
|
| 297 |
|
| 298 |
| Pattern | Count | Share of all tokens |
|
| 299 |
|---|---:|---:|
|
| 300 |
-
| `w roku` | 585,
|
| 301 |
-
| `klasyfikacji` | 164,
|
| 302 |
-
| `ustawa` | 659,
|
| 303 |
-
| `artykuł` | 2,416,
|
| 304 |
-
| `parlament` | 1,285,
|
| 305 |
-
| `rozporządzenie` | 1,527,
|
| 306 |
-
| `w pobliżu` | 127,
|
| 307 |
-
| `mieszkańców` | 476,
|
| 308 |
| `Dz.U.` | 987,048 | 0.0102% |
|
| 309 |
|
| 310 |
### Per-source shares
|
|
@@ -401,15 +410,15 @@ Raw counts and token-normalized shares are regenerated from the current Parquet
|
|
| 401 |
| `parliamentary` | `w pobliżu` | 4,964 | 0.00030% |
|
| 402 |
| `parliamentary` | `mieszkańców` | 78,048 | 0.00474% |
|
| 403 |
| `parliamentary` | `Dz.U.` | 23,809 | 0.00145% |
|
| 404 |
-
| `samorzad_gov_pl` | `w roku` | 3,
|
| 405 |
-
| `samorzad_gov_pl` | `klasyfikacji` | 520 | 0.
|
| 406 |
-
| `samorzad_gov_pl` | `ustawa` | 1,
|
| 407 |
-
| `samorzad_gov_pl` | `artykuł` | 1,269 | 0.
|
| 408 |
-
| `samorzad_gov_pl` | `parlament` | 1,
|
| 409 |
-
| `samorzad_gov_pl` | `rozporządzenie` | 1,
|
| 410 |
-
| `samorzad_gov_pl` | `w pobliżu` | 401 | 0.
|
| 411 |
-
| `samorzad_gov_pl` | `mieszkańców` | 14,
|
| 412 |
-
| `samorzad_gov_pl` | `Dz.U.` | 1,380 | 0.
|
| 413 |
| `wikibooks` | `w roku` | 319 | 0.00205% |
|
| 414 |
| `wikibooks` | `klasyfikacji` | 37 | 0.00024% |
|
| 415 |
| `wikibooks` | `ustawa` | 165 | 0.00106% |
|
|
@@ -464,6 +473,15 @@ Raw counts and token-normalized shares are regenerated from the current Parquet
|
|
| 464 |
| `wikivoyage` | `w pobliżu` | 6,480 | 0.03783% |
|
| 465 |
| `wikivoyage` | `mieszkańców` | 4,100 | 0.02394% |
|
| 466 |
| `wikivoyage` | `Dz.U.` | 1 | 0.00001% |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 467 |
| `wolne_lektury` | `w roku` | 1,898 | 0.00184% |
|
| 468 |
| `wolne_lektury` | `klasyfikacji` | 80 | 0.00008% |
|
| 469 |
| `wolne_lektury` | `ustawa` | 1,060 | 0.00103% |
|
|
|
|
| 19 |
edition in the [Dynaword](https://huggingface.co/datasets/danish-foundation-models/danish-dynaword)
|
| 20 |
family (Enevoldsen et al., [arXiv:2508.02271](https://arxiv.org/abs/2508.02271)).
|
| 21 |
|
| 22 |
+
> **v0.2.6 stable** · 4,327,540 documents · **9.64B tokens**
|
| 23 |
+
> (tiktoken proxy; canonical Llama-3 count at release) · 19 sources
|
| 24 |
+
> Updated: **2026-08-22**
|
| 25 |
|
| 26 |
> **v0.3-dev experimental track** · quality/diversity workflow, source-gate
|
| 27 |
> validation and candidate-data audits. This is development work, not a released
|
| 28 |
+
> corpus version, and it does not replace the v0.2.6 stable parquets.
|
| 29 |
|
| 30 |
> **Europeana validation artifact (2026-07-10)** · a separate reproducible
|
| 31 |
> 810-document direct-ingestion sample stored under the legacy path
|
|
|
|
| 37 |
|
| 38 |
| version | status | documents | tokens | notes |
|
| 39 |
|---|---|---:|---:|---|
|
| 40 |
+
| `v0.2.6` | stable release | 4,327,540 | 9.64B | Updates `samorzad_gov_pl` from the de-identified upstream v0.2 release and includes `wiktionary_examples` in stable totals. |
|
| 41 |
+
| `v0.2.5` | previous stable | 4,319,200 | 9.64B | Added community-contributed `samorzad_gov_pl` with institution-level author attribution and a URL-bearing attribution sidecar. |
|
| 42 |
| `v0.2.4` | previous stable | 4,246,429 | 9.60B | Expanded `european_hplt_v3_pl` to WDS bins 10-5 (+1.49M docs / 2.04B tok); phone PII-scrub hardening (independent dual-lens) + cross-source dedup (zero-overlap). |
|
| 43 |
| `v0.2.3` | previous stable | 2,710,974 | 6.88B | Adds community-contributed `european_hplt_v3_pl`, `global_voices` and `nkjp1m`. |
|
| 44 |
| `v0.2.2` | previous stable | 2,579,963 | 6.36B | Added community-contributed `govpl`: 88,190 docs / 80.7M tokens. |
|
|
|
|
| 56 |
|
| 57 |
### Version details
|
| 58 |
|
| 59 |
+
#### v0.2.6 — current stable
|
| 60 |
+
|
| 61 |
+
Updated `samorzad_gov_pl` to the filtered and de-identified upstream v0.2
|
| 62 |
+
release: **72,472 documents / 40,011,099 cl100k-proxy tokens**. The conversion
|
| 63 |
+
remains pinned by revision, manifest SHA-256 and record-text digest. Stable
|
| 64 |
+
totals now also include the previously merged `wiktionary_examples` source.
|
| 65 |
+
|
| 66 |
+
#### v0.2.5 — previous stable
|
| 67 |
+
|
| 68 |
+
Added `samorzad_gov_pl`, a directly collected corpus of articles from 246
|
| 69 |
+
Polish local public institutions and one central platform tenant. The
|
| 70 |
+
contribution preserves the publishing institution as `author`, discovered and
|
| 71 |
+
fetched article URLs in an attribution sidecar and the platform's CC-BY-SA-4.0
|
| 72 |
+
basis.
|
| 73 |
|
| 74 |
#### v0.2.4 — previous stable
|
| 75 |
|
|
|
|
| 155 |
| [Bart Kobyliński](https://huggingface.co/bartoszkobylinski1) | Added `1000_novels`; expanded Biblioteka Nauki and Europeana ingestion with per-document license and author metadata. | `v0.2.1`, [PR #1](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/1) |
|
| 156 |
| [Paweł Puzio](https://huggingface.co/ppuzio) | Built `govpl`: subsite discovery, direct ingestion pipeline, dataset artifact, contract tests and documentation. | `v0.2.2`, [PR #9](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/9) |
|
| 157 |
| [Arkadiusz Słota](https://huggingface.co/Maggio33) | Built & expanded `european_hplt_v3_pl`: HPLT v3 WDS 10+9 (PR #5) then WDS 10-5 expansion (+1,493,384 docs / 2.04B tok), modular cleaning pipeline, phone-recall PII-scrub (v12b, independent dual-lens), cross-source dedup-vs-base (zero-overlap), validation and documentation. | `v0.2.3` (PR #5), `v0.2.4` |
|
| 158 |
+
| [Dawid Majewski](https://huggingface.co/dawidmajewski) | Added the reviewed Global Voices Polish corpus; built and updated `samorzad_gov_pl` with direct acquisition, de-identification, institution attribution, licensing evidence, release artifacts and reproducible conversion. | `v0.2.3`, [PR #7](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/7); `v0.2.5`, `v0.2.6` |
|
| 159 |
| [1am](https://huggingface.co/1am) | Added `nkjp1m`: the manually annotated 1-million-word NKJP subcorpus, direct fetch/build pipeline, source documentation and release artifact. | `v0.2.3`, [PR #8](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/8) |
|
| 160 |
|
| 161 |
Contributions are credited when they add a verifiable dataset artifact, pipeline,
|
|
|
|
| 182 |
| [wolne_lektury](data/wolne_lektury/wolne_lektury.md) | Wolne Lektury (school readings) | `CC-BY-SA-4.0 / Wolna Sztuka 1.3` | 6,141 | 103.0M |
|
| 183 |
| [govpl](data/govpl/govpl.md) | gov.pl — Polish government press releases | `CC-BY-SA-4.0` | 88,190 | 80.7M |
|
| 184 |
| [1000_novels](data/1000_novels/1000_novels.md) | 1000 Novels Corpus (CLARIN-PL) | `CC-BY-4.0` | 1,000 | 60.5M |
|
| 185 |
+
| [samorzad_gov_pl](data/samorzad_gov_pl/samorzad_gov_pl.md) | samorzad.gov.pl — Polish public-sector institutions | `CC-BY-SA-4.0` | 72,472 | 40.0M |
|
| 186 |
| [wikiquote](data/wikiquote/wikiquote.md) | Polish Wikiquote (quotations) | `CC-BY-SA-3.0` | 30,363 | 31.9M |
|
| 187 |
| [eltec_pol](data/eltec_pol/eltec_pol.md) | ELTeC-pol (European Literary Text Collection, Polish) | `CC-BY-4.0` | 100 | 21.5M |
|
| 188 |
| [wikivoyage](data/wikivoyage/wikivoyage.md) | Polish Wikivoyage (travel guides) | `CC-BY-SA-3.0` | 13,645 | 17.1M |
|
|
|
|
| 190 |
| [wikinews](data/wikinews/wikinews.md) | Polish Wikinews | `CC-BY-2.5` | 24,386 | 12.1M |
|
| 191 |
| [global_voices](data/global_voices/global_voices.md) | Global Voices Polish | `CC-BY-3.0` | 2,040 | 3.7M |
|
| 192 |
| [nkjp1m](data/nkjp1m/nkjp1m.md) | The manually annotated 1-million word subcorpus of the National Corpus of Polish | `CC-BY` | 18,381 | 2.6M |
|
| 193 |
+
| [wiktionary_examples](data/wiktionary_examples/wiktionary_examples.md) | Polish Wiktionary usage examples | `CC-BY-SA-3.0` | 8,639 | 1.1M |
|
| 194 |
+
| **total** | | | **4,327,540** | **9,639.0M** |
|
| 195 |
|
| 196 |
## Method
|
| 197 |
Only **human-authored** text — no synthetic, machine-translated, or auto-transcribed
|
|
|
|
| 230 |
- Europeana release policy: split conservatively at pre-1929 records for
|
| 231 |
US-sensitive downstream reuse, and keep later/unknown records separately
|
| 232 |
labeled or held until legal review.
|
| 233 |
+
- `european_hplt_v3_pl`: WDS bins 10-5 are included in v0.2.6 after contract
|
| 234 |
validation. HPLT packaging is CC0, while underlying crawled web documents can
|
| 235 |
carry independent rights; downstream near-dedup and web-content review remain
|
| 236 |
recommended before training.
|
|
|
|
| 300 |
|
| 301 |
### Corpus phrase frequency (normalized by tokens)
|
| 302 |
|
| 303 |
+
Raw counts and token-normalized shares are regenerated from the current parquet files with `src/pattern_frequency_report.py`.
|
| 304 |
|
| 305 |
+
- Total token count (tiktoken proxy): **9,639,034,986**
|
| 306 |
|
| 307 |
| Pattern | Count | Share of all tokens |
|
| 308 |
|---|---:|---:|
|
| 309 |
+
| `w roku` | 585,125 | 0.0061% |
|
| 310 |
+
| `klasyfikacji` | 164,762 | 0.0017% |
|
| 311 |
+
| `ustawa` | 659,092 | 0.0068% |
|
| 312 |
+
| `artykuł` | 2,416,403 | 0.0251% |
|
| 313 |
+
| `parlament` | 1,285,819 | 0.0133% |
|
| 314 |
+
| `rozporządzenie` | 1,527,449 | 0.0158% |
|
| 315 |
+
| `w pobliżu` | 127,816 | 0.0013% |
|
| 316 |
+
| `mieszkańców` | 476,772 | 0.0049% |
|
| 317 |
| `Dz.U.` | 987,048 | 0.0102% |
|
| 318 |
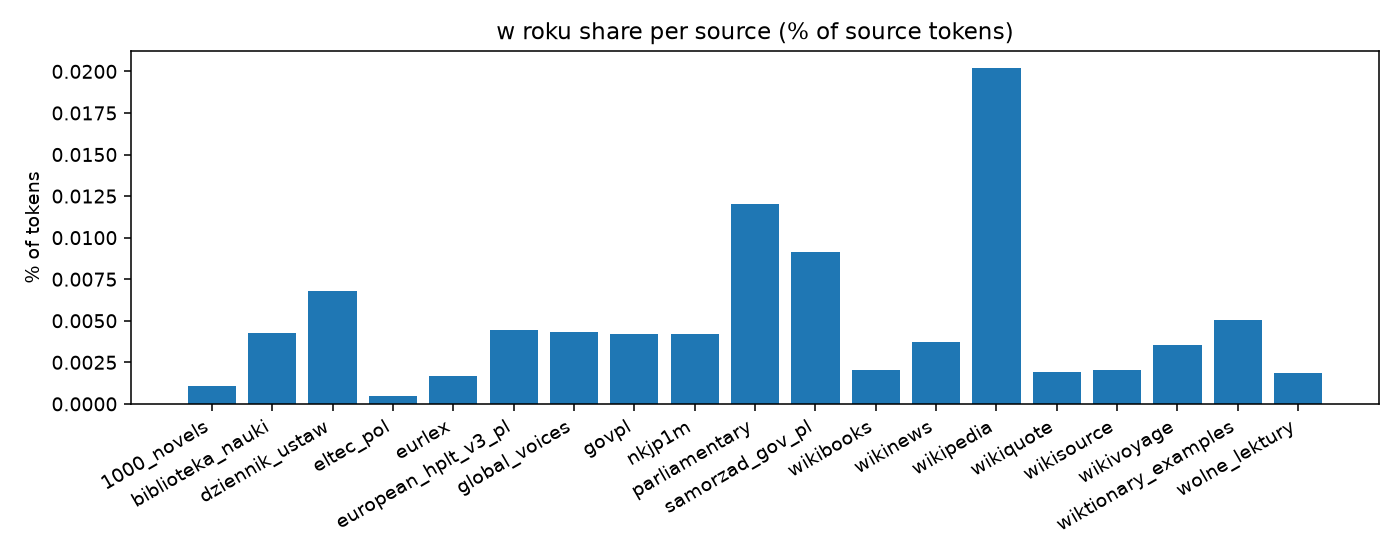
|
| 319 |
### Per-source shares
|
|
|
|
| 410 |
| `parliamentary` | `w pobliżu` | 4,964 | 0.00030% |
|
| 411 |
| `parliamentary` | `mieszkańców` | 78,048 | 0.00474% |
|
| 412 |
| `parliamentary` | `Dz.U.` | 23,809 | 0.00145% |
|
| 413 |
+
| `samorzad_gov_pl` | `w roku` | 3,658 | 0.00914% |
|
| 414 |
+
| `samorzad_gov_pl` | `klasyfikacji` | 520 | 0.00130% |
|
| 415 |
+
| `samorzad_gov_pl` | `ustawa` | 1,786 | 0.00446% |
|
| 416 |
+
| `samorzad_gov_pl` | `artykuł` | 1,269 | 0.00317% |
|
| 417 |
+
| `samorzad_gov_pl` | `parlament` | 1,217 | 0.00304% |
|
| 418 |
+
| `samorzad_gov_pl` | `rozporządzenie` | 1,397 | 0.00349% |
|
| 419 |
+
| `samorzad_gov_pl` | `w pobliżu` | 401 | 0.00100% |
|
| 420 |
+
| `samorzad_gov_pl` | `mieszkańców` | 14,448 | 0.03611% |
|
| 421 |
+
| `samorzad_gov_pl` | `Dz.U.` | 1,380 | 0.00345% |
|
| 422 |
| `wikibooks` | `w roku` | 319 | 0.00205% |
|
| 423 |
| `wikibooks` | `klasyfikacji` | 37 | 0.00024% |
|
| 424 |
| `wikibooks` | `ustawa` | 165 | 0.00106% |
|
|
|
|
| 473 |
| `wikivoyage` | `w pobliżu` | 6,480 | 0.03783% |
|
| 474 |
| `wikivoyage` | `mieszkańców` | 4,100 | 0.02394% |
|
| 475 |
| `wikivoyage` | `Dz.U.` | 1 | 0.00001% |
|
| 476 |
+
| `wiktionary_examples` | `w roku` | 56 | 0.00502% |
|
| 477 |
+
| `wiktionary_examples` | `klasyfikacji` | 5 | 0.00045% |
|
| 478 |
+
| `wiktionary_examples` | `ustawa` | 26 | 0.00233% |
|
| 479 |
+
| `wiktionary_examples` | `artykuł` | 42 | 0.00376% |
|
| 480 |
+
| `wiktionary_examples` | `parlament` | 28 | 0.00251% |
|
| 481 |
+
| `wiktionary_examples` | `rozporządzenie` | 5 | 0.00045% |
|
| 482 |
+
| `wiktionary_examples` | `w pobliżu` | 32 | 0.00287% |
|
| 483 |
+
| `wiktionary_examples` | `mieszkańców` | 64 | 0.00574% |
|
| 484 |
+
| `wiktionary_examples` | `Dz.U.` | 0 | 0.00000% |
|
| 485 |
| `wolne_lektury` | `w roku` | 1,898 | 0.00184% |
|
| 486 |
| `wolne_lektury` | `klasyfikacji` | 80 | 0.00008% |
|
| 487 |
| `wolne_lektury` | `ustawa` | 1,060 | 0.00103% |
|
|
Git LFS Details
|
|
Git LFS Details
|
|
Git LFS Details
|
|
Git LFS Details
|
|
@@ -1,17 +1,17 @@
|
|
| 1 |
## Phrase frequency in corpus (token-normalized)
|
| 2 |
|
| 3 |
-
- Total token count (tiktoken proxy): **9,639,
|
| 4 |
|
| 5 |
| Pattern | Count | Share of all tokens |
|
| 6 |
|---|---:|---:|
|
| 7 |
-
| `w roku` | 585,
|
| 8 |
-
| `klasyfikacji` | 164,
|
| 9 |
-
| `ustawa` | 659,
|
| 10 |
-
| `artykuł` | 2,416,
|
| 11 |
-
| `parlament` | 1,285,
|
| 12 |
-
| `rozporządzenie` | 1,527,
|
| 13 |
-
| `w pobliżu` | 127,
|
| 14 |
-
| `mieszkańców` | 476,
|
| 15 |
| `Dz.U.` | 987,048 | 0.0102% |
|
| 16 |
|
| 17 |
### Per-source shares
|
|
@@ -108,15 +108,15 @@
|
|
| 108 |
| `parliamentary` | `w pobliżu` | 4,964 | 0.00030% |
|
| 109 |
| `parliamentary` | `mieszkańców` | 78,048 | 0.00474% |
|
| 110 |
| `parliamentary` | `Dz.U.` | 23,809 | 0.00145% |
|
| 111 |
-
| `samorzad_gov_pl` | `w roku` | 3,
|
| 112 |
-
| `samorzad_gov_pl` | `klasyfikacji` | 520 | 0.
|
| 113 |
-
| `samorzad_gov_pl` | `ustawa` | 1,
|
| 114 |
-
| `samorzad_gov_pl` | `artykuł` | 1,269 | 0.
|
| 115 |
-
| `samorzad_gov_pl` | `parlament` | 1,
|
| 116 |
-
| `samorzad_gov_pl` | `rozporządzenie` | 1,
|
| 117 |
-
| `samorzad_gov_pl` | `w pobliżu` | 401 | 0.
|
| 118 |
-
| `samorzad_gov_pl` | `mieszkańców` | 14,
|
| 119 |
-
| `samorzad_gov_pl` | `Dz.U.` | 1,380 | 0.
|
| 120 |
| `wikibooks` | `w roku` | 319 | 0.00205% |
|
| 121 |
| `wikibooks` | `klasyfikacji` | 37 | 0.00024% |
|
| 122 |
| `wikibooks` | `ustawa` | 165 | 0.00106% |
|
|
@@ -171,6 +171,15 @@
|
|
| 171 |
| `wikivoyage` | `w pobliżu` | 6,480 | 0.03783% |
|
| 172 |
| `wikivoyage` | `mieszkańców` | 4,100 | 0.02394% |
|
| 173 |
| `wikivoyage` | `Dz.U.` | 1 | 0.00001% |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 174 |
| `wolne_lektury` | `w roku` | 1,898 | 0.00184% |
|
| 175 |
| `wolne_lektury` | `klasyfikacji` | 80 | 0.00008% |
|
| 176 |
| `wolne_lektury` | `ustawa` | 1,060 | 0.00103% |
|
|
|
|
| 1 |
## Phrase frequency in corpus (token-normalized)
|
| 2 |
|
| 3 |
+
- Total token count (tiktoken proxy): **9,639,034,986**
|
| 4 |
|
| 5 |
| Pattern | Count | Share of all tokens |
|
| 6 |
|---|---:|---:|
|
| 7 |
+
| `w roku` | 585,125 | 0.0061% |
|
| 8 |
+
| `klasyfikacji` | 164,762 | 0.0017% |
|
| 9 |
+
| `ustawa` | 659,092 | 0.0068% |
|
| 10 |
+
| `artykuł` | 2,416,403 | 0.0251% |
|
| 11 |
+
| `parlament` | 1,285,819 | 0.0133% |
|
| 12 |
+
| `rozporządzenie` | 1,527,449 | 0.0158% |
|
| 13 |
+
| `w pobliżu` | 127,816 | 0.0013% |
|
| 14 |
+
| `mieszkańców` | 476,772 | 0.0049% |
|
| 15 |
| `Dz.U.` | 987,048 | 0.0102% |
|
| 16 |
|
| 17 |
### Per-source shares
|
|
|
|
| 108 |
| `parliamentary` | `w pobliżu` | 4,964 | 0.00030% |
|
| 109 |
| `parliamentary` | `mieszkańców` | 78,048 | 0.00474% |
|
| 110 |
| `parliamentary` | `Dz.U.` | 23,809 | 0.00145% |
|
| 111 |
+
| `samorzad_gov_pl` | `w roku` | 3,658 | 0.00914% |
|
| 112 |
+
| `samorzad_gov_pl` | `klasyfikacji` | 520 | 0.00130% |
|
| 113 |
+
| `samorzad_gov_pl` | `ustawa` | 1,786 | 0.00446% |
|
| 114 |
+
| `samorzad_gov_pl` | `artykuł` | 1,269 | 0.00317% |
|
| 115 |
+
| `samorzad_gov_pl` | `parlament` | 1,217 | 0.00304% |
|
| 116 |
+
| `samorzad_gov_pl` | `rozporządzenie` | 1,397 | 0.00349% |
|
| 117 |
+
| `samorzad_gov_pl` | `w pobliżu` | 401 | 0.00100% |
|
| 118 |
+
| `samorzad_gov_pl` | `mieszkańców` | 14,448 | 0.03611% |
|
| 119 |
+
| `samorzad_gov_pl` | `Dz.U.` | 1,380 | 0.00345% |
|
| 120 |
| `wikibooks` | `w roku` | 319 | 0.00205% |
|
| 121 |
| `wikibooks` | `klasyfikacji` | 37 | 0.00024% |
|
| 122 |
| `wikibooks` | `ustawa` | 165 | 0.00106% |
|
|
|
|
| 171 |
| `wikivoyage` | `w pobliżu` | 6,480 | 0.03783% |
|
| 172 |
| `wikivoyage` | `mieszkańców` | 4,100 | 0.02394% |
|
| 173 |
| `wikivoyage` | `Dz.U.` | 1 | 0.00001% |
|
| 174 |
+
| `wiktionary_examples` | `w roku` | 56 | 0.00502% |
|
| 175 |
+
| `wiktionary_examples` | `klasyfikacji` | 5 | 0.00045% |
|
| 176 |
+
| `wiktionary_examples` | `ustawa` | 26 | 0.00233% |
|
| 177 |
+
| `wiktionary_examples` | `artykuł` | 42 | 0.00376% |
|
| 178 |
+
| `wiktionary_examples` | `parlament` | 28 | 0.00251% |
|
| 179 |
+
| `wiktionary_examples` | `rozporządzenie` | 5 | 0.00045% |
|
| 180 |
+
| `wiktionary_examples` | `w pobliżu` | 32 | 0.00287% |
|
| 181 |
+
| `wiktionary_examples` | `mieszkańców` | 64 | 0.00574% |
|
| 182 |
+
| `wiktionary_examples` | `Dz.U.` | 0 | 0.00000% |
|
| 183 |
| `wolne_lektury` | `w roku` | 1,898 | 0.00184% |
|
| 184 |
| `wolne_lektury` | `klasyfikacji` | 80 | 0.00008% |
|
| 185 |
| `wolne_lektury` | `ustawa` | 1,060 | 0.00103% |
|
|
Git LFS Details
|
|
Git LFS Details
|
|
Git LFS Details
|
|
Git LFS Details
|
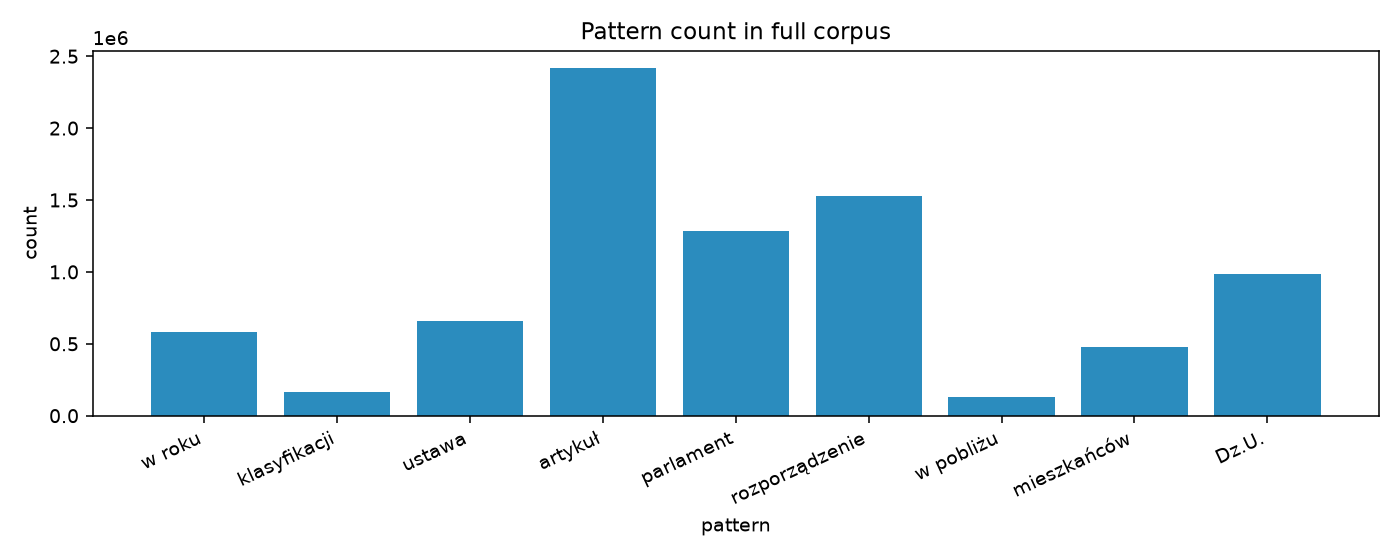
|
Git LFS Details
|
|
Git LFS Details
|
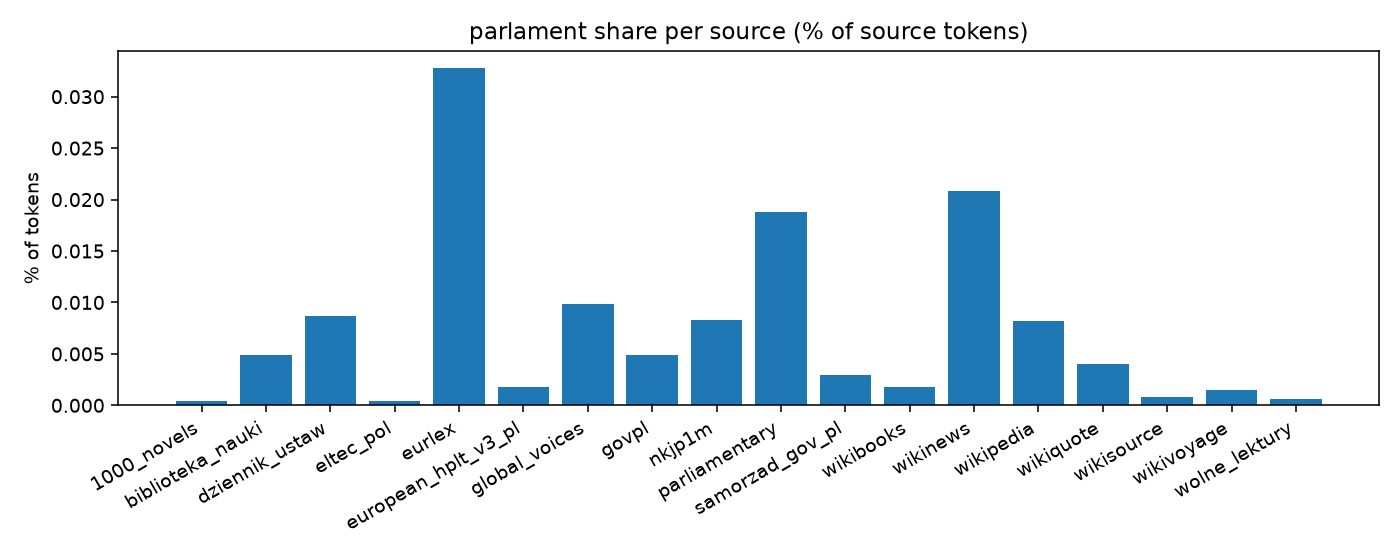
|
Git LFS Details
|
|
Git LFS Details
|

|
Git LFS Details
|

|
Git LFS Details
|
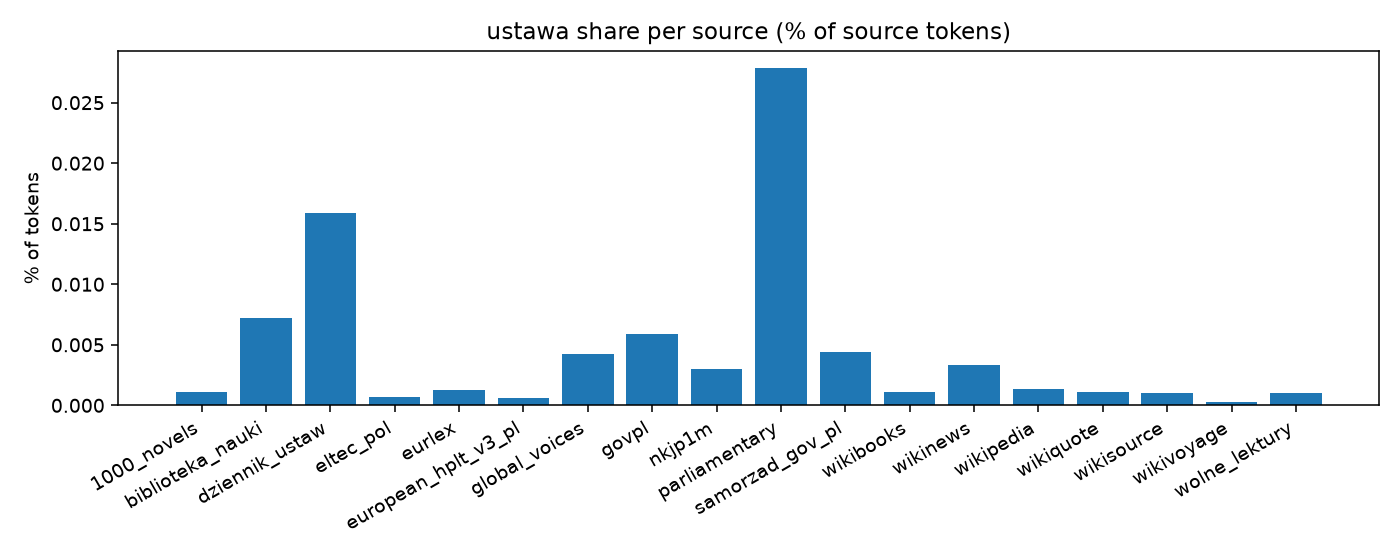
|
Git LFS Details
|
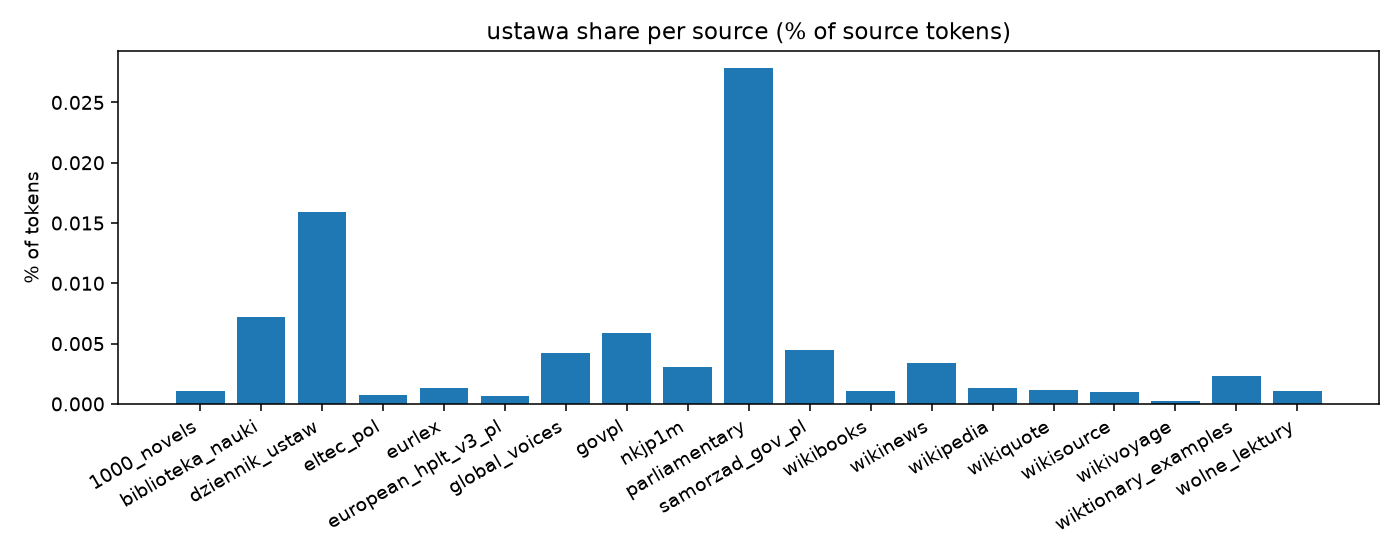
|
Git LFS Details
|

|
Git LFS Details
|
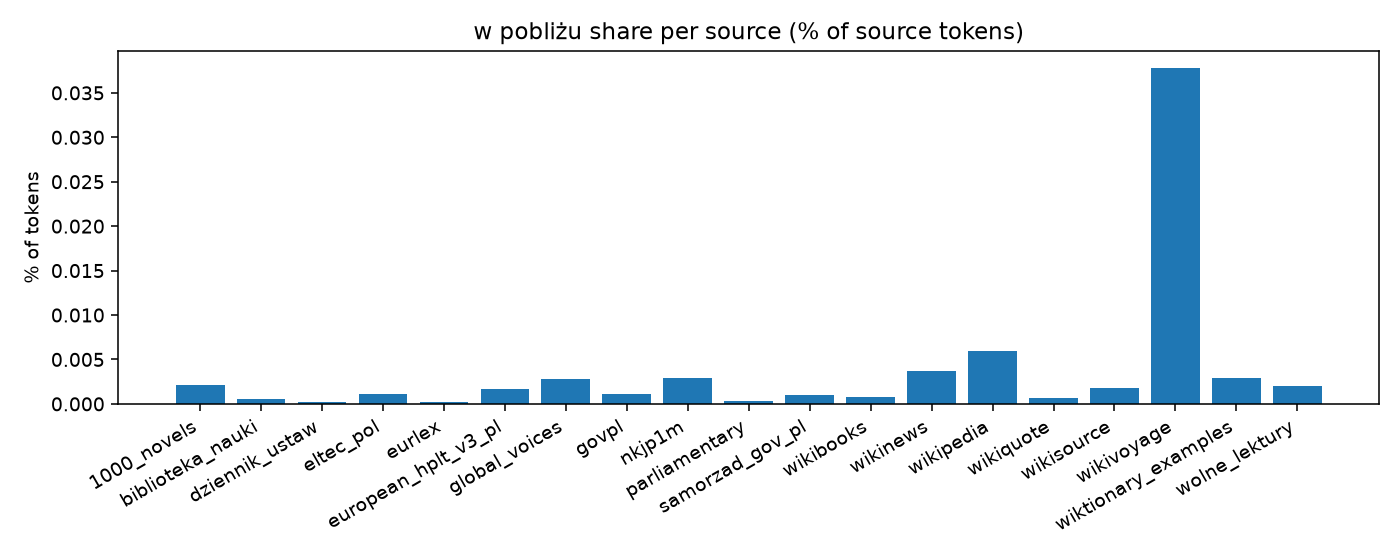
|
Git LFS Details
|
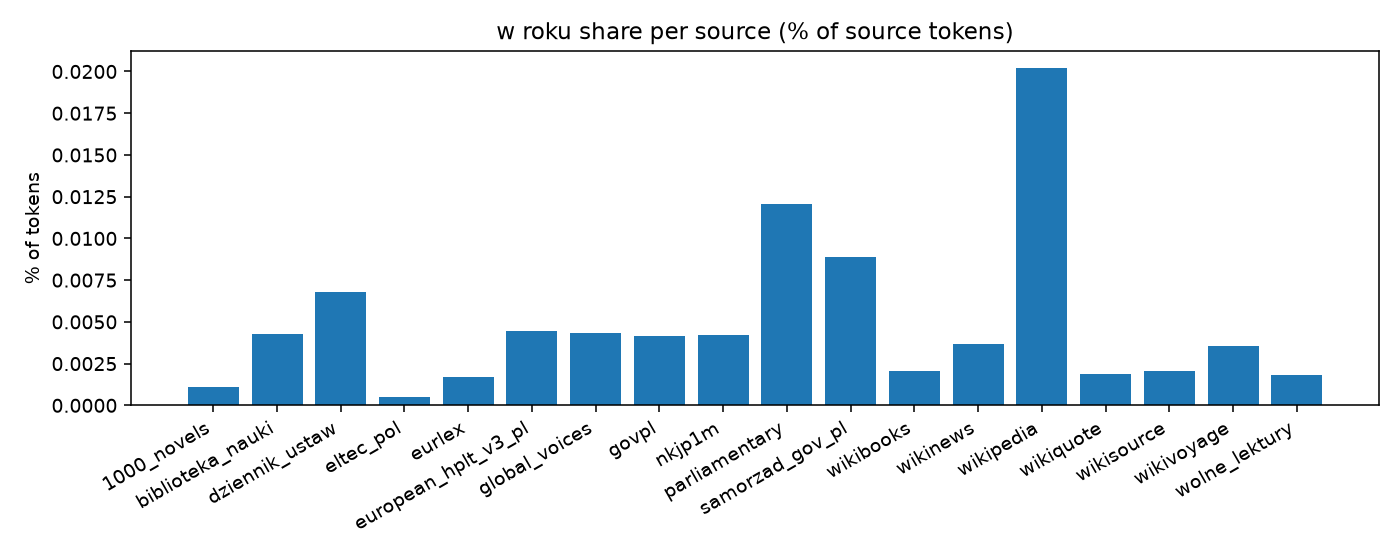
|
Git LFS Details
|
|
Git LFS Details
|
|
@@ -7,8 +7,8 @@ platform.
|
|
| 7 |
The platform footer states that textual content published in the service,
|
| 8 |
excluding audiovisual content, is available under the [Creative Commons
|
| 9 |
Attribution-ShareAlike 4.0 International](https://creativecommons.org/licenses/by-sa/4.0/)
|
| 10 |
-
license (`CC-BY-SA-4.0`). Every
|
| 11 |
-
|
| 12 |
|
| 13 |
For every released DynaWord document:
|
| 14 |
|
|
@@ -16,8 +16,9 @@ For every released DynaWord document:
|
|
| 16 |
- `samorzad_gov_pl.attribution.jsonl` preserves the discovered `source_url`,
|
| 17 |
fetched `final_url`, recommended `attribution_url`, article title,
|
| 18 |
institution, tenant identifier, license URL and modification notice;
|
| 19 |
-
- article text was extracted from source HTML
|
| 20 |
-
|
|
|
|
| 21 |
|
| 22 |
When redistributing or adapting these texts, retain the source attribution,
|
| 23 |
indicate changes and distribute adaptations under compatible
|
|
|
|
| 7 |
The platform footer states that textual content published in the service,
|
| 8 |
excluding audiovisual content, is available under the [Creative Commons
|
| 9 |
Attribution-ShareAlike 4.0 International](https://creativecommons.org/licenses/by-sa/4.0/)
|
| 10 |
+
license (`CC-BY-SA-4.0`). Every page in the published v0.2 source dataset belongs
|
| 11 |
+
to the v0.1 source set for which the shared footer reference was verified.
|
| 12 |
|
| 13 |
For every released DynaWord document:
|
| 14 |
|
|
|
|
| 16 |
- `samorzad_gov_pl.attribution.jsonl` preserves the discovered `source_url`,
|
| 17 |
fetched `final_url`, recommended `attribution_url`, article title,
|
| 18 |
institution, tenant identifier, license URL and modification notice;
|
| 19 |
+
- article text was extracted from source HTML and de-identified upstream;
|
| 20 |
+
- this contribution normalizes metadata and excludes short, non-Polish or
|
| 21 |
+
duplicate records.
|
| 22 |
|
| 23 |
When redistributing or adapting these texts, retain the source attribution,
|
| 24 |
indicate changes and distribute adaptations under compatible
|
|
@@ -1,3 +1,3 @@
|
|
| 1 |
version https://git-lfs.github.com/spec/v1
|
| 2 |
-
oid sha256:
|
| 3 |
-
size
|
|
|
|
| 1 |
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:2def7488c34e749204842bcf21d33149738b34de2515115e3f79401f7eb271c4
|
| 3 |
+
size 72438302
|
|
@@ -9,7 +9,7 @@ institutions and other public bodies.
|
|
| 9 |
## Dataset description
|
| 10 |
|
| 11 |
- **Published source dataset:** https://huggingface.co/datasets/dawidmajewski/samorzad-gov-pl-articles
|
| 12 |
-
- **Source revision:** `
|
| 13 |
- **Original platform:** https://samorzad.gov.pl/
|
| 14 |
- **Domain:** local government, education, social services and culture
|
| 15 |
- **Language:** Polish (`pl`)
|
|
@@ -21,7 +21,7 @@ institutions and other public bodies.
|
|
| 21 |
|
| 22 |
| read | kept | characters | tokens (`cl100k_base` proxy) | publishers |
|
| 23 |
|---:|---:|---:|---:|---:|
|
| 24 |
-
| 81,
|
| 25 |
|
| 26 |
The released Parquet uses the canonical DynaWord schema:
|
| 27 |
|
|
@@ -32,40 +32,56 @@ institution in `author`. The names were obtained from the `og:site_name`
|
|
| 32 |
metadata on each institution's platform homepage and frozen in
|
| 33 |
`src/samorzad_gov_pl_publishers.json`.
|
| 34 |
|
| 35 |
-
## Provenance
|
| 36 |
|
| 37 |
The source release was collected directly from public samorzad.gov.pl pages.
|
| 38 |
It contains every article URL found and successfully extracted during that
|
| 39 |
-
crawl, rather than a topical or length-selected sample.
|
| 40 |
-
|
| 41 |
-
|
| 42 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 43 |
DynaWord schema, applies the common minimum-length and Polish-language checks,
|
| 44 |
-
removes exact duplicate text and counts tokens with `cl100k_base`.
|
| 45 |
-
|
| 46 |
|
| 47 |
## Licensing — traceable basis and attribution
|
| 48 |
|
| 49 |
The platform's shared footer states that textual content published in the
|
| 50 |
service, excluding audiovisual content, is available under CC BY-SA 4.0. A
|
| 51 |
-
release-time audit verified the live shared footer script
|
| 52 |
-
|
| 53 |
-
|
|
|
|
| 54 |
`samorzad_gov_pl.license-evidence.json`.
|
| 55 |
|
| 56 |
The fixed DynaWord schema does not contain article titles or URLs. Therefore,
|
| 57 |
`samorzad_gov_pl.attribution.jsonl` maps every released `id` to its title,
|
| 58 |
discovered `source_url`, fetched `final_url`, recommended `attribution_url`,
|
| 59 |
publishing institution, platform tenant, license URL and modification notice.
|
| 60 |
-
For
|
| 61 |
platform redirected the request; `attribution_url` uses the fetched final URL.
|
| 62 |
|
| 63 |
Recommended attribution:
|
| 64 |
|
| 65 |
> Publishing institution listed in the `author` column; article title and
|
| 66 |
> canonical samorzad.gov.pl URL from the attribution sidecar; CC BY-SA 4.0.
|
| 67 |
-
> Article text was extracted from HTML
|
| 68 |
-
> DynaWord.
|
| 69 |
|
| 70 |
Photographs, recordings, videos and attachment bytes are not redistributed.
|
| 71 |
The source platform gives audiovisual materials separate terms, and linked
|
|
@@ -76,11 +92,11 @@ not redistribute those files.
|
|
| 76 |
|
| 77 |
| result | documents |
|
| 78 |
|---|---:|
|
| 79 |
-
| source records read | 81,
|
| 80 |
-
| shorter than 200 characters | 6,
|
| 81 |
-
| below the Polish-language heuristic |
|
| 82 |
-
| exact duplicate text | 1,
|
| 83 |
-
| retained | 72,
|
| 84 |
|
| 85 |
Exact duplicate removal is performed after short-text and language checks.
|
| 86 |
Existing DynaWord sources take priority when the same text is already present
|
|
@@ -88,11 +104,13 @@ elsewhere in the corpus.
|
|
| 88 |
|
| 89 |
## Limitations and recommended use
|
| 90 |
|
|
|
|
|
|
|
|
|
|
| 91 |
- The collection is not a complete historical archive of samorzad.gov.pl. It
|
| 92 |
contains the pages found and successfully extracted during one crawl.
|
| 93 |
-
-
|
| 94 |
-
|
| 95 |
-
inferred for them.
|
| 96 |
- The source text can contain spelling errors, extraction remnants or captions.
|
| 97 |
- Very short source records are excluded by DynaWord's 200-character minimum.
|
| 98 |
- Institution names describe the publishing body, not necessarily the person
|
|
@@ -112,18 +130,19 @@ elsewhere in the corpus.
|
|
| 112 |
## Reproduction
|
| 113 |
|
| 114 |
The converter refuses to build unless the downloaded `manifest.json` and all
|
| 115 |
-
10 Parquet shards match the pinned release. It verifies the manifest
|
| 116 |
-
artifact set, shard sizes and SHA-256 values, row counts, schema,
|
| 117 |
-
IDs and the release-wide record-text digest before conversion.
|
| 118 |
-
written to temporary files, cross-checked, synced and
|
| 119 |
-
a failed replacement restores the previous artifact
|
|
|
|
| 120 |
|
| 121 |
Download the published source Parquet shards and run:
|
| 122 |
|
| 123 |
```bash
|
| 124 |
hf download dawidmajewski/samorzad-gov-pl-articles \
|
| 125 |
--repo-type dataset \
|
| 126 |
-
--revision
|
| 127 |
--include 'data/*.parquet' --include manifest.json \
|
| 128 |
--local-dir /tmp/samorzad-gov-pl-articles
|
| 129 |
|
|
|
|
| 9 |
## Dataset description
|
| 10 |
|
| 11 |
- **Published source dataset:** https://huggingface.co/datasets/dawidmajewski/samorzad-gov-pl-articles
|
| 12 |
+
- **Source revision:** `a998efea84bb0a62d94effc0b54f88b422d9898f` (`v0.2`)
|
| 13 |
- **Original platform:** https://samorzad.gov.pl/
|
| 14 |
- **Domain:** local government, education, social services and culture
|
| 15 |
- **Language:** Polish (`pl`)
|
|
|
|
| 21 |
|
| 22 |
| read | kept | characters | tokens (`cl100k_base` proxy) | publishers |
|
| 23 |
|---:|---:|---:|---:|---:|
|
| 24 |
+
| 81,418 | 72,472 | 107,130,266 | 40,011,099 | 247 |
|
| 25 |
|
| 26 |
The released Parquet uses the canonical DynaWord schema:
|
| 27 |
|
|
|
|
| 32 |
metadata on each institution's platform homepage and frozen in
|
| 33 |
`src/samorzad_gov_pl_publishers.json`.
|
| 34 |
|
| 35 |
+
## Provenance and de-identification
|
| 36 |
|
| 37 |
The source release was collected directly from public samorzad.gov.pl pages.
|
| 38 |
It contains every article URL found and successfully extracted during that
|
| 39 |
+
crawl, rather than a topical or length-selected sample. Its v0.2 release
|
| 40 |
+
contains 81,418 articles from 247 institutions after four corrupted source
|
| 41 |
+
records were excluded.
|
| 42 |
+
|
| 43 |
+
Consumer-facing text was de-identified upstream before conversion to DynaWord.
|
| 44 |
+
Names were detected with the pinned Polish PII model
|
| 45 |
+
[`ArkadiuszPawlak/fastpdn-ner-polish-pii`](https://huggingface.co/ArkadiuszPawlak/fastpdn-ner-polish-pii)
|
| 46 |
+
at revision `636c57fe77b0afad8f065e7c76243dc051437035`. Deterministic
|
| 47 |
+
rules and checksum validation covered structured identifiers and contact data.
|
| 48 |
+
Removed values were replaced by typed placeholders such as `<PERSON>`,
|
| 49 |
+
`<PHONE>`, `<EMAIL>` and `<URL>`.
|
| 50 |
+
|
| 51 |
+
The upstream release audit scanned all 81,418 records for structured residuals,
|
| 52 |
+
reran the PERSON model on an evenly spaced 1,000-record sample, validated
|
| 53 |
+
placeholder structure, verified the 10 Parquet files by size and SHA-256, and
|
| 54 |
+
checked record provenance against the pinned source manifest. All required
|
| 55 |
+
release gates passed.
|
| 56 |
+
|
| 57 |
+
`src/clean_samorzad_gov_pl.py` verifies and converts the v0.2 Parquets into the
|
| 58 |
DynaWord schema, applies the common minimum-length and Polish-language checks,
|
| 59 |
+
removes exact duplicate text and counts tokens with `cl100k_base`. Retained text
|
| 60 |
+
is otherwise unchanged after upstream de-identification.
|
| 61 |
|
| 62 |
## Licensing — traceable basis and attribution
|
| 63 |
|
| 64 |
The platform's shared footer states that textual content published in the
|
| 65 |
service, excluding audiovisual content, is available under CC BY-SA 4.0. A
|
| 66 |
+
release-time audit verified the live shared footer script for all 81,422 pages
|
| 67 |
+
in the v0.1 source set. The four records omitted from v0.2 were a subset of that
|
| 68 |
+
audited set, so every v0.2 article remains covered by the same evidence. The
|
| 69 |
+
evidence URL, byte count and SHA-256 digest are recorded in
|
| 70 |
`samorzad_gov_pl.license-evidence.json`.
|
| 71 |
|
| 72 |
The fixed DynaWord schema does not contain article titles or URLs. Therefore,
|
| 73 |
`samorzad_gov_pl.attribution.jsonl` maps every released `id` to its title,
|
| 74 |
discovered `source_url`, fetched `final_url`, recommended `attribution_url`,
|
| 75 |
publishing institution, platform tenant, license URL and modification notice.
|
| 76 |
+
For 688 retained records the discovered and final URLs differ because the
|
| 77 |
platform redirected the request; `attribution_url` uses the fetched final URL.
|
| 78 |
|
| 79 |
Recommended attribution:
|
| 80 |
|
| 81 |
> Publishing institution listed in the `author` column; article title and
|
| 82 |
> canonical samorzad.gov.pl URL from the attribution sidecar; CC BY-SA 4.0.
|
| 83 |
+
> Article text was extracted from HTML, de-identified upstream and normalized
|
| 84 |
+
> for inclusion in Polish DynaWord.
|
| 85 |
|
| 86 |
Photographs, recordings, videos and attachment bytes are not redistributed.
|
| 87 |
The source platform gives audiovisual materials separate terms, and linked
|
|
|
|
| 92 |
|
| 93 |
| result | documents |
|
| 94 |
|---|---:|
|
| 95 |
+
| source records read | 81,418 |
|
| 96 |
+
| shorter than 200 characters | 6,932 |
|
| 97 |
+
| below the Polish-language heuristic | 34 |
|
| 98 |
+
| exact duplicate text | 1,980 |
|
| 99 |
+
| retained | 72,472 |
|
| 100 |
|
| 101 |
Exact duplicate removal is performed after short-text and language checks.
|
| 102 |
Existing DynaWord sources take priority when the same text is already present
|
|
|
|
| 104 |
|
| 105 |
## Limitations and recommended use
|
| 106 |
|
| 107 |
+
- Automated de-identification reduces but cannot guarantee removal of every
|
| 108 |
+
identifying value; downstream users should apply controls appropriate to
|
| 109 |
+
their use case.
|
| 110 |
- The collection is not a complete historical archive of samorzad.gov.pl. It
|
| 111 |
contains the pages found and successfully extracted during one crawl.
|
| 112 |
+
- After filtering, 51,964 retained records have an empty `created` value; no
|
| 113 |
+
date is inferred for them.
|
|
|
|
| 114 |
- The source text can contain spelling errors, extraction remnants or captions.
|
| 115 |
- Very short source records are excluded by DynaWord's 200-character minimum.
|
| 116 |
- Institution names describe the publishing body, not necessarily the person
|
|
|
|
| 130 |
## Reproduction
|
| 131 |
|
| 132 |
The converter refuses to build unless the downloaded `manifest.json` and all
|
| 133 |
+
10 Parquet shards match the pinned v0.2 release. It verifies the manifest
|
| 134 |
+
SHA-256, artifact set, shard sizes and SHA-256 values, row counts, schema,
|
| 135 |
+
unique record IDs and the release-wide record-text digest before conversion.
|
| 136 |
+
Outputs are written to temporary files, cross-checked, synced and
|
| 137 |
+
transactionally replaced; a failed replacement restores the previous artifact
|
| 138 |
+
set.
|
| 139 |
|
| 140 |
Download the published source Parquet shards and run:
|
| 141 |
|
| 142 |
```bash
|
| 143 |
hf download dawidmajewski/samorzad-gov-pl-articles \
|
| 144 |
--repo-type dataset \
|
| 145 |
+
--revision a998efea84bb0a62d94effc0b54f88b422d9898f \
|
| 146 |
--include 'data/*.parquet' --include manifest.json \
|
| 147 |
--local-dir /tmp/samorzad-gov-pl-articles
|
| 148 |
|
|
@@ -1,3 +1,3 @@
|
|
| 1 |
version https://git-lfs.github.com/spec/v1
|
| 2 |
-
oid sha256:
|
| 3 |
-
size
|
|
|
|
| 1 |
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:3a683b4220b9b70698d7c524637d9ea5c1d72630b8f92ea7a871642a719cf2c0
|
| 3 |
+
size 49612214
|
|
@@ -1,25 +1,29 @@
|
|
| 1 |
{
|
| 2 |
-
"authors_with_value":
|
| 3 |
"central_tenant_count": 1,
|
| 4 |
-
"chars":
|
| 5 |
-
"cross_source_hashes_loaded":
|
| 6 |
-
"drop_dup":
|
| 7 |
-
"drop_lang":
|
| 8 |
"drop_ocr": 0,
|
| 9 |
-
"drop_short":
|
| 10 |
-
"kept":
|
| 11 |
"license": "CC-BY-SA-4.0",
|
| 12 |
"licenses": {
|
| 13 |
-
"CC-BY-SA-4.0":
|
| 14 |
},
|
| 15 |
"local_public_tenant_count": 246,
|
| 16 |
"publisher_count": 247,
|
| 17 |
-
"read":
|
| 18 |
-
"redirected_urls":
|
| 19 |
-
"tokens":
|
| 20 |
"upstream_artifact_count": 10,
|
| 21 |
"upstream_dataset": "dawidmajewski/samorzad-gov-pl-articles",
|
| 22 |
-
"
|
| 23 |
-
"
|
| 24 |
-
"
|
|
|
|
|
|
|
|
|
|
|
|
|
| 25 |
}
|
|
|
|
| 1 |
{
|
| 2 |
+
"authors_with_value": 72472,
|
| 3 |
"central_tenant_count": 1,
|
| 4 |
+
"chars": 107130266,
|
| 5 |
+
"cross_source_hashes_loaded": 4255011,
|
| 6 |
+
"drop_dup": 1980,
|
| 7 |
+
"drop_lang": 34,
|
| 8 |
"drop_ocr": 0,
|
| 9 |
+
"drop_short": 6932,
|
| 10 |
+
"kept": 72472,
|
| 11 |
"license": "CC-BY-SA-4.0",
|
| 12 |
"licenses": {
|
| 13 |
+
"CC-BY-SA-4.0": 72472
|
| 14 |
},
|
| 15 |
"local_public_tenant_count": 246,
|
| 16 |
"publisher_count": 247,
|
| 17 |
+
"read": 81418,
|
| 18 |
+
"redirected_urls": 688,
|
| 19 |
+
"tokens": 40011099,
|
| 20 |
"upstream_artifact_count": 10,
|
| 21 |
"upstream_dataset": "dawidmajewski/samorzad-gov-pl-articles",
|
| 22 |
+
"upstream_deidentification_model": "ArkadiuszPawlak/fastpdn-ner-polish-pii",
|
| 23 |
+
"upstream_deidentification_model_revision": "636c57fe77b0afad8f065e7c76243dc051437035",
|
| 24 |
+
"upstream_deidentification_policy": "samorzad-pii-v3",
|
| 25 |
+
"upstream_manifest_sha256": "9d349bb271033fef62a051e311115460e030740f9593bb7f3158cb1437f87639",
|
| 26 |
+
"upstream_record_text_sha256": "9378f130ce26fc95015f661910e660f8bbe6442e75640089185f78052533377d",
|
| 27 |
+
"upstream_revision": "a998efea84bb0a62d94effc0b54f88b422d9898f",
|
| 28 |
+
"upstream_source_quality_excluded_records": 4
|
| 29 |
}
|
|
@@ -1,17 +1,17 @@
|
|
| 1 |
## Pattern frequency on corpus
|
| 2 |
|
| 3 |
-
- total tokens (tiktoken proxy): `9,639,
|
| 4 |
|
| 5 |
| pattern | count | share of all tokens |
|
| 6 |
|---|---:|---:|
|
| 7 |
-
| `w roku` | 585,
|
| 8 |
-
| `klasyfikacji` | 164,
|
| 9 |
-
| `ustawa` | 659,
|
| 10 |
-
| `artykuł` | 2,416,
|
| 11 |
-
| `parlament` | 1,285,
|
| 12 |
-
| `rozporządzenie` | 1,527,
|
| 13 |
-
| `w pobliżu` | 127,
|
| 14 |
-
| `mieszkańców` | 476,
|
| 15 |
| `Dz.U.` | 987,048 | 0.0102% |
|
| 16 |
|
| 17 |
| source | pattern | count | per-token share |
|
|
@@ -106,15 +106,15 @@
|
|
| 106 |
| parliamentary | `w pobliżu` | 4,964 | 0.00030% |
|
| 107 |
| parliamentary | `mieszkańców` | 78,048 | 0.00474% |
|
| 108 |
| parliamentary | `Dz.U.` | 23,809 | 0.00145% |
|
| 109 |
-
| samorzad_gov_pl | `w roku` | 3,
|
| 110 |
-
| samorzad_gov_pl | `klasyfikacji` | 520 | 0.
|
| 111 |
-
| samorzad_gov_pl | `ustawa` | 1,
|
| 112 |
-
| samorzad_gov_pl | `artykuł` | 1,269 | 0.
|
| 113 |
-
| samorzad_gov_pl | `parlament` | 1,
|
| 114 |
-
| samorzad_gov_pl | `rozporządzenie` | 1,
|
| 115 |
-
| samorzad_gov_pl | `w pobliżu` | 401 | 0.
|
| 116 |
-
| samorzad_gov_pl | `mieszkańców` | 14,
|
| 117 |
-
| samorzad_gov_pl | `Dz.U.` | 1,380 | 0.
|
| 118 |
| wikibooks | `w roku` | 319 | 0.00205% |
|
| 119 |
| wikibooks | `klasyfikacji` | 37 | 0.00024% |
|
| 120 |
| wikibooks | `ustawa` | 165 | 0.00106% |
|
|
@@ -169,6 +169,15 @@
|
|
| 169 |
| wikivoyage | `w pobliżu` | 6,480 | 0.03783% |
|
| 170 |
| wikivoyage | `mieszkańców` | 4,100 | 0.02394% |
|
| 171 |
| wikivoyage | `Dz.U.` | 1 | 0.00001% |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 172 |
| wolne_lektury | `w roku` | 1,898 | 0.00184% |
|
| 173 |
| wolne_lektury | `klasyfikacji` | 80 | 0.00008% |
|
| 174 |
| wolne_lektury | `ustawa` | 1,060 | 0.00103% |
|
|
|
|
| 1 |
## Pattern frequency on corpus
|
| 2 |
|
| 3 |
+
- total tokens (tiktoken proxy): `9,639,034,986`
|
| 4 |
|
| 5 |
| pattern | count | share of all tokens |
|
| 6 |
|---|---:|---:|
|
| 7 |
+
| `w roku` | 585,125 | 0.0061% |
|
| 8 |
+
| `klasyfikacji` | 164,762 | 0.0017% |
|
| 9 |
+
| `ustawa` | 659,092 | 0.0068% |
|
| 10 |
+
| `artykuł` | 2,416,403 | 0.0251% |
|
| 11 |
+
| `parlament` | 1,285,819 | 0.0133% |
|
| 12 |
+
| `rozporządzenie` | 1,527,449 | 0.0158% |
|
| 13 |
+
| `w pobliżu` | 127,816 | 0.0013% |
|
| 14 |
+
| `mieszkańców` | 476,772 | 0.0049% |
|
| 15 |
| `Dz.U.` | 987,048 | 0.0102% |
|
| 16 |
|
| 17 |
| source | pattern | count | per-token share |
|
|
|
|
| 106 |
| parliamentary | `w pobliżu` | 4,964 | 0.00030% |
|
| 107 |
| parliamentary | `mieszkańców` | 78,048 | 0.00474% |
|
| 108 |
| parliamentary | `Dz.U.` | 23,809 | 0.00145% |
|
| 109 |
+
| samorzad_gov_pl | `w roku` | 3,658 | 0.00914% |
|
| 110 |
+
| samorzad_gov_pl | `klasyfikacji` | 520 | 0.00130% |
|
| 111 |
+
| samorzad_gov_pl | `ustawa` | 1,786 | 0.00446% |
|
| 112 |
+
| samorzad_gov_pl | `artykuł` | 1,269 | 0.00317% |
|
| 113 |
+
| samorzad_gov_pl | `parlament` | 1,217 | 0.00304% |
|
| 114 |
+
| samorzad_gov_pl | `rozporządzenie` | 1,397 | 0.00349% |
|
| 115 |
+
| samorzad_gov_pl | `w pobliżu` | 401 | 0.00100% |
|
| 116 |
+
| samorzad_gov_pl | `mieszkańców` | 14,448 | 0.03611% |
|
| 117 |
+
| samorzad_gov_pl | `Dz.U.` | 1,380 | 0.00345% |
|
| 118 |
| wikibooks | `w roku` | 319 | 0.00205% |
|
| 119 |
| wikibooks | `klasyfikacji` | 37 | 0.00024% |
|
| 120 |
| wikibooks | `ustawa` | 165 | 0.00106% |
|
|
|
|
| 169 |
| wikivoyage | `w pobliżu` | 6,480 | 0.03783% |
|
| 170 |
| wikivoyage | `mieszkańców` | 4,100 | 0.02394% |
|
| 171 |
| wikivoyage | `Dz.U.` | 1 | 0.00001% |
|
| 172 |
+
| wiktionary_examples | `w roku` | 56 | 0.00502% |
|
| 173 |
+
| wiktionary_examples | `klasyfikacji` | 5 | 0.00045% |
|
| 174 |
+
| wiktionary_examples | `ustawa` | 26 | 0.00233% |
|
| 175 |
+
| wiktionary_examples | `artykuł` | 42 | 0.00376% |
|
| 176 |
+
| wiktionary_examples | `parlament` | 28 | 0.00251% |
|
| 177 |
+
| wiktionary_examples | `rozporządzenie` | 5 | 0.00045% |
|
| 178 |
+
| wiktionary_examples | `w pobliżu` | 32 | 0.00287% |
|
| 179 |
+
| wiktionary_examples | `mieszkańców` | 64 | 0.00574% |
|
| 180 |
+
| wiktionary_examples | `Dz.U.` | 0 | 0.00000% |
|
| 181 |
| wolne_lektury | `w roku` | 1,898 | 0.00184% |
|
| 182 |
| wolne_lektury | `klasyfikacji` | 80 | 0.00008% |
|
| 183 |
| wolne_lektury | `ustawa` | 1,060 | 0.00103% |
|
|
@@ -29,14 +29,14 @@ SOURCE = "samorzad_gov_pl"
|
|
| 29 |
LICENSE = "CC-BY-SA-4.0"
|
| 30 |
LICENSE_URL = "https://creativecommons.org/licenses/by-sa/4.0/"
|
| 31 |
UPSTREAM_DATASET = "dawidmajewski/samorzad-gov-pl-articles"
|
| 32 |
-
UPSTREAM_REVISION = "
|
| 33 |
-
UPSTREAM_TEXT_SHA256 = "
|
| 34 |
-
UPSTREAM_MANIFEST_SHA256 = "
|
| 35 |
UPSTREAM_EXPECTED = {
|
| 36 |
"manifest_sha256": UPSTREAM_MANIFEST_SHA256,
|
| 37 |
"dataset_id": UPSTREAM_DATASET,
|
| 38 |
"schema_version": "1.0.0",
|
| 39 |
-
"record_count":
|
| 40 |
"record_text_sha256": UPSTREAM_TEXT_SHA256,
|
| 41 |
}
|
| 42 |
MIN_CHARS = 200
|
|
@@ -251,9 +251,10 @@ def normalize_record(
|
|
| 251 |
"license_url": LICENSE_URL,
|
| 252 |
"modified": True,
|
| 253 |
"modification_notice": (
|
| 254 |
-
"Article text was extracted from the source HTML
|
| 255 |
-
"release normalizes metadata and may exclude
|
| 256 |
-
"duplicate records;
|
|
|
|
| 257 |
),
|
| 258 |
}
|
| 259 |
return row, attribution
|
|
@@ -394,6 +395,7 @@ def build(
|
|
| 394 |
seen = set(prior_hashes)
|
| 395 |
|
| 396 |
candidates: list[dict] = []
|
|
|
|
| 397 |
stats = {
|
| 398 |
"read": len(records),
|
| 399 |
"kept": 0,
|
|
@@ -420,6 +422,14 @@ def build(
|
|
| 420 |
"upstream_record_text_sha256": UPSTREAM_TEXT_SHA256,
|
| 421 |
"upstream_manifest_sha256": hashlib.sha256(manifest_path.read_bytes()).hexdigest(),
|
| 422 |
"upstream_artifact_count": len(manifest["artifacts"]),
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 423 |
}
|
| 424 |
for record in records:
|
| 425 |
text = str(record.get("text") or "").strip()
|
|
|
|
| 29 |
LICENSE = "CC-BY-SA-4.0"
|
| 30 |
LICENSE_URL = "https://creativecommons.org/licenses/by-sa/4.0/"
|
| 31 |
UPSTREAM_DATASET = "dawidmajewski/samorzad-gov-pl-articles"
|
| 32 |
+
UPSTREAM_REVISION = "a998efea84bb0a62d94effc0b54f88b422d9898f"
|
| 33 |
+
UPSTREAM_TEXT_SHA256 = "9378f130ce26fc95015f661910e660f8bbe6442e75640089185f78052533377d"
|
| 34 |
+
UPSTREAM_MANIFEST_SHA256 = "9d349bb271033fef62a051e311115460e030740f9593bb7f3158cb1437f87639"
|
| 35 |
UPSTREAM_EXPECTED = {
|
| 36 |
"manifest_sha256": UPSTREAM_MANIFEST_SHA256,
|
| 37 |
"dataset_id": UPSTREAM_DATASET,
|
| 38 |
"schema_version": "1.0.0",
|
| 39 |
+
"record_count": 81_418,
|
| 40 |
"record_text_sha256": UPSTREAM_TEXT_SHA256,
|
| 41 |
}
|
| 42 |
MIN_CHARS = 200
|
|
|
|
| 251 |
"license_url": LICENSE_URL,
|
| 252 |
"modified": True,
|
| 253 |
"modification_notice": (
|
| 254 |
+
"Article text was extracted from the source HTML and de-identified "
|
| 255 |
+
"upstream. This DynaWord release normalizes metadata and may exclude "
|
| 256 |
+
"short, non-Polish or duplicate records; retained text is otherwise "
|
| 257 |
+
"unchanged after upstream de-identification."
|
| 258 |
),
|
| 259 |
}
|
| 260 |
return row, attribution
|
|
|
|
| 395 |
seen = set(prior_hashes)
|
| 396 |
|
| 397 |
candidates: list[dict] = []
|
| 398 |
+
metadata = manifest["dataset_metadata"]
|
| 399 |
stats = {
|
| 400 |
"read": len(records),
|
| 401 |
"kept": 0,
|
|
|
|
| 422 |
"upstream_record_text_sha256": UPSTREAM_TEXT_SHA256,
|
| 423 |
"upstream_manifest_sha256": hashlib.sha256(manifest_path.read_bytes()).hexdigest(),
|
| 424 |
"upstream_artifact_count": len(manifest["artifacts"]),
|
| 425 |
+
"upstream_deidentification_model": metadata["deidentification_model"],
|
| 426 |
+
"upstream_deidentification_model_revision": metadata[
|
| 427 |
+
"deidentification_model_revision"
|
| 428 |
+
],
|
| 429 |
+
"upstream_deidentification_policy": metadata["deidentification_policy"],
|
| 430 |
+
"upstream_source_quality_excluded_records": metadata[
|
| 431 |
+
"source_quality_excluded_records"
|
| 432 |
+
],
|
| 433 |
}
|
| 434 |
for record in records:
|
| 435 |
text = str(record.get("text") or "").strip()
|
|
@@ -13,8 +13,8 @@ sys.path.insert(0, str(Path(__file__).resolve().parent))
|
|
| 13 |
from sources import SOURCES, EXCLUDED, ADDED
|
| 14 |
|
| 15 |
ROOT = Path(__file__).resolve().parent.parent
|
| 16 |
-
VERSION = "0.2.
|
| 17 |
-
RELEASE_DATE = "2026-08-
|
| 18 |
CONTACT = "k.wikiel@gmail.com" # notice-and-takedown / data-removal requests
|
| 19 |
|
| 20 |
# Dupochron: documented good-faith provenance + no-warranty + takedown + PII.
|
|
@@ -186,8 +186,9 @@ family (Enevoldsen et al., [arXiv:2508.02271](https://arxiv.org/abs/2508.02271))
|
|
| 186 |
|
| 187 |
| version | status | documents | tokens | notes |
|
| 188 |
|---|---|---:|---:|---|
|
| 189 |
-
| `v0.2.
|
| 190 |
-
| `v0.2.
|
|
|
|
| 191 |
| `v0.2.3` | previous stable | 2,710,974 | 6.88B | Adds community-contributed `european_hplt_v3_pl`, `global_voices` and `nkjp1m`. |
|
| 192 |
| `v0.2.2` | previous stable | 2,579,963 | 6.36B | Added community-contributed `govpl`: 88,190 docs / 80.7M tokens. |
|
| 193 |
| `v0.2.1` | previous stable | 2,491,773 | 6.28B | 12-source corpus with `license` and `author` metadata columns; added `1000_novels`. |
|
|
@@ -204,7 +205,14 @@ family (Enevoldsen et al., [arXiv:2508.02271](https://arxiv.org/abs/2508.02271))
|
|
| 204 |
|
| 205 |
### Version details
|
| 206 |
|
| 207 |
-
#### v0.2.
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 208 |
|
| 209 |
Added `samorzad_gov_pl`, a directly collected corpus of articles from 246
|
| 210 |
Polish local public institutions and one central platform tenant. The
|
|
@@ -296,7 +304,7 @@ as the redistributing aggregator; this release does not claim ownership of them
|
|
| 296 |
| [Bart Kobyliński](https://huggingface.co/bartoszkobylinski1) | Added `1000_novels`; expanded Biblioteka Nauki and Europeana ingestion with per-document license and author metadata. | `v0.2.1`, [PR #1](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/1) |
|
| 297 |
| [Paweł Puzio](https://huggingface.co/ppuzio) | Built `govpl`: subsite discovery, direct ingestion pipeline, dataset artifact, contract tests and documentation. | `v0.2.2`, [PR #9](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/9) |
|
| 298 |
| [Arkadiusz Słota](https://huggingface.co/Maggio33) | Built & expanded `european_hplt_v3_pl`: HPLT v3 WDS 10+9 (PR #5) then WDS 10-5 expansion (+1,493,384 docs / 2.04B tok), modular cleaning pipeline, phone-recall PII-scrub (v12b, independent dual-lens), cross-source dedup-vs-base (zero-overlap), validation and documentation. | `v0.2.3` (PR #5), `v0.2.4` |
|
| 299 |
-
| [Dawid Majewski](https://huggingface.co/dawidmajewski) | Added the reviewed Global Voices Polish corpus; built `samorzad_gov_pl` with direct acquisition, institution attribution, licensing evidence, release
|
| 300 |
| [1am](https://huggingface.co/1am) | Added `nkjp1m`: the manually annotated 1-million-word NKJP subcorpus, direct fetch/build pipeline, source documentation and release artifact. | `v0.2.3`, [PR #8](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/8) |
|
| 301 |
|
| 302 |
Contributions are credited when they add a verifiable dataset artifact, pipeline,
|
|
|
|
| 13 |
from sources import SOURCES, EXCLUDED, ADDED
|
| 14 |
|
| 15 |
ROOT = Path(__file__).resolve().parent.parent
|
| 16 |
+
VERSION = "0.2.6"
|
| 17 |
+
RELEASE_DATE = "2026-08-22"
|
| 18 |
CONTACT = "k.wikiel@gmail.com" # notice-and-takedown / data-removal requests
|
| 19 |
|
| 20 |
# Dupochron: documented good-faith provenance + no-warranty + takedown + PII.
|
|
|
|
| 186 |
|
| 187 |
| version | status | documents | tokens | notes |
|
| 188 |
|---|---|---:|---:|---|
|
| 189 |
+
| `v0.2.6` | stable release | {tot_doc:,} | {tot_tok/1e9:.2f}B | Updates `samorzad_gov_pl` from the de-identified upstream v0.2 release and includes `wiktionary_examples` in stable totals. |
|
| 190 |
+
| `v0.2.5` | previous stable | 4,319,200 | 9.64B | Added community-contributed `samorzad_gov_pl` with institution-level author attribution and a URL-bearing attribution sidecar. |
|
| 191 |
+
| `v0.2.4` | previous stable | 4,246,429 | 9.60B | Expanded `european_hplt_v3_pl` to WDS bins 10-5 (+1.49M docs / 2.04B tok); phone PII-scrub hardening (independent dual-lens) + cross-source dedup (zero-overlap). |
|
| 192 |
| `v0.2.3` | previous stable | 2,710,974 | 6.88B | Adds community-contributed `european_hplt_v3_pl`, `global_voices` and `nkjp1m`. |
|
| 193 |
| `v0.2.2` | previous stable | 2,579,963 | 6.36B | Added community-contributed `govpl`: 88,190 docs / 80.7M tokens. |
|
| 194 |
| `v0.2.1` | previous stable | 2,491,773 | 6.28B | 12-source corpus with `license` and `author` metadata columns; added `1000_novels`. |
|
|
|
|
| 205 |
|
| 206 |
### Version details
|
| 207 |
|
| 208 |
+
#### v0.2.6 — current stable
|
| 209 |
+
|
| 210 |
+
Updated `samorzad_gov_pl` to the filtered and de-identified upstream v0.2
|
| 211 |
+
release: **72,472 documents / 40,011,099 cl100k-proxy tokens**. The conversion
|
| 212 |
+
remains pinned by revision, manifest SHA-256 and record-text digest. Stable
|
| 213 |
+
totals now also include the previously merged `wiktionary_examples` source.
|
| 214 |
+
|
| 215 |
+
#### v0.2.5 — previous stable
|
| 216 |
|
| 217 |
Added `samorzad_gov_pl`, a directly collected corpus of articles from 246
|
| 218 |
Polish local public institutions and one central platform tenant. The
|
|
|
|
| 304 |
| [Bart Kobyliński](https://huggingface.co/bartoszkobylinski1) | Added `1000_novels`; expanded Biblioteka Nauki and Europeana ingestion with per-document license and author metadata. | `v0.2.1`, [PR #1](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/1) |
|
| 305 |
| [Paweł Puzio](https://huggingface.co/ppuzio) | Built `govpl`: subsite discovery, direct ingestion pipeline, dataset artifact, contract tests and documentation. | `v0.2.2`, [PR #9](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/9) |
|
| 306 |
| [Arkadiusz Słota](https://huggingface.co/Maggio33) | Built & expanded `european_hplt_v3_pl`: HPLT v3 WDS 10+9 (PR #5) then WDS 10-5 expansion (+1,493,384 docs / 2.04B tok), modular cleaning pipeline, phone-recall PII-scrub (v12b, independent dual-lens), cross-source dedup-vs-base (zero-overlap), validation and documentation. | `v0.2.3` (PR #5), `v0.2.4` |
|
| 307 |
+
| [Dawid Majewski](https://huggingface.co/dawidmajewski) | Added the reviewed Global Voices Polish corpus; built and updated `samorzad_gov_pl` with direct acquisition, de-identification, institution attribution, licensing evidence, release artifacts and reproducible conversion. | `v0.2.3`, [PR #7](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/7); `v0.2.5`, `v0.2.6` |
|
| 308 |
| [1am](https://huggingface.co/1am) | Added `nkjp1m`: the manually annotated 1-million-word NKJP subcorpus, direct fetch/build pipeline, source documentation and release artifact. | `v0.2.3`, [PR #8](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/8) |
|
| 309 |
|
| 310 |
Contributions are credited when they add a verifiable dataset artifact, pipeline,
|
|
@@ -232,12 +232,13 @@ SOURCES = {
|
|
| 232 |
"license": "CC-BY-SA-4.0",
|
| 233 |
"license_spdx": "CC-BY-SA-4.0",
|
| 234 |
"traceable": "The shared samorzad.gov.pl platform footer publishes textual "
|
| 235 |
-
"content under CC BY-SA 4.0.
|
| 236 |
-
"
|
|
|
|
| 237 |
"attachment bytes are not redistributed.",
|
| 238 |
"upstream": "https://huggingface.co/datasets/dawidmajewski/samorzad-gov-pl-articles",
|
| 239 |
-
"provenance": "Converted reproducibly from the published v0.
|
| 240 |
-
"by src/clean_samorzad_gov_pl.py. The source was collected "
|
| 241 |
"directly from public samorzad.gov.pl pages across 246 local "
|
| 242 |
"public institutions and one central platform tenant. "
|
| 243 |
"Institution display names are frozen "
|
|
|
|
| 232 |
"license": "CC-BY-SA-4.0",
|
| 233 |
"license_spdx": "CC-BY-SA-4.0",
|
| 234 |
"traceable": "The shared samorzad.gov.pl platform footer publishes textual "
|
| 235 |
+
"content under CC BY-SA 4.0. The v0.2 source release is a "
|
| 236 |
+
"de-identified subset of the audited v0.1 pages, all of which "
|
| 237 |
+
"referenced the shared footer script; audiovisual media and "
|
| 238 |
"attachment bytes are not redistributed.",
|
| 239 |
"upstream": "https://huggingface.co/datasets/dawidmajewski/samorzad-gov-pl-articles",
|
| 240 |
+
"provenance": "Converted reproducibly from the published, de-identified v0.2 "
|
| 241 |
+
"source dataset by src/clean_samorzad_gov_pl.py. The source was collected "
|
| 242 |
"directly from public samorzad.gov.pl pages across 246 local "
|
| 243 |
"public institutions and one central platform tenant. "
|
| 244 |
"Institution display names are frozen "
|
|
@@ -73,6 +73,7 @@ def test_normalize_record_maps_publisher_to_author_and_preserves_provenance():
|
|
| 73 |
assert attribution["title"] == source["title"]
|
| 74 |
assert attribution["license_url"] == "https://creativecommons.org/licenses/by-sa/4.0/"
|
| 75 |
assert attribution["modified"] is True
|
|
|
|
| 76 |
|
| 77 |
|
| 78 |
def test_verify_upstream_release_rejects_modified_shard(tmp_path):
|
|
@@ -183,14 +184,24 @@ def test_release_artifact_matches_stats_and_has_institution_authors():
|
|
| 183 |
|
| 184 |
assert table.schema == DYNAWORD_SCHEMA
|
| 185 |
assert table.num_rows == stats["kept"] == len(attributions)
|
|
|
|
|
|
|
| 186 |
assert stats["authors_with_value"] == stats["kept"]
|
| 187 |
assert stats["publisher_count"] == 247
|
| 188 |
assert stats["local_public_tenant_count"] == 246
|
| 189 |
assert stats["central_tenant_count"] == 1
|
| 190 |
-
assert stats["redirected_urls"] ==
|
| 191 |
assert stats["upstream_artifact_count"] == 10
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 192 |
assert stats["upstream_manifest_sha256"] == (
|
| 193 |
-
"
|
| 194 |
)
|
| 195 |
assert set(table["source"].to_pylist()) == {"samorzad_gov_pl"}
|
| 196 |
assert set(table["license"].to_pylist()) == {"CC-BY-SA-4.0"}
|
|
|
|
| 73 |
assert attribution["title"] == source["title"]
|
| 74 |
assert attribution["license_url"] == "https://creativecommons.org/licenses/by-sa/4.0/"
|
| 75 |
assert attribution["modified"] is True
|
| 76 |
+
assert "de-identified upstream" in attribution["modification_notice"]
|
| 77 |
|
| 78 |
|
| 79 |
def test_verify_upstream_release_rejects_modified_shard(tmp_path):
|
|
|
|
| 184 |
|
| 185 |
assert table.schema == DYNAWORD_SCHEMA
|
| 186 |
assert table.num_rows == stats["kept"] == len(attributions)
|
| 187 |
+
assert stats["read"] == 81_418
|
| 188 |
+
assert stats["kept"] == 72_472
|
| 189 |
assert stats["authors_with_value"] == stats["kept"]
|
| 190 |
assert stats["publisher_count"] == 247
|
| 191 |
assert stats["local_public_tenant_count"] == 246
|
| 192 |
assert stats["central_tenant_count"] == 1
|
| 193 |
+
assert stats["redirected_urls"] == 688
|
| 194 |
assert stats["upstream_artifact_count"] == 10
|
| 195 |
+
assert stats["upstream_deidentification_model"] == (
|
| 196 |
+
"ArkadiuszPawlak/fastpdn-ner-polish-pii"
|
| 197 |
+
)
|
| 198 |
+
assert stats["upstream_deidentification_model_revision"] == (
|
| 199 |
+
"636c57fe77b0afad8f065e7c76243dc051437035"
|
| 200 |
+
)
|
| 201 |
+
assert stats["upstream_deidentification_policy"] == "samorzad-pii-v3"
|
| 202 |
+
assert stats["upstream_source_quality_excluded_records"] == 4
|
| 203 |
assert stats["upstream_manifest_sha256"] == (
|
| 204 |
+
"9d349bb271033fef62a051e311115460e030740f9593bb7f3158cb1437f87639"
|
| 205 |
)
|
| 206 |
assert set(table["source"].to_pylist()) == {"samorzad_gov_pl"}
|
| 207 |
assert set(table["license"].to_pylist()) == {"CC-BY-SA-4.0"}
|