
Datasets:


Commit ·
8cc48a3
1
Parent(s): 85e7d9b
feat(data): add samorzad.gov.pl institutional corpus (#13)
Browse files- feat(data): add samorzad.gov.pl institutional corpus (099af7a866374ce5206afb62e7dd9b65a32fb8fa)
Co-authored-by: Dawid Majewski <dawidmajewski@users.noreply.huggingface.co>
- .gitattributes +1 -0
- CHANGELOG.md +21 -0
- README.md +58 -32
- artifacts/dataset_size_by_version.png +2 -2
- artifacts/pattern_frequency_artykul.png +2 -2
- artifacts/pattern_frequency_dzu.png +2 -2
- artifacts/pattern_frequency_hf_snippet.md +37 -19
- artifacts/pattern_frequency_klasyfikacji.png +2 -2
- artifacts/pattern_frequency_mieszkańców.png +2 -2
- artifacts/pattern_frequency_overall.png +2 -2
- artifacts/pattern_frequency_parlament.png +2 -2
- artifacts/pattern_frequency_rozporządzenie.png +2 -2
- artifacts/pattern_frequency_ustawa.png +2 -2
- artifacts/pattern_frequency_w_pobliżu.png +2 -2
- artifacts/pattern_frequency_w_roku.png +2 -2
- data/samorzad_gov_pl/NOTICE.md +28 -0
- data/samorzad_gov_pl/samorzad_gov_pl.attribution.jsonl +3 -0
- data/samorzad_gov_pl/samorzad_gov_pl.license-evidence.json +17 -0
- data/samorzad_gov_pl/samorzad_gov_pl.md +138 -0
- data/samorzad_gov_pl/samorzad_gov_pl.parquet +3 -0
- data/samorzad_gov_pl/samorzad_gov_pl.stats.json +25 -0
- pattern_frequency_report.md +37 -19
- src/clean_samorzad_gov_pl.py +513 -0
- src/make_docs.py +17 -9
- src/plot_version_growth.py +17 -3
- src/samorzad_gov_pl_publishers.json +253 -0
- src/sources.py +23 -0
- src/test_samorzad_gov_pl_contract.py +209 -0
.gitattributes
CHANGED
|
@@ -35,6 +35,7 @@ saved_model/**/* filter=lfs diff=lfs merge=lfs -text
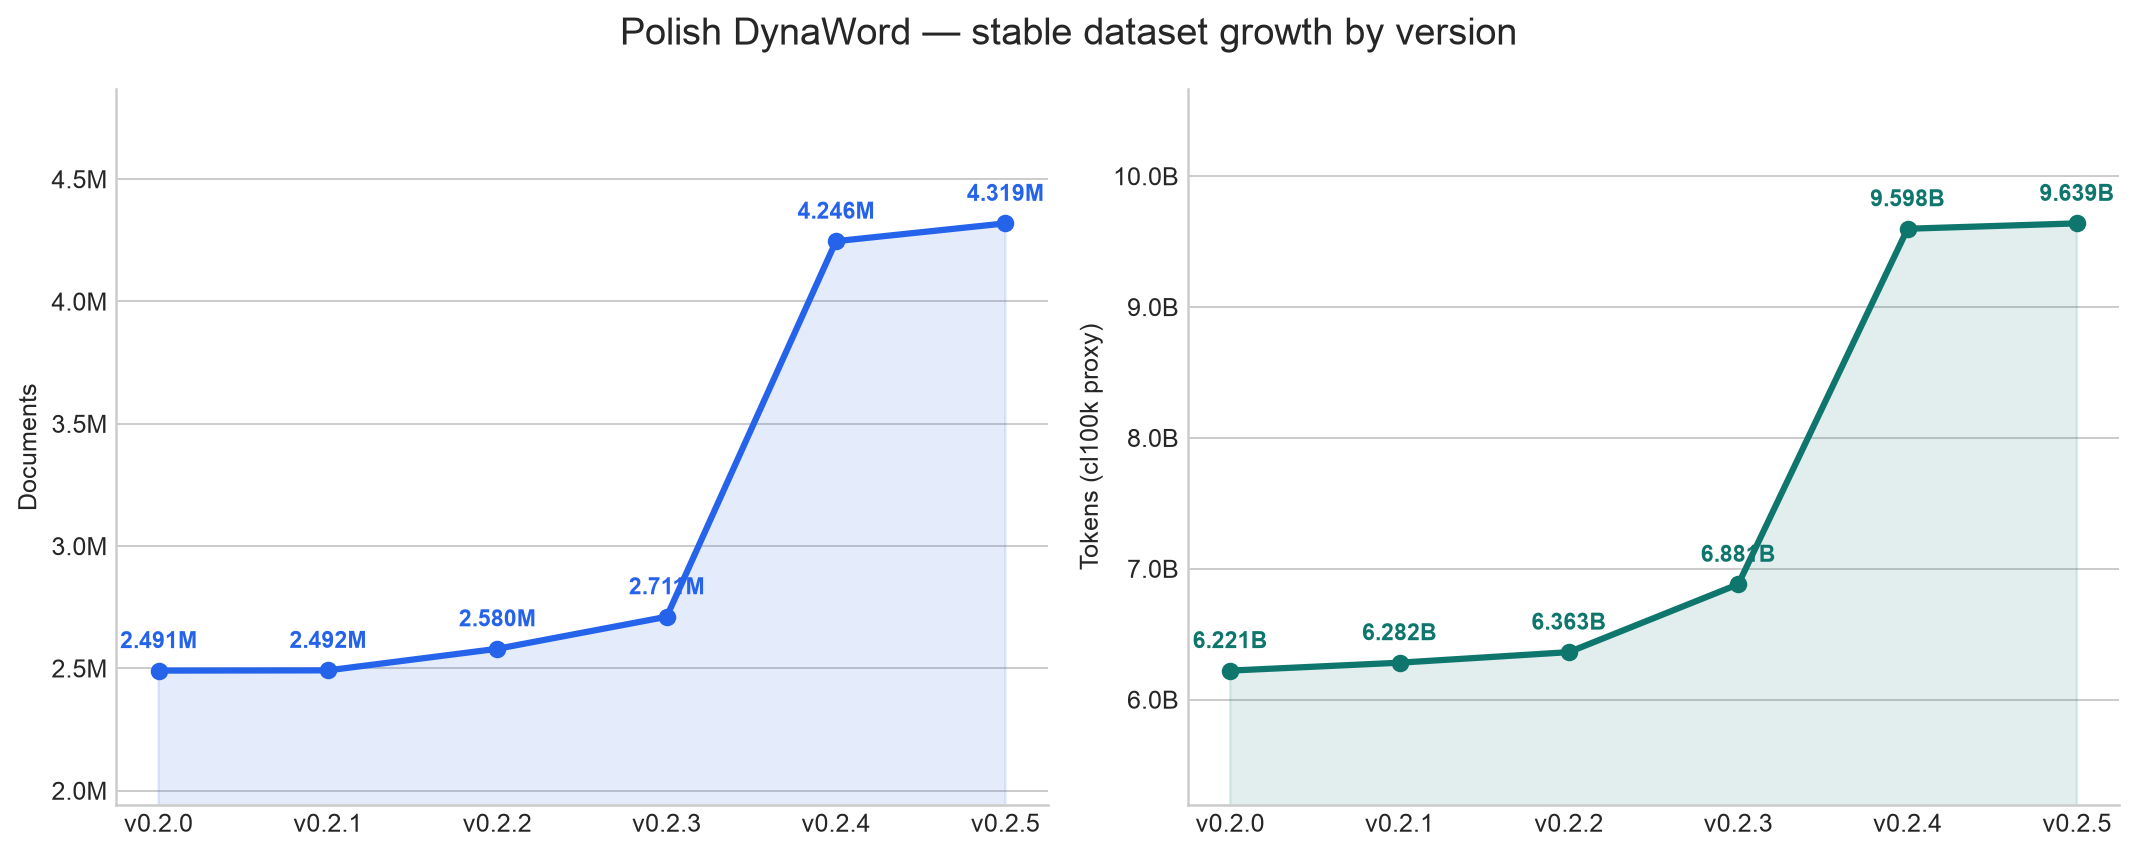
|
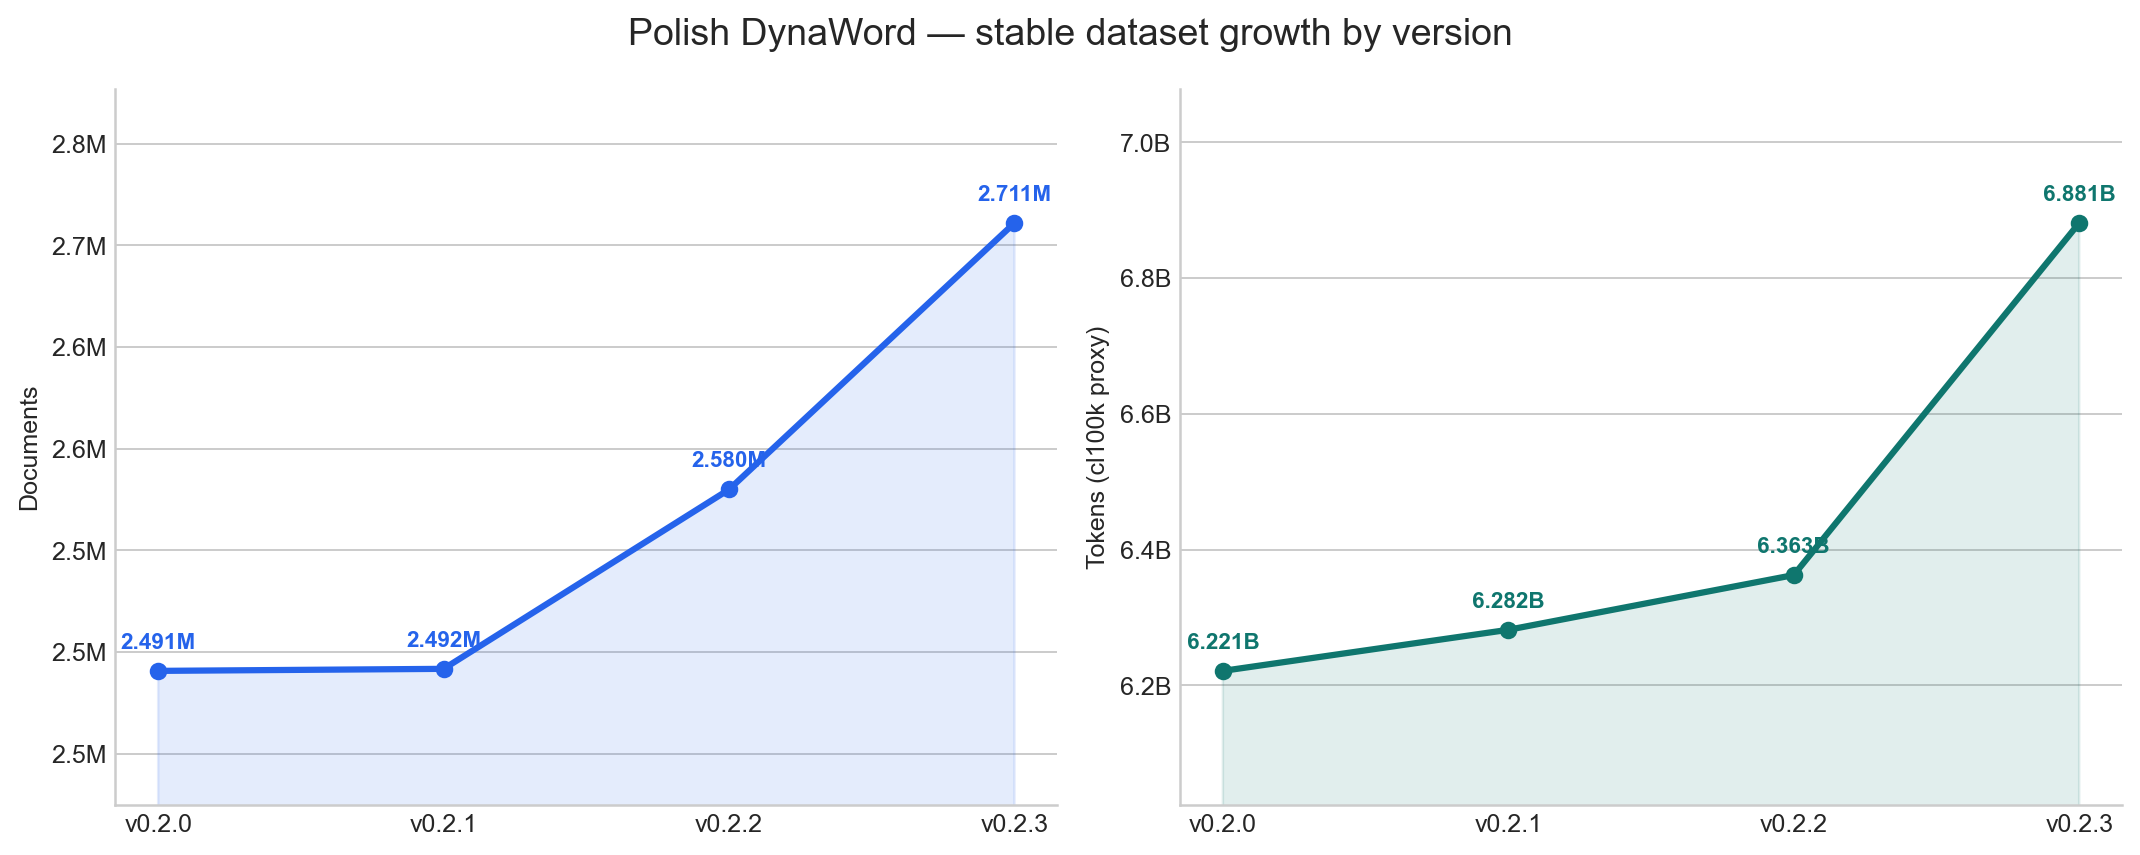
|
| 35 |
*.xz filter=lfs diff=lfs merge=lfs -text
|
| 36 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 37 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
|
|
|
| 38 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 39 |
# Audio files - uncompressed
|
| 40 |
*.pcm filter=lfs diff=lfs merge=lfs -text
|
|
|
|
| 35 |
*.xz filter=lfs diff=lfs merge=lfs -text
|
| 36 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 37 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 38 |
+
data/samorzad_gov_pl/*.jsonl filter=lfs diff=lfs merge=lfs -text
|
| 39 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 40 |
# Audio files - uncompressed
|
| 41 |
*.pcm filter=lfs diff=lfs merge=lfs -text
|
CHANGELOG.md
CHANGED
|
@@ -1,5 +1,26 @@
|
|
| 1 |
# Changelog
|
| 2 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 3 |
## v0.2.4 (2026-08-07)
|
| 4 |
|
| 5 |
- Expanded `european_hplt_v3_pl` (Arkadiusz Słota / `Maggio33`) from HPLT v3.0
|
|
|
|
| 1 |
# Changelog
|
| 2 |
|
| 3 |
+
## v0.2.5 (2026-08-14)
|
| 4 |
+
|
| 5 |
+
- Added the community contribution `samorzad_gov_pl` by Dawid Majewski
|
| 6 |
+
(`dawidmajewski`): 72,771 Polish articles / 41,154,506 cl100k-proxy tokens
|
| 7 |
+
from 246 local public institutions and one central platform tenant using the
|
| 8 |
+
shared samorzad.gov.pl platform.
|
| 9 |
+
- Converted the published, directly collected source dataset at revision
|
| 10 |
+
`d5eaefc32c3f17cfa5a01d14573f8e4ee7d43385`; retained 72,771 of 81,422
|
| 11 |
+
records after dropping 6,624 short, 35 below the Polish-language heuristic
|
| 12 |
+
and 1,992 exact-duplicate records.
|
| 13 |
+
- Preserved the human-readable publishing institution in every `author` value.
|
| 14 |
+
Added a 72,771-record attribution sidecar with discovered source URLs,
|
| 15 |
+
fetched final URLs, recommended attribution URLs, titles, institution names,
|
| 16 |
+
license URLs and modification notices.
|
| 17 |
+
- Added the frozen 247-institution publisher manifest, reproducible conversion
|
| 18 |
+
script, contract tests, source datasheet, NOTICE and release-time license
|
| 19 |
+
evidence. The live shared footer script matched the audited SHA-256
|
| 20 |
+
`b36ec507901ed443195479d8d8009386159ae59d7486ce266bfb3308043e99aa`.
|
| 21 |
+
- Recomputed complete-corpus totals: 4,319,200 documents and 9,639,062,573
|
| 22 |
+
cl100k-proxy tokens across 18 sources.
|
| 23 |
+
|
| 24 |
## v0.2.4 (2026-08-07)
|
| 25 |
|
| 26 |
- Expanded `european_hplt_v3_pl` (Arkadiusz Słota / `Maggio33`) from HPLT v3.0
|
README.md
CHANGED
|
@@ -19,13 +19,13 @@ A continuously developed, **openly-licensed**, human-text Polish corpus — a Po
|
|
| 19 |
edition in the [Dynaword](https://huggingface.co/datasets/danish-foundation-models/danish-dynaword)
|
| 20 |
family (Enevoldsen et al., [arXiv:2508.02271](https://arxiv.org/abs/2508.02271)).
|
| 21 |
|
| 22 |
-
> **v0.2.
|
| 23 |
-
> (tiktoken proxy; canonical Llama-3 count at release) ·
|
| 24 |
-
> Updated: **2026-08-
|
| 25 |
|
| 26 |
> **v0.3-dev experimental track** · quality/diversity workflow, source-gate
|
| 27 |
> validation and candidate-data audits. This is development work, not a released
|
| 28 |
-
> corpus version, and it does not replace the v0.2.
|
| 29 |
|
| 30 |
> **Europeana validation artifact (2026-07-10)** · a separate reproducible
|
| 31 |
> 810-document direct-ingestion sample stored under the legacy path
|
|
@@ -37,7 +37,8 @@ family (Enevoldsen et al., [arXiv:2508.02271](https://arxiv.org/abs/2508.02271))
|
|
| 37 |
|
| 38 |
| version | status | documents | tokens | notes |
|
| 39 |
|---|---|---:|---:|---|
|
| 40 |
-
| `v0.2.
|
|
|
|
| 41 |
| `v0.2.3` | previous stable | 2,710,974 | 6.88B | Adds community-contributed `european_hplt_v3_pl`, `global_voices` and `nkjp1m`. |
|
| 42 |
| `v0.2.2` | previous stable | 2,579,963 | 6.36B | Added community-contributed `govpl`: 88,190 docs / 80.7M tokens. |
|
| 43 |
| `v0.2.1` | previous stable | 2,491,773 | 6.28B | 12-source corpus with `license` and `author` metadata columns; added `1000_novels`. |
|
|
@@ -54,7 +55,15 @@ family (Enevoldsen et al., [arXiv:2508.02271](https://arxiv.org/abs/2508.02271))
|
|
| 54 |
|
| 55 |
### Version details
|
| 56 |
|
| 57 |
-
#### v0.2.
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 58 |
|
| 59 |
Expanded `european_hplt_v3_pl` from WDS bins 10+9 to **WDS bins 10-5** (added
|
| 60 |
quality bins 8/7/6/5 and further WDS-9 shards): **+1,493,384 documents /
|
|
@@ -138,7 +147,7 @@ as the redistributing aggregator; this release does not claim ownership of them
|
|
| 138 |
| [Bart Kobyliński](https://huggingface.co/bartoszkobylinski1) | Added `1000_novels`; expanded Biblioteka Nauki and Europeana ingestion with per-document license and author metadata. | `v0.2.1`, [PR #1](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/1) |
|
| 139 |
| [Paweł Puzio](https://huggingface.co/ppuzio) | Built `govpl`: subsite discovery, direct ingestion pipeline, dataset artifact, contract tests and documentation. | `v0.2.2`, [PR #9](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/9) |
|
| 140 |
| [Arkadiusz Słota](https://huggingface.co/Maggio33) | Built & expanded `european_hplt_v3_pl`: HPLT v3 WDS 10+9 (PR #5) then WDS 10-5 expansion (+1,493,384 docs / 2.04B tok), modular cleaning pipeline, phone-recall PII-scrub (v12b, independent dual-lens), cross-source dedup-vs-base (zero-overlap), validation and documentation. | `v0.2.3` (PR #5), `v0.2.4` |
|
| 141 |
-
| [Dawid Majewski](https://huggingface.co/dawidmajewski) | Added the reviewed Global Voices Polish corpus with
|
| 142 |
| [1am](https://huggingface.co/1am) | Added `nkjp1m`: the manually annotated 1-million-word NKJP subcorpus, direct fetch/build pipeline, source documentation and release artifact. | `v0.2.3`, [PR #8](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/8) |
|
| 143 |
|
| 144 |
Contributions are credited when they add a verifiable dataset artifact, pipeline,
|
|
@@ -165,6 +174,7 @@ files is not listed as a data contribution.
|
|
| 165 |
| [wolne_lektury](data/wolne_lektury/wolne_lektury.md) | Wolne Lektury (school readings) | `CC-BY-SA-4.0 / Wolna Sztuka 1.3` | 6,141 | 103.0M |
|
| 166 |
| [govpl](data/govpl/govpl.md) | gov.pl — Polish government press releases | `CC-BY-SA-4.0` | 88,190 | 80.7M |
|
| 167 |
| [1000_novels](data/1000_novels/1000_novels.md) | 1000 Novels Corpus (CLARIN-PL) | `CC-BY-4.0` | 1,000 | 60.5M |
|
|
|
|
| 168 |
| [wikiquote](data/wikiquote/wikiquote.md) | Polish Wikiquote (quotations) | `CC-BY-SA-3.0` | 30,363 | 31.9M |
|
| 169 |
| [eltec_pol](data/eltec_pol/eltec_pol.md) | ELTeC-pol (European Literary Text Collection, Polish) | `CC-BY-4.0` | 100 | 21.5M |
|
| 170 |
| [wikivoyage](data/wikivoyage/wikivoyage.md) | Polish Wikivoyage (travel guides) | `CC-BY-SA-3.0` | 13,645 | 17.1M |
|
|
@@ -203,16 +213,15 @@ workflow therefore separates **source inclusion** from **training mix**:
|
|
| 203 |
|
| 204 |
Current v0.3 source-ingestion status:
|
| 205 |
|
| 206 |
-
- `biblioteka_nauki`:
|
| 207 |
-
|
| 208 |
-
v0.2.4 parquets yet.
|
| 209 |
- `europeana`: prepared in the source registry as a direct-upstream rebuild
|
| 210 |
target with per-record rights statements and creator metadata; raw SpeakLeash
|
| 211 |
Europeana remains excluded.
|
| 212 |
- Europeana release policy: split conservatively at pre-1929 records for
|
| 213 |
US-sensitive downstream reuse, and keep later/unknown records separately
|
| 214 |
labeled or held until legal review.
|
| 215 |
-
- `european_hplt_v3_pl`: WDS bins 10
|
| 216 |
validation. HPLT packaging is CC0, while underlying crawled web documents can
|
| 217 |
carry independent rights; downstream near-dedup and web-content review remain
|
| 218 |
recommended before training.
|
|
@@ -282,21 +291,21 @@ python3 src/make_docs.py
|
|
| 282 |
|
| 283 |
### Corpus phrase frequency (normalized by tokens)
|
| 284 |
|
| 285 |
-
Raw counts and token-normalized shares are regenerated from the current
|
| 286 |
|
| 287 |
-
- Total token count (tiktoken proxy): **
|
| 288 |
|
| 289 |
| Pattern | Count | Share of all tokens |
|
| 290 |
|---|---:|---:|
|
| 291 |
-
| `w roku` |
|
| 292 |
-
| `klasyfikacji` |
|
| 293 |
-
| `ustawa` |
|
| 294 |
-
| `artykuł` | 2,
|
| 295 |
-
| `parlament` | 1,
|
| 296 |
-
| `rozporządzenie` | 1,
|
| 297 |
-
| `w pobliżu` |
|
| 298 |
-
| `mieszkańców` |
|
| 299 |
-
| `Dz.U.` |
|
| 300 |
|
| 301 |
### Per-source shares
|
| 302 |
|
|
@@ -311,6 +320,15 @@ Raw counts and token-normalized shares are regenerated from the current parquet
|
|
| 311 |
| `1000_novels` | `w pobliżu` | 1,262 | 0.00209% |
|
| 312 |
| `1000_novels` | `mieszkańców` | 868 | 0.00143% |
|
| 313 |
| `1000_novels` | `Dz.U.` | 0 | 0.00000% |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 314 |
| `dziennik_ustaw` | `w roku` | 33,096 | 0.00681% |
|
| 315 |
| `dziennik_ustaw` | `klasyfikacji` | 10,896 | 0.00224% |
|
| 316 |
| `dziennik_ustaw` | `ustawa` | 77,376 | 0.01592% |
|
|
@@ -338,15 +356,15 @@ Raw counts and token-normalized shares are regenerated from the current parquet
|
|
| 338 |
| `eurlex` | `w pobliżu` | 6,088 | 0.00026% |
|
| 339 |
| `eurlex` | `mieszkańców` | 9,441 | 0.00040% |
|
| 340 |
| `eurlex` | `Dz.U.` | 915,707 | 0.03851% |
|
| 341 |
-
| `european_hplt_v3_pl` | `w roku` |
|
| 342 |
-
| `european_hplt_v3_pl` | `klasyfikacji` |
|
| 343 |
-
| `european_hplt_v3_pl` | `ustawa` |
|
| 344 |
-
| `european_hplt_v3_pl` | `artykuł` |
|
| 345 |
-
| `european_hplt_v3_pl` | `parlament` |
|
| 346 |
-
| `european_hplt_v3_pl` | `rozporządzenie` |
|
| 347 |
-
| `european_hplt_v3_pl` | `w pobliżu` |
|
| 348 |
-
| `european_hplt_v3_pl` | `mieszkańców` |
|
| 349 |
-
| `european_hplt_v3_pl` | `Dz.U.` |
|
| 350 |
| `global_voices` | `w roku` | 160 | 0.00431% |
|
| 351 |
| `global_voices` | `klasyfikacji` | 5 | 0.00013% |
|
| 352 |
| `global_voices` | `ustawa` | 157 | 0.00423% |
|
|
@@ -383,6 +401,15 @@ Raw counts and token-normalized shares are regenerated from the current parquet
|
|
| 383 |
| `parliamentary` | `w pobliżu` | 4,964 | 0.00030% |
|
| 384 |
| `parliamentary` | `mieszkańców` | 78,048 | 0.00474% |
|
| 385 |
| `parliamentary` | `Dz.U.` | 23,809 | 0.00145% |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 386 |
| `wikibooks` | `w roku` | 319 | 0.00205% |
|
| 387 |
| `wikibooks` | `klasyfikacji` | 37 | 0.00024% |
|
| 388 |
| `wikibooks` | `ustawa` | 165 | 0.00106% |
|
|
@@ -458,4 +485,3 @@ Raw counts and token-normalized shares are regenerated from the current parquet
|
|
| 458 |

|
| 459 |

|
| 460 |

|
| 461 |
-
|
|
|
|
| 19 |
edition in the [Dynaword](https://huggingface.co/datasets/danish-foundation-models/danish-dynaword)
|
| 20 |
family (Enevoldsen et al., [arXiv:2508.02271](https://arxiv.org/abs/2508.02271)).
|
| 21 |
|
| 22 |
+
> **v0.2.5 stable** · 4,319,200 documents · **9.64B tokens**
|
| 23 |
+
> (tiktoken proxy; canonical Llama-3 count at release) · 18 sources
|
| 24 |
+
> Updated: **2026-08-14**
|
| 25 |
|
| 26 |
> **v0.3-dev experimental track** · quality/diversity workflow, source-gate
|
| 27 |
> validation and candidate-data audits. This is development work, not a released
|
| 28 |
+
> corpus version, and it does not replace the v0.2.5 stable parquets.
|
| 29 |
|
| 30 |
> **Europeana validation artifact (2026-07-10)** · a separate reproducible
|
| 31 |
> 810-document direct-ingestion sample stored under the legacy path
|
|
|
|
| 37 |
|
| 38 |
| version | status | documents | tokens | notes |
|
| 39 |
|---|---|---:|---:|---|
|
| 40 |
+
| `v0.2.5` | stable release | 4,319,200 | 9.64B | Adds community-contributed `samorzad_gov_pl` with institution-level author attribution and a URL-bearing attribution sidecar. |
|
| 41 |
+
| `v0.2.4` | previous stable | 4,246,429 | 9.60B | Expanded `european_hplt_v3_pl` to WDS bins 10-5 (+1.49M docs / 2.04B tok); phone PII-scrub hardening (independent dual-lens) + cross-source dedup (zero-overlap). |
|
| 42 |
| `v0.2.3` | previous stable | 2,710,974 | 6.88B | Adds community-contributed `european_hplt_v3_pl`, `global_voices` and `nkjp1m`. |
|
| 43 |
| `v0.2.2` | previous stable | 2,579,963 | 6.36B | Added community-contributed `govpl`: 88,190 docs / 80.7M tokens. |
|
| 44 |
| `v0.2.1` | previous stable | 2,491,773 | 6.28B | 12-source corpus with `license` and `author` metadata columns; added `1000_novels`. |
|
|
|
|
| 55 |
|
| 56 |
### Version details
|
| 57 |
|
| 58 |
+
#### v0.2.5 — current stable
|
| 59 |
+
|
| 60 |
+
Added `samorzad_gov_pl`: **72,771 documents / 41,154,506 cl100k-proxy
|
| 61 |
+
tokens** from 246 Polish local public institutions and one central platform
|
| 62 |
+
tenant. The contribution preserves the publishing institution as `author`,
|
| 63 |
+
discovered and fetched article URLs in an attribution sidecar and the verified
|
| 64 |
+
platform-wide CC-BY-SA-4.0 basis.
|
| 65 |
+
|
| 66 |
+
#### v0.2.4 — previous stable
|
| 67 |
|
| 68 |
Expanded `european_hplt_v3_pl` from WDS bins 10+9 to **WDS bins 10-5** (added
|
| 69 |
quality bins 8/7/6/5 and further WDS-9 shards): **+1,493,384 documents /
|
|
|
|
| 147 |
| [Bart Kobyliński](https://huggingface.co/bartoszkobylinski1) | Added `1000_novels`; expanded Biblioteka Nauki and Europeana ingestion with per-document license and author metadata. | `v0.2.1`, [PR #1](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/1) |
|
| 148 |
| [Paweł Puzio](https://huggingface.co/ppuzio) | Built `govpl`: subsite discovery, direct ingestion pipeline, dataset artifact, contract tests and documentation. | `v0.2.2`, [PR #9](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/9) |
|
| 149 |
| [Arkadiusz Słota](https://huggingface.co/Maggio33) | Built & expanded `european_hplt_v3_pl`: HPLT v3 WDS 10+9 (PR #5) then WDS 10-5 expansion (+1,493,384 docs / 2.04B tok), modular cleaning pipeline, phone-recall PII-scrub (v12b, independent dual-lens), cross-source dedup-vs-base (zero-overlap), validation and documentation. | `v0.2.3` (PR #5), `v0.2.4` |
|
| 150 |
+
| [Dawid Majewski](https://huggingface.co/dawidmajewski) | Added the reviewed Global Voices Polish corpus; built `samorzad_gov_pl` with direct acquisition, institution attribution, licensing evidence, release artifact and reproducible conversion. | `v0.2.3`, [PR #7](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/7); `v0.2.5` |
|
| 151 |
| [1am](https://huggingface.co/1am) | Added `nkjp1m`: the manually annotated 1-million-word NKJP subcorpus, direct fetch/build pipeline, source documentation and release artifact. | `v0.2.3`, [PR #8](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/8) |
|
| 152 |
|
| 153 |
Contributions are credited when they add a verifiable dataset artifact, pipeline,
|
|
|
|
| 174 |
| [wolne_lektury](data/wolne_lektury/wolne_lektury.md) | Wolne Lektury (school readings) | `CC-BY-SA-4.0 / Wolna Sztuka 1.3` | 6,141 | 103.0M |
|
| 175 |
| [govpl](data/govpl/govpl.md) | gov.pl — Polish government press releases | `CC-BY-SA-4.0` | 88,190 | 80.7M |
|
| 176 |
| [1000_novels](data/1000_novels/1000_novels.md) | 1000 Novels Corpus (CLARIN-PL) | `CC-BY-4.0` | 1,000 | 60.5M |
|
| 177 |
+
| [samorzad_gov_pl](data/samorzad_gov_pl/samorzad_gov_pl.md) | samorzad.gov.pl — Polish public-sector institutions | `CC-BY-SA-4.0` | 72,771 | 41.2M |
|
| 178 |
| [wikiquote](data/wikiquote/wikiquote.md) | Polish Wikiquote (quotations) | `CC-BY-SA-3.0` | 30,363 | 31.9M |
|
| 179 |
| [eltec_pol](data/eltec_pol/eltec_pol.md) | ELTeC-pol (European Literary Text Collection, Polish) | `CC-BY-4.0` | 100 | 21.5M |
|
| 180 |
| [wikivoyage](data/wikivoyage/wikivoyage.md) | Polish Wikivoyage (travel guides) | `CC-BY-SA-3.0` | 13,645 | 17.1M |
|
|
|
|
| 213 |
|
| 214 |
Current v0.3 source-ingestion status:
|
| 215 |
|
| 216 |
+
- `biblioteka_nauki`: included from the direct-upstream rebuild with
|
| 217 |
+
per-document license and author metadata.
|
|
|
|
| 218 |
- `europeana`: prepared in the source registry as a direct-upstream rebuild
|
| 219 |
target with per-record rights statements and creator metadata; raw SpeakLeash
|
| 220 |
Europeana remains excluded.
|
| 221 |
- Europeana release policy: split conservatively at pre-1929 records for
|
| 222 |
US-sensitive downstream reuse, and keep later/unknown records separately
|
| 223 |
labeled or held until legal review.
|
| 224 |
+
- `european_hplt_v3_pl`: WDS bins 10-5 are included in v0.2.5 after contract
|
| 225 |
validation. HPLT packaging is CC0, while underlying crawled web documents can
|
| 226 |
carry independent rights; downstream near-dedup and web-content review remain
|
| 227 |
recommended before training.
|
|
|
|
| 291 |
|
| 292 |
### Corpus phrase frequency (normalized by tokens)
|
| 293 |
|
| 294 |
+
Raw counts and token-normalized shares are regenerated from the current Parquet files with `src/pattern_frequency_report.py`.
|
| 295 |
|
| 296 |
+
- Total token count (tiktoken proxy): **9,639,062,573**
|
| 297 |
|
| 298 |
| Pattern | Count | Share of all tokens |
|
| 299 |
|---|---:|---:|
|
| 300 |
+
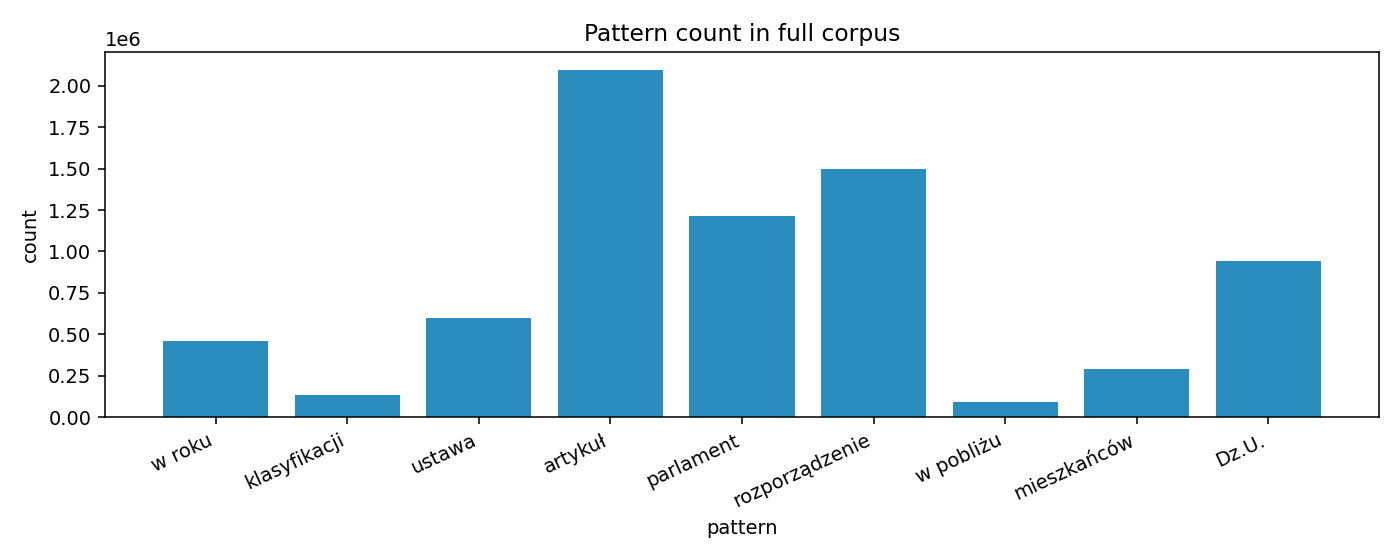
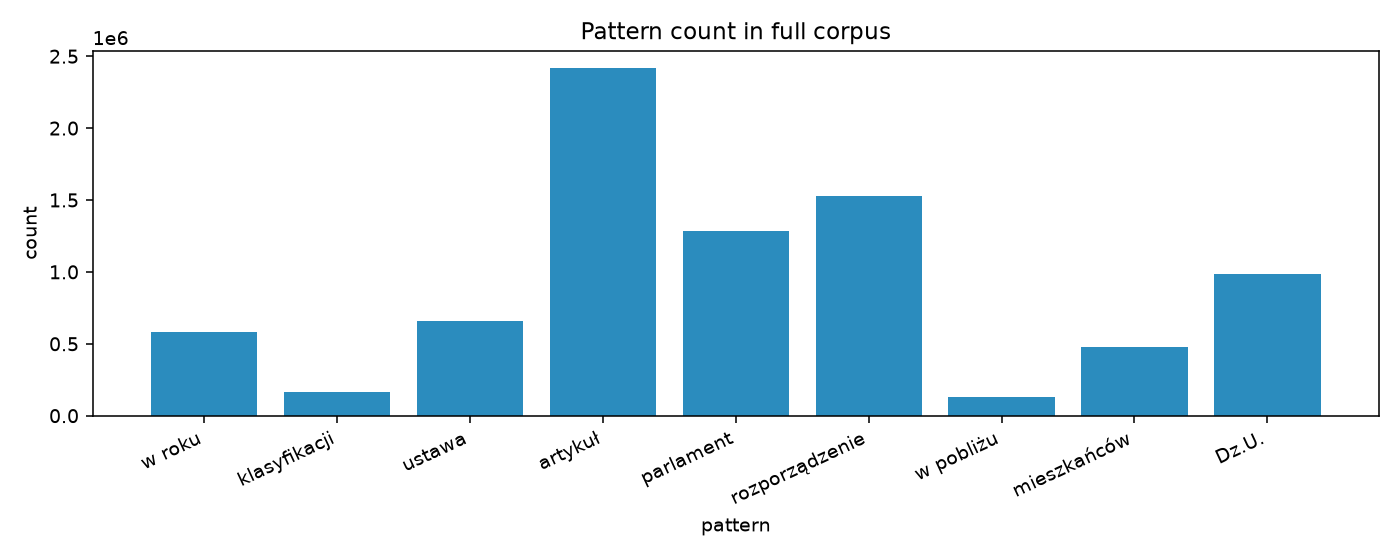
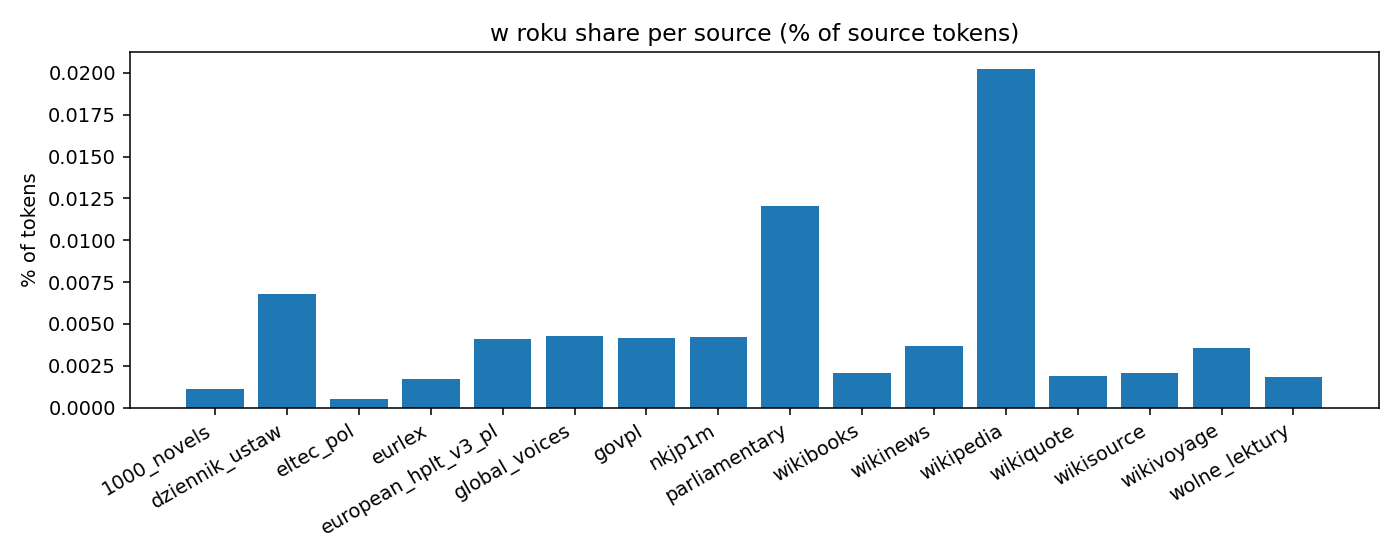
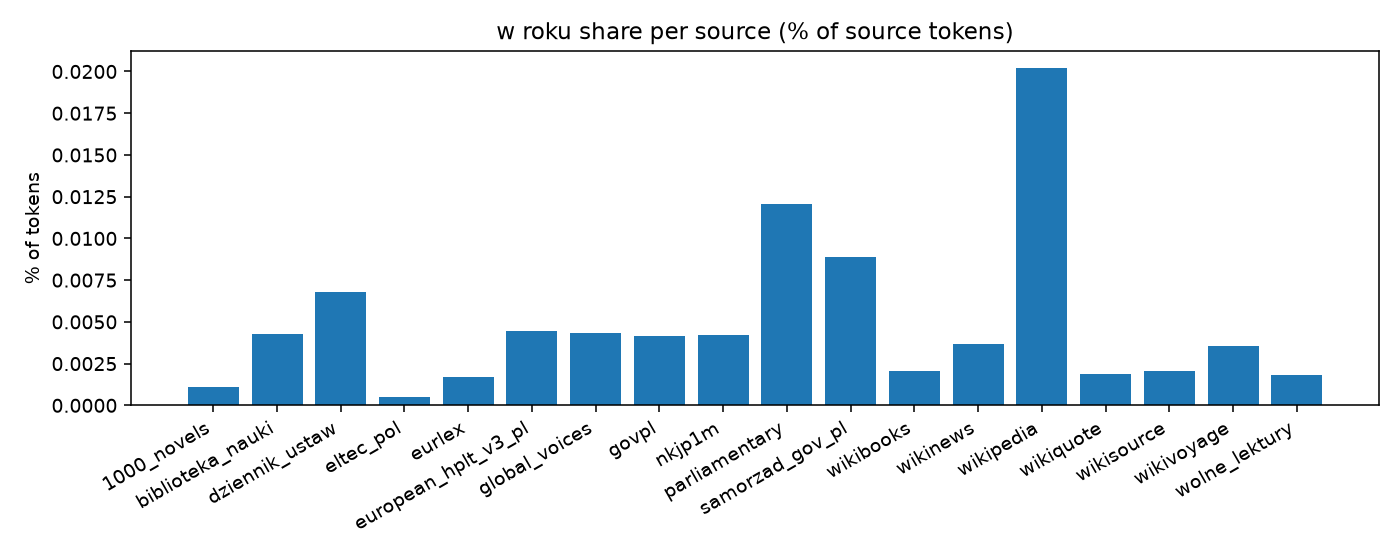
| `w roku` | 585,072 | 0.0061% |
|
| 301 |
+
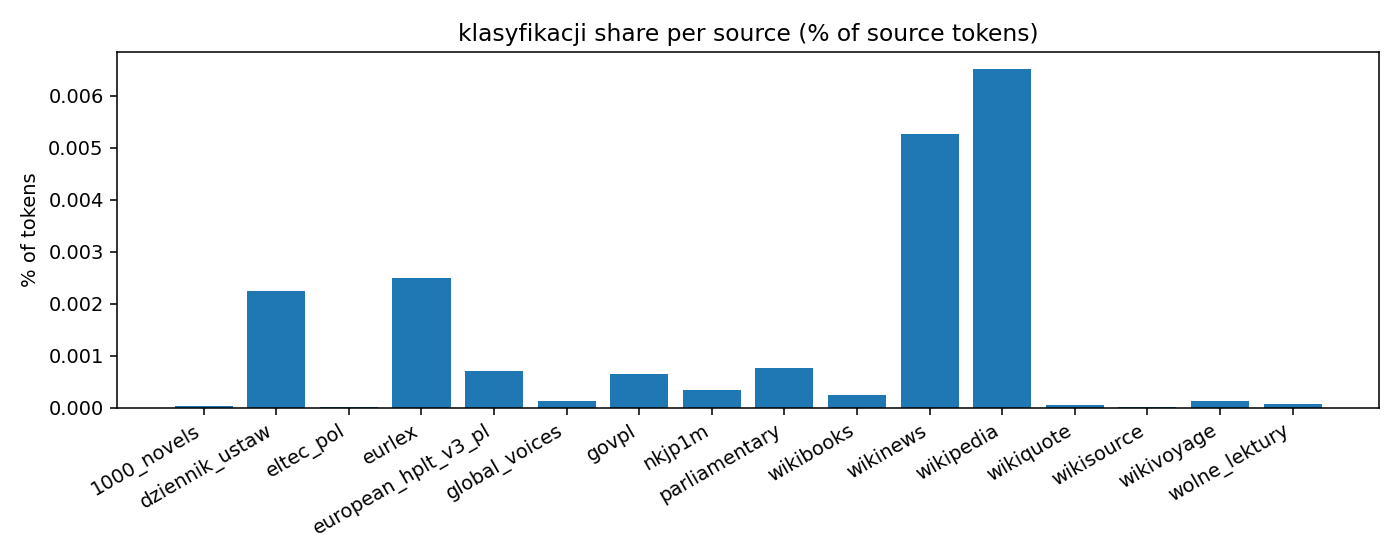
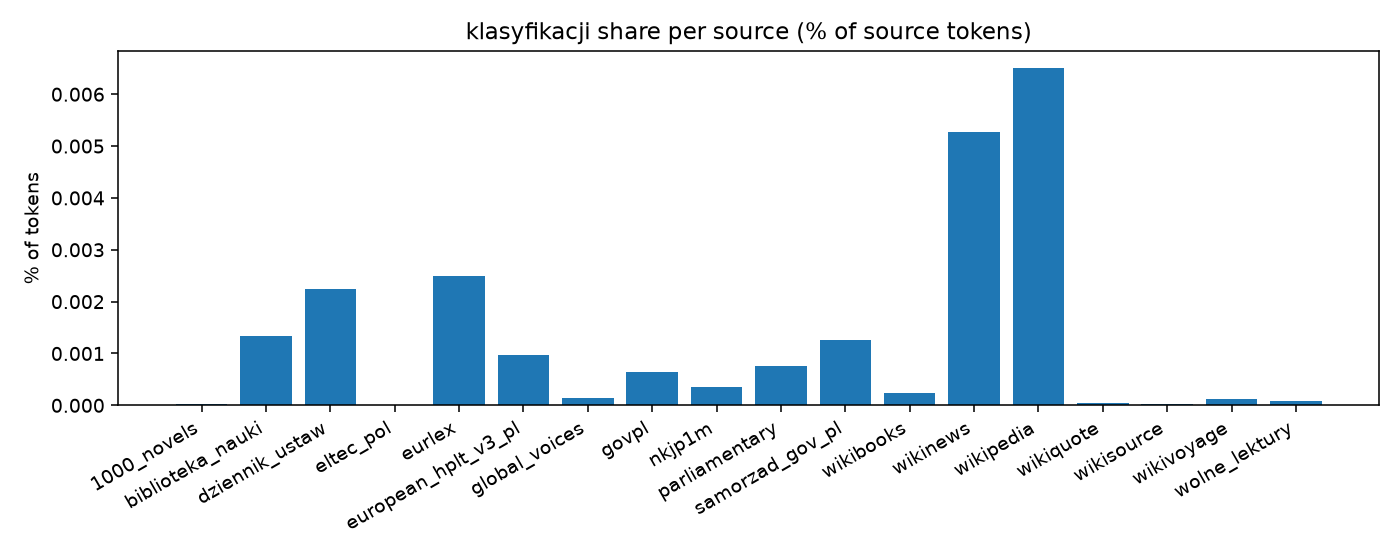
| `klasyfikacji` | 164,757 | 0.0017% |
|
| 302 |
+
| `ustawa` | 659,103 | 0.0068% |
|
| 303 |
+
| `artykuł` | 2,416,361 | 0.0251% |
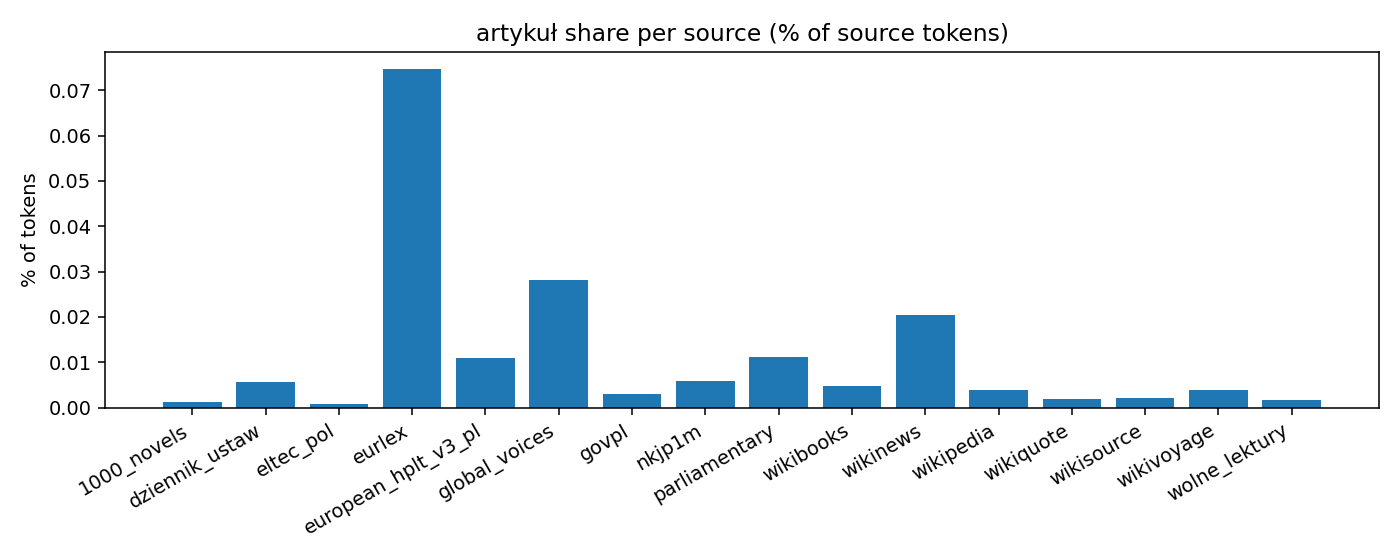
|
| 304 |
+
| `parlament` | 1,285,792 | 0.0133% |
|
| 305 |
+
| `rozporządzenie` | 1,527,456 | 0.0158% |
|
| 306 |
+
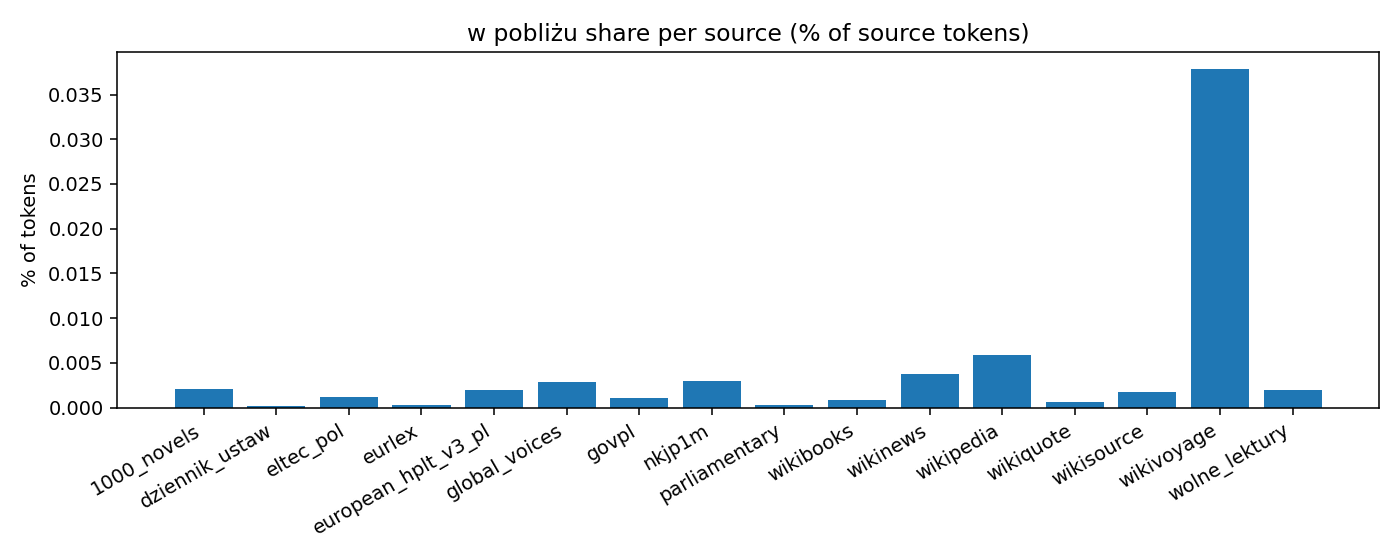
| `w pobliżu` | 127,784 | 0.0013% |
|
| 307 |
+
| `mieszkańców` | 476,710 | 0.0049% |
|
| 308 |
+
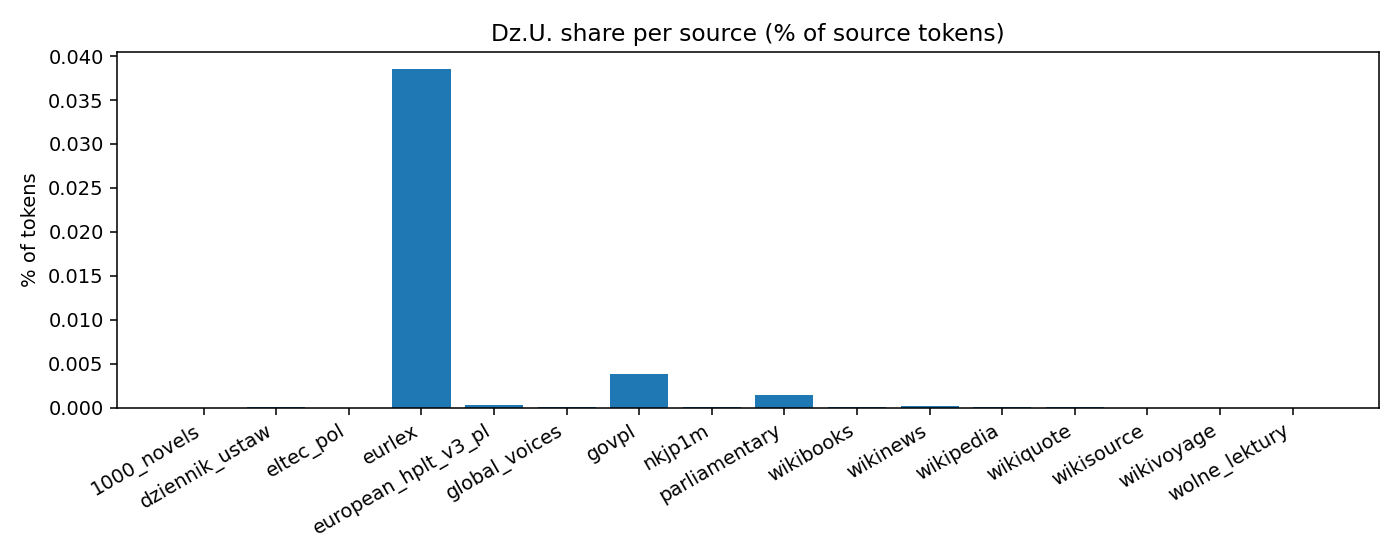
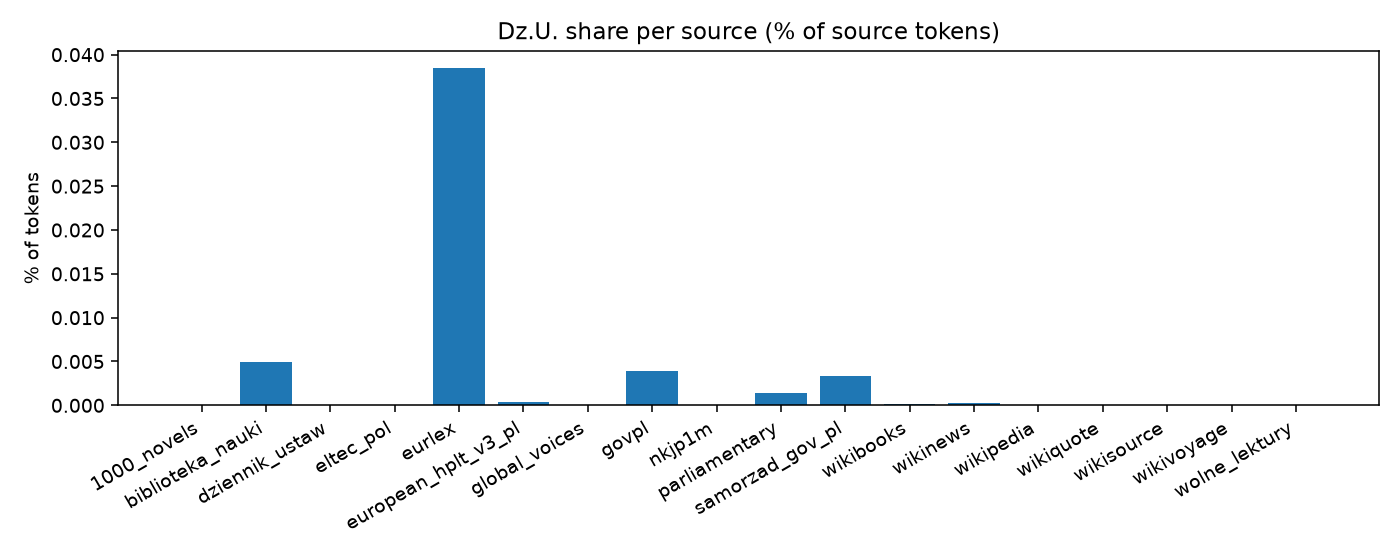
| `Dz.U.` | 987,048 | 0.0102% |
|
| 309 |
|
| 310 |
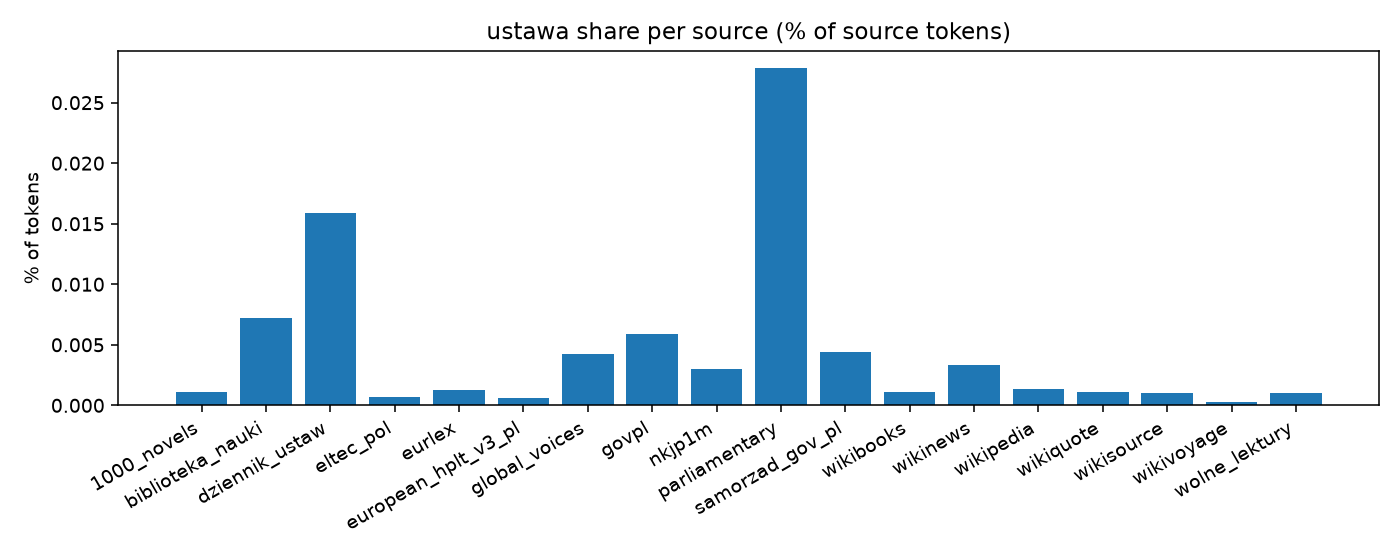
### Per-source shares
|
| 311 |
|
|
|
|
| 320 |
| `1000_novels` | `w pobliżu` | 1,262 | 0.00209% |
|
| 321 |
| `1000_novels` | `mieszkańców` | 868 | 0.00143% |
|
| 322 |
| `1000_novels` | `Dz.U.` | 0 | 0.00000% |
|
| 323 |
+
| `biblioteka_nauki` | `w roku` | 28,728 | 0.00427% |
|
| 324 |
+
| `biblioteka_nauki` | `klasyfikacji` | 9,045 | 0.00134% |
|
| 325 |
+
| `biblioteka_nauki` | `ustawa` | 48,791 | 0.00724% |
|
| 326 |
+
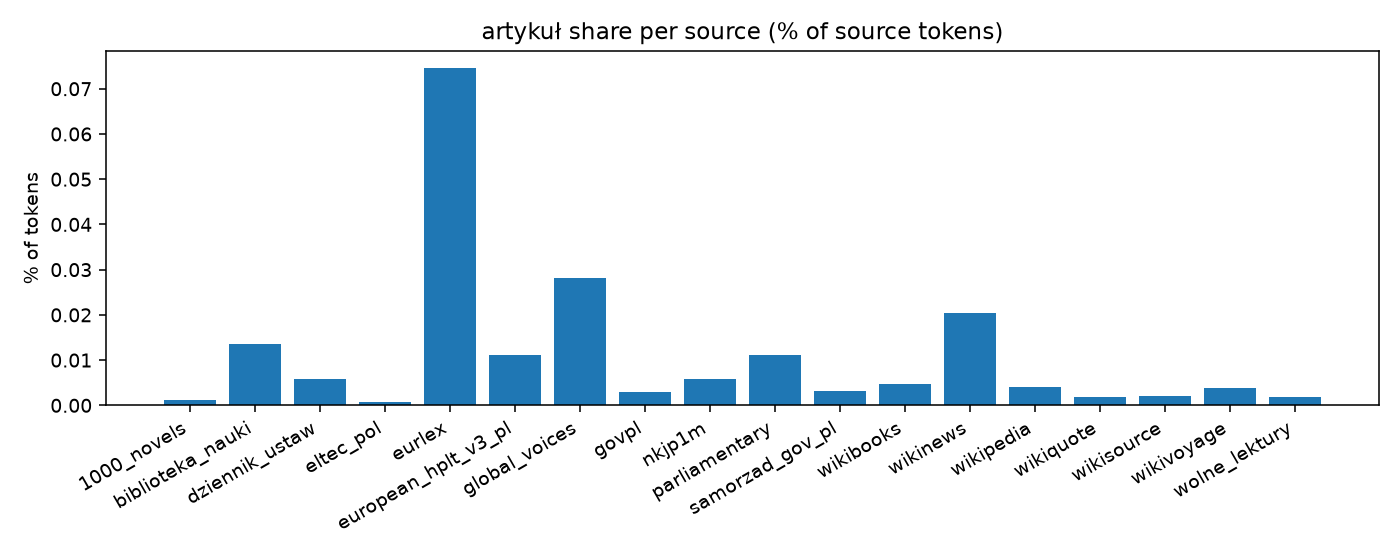
| `biblioteka_nauki` | `artykuł` | 91,241 | 0.01355% |
|
| 327 |
+
| `biblioteka_nauki` | `parlament` | 32,868 | 0.00488% |
|
| 328 |
+
| `biblioteka_nauki` | `rozporządzenie` | 19,594 | 0.00291% |
|
| 329 |
+
| `biblioteka_nauki` | `w pobliżu` | 3,378 | 0.00050% |
|
| 330 |
+
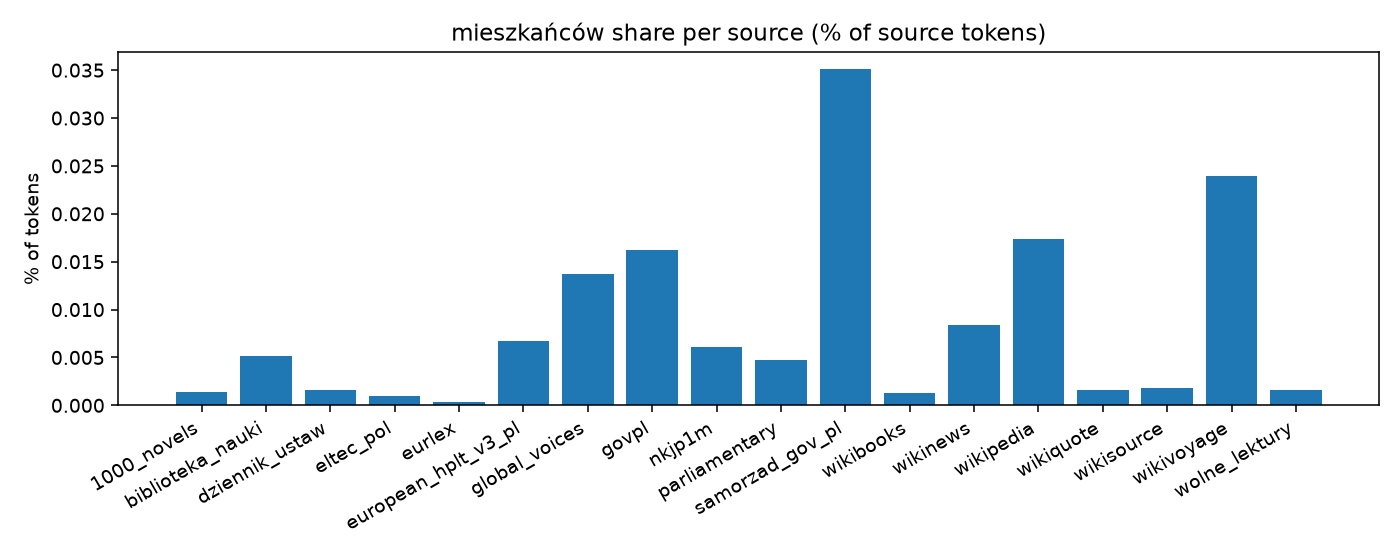
| `biblioteka_nauki` | `mieszkańców` | 34,392 | 0.00511% |
|
| 331 |
+
| `biblioteka_nauki` | `Dz.U.` | 33,098 | 0.00491% |
|
| 332 |
| `dziennik_ustaw` | `w roku` | 33,096 | 0.00681% |
|
| 333 |
| `dziennik_ustaw` | `klasyfikacji` | 10,896 | 0.00224% |
|
| 334 |
| `dziennik_ustaw` | `ustawa` | 77,376 | 0.01592% |
|
|
|
|
| 356 |
| `eurlex` | `w pobliżu` | 6,088 | 0.00026% |
|
| 357 |
| `eurlex` | `mieszkańców` | 9,441 | 0.00040% |
|
| 358 |
| `eurlex` | `Dz.U.` | 915,707 | 0.03851% |
|
| 359 |
+
| `european_hplt_v3_pl` | `w roku` | 113,501 | 0.00444% |
|
| 360 |
+
| `european_hplt_v3_pl` | `klasyfikacji` | 24,675 | 0.00097% |
|
| 361 |
+
| `european_hplt_v3_pl` | `ustawa` | 16,067 | 0.00063% |
|
| 362 |
+
| `european_hplt_v3_pl` | `artykuł` | 283,875 | 0.01111% |
|
| 363 |
+
| `european_hplt_v3_pl` | `parlament` | 45,516 | 0.00178% |
|
| 364 |
+
| `european_hplt_v3_pl` | `rozporządzenie` | 11,841 | 0.00046% |
|
| 365 |
+
| `european_hplt_v3_pl` | `w pobliżu` | 44,108 | 0.00173% |
|
| 366 |
+
| `european_hplt_v3_pl` | `mieszkańców` | 172,896 | 0.00677% |
|
| 367 |
+
| `european_hplt_v3_pl` | `Dz.U.` | 9,487 | 0.00037% |
|
| 368 |
| `global_voices` | `w roku` | 160 | 0.00431% |
|
| 369 |
| `global_voices` | `klasyfikacji` | 5 | 0.00013% |
|
| 370 |
| `global_voices` | `ustawa` | 157 | 0.00423% |
|
|
|
|
| 401 |
| `parliamentary` | `w pobliżu` | 4,964 | 0.00030% |
|
| 402 |
| `parliamentary` | `mieszkańców` | 78,048 | 0.00474% |
|
| 403 |
| `parliamentary` | `Dz.U.` | 23,809 | 0.00145% |
|
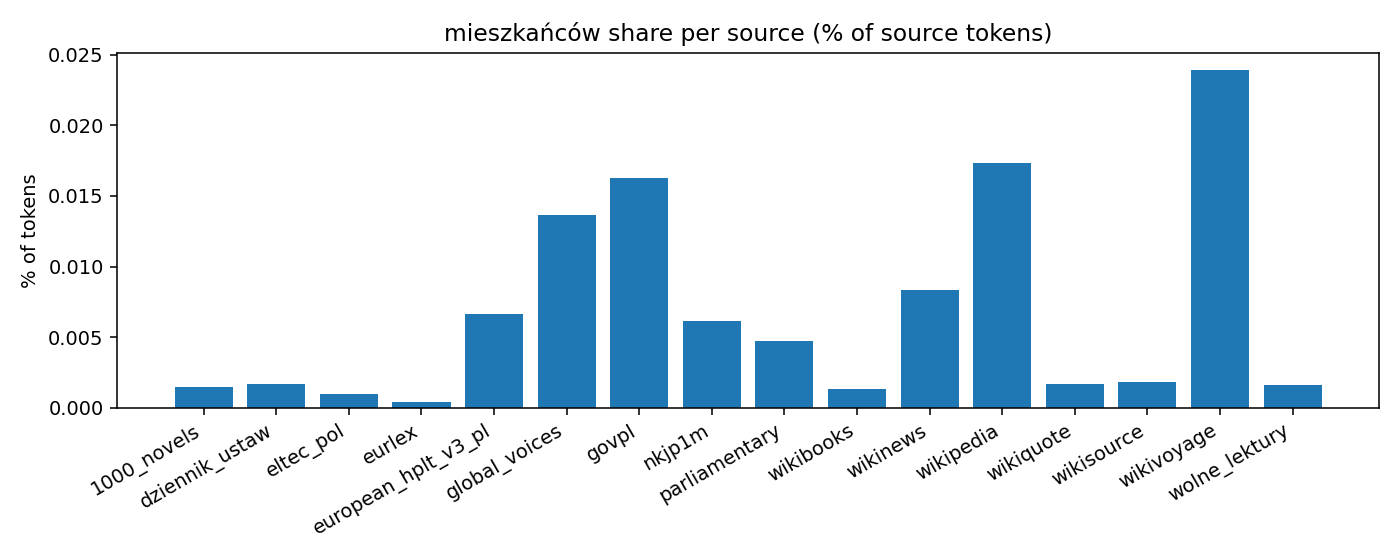
| 404 |
+
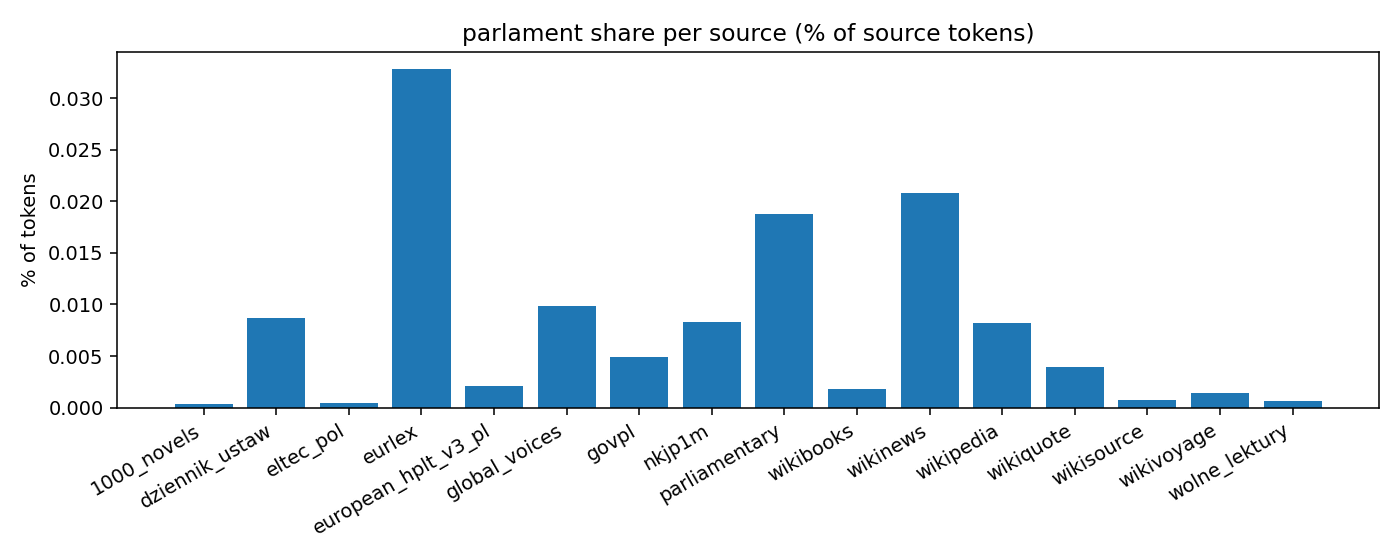
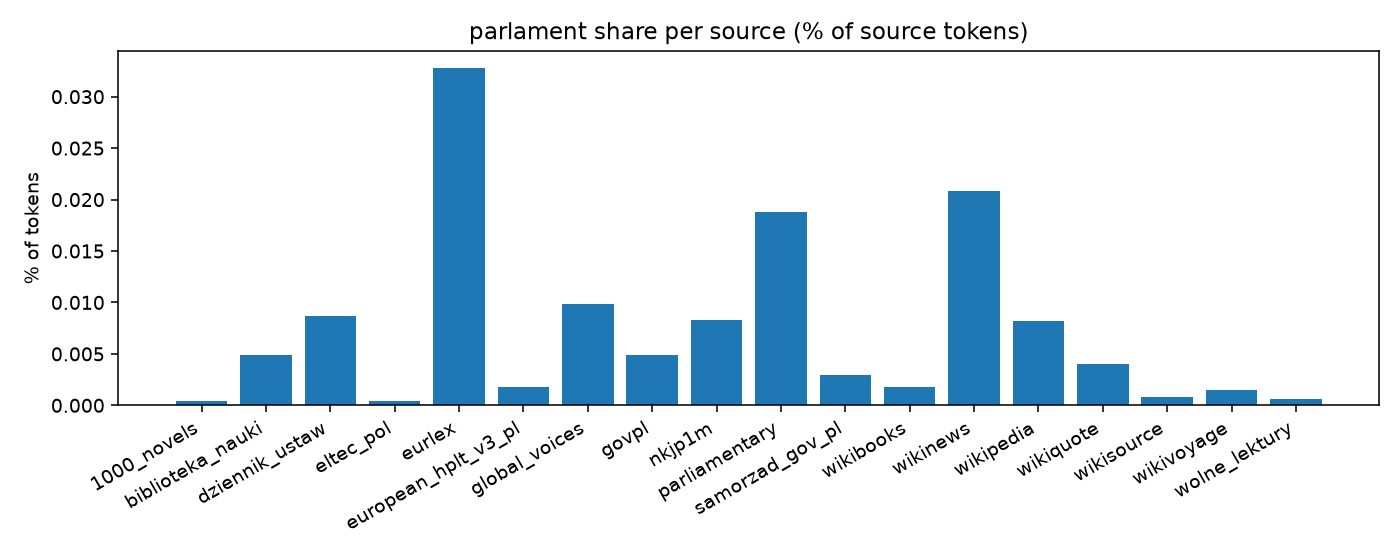
| `samorzad_gov_pl` | `w roku` | 3,661 | 0.00890% |
|
| 405 |
+
| `samorzad_gov_pl` | `klasyfikacji` | 520 | 0.00126% |
|
| 406 |
+
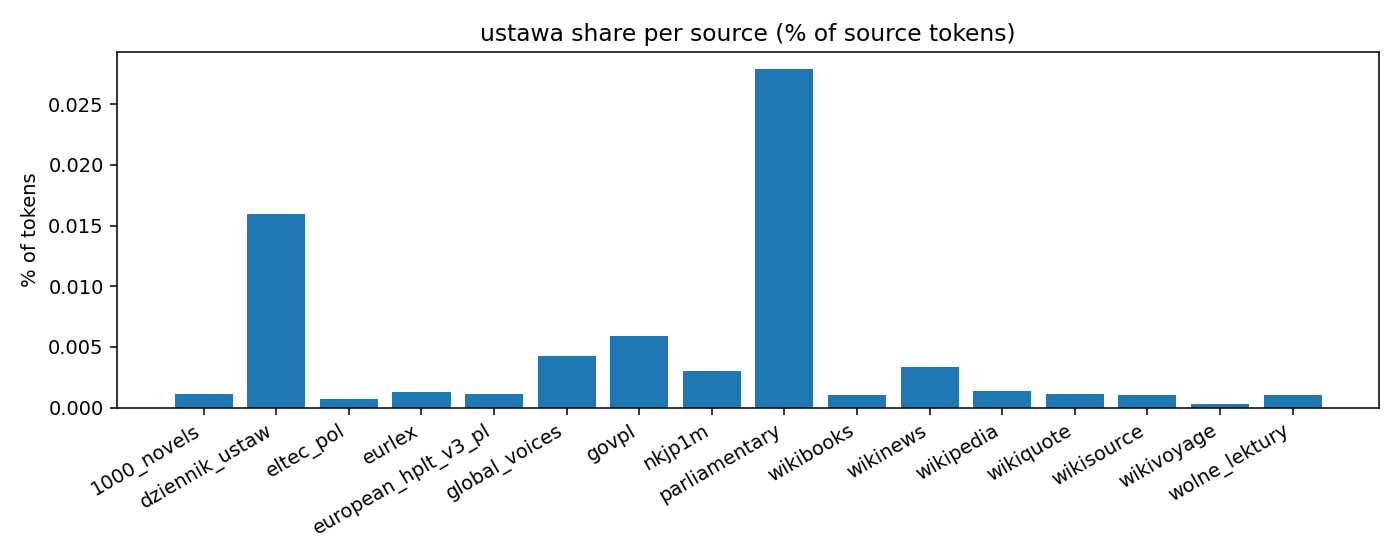
| `samorzad_gov_pl` | `ustawa` | 1,823 | 0.00443% |
|
| 407 |
+
| `samorzad_gov_pl` | `artykuł` | 1,269 | 0.00308% |
|
| 408 |
+
| `samorzad_gov_pl` | `parlament` | 1,218 | 0.00296% |
|
| 409 |
+
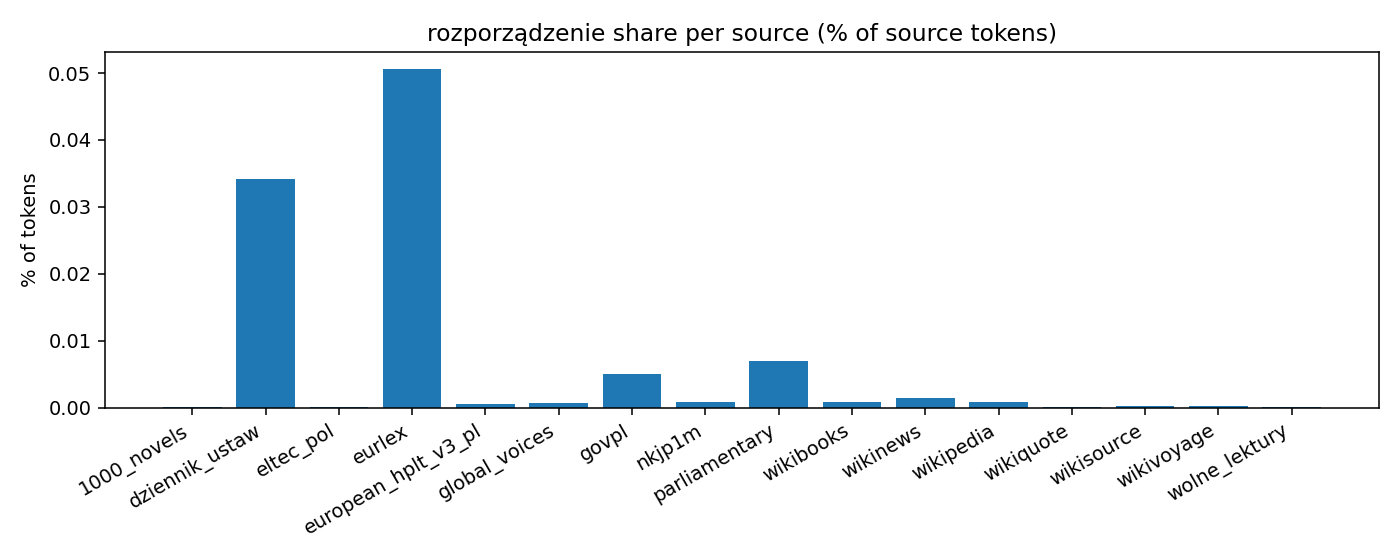
| `samorzad_gov_pl` | `rozporządzenie` | 1,409 | 0.00342% |
|
| 410 |
+
| `samorzad_gov_pl` | `w pobliżu` | 401 | 0.00097% |
|
| 411 |
+
| `samorzad_gov_pl` | `mieszkańców` | 14,450 | 0.03511% |
|
| 412 |
+
| `samorzad_gov_pl` | `Dz.U.` | 1,380 | 0.00335% |
|
| 413 |
| `wikibooks` | `w roku` | 319 | 0.00205% |
|
| 414 |
| `wikibooks` | `klasyfikacji` | 37 | 0.00024% |
|
| 415 |
| `wikibooks` | `ustawa` | 165 | 0.00106% |
|
|
|
|
| 485 |

|
| 486 |

|
| 487 |

|
|
|
artifacts/dataset_size_by_version.png
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
artifacts/pattern_frequency_artykul.png
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
artifacts/pattern_frequency_dzu.png
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
artifacts/pattern_frequency_hf_snippet.md
CHANGED
|
@@ -1,18 +1,18 @@
|
|
| 1 |
## Phrase frequency in corpus (token-normalized)
|
| 2 |
|
| 3 |
-
- Total token count (tiktoken proxy): **
|
| 4 |
|
| 5 |
| Pattern | Count | Share of all tokens |
|
| 6 |
|---|---:|---:|
|
| 7 |
-
| `w roku` |
|
| 8 |
-
| `klasyfikacji` |
|
| 9 |
-
| `ustawa` |
|
| 10 |
-
| `artykuł` | 2,
|
| 11 |
-
| `parlament` | 1,
|
| 12 |
-
| `rozporządzenie` | 1,
|
| 13 |
-
| `w pobliżu` |
|
| 14 |
-
| `mieszkańców` |
|
| 15 |
-
| `Dz.U.` |
|
| 16 |
|
| 17 |
### Per-source shares
|
| 18 |
|
|
@@ -27,6 +27,15 @@
|
|
| 27 |
| `1000_novels` | `w pobliżu` | 1,262 | 0.00209% |
|
| 28 |
| `1000_novels` | `mieszkańców` | 868 | 0.00143% |
|
| 29 |
| `1000_novels` | `Dz.U.` | 0 | 0.00000% |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 30 |
| `dziennik_ustaw` | `w roku` | 33,096 | 0.00681% |
|
| 31 |
| `dziennik_ustaw` | `klasyfikacji` | 10,896 | 0.00224% |
|
| 32 |
| `dziennik_ustaw` | `ustawa` | 77,376 | 0.01592% |
|
|
@@ -54,15 +63,15 @@
|
|
| 54 |
| `eurlex` | `w pobliżu` | 6,088 | 0.00026% |
|
| 55 |
| `eurlex` | `mieszkańców` | 9,441 | 0.00040% |
|
| 56 |
| `eurlex` | `Dz.U.` | 915,707 | 0.03851% |
|
| 57 |
-
| `european_hplt_v3_pl` | `w roku` |
|
| 58 |
-
| `european_hplt_v3_pl` | `klasyfikacji` |
|
| 59 |
-
| `european_hplt_v3_pl` | `ustawa` |
|
| 60 |
-
| `european_hplt_v3_pl` | `artykuł` |
|
| 61 |
-
| `european_hplt_v3_pl` | `parlament` |
|
| 62 |
-
| `european_hplt_v3_pl` | `rozporządzenie` |
|
| 63 |
-
| `european_hplt_v3_pl` | `w pobliżu` |
|
| 64 |
-
| `european_hplt_v3_pl` | `mieszkańców` |
|
| 65 |
-
| `european_hplt_v3_pl` | `Dz.U.` |
|
| 66 |
| `global_voices` | `w roku` | 160 | 0.00431% |
|
| 67 |
| `global_voices` | `klasyfikacji` | 5 | 0.00013% |
|
| 68 |
| `global_voices` | `ustawa` | 157 | 0.00423% |
|
|
@@ -99,6 +108,15 @@
|
|
| 99 |
| `parliamentary` | `w pobliżu` | 4,964 | 0.00030% |
|
| 100 |
| `parliamentary` | `mieszkańców` | 78,048 | 0.00474% |
|
| 101 |
| `parliamentary` | `Dz.U.` | 23,809 | 0.00145% |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 102 |
| `wikibooks` | `w roku` | 319 | 0.00205% |
|
| 103 |
| `wikibooks` | `klasyfikacji` | 37 | 0.00024% |
|
| 104 |
| `wikibooks` | `ustawa` | 165 | 0.00106% |
|
|
|
|
| 1 |
## Phrase frequency in corpus (token-normalized)
|
| 2 |
|
| 3 |
+
- Total token count (tiktoken proxy): **9,639,062,573**
|
| 4 |
|
| 5 |
| Pattern | Count | Share of all tokens |
|
| 6 |
|---|---:|---:|
|
| 7 |
+
| `w roku` | 585,072 | 0.0061% |
|
| 8 |
+
| `klasyfikacji` | 164,757 | 0.0017% |
|
| 9 |
+
| `ustawa` | 659,103 | 0.0068% |
|
| 10 |
+
| `artykuł` | 2,416,361 | 0.0251% |
|
| 11 |
+
| `parlament` | 1,285,792 | 0.0133% |
|
| 12 |
+
| `rozporządzenie` | 1,527,456 | 0.0158% |
|
| 13 |
+
| `w pobliżu` | 127,784 | 0.0013% |
|
| 14 |
+
| `mieszkańców` | 476,710 | 0.0049% |
|
| 15 |
+
| `Dz.U.` | 987,048 | 0.0102% |
|
| 16 |
|
| 17 |
### Per-source shares
|
| 18 |
|
|
|
|
| 27 |
| `1000_novels` | `w pobliżu` | 1,262 | 0.00209% |
|
| 28 |
| `1000_novels` | `mieszkańców` | 868 | 0.00143% |
|
| 29 |
| `1000_novels` | `Dz.U.` | 0 | 0.00000% |
|
| 30 |
+
| `biblioteka_nauki` | `w roku` | 28,728 | 0.00427% |
|
| 31 |
+
| `biblioteka_nauki` | `klasyfikacji` | 9,045 | 0.00134% |
|
| 32 |
+
| `biblioteka_nauki` | `ustawa` | 48,791 | 0.00724% |
|
| 33 |
+
| `biblioteka_nauki` | `artykuł` | 91,241 | 0.01355% |
|
| 34 |
+
| `biblioteka_nauki` | `parlament` | 32,868 | 0.00488% |
|
| 35 |
+
| `biblioteka_nauki` | `rozporządzenie` | 19,594 | 0.00291% |
|
| 36 |
+
| `biblioteka_nauki` | `w pobliżu` | 3,378 | 0.00050% |
|
| 37 |
+
| `biblioteka_nauki` | `mieszkańców` | 34,392 | 0.00511% |
|
| 38 |
+
| `biblioteka_nauki` | `Dz.U.` | 33,098 | 0.00491% |
|
| 39 |
| `dziennik_ustaw` | `w roku` | 33,096 | 0.00681% |
|
| 40 |
| `dziennik_ustaw` | `klasyfikacji` | 10,896 | 0.00224% |
|
| 41 |
| `dziennik_ustaw` | `ustawa` | 77,376 | 0.01592% |
|
|
|
|
| 63 |
| `eurlex` | `w pobliżu` | 6,088 | 0.00026% |
|
| 64 |
| `eurlex` | `mieszkańców` | 9,441 | 0.00040% |
|
| 65 |
| `eurlex` | `Dz.U.` | 915,707 | 0.03851% |
|
| 66 |
+
| `european_hplt_v3_pl` | `w roku` | 113,501 | 0.00444% |
|
| 67 |
+
| `european_hplt_v3_pl` | `klasyfikacji` | 24,675 | 0.00097% |
|
| 68 |
+
| `european_hplt_v3_pl` | `ustawa` | 16,067 | 0.00063% |
|
| 69 |
+
| `european_hplt_v3_pl` | `artykuł` | 283,875 | 0.01111% |
|
| 70 |
+
| `european_hplt_v3_pl` | `parlament` | 45,516 | 0.00178% |
|
| 71 |
+
| `european_hplt_v3_pl` | `rozporządzenie` | 11,841 | 0.00046% |
|
| 72 |
+
| `european_hplt_v3_pl` | `w pobliżu` | 44,108 | 0.00173% |
|
| 73 |
+
| `european_hplt_v3_pl` | `mieszkańców` | 172,896 | 0.00677% |
|
| 74 |
+
| `european_hplt_v3_pl` | `Dz.U.` | 9,487 | 0.00037% |
|
| 75 |
| `global_voices` | `w roku` | 160 | 0.00431% |
|
| 76 |
| `global_voices` | `klasyfikacji` | 5 | 0.00013% |
|
| 77 |
| `global_voices` | `ustawa` | 157 | 0.00423% |
|
|
|
|
| 108 |
| `parliamentary` | `w pobliżu` | 4,964 | 0.00030% |
|
| 109 |
| `parliamentary` | `mieszkańców` | 78,048 | 0.00474% |
|
| 110 |
| `parliamentary` | `Dz.U.` | 23,809 | 0.00145% |
|
| 111 |
+
| `samorzad_gov_pl` | `w roku` | 3,661 | 0.00890% |
|
| 112 |
+
| `samorzad_gov_pl` | `klasyfikacji` | 520 | 0.00126% |
|
| 113 |
+
| `samorzad_gov_pl` | `ustawa` | 1,823 | 0.00443% |
|
| 114 |
+
| `samorzad_gov_pl` | `artykuł` | 1,269 | 0.00308% |
|
| 115 |
+
| `samorzad_gov_pl` | `parlament` | 1,218 | 0.00296% |
|
| 116 |
+
| `samorzad_gov_pl` | `rozporządzenie` | 1,409 | 0.00342% |
|
| 117 |
+
| `samorzad_gov_pl` | `w pobliżu` | 401 | 0.00097% |
|
| 118 |
+
| `samorzad_gov_pl` | `mieszkańców` | 14,450 | 0.03511% |
|
| 119 |
+
| `samorzad_gov_pl` | `Dz.U.` | 1,380 | 0.00335% |
|
| 120 |
| `wikibooks` | `w roku` | 319 | 0.00205% |
|
| 121 |
| `wikibooks` | `klasyfikacji` | 37 | 0.00024% |
|
| 122 |
| `wikibooks` | `ustawa` | 165 | 0.00106% |
|
artifacts/pattern_frequency_klasyfikacji.png
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
artifacts/pattern_frequency_mieszkańców.png
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
artifacts/pattern_frequency_overall.png
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
artifacts/pattern_frequency_parlament.png
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
artifacts/pattern_frequency_rozporządzenie.png
CHANGED
|
Git LFS Details
|

|
Git LFS Details
|
artifacts/pattern_frequency_ustawa.png
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
artifacts/pattern_frequency_w_pobliżu.png
CHANGED
|
Git LFS Details
|

|
Git LFS Details
|
artifacts/pattern_frequency_w_roku.png
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
data/samorzad_gov_pl/NOTICE.md
ADDED
|
@@ -0,0 +1,28 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Attribution and licensing notice
|
| 2 |
+
|
| 3 |
+
The `samorzad_gov_pl` source contains textual articles collected from public
|
| 4 |
+
pages hosted on the shared [samorzad.gov.pl](https://samorzad.gov.pl/)
|
| 5 |
+
platform.
|
| 6 |
+
|
| 7 |
+
The platform footer states that textual content published in the service,
|
| 8 |
+
excluding audiovisual content, is available under the [Creative Commons
|
| 9 |
+
Attribution-ShareAlike 4.0 International](https://creativecommons.org/licenses/by-sa/4.0/)
|
| 10 |
+
license (`CC-BY-SA-4.0`). Every source page retained in the published v0.1
|
| 11 |
+
upstream dataset referenced the shared platform footer script.
|
| 12 |
+
|
| 13 |
+
For every released DynaWord document:
|
| 14 |
+
|
| 15 |
+
- the `author` column identifies the publishing institution;
|
| 16 |
+
- `samorzad_gov_pl.attribution.jsonl` preserves the discovered `source_url`,
|
| 17 |
+
fetched `final_url`, recommended `attribution_url`, article title,
|
| 18 |
+
institution, tenant identifier, license URL and modification notice;
|
| 19 |
+
- article text was extracted from source HTML, and this contribution normalizes
|
| 20 |
+
metadata and excludes short, non-Polish or duplicate records.
|
| 21 |
+
|
| 22 |
+
When redistributing or adapting these texts, retain the source attribution,
|
| 23 |
+
indicate changes and distribute adaptations under compatible
|
| 24 |
+
`CC-BY-SA-4.0` terms.
|
| 25 |
+
|
| 26 |
+
Photographs, videos, recordings and attachment bytes are not included. Their
|
| 27 |
+
rights must be evaluated separately at the source. URLs and descriptive
|
| 28 |
+
metadata in the attribution sidecar do not redistribute the linked files.
|
data/samorzad_gov_pl/samorzad_gov_pl.attribution.jsonl
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:e50acff3137b4680dc63a402667227b24cdd362e9c07895f1485a530ea5116c3
|
| 3 |
+
size 68676369
|
data/samorzad_gov_pl/samorzad_gov_pl.license-evidence.json
ADDED
|
@@ -0,0 +1,17 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"checked_at": "2026-08-13T23:42:06Z",
|
| 3 |
+
"evidence_url": "https://samorzad.gov.pl/scripts/govpl_template.js?locale=pl_PL",
|
| 4 |
+
"etag": "W/\"0b36ec507901ed443195479d8d8009386\"",
|
| 5 |
+
"bytes": 9291,
|
| 6 |
+
"sha256": "b36ec507901ed443195479d8d8009386159ae59d7486ce266bfb3308043e99aa",
|
| 7 |
+
"text_license": "CC BY-SA 4.0",
|
| 8 |
+
"audiovisual_license": "CC BY-NC-ND 4.0 unless stated otherwise",
|
| 9 |
+
"release_scope": {
|
| 10 |
+
"records": 81422,
|
| 11 |
+
"tenants": 247,
|
| 12 |
+
"source_pages_referencing_shared_footer_script": 81422,
|
| 13 |
+
"source_pages_without_reference": 0,
|
| 14 |
+
"missing_source_artifacts": 0
|
| 15 |
+
},
|
| 16 |
+
"method": "Checked the live shared footer script and searched every preserved source HTML artifact in release v0.1 for /scripts/govpl_template.js?locale=pl_PL."
|
| 17 |
+
}
|
data/samorzad_gov_pl/samorzad_gov_pl.md
ADDED
|
@@ -0,0 +1,138 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# samorzad_gov_pl
|
| 2 |
+
|
| 3 |
+
Polish-language articles published by 246 local public institutions and one
|
| 4 |
+
central platform tenant using the shared
|
| 5 |
+
[samorzad.gov.pl](https://samorzad.gov.pl/) platform. The collection includes
|
| 6 |
+
municipalities, counties, schools, social-service institutions, cultural
|
| 7 |
+
institutions and other public bodies.
|
| 8 |
+
|
| 9 |
+
## Dataset description
|
| 10 |
+
|
| 11 |
+
- **Published source dataset:** https://huggingface.co/datasets/dawidmajewski/samorzad-gov-pl-articles
|
| 12 |
+
- **Source revision:** `d5eaefc32c3f17cfa5a01d14573f8e4ee7d43385` (`v0.1`)
|
| 13 |
+
- **Original platform:** https://samorzad.gov.pl/
|
| 14 |
+
- **Domain:** local government, education, social services and culture
|
| 15 |
+
- **Language:** Polish (`pl`)
|
| 16 |
+
- **License:** `CC-BY-SA-4.0`
|
| 17 |
+
- **Created:** 2020–2026 for dated records; most source records do not expose a date
|
| 18 |
+
- **Added:** 2026-08-14
|
| 19 |
+
|
| 20 |
+
## Statistics
|
| 21 |
+
|
| 22 |
+
| read | kept | characters | tokens (`cl100k_base` proxy) | publishers |
|
| 23 |
+
|---:|---:|---:|---:|---:|
|
| 24 |
+
| 81,422 | 72,771 | 109,513,754 | 41,154,506 | 247 |
|
| 25 |
+
|
| 26 |
+
The released Parquet uses the canonical DynaWord schema:
|
| 27 |
+
|
| 28 |
+
`id, text, source, added, created, token_count, license, author`
|
| 29 |
+
|
| 30 |
+
Every retained document has the human-readable name of its publishing
|
| 31 |
+
institution in `author`. The names were obtained from the `og:site_name`
|
| 32 |
+
metadata on each institution's platform homepage and frozen in
|
| 33 |
+
`src/samorzad_gov_pl_publishers.json`.
|
| 34 |
+
|
| 35 |
+
## Provenance
|
| 36 |
+
|
| 37 |
+
The source release was collected directly from public samorzad.gov.pl pages.
|
| 38 |
+
It contains every article URL found and successfully extracted during that
|
| 39 |
+
crawl, rather than a topical or length-selected sample. The published source
|
| 40 |
+
release contains 81,422 extracted articles from 247 institutions.
|
| 41 |
+
|
| 42 |
+
`src/clean_samorzad_gov_pl.py` converts the published source Parquets into the
|
| 43 |
+
DynaWord schema, applies the common minimum-length and Polish-language checks,
|
| 44 |
+
removes exact duplicate text and counts tokens with `cl100k_base`. The retained
|
| 45 |
+
article text is otherwise unchanged.
|
| 46 |
+
|
| 47 |
+
## Licensing — traceable basis and attribution
|
| 48 |
+
|
| 49 |
+
The platform's shared footer states that textual content published in the
|
| 50 |
+
service, excluding audiovisual content, is available under CC BY-SA 4.0. A
|
| 51 |
+
release-time audit verified the live shared footer script and confirmed that
|
| 52 |
+
all 81,422 preserved source pages referenced that script. The evidence URL,
|
| 53 |
+
byte count and SHA-256 digest are recorded in
|
| 54 |
+
`samorzad_gov_pl.license-evidence.json`.
|
| 55 |
+
|
| 56 |
+
The fixed DynaWord schema does not contain article titles or URLs. Therefore,
|
| 57 |
+
`samorzad_gov_pl.attribution.jsonl` maps every released `id` to its title,
|
| 58 |
+
discovered `source_url`, fetched `final_url`, recommended `attribution_url`,
|
| 59 |
+
publishing institution, platform tenant, license URL and modification notice.
|
| 60 |
+
For 693 retained records the discovered and final URLs differ because the
|
| 61 |
+
platform redirected the request; `attribution_url` uses the fetched final URL.
|
| 62 |
+
|
| 63 |
+
Recommended attribution:
|
| 64 |
+
|
| 65 |
+
> Publishing institution listed in the `author` column; article title and
|
| 66 |
+
> canonical samorzad.gov.pl URL from the attribution sidecar; CC BY-SA 4.0.
|
| 67 |
+
> Article text was extracted from HTML and normalized for inclusion in Polish
|
| 68 |
+
> DynaWord.
|
| 69 |
+
|
| 70 |
+
Photographs, recordings, videos and attachment bytes are not redistributed.
|
| 71 |
+
The source platform gives audiovisual materials separate terms, and linked
|
| 72 |
+
attachments can carry their own conditions. URLs and descriptive metadata do
|
| 73 |
+
not redistribute those files.
|
| 74 |
+
|
| 75 |
+
## Filters applied
|
| 76 |
+
|
| 77 |
+
| result | documents |
|
| 78 |
+
|---|---:|
|
| 79 |
+
| source records read | 81,422 |
|
| 80 |
+
| shorter than 200 characters | 6,624 |
|
| 81 |
+
| below the Polish-language heuristic | 35 |
|
| 82 |
+
| exact duplicate text | 1,992 |
|
| 83 |
+
| retained | 72,771 |
|
| 84 |
+
|
| 85 |
+
Exact duplicate removal is performed after short-text and language checks.
|
| 86 |
+
Existing DynaWord sources take priority when the same text is already present
|
| 87 |
+
elsewhere in the corpus.
|
| 88 |
+
|
| 89 |
+
## Limitations and recommended use
|
| 90 |
+
|
| 91 |
+
- The collection is not a complete historical archive of samorzad.gov.pl. It
|
| 92 |
+
contains the pages found and successfully extracted during one crawl.
|
| 93 |
+
- Only 21,892 of the 81,422 source records expose a publication date. After
|
| 94 |
+
filtering, 52,214 retained records have an empty `created` value; no date is
|
| 95 |
+
inferred for them.
|
| 96 |
+
- The source text can contain spelling errors, extraction remnants or captions.
|
| 97 |
+
- Very short source records are excluded by DynaWord's 200-character minimum.
|
| 98 |
+
- Institution names describe the publishing body, not necessarily the person
|
| 99 |
+
who wrote an article.
|
| 100 |
+
- Government and institutional language is overrepresented; this source should
|
| 101 |
+
complement, not stand in for, conversational or general Polish.
|
| 102 |
+
- Canonical URLs may stop working as institutions update their websites.
|
| 103 |
+
|
| 104 |
+
## Included files
|
| 105 |
+
|
| 106 |
+
- `samorzad_gov_pl.parquet` — canonical DynaWord records;
|
| 107 |
+
- `samorzad_gov_pl.stats.json` — build and release statistics;
|
| 108 |
+
- `samorzad_gov_pl.attribution.jsonl` — per-document source attribution;
|
| 109 |
+
- `samorzad_gov_pl.license-evidence.json` — release-time license evidence;
|
| 110 |
+
- `NOTICE.md` — attribution and redistribution notice.
|
| 111 |
+
|
| 112 |
+
## Reproduction
|
| 113 |
+
|
| 114 |
+
The converter refuses to build unless the downloaded `manifest.json` and all
|
| 115 |
+
10 Parquet shards match the pinned release. It verifies the manifest SHA-256,
|
| 116 |
+
artifact set, shard sizes and SHA-256 values, row counts, schema, unique record
|
| 117 |
+
IDs and the release-wide record-text digest before conversion. Outputs are
|
| 118 |
+
written to temporary files, cross-checked, synced and transactionally replaced;
|
| 119 |
+
a failed replacement restores the previous artifact set.
|
| 120 |
+
|
| 121 |
+
Download the published source Parquet shards and run:
|
| 122 |
+
|
| 123 |
+
```bash
|
| 124 |
+
hf download dawidmajewski/samorzad-gov-pl-articles \
|
| 125 |
+
--repo-type dataset \
|
| 126 |
+
--revision d5eaefc32c3f17cfa5a01d14573f8e4ee7d43385 \
|
| 127 |
+
--include 'data/*.parquet' --include manifest.json \
|
| 128 |
+
--local-dir /tmp/samorzad-gov-pl-articles
|
| 129 |
+
|
| 130 |
+
uv run --with pyarrow --with tiktoken python src/clean_samorzad_gov_pl.py \
|
| 131 |
+
--input /tmp/samorzad-gov-pl-articles/data \
|
| 132 |
+
--repo-root . \
|
| 133 |
+
--added 2026-08-14
|
| 134 |
+
```
|
| 135 |
+
|
| 136 |
+
Use `--refresh-publishers` only when intentionally updating the frozen
|
| 137 |
+
institution-name manifest from live tenant homepages. Review any changed name
|
| 138 |
+
before publishing a new release.
|
data/samorzad_gov_pl/samorzad_gov_pl.parquet
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:b4f788030bb987b6c12487ea3e2e587bca1d1fd86294c1488961045bfe8fd137
|
| 3 |
+
size 51930059
|
data/samorzad_gov_pl/samorzad_gov_pl.stats.json
ADDED
|
@@ -0,0 +1,25 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"authors_with_value": 72771,
|
| 3 |
+
"central_tenant_count": 1,
|
| 4 |
+
"chars": 109513754,
|
| 5 |
+
"cross_source_hashes_loaded": 4246372,
|
| 6 |
+
"drop_dup": 1992,
|
| 7 |
+
"drop_lang": 35,
|
| 8 |
+
"drop_ocr": 0,
|
| 9 |
+
"drop_short": 6624,
|
| 10 |
+
"kept": 72771,
|
| 11 |
+
"license": "CC-BY-SA-4.0",
|
| 12 |
+
"licenses": {
|
| 13 |
+
"CC-BY-SA-4.0": 72771
|
| 14 |
+
},
|
| 15 |
+
"local_public_tenant_count": 246,
|
| 16 |
+
"publisher_count": 247,
|
| 17 |
+
"read": 81422,
|
| 18 |
+
"redirected_urls": 693,
|
| 19 |
+
"tokens": 41154506,
|
| 20 |
+
"upstream_artifact_count": 10,
|
| 21 |
+
"upstream_dataset": "dawidmajewski/samorzad-gov-pl-articles",
|
| 22 |
+
"upstream_manifest_sha256": "97b5a266b2fd4f043648b7d3c757721cd826c7ca1048301761084b0abdee5c48",
|
| 23 |
+
"upstream_record_text_sha256": "6c35e1dc0bd35863ddb2f4e43d5bd08264c1fc27affdd60684ab5ecbc5457f63",
|
| 24 |
+
"upstream_revision": "d5eaefc32c3f17cfa5a01d14573f8e4ee7d43385"
|
| 25 |
+
}
|
pattern_frequency_report.md
CHANGED
|
@@ -1,18 +1,18 @@
|
|
| 1 |
## Pattern frequency on corpus
|
| 2 |
|
| 3 |
-
- total tokens (tiktoken proxy): `
|
| 4 |
|
| 5 |
| pattern | count | share of all tokens |
|
| 6 |
|---|---:|---:|
|
| 7 |
-
| `w roku` |
|
| 8 |
-
| `klasyfikacji` |
|
| 9 |
-
| `ustawa` |
|
| 10 |
-
| `artykuł` | 2,
|
| 11 |
-
| `parlament` | 1,
|
| 12 |
-
| `rozporządzenie` | 1,
|
| 13 |
-
| `w pobliżu` |
|
| 14 |
-
| `mieszkańców` |
|
| 15 |
-
| `Dz.U.` |
|
| 16 |
|
| 17 |
| source | pattern | count | per-token share |
|
| 18 |
|---|---|---:|---:|
|
|
@@ -25,6 +25,15 @@
|
|
| 25 |
| 1000_novels | `w pobliżu` | 1,262 | 0.00209% |
|
| 26 |
| 1000_novels | `mieszkańców` | 868 | 0.00143% |
|
| 27 |
| 1000_novels | `Dz.U.` | 0 | 0.00000% |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 28 |
| dziennik_ustaw | `w roku` | 33,096 | 0.00681% |
|
| 29 |
| dziennik_ustaw | `klasyfikacji` | 10,896 | 0.00224% |
|
| 30 |
| dziennik_ustaw | `ustawa` | 77,376 | 0.01592% |
|
|
@@ -52,15 +61,15 @@
|
|
| 52 |
| eurlex | `w pobliżu` | 6,088 | 0.00026% |
|
| 53 |
| eurlex | `mieszkańców` | 9,441 | 0.00040% |
|
| 54 |
| eurlex | `Dz.U.` | 915,707 | 0.03851% |
|
| 55 |
-
| european_hplt_v3_pl | `w roku` |
|
| 56 |
-
| european_hplt_v3_pl | `klasyfikacji` |
|
| 57 |
-
| european_hplt_v3_pl | `ustawa` |
|
| 58 |
-
| european_hplt_v3_pl | `artykuł` |
|
| 59 |
-
| european_hplt_v3_pl | `parlament` |
|
| 60 |
-
| european_hplt_v3_pl | `rozporządzenie` |
|
| 61 |
-
| european_hplt_v3_pl | `w pobliżu` |
|
| 62 |
-
| european_hplt_v3_pl | `mieszkańców` |
|
| 63 |
-
| european_hplt_v3_pl | `Dz.U.` |
|
| 64 |
| global_voices | `w roku` | 160 | 0.00431% |
|
| 65 |
| global_voices | `klasyfikacji` | 5 | 0.00013% |
|
| 66 |
| global_voices | `ustawa` | 157 | 0.00423% |
|
|
@@ -97,6 +106,15 @@
|
|
| 97 |
| parliamentary | `w pobliżu` | 4,964 | 0.00030% |
|
| 98 |
| parliamentary | `mieszkańców` | 78,048 | 0.00474% |
|
| 99 |
| parliamentary | `Dz.U.` | 23,809 | 0.00145% |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 100 |
| wikibooks | `w roku` | 319 | 0.00205% |
|
| 101 |
| wikibooks | `klasyfikacji` | 37 | 0.00024% |
|
| 102 |
| wikibooks | `ustawa` | 165 | 0.00106% |
|
|
|
|
| 1 |
## Pattern frequency on corpus
|
| 2 |
|
| 3 |
+
- total tokens (tiktoken proxy): `9,639,062,573`
|
| 4 |
|
| 5 |
| pattern | count | share of all tokens |
|
| 6 |
|---|---:|---:|
|
| 7 |
+
| `w roku` | 585,072 | 0.0061% |
|
| 8 |
+
| `klasyfikacji` | 164,757 | 0.0017% |
|
| 9 |
+
| `ustawa` | 659,103 | 0.0068% |
|
| 10 |
+
| `artykuł` | 2,416,361 | 0.0251% |
|
| 11 |
+
| `parlament` | 1,285,792 | 0.0133% |
|
| 12 |
+
| `rozporządzenie` | 1,527,456 | 0.0158% |
|
| 13 |
+
| `w pobliżu` | 127,784 | 0.0013% |
|
| 14 |
+
| `mieszkańców` | 476,710 | 0.0049% |
|
| 15 |
+
| `Dz.U.` | 987,048 | 0.0102% |
|
| 16 |
|
| 17 |
| source | pattern | count | per-token share |
|
| 18 |
|---|---|---:|---:|
|
|
|
|
| 25 |
| 1000_novels | `w pobliżu` | 1,262 | 0.00209% |
|
| 26 |
| 1000_novels | `mieszkańców` | 868 | 0.00143% |
|
| 27 |
| 1000_novels | `Dz.U.` | 0 | 0.00000% |
|
| 28 |
+
| biblioteka_nauki | `w roku` | 28,728 | 0.00427% |
|
| 29 |
+
| biblioteka_nauki | `klasyfikacji` | 9,045 | 0.00134% |
|
| 30 |
+
| biblioteka_nauki | `ustawa` | 48,791 | 0.00724% |
|
| 31 |
+
| biblioteka_nauki | `artykuł` | 91,241 | 0.01355% |
|
| 32 |
+
| biblioteka_nauki | `parlament` | 32,868 | 0.00488% |
|
| 33 |
+
| biblioteka_nauki | `rozporządzenie` | 19,594 | 0.00291% |
|
| 34 |
+
| biblioteka_nauki | `w pobliżu` | 3,378 | 0.00050% |
|
| 35 |
+
| biblioteka_nauki | `mieszkańców` | 34,392 | 0.00511% |
|
| 36 |
+
| biblioteka_nauki | `Dz.U.` | 33,098 | 0.00491% |
|
| 37 |
| dziennik_ustaw | `w roku` | 33,096 | 0.00681% |
|
| 38 |
| dziennik_ustaw | `klasyfikacji` | 10,896 | 0.00224% |
|
| 39 |
| dziennik_ustaw | `ustawa` | 77,376 | 0.01592% |
|
|
|
|
| 61 |
| eurlex | `w pobliżu` | 6,088 | 0.00026% |
|
| 62 |
| eurlex | `mieszkańców` | 9,441 | 0.00040% |
|
| 63 |
| eurlex | `Dz.U.` | 915,707 | 0.03851% |
|
| 64 |
+
| european_hplt_v3_pl | `w roku` | 113,501 | 0.00444% |
|
| 65 |
+
| european_hplt_v3_pl | `klasyfikacji` | 24,675 | 0.00097% |
|
| 66 |
+
| european_hplt_v3_pl | `ustawa` | 16,067 | 0.00063% |
|
| 67 |
+
| european_hplt_v3_pl | `artykuł` | 283,875 | 0.01111% |
|
| 68 |
+
| european_hplt_v3_pl | `parlament` | 45,516 | 0.00178% |
|
| 69 |
+
| european_hplt_v3_pl | `rozporządzenie` | 11,841 | 0.00046% |
|
| 70 |
+
| european_hplt_v3_pl | `w pobliżu` | 44,108 | 0.00173% |
|
| 71 |
+
| european_hplt_v3_pl | `mieszkańców` | 172,896 | 0.00677% |
|
| 72 |
+
| european_hplt_v3_pl | `Dz.U.` | 9,487 | 0.00037% |
|
| 73 |
| global_voices | `w roku` | 160 | 0.00431% |
|
| 74 |
| global_voices | `klasyfikacji` | 5 | 0.00013% |
|
| 75 |
| global_voices | `ustawa` | 157 | 0.00423% |
|
|
|
|
| 106 |
| parliamentary | `w pobliżu` | 4,964 | 0.00030% |
|
| 107 |
| parliamentary | `mieszkańców` | 78,048 | 0.00474% |
|
| 108 |
| parliamentary | `Dz.U.` | 23,809 | 0.00145% |
|
| 109 |
+
| samorzad_gov_pl | `w roku` | 3,661 | 0.00890% |
|
| 110 |
+
| samorzad_gov_pl | `klasyfikacji` | 520 | 0.00126% |
|
| 111 |
+
| samorzad_gov_pl | `ustawa` | 1,823 | 0.00443% |
|
| 112 |
+
| samorzad_gov_pl | `artykuł` | 1,269 | 0.00308% |
|
| 113 |
+
| samorzad_gov_pl | `parlament` | 1,218 | 0.00296% |
|
| 114 |
+
| samorzad_gov_pl | `rozporządzenie` | 1,409 | 0.00342% |
|
| 115 |
+
| samorzad_gov_pl | `w pobliżu` | 401 | 0.00097% |
|
| 116 |
+
| samorzad_gov_pl | `mieszkańców` | 14,450 | 0.03511% |
|
| 117 |
+
| samorzad_gov_pl | `Dz.U.` | 1,380 | 0.00335% |
|
| 118 |
| wikibooks | `w roku` | 319 | 0.00205% |
|
| 119 |
| wikibooks | `klasyfikacji` | 37 | 0.00024% |
|
| 120 |
| wikibooks | `ustawa` | 165 | 0.00106% |
|
src/clean_samorzad_gov_pl.py
ADDED
|
@@ -0,0 +1,513 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
#!/usr/bin/env python3
|
| 2 |
+
"""Convert dawidmajewski/samorzad-gov-pl-articles to DynaWord.
|
| 3 |
+
|
| 4 |
+
The input is the published source dataset. Institution names are frozen in a
|
| 5 |
+
committed publisher manifest generated from each tenant homepage's
|
| 6 |
+
``og:site_name`` metadata. The output uses DynaWord's canonical eight columns
|
| 7 |
+
and writes a URL-bearing attribution sidecar for CC-BY-SA compliance.
|
| 8 |
+
"""
|
| 9 |
+
from __future__ import annotations
|
| 10 |
+
|
| 11 |
+
import argparse
|
| 12 |
+
import hashlib
|
| 13 |
+
import html as html_module
|
| 14 |
+
import http.client
|
| 15 |
+
import json
|
| 16 |
+
import os
|
| 17 |
+
import re
|
| 18 |
+
import shutil
|
| 19 |
+
import tempfile
|
| 20 |
+
import time
|
| 21 |
+
import urllib.request
|
| 22 |
+
from pathlib import Path
|
| 23 |
+
|
| 24 |
+
import pyarrow as pa
|
| 25 |
+
import pyarrow.dataset as ds
|
| 26 |
+
import pyarrow.parquet as pq
|
| 27 |
+
|
| 28 |
+
SOURCE = "samorzad_gov_pl"
|
| 29 |
+
LICENSE = "CC-BY-SA-4.0"
|
| 30 |
+
LICENSE_URL = "https://creativecommons.org/licenses/by-sa/4.0/"
|
| 31 |
+
UPSTREAM_DATASET = "dawidmajewski/samorzad-gov-pl-articles"
|
| 32 |
+
UPSTREAM_REVISION = "d5eaefc32c3f17cfa5a01d14573f8e4ee7d43385"
|
| 33 |
+
UPSTREAM_TEXT_SHA256 = "6c35e1dc0bd35863ddb2f4e43d5bd08264c1fc27affdd60684ab5ecbc5457f63"
|
| 34 |
+
UPSTREAM_MANIFEST_SHA256 = "97b5a266b2fd4f043648b7d3c757721cd826c7ca1048301761084b0abdee5c48"
|
| 35 |
+
UPSTREAM_EXPECTED = {
|
| 36 |
+
"manifest_sha256": UPSTREAM_MANIFEST_SHA256,
|
| 37 |
+
"dataset_id": UPSTREAM_DATASET,
|
| 38 |
+
"schema_version": "1.0.0",
|
| 39 |
+
"record_count": 81_422,
|
| 40 |
+
"record_text_sha256": UPSTREAM_TEXT_SHA256,
|
| 41 |
+
}
|
| 42 |
+
MIN_CHARS = 200
|
| 43 |
+
MIN_POLISH_RATIO = 0.005
|
| 44 |
+
POLISH_RE = re.compile(r"[ąćęłńóśźżĄĆĘŁŃÓŚŹŻ]")
|
| 45 |
+
ALPHA_RE = re.compile(r"[^\W\d_]", re.UNICODE)
|
| 46 |
+
_SITE_NAME_RE = re.compile(
|
| 47 |
+
r"<meta\b(?=[^>]*\bproperty\s*=\s*['\"]og:site_name['\"])(?=[^>]*\bcontent\s*=\s*(['\"])(.*?)\1)[^>]*>",
|
| 48 |
+
re.IGNORECASE | re.DOTALL,
|
| 49 |
+
)
|
| 50 |
+
_TITLE_RE = re.compile(r"<title\b[^>]*>(.*?)</title>", re.IGNORECASE | re.DOTALL)
|
| 51 |
+
DYNAWORD_SCHEMA = pa.schema(
|
| 52 |
+
[
|
| 53 |
+
("id", pa.string()),
|
| 54 |
+
("text", pa.string()),
|
| 55 |
+
("source", pa.string()),
|
| 56 |
+
("added", pa.string()),
|
| 57 |
+
("created", pa.string()),
|
| 58 |
+
("token_count", pa.int64()),
|
| 59 |
+
("license", pa.string()),
|
| 60 |
+
("author", pa.string()),
|
| 61 |
+
]
|
| 62 |
+
)
|
| 63 |
+
|
| 64 |
+
|
| 65 |
+
def _clean_html_text(value: str) -> str:
|
| 66 |
+
value = re.sub(r"<[^>]+>", " ", value)
|
| 67 |
+
return " ".join(html_module.unescape(value).split())
|
| 68 |
+
|
| 69 |
+
|
| 70 |
+
def publisher_name_from_html(html: str) -> str:
|
| 71 |
+
"""Extract the human-readable institution name from a tenant homepage."""
|
| 72 |
+
match = _SITE_NAME_RE.search(html)
|
| 73 |
+
if match:
|
| 74 |
+
return _clean_html_text(match.group(2))
|
| 75 |
+
match = _TITLE_RE.search(html)
|
| 76 |
+
if not match:
|
| 77 |
+
return ""
|
| 78 |
+
title = _clean_html_text(match.group(1))
|
| 79 |
+
prefix, suffix = "Strona główna - ", " - Portal gov.pl"
|
| 80 |
+
if title.startswith(prefix) and title.endswith(suffix):
|
| 81 |
+
return title[len(prefix) : -len(suffix)].strip()
|
| 82 |
+
return ""
|
| 83 |
+
|
| 84 |
+
|
| 85 |
+
def _fetch(url: str, attempts: int = 5) -> str:
|
| 86 |
+
last_error: Exception | None = None
|
| 87 |
+
for attempt in range(attempts):
|
| 88 |
+
try:
|
| 89 |
+
request = urllib.request.Request(
|
| 90 |
+
url,
|
| 91 |
+
headers={"User-Agent": "Polish-DynaWord-source-builder/1.0"},
|
| 92 |
+
)
|
| 93 |
+
with urllib.request.urlopen(request, timeout=45) as response:
|
| 94 |
+
return response.read().decode("utf-8", "replace")
|
| 95 |
+
except (OSError, TimeoutError, http.client.HTTPException) as error:
|
| 96 |
+
last_error = error
|
| 97 |
+
time.sleep(2**attempt)
|
| 98 |
+
raise RuntimeError(f"Could not fetch {url}: {last_error}")
|
| 99 |
+
|
| 100 |
+
|
| 101 |
+
def refresh_publishers(tenants: list[str], output: Path) -> dict[str, str]:
|
| 102 |
+
"""Fetch and freeze one verified display name for every source tenant."""
|
| 103 |
+
publishers: dict[str, str] = {}
|
| 104 |
+
failures: list[str] = []
|
| 105 |
+
for index, tenant in enumerate(sorted(set(tenants)), 1):
|
| 106 |
+
url = f"https://samorzad.gov.pl/web/{tenant}"
|
| 107 |
+
try:
|
| 108 |
+
name = publisher_name_from_html(_fetch(url))
|
| 109 |
+
except RuntimeError:
|
| 110 |
+
name = ""
|
| 111 |
+
if not name:
|
| 112 |
+
failures.append(tenant)
|
| 113 |
+
else:
|
| 114 |
+
publishers[tenant] = name
|
| 115 |
+
print(f"publishers {index}/{len(set(tenants))}: {tenant} -> {name or 'FAILED'}")
|
| 116 |
+
if failures:
|
| 117 |
+
raise RuntimeError(
|
| 118 |
+
"Publisher-name refresh incomplete; retry before release: "
|
| 119 |
+
+ ", ".join(failures)
|
| 120 |
+
)
|
| 121 |
+
output.parent.mkdir(parents=True, exist_ok=True)
|
| 122 |
+
output.write_text(
|
| 123 |
+
json.dumps(
|
| 124 |
+
{
|
| 125 |
+
"schema_version": "1.0.0",
|
| 126 |
+
"source": "tenant homepage og:site_name",
|
| 127 |
+
"publishers": publishers,
|
| 128 |
+
},
|
| 129 |
+
ensure_ascii=False,
|
| 130 |
+
indent=2,
|
| 131 |
+
sort_keys=True,
|
| 132 |
+
)
|
| 133 |
+
+ "\n",
|
| 134 |
+
encoding="utf-8",
|
| 135 |
+
)
|
| 136 |
+
return publishers
|
| 137 |
+
|
| 138 |
+
|
| 139 |
+
def load_publishers(path: Path) -> dict[str, str]:
|
| 140 |
+
data = json.loads(path.read_text(encoding="utf-8"))
|
| 141 |
+
publishers = data.get("publishers")
|
| 142 |
+
if data.get("schema_version") != "1.0.0" or not isinstance(publishers, dict):
|
| 143 |
+
raise ValueError(f"Invalid publisher manifest: {path}")
|
| 144 |
+
if not all(isinstance(k, str) and isinstance(v, str) and v.strip() for k, v in publishers.items()):
|
| 145 |
+
raise ValueError(f"Empty or invalid publisher in {path}")
|
| 146 |
+
return publishers
|
| 147 |
+
|
| 148 |
+
|
| 149 |
+
def _file_sha256(path: Path) -> str:
|
| 150 |
+
digest = hashlib.sha256()
|
| 151 |
+
with path.open("rb") as handle:
|
| 152 |
+
for chunk in iter(lambda: handle.read(1024 * 1024), b""):
|
| 153 |
+
digest.update(chunk)
|
| 154 |
+
return digest.hexdigest()
|
| 155 |
+
|
| 156 |
+
|
| 157 |
+
def verify_upstream_release(
|
| 158 |
+
input_path: Path,
|
| 159 |
+
manifest_path: Path,
|
| 160 |
+
expected: dict[str, object] = UPSTREAM_EXPECTED,
|
| 161 |
+
) -> dict:
|
| 162 |
+
"""Fail closed unless input exactly matches the pinned published release."""
|
| 163 |
+
input_path = input_path.resolve()
|
| 164 |
+
manifest_path = manifest_path.resolve()
|
| 165 |
+
raw_manifest = manifest_path.read_bytes()
|
| 166 |
+
if hashlib.sha256(raw_manifest).hexdigest() != expected["manifest_sha256"]:
|
| 167 |
+
raise ValueError("Upstream manifest hash mismatch")
|
| 168 |
+
manifest = json.loads(raw_manifest)
|
| 169 |
+
for key in ("dataset_id", "schema_version", "record_count", "record_text_sha256"):
|
| 170 |
+
if manifest.get(key) != expected[key]:
|
| 171 |
+
raise ValueError(f"Upstream manifest {key} mismatch")
|
| 172 |
+
|
| 173 |
+
artifact_paths: list[Path] = []
|
| 174 |
+
artifact_records = 0
|
| 175 |
+
for artifact in manifest.get("artifacts", []):
|
| 176 |
+
path = (manifest_path.parent / artifact["path"]).resolve()
|
| 177 |
+
if path.parent != input_path:
|
| 178 |
+
raise ValueError(f"Upstream artifact outside input directory: {path}")
|
| 179 |
+
if not path.is_file():
|
| 180 |
+
raise ValueError(f"Missing upstream artifact: {path}")
|
| 181 |
+
if path.stat().st_size != artifact["bytes"]:
|
| 182 |
+
raise ValueError(f"Upstream artifact size mismatch: {path.name}")
|
| 183 |
+
if _file_sha256(path) != artifact["sha256"]:
|
| 184 |
+
raise ValueError(f"Upstream artifact hash mismatch: {path.name}")
|
| 185 |
+
if pq.ParquetFile(path).metadata.num_rows != artifact["records"]:
|
| 186 |
+
raise ValueError(f"Upstream artifact row-count mismatch: {path.name}")
|
| 187 |
+
artifact_paths.append(path)
|
| 188 |
+
artifact_records += artifact["records"]
|
| 189 |
+
|
| 190 |
+
actual_paths = sorted(path.resolve() for path in input_path.glob("*.parquet"))
|
| 191 |
+
if sorted(artifact_paths) != actual_paths:
|
| 192 |
+
raise ValueError("Upstream artifact set differs from manifest")
|
| 193 |
+
if artifact_records != expected["record_count"]:
|
| 194 |
+
raise ValueError("Upstream artifact record total mismatch")
|
| 195 |
+
|
| 196 |
+
source_dataset = ds.dataset([str(path) for path in actual_paths], format="parquet")
|
| 197 |
+
if source_dataset.schema.names != manifest["record_fields"]:
|
| 198 |
+
raise ValueError("Upstream Parquet schema differs from manifest")
|
| 199 |
+
source_rows = source_dataset.to_table(columns=["record_id", "text"]).to_pylist()
|
| 200 |
+
if len(source_rows) != expected["record_count"]:
|
| 201 |
+
raise ValueError("Upstream dataset record count mismatch")
|
| 202 |
+
source_rows.sort(key=lambda row: row["record_id"])
|
| 203 |
+
if len({row["record_id"] for row in source_rows}) != len(source_rows):
|
| 204 |
+
raise ValueError("Upstream record IDs are not unique")
|
| 205 |
+
text_digest = hashlib.sha256()
|
| 206 |
+
for row in source_rows:
|
| 207 |
+
text_digest.update(row["record_id"].encode())
|
| 208 |
+
text_digest.update(b"\0")
|
| 209 |
+
text_digest.update(row["text"].encode())
|
| 210 |
+
text_digest.update(b"\n")
|
| 211 |
+
if text_digest.hexdigest() != expected["record_text_sha256"]:
|
| 212 |
+
raise ValueError("Upstream record-text digest mismatch")
|
| 213 |
+
return manifest
|
| 214 |
+
|
| 215 |
+
|
| 216 |
+
def normalize_record(
|
| 217 |
+
source: dict,
|
| 218 |
+
publishers: dict[str, str],
|
| 219 |
+
token_count: int,
|
| 220 |
+
added: str,
|
| 221 |
+
) -> tuple[dict, dict]:
|
| 222 |
+
tenant = str(source["tenant"])
|
| 223 |
+
try:
|
| 224 |
+
publisher = publishers[tenant]
|
| 225 |
+
except KeyError as error:
|
| 226 |
+
raise KeyError(f"No publisher name for tenant {tenant}") from error
|
| 227 |
+
record_id = f"{SOURCE}_{source['record_id']}"
|
| 228 |
+
created = source.get("published_date") or ""
|
| 229 |
+
source_url = str(source["source_url"])
|
| 230 |
+
final_url = str(source.get("final_url") or source_url)
|
| 231 |
+
row = {
|
| 232 |
+
"id": record_id,
|
| 233 |
+
"text": str(source["text"]),
|
| 234 |
+
"source": SOURCE,
|
| 235 |
+
"added": added,
|
| 236 |
+
"created": str(created),
|
| 237 |
+
"token_count": int(token_count),
|
| 238 |
+
"license": LICENSE,
|
| 239 |
+
"author": publisher,
|
| 240 |
+
}
|
| 241 |
+
attribution = {
|
| 242 |
+
"id": record_id,
|
| 243 |
+
"title": str(source.get("title") or ""),
|
| 244 |
+
"source_url": source_url,
|
| 245 |
+
"final_url": final_url,
|
| 246 |
+
"attribution_url": final_url,
|
| 247 |
+
"publisher": publisher,
|
| 248 |
+
"tenant": tenant,
|
| 249 |
+
"publisher_type": str(source.get("publisher_type") or ""),
|
| 250 |
+
"license": LICENSE,
|
| 251 |
+
"license_url": LICENSE_URL,
|
| 252 |
+
"modified": True,
|
| 253 |
+
"modification_notice": (
|
| 254 |
+
"Article text was extracted from the source HTML. This DynaWord "
|
| 255 |
+
"release normalizes metadata and may exclude short, non-Polish or "
|
| 256 |
+
"duplicate records; the retained text is otherwise unchanged."
|
| 257 |
+
),
|
| 258 |
+
}
|
| 259 |
+
return row, attribution
|
| 260 |
+
|
| 261 |
+
|
| 262 |
+
def _polish_ratio(text: str) -> float:
|
| 263 |
+
letters = ALPHA_RE.findall(text)
|
| 264 |
+
return len(POLISH_RE.findall(text)) / len(letters) if letters else 0.0
|
| 265 |
+
|
| 266 |
+
|
| 267 |
+
def _text_hash(text: str) -> bytes:
|
| 268 |
+
return hashlib.sha256(text.encode("utf-8")).digest()
|
| 269 |
+
|
| 270 |
+
|
| 271 |
+
def existing_text_hashes(repo_root: Path, output_path: Path) -> set[bytes]:
|
| 272 |
+
"""Load exact-text hashes from all existing DynaWord source Parquets."""
|
| 273 |
+
hashes: set[bytes] = set()
|
| 274 |
+
output_resolved = output_path.resolve()
|
| 275 |
+
for path in sorted((repo_root / "data").glob("*/*.parquet")):
|
| 276 |
+
if path.resolve() == output_resolved or path.parent.name == SOURCE:
|
| 277 |
+
continue
|
| 278 |
+
for batch in pq.ParquetFile(path).iter_batches(columns=["text"], batch_size=4096):
|
| 279 |
+
hashes.update(_text_hash(text) for text in batch.column(0).to_pylist() if text)
|
| 280 |
+
return hashes
|
| 281 |
+
|
| 282 |
+
|
| 283 |
+
def _fsync_path(path: Path) -> None:
|
| 284 |
+
with path.open("rb") as handle:
|
| 285 |
+
os.fsync(handle.fileno())
|
| 286 |
+
|
| 287 |
+
|
| 288 |
+
def _write_text_synced(path: Path, content: str) -> None:
|
| 289 |
+
with path.open("w", encoding="utf-8") as handle:
|
| 290 |
+
handle.write(content)
|
| 291 |
+
handle.flush()
|
| 292 |
+
os.fsync(handle.fileno())
|
| 293 |
+
|
| 294 |
+
|
| 295 |
+
def _validate_staged_release(staged_dir: Path) -> None:
|
| 296 |
+
parquet_path = staged_dir / f"{SOURCE}.parquet"
|
| 297 |
+
sidecar_path = staged_dir / f"{SOURCE}.attribution.jsonl"
|
| 298 |
+
stats = json.loads((staged_dir / f"{SOURCE}.stats.json").read_text())
|
| 299 |
+
table = pq.read_table(parquet_path)
|
| 300 |
+
if table.schema != DYNAWORD_SCHEMA or table.num_rows != stats["kept"]:
|
| 301 |
+
raise ValueError("Staged Parquet does not match canonical schema or stats")
|
| 302 |
+
ids = table["id"].to_pylist()
|
| 303 |
+
authors = table["author"].to_pylist()
|
| 304 |
+
if len(ids) != len(set(ids)):
|
| 305 |
+
raise ValueError("Staged IDs are not unique")
|
| 306 |
+
sidecar_count = 0
|
| 307 |
+
with sidecar_path.open(encoding="utf-8") as handle:
|
| 308 |
+
for sidecar_count, (line, record_id, author) in enumerate(
|
| 309 |
+
zip(handle, ids, authors, strict=True),
|
| 310 |
+
1,
|
| 311 |
+
):
|
| 312 |
+
attribution = json.loads(line)
|
| 313 |
+
if attribution["id"] != record_id or attribution["publisher"] != author:
|
| 314 |
+
raise ValueError("Staged sidecar does not match Parquet order")
|
| 315 |
+
if attribution["attribution_url"] != attribution["final_url"]:
|
| 316 |
+
raise ValueError("Staged attribution URL is not the fetched final URL")
|
| 317 |
+
if sidecar_count != stats["kept"]:
|
| 318 |
+
raise ValueError("Staged sidecar count does not match stats")
|
| 319 |
+
|
| 320 |
+
|
| 321 |
+
def _replace_release(staged_dir: Path, output_dir: Path) -> None:
|
| 322 |
+
"""Replace a validated artifact set, restoring the previous set on error."""
|
| 323 |
+
names = (
|
| 324 |
+
f"{SOURCE}.parquet",
|
| 325 |
+
f"{SOURCE}.attribution.jsonl",
|
| 326 |
+
f"{SOURCE}.stats.json",
|
| 327 |
+
)
|
| 328 |
+
backup_dir = staged_dir / "backup"
|
| 329 |
+
backup_dir.mkdir()
|
| 330 |
+
had_previous: set[str] = set()
|
| 331 |
+
for name in names:
|
| 332 |
+
destination = output_dir / name
|
| 333 |
+
if destination.exists():
|
| 334 |
+
shutil.copy2(destination, backup_dir / name)
|
| 335 |
+
_fsync_path(backup_dir / name)
|
| 336 |
+
had_previous.add(name)
|
| 337 |
+
try:
|
| 338 |
+
for name in names:
|
| 339 |
+
os.replace(staged_dir / name, output_dir / name)
|
| 340 |
+
directory_fd = os.open(output_dir, os.O_RDONLY)
|
| 341 |
+
try:
|
| 342 |
+
os.fsync(directory_fd)
|
| 343 |
+
finally:
|
| 344 |
+
os.close(directory_fd)
|
| 345 |
+
except BaseException:
|
| 346 |
+
for name in names:
|
| 347 |
+
destination = output_dir / name
|
| 348 |
+
backup = backup_dir / name
|
| 349 |
+
if name in had_previous:
|
| 350 |
+
os.replace(backup, destination)
|
| 351 |
+
elif destination.exists():
|
| 352 |
+
destination.unlink()
|
| 353 |
+
raise
|
| 354 |
+
|
| 355 |
+
|
| 356 |
+
def build(
|
| 357 |
+
input_path: Path,
|
| 358 |
+
manifest_path: Path,
|
| 359 |
+
repo_root: Path,
|
| 360 |
+
publishers_path: Path,
|
| 361 |
+
added: str,
|
| 362 |
+
refresh: bool,
|
| 363 |
+
) -> dict:
|
| 364 |
+
manifest = verify_upstream_release(input_path, manifest_path)
|
| 365 |
+
source_dataset = ds.dataset(str(input_path), format="parquet")
|
| 366 |
+
source_table = source_dataset.to_table(
|
| 367 |
+
columns=[
|
| 368 |
+
"record_id",
|
| 369 |
+
"source_url",
|
| 370 |
+
"final_url",
|
| 371 |
+
"tenant",
|
| 372 |
+
"publisher_type",
|
| 373 |
+
"title",
|
| 374 |
+
"text",
|
| 375 |
+
"published_date",
|
| 376 |
+
]
|
| 377 |
+
)
|
| 378 |
+
records = sorted(source_table.to_pylist(), key=lambda row: row["record_id"])
|
| 379 |
+
tenants = sorted({row["tenant"] for row in records})
|
| 380 |
+
tenant_types = {row["tenant"]: row["publisher_type"] for row in records}
|
| 381 |
+
publishers = (
|
| 382 |
+
refresh_publishers(tenants, publishers_path)
|
| 383 |
+
if refresh
|
| 384 |
+
else load_publishers(publishers_path)
|
| 385 |
+
)
|
| 386 |
+
missing = sorted(set(tenants) - set(publishers))
|
| 387 |
+
if missing:
|
| 388 |
+
raise RuntimeError(f"Publisher manifest misses {len(missing)} tenants: {missing}")
|
| 389 |
+
|
| 390 |
+
output_dir = repo_root / "data" / SOURCE
|
| 391 |
+
output_dir.mkdir(parents=True, exist_ok=True)
|
| 392 |
+
parquet_path = output_dir / f"{SOURCE}.parquet"
|
| 393 |
+
prior_hashes = existing_text_hashes(repo_root, parquet_path)
|
| 394 |
+
seen = set(prior_hashes)
|
| 395 |
+
|
| 396 |
+
candidates: list[dict] = []
|
| 397 |
+
stats = {
|
| 398 |
+
"read": len(records),
|
| 399 |
+
"kept": 0,
|
| 400 |
+
"drop_short": 0,
|
| 401 |
+
"drop_lang": 0,
|
| 402 |
+
"drop_dup": 0,
|
| 403 |
+
"drop_ocr": 0,
|
| 404 |
+
"chars": 0,
|
| 405 |
+
"tokens": 0,
|
| 406 |
+
"licenses": {LICENSE: 0},
|
| 407 |
+
"authors_with_value": 0,
|
| 408 |
+
"publisher_count": len(publishers),
|
| 409 |
+
"local_public_tenant_count": sum(
|
| 410 |
+
publisher_type != "central" for publisher_type in tenant_types.values()
|
| 411 |
+
),
|
| 412 |
+
"central_tenant_count": sum(
|
| 413 |
+
publisher_type == "central" for publisher_type in tenant_types.values()
|
| 414 |
+
),
|
| 415 |
+
"redirected_urls": 0,
|
| 416 |
+
"cross_source_hashes_loaded": len(prior_hashes),
|
| 417 |
+
"license": LICENSE,
|
| 418 |
+
"upstream_dataset": UPSTREAM_DATASET,
|
| 419 |
+
"upstream_revision": UPSTREAM_REVISION,
|
| 420 |
+
"upstream_record_text_sha256": UPSTREAM_TEXT_SHA256,
|
| 421 |
+
"upstream_manifest_sha256": hashlib.sha256(manifest_path.read_bytes()).hexdigest(),
|
| 422 |
+
"upstream_artifact_count": len(manifest["artifacts"]),
|
| 423 |
+
}
|
| 424 |
+
for record in records:
|
| 425 |
+
text = str(record.get("text") or "").strip()
|
| 426 |
+
if len(text) < MIN_CHARS:
|
| 427 |
+
stats["drop_short"] += 1
|
| 428 |
+
continue
|
| 429 |
+
if _polish_ratio(text) < MIN_POLISH_RATIO:
|
| 430 |
+
stats["drop_lang"] += 1
|
| 431 |
+
continue
|
| 432 |
+
digest = _text_hash(text)
|
| 433 |
+
if digest in seen:
|
| 434 |
+
stats["drop_dup"] += 1
|
| 435 |
+
continue
|
| 436 |
+
seen.add(digest)
|
| 437 |
+
record["text"] = text
|
| 438 |
+
candidates.append(record)
|
| 439 |
+
|
| 440 |
+
import tiktoken
|
| 441 |
+
|
| 442 |
+
encoder = tiktoken.get_encoding("cl100k_base")
|
| 443 |
+
token_counts = [
|
| 444 |
+
len(tokens)
|
| 445 |
+
for tokens in encoder.encode_ordinary_batch(
|
| 446 |
+
[record["text"] for record in candidates], num_threads=8
|
| 447 |
+
)
|
| 448 |
+
]
|
| 449 |
+
rows: list[dict] = []
|
| 450 |
+
attribution_rows: list[dict] = []
|
| 451 |
+
for source_row, token_count in zip(candidates, token_counts, strict=True):
|
| 452 |
+
row, attribution = normalize_record(source_row, publishers, token_count, added)
|
| 453 |
+
rows.append(row)
|
| 454 |
+
attribution_rows.append(attribution)
|
| 455 |
+
stats["kept"] += 1
|
| 456 |
+
stats["chars"] += len(row["text"])
|
| 457 |
+
stats["tokens"] += token_count
|
| 458 |
+
stats["licenses"][LICENSE] += 1
|
| 459 |
+
stats["authors_with_value"] += int(bool(row["author"]))
|
| 460 |
+
stats["redirected_urls"] += int(
|
| 461 |
+
attribution["source_url"] != attribution["final_url"]
|
| 462 |
+
)
|
| 463 |
+
|
| 464 |
+
table = pa.Table.from_pylist(rows, schema=DYNAWORD_SCHEMA)
|
| 465 |
+
with tempfile.TemporaryDirectory(prefix=f".{SOURCE}-", dir=output_dir) as temp:
|
| 466 |
+
staged_dir = Path(temp)
|
| 467 |
+
staged_parquet = staged_dir / f"{SOURCE}.parquet"
|
| 468 |
+
staged_sidecar = staged_dir / f"{SOURCE}.attribution.jsonl"
|
| 469 |
+
staged_stats = staged_dir / f"{SOURCE}.stats.json"
|
| 470 |
+
pq.write_table(table, staged_parquet, compression="zstd", row_group_size=4096)
|
| 471 |
+
_fsync_path(staged_parquet)
|
| 472 |
+
_write_text_synced(
|
| 473 |
+
staged_sidecar,
|
| 474 |
+
"".join(
|
| 475 |
+
json.dumps(row, ensure_ascii=False, sort_keys=True) + "\n"
|
| 476 |
+
for row in attribution_rows
|
| 477 |
+
),
|
| 478 |
+
)
|
| 479 |
+
_write_text_synced(
|
| 480 |
+
staged_stats,
|
| 481 |
+
json.dumps(stats, ensure_ascii=False, indent=2, sort_keys=True) + "\n",
|
| 482 |
+
)
|
| 483 |
+
_validate_staged_release(staged_dir)
|
| 484 |
+
_replace_release(staged_dir, output_dir)
|
| 485 |
+
return stats
|
| 486 |
+
|
| 487 |
+
|
| 488 |
+
def main() -> None:
|
| 489 |
+
parser = argparse.ArgumentParser()
|
| 490 |
+
parser.add_argument("--input", type=Path, required=True, help="directory containing source Parquet shards")
|
| 491 |
+
parser.add_argument(
|
| 492 |
+
"--manifest",
|
| 493 |
+
type=Path,
|
| 494 |
+
help="pinned source manifest (default: MANIFEST next to the input directory)",
|
| 495 |
+
)
|
| 496 |
+
parser.add_argument("--repo-root", type=Path, default=Path(__file__).resolve().parents[1])
|
| 497 |
+
parser.add_argument("--publishers", type=Path, default=Path(__file__).with_name("samorzad_gov_pl_publishers.json"))
|
| 498 |
+
parser.add_argument("--added", required=True)
|
| 499 |
+
parser.add_argument("--refresh-publishers", action="store_true")
|
| 500 |
+
args = parser.parse_args()
|
| 501 |
+
stats = build(
|
| 502 |
+
input_path=args.input,
|
| 503 |
+
manifest_path=args.manifest or args.input.parent / "manifest.json",
|
| 504 |
+
repo_root=args.repo_root.resolve(),
|
| 505 |
+
publishers_path=args.publishers,
|
| 506 |
+
added=args.added,
|
| 507 |
+
refresh=args.refresh_publishers,
|
| 508 |
+
)
|
| 509 |
+
print(json.dumps(stats, ensure_ascii=False, indent=2))
|
| 510 |
+
|
| 511 |
+
|
| 512 |
+
if __name__ == "__main__":
|
| 513 |
+
main()
|
src/make_docs.py
CHANGED
|
@@ -13,8 +13,8 @@ sys.path.insert(0, str(Path(__file__).resolve().parent))
|
|
| 13 |
from sources import SOURCES, EXCLUDED, ADDED
|
| 14 |
|
| 15 |
ROOT = Path(__file__).resolve().parent.parent
|
| 16 |
-
VERSION = "0.2.
|
| 17 |
-
RELEASE_DATE = "2026-08-
|
| 18 |
CONTACT = "k.wikiel@gmail.com" # notice-and-takedown / data-removal requests
|
| 19 |
|
| 20 |
# Dupochron: documented good-faith provenance + no-warranty + takedown + PII.
|
|
@@ -186,7 +186,8 @@ family (Enevoldsen et al., [arXiv:2508.02271](https://arxiv.org/abs/2508.02271))
|
|
| 186 |
|
| 187 |
| version | status | documents | tokens | notes |
|
| 188 |
|---|---|---:|---:|---|
|
| 189 |
-
| `v0.2.
|
|
|
|
| 190 |
| `v0.2.3` | previous stable | 2,710,974 | 6.88B | Adds community-contributed `european_hplt_v3_pl`, `global_voices` and `nkjp1m`. |
|
| 191 |
| `v0.2.2` | previous stable | 2,579,963 | 6.36B | Added community-contributed `govpl`: 88,190 docs / 80.7M tokens. |
|
| 192 |
| `v0.2.1` | previous stable | 2,491,773 | 6.28B | 12-source corpus with `license` and `author` metadata columns; added `1000_novels`. |
|
|
@@ -203,7 +204,15 @@ family (Enevoldsen et al., [arXiv:2508.02271](https://arxiv.org/abs/2508.02271))
|
|
| 203 |
|
| 204 |
### Version details
|
| 205 |
|
| 206 |
-
#### v0.2.
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 207 |
|
| 208 |
Expanded `european_hplt_v3_pl` from WDS bins 10+9 to **WDS bins 10-5** (added
|
| 209 |
quality bins 8/7/6/5 and further WDS-9 shards): **+1,493,384 documents /
|
|
@@ -287,7 +296,7 @@ as the redistributing aggregator; this release does not claim ownership of them
|
|
| 287 |
| [Bart Kobyliński](https://huggingface.co/bartoszkobylinski1) | Added `1000_novels`; expanded Biblioteka Nauki and Europeana ingestion with per-document license and author metadata. | `v0.2.1`, [PR #1](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/1) |
|
| 288 |
| [Paweł Puzio](https://huggingface.co/ppuzio) | Built `govpl`: subsite discovery, direct ingestion pipeline, dataset artifact, contract tests and documentation. | `v0.2.2`, [PR #9](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/9) |
|
| 289 |
| [Arkadiusz Słota](https://huggingface.co/Maggio33) | Built & expanded `european_hplt_v3_pl`: HPLT v3 WDS 10+9 (PR #5) then WDS 10-5 expansion (+1,493,384 docs / 2.04B tok), modular cleaning pipeline, phone-recall PII-scrub (v12b, independent dual-lens), cross-source dedup-vs-base (zero-overlap), validation and documentation. | `v0.2.3` (PR #5), `v0.2.4` |
|
| 290 |
-
| [Dawid Majewski](https://huggingface.co/dawidmajewski) | Added the reviewed Global Voices Polish corpus with
|
| 291 |
| [1am](https://huggingface.co/1am) | Added `nkjp1m`: the manually annotated 1-million-word NKJP subcorpus, direct fetch/build pipeline, source documentation and release artifact. | `v0.2.3`, [PR #8](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/8) |
|
| 292 |
|
| 293 |
Contributions are credited when they add a verifiable dataset artifact, pipeline,
|
|
@@ -336,16 +345,15 @@ workflow therefore separates **source inclusion** from **training mix**:
|
|
| 336 |
|
| 337 |
Current v0.3 source-ingestion status:
|
| 338 |
|
| 339 |
-
- `biblioteka_nauki`:
|
| 340 |
-
|
| 341 |
-
v{VERSION} parquets yet.
|
| 342 |
- `europeana`: prepared in the source registry as a direct-upstream rebuild
|
| 343 |
target with per-record rights statements and creator metadata; raw SpeakLeash
|
| 344 |
Europeana remains excluded.
|
| 345 |
- Europeana release policy: split conservatively at pre-1929 records for
|
| 346 |
US-sensitive downstream reuse, and keep later/unknown records separately
|
| 347 |
labeled or held until legal review.
|
| 348 |
-
- `european_hplt_v3_pl`: WDS bins 10
|
| 349 |
validation. HPLT packaging is CC0, while underlying crawled web documents can
|
| 350 |
carry independent rights; downstream near-dedup and web-content review remain
|
| 351 |
recommended before training.
|
|
|
|
| 13 |
from sources import SOURCES, EXCLUDED, ADDED
|
| 14 |
|
| 15 |
ROOT = Path(__file__).resolve().parent.parent
|
| 16 |
+
VERSION = "0.2.5"
|
| 17 |
+
RELEASE_DATE = "2026-08-14"
|
| 18 |
CONTACT = "k.wikiel@gmail.com" # notice-and-takedown / data-removal requests
|
| 19 |
|
| 20 |
# Dupochron: documented good-faith provenance + no-warranty + takedown + PII.
|
|
|
|
| 186 |
|
| 187 |
| version | status | documents | tokens | notes |
|
| 188 |
|---|---|---:|---:|---|
|
| 189 |
+
| `v0.2.5` | stable release | {tot_doc:,} | {tot_tok/1e9:.2f}B | Adds community-contributed `samorzad_gov_pl` with institution-level author attribution and a URL-bearing attribution sidecar. |
|
| 190 |
+
| `v0.2.4` | previous stable | 4,246,429 | 9.60B | Expanded `european_hplt_v3_pl` to WDS bins 10-5 (+1.49M docs / 2.04B tok); phone PII-scrub hardening (independent dual-lens) + cross-source dedup (zero-overlap). |
|
| 191 |
| `v0.2.3` | previous stable | 2,710,974 | 6.88B | Adds community-contributed `european_hplt_v3_pl`, `global_voices` and `nkjp1m`. |
|
| 192 |
| `v0.2.2` | previous stable | 2,579,963 | 6.36B | Added community-contributed `govpl`: 88,190 docs / 80.7M tokens. |
|
| 193 |
| `v0.2.1` | previous stable | 2,491,773 | 6.28B | 12-source corpus with `license` and `author` metadata columns; added `1000_novels`. |
|
|
|
|
| 204 |
|
| 205 |
### Version details
|
| 206 |
|
| 207 |
+
#### v0.2.5 — current stable
|
| 208 |
+
|
| 209 |
+
Added `samorzad_gov_pl`, a directly collected corpus of articles from 246
|
| 210 |
+
Polish local public institutions and one central platform tenant. The
|
| 211 |
+
contribution preserves the publishing institution as `author`, discovered and
|
| 212 |
+
fetched article URLs in an attribution sidecar and the platform's CC-BY-SA-4.0
|
| 213 |
+
basis.
|
| 214 |
+
|
| 215 |
+
#### v0.2.4 — previous stable
|
| 216 |
|
| 217 |
Expanded `european_hplt_v3_pl` from WDS bins 10+9 to **WDS bins 10-5** (added
|
| 218 |
quality bins 8/7/6/5 and further WDS-9 shards): **+1,493,384 documents /
|
|
|
|
| 296 |
| [Bart Kobyliński](https://huggingface.co/bartoszkobylinski1) | Added `1000_novels`; expanded Biblioteka Nauki and Europeana ingestion with per-document license and author metadata. | `v0.2.1`, [PR #1](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/1) |
|
| 297 |
| [Paweł Puzio](https://huggingface.co/ppuzio) | Built `govpl`: subsite discovery, direct ingestion pipeline, dataset artifact, contract tests and documentation. | `v0.2.2`, [PR #9](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/9) |
|
| 298 |
| [Arkadiusz Słota](https://huggingface.co/Maggio33) | Built & expanded `european_hplt_v3_pl`: HPLT v3 WDS 10+9 (PR #5) then WDS 10-5 expansion (+1,493,384 docs / 2.04B tok), modular cleaning pipeline, phone-recall PII-scrub (v12b, independent dual-lens), cross-source dedup-vs-base (zero-overlap), validation and documentation. | `v0.2.3` (PR #5), `v0.2.4` |
|
| 299 |
+
| [Dawid Majewski](https://huggingface.co/dawidmajewski) | Added the reviewed Global Voices Polish corpus; built `samorzad_gov_pl` with direct acquisition, institution attribution, licensing evidence, release artifact and reproducible conversion. | `v0.2.3`, [PR #7](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/7); `v0.2.5` |
|
| 300 |
| [1am](https://huggingface.co/1am) | Added `nkjp1m`: the manually annotated 1-million-word NKJP subcorpus, direct fetch/build pipeline, source documentation and release artifact. | `v0.2.3`, [PR #8](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/8) |
|
| 301 |
|
| 302 |
Contributions are credited when they add a verifiable dataset artifact, pipeline,
|
|
|
|
| 345 |
|
| 346 |
Current v0.3 source-ingestion status:
|
| 347 |
|
| 348 |
+
- `biblioteka_nauki`: included from the direct-upstream rebuild with
|
| 349 |
+
per-document license and author metadata.
|
|
|
|
| 350 |
- `europeana`: prepared in the source registry as a direct-upstream rebuild
|
| 351 |
target with per-record rights statements and creator metadata; raw SpeakLeash
|
| 352 |
Europeana remains excluded.
|
| 353 |
- Europeana release policy: split conservatively at pre-1929 records for
|
| 354 |
US-sensitive downstream reuse, and keep later/unknown records separately
|
| 355 |
labeled or held until legal review.
|
| 356 |
+
- `european_hplt_v3_pl`: WDS bins 10-5 are included in v{VERSION} after contract
|
| 357 |
validation. HPLT packaging is CC0, while underlying crawled web documents can
|
| 358 |
carry independent rights; downstream near-dedup and web-content review remain
|
| 359 |
recommended before training.
|
src/plot_version_growth.py
CHANGED
|
@@ -10,9 +10,23 @@ from matplotlib.ticker import FuncFormatter
|
|
| 10 |
ROOT = Path(__file__).resolve().parent.parent
|
| 11 |
OUTPUT = ROOT / "artifacts" / "dataset_size_by_version.png"
|
| 12 |
|
| 13 |
-
VERSIONS = ["v0.2.0", "v0.2.1", "v0.2.2", "v0.2.3"]
|
| 14 |
-
DOCUMENTS = [
|
| 15 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 16 |
|
| 17 |
|
| 18 |
def millions(value, _position):
|
|
|
|
| 10 |
ROOT = Path(__file__).resolve().parent.parent
|
| 11 |
OUTPUT = ROOT / "artifacts" / "dataset_size_by_version.png"
|
| 12 |
|
| 13 |
+
VERSIONS = ["v0.2.0", "v0.2.1", "v0.2.2", "v0.2.3", "v0.2.4", "v0.2.5"]
|
| 14 |
+
DOCUMENTS = [
|
| 15 |
+
2_490_773,
|
| 16 |
+
2_491_773,
|
| 17 |
+
2_579_963,
|
| 18 |
+
2_710_974,
|
| 19 |
+
4_246_429,
|
| 20 |
+
4_319_200,
|
| 21 |
+
]
|
| 22 |
+
TOKENS = [
|
| 23 |
+
6_221_393_871,
|
| 24 |
+
6_281_911_234,
|
| 25 |
+
6_362_577_363,
|
| 26 |
+
6_881_277_362,
|
| 27 |
+
9_597_908_067,
|
| 28 |
+
9_639_062_573,
|
| 29 |
+
]
|
| 30 |
|
| 31 |
|
| 32 |
def millions(value, _position):
|
src/samorzad_gov_pl_publishers.json
ADDED
|
@@ -0,0 +1,253 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"publishers": {
|
| 3 |
+
"bajka-konstantynow": "Przedszkole nr 3 BAJKA w Konstantynowie Łódzkim",
|
| 4 |
+
"bursa-ostrowiec": "Bursa Szkolna w Ostrowcu Świętokrzyskim",
|
| 5 |
+
"bursa-zambrow": "Bursa Szkolna Nr 1 w Zambrowie",
|
| 6 |
+
"centrum-kultury-i-promocji-gminy-bobowa": "Centrum Kultury i Promocji Gminy Bobowa",
|
| 7 |
+
"ckz1-jaslo": "Centrum Kształcenia Zawodowego Nr 1 w Jaśle",
|
| 8 |
+
"cuw-deblin": "Centrum Usług Wspólnych w Dęblinie",
|
| 9 |
+
"cuw-ostrowiec": "Centrum Usług Wspólnych w Ostrowcu Świętokrzyskim",
|
| 10 |
+
"dps-w-barczewie": "DPS w Barczewie",
|
| 11 |
+
"dps-zielonka": "DPS Zielonka",
|
| 12 |
+
"gmina-augustow": "Gmina Augustów",
|
| 13 |
+
"gmina-bobowa": "Gmina Bobowa",
|
| 14 |
+
"gmina-bodzechow": "Gmina Bodzechów",
|
| 15 |
+
"gmina-bransk": "Gmina Brańsk",
|
| 16 |
+
"gmina-branszczyk": "Gmina Brańszczyk",
|
| 17 |
+
"gmina-brzyska": "Gmina Brzyska",
|
| 18 |
+
"gmina-buczkowice": "Gmina Buczkowice",
|
| 19 |
+
"gmina-budzyn": "Gmina Budzyń",
|
| 20 |
+
"gmina-chlopice": "Gmina Chłopice",
|
| 21 |
+
"gmina-chodziez": "Gmina Chodzież",
|
| 22 |
+
"gmina-ciepielow": "Gmina Ciepielów",
|
| 23 |
+
"gmina-ciezkowice": "Gmina Ciężkowice",
|
| 24 |
+
"gmina-dlutow": "Gmina Dłutów",
|
| 25 |
+
"gmina-dobron": "Gmina Dobroń",
|
| 26 |
+
"gmina-gielniow": "Gmina Gielniów",
|
| 27 |
+
"gmina-goraj": "Gmina Goraj",
|
| 28 |
+
"gmina-gorzno": "Gmina Górzno",
|
| 29 |
+
"gmina-grajewo": "Gmina Grajewo",
|
| 30 |
+
"gmina-grodzisko-dolne": "Gmina Grodzisko Dolne",
|
| 31 |
+
"gmina-hazlach": "Gmina Hażlach",
|
| 32 |
+
"gmina-jablonna-lacka": "Gmina Jabłonna Lacka",
|
| 33 |
+
"gmina-janowiec-wielkopolski": "Gmina Janowiec Wielkopolski",
|
| 34 |
+
"gmina-jaslo": "Gmina Jasło",
|
| 35 |
+
"gmina-kalwaria-zebrzydowska": "Gmina Kalwaria Zebrzydowska",
|
| 36 |
+
"gmina-kamieniec-zabkowicki": "Gmina Kamieniec Ząbkowicki",
|
| 37 |
+
"gmina-klodawa-wielkopolskie": "Gmina Kłodawa wielkopolskie",
|
| 38 |
+
"gmina-kluczewsko": "Gmina Kluczewsko",
|
| 39 |
+
"gmina-kobiele-wielkie": "Gmina Kobiele Wielkie",
|
| 40 |
+
"gmina-kobior": "Gmina Kobiór",
|
| 41 |
+
"gmina-konstantynow-lodzki": "Gmina Konstantynów Łódzki",
|
| 42 |
+
"gmina-korczew": "Gmina Korczew",
|
| 43 |
+
"gmina-krasnopol": "Gmina Krasnopol",
|
| 44 |
+
"gmina-krempna": "Gmina Krempna",
|
| 45 |
+
"gmina-krzyz-wielkopolski": "Gmina Krzyż Wielkopolski",
|
| 46 |
+
"gmina-lanckorona": "Gmina Lanckorona",
|
| 47 |
+
"gmina-leczyce": "Gmina Łęczyce",
|
| 48 |
+
"gmina-lezajsk": "Gmina Leżajsk",
|
| 49 |
+
"gmina-lubenia": "Gmina Lubenia",
|
| 50 |
+
"gmina-lutocin": "Gmina Lutocin",
|
| 51 |
+
"gmina-lutomiersk": "Gmina Lutomiersk",
|
| 52 |
+
"gmina-luzino": "Gmina Luzino",
|
| 53 |
+
"gmina-margonin": "Gmina Margonin",
|
| 54 |
+
"gmina-medyka": "Gmina Medyka",
|
| 55 |
+
"gmina-miasto-mordy": "Gmina i Miasto Mordy",
|
| 56 |
+
"gmina-mokobody": "Gmina Mokobody",
|
| 57 |
+
"gmina-mucharz": "Gmina Mucharz",
|
| 58 |
+
"gmina-olszanka": "Gmina Olszanka",
|
| 59 |
+
"gmina-pokrzywnica": "Gmina Pokrzywnica",
|
| 60 |
+
"gmina-raba-wyzna": "Gmina Raba Wyżna",
|
| 61 |
+
"gmina-radzanow": "Gmina Radzanów",
|
| 62 |
+
"gmina-repki": "Gmina Repki",
|
| 63 |
+
"gmina-rojewo": "Gmina Rojewo",
|
| 64 |
+
"gmina-ruda-maleniecka": "Gmina Ruda Maleniecka",
|
| 65 |
+
"gmina-rudka": "Gmina Rudka",
|
| 66 |
+
"gmina-sawin": "Gmina Sawin",
|
| 67 |
+
"gmina-siedlce": "Gmina Siedlce",
|
| 68 |
+
"gmina-siepraw": "Gmina Siepraw",
|
| 69 |
+
"gmina-skape": "Gmina Skąpe",
|
| 70 |
+
"gmina-skorzec": "Gmina Skórzec",
|
| 71 |
+
"gmina-smykow": "Gmina Smyków",
|
| 72 |
+
"gmina-somianka": "Gmina Somianka",
|
| 73 |
+
"gmina-stryszow": "Gmina Stryszów",
|
| 74 |
+
"gmina-swierklaniec": "Gmina Świerklaniec",
|
| 75 |
+
"gmina-szastarka": "Gmina Szastarka",
|
| 76 |
+
"gmina-tyczyn": "Gmina Tyczyn",
|
| 77 |
+
"gmina-tymbark": "Gmina Tymbark",
|
| 78 |
+
"gmina-wielgomlyny": "Gmina Wielgomłyny",
|
| 79 |
+
"gmina-wieniawa": "Gmina Wieniawa",
|
| 80 |
+
"gmina-wierzbica": "Gmina Wierzbica",
|
| 81 |
+
"gmina-wietrzychowice": "Gmina Wietrzychowice",
|
| 82 |
+
"gmina-wisniew": "Gmina Wiśniew",
|
| 83 |
+
"gmina-wymiarki": "Gmina Wymiarki",
|
| 84 |
+
"gmina-zabrodzie": "Gmina Zabrodzie",
|
| 85 |
+
"gmina-zwolen": "Gmina Zwoleń",
|
| 86 |
+
"gminna-biblioteka-publiczna-w-pokrzywnicy": "Gminna Biblioteka Publiczna w Pokrzywnicy",
|
| 87 |
+
"gminne-przedszkole-w-wierzbicy": "Gminne Przedszkole w Wierzbicy",
|
| 88 |
+
"gminny-klub-dzieciecy-w-gzowie": "Gminny Klub Dziecięcy w Gzowie",
|
| 89 |
+
"gminny-osrodek-pomocy-spolecznej-w-lutomiersku": "Gminny Ośrodek Pomocy Społecznej w Lutomiersku",
|
| 90 |
+
"gok-lutomiersk": "Gminny Ośrodek Kultury w Lutomiersku",
|
| 91 |
+
"gops-augustow": "GOPS Augustów",
|
| 92 |
+
"gops-baranowo": "GOPS Baranowo",
|
| 93 |
+
"gops-buczkowice": "GOPS Buczkowice",
|
| 94 |
+
"gops-ciezkowice": "GOPS Ciężkowice",
|
| 95 |
+
"gops-dobron": "GOPS Dobroń",
|
| 96 |
+
"gops-hajnowka": "GOPS Hajnówka",
|
| 97 |
+
"gops-klukowo": "GOPS Klukowo",
|
| 98 |
+
"gops-korczew": "GOPS Korczew",
|
| 99 |
+
"gops-krupski-mlyn": "GOPS Krupski Młyn",
|
| 100 |
+
"gops-lanckorona": "GOPS Lanckorona",
|
| 101 |
+
"gops-mokobody": "GOPS Mokobody",
|
| 102 |
+
"gops-mszana-dolna": "GOPS Mszana Dolna",
|
| 103 |
+
"gops-opatow": "GOPS Opatów",
|
| 104 |
+
"gops-pokrzywnica": "GOPS Pokrzywnica",
|
| 105 |
+
"gops-pszczolki": "GOPS Pszczółki",
|
| 106 |
+
"gops-sabnie": "GOPS Sabnie",
|
| 107 |
+
"gops-siedlce": "GOPS Siedlce",
|
| 108 |
+
"gops-wapno": "GOPS Wapno",
|
| 109 |
+
"gops-wysokie-mazowieckie": "GOPS Wysokie Mazowieckie",
|
| 110 |
+
"gops-zabrodzie": "GOPS Zabrodzie",
|
| 111 |
+
"gops-zbroslawice": "GOPS Zbrosławice",
|
| 112 |
+
"gov": "Gov.pl",
|
| 113 |
+
"lo-turek": "I Liceum Ogólnokształcące im. Tadeusza Kościuszki w Turku",
|
| 114 |
+
"lo1-sandomierz": "I Liceum Ogólnokształcące Collegium Gostomianum w Sandomierzu",
|
| 115 |
+
"maz-wierzbica": "Gmina Wierzbica (woj. mazowieckie)",
|
| 116 |
+
"mazowieckie-centrum-rehabilitacji-stocer-sp-z-oo": "Mazowieckie Centrum Rehabilitacji \"Stocer\" Sp. z o.o.",
|
| 117 |
+
"mgops-janowiec-wielkopolski": "MGOPS Janowiec Wielkopolski",
|
| 118 |
+
"mgops-kaczory": "MGOPS w Kaczorach",
|
| 119 |
+
"mgops-szepietowo": "MGOPS Szepietowo",
|
| 120 |
+
"mgops-w-twardogorze": "MGOPS w Twardogórze",
|
| 121 |
+
"mgops-witnica": "MGOPS Witnica",
|
| 122 |
+
"miasto-chelm": "Miasto Chełm",
|
| 123 |
+
"miasto-chodziez": "Miasto Chodzież",
|
| 124 |
+
"miasto-i-gmina-kaczory": "Miasto i Gmina Kaczory",
|
| 125 |
+
"miasto-i-gmina-lipsko": "Miasto i Gmina Lipsko",
|
| 126 |
+
"miasto-lubawa": "Miasto Lubawa",
|
| 127 |
+
"miasto-rybnik": "Miasto Rybnik",
|
| 128 |
+
"miejskie-przedszkole-nr-3-w-sokolowie-podlskim": "Miejskie Przedszkole nr 3 w Sokołowie Podlaskim",
|
| 129 |
+
"mig-solec": "Miasto i Gmina Solec nad Wisłą",
|
| 130 |
+
"mops-chodziez": "MOPS Chodzież",
|
| 131 |
+
"mops-dabrowa-bialostocka": "MOPS Dąbrowa Białostocka",
|
| 132 |
+
"mops-konstantynow-lodzki": "MOPS Konstantynów Łódzki",
|
| 133 |
+
"mops-mragowo": "MOPS Mrągowo",
|
| 134 |
+
"mops-rumia": "MOPS Rumia",
|
| 135 |
+
"mops-szczecinek": "MOPS Szczecinek",
|
| 136 |
+
"mops-zgierz": "MOPS Zgierz",
|
| 137 |
+
"pcpr-dabrowa-tarnowska": "PCPR Dąbrowa Tarnowska",
|
| 138 |
+
"pcpr-goldap": "PCPR Gołdap",
|
| 139 |
+
"pcpr-hajnowka": "PCPR Hajnówka",
|
| 140 |
+
"pcpr-konskie": "PCPR Końskie",
|
| 141 |
+
"pcpr-kutno": "PCPR Kutno",
|
| 142 |
+
"pcpr-ostrowiec-swietokrzyski": "PCPR Ostrowiec Świętokrzyski",
|
| 143 |
+
"pcpr-proszowice": "PCPR Proszowice",
|
| 144 |
+
"pcpr-sandomierz": "PCPR Sandomierz",
|
| 145 |
+
"pcpr-zambrow": "PCPR Zambrów",
|
| 146 |
+
"pop-starachowice": "Państwowe Ognisko Plastyczne w Starachowicach",
|
| 147 |
+
"popppidm-polkowice": "POPPPiDM w Polkowicach",
|
| 148 |
+
"poradnia-pp-hajnowka": "Poradnia Psychologiczno-Pedagogiczna w Hajnówce",
|
| 149 |
+
"powiat-bialostocki": "Powiat Białostocki",
|
| 150 |
+
"powiat-bielski": "Powiat Bielski",
|
| 151 |
+
"powiat-dabrowski": "Powiat Dąbrowski",
|
| 152 |
+
"powiat-garwolin": "Powiat Garwoliński",
|
| 153 |
+
"powiat-goldapski": "Powiat Gołdapski",
|
| 154 |
+
"powiat-gorlicki": "Powiat Gorlicki",
|
| 155 |
+
"powiat-hajnowski": "Powiat Hajnowski",
|
| 156 |
+
"powiat-jasielski": "Powiat Jasielski",
|
| 157 |
+
"powiat-konecki": "Powiat Konecki",
|
| 158 |
+
"powiat-krasnicki": "Powiat Kraśnicki",
|
| 159 |
+
"powiat-kutnowski": "Powiat Kutnowski",
|
| 160 |
+
"powiat-lipski": "Powiat Lipski",
|
| 161 |
+
"powiat-losicki": "Powiat Łosicki",
|
| 162 |
+
"powiat-makowski": "Powiat Makowski",
|
| 163 |
+
"powiat-mragowo": "Powiat Mrągowo",
|
| 164 |
+
"powiat-nowomiejski": "Powiat Nowomiejski",
|
| 165 |
+
"powiat-oleski": "Powiat Oleski",
|
| 166 |
+
"powiat-olesnicki": "Powiat Oleśnicki",
|
| 167 |
+
"powiat-ostrowiecki": "Powiat Ostrowiecki",
|
| 168 |
+
"powiat-polkowicki": "Powiat Polkowicki",
|
| 169 |
+
"powiat-proszowicki": "Powiat Proszowicki",
|
| 170 |
+
"powiat-pruszkowski": "Powiat Pruszkowski",
|
| 171 |
+
"powiat-przasnyski": "Powiat Przasnyski",
|
| 172 |
+
"powiat-siedlecki": "Powiat Siedlecki",
|
| 173 |
+
"powiat-siemiatycki": "Powiat Siemiatycki",
|
| 174 |
+
"powiat-sokolowski": "Powiat Sokołowski",
|
| 175 |
+
"powiat-swiebodzinski": "Powiat Świebodziński",
|
| 176 |
+
"powiat-wloclawski": "Powiat Włocławski",
|
| 177 |
+
"powiat-wolominski": "Powiat Wołomiński",
|
| 178 |
+
"powiat-zambrowski": "Powiat Zambrowski",
|
| 179 |
+
"powiatowe-centrum-pomocy-rodzinie-w-skarzysku-kamiennej": "Powiatowe Centrum Pomocy Rodzinie w Skarżysku Kamiennej",
|
| 180 |
+
"pp7-ostrowiec": "Przedszkole Publiczne nr 7 w Ostrowcu Świętokrzyskim",
|
| 181 |
+
"ppp-wloszczowa": "Poradnia Psychologiczno-Pedagogiczna we Włoszczowie",
|
| 182 |
+
"pppp-w-stoku-lackim": "Powiatowa Poradnia Psychologiczno-Pedagogiczna w Stoku Lackim",
|
| 183 |
+
"przedszkole-cikowice": "Gminne Przedszkole w Cikowicach",
|
| 184 |
+
"przedszkole-kaczory": "Publiczne Przedszkole w Kaczorach",
|
| 185 |
+
"przedszkole-nr1-rumia": "Słoneczna Jedynka Przedszkole Nr 1 w Rumi",
|
| 186 |
+
"przedszkole-rumia": "Przedszkole pod Topolą w Rumi",
|
| 187 |
+
"przedszkole3-hajnowka": "Przedszkole Nr 3 z Oddziałami Integracyjnymi im. Żubra Pompika w Hajnówce",
|
| 188 |
+
"psds-w-staporkowie": "PŚDS w Stąporkowie",
|
| 189 |
+
"pzdp-cieszyn": "Powiatowy Zarząd Dróg Publicznych w Cieszynie",
|
| 190 |
+
"pzopo-makowmaz": "Powiatowy Zespół ds. Obsługi Szkół i Placówek Oświatowych w Makowie Mazowieckim",
|
| 191 |
+
"scdn-kielce": "ŚCDN Kielce",
|
| 192 |
+
"smbusko-zdroj": "Szkoła Muzyczna I stopnia im. Krzysztofa Pendereckiego w Busku-Zdroju",
|
| 193 |
+
"sp-damienice": "Szkoła Podstawowa im. Króla Kazimierza Wielkiego w Damienicach",
|
| 194 |
+
"sp-kolakowskiego-domanowo": "Szkoła Podstawowa im. por. Izydora Kołakowskiego w Domanowie",
|
| 195 |
+
"sp-labowa": "Szkoła Podstawowa im. Św. Franciszka z Asyżu w Łabowej",
|
| 196 |
+
"sp-lysakow": "SP im. Franciszka Nawrota w Łysakowie",
|
| 197 |
+
"sp-nowawies": "Szkoła Podstawowa im. Ks. Kardynała Stefana Wyszyńskiego w Nowej Wsi",
|
| 198 |
+
"sp-pieczyska": "Szkoła Podstawowa w Pieczyskach",
|
| 199 |
+
"sp-pogwizdow": "Szkoła Podstawowa im. gen. Józefa Bema w Pogwizdowie",
|
| 200 |
+
"sp-raczyce": "Szkoła Podstawowa w Raczycach",
|
| 201 |
+
"sp-radoszyce": "Szkoła Podstawowa im. gen. bryg. Antoniego Hedy Szarego w Radoszycach",
|
| 202 |
+
"sp-sybirakow-netta": "Szkoła Podstawowa im. Sybiraków w Netcie",
|
| 203 |
+
"sp-szydlow": "Szkoła Podstawowa im. Adama Mickiewicza w Szydłowie",
|
| 204 |
+
"sp-tluszcz": "Szkoła Podstawowa im. Jana Pawła II w Tłuszczu",
|
| 205 |
+
"sp-w-dabrowicy": "Szkoła Podstawowa im. Mikołaja Kopernika w Dąbrowicy",
|
| 206 |
+
"sp-zarnow": "Szkoła Podstawowa im. Jana Pawła II w Żarnowie",
|
| 207 |
+
"ssp-wodzislaw": "Samorządowa Szkoła Podstawowa im. Wojska Polskiego w Wodzisławiu",
|
| 208 |
+
"szkola-nr1-rumia": "Szkoła Podstawowa Nr 1 im. Józefa Wybickiego w Rumi",
|
| 209 |
+
"szkola-nr10-rumia": "Szkoła Podstawowa Nr 10 im. Jana Brzechwy w Rumi",
|
| 210 |
+
"szkola-nr4-rumia": "Szkoła Podstawowa Nr 4 im. Janusza Korczaka w Rumi",
|
| 211 |
+
"szkola-nr7-rumia": "Szkoła Podstawowa Nr 7 im. Karola Wojtyły w Rumi",
|
| 212 |
+
"szkola-nr8-rumia": "Szkoła Podstawowa Nr 8 im. ks. Stanisława Ormińskiego w Rumi",
|
| 213 |
+
"szkola-podstawowa-im-doroty-gellner-w-pobylkowie-duzym": "Szkoła Podstawowa im. Doroty Gellner w Pobyłkowie Dużym",
|
| 214 |
+
"szkola-podstawowa-im-jana-pawla-ii-w-holonkach": "Szkoła Podstawowa im. Jana Pawła II w Holonkach",
|
| 215 |
+
"szkola-podstawowa-im-krolowej-jadwigi-w-tluszczu": "Szkoła Podstawowa im. Królowej Jadwigi w Tłuszczu",
|
| 216 |
+
"szkola-podstawowa-im-ks-jana-twardowskiego-w-gzowie": "Szkoła Podstawowa im. Ks. Jana Twardowskiego w Gzowie",
|
| 217 |
+
"szkola-podstawowa-nr-1-im-juliusza-slowackiego-w-trzciance": "Szkoła Podstawowa Nr 1 im. Juliusza Słowackiego w Trzciance",
|
| 218 |
+
"szkola-podstawowa-w-radomysli": "Szkoła Podstawowa w Radomyśli",
|
| 219 |
+
"szkola-podstawowa-w-smiarach": "Szkoła Podstawowa im. Jana Pawła II w Śmiarach",
|
| 220 |
+
"wombb": "RODN \"WOM\" w Bielsku-Białej",
|
| 221 |
+
"zespol-obslugi-szkol-i-przedszkoli-w-wilkowicach": "Zespół Obsługi Szkół i Przedszkoli w Wilkowicach",
|
| 222 |
+
"zespol-oswiatowy-w-wisniewie": "Zespół Oświatowy w Wiśniewie",
|
| 223 |
+
"zespol-oswiatowy-w-zelkowie-kolonii": "Zespół Oświatowy w Żelkowie-Kolonii",
|
| 224 |
+
"zespol-szkol-nr-3-w-przytkowicach": "Zespół Szkół Nr 3 w Przytkowicach",
|
| 225 |
+
"zespol-szkol-uslugowych-i-spozywczych-w-jasle": "Zespół Szkół Usługowych i Spożywczych w Jaśle",
|
| 226 |
+
"zlobek-chodow": "Żłobek Gminny w Chodowie",
|
| 227 |
+
"zo-pruszyn": "Zespół Oświatowy w Pruszynie",
|
| 228 |
+
"zo-stok-lacki": "Zespół Oświatowy im. Jana Pawła II w Stoku Lackim",
|
| 229 |
+
"zow-strzala": "Zespół Oświatowo-Wychowawczy w Strzale",
|
| 230 |
+
"zow-w-bialkach": "Zespół Oświatowo-Wychowawczy w Białkach",
|
| 231 |
+
"zpo-dziebaltow": "Zespół Placówek Oświatowych w Dziebałtowie",
|
| 232 |
+
"zs-chorzelow": "Zespół Szkół w Chorzelowie",
|
| 233 |
+
"zs-kostomloty-drugie": "Zespół Szkół w Kostomłotach Drugich",
|
| 234 |
+
"zs-podleszany": "Zespół Szkół w Podleszanach",
|
| 235 |
+
"zs-trzesn": "Zespół Szkół w Trześni",
|
| 236 |
+
"zs-wmielecka": "Zespół Szkół w Woli Mieleckiej im. J. M. Ossolińskiego",
|
| 237 |
+
"zs2-wagrowiec": "Zespół Szkół nr 2 im. ppłk. dr Stanisława Kulińskiego w Wągrowcu",
|
| 238 |
+
"zsg-baczkow": "Zespół Szkół Gminnych im. Adama Mickiewicza w Baczkowie",
|
| 239 |
+
"zsg-bogucice": "Zespół Szkół Gminnych im. H. Sienkiewicza w Bogucicach",
|
| 240 |
+
"zsg-nieszkowice-male": "Zespół Szkół Gminnych im. Jana Pawła II w Nieszkowicach Małych",
|
| 241 |
+
"zsg-nieszkowice-wielkie": "Zespół Szkół Gminnych im. Lotników Polskich w Nieszkowicach Wielkich",
|
| 242 |
+
"zsg-proszowki": "Zespół Szkół Gminnych w Proszówkach",
|
| 243 |
+
"zsg-siedlec": "Zespół Szkół Gminnych im. Bohaterów Westerplatte w Siedlcu",
|
| 244 |
+
"zsg-stanislawice": "Zespół Szkół Gminnych w Stanisławicach",
|
| 245 |
+
"zso-rumia": "Zespół Szkół Ogólnokształcących w Rumi",
|
| 246 |
+
"zsp-brzeznica": "Zespół Szkolno-Przedszkolny w Brzeźnicy",
|
| 247 |
+
"zsp-ksiaznice": "Zespół Szkolno-Przedszkolny w Książnicach",
|
| 248 |
+
"zsp-rydzow": "Zespół Szkolno-Przedszkolny w Rydzowie",
|
| 249 |
+
"zsp-rzedzianowice": "Zespół Szkolno-Przedszkolny w Rzędzianowicach"
|
| 250 |
+
},
|
| 251 |
+
"schema_version": "1.0.0",
|
| 252 |
+
"source": "tenant homepage og:site_name"
|
| 253 |
+
}
|
src/sources.py
CHANGED
|
@@ -226,6 +226,29 @@ SOURCES = {
|
|
| 226 |
"created": "2005-09-26, 2026-07-19",
|
| 227 |
"is_ocr": False,
|
| 228 |
},
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 229 |
"biblioteka_nauki": {
|
| 230 |
"file_key": "biblioteka_nauki_pl_corpus",
|
| 231 |
"pretty": "Biblioteka Nauki",
|
|
|
|
| 226 |
"created": "2005-09-26, 2026-07-19",
|
| 227 |
"is_ocr": False,
|
| 228 |
},
|
| 229 |
+
"samorzad_gov_pl": {
|
| 230 |
+
"file_key": "samorzad_gov_pl",
|
| 231 |
+
"pretty": "samorzad.gov.pl — Polish public-sector institutions",
|
| 232 |
+
"license": "CC-BY-SA-4.0",
|
| 233 |
+
"license_spdx": "CC-BY-SA-4.0",
|
| 234 |
+
"traceable": "The shared samorzad.gov.pl platform footer publishes textual "
|
| 235 |
+
"content under CC BY-SA 4.0. Every retained v0.1 source page "
|
| 236 |
+
"referenced the shared footer script; audiovisual media and "
|
| 237 |
+
"attachment bytes are not redistributed.",
|
| 238 |
+
"upstream": "https://huggingface.co/datasets/dawidmajewski/samorzad-gov-pl-articles",
|
| 239 |
+
"provenance": "Converted reproducibly from the published v0.1 source dataset "
|
| 240 |
+
"by src/clean_samorzad_gov_pl.py. The source was collected "
|
| 241 |
+
"directly from public samorzad.gov.pl pages across 246 local "
|
| 242 |
+
"public institutions and one central platform tenant. "
|
| 243 |
+
"Institution display names are frozen "
|
| 244 |
+
"from each tenant homepage's og:site_name metadata and stored "
|
| 245 |
+
"as DynaWord author values; discovered, fetched and attribution "
|
| 246 |
+
"URLs plus license details are preserved in the sidecar.",
|
| 247 |
+
"domain": "local government, education, social services and culture",
|
| 248 |
+
"created": "2020-2026 for 21,892 dated records; 59,530 source records undated",
|
| 249 |
+
"is_ocr": False,
|
| 250 |
+
"custom_datasheet": True,
|
| 251 |
+
},
|
| 252 |
"biblioteka_nauki": {
|
| 253 |
"file_key": "biblioteka_nauki_pl_corpus",
|
| 254 |
"pretty": "Biblioteka Nauki",
|
src/test_samorzad_gov_pl_contract.py
ADDED
|
@@ -0,0 +1,209 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Contract tests for the samorzad.gov.pl contribution."""
|
| 2 |
+
from __future__ import annotations
|
| 3 |
+
|
| 4 |
+
import hashlib
|
| 5 |
+
import json
|
| 6 |
+
import os
|
| 7 |
+
import sys
|
| 8 |
+
from pathlib import Path
|
| 9 |
+
|
| 10 |
+
import pyarrow as pa
|
| 11 |
+
import pyarrow.parquet as pq
|
| 12 |
+
import pytest
|
| 13 |
+
|
| 14 |
+
sys.path.insert(0, str(Path(__file__).resolve().parent))
|
| 15 |
+
|
| 16 |
+
from clean_samorzad_gov_pl import (
|
| 17 |
+
DYNAWORD_SCHEMA,
|
| 18 |
+
_replace_release,
|
| 19 |
+
normalize_record,
|
| 20 |
+
publisher_name_from_html,
|
| 21 |
+
verify_upstream_release,
|
| 22 |
+
)
|
| 23 |
+
|
| 24 |
+
|
| 25 |
+
def test_publisher_name_comes_from_site_name_metadata():
|
| 26 |
+
html = """
|
| 27 |
+
<html><head>
|
| 28 |
+
<meta property="og:site_name" content="Szkoła Podstawowa im. Sybiraków w Netcie">
|
| 29 |
+
<title>Strona główna - inna wartość - Portal gov.pl</title>
|
| 30 |
+
</head></html>
|
| 31 |
+
"""
|
| 32 |
+
assert publisher_name_from_html(html) == "Szkoła Podstawowa im. Sybiraków w Netcie"
|
| 33 |
+
|
| 34 |
+
|
| 35 |
+
def test_publisher_name_falls_back_to_homepage_title():
|
| 36 |
+
html = "<title>Strona główna - Gmina Chłopice - Portal gov.pl</title>"
|
| 37 |
+
assert publisher_name_from_html(html) == "Gmina Chłopice"
|
| 38 |
+
|
| 39 |
+
|
| 40 |
+
def test_normalize_record_maps_publisher_to_author_and_preserves_provenance():
|
| 41 |
+
source = {
|
| 42 |
+
"record_id": "abc123",
|
| 43 |
+
"source_url": "https://samorzad.gov.pl/web/gmina-chlopice/przyklad",
|
| 44 |
+
"final_url": "https://samorzad.gov.pl/web/gmina-chlopice/przyklad-docelowy",
|
| 45 |
+
"tenant": "gmina-chlopice",
|
| 46 |
+
"publisher_type": "municipality",
|
| 47 |
+
"title": "Przykładowy artykuł",
|
| 48 |
+
"text": "Zażółć gęślą jaźń. " * 20,
|
| 49 |
+
"published_date": "2024-05-17",
|
| 50 |
+
}
|
| 51 |
+
row, attribution = normalize_record(
|
| 52 |
+
source,
|
| 53 |
+
publishers={"gmina-chlopice": "Gmina Chłopice"},
|
| 54 |
+
token_count=123,
|
| 55 |
+
added="2026-08-14",
|
| 56 |
+
)
|
| 57 |
+
|
| 58 |
+
assert row == {
|
| 59 |
+
"id": "samorzad_gov_pl_abc123",
|
| 60 |
+
"text": source["text"],
|
| 61 |
+
"source": "samorzad_gov_pl",
|
| 62 |
+
"added": "2026-08-14",
|
| 63 |
+
"created": "2024-05-17",
|
| 64 |
+
"token_count": 123,
|
| 65 |
+
"license": "CC-BY-SA-4.0",
|
| 66 |
+
"author": "Gmina Chłopice",
|
| 67 |
+
}
|
| 68 |
+
assert attribution["id"] == row["id"]
|
| 69 |
+
assert attribution["source_url"] == source["source_url"]
|
| 70 |
+
assert attribution["final_url"] == source["final_url"]
|
| 71 |
+
assert attribution["attribution_url"] == source["final_url"]
|
| 72 |
+
assert attribution["publisher"] == "Gmina Chłopice"
|
| 73 |
+
assert attribution["title"] == source["title"]
|
| 74 |
+
assert attribution["license_url"] == "https://creativecommons.org/licenses/by-sa/4.0/"
|
| 75 |
+
assert attribution["modified"] is True
|
| 76 |
+
|
| 77 |
+
|
| 78 |
+
def test_verify_upstream_release_rejects_modified_shard(tmp_path):
|
| 79 |
+
data_dir = tmp_path / "data"
|
| 80 |
+
data_dir.mkdir()
|
| 81 |
+
shard = data_dir / "train.parquet"
|
| 82 |
+
pq.write_table(
|
| 83 |
+
pa.table({"record_id": ["one"], "text": ["Treść źródłowa"]}),
|
| 84 |
+
shard,
|
| 85 |
+
)
|
| 86 |
+
text_digest = hashlib.sha256()
|
| 87 |
+
text_digest.update("one\0Treść źródłowa\n".encode())
|
| 88 |
+
manifest = {
|
| 89 |
+
"schema_version": "fixture-1",
|
| 90 |
+
"dataset_id": "fixture/dataset",
|
| 91 |
+
"record_count": 1,
|
| 92 |
+
"record_fields": ["record_id", "text"],
|
| 93 |
+
"record_text_sha256": text_digest.hexdigest(),
|
| 94 |
+
"artifacts": [
|
| 95 |
+
{
|
| 96 |
+
"path": "data/train.parquet",
|
| 97 |
+
"records": 1,
|
| 98 |
+
"bytes": shard.stat().st_size,
|
| 99 |
+
"sha256": hashlib.sha256(shard.read_bytes()).hexdigest(),
|
| 100 |
+
}
|
| 101 |
+
],
|
| 102 |
+
}
|
| 103 |
+
manifest_path = tmp_path / "manifest.json"
|
| 104 |
+
manifest_path.write_text(json.dumps(manifest), encoding="utf-8")
|
| 105 |
+
expected = {
|
| 106 |
+
"manifest_sha256": hashlib.sha256(manifest_path.read_bytes()).hexdigest(),
|
| 107 |
+
"dataset_id": "fixture/dataset",
|
| 108 |
+
"schema_version": "fixture-1",
|
| 109 |
+
"record_count": 1,
|
| 110 |
+
"record_text_sha256": text_digest.hexdigest(),
|
| 111 |
+
}
|
| 112 |
+
|
| 113 |
+
verify_upstream_release(data_dir, manifest_path, expected)
|
| 114 |
+
shard.write_bytes(shard.read_bytes() + b"corrupt")
|
| 115 |
+
with pytest.raises(ValueError, match="(size|hash) mismatch"):
|
| 116 |
+
verify_upstream_release(data_dir, manifest_path, expected)
|
| 117 |
+
|
| 118 |
+
|
| 119 |
+
def test_release_replacement_rolls_back_on_failure(tmp_path, monkeypatch):
|
| 120 |
+
names = (
|
| 121 |
+
"samorzad_gov_pl.parquet",
|
| 122 |
+
"samorzad_gov_pl.attribution.jsonl",
|
| 123 |
+
"samorzad_gov_pl.stats.json",
|
| 124 |
+
)
|
| 125 |
+
staged = tmp_path / "staged"
|
| 126 |
+
output = tmp_path / "output"
|
| 127 |
+
staged.mkdir()
|
| 128 |
+
output.mkdir()
|
| 129 |
+
for name in names:
|
| 130 |
+
(staged / name).write_text(f"new:{name}")
|
| 131 |
+
(output / name).write_text(f"old:{name}")
|
| 132 |
+
|
| 133 |
+
original_replace = os.replace
|
| 134 |
+
failed = False
|
| 135 |
+
|
| 136 |
+
def fail_once(source, destination):
|
| 137 |
+
nonlocal failed
|
| 138 |
+
if Path(source) == staged / names[1] and not failed:
|
| 139 |
+
failed = True
|
| 140 |
+
raise OSError("injected replacement failure")
|
| 141 |
+
original_replace(source, destination)
|
| 142 |
+
|
| 143 |
+
monkeypatch.setattr(os, "replace", fail_once)
|
| 144 |
+
with pytest.raises(OSError, match="injected"):
|
| 145 |
+
_replace_release(staged, output)
|
| 146 |
+
assert [(output / name).read_text() for name in names] == [
|
| 147 |
+
f"old:{name}" for name in names
|
| 148 |
+
]
|
| 149 |
+
|
| 150 |
+
|
| 151 |
+
def test_canonical_schema_matches_dynaword():
|
| 152 |
+
assert DYNAWORD_SCHEMA == pa.schema(
|
| 153 |
+
[
|
| 154 |
+
("id", pa.string()),
|
| 155 |
+
("text", pa.string()),
|
| 156 |
+
("source", pa.string()),
|
| 157 |
+
("added", pa.string()),
|
| 158 |
+
("created", pa.string()),
|
| 159 |
+
("token_count", pa.int64()),
|
| 160 |
+
("license", pa.string()),
|
| 161 |
+
("author", pa.string()),
|
| 162 |
+
]
|
| 163 |
+
)
|
| 164 |
+
|
| 165 |
+
|
| 166 |
+
def test_release_artifact_matches_stats_and_has_institution_authors():
|
| 167 |
+
root = Path(__file__).resolve().parents[1]
|
| 168 |
+
data_dir = root / "data" / "samorzad_gov_pl"
|
| 169 |
+
parquet_path = data_dir / "samorzad_gov_pl.parquet"
|
| 170 |
+
stats_path = data_dir / "samorzad_gov_pl.stats.json"
|
| 171 |
+
sidecar_path = data_dir / "samorzad_gov_pl.attribution.jsonl"
|
| 172 |
+
|
| 173 |
+
table = pq.read_table(parquet_path)
|
| 174 |
+
stats = json.loads(stats_path.read_text(encoding="utf-8"))
|
| 175 |
+
attributions = [
|
| 176 |
+
json.loads(line)
|
| 177 |
+
for line in sidecar_path.open(encoding="utf-8")
|
| 178 |
+
if line.strip()
|
| 179 |
+
]
|
| 180 |
+
ids = table["id"].to_pylist()
|
| 181 |
+
texts = table["text"].to_pylist()
|
| 182 |
+
authors = table["author"].to_pylist()
|
| 183 |
+
|
| 184 |
+
assert table.schema == DYNAWORD_SCHEMA
|
| 185 |
+
assert table.num_rows == stats["kept"] == len(attributions)
|
| 186 |
+
assert stats["authors_with_value"] == stats["kept"]
|
| 187 |
+
assert stats["publisher_count"] == 247
|
| 188 |
+
assert stats["local_public_tenant_count"] == 246
|
| 189 |
+
assert stats["central_tenant_count"] == 1
|
| 190 |
+
assert stats["redirected_urls"] == 693
|
| 191 |
+
assert stats["upstream_artifact_count"] == 10
|
| 192 |
+
assert stats["upstream_manifest_sha256"] == (
|
| 193 |
+
"97b5a266b2fd4f043648b7d3c757721cd826c7ca1048301761084b0abdee5c48"
|
| 194 |
+
)
|
| 195 |
+
assert set(table["source"].to_pylist()) == {"samorzad_gov_pl"}
|
| 196 |
+
assert set(table["license"].to_pylist()) == {"CC-BY-SA-4.0"}
|
| 197 |
+
assert len(ids) == len(set(ids))
|
| 198 |
+
assert ids == sorted(ids)
|
| 199 |
+
assert len(texts) == len(set(texts))
|
| 200 |
+
assert all(value.strip() for value in authors)
|
| 201 |
+
assert all(value > 0 for value in table["token_count"].to_pylist())
|
| 202 |
+
assert stats["chars"] == sum(map(len, texts))
|
| 203 |
+
assert stats["tokens"] == sum(table["token_count"].to_pylist())
|
| 204 |
+
assert [item["id"] for item in attributions] == ids
|
| 205 |
+
assert [item["publisher"] for item in attributions] == authors
|
| 206 |
+
assert all(item["attribution_url"] == item["final_url"] for item in attributions)
|
| 207 |
+
assert sum(
|
| 208 |
+
item["source_url"] != item["final_url"] for item in attributions
|
| 209 |
+
) == stats["redirected_urls"]
|