
Datasets:


docs: v0.2.5 includes all 20 sources in the tagged tree
Browse filesThe v0.2.5 tag contains 20 source directories, but the card, changelog and
registry treated sejm_api and wiktionary_examples as built but unreleased
(18 sources, 4,319,200 documents, 9,639,062,573 proxy tokens).
- src/sources.py: release None -> "0.2.5" for sejm_api, wiktionary_examples
- README.md: regenerated with src/make_docs.py; 20 sources, 4,366,651 documents,
9,676,513,980 proxy tokens; unreleased table removed; contributors added
- CHANGELOG.md: remove "Unreleased" section; v0.2.5 lists three added sources
and keeps 2026-08-14 with the tag date 2026-09-07
- src/make_docs.py: same v0.2.5 text so regeneration does not revert it
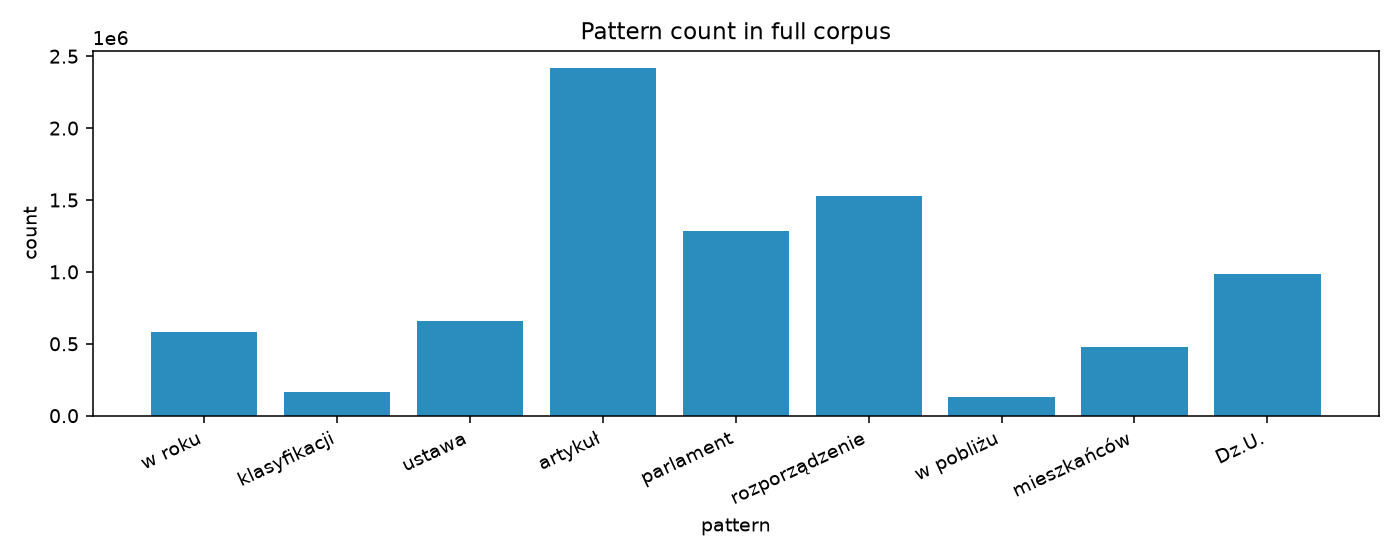
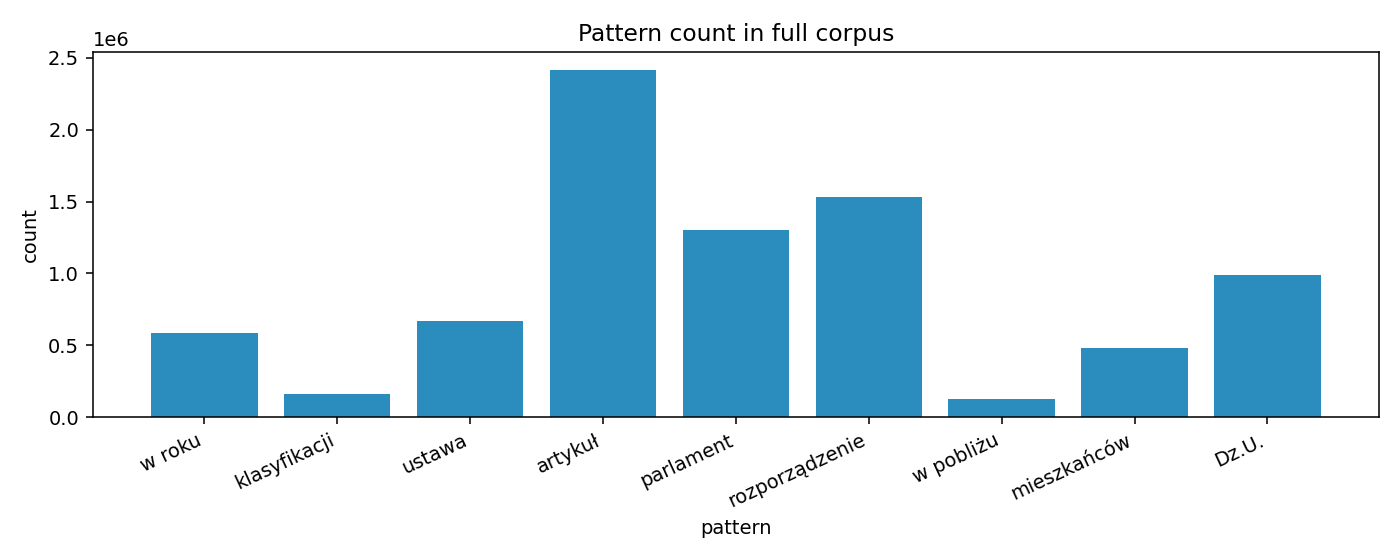
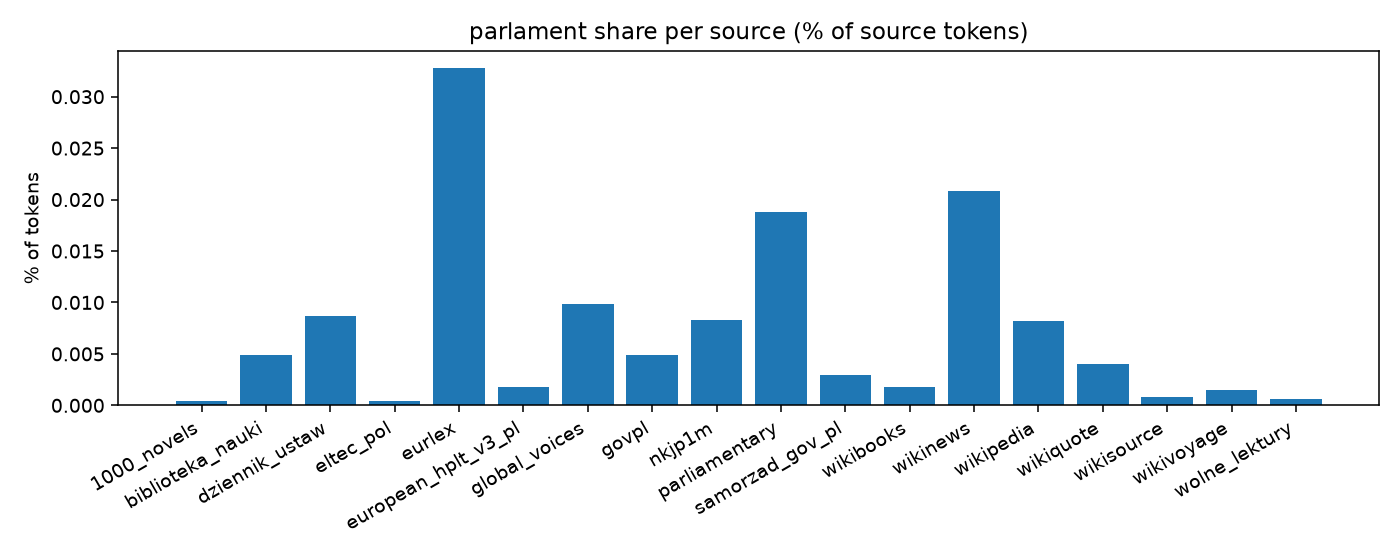
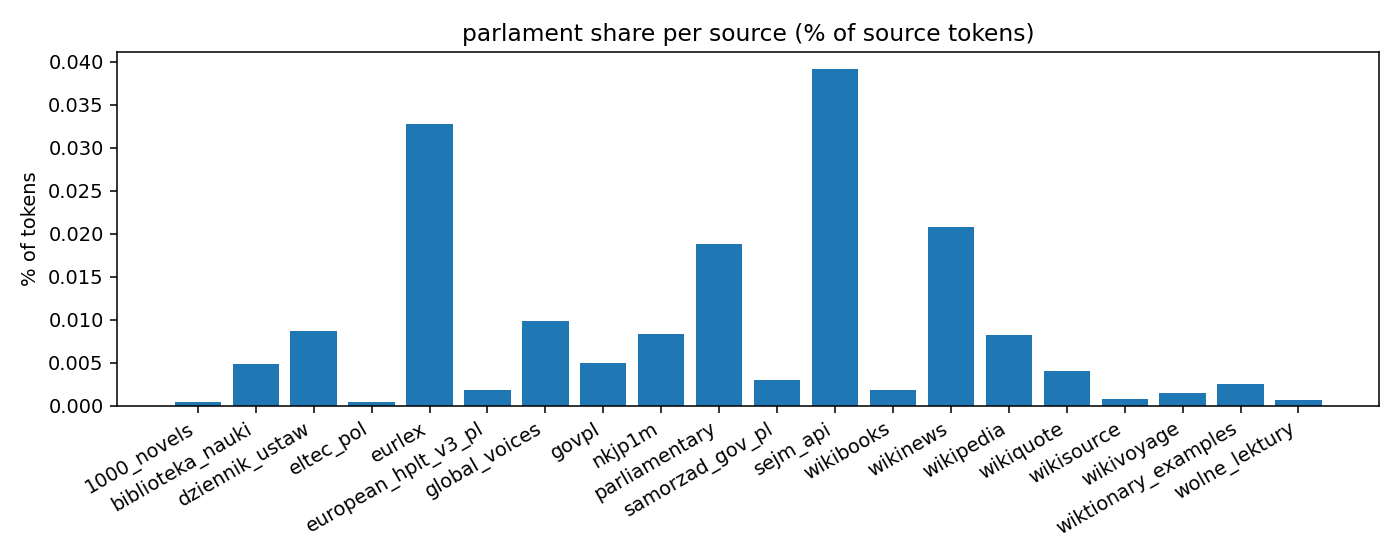
- phrase-frequency report, snippet and charts recomputed over all 20 Parquets
Co-Authored-By: Claude Fable 5.1 <noreply@anthropic.com>
- CHANGELOG.md +17 -13
- README.md +55 -26
- artifacts/pattern_frequency_artykul.png +2 -2
- artifacts/pattern_frequency_dzu.png +2 -2
- artifacts/pattern_frequency_hf_snippet.md +28 -10
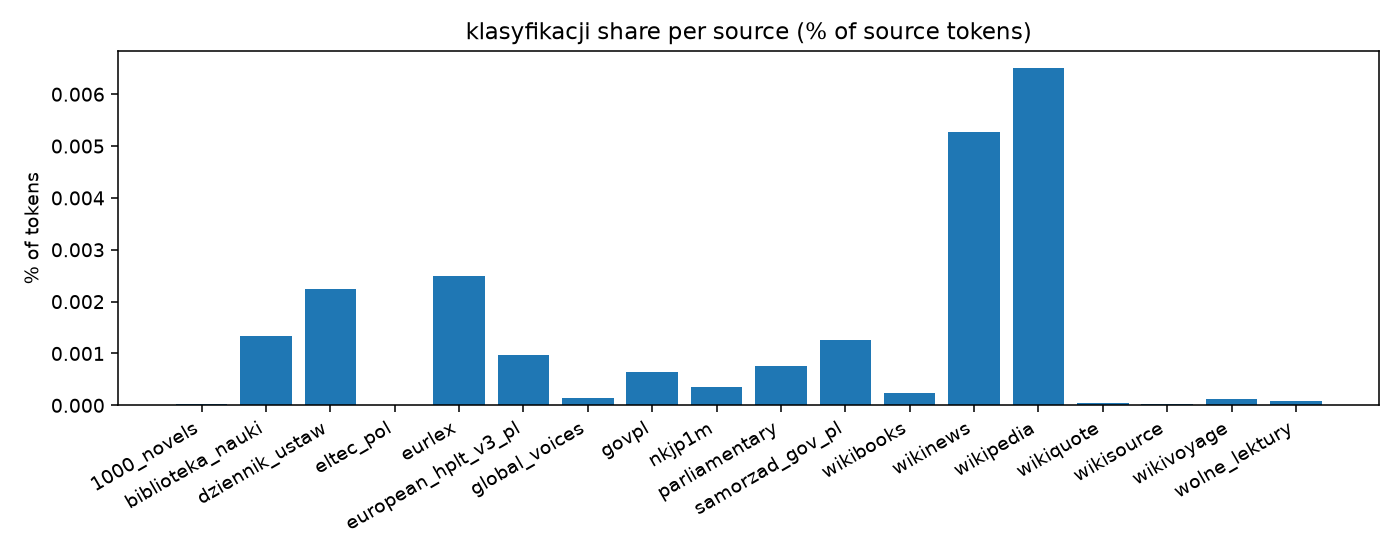
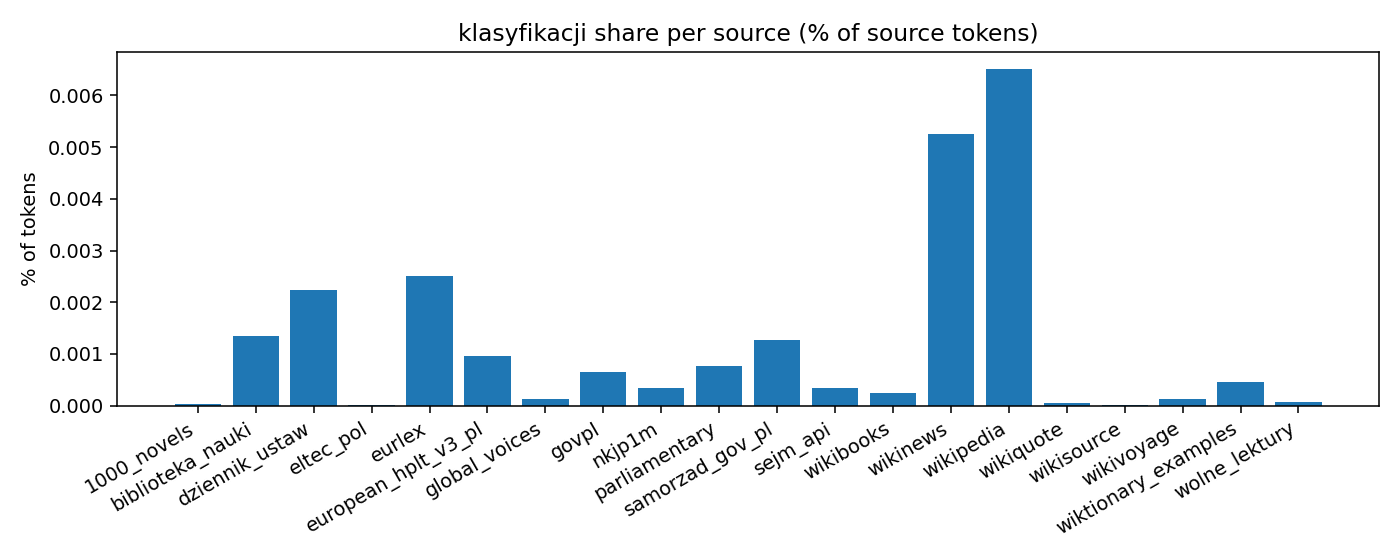
- artifacts/pattern_frequency_klasyfikacji.png +2 -2
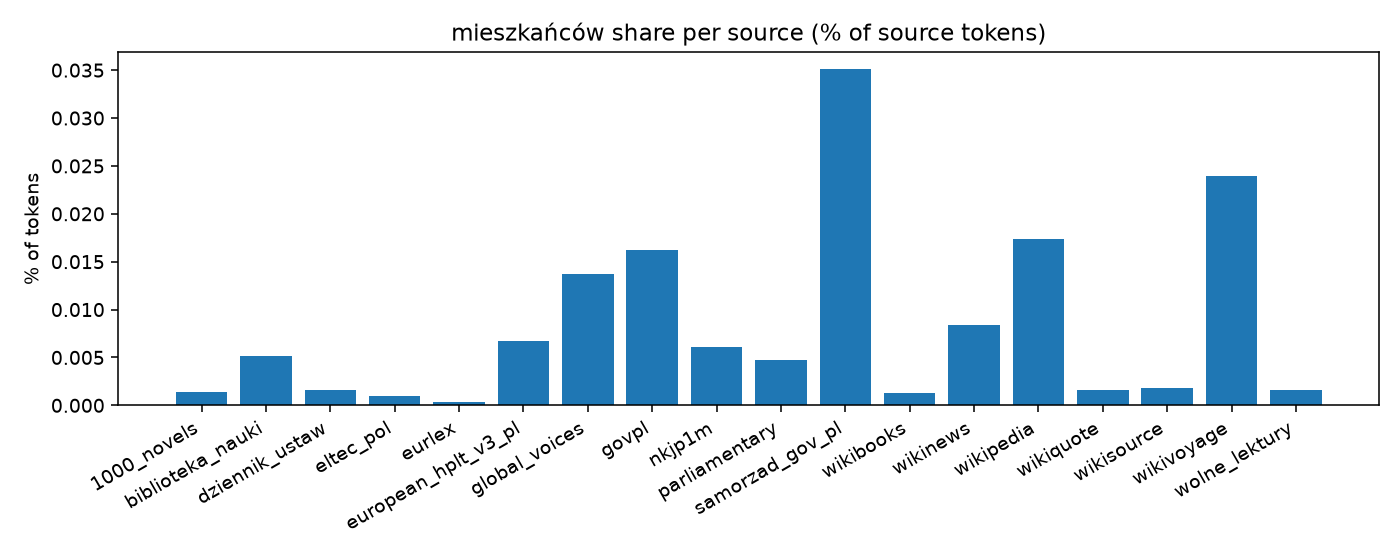
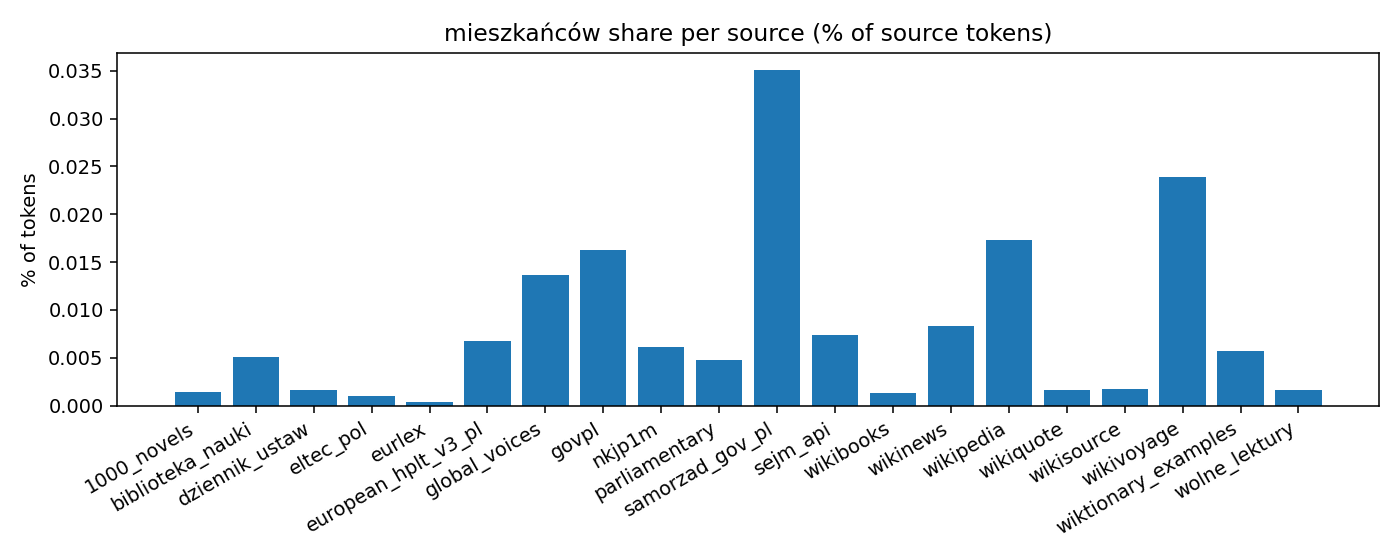
- artifacts/pattern_frequency_mieszkańców.png +2 -2
- artifacts/pattern_frequency_overall.png +2 -2
- artifacts/pattern_frequency_parlament.png +2 -2
- artifacts/pattern_frequency_rozporządzenie.png +2 -2
- artifacts/pattern_frequency_ustawa.png +2 -2
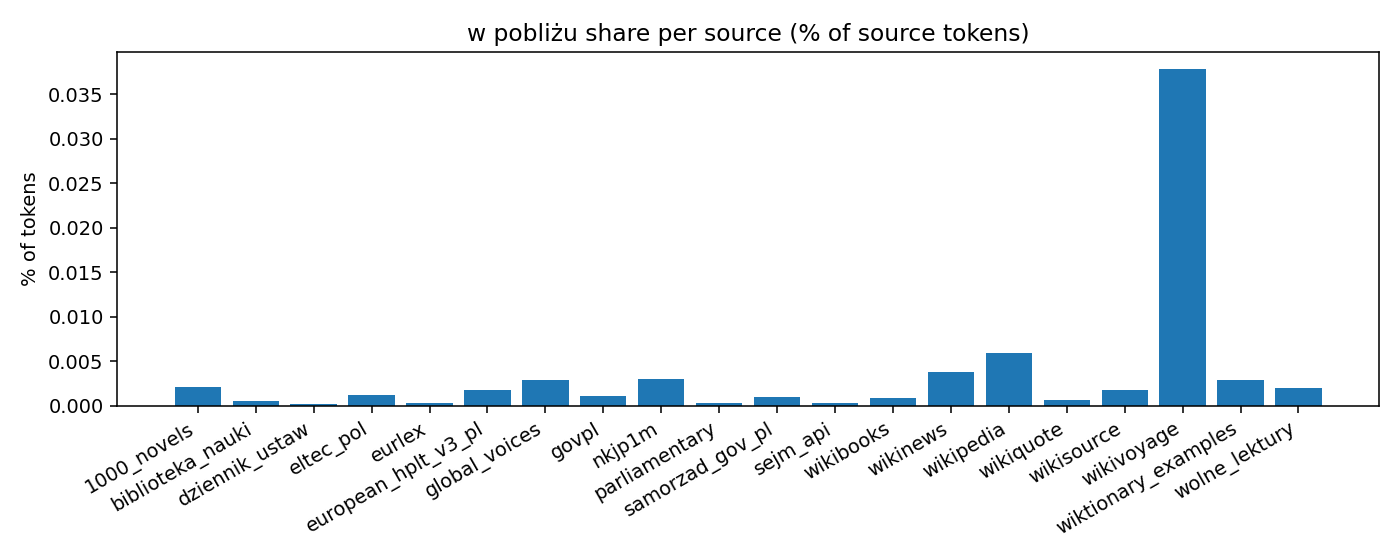
- artifacts/pattern_frequency_w_pobliżu.png +2 -2
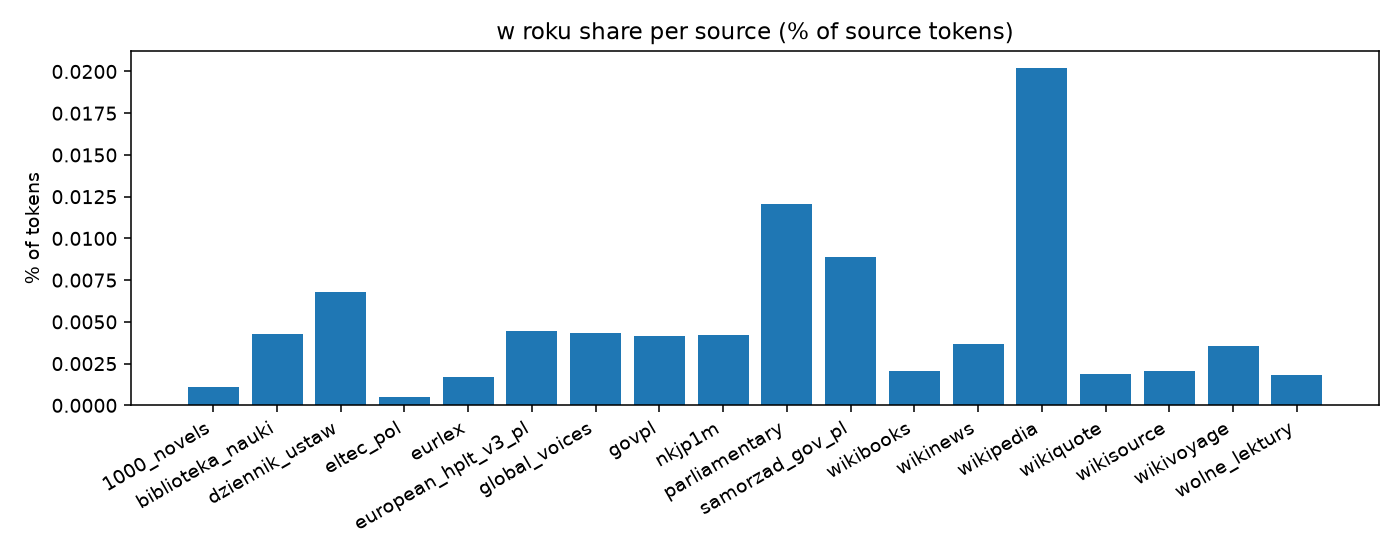
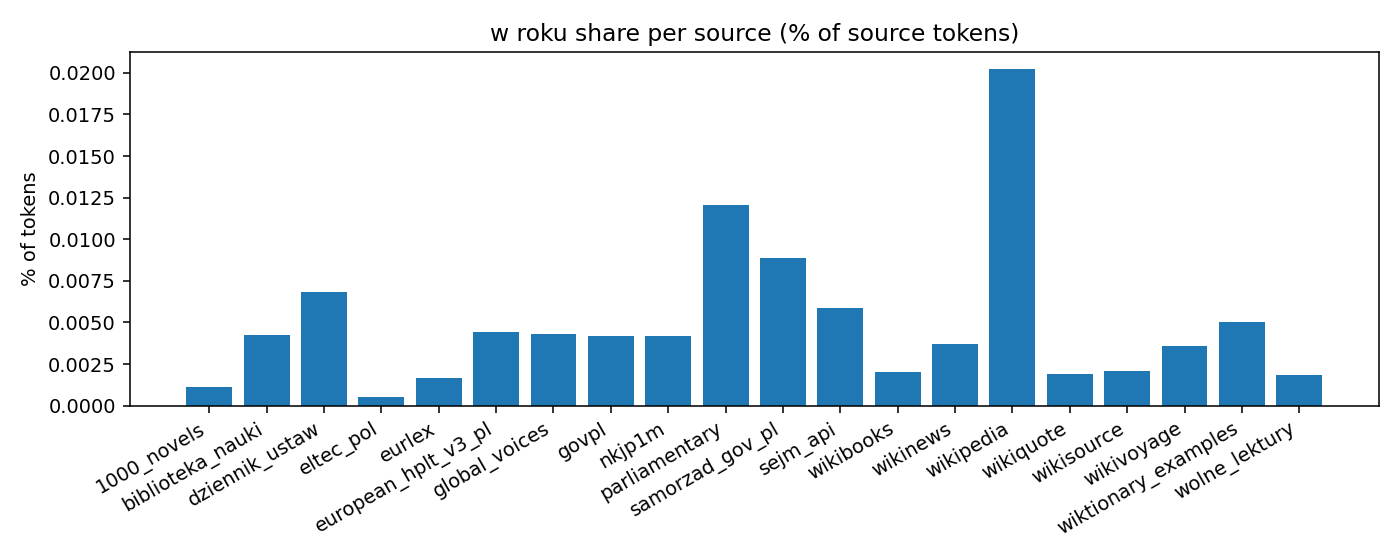
- artifacts/pattern_frequency_w_roku.png +2 -2
- pattern_frequency_report.md +28 -10
- src/make_docs.py +23 -6
- src/sources.py +2 -2
|
@@ -1,16 +1,18 @@
|
|
| 1 |
# Changelog
|
| 2 |
|
| 3 |
-
##
|
| 4 |
-
|
| 5 |
-
-
|
| 6 |
-
|
| 7 |
-
|
| 8 |
-
|
| 9 |
-
|
| 10 |
-
|
| 11 |
-
|
| 12 |
-
|
| 13 |
-
|
|
|
|
|
|
|
| 14 |
- Added the community contribution `samorzad_gov_pl` by Dawid Majewski
|
| 15 |
(`dawidmajewski`): 72,771 Polish articles / 41,154,506 cl100k-proxy tokens
|
| 16 |
from 246 local public institutions and one central platform tenant using the
|
|
@@ -27,8 +29,10 @@
|
|
| 27 |
script, contract tests, source datasheet, NOTICE and release-time license
|
| 28 |
evidence. The live shared footer script matched the audited SHA-256
|
| 29 |
`b36ec507901ed443195479d8d8009386159ae59d7486ce266bfb3308043e99aa`.
|
| 30 |
-
- Recomputed complete-corpus totals: 4,
|
| 31 |
-
cl100k-proxy tokens across
|
|
|
|
|
|
|
| 32 |
|
| 33 |
## v0.2.4 (2026-08-07)
|
| 34 |
|
|
|
|
| 1 |
# Changelog
|
| 2 |
|
| 3 |
+
## v0.2.5 (2026-08-14; tagged 2026-09-07)
|
| 4 |
+
|
| 5 |
+
- The v0.2.5 tag contains 20 sources: `samorzad_gov_pl`, `sejm_api` and
|
| 6 |
+
`wiktionary_examples` were added in this release. `sejm_api` and
|
| 7 |
+
`wiktionary_examples` were previously documented as built but not released
|
| 8 |
+
(`release: None` in `src/sources.py`); that was a documentation error, and
|
| 9 |
+
the registry now sets `release: "0.2.5"` for both.
|
| 10 |
+
- Added `sejm_api` by Piotr Styła: 38,812 parliamentary-speech documents
|
| 11 |
+
(2023 onward) / 36,335,587 cl100k-proxy tokens from the official Sejm API,
|
| 12 |
+
`public-domain (official documents)` (Hub PR #16).
|
| 13 |
+
- Added `wiktionary_examples` by Katarzyna Majzel-Pośpiech: 8,639 Polish
|
| 14 |
+
Wiktionary usage-example documents / 1,115,820 cl100k-proxy tokens,
|
| 15 |
+
`CC-BY-SA-3.0` (Hub PR #14).
|
| 16 |
- Added the community contribution `samorzad_gov_pl` by Dawid Majewski
|
| 17 |
(`dawidmajewski`): 72,771 Polish articles / 41,154,506 cl100k-proxy tokens
|
| 18 |
from 246 local public institutions and one central platform tenant using the
|
|
|
|
| 29 |
script, contract tests, source datasheet, NOTICE and release-time license
|
| 30 |
evidence. The live shared footer script matched the audited SHA-256
|
| 31 |
`b36ec507901ed443195479d8d8009386159ae59d7486ce266bfb3308043e99aa`.
|
| 32 |
+
- Recomputed complete-corpus totals: 4,366,651 documents and 9,676,513,980
|
| 33 |
+
cl100k-proxy tokens across 20 sources (earlier drafts of this entry gave
|
| 34 |
+
4,319,200 documents / 9,639,062,573 tokens across 18 sources, before
|
| 35 |
+
`sejm_api` and `wiktionary_examples` were counted).
|
| 36 |
|
| 37 |
## v0.2.4 (2026-08-07)
|
| 38 |
|
|
@@ -19,8 +19,8 @@ A continuously developed, **openly-licensed**, human-text Polish corpus — a Po
|
|
| 19 |
edition in the [Dynaword](https://huggingface.co/datasets/danish-foundation-models/danish-dynaword)
|
| 20 |
family (Enevoldsen et al., [arXiv:2508.02271](https://arxiv.org/abs/2508.02271)).
|
| 21 |
|
| 22 |
-
> **v0.2.5 stable** · 4,
|
| 23 |
-
> (tiktoken proxy; canonical Llama-3 count at release) ·
|
| 24 |
> Updated: **2026-08-14**
|
| 25 |
|
| 26 |
> **v0.3-dev experimental track** · quality/diversity workflow, source-gate
|
|
@@ -37,7 +37,7 @@ family (Enevoldsen et al., [arXiv:2508.02271](https://arxiv.org/abs/2508.02271))
|
|
| 37 |
|
| 38 |
| version | status | documents | tokens | notes |
|
| 39 |
|---|---|---:|---:|---|
|
| 40 |
-
| `v0.2.5` | stable release | 4,
|
| 41 |
| `v0.2.4` | previous stable | 4,246,429 | 9.60B | Expanded `european_hplt_v3_pl` to WDS bins 10-5 (+1.49M docs / 2.04B tok); phone PII-scrub hardening (independent dual-lens) + cross-source dedup (zero-overlap). |
|
| 42 |
| `v0.2.3` | previous stable | 2,710,974 | 6.88B | Adds community-contributed `european_hplt_v3_pl`, `global_voices` and `nkjp1m`. |
|
| 43 |
| `v0.2.2` | previous stable | 2,579,963 | 6.36B | Added community-contributed `govpl`: 88,190 docs / 80.7M tokens. |
|
|
@@ -57,11 +57,26 @@ family (Enevoldsen et al., [arXiv:2508.02271](https://arxiv.org/abs/2508.02271))
|
|
| 57 |
|
| 58 |
#### v0.2.5 — current stable
|
| 59 |
|
| 60 |
-
Added
|
| 61 |
-
|
| 62 |
-
|
| 63 |
-
|
| 64 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 65 |
|
| 66 |
#### v0.2.4 — previous stable
|
| 67 |
|
|
@@ -149,6 +164,8 @@ as the redistributing aggregator; this release does not claim ownership of them
|
|
| 149 |
| [Arkadiusz Słota](https://huggingface.co/Maggio33) | Built & expanded `european_hplt_v3_pl`: HPLT v3 WDS 10+9 (PR #5) then WDS 10-5 expansion (+1,493,384 docs / 2.04B tok), modular cleaning pipeline, phone-recall PII-scrub (v12b, independent dual-lens), cross-source dedup-vs-base (zero-overlap), validation and documentation. | `v0.2.3` (PR #5), `v0.2.4` |
|
| 150 |
| [Dawid Majewski](https://huggingface.co/dawidmajewski) | Added the reviewed Global Voices Polish corpus; built `samorzad_gov_pl` with direct acquisition, institution attribution, licensing evidence, release artifact and reproducible conversion. | `v0.2.3`, [PR #7](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/7); `v0.2.5` |
|
| 151 |
| [1am](https://huggingface.co/1am) | Added `nkjp1m`: the manually annotated 1-million-word NKJP subcorpus, direct fetch/build pipeline, source documentation and release artifact. | `v0.2.3`, [PR #8](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/8) |
|
|
|
|
|
|
|
| 152 |
|
| 153 |
Contributions are credited when they add a verifiable dataset artifact, pipeline,
|
| 154 |
validation, documentation or release work. A merged discussion with no resulting
|
|
@@ -175,6 +192,7 @@ files is not listed as a data contribution.
|
|
| 175 |
| [govpl](data/govpl/govpl.md) | gov.pl — Polish government press releases | `CC-BY-SA-4.0` | 88,190 | 80.7M |
|
| 176 |
| [1000_novels](data/1000_novels/1000_novels.md) | 1000 Novels Corpus (CLARIN-PL) | `CC-BY-4.0` | 1,000 | 60.5M |
|
| 177 |
| [samorzad_gov_pl](data/samorzad_gov_pl/samorzad_gov_pl.md) | samorzad.gov.pl — Polish public-sector institutions | `CC-BY-SA-4.0` | 72,771 | 41.2M |
|
|
|
|
| 178 |
| [wikiquote](data/wikiquote/wikiquote.md) | Polish Wikiquote (quotations) | `CC-BY-SA-3.0` | 30,363 | 31.9M |
|
| 179 |
| [eltec_pol](data/eltec_pol/eltec_pol.md) | ELTeC-pol (European Literary Text Collection, Polish) | `CC-BY-4.0` | 100 | 21.5M |
|
| 180 |
| [wikivoyage](data/wikivoyage/wikivoyage.md) | Polish Wikivoyage (travel guides) | `CC-BY-SA-3.0` | 13,645 | 17.1M |
|
|
@@ -182,15 +200,8 @@ files is not listed as a data contribution.
|
|
| 182 |
| [wikinews](data/wikinews/wikinews.md) | Polish Wikinews | `CC-BY-2.5` | 24,386 | 12.1M |
|
| 183 |
| [global_voices](data/global_voices/global_voices.md) | Global Voices Polish | `CC-BY-3.0` | 2,040 | 3.7M |
|
| 184 |
| [nkjp1m](data/nkjp1m/nkjp1m.md) | The manually annotated 1-million word subcorpus of the National Corpus of Polish | `CC-BY` | 18,381 | 2.6M |
|
| 185 |
-
| **total** | | | **4,319,200** | **9,639.1M** |
|
| 186 |
-
|
| 187 |
-
## Sources on main, not yet released
|
| 188 |
-
Built and documented, but **not** part of v0.2.5 and excluded from every total above. They join a release when a CHANGELOG entry admits them.
|
| 189 |
-
|
| 190 |
-
| source | description | license | documents | tokens |
|
| 191 |
-
|---|---|---|---:|---:|
|
| 192 |
-
| [sejm_api](data/sejm_api/sejm_api.md) | Sejm API parliamentary speeches (2023 onward) | `public-domain (official documents)` | 38,812 | 36.3M |
|
| 193 |
| [wiktionary_examples](data/wiktionary_examples/wiktionary_examples.md) | Polish Wiktionary usage examples | `CC-BY-SA-3.0` | 8,639 | 1.1M |
|
|
|
|
| 194 |
|
| 195 |
## Method
|
| 196 |
Only **human-authored** text — no synthetic, machine-translated, or auto-transcribed
|
|
@@ -301,19 +312,19 @@ python3 src/make_docs.py
|
|
| 301 |
|
| 302 |
Raw counts and token-normalized shares are regenerated from the current Parquet files with `src/pattern_frequency_report.py`.
|
| 303 |
|
| 304 |
-
- Total token count (tiktoken proxy): **9,
|
| 305 |
|
| 306 |
| Pattern | Count | Share of all tokens |
|
| 307 |
|---|---:|---:|
|
| 308 |
-
| `w roku` |
|
| 309 |
-
| `klasyfikacji` | 164,
|
| 310 |
-
| `ustawa` |
|
| 311 |
-
| `artykuł` | 2,
|
| 312 |
-
| `parlament` | 1,
|
| 313 |
-
| `rozporządzenie` | 1,
|
| 314 |
-
| `w pobliżu` | 127,
|
| 315 |
-
| `mieszkańców` |
|
| 316 |
-
| `Dz.U.` | 987,
|
| 317 |
|
| 318 |
### Per-source shares
|
| 319 |
|
|
@@ -418,6 +429,15 @@ Raw counts and token-normalized shares are regenerated from the current Parquet
|
|
| 418 |
| `samorzad_gov_pl` | `w pobliżu` | 401 | 0.00097% |
|
| 419 |
| `samorzad_gov_pl` | `mieszkańców` | 14,450 | 0.03511% |
|
| 420 |
| `samorzad_gov_pl` | `Dz.U.` | 1,380 | 0.00335% |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 421 |
| `wikibooks` | `w roku` | 319 | 0.00205% |
|
| 422 |
| `wikibooks` | `klasyfikacji` | 37 | 0.00024% |
|
| 423 |
| `wikibooks` | `ustawa` | 165 | 0.00106% |
|
|
@@ -472,6 +492,15 @@ Raw counts and token-normalized shares are regenerated from the current Parquet
|
|
| 472 |
| `wikivoyage` | `w pobliżu` | 6,480 | 0.03783% |
|
| 473 |
| `wikivoyage` | `mieszkańców` | 4,100 | 0.02394% |
|
| 474 |
| `wikivoyage` | `Dz.U.` | 1 | 0.00001% |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 475 |
| `wolne_lektury` | `w roku` | 1,898 | 0.00184% |
|
| 476 |
| `wolne_lektury` | `klasyfikacji` | 80 | 0.00008% |
|
| 477 |
| `wolne_lektury` | `ustawa` | 1,060 | 0.00103% |
|
|
|
|
| 19 |
edition in the [Dynaword](https://huggingface.co/datasets/danish-foundation-models/danish-dynaword)
|
| 20 |
family (Enevoldsen et al., [arXiv:2508.02271](https://arxiv.org/abs/2508.02271)).
|
| 21 |
|
| 22 |
+
> **v0.2.5 stable** · 4,366,651 documents · **9.68B tokens**
|
| 23 |
+
> (tiktoken proxy; canonical Llama-3 count at release) · 20 sources
|
| 24 |
> Updated: **2026-08-14**
|
| 25 |
|
| 26 |
> **v0.3-dev experimental track** · quality/diversity workflow, source-gate
|
|
|
|
| 37 |
|
| 38 |
| version | status | documents | tokens | notes |
|
| 39 |
|---|---|---:|---:|---|
|
| 40 |
+
| `v0.2.5` | stable release | 4,366,651 | 9.68B | Adds community-contributed `samorzad_gov_pl` (institution-level author attribution and a URL-bearing attribution sidecar), `sejm_api` and `wiktionary_examples`. |
|
| 41 |
| `v0.2.4` | previous stable | 4,246,429 | 9.60B | Expanded `european_hplt_v3_pl` to WDS bins 10-5 (+1.49M docs / 2.04B tok); phone PII-scrub hardening (independent dual-lens) + cross-source dedup (zero-overlap). |
|
| 42 |
| `v0.2.3` | previous stable | 2,710,974 | 6.88B | Adds community-contributed `european_hplt_v3_pl`, `global_voices` and `nkjp1m`. |
|
| 43 |
| `v0.2.2` | previous stable | 2,579,963 | 6.36B | Added community-contributed `govpl`: 88,190 docs / 80.7M tokens. |
|
|
|
|
| 57 |
|
| 58 |
#### v0.2.5 — current stable
|
| 59 |
|
| 60 |
+
Added three sources, bringing the complete release to **20 sources,
|
| 61 |
+
4,366,651 documents / 9,676,513,980 cl100k-proxy tokens**:
|
| 62 |
+
|
| 63 |
+
- `samorzad_gov_pl`: **72,771 documents / 41,154,506 cl100k-proxy
|
| 64 |
+
tokens** from 246 Polish local public institutions and one central platform
|
| 65 |
+
tenant. The contribution preserves the publishing institution as `author`,
|
| 66 |
+
discovered and fetched article URLs in an attribution sidecar and the verified
|
| 67 |
+
platform-wide CC-BY-SA-4.0 basis.
|
| 68 |
+
- `sejm_api`: **38,812 documents / 36,335,587 cl100k-proxy tokens** of
|
| 69 |
+
parliamentary speeches (2023 onward) from the official Sejm API,
|
| 70 |
+
`public-domain (official documents)`
|
| 71 |
+
([PR #16](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/16)).
|
| 72 |
+
- `wiktionary_examples`: **8,639 documents / 1,115,820 cl100k-proxy tokens**
|
| 73 |
+
of Polish Wiktionary usage examples, one document per headword,
|
| 74 |
+
`CC-BY-SA-3.0`
|
| 75 |
+
([PR #14](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/14)).
|
| 76 |
+
|
| 77 |
+
Documentation correction: the v0.2.5 tag contains all 20 sources. Earlier
|
| 78 |
+
copies of this card counted only 18 (4,319,200 documents / 9,639,062,573
|
| 79 |
+
tokens) and listed `sejm_api` and `wiktionary_examples` as not released.
|
| 80 |
|
| 81 |
#### v0.2.4 — previous stable
|
| 82 |
|
|
|
|
| 164 |
| [Arkadiusz Słota](https://huggingface.co/Maggio33) | Built & expanded `european_hplt_v3_pl`: HPLT v3 WDS 10+9 (PR #5) then WDS 10-5 expansion (+1,493,384 docs / 2.04B tok), modular cleaning pipeline, phone-recall PII-scrub (v12b, independent dual-lens), cross-source dedup-vs-base (zero-overlap), validation and documentation. | `v0.2.3` (PR #5), `v0.2.4` |
|
| 165 |
| [Dawid Majewski](https://huggingface.co/dawidmajewski) | Added the reviewed Global Voices Polish corpus; built `samorzad_gov_pl` with direct acquisition, institution attribution, licensing evidence, release artifact and reproducible conversion. | `v0.2.3`, [PR #7](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/7); `v0.2.5` |
|
| 166 |
| [1am](https://huggingface.co/1am) | Added `nkjp1m`: the manually annotated 1-million-word NKJP subcorpus, direct fetch/build pipeline, source documentation and release artifact. | `v0.2.3`, [PR #8](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/8) |
|
| 167 |
+
| Piotr Styła (HF: `PiotrSty`) | Corpus preparation and contribution of `sejm_api`: parliamentary speeches from the official Sejm API with speaker attribution and immutable `PiotrSty/sejm-speeches-corpus` v1.0.1 provenance. | `v0.2.5`, [PR #16](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/16) |
|
| 168 |
+
| Katarzyna Majzel-Pośpiech | Added `wiktionary_examples`: usage examples extracted from the Polish Wiktionary dump, one document per headword. | `v0.2.5`, [PR #14](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/14) |
|
| 169 |
|
| 170 |
Contributions are credited when they add a verifiable dataset artifact, pipeline,
|
| 171 |
validation, documentation or release work. A merged discussion with no resulting
|
|
|
|
| 192 |
| [govpl](data/govpl/govpl.md) | gov.pl — Polish government press releases | `CC-BY-SA-4.0` | 88,190 | 80.7M |
|
| 193 |
| [1000_novels](data/1000_novels/1000_novels.md) | 1000 Novels Corpus (CLARIN-PL) | `CC-BY-4.0` | 1,000 | 60.5M |
|
| 194 |
| [samorzad_gov_pl](data/samorzad_gov_pl/samorzad_gov_pl.md) | samorzad.gov.pl — Polish public-sector institutions | `CC-BY-SA-4.0` | 72,771 | 41.2M |
|
| 195 |
+
| [sejm_api](data/sejm_api/sejm_api.md) | Sejm API parliamentary speeches (2023 onward) | `public-domain (official documents)` | 38,812 | 36.3M |
|
| 196 |
| [wikiquote](data/wikiquote/wikiquote.md) | Polish Wikiquote (quotations) | `CC-BY-SA-3.0` | 30,363 | 31.9M |
|
| 197 |
| [eltec_pol](data/eltec_pol/eltec_pol.md) | ELTeC-pol (European Literary Text Collection, Polish) | `CC-BY-4.0` | 100 | 21.5M |
|
| 198 |
| [wikivoyage](data/wikivoyage/wikivoyage.md) | Polish Wikivoyage (travel guides) | `CC-BY-SA-3.0` | 13,645 | 17.1M |
|
|
|
|
| 200 |
| [wikinews](data/wikinews/wikinews.md) | Polish Wikinews | `CC-BY-2.5` | 24,386 | 12.1M |
|
| 201 |
| [global_voices](data/global_voices/global_voices.md) | Global Voices Polish | `CC-BY-3.0` | 2,040 | 3.7M |
|
| 202 |
| [nkjp1m](data/nkjp1m/nkjp1m.md) | The manually annotated 1-million word subcorpus of the National Corpus of Polish | `CC-BY` | 18,381 | 2.6M |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 203 |
| [wiktionary_examples](data/wiktionary_examples/wiktionary_examples.md) | Polish Wiktionary usage examples | `CC-BY-SA-3.0` | 8,639 | 1.1M |
|
| 204 |
+
| **total** | | | **4,366,651** | **9,676.5M** |
|
| 205 |
|
| 206 |
## Method
|
| 207 |
Only **human-authored** text — no synthetic, machine-translated, or auto-transcribed
|
|
|
|
| 312 |
|
| 313 |
Raw counts and token-normalized shares are regenerated from the current Parquet files with `src/pattern_frequency_report.py`.
|
| 314 |
|
| 315 |
+
- Total token count (tiktoken proxy): **9,676,513,980**
|
| 316 |
|
| 317 |
| Pattern | Count | Share of all tokens |
|
| 318 |
|---|---:|---:|
|
| 319 |
+
| `w roku` | 587,251 | 0.0061% |
|
| 320 |
+
| `klasyfikacji` | 164,888 | 0.0017% |
|
| 321 |
+
| `ustawa` | 670,171 | 0.0069% |
|
| 322 |
+
| `artykuł` | 2,417,211 | 0.0250% |
|
| 323 |
+
| `parlament` | 1,300,050 | 0.0134% |
|
| 324 |
+
| `rozporządzenie` | 1,528,556 | 0.0158% |
|
| 325 |
+
| `w pobliżu` | 127,903 | 0.0013% |
|
| 326 |
+
| `mieszkańców` | 479,471 | 0.0050% |
|
| 327 |
+
| `Dz.U.` | 987,052 | 0.0102% |
|
| 328 |
|
| 329 |
### Per-source shares
|
| 330 |
|
|
|
|
| 429 |
| `samorzad_gov_pl` | `w pobliżu` | 401 | 0.00097% |
|
| 430 |
| `samorzad_gov_pl` | `mieszkańców` | 14,450 | 0.03511% |
|
| 431 |
| `samorzad_gov_pl` | `Dz.U.` | 1,380 | 0.00335% |
|
| 432 |
+
| `sejm_api` | `w roku` | 2,123 | 0.00584% |
|
| 433 |
+
| `sejm_api` | `klasyfikacji` | 126 | 0.00035% |
|
| 434 |
+
| `sejm_api` | `ustawa` | 11,042 | 0.03039% |
|
| 435 |
+
| `sejm_api` | `artykuł` | 808 | 0.00222% |
|
| 436 |
+
| `sejm_api` | `parlament` | 14,230 | 0.03916% |
|
| 437 |
+
| `sejm_api` | `rozporządzenie` | 1,095 | 0.00301% |
|
| 438 |
+
| `sejm_api` | `w pobliżu` | 87 | 0.00024% |
|
| 439 |
+
| `sejm_api` | `mieszkańców` | 2,697 | 0.00742% |
|
| 440 |
+
| `sejm_api` | `Dz.U.` | 4 | 0.00001% |
|
| 441 |
| `wikibooks` | `w roku` | 319 | 0.00205% |
|
| 442 |
| `wikibooks` | `klasyfikacji` | 37 | 0.00024% |
|
| 443 |
| `wikibooks` | `ustawa` | 165 | 0.00106% |
|
|
|
|
| 492 |
| `wikivoyage` | `w pobliżu` | 6,480 | 0.03783% |
|
| 493 |
| `wikivoyage` | `mieszkańców` | 4,100 | 0.02394% |
|
| 494 |
| `wikivoyage` | `Dz.U.` | 1 | 0.00001% |
|
| 495 |
+
| `wiktionary_examples` | `w roku` | 56 | 0.00502% |
|
| 496 |
+
| `wiktionary_examples` | `klasyfikacji` | 5 | 0.00045% |
|
| 497 |
+
| `wiktionary_examples` | `ustawa` | 26 | 0.00233% |
|
| 498 |
+
| `wiktionary_examples` | `artykuł` | 42 | 0.00376% |
|
| 499 |
+
| `wiktionary_examples` | `parlament` | 28 | 0.00251% |
|
| 500 |
+
| `wiktionary_examples` | `rozporządzenie` | 5 | 0.00045% |
|
| 501 |
+
| `wiktionary_examples` | `w pobliżu` | 32 | 0.00287% |
|
| 502 |
+
| `wiktionary_examples` | `mieszkańców` | 64 | 0.00574% |
|
| 503 |
+
| `wiktionary_examples` | `Dz.U.` | 0 | 0.00000% |
|
| 504 |
| `wolne_lektury` | `w roku` | 1,898 | 0.00184% |
|
| 505 |
| `wolne_lektury` | `klasyfikacji` | 80 | 0.00008% |
|
| 506 |
| `wolne_lektury` | `ustawa` | 1,060 | 0.00103% |
|
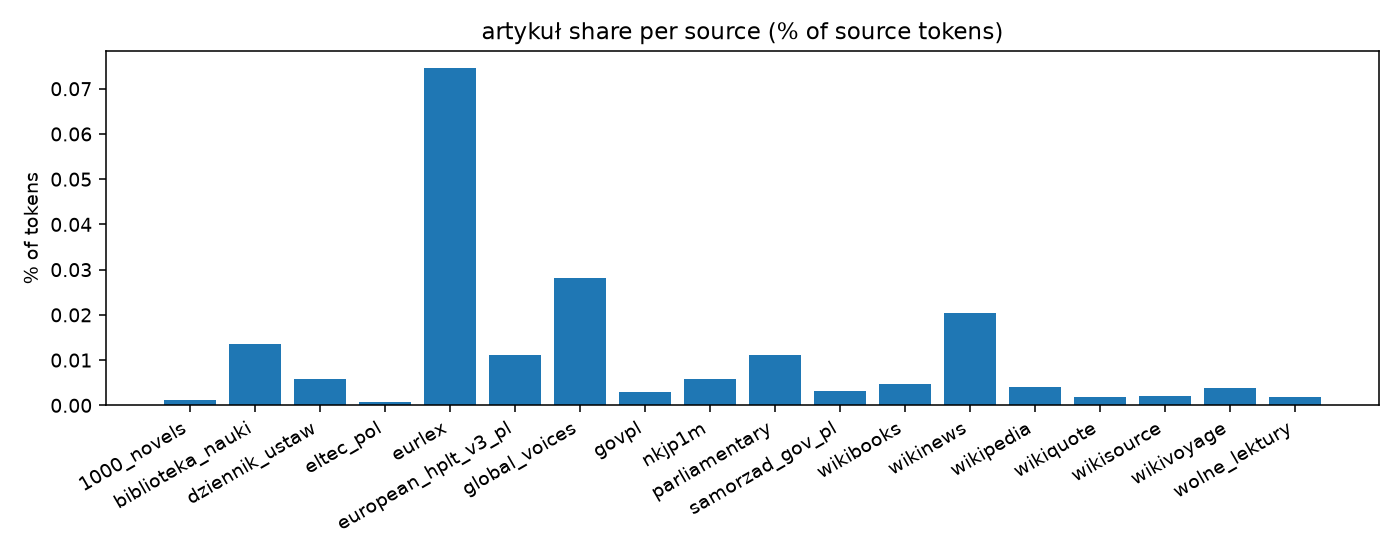
|
Git LFS Details
|
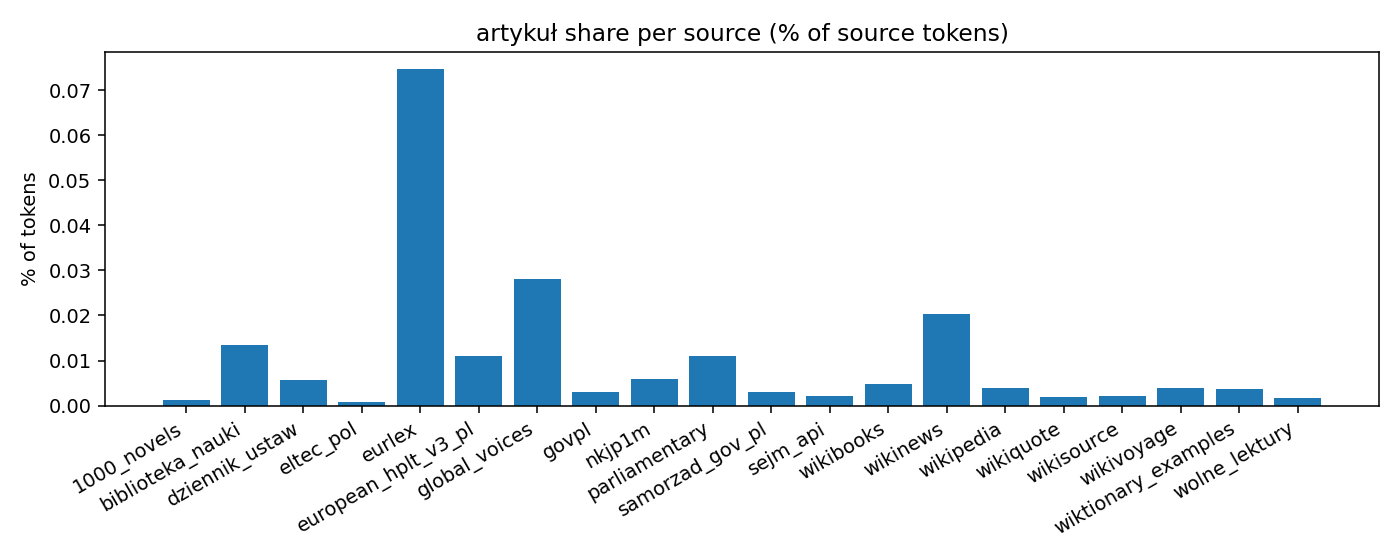
|
Git LFS Details
|
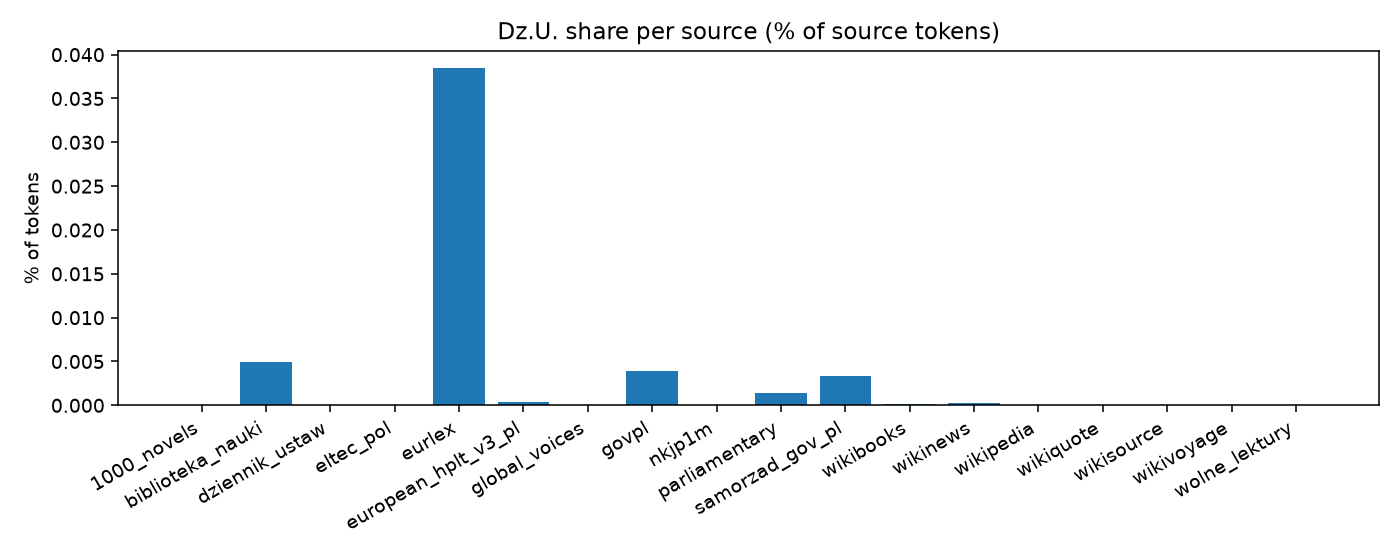
|
Git LFS Details
|
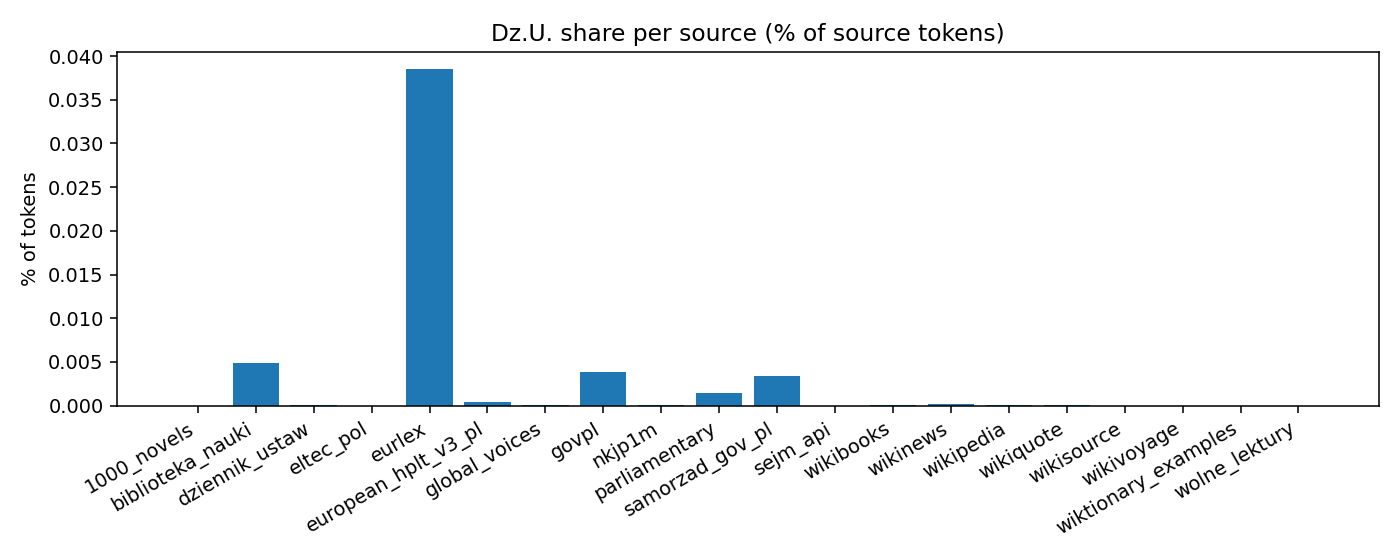
|
Git LFS Details
|
|
@@ -1,18 +1,18 @@
|
|
| 1 |
## Phrase frequency in corpus (token-normalized)
|
| 2 |
|
| 3 |
-
- Total token count (tiktoken proxy): **9,
|
| 4 |
|
| 5 |
| Pattern | Count | Share of all tokens |
|
| 6 |
|---|---:|---:|
|
| 7 |
-
| `w roku` |
|
| 8 |
-
| `klasyfikacji` | 164,
|
| 9 |
-
| `ustawa` |
|
| 10 |
-
| `artykuł` | 2,
|
| 11 |
-
| `parlament` | 1,
|
| 12 |
-
| `rozporządzenie` | 1,
|
| 13 |
-
| `w pobliżu` | 127,
|
| 14 |
-
| `mieszkańców` |
|
| 15 |
-
| `Dz.U.` | 987,
|
| 16 |
|
| 17 |
### Per-source shares
|
| 18 |
|
|
@@ -117,6 +117,15 @@
|
|
| 117 |
| `samorzad_gov_pl` | `w pobliżu` | 401 | 0.00097% |
|
| 118 |
| `samorzad_gov_pl` | `mieszkańców` | 14,450 | 0.03511% |
|
| 119 |
| `samorzad_gov_pl` | `Dz.U.` | 1,380 | 0.00335% |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 120 |
| `wikibooks` | `w roku` | 319 | 0.00205% |
|
| 121 |
| `wikibooks` | `klasyfikacji` | 37 | 0.00024% |
|
| 122 |
| `wikibooks` | `ustawa` | 165 | 0.00106% |
|
|
@@ -171,6 +180,15 @@
|
|
| 171 |
| `wikivoyage` | `w pobliżu` | 6,480 | 0.03783% |
|
| 172 |
| `wikivoyage` | `mieszkańców` | 4,100 | 0.02394% |
|
| 173 |
| `wikivoyage` | `Dz.U.` | 1 | 0.00001% |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 174 |
| `wolne_lektury` | `w roku` | 1,898 | 0.00184% |
|
| 175 |
| `wolne_lektury` | `klasyfikacji` | 80 | 0.00008% |
|
| 176 |
| `wolne_lektury` | `ustawa` | 1,060 | 0.00103% |
|
|
|
|
| 1 |
## Phrase frequency in corpus (token-normalized)
|
| 2 |
|
| 3 |
+
- Total token count (tiktoken proxy): **9,676,513,980**
|
| 4 |
|
| 5 |
| Pattern | Count | Share of all tokens |
|
| 6 |
|---|---:|---:|
|
| 7 |
+
| `w roku` | 587,251 | 0.0061% |
|
| 8 |
+
| `klasyfikacji` | 164,888 | 0.0017% |
|
| 9 |
+
| `ustawa` | 670,171 | 0.0069% |
|
| 10 |
+
| `artykuł` | 2,417,211 | 0.0250% |
|
| 11 |
+
| `parlament` | 1,300,050 | 0.0134% |
|
| 12 |
+
| `rozporządzenie` | 1,528,556 | 0.0158% |
|
| 13 |
+
| `w pobliżu` | 127,903 | 0.0013% |
|
| 14 |
+
| `mieszkańców` | 479,471 | 0.0050% |
|
| 15 |
+
| `Dz.U.` | 987,052 | 0.0102% |
|
| 16 |
|
| 17 |
### Per-source shares
|
| 18 |
|
|
|
|
| 117 |
| `samorzad_gov_pl` | `w pobliżu` | 401 | 0.00097% |
|
| 118 |
| `samorzad_gov_pl` | `mieszkańców` | 14,450 | 0.03511% |
|
| 119 |
| `samorzad_gov_pl` | `Dz.U.` | 1,380 | 0.00335% |
|
| 120 |
+
| `sejm_api` | `w roku` | 2,123 | 0.00584% |
|
| 121 |
+
| `sejm_api` | `klasyfikacji` | 126 | 0.00035% |
|
| 122 |
+
| `sejm_api` | `ustawa` | 11,042 | 0.03039% |
|
| 123 |
+
| `sejm_api` | `artykuł` | 808 | 0.00222% |
|
| 124 |
+
| `sejm_api` | `parlament` | 14,230 | 0.03916% |
|
| 125 |
+
| `sejm_api` | `rozporządzenie` | 1,095 | 0.00301% |
|
| 126 |
+
| `sejm_api` | `w pobliżu` | 87 | 0.00024% |
|
| 127 |
+
| `sejm_api` | `mieszkańców` | 2,697 | 0.00742% |
|
| 128 |
+
| `sejm_api` | `Dz.U.` | 4 | 0.00001% |
|
| 129 |
| `wikibooks` | `w roku` | 319 | 0.00205% |
|
| 130 |
| `wikibooks` | `klasyfikacji` | 37 | 0.00024% |
|
| 131 |
| `wikibooks` | `ustawa` | 165 | 0.00106% |
|
|
|
|
| 180 |
| `wikivoyage` | `w pobliżu` | 6,480 | 0.03783% |
|
| 181 |
| `wikivoyage` | `mieszkańców` | 4,100 | 0.02394% |
|
| 182 |
| `wikivoyage` | `Dz.U.` | 1 | 0.00001% |
|
| 183 |
+
| `wiktionary_examples` | `w roku` | 56 | 0.00502% |
|
| 184 |
+
| `wiktionary_examples` | `klasyfikacji` | 5 | 0.00045% |
|
| 185 |
+
| `wiktionary_examples` | `ustawa` | 26 | 0.00233% |
|
| 186 |
+
| `wiktionary_examples` | `artykuł` | 42 | 0.00376% |
|
| 187 |
+
| `wiktionary_examples` | `parlament` | 28 | 0.00251% |
|
| 188 |
+
| `wiktionary_examples` | `rozporządzenie` | 5 | 0.00045% |
|
| 189 |
+
| `wiktionary_examples` | `w pobliżu` | 32 | 0.00287% |
|
| 190 |
+
| `wiktionary_examples` | `mieszkańców` | 64 | 0.00574% |
|
| 191 |
+
| `wiktionary_examples` | `Dz.U.` | 0 | 0.00000% |
|
| 192 |
| `wolne_lektury` | `w roku` | 1,898 | 0.00184% |
|
| 193 |
| `wolne_lektury` | `klasyfikacji` | 80 | 0.00008% |
|
| 194 |
| `wolne_lektury` | `ustawa` | 1,060 | 0.00103% |
|
|
Git LFS Details
|
|
Git LFS Details
|
|
Git LFS Details
|
|
Git LFS Details
|
|
Git LFS Details
|
|
Git LFS Details
|
|
Git LFS Details
|
|
Git LFS Details
|

|
Git LFS Details
|
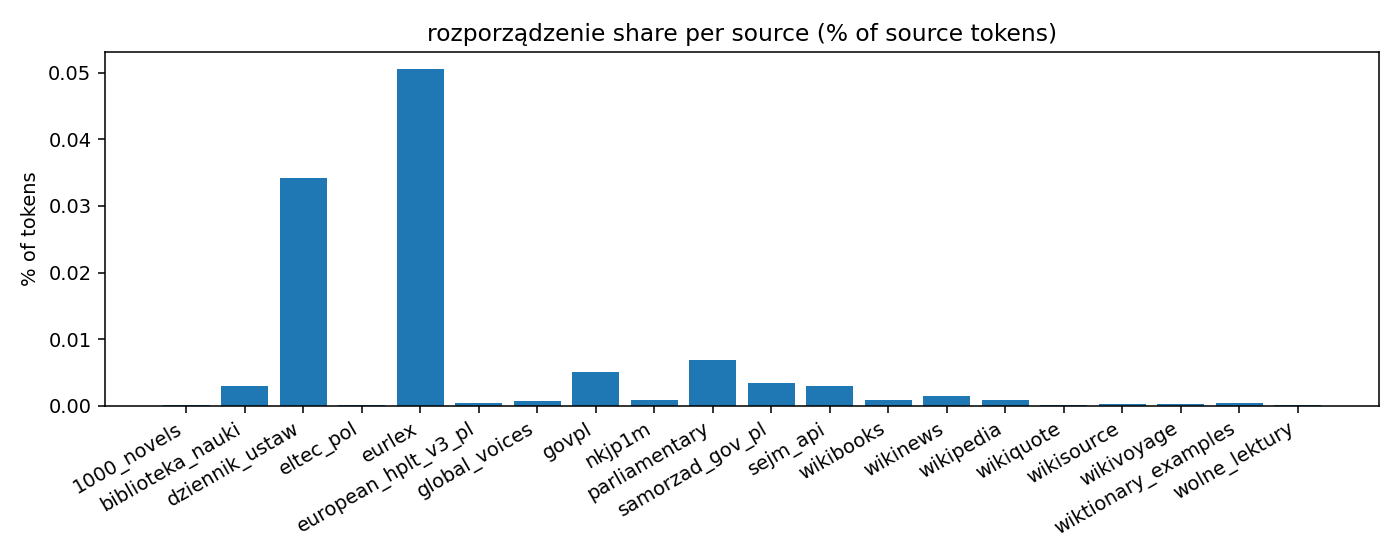
|
Git LFS Details
|
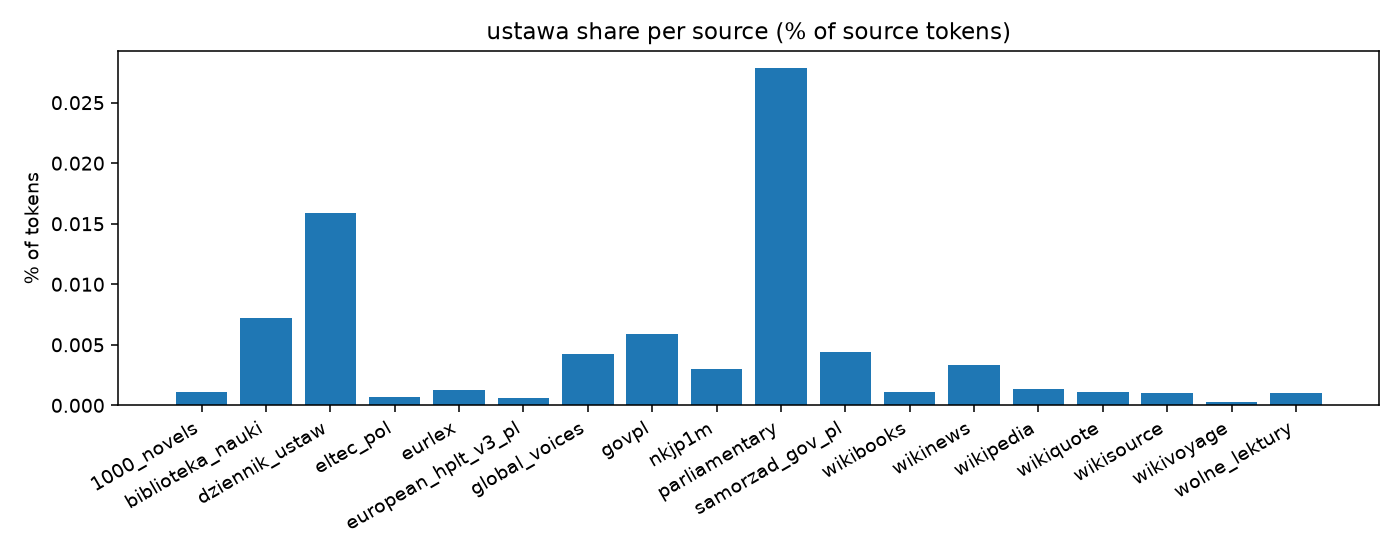
|
Git LFS Details
|
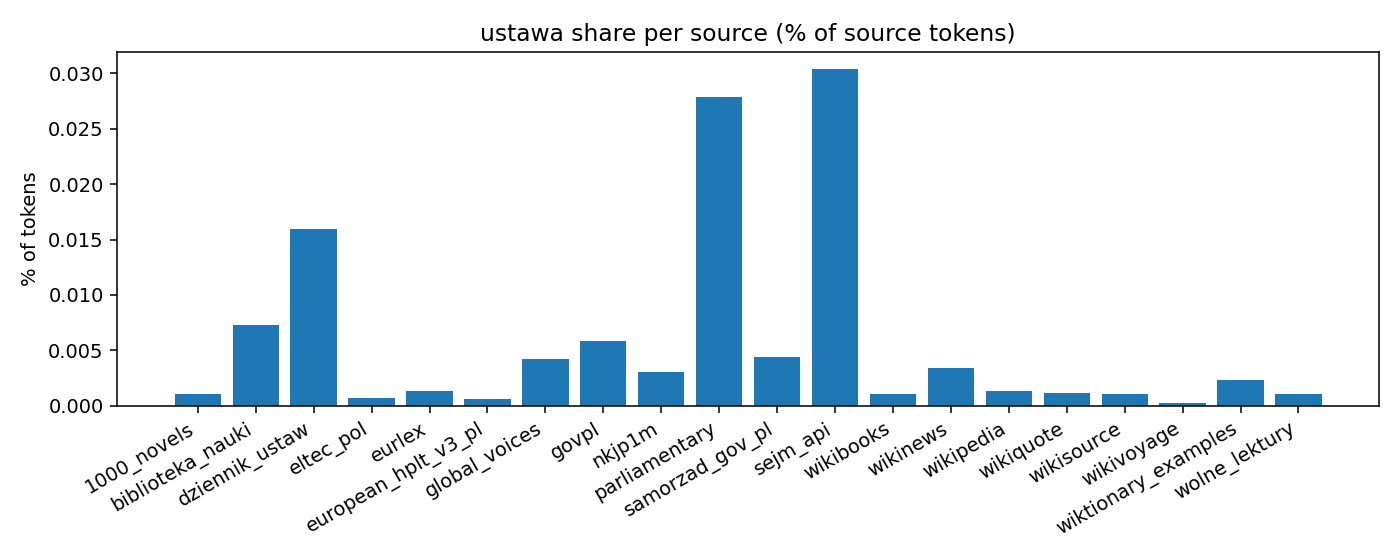
|
Git LFS Details
|
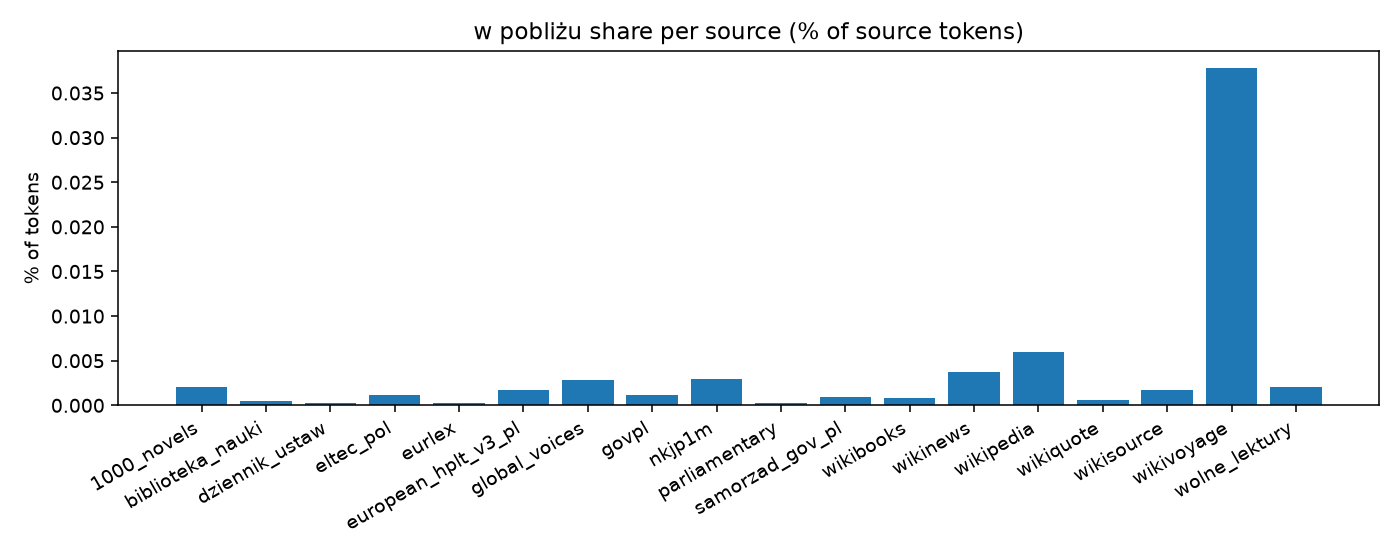
|
Git LFS Details
|
|
Git LFS Details
|
|
Git LFS Details
|
|
Git LFS Details
|
|
@@ -1,18 +1,18 @@
|
|
| 1 |
## Pattern frequency on corpus
|
| 2 |
|
| 3 |
-
- total tokens (tiktoken proxy): `9,
|
| 4 |
|
| 5 |
| pattern | count | share of all tokens |
|
| 6 |
|---|---:|---:|
|
| 7 |
-
| `w roku` |
|
| 8 |
-
| `klasyfikacji` | 164,
|
| 9 |
-
| `ustawa` |
|
| 10 |
-
| `artykuł` | 2,
|
| 11 |
-
| `parlament` | 1,
|
| 12 |
-
| `rozporządzenie` | 1,
|
| 13 |
-
| `w pobliżu` | 127,
|
| 14 |
-
| `mieszkańców` |
|
| 15 |
-
| `Dz.U.` | 987,
|
| 16 |
|
| 17 |
| source | pattern | count | per-token share |
|
| 18 |
|---|---|---:|---:|
|
|
@@ -115,6 +115,15 @@
|
|
| 115 |
| samorzad_gov_pl | `w pobliżu` | 401 | 0.00097% |
|
| 116 |
| samorzad_gov_pl | `mieszkańców` | 14,450 | 0.03511% |
|
| 117 |
| samorzad_gov_pl | `Dz.U.` | 1,380 | 0.00335% |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 118 |
| wikibooks | `w roku` | 319 | 0.00205% |
|
| 119 |
| wikibooks | `klasyfikacji` | 37 | 0.00024% |
|
| 120 |
| wikibooks | `ustawa` | 165 | 0.00106% |
|
|
@@ -169,6 +178,15 @@
|
|
| 169 |
| wikivoyage | `w pobliżu` | 6,480 | 0.03783% |
|
| 170 |
| wikivoyage | `mieszkańców` | 4,100 | 0.02394% |
|
| 171 |
| wikivoyage | `Dz.U.` | 1 | 0.00001% |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 172 |
| wolne_lektury | `w roku` | 1,898 | 0.00184% |
|
| 173 |
| wolne_lektury | `klasyfikacji` | 80 | 0.00008% |
|
| 174 |
| wolne_lektury | `ustawa` | 1,060 | 0.00103% |
|
|
|
|
| 1 |
## Pattern frequency on corpus
|
| 2 |
|
| 3 |
+
- total tokens (tiktoken proxy): `9,676,513,980`
|
| 4 |
|
| 5 |
| pattern | count | share of all tokens |
|
| 6 |
|---|---:|---:|
|
| 7 |
+
| `w roku` | 587,251 | 0.0061% |
|
| 8 |
+
| `klasyfikacji` | 164,888 | 0.0017% |
|
| 9 |
+
| `ustawa` | 670,171 | 0.0069% |
|
| 10 |
+
| `artykuł` | 2,417,211 | 0.0250% |
|
| 11 |
+
| `parlament` | 1,300,050 | 0.0134% |
|
| 12 |
+
| `rozporządzenie` | 1,528,556 | 0.0158% |
|
| 13 |
+
| `w pobliżu` | 127,903 | 0.0013% |
|
| 14 |
+
| `mieszkańców` | 479,471 | 0.0050% |
|
| 15 |
+
| `Dz.U.` | 987,052 | 0.0102% |
|
| 16 |
|
| 17 |
| source | pattern | count | per-token share |
|
| 18 |
|---|---|---:|---:|
|
|
|
|
| 115 |
| samorzad_gov_pl | `w pobliżu` | 401 | 0.00097% |
|
| 116 |
| samorzad_gov_pl | `mieszkańców` | 14,450 | 0.03511% |
|
| 117 |
| samorzad_gov_pl | `Dz.U.` | 1,380 | 0.00335% |
|
| 118 |
+
| sejm_api | `w roku` | 2,123 | 0.00584% |
|
| 119 |
+
| sejm_api | `klasyfikacji` | 126 | 0.00035% |
|
| 120 |
+
| sejm_api | `ustawa` | 11,042 | 0.03039% |
|
| 121 |
+
| sejm_api | `artykuł` | 808 | 0.00222% |
|
| 122 |
+
| sejm_api | `parlament` | 14,230 | 0.03916% |
|
| 123 |
+
| sejm_api | `rozporządzenie` | 1,095 | 0.00301% |
|
| 124 |
+
| sejm_api | `w pobliżu` | 87 | 0.00024% |
|
| 125 |
+
| sejm_api | `mieszkańców` | 2,697 | 0.00742% |
|
| 126 |
+
| sejm_api | `Dz.U.` | 4 | 0.00001% |
|
| 127 |
| wikibooks | `w roku` | 319 | 0.00205% |
|
| 128 |
| wikibooks | `klasyfikacji` | 37 | 0.00024% |
|
| 129 |
| wikibooks | `ustawa` | 165 | 0.00106% |
|
|
|
|
| 178 |
| wikivoyage | `w pobliżu` | 6,480 | 0.03783% |
|
| 179 |
| wikivoyage | `mieszkańców` | 4,100 | 0.02394% |
|
| 180 |
| wikivoyage | `Dz.U.` | 1 | 0.00001% |
|
| 181 |
+
| wiktionary_examples | `w roku` | 56 | 0.00502% |
|
| 182 |
+
| wiktionary_examples | `klasyfikacji` | 5 | 0.00045% |
|
| 183 |
+
| wiktionary_examples | `ustawa` | 26 | 0.00233% |
|
| 184 |
+
| wiktionary_examples | `artykuł` | 42 | 0.00376% |
|
| 185 |
+
| wiktionary_examples | `parlament` | 28 | 0.00251% |
|
| 186 |
+
| wiktionary_examples | `rozporządzenie` | 5 | 0.00045% |
|
| 187 |
+
| wiktionary_examples | `w pobliżu` | 32 | 0.00287% |
|
| 188 |
+
| wiktionary_examples | `mieszkańców` | 64 | 0.00574% |
|
| 189 |
+
| wiktionary_examples | `Dz.U.` | 0 | 0.00000% |
|
| 190 |
| wolne_lektury | `w roku` | 1,898 | 0.00184% |
|
| 191 |
| wolne_lektury | `klasyfikacji` | 80 | 0.00008% |
|
| 192 |
| wolne_lektury | `ustawa` | 1,060 | 0.00103% |
|
|
@@ -253,7 +253,7 @@ family (Enevoldsen et al., [arXiv:2508.02271](https://arxiv.org/abs/2508.02271))
|
|
| 253 |
|
| 254 |
| version | status | documents | tokens | notes |
|
| 255 |
|---|---|---:|---:|---|
|
| 256 |
-
| `v0.2.5` | stable release | {tot_doc:,} | {tot_tok/1e9:.2f}B | Adds community-contributed `samorzad_gov_pl`
|
| 257 |
| `v0.2.4` | previous stable | 4,246,429 | 9.60B | Expanded `european_hplt_v3_pl` to WDS bins 10-5 (+1.49M docs / 2.04B tok); phone PII-scrub hardening (independent dual-lens) + cross-source dedup (zero-overlap). |
|
| 258 |
| `v0.2.3` | previous stable | 2,710,974 | 6.88B | Adds community-contributed `european_hplt_v3_pl`, `global_voices` and `nkjp1m`. |
|
| 259 |
| `v0.2.2` | previous stable | 2,579,963 | 6.36B | Added community-contributed `govpl`: 88,190 docs / 80.7M tokens. |
|
|
@@ -273,11 +273,26 @@ family (Enevoldsen et al., [arXiv:2508.02271](https://arxiv.org/abs/2508.02271))
|
|
| 273 |
|
| 274 |
#### v0.2.5 — current stable
|
| 275 |
|
| 276 |
-
Added
|
| 277 |
-
|
| 278 |
-
|
| 279 |
-
|
| 280 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 281 |
|
| 282 |
#### v0.2.4 — previous stable
|
| 283 |
|
|
@@ -365,6 +380,8 @@ as the redistributing aggregator; this release does not claim ownership of them
|
|
| 365 |
| [Arkadiusz Słota](https://huggingface.co/Maggio33) | Built & expanded `european_hplt_v3_pl`: HPLT v3 WDS 10+9 (PR #5) then WDS 10-5 expansion (+1,493,384 docs / 2.04B tok), modular cleaning pipeline, phone-recall PII-scrub (v12b, independent dual-lens), cross-source dedup-vs-base (zero-overlap), validation and documentation. | `v0.2.3` (PR #5), `v0.2.4` |
|
| 366 |
| [Dawid Majewski](https://huggingface.co/dawidmajewski) | Added the reviewed Global Voices Polish corpus; built `samorzad_gov_pl` with direct acquisition, institution attribution, licensing evidence, release artifact and reproducible conversion. | `v0.2.3`, [PR #7](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/7); `v0.2.5` |
|
| 367 |
| [1am](https://huggingface.co/1am) | Added `nkjp1m`: the manually annotated 1-million-word NKJP subcorpus, direct fetch/build pipeline, source documentation and release artifact. | `v0.2.3`, [PR #8](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/8) |
|
|
|
|
|
|
|
| 368 |
|
| 369 |
Contributions are credited when they add a verifiable dataset artifact, pipeline,
|
| 370 |
validation, documentation or release work. A merged discussion with no resulting
|
|
|
|
| 253 |
|
| 254 |
| version | status | documents | tokens | notes |
|
| 255 |
|---|---|---:|---:|---|
|
| 256 |
+
| `v0.2.5` | stable release | {tot_doc:,} | {tot_tok/1e9:.2f}B | Adds community-contributed `samorzad_gov_pl` (institution-level author attribution and a URL-bearing attribution sidecar), `sejm_api` and `wiktionary_examples`. |
|
| 257 |
| `v0.2.4` | previous stable | 4,246,429 | 9.60B | Expanded `european_hplt_v3_pl` to WDS bins 10-5 (+1.49M docs / 2.04B tok); phone PII-scrub hardening (independent dual-lens) + cross-source dedup (zero-overlap). |
|
| 258 |
| `v0.2.3` | previous stable | 2,710,974 | 6.88B | Adds community-contributed `european_hplt_v3_pl`, `global_voices` and `nkjp1m`. |
|
| 259 |
| `v0.2.2` | previous stable | 2,579,963 | 6.36B | Added community-contributed `govpl`: 88,190 docs / 80.7M tokens. |
|
|
|
|
| 273 |
|
| 274 |
#### v0.2.5 — current stable
|
| 275 |
|
| 276 |
+
Added three sources, bringing the complete release to **20 sources,
|
| 277 |
+
4,366,651 documents / 9,676,513,980 cl100k-proxy tokens**:
|
| 278 |
+
|
| 279 |
+
- `samorzad_gov_pl`: **72,771 documents / 41,154,506 cl100k-proxy
|
| 280 |
+
tokens** from 246 Polish local public institutions and one central platform
|
| 281 |
+
tenant. The contribution preserves the publishing institution as `author`,
|
| 282 |
+
discovered and fetched article URLs in an attribution sidecar and the verified
|
| 283 |
+
platform-wide CC-BY-SA-4.0 basis.
|
| 284 |
+
- `sejm_api`: **38,812 documents / 36,335,587 cl100k-proxy tokens** of
|
| 285 |
+
parliamentary speeches (2023 onward) from the official Sejm API,
|
| 286 |
+
`public-domain (official documents)`
|
| 287 |
+
([PR #16](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/16)).
|
| 288 |
+
- `wiktionary_examples`: **8,639 documents / 1,115,820 cl100k-proxy tokens**
|
| 289 |
+
of Polish Wiktionary usage examples, one document per headword,
|
| 290 |
+
`CC-BY-SA-3.0`
|
| 291 |
+
([PR #14](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/14)).
|
| 292 |
+
|
| 293 |
+
Documentation correction: the v0.2.5 tag contains all 20 sources. Earlier
|
| 294 |
+
copies of this card counted only 18 (4,319,200 documents / 9,639,062,573
|
| 295 |
+
tokens) and listed `sejm_api` and `wiktionary_examples` as not released.
|
| 296 |
|
| 297 |
#### v0.2.4 — previous stable
|
| 298 |
|
|
|
|
| 380 |
| [Arkadiusz Słota](https://huggingface.co/Maggio33) | Built & expanded `european_hplt_v3_pl`: HPLT v3 WDS 10+9 (PR #5) then WDS 10-5 expansion (+1,493,384 docs / 2.04B tok), modular cleaning pipeline, phone-recall PII-scrub (v12b, independent dual-lens), cross-source dedup-vs-base (zero-overlap), validation and documentation. | `v0.2.3` (PR #5), `v0.2.4` |
|
| 381 |
| [Dawid Majewski](https://huggingface.co/dawidmajewski) | Added the reviewed Global Voices Polish corpus; built `samorzad_gov_pl` with direct acquisition, institution attribution, licensing evidence, release artifact and reproducible conversion. | `v0.2.3`, [PR #7](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/7); `v0.2.5` |
|
| 382 |
| [1am](https://huggingface.co/1am) | Added `nkjp1m`: the manually annotated 1-million-word NKJP subcorpus, direct fetch/build pipeline, source documentation and release artifact. | `v0.2.3`, [PR #8](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/8) |
|
| 383 |
+
| Piotr Styła (HF: `PiotrSty`) | Corpus preparation and contribution of `sejm_api`: parliamentary speeches from the official Sejm API with speaker attribution and immutable `PiotrSty/sejm-speeches-corpus` v1.0.1 provenance. | `v0.2.5`, [PR #16](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/16) |
|
| 384 |
+
| Katarzyna Majzel-Pośpiech | Added `wiktionary_examples`: usage examples extracted from the Polish Wiktionary dump, one document per headword. | `v0.2.5`, [PR #14](https://huggingface.co/datasets/SlayerLab/polish-dynaword/discussions/14) |
|
| 385 |
|
| 386 |
Contributions are credited when they add a verifiable dataset artifact, pipeline,
|
| 387 |
validation, documentation or release work. A merged discussion with no resulting
|
|
@@ -45,7 +45,7 @@ SOURCES = {
|
|
| 45 |
},
|
| 46 |
"wiktionary_examples": {
|
| 47 |
"added": "2026-07-19",
|
| 48 |
-
"release":
|
| 49 |
"file_key": "wiktionary_examples",
|
| 50 |
"pretty": "Polish Wiktionary usage examples",
|
| 51 |
"provenance": "Parsed directly from the official Wikimedia dump "
|
|
@@ -96,7 +96,7 @@ SOURCES = {
|
|
| 96 |
"sejm_api": {
|
| 97 |
"added": "2026-08-22",
|
| 98 |
"custom_datasheet": True,
|
| 99 |
-
"release":
|
| 100 |
"file_key": "sejm_api",
|
| 101 |
"pretty": "Sejm API parliamentary speeches (2023 onward)",
|
| 102 |
"license": "public-domain (official documents)",
|
|
|
|
| 45 |
},
|
| 46 |
"wiktionary_examples": {
|
| 47 |
"added": "2026-07-19",
|
| 48 |
+
"release": "0.2.5",
|
| 49 |
"file_key": "wiktionary_examples",
|
| 50 |
"pretty": "Polish Wiktionary usage examples",
|
| 51 |
"provenance": "Parsed directly from the official Wikimedia dump "
|
|
|
|
| 96 |
"sejm_api": {
|
| 97 |
"added": "2026-08-22",
|
| 98 |
"custom_datasheet": True,
|
| 99 |
+
"release": "0.2.5",
|
| 100 |
"file_key": "sejm_api",
|
| 101 |
"pretty": "Sejm API parliamentary speeches (2023 onward)",
|
| 102 |
"license": "public-domain (official documents)",
|