
Datasets:

Add source: nkjp1m
#8
by 1am - opened
This view is limited to 50 files because it contains too many changes. See the raw diff here.
- .gitattributes +0 -4
- AGENTS.md +0 -257
- CHANGELOG.md +48 -131
- README.md +365 -495
- artifacts/dataset_size_by_version.png +0 -3
- artifacts/pattern_frequency_artykul.png +2 -2
- artifacts/pattern_frequency_dzu.png +2 -2
- artifacts/pattern_frequency_hf_snippet.md +10 -55
- artifacts/pattern_frequency_klasyfikacji.png +2 -2
- artifacts/pattern_frequency_mieszkańców.png +2 -2
- artifacts/pattern_frequency_overall.png +2 -2
- artifacts/pattern_frequency_parlament.png +2 -2
- artifacts/pattern_frequency_rozporządzenie.png +2 -2
- artifacts/pattern_frequency_ustawa.png +2 -2
- artifacts/pattern_frequency_w_pobliżu.png +2 -2
- artifacts/pattern_frequency_w_roku.png +2 -2
- artifacts/rock_pollub_pl_ontology_manifest.json +0 -236
- artifacts/sejm_api_ontology_manifest.json +0 -238
- artifacts/source_findings.md +0 -543
- artifacts/uzp_orzeczenia_pl_ontology_manifest.json +0 -134
- data/biblioteka_nauki/biblioteka_nauki.md +0 -60
- data/biblioteka_nauki/biblioteka_nauki.parquet +0 -3
- data/biblioteka_nauki/biblioteka_nauki.stats.json +0 -12
- data/biblioteka_nauki/recover_attribution.py +0 -125
- data/biblioteka_nauki/recover_licenses.py +0 -171
- data/european_hplt_v3_pl/european_hplt_v3_pl.md +57 -0
- data/{rock_pollub_pl/rock_pollub_pl.parquet → european_hplt_v3_pl/european_hplt_v3_pl.parquet} +2 -2
- data/european_hplt_v3_pl/european_hplt_v3_pl.stats.json +41 -0
- data/global_voices/global_voices.attribution.jsonl +0 -0
- data/rock_pollub_pl/NOTICE.md +0 -8
- data/rock_pollub_pl/rock_pollub_pl.attribution.jsonl +0 -3
- data/rock_pollub_pl/rock_pollub_pl.decisions.jsonl +0 -3
- data/rock_pollub_pl/rock_pollub_pl.md +0 -29
- data/rock_pollub_pl/rock_pollub_pl.overlap_audit.json +0 -61
- data/rock_pollub_pl/rock_pollub_pl.qa.json +0 -81
- data/rock_pollub_pl/rock_pollub_pl.sample.jsonl +0 -0
- data/rock_pollub_pl/rock_pollub_pl.stats.json +0 -12
- data/samorzad_gov_pl/NOTICE.md +0 -28
- data/samorzad_gov_pl/samorzad_gov_pl.attribution.jsonl +0 -3
- data/samorzad_gov_pl/samorzad_gov_pl.license-evidence.json +0 -17
- data/samorzad_gov_pl/samorzad_gov_pl.md +0 -138
- data/samorzad_gov_pl/samorzad_gov_pl.parquet +0 -3
- data/samorzad_gov_pl/samorzad_gov_pl.stats.json +0 -25
- data/sejm_api/NOTICE.md +0 -9
- data/sejm_api/sejm_api.attribution.jsonl +0 -3
- data/sejm_api/sejm_api.license-evidence.json +0 -34
- data/sejm_api/sejm_api.md +0 -65
- data/sejm_api/sejm_api.parquet +0 -3
- data/sejm_api/sejm_api.stats.json +0 -36
- data/uzp_orzeczenia_pl/NOTICE.md +0 -7
.gitattributes
CHANGED
|
@@ -35,7 +35,6 @@ saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
|
| 35 |
*.xz filter=lfs diff=lfs merge=lfs -text
|
| 36 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 37 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 38 |
-
data/samorzad_gov_pl/*.jsonl filter=lfs diff=lfs merge=lfs -text
|
| 39 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 40 |
# Audio files - uncompressed
|
| 41 |
*.pcm filter=lfs diff=lfs merge=lfs -text
|
|
@@ -59,6 +58,3 @@ data/samorzad_gov_pl/*.jsonl filter=lfs diff=lfs merge=lfs -text
|
|
| 59 |
# Video files - compressed
|
| 60 |
*.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 61 |
*.webm filter=lfs diff=lfs merge=lfs -text
|
| 62 |
-
# Per-source audit trails: one rule for all sources, so source PRs don't edit this file
|
| 63 |
-
data/*/*.attribution.jsonl filter=lfs diff=lfs merge=lfs -text
|
| 64 |
-
data/*/*.decisions.jsonl filter=lfs diff=lfs merge=lfs -text
|
|
|
|
| 35 |
*.xz filter=lfs diff=lfs merge=lfs -text
|
| 36 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 37 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
|
|
|
| 38 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 39 |
# Audio files - uncompressed
|
| 40 |
*.pcm filter=lfs diff=lfs merge=lfs -text
|
|
|
|
| 58 |
# Video files - compressed
|
| 59 |
*.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 60 |
*.webm filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
AGENTS.md
DELETED
|
@@ -1,257 +0,0 @@
|
|
| 1 |
-
# AGENTS.md
|
| 2 |
-
|
| 3 |
-
Guidance for agents and contributors adding a source and cutting a release.
|
| 4 |
-
Read this before opening a PR. Source PRs and releases are separate: a source PR
|
| 5 |
-
adds one source with `release: None`; the maintainer later cuts one release that
|
| 6 |
-
bumps the version and docs for every source merged since the last one.
|
| 7 |
-
|
| 8 |
-
## How the docs are actually maintained
|
| 9 |
-
|
| 10 |
-
`src/make_docs.py` is a **scaffolding/assembly helper, not a round-trip source
|
| 11 |
-
of truth.** It regenerates the README source table + release totals, `LICENSE`,
|
| 12 |
-
a `CHANGELOG` stub, and *template* datasheets — but it does **not** reproduce the
|
| 13 |
-
committed docs on its own:
|
| 14 |
-
|
| 15 |
-
- It iterates `SOURCES` in `src/sources.py`; any source in `data/` but missing
|
| 16 |
-
from `SOURCES` is silently dropped from the table and totals.
|
| 17 |
-
- It stamps a regenerated datasheet's "Added" with the source's `added` field,
|
| 18 |
-
falling back to the global `ADDED` constant when the entry has none — so a new
|
| 19 |
-
entry without `added` still gets a wrong date.
|
| 20 |
-
- It cannot reproduce hand-written README narrative (audit notes, policy notes,
|
| 21 |
-
the phrase-frequency section).
|
| 22 |
-
|
| 23 |
-
So datasheets and the README narrative are **hand/contributor-maintained**.
|
| 24 |
-
Never run `make_docs.py` and commit the result blind — `git diff` first and
|
| 25 |
-
restore anything it dropped or restamped.
|
| 26 |
-
|
| 27 |
-
## Before you start: check the findings log
|
| 28 |
-
|
| 29 |
-
`artifacts/source_findings.md` records sources already investigated, including
|
| 30 |
-
the rejected ones and *why*. Check it before spending a day on a source someone
|
| 31 |
-
already found to be blocked — and append your own finding there whether the
|
| 32 |
-
answer was yes or no.
|
| 33 |
-
|
| 34 |
-
## Add a source
|
| 35 |
-
|
| 36 |
-
1. Produce the artifact under `data/<key>/`:
|
| 37 |
-
- `<key>.parquet` — built by `src/build_dynaword.py` (LFS-tracked automatically).
|
| 38 |
-
- `<key>.stats.json` — doc/token/char counts (drives all totals).
|
| 39 |
-
- `<key>.md` — datasheet (see below).
|
| 40 |
-
2. Add the ingestion script: `src/fetch_<key>.py` or `src/clean_<key>.py`, so the
|
| 41 |
-
source is reproducible. `build_source` (build_dynaword.py) expects a
|
| 42 |
-
`<file_key|speakleash_key>.jsonl.zst` intermediate.
|
| 43 |
-
3. Register the source in `src/sources.py` (`SOURCES`) — required, or make_docs
|
| 44 |
-
never sees it. Copy an existing entry's shape: `pretty`, `license`,
|
| 45 |
-
`license_spdx`, `traceable`, `upstream`, `domain`, `created`, `is_ocr`, and the
|
| 46 |
-
`speakleash_key`/`file_key`. If the datasheet is hand-authored (rich provenance
|
| 47 |
-
or a fixed add date), add `"custom_datasheet": True` so make_docs leaves it
|
| 48 |
-
alone.
|
| 49 |
-
|
| 50 |
-
Also set `added` (the real add date) and `release`. `release` is what admits a
|
| 51 |
-
source to a release's totals: `None` means "on main, not in any release yet",
|
| 52 |
-
which is the correct value for a new source until the release that ships it is
|
| 53 |
-
cut. Nothing is counted just because it has a `stats.json`.
|
| 54 |
-
4. Add a contract test: `src/test_<key>_contract.py` (canonical schema, non-empty
|
| 55 |
-
text, positive token counts, uniform source/license, stats-file consistency).
|
| 56 |
-
Run `python3 -m pytest src/` before committing.
|
| 57 |
-
|
| 58 |
-
### Keep the PR to your source
|
| 59 |
-
|
| 60 |
-
Many source PRs are open at once, and each one that touches shared files
|
| 61 |
-
conflicts with the others. A source PR changes only:
|
| 62 |
-
|
| 63 |
-
- `data/<key>/*`, `src/fetch_<key>.py` / `src/clean_<key>.py`,
|
| 64 |
-
`src/test_<key>_contract.py`;
|
| 65 |
-
- **one** new entry in `src/sources.py`, with `release: None`;
|
| 66 |
-
- your entry appended to `artifacts/source_findings.md`.
|
| 67 |
-
|
| 68 |
-
It does **not** touch `README.md`, `CHANGELOG.md`, `VERSION`/`RELEASE_DATE` in
|
| 69 |
-
`src/make_docs.py`, the phrase-frequency report, `AGENTS.md`, or other sources'
|
| 70 |
-
fetchers — those change in the release commit (below) or in their own PR.
|
| 71 |
-
`.gitattributes` already LFS-tracks `data/*/*.attribution.jsonl` and
|
| 72 |
-
`*.decisions.jsonl`; do not add per-file lines.
|
| 73 |
-
Commit with LF line endings — a CRLF `sources.py` shows as a whole-file rewrite
|
| 74 |
-
and conflicts with every other PR. Rebase onto `main` before asking for review.
|
| 75 |
-
|
| 76 |
-
## What the PR must show
|
| 77 |
-
|
| 78 |
-
These two are not optional — they are the difference between a source a reviewer
|
| 79 |
-
can accept and one that sits in the queue. Treat every source PR as a worked
|
| 80 |
-
example other contributors will copy.
|
| 81 |
-
|
| 82 |
-
1. **A sample of the data, inline in the PR description.** A few real documents
|
| 83 |
-
(or truncated ones), verbatim, so a reviewer can see at a glance what kind of
|
| 84 |
-
text this actually is — prose, transcripts, boilerplate, OCR noise, HTML
|
| 85 |
-
leftovers. Include the metadata columns too, not just `text`. Don't make the
|
| 86 |
-
reviewer download a parquet to find out — and a linked `.sample.jsonl` is not
|
| 87 |
-
a substitute: on the Hub it renders as one escaped line per document.
|
| 88 |
-
|
| 89 |
-
Generate it from the built shard and paste the output into the PR description:
|
| 90 |
-
```bash
|
| 91 |
-
python3 src/render_sample.py data/<key>/<key>.parquet -n 3
|
| 92 |
-
```
|
| 93 |
-
Each document is a fenced block — metadata as `key: value` lines, a blank
|
| 94 |
-
line, then the text with its real line breaks, truncated with `[…]`:
|
| 95 |
-
````
|
| 96 |
-
```
|
| 97 |
-
id: sejm_interpellations_2388
|
| 98 |
-
source: sejm_interpellations
|
| 99 |
-
added: 2026-07-19
|
| 100 |
-
token_count: 415
|
| 101 |
-
license: public-domain (official documents)
|
| 102 |
-
author: Daniel Milewski
|
| 103 |
-
|
| 104 |
-
Szanowny Panie Ministrze,
|
| 105 |
-
|
| 106 |
-
latem 2022 roku na podlaskiej części granicy z Białorusią ukończono […]
|
| 107 |
-
```
|
| 108 |
-
````
|
| 109 |
-
Pick rows that show the typical document; if the source has distinct
|
| 110 |
-
document types (question vs reply, article vs talk page), show one of each.
|
| 111 |
-
|
| 112 |
-
2. **Provenance and licensing, written out in the datasheet (`data/<key>/<key>.md`)
|
| 113 |
-
and summarized in the PR description:**
|
| 114 |
-
- Where the data comes from — the concrete origin (institution, portal, API,
|
| 115 |
-
dump), not just a domain name. Link it.
|
| 116 |
-
- Under what license, and **where that license statement lives** — link the
|
| 117 |
-
exact terms-of-use page, API docs section, or statute. "Public domain
|
| 118 |
-
because it's government data" is a claim, not a source; cite the provision.
|
| 119 |
-
- What the texts are — genre, register, time span, language variety, whether
|
| 120 |
-
they are OCR'd, machine-translated, or user-generated.
|
| 121 |
-
- How it was collected and filtered — dedup, minimum length, language ID,
|
| 122 |
-
anything dropped and why.
|
| 123 |
-
- The argument for inclusion — what this adds that the corpus does not
|
| 124 |
-
already have, and any known bias or quality caveat a downstream user should
|
| 125 |
-
weigh.
|
| 126 |
-
|
| 127 |
-
Yes, this is meta work on top of the fetching. That is the point: the datasheet
|
| 128 |
-
is the artifact other people read to learn how to contribute well.
|
| 129 |
-
|
| 130 |
-
## Normalize the text before you build
|
| 131 |
-
|
| 132 |
-
`build_dynaword.py` applies only *minimal gates* — strip, `len < 200`, Polish
|
| 133 |
-
diacritic ratio, OCR alpha ratio, exact sha1 dedup. It does **not** clean text.
|
| 134 |
-
`src/normalize_schema.py` is a schema/stats tool despite the name; it never
|
| 135 |
-
touches `text`. So normalization is the fetcher's job, and today each fetcher
|
| 136 |
-
reimplements it (`fetch_govpl.py:43` and `fetch_saos.py:42` carry byte-identical
|
| 137 |
-
`html_to_text`; `clean_samorzad_gov_pl.py:65` a third variant). If you are
|
| 138 |
-
writing a new fetcher, factor the shared parts out rather than pasting a fourth
|
| 139 |
-
copy.
|
| 140 |
-
|
| 141 |
-
What a fetcher should do to `text` before writing the `.jsonl.zst`:
|
| 142 |
-
|
| 143 |
-
- **Unicode**: NFKC normalize. Map non-breaking/thin/zero-width spaces to plain
|
| 144 |
-
space (or drop), strip control characters and soft hyphens, normalize the
|
| 145 |
-
quote/dash/ellipsis zoo. Repair mojibake if the upstream encoding is unreliable.
|
| 146 |
-
- **Whitespace**: collapse runs of spaces/tabs, trim per line, cap blank runs at
|
| 147 |
-
one empty line. Do not flatten paragraph breaks — they carry structure.
|
| 148 |
-
- **Structural junk**: navigation, cookie banners, "share this", pagination,
|
| 149 |
-
footnote back-references, and — for OCR/PDF sources — page headers/footers,
|
| 150 |
-
running titles, and hyphenation split across line breaks.
|
| 151 |
-
- **Numbering**: strip standalone chapter/section/page numbers and repeated
|
| 152 |
-
heading numerals (`1.`, `Art. 5.`, `Rozdział III`) *only where they are layout
|
| 153 |
-
artifacts*. In `dziennik_ustaw` or `saos` the article numbering is content —
|
| 154 |
-
removing it destroys the document. Judge per source, and say what you did in
|
| 155 |
-
the datasheet.
|
| 156 |
-
- **Boilerplate**: near-identical blocks repeated across most documents of a
|
| 157 |
-
source (license footers, institutional disclaimers, "Pokaż odpowiedź"-style UI
|
| 158 |
-
chrome) should be detected by frequency across the shard and removed, not
|
| 159 |
-
hand-listed.
|
| 160 |
-
- **Personal data**: do not keep a scrubber in this repo. Apply
|
| 161 |
-
[`SlayerLab/NERGAL`](https://huggingface.co/SlayerLab/NERGAL) before the
|
| 162 |
-
parquet is written (frozen regex ∪ model; placeholders `[PII]` / `[Telefon]`).
|
| 163 |
-
Names of public officials acting in an official capacity are not PII and
|
| 164 |
-
should stay — removing them would gut parliamentary and judicial sources.
|
| 165 |
-
A source scrubbed some other way may still merge with `release: None`, but it
|
| 166 |
-
is not admitted to a release until its shard has been re-run through NERGAL.
|
| 167 |
-
Say in the datasheet which scrubber ran. Note that `main` is public on the Hub
|
| 168 |
-
whether or not a source is released.
|
| 169 |
-
|
| 170 |
-
Two rules about all of the above:
|
| 171 |
-
|
| 172 |
-
1. **The normalization must live in the committed fetch/clean script**, so the
|
| 173 |
-
shard is reproducible. A shard whose datasheet describes a cleaning step that
|
| 174 |
-
no script in `src/` performs is not reproducible, however good the intent.
|
| 175 |
-
2. **Report it in the datasheet**: which steps ran, and what the gates dropped.
|
| 176 |
-
Include a handful of before/after excerpts in the PR — this is the fastest way
|
| 177 |
-
for a reviewer to see whether normalization ate real content.
|
| 178 |
-
|
| 179 |
-
## Cut the release (maintainer, one commit after the source PRs merge)
|
| 180 |
-
|
| 181 |
-
0. In `src/sources.py`, set `release` on each merged source this release ships
|
| 182 |
-
(check its shard went through NERGAL first).
|
| 183 |
-
1. In `src/make_docs.py`: bump `VERSION` and `RELEASE_DATE`. Add a row for the new
|
| 184 |
-
version to the version table and a row for each new contributor to the
|
| 185 |
-
Contributors table (both are literal rows in the template).
|
| 186 |
-
2. Regenerate the phrase-frequency report and charts (registry-independent — it
|
| 187 |
-
globs `data/*/*.parquet`):
|
| 188 |
-
```bash
|
| 189 |
-
python3 src/pattern_frequency_report.py
|
| 190 |
-
```
|
| 191 |
-
Writes `artifacts/pattern_frequency_hf_snippet.md` + 10 PNGs. Splice the tables
|
| 192 |
-
and chart embeds into the README "Results" section by hand.
|
| 193 |
-
3. Update `README.md` by hand: header totals, version table, source table row,
|
| 194 |
-
Contributors row. The document/token totals must equal the sum of the
|
| 195 |
-
per-source `stats.json` files.
|
| 196 |
-
4. Prepend the release notes to `CHANGELOG.md` under a new `## vX.Y.Z (date)`
|
| 197 |
-
heading. History is append-only — never rewrite earlier releases.
|
| 198 |
-
|
| 199 |
-
## Push to Hugging Face
|
| 200 |
-
|
| 201 |
-
`origin` is the Hub itself
|
| 202 |
-
(`https://huggingface.co/datasets/SlayerLab/polish-dynaword`) — there is no GitHub
|
| 203 |
-
remote. `git push` authenticates through the git credential helper (macOS:
|
| 204 |
-
`osxkeychain`), which is separate from `hf auth login`: pushes can work fine while
|
| 205 |
-
`hf auth whoami` still reports "Not logged in". The Python API and `hf` CLI need
|
| 206 |
-
the login (or `HF_TOKEN`).
|
| 207 |
-
|
| 208 |
-
Hub pull requests use no forks and no named branches. A PR *is* the ref
|
| 209 |
-
`refs/pr/N` and the Hub assigns `N`, so you cannot open one by pushing — the ref
|
| 210 |
-
has to exist first. (Plain branches can be pushed, but a branch is not a PR and
|
| 211 |
-
nobody reviews it.)
|
| 212 |
-
|
| 213 |
-
Open a PR for work already committed locally:
|
| 214 |
-
|
| 215 |
-
```bash
|
| 216 |
-
# 1. create the empty PR (needs the write token)
|
| 217 |
-
python3 -c "
|
| 218 |
-
from huggingface_hub import HfApi
|
| 219 |
-
pr = HfApi().create_pull_request(
|
| 220 |
-
'SlayerLab/polish-dynaword', repo_type='dataset',
|
| 221 |
-
title='<title>', description='<what changed and why>')
|
| 222 |
-
print(pr.num, pr.url)"
|
| 223 |
-
|
| 224 |
-
# 2. push your local branch onto that ref
|
| 225 |
-
git push origin <local-branch>:refs/pr/<N>
|
| 226 |
-
```
|
| 227 |
-
|
| 228 |
-
Opened this way the PR starts in **draft** — publish it from the web UI.
|
| 229 |
-
|
| 230 |
-
Pick up an existing PR (42 here):
|
| 231 |
-
|
| 232 |
-
```bash
|
| 233 |
-
GIT_LFS_SKIP_SMUDGE=1 git -c fetch.negotiationAlgorithm=noop fetch origin refs/pr/42:pr/42
|
| 234 |
-
git checkout pr/42
|
| 235 |
-
git push origin pr/42:refs/pr/42
|
| 236 |
-
```
|
| 237 |
-
|
| 238 |
-
The `noop` negotiation is needed: for some refs the Hub fails the have/ack
|
| 239 |
-
exchange (`fatal: expected 'acknowledgments'`), and skipping it makes the server
|
| 240 |
-
send the full history instead. `GIT_LFS_SKIP_SMUDGE=1` keeps it to pointers;
|
| 241 |
-
pull a single blob with `git lfs pull --include <path>`.
|
| 242 |
-
|
| 243 |
-
`repo_type='dataset'` is required on every `huggingface_hub` call — this is a
|
| 244 |
-
dataset repo, not a model. Push straight to `main` only when cutting a release.
|
| 245 |
-
|
| 246 |
-
## Do not commit
|
| 247 |
-
|
| 248 |
-
`*.log` (fetch/build logs), `.DS_Store`, `src/__pycache__/`. Only `logs/` is in
|
| 249 |
-
`.gitignore` — root-level logs and OS cruft are not, so check `git status`
|
| 250 |
-
before staging. `*.parquet` is LFS-tracked; commit the pointer, not the blob.
|
| 251 |
-
|
| 252 |
-
## Known drift / cleanup opportunities
|
| 253 |
-
|
| 254 |
-
- `europeana` is in `SOURCES` but has no `data/` shard anywhere, and
|
| 255 |
-
`parlamint_pl` has one only in some working trees — it is not committed.
|
| 256 |
-
make_docs skips both with `! no stats`. Intentional placeholders or stale —
|
| 257 |
-
confirm before relying on `build_dynaword.py --all`.
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
CHANGELOG.md
CHANGED
|
@@ -1,131 +1,48 @@
|
|
| 1 |
-
# Changelog
|
| 2 |
-
|
| 3 |
-
##
|
| 4 |
-
|
| 5 |
-
-
|
| 6 |
-
|
| 7 |
-
|
| 8 |
-
|
| 9 |
-
|
| 10 |
-
|
| 11 |
-
|
| 12 |
-
|
| 13 |
-
|
| 14 |
-
|
| 15 |
-
|
| 16 |
-
|
| 17 |
-
|
| 18 |
-
|
| 19 |
-
|
| 20 |
-
|
| 21 |
-
|
| 22 |
-
|
| 23 |
-
|
| 24 |
-
|
| 25 |
-
|
| 26 |
-
|
| 27 |
-
|
| 28 |
-
|
| 29 |
-
|
| 30 |
-
|
| 31 |
-
|
| 32 |
-
|
| 33 |
-
|
| 34 |
-
|
| 35 |
-
|
| 36 |
-
|
| 37 |
-
|
| 38 |
-
|
| 39 |
-
|
| 40 |
-
|
| 41 |
-
|
| 42 |
-
|
| 43 |
-
|
| 44 |
-
|
| 45 |
-
|
| 46 |
-
-
|
| 47 |
-
|
| 48 |
-
|
| 49 |
-
"downstream near-dedup remains" caveat from the original release.
|
| 50 |
-
- Contract-revalidated the merged parquet (canonical schema, non-empty text,
|
| 51 |
-
positive token counts, uniform source/license, stats-file consistency).
|
| 52 |
-
- Expanded contributor credit for Arkadiusz Słota (`Maggio33`) for the WDS 10-5
|
| 53 |
-
expansion, PII-scrub and dedup work.
|
| 54 |
-
- Updated the complete-corpus release totals from per-source parquet stats:
|
| 55 |
-
4,246,429 documents and 9,597,908,067 cl100k-proxy tokens across 17 sources
|
| 56 |
-
(also reflects the separately-merged `biblioteka_nauki` source now present on
|
| 57 |
-
main).
|
| 58 |
-
|
| 59 |
-
## v0.2.3 (2026-07-26)
|
| 60 |
-
|
| 61 |
-
- Added the community contribution `european_hplt_v3_pl` by Arkadiusz Słota
|
| 62 |
-
(`Maggio33`): HPLT v3.0 Polish WDS quality bins 10+9, 110,590 documents and
|
| 63 |
-
512,383,778 cl100k-proxy tokens under CC0-1.0 packaging.
|
| 64 |
-
- Added the reviewed `global_voices` contribution by Dawid Majewski
|
| 65 |
-
(`dawidmajewski`): 2,040 documents / 3,715,020 tokens with CC-BY-3.0 and
|
| 66 |
-
per-document author attribution metadata.
|
| 67 |
-
- Added `nkjp1m` from contributor `1am`: 18,381 documents / 2,601,201 tokens
|
| 68 |
-
from the manually annotated 1-million-word NKJP subcorpus under the upstream
|
| 69 |
-
version-unspecified CC-BY statement.
|
| 70 |
-
- Revalidated the contributed parquet against the canonical schema, non-empty
|
| 71 |
-
text, positive token counts, uniform source/license metadata, and stats-file
|
| 72 |
-
consistency.
|
| 73 |
-
- Updated the complete 16-source release totals from per-source parquet stats:
|
| 74 |
-
2,710,974 documents and 6,881,277,362 cl100k-proxy tokens.
|
| 75 |
-
- Recomputed the full-corpus phrase-frequency report and charts. Updated the
|
| 76 |
-
Arrow reporting path to use 64-bit string offsets for large row groups.
|
| 77 |
-
- Fixed `src/test_hplt_v3_contract.py` to resolve its fixture relative to the
|
| 78 |
-
repository instead of a contributor-local Windows path.
|
| 79 |
-
- Added public contributor credit for Arkadiusz Słota (`Maggio33`) and Paweł
|
| 80 |
-
Puzio (`ppuzio`, author of the `govpl` contribution released in v0.2.2), plus
|
| 81 |
-
Dawid Majewski (`dawidmajewski`) for Global Voices Polish.
|
| 82 |
-
- HPLT caveat: CC0 applies to the HPLT packaging; underlying web documents can
|
| 83 |
-
carry independent rights. Downstream near-dedup and web-content review remain
|
| 84 |
-
recommended before training.
|
| 85 |
-
|
| 86 |
-
## v0.2.2 (2026-07-19)
|
| 87 |
-
|
| 88 |
-
- Added `govpl` — gov.pl Polish government press releases (CC-BY-SA-4.0),
|
| 89 |
-
88,190 documents / 80.7M tokens, fetched directly from gov.pl across 133
|
| 90 |
-
ministry/agency subsites. New scripts: `src/discover_govpl.py` (discovers each
|
| 91 |
-
subsite's news-section path into the committed `src/govpl_subsites.json`
|
| 92 |
-
manifest) and `src/fetch_govpl.py` (pure-stdlib crawl of that manifest).
|
| 93 |
-
- Stable totals after adding govpl: 13 sources, 2,579,963 docs, 6.36B tokens
|
| 94 |
-
(tiktoken proxy).
|
| 95 |
-
- Article date range 2005-09-26 → 2026-07-19. Build dropped 24 non-Polish and
|
| 96 |
-
deduped 1,926 cross-posted articles (exact sha1).
|
| 97 |
-
|
| 98 |
-
## v0.3.1-preview (2026-07-10)
|
| 99 |
-
|
| 100 |
-
- Added a separate 810-document Europeana direct-ingestion preview parquet at
|
| 101 |
-
`previews/v0.3.1/europeana.parquet`. It was built from 1,000 live API records
|
| 102 |
-
using per-record rights/creator metadata in 59.4 seconds; 808 retained records are Public
|
| 103 |
-
Domain Mark and two are CC-BY-SA-4.0.
|
| 104 |
-
- The direct source gate dropped 181 non-Polish and nine OCR-garble records.
|
| 105 |
-
`dsbench` found unique IDs, no empty text, no duplicate text and no eval-set
|
| 106 |
-
overlap. Potential-phone matches remain warnings for manual review.
|
| 107 |
-
- This preview does not change v0.2.1 stable totals or promote Europeana to a
|
| 108 |
-
stable source. It is the measured contract for the full rights-preserving run.
|
| 109 |
-
|
| 110 |
-
## v0.3.0-preview (in progress)
|
| 111 |
-
|
| 112 |
-
- Validated the source-policy gate on live local SpeakLeash shards: 12 reviewed
|
| 113 |
-
sources sampled and cleared blocking checks; four sources remain excluded and
|
| 114 |
-
two talk-page shards remain on hold pending a separate policy.
|
| 115 |
-
- Ran a direct Europeana 200-record rebuild probe with per-record rights and
|
| 116 |
-
creator metadata: 197 Public Domain Mark and three CC-BY-SA-4.0 records
|
| 117 |
-
cleared blocking validation. This is candidate validation, not a release
|
| 118 |
-
inclusion.
|
| 119 |
-
- Biblioteka Nauki direct probe currently returns HTTP 500 and is held out of
|
| 120 |
-
the preview until the upstream request is repaired and audited.
|
| 121 |
-
|
| 122 |
-
## v0.2.1 (2026-07-02)
|
| 123 |
-
|
| 124 |
-
- Released a stable metadata-schema update: `id, text, source, added, created, token_count, license, author`.
|
| 125 |
-
- Current release totals after parquet recount: 12 sources, 2,491,773 docs, 6.28B tokens (tiktoken proxy).
|
| 126 |
-
- Added `1000_novels` as a stable CC-BY-4.0 literature source.
|
| 127 |
-
- Added source registry entries and PR contract for future `biblioteka_nauki` and `europeana` ingestion with per-document license/author metadata. These sources are not included in v0.2.1 parquets yet.
|
| 128 |
-
- Credited Bart Kobyliński for source expansion work on Biblioteka Nauki and Europeana metadata/rebuild preparation.
|
| 129 |
-
- Kept raw SpeakLeash Europeana excluded unless a direct rebuild preserves per-record rights metadata.
|
| 130 |
-
- Sources: eurlex, parliamentary, wikisource, wikipedia, dziennik_ustaw, wolne_lektury, 1000_novels, wikiquote, eltec_pol, wikivoyage, wikibooks, wikinews.
|
| 131 |
-
- Excluded (see README): open_subtitles_corpus, europeana_eu_pl_corpus_raw_speakleash, project_gutenberg_pl_corpus.
|
|
|
|
| 1 |
+
# Changelog
|
| 2 |
+
|
| 3 |
+
## v0.2.2 (2026-07-19)
|
| 4 |
+
|
| 5 |
+
- Added `govpl` — gov.pl Polish government press releases (CC-BY-SA-4.0),
|
| 6 |
+
88,190 documents / 80.7M tokens, fetched directly from gov.pl across 133
|
| 7 |
+
ministry/agency subsites. New scripts: `src/discover_govpl.py` (discovers each
|
| 8 |
+
subsite's news-section path into the committed `src/govpl_subsites.json`
|
| 9 |
+
manifest) and `src/fetch_govpl.py` (pure-stdlib crawl of that manifest).
|
| 10 |
+
- Stable totals after adding govpl: 13 sources, 2,579,963 docs, 6.36B tokens
|
| 11 |
+
(tiktoken proxy).
|
| 12 |
+
- Article date range 2005-09-26 → 2026-07-19. Build dropped 24 non-Polish and
|
| 13 |
+
deduped 1,926 cross-posted articles (exact sha1).
|
| 14 |
+
|
| 15 |
+
## v0.3.1-preview (2026-07-10)
|
| 16 |
+
|
| 17 |
+
- Added a separate 810-document Europeana direct-ingestion preview parquet at
|
| 18 |
+
`previews/v0.3.1/europeana.parquet`. It was built from 1,000 live API records
|
| 19 |
+
using per-record rights/creator metadata in 59.4 seconds; 808 retained records are Public
|
| 20 |
+
Domain Mark and two are CC-BY-SA-4.0.
|
| 21 |
+
- The direct source gate dropped 181 non-Polish and nine OCR-garble records.
|
| 22 |
+
`dsbench` found unique IDs, no empty text, no duplicate text and no eval-set
|
| 23 |
+
overlap. Potential-phone matches remain warnings for manual review.
|
| 24 |
+
- This preview does not change v0.2.1 stable totals or promote Europeana to a
|
| 25 |
+
stable source. It is the measured contract for the full rights-preserving run.
|
| 26 |
+
|
| 27 |
+
## v0.3.0-preview (in progress)
|
| 28 |
+
|
| 29 |
+
- Validated the source-policy gate on live local SpeakLeash shards: 12 reviewed
|
| 30 |
+
sources sampled and cleared blocking checks; four sources remain excluded and
|
| 31 |
+
two talk-page shards remain on hold pending a separate policy.
|
| 32 |
+
- Ran a direct Europeana 200-record rebuild probe with per-record rights and
|
| 33 |
+
creator metadata: 197 Public Domain Mark and three CC-BY-SA-4.0 records
|
| 34 |
+
cleared blocking validation. This is candidate validation, not a release
|
| 35 |
+
inclusion.
|
| 36 |
+
- Biblioteka Nauki direct probe currently returns HTTP 500 and is held out of
|
| 37 |
+
the preview until the upstream request is repaired and audited.
|
| 38 |
+
|
| 39 |
+
## v0.2.1 (2026-07-02)
|
| 40 |
+
|
| 41 |
+
- Released a stable metadata-schema update: `id, text, source, added, created, token_count, license, author`.
|
| 42 |
+
- Current release totals after parquet recount: 12 sources, 2,491,773 docs, 6.28B tokens (tiktoken proxy).
|
| 43 |
+
- Added `1000_novels` as a stable CC-BY-4.0 literature source.
|
| 44 |
+
- Added source registry entries and PR contract for future `biblioteka_nauki` and `europeana` ingestion with per-document license/author metadata. These sources are not included in v0.2.1 parquets yet.
|
| 45 |
+
- Credited Bart Kobyliński for source expansion work on Biblioteka Nauki and Europeana metadata/rebuild preparation.
|
| 46 |
+
- Kept raw SpeakLeash Europeana excluded unless a direct rebuild preserves per-record rights metadata.
|
| 47 |
+
- Sources: eurlex, parliamentary, wikisource, wikipedia, dziennik_ustaw, wolne_lektury, 1000_novels, wikiquote, eltec_pol, wikivoyage, wikibooks, wikinews.
|
| 48 |
+
- Excluded (see README): open_subtitles_corpus, europeana_eu_pl_corpus_raw_speakleash, project_gutenberg_pl_corpus.
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
README.md
CHANGED
|
@@ -1,495 +1,365 @@
|
|
| 1 |
-
---
|
| 2 |
-
license: cc-by-sa-4.0
|
| 3 |
-
language:
|
| 4 |
-
- pl
|
| 5 |
-
pretty_name: Polish DynaWord
|
| 6 |
-
task_categories:
|
| 7 |
-
- text-generation
|
| 8 |
-
size_categories:
|
| 9 |
-
- 1M<n<10M
|
| 10 |
-
tags:
|
| 11 |
-
- polish
|
| 12 |
-
- pretraining
|
| 13 |
-
- dynaword
|
| 14 |
-
---
|
| 15 |
-
|
| 16 |
-
# Polish DynaWord
|
| 17 |
-
|
| 18 |
-
A continuously developed, **openly-licensed**, human-text Polish corpus — a Polish
|
| 19 |
-
edition in the [Dynaword](https://huggingface.co/datasets/danish-foundation-models/danish-dynaword)
|
| 20 |
-
family (Enevoldsen et al., [arXiv:2508.02271](https://arxiv.org/abs/2508.02271)).
|
| 21 |
-
|
| 22 |
-
> **v0.2.
|
| 23 |
-
> (tiktoken proxy; canonical Llama-3 count at release) ·
|
| 24 |
-
> Updated: **2026-
|
| 25 |
-
|
| 26 |
-
> **v0.3-
|
| 27 |
-
>
|
| 28 |
-
>
|
| 29 |
-
|
| 30 |
-
|
| 31 |
-
>
|
| 32 |
-
>
|
| 33 |
-
|
| 34 |
-
|
| 35 |
-
|
| 36 |
-
|
| 37 |
-
|
| 38 |
-
|
| 39 |
-
|
|
| 40 |
-
|
|
| 41 |
-
| `v0.2.
|
| 42 |
-
| `v0.2.
|
| 43 |
-
| `v0.2.
|
| 44 |
-
| `v0.
|
| 45 |
-
| `v0.
|
| 46 |
-
|
| 47 |
-
|
| 48 |
-
|
| 49 |
-
|
| 50 |
-
|
| 51 |
-
|
| 52 |
-
|
| 53 |
-
|
| 54 |
-
|
| 55 |
-
|
| 56 |
-
|
| 57 |
-
|
| 58 |
-
|
| 59 |
-
|
| 60 |
-
|
| 61 |
-
|
| 62 |
-
|
| 63 |
-
|
| 64 |
-
|
| 65 |
-
|
| 66 |
-
|
| 67 |
-
|
| 68 |
-
|
| 69 |
-
|
| 70 |
-
|
| 71 |
-
|
| 72 |
-
|
| 73 |
-
|
| 74 |
-
|
| 75 |
-
|
| 76 |
-
|
| 77 |
-
|
| 78 |
-
|
| 79 |
-
|
| 80 |
-
|
| 81 |
-
|
| 82 |
-
|
| 83 |
-
|
| 84 |
-
|
| 85 |
-
|
| 86 |
-
|
| 87 |
-
|
| 88 |
-
|
| 89 |
-
|
| 90 |
-
|
| 91 |
-
|
| 92 |
-
|
| 93 |
-
|
| 94 |
-
|
| 95 |
-
|
| 96 |
-
|
| 97 |
-
|
| 98 |
-
|
| 99 |
-
|
| 100 |
-
|
| 101 |
-
|
| 102 |
-
|
| 103 |
-
|
| 104 |
-
|
| 105 |
-
|
| 106 |
-
|
| 107 |
-
|
| 108 |
-
|
| 109 |
-
##
|
| 110 |
-
|
| 111 |
-
|
| 112 |
-
|
| 113 |
-
|
| 114 |
-
|
| 115 |
-
|
| 116 |
-
|
| 117 |
-
|
| 118 |
-
|
| 119 |
-
|
| 120 |
-
|
| 121 |
-
|
| 122 |
-
|
| 123 |
-
|
| 124 |
-
|
| 125 |
-
|
| 126 |
-
|
| 127 |
-
|
| 128 |
-
|
| 129 |
-
|
| 130 |
-
|
| 131 |
-
|
| 132 |
-
|
| 133 |
-
|
| 134 |
-
|
| 135 |
-
|
| 136 |
-
|
| 137 |
-
|
| 138 |
-
|
| 139 |
-
|
| 140 |
-
|
| 141 |
-
|
| 142 |
-
|
| 143 |
-
|
| 144 |
-
|
| 145 |
-
|
| 146 |
-
|
| 147 |
-
|
| 148 |
-
|
| 149 |
-
|
| 150 |
-
|
| 151 |
-
|
| 152 |
-
|
| 153 |
-
|
| 154 |
-
|
| 155 |
-
|
| 156 |
-
|
| 157 |
-
|
| 158 |
-
|
| 159 |
-
|
| 160 |
-
|
| 161 |
-
|
| 162 |
-
|
| 163 |
-
|
| 164 |
-
|
| 165 |
-
| source |
|
| 166 |
-
|---|---|
|
| 167 |
-
|
|
| 168 |
-
|
|
| 169 |
-
|
|
| 170 |
-
|
| 171 |
-
|
| 172 |
-
|
| 173 |
-
|
| 174 |
-
|
| 175 |
-
|
| 176 |
-
|
| 177 |
-
|
| 178 |
-
|
| 179 |
-
|
| 180 |
-
|
| 181 |
-
|
| 182 |
-
|
| 183 |
-
|
| 184 |
-
|
| 185 |
-
|
| 186 |
-
|
| 187 |
-
|
| 188 |
-
|
| 189 |
-
|
| 190 |
-
|
| 191 |
-
|
| 192 |
-
|
| 193 |
-
|
| 194 |
-
|
| 195 |
-
|
| 196 |
-
|
| 197 |
-
|
| 198 |
-
|
| 199 |
-
|
| 200 |
-
|
| 201 |
-
|
| 202 |
-
|
| 203 |
-
|
| 204 |
-
|
| 205 |
-
|
| 206 |
-
|
| 207 |
-
|
| 208 |
-
|
| 209 |
-
|
| 210 |
-
|
| 211 |
-
|
| 212 |
-
|
| 213 |
-
|
| 214 |
-
|
| 215 |
-
|
| 216 |
-
|
| 217 |
-
-
|
| 218 |
-
|
| 219 |
-
|
| 220 |
-
|
| 221 |
-
|
| 222 |
-
|
| 223 |
-
|
| 224 |
-
|
| 225 |
-
|
| 226 |
-
|
| 227 |
-
|
| 228 |
-
|
| 229 |
-
|
| 230 |
-
|
| 231 |
-
|
| 232 |
-
|
| 233 |
-
|
| 234 |
-
|
| 235 |
-
|
| 236 |
-
|
| 237 |
-
|
| 238 |
-
|
| 239 |
-
|
| 240 |
-
|
| 241 |
-
|
| 242 |
-
|
| 243 |
-
|
| 244 |
-
|
| 245 |
-
|
| 246 |
-
|
| 247 |
-
|
| 248 |
-
|
| 249 |
-
|
|
| 250 |
-
|
|
| 251 |
-
| `
|
| 252 |
-
| `
|
| 253 |
-
| `
|
| 254 |
-
| `
|
| 255 |
-
|
| 256 |
-
|
| 257 |
-
|
| 258 |
-
|
| 259 |
-
|
| 260 |
-
|
| 261 |
-
|
| 262 |
-
|
| 263 |
-
|
| 264 |
-
|
| 265 |
-
|
| 266 |
-
|
| 267 |
-
|
| 268 |
-
|
| 269 |
-
|
| 270 |
-
|
| 271 |
-
|
| 272 |
-
|
| 273 |
-
|
| 274 |
-
|
| 275 |
-
|
| 276 |
-
|
| 277 |
-
|
| 278 |
-
|
| 279 |
-
|
| 280 |
-
|
| 281 |
-
|
| 282 |
-
|
| 283 |
-
|
| 284 |
-
|
| 285 |
-
|
| 286 |
-
|
| 287 |
-
|
| 288 |
-
|
| 289 |
-
|
| 290 |
-
|
| 291 |
-
|
| 292 |
-
|
| 293 |
-
```
|
| 294 |
-
|
| 295 |
-
|
| 296 |
-
```
|
| 297 |
-
|
| 298 |
-
|
| 299 |
-
|
| 300 |
-
|
| 301 |
-
|
| 302 |
-
|
| 303 |
-
|
| 304 |
-
|
| 305 |
-
|
| 306 |
-
|
|
| 307 |
-
|
|
| 308 |
-
| `
|
| 309 |
-
| `
|
| 310 |
-
| `
|
| 311 |
-
| `
|
| 312 |
-
| `
|
| 313 |
-
| `
|
| 314 |
-
| `
|
| 315 |
-
| `
|
| 316 |
-
| `
|
| 317 |
-
|
| 318 |
-
|
| 319 |
-
|
| 320 |
-
|
|
| 321 |
-
|
|
| 322 |
-
| `
|
| 323 |
-
| `
|
| 324 |
-
| `
|
| 325 |
-
| `
|
| 326 |
-
| `
|
| 327 |
-
| `
|
| 328 |
-
| `
|
| 329 |
-
| `
|
| 330 |
-
| `
|
| 331 |
-
| `
|
| 332 |
-
| `
|
| 333 |
-
| `
|
| 334 |
-
| `
|
| 335 |
-
| `
|
| 336 |
-
| `
|
| 337 |
-
| `
|
| 338 |
-
| `
|
| 339 |
-
| `
|
| 340 |
-
| `
|
| 341 |
-
| `
|
| 342 |
-
| `
|
| 343 |
-
| `
|
| 344 |
-
| `
|
| 345 |
-
| `
|
| 346 |
-
| `
|
| 347 |
-
| `
|
| 348 |
-
| `
|
| 349 |
-
| `
|
| 350 |
-
| `
|
| 351 |
-
| `
|
| 352 |
-
| `
|
| 353 |
-
| `
|
| 354 |
-
|
| 355 |
-
|
| 356 |
-
|
| 357 |
-
|
| 358 |
-
|
| 359 |
-
|
| 360 |
-
|
| 361 |
-
|
| 362 |
-
|
| 363 |
-
|
| 364 |
-
|
| 365 |
-
|
| 366 |
-
| `eurlex` | `Dz.U.` | 915,707 | 0.03851% |
|
| 367 |
-
| `european_hplt_v3_pl` | `w roku` | 113,501 | 0.00444% |
|
| 368 |
-
| `european_hplt_v3_pl` | `klasyfikacji` | 24,675 | 0.00097% |
|
| 369 |
-
| `european_hplt_v3_pl` | `ustawa` | 16,067 | 0.00063% |
|
| 370 |
-
| `european_hplt_v3_pl` | `artykuł` | 283,875 | 0.01111% |
|
| 371 |
-
| `european_hplt_v3_pl` | `parlament` | 45,516 | 0.00178% |
|
| 372 |
-
| `european_hplt_v3_pl` | `rozporządzenie` | 11,841 | 0.00046% |
|
| 373 |
-
| `european_hplt_v3_pl` | `w pobliżu` | 44,108 | 0.00173% |
|
| 374 |
-
| `european_hplt_v3_pl` | `mieszkańców` | 172,896 | 0.00677% |
|
| 375 |
-
| `european_hplt_v3_pl` | `Dz.U.` | 9,487 | 0.00037% |
|
| 376 |
-
| `global_voices` | `w roku` | 160 | 0.00431% |
|
| 377 |
-
| `global_voices` | `klasyfikacji` | 5 | 0.00013% |
|
| 378 |
-
| `global_voices` | `ustawa` | 157 | 0.00423% |
|
| 379 |
-
| `global_voices` | `artykuł` | 1,047 | 0.02818% |
|
| 380 |
-
| `global_voices` | `parlament` | 366 | 0.00985% |
|
| 381 |
-
| `global_voices` | `rozporządzenie` | 26 | 0.00070% |
|
| 382 |
-
| `global_voices` | `w pobliżu` | 105 | 0.00283% |
|
| 383 |
-
| `global_voices` | `mieszkańców` | 508 | 0.01367% |
|
| 384 |
-
| `global_voices` | `Dz.U.` | 1 | 0.00003% |
|
| 385 |
-
| `govpl` | `w roku` | 3,372 | 0.00418% |
|
| 386 |
-
| `govpl` | `klasyfikacji` | 526 | 0.00065% |
|
| 387 |
-
| `govpl` | `ustawa` | 4,727 | 0.00586% |
|
| 388 |
-
| `govpl` | `artykuł` | 2,417 | 0.00300% |
|
| 389 |
-
| `govpl` | `parlament` | 3,967 | 0.00492% |
|
| 390 |
-
| `govpl` | `rozporządzenie` | 4,102 | 0.00509% |
|
| 391 |
-
| `govpl` | `w pobliżu` | 892 | 0.00111% |
|
| 392 |
-
| `govpl` | `mieszkańców` | 13,105 | 0.01625% |
|
| 393 |
-
| `govpl` | `Dz.U.` | 3,114 | 0.00386% |
|
| 394 |
-
| `nkjp1m` | `w roku` | 109 | 0.00419% |
|
| 395 |
-
| `nkjp1m` | `klasyfikacji` | 9 | 0.00035% |
|
| 396 |
-
| `nkjp1m` | `ustawa` | 79 | 0.00304% |
|
| 397 |
-
| `nkjp1m` | `artykuł` | 153 | 0.00588% |
|
| 398 |
-
| `nkjp1m` | `parlament` | 216 | 0.00830% |
|
| 399 |
-
| `nkjp1m` | `rozporządzenie` | 20 | 0.00077% |
|
| 400 |
-
| `nkjp1m` | `w pobliżu` | 77 | 0.00296% |
|
| 401 |
-
| `nkjp1m` | `mieszkańców` | 159 | 0.00611% |
|
| 402 |
-
| `nkjp1m` | `Dz.U.` | 2 | 0.00008% |
|
| 403 |
-
| `parliamentary` | `w roku` | 198,192 | 0.01203% |
|
| 404 |
-
| `parliamentary` | `klasyfikacji` | 12,637 | 0.00077% |
|
| 405 |
-
| `parliamentary` | `ustawa` | 459,179 | 0.02788% |
|
| 406 |
-
| `parliamentary` | `artykuł` | 182,038 | 0.01105% |
|
| 407 |
-
| `parliamentary` | `parlament` | 309,695 | 0.01881% |
|
| 408 |
-
| `parliamentary` | `rozporządzenie` | 113,547 | 0.00689% |
|
| 409 |
-
| `parliamentary` | `w pobliżu` | 4,964 | 0.00030% |
|
| 410 |
-
| `parliamentary` | `mieszkańców` | 78,048 | 0.00474% |
|
| 411 |
-
| `parliamentary` | `Dz.U.` | 23,809 | 0.00145% |
|
| 412 |
-
| `samorzad_gov_pl` | `w roku` | 3,661 | 0.00890% |
|
| 413 |
-
| `samorzad_gov_pl` | `klasyfikacji` | 520 | 0.00126% |
|
| 414 |
-
| `samorzad_gov_pl` | `ustawa` | 1,823 | 0.00443% |
|
| 415 |
-
| `samorzad_gov_pl` | `artykuł` | 1,269 | 0.00308% |
|
| 416 |
-
| `samorzad_gov_pl` | `parlament` | 1,218 | 0.00296% |
|
| 417 |
-
| `samorzad_gov_pl` | `rozporządzenie` | 1,409 | 0.00342% |
|
| 418 |
-
| `samorzad_gov_pl` | `w pobliżu` | 401 | 0.00097% |
|
| 419 |
-
| `samorzad_gov_pl` | `mieszkańców` | 14,450 | 0.03511% |
|
| 420 |
-
| `samorzad_gov_pl` | `Dz.U.` | 1,380 | 0.00335% |
|
| 421 |
-
| `wikibooks` | `w roku` | 319 | 0.00205% |
|
| 422 |
-
| `wikibooks` | `klasyfikacji` | 37 | 0.00024% |
|
| 423 |
-
| `wikibooks` | `ustawa` | 165 | 0.00106% |
|
| 424 |
-
| `wikibooks` | `artykuł` | 732 | 0.00470% |
|
| 425 |
-
| `wikibooks` | `parlament` | 283 | 0.00182% |
|
| 426 |
-
| `wikibooks` | `rozporządzenie` | 131 | 0.00084% |
|
| 427 |
-
| `wikibooks` | `w pobliżu` | 125 | 0.00080% |
|
| 428 |
-
| `wikibooks` | `mieszkańców` | 204 | 0.00131% |
|
| 429 |
-
| `wikibooks` | `Dz.U.` | 16 | 0.00010% |
|
| 430 |
-
| `wikinews` | `w roku` | 449 | 0.00370% |
|
| 431 |
-
| `wikinews` | `klasyfikacji` | 639 | 0.00526% |
|
| 432 |
-
| `wikinews` | `ustawa` | 407 | 0.00335% |
|
| 433 |
-
| `wikinews` | `artykuł` | 2,474 | 0.02038% |
|
| 434 |
-
| `wikinews` | `parlament` | 2,530 | 0.02084% |
|
| 435 |
-
| `wikinews` | `rozporządzenie` | 168 | 0.00138% |
|
| 436 |
-
| `wikinews` | `w pobliżu` | 455 | 0.00375% |
|
| 437 |
-
| `wikinews` | `mieszkańców` | 1,014 | 0.00835% |
|
| 438 |
-
| `wikinews` | `Dz.U.` | 27 | 0.00022% |
|
| 439 |
-
| `wikipedia` | `w roku` | 143,023 | 0.02022% |
|
| 440 |
-
| `wikipedia` | `klasyfikacji` | 46,043 | 0.00651% |
|
| 441 |
-
| `wikipedia` | `ustawa` | 9,536 | 0.00135% |
|
| 442 |
-
| `wikipedia` | `artykuł` | 28,165 | 0.00398% |
|
| 443 |
-
| `wikipedia` | `parlament` | 57,863 | 0.00818% |
|
| 444 |
-
| `wikipedia` | `rozporządzenie` | 5,637 | 0.00080% |
|
| 445 |
-
| `wikipedia` | `w pobliżu` | 41,915 | 0.00593% |
|
| 446 |
-
| `wikipedia` | `mieszkańców` | 122,766 | 0.01736% |
|
| 447 |
-
| `wikipedia` | `Dz.U.` | 232 | 0.00003% |
|
| 448 |
-
| `wikiquote` | `w roku` | 608 | 0.00191% |
|
| 449 |
-
| `wikiquote` | `klasyfikacji` | 15 | 0.00005% |
|
| 450 |
-
| `wikiquote` | `ustawa` | 357 | 0.00112% |
|
| 451 |
-
| `wikiquote` | `artykuł` | 606 | 0.00190% |
|
| 452 |
-
| `wikiquote` | `parlament` | 1,271 | 0.00398% |
|
| 453 |
-
| `wikiquote` | `rozporządzenie` | 27 | 0.00008% |
|
| 454 |
-
| `wikiquote` | `w pobliżu` | 207 | 0.00065% |
|
| 455 |
-
| `wikiquote` | `mieszkańców` | 527 | 0.00165% |
|
| 456 |
-
| `wikiquote` | `Dz.U.` | 6 | 0.00002% |
|
| 457 |
-
| `wikisource` | `w roku` | 16,571 | 0.00207% |
|
| 458 |
-
| `wikisource` | `klasyfikacji` | 166 | 0.00002% |
|
| 459 |
-
| `wikisource` | `ustawa` | 8,156 | 0.00102% |
|
| 460 |
-
| `wikisource` | `artykuł` | 16,230 | 0.00202% |
|
| 461 |
-
| `wikisource` | `parlament` | 6,119 | 0.00076% |
|
| 462 |
-
| `wikisource` | `rozporządzenie` | 1,651 | 0.00021% |
|
| 463 |
-
| `wikisource` | `w pobliżu` | 13,921 | 0.00174% |
|
| 464 |
-
| `wikisource` | `mieszkańców` | 14,335 | 0.00179% |
|
| 465 |
-
| `wikisource` | `Dz.U.` | 5 | 0.00000% |
|
| 466 |
-
| `wikivoyage` | `w roku` | 609 | 0.00356% |
|
| 467 |
-
| `wikivoyage` | `klasyfikacji` | 21 | 0.00012% |
|
| 468 |
-
| `wikivoyage` | `ustawa` | 46 | 0.00027% |
|
| 469 |
-
| `wikivoyage` | `artykuł` | 657 | 0.00384% |
|
| 470 |
-
| `wikivoyage` | `parlament` | 249 | 0.00145% |
|
| 471 |
-
| `wikivoyage` | `rozporządzenie` | 34 | 0.00020% |
|
| 472 |
-
| `wikivoyage` | `w pobliżu` | 6,480 | 0.03783% |
|
| 473 |
-
| `wikivoyage` | `mieszkańców` | 4,100 | 0.02394% |
|
| 474 |
-
| `wikivoyage` | `Dz.U.` | 1 | 0.00001% |
|
| 475 |
-
| `wolne_lektury` | `w roku` | 1,898 | 0.00184% |
|
| 476 |
-
| `wolne_lektury` | `klasyfikacji` | 80 | 0.00008% |
|
| 477 |
-
| `wolne_lektury` | `ustawa` | 1,060 | 0.00103% |
|
| 478 |
-
| `wolne_lektury` | `artykuł` | 1,824 | 0.00177% |
|
| 479 |
-
| `wolne_lektury` | `parlament` | 672 | 0.00065% |
|
| 480 |
-
| `wolne_lektury` | `rozporządzenie` | 128 | 0.00012% |
|
| 481 |
-
| `wolne_lektury` | `w pobliżu` | 2,073 | 0.00201% |
|
| 482 |
-
| `wolne_lektury` | `mieszkańców` | 1,658 | 0.00161% |
|
| 483 |
-
| `wolne_lektury` | `Dz.U.` | 5 | 0.00000% |
|
| 484 |
-
|
| 485 |
-

|
| 486 |
-
|
| 487 |
-

|
| 488 |
-

|
| 489 |
-

|
| 490 |
-

|
| 491 |
-

|
| 492 |
-

|
| 493 |
-

|
| 494 |
-

|
| 495 |
-

|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: cc-by-sa-4.0
|
| 3 |
+
language:
|
| 4 |
+
- pl
|
| 5 |
+
pretty_name: Polish DynaWord
|
| 6 |
+
task_categories:
|
| 7 |
+
- text-generation
|
| 8 |
+
size_categories:
|
| 9 |
+
- 1M<n<10M
|
| 10 |
+
tags:
|
| 11 |
+
- polish
|
| 12 |
+
- pretraining
|
| 13 |
+
- dynaword
|
| 14 |
+
---
|
| 15 |
+
|
| 16 |
+
# Polish DynaWord
|
| 17 |
+
|
| 18 |
+
A continuously developed, **openly-licensed**, human-text Polish corpus — a Polish
|
| 19 |
+
edition in the [Dynaword](https://huggingface.co/datasets/danish-foundation-models/danish-dynaword)
|
| 20 |
+
family (Enevoldsen et al., [arXiv:2508.02271](https://arxiv.org/abs/2508.02271)).
|
| 21 |
+
|
| 22 |
+
> **v0.2.2 stable** · 2,579,963 documents · **6.36B tokens**
|
| 23 |
+
> (tiktoken proxy; canonical Llama-3 count at release) · 13 sources
|
| 24 |
+
> Updated: **2026-07-19**
|
| 25 |
+
|
| 26 |
+
> **v0.3.0-preview validation release** · live source-gate validation for
|
| 27 |
+
> SpeakLeash shards and direct Europeana candidate data, plus the quality/diversity
|
| 28 |
+
> remix workflow. This is candidate-only metadata and audit work: it does not
|
| 29 |
+
> replace the v0.2.1 stable parquets.
|
| 30 |
+
|
| 31 |
+
> **v0.3.1-preview** · first reproducible Europeana direct-ingestion shard:
|
| 32 |
+
> 1,000 API records → 810 quality-gated parquet documents, each preserving
|
| 33 |
+
> per-record rights and creator metadata. Stored separately under
|
| 34 |
+
> `previews/v0.3.1/europeana.parquet`; the paged Search API run took 59.4 s and
|
| 35 |
+
> does not alter v0.2.1 stable totals.
|
| 36 |
+
|
| 37 |
+
## Versions
|
| 38 |
+
|
| 39 |
+
| version | status | documents | tokens | notes |
|
| 40 |
+
|---|---|---:|---:|---|
|
| 41 |
+
| `v0.2.2` | stable release | 2,579,963 | 6.36B | Adds `govpl` (gov.pl government press releases, CC-BY-SA-4.0): 88,190 docs / 80.7M tokens fetched directly across 133 ministry/agency subsites. |
|
| 42 |
+
| `v0.2.1` | previous stable | 2,491,773 | 6.28B | 12-source stable corpus with `license` and `author` metadata columns; adds `1000_novels`. |
|
| 43 |
+
| `v0.2.0` | previous stable | 2,490,773 | 6.22B | Provenance-first corpus from 11 open/official sources. |
|
| 44 |
+
| `v0.3.0-preview` | validation release, candidate-only | candidate-only | TBD | Live source gates validated; Biblioteka Nauki, Europeana, and HPLT/Common Corpus expansion remain subject to per-source QA, dedup, and legal review. |
|
| 45 |
+
| `v0.3.1-preview` | reproducible Europeana shard | 810 | 140,042 | 1,000 direct API records sampled; 810 passed short/language/OCR gates, with per-record rights and author metadata. |
|
| 46 |
+
|
| 47 |
+
## What this dataset contributes
|
| 48 |
+
The raw texts come from existing open corpora (redistributed via SpeakLeash and,
|
| 49 |
+
where applicable, fetched from upstream). **The value added here is the curation,
|
| 50 |
+
not the bytes**, following the Dynaword methodology:
|
| 51 |
+
|
| 52 |
+
1. **License review per source** — each source vetted for an *openly-licensed,
|
| 53 |
+
traceable* legal basis (documented in its datasheet); sources that fail the
|
| 54 |
+
review are **excluded with a stated reason** (see table below), not silently
|
| 55 |
+
kept. This is the core editorial work.
|
| 56 |
+
2. **Filtering & normalization** — minimal, reproducible gates (short-doc,
|
| 57 |
+
non-Polish, exact cross-source dedup, OCR garble) applied uniformly to one
|
| 58 |
+
clean schema: `id, text, source, added, created, token_count, license, author`.
|
| 59 |
+
3. **Documentation** — a datasheet per source (Gebru et al. 2021) + this card,
|
| 60 |
+
so provenance and licensing are auditable rather than assumed.
|
| 61 |
+
4. **Reproducibility & versioning** — `src/` rebuilds the corpus from sources;
|
| 62 |
+
new sources and removals are tracked in the CHANGELOG.
|
| 63 |
+
|
| 64 |
+
Credit for the underlying texts belongs to the upstream sources and to SpeakLeash
|
| 65 |
+
as the redistributing aggregator; this release does not claim ownership of them
|
| 66 |
+
(see Disclaimer).
|
| 67 |
+
|
| 68 |
+
## Contributors
|
| 69 |
+
|
| 70 |
+
- **Kacper Wikieł** — corpus curation, release engineering, documentation, and
|
| 71 |
+
reproducible build workflow.
|
| 72 |
+
- **Bart Kobyliński** — source expansion work for Biblioteka Nauki and Europeana,
|
| 73 |
+
including per-document license/author metadata collection and rebuild planning.
|
| 74 |
+
|
| 75 |
+
## Guiding principles
|
| 76 |
+
1. **Open & traceable licensing** — every source is *openly licensed* with a documented
|
| 77 |
+
legal basis (see each datasheet's "traceable basis"), not a vague "public domain".
|
| 78 |
+
2. **Reproducibility** — `src/build_dynaword.py` rebuilds the corpus from sources.
|
| 79 |
+
3. **Documented** — a datasheet per source under `data/<source>/`.
|
| 80 |
+
4. **Extensibility** — versioned; new sources via PR.
|
| 81 |
+
|
| 82 |
+
## Sources
|
| 83 |
+
| source | description | license | documents | tokens |
|
| 84 |
+
|---|---|---|---:|---:|
|
| 85 |
+
| [eurlex](data/eurlex/eurlex.md) | EUR-Lex (EU legal acts, Polish) | `CC-BY-4.0` | 243,060 | 2,378.1M |
|
| 86 |
+
| [parliamentary](data/parliamentary/parliamentary.md) | Polish Parliamentary Corpus (Sejm/Senat) | `public-domain (official documents)` | 324,622 | 1,646.8M |
|
| 87 |
+
| [wikisource](data/wikisource/wikisource.md) | Polish Wikisource | `CC-BY-SA-3.0` | 632,005 | 801.9M |
|
| 88 |
+
| [wikipedia](data/wikipedia/wikipedia.md) | Polish Wikipedia | `CC-BY-SA-3.0` | 1,171,897 | 707.2M |
|
| 89 |
+
| [dziennik_ustaw](data/dziennik_ustaw/dziennik_ustaw.md) | Dziennik Ustaw + Monitor Polski (Polish primary legislation) | `public-domain (official documents)` | 35,442 | 486.1M |
|
| 90 |
+
| [wolne_lektury](data/wolne_lektury/wolne_lektury.md) | Wolne Lektury (school readings) | `CC-BY-SA-4.0 / Wolna Sztuka 1.3` | 6,141 | 103.0M |
|
| 91 |
+
| [govpl](data/govpl/govpl.md) | gov.pl — Polish government press releases | `CC-BY-SA-4.0` | 88,190 | 80.7M |
|
| 92 |
+
| [1000_novels](data/1000_novels/1000_novels.md) | 1000 Novels Corpus (CLARIN-PL) | `CC-BY-4.0` | 1,000 | 60.5M |
|
| 93 |
+
| [wikiquote](data/wikiquote/wikiquote.md) | Polish Wikiquote (quotations) | `CC-BY-SA-3.0` | 30,363 | 31.9M |
|
| 94 |
+
| [eltec_pol](data/eltec_pol/eltec_pol.md) | ELTeC-pol (European Literary Text Collection, Polish) | `CC-BY-4.0` | 100 | 21.5M |
|
| 95 |
+
| [wikivoyage](data/wikivoyage/wikivoyage.md) | Polish Wikivoyage (travel guides) | `CC-BY-SA-3.0` | 13,645 | 17.1M |
|
| 96 |
+
| [wikibooks](data/wikibooks/wikibooks.md) | Polish Wikibooks (open textbooks) | `CC-BY-SA-3.0` | 9,112 | 15.6M |
|
| 97 |
+
| [wikinews](data/wikinews/wikinews.md) | Polish Wikinews | `CC-BY-2.5` | 24,386 | 12.1M |
|
| 98 |
+
| **total** | | | **2,579,963** | **6,362.6M** |
|
| 99 |
+
|
| 100 |
+
## Method
|
| 101 |
+
Only **human-authored** text — no synthetic, machine-translated, or auto-transcribed
|
| 102 |
+
data. Gates are intentionally minimal (drop short docs, non-Polish, exact duplicates,
|
| 103 |
+
OCR garble); heavy quality filtering and mix-weighting are left to downstream training.
|
| 104 |
+
Evaluation-set decontamination is applied/marked separately. Schema:
|
| 105 |
+
`id, text, source, added, created, token_count, license, author`. The `license`
|
| 106 |
+
and `author` columns are per-document metadata when upstream exposes them; older
|
| 107 |
+
sources use the source-level license and an empty author field.
|
| 108 |
+
|
| 109 |
+
## v0.3 quality roadmap and current status
|
| 110 |
+
|
| 111 |
+
The v0.2.x raw corpus is intentionally provenance-first, but its token mix is too
|
| 112 |
+
heavy in legal/parliamentary language for natural general pretraining. The v0.3
|
| 113 |
+
workflow therefore separates **source inclusion** from **training mix**:
|
| 114 |
+
|
| 115 |
+
- cap `eurlex + parliamentary + dziennik_ustaw` to roughly **10-20%** of training
|
| 116 |
+
tokens combined;
|
| 117 |
+
- use source-level temperature sampling (`sqrt`, alpha `0.5`) instead of raw
|
| 118 |
+
token-proportional sampling;
|
| 119 |
+
- add traceably licensed contemporary/natural Polish: open web, academic prose,
|
| 120 |
+
cultural heritage text, guides, technical documentation/blogs, Q&A, and
|
| 121 |
+
dialogue/instruction data;
|
| 122 |
+
- run aggressive exact, normalized, and near-duplicate removal;
|
| 123 |
+
- reserve the final **5-15%** of training for higher-quality sources rather than
|
| 124 |
+
the largest sources;
|
| 125 |
+
- evaluate per-source perplexity and style contamination, not only global loss.
|
| 126 |
+
|
| 127 |
+
Current v0.3 source-ingestion status:
|
| 128 |
+
|
| 129 |
+
- `biblioteka_nauki`: prepared in the source registry as a direct-upstream
|
| 130 |
+
rebuild target with per-document license and author metadata. A live probe
|
| 131 |
+
currently returns HTTP 500 and zero records, so it is **not included** in
|
| 132 |
+
v0.2.1 or the v0.3 preview candidate data.
|
| 133 |
+
- `europeana`: prepared in the source registry as a direct-upstream rebuild
|
| 134 |
+
target with per-record rights statements and creator metadata. A 200-record
|
| 135 |
+
live direct-rebuild audit found 197 Public Domain Mark records and three
|
| 136 |
+
CC-BY-SA-4.0 records; all passed the blocking schema, license, duplicate and
|
| 137 |
+
evaluation-overlap gates. It remains candidate-only until a complete rebuild,
|
| 138 |
+
date split, and legal review are complete. Raw SpeakLeash Europeana remains
|
| 139 |
+
excluded.
|
| 140 |
+
- Local SpeakLeash shard audit: 12 reviewed source shards were sampled directly
|
| 141 |
+
from the live `.jsonl.zst` inputs and passed the blocking gates; four shards
|
| 142 |
+
are explicitly excluded (`open_subtitles_corpus`, raw Europeana,
|
| 143 |
+
`1000_novels_corpus_CLARIN-PL`, `project_gutenberg_pl_corpus`) and two talk
|
| 144 |
+
shards remain on hold pending a separate source policy. The audit mechanism is
|
| 145 |
+
aligned with [slayer-dsbench](https://github.com/slayerlabs/slayer-dsbench).
|
| 146 |
+
- Europeana release policy: split conservatively at pre-1929 records for
|
| 147 |
+
US-sensitive downstream reuse, and keep later/unknown records separately
|
| 148 |
+
labeled or held until legal review.
|
| 149 |
+
- `ashtok897/european-hplt-v1`: candidate workflow exists, but web-crawl
|
| 150 |
+
provenance, dedup, QA, and final mix weighting are still pending before stable
|
| 151 |
+
inclusion.
|
| 152 |
+
|
| 153 |
+
Current review artifacts:
|
| 154 |
+
|
| 155 |
+
- `configs/source_candidates_v0_3.json` — candidate decisions and license policy.
|
| 156 |
+
- `artifacts/source_license_review_v0_3.md` — source-by-source license review.
|
| 157 |
+
- `artifacts/source_candidate_audit_v0_3.md` — generated Hugging Face metadata audit.
|
| 158 |
+
- `artifacts/training_mix_v0_3.md` — example 1B-token training mix with legal sources capped at 15%.
|
| 159 |
+
- `artifacts/bartek_source_ingestion_plan_2026-07-02.md` — PR contract for
|
| 160 |
+
Biblioteka Nauki and Europeana ingestion.
|
| 161 |
+
|
| 162 |
+
## Excluded sources (transparency)
|
| 163 |
+
Sources we reviewed and **deliberately left out** — part of the curation:
|
| 164 |
+
|
| 165 |
+
| source | reason |
|
| 166 |
+
|---|---|
|
| 167 |
+
| `open_subtitles_corpus` | Derivative of copyrighted film/TV dialogue; OpenSubtitles uploads largely unlicensed. Same copyright lesson as Danish Gigaword's OpenSubtitles (paper 2508.02271). Not openly licensed. |
|
| 168 |
+
| `europeana_eu_pl_corpus_raw_speakleash` | Aggregated items with mixed per-record rights (PD / CC-BY-NC / rights-reserved). The raw SpeakLeash redistribution is excluded; only a direct rebuild preserving per-record rights metadata may be included. |
|
| 169 |
+
| `project_gutenberg_pl_corpus` | Only 31 PL books (4.3MB) — PG is ~99% English; Polish PD literature already covered by wolne_lektury + wikisource (so near-redundant after dedup). Dropped to avoid the PD-in-EU per-work check (PG claims PD-in-US only) for negligible token gain. |
|
| 170 |
+
|
| 171 |
+
## Personal & sensitive data
|
| 172 |
+
This corpus contains **only** text that its upstream sources already published
|
| 173 |
+
under open licenses or as official public-domain record. It therefore includes
|
| 174 |
+
names and statements of **public figures acting in a public capacity** — e.g.
|
| 175 |
+
parliamentary speakers (PPC), authorities named in legal acts (EUR-Lex), and
|
| 176 |
+
people described in encyclopedic articles (Wikipedia/Wikisource). No private,
|
| 177 |
+
non-public personal data was collected or added. If you are a data subject and
|
| 178 |
+
want content concerning you removed, contact **k.wikiel@gmail.com** — it will be dropped
|
| 179 |
+
from the next version (see retroactive-removal policy below).
|
| 180 |
+
|
| 181 |
+
## Disclaimer & legal
|
| 182 |
+
- **Provenance in good faith.** Per-source licenses are reproduced *as documented
|
| 183 |
+
by the upstream sources and by SpeakLeash* (the intermediate aggregator), to the
|
| 184 |
+
best of our knowledge. We make no independent legal warranty about the copyright
|
| 185 |
+
status of any individual document.
|
| 186 |
+
- **No ownership claim.** This release is a *curated, license-reviewed, documented
|
| 187 |
+
aggregation*. We claim no ownership of the underlying texts; rights remain with
|
| 188 |
+
the original authors/rightsholders under their respective licenses.
|
| 189 |
+
- **Provided "as is"**, without warranty of any kind, express or implied. This is
|
| 190 |
+
not legal advice.
|
| 191 |
+
- **Your compliance is yours.** Downstream users must satisfy each upstream
|
| 192 |
+
license themselves — in particular **CC-BY-SA-4.0 attribution and share-alike**
|
| 193 |
+
for derivatives of this dataset, and attribution to the upstream sources and to
|
| 194 |
+
SpeakLeash.
|
| 195 |
+
- **Notice-and-takedown.** Any source or rightsholder raising a substantiated
|
| 196 |
+
objection can have material removed: contact **k.wikiel@gmail.com**; it is dropped from
|
| 197 |
+
the next version and recorded in the CHANGELOG. Removal is retroactive
|
| 198 |
+
going-forward (prior immutable snapshots/commits may persist).
|
| 199 |
+
|
| 200 |
+
## License & attribution
|
| 201 |
+
Released under **CC-BY-SA-4.0** (copyleft inherited from CC-BY-SA sources such as
|
| 202 |
+
Wikipedia/Wikisource/Wolne Lektury). Attribution due to each upstream (see datasheets)
|
| 203 |
+
and to **SpeakLeash** as the intermediate aggregator. Retroactive-removal policy: a
|
| 204 |
+
source that raises an objection is dropped from subsequent versions, recorded in the
|
| 205 |
+
CHANGELOG.
|
| 206 |
+
|
| 207 |
+
## Reproduce
|
| 208 |
+
```bash
|
| 209 |
+
python3 src/build_dynaword.py --all --speakleash-dir <speakleash_zst_dir> --out .
|
| 210 |
+
python3 src/make_docs.py
|
| 211 |
+
```
|
| 212 |
+
|
| 213 |
+
## Results
|
| 214 |
+
|
| 215 |
+
### Corpus phrase frequency (normalized by tokens)
|
| 216 |
+
|
| 217 |
+
Raw counts and token-normalized shares are regenerated from the current parquet files with `src/pattern_frequency_report.py`.
|
| 218 |
+
|
| 219 |
+
- Total token count (tiktoken proxy): **6,362,577,363**
|
| 220 |
+
|
| 221 |
+
| Pattern | Count | Share of all tokens |
|
| 222 |
+
|---|---:|---:|
|
| 223 |
+
| `w roku` | 438,913 | 0.0069% |
|
| 224 |
+
| `klasyfikacji` | 130,503 | 0.0021% |
|
| 225 |
+
| `ustawa` | 592,186 | 0.0093% |
|
| 226 |
+
| `artykuł` | 2,038,776 | 0.0320% |
|
| 227 |
+
| `parlament` | 1,205,608 | 0.0189% |
|
| 228 |
+
| `rozporządzenie` | 1,494,566 | 0.0235% |
|
| 229 |
+
| `w pobliżu` | 79,715 | 0.0013% |
|
| 230 |
+
| `mieszkańców` | 254,305 | 0.0040% |
|
| 231 |
+
| `Dz.U.` | 943,080 | 0.0148% |
|
| 232 |
+
|
| 233 |
+
### Per-source shares
|
| 234 |
+
|
| 235 |
+
| source | pattern | count | share of source tokens |
|
| 236 |
+
|---|---|---:|---:|
|
| 237 |
+
| `1000_novels` | `w roku` | 659 | 0.00109% |
|
| 238 |
+
| `1000_novels` | `klasyfikacji` | 14 | 0.00002% |
|
| 239 |
+
| `1000_novels` | `ustawa` | 656 | 0.00108% |
|
| 240 |
+
| `1000_novels` | `artykuł` | 729 | 0.00120% |
|
| 241 |
+
| `1000_novels` | `parlament` | 240 | 0.00040% |
|
| 242 |
+
| `1000_novels` | `rozporządzenie` | 65 | 0.00011% |
|
| 243 |
+
| `1000_novels` | `w pobliżu` | 1,262 | 0.00209% |
|
| 244 |
+
| `1000_novels` | `mieszkańców` | 868 | 0.00143% |
|
| 245 |
+
| `1000_novels` | `Dz.U.` | 0 | 0.00000% |
|
| 246 |
+
| `dziennik_ustaw` | `w roku` | 33,096 | 0.00681% |
|
| 247 |
+
| `dziennik_ustaw` | `klasyfikacji` | 10,896 | 0.00224% |
|
| 248 |
+
| `dziennik_ustaw` | `ustawa` | 77,376 | 0.01592% |
|
| 249 |
+
| `dziennik_ustaw` | `artykuł` | 27,773 | 0.00571% |
|
| 250 |
+
| `dziennik_ustaw` | `parlament` | 42,338 | 0.00871% |
|
| 251 |
+
| `dziennik_ustaw` | `rozporządzenie` | 166,383 | 0.03423% |
|
| 252 |
+
| `dziennik_ustaw` | `w pobliżu` | 1,087 | 0.00022% |
|
| 253 |
+
| `dziennik_ustaw` | `mieszkańców` | 8,025 | 0.00165% |
|
| 254 |
+
| `dziennik_ustaw` | `Dz.U.` | 158 | 0.00003% |
|
| 255 |
+
| `eltec_pol` | `w roku` | 108 | 0.00050% |
|
| 256 |
+
| `eltec_pol` | `klasyfikacji` | 1 | 0.00000% |
|
| 257 |
+
| `eltec_pol` | `ustawa` | 153 | 0.00071% |
|
| 258 |
+
| `eltec_pol` | `artykuł` | 173 | 0.00081% |
|
| 259 |
+
| `eltec_pol` | `parlament` | 95 | 0.00044% |
|
| 260 |
+
| `eltec_pol` | `rozporządzenie` | 35 | 0.00016% |
|
| 261 |
+
| `eltec_pol` | `w pobliżu` | 246 | 0.00114% |
|
| 262 |
+
| `eltec_pol` | `mieszkańców` | 214 | 0.00100% |
|
| 263 |
+
| `eltec_pol` | `Dz.U.` | 0 | 0.00000% |
|
| 264 |
+
| `eurlex` | `w roku` | 40,009 | 0.00168% |
|
| 265 |
+
| `eurlex` | `klasyfikacji` | 59,428 | 0.00250% |
|
| 266 |
+
| `eurlex` | `ustawa` | 30,368 | 0.00128% |
|
| 267 |
+
| `eurlex` | `artykuł` | 1,774,958 | 0.07464% |
|
| 268 |
+
| `eurlex` | `parlament` | 780,286 | 0.03281% |
|
| 269 |
+
| `eurlex` | `rozporządzenie` | 1,202,658 | 0.05057% |
|
| 270 |
+
| `eurlex` | `w pobliżu` | 6,088 | 0.00026% |
|
| 271 |
+
| `eurlex` | `mieszkańców` | 9,441 | 0.00040% |
|
| 272 |
+
| `eurlex` | `Dz.U.` | 915,707 | 0.03851% |
|
| 273 |
+
| `govpl` | `w roku` | 3,372 | 0.00418% |
|
| 274 |
+
| `govpl` | `klasyfikacji` | 526 | 0.00065% |
|
| 275 |
+
| `govpl` | `ustawa` | 4,727 | 0.00586% |
|
| 276 |
+
| `govpl` | `artykuł` | 2,417 | 0.00300% |
|
| 277 |
+
| `govpl` | `parlament` | 3,967 | 0.00492% |
|
| 278 |
+
| `govpl` | `rozporządzenie` | 4,102 | 0.00509% |
|
| 279 |
+
| `govpl` | `w pobliżu` | 892 | 0.00111% |
|
| 280 |
+
| `govpl` | `mieszkańców` | 13,105 | 0.01625% |
|
| 281 |
+
| `govpl` | `Dz.U.` | 3,114 | 0.00386% |
|
| 282 |
+
| `parliamentary` | `w roku` | 198,192 | 0.01203% |
|
| 283 |
+
| `parliamentary` | `klasyfikacji` | 12,637 | 0.00077% |
|
| 284 |
+
| `parliamentary` | `ustawa` | 459,179 | 0.02788% |
|
| 285 |
+
| `parliamentary` | `artykuł` | 182,038 | 0.01105% |
|
| 286 |
+
| `parliamentary` | `parlament` | 309,695 | 0.01881% |
|
| 287 |
+
| `parliamentary` | `rozporządzenie` | 113,547 | 0.00689% |
|
| 288 |
+
| `parliamentary` | `w pobliżu` | 4,964 | 0.00030% |
|
| 289 |
+
| `parliamentary` | `mieszkańców` | 78,048 | 0.00474% |
|
| 290 |
+
| `parliamentary` | `Dz.U.` | 23,809 | 0.00145% |
|
| 291 |
+
| `wikibooks` | `w roku` | 319 | 0.00205% |
|
| 292 |
+
| `wikibooks` | `klasyfikacji` | 37 | 0.00024% |
|
| 293 |
+
| `wikibooks` | `ustawa` | 165 | 0.00106% |
|
| 294 |
+
| `wikibooks` | `artykuł` | 732 | 0.00470% |
|
| 295 |
+
| `wikibooks` | `parlament` | 283 | 0.00182% |
|
| 296 |
+
| `wikibooks` | `rozporządzenie` | 131 | 0.00084% |
|
| 297 |
+
| `wikibooks` | `w pobliżu` | 125 | 0.00080% |
|
| 298 |
+
| `wikibooks` | `mieszkańców` | 204 | 0.00131% |
|
| 299 |
+
| `wikibooks` | `Dz.U.` | 16 | 0.00010% |
|
| 300 |
+
| `wikinews` | `w roku` | 449 | 0.00370% |
|
| 301 |
+
| `wikinews` | `klasyfikacji` | 639 | 0.00526% |
|
| 302 |
+
| `wikinews` | `ustawa` | 407 | 0.00335% |
|
| 303 |
+
| `wikinews` | `artykuł` | 2,474 | 0.02038% |
|
| 304 |
+
| `wikinews` | `parlament` | 2,530 | 0.02084% |
|
| 305 |
+
| `wikinews` | `rozporządzenie` | 168 | 0.00138% |
|
| 306 |
+
| `wikinews` | `w pobliżu` | 455 | 0.00375% |
|
| 307 |
+
| `wikinews` | `mieszkańców` | 1,014 | 0.00835% |
|
| 308 |
+
| `wikinews` | `Dz.U.` | 27 | 0.00022% |
|
| 309 |
+
| `wikipedia` | `w roku` | 143,023 | 0.02022% |
|
| 310 |
+
| `wikipedia` | `klasyfikacji` | 46,043 | 0.00651% |
|
| 311 |
+
| `wikipedia` | `ustawa` | 9,536 | 0.00135% |
|
| 312 |
+
| `wikipedia` | `artykuł` | 28,165 | 0.00398% |
|
| 313 |
+
| `wikipedia` | `parlament` | 57,863 | 0.00818% |
|
| 314 |
+
| `wikipedia` | `rozporządzenie` | 5,637 | 0.00080% |
|
| 315 |
+
| `wikipedia` | `w pobliżu` | 41,915 | 0.00593% |
|
| 316 |
+
| `wikipedia` | `mieszkańców` | 122,766 | 0.01736% |
|
| 317 |
+
| `wikipedia` | `Dz.U.` | 232 | 0.00003% |
|
| 318 |
+
| `wikiquote` | `w roku` | 608 | 0.00191% |
|
| 319 |
+
| `wikiquote` | `klasyfikacji` | 15 | 0.00005% |
|
| 320 |
+
| `wikiquote` | `ustawa` | 357 | 0.00112% |
|
| 321 |
+
| `wikiquote` | `artykuł` | 606 | 0.00190% |
|
| 322 |
+
| `wikiquote` | `parlament` | 1,271 | 0.00398% |
|
| 323 |
+
| `wikiquote` | `rozporządzenie` | 27 | 0.00008% |
|
| 324 |
+
| `wikiquote` | `w pobliżu` | 207 | 0.00065% |
|
| 325 |
+
| `wikiquote` | `mieszkańców` | 527 | 0.00165% |
|
| 326 |
+
| `wikiquote` | `Dz.U.` | 6 | 0.00002% |
|
| 327 |
+
| `wikisource` | `w roku` | 16,571 | 0.00207% |
|
| 328 |
+
| `wikisource` | `klasyfikacji` | 166 | 0.00002% |
|
| 329 |
+
| `wikisource` | `ustawa` | 8,156 | 0.00102% |
|
| 330 |
+
| `wikisource` | `artykuł` | 16,230 | 0.00202% |
|
| 331 |
+
| `wikisource` | `parlament` | 6,119 | 0.00076% |
|
| 332 |
+
| `wikisource` | `rozporządzenie` | 1,651 | 0.00021% |
|
| 333 |
+
| `wikisource` | `w pobliżu` | 13,921 | 0.00174% |
|
| 334 |
+
| `wikisource` | `mieszkańców` | 14,335 | 0.00179% |
|
| 335 |
+
| `wikisource` | `Dz.U.` | 5 | 0.00000% |
|
| 336 |
+
| `wikivoyage` | `w roku` | 609 | 0.00356% |
|
| 337 |
+
| `wikivoyage` | `klasyfikacji` | 21 | 0.00012% |
|
| 338 |
+
| `wikivoyage` | `ustawa` | 46 | 0.00027% |
|
| 339 |
+
| `wikivoyage` | `artykuł` | 657 | 0.00384% |
|
| 340 |
+
| `wikivoyage` | `parlament` | 249 | 0.00145% |
|
| 341 |
+
| `wikivoyage` | `rozporządzenie` | 34 | 0.00020% |
|
| 342 |
+
| `wikivoyage` | `w pobliżu` | 6,480 | 0.03783% |
|
| 343 |
+
| `wikivoyage` | `mieszkańców` | 4,100 | 0.02394% |
|
| 344 |
+
| `wikivoyage` | `Dz.U.` | 1 | 0.00001% |
|
| 345 |
+
| `wolne_lektury` | `w roku` | 1,898 | 0.00184% |
|
| 346 |
+
| `wolne_lektury` | `klasyfikacji` | 80 | 0.00008% |
|
| 347 |
+
| `wolne_lektury` | `ustawa` | 1,060 | 0.00103% |
|
| 348 |
+
| `wolne_lektury` | `artykuł` | 1,824 | 0.00177% |
|
| 349 |
+
| `wolne_lektury` | `parlament` | 672 | 0.00065% |
|
| 350 |
+
| `wolne_lektury` | `rozporządzenie` | 128 | 0.00012% |
|
| 351 |
+
| `wolne_lektury` | `w pobliżu` | 2,073 | 0.00201% |
|
| 352 |
+
| `wolne_lektury` | `mieszkańców` | 1,658 | 0.00161% |
|
| 353 |
+
| `wolne_lektury` | `Dz.U.` | 5 | 0.00000% |
|
| 354 |
+
|
| 355 |
+

|
| 356 |
+
|
| 357 |
+

|
| 358 |
+

|
| 359 |
+

|
| 360 |
+

|
| 361 |
+

|
| 362 |
+

|
| 363 |
+

|
| 364 |
+

|
| 365 |
+

|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
artifacts/dataset_size_by_version.png
DELETED
Git LFS Details
|
artifacts/pattern_frequency_artykul.png
CHANGED
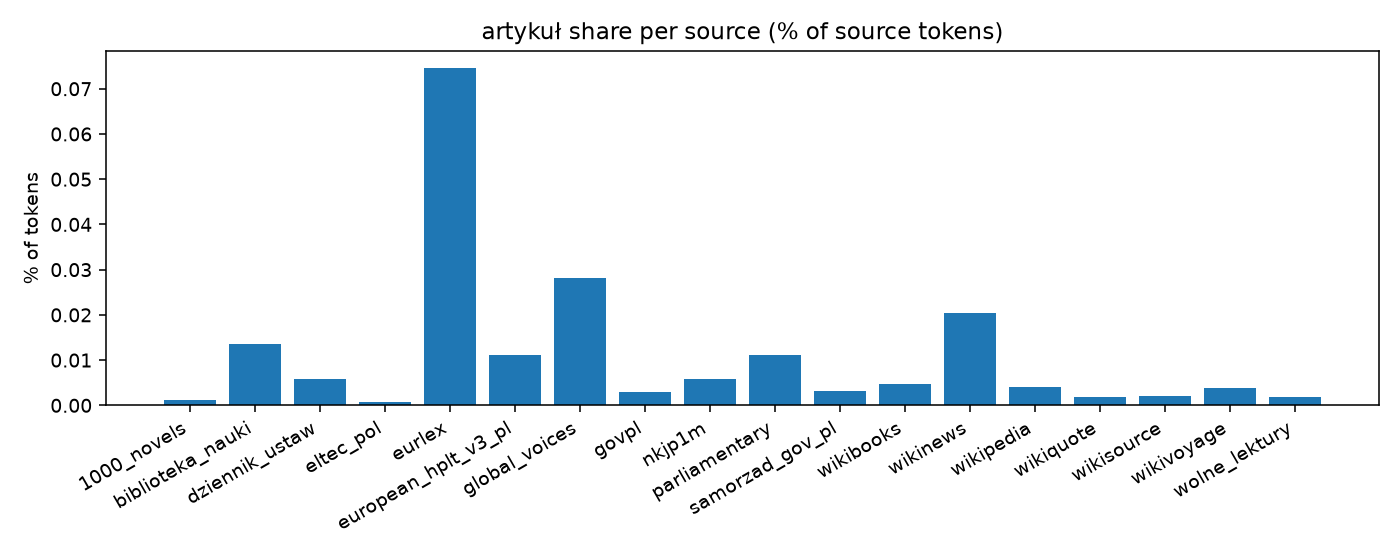
|
Git LFS Details
|

|
Git LFS Details
|
artifacts/pattern_frequency_dzu.png
CHANGED
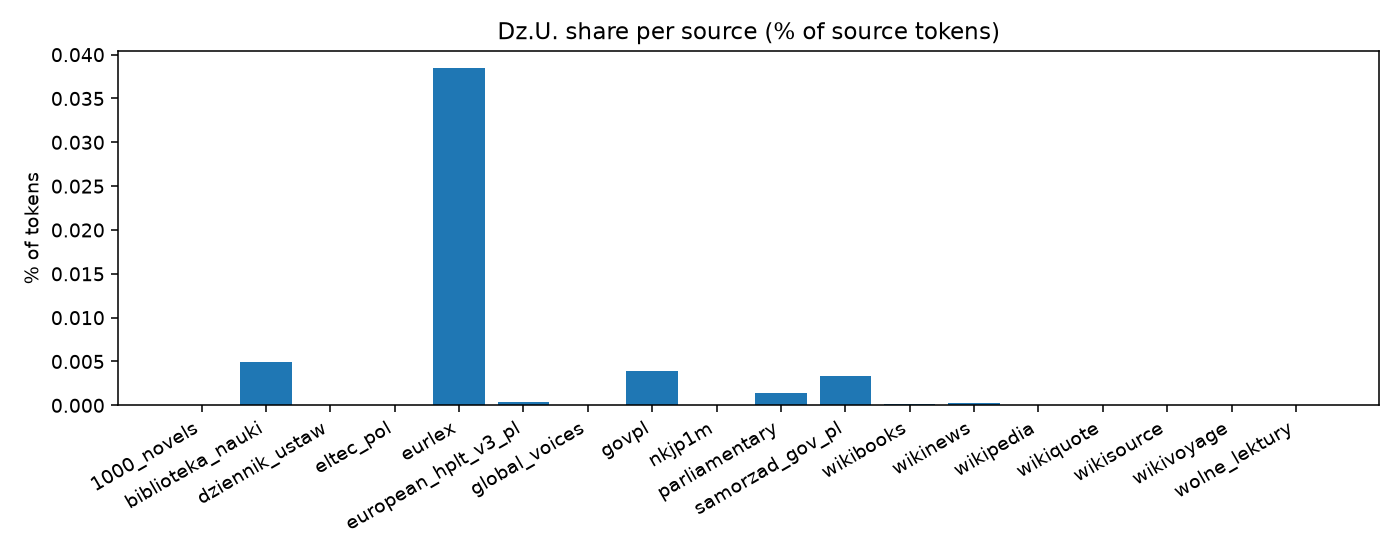
|
Git LFS Details
|

|
Git LFS Details
|
artifacts/pattern_frequency_hf_snippet.md
CHANGED
|
@@ -1,18 +1,18 @@
|
|
| 1 |
## Phrase frequency in corpus (token-normalized)
|
| 2 |
|
| 3 |
-
- Total token count (tiktoken proxy): **
|
| 4 |
|
| 5 |
| Pattern | Count | Share of all tokens |
|
| 6 |
|---|---:|---:|
|
| 7 |
-
| `w roku` |
|
| 8 |
-
| `klasyfikacji` |
|
| 9 |
-
| `ustawa` |
|
| 10 |
-
| `artykuł` | 2,
|
| 11 |
-
| `parlament` | 1,
|
| 12 |
-
| `rozporządzenie` | 1,
|
| 13 |
-
| `w pobliżu` |
|
| 14 |
-
| `mieszkańców` |
|
| 15 |
-
| `Dz.U.` |
|
| 16 |
|
| 17 |
### Per-source shares
|
| 18 |
|
|
@@ -27,15 +27,6 @@
|
|
| 27 |
| `1000_novels` | `w pobliżu` | 1,262 | 0.00209% |
|
| 28 |
| `1000_novels` | `mieszkańców` | 868 | 0.00143% |
|
| 29 |
| `1000_novels` | `Dz.U.` | 0 | 0.00000% |
|
| 30 |
-
| `biblioteka_nauki` | `w roku` | 28,728 | 0.00427% |
|
| 31 |
-
| `biblioteka_nauki` | `klasyfikacji` | 9,045 | 0.00134% |
|
| 32 |
-
| `biblioteka_nauki` | `ustawa` | 48,791 | 0.00724% |
|
| 33 |
-
| `biblioteka_nauki` | `artykuł` | 91,241 | 0.01355% |
|
| 34 |
-
| `biblioteka_nauki` | `parlament` | 32,868 | 0.00488% |
|
| 35 |
-
| `biblioteka_nauki` | `rozporządzenie` | 19,594 | 0.00291% |
|
| 36 |
-
| `biblioteka_nauki` | `w pobliżu` | 3,378 | 0.00050% |
|
| 37 |
-
| `biblioteka_nauki` | `mieszkańców` | 34,392 | 0.00511% |
|
| 38 |
-
| `biblioteka_nauki` | `Dz.U.` | 33,098 | 0.00491% |
|
| 39 |
| `dziennik_ustaw` | `w roku` | 33,096 | 0.00681% |
|
| 40 |
| `dziennik_ustaw` | `klasyfikacji` | 10,896 | 0.00224% |
|
| 41 |
| `dziennik_ustaw` | `ustawa` | 77,376 | 0.01592% |
|
|
@@ -63,24 +54,6 @@
|
|
| 63 |
| `eurlex` | `w pobliżu` | 6,088 | 0.00026% |
|
| 64 |
| `eurlex` | `mieszkańców` | 9,441 | 0.00040% |
|
| 65 |
| `eurlex` | `Dz.U.` | 915,707 | 0.03851% |
|
| 66 |
-
| `european_hplt_v3_pl` | `w roku` | 113,501 | 0.00444% |
|
| 67 |
-
| `european_hplt_v3_pl` | `klasyfikacji` | 24,675 | 0.00097% |
|
| 68 |
-
| `european_hplt_v3_pl` | `ustawa` | 16,067 | 0.00063% |
|
| 69 |
-
| `european_hplt_v3_pl` | `artykuł` | 283,875 | 0.01111% |
|
| 70 |
-
| `european_hplt_v3_pl` | `parlament` | 45,516 | 0.00178% |
|
| 71 |
-
| `european_hplt_v3_pl` | `rozporządzenie` | 11,841 | 0.00046% |
|
| 72 |
-
| `european_hplt_v3_pl` | `w pobliżu` | 44,108 | 0.00173% |
|
| 73 |
-
| `european_hplt_v3_pl` | `mieszkańców` | 172,896 | 0.00677% |
|
| 74 |
-
| `european_hplt_v3_pl` | `Dz.U.` | 9,487 | 0.00037% |
|
| 75 |
-
| `global_voices` | `w roku` | 160 | 0.00431% |
|
| 76 |
-
| `global_voices` | `klasyfikacji` | 5 | 0.00013% |
|
| 77 |
-
| `global_voices` | `ustawa` | 157 | 0.00423% |
|
| 78 |
-
| `global_voices` | `artykuł` | 1,047 | 0.02818% |
|
| 79 |
-
| `global_voices` | `parlament` | 366 | 0.00985% |
|
| 80 |
-
| `global_voices` | `rozporządzenie` | 26 | 0.00070% |
|
| 81 |
-
| `global_voices` | `w pobliżu` | 105 | 0.00283% |
|
| 82 |
-
| `global_voices` | `mieszkańców` | 508 | 0.01367% |
|
| 83 |
-
| `global_voices` | `Dz.U.` | 1 | 0.00003% |
|
| 84 |
| `govpl` | `w roku` | 3,372 | 0.00418% |
|
| 85 |
| `govpl` | `klasyfikacji` | 526 | 0.00065% |
|
| 86 |
| `govpl` | `ustawa` | 4,727 | 0.00586% |
|
|
@@ -90,15 +63,6 @@
|
|
| 90 |
| `govpl` | `w pobliżu` | 892 | 0.00111% |
|
| 91 |
| `govpl` | `mieszkańców` | 13,105 | 0.01625% |
|
| 92 |
| `govpl` | `Dz.U.` | 3,114 | 0.00386% |
|
| 93 |
-
| `nkjp1m` | `w roku` | 109 | 0.00419% |
|
| 94 |
-
| `nkjp1m` | `klasyfikacji` | 9 | 0.00035% |
|
| 95 |
-
| `nkjp1m` | `ustawa` | 79 | 0.00304% |
|
| 96 |
-
| `nkjp1m` | `artykuł` | 153 | 0.00588% |
|
| 97 |
-
| `nkjp1m` | `parlament` | 216 | 0.00830% |
|
| 98 |
-
| `nkjp1m` | `rozporządzenie` | 20 | 0.00077% |
|
| 99 |
-
| `nkjp1m` | `w pobliżu` | 77 | 0.00296% |
|
| 100 |
-
| `nkjp1m` | `mieszkańców` | 159 | 0.00611% |
|
| 101 |
-
| `nkjp1m` | `Dz.U.` | 2 | 0.00008% |
|
| 102 |
| `parliamentary` | `w roku` | 198,192 | 0.01203% |
|
| 103 |
| `parliamentary` | `klasyfikacji` | 12,637 | 0.00077% |
|
| 104 |
| `parliamentary` | `ustawa` | 459,179 | 0.02788% |
|
|
@@ -108,15 +72,6 @@
|
|
| 108 |
| `parliamentary` | `w pobliżu` | 4,964 | 0.00030% |
|
| 109 |
| `parliamentary` | `mieszkańców` | 78,048 | 0.00474% |
|
| 110 |
| `parliamentary` | `Dz.U.` | 23,809 | 0.00145% |
|
| 111 |
-
| `samorzad_gov_pl` | `w roku` | 3,661 | 0.00890% |
|
| 112 |
-
| `samorzad_gov_pl` | `klasyfikacji` | 520 | 0.00126% |
|
| 113 |
-
| `samorzad_gov_pl` | `ustawa` | 1,823 | 0.00443% |
|
| 114 |
-
| `samorzad_gov_pl` | `artykuł` | 1,269 | 0.00308% |
|
| 115 |
-
| `samorzad_gov_pl` | `parlament` | 1,218 | 0.00296% |
|
| 116 |
-
| `samorzad_gov_pl` | `rozporządzenie` | 1,409 | 0.00342% |
|
| 117 |
-
| `samorzad_gov_pl` | `w pobliżu` | 401 | 0.00097% |
|
| 118 |
-
| `samorzad_gov_pl` | `mieszkańców` | 14,450 | 0.03511% |
|
| 119 |
-
| `samorzad_gov_pl` | `Dz.U.` | 1,380 | 0.00335% |
|
| 120 |
| `wikibooks` | `w roku` | 319 | 0.00205% |
|
| 121 |
| `wikibooks` | `klasyfikacji` | 37 | 0.00024% |
|
| 122 |
| `wikibooks` | `ustawa` | 165 | 0.00106% |
|
|
|
|
| 1 |
## Phrase frequency in corpus (token-normalized)
|
| 2 |
|
| 3 |
+
- Total token count (tiktoken proxy): **6,362,577,363**
|
| 4 |
|
| 5 |
| Pattern | Count | Share of all tokens |
|
| 6 |
|---|---:|---:|
|
| 7 |
+
| `w roku` | 438,913 | 0.0069% |
|
| 8 |
+
| `klasyfikacji` | 130,503 | 0.0021% |
|
| 9 |
+
| `ustawa` | 592,186 | 0.0093% |
|
| 10 |
+
| `artykuł` | 2,038,776 | 0.0320% |
|
| 11 |
+
| `parlament` | 1,205,608 | 0.0189% |
|
| 12 |
+
| `rozporządzenie` | 1,494,566 | 0.0235% |
|
| 13 |
+
| `w pobliżu` | 79,715 | 0.0013% |
|
| 14 |
+
| `mieszkańców` | 254,305 | 0.0040% |
|
| 15 |
+
| `Dz.U.` | 943,080 | 0.0148% |
|
| 16 |
|
| 17 |
### Per-source shares
|
| 18 |
|
|
|
|
| 27 |
| `1000_novels` | `w pobliżu` | 1,262 | 0.00209% |
|
| 28 |
| `1000_novels` | `mieszkańców` | 868 | 0.00143% |
|
| 29 |
| `1000_novels` | `Dz.U.` | 0 | 0.00000% |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 30 |
| `dziennik_ustaw` | `w roku` | 33,096 | 0.00681% |
|
| 31 |
| `dziennik_ustaw` | `klasyfikacji` | 10,896 | 0.00224% |
|
| 32 |
| `dziennik_ustaw` | `ustawa` | 77,376 | 0.01592% |
|
|
|
|
| 54 |
| `eurlex` | `w pobliżu` | 6,088 | 0.00026% |
|
| 55 |
| `eurlex` | `mieszkańców` | 9,441 | 0.00040% |
|
| 56 |
| `eurlex` | `Dz.U.` | 915,707 | 0.03851% |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 57 |
| `govpl` | `w roku` | 3,372 | 0.00418% |
|
| 58 |
| `govpl` | `klasyfikacji` | 526 | 0.00065% |
|
| 59 |
| `govpl` | `ustawa` | 4,727 | 0.00586% |
|
|
|
|
| 63 |
| `govpl` | `w pobliżu` | 892 | 0.00111% |
|
| 64 |
| `govpl` | `mieszkańców` | 13,105 | 0.01625% |
|
| 65 |
| `govpl` | `Dz.U.` | 3,114 | 0.00386% |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 66 |
| `parliamentary` | `w roku` | 198,192 | 0.01203% |
|
| 67 |
| `parliamentary` | `klasyfikacji` | 12,637 | 0.00077% |
|
| 68 |
| `parliamentary` | `ustawa` | 459,179 | 0.02788% |
|
|
|
|
| 72 |
| `parliamentary` | `w pobliżu` | 4,964 | 0.00030% |
|
| 73 |
| `parliamentary` | `mieszkańców` | 78,048 | 0.00474% |
|
| 74 |
| `parliamentary` | `Dz.U.` | 23,809 | 0.00145% |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 75 |
| `wikibooks` | `w roku` | 319 | 0.00205% |
|
| 76 |
| `wikibooks` | `klasyfikacji` | 37 | 0.00024% |
|
| 77 |
| `wikibooks` | `ustawa` | 165 | 0.00106% |
|
artifacts/pattern_frequency_klasyfikacji.png
CHANGED
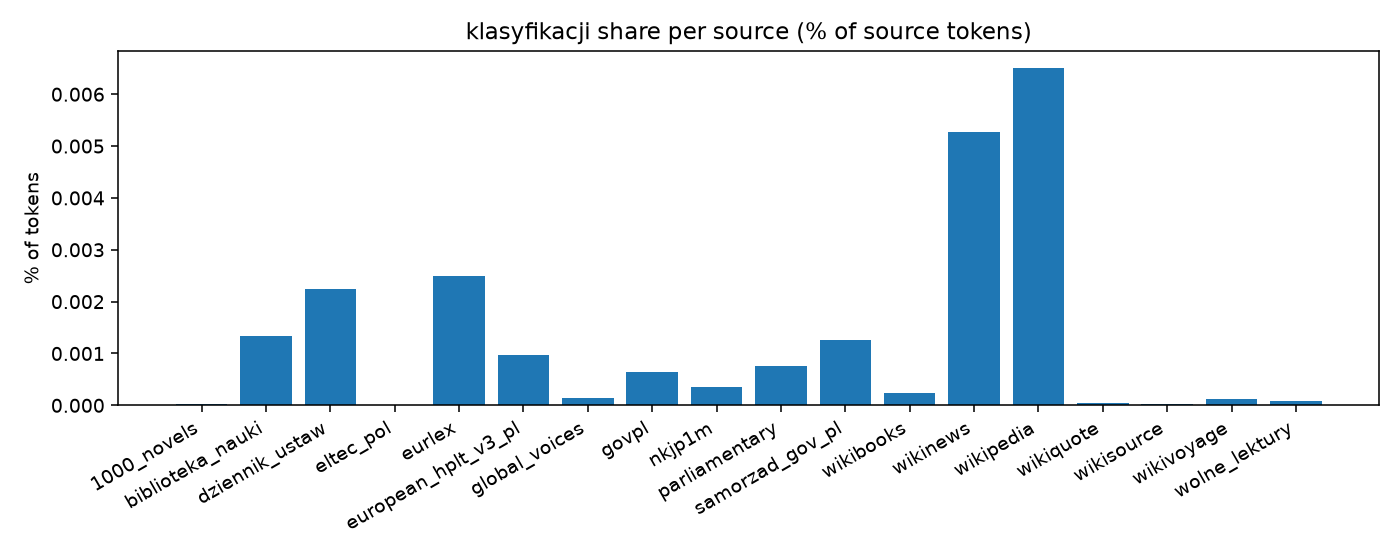
|
Git LFS Details
|

|
Git LFS Details
|
artifacts/pattern_frequency_mieszkańców.png
CHANGED
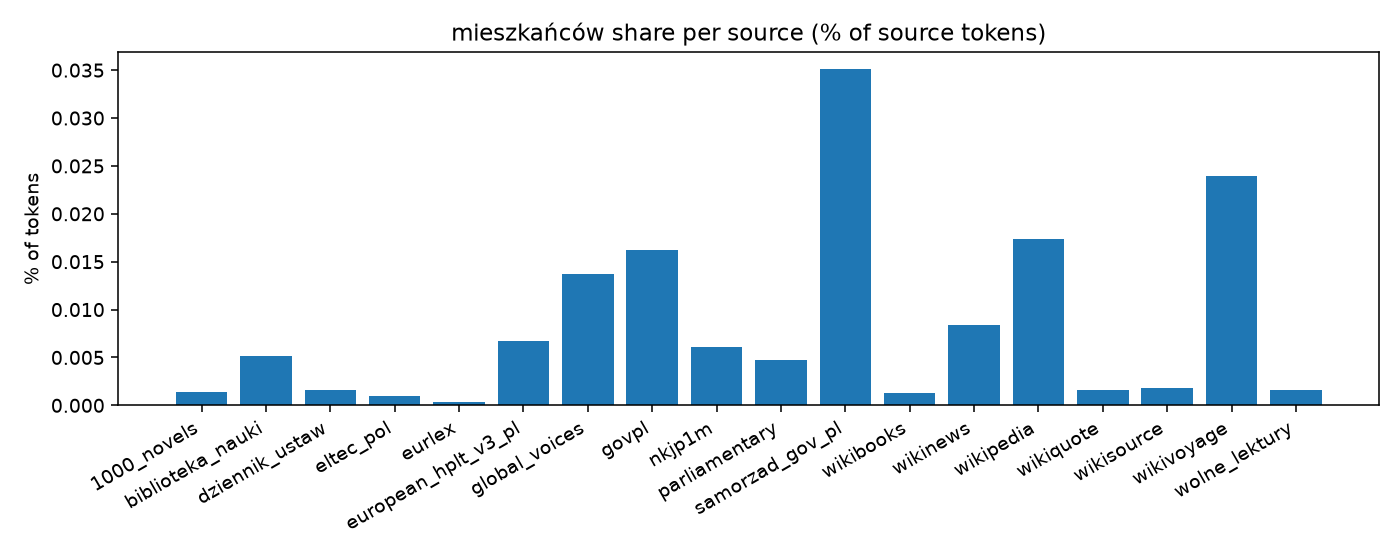
|
Git LFS Details
|

|
Git LFS Details
|
artifacts/pattern_frequency_overall.png
CHANGED
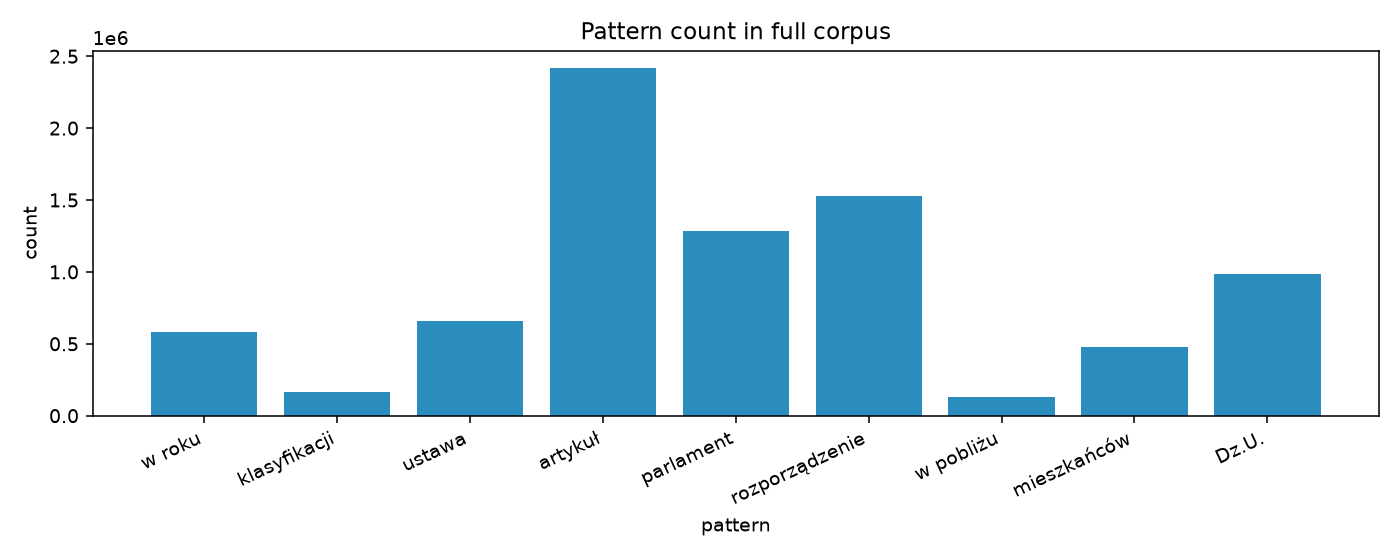
|
Git LFS Details
|

|
Git LFS Details
|
artifacts/pattern_frequency_parlament.png
CHANGED
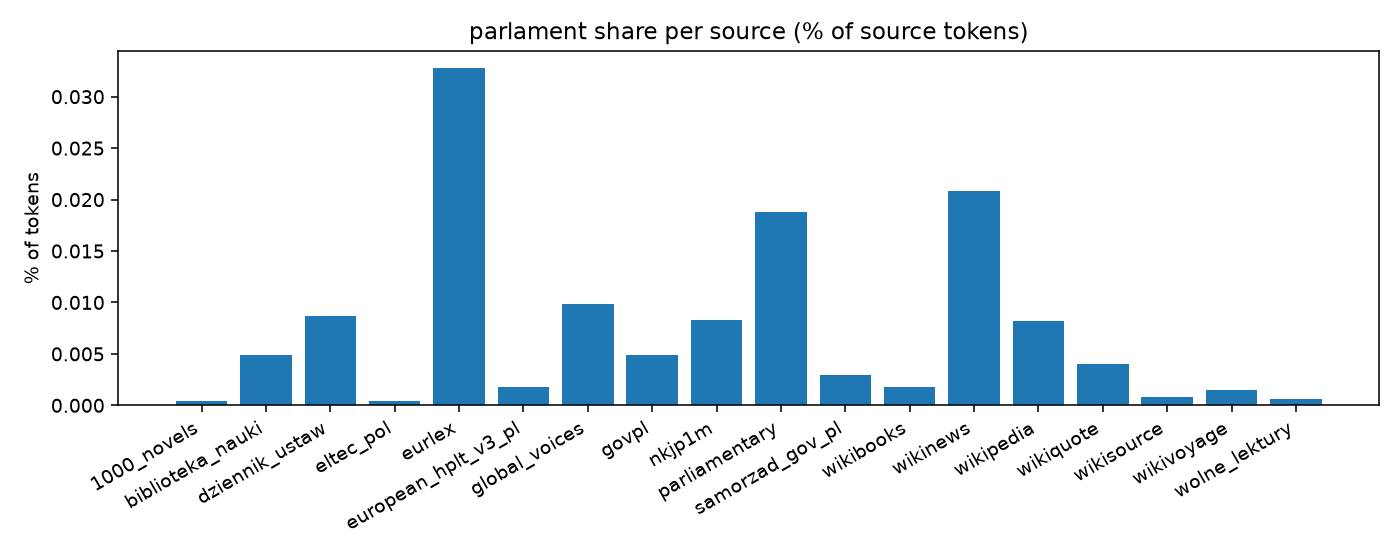
|
Git LFS Details
|

|
Git LFS Details
|
artifacts/pattern_frequency_rozporządzenie.png
CHANGED
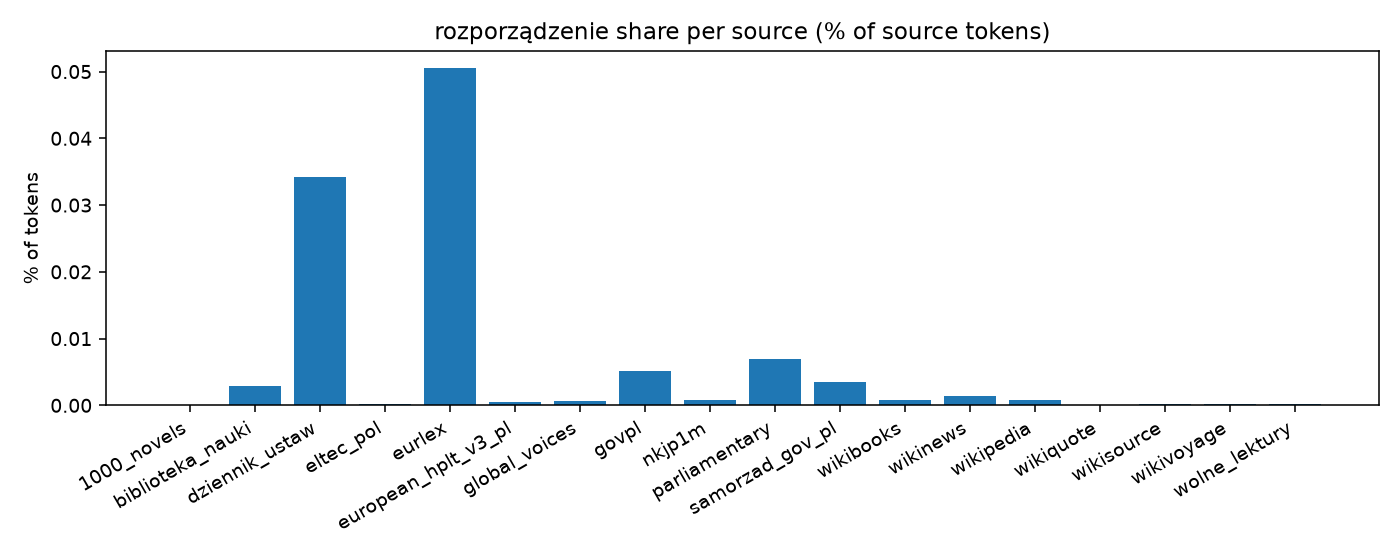
|
Git LFS Details
|

|
Git LFS Details
|
artifacts/pattern_frequency_ustawa.png
CHANGED
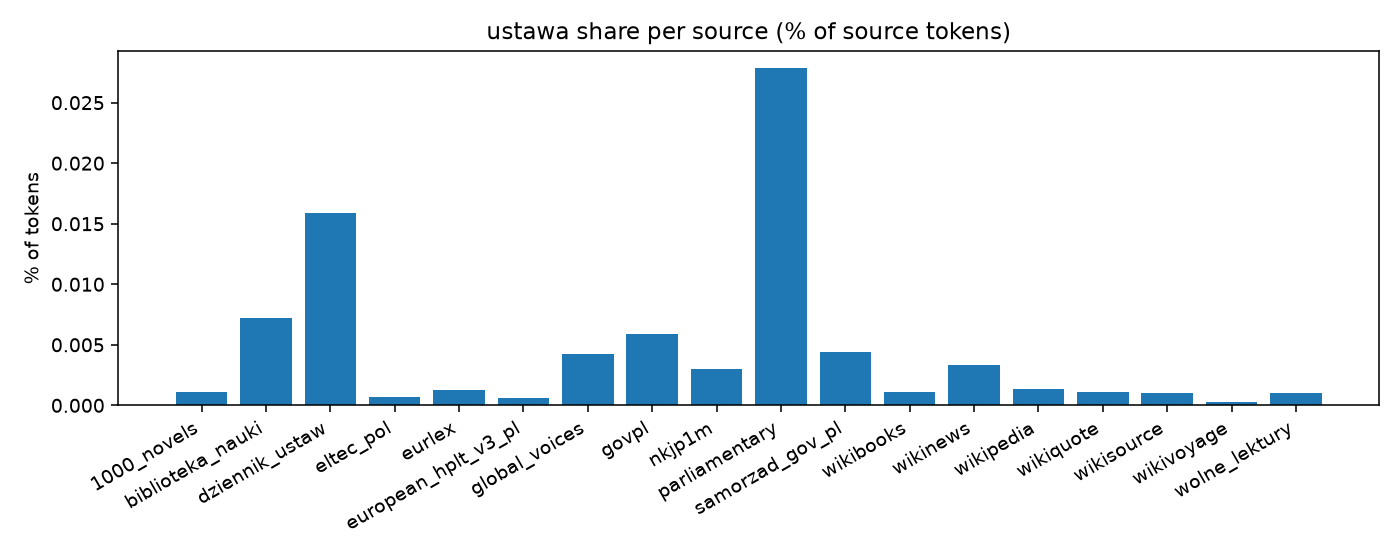
|
Git LFS Details
|

|
Git LFS Details
|
artifacts/pattern_frequency_w_pobliżu.png
CHANGED
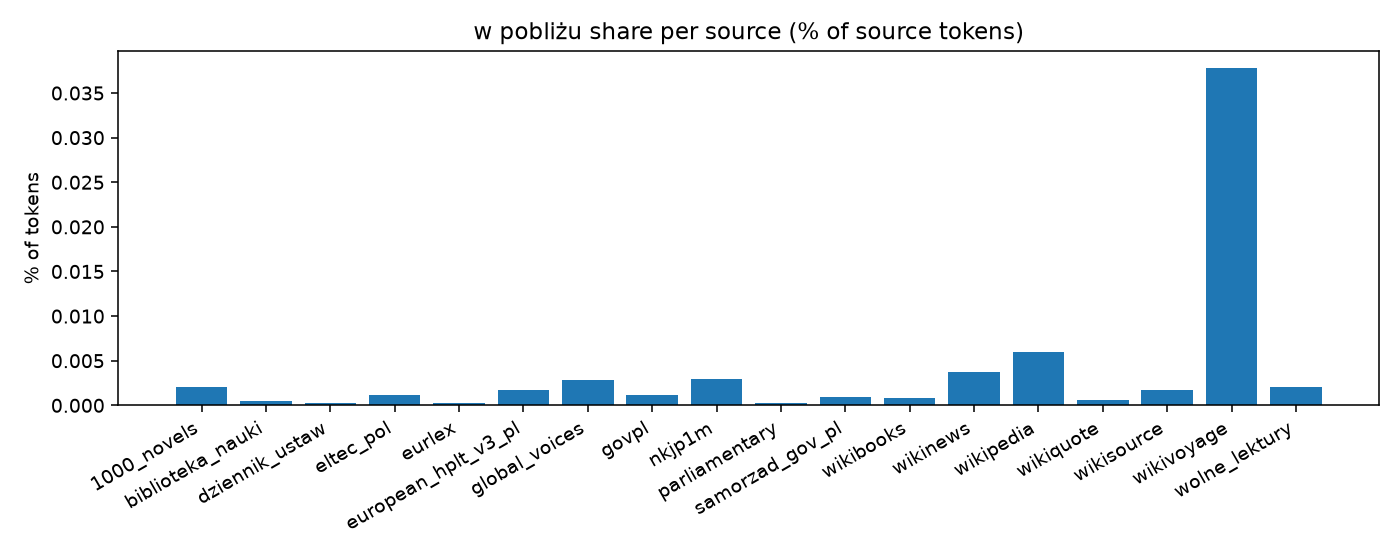
|
Git LFS Details
|

|
Git LFS Details
|
artifacts/pattern_frequency_w_roku.png
CHANGED
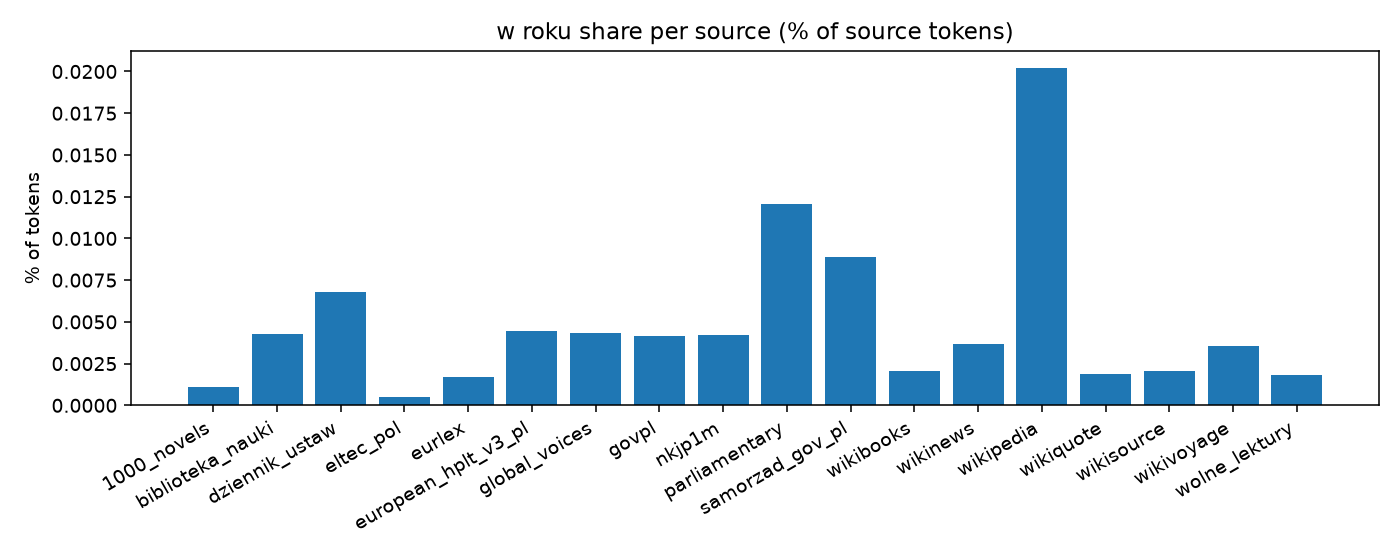
|
Git LFS Details
|

|
Git LFS Details
|
artifacts/rock_pollub_pl_ontology_manifest.json
DELETED
|
@@ -1,236 +0,0 @@
|
|
| 1 |
-
{
|
| 2 |
-
"actors": [
|
| 3 |
-
{
|
| 4 |
-
"id": "actor:piotrsty",
|
| 5 |
-
"type": "Contributor"
|
| 6 |
-
},
|
| 7 |
-
{
|
| 8 |
-
"id": "actor:politechnika-lubelska",
|
| 9 |
-
"type": "Organization"
|
| 10 |
-
},
|
| 11 |
-
{
|
| 12 |
-
"id": "actor:codex",
|
| 13 |
-
"type": "Agent"
|
| 14 |
-
}
|
| 15 |
-
],
|
| 16 |
-
"claims": [
|
| 17 |
-
{
|
| 18 |
-
"falsification_condition": "A retained record lacks Polish book metadata or either rights assertion.",
|
| 19 |
-
"id": "claim:pilot-eligibility",
|
| 20 |
-
"statement": "Retained pilot records have Polish book metadata and CC BY-SA 4.0 evidence at item and matched PDF-bitstream level.",
|
| 21 |
-
"supported_by": [
|
| 22 |
-
"evidence:inventory:33db1ffd21efb1535b0255b31f539a669f129a41b9d8e7d449fe733321c48775",
|
| 23 |
-
"evidence:qa:84834c8c5f4e947e34c34d32d89932767e5a82b3d53ab217d5f5a8dbeed087ea"
|
| 24 |
-
]
|
| 25 |
-
},
|
| 26 |
-
{
|
| 27 |
-
"falsification_condition": "The recorded comparison contains a match, or a rerun against the pinned target version finds one.",
|
| 28 |
-
"id": "claim:no-title-overlap-detected",
|
| 29 |
-
"statement": "No exact or near title match was detected against the current Biblioteka Nauki attribution column.",
|
| 30 |
-
"supported_by": [
|
| 31 |
-
"evidence:overlap:2557b13a55ad40599070cb1101af5fd74c46247e527a525b5f06543ab0645101"
|
| 32 |
-
]
|
| 33 |
-
},
|
| 34 |
-
{
|
| 35 |
-
"falsification_condition": "The pinned registry or recorded discussion list contains this source.",
|
| 36 |
-
"id": "claim:not-registered-at-audit",
|
| 37 |
-
"statement": "The source key and a matching ROCK/Pollub proposal were absent from the pinned DynaWord registry and discussion list at audit time.",
|
| 38 |
-
"supported_by": [
|
| 39 |
-
"evidence:target-audit:cddb52e9a3f5dc34073ecc22828028965a8578f2dad4c73036ca3cfa0178c303"
|
| 40 |
-
]
|
| 41 |
-
},
|
| 42 |
-
{
|
| 43 |
-
"falsification_condition": "A controlled ablation and target-wide overlap analysis establish those properties.",
|
| 44 |
-
"id": "claim:training-value-untested",
|
| 45 |
-
"statement": "Training benefit and full-corpus novelty remain untested hypotheses.",
|
| 46 |
-
"supported_by": [
|
| 47 |
-
"evidence:qa:84834c8c5f4e947e34c34d32d89932767e5a82b3d53ab217d5f5a8dbeed087ea"
|
| 48 |
-
]
|
| 49 |
-
}
|
| 50 |
-
],
|
| 51 |
-
"evidence": [
|
| 52 |
-
{
|
| 53 |
-
"artifact": "artifacts/inventory.json",
|
| 54 |
-
"content_address": "33db1ffd21efb1535b0255b31f539a669f129a41b9d8e7d449fe733321c48775",
|
| 55 |
-
"id": "evidence:inventory:33db1ffd21efb1535b0255b31f539a669f129a41b9d8e7d449fe733321c48775",
|
| 56 |
-
"observation_type": "source_inventory",
|
| 57 |
-
"produced_by": "run:324c1f246ff79d11e768795cddc0709ebec0a8ef3b2c3b47c75539b4b2f1bea0"
|
| 58 |
-
},
|
| 59 |
-
{
|
| 60 |
-
"id": "evidence:qa:84834c8c5f4e947e34c34d32d89932767e5a82b3d53ab217d5f5a8dbeed087ea",
|
| 61 |
-
"observation_type": "pilot_qa",
|
| 62 |
-
"payload": {
|
| 63 |
-
"benchmark_overlap": "pending",
|
| 64 |
-
"biblioteka_nauki_overlap": {
|
| 65 |
-
"candidate_records": 8,
|
| 66 |
-
"method": "normalized title substring; fallback SequenceMatcher >= 0.90 over attribution",
|
| 67 |
-
"observed_at": "2026-09-08T16:37:35.661794+00:00",
|
| 68 |
-
"records_with_exact_title_match": 0,
|
| 69 |
-
"records_with_fuzzy_title_match": 0,
|
| 70 |
-
"results": [
|
| 71 |
-
{
|
| 72 |
-
"exact_title_matches": [],
|
| 73 |
-
"fuzzy_title_matches": [],
|
| 74 |
-
"item_id": "513c690d-72b3-4604-b62e-e21e44b91645",
|
| 75 |
-
"title": "Modelowanie i analiza eksperymentalna parametrów pracy modułów fotowoltaicznych w warunkach rzeczywistych"
|
| 76 |
-
},
|
| 77 |
-
{
|
| 78 |
-
"exact_title_matches": [],
|
| 79 |
-
"fuzzy_title_matches": [],
|
| 80 |
-
"item_id": "e9e7a67e-c405-4968-b87a-0ff169c7b3d1",
|
| 81 |
-
"title": "Ćwiczenia i zadania ze wstępu do matematyki finansowej"
|
| 82 |
-
},
|
| 83 |
-
{
|
| 84 |
-
"exact_title_matches": [],
|
| 85 |
-
"fuzzy_title_matches": [],
|
| 86 |
-
"item_id": "a6c38c5d-ba8f-47ac-a3e6-b50df14a595b",
|
| 87 |
-
"title": "Dobór architektury i parametrów procesu uczenia sieci neuronowych w doskonaleniu procesów produkcyjnych"
|
| 88 |
-
},
|
| 89 |
-
{
|
| 90 |
-
"exact_title_matches": [],
|
| 91 |
-
"fuzzy_title_matches": [],
|
| 92 |
-
"item_id": "903f22e1-a2ab-4231-a402-2bc9535c12f2",
|
| 93 |
-
"title": "Wyzwania współczesnego publikowania"
|
| 94 |
-
},
|
| 95 |
-
{
|
| 96 |
-
"exact_title_matches": [],
|
| 97 |
-
"fuzzy_title_matches": [],
|
| 98 |
-
"item_id": "0e26bff5-e51a-4d36-9524-fdef6e3e6ab7",
|
| 99 |
-
"title": "Symulacje Monte Carlo. Teoria i zastosowania"
|
| 100 |
-
},
|
| 101 |
-
{
|
| 102 |
-
"exact_title_matches": [],
|
| 103 |
-
"fuzzy_title_matches": [],
|
| 104 |
-
"item_id": "032a14e5-5c8e-4153-9cf7-2dfd9e361e6d",
|
| 105 |
-
"title": "Zastosowanie uczenia maszynowego do obrazowania stanu zawilgocenia murów z wykorzystaniem tomografii impedancyjnej"
|
| 106 |
-
},
|
| 107 |
-
{
|
| 108 |
-
"exact_title_matches": [],
|
| 109 |
-
"fuzzy_title_matches": [],
|
| 110 |
-
"item_id": "da87b1d3-7018-46fa-81bd-380f0780a1b3",
|
| 111 |
-
"title": "Zarządzanie współprac�� instytucji państwa z diasporą. Przegląd teorii, analiza porównawcza wybranych państw"
|
| 112 |
-
},
|
| 113 |
-
{
|
| 114 |
-
"exact_title_matches": [],
|
| 115 |
-
"fuzzy_title_matches": [],
|
| 116 |
-
"item_id": "a257b1ce-1af7-4dfc-ae38-ec67ef877689",
|
| 117 |
-
"title": "Komputerowa grafika inżynierska. Ćwiczenia do programu AutoCAD 2023"
|
| 118 |
-
}
|
| 119 |
-
],
|
| 120 |
-
"target": "SlayerLab/polish-dynaword:data/biblioteka_nauki",
|
| 121 |
-
"target_revision": "02bcb0b5f991a30f8454c6444f701633b71f69d4",
|
| 122 |
-
"target_rows": 42071,
|
| 123 |
-
"text_overlap": "not tested; target-wide text dedup remains an integration gate"
|
| 124 |
-
},
|
| 125 |
-
"cross_source_dedup": "pending target integration",
|
| 126 |
-
"exact_dedup": true,
|
| 127 |
-
"license_gate": "CC-BY-SA-4.0 in item and matched PDF bitstream metadata",
|
| 128 |
-
"limitations": [
|
| 129 |
-
"PDF extraction may flatten tables and equations",
|
| 130 |
-
"third-party figures and quoted material are not included as images but textual excerpts require review",
|
| 131 |
-
"isolated PDF extraction replacement characters are represented as [UNREADABLE_GLYPH]",
|
| 132 |
-
"pattern checks are not comprehensive de-identification",
|
| 133 |
-
"pilot yield must not be extrapolated without a full inventory run"
|
| 134 |
-
],
|
| 135 |
-
"near_dedup": "exact 5-word-shingle Jaccard >= 0.90 within pilot",
|
| 136 |
-
"pii_pattern_matches": {
|
| 137 |
-
"email": 2,
|
| 138 |
-
"labelled_phone": 0
|
| 139 |
-
},
|
| 140 |
-
"scope": "pilot target 20; acquired 8; not a completeness claim",
|
| 141 |
-
"target_reached": false
|
| 142 |
-
},
|
| 143 |
-
"produced_by": "run:324c1f246ff79d11e768795cddc0709ebec0a8ef3b2c3b47c75539b4b2f1bea0"
|
| 144 |
-
},
|
| 145 |
-
{
|
| 146 |
-
"artifact": "artifacts/overlap_audit.json",
|
| 147 |
-
"content_address": "2557b13a55ad40599070cb1101af5fd74c46247e527a525b5f06543ab0645101",
|
| 148 |
-
"id": "evidence:overlap:2557b13a55ad40599070cb1101af5fd74c46247e527a525b5f06543ab0645101",
|
| 149 |
-
"observation_type": "metadata_overlap_audit",
|
| 150 |
-
"produced_by": "run:324c1f246ff79d11e768795cddc0709ebec0a8ef3b2c3b47c75539b4b2f1bea0"
|
| 151 |
-
},
|
| 152 |
-
{
|
| 153 |
-
"artifact": "artifacts/target_audit.json",
|
| 154 |
-
"content_address": "cddb52e9a3f5dc34073ecc22828028965a8578f2dad4c73036ca3cfa0178c303",
|
| 155 |
-
"id": "evidence:target-audit:cddb52e9a3f5dc34073ecc22828028965a8578f2dad4c73036ca3cfa0178c303",
|
| 156 |
-
"observation_type": "target_registry_audit",
|
| 157 |
-
"produced_by": "run:324c1f246ff79d11e768795cddc0709ebec0a8ef3b2c3b47c75539b4b2f1bea0"
|
| 158 |
-
}
|
| 159 |
-
],
|
| 160 |
-
"objects": [
|
| 161 |
-
{
|
| 162 |
-
"id": "object:source:rock-pollub",
|
| 163 |
-
"type": "Source"
|
| 164 |
-
},
|
| 165 |
-
{
|
| 166 |
-
"id": "object:dataset:rock-pollub-pl-pilot",
|
| 167 |
-
"type": "Dataset"
|
| 168 |
-
}
|
| 169 |
-
],
|
| 170 |
-
"pending": [
|
| 171 |
-
"Biblioteka Nauki text overlap",
|
| 172 |
-
"full collection inventory",
|
| 173 |
-
"cross-source deduplication",
|
| 174 |
-
"benchmark contamination check",
|
| 175 |
-
"legal review of third-party textual excerpts",
|
| 176 |
-
"controlled training ablation"
|
| 177 |
-
],
|
| 178 |
-
"protocols": [
|
| 179 |
-
{
|
| 180 |
-
"id": "protocol:rock-pilot-v1",
|
| 181 |
-
"procedure": "item+PDF rights gate, matched repository text, normalization, PII patterns, exact/near dedup"
|
| 182 |
-
}
|
| 183 |
-
],
|
| 184 |
-
"relations": [
|
| 185 |
-
{
|
| 186 |
-
"predicate": "DERIVED_FROM",
|
| 187 |
-
"source": "version:dataset:18ea2bb4ce1035ac7d39295f627d43da02a2959baddd52fab901970ed0fae9eb",
|
| 188 |
-
"target": "version:source:ae3d159ce612b8088f43097ff3d16a55ba8e8807ad3b3b4e8b2866ace23e543d"
|
| 189 |
-
},
|
| 190 |
-
{
|
| 191 |
-
"predicate": "GENERATED_BY",
|
| 192 |
-
"source": "version:dataset:18ea2bb4ce1035ac7d39295f627d43da02a2959baddd52fab901970ed0fae9eb",
|
| 193 |
-
"target": "run:324c1f246ff79d11e768795cddc0709ebec0a8ef3b2c3b47c75539b4b2f1bea0"
|
| 194 |
-
},
|
| 195 |
-
{
|
| 196 |
-
"predicate": "VALIDATED_AGAINST",
|
| 197 |
-
"source": "version:dataset:18ea2bb4ce1035ac7d39295f627d43da02a2959baddd52fab901970ed0fae9eb",
|
| 198 |
-
"target": "hf:dataset:SlayerLab/polish-dynaword@02bcb0b5f991a30f8454c6444f701633b71f69d4"
|
| 199 |
-
}
|
| 200 |
-
],
|
| 201 |
-
"runs": [
|
| 202 |
-
{
|
| 203 |
-
"actor": "actor:codex",
|
| 204 |
-
"finished_at": "2026-09-08T16:46:45.891136+00:00",
|
| 205 |
-
"id": "run:324c1f246ff79d11e768795cddc0709ebec0a8ef3b2c3b47c75539b4b2f1bea0",
|
| 206 |
-
"protocol": "protocol:rock-pilot-v1",
|
| 207 |
-
"started_at": "2026-09-08T16:26:05.196224+00:00",
|
| 208 |
-
"stats": {
|
| 209 |
-
"acquired": 8,
|
| 210 |
-
"added": "2026-09-08",
|
| 211 |
-
"author_coverage": 1.0,
|
| 212 |
-
"characters": 3380937,
|
| 213 |
-
"discovered_collection_items": 771,
|
| 214 |
-
"kept": 8,
|
| 215 |
-
"pilot_limit": 20,
|
| 216 |
-
"rejected": 0,
|
| 217 |
-
"sample_count": 8,
|
| 218 |
-
"tokens": 1177858
|
| 219 |
-
},
|
| 220 |
-
"success": true
|
| 221 |
-
}
|
| 222 |
-
],
|
| 223 |
-
"schema": "slayer-research-ontology-profile-v1",
|
| 224 |
-
"versions": [
|
| 225 |
-
{
|
| 226 |
-
"content_address": "ae3d159ce612b8088f43097ff3d16a55ba8e8807ad3b3b4e8b2866ace23e543d",
|
| 227 |
-
"id": "version:source:ae3d159ce612b8088f43097ff3d16a55ba8e8807ad3b3b4e8b2866ace23e543d",
|
| 228 |
-
"object": "object:source:rock-pollub"
|
| 229 |
-
},
|
| 230 |
-
{
|
| 231 |
-
"content_address": "18ea2bb4ce1035ac7d39295f627d43da02a2959baddd52fab901970ed0fae9eb",
|
| 232 |
-
"id": "version:dataset:18ea2bb4ce1035ac7d39295f627d43da02a2959baddd52fab901970ed0fae9eb",
|
| 233 |
-
"object": "object:dataset:rock-pollub-pl-pilot"
|
| 234 |
-
}
|
| 235 |
-
]
|
| 236 |
-
}
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
artifacts/sejm_api_ontology_manifest.json
DELETED
|
@@ -1,238 +0,0 @@
|
|
| 1 |
-
{
|
| 2 |
-
"actors": [
|
| 3 |
-
{
|
| 4 |
-
"id": "github:PiotrStyla",
|
| 5 |
-
"kind": "automation"
|
| 6 |
-
}
|
| 7 |
-
],
|
| 8 |
-
"attestations": [
|
| 9 |
-
{
|
| 10 |
-
"actor_id": "github:PiotrStyla",
|
| 11 |
-
"fields": [
|
| 12 |
-
"id",
|
| 13 |
-
"text",
|
| 14 |
-
"source",
|
| 15 |
-
"added",
|
| 16 |
-
"created",
|
| 17 |
-
"token_count",
|
| 18 |
-
"license",
|
| 19 |
-
"author"
|
| 20 |
-
],
|
| 21 |
-
"type": "schema_valid",
|
| 22 |
-
"value": true
|
| 23 |
-
},
|
| 24 |
-
{
|
| 25 |
-
"actor_id": "github:PiotrStyla",
|
| 26 |
-
"supported_by": [
|
| 27 |
-
"slayer://evidence/sejm-api-legal-basis@sha256:38e42a791d68d593f82e"
|
| 28 |
-
],
|
| 29 |
-
"type": "license_policy",
|
| 30 |
-
"value": "open_public_sector_reuse"
|
| 31 |
-
},
|
| 32 |
-
{
|
| 33 |
-
"actor_id": "github:PiotrStyla",
|
| 34 |
-
"supported_by": [
|
| 35 |
-
"slayer://evidence/sejm-api-temporal-novelty@sha256:38e42a791d68d593f82e"
|
| 36 |
-
],
|
| 37 |
-
"type": "temporal_overlap",
|
| 38 |
-
"value": "none_for_registered_parliamentary_sources"
|
| 39 |
-
},
|
| 40 |
-
{
|
| 41 |
-
"actor_id": "github:PiotrStyla",
|
| 42 |
-
"supported_by": [
|
| 43 |
-
"slayer://evidence/sejm-api-author-attribution@sha256:38e42a791d68d593f82e"
|
| 44 |
-
],
|
| 45 |
-
"type": "speaker_attribution",
|
| 46 |
-
"value": "100_percent"
|
| 47 |
-
}
|
| 48 |
-
],
|
| 49 |
-
"claim_evidence": [
|
| 50 |
-
{
|
| 51 |
-
"claim_id": "slayer://claim/sejm-api-temporal-novelty@sha256:38e42a791d68d593f82e",
|
| 52 |
-
"evidence_id": "slayer://evidence/sejm-api-temporal-novelty@sha256:38e42a791d68d593f82e",
|
| 53 |
-
"relation": "SUPPORTS"
|
| 54 |
-
},
|
| 55 |
-
{
|
| 56 |
-
"claim_id": "slayer://claim/sejm-api-full-speaker-attribution@sha256:38e42a791d68d593f82e",
|
| 57 |
-
"evidence_id": "slayer://evidence/sejm-api-author-attribution@sha256:38e42a791d68d593f82e",
|
| 58 |
-
"relation": "SUPPORTS"
|
| 59 |
-
},
|
| 60 |
-
{
|
| 61 |
-
"claim_id": "slayer://claim/sejm-api-open-official-materials@sha256:38e42a791d68d593f82e",
|
| 62 |
-
"evidence_id": "slayer://evidence/sejm-api-legal-basis@sha256:38e42a791d68d593f82e",
|
| 63 |
-
"relation": "SUPPORTS"
|
| 64 |
-
}
|
| 65 |
-
],
|
| 66 |
-
"claims": [
|
| 67 |
-
{
|
| 68 |
-
"asserted_by": "github:PiotrStyla",
|
| 69 |
-
"falsification_condition": "Any contributed created date is <= either documented source end date.",
|
| 70 |
-
"id": "slayer://claim/sejm-api-temporal-novelty@sha256:38e42a791d68d593f82e",
|
| 71 |
-
"scope": [
|
| 72 |
-
"slayer://version/dataset-source/sejm-api@sha256:38e42a791d68d593f82e1125f2bb94cd8f68212433e71d3e3da90f82d78eaf32"
|
| 73 |
-
],
|
| 74 |
-
"statement": "Every contributed speech postdates both registered parliamentary source ranges.",
|
| 75 |
-
"supported_by": [
|
| 76 |
-
"slayer://evidence/sejm-api-temporal-novelty@sha256:38e42a791d68d593f82e"
|
| 77 |
-
]
|
| 78 |
-
},
|
| 79 |
-
{
|
| 80 |
-
"asserted_by": "github:PiotrStyla",
|
| 81 |
-
"falsification_condition": "Any contributed document has an empty author field.",
|
| 82 |
-
"id": "slayer://claim/sejm-api-full-speaker-attribution@sha256:38e42a791d68d593f82e",
|
| 83 |
-
"scope": [
|
| 84 |
-
"slayer://version/dataset-source/sejm-api@sha256:38e42a791d68d593f82e1125f2bb94cd8f68212433e71d3e3da90f82d78eaf32"
|
| 85 |
-
],
|
| 86 |
-
"statement": "Every contributed document has a non-empty speech-speaker attribution.",
|
| 87 |
-
"supported_by": [
|
| 88 |
-
"slayer://evidence/sejm-api-author-attribution@sha256:38e42a791d68d593f82e"
|
| 89 |
-
]
|
| 90 |
-
},
|
| 91 |
-
{
|
| 92 |
-
"asserted_by": "github:PiotrStyla",
|
| 93 |
-
"falsification_condition": "A record is not an official parliamentary material or an applicable statutory limitation defeats reuse.",
|
| 94 |
-
"id": "slayer://claim/sejm-api-open-official-materials@sha256:38e42a791d68d593f82e",
|
| 95 |
-
"scope": [
|
| 96 |
-
"slayer://version/dataset-source/sejm-api@sha256:38e42a791d68d593f82e1125f2bb94cd8f68212433e71d3e3da90f82d78eaf32"
|
| 97 |
-
],
|
| 98 |
-
"statement": "The source contains official parliamentary materials with documented statutory reuse.",
|
| 99 |
-
"supported_by": [
|
| 100 |
-
"slayer://evidence/sejm-api-legal-basis@sha256:38e42a791d68d593f82e"
|
| 101 |
-
]
|
| 102 |
-
}
|
| 103 |
-
],
|
| 104 |
-
"evidence": [
|
| 105 |
-
{
|
| 106 |
-
"id": "slayer://evidence/sejm-api-record-counts@sha256:38e42a791d68d593f82e",
|
| 107 |
-
"observation_type": "dataset_record_counts",
|
| 108 |
-
"payload": {
|
| 109 |
-
"drop_before_start": 118902,
|
| 110 |
-
"drop_dup": 0,
|
| 111 |
-
"kept": 38812,
|
| 112 |
-
"read": 157714,
|
| 113 |
-
"tokens": 36335587
|
| 114 |
-
},
|
| 115 |
-
"run_id": "github-actions:32586999448:attempt:1",
|
| 116 |
-
"subject_version": "slayer://version/dataset-source/sejm-api@sha256:38e42a791d68d593f82e1125f2bb94cd8f68212433e71d3e3da90f82d78eaf32"
|
| 117 |
-
},
|
| 118 |
-
{
|
| 119 |
-
"id": "slayer://evidence/sejm-api-temporal-novelty@sha256:38e42a791d68d593f82e",
|
| 120 |
-
"observation_type": "registered_source_date_ranges",
|
| 121 |
-
"payload": {
|
| 122 |
-
"candidate_max": "2026-07-03",
|
| 123 |
-
"candidate_min": "2023-01-11",
|
| 124 |
-
"existing_source_end_dates": {
|
| 125 |
-
"parlamint_pl": "2022-12-31",
|
| 126 |
-
"parliamentary": "2019-12-31"
|
| 127 |
-
}
|
| 128 |
-
},
|
| 129 |
-
"run_id": "github-actions:32586999448:attempt:1",
|
| 130 |
-
"subject_version": "slayer://version/dataset-source/sejm-api@sha256:38e42a791d68d593f82e1125f2bb94cd8f68212433e71d3e3da90f82d78eaf32"
|
| 131 |
-
},
|
| 132 |
-
{
|
| 133 |
-
"id": "slayer://evidence/sejm-api-author-attribution@sha256:38e42a791d68d593f82e",
|
| 134 |
-
"observation_type": "speaker_attribution_coverage",
|
| 135 |
-
"payload": {
|
| 136 |
-
"attributed_documents": 38812,
|
| 137 |
-
"documents": 38812
|
| 138 |
-
},
|
| 139 |
-
"run_id": "github-actions:32586999448:attempt:1",
|
| 140 |
-
"subject_version": "slayer://version/dataset-source/sejm-api@sha256:38e42a791d68d593f82e1125f2bb94cd8f68212433e71d3e3da90f82d78eaf32"
|
| 141 |
-
},
|
| 142 |
-
{
|
| 143 |
-
"id": "slayer://evidence/sejm-api-legal-basis@sha256:38e42a791d68d593f82e",
|
| 144 |
-
"observation_type": "official_statutory_reuse_sources",
|
| 145 |
-
"payload": {
|
| 146 |
-
"copyright_act": "https://eli.gov.pl/api/acts/DU/2025/24/text/O/D20250024.pdf",
|
| 147 |
-
"legal_evidence_sha256": "ff52cd0c374aee51162d4088088f7bdfbabaa9c6e3d1816063b404b11369da0f",
|
| 148 |
-
"license": "public-domain (official documents)",
|
| 149 |
-
"open_data_act": "https://eli.gov.pl/api/acts/DU/2023/1524/text.html",
|
| 150 |
-
"source_documentation": "https://api.sejm.gov.pl/sejm.html"
|
| 151 |
-
},
|
| 152 |
-
"run_id": "github-actions:32586999448:attempt:1",
|
| 153 |
-
"subject_version": "slayer://version/dataset-source/sejm-api@sha256:38e42a791d68d593f82e1125f2bb94cd8f68212433e71d3e3da90f82d78eaf32"
|
| 154 |
-
},
|
| 155 |
-
{
|
| 156 |
-
"id": "slayer://evidence/sejm-api-artifact-digests@sha256:38e42a791d68d593f82e",
|
| 157 |
-
"observation_type": "artifact_checksums",
|
| 158 |
-
"payload": {
|
| 159 |
-
"attribution_sha256": "4ab6513f8173498d403f7ec1a9534b8e0086264d3eca6ff9ac4f9c5dbca4c069",
|
| 160 |
-
"parquet_sha256": "56f7b03483488dec8f0fa145c6d26746926175d83096e9d1931e535aa81cf161"
|
| 161 |
-
},
|
| 162 |
-
"run_id": "github-actions:32586999448:attempt:1",
|
| 163 |
-
"subject_version": "slayer://version/dataset-source/sejm-api@sha256:38e42a791d68d593f82e1125f2bb94cd8f68212433e71d3e3da90f82d78eaf32"
|
| 164 |
-
}
|
| 165 |
-
],
|
| 166 |
-
"object": {
|
| 167 |
-
"id": "slayer://object/dataset-source/slayerlab-polish-dynaword-sejm-api",
|
| 168 |
-
"kind": "dataset_source",
|
| 169 |
-
"name": "sejm_api"
|
| 170 |
-
},
|
| 171 |
-
"protocol": {
|
| 172 |
-
"configuration": {
|
| 173 |
-
"added": "2026-08-22",
|
| 174 |
-
"exact_deduplication": "sha1(normalized_text)",
|
| 175 |
-
"registered_parliamentary_end_dates": {
|
| 176 |
-
"parlamint_pl": "2022-12-31",
|
| 177 |
-
"parliamentary": "2019-12-31"
|
| 178 |
-
},
|
| 179 |
-
"schema_fields": [
|
| 180 |
-
"id",
|
| 181 |
-
"text",
|
| 182 |
-
"source",
|
| 183 |
-
"added",
|
| 184 |
-
"created",
|
| 185 |
-
"token_count",
|
| 186 |
-
"license",
|
| 187 |
-
"author"
|
| 188 |
-
],
|
| 189 |
-
"source_release": "v1.0.1",
|
| 190 |
-
"source_revision": "124557799608ce4212cf22fa90ca7904618de1b6",
|
| 191 |
-
"start_date": "2023-01-01",
|
| 192 |
-
"target_base_revision": "8cc48a3c564ac9edabfbbf012842ad11f70a3e5c",
|
| 193 |
-
"tokenizer": "cl100k_base"
|
| 194 |
-
},
|
| 195 |
-
"entrypoint": "python src/fetch_sejm_api.py",
|
| 196 |
-
"git_commit": "2a50019652d90f135f0d3a91c8c2c7176619c784"
|
| 197 |
-
},
|
| 198 |
-
"relations": [
|
| 199 |
-
{
|
| 200 |
-
"introduced_by_run": "github-actions:32586999448:attempt:1",
|
| 201 |
-
"predicate": "DERIVED_FROM",
|
| 202 |
-
"source_version": "slayer://version/dataset-source/sejm-api@sha256:38e42a791d68d593f82e1125f2bb94cd8f68212433e71d3e3da90f82d78eaf32",
|
| 203 |
-
"target_version": "hf://datasets/PiotrSty/sejm-speeches-corpus@124557799608ce4212cf22fa90ca7904618de1b6"
|
| 204 |
-
},
|
| 205 |
-
{
|
| 206 |
-
"introduced_by_run": "github-actions:32586999448:attempt:1",
|
| 207 |
-
"predicate": "COMPATIBLE_WITH",
|
| 208 |
-
"source_version": "slayer://version/dataset-source/sejm-api@sha256:38e42a791d68d593f82e1125f2bb94cd8f68212433e71d3e3da90f82d78eaf32",
|
| 209 |
-
"target_version": "hf://datasets/SlayerLab/polish-dynaword@8cc48a3c564ac9edabfbbf012842ad11f70a3e5c"
|
| 210 |
-
}
|
| 211 |
-
],
|
| 212 |
-
"run": {
|
| 213 |
-
"actor_id": "github:PiotrStyla",
|
| 214 |
-
"git_commit": "2a50019652d90f135f0d3a91c8c2c7176619c784",
|
| 215 |
-
"id": "github-actions:32586999448:attempt:1",
|
| 216 |
-
"inputs": [
|
| 217 |
-
{
|
| 218 |
-
"role": "source",
|
| 219 |
-
"version_id": "hf://datasets/PiotrSty/sejm-speeches-corpus@124557799608ce4212cf22fa90ca7904618de1b6"
|
| 220 |
-
},
|
| 221 |
-
{
|
| 222 |
-
"role": "target_base",
|
| 223 |
-
"version_id": "hf://datasets/SlayerLab/polish-dynaword@8cc48a3c564ac9edabfbbf012842ad11f70a3e5c"
|
| 224 |
-
}
|
| 225 |
-
],
|
| 226 |
-
"outputs": [
|
| 227 |
-
{
|
| 228 |
-
"role": "dataset_source",
|
| 229 |
-
"version_id": "slayer://version/dataset-source/sejm-api@sha256:38e42a791d68d593f82e1125f2bb94cd8f68212433e71d3e3da90f82d78eaf32"
|
| 230 |
-
}
|
| 231 |
-
]
|
| 232 |
-
},
|
| 233 |
-
"schema_version": "slayer.ai/dataset-source-contribution/v1",
|
| 234 |
-
"version": {
|
| 235 |
-
"digest": "sha256:38e42a791d68d593f82e1125f2bb94cd8f68212433e71d3e3da90f82d78eaf32",
|
| 236 |
-
"id": "slayer://version/dataset-source/sejm-api@sha256:38e42a791d68d593f82e1125f2bb94cd8f68212433e71d3e3da90f82d78eaf32"
|
| 237 |
-
}
|
| 238 |
-
}
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
artifacts/source_findings.md
DELETED
|
@@ -1,543 +0,0 @@
|
|
| 1 |
-
# Source investigation findings
|
| 2 |
-
|
| 3 |
-
Running log of sources that were investigated, whether or not they were added.
|
| 4 |
-
**Append-only, version-independent** — unlike the `*_v0_3.md` artifacts, which are
|
| 5 |
-
point-in-time snapshots of one release's candidate review.
|
| 6 |
-
|
| 7 |
-
Purpose: stop the same source being re-investigated from scratch every few months.
|
| 8 |
-
A negative finding is as valuable as a positive one, as long as it records *what
|
| 9 |
-
was checked* and *what would change the answer*.
|
| 10 |
-
|
| 11 |
-
Related, don't duplicate:
|
| 12 |
-
- `source_scouting_v0_3.md` — v0.3 candidate shortlist (HuggingFace-centric)
|
| 13 |
-
- `source_candidate_audit_v0_3.md` — machine-generated audit of those HF cards
|
| 14 |
-
- `source_license_review_v0_3.md` — v0.3 license decision table
|
| 15 |
-
|
| 16 |
-
## How to add an entry
|
| 17 |
-
|
| 18 |
-
One `##` section per source. Keep these fields:
|
| 19 |
-
|
| 20 |
-
- **Investigated** — date, so a stale finding is visible as stale.
|
| 21 |
-
- **Verdict** — `added` / `blocked` / `hold` / `rejected`, plus the one-line reason.
|
| 22 |
-
- **Enumeration** — how you would actually get the data, or why you can't.
|
| 23 |
-
- **License evidence** — what you checked, with URLs. Separate what you *verified
|
| 24 |
-
yourself* from what you read second-hand; label the weak ones.
|
| 25 |
-
- **Blockers** — what must be resolved before this can ship.
|
| 26 |
-
- **Lesson** — anything generalizable to other sources. Optional.
|
| 27 |
-
|
| 28 |
-
Write down the API endpoints and quirks you had to dig for. That digging is the
|
| 29 |
-
expensive part, and it is invisible in a verdict line.
|
| 30 |
-
|
| 31 |
-
---
|
| 32 |
-
|
| 33 |
-
## zpe.gov.pl — Zintegrowana Platforma Edukacyjna
|
| 34 |
-
|
| 35 |
-
**Investigated:** 2026-08-27
|
| 36 |
-
**Verdict:** `hold` — technically very tractable, blocked on per-material license
|
| 37 |
-
evidence. Do not build a fetcher until the license question below is answered.
|
| 38 |
-
|
| 39 |
-
Ministry of Education platform (successor to `epodreczniki.pl`), e-materials
|
| 40 |
-
across all school subjects. Attractive because the corpus has **no modern
|
| 41 |
-
instructional/pedagogic register at all**, and this is contemporary, clean,
|
| 42 |
-
editorially reviewed Polish prose.
|
| 43 |
-
|
| 44 |
-
### Enumeration — solved
|
| 45 |
-
|
| 46 |
-
There is no sitemap (`/sitemap.xml` → 404) and site search is client-side, but
|
| 47 |
-
`https://zpe.gov.pl/config.js` exposes an undocumented JSON API:
|
| 48 |
-
|
| 49 |
-
```
|
| 50 |
-
window.CP_CONFIGURATION = {... "apiUrl":"https://zpe.gov.pl/api/v1/" ...}
|
| 51 |
-
```
|
| 52 |
-
|
| 53 |
-
```
|
| 54 |
-
GET https://zpe.gov.pl/api/v1/search?query=&limit=20&offset=N
|
| 55 |
-
→ {"count": 23843, "offset": 0, "limit": 20,
|
| 56 |
-
"data": [{"id": "P18l4AKOi", "title": "Fotosynteza",
|
| 57 |
-
"subject": [...], "stage": [...], "tags": [], ...}]}
|
| 58 |
-
```
|
| 59 |
-
|
| 60 |
-
Verified directly (2026-08-27):
|
| 61 |
-
|
| 62 |
-
- `count` = **23,843** materials for the empty query.
|
| 63 |
-
- Deep paging works — `offset=5000` returns rows, no cursor needed.
|
| 64 |
-
- `robots.txt` is `User-agent: * / Allow: /`.
|
| 65 |
-
- Article pages `/a/<slug>/<CODE>` are **fully server-rendered**; text lives in
|
| 66 |
-
`data-editor-content` blocks. No JS execution required to extract prose.
|
| 67 |
-
- Book pages `/b/<slug>/<CODE>` render their material list client-side (0
|
| 68 |
-
server-side `/a/` links), so `/b/` is useless for crawling. Use the API.
|
| 69 |
-
|
| 70 |
-
Other endpoints probed and 404: `api/v1/materials`, `api/v1/document(s)/<CODE>`,
|
| 71 |
-
`api/v1/footer`, `api/v1/menu`, `api/v1/search/materials`. Only
|
| 72 |
-
`api/v1/search?query=` responded.
|
| 73 |
-
|
| 74 |
-
### License evidence — the blocker
|
| 75 |
-
|
| 76 |
-
**Verified directly:**
|
| 77 |
-
|
| 78 |
-
- **No document-level license marker exists in the served HTML.** The only
|
| 79 |
-
machine-readable license strings are per-figure, inside
|
| 80 |
-
`<div class="figure_caption_bibliography">`, e.g.
|
| 81 |
-
`Źródło: GroMar, licencja: CC BY 3.0.` and
|
| 82 |
-
`Źródło: Sławomir Szaruga, licencja: CC BY 3.0.` These attach to
|
| 83 |
-
**illustrations, not to the prose**.
|
| 84 |
-
- **The site footer is `<div id="footer_app"></div>` — JS-rendered.** This
|
| 85 |
-
matters: the accepted legal basis for both `govpl` and `samorzad_gov_pl` in
|
| 86 |
-
`src/sources.py` is a *server-side footer string* declaring CC BY-SA 4.0.
|
| 87 |
-
ZPE has no such string. **That precedent does not transfer to ZPE.**
|
| 88 |
-
- The platform `regulamin` states:
|
| 89 |
-
*"Korzystanie z Materiału odbywać się może tylko i wyłącznie w zakresie
|
| 90 |
-
dozwolonym przepisami ustawy o prawie autorskim i prawach pokrewnych"* —
|
| 91 |
-
statutory permitted-use only, which is not an open license. Reading the
|
| 92 |
-
surrounding clauses, this section appears scoped to material *uploaded by
|
| 93 |
-
users to* the platform rather than to ministry e-materials, but the wording is
|
| 94 |
-
not self-limiting and a reviewer will land on it.
|
| 95 |
-
|
| 96 |
-
**Second-hand, not verified — confirm before relying on any of it:**
|
| 97 |
-
|
| 98 |
-
- Ministry-produced e-materials are said to be CC BY 3.0, funded under
|
| 99 |
-
POKL 2007–2013 / POWER 2014–2020.
|
| 100 |
-
- User-contributed materials are reported to carry **CC BY-NC-SA 4.0**. NC is
|
| 101 |
-
already on the reject list (`source_scouting_v0_3.md`), so those must be
|
| 102 |
-
excluded, not merely flagged.
|
| 103 |
-
- Literary works embedded in e-materials are reported to sit under a
|
| 104 |
-
non-free *"licencja edukacyjna"* where authors or heirs did not agree to open
|
| 105 |
-
release. This is the highest-risk content class on the platform.
|
| 106 |
-
|
| 107 |
-
### Consequences for design
|
| 108 |
-
|
| 109 |
-
- ZPE cannot be a single-license shard. It has to be **per-record license-gated**,
|
| 110 |
-
`license_spdx: MIXED`, same shape as `biblioteka_nauki` and `europeana`.
|
| 111 |
-
- Available heuristic, **not** license evidence: ministry materials come back with
|
| 112 |
-
`subject` and `stage` populated; user uploads return `"subject": [], "stage": []`
|
| 113 |
-
(the first empty-query result is an all-caps user upload with both empty). Usable
|
| 114 |
-
as a pre-filter, useless as provenance.
|
| 115 |
-
- Rough size if ~10–15k ministry materials survive the gate: **~30–100M tokens**.
|
| 116 |
-
Estimate only — nothing was counted. Good register, modest scale.
|
| 117 |
-
|
| 118 |
-
### Extraction hazards (seen in a single sampled page)
|
| 119 |
-
|
| 120 |
-
- Interactive-exercise chrome: `Pokaż podpowiedź`, `Pokaż odpowiedź` buttons.
|
| 121 |
-
- JSON blobs embedded in `data-editor-params` attributes (`gameTitle`,
|
| 122 |
-
`feedbackPositive`, …) — must not leak into `text`.
|
| 123 |
-
- Per-figure attribution lines repeated throughout the body.
|
| 124 |
-
- Glossary / `Zapamiętaj!` boilerplate repeated across many materials — needs
|
| 125 |
-
frequency-based boilerplate detection, not a hand-written blocklist.
|
| 126 |
-
|
| 127 |
-
### What would unblock this
|
| 128 |
-
|
| 129 |
-
Any one of: a resolvable per-material license field (API or page markup); an
|
| 130 |
-
authoritative ORE/MEN page granting open reuse of e-material *text*; or written
|
| 131 |
-
permission. Absent that, ZPE stays out — the datasheet could not honestly answer
|
| 132 |
-
"where does the license statement live", which is a required field for any PR.
|
| 133 |
-
|
| 134 |
-
### Lesson
|
| 135 |
-
|
| 136 |
-
Check for a **server-rendered** license statement early. A JS-rendered footer is
|
| 137 |
-
not usable license evidence, and "it's a `gov.pl` domain" is not a license — the
|
| 138 |
-
`govpl` and `samorzad_gov_pl` entries hold up because a specific footer string
|
| 139 |
-
was fetched and quoted, not because of the domain.
|
| 140 |
-
|
| 141 |
-
---
|
| 142 |
-
|
| 143 |
-
## ParlaMint-PL — parliamentary debates 2015–2022
|
| 144 |
-
|
| 145 |
-
**Investigated:** 2026-08-27
|
| 146 |
-
**Verdict:** `ready to build, low yield` — license and distribution verified, the
|
| 147 |
-
fetcher is the only missing piece. But it is a **date-hole patch worth ~36M
|
| 148 |
-
net-new tokens**, not a diversity win. Size it before prioritising it.
|
| 149 |
-
|
| 150 |
-
Already registered in `src/sources.py` as `parlamint_pl`, but there is **no shard
|
| 151 |
-
in `data/`**.
|
| 152 |
-
|
| 153 |
-
### Size — measured, not guessed
|
| 154 |
-
|
| 155 |
-
From the official stats at
|
| 156 |
-
`github.com/clarin-eric/ParlaMint/tree/v5.0/Build/Metadata`
|
| 157 |
-
(`ParlaMint-overview-stats.tsv`, `ParlaMint-speeches-stats.tsv`):
|
| 158 |
-
|
| 159 |
-
```
|
| 160 |
-
ID Lang Bodies Ts From To Yrs Mw/Yr Mw
|
| 161 |
-
PL pl low+upp 4 2015-11 2022-06 6.7 5.35 36.06
|
| 162 |
-
```
|
| 163 |
-
|
| 164 |
-
- **36.06M words**, **228,326 speeches**, 4 terms, both chambers.
|
| 165 |
-
- Token conversion measured on our own `parliamentary` shard (same register, same
|
| 166 |
-
cl100k encoder; 6,000 docs / 9.7M words): **2.654 tokens/word**, 7.24 chars/word.
|
| 167 |
-
- → **~96M tokens gross**, ≈1% of the current 9.68B corpus.
|
| 168 |
-
- Download: `ParlaMint-PL.tgz`, 185.3 MB.
|
| 169 |
-
|
| 170 |
-
### Overlap with the existing `parliamentary` shard — the real issue
|
| 171 |
-
|
| 172 |
-
ParlaMint-PL is **derived from PPC**, which is exactly what the `parliamentary`
|
| 173 |
-
shard is (1991–2019). Time overlap runs 2015-11 → 2019-12, about 4.2 of the 6.7
|
| 174 |
-
years, ≈22M words likely already present. **Net new ≈ 14M words ≈ 36M tokens**,
|
| 175 |
-
covering 2020-01 → 2022-06.
|
| 176 |
-
|
| 177 |
-
That estimate is soft in both directions:
|
| 178 |
-
|
| 179 |
-
- `parliamentary` has **no per-document dates** — `created` is the single literal
|
| 180 |
-
`'1991-01-01, 2019-12-31'` on all 324,622 rows. The overlap cannot be measured
|
| 181 |
-
by filtering, only by comparing content.
|
| 182 |
-
- PPC includes committee sittings and interpellations; ParlaMint-PL is plenary
|
| 183 |
-
only. So ParlaMint's 2015–2019 portion is plausibly a *subset* of what already
|
| 184 |
-
ships, making the real overlap higher than the time-share implies.
|
| 185 |
-
|
| 186 |
-
**Exact dedup will not catch this.** `build_dynaword.py` dedups on `sha1` of the
|
| 187 |
-
whole document. ParlaMint ships one document per session; PPC's segmentation
|
| 188 |
-
differs, so byte-identical documents are unlikely and the duplicates pass
|
| 189 |
-
straight through the gate. This needs **near-dedup, for which the repo has no
|
| 190 |
-
committed tooling** — the HPLT expansion's near-dedup was run outside `src/`.
|
| 191 |
-
Budget for that, or the shard silently duplicates existing data.
|
| 192 |
-
|
| 193 |
-
### Version note
|
| 194 |
-
|
| 195 |
-
**ParlaMint 5.0 does not extend Polish** — PL still ends 2022-06, same as the 3.0
|
| 196 |
-
deposit already cited in `sources.py` (handle `11356/1486`; 5.0 is `11356/2004`).
|
| 197 |
-
Upgrading buys corrections, not coverage. Neither version closes the gap to
|
| 198 |
-
`sejm_api` (2023 onward): mid-2022 through end-2022 stays empty.
|
| 199 |
-
|
| 200 |
-
### Verified
|
| 201 |
-
|
| 202 |
-
- CLARIN.SI handle `11356/1486` resolves (HTTP 200). The `upstream` URL recorded
|
| 203 |
-
in `sources.py` is correct and live.
|
| 204 |
-
- License: **CC BY 4.0**, stated on the repository record.
|
| 205 |
-
- ParlaMint 3.0 overall: 26 comparable corpora, 7,468,674 utterances,
|
| 206 |
-
1,147,800,265 words; debates mostly 2015 → mid-2022.
|
| 207 |
-
- The distribution ships a **plain-text (`.txt`) edition** alongside TEI/XML and
|
| 208 |
-
linguistically-annotated `.ana.xml`. Filenames are per-session, e.g.
|
| 209 |
-
`ParlaMint-PL_2017-07-20-sejm-46-3.txt`. Use the `.txt` edition — no TEI parsing
|
| 210 |
-
needed.
|
| 211 |
-
- Polish covers **both chambers**: `-sejm-` and `-senat-` session files.
|
| 212 |
-
|
| 213 |
-
### Why it is still worth doing
|
| 214 |
-
|
| 215 |
-
Fills 2020 → mid-2022, between `parliamentary` (ends 2019) and `sejm_api` (2023
|
| 216 |
-
onward). Same CC-BY-4.0 family as existing sources, so there is no new license
|
| 217 |
-
question to answer, and the plain-text edition means no TEI parsing. Cheap. Just
|
| 218 |
-
do not expect it to move the totals — and do not build it before a source that
|
| 219 |
-
adds a register the corpus lacks.
|
| 220 |
-
|
| 221 |
-
### Drift found while checking
|
| 222 |
-
|
| 223 |
-
`src/sources.py` (the `parlamint_pl` `provenance` field) states the corpus was
|
| 224 |
-
*"Fetched directly from the CLARIN.SI plain-text edition (ParlaMint-PL.tgz) by
|
| 225 |
-
`src/fetch_parlamint.py`"*. **That script does not exist in `src/`.** The
|
| 226 |
-
provenance describes a fetch that no committed code performs. Either write the
|
| 227 |
-
script or correct the field before this ships.
|
| 228 |
-
|
| 229 |
-
---
|
| 230 |
-
|
| 231 |
-
## Sejm API — interpelacje and zapytania poselskie
|
| 232 |
-
|
| 233 |
-
**Investigated:** 2026-08-27
|
| 234 |
-
**Verdict:** `hold — recheck`. Not a license problem; `api.sejm.gov.pl` was
|
| 235 |
-
unreachable from the investigating network on the day, so the endpoints could not
|
| 236 |
-
be confirmed. Retry before writing anything off.
|
| 237 |
-
|
| 238 |
-
### What happened
|
| 239 |
-
|
| 240 |
-
- `api.sejm.gov.pl` resolves (`194.41.12.231`) but every request hangs and then
|
| 241 |
-
fails — plain `curl` times out at 45s, a proxied fetch returns `ECONNRESET`.
|
| 242 |
-
- `https://www.sejm.gov.pl/` responds normally (302), and other external hosts
|
| 243 |
-
were fine the same session, so this is specific to the API host: either an
|
| 244 |
-
outage, or that host filtering the source network.
|
| 245 |
-
- `src/fetch_sejm_api.py` (committed, working) uses this same host, so the API
|
| 246 |
-
is normally reachable. Treat as transient until proven otherwise.
|
| 247 |
-
|
| 248 |
-
### Unverified — what to check on retry
|
| 249 |
-
|
| 250 |
-
- Whether `sejm/term{N}/interpellations` and `sejm/term{N}/writtenQuestions`
|
| 251 |
-
exist, and their paging parameters.
|
| 252 |
-
- Whether the **ministry's reply body** is retrievable as text, or only as a
|
| 253 |
-
linked PDF. This decides whether the source is worth building: the replies are
|
| 254 |
-
the substantial half.
|
| 255 |
-
- Document counts per term.
|
| 256 |
-
|
| 257 |
-
### Why it is on the list
|
| 258 |
-
|
| 259 |
-
Reuses the existing `fetch_sejm_api.py` legal basis unchanged — official
|
| 260 |
-
parliamentary materials outside copyright under art. 4(2) pr. aut., reusable
|
| 261 |
-
under the Open Data Act. Question/answer prose is argumentative register, which
|
| 262 |
-
the corpus is short on. No new license work needed.
|
| 263 |
-
|
| 264 |
-
---
|
| 265 |
-
|
| 266 |
-
## CLARIN-PL DSpace (PELCRA Spokes, and the `1000_novels` upstream)
|
| 267 |
-
|
| 268 |
-
**Investigated:** 2026-08-27
|
| 269 |
-
**Verdict:** `blocked — temporary`. The repository is down for reorganization.
|
| 270 |
-
Nothing to decide until it returns.
|
| 271 |
-
|
| 272 |
-
### Verified
|
| 273 |
-
|
| 274 |
-
- `https://clarin-pl.eu/dspace/` serves a maintenance notice:
|
| 275 |
-
*"Trwają prace nad repozytorium. Prowadzimy prace serwisowe oraz reorganizację
|
| 276 |
-
repozytorium DSpace… Repozytorium będzie ponownie dostępne wkrótce."*
|
| 277 |
-
- Every item handle under it 404s: `11321/312`, `11321/544`, `11321/545`,
|
| 278 |
-
`11321/547` — nginx 404, not a DSpace "item not found".
|
| 279 |
-
- The global resolver is broken for this prefix too: `hdl.handle.net/11321/*`
|
| 280 |
-
returns **HTTP 500**.
|
| 281 |
-
|
| 282 |
-
So no PELCRA record (Spokes, EMO, PARL, EMI) can have its license checked right
|
| 283 |
-
now. Conversational Polish remains the corpus's biggest register gap, so this is
|
| 284 |
-
worth re-checking periodically.
|
| 285 |
-
|
| 286 |
-
### Side effect on shipped data
|
| 287 |
-
|
| 288 |
-
`src/sources.py` records `https://clarin-pl.eu/dspace/handle/11321/312` as the
|
| 289 |
-
`upstream` for **`1000_novels`**, which is a released shard. That URL currently
|
| 290 |
-
does not resolve. Presumed temporary, but the citation in a published datasheet
|
| 291 |
-
is dead as of this date.
|
| 292 |
-
|
| 293 |
-
### Expected concern when it returns
|
| 294 |
-
|
| 295 |
-
PELCRA spoken corpora are transcribed private conversation. Expect NC-flavoured
|
| 296 |
-
or restricted licensing, and expect a personal-data question — these recordings
|
| 297 |
-
involve identifiable private individuals, not public officials acting officially.
|
| 298 |
-
Both must be resolved before use.
|
| 299 |
-
|
| 300 |
-
---
|
| 301 |
-
|
| 302 |
-
## NIK — Najwyższa Izba Kontroli audit reports
|
| 303 |
-
|
| 304 |
-
**Investigated:** 2026-08-27
|
| 305 |
-
**Verdict:** `hold` — permissive but **non-standard** license, and enumeration is
|
| 306 |
-
unsolved. Viable with work; not a quick win.
|
| 307 |
-
|
| 308 |
-
### License evidence — verified
|
| 309 |
-
|
| 310 |
-
`https://www.nik.gov.pl/zasady/prawa-autorskie.html` states:
|
| 311 |
-
|
| 312 |
-
> *"Korzystanie z materiałów publikowanych w serwisach internetowych Najwyższej
|
| 313 |
-
> Izby Kontroli nie wymaga uzyskania zgody NIK. Nie dotyczy to elementów odrębnie
|
| 314 |
-
> zastrzeżonych (do których prawa autorskie przysługują osobom trzecim), w
|
| 315 |
-
> szczególności oznaczonych materiałów zdjęciowych oraz tekstów publikowanych
|
| 316 |
-
> pierwotnie w innych źródłach."*
|
| 317 |
-
|
| 318 |
-
Attribution to *"Najwyższa Izba Kontroli (nik.gov.pl)"* is requested, not required.
|
| 319 |
-
|
| 320 |
-
Assessment: a **custom permissive notice, not a standard open license** — no CC,
|
| 321 |
-
no CC0, no SPDX identifier. It carries a third-party carve-out that matters here,
|
| 322 |
-
because audit reports quote external sources. A separate and probably stronger
|
| 323 |
-
argument is that audit reports are *materiały urzędowe* under art. 4 pkt 2 pr.
|
| 324 |
-
aut., the same basis as `dziennik_ustaw` and `sejm_api`. If this source is built,
|
| 325 |
-
lead with the statutory argument and cite the site notice as corroboration.
|
| 326 |
-
|
| 327 |
-
### Enumeration — unsolved
|
| 328 |
-
|
| 329 |
-
- `robots.txt` allows crawling, but disallows `/szukaj/`, `/p/`, `/g2/`,
|
| 330 |
-
`/cms/`, `/do_druku/`. `/g2/` looks like the file store, which likely means
|
| 331 |
-
**report PDFs are off-limits to crawlers**.
|
| 332 |
-
- `/kontrole/wyniki-kontroli-nik/` returns 200 (~72 kB) but the report list is
|
| 333 |
-
**JS-rendered**: zero report links in the server HTML, only pagination
|
| 334 |
-
scaffolding (`fmax,js,strona,1.html`).
|
| 335 |
-
- The `/prosta/` ("simple") variant is also JS-rendered — 0 report links.
|
| 336 |
-
- No `/sitemap.xml` (404).
|
| 337 |
-
|
| 338 |
-
Same shape as ZPE: a backend API almost certainly exists and would need to be
|
| 339 |
-
found (check the page's JS config for an `apiUrl`, as worked for ZPE).
|
| 340 |
-
|
| 341 |
-
### Verdict rationale
|
| 342 |
-
|
| 343 |
-
Register value is real — long-form analytical prose, unlike statute text. But
|
| 344 |
-
between a bespoke license, a third-party-content carve-out, PDF paths blocked by
|
| 345 |
-
`robots.txt`, and unsolved enumeration, this is several days of work. Lower
|
| 346 |
-
priority than ParlaMint-PL or Sejm interpelacje.
|
| 347 |
-
|
| 348 |
-
---
|
| 349 |
-
|
| 350 |
-
## Billion-scale survey — what can actually move the totals
|
| 351 |
-
|
| 352 |
-
**Investigated:** 2026-08-27
|
| 353 |
-
|
| 354 |
-
Context: most candidates land at 30–200M tokens, which is noise against a 9.68B
|
| 355 |
-
corpus. This entry records the only options measured at **500M–5B**, i.e.
|
| 356 |
-
comparable to `european_hplt_v3_pl` (2.56B), `eurlex` (2.38B), `parliamentary`
|
| 357 |
-
(1.65B). All numbers below were measured on the day, not taken from cards.
|
| 358 |
-
|
| 359 |
-
Token conversion throughout: **2.654 tokens/word**, measured on the repo's own
|
| 360 |
-
`parliamentary` shard (6,000 docs / 9.7M words, cl100k). Use it instead of
|
| 361 |
-
guessing — Polish runs far above the ~1.3 rule of thumb for English.
|
| 362 |
-
|
| 363 |
-
| candidate | measured | est. tokens | license | blocker |
|
| 364 |
-
|---|---|---|---|---|
|
| 365 |
-
| SAOS judgments | 540,338 docs, mean 3,067 w | **~4.4B** (floor ~2.8B) | art. 4 pkt 2 pr. aut. | register: pure legal |
|
| 366 |
-
| FineWeb-2 `pol_Latn` | 152,003,298 docs, 225.9 GB | ~83B raw, **4–8B** filtered | ODC-By | dedup vs existing HPLT |
|
| 367 |
-
| PleIAs/Polish-PD | 68,176 docs, 0.75B words | **~2.0B** nominal | public domain | OCR corruption |
|
| 368 |
-
| HPLT leftovers | shards `8_5`, `8_6`, 31.6 GB | ~230M | CC0 | none — just small |
|
| 369 |
-
|
| 370 |
-
### SAOS — biggest clean win, already half-built
|
| 371 |
-
|
| 372 |
-
`https://www.saos.org.pl/api/search/judgments?pageSize=1&pageNumber=0` reports
|
| 373 |
-
`totalResults: 540338`. Sampled 100 judgments from
|
| 374 |
-
`api/dump/judgments?pageSize=100&pageNumber=0`: **mean 3,067 words, median 1,920,
|
| 375 |
-
p10 816, p90 7,197**, court types `COMMON` and `CONSTITUTIONAL_TRIBUNAL`.
|
| 376 |
-
|
| 377 |
-
540,338 × 3,067 = 1.66B words → **~4.4B tokens**. Using the median instead, to
|
| 378 |
-
guard against long-tail skew, still gives ~2.75B. Either way this is **larger
|
| 379 |
-
than any shard currently in the corpus**.
|
| 380 |
-
|
| 381 |
-
`src/fetch_saos.py` already exists (uncommitted as of this date) and documents the
|
| 382 |
-
legal basis: judgments are *materiały urzędowe* outside copyright under art. 4
|
| 383 |
-
pkt 2 pr. aut., redistributed by SAOS (CeON/ICM UW + Fundacja ePaństwo) through a
|
| 384 |
-
bulk-dump API built for exactly this.
|
| 385 |
-
|
| 386 |
-
Open question before building: judgments are court-anonymised, but that should be
|
| 387 |
-
**verified on sampled text**, not assumed — this is the one candidate here where
|
| 388 |
-
personal data is a live risk rather than a formality.
|
| 389 |
-
|
| 390 |
-
Cost of shipping it: legal/official goes from **48% to roughly 65%** of the
|
| 391 |
-
corpus. That is the trade, and it should be a deliberate decision rather than a
|
| 392 |
-
side effect of it being the easy build.
|
| 393 |
-
|
| 394 |
-
### FineWeb-2 Polish — only billion-scale contemporary prose
|
| 395 |
-
|
| 396 |
-
`datasets-server` size endpoint, config `pol_Latn`: **152,003,298 rows /
|
| 397 |
-
225.9 GB**. At the measured 0.367 tokens/char that is **~83B tokens raw**.
|
| 398 |
-
|
| 399 |
-
License `odc-by`. Same argument shape as the accepted HPLT basis: the packaging
|
| 400 |
-
is licensed, the underlying web text is not owned by the publisher. Note that
|
| 401 |
-
ODC-By is **attribution-required**, unlike HPLT's CC0 — a different obligation
|
| 402 |
-
shape, and it has to be stated in the datasheet.
|
| 403 |
-
|
| 404 |
-
#### Dedup is not the bottleneck — this was checked, not assumed
|
| 405 |
-
|
| 406 |
-
The obvious worry is overlap with the existing HPLT shard, since both derive from
|
| 407 |
-
Common Crawl. It is the *smallest* of the problems:
|
| 408 |
-
|
| 409 |
-
- The existing HPLT shard is **1.6M docs against FineWeb-2's 152M**. Even total
|
| 410 |
-
overlap removes ~1% of candidates (~12% if working from the HQ subset below).
|
| 411 |
-
- **Internal dedup is already done upstream.** The schema carries
|
| 412 |
-
`minhash_cluster_size`, i.e. FineWeb-2 ran MinHash per language before release.
|
| 413 |
-
|
| 414 |
-
Cross-dedup against HPLT is still worth doing for hygiene, and the repo still has
|
| 415 |
-
no committed near-dedup tooling — but it is not what makes this source expensive.
|
| 416 |
-
|
| 417 |
-
#### The actual blocker: the HPLT gate cannot be ported
|
| 418 |
-
|
| 419 |
-
FineWeb-2 `pol_Latn` columns are:
|
| 420 |
-
|
| 421 |
-
```
|
| 422 |
-
text, id, dump, url, date, file_path, language,
|
| 423 |
-
language_score, language_script, minhash_cluster_size, top_langs
|
| 424 |
-
```
|
| 425 |
-
|
| 426 |
-
`src/clean_hplt_v3.py` filters on **WDS quality score, register class
|
| 427 |
-
(ID/OP/HI/IN/NA), and MT-probability**. *None of those exist in FineWeb-2.* Every
|
| 428 |
-
signal the existing web pipeline depends on is absent, so "filter it like we
|
| 429 |
-
filtered HPLT" is not an option — it would mean building quality classification
|
| 430 |
-
over 152M documents from scratch.
|
| 431 |
-
|
| 432 |
-
#### `epfml/FineWeb2-HQ` — the better target
|
| 433 |
-
|
| 434 |
-
A published quality-filtered derivative, config `pol_Latn`:
|
| 435 |
-
|
| 436 |
-
- **13,384,885 rows**, `odc-by`, 180.4 GB parquet (size dominated by an
|
| 437 |
-
`embeddings` column, not text).
|
| 438 |
-
- Adds a **`quality_score`** column, retained per document, so the selection
|
| 439 |
-
threshold stays a tunable knob instead of a baked-in decision — and the
|
| 440 |
-
classifier is someone else's published work, which is easier to cite than a
|
| 441 |
-
home-grown one.
|
| 442 |
-
- Sampled 880 docs across 22 evenly-spread offsets: **mean 2,663 chars/doc**
|
| 443 |
-
→ ~13.1B tokens for the whole HQ subset. Larger than the entire current corpus.
|
| 444 |
-
|
| 445 |
-
#### quality_score → token yield
|
| 446 |
-
|
| 447 |
-
Distribution from the `statistics` endpoint (computed on a **partial 407,184-row
|
| 448 |
-
sample**, not all 13.4M): min 0.013, max 0.9999, mean 0.145, **median 0.0496** —
|
| 449 |
-
heavily right-skewed, so most of HQ still scores low.
|
| 450 |
-
|
| 451 |
-
Doc fractions from that histogram, mean lengths from the 880-doc sample:
|
| 452 |
-
|
| 453 |
-
| `quality_score` ≥ | % docs | docs | mean chars | est. tokens |
|
| 454 |
-
|---|---:|---:|---:|---:|
|
| 455 |
-
| 0.00 (all) | 100% | 13,384,885 | 2,663 | **13.1B** |
|
| 456 |
-
| 0.11 | 31.0% | 4,149,000 | 2,375 | **3.6B** |
|
| 457 |
-
| 0.21 | 20.0% | 2,677,000 | 2,074 | **2.0B** |
|
| 458 |
-
| 0.31 | 14.6% | 1,954,000 | 1,929 | **1.4B** |
|
| 459 |
-
| 0.41 | 11.1% | 1,486,000 | 1,912 | **1.0B** |
|
| 460 |
-
| 0.51 | 8.5% | 1,138,000 | 1,798 | **0.75B** |
|
| 461 |
-
| 0.70 | 4.8% | 642,000 | 1,750 | **0.41B** |
|
| 462 |
-
| 0.90 | 1.8% | 241,000 | 914 | **0.08B** |
|
| 463 |
-
|
| 464 |
-
A second pass computing fractions directly from the 880-doc sample agreed with
|
| 465 |
-
these within ~15%. Treat them as ±20%, good enough to pick a threshold.
|
| 466 |
-
|
| 467 |
-
**Watch out: `quality_score` anti-correlates with document length.** Mean length
|
| 468 |
-
falls from 2,663 chars at no threshold to 914 at ≥0.90. The classifier is not
|
| 469 |
-
rewarding long-form prose, so raising the threshold costs more tokens than the
|
| 470 |
-
doc-count alone implies, and it may actively select *against* the extended prose
|
| 471 |
-
this corpus is short on. Sample the text at whatever threshold is chosen before
|
| 472 |
-
committing to it.
|
| 473 |
-
|
| 474 |
-
#### Recommended operating point
|
| 475 |
-
|
| 476 |
-
**Threshold ≈ 0.20 → ~2.7M docs, ~2.0–2.3B tokens.** Comparable to the largest
|
| 477 |
-
existing shards (`european_hplt_v3_pl` 2.56B, `eurlex` 2.38B) and it *improves*
|
| 478 |
-
the balance rather than wrecking it: web goes 26% → ~41%, legal drops 48% → ~39%.
|
| 479 |
-
|
| 480 |
-
Taking all 13.1B instead would put the corpus at ~22.7B with **web at ~69%** —
|
| 481 |
-
trading "two-thirds legalese" for "two-thirds crawl". Same failure, different axis.
|
| 482 |
-
|
| 483 |
-
#### Work order if this is built
|
| 484 |
-
|
| 485 |
-
1. Pick HQ vs full, and a `quality_score` threshold (see above).
|
| 486 |
-
2. **Build the PII scrub.** `sources.py` already claims one for the HPLT shard
|
| 487 |
-
that has no implementing code in `src/`; shipping a second web source with the
|
| 488 |
-
same gap is indefensible.
|
| 489 |
-
3. Near-dedup against the existing HPLT shard — needed, but ~1–12% effect.
|
| 490 |
-
4. Compute. Tokenizing billions of tokens is the genuinely expensive step.
|
| 491 |
-
|
| 492 |
-
### PleIAs/Polish-PD — good on paper, rough in practice
|
| 493 |
-
|
| 494 |
-
68,176 rows. Sampled `word_count` at four offsets (n=200): **mean 10,971 words,
|
| 495 |
-
median 8,468** → ~0.75B words → **~2.0B tokens**. Columns are `identifier`,
|
| 496 |
-
`file`, `title`, `creator`, `language`, `word_count`, `character_count`,
|
| 497 |
-
`complete_text`. Public domain, pre-1884 monographs and periodicals, largely
|
| 498 |
-
sourced from Polish digital libraries (`jbc.bj.uj.edu.pl` in the sample).
|
| 499 |
-
|
| 500 |
-
Register-wise this is the most attractive of the three — books and periodicals,
|
| 501 |
-
against a corpus that is only 1.9% literature.
|
| 502 |
-
|
| 503 |
-
But the OCR is bad. First sampled record (an 1817 newspaper) opens:
|
| 504 |
-
|
| 505 |
-
```
|
| 506 |
-
U
|
| 507 |
-
RUSKI
|
| 508 |
-
czwaRTEŁ SONAER
|
| 509 |
-
5 PC Nę R
|
| 510 |
-
WIADOMOŚC
|
| 511 |
-
```
|
| 512 |
-
|
| 513 |
-
with pre-1884 orthography throughout (`Nayiaśnieyszy`, `roskazać`, `klassy`).
|
| 514 |
-
|
| 515 |
-
**The existing OCR gate will not catch this.** `build_dynaword.py` applies
|
| 516 |
-
`MIN_ALPHA_RATIO = 0.70` when `is_ocr: True`, which tests the ratio of letters to
|
| 517 |
-
symbols. Garbled *words* made of ordinary letters pass it cleanly. Filtering this
|
| 518 |
-
source needs a dictionary- or perplexity-based check, which does not exist here.
|
| 519 |
-
Treat the 2.0B as nominal; real usable yield is materially lower.
|
| 520 |
-
|
| 521 |
-
### HPLT is exhausted — correction to an earlier assumption
|
| 522 |
-
|
| 523 |
-
`https://data.hplt-project.org/three/sorted/pol_Latn/` lists **exactly 19 shards**:
|
| 524 |
-
`10_1`, `9_1`–`9_4`, `8_1`–`8_6`, `7_1`–`7_4`, `6_1`–`6_2`, `5_1`–`5_2`.
|
| 525 |
-
**There are no WDS bins below 5 for Polish.**
|
| 526 |
-
|
| 527 |
-
`sources.py` records 17 of those as ingested. The only unused shards are
|
| 528 |
-
**`8_5` (24.24 GB)** and **`8_6` (7.37 GB)** — roughly 230M tokens at the
|
| 529 |
-
post-filter rate implied by the existing shard.
|
| 530 |
-
|
| 531 |
-
So "add more HPLT bins" is not a path to billions. It is one small top-up, and
|
| 532 |
-
then the source is finished.
|
| 533 |
-
|
| 534 |
-
### Conclusion
|
| 535 |
-
|
| 536 |
-
Every clean billion-scale Polish source is **legal, official, or archaic** —
|
| 537 |
-
which follows directly from what falls outside copyright. The only billion-scale
|
| 538 |
-
contemporary general prose is web crawl, and that is a re-derivation of Common
|
| 539 |
-
Crawl the corpus already draws on.
|
| 540 |
-
|
| 541 |
-
If the goal is raw scale: SAOS. If the goal is a corpus that is not two-thirds
|
| 542 |
-
legalese, **there is no billion-scale option**, and the honest plan is a number of
|
| 543 |
-
50–200M-token sources across different registers.
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
artifacts/uzp_orzeczenia_pl_ontology_manifest.json
DELETED
|
@@ -1,134 +0,0 @@
|
|
| 1 |
-
{
|
| 2 |
-
"actors": [
|
| 3 |
-
{
|
| 4 |
-
"id": "actor:piotrsty",
|
| 5 |
-
"type": "Contributor"
|
| 6 |
-
},
|
| 7 |
-
{
|
| 8 |
-
"id": "actor:uzp",
|
| 9 |
-
"type": "Organization"
|
| 10 |
-
},
|
| 11 |
-
{
|
| 12 |
-
"id": "actor:devin",
|
| 13 |
-
"type": "Agent"
|
| 14 |
-
}
|
| 15 |
-
],
|
| 16 |
-
"claims": [
|
| 17 |
-
{
|
| 18 |
-
"falsification_condition": "The pinned Parquet, decisions or overlap report do not reproduce these counts.",
|
| 19 |
-
"id": "claim:uzp-target-retention",
|
| 20 |
-
"statement": "The proposed DynaWord slice contains 34715 records after excluding 0 signature overlaps.",
|
| 21 |
-
"supported_by": [
|
| 22 |
-
"evidence:uzp-target-stats:57384373cb2c3883fb240ab0468d309dc62893a01ccd939f25081a931a1c20c0",
|
| 23 |
-
"evidence:uzp-target-overlap:d70053726c85373e3411cc28da26c3aeffbd25cf9adf7c30a3ecdda3ebeaef10"
|
| 24 |
-
]
|
| 25 |
-
},
|
| 26 |
-
{
|
| 27 |
-
"falsification_condition": "Target-wide text deduplication and controlled ablations establish those properties.",
|
| 28 |
-
"id": "claim:uzp-training-value-untested",
|
| 29 |
-
"statement": "Net text novelty and training benefit remain untested hypotheses.",
|
| 30 |
-
"supported_by": [
|
| 31 |
-
"evidence:uzp-target-overlap:d70053726c85373e3411cc28da26c3aeffbd25cf9adf7c30a3ecdda3ebeaef10"
|
| 32 |
-
]
|
| 33 |
-
}
|
| 34 |
-
],
|
| 35 |
-
"evidence": [
|
| 36 |
-
{
|
| 37 |
-
"artifact": "data/uzp_orzeczenia_pl/uzp_orzeczenia_pl.stats.json",
|
| 38 |
-
"content_address": "57384373cb2c3883fb240ab0468d309dc62893a01ccd939f25081a931a1c20c0",
|
| 39 |
-
"id": "evidence:uzp-target-stats:57384373cb2c3883fb240ab0468d309dc62893a01ccd939f25081a931a1c20c0",
|
| 40 |
-
"observation_type": "target_slice_counts",
|
| 41 |
-
"produced_by": "run:uzp-orzeczenia-dynaword-integration:57384373cb2c3883fb240ab0468d309dc62893a01ccd939f25081a931a1c20c0"
|
| 42 |
-
},
|
| 43 |
-
{
|
| 44 |
-
"artifact": "data/uzp_orzeczenia_pl/uzp_orzeczenia_pl.overlap_audit.json",
|
| 45 |
-
"content_address": "d70053726c85373e3411cc28da26c3aeffbd25cf9adf7c30a3ecdda3ebeaef10",
|
| 46 |
-
"id": "evidence:uzp-target-overlap:d70053726c85373e3411cc28da26c3aeffbd25cf9adf7c30a3ecdda3ebeaef10",
|
| 47 |
-
"observation_type": "metadata_overlap_audit",
|
| 48 |
-
"produced_by": "run:uzp-orzeczenia-dynaword-integration:57384373cb2c3883fb240ab0468d309dc62893a01ccd939f25081a931a1c20c0"
|
| 49 |
-
}
|
| 50 |
-
],
|
| 51 |
-
"objects": [
|
| 52 |
-
{
|
| 53 |
-
"id": "object:dataset:uzp-orzeczenia-pl",
|
| 54 |
-
"type": "Dataset"
|
| 55 |
-
},
|
| 56 |
-
{
|
| 57 |
-
"id": "object:dataset:uzp-orzeczenia-pl-dynaword-slice",
|
| 58 |
-
"type": "Dataset"
|
| 59 |
-
}
|
| 60 |
-
],
|
| 61 |
-
"pending": [
|
| 62 |
-
"formal legal review of art. 4(2) application",
|
| 63 |
-
"cross-source text deduplication",
|
| 64 |
-
"benchmark contamination check",
|
| 65 |
-
"review of quoted third-party text",
|
| 66 |
-
"controlled training ablation"
|
| 67 |
-
],
|
| 68 |
-
"protocols": [
|
| 69 |
-
{
|
| 70 |
-
"id": "protocol:uzp-orzeczenia-dynaword-integration-v1",
|
| 71 |
-
"procedure": "exclude source-QA failures and signature overlaps with pinned saos; preserve attribution and pending text-level gates"
|
| 72 |
-
}
|
| 73 |
-
],
|
| 74 |
-
"relations": [
|
| 75 |
-
{
|
| 76 |
-
"predicate": "DERIVED_FROM",
|
| 77 |
-
"source": "version:dataset:uzp-orzeczenia-pl-dynaword:2c7a13f99ee5571aa66a4d576a6b6705a3a896675ffc93d889447ca0ed9aae1a",
|
| 78 |
-
"target": "hf:dataset:PiotrSty/uzp-orzeczenia-pl@696485691e9f8cb85d1a34221897250e25359ba0"
|
| 79 |
-
},
|
| 80 |
-
{
|
| 81 |
-
"predicate": "GENERATED_BY",
|
| 82 |
-
"source": "version:dataset:uzp-orzeczenia-pl-dynaword:2c7a13f99ee5571aa66a4d576a6b6705a3a896675ffc93d889447ca0ed9aae1a",
|
| 83 |
-
"target": "run:uzp-orzeczenia-dynaword-integration:57384373cb2c3883fb240ab0468d309dc62893a01ccd939f25081a931a1c20c0"
|
| 84 |
-
},
|
| 85 |
-
{
|
| 86 |
-
"predicate": "VALIDATED_AGAINST",
|
| 87 |
-
"source": "version:dataset:uzp-orzeczenia-pl-dynaword:2c7a13f99ee5571aa66a4d576a6b6705a3a896675ffc93d889447ca0ed9aae1a",
|
| 88 |
-
"target": "hf:dataset:SlayerLab/polish-dynaword@bade8e7cae51bd30e9530c3be38dd0e3eeba1f70"
|
| 89 |
-
}
|
| 90 |
-
],
|
| 91 |
-
"runs": [
|
| 92 |
-
{
|
| 93 |
-
"actor": "actor:devin",
|
| 94 |
-
"finished_at": "2026-09-19T06:14:52.208957+00:00",
|
| 95 |
-
"id": "run:uzp-orzeczenia-dynaword-integration:57384373cb2c3883fb240ab0468d309dc62893a01ccd939f25081a931a1c20c0",
|
| 96 |
-
"protocol": "protocol:uzp-orzeczenia-dynaword-integration-v1",
|
| 97 |
-
"started_at": "2026-09-19T06:14:52.208957+00:00",
|
| 98 |
-
"stats": {
|
| 99 |
-
"added": "2026-09-17",
|
| 100 |
-
"characters": 1110428704,
|
| 101 |
-
"enumerated": 35694,
|
| 102 |
-
"kept": 34715,
|
| 103 |
-
"license_counts": {
|
| 104 |
-
"public-domain (official documents)": 34715
|
| 105 |
-
},
|
| 106 |
-
"per_kind": {
|
| 107 |
-
"KIO": 34412,
|
| 108 |
-
"SA": 3,
|
| 109 |
-
"SN": 2,
|
| 110 |
-
"SO": 1277
|
| 111 |
-
},
|
| 112 |
-
"sample_count": 12,
|
| 113 |
-
"source_slice_kept": 34715,
|
| 114 |
-
"target_overlap_excluded": 0,
|
| 115 |
-
"target_revision": "bade8e7cae51bd30e9530c3be38dd0e3eeba1f70",
|
| 116 |
-
"tokens": 422043881
|
| 117 |
-
},
|
| 118 |
-
"success": true
|
| 119 |
-
}
|
| 120 |
-
],
|
| 121 |
-
"schema": "slayer-research-ontology-profile-v1",
|
| 122 |
-
"versions": [
|
| 123 |
-
{
|
| 124 |
-
"content_address": "696485691e9f8cb85d1a34221897250e25359ba0",
|
| 125 |
-
"id": "hf:dataset:PiotrSty/uzp-orzeczenia-pl@696485691e9f8cb85d1a34221897250e25359ba0",
|
| 126 |
-
"object": "object:dataset:uzp-orzeczenia-pl"
|
| 127 |
-
},
|
| 128 |
-
{
|
| 129 |
-
"content_address": "2c7a13f99ee5571aa66a4d576a6b6705a3a896675ffc93d889447ca0ed9aae1a",
|
| 130 |
-
"id": "version:dataset:uzp-orzeczenia-pl-dynaword:2c7a13f99ee5571aa66a4d576a6b6705a3a896675ffc93d889447ca0ed9aae1a",
|
| 131 |
-
"object": "object:dataset:uzp-orzeczenia-pl-dynaword-slice"
|
| 132 |
-
}
|
| 133 |
-
]
|
| 134 |
-
}
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
data/biblioteka_nauki/biblioteka_nauki.md
DELETED
|
@@ -1,60 +0,0 @@
|
|
| 1 |
-
# biblioteka_nauki
|
| 2 |
-
|
| 3 |
-
Biblioteka Nauki — Polish open-access scholarly corpus (scientific articles, books, chapters)
|
| 4 |
-
|
| 5 |
-
## Dataset description
|
| 6 |
-
- **Source (upstream):** https://bibliotekanauki.pl (operated by ICM, University of Warsaw — Centrum Otwartej Nauki)
|
| 7 |
-
- **Domain:** academic (scientific articles, books, chapters)
|
| 8 |
-
- **Language:** Polish (pl)
|
| 9 |
-
- **License:** per-document — CC BY 4.0 28,335 · CC BY-SA 4.0 13,733 · Public Domain 3
|
| 10 |
-
- **Created (range):** per-document publication year, from each item's bibliotekanauki.pl metadata
|
| 11 |
-
- **Added:** 2026-06-27
|
| 12 |
-
|
| 13 |
-
## Licensing — traceable basis
|
| 14 |
-
The SpeakLeash blob carries no per-document license field, and ~53% of the upstream collection is
|
| 15 |
-
all-rights-reserved, so a per-item gate was mandatory. Each item's license was recovered from the
|
| 16 |
-
bibliotekanauki.pl API (`bibliotekanauki.pl/api/{type}/<id>` → `license.iconId`). Only openly-licensed
|
| 17 |
-
items are kept; all-rights-reserved and unknown items are gated out. Recovery yielded 43,576 clean ids.
|
| 18 |
-
|
| 19 |
-
| license | documents |
|
| 20 |
-
|---|---:|
|
| 21 |
-
| CC BY 4.0 | 28,335 |
|
| 22 |
-
| CC BY-SA 4.0 | 13,733 |
|
| 23 |
-
| Public Domain | 3 |
|
| 24 |
-
|
| 25 |
-
The per-document license is carried in the parquet `license` column.
|
| 26 |
-
|
| 27 |
-
## Attribution
|
| 28 |
-
Per-document attribution (author · year · title · publisher) was re-fetched 1:1 from
|
| 29 |
-
bibliotekanauki.pl (43,576 / 43,576 ok) and is carried in the parquet `attribution` column,
|
| 30 |
-
satisfying the CC BY / CC BY-SA attribution requirement that applies to every document here.
|
| 31 |
-
|
| 32 |
-
## Provenance
|
| 33 |
-
Pulled from SpeakLeash's public redistribution (`speakleash-ds-pub`, key `biblioteka_nauki_pl_corpus`)
|
| 34 |
-
of the upstream source above. SpeakLeash credited as intermediate aggregator; upstream license and
|
| 35 |
-
attribution recovered per document and preserved.
|
| 36 |
-
|
| 37 |
-
## Statistics
|
| 38 |
-
| documents | characters | tokens (tiktoken proxy) |
|
| 39 |
-
|---:|---:|---:|
|
| 40 |
-
| 42,071 | 1,748,333,935 | 673,488,831 |
|
| 41 |
-
|
| 42 |
-
## Filters applied (build_dynaword.py)
|
| 43 |
-
Minimal, per Dynaword guidelines (heavy filtering left to downstream use):
|
| 44 |
-
- drop documents < 200 chars: **0**
|
| 45 |
-
- drop non-Polish (diacritic ratio): **925**
|
| 46 |
-
- exact cross-source dedup (sha1): **180**
|
| 47 |
-
- OCR alpha-ratio < 0.70 (OCR source): **400**
|
| 48 |
-
- read 43,576 → kept 42,071
|
| 49 |
-
|
| 50 |
-
Token counts are a fast tiktoken (cl100k) proxy (~1% off Llama-3); the canonical
|
| 51 |
-
Llama-3 count is computed at release.
|
| 52 |
-
|
| 53 |
-
## Limitations
|
| 54 |
-
- **Mixed license.** Roughly one third of the documents are CC BY-SA 4.0 (share-alike); the exact
|
| 55 |
-
per-document license is in the `license` column. Downstream redistribution must respect share-alike
|
| 56 |
-
for those documents.
|
| 57 |
-
- **OCR / extraction noise.** Text is extracted from publisher PDFs; some layout and hyphenation
|
| 58 |
-
artefacts remain after the alpha-ratio filter.
|
| 59 |
-
- **Per-document dates.** `created` is the publication year from upstream metadata; finer-grained
|
| 60 |
-
dates are not available.
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
data/biblioteka_nauki/biblioteka_nauki.parquet
DELETED
|
@@ -1,3 +0,0 @@
|
|
| 1 |
-
version https://git-lfs.github.com/spec/v1
|
| 2 |
-
oid sha256:cc93cdd5ca3e6576a1da0aa294df1308e879b8516ac30911289e430c69a07b26
|
| 3 |
-
size 1076638904
|
|
|
|
|
|
|
|
|
|
|
|
data/biblioteka_nauki/biblioteka_nauki.stats.json
DELETED
|
@@ -1,12 +0,0 @@
|
|
| 1 |
-
{
|
| 2 |
-
"read": 43576,
|
| 3 |
-
"kept": 42071,
|
| 4 |
-
"drop_short": 0,
|
| 5 |
-
"drop_lang": 925,
|
| 6 |
-
"drop_dup": 180,
|
| 7 |
-
"drop_ocr": 400,
|
| 8 |
-
"chars": 1748333935,
|
| 9 |
-
"tokens": 673488831,
|
| 10 |
-
"secs": 484.1,
|
| 11 |
-
"license": "CC-BY-4.0 / CC-BY-SA-4.0"
|
| 12 |
-
}
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
data/biblioteka_nauki/recover_attribution.py
DELETED
|
@@ -1,125 +0,0 @@
|
|
| 1 |
-
#!/usr/bin/env python3
|
| 2 |
-
"""Targeted attribution pass for the CLEAN (CC-BY/CC-BY-SA/PD) Biblioteka Nauki ids ONLY.
|
| 3 |
-
The first recovery pass stored the license correctly but parsed the wrong attribution fields.
|
| 4 |
-
CC-BY/CC-BY-SA legally REQUIRE attribution, so re-fetch just the ~43.6k clean ids and extract:
|
| 5 |
-
authors = contributors[role=AUTHOR] firstName+lastName ; year = dates[PUBLISHED].date.year ;
|
| 6 |
-
title = mainTitle.text ; publisher = publishingCompanyInfo.name
|
| 7 |
-
|
| 8 |
-
licenses.jsonl -> attribution.jsonl {type,id,license,authors,year,title,publisher}
|
| 9 |
-
Resumable, threaded, polite. ~43.6k calls.
|
| 10 |
-
"""
|
| 11 |
-
import json, os, random, sys, threading, time
|
| 12 |
-
from concurrent.futures import ThreadPoolExecutor, as_completed
|
| 13 |
-
import requests
|
| 14 |
-
|
| 15 |
-
HERE = os.path.dirname(os.path.abspath(__file__))
|
| 16 |
-
LIC = os.path.join(HERE, "licenses.jsonl")
|
| 17 |
-
OUT = os.path.join(HERE, "attribution.jsonl")
|
| 18 |
-
PROG = os.path.join(HERE, "attribution_progress.txt")
|
| 19 |
-
CLEAN = {"cc-by", "cc-by-sa", "cc0", "public-domain"}
|
| 20 |
-
WORKERS = 8
|
| 21 |
-
UA = ("Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 "
|
| 22 |
-
"(KHTML, like Gecko) Chrome/124 Safari/537.36")
|
| 23 |
-
HEADERS = {"User-Agent": UA, "Accept": "application/json", "Referer": "https://bibliotekanauki.pl/"}
|
| 24 |
-
_local = threading.local()
|
| 25 |
-
_wlock = threading.Lock()
|
| 26 |
-
|
| 27 |
-
|
| 28 |
-
def session():
|
| 29 |
-
s = getattr(_local, "s", None)
|
| 30 |
-
if s is None:
|
| 31 |
-
s = requests.Session()
|
| 32 |
-
s.headers.update(HEADERS)
|
| 33 |
-
s.mount("https://", requests.adapters.HTTPAdapter(pool_connections=4, pool_maxsize=4))
|
| 34 |
-
_local.s = s
|
| 35 |
-
return s
|
| 36 |
-
|
| 37 |
-
|
| 38 |
-
def parse(d):
|
| 39 |
-
authors = []
|
| 40 |
-
for c in (d.get("contributors") or []):
|
| 41 |
-
if c.get("role") == "AUTHOR":
|
| 42 |
-
nm = f"{c.get('firstName','') or ''} {c.get('lastName','') or ''}".strip()
|
| 43 |
-
if nm:
|
| 44 |
-
authors.append(nm)
|
| 45 |
-
year = None
|
| 46 |
-
dates = d.get("dates") or []
|
| 47 |
-
for dt in dates:
|
| 48 |
-
if dt.get("type") == "PUBLISHED":
|
| 49 |
-
year = (dt.get("date") or {}).get("year")
|
| 50 |
-
break
|
| 51 |
-
if not year and dates:
|
| 52 |
-
year = (dates[0].get("date") or {}).get("year")
|
| 53 |
-
title = (d.get("mainTitle") or {}).get("text")
|
| 54 |
-
pub = (d.get("publishingCompanyInfo") or {}).get("name")
|
| 55 |
-
return authors[:20], (str(year) if year else None), title, pub
|
| 56 |
-
|
| 57 |
-
|
| 58 |
-
def fetch(item):
|
| 59 |
-
typ, _id, lic = item
|
| 60 |
-
url = f"https://bibliotekanauki.pl/api/{typ}/{_id}"
|
| 61 |
-
for attempt in range(4):
|
| 62 |
-
try:
|
| 63 |
-
r = session().get(url, timeout=25)
|
| 64 |
-
if r.status_code == 200:
|
| 65 |
-
a, y, t, p = parse(r.json())
|
| 66 |
-
return {"type": typ, "id": _id, "license": lic,
|
| 67 |
-
"authors": a, "year": y, "title": t, "publisher": p, "status": "ok"}
|
| 68 |
-
if r.status_code in (403, 404, 410):
|
| 69 |
-
return {"type": typ, "id": _id, "license": lic, "status": f"http{r.status_code}"}
|
| 70 |
-
time.sleep((2 ** attempt) + random.random())
|
| 71 |
-
except Exception as e:
|
| 72 |
-
if attempt == 3:
|
| 73 |
-
return {"type": typ, "id": _id, "license": lic, "status": f"err:{type(e).__name__}"}
|
| 74 |
-
time.sleep((2 ** attempt) + random.random())
|
| 75 |
-
return {"type": typ, "id": _id, "license": lic, "status": "err:retries"}
|
| 76 |
-
|
| 77 |
-
|
| 78 |
-
def main():
|
| 79 |
-
best = {}
|
| 80 |
-
for l in open(LIC, encoding="utf-8"):
|
| 81 |
-
try:
|
| 82 |
-
r = json.loads(l)
|
| 83 |
-
except Exception:
|
| 84 |
-
continue
|
| 85 |
-
best[(r["type"], r["id"])] = r
|
| 86 |
-
clean = [(t, i, r["iconId"]) for (t, i), r in best.items()
|
| 87 |
-
if r.get("status") == "ok" and r.get("iconId") in CLEAN]
|
| 88 |
-
done = set()
|
| 89 |
-
if os.path.exists(OUT):
|
| 90 |
-
for l in open(OUT, encoding="utf-8"):
|
| 91 |
-
try:
|
| 92 |
-
r = json.loads(l)
|
| 93 |
-
done.add((r["type"], r["id"]))
|
| 94 |
-
except Exception:
|
| 95 |
-
pass
|
| 96 |
-
todo = [c for c in clean if (c[0], c[1]) not in done]
|
| 97 |
-
print(f"clean={len(clean)} done={len(done)} todo={len(todo)} workers={WORKERS}", flush=True)
|
| 98 |
-
|
| 99 |
-
out = open(OUT, "a", encoding="utf-8")
|
| 100 |
-
n = len(done)
|
| 101 |
-
t0 = time.time()
|
| 102 |
-
counts = {}
|
| 103 |
-
with ThreadPoolExecutor(max_workers=WORKERS) as ex:
|
| 104 |
-
futs = [ex.submit(fetch, c) for c in todo]
|
| 105 |
-
for fut in as_completed(futs):
|
| 106 |
-
res = fut.result()
|
| 107 |
-
with _wlock:
|
| 108 |
-
out.write(json.dumps(res, ensure_ascii=False) + "\n")
|
| 109 |
-
n += 1
|
| 110 |
-
counts[res.get("status")] = counts.get(res.get("status"), 0) + 1
|
| 111 |
-
time.sleep(random.uniform(0.02, 0.10))
|
| 112 |
-
if n % 500 == 0:
|
| 113 |
-
out.flush()
|
| 114 |
-
rate = (n - len(done)) / max(time.time() - t0, 1)
|
| 115 |
-
eta = (len(clean) - n) / max(rate, 0.1) / 60
|
| 116 |
-
msg = f"{n}/{len(clean)} {rate:.1f}/s ETA {eta:.0f}m " + \
|
| 117 |
-
" ".join(f"{k}={v}" for k, v in sorted(counts.items()))
|
| 118 |
-
print(msg, flush=True)
|
| 119 |
-
open(PROG, "w").write(msg + "\n")
|
| 120 |
-
out.flush(); out.close()
|
| 121 |
-
print(f"DONE attribution: {n}/{len(clean)} counts={counts}", flush=True)
|
| 122 |
-
|
| 123 |
-
|
| 124 |
-
if __name__ == "__main__":
|
| 125 |
-
main()
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
data/biblioteka_nauki/recover_licenses.py
DELETED
|
@@ -1,171 +0,0 @@
|
|
| 1 |
-
#!/usr/bin/env python3
|
| 2 |
-
"""Pass 2: recover the per-item license for every Biblioteka Nauki doc via the public API.
|
| 3 |
-
index.jsonl -> GET bibliotekanauki.pl/api/{type}/{id} -> licenses.jsonl
|
| 4 |
-
|
| 5 |
-
Resumable (skips ids already in licenses.jsonl), polite (modest concurrency + jitter + backoff),
|
| 6 |
-
keep-alive sessions, and a circuit-breaker if the host starts blocking us.
|
| 7 |
-
|
| 8 |
-
Output line: {type,id, iconId, cc(bool), restricted(bool), authors, year, source, status}
|
| 9 |
-
status: "ok" | "http404" | "http403" | "err:<Type>"
|
| 10 |
-
"""
|
| 11 |
-
import json, os, random, sys, threading, time
|
| 12 |
-
from concurrent.futures import ThreadPoolExecutor, as_completed
|
| 13 |
-
import requests
|
| 14 |
-
|
| 15 |
-
HERE = os.path.dirname(os.path.abspath(__file__))
|
| 16 |
-
INDEX = os.path.join(HERE, "index.jsonl")
|
| 17 |
-
OUT = os.path.join(HERE, "licenses.jsonl")
|
| 18 |
-
PROG = os.path.join(HERE, "recover_progress.txt")
|
| 19 |
-
|
| 20 |
-
WORKERS = 8
|
| 21 |
-
TIMEOUT = 25
|
| 22 |
-
MAX_RETRY = 4
|
| 23 |
-
UA = ("Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 "
|
| 24 |
-
"(KHTML, like Gecko) Chrome/124 Safari/537.36")
|
| 25 |
-
HEADERS = {"User-Agent": UA, "Accept": "application/json", "Referer": "https://bibliotekanauki.pl/"}
|
| 26 |
-
|
| 27 |
-
_local = threading.local()
|
| 28 |
-
_write_lock = threading.Lock()
|
| 29 |
-
_recent = [] # rolling window of recent statuses for the circuit breaker
|
| 30 |
-
_recent_lock = threading.Lock()
|
| 31 |
-
_stop = threading.Event()
|
| 32 |
-
|
| 33 |
-
|
| 34 |
-
def session():
|
| 35 |
-
s = getattr(_local, "s", None)
|
| 36 |
-
if s is None:
|
| 37 |
-
s = requests.Session()
|
| 38 |
-
s.headers.update(HEADERS)
|
| 39 |
-
a = requests.adapters.HTTPAdapter(pool_connections=4, pool_maxsize=4)
|
| 40 |
-
s.mount("https://", a)
|
| 41 |
-
_local.s = s
|
| 42 |
-
return s
|
| 43 |
-
|
| 44 |
-
|
| 45 |
-
def load_done():
|
| 46 |
-
done = set()
|
| 47 |
-
if os.path.exists(OUT):
|
| 48 |
-
with open(OUT, encoding="utf-8") as f:
|
| 49 |
-
for line in f:
|
| 50 |
-
try:
|
| 51 |
-
r = json.loads(line)
|
| 52 |
-
done.add((r["type"], r["id"]))
|
| 53 |
-
except Exception:
|
| 54 |
-
pass
|
| 55 |
-
return done
|
| 56 |
-
|
| 57 |
-
|
| 58 |
-
def fetch(item):
|
| 59 |
-
if _stop.is_set():
|
| 60 |
-
return None
|
| 61 |
-
typ, _id = item["type"], item["id"]
|
| 62 |
-
url = f"https://bibliotekanauki.pl/api/{typ}/{_id}"
|
| 63 |
-
for attempt in range(MAX_RETRY):
|
| 64 |
-
try:
|
| 65 |
-
r = session().get(url, timeout=TIMEOUT)
|
| 66 |
-
if r.status_code == 200:
|
| 67 |
-
d = r.json()
|
| 68 |
-
lic = d.get("license") or {}
|
| 69 |
-
authors = []
|
| 70 |
-
for c in (d.get("contributors") or []):
|
| 71 |
-
nm = (c.get("name") or "").strip()
|
| 72 |
-
if nm:
|
| 73 |
-
authors.append(nm)
|
| 74 |
-
year = None
|
| 75 |
-
for dt in (d.get("dates") or []):
|
| 76 |
-
y = str(dt.get("year") or dt.get("value") or "")[:4]
|
| 77 |
-
if y.isdigit():
|
| 78 |
-
year = y
|
| 79 |
-
break
|
| 80 |
-
insts = d.get("publicationInstitutions") or d.get("journal") or None
|
| 81 |
-
if isinstance(insts, list):
|
| 82 |
-
insts = "; ".join(x.get("name", "") if isinstance(x, dict) else str(x) for x in insts) or None
|
| 83 |
-
return {
|
| 84 |
-
"type": typ, "id": _id,
|
| 85 |
-
"iconId": lic.get("iconId"),
|
| 86 |
-
"cc": bool(lic.get("creativeCommons")),
|
| 87 |
-
"restricted": bool(d.get("restricted")),
|
| 88 |
-
"authors": authors[:12],
|
| 89 |
-
"year": year,
|
| 90 |
-
"source": insts,
|
| 91 |
-
"status": "ok",
|
| 92 |
-
}
|
| 93 |
-
if r.status_code in (403,):
|
| 94 |
-
return {"type": typ, "id": _id, "status": "http403"}
|
| 95 |
-
if r.status_code in (404, 410):
|
| 96 |
-
return {"type": typ, "id": _id, "status": "http404"}
|
| 97 |
-
# 429 / 5xx -> backoff & retry
|
| 98 |
-
time.sleep((2 ** attempt) + random.random())
|
| 99 |
-
except Exception as e:
|
| 100 |
-
if attempt == MAX_RETRY - 1:
|
| 101 |
-
return {"type": typ, "id": _id, "status": f"err:{type(e).__name__}"}
|
| 102 |
-
time.sleep((2 ** attempt) + random.random())
|
| 103 |
-
return {"type": typ, "id": _id, "status": "err:retries"}
|
| 104 |
-
|
| 105 |
-
|
| 106 |
-
def note(status):
|
| 107 |
-
with _recent_lock:
|
| 108 |
-
_recent.append(status)
|
| 109 |
-
if len(_recent) > 200:
|
| 110 |
-
_recent.pop(0)
|
| 111 |
-
# circuit breaker: >60% 403 over a full window => host is blocking us
|
| 112 |
-
if len(_recent) == 200 and sum(1 for s in _recent if s == "http403") > 120:
|
| 113 |
-
_stop.set()
|
| 114 |
-
|
| 115 |
-
|
| 116 |
-
def main():
|
| 117 |
-
if not os.path.exists(INDEX):
|
| 118 |
-
sys.exit(f"missing {INDEX} — run build_index.py first")
|
| 119 |
-
items = []
|
| 120 |
-
with open(INDEX, encoding="utf-8") as f:
|
| 121 |
-
for line in f:
|
| 122 |
-
try:
|
| 123 |
-
r = json.loads(line)
|
| 124 |
-
items.append({"type": r["type"], "id": r["id"]})
|
| 125 |
-
except Exception:
|
| 126 |
-
pass
|
| 127 |
-
done = load_done()
|
| 128 |
-
todo = [it for it in items if (it["type"], it["id"]) not in done]
|
| 129 |
-
total = len(items)
|
| 130 |
-
print(f"index={total} done={len(done)} todo={len(todo)} workers={WORKERS}", flush=True)
|
| 131 |
-
|
| 132 |
-
n = len(done)
|
| 133 |
-
t0 = time.time()
|
| 134 |
-
out = open(OUT, "a", encoding="utf-8")
|
| 135 |
-
counts = {}
|
| 136 |
-
try:
|
| 137 |
-
with ThreadPoolExecutor(max_workers=WORKERS) as ex:
|
| 138 |
-
futs = [ex.submit(fetch, it) for it in todo]
|
| 139 |
-
for fut in as_completed(futs):
|
| 140 |
-
res = fut.result()
|
| 141 |
-
if res is None:
|
| 142 |
-
continue
|
| 143 |
-
with _write_lock:
|
| 144 |
-
out.write(json.dumps(res, ensure_ascii=False) + "\n")
|
| 145 |
-
n += 1
|
| 146 |
-
st = res.get("status", "?")
|
| 147 |
-
counts[st] = counts.get(st, 0) + 1
|
| 148 |
-
note(st)
|
| 149 |
-
# politeness jitter (per completed task; with 8 workers ~ a few hundred req/min)
|
| 150 |
-
time.sleep(random.uniform(0.02, 0.12))
|
| 151 |
-
if n % 500 == 0:
|
| 152 |
-
out.flush()
|
| 153 |
-
rate = (n - len(done)) / max(time.time() - t0, 1)
|
| 154 |
-
eta = (total - n) / max(rate, 0.1) / 60
|
| 155 |
-
msg = (f"{n}/{total} {rate:.1f}/s ETA {eta:.0f}m "
|
| 156 |
-
+ " ".join(f"{k}={v}" for k, v in sorted(counts.items())))
|
| 157 |
-
print(msg, flush=True)
|
| 158 |
-
with open(PROG, "w") as p:
|
| 159 |
-
p.write(msg + "\n")
|
| 160 |
-
if _stop.is_set():
|
| 161 |
-
print("!! circuit breaker tripped (sustained 403) — stopping. Re-run later to resume.", flush=True)
|
| 162 |
-
break
|
| 163 |
-
finally:
|
| 164 |
-
out.flush()
|
| 165 |
-
out.close()
|
| 166 |
-
print(f"FINISHED pass: wrote {n}/{total}. counts={counts}", flush=True)
|
| 167 |
-
print("Next: build_parquet.py to assemble the CC-BY/SA subset.", flush=True)
|
| 168 |
-
|
| 169 |
-
|
| 170 |
-
if __name__ == "__main__":
|
| 171 |
-
main()
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
data/european_hplt_v3_pl/european_hplt_v3_pl.md
ADDED
|
@@ -0,0 +1,57 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# european_hplt_v3_pl
|
| 2 |
+
|
| 3 |
+
Filtered Polish subset of **HPLT v3.0** (`pol_Latn`), top quality bins (WDS = 10 and 9), merged into one file.
|
| 4 |
+
|
| 5 |
+
## Dataset description
|
| 6 |
+
- **Source (upstream):** https://hplt-project.org/datasets/v3.0 (`pol_Latn`, shards `10_1` [WDS=10] + `9_1` prefix [WDS=9])
|
| 7 |
+
- **Domain:** web (modern natural Polish — informational, narrative, opinion, how-to, discussion)
|
| 8 |
+
- **Language:** Polish (pl)
|
| 9 |
+
- **License:** `CC0-1.0` (packaging; see licensing note)
|
| 10 |
+
- **Created (range):** web crawls 2012-2024 (Internet Archive + Common Crawl)
|
| 11 |
+
- **Added:** 2026-07-14
|
| 12 |
+
|
| 13 |
+
## Licensing - traceable basis
|
| 14 |
+
HPLT licenses the **packaging** of these text data under Creative Commons CC0 1.0 ("no rights reserved"),
|
| 15 |
+
per the HPLT v3.0 Terms of Use (hplt-project.org/datasets/v3.0) and the HF card `HPLT/HPLT3.0`.
|
| 16 |
+
HPLT does not own the underlying web text; a notice-and-takedown policy applies and downstream users
|
| 17 |
+
remain responsible for compliance (EU CDSM Directive 2019/790, GDPR). This is a web-crawl source: it is
|
| 18 |
+
offered at parity with the already-listed `european-hplt-v1` (CC0) basis and still needs maintainer
|
| 19 |
+
web/legal review (`accept_after_web_review`), not auto-accept.
|
| 20 |
+
|
| 21 |
+
## Provenance
|
| 22 |
+
Fetched directly from the HPLT distribution (`data.hplt-project.org/three/sorted/pol_Latn/{10_1,9_1}.jsonl.zst`),
|
| 23 |
+
NOT via SpeakLeash. HPLT v3 is globally deduplicated upstream and sorted into Web-Docs-Scorer (WDS) quality
|
| 24 |
+
bins; only the two top bins are used. Per-document URL, WDS score, web-register, MT-probability and PII spans
|
| 25 |
+
are available in the raw HPLT record and were used for filtering (not retained in the released canonical schema).
|
| 26 |
+
|
| 27 |
+
## Statistics
|
| 28 |
+
| documents | characters | tokens (tiktoken cl100k proxy) |
|
| 29 |
+
|---:|---:|---:|
|
| 30 |
+
| 110,590 | 1,426,290,944 | 512,383,778 |
|
| 31 |
+
|
| 32 |
+
Composition (single merged parquet): bin-10 (WDS=10) 55,590 docs / 261,468,813 tok;
|
| 33 |
+
bin-9 (WDS=9) 55,000 docs / 250,914,965 tok. See `european_hplt_v3_pl.stats.json` for the per-bin + drop breakdown.
|
| 34 |
+
|
| 35 |
+
## Per-document license metadata
|
| 36 |
+
| license | documents |
|
| 37 |
+
|---|---:|
|
| 38 |
+
| `CC0-1.0` | 110,590 |
|
| 39 |
+
|
| 40 |
+
## Filters applied (src/clean_hplt_v3.py; thresholds inherited from src/filter_european_hplt.py)
|
| 41 |
+
Per-shard keep: bin-10 55,590/195,874 (28.4%), bin-9 55,000/152,380 (36.1%). Drop reasons:
|
| 42 |
+
`register` (not ID/OP/HI/IN/NA), `machine_translated` (MT>=0.20), `domain`
|
| 43 |
+
(wikipedia/wikisource/wikimedia + file-hosts excluded), `adult_spam`, `legalish` (drops legal/parliamentary
|
| 44 |
+
phrasing - serves the anti-legalese goal), `boilerplate`, `too_long` (>120k chars = book-length copyright/OCR
|
| 45 |
+
risk), `mojibake` (>=3 CJK/replacement chars - upstream HPLT UTF-8->GBK mis-decode), `filehost` (PDF/file-share
|
| 46 |
+
headers), `domain_cap` (>250 docs/domain). MT-probability of kept docs: mean ~0.08. Mojibake residual: 0.
|
| 47 |
+
|
| 48 |
+
## Status & caveats (web-crawl - NOT "release-clean")
|
| 49 |
+
- **Copyright is not fully solved by filtering.** The length cap removes obvious book-length works, but
|
| 50 |
+
in-copyright text recurs in web-crawl at ALL lengths (news reprints, blog reposts, excerpts). Inherent to
|
| 51 |
+
web sources; the reason HPLT ships CC0-on-packaging + notice-and-takedown.
|
| 52 |
+
- **Near-dup NOT removed** (Dynaword leaves heavy filtering downstream). ~11.8% of an HPLT sample's 8-grams
|
| 53 |
+
overlap Polish Wikipedia; wikipedia/wikisource domain exclusion mitigates the largest sources, but
|
| 54 |
+
cross-source near/containment dedup vs the full corpus remains a downstream step.
|
| 55 |
+
- Surface-metric parity with accepted sources: mojibake 0%, boilerplate ~0.2%, diacritic-ratio ~0.066,
|
| 56 |
+
TTR@500 ~0.64 (within the accepted range, ~= parliamentary). ~9% commercial/SEO-adjacent pages (web-inherent).
|
| 57 |
+
- This is 2 top bins merged. The full `pol_Latn` corpus is ~270B raw tokens across WDS bins 10->5.
|
data/{rock_pollub_pl/rock_pollub_pl.parquet → european_hplt_v3_pl/european_hplt_v3_pl.parquet}
RENAMED
|
@@ -1,3 +1,3 @@
|
|
| 1 |
version https://git-lfs.github.com/spec/v1
|
| 2 |
-
oid sha256:
|
| 3 |
-
size
|
|
|
|
| 1 |
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:6295b3280cef2b99e9bf511a1c48be9c94cd219455d2e9666ebf17363771b714
|
| 3 |
+
size 610242503
|
data/european_hplt_v3_pl/european_hplt_v3_pl.stats.json
ADDED
|
@@ -0,0 +1,41 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"read": 348254,
|
| 3 |
+
"kept": 110590,
|
| 4 |
+
"drop_short": 0,
|
| 5 |
+
"drop_lang": 2,
|
| 6 |
+
"drop_dup": 0,
|
| 7 |
+
"drop_ocr": 0,
|
| 8 |
+
"chars": 1426290944,
|
| 9 |
+
"tokens": 512383778,
|
| 10 |
+
"licenses": {
|
| 11 |
+
"CC0-1.0": 110590
|
| 12 |
+
},
|
| 13 |
+
"authors_with_value": 0,
|
| 14 |
+
"license": "CC0-1.0",
|
| 15 |
+
"stats_recomputed_from_parquet": true,
|
| 16 |
+
"drop_detail": {
|
| 17 |
+
"machine_translated": 46477,
|
| 18 |
+
"adult_spam": 18682,
|
| 19 |
+
"register": 128956,
|
| 20 |
+
"legalish": 15881,
|
| 21 |
+
"domain": 23234,
|
| 22 |
+
"boilerplate": 3183,
|
| 23 |
+
"mojibake": 241,
|
| 24 |
+
"too_long": 216,
|
| 25 |
+
"filehost": 7,
|
| 26 |
+
"lang_prob": 2,
|
| 27 |
+
"domain_cap": 785
|
| 28 |
+
},
|
| 29 |
+
"shards": {
|
| 30 |
+
"bin10_WDS10": {
|
| 31 |
+
"kept": 55590,
|
| 32 |
+
"tokens": 261468813
|
| 33 |
+
},
|
| 34 |
+
"bin9_WDS9": {
|
| 35 |
+
"kept": 55000,
|
| 36 |
+
"tokens": 250914965
|
| 37 |
+
}
|
| 38 |
+
},
|
| 39 |
+
"mt_prob_mean_kept": 0.08,
|
| 40 |
+
"source_repo": "HPLT/HPLT3.0 pol_Latn WDS bins 10+9 (data.hplt-project.org)"
|
| 41 |
+
}
|
data/global_voices/global_voices.attribution.jsonl
CHANGED
|
The diff for this file is too large to render.
See raw diff
|
|
|
data/rock_pollub_pl/NOTICE.md
DELETED
|
@@ -1,8 +0,0 @@
|
|
| 1 |
-
# Notice and attribution
|
| 2 |
-
|
| 3 |
-
Source collection: https://rock.pollub.pl/collections/a42db069-319d-4d51-88d1-490ee7e6bad8
|
| 4 |
-
Publisher policy: https://wpl.pollub.pl/pl/i/Polityka-publikacyjna/20
|
| 5 |
-
|
| 6 |
-
The eight retained books expose `CC-BY-SA-4.0` in both the item record and the metadata of the matched original PDF bitstream. Per-record authors, titles, source URLs, license evidence and source-file checksums are preserved in `artifacts/attribution.jsonl` and `artifacts/inventory.json`.
|
| 7 |
-
|
| 8 |
-
Transformations: PDF text extraction with pdfplumber, Unicode and whitespace normalization, page-number-only removal, line-wrap repair, limited email and labelled-phone redaction, and within-source exact/near deduplication. Images are excluded. Isolated unreadable PDF glyphs are represented as `[UNREADABLE_GLYPH]`. Attribution and ShareAlike obligations remain applicable.
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
data/rock_pollub_pl/rock_pollub_pl.attribution.jsonl
DELETED
|
@@ -1,3 +0,0 @@
|
|
| 1 |
-
version https://git-lfs.github.com/spec/v1
|
| 2 |
-
oid sha256:7f402aa851f338dd7661310e886a140f551ce58d8cd42a04034104204c7b9ea9
|
| 3 |
-
size 13279
|
|
|
|
|
|
|
|
|
|
|
|
data/rock_pollub_pl/rock_pollub_pl.decisions.jsonl
DELETED
|
@@ -1,3 +0,0 @@
|
|
| 1 |
-
version https://git-lfs.github.com/spec/v1
|
| 2 |
-
oid sha256:e60fe6b5610cf9453b432ffb4e5cb3630bf3b313a15e5042ea0a176feb1ea6d7
|
| 3 |
-
size 1880
|
|
|
|
|
|
|
|
|
|
|
|
data/rock_pollub_pl/rock_pollub_pl.md
DELETED
|
@@ -1,29 +0,0 @@
|
|
| 1 |
-
---
|
| 2 |
-
license: cc-by-sa-4.0
|
| 3 |
-
language:
|
| 4 |
-
- pl
|
| 5 |
-
task_categories:
|
| 6 |
-
- text-generation
|
| 7 |
-
configs:
|
| 8 |
-
- config_name: default
|
| 9 |
-
data_files:
|
| 10 |
-
- split: train
|
| 11 |
-
path: data/train-00000-of-00001.parquet
|
| 12 |
-
---
|
| 13 |
-
|
| 14 |
-
# ROCK Politechnika Lubelska PL books
|
| 15 |
-
|
| 16 |
-
A fail-closed Polish academic-book subset extracted from the official ROCK repository of Lublin University of Technology.
|
| 17 |
-
|
| 18 |
-
- Retained books: 8
|
| 19 |
-
- Text characters: 3,380,937
|
| 20 |
-
- Tokens: 1,177,858 (`cl100k_base` proxy)
|
| 21 |
-
- Author coverage: 100.0%
|
| 22 |
-
- License: CC BY-SA 4.0, confirmed for every retained item and matched PDF bitstream
|
| 23 |
-
- Source period: 2023-2026
|
| 24 |
-
|
| 25 |
-
The acquisition target was 20 books, but only eight passed the conservative per-file rights gate. The other inspected candidates are not included. See `NOTICE.md` and `artifacts/` for attribution, decisions, the source inventory, deterministic complete-record samples, QA, checksums, overlap audit and Slayer ontology manifest.
|
| 26 |
-
|
| 27 |
-
## Limitations
|
| 28 |
-
|
| 29 |
-
PDF extraction can flatten tables and equations. Two isolated unreadable glyphs were marked explicitly. Pattern-based PII checks are not comprehensive de-identification. No title overlap was detected against the pinned `biblioteka_nauki` attribution column, but target-wide text deduplication, benchmark checks and controlled training ablations remain pending.
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
data/rock_pollub_pl/rock_pollub_pl.overlap_audit.json
DELETED
|
@@ -1,61 +0,0 @@
|
|
| 1 |
-
{
|
| 2 |
-
"candidate_records": 8,
|
| 3 |
-
"method": "normalized title substring; fallback SequenceMatcher >= 0.90 over attribution",
|
| 4 |
-
"observed_at": "2026-09-08T16:37:35.661794+00:00",
|
| 5 |
-
"records_with_exact_title_match": 0,
|
| 6 |
-
"records_with_fuzzy_title_match": 0,
|
| 7 |
-
"results": [
|
| 8 |
-
{
|
| 9 |
-
"exact_title_matches": [],
|
| 10 |
-
"fuzzy_title_matches": [],
|
| 11 |
-
"item_id": "513c690d-72b3-4604-b62e-e21e44b91645",
|
| 12 |
-
"title": "Modelowanie i analiza eksperymentalna parametrów pracy modułów fotowoltaicznych w warunkach rzeczywistych"
|
| 13 |
-
},
|
| 14 |
-
{
|
| 15 |
-
"exact_title_matches": [],
|
| 16 |
-
"fuzzy_title_matches": [],
|
| 17 |
-
"item_id": "e9e7a67e-c405-4968-b87a-0ff169c7b3d1",
|
| 18 |
-
"title": "Ćwiczenia i zadania ze wstępu do matematyki finansowej"
|
| 19 |
-
},
|
| 20 |
-
{
|
| 21 |
-
"exact_title_matches": [],
|
| 22 |
-
"fuzzy_title_matches": [],
|
| 23 |
-
"item_id": "a6c38c5d-ba8f-47ac-a3e6-b50df14a595b",
|
| 24 |
-
"title": "Dobór architektury i parametrów procesu uczenia sieci neuronowych w doskonaleniu procesów produkcyjnych"
|
| 25 |
-
},
|
| 26 |
-
{
|
| 27 |
-
"exact_title_matches": [],
|
| 28 |
-
"fuzzy_title_matches": [],
|
| 29 |
-
"item_id": "903f22e1-a2ab-4231-a402-2bc9535c12f2",
|
| 30 |
-
"title": "Wyzwania współczesnego publikowania"
|
| 31 |
-
},
|
| 32 |
-
{
|
| 33 |
-
"exact_title_matches": [],
|
| 34 |
-
"fuzzy_title_matches": [],
|
| 35 |
-
"item_id": "0e26bff5-e51a-4d36-9524-fdef6e3e6ab7",
|
| 36 |
-
"title": "Symulacje Monte Carlo. Teoria i zastosowania"
|
| 37 |
-
},
|
| 38 |
-
{
|
| 39 |
-
"exact_title_matches": [],
|
| 40 |
-
"fuzzy_title_matches": [],
|
| 41 |
-
"item_id": "032a14e5-5c8e-4153-9cf7-2dfd9e361e6d",
|
| 42 |
-
"title": "Zastosowanie uczenia maszynowego do obrazowania stanu zawilgocenia murów z wykorzystaniem tomografii impedancyjnej"
|
| 43 |
-
},
|
| 44 |
-
{
|
| 45 |
-
"exact_title_matches": [],
|
| 46 |
-
"fuzzy_title_matches": [],
|
| 47 |
-
"item_id": "da87b1d3-7018-46fa-81bd-380f0780a1b3",
|
| 48 |
-
"title": "Zarządzanie współpracą instytucji państwa z diasporą. Przegląd teorii, analiza porównawcza wybranych państw"
|
| 49 |
-
},
|
| 50 |
-
{
|
| 51 |
-
"exact_title_matches": [],
|
| 52 |
-
"fuzzy_title_matches": [],
|
| 53 |
-
"item_id": "a257b1ce-1af7-4dfc-ae38-ec67ef877689",
|
| 54 |
-
"title": "Komputerowa grafika inżynierska. Ćwiczenia do programu AutoCAD 2023"
|
| 55 |
-
}
|
| 56 |
-
],
|
| 57 |
-
"target": "SlayerLab/polish-dynaword:data/biblioteka_nauki",
|
| 58 |
-
"target_revision": "02bcb0b5f991a30f8454c6444f701633b71f69d4",
|
| 59 |
-
"target_rows": 42071,
|
| 60 |
-
"text_overlap": "not tested; target-wide text dedup remains an integration gate"
|
| 61 |
-
}
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
data/rock_pollub_pl/rock_pollub_pl.qa.json
DELETED
|
@@ -1,81 +0,0 @@
|
|
| 1 |
-
{
|
| 2 |
-
"benchmark_overlap": "pending",
|
| 3 |
-
"biblioteka_nauki_overlap": {
|
| 4 |
-
"candidate_records": 8,
|
| 5 |
-
"method": "normalized title substring; fallback SequenceMatcher >= 0.90 over attribution",
|
| 6 |
-
"observed_at": "2026-09-08T16:37:35.661794+00:00",
|
| 7 |
-
"records_with_exact_title_match": 0,
|
| 8 |
-
"records_with_fuzzy_title_match": 0,
|
| 9 |
-
"results": [
|
| 10 |
-
{
|
| 11 |
-
"exact_title_matches": [],
|
| 12 |
-
"fuzzy_title_matches": [],
|
| 13 |
-
"item_id": "513c690d-72b3-4604-b62e-e21e44b91645",
|
| 14 |
-
"title": "Modelowanie i analiza eksperymentalna parametrów pracy modułów fotowoltaicznych w warunkach rzeczywistych"
|
| 15 |
-
},
|
| 16 |
-
{
|
| 17 |
-
"exact_title_matches": [],
|
| 18 |
-
"fuzzy_title_matches": [],
|
| 19 |
-
"item_id": "e9e7a67e-c405-4968-b87a-0ff169c7b3d1",
|
| 20 |
-
"title": "Ćwiczenia i zadania ze wstępu do matematyki finansowej"
|
| 21 |
-
},
|
| 22 |
-
{
|
| 23 |
-
"exact_title_matches": [],
|
| 24 |
-
"fuzzy_title_matches": [],
|
| 25 |
-
"item_id": "a6c38c5d-ba8f-47ac-a3e6-b50df14a595b",
|
| 26 |
-
"title": "Dobór architektury i parametrów procesu uczenia sieci neuronowych w doskonaleniu procesów produkcyjnych"
|
| 27 |
-
},
|
| 28 |
-
{
|
| 29 |
-
"exact_title_matches": [],
|
| 30 |
-
"fuzzy_title_matches": [],
|
| 31 |
-
"item_id": "903f22e1-a2ab-4231-a402-2bc9535c12f2",
|
| 32 |
-
"title": "Wyzwania współczesnego publikowania"
|
| 33 |
-
},
|
| 34 |
-
{
|
| 35 |
-
"exact_title_matches": [],
|
| 36 |
-
"fuzzy_title_matches": [],
|
| 37 |
-
"item_id": "0e26bff5-e51a-4d36-9524-fdef6e3e6ab7",
|
| 38 |
-
"title": "Symulacje Monte Carlo. Teoria i zastosowania"
|
| 39 |
-
},
|
| 40 |
-
{
|
| 41 |
-
"exact_title_matches": [],
|
| 42 |
-
"fuzzy_title_matches": [],
|
| 43 |
-
"item_id": "032a14e5-5c8e-4153-9cf7-2dfd9e361e6d",
|
| 44 |
-
"title": "Zastosowanie uczenia maszynowego do obrazowania stanu zawilgocenia murów z wykorzystaniem tomografii impedancyjnej"
|
| 45 |
-
},
|
| 46 |
-
{
|
| 47 |
-
"exact_title_matches": [],
|
| 48 |
-
"fuzzy_title_matches": [],
|
| 49 |
-
"item_id": "da87b1d3-7018-46fa-81bd-380f0780a1b3",
|
| 50 |
-
"title": "Zarządzanie współpracą instytucji państwa z diasporą. Przegląd teorii, analiza porównawcza wybranych państw"
|
| 51 |
-
},
|
| 52 |
-
{
|
| 53 |
-
"exact_title_matches": [],
|
| 54 |
-
"fuzzy_title_matches": [],
|
| 55 |
-
"item_id": "a257b1ce-1af7-4dfc-ae38-ec67ef877689",
|
| 56 |
-
"title": "Komputerowa grafika inżynierska. Ćwiczenia do programu AutoCAD 2023"
|
| 57 |
-
}
|
| 58 |
-
],
|
| 59 |
-
"target": "SlayerLab/polish-dynaword:data/biblioteka_nauki",
|
| 60 |
-
"target_revision": "02bcb0b5f991a30f8454c6444f701633b71f69d4",
|
| 61 |
-
"target_rows": 42071,
|
| 62 |
-
"text_overlap": "not tested; target-wide text dedup remains an integration gate"
|
| 63 |
-
},
|
| 64 |
-
"cross_source_dedup": "pending target integration",
|
| 65 |
-
"exact_dedup": true,
|
| 66 |
-
"license_gate": "CC-BY-SA-4.0 in item and matched PDF bitstream metadata",
|
| 67 |
-
"limitations": [
|
| 68 |
-
"PDF extraction may flatten tables and equations",
|
| 69 |
-
"third-party figures and quoted material are not included as images but textual excerpts require review",
|
| 70 |
-
"isolated PDF extraction replacement characters are represented as [UNREADABLE_GLYPH]",
|
| 71 |
-
"pattern checks are not comprehensive de-identification",
|
| 72 |
-
"pilot yield must not be extrapolated without a full inventory run"
|
| 73 |
-
],
|
| 74 |
-
"near_dedup": "exact 5-word-shingle Jaccard >= 0.90 within pilot",
|
| 75 |
-
"pii_pattern_matches": {
|
| 76 |
-
"email": 2,
|
| 77 |
-
"labelled_phone": 0
|
| 78 |
-
},
|
| 79 |
-
"scope": "pilot target 20; acquired 8; not a completeness claim",
|
| 80 |
-
"target_reached": false
|
| 81 |
-
}
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
data/rock_pollub_pl/rock_pollub_pl.sample.jsonl
DELETED
|
The diff for this file is too large to render.
See raw diff
|
|
|
data/rock_pollub_pl/rock_pollub_pl.stats.json
DELETED
|
@@ -1,12 +0,0 @@
|
|
| 1 |
-
{
|
| 2 |
-
"acquired": 8,
|
| 3 |
-
"added": "2026-09-08",
|
| 4 |
-
"author_coverage": 1.0,
|
| 5 |
-
"characters": 3380937,
|
| 6 |
-
"discovered_collection_items": 771,
|
| 7 |
-
"kept": 8,
|
| 8 |
-
"pilot_limit": 20,
|
| 9 |
-
"rejected": 0,
|
| 10 |
-
"sample_count": 8,
|
| 11 |
-
"tokens": 1177858
|
| 12 |
-
}
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
data/samorzad_gov_pl/NOTICE.md
DELETED
|
@@ -1,28 +0,0 @@
|
|
| 1 |
-
# Attribution and licensing notice
|
| 2 |
-
|
| 3 |
-
The `samorzad_gov_pl` source contains textual articles collected from public
|
| 4 |
-
pages hosted on the shared [samorzad.gov.pl](https://samorzad.gov.pl/)
|
| 5 |
-
platform.
|
| 6 |
-
|
| 7 |
-
The platform footer states that textual content published in the service,
|
| 8 |
-
excluding audiovisual content, is available under the [Creative Commons
|
| 9 |
-
Attribution-ShareAlike 4.0 International](https://creativecommons.org/licenses/by-sa/4.0/)
|
| 10 |
-
license (`CC-BY-SA-4.0`). Every source page retained in the published v0.1
|
| 11 |
-
upstream dataset referenced the shared platform footer script.
|
| 12 |
-
|
| 13 |
-
For every released DynaWord document:
|
| 14 |
-
|
| 15 |
-
- the `author` column identifies the publishing institution;
|
| 16 |
-
- `samorzad_gov_pl.attribution.jsonl` preserves the discovered `source_url`,
|
| 17 |
-
fetched `final_url`, recommended `attribution_url`, article title,
|
| 18 |
-
institution, tenant identifier, license URL and modification notice;
|
| 19 |
-
- article text was extracted from source HTML, and this contribution normalizes
|
| 20 |
-
metadata and excludes short, non-Polish or duplicate records.
|
| 21 |
-
|
| 22 |
-
When redistributing or adapting these texts, retain the source attribution,
|
| 23 |
-
indicate changes and distribute adaptations under compatible
|
| 24 |
-
`CC-BY-SA-4.0` terms.
|
| 25 |
-
|
| 26 |
-
Photographs, videos, recordings and attachment bytes are not included. Their
|
| 27 |
-
rights must be evaluated separately at the source. URLs and descriptive
|
| 28 |
-
metadata in the attribution sidecar do not redistribute the linked files.
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
data/samorzad_gov_pl/samorzad_gov_pl.attribution.jsonl
DELETED
|
@@ -1,3 +0,0 @@
|
|
| 1 |
-
version https://git-lfs.github.com/spec/v1
|
| 2 |
-
oid sha256:e50acff3137b4680dc63a402667227b24cdd362e9c07895f1485a530ea5116c3
|
| 3 |
-
size 68676369
|
|
|
|
|
|
|
|
|
|
|
|
data/samorzad_gov_pl/samorzad_gov_pl.license-evidence.json
DELETED
|
@@ -1,17 +0,0 @@
|
|
| 1 |
-
{
|
| 2 |
-
"checked_at": "2026-08-13T23:42:06Z",
|
| 3 |
-
"evidence_url": "https://samorzad.gov.pl/scripts/govpl_template.js?locale=pl_PL",
|
| 4 |
-
"etag": "W/\"0b36ec507901ed443195479d8d8009386\"",
|
| 5 |
-
"bytes": 9291,
|
| 6 |
-
"sha256": "b36ec507901ed443195479d8d8009386159ae59d7486ce266bfb3308043e99aa",
|
| 7 |
-
"text_license": "CC BY-SA 4.0",
|
| 8 |
-
"audiovisual_license": "CC BY-NC-ND 4.0 unless stated otherwise",
|
| 9 |
-
"release_scope": {
|
| 10 |
-
"records": 81422,
|
| 11 |
-
"tenants": 247,
|
| 12 |
-
"source_pages_referencing_shared_footer_script": 81422,
|
| 13 |
-
"source_pages_without_reference": 0,
|
| 14 |
-
"missing_source_artifacts": 0
|
| 15 |
-
},
|
| 16 |
-
"method": "Checked the live shared footer script and searched every preserved source HTML artifact in release v0.1 for /scripts/govpl_template.js?locale=pl_PL."
|
| 17 |
-
}
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
data/samorzad_gov_pl/samorzad_gov_pl.md
DELETED
|
@@ -1,138 +0,0 @@
|
|
| 1 |
-
# samorzad_gov_pl
|
| 2 |
-
|
| 3 |
-
Polish-language articles published by 246 local public institutions and one
|
| 4 |
-
central platform tenant using the shared
|
| 5 |
-
[samorzad.gov.pl](https://samorzad.gov.pl/) platform. The collection includes
|
| 6 |
-
municipalities, counties, schools, social-service institutions, cultural
|
| 7 |
-
institutions and other public bodies.
|
| 8 |
-
|
| 9 |
-
## Dataset description
|
| 10 |
-
|
| 11 |
-
- **Published source dataset:** https://huggingface.co/datasets/dawidmajewski/samorzad-gov-pl-articles
|
| 12 |
-
- **Source revision:** `d5eaefc32c3f17cfa5a01d14573f8e4ee7d43385` (`v0.1`)
|
| 13 |
-
- **Original platform:** https://samorzad.gov.pl/
|
| 14 |
-
- **Domain:** local government, education, social services and culture
|
| 15 |
-
- **Language:** Polish (`pl`)
|
| 16 |
-
- **License:** `CC-BY-SA-4.0`
|
| 17 |
-
- **Created:** 2020–2026 for dated records; most source records do not expose a date
|
| 18 |
-
- **Added:** 2026-08-14
|
| 19 |
-
|
| 20 |
-
## Statistics
|
| 21 |
-
|
| 22 |
-
| read | kept | characters | tokens (`cl100k_base` proxy) | publishers |
|
| 23 |
-
|---:|---:|---:|---:|---:|
|
| 24 |
-
| 81,422 | 72,771 | 109,513,754 | 41,154,506 | 247 |
|
| 25 |
-
|
| 26 |
-
The released Parquet uses the canonical DynaWord schema:
|
| 27 |
-
|
| 28 |
-
`id, text, source, added, created, token_count, license, author`
|
| 29 |
-
|
| 30 |
-
Every retained document has the human-readable name of its publishing
|
| 31 |
-
institution in `author`. The names were obtained from the `og:site_name`
|
| 32 |
-
metadata on each institution's platform homepage and frozen in
|
| 33 |
-
`src/samorzad_gov_pl_publishers.json`.
|
| 34 |
-
|
| 35 |
-
## Provenance
|
| 36 |
-
|
| 37 |
-
The source release was collected directly from public samorzad.gov.pl pages.
|
| 38 |
-
It contains every article URL found and successfully extracted during that
|
| 39 |
-
crawl, rather than a topical or length-selected sample. The published source
|
| 40 |
-
release contains 81,422 extracted articles from 247 institutions.
|
| 41 |
-
|
| 42 |
-
`src/clean_samorzad_gov_pl.py` converts the published source Parquets into the
|
| 43 |
-
DynaWord schema, applies the common minimum-length and Polish-language checks,
|
| 44 |
-
removes exact duplicate text and counts tokens with `cl100k_base`. The retained
|
| 45 |
-
article text is otherwise unchanged.
|
| 46 |
-
|
| 47 |
-
## Licensing — traceable basis and attribution
|
| 48 |
-
|
| 49 |
-
The platform's shared footer states that textual content published in the
|
| 50 |
-
service, excluding audiovisual content, is available under CC BY-SA 4.0. A
|
| 51 |
-
release-time audit verified the live shared footer script and confirmed that
|
| 52 |
-
all 81,422 preserved source pages referenced that script. The evidence URL,
|
| 53 |
-
byte count and SHA-256 digest are recorded in
|
| 54 |
-
`samorzad_gov_pl.license-evidence.json`.
|
| 55 |
-
|
| 56 |
-
The fixed DynaWord schema does not contain article titles or URLs. Therefore,
|
| 57 |
-
`samorzad_gov_pl.attribution.jsonl` maps every released `id` to its title,
|
| 58 |
-
discovered `source_url`, fetched `final_url`, recommended `attribution_url`,
|
| 59 |
-
publishing institution, platform tenant, license URL and modification notice.
|
| 60 |
-
For 693 retained records the discovered and final URLs differ because the
|
| 61 |
-
platform redirected the request; `attribution_url` uses the fetched final URL.
|
| 62 |
-
|
| 63 |
-
Recommended attribution:
|
| 64 |
-
|
| 65 |
-
> Publishing institution listed in the `author` column; article title and
|
| 66 |
-
> canonical samorzad.gov.pl URL from the attribution sidecar; CC BY-SA 4.0.
|
| 67 |
-
> Article text was extracted from HTML and normalized for inclusion in Polish
|
| 68 |
-
> DynaWord.
|
| 69 |
-
|
| 70 |
-
Photographs, recordings, videos and attachment bytes are not redistributed.
|
| 71 |
-
The source platform gives audiovisual materials separate terms, and linked
|
| 72 |
-
attachments can carry their own conditions. URLs and descriptive metadata do
|
| 73 |
-
not redistribute those files.
|
| 74 |
-
|
| 75 |
-
## Filters applied
|
| 76 |
-
|
| 77 |
-
| result | documents |
|
| 78 |
-
|---|---:|
|
| 79 |
-
| source records read | 81,422 |
|
| 80 |
-
| shorter than 200 characters | 6,624 |
|
| 81 |
-
| below the Polish-language heuristic | 35 |
|
| 82 |
-
| exact duplicate text | 1,992 |
|
| 83 |
-
| retained | 72,771 |
|
| 84 |
-
|
| 85 |
-
Exact duplicate removal is performed after short-text and language checks.
|
| 86 |
-
Existing DynaWord sources take priority when the same text is already present
|
| 87 |
-
elsewhere in the corpus.
|
| 88 |
-
|
| 89 |
-
## Limitations and recommended use
|
| 90 |
-
|
| 91 |
-
- The collection is not a complete historical archive of samorzad.gov.pl. It
|
| 92 |
-
contains the pages found and successfully extracted during one crawl.
|
| 93 |
-
- Only 21,892 of the 81,422 source records expose a publication date. After
|
| 94 |
-
filtering, 52,214 retained records have an empty `created` value; no date is
|
| 95 |
-
inferred for them.
|
| 96 |
-
- The source text can contain spelling errors, extraction remnants or captions.
|
| 97 |
-
- Very short source records are excluded by DynaWord's 200-character minimum.
|
| 98 |
-
- Institution names describe the publishing body, not necessarily the person
|
| 99 |
-
who wrote an article.
|
| 100 |
-
- Government and institutional language is overrepresented; this source should
|
| 101 |
-
complement, not stand in for, conversational or general Polish.
|
| 102 |
-
- Canonical URLs may stop working as institutions update their websites.
|
| 103 |
-
|
| 104 |
-
## Included files
|
| 105 |
-
|
| 106 |
-
- `samorzad_gov_pl.parquet` — canonical DynaWord records;
|
| 107 |
-
- `samorzad_gov_pl.stats.json` — build and release statistics;
|
| 108 |
-
- `samorzad_gov_pl.attribution.jsonl` — per-document source attribution;
|
| 109 |
-
- `samorzad_gov_pl.license-evidence.json` — release-time license evidence;
|
| 110 |
-
- `NOTICE.md` — attribution and redistribution notice.
|
| 111 |
-
|
| 112 |
-
## Reproduction
|
| 113 |
-
|
| 114 |
-
The converter refuses to build unless the downloaded `manifest.json` and all
|
| 115 |
-
10 Parquet shards match the pinned release. It verifies the manifest SHA-256,
|
| 116 |
-
artifact set, shard sizes and SHA-256 values, row counts, schema, unique record
|
| 117 |
-
IDs and the release-wide record-text digest before conversion. Outputs are
|
| 118 |
-
written to temporary files, cross-checked, synced and transactionally replaced;
|
| 119 |
-
a failed replacement restores the previous artifact set.
|
| 120 |
-
|
| 121 |
-
Download the published source Parquet shards and run:
|
| 122 |
-
|
| 123 |
-
```bash
|
| 124 |
-
hf download dawidmajewski/samorzad-gov-pl-articles \
|
| 125 |
-
--repo-type dataset \
|
| 126 |
-
--revision d5eaefc32c3f17cfa5a01d14573f8e4ee7d43385 \
|
| 127 |
-
--include 'data/*.parquet' --include manifest.json \
|
| 128 |
-
--local-dir /tmp/samorzad-gov-pl-articles
|
| 129 |
-
|
| 130 |
-
uv run --with pyarrow --with tiktoken python src/clean_samorzad_gov_pl.py \
|
| 131 |
-
--input /tmp/samorzad-gov-pl-articles/data \
|
| 132 |
-
--repo-root . \
|
| 133 |
-
--added 2026-08-14
|
| 134 |
-
```
|
| 135 |
-
|
| 136 |
-
Use `--refresh-publishers` only when intentionally updating the frozen
|
| 137 |
-
institution-name manifest from live tenant homepages. Review any changed name
|
| 138 |
-
before publishing a new release.
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
data/samorzad_gov_pl/samorzad_gov_pl.parquet
DELETED
|
@@ -1,3 +0,0 @@
|
|
| 1 |
-
version https://git-lfs.github.com/spec/v1
|
| 2 |
-
oid sha256:b4f788030bb987b6c12487ea3e2e587bca1d1fd86294c1488961045bfe8fd137
|
| 3 |
-
size 51930059
|
|
|
|
|
|
|
|
|
|
|
|
data/samorzad_gov_pl/samorzad_gov_pl.stats.json
DELETED
|
@@ -1,25 +0,0 @@
|
|
| 1 |
-
{
|
| 2 |
-
"authors_with_value": 72771,
|
| 3 |
-
"central_tenant_count": 1,
|
| 4 |
-
"chars": 109513754,
|
| 5 |
-
"cross_source_hashes_loaded": 4246372,
|
| 6 |
-
"drop_dup": 1992,
|
| 7 |
-
"drop_lang": 35,
|
| 8 |
-
"drop_ocr": 0,
|
| 9 |
-
"drop_short": 6624,
|
| 10 |
-
"kept": 72771,
|
| 11 |
-
"license": "CC-BY-SA-4.0",
|
| 12 |
-
"licenses": {
|
| 13 |
-
"CC-BY-SA-4.0": 72771
|
| 14 |
-
},
|
| 15 |
-
"local_public_tenant_count": 246,
|
| 16 |
-
"publisher_count": 247,
|
| 17 |
-
"read": 81422,
|
| 18 |
-
"redirected_urls": 693,
|
| 19 |
-
"tokens": 41154506,
|
| 20 |
-
"upstream_artifact_count": 10,
|
| 21 |
-
"upstream_dataset": "dawidmajewski/samorzad-gov-pl-articles",
|
| 22 |
-
"upstream_manifest_sha256": "97b5a266b2fd4f043648b7d3c757721cd826c7ca1048301761084b0abdee5c48",
|
| 23 |
-
"upstream_record_text_sha256": "6c35e1dc0bd35863ddb2f4e43d5bd08264c1fc27affdd60684ab5ecbc5457f63",
|
| 24 |
-
"upstream_revision": "d5eaefc32c3f17cfa5a01d14573f8e4ee7d43385"
|
| 25 |
-
}
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
data/sejm_api/NOTICE.md
DELETED
|
@@ -1,9 +0,0 @@
|
|
| 1 |
-
# Source attribution
|
| 2 |
-
|
| 3 |
-
Official materials: Kancelaria Sejmu RP, API Sejmu — https://api.sejm.gov.pl/.
|
| 4 |
-
|
| 5 |
-
Speech attribution is preserved in `author`; the full source URL is in `sejm_api.attribution.jsonl`.
|
| 6 |
-
|
| 7 |
-
Corpus preparation and contribution: Piotr Styła (Hugging Face: PiotrSty; GitHub: PiotrStyla).
|
| 8 |
-
|
| 9 |
-
Reuse follows Polish Copyright Act art. 4(2) and the Polish Open Data Act. No upstream Creative Commons grant is asserted.
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
data/sejm_api/sejm_api.attribution.jsonl
DELETED
|
@@ -1,3 +0,0 @@
|
|
| 1 |
-
version https://git-lfs.github.com/spec/v1
|
| 2 |
-
oid sha256:4ab6513f8173498d403f7ec1a9534b8e0086264d3eca6ff9ac4f9c5dbca4c069
|
| 3 |
-
size 18722278
|
|
|
|
|
|
|
|
|
|
|
|
data/sejm_api/sejm_api.license-evidence.json
DELETED
|
@@ -1,34 +0,0 @@
|
|
| 1 |
-
{
|
| 2 |
-
"copyright_basis": {
|
| 3 |
-
"act": "Polish Copyright and Related Rights Act",
|
| 4 |
-
"article": "4(2)",
|
| 5 |
-
"finding": "official documents and materials are excluded from copyright",
|
| 6 |
-
"url": "https://eli.gov.pl/api/acts/DU/2025/24/text/O/D20250024.pdf"
|
| 7 |
-
},
|
| 8 |
-
"dataset_record_license": "public-domain (official documents)",
|
| 9 |
-
"hf_source_license_name": "polish-public-sector-open-statutory-reuse",
|
| 10 |
-
"limitations": [
|
| 11 |
-
"privacy and personal-data exceptions",
|
| 12 |
-
"third-party rights and provider-specific conditions",
|
| 13 |
-
"no upstream Creative Commons grant is asserted"
|
| 14 |
-
],
|
| 15 |
-
"official_source": "https://api.sejm.gov.pl/",
|
| 16 |
-
"official_source_documentation": "https://api.sejm.gov.pl/sejm.html",
|
| 17 |
-
"pinned_source": "hf://datasets/PiotrSty/sejm-speeches-corpus@124557799608ce4212cf22fa90ca7904618de1b6",
|
| 18 |
-
"pinned_target_base": "hf://datasets/SlayerLab/polish-dynaword@8cc48a3c564ac9edabfbbf012842ad11f70a3e5c",
|
| 19 |
-
"provider": "Kancelaria Sejmu RP",
|
| 20 |
-
"reuse_basis": {
|
| 21 |
-
"act": "Polish Open Data and Reuse of Public Sector Information Act",
|
| 22 |
-
"articles": [
|
| 23 |
-
"2(12)",
|
| 24 |
-
"5",
|
| 25 |
-
"6",
|
| 26 |
-
"14(1)",
|
| 27 |
-
"15",
|
| 28 |
-
"17"
|
| 29 |
-
],
|
| 30 |
-
"url": "https://eli.gov.pl/api/acts/DU/2023/1524/text.html"
|
| 31 |
-
},
|
| 32 |
-
"source": "sejm_api",
|
| 33 |
-
"status": "reviewed-open-official-materials"
|
| 34 |
-
}
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
data/sejm_api/sejm_api.md
DELETED
|
@@ -1,65 +0,0 @@
|
|
| 1 |
-
# sejm_api
|
| 2 |
-
|
| 3 |
-
Contemporary official Polish Sejm speeches, supplementing existing parliamentary sources.
|
| 4 |
-
|
| 5 |
-
## Dataset description
|
| 6 |
-
|
| 7 |
-
- Source (upstream): https://api.sejm.gov.pl/
|
| 8 |
-
- Source documentation: https://api.sejm.gov.pl/sejm.html
|
| 9 |
-
- Domain: political/spoken
|
| 10 |
-
- Language: Polish (`pl`)
|
| 11 |
-
- License: `public-domain (official documents)`
|
| 12 |
-
- Created (range): 2023-01-11, 2026-07-03
|
| 13 |
-
- Added: 2026-08-22
|
| 14 |
-
- Contributor: Piotr Styła (`PiotrSty` on Hugging Face; `PiotrStyla` on GitHub).
|
| 15 |
-
|
| 16 |
-
## Licensing — traceable basis
|
| 17 |
-
|
| 18 |
-
Official parliamentary documents and materials are excluded from copyright by
|
| 19 |
-
article 4(2) of the Polish Copyright Act: https://eli.gov.pl/api/acts/DU/2025/24/text/O/D20250024.pdf.
|
| 20 |
-
|
| 21 |
-
Reuse of public-sector information is governed by articles 2(12), 5, 6, 14,
|
| 22 |
-
15 and 17 of the Polish Open Data Act: https://eli.gov.pl/api/acts/DU/2023/1524/text.html.
|
| 23 |
-
|
| 24 |
-
The per-document value intentionally matches the existing `parliamentary`
|
| 25 |
-
source. No unverified upstream Creative Commons license is asserted.
|
| 26 |
-
|
| 27 |
-
## Provenance and reproducibility
|
| 28 |
-
|
| 29 |
-
- Official provider: Kancelaria Sejmu RP.
|
| 30 |
-
- Immutable source release: `PiotrSty/sejm-speeches-corpus@v1.0.1`.
|
| 31 |
-
- Pinned source commit: `124557799608ce4212cf22fa90ca7904618de1b6`.
|
| 32 |
-
- Reviewed DynaWord base commit: `8cc48a3c564ac9edabfbbf012842ad11f70a3e5c`.
|
| 33 |
-
- Rebuild: `python src/fetch_sejm_api.py --help`.
|
| 34 |
-
- Source URLs and speech-level provenance are in `sejm_api.attribution.jsonl`.
|
| 35 |
-
- Slayer contribution digest: `sha256:38e42a791d68d593f82e1125f2bb94cd8f68212433e71d3e3da90f82d78eaf32`.
|
| 36 |
-
|
| 37 |
-
## Temporal novelty and deduplication
|
| 38 |
-
|
| 39 |
-
`parliamentary` ends on `2019-12-31` and registered
|
| 40 |
-
`parlamint_pl` ends on `2022-12-31`. Every contributed
|
| 41 |
-
record is dated on or after `2023-01-01`, so its date range overlaps neither
|
| 42 |
-
source. Exact duplicate speech texts within the contribution are removed using
|
| 43 |
-
SHA-1 fingerprints; this is not a claim of global cross-domain near-deduplication.
|
| 44 |
-
|
| 45 |
-
## Statistics
|
| 46 |
-
|
| 47 |
-
| Measure | Value |
|
| 48 |
-
|---|---:|
|
| 49 |
-
| Source rows inspected | 157,714 |
|
| 50 |
-
| Rows before 2023-01-01 | 118,902 |
|
| 51 |
-
| Exact duplicate texts removed | 0 |
|
| 52 |
-
| Documents published | 38,812 |
|
| 53 |
-
| Characters | 96,596,566 |
|
| 54 |
-
| Tokens (`cl100k_base` proxy) | 36,335,587 |
|
| 55 |
-
| Documents with speaker attribution | 38,812 |
|
| 56 |
-
|
| 57 |
-
Statistics are recomputed from the released Parquet file. The canonical schema
|
| 58 |
-
is `id, text, source, added, created, token_count, license, author`.
|
| 59 |
-
|
| 60 |
-
## Privacy and limitations
|
| 61 |
-
|
| 62 |
-
The upstream release heuristically redacts email addresses, PESEL identifiers
|
| 63 |
-
and unambiguous Polish telephone numbers. Public-official names and speech
|
| 64 |
-
attribution remain. Regex redaction is not a guarantee of zero personal data.
|
| 65 |
-
Downstream users must review applicable privacy, third-party and source terms.
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
data/sejm_api/sejm_api.parquet
DELETED
|
@@ -1,3 +0,0 @@
|
|
| 1 |
-
version https://git-lfs.github.com/spec/v1
|
| 2 |
-
oid sha256:56f7b03483488dec8f0fa145c6d26746926175d83096e9d1931e535aa81cf161
|
| 3 |
-
size 35267581
|
|
|
|
|
|
|
|
|
|
|
|
data/sejm_api/sejm_api.stats.json
DELETED
|
@@ -1,36 +0,0 @@
|
|
| 1 |
-
{
|
| 2 |
-
"added": "2026-08-22",
|
| 3 |
-
"authors_with_value": 38812,
|
| 4 |
-
"by_source_split": {
|
| 5 |
-
"train": 38053,
|
| 6 |
-
"validation": 759
|
| 7 |
-
},
|
| 8 |
-
"by_term": {
|
| 9 |
-
"10": 30789,
|
| 10 |
-
"9": 8023
|
| 11 |
-
},
|
| 12 |
-
"by_year": {
|
| 13 |
-
"2023": 10220,
|
| 14 |
-
"2024": 4788,
|
| 15 |
-
"2025": 13712,
|
| 16 |
-
"2026": 10092
|
| 17 |
-
},
|
| 18 |
-
"chars": 96596566,
|
| 19 |
-
"created_max": "2026-07-03",
|
| 20 |
-
"created_min": "2023-01-11",
|
| 21 |
-
"drop_before_start": 118902,
|
| 22 |
-
"drop_dup": 0,
|
| 23 |
-
"drop_lang": 0,
|
| 24 |
-
"drop_ocr": 0,
|
| 25 |
-
"drop_short": 0,
|
| 26 |
-
"kept": 38812,
|
| 27 |
-
"license": "public-domain (official documents)",
|
| 28 |
-
"licenses": {
|
| 29 |
-
"public-domain (official documents)": 38812
|
| 30 |
-
},
|
| 31 |
-
"read": 157714,
|
| 32 |
-
"source_revision": "124557799608ce4212cf22fa90ca7904618de1b6",
|
| 33 |
-
"stats_recomputed_from_parquet": true,
|
| 34 |
-
"target_base_revision": "8cc48a3c564ac9edabfbbf012842ad11f70a3e5c",
|
| 35 |
-
"tokens": 36335587
|
| 36 |
-
}
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
data/uzp_orzeczenia_pl/NOTICE.md
DELETED
|
@@ -1,7 +0,0 @@
|
|
| 1 |
-
# Attribution and legal basis
|
| 2 |
-
|
| 3 |
-
Source: UZP decision search service, https://orzeczenia.uzp.gov.pl/ (Urzad Zamowien Publicznych / Public Procurement Office).
|
| 4 |
-
|
| 5 |
-
Records are official rulings (KIO, district courts, administrative courts, Supreme Court) in public procurement matters. Working basis: Polish Copyright Act art. 4(2) excludes official documents from copyright; no per-record license field exists on the service. Formal legal review has not been performed. Consult `artifacts/attribution.jsonl` for per-record provenance (organ, signature, issue date, URLs, checksums).
|
| 6 |
-
|
| 7 |
-
Preparation: Piotr Styla with Devin (Cognition). Changes: service-PDF text extraction, running-head and page-number removal, Unicode/whitespace normalization, line-wrap repair, limited email/phone/IP/identifier/account pattern redaction, language/quality filtering and within-source deduplication. Names of parties and adjudicators remain as part of the official record. No endorsement by UZP, KIO or the courts is implied.
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|