
Datasets:

Add files using upload-large-folder tool
Browse files- assets/foundation-pipelines/README.md +16 -0
- assets/foundation-pipelines/human-video-world-model-pipeline.png +3 -0
- assets/foundation-pipelines/prompts.md +39 -0
- assets/foundation-pipelines/spatial-intelligence-pipeline.png +3 -0
- assets/foundation-pipelines/vision-language-action-pipeline.png +3 -0
- docs/assets/foundation-pipelines/human-video-world-model-pipeline.png +3 -0
- docs/assets/foundation-pipelines/spatial-intelligence-pipeline.png +3 -0
- docs/assets/foundation-pipelines/vision-language-action-pipeline.png +3 -0
- scripts/omni/collect_qwen3_future_task_probe_results.sh +9 -7
- scripts/omni/eval_qwen3_omni_future_task_probes.py +195 -14
assets/foundation-pipelines/README.md
ADDED
|
@@ -0,0 +1,16 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Foundation Pipeline Placeholder Figures
|
| 2 |
+
|
| 3 |
+
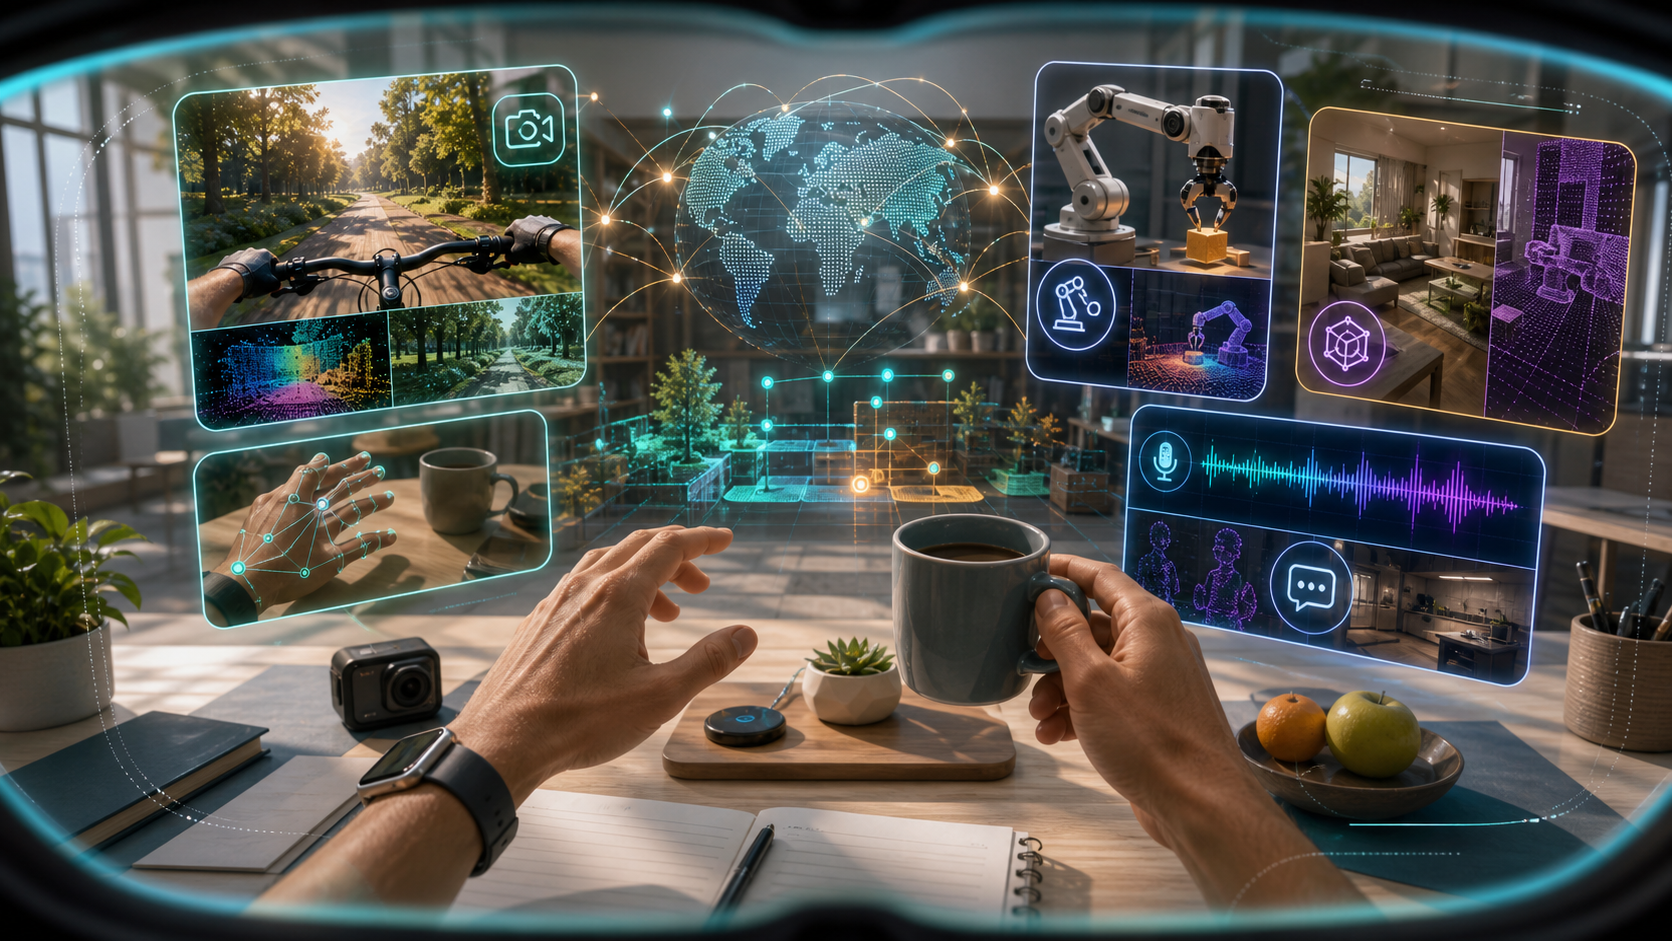
These three bitmap figures are ChatGPT image-generated placeholder visuals for
|
| 4 |
+
the foundation pipeline tracks documented in `THREE_FOUNDATION_PIPELINES.md`
|
| 5 |
+
and `docs/data/three_foundation_pipelines.json`.
|
| 6 |
+
|
| 7 |
+
They are **pipeline placeholders**, not evidence of completed foundation-model
|
| 8 |
+
training. Exact technical claims live in the surrounding Markdown, JSON, and
|
| 9 |
+
website labels.
|
| 10 |
+
|
| 11 |
+
| Track | Asset |
|
| 12 |
+
| --- | --- |
|
| 13 |
+
| Spatial intelligence models | `spatial-intelligence-pipeline.png` |
|
| 14 |
+
| Human-video world models | `human-video-world-model-pipeline.png` |
|
| 15 |
+
| Vision-language-action models | `vision-language-action-pipeline.png` |
|
| 16 |
+
|
assets/foundation-pipelines/human-video-world-model-pipeline.png
ADDED

|
Git LFS Details
|
assets/foundation-pipelines/prompts.md
ADDED
|
@@ -0,0 +1,39 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# ChatGPT Image Prompts
|
| 2 |
+
|
| 3 |
+
## Spatial Intelligence
|
| 4 |
+
|
| 5 |
+
Use case: infographic-diagram. Asset type: 16:9 website figure for Ropedia
|
| 6 |
+
Xperience-10M foundation pipeline track. Create a polished text-free diagram
|
| 7 |
+
image for a spatial intelligence model training pipeline. Show multi-view video
|
| 8 |
+
frames and depth/pose streams flowing into a scene-object memory module, then
|
| 9 |
+
spatial reasoning outputs like 3D structure, object permanence, counting, and
|
| 10 |
+
question answering. Use a premium dark research-product presentation style,
|
| 11 |
+
high contrast, crisp geometric panels, subtle neon green/cyan/white accents,
|
| 12 |
+
clean technical linework, no decorative blobs, no logos, no readable text, no
|
| 13 |
+
watermark.
|
| 14 |
+
|
| 15 |
+
## Human-Video World Models
|
| 16 |
+
|
| 17 |
+
Use case: infographic-diagram. Asset type: 16:9 website figure for Ropedia
|
| 18 |
+
Xperience-10M foundation pipeline track. Create a polished text-free diagram
|
| 19 |
+
image for a human-video world model training pipeline. Show observed egocentric
|
| 20 |
+
video/audio/sensor windows flowing into a latent world-state model, then
|
| 21 |
+
predicted future frames, future action bars, object/contact state changes, and
|
| 22 |
+
uncertainty bands. Use a premium dark research-product presentation style,
|
| 23 |
+
high contrast, crisp geometric panels, subtle neon green/teal/white accents
|
| 24 |
+
with small amber highlights, clean technical linework, no decorative blobs, no
|
| 25 |
+
logos, no readable text, no watermark.
|
| 26 |
+
|
| 27 |
+
## Vision-Language-Action
|
| 28 |
+
|
| 29 |
+
Use case: infographic-diagram. Asset type: 16:9 website figure for Ropedia
|
| 30 |
+
Xperience-10M foundation pipeline track. Create a polished text-free diagram
|
| 31 |
+
image for a vision-language-action model training pipeline. Show egocentric
|
| 32 |
+
video frames, language caption tokens, hand/body motion traces, object/contact
|
| 33 |
+
cues, and procedure labels flowing into a multimodal action policy module, then
|
| 34 |
+
predicted action chunks, hand trajectory curves, contact decisions, and policy
|
| 35 |
+
evaluation panels. Use a premium dark research-product presentation style,
|
| 36 |
+
high contrast, crisp geometric panels, subtle neon green/cyan/white accents
|
| 37 |
+
with small magenta highlights, clean technical linework, no decorative blobs,
|
| 38 |
+
no logos, no readable text, no watermark.
|
| 39 |
+
|
assets/foundation-pipelines/spatial-intelligence-pipeline.png
ADDED

|
Git LFS Details
|
assets/foundation-pipelines/vision-language-action-pipeline.png
ADDED

|
Git LFS Details
|
docs/assets/foundation-pipelines/human-video-world-model-pipeline.png
ADDED

|
Git LFS Details
|
docs/assets/foundation-pipelines/spatial-intelligence-pipeline.png
ADDED
|
Git LFS Details
|
docs/assets/foundation-pipelines/vision-language-action-pipeline.png
ADDED

|
Git LFS Details
|
scripts/omni/collect_qwen3_future_task_probe_results.sh
CHANGED
|
@@ -14,12 +14,9 @@ REMOTE_RUN_DIR="${REMOTE_ROOT}/${RESULT_ROOT}/${RUN_ID}"
|
|
| 14 |
LOCAL_RUN_DIR="${PROJECT_ROOT}/${RESULT_ROOT}/${RUN_ID}"
|
| 15 |
LOCAL_LAUNCHER_DIR="${PROJECT_ROOT}/${RESULT_ROOT}/deferred_launchers"
|
| 16 |
REMOTE_LAUNCHER_LOG="${REMOTE_ROOT}/${RESULT_ROOT}/deferred_launchers/${RUN_ID}.launcher.log"
|
|
|
|
| 17 |
|
| 18 |
-
|
| 19 |
-
long_horizon_next_action
|
| 20 |
-
next_subtask_forecast
|
| 21 |
-
object_set_forecast
|
| 22 |
-
)
|
| 23 |
|
| 24 |
echo "checking remote run ${REMOTE_HOST}:${REMOTE_RUN_DIR}"
|
| 25 |
ssh "$REMOTE_HOST" "cd '$REMOTE_ROOT' && test -s '${RESULT_ROOT}/${RUN_ID}/summary.json'"
|
|
@@ -33,19 +30,24 @@ ssh "$REMOTE_HOST" "test -s '$REMOTE_LAUNCHER_LOG'" >/dev/null 2>&1 \
|
|
| 33 |
&& rsync -av "${REMOTE_HOST}:${REMOTE_LAUNCHER_LOG}" "$LOCAL_LAUNCHER_DIR/" \
|
| 34 |
|| true
|
| 35 |
|
| 36 |
-
python3 - "$PROJECT_ROOT" "$RUN_ID" <<'PY'
|
| 37 |
import json
|
| 38 |
import sys
|
| 39 |
from pathlib import Path
|
| 40 |
|
| 41 |
root = Path(sys.argv[1])
|
| 42 |
run_id = sys.argv[2]
|
|
|
|
| 43 |
run_dir = root / "results/omni_finetune" / run_id
|
| 44 |
-
|
|
|
|
|
|
|
| 45 |
"long_horizon_next_action": "long_horizon_next_action_macro_f1",
|
| 46 |
"next_subtask_forecast": "next_subtask_forecast_macro_f1",
|
| 47 |
"object_set_forecast": "object_set_forecast_micro_f1",
|
|
|
|
| 48 |
}
|
|
|
|
| 49 |
|
| 50 |
summary_path = run_dir / "summary.json"
|
| 51 |
if not summary_path.exists():
|
|
|
|
| 14 |
LOCAL_RUN_DIR="${PROJECT_ROOT}/${RESULT_ROOT}/${RUN_ID}"
|
| 15 |
LOCAL_LAUNCHER_DIR="${PROJECT_ROOT}/${RESULT_ROOT}/deferred_launchers"
|
| 16 |
REMOTE_LAUNCHER_LOG="${REMOTE_ROOT}/${RESULT_ROOT}/deferred_launchers/${RUN_ID}.launcher.log"
|
| 17 |
+
TASKS_CSV="${TASKS_CSV:-long_horizon_next_action,next_subtask_forecast,object_set_forecast}"
|
| 18 |
|
| 19 |
+
IFS=',' read -r -a TASKS <<< "$TASKS_CSV"
|
|
|
|
|
|
|
|
|
|
|
|
|
| 20 |
|
| 21 |
echo "checking remote run ${REMOTE_HOST}:${REMOTE_RUN_DIR}"
|
| 22 |
ssh "$REMOTE_HOST" "cd '$REMOTE_ROOT' && test -s '${RESULT_ROOT}/${RUN_ID}/summary.json'"
|
|
|
|
| 30 |
&& rsync -av "${REMOTE_HOST}:${REMOTE_LAUNCHER_LOG}" "$LOCAL_LAUNCHER_DIR/" \
|
| 31 |
|| true
|
| 32 |
|
| 33 |
+
python3 - "$PROJECT_ROOT" "$RUN_ID" "$TASKS_CSV" <<'PY'
|
| 34 |
import json
|
| 35 |
import sys
|
| 36 |
from pathlib import Path
|
| 37 |
|
| 38 |
root = Path(sys.argv[1])
|
| 39 |
run_id = sys.argv[2]
|
| 40 |
+
task_ids = [item.strip() for item in sys.argv[3].split(",") if item.strip()]
|
| 41 |
run_dir = root / "results/omni_finetune" / run_id
|
| 42 |
+
metric_key_by_task = {
|
| 43 |
+
"temporal_order": "temporal_order_f1",
|
| 44 |
+
"misalignment_detection": "misalignment_detection_f1",
|
| 45 |
"long_horizon_next_action": "long_horizon_next_action_macro_f1",
|
| 46 |
"next_subtask_forecast": "next_subtask_forecast_macro_f1",
|
| 47 |
"object_set_forecast": "object_set_forecast_micro_f1",
|
| 48 |
+
"time_to_transition": "time_to_transition_mae",
|
| 49 |
}
|
| 50 |
+
expected = {task_id: metric_key_by_task[task_id] for task_id in task_ids}
|
| 51 |
|
| 52 |
summary_path = run_dir / "summary.json"
|
| 53 |
if not summary_path.exists():
|
scripts/omni/eval_qwen3_omni_future_task_probes.py
CHANGED
|
@@ -1,14 +1,17 @@
|
|
| 1 |
#!/usr/bin/env python3
|
| 2 |
"""Evaluate Qwen3-Omni on future-target task probes from the 128-episode JSON.
|
| 3 |
|
| 4 |
-
This runner scores
|
| 5 |
-
multi-episode JSON export:
|
| 6 |
|
| 7 |
- Task 13: long-horizon next action, +100 frames.
|
| 8 |
- Task 14: long-horizon next subtask, +100 frames.
|
| 9 |
- Task 17: future object set, +100 frames.
|
|
|
|
|
|
|
|
|
|
| 10 |
|
| 11 |
-
It does not fabricate scores for
|
| 12 |
missing-modality targets.
|
| 13 |
"""
|
| 14 |
|
|
@@ -16,7 +19,9 @@ from __future__ import annotations
|
|
| 16 |
|
| 17 |
import argparse
|
| 18 |
import csv
|
|
|
|
| 19 |
import json
|
|
|
|
| 20 |
import time
|
| 21 |
from collections import OrderedDict
|
| 22 |
from pathlib import Path
|
|
@@ -37,6 +42,32 @@ from qwen3_omni_dataset_utils import (
|
|
| 37 |
|
| 38 |
TASK_SPECS: OrderedDict[str, dict[str, Any]] = OrderedDict(
|
| 39 |
[
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 40 |
(
|
| 41 |
"long_horizon_next_action",
|
| 42 |
{
|
|
@@ -73,6 +104,18 @@ TASK_SPECS: OrderedDict[str, dict[str, Any]] = OrderedDict(
|
|
| 73 |
"option_field": None,
|
| 74 |
},
|
| 75 |
),
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 76 |
]
|
| 77 |
)
|
| 78 |
|
|
@@ -207,6 +250,22 @@ def future_index_map(samples: list[dict[str, Any]], frame_offset: int) -> dict[i
|
|
| 207 |
return mapping
|
| 208 |
|
| 209 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 210 |
def parse_json_object(text: str) -> dict[str, Any]:
|
| 211 |
raw = str(text or "").strip()
|
| 212 |
if raw.startswith("```"):
|
|
@@ -227,7 +286,25 @@ def parse_json_object(text: str) -> dict[str, Any]:
|
|
| 227 |
return payload if isinstance(payload, dict) else {}
|
| 228 |
|
| 229 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 230 |
def task_options(sample: dict[str, Any], spec: dict[str, Any]) -> list[str]:
|
|
|
|
|
|
|
| 231 |
option_field = spec.get("option_field")
|
| 232 |
options = sample.get(option_field) if option_field else None
|
| 233 |
if isinstance(options, list) and options:
|
|
@@ -247,8 +324,12 @@ def build_task_prompt(sample: dict[str, Any], future_sample: dict[str, Any], tas
|
|
| 247 |
f"Task {spec['task_number']}: {spec['label']}",
|
| 248 |
f"Episode: {sample.get('episode_id')}",
|
| 249 |
f"Current visible/audio context frames: {start}-{end}",
|
| 250 |
-
f"Predict the target at the future window starting near frame {start + future_frames} (resolved target start frame {future_start}).",
|
| 251 |
]
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 252 |
options = task_options(sample, spec)
|
| 253 |
if task_id == "long_horizon_next_action":
|
| 254 |
lines.extend(
|
|
@@ -276,6 +357,35 @@ def build_task_prompt(sample: dict[str, Any], future_sample: dict[str, Any], tas
|
|
| 276 |
"List the objects likely to be active or manipulated in that future window. Use short object names.",
|
| 277 |
]
|
| 278 |
)
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 279 |
else:
|
| 280 |
raise ValueError(f"unknown task: {task_id}")
|
| 281 |
return "\n".join(lines)
|
|
@@ -290,14 +400,30 @@ def build_messages(
|
|
| 290 |
*,
|
| 291 |
include_audio: bool = True,
|
| 292 |
) -> list[dict[str, Any]]:
|
| 293 |
-
|
| 294 |
-
|
| 295 |
-
audio_path = media.get("audio_path")
|
| 296 |
content: list[dict[str, Any]] = []
|
| 297 |
-
if
|
| 298 |
-
|
| 299 |
-
|
| 300 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 301 |
content.append({"type": "text", "text": build_task_prompt(sample, future_sample, task_id, spec, future_frames)})
|
| 302 |
return [
|
| 303 |
{"role": "system", "content": [{"type": "text", "text": SYSTEM_PROMPT}]},
|
|
@@ -394,10 +520,32 @@ def extract_prediction(raw: str, sample: dict[str, Any], spec: dict[str, Any]) -
|
|
| 394 |
value = payload.get(spec["prediction_key"])
|
| 395 |
if spec["family"] == "multi_label":
|
| 396 |
return normalize_objects(value)
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 397 |
options = task_options(sample, spec)
|
| 398 |
return match_label(str(value or raw), options) if options else normalize_text(value)
|
| 399 |
|
| 400 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 401 |
def object_set_metrics(rows: list[dict[str, Any]]) -> dict[str, float]:
|
| 402 |
tp = fp = fn = exact = 0
|
| 403 |
for row in rows:
|
|
@@ -419,6 +567,26 @@ def object_set_metrics(rows: list[dict[str, Any]]) -> dict[str, float]:
|
|
| 419 |
}
|
| 420 |
|
| 421 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 422 |
def score_task(task_id: str, spec: dict[str, Any], rows: list[dict[str, Any]], output_dir: Path, args: argparse.Namespace) -> dict[str, Any]:
|
| 423 |
task_dir = output_dir / task_id
|
| 424 |
task_dir.mkdir(parents=True, exist_ok=True)
|
|
@@ -471,11 +639,17 @@ def score_task(task_id: str, spec: dict[str, Any], rows: list[dict[str, Any]], o
|
|
| 471 |
metrics[f"{task_id}_accuracy"] = metrics["accuracy"]
|
| 472 |
write_csv(task_dir / "per_class_metrics.csv", per_class, ["class_name", "support", "predicted", "precision", "recall", "f1"])
|
| 473 |
primary_score = metrics["macro_f1"]
|
| 474 |
-
|
| 475 |
metrics = object_set_metrics(rows)
|
| 476 |
metrics[f"{task_id}_micro_f1"] = metrics["micro_f1"]
|
| 477 |
metrics[f"{task_id}_exact_match"] = metrics["exact_match"]
|
| 478 |
primary_score = metrics["micro_f1"]
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 479 |
|
| 480 |
metrics.update(
|
| 481 |
{
|
|
@@ -516,6 +690,7 @@ def main() -> int:
|
|
| 516 |
selected_tasks = select_tasks(args.tasks)
|
| 517 |
samples = load_jsonl(args.dataset_jsonl)
|
| 518 |
future_map = future_index_map(samples, args.future_frames)
|
|
|
|
| 519 |
eval_indices = [idx for idx in select_eval_indices(samples, args) if idx in future_map]
|
| 520 |
if not eval_indices:
|
| 521 |
raise ValueError("No evaluation samples with future targets selected.")
|
|
@@ -554,8 +729,14 @@ def main() -> int:
|
|
| 554 |
continue
|
| 555 |
started = time.time()
|
| 556 |
raw = generate_messages(model, processor, sample, future_sample, task_id, spec, args)
|
| 557 |
-
true_value =
|
| 558 |
predicted_value = extract_prediction(raw, sample, spec)
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 559 |
row = {
|
| 560 |
"prediction_id": pred_id,
|
| 561 |
"id": sample.get("id"),
|
|
@@ -571,7 +752,7 @@ def main() -> int:
|
|
| 571 |
"true_value": true_value,
|
| 572 |
"predicted_value": predicted_value,
|
| 573 |
"raw_prediction": raw,
|
| 574 |
-
"correct":
|
| 575 |
}
|
| 576 |
partial_by_task[task_id][pred_id] = row
|
| 577 |
append_jsonl(partial_path, row)
|
|
|
|
| 1 |
#!/usr/bin/env python3
|
| 2 |
"""Evaluate Qwen3-Omni on future-target task probes from the 128-episode JSON.
|
| 3 |
|
| 4 |
+
This runner scores task targets that can be derived from the current
|
| 5 |
+
multi-episode JSON export and staged media:
|
| 6 |
|
| 7 |
- Task 13: long-horizon next action, +100 frames.
|
| 8 |
- Task 14: long-horizon next subtask, +100 frames.
|
| 9 |
- Task 17: future object set, +100 frames.
|
| 10 |
+
- Task 11: temporal order from two staged video windows.
|
| 11 |
+
- Task 12: audio-video misalignment from staged video/audio windows.
|
| 12 |
+
- Task 20: capped frames until next action transition.
|
| 13 |
|
| 14 |
+
It does not fabricate scores for retrieval, raw-caption, raw hand-pose, or
|
| 15 |
missing-modality targets.
|
| 16 |
"""
|
| 17 |
|
|
|
|
| 19 |
|
| 20 |
import argparse
|
| 21 |
import csv
|
| 22 |
+
import hashlib
|
| 23 |
import json
|
| 24 |
+
import re
|
| 25 |
import time
|
| 26 |
from collections import OrderedDict
|
| 27 |
from pathlib import Path
|
|
|
|
| 42 |
|
| 43 |
TASK_SPECS: OrderedDict[str, dict[str, Any]] = OrderedDict(
|
| 44 |
[
|
| 45 |
+
(
|
| 46 |
+
"temporal_order",
|
| 47 |
+
{
|
| 48 |
+
"task_number": 11,
|
| 49 |
+
"label": "Temporal Order Verification",
|
| 50 |
+
"family": "classification",
|
| 51 |
+
"metric_key": "temporal_order_f1",
|
| 52 |
+
"prediction_key": "temporal_order",
|
| 53 |
+
"target_field": None,
|
| 54 |
+
"option_field": None,
|
| 55 |
+
"options": ["correct", "reversed"],
|
| 56 |
+
},
|
| 57 |
+
),
|
| 58 |
+
(
|
| 59 |
+
"misalignment_detection",
|
| 60 |
+
{
|
| 61 |
+
"task_number": 12,
|
| 62 |
+
"label": "Multimodal Misalignment Detection",
|
| 63 |
+
"family": "classification",
|
| 64 |
+
"metric_key": "misalignment_detection_f1",
|
| 65 |
+
"prediction_key": "misalignment_detection",
|
| 66 |
+
"target_field": None,
|
| 67 |
+
"option_field": None,
|
| 68 |
+
"options": ["aligned", "shifted"],
|
| 69 |
+
},
|
| 70 |
+
),
|
| 71 |
(
|
| 72 |
"long_horizon_next_action",
|
| 73 |
{
|
|
|
|
| 104 |
"option_field": None,
|
| 105 |
},
|
| 106 |
),
|
| 107 |
+
(
|
| 108 |
+
"time_to_transition",
|
| 109 |
+
{
|
| 110 |
+
"task_number": 20,
|
| 111 |
+
"label": "Time to Transition",
|
| 112 |
+
"family": "regression",
|
| 113 |
+
"metric_key": "time_to_transition_mae",
|
| 114 |
+
"prediction_key": "time_to_transition_frames",
|
| 115 |
+
"target_field": None,
|
| 116 |
+
"option_field": None,
|
| 117 |
+
},
|
| 118 |
+
),
|
| 119 |
]
|
| 120 |
)
|
| 121 |
|
|
|
|
| 250 |
return mapping
|
| 251 |
|
| 252 |
|
| 253 |
+
def time_to_transition_map(samples: list[dict[str, Any]], cap_frames: int = 200) -> dict[int, int]:
|
| 254 |
+
mapping: dict[int, int] = {}
|
| 255 |
+
for indices in by_episode_sorted(samples).values():
|
| 256 |
+
actions = [normalize_text(answer(samples[idx]).get("action")) for idx in indices]
|
| 257 |
+
starts = [row_start(samples[idx]) for idx in indices]
|
| 258 |
+
for pos, idx in enumerate(indices):
|
| 259 |
+
current_action = actions[pos]
|
| 260 |
+
target = cap_frames
|
| 261 |
+
for next_pos in range(pos + 1, len(indices)):
|
| 262 |
+
if actions[next_pos] and actions[next_pos] != current_action:
|
| 263 |
+
target = min(cap_frames, max(0, starts[next_pos] - starts[pos]))
|
| 264 |
+
break
|
| 265 |
+
mapping[idx] = target
|
| 266 |
+
return mapping
|
| 267 |
+
|
| 268 |
+
|
| 269 |
def parse_json_object(text: str) -> dict[str, Any]:
|
| 270 |
raw = str(text or "").strip()
|
| 271 |
if raw.startswith("```"):
|
|
|
|
| 286 |
return payload if isinstance(payload, dict) else {}
|
| 287 |
|
| 288 |
|
| 289 |
+
def stable_variant(task_id: str, sample: dict[str, Any]) -> bool:
|
| 290 |
+
key = f"{task_id}::{sample.get('id')}"
|
| 291 |
+
digest = hashlib.sha1(key.encode("utf-8")).hexdigest()
|
| 292 |
+
return int(digest[:2], 16) % 2 == 0
|
| 293 |
+
|
| 294 |
+
|
| 295 |
+
def media_video_path(sample: dict[str, Any]) -> str | None:
|
| 296 |
+
media = sample.get("media") if isinstance(sample.get("media"), dict) else {}
|
| 297 |
+
return media.get("mosaic_video_path") or sample.get("primary_video_path")
|
| 298 |
+
|
| 299 |
+
|
| 300 |
+
def media_audio_path(sample: dict[str, Any]) -> str | None:
|
| 301 |
+
media = sample.get("media") if isinstance(sample.get("media"), dict) else {}
|
| 302 |
+
return media.get("audio_path")
|
| 303 |
+
|
| 304 |
+
|
| 305 |
def task_options(sample: dict[str, Any], spec: dict[str, Any]) -> list[str]:
|
| 306 |
+
if isinstance(spec.get("options"), list):
|
| 307 |
+
return [str(item) for item in spec["options"]]
|
| 308 |
option_field = spec.get("option_field")
|
| 309 |
options = sample.get(option_field) if option_field else None
|
| 310 |
if isinstance(options, list) and options:
|
|
|
|
| 324 |
f"Task {spec['task_number']}: {spec['label']}",
|
| 325 |
f"Episode: {sample.get('episode_id')}",
|
| 326 |
f"Current visible/audio context frames: {start}-{end}",
|
|
|
|
| 327 |
]
|
| 328 |
+
if task_id in {"long_horizon_next_action", "next_subtask_forecast", "object_set_forecast"}:
|
| 329 |
+
lines.append(
|
| 330 |
+
f"Predict the target at the future window starting near frame {start + future_frames} "
|
| 331 |
+
f"(resolved target start frame {future_start})."
|
| 332 |
+
)
|
| 333 |
options = task_options(sample, spec)
|
| 334 |
if task_id == "long_horizon_next_action":
|
| 335 |
lines.extend(
|
|
|
|
| 357 |
"List the objects likely to be active or manipulated in that future window. Use short object names.",
|
| 358 |
]
|
| 359 |
)
|
| 360 |
+
elif task_id == "temporal_order":
|
| 361 |
+
lines.extend(
|
| 362 |
+
[
|
| 363 |
+
"You will receive two video clips named Clip A and Clip B.",
|
| 364 |
+
"Return JSON only with this schema:",
|
| 365 |
+
f'{{"{prediction_key}":"<correct or reversed>"}}',
|
| 366 |
+
"Answer correct if Clip A happens before Clip B in the same episode.",
|
| 367 |
+
"Answer reversed if Clip A happens after Clip B in the same episode.",
|
| 368 |
+
]
|
| 369 |
+
)
|
| 370 |
+
elif task_id == "misalignment_detection":
|
| 371 |
+
lines.extend(
|
| 372 |
+
[
|
| 373 |
+
"You will receive one video clip and one audio clip.",
|
| 374 |
+
"Return JSON only with this schema:",
|
| 375 |
+
f'{{"{prediction_key}":"<aligned or shifted>"}}',
|
| 376 |
+
"Answer aligned if the audio belongs to the same time window as the video.",
|
| 377 |
+
"Answer shifted if the audio comes from a later shifted window in the same episode.",
|
| 378 |
+
]
|
| 379 |
+
)
|
| 380 |
+
elif task_id == "time_to_transition":
|
| 381 |
+
lines.extend(
|
| 382 |
+
[
|
| 383 |
+
"Estimate how many frames remain until the next action-label boundary.",
|
| 384 |
+
"The answer is capped at 200 frames.",
|
| 385 |
+
"Return JSON only with this schema:",
|
| 386 |
+
f'{{"{prediction_key}":<integer from 0 to 200>}}',
|
| 387 |
+
]
|
| 388 |
+
)
|
| 389 |
else:
|
| 390 |
raise ValueError(f"unknown task: {task_id}")
|
| 391 |
return "\n".join(lines)
|
|
|
|
| 400 |
*,
|
| 401 |
include_audio: bool = True,
|
| 402 |
) -> list[dict[str, Any]]:
|
| 403 |
+
video_path = media_video_path(sample)
|
| 404 |
+
audio_path = media_audio_path(sample)
|
|
|
|
| 405 |
content: list[dict[str, Any]] = []
|
| 406 |
+
if task_id == "temporal_order":
|
| 407 |
+
future_video_path = media_video_path(future_sample)
|
| 408 |
+
if stable_variant(task_id, sample):
|
| 409 |
+
first_video, second_video = video_path, future_video_path
|
| 410 |
+
else:
|
| 411 |
+
first_video, second_video = future_video_path, video_path
|
| 412 |
+
if first_video:
|
| 413 |
+
content.append({"type": "video", "video": first_video})
|
| 414 |
+
if second_video:
|
| 415 |
+
content.append({"type": "video", "video": second_video})
|
| 416 |
+
elif task_id == "misalignment_detection":
|
| 417 |
+
paired_audio_path = audio_path if stable_variant(task_id, sample) else media_audio_path(future_sample)
|
| 418 |
+
if video_path:
|
| 419 |
+
content.append({"type": "video", "video": video_path})
|
| 420 |
+
if include_audio and paired_audio_path:
|
| 421 |
+
content.append({"type": "audio", "audio": paired_audio_path})
|
| 422 |
+
else:
|
| 423 |
+
if video_path:
|
| 424 |
+
content.append({"type": "video", "video": video_path})
|
| 425 |
+
if include_audio and audio_path:
|
| 426 |
+
content.append({"type": "audio", "audio": audio_path})
|
| 427 |
content.append({"type": "text", "text": build_task_prompt(sample, future_sample, task_id, spec, future_frames)})
|
| 428 |
return [
|
| 429 |
{"role": "system", "content": [{"type": "text", "text": SYSTEM_PROMPT}]},
|
|
|
|
| 520 |
value = payload.get(spec["prediction_key"])
|
| 521 |
if spec["family"] == "multi_label":
|
| 522 |
return normalize_objects(value)
|
| 523 |
+
if spec["family"] == "regression":
|
| 524 |
+
match = re.search(r"-?\d+(?:\.\d+)?", str(value if value is not None else raw))
|
| 525 |
+
if not match:
|
| 526 |
+
return None
|
| 527 |
+
return max(0.0, min(200.0, float(match.group(0))))
|
| 528 |
options = task_options(sample, spec)
|
| 529 |
return match_label(str(value or raw), options) if options else normalize_text(value)
|
| 530 |
|
| 531 |
|
| 532 |
+
def task_target_value(
|
| 533 |
+
task_id: str,
|
| 534 |
+
sample: dict[str, Any],
|
| 535 |
+
future_sample: dict[str, Any],
|
| 536 |
+
spec: dict[str, Any],
|
| 537 |
+
transition_targets: dict[int, int],
|
| 538 |
+
sample_idx: int,
|
| 539 |
+
) -> Any:
|
| 540 |
+
if task_id == "temporal_order":
|
| 541 |
+
return "correct" if stable_variant(task_id, sample) else "reversed"
|
| 542 |
+
if task_id == "misalignment_detection":
|
| 543 |
+
return "aligned" if stable_variant(task_id, sample) else "shifted"
|
| 544 |
+
if task_id == "time_to_transition":
|
| 545 |
+
return float(transition_targets[sample_idx])
|
| 546 |
+
return task_target(future_sample, spec)
|
| 547 |
+
|
| 548 |
+
|
| 549 |
def object_set_metrics(rows: list[dict[str, Any]]) -> dict[str, float]:
|
| 550 |
tp = fp = fn = exact = 0
|
| 551 |
for row in rows:
|
|
|
|
| 567 |
}
|
| 568 |
|
| 569 |
|
| 570 |
+
def regression_metrics(rows: list[dict[str, Any]]) -> dict[str, float]:
|
| 571 |
+
errors = []
|
| 572 |
+
within_20 = 0
|
| 573 |
+
for row in rows:
|
| 574 |
+
true_value = float(row.get("true_value") or 0.0)
|
| 575 |
+
pred_value = row.get("predicted_value")
|
| 576 |
+
if pred_value is None:
|
| 577 |
+
pred_value = 200.0
|
| 578 |
+
err = abs(float(pred_value) - true_value)
|
| 579 |
+
errors.append(err)
|
| 580 |
+
within_20 += int(err <= 20.0)
|
| 581 |
+
mae = float(np.mean(errors)) if errors else 0.0
|
| 582 |
+
return {
|
| 583 |
+
"num_samples": len(rows),
|
| 584 |
+
"mae": mae,
|
| 585 |
+
"time_to_transition_mae": mae,
|
| 586 |
+
"within_20_frames": within_20 / len(rows) if rows else 0.0,
|
| 587 |
+
}
|
| 588 |
+
|
| 589 |
+
|
| 590 |
def score_task(task_id: str, spec: dict[str, Any], rows: list[dict[str, Any]], output_dir: Path, args: argparse.Namespace) -> dict[str, Any]:
|
| 591 |
task_dir = output_dir / task_id
|
| 592 |
task_dir.mkdir(parents=True, exist_ok=True)
|
|
|
|
| 639 |
metrics[f"{task_id}_accuracy"] = metrics["accuracy"]
|
| 640 |
write_csv(task_dir / "per_class_metrics.csv", per_class, ["class_name", "support", "predicted", "precision", "recall", "f1"])
|
| 641 |
primary_score = metrics["macro_f1"]
|
| 642 |
+
elif spec["family"] == "multi_label":
|
| 643 |
metrics = object_set_metrics(rows)
|
| 644 |
metrics[f"{task_id}_micro_f1"] = metrics["micro_f1"]
|
| 645 |
metrics[f"{task_id}_exact_match"] = metrics["exact_match"]
|
| 646 |
primary_score = metrics["micro_f1"]
|
| 647 |
+
elif spec["family"] == "regression":
|
| 648 |
+
metrics = regression_metrics(rows)
|
| 649 |
+
primary_score = metrics["mae"]
|
| 650 |
+
else:
|
| 651 |
+
raise ValueError(f"unsupported task family: {spec['family']}")
|
| 652 |
+
metrics[spec["metric_key"]] = primary_score
|
| 653 |
|
| 654 |
metrics.update(
|
| 655 |
{
|
|
|
|
| 690 |
selected_tasks = select_tasks(args.tasks)
|
| 691 |
samples = load_jsonl(args.dataset_jsonl)
|
| 692 |
future_map = future_index_map(samples, args.future_frames)
|
| 693 |
+
transition_targets = time_to_transition_map(samples)
|
| 694 |
eval_indices = [idx for idx in select_eval_indices(samples, args) if idx in future_map]
|
| 695 |
if not eval_indices:
|
| 696 |
raise ValueError("No evaluation samples with future targets selected.")
|
|
|
|
| 729 |
continue
|
| 730 |
started = time.time()
|
| 731 |
raw = generate_messages(model, processor, sample, future_sample, task_id, spec, args)
|
| 732 |
+
true_value = task_target_value(task_id, sample, future_sample, spec, transition_targets, sample_idx)
|
| 733 |
predicted_value = extract_prediction(raw, sample, spec)
|
| 734 |
+
if spec["family"] == "classification":
|
| 735 |
+
correct = int(true_value == predicted_value)
|
| 736 |
+
elif spec["family"] == "multi_label":
|
| 737 |
+
correct = int(set(true_value) == set(predicted_value))
|
| 738 |
+
else:
|
| 739 |
+
correct = int(predicted_value is not None and abs(float(true_value) - float(predicted_value)) <= 20.0)
|
| 740 |
row = {
|
| 741 |
"prediction_id": pred_id,
|
| 742 |
"id": sample.get("id"),
|
|
|
|
| 752 |
"true_value": true_value,
|
| 753 |
"predicted_value": predicted_value,
|
| 754 |
"raw_prediction": raw,
|
| 755 |
+
"correct": correct,
|
| 756 |
}
|
| 757 |
partial_by_task[task_id][pred_id] = row
|
| 758 |
append_jsonl(partial_path, row)
|