
Datasets:
Publish Xperience-10M task-suite derived artifacts
Browse files- DATA_NOTICE.md +2 -2
- PROJECT_README.md +112 -13
- README.md +5 -5
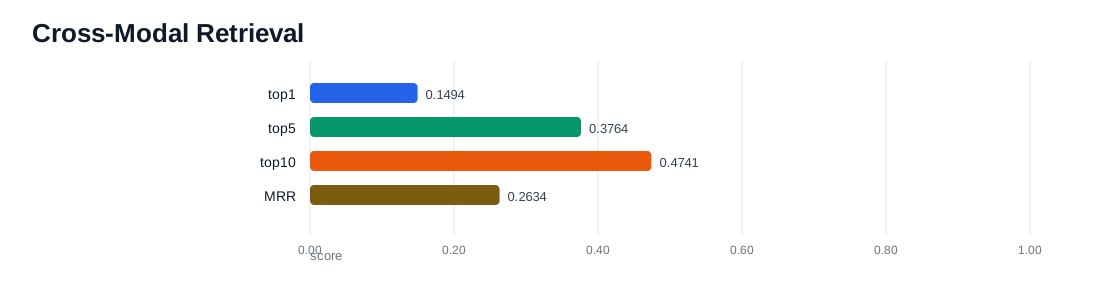
- assets/charts/cross_modal_retrieval.svg +29 -0
- assets/charts/episode_task_scores.svg +53 -0
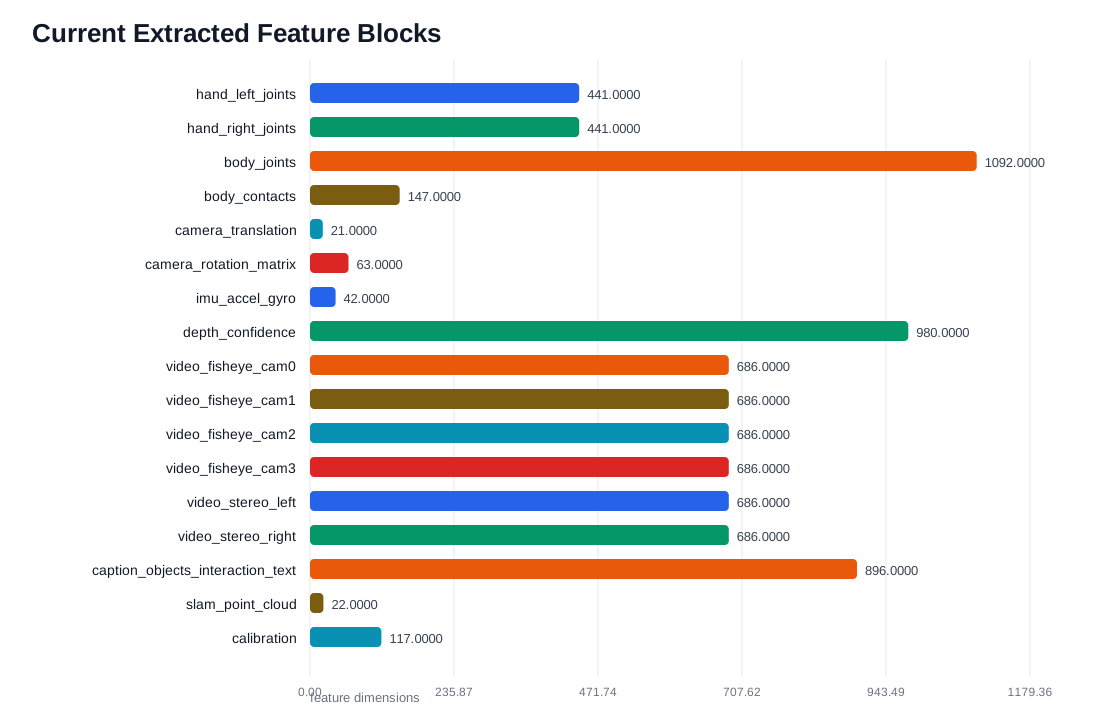
- assets/charts/feature_blocks.svg +68 -0
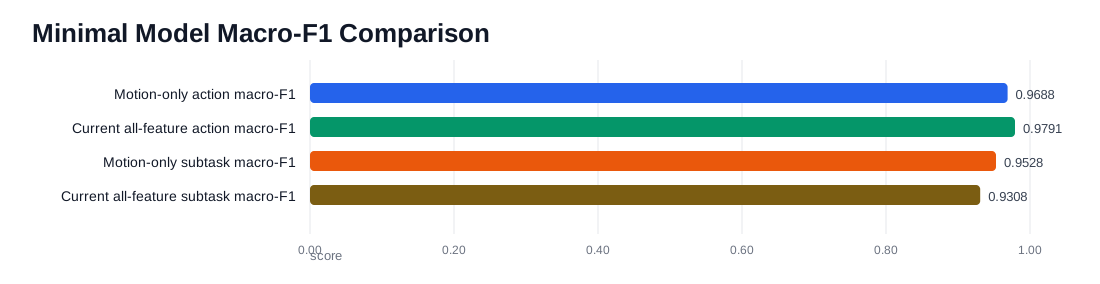
- assets/charts/model_macro_f1.svg +29 -0
- assets/pipeline_diagram.png +2 -2
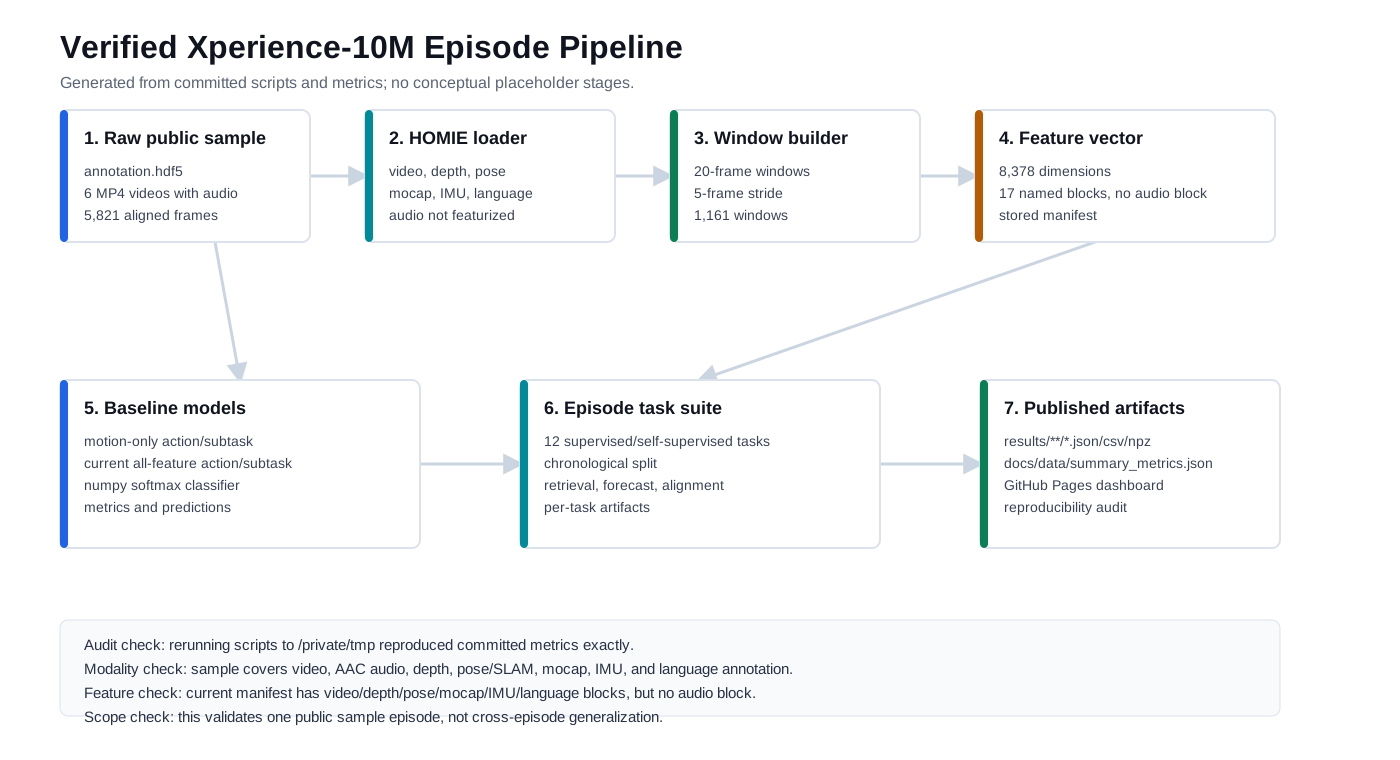
- assets/pipeline_diagram.svg +1 -1
- assets/pipeline_diagram_base.png +3 -0
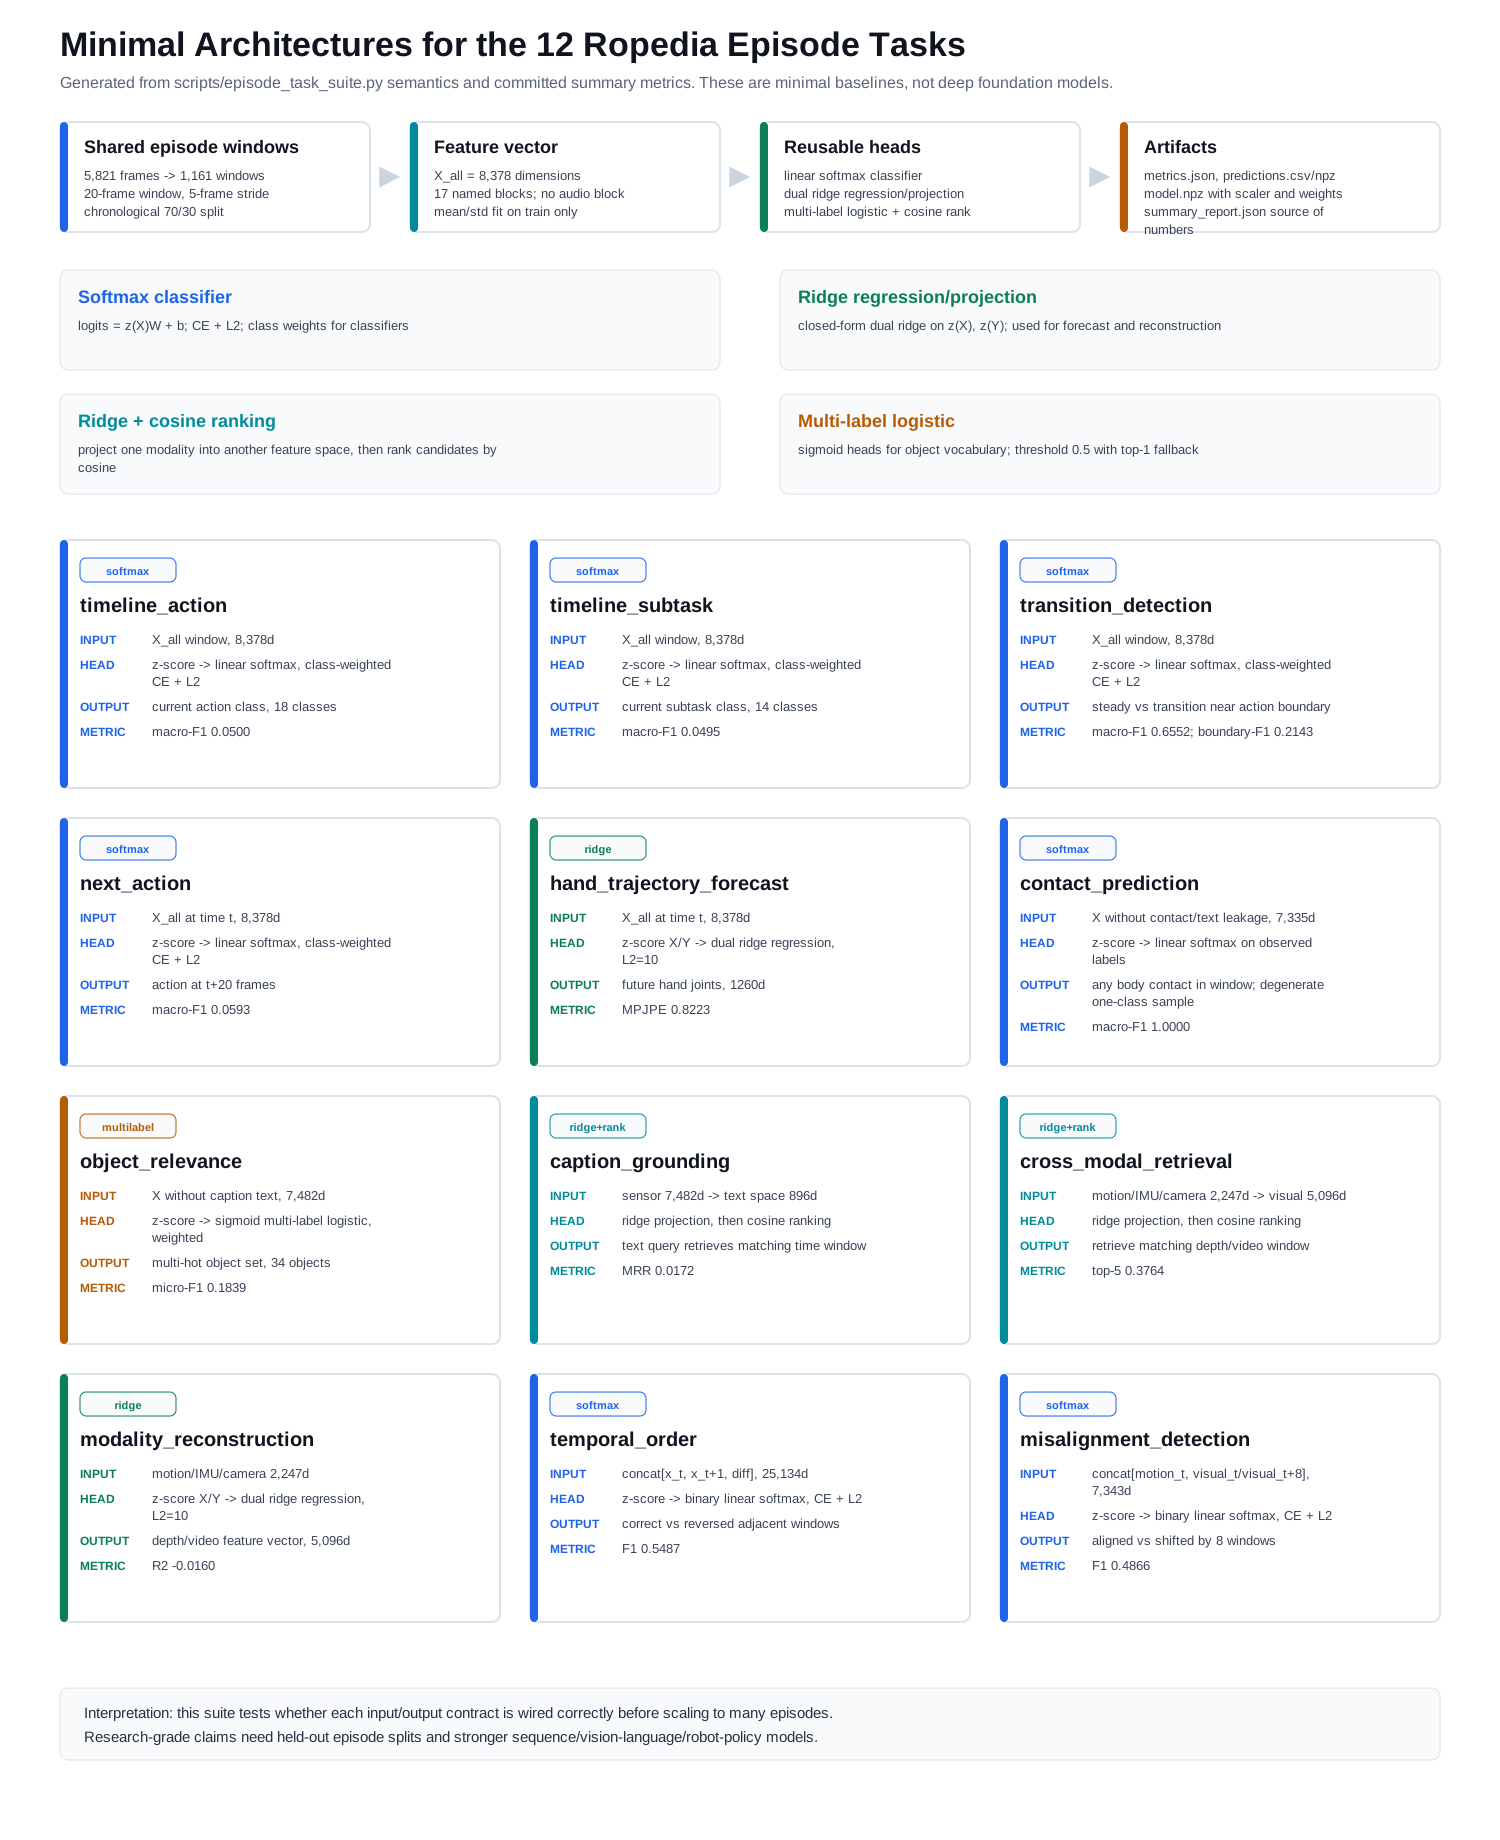
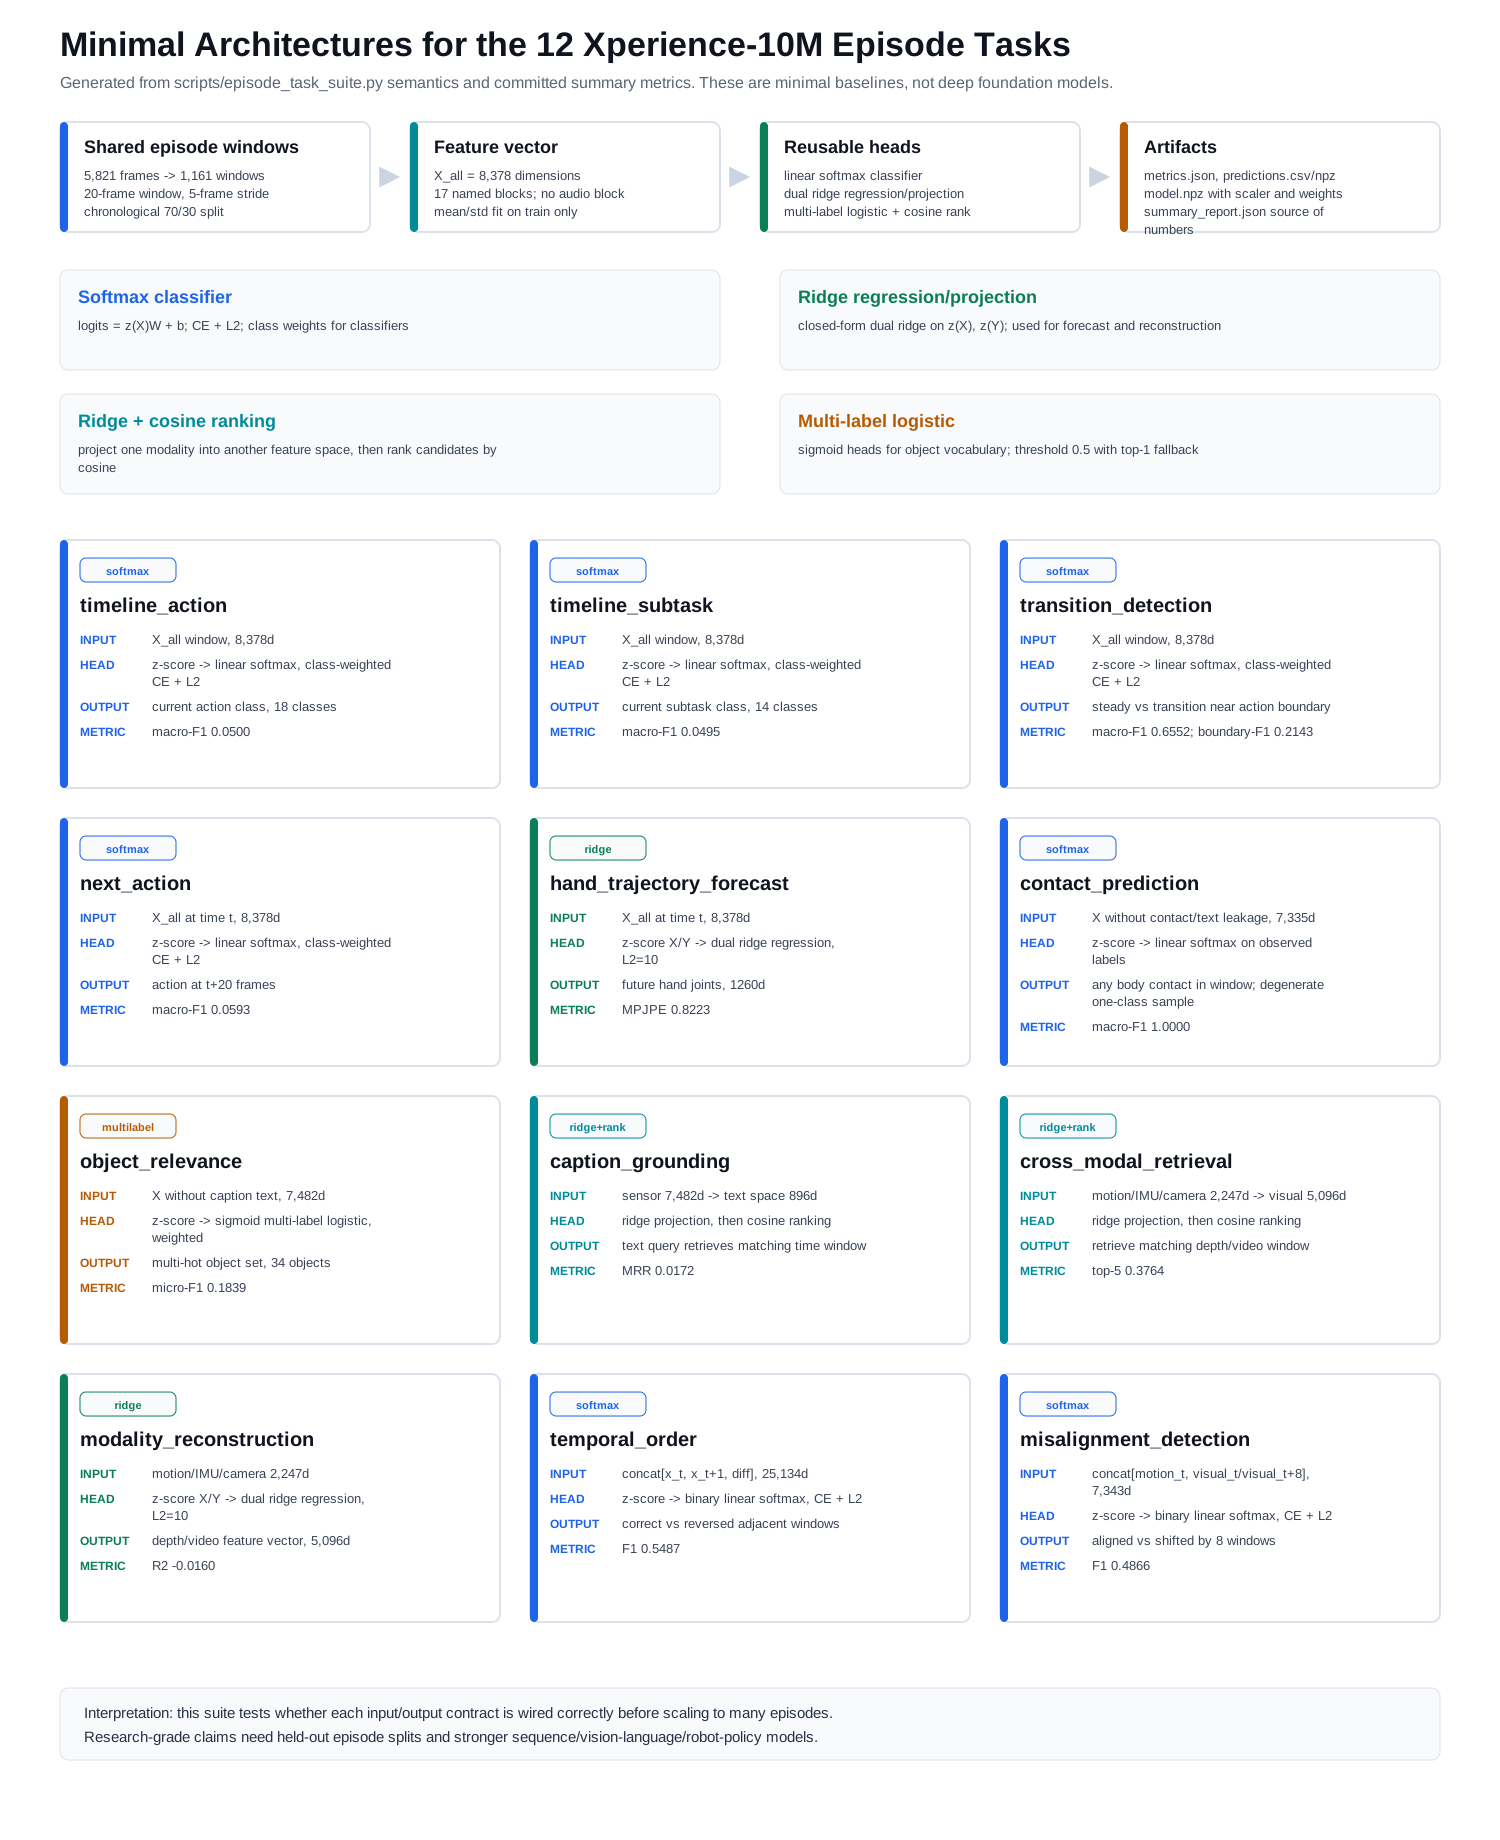
- assets/task_architectures.png +2 -2
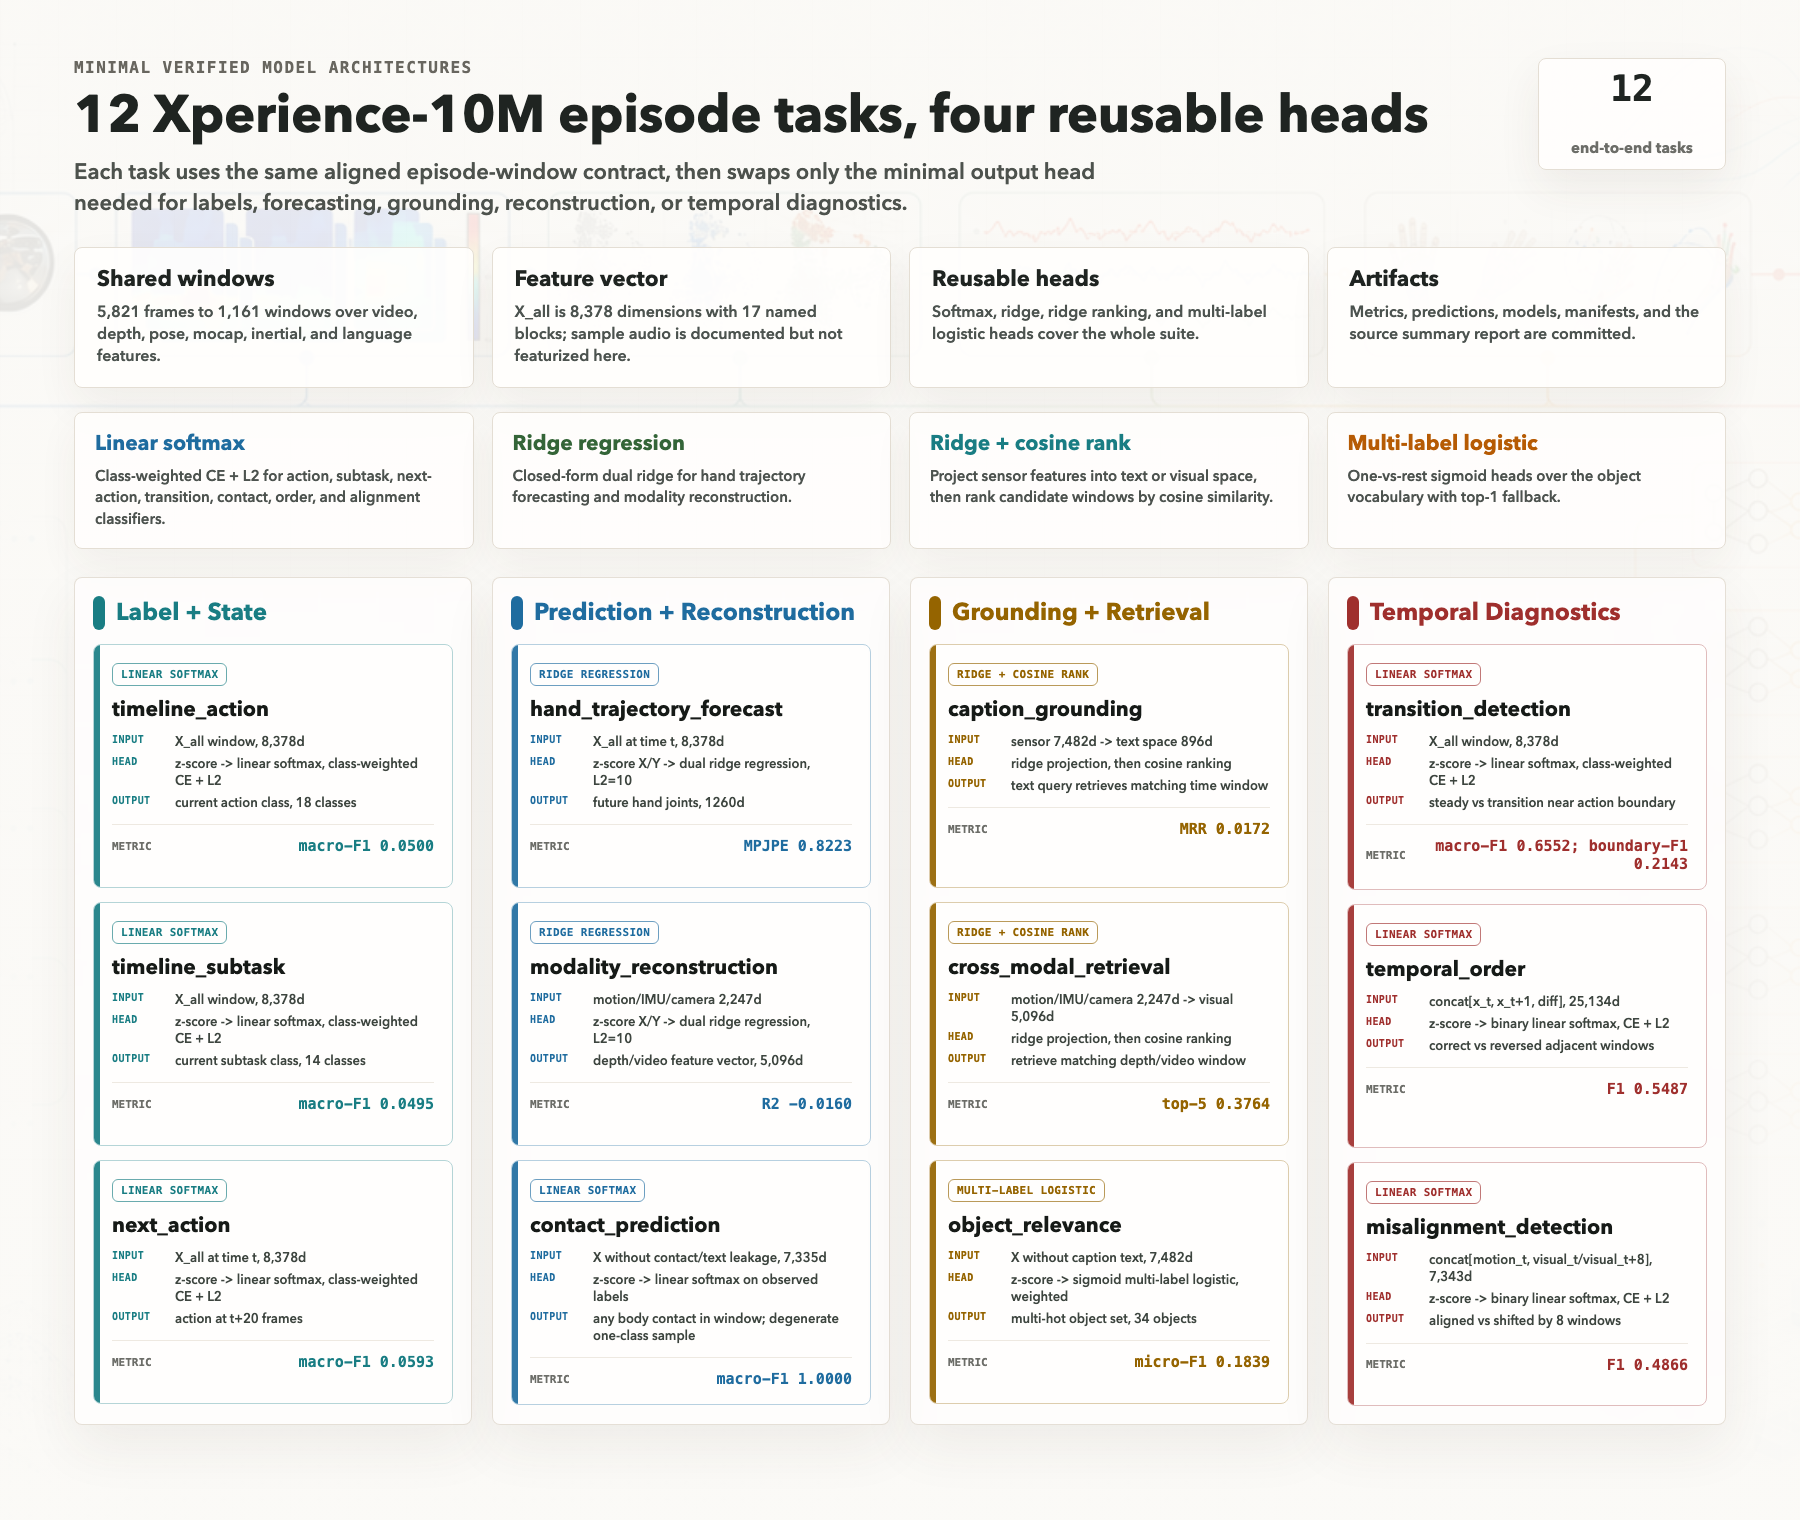
- assets/task_architectures.svg +1 -1
- assets/task_architectures_base.png +3 -0
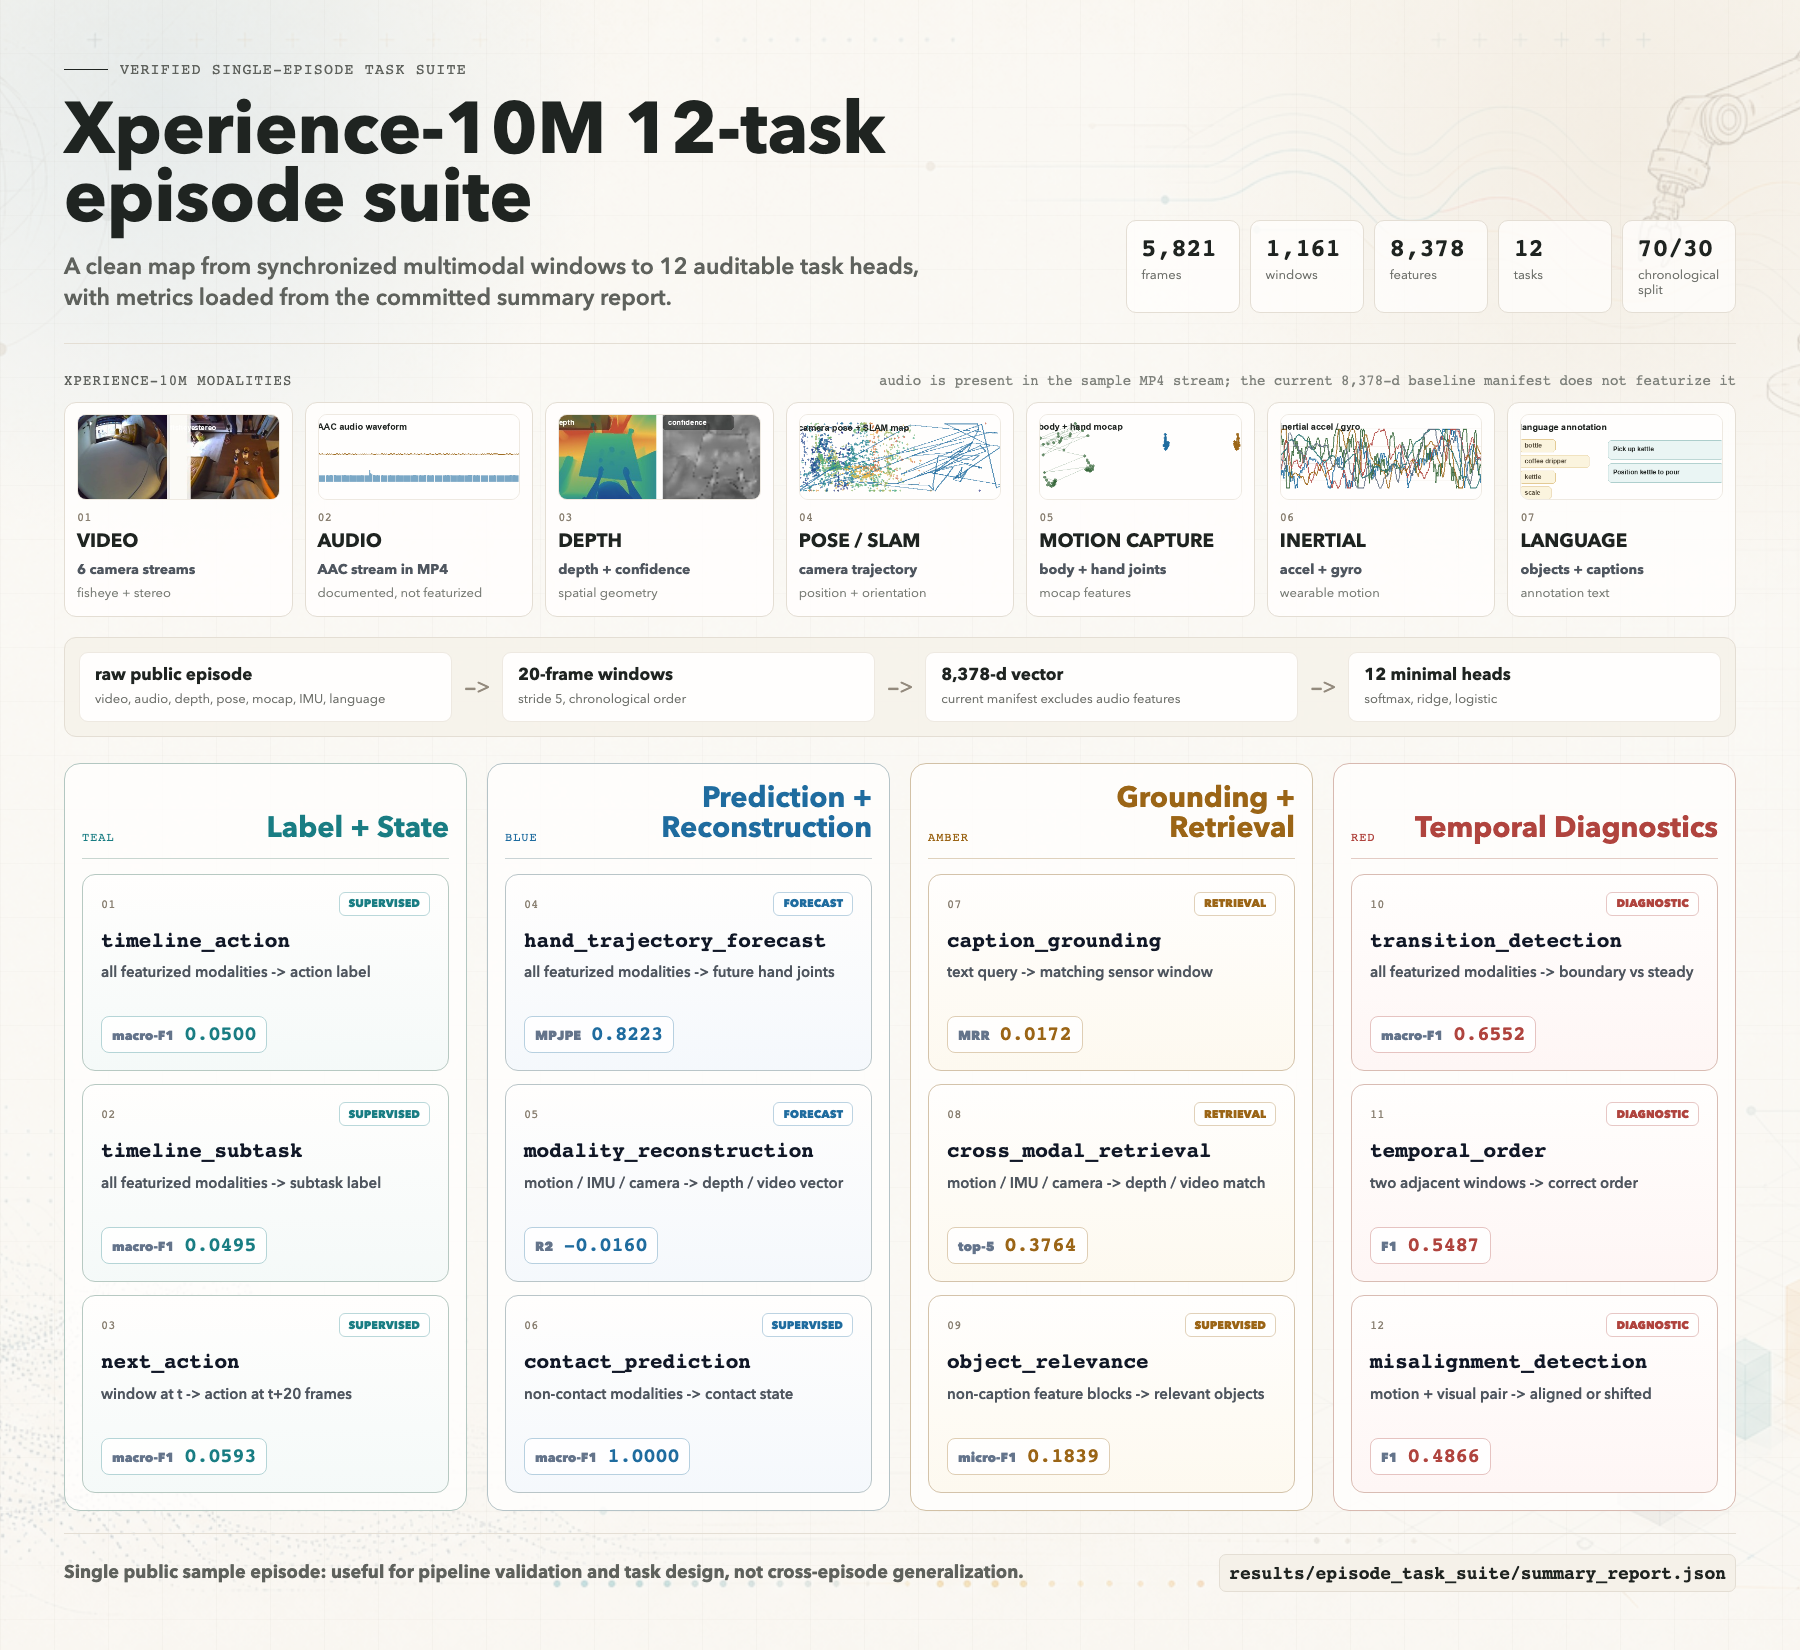
- assets/task_suite_infographic.png +2 -2
- assets/task_suite_infographic_base.png +3 -0
- docs/assets/pipeline_diagram.png +2 -2
- docs/assets/pipeline_diagram.svg +1 -1
- docs/assets/task_architectures.png +2 -2
- docs/assets/task_architectures.svg +1 -1
- docs/assets/task_suite_infographic.png +2 -2
- docs/index.html +15 -15
- notes/episode_task_suite.md +1 -1
- notes/min_action_model.md +1 -1
- notes/reproducibility_audit.md +1 -1
- results/omni_exploration/modelscope_manifest.json +66 -0
- results/omni_exploration/qwen3_adapter_smoke/RUN_REPORT.md +15 -0
- results/omni_exploration/qwen3_adapter_smoke/adapter_blocks.json +68 -0
- results/omni_exploration/qwen3_adapter_smoke/available_modalities.json +34 -0
- results/omni_exploration/qwen3_adapter_smoke/confusion_matrix.csv +19 -0
- results/omni_exploration/qwen3_adapter_smoke/feature_manifest.json +68 -0
- results/omni_exploration/qwen3_adapter_smoke/metrics.json +30 -0
- results/omni_exploration/qwen3_adapter_smoke/per_class_metrics.csv +19 -0
- results/omni_exploration/qwen3_adapter_smoke/predictions.csv +19 -0
- scripts/episode_task_suite.py +2 -2
- scripts/generate_visualizations.py +3 -3
- scripts/omni/build_episode_manifest.py +101 -0
- scripts/omni/download_sample_modelscope.py +78 -0
- scripts/omni/plan_finetune_sample_budget.py +147 -0
- scripts/omni/qwen3_omni_adapter_smoke.py +493 -0
- scripts/omni/qwen3_omni_next_steps.md +20 -0
- scripts/render_overview_figures.py +2 -2
- scripts/render_task_suite_infographic.py +4 -4
- scripts/train_all_modalities_model.py +1 -1
- scripts/train_min_action_model.py +1 -1
DATA_NOTICE.md
CHANGED
|
@@ -1,6 +1,6 @@
|
|
| 1 |
# Data Notice
|
| 2 |
|
| 3 |
-
This repository does not redistribute raw
|
| 4 |
|
| 5 |
To reproduce the experiments, download the public sample from Hugging Face:
|
| 6 |
|
|
@@ -22,4 +22,4 @@ stereo_left.mp4
|
|
| 22 |
stereo_right.mp4
|
| 23 |
```
|
| 24 |
|
| 25 |
-
Use of the dataset is governed by the original
|
|
|
|
| 1 |
# Data Notice
|
| 2 |
|
| 3 |
+
This repository does not redistribute raw Xperience-10M data.
|
| 4 |
|
| 5 |
To reproduce the experiments, download the public sample from Hugging Face:
|
| 6 |
|
|
|
|
| 22 |
stereo_right.mp4
|
| 23 |
```
|
| 24 |
|
| 25 |
+
Use of the dataset is governed by the original Xperience-10M dataset terms.
|
PROJECT_README.md
CHANGED
|
@@ -1,12 +1,12 @@
|
|
| 1 |
-
#
|
| 2 |
|
| 3 |
[](https://chaoyue0307.github.io/ropedia-episode-task-suite/)
|
| 4 |
[](https://huggingface.co/spaces/cy0307/ropedia-episode-task-suite)
|
| 5 |
-
[](#scope)
|
| 7 |
|
| 8 |
-
An audit-first embodied-AI learning repo built around one public
|
| 9 |
-
Xperience-10M sample episode.
|
| 10 |
|
| 11 |
The project does one narrow thing carefully: it turns a raw multimodal episode
|
| 12 |
into:
|
|
@@ -58,7 +58,7 @@ Hugging Face Space app:
|
|
| 58 |
| Derived artifacts on Hugging Face | https://huggingface.co/datasets/cy0307/ropedia-episode-task-suite-artifacts |
|
| 59 |
| Minimal baseline models on Hugging Face | https://huggingface.co/cy0307/ropedia-minimal-task-baselines |
|
| 60 |
| Hugging Face collection | https://huggingface.co/collections/cy0307/ropedia-episode-task-suite |
|
| 61 |
-
|
|
| 62 |
| Xperience-10M release page | https://ropedia.com/blog/20260316_xperience_10m |
|
| 63 |
| Ropedia GitHub organization | https://github.com/Ropedia |
|
| 64 |
| HOMIE Toolkit | https://github.com/Ropedia/HOMIE-toolkit |
|
|
@@ -66,7 +66,7 @@ Hugging Face Space app:
|
|
| 66 |
| Xperience-10M sample on Hugging Face | https://huggingface.co/datasets/ropedia-ai/xperience-10m-sample |
|
| 67 |
| Ropedia Hugging Face organization | https://huggingface.co/ropedia-ai |
|
| 68 |
|
| 69 |
-
](https://chaoyue0307.github.io/ropedia-episode-task-suite/)
|
| 4 |
[](https://huggingface.co/spaces/cy0307/ropedia-episode-task-suite)
|
| 5 |
+
[](https://github.com/Ropedia)
|
| 6 |
[](#scope)
|
| 7 |
|
| 8 |
+
An audit-first embodied-AI learning repo built around one public
|
| 9 |
+
Xperience-10M sample episode released by Ropedia.
|
| 10 |
|
| 11 |
The project does one narrow thing carefully: it turns a raw multimodal episode
|
| 12 |
into:
|
|
|
|
| 58 |
| Derived artifacts on Hugging Face | https://huggingface.co/datasets/cy0307/ropedia-episode-task-suite-artifacts |
|
| 59 |
| Minimal baseline models on Hugging Face | https://huggingface.co/cy0307/ropedia-minimal-task-baselines |
|
| 60 |
| Hugging Face collection | https://huggingface.co/collections/cy0307/ropedia-episode-task-suite |
|
| 61 |
+
| Xperience-10M dataset website | https://ropedia.com/dataset |
|
| 62 |
| Xperience-10M release page | https://ropedia.com/blog/20260316_xperience_10m |
|
| 63 |
| Ropedia GitHub organization | https://github.com/Ropedia |
|
| 64 |
| HOMIE Toolkit | https://github.com/Ropedia/HOMIE-toolkit |
|
|
|
|
| 66 |
| Xperience-10M sample on Hugging Face | https://huggingface.co/datasets/ropedia-ai/xperience-10m-sample |
|
| 67 |
| Ropedia Hugging Face organization | https://huggingface.co/ropedia-ai |
|
| 68 |
|
| 69 |
+

|
| 70 |
|
| 71 |
The infographic uses a ChatGPT-image-generated text-free research background and
|
| 72 |
low-resolution modality thumbnails extracted from the public sample episode. The
|
|
|
|
| 76 |
so the published PNG is a presentation graphic with verified labels and metrics,
|
| 77 |
not a hallucinated metric sheet.
|
| 78 |
|
| 79 |
+

|
| 80 |
|
| 81 |
+

|
| 82 |
|
| 83 |
The pipeline and architecture figures use the same pattern: ChatGPT-image
|
| 84 |
provides text-free visual backgrounds, while
|
|
|
|
| 102 |
generate_visualizations.py # refreshes SVG charts + summary JSON
|
| 103 |
render_task_suite_infographic.py # renders the ChatGPT-image-backed PNG
|
| 104 |
render_overview_figures.py # renders polished pipeline/architecture PNGs
|
| 105 |
+
omni/
|
| 106 |
+
download_sample_modelscope.py # mainland-China friendly sample download
|
| 107 |
+
build_episode_manifest.py # metadata-only multi-episode scanner
|
| 108 |
+
plan_finetune_sample_budget.py # H20 storage/sample-count planner
|
| 109 |
+
qwen3_omni_adapter_smoke.py # real-data Qwen3-Omni adapter smoke test
|
| 110 |
|
| 111 |
results/
|
| 112 |
min_action_model/ # motion-only action baseline artifacts
|
|
|
|
| 114 |
min_all_modalities_action_model/ # current all-feature action artifacts
|
| 115 |
min_all_modalities_subtask_model/ # current all-feature subtask artifacts
|
| 116 |
episode_task_suite/ # 12-task suite metrics and predictions
|
| 117 |
+
omni_exploration/ # H20/ModelScope smoke-test artifacts
|
| 118 |
|
| 119 |
docs/
|
| 120 |
index.html # GitHub Pages dashboard
|
|
|
|
| 130 |
episode_task_suite.md
|
| 131 |
```
|
| 132 |
|
| 133 |
+
Raw Xperience-10M data is **not** committed. Download it from the official
|
| 134 |
+
Ropedia distribution and follow the dataset terms.
|
| 135 |
|
| 136 |
## Data Expected
|
| 137 |
|
| 138 |
+
The scripts expect a workspace with the Ropedia HOMIE toolkit and the
|
| 139 |
+
Xperience-10M sample episode:
|
| 140 |
|
| 141 |
```text
|
| 142 |
<workspace>/
|
|
|
|
| 182 |
--local-dir data/sample/xperience-10m-sample
|
| 183 |
```
|
| 184 |
|
| 185 |
+
On mainland-China servers, use ModelScope instead:
|
| 186 |
+
|
| 187 |
+
```bash
|
| 188 |
+
python scripts/omni/download_sample_modelscope.py \
|
| 189 |
+
--output-dir data/sample/xperience-10m-sample \
|
| 190 |
+
--mode minimal
|
| 191 |
+
```
|
| 192 |
+
|
| 193 |
+
`--mode minimal` downloads `annotation.hdf5`, `README.md`, and
|
| 194 |
+
`fisheye_cam0.mp4`. Use `--mode all-training` to add all six MP4 streams while
|
| 195 |
+
still skipping `visualization.rrd`.
|
| 196 |
+
|
| 197 |
Clone and run this repo:
|
| 198 |
|
| 199 |
```bash
|
|
|
|
| 209 |
python scripts/train_all_modalities_model.py --workspace /path/to/workspace
|
| 210 |
```
|
| 211 |
|
| 212 |
+
## Xperience-10M Fine-Tuning Exploration On H20
|
| 213 |
+
|
| 214 |
+
This repo now includes a concrete first step toward a Qwen3-Omni fine-tuning
|
| 215 |
+
pipeline over Xperience-10M. The important separation is:
|
| 216 |
+
|
| 217 |
+
- direct Qwen3-Omni inputs: RGB/fisheye video, embedded MP4 audio, and language
|
| 218 |
+
prompts,
|
| 219 |
+
- adapter-required Xperience-10M sensor inputs: depth, pose/SLAM, hand/body
|
| 220 |
+
mocap, contacts, and IMU.
|
| 221 |
+
|
| 222 |
+
The H20 smoke test validates the adapter-required side first, using real
|
| 223 |
+
Xperience-10M sample data from ModelScope and real action labels. It does not
|
| 224 |
+
download or fine-tune the 30B Qwen3-Omni weights yet.
|
| 225 |
+
|
| 226 |
+
```bash
|
| 227 |
+
python scripts/omni/build_episode_manifest.py \
|
| 228 |
+
--data-root /home/cy/Ropedia/modelscope_data \
|
| 229 |
+
--output outputs/omni_exploration/modelscope_manifest.json
|
| 230 |
+
|
| 231 |
+
python scripts/omni/qwen3_omni_adapter_smoke.py \
|
| 232 |
+
--workspace /home/cy/Ropedia/ropedia-episode-task-suite \
|
| 233 |
+
--episode-root /home/cy/Ropedia/modelscope_data/xperience-10m-sample \
|
| 234 |
+
--target action \
|
| 235 |
+
--window-frames 20 \
|
| 236 |
+
--stride-frames 100 \
|
| 237 |
+
--max-windows-per-episode 64 \
|
| 238 |
+
--epochs 2 \
|
| 239 |
+
--skip-video-features
|
| 240 |
+
```
|
| 241 |
+
|
| 242 |
+
Verified H20 run:
|
| 243 |
+
|
| 244 |
+
| Item | Value |
|
| 245 |
+
| --- | ---: |
|
| 246 |
+
| Server | 8 x NVIDIA H20, 96GB each |
|
| 247 |
+
| Free storage checked | about 1.5TB under `/home/cy` |
|
| 248 |
+
| Data source | ModelScope `ropedia-ai/xperience-10m-sample` |
|
| 249 |
+
| Downloaded minimal data | 1.93GB `annotation.hdf5` + 85.7MB `fisheye_cam0.mp4` |
|
| 250 |
+
| Smoke windows | 59 |
|
| 251 |
+
| Split | single-episode chronological |
|
| 252 |
+
| Feature dim | 4,262 |
|
| 253 |
+
| Adapter soft-token blocks | 11 |
|
| 254 |
+
| Qwen3-Omni weights loaded | no |
|
| 255 |
+
| Result | 0.0000 macro-F1, expected for this single-episode chronological smoke split |
|
| 256 |
+
|
| 257 |
+
The zero score is not treated as a model claim. It is a useful signal that this
|
| 258 |
+
split is not leaking labels across time: the train segment does not cover every
|
| 259 |
+
action that appears in the held-out segment. The next real step is to add more
|
| 260 |
+
episodes and split by held-out episode.
|
| 261 |
+
|
| 262 |
+
### Sample Count Decision
|
| 263 |
+
|
| 264 |
+
The local Mac sample is only one episode. For H20 fine-tuning, decide sample
|
| 265 |
+
count by storage and evaluation design, not by the local folder. The current H20
|
| 266 |
+
has about 1.5TB free under `/home/cy`; after reserving space for model weights,
|
| 267 |
+
checkpoints, caches, and logs, a realistic first budget is:
|
| 268 |
+
|
| 269 |
+
| Phase | Episodes/samples | Approx windows at stride 5 | Purpose |
|
| 270 |
+
| --- | ---: | ---: | --- |
|
| 271 |
+
| Smoke | 1-3 | 1k-3k | Verify loaders, token alignment, and task heads |
|
| 272 |
+
| Pilot | 16-32 | 18k-37k | First held-out-episode evaluation |
|
| 273 |
+
| Useful LoRA run | 64-128 | 74k-149k | Train sensor adapters plus selected Qwen3-Omni LoRA |
|
| 274 |
+
| Storage-heavy run | 256+ | 297k+ | Only after download layout and checkpoint size are stable |
|
| 275 |
+
|
| 276 |
+
For the next run, use **32 episodes** if ModelScope exposes enough files
|
| 277 |
+
cleanly. If download structure is simple and disk remains above 800GB free,
|
| 278 |
+
scale to **64 or 128 episodes**. Do not aim for 10k samples first; at the
|
| 279 |
+
observed sample-equivalent size, that would become a data-management project
|
| 280 |
+
before it is a modeling experiment.
|
| 281 |
+
|
| 282 |
+
Use the budget helper before downloading:
|
| 283 |
+
|
| 284 |
+
```bash
|
| 285 |
+
python scripts/omni/plan_finetune_sample_budget.py \
|
| 286 |
+
--storage-root /home/cy \
|
| 287 |
+
--target-free-after-download-gb 800 \
|
| 288 |
+
--all-training-per-episode-gb 2.4 \
|
| 289 |
+
--full-preview-per-episode-gb 5.1
|
| 290 |
+
```
|
| 291 |
+
|
| 292 |
Refresh charts and the website data bundle:
|
| 293 |
|
| 294 |
```bash
|
|
|
|
| 396 |
|
| 397 |
## Data Notice
|
| 398 |
|
| 399 |
+
Xperience-10M data belongs to its original authors and is subject to the
|
| 400 |
+
official Ropedia dataset license and access terms. This repo contains code and
|
| 401 |
derived experiment artifacts only; it does not redistribute the raw videos or
|
| 402 |
raw annotation dataset.
|
README.md
CHANGED
|
@@ -1,6 +1,6 @@
|
|
| 1 |
---
|
| 2 |
license: other
|
| 3 |
-
pretty_name:
|
| 4 |
tags:
|
| 5 |
- robotics
|
| 6 |
- embodied-ai
|
|
@@ -20,11 +20,11 @@ size_categories:
|
|
| 20 |
- n<1K
|
| 21 |
---
|
| 22 |
|
| 23 |
-
#
|
| 24 |
|
| 25 |
-
This dataset repo contains the derived evidence layer for the public
|
| 26 |
|
| 27 |
-
It does **not** contain raw
|
| 28 |
|
| 29 |
## Why This Repo Exists
|
| 30 |
|
|
@@ -54,7 +54,7 @@ https://huggingface.co/cy0307/ropedia-minimal-task-baselines
|
|
| 54 |
| Minimal model repo | https://huggingface.co/cy0307/ropedia-minimal-task-baselines |
|
| 55 |
| GitHub repo | https://github.com/ChaoYue0307/ropedia-episode-task-suite |
|
| 56 |
| GitHub Pages dashboard | https://chaoyue0307.github.io/ropedia-episode-task-suite/ |
|
| 57 |
-
|
|
| 58 |
| Xperience-10M release page | https://ropedia.com/blog/20260316_xperience_10m |
|
| 59 |
| Ropedia GitHub organization | https://github.com/Ropedia |
|
| 60 |
| HOMIE Toolkit | https://github.com/Ropedia/HOMIE-toolkit |
|
|
|
|
| 1 |
---
|
| 2 |
license: other
|
| 3 |
+
pretty_name: Xperience-10M Episode Task Suite Artifacts
|
| 4 |
tags:
|
| 5 |
- robotics
|
| 6 |
- embodied-ai
|
|
|
|
| 20 |
- n<1K
|
| 21 |
---
|
| 22 |
|
| 23 |
+
# Xperience-10M Episode Task Suite Artifacts
|
| 24 |
|
| 25 |
+
This dataset repo contains the derived evidence layer for the public Xperience-10M sample episode released by Ropedia: metrics, predictions, manifests, charts, diagrams, notes, and reproduction scripts.
|
| 26 |
|
| 27 |
+
It does **not** contain raw Xperience-10M videos or raw `annotation.hdf5`. Download raw data only from the official Ropedia / Hugging Face sources and follow their terms.
|
| 28 |
|
| 29 |
## Why This Repo Exists
|
| 30 |
|
|
|
|
| 54 |
| Minimal model repo | https://huggingface.co/cy0307/ropedia-minimal-task-baselines |
|
| 55 |
| GitHub repo | https://github.com/ChaoYue0307/ropedia-episode-task-suite |
|
| 56 |
| GitHub Pages dashboard | https://chaoyue0307.github.io/ropedia-episode-task-suite/ |
|
| 57 |
+
| Xperience-10M website | https://ropedia.com/dataset |
|
| 58 |
| Xperience-10M release page | https://ropedia.com/blog/20260316_xperience_10m |
|
| 59 |
| Ropedia GitHub organization | https://github.com/Ropedia |
|
| 60 |
| HOMIE Toolkit | https://github.com/Ropedia/HOMIE-toolkit |
|
assets/charts/cross_modal_retrieval.svg
ADDED
|
assets/charts/episode_task_scores.svg
ADDED

|
assets/charts/feature_blocks.svg
ADDED
|
assets/charts/model_macro_f1.svg
ADDED
|
assets/pipeline_diagram.png
CHANGED

|
Git LFS Details
|

|
Git LFS Details
|
assets/pipeline_diagram.svg
CHANGED

|
|
assets/pipeline_diagram_base.png
ADDED
|
Git LFS Details
|
assets/task_architectures.png
CHANGED

|
Git LFS Details
|
|
Git LFS Details
|
assets/task_architectures.svg
CHANGED
|
|
assets/task_architectures_base.png
ADDED
|
Git LFS Details
|
assets/task_suite_infographic.png
CHANGED

|
Git LFS Details
|
|
Git LFS Details
|
assets/task_suite_infographic_base.png
ADDED
|
Git LFS Details
|
docs/assets/pipeline_diagram.png
CHANGED

|
Git LFS Details
|
|
Git LFS Details
|
docs/assets/pipeline_diagram.svg
CHANGED

|
|
docs/assets/task_architectures.png
CHANGED
|
Git LFS Details
|
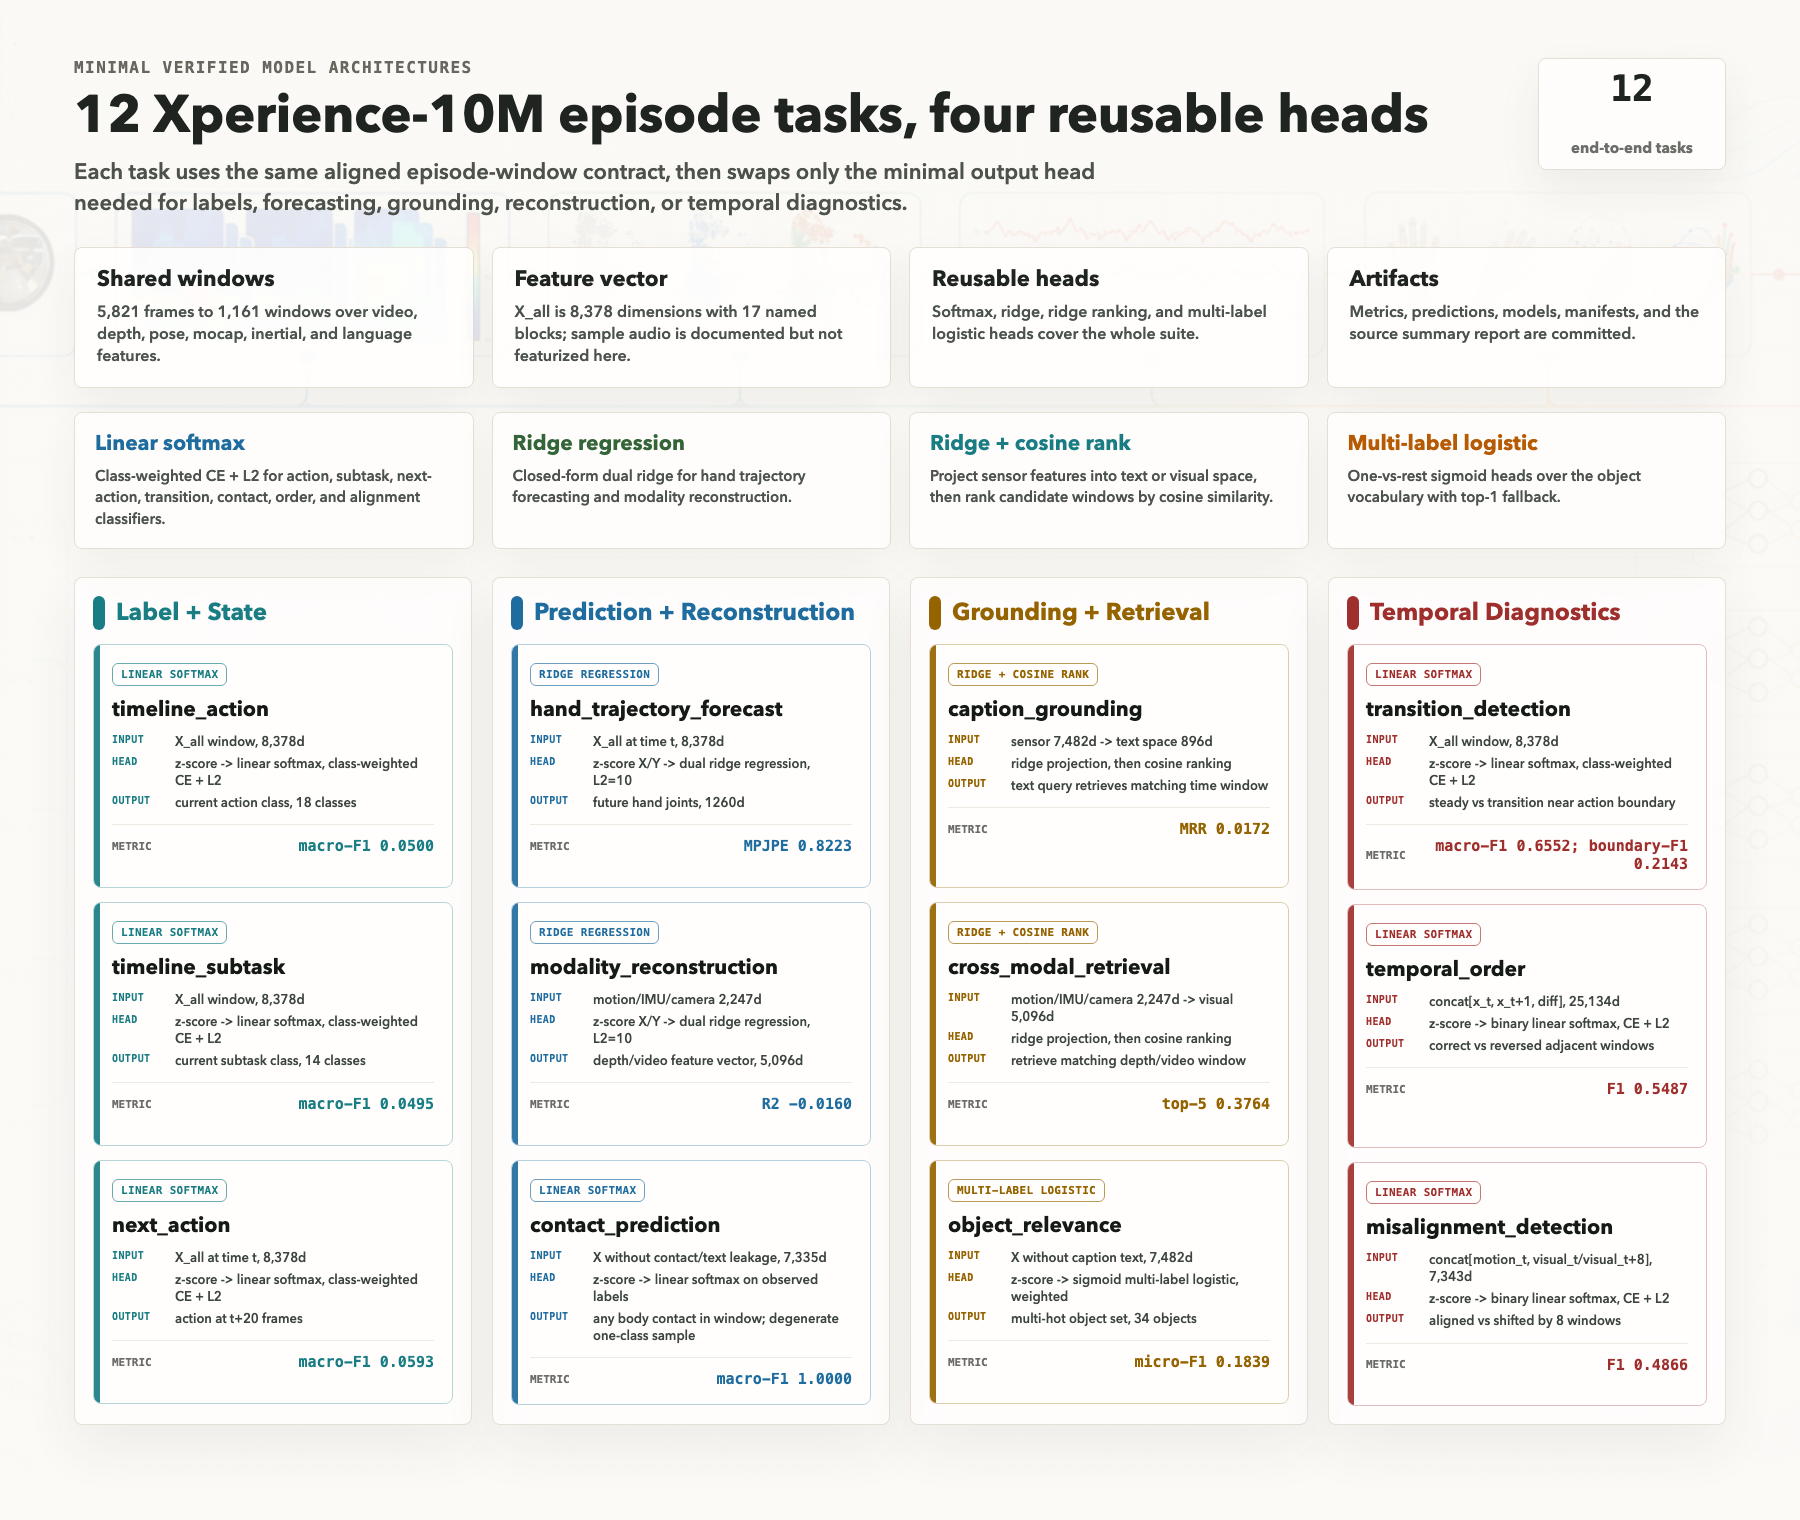
|
Git LFS Details
|
docs/assets/task_architectures.svg
CHANGED
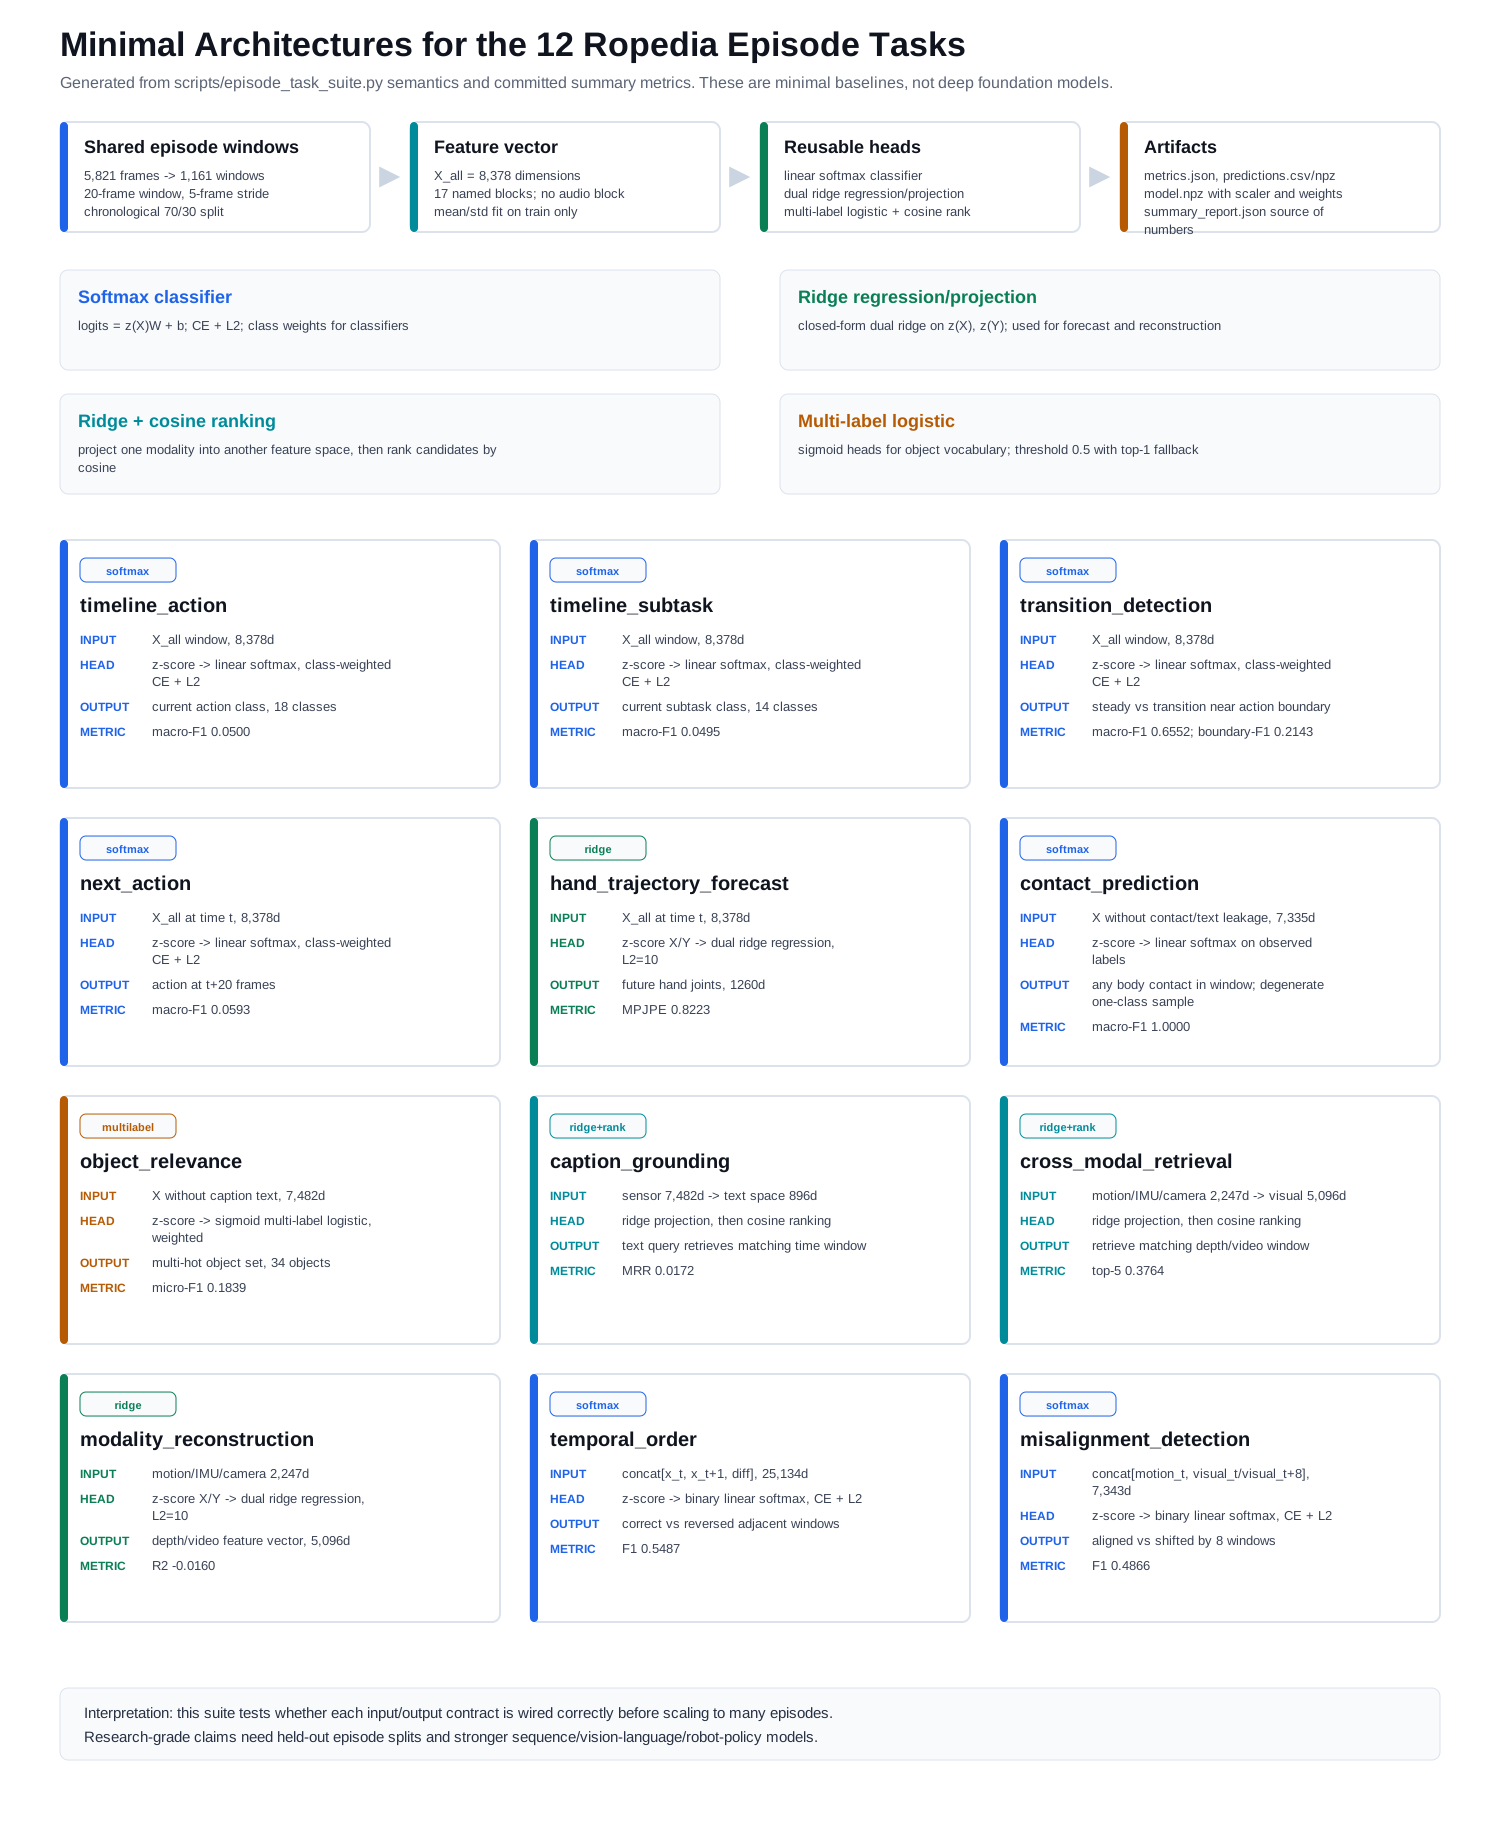
|
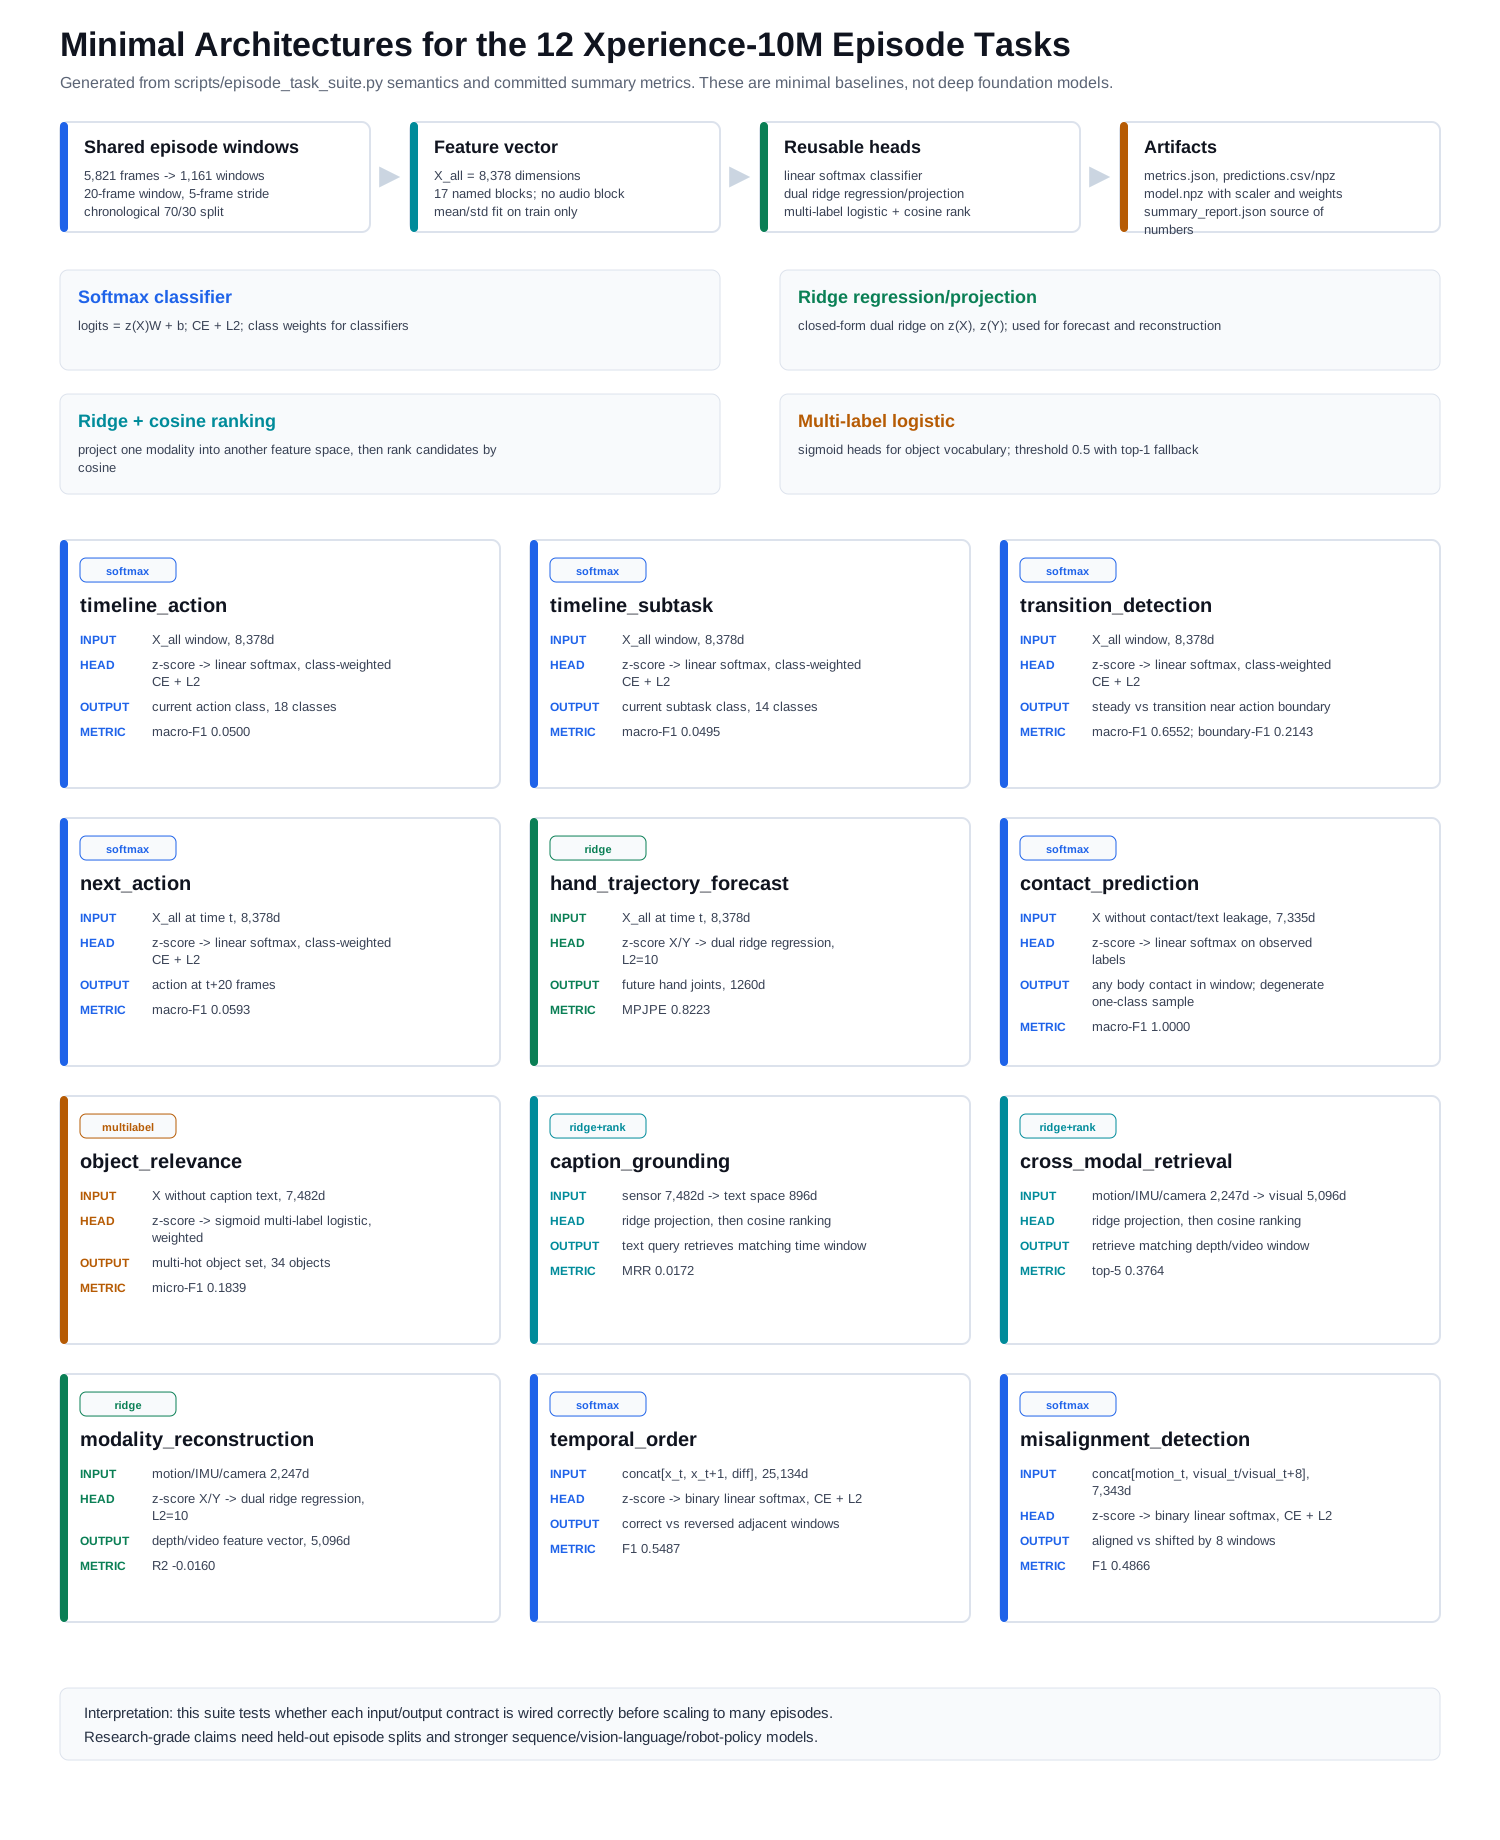
|
docs/assets/task_suite_infographic.png
CHANGED

|
Git LFS Details
|
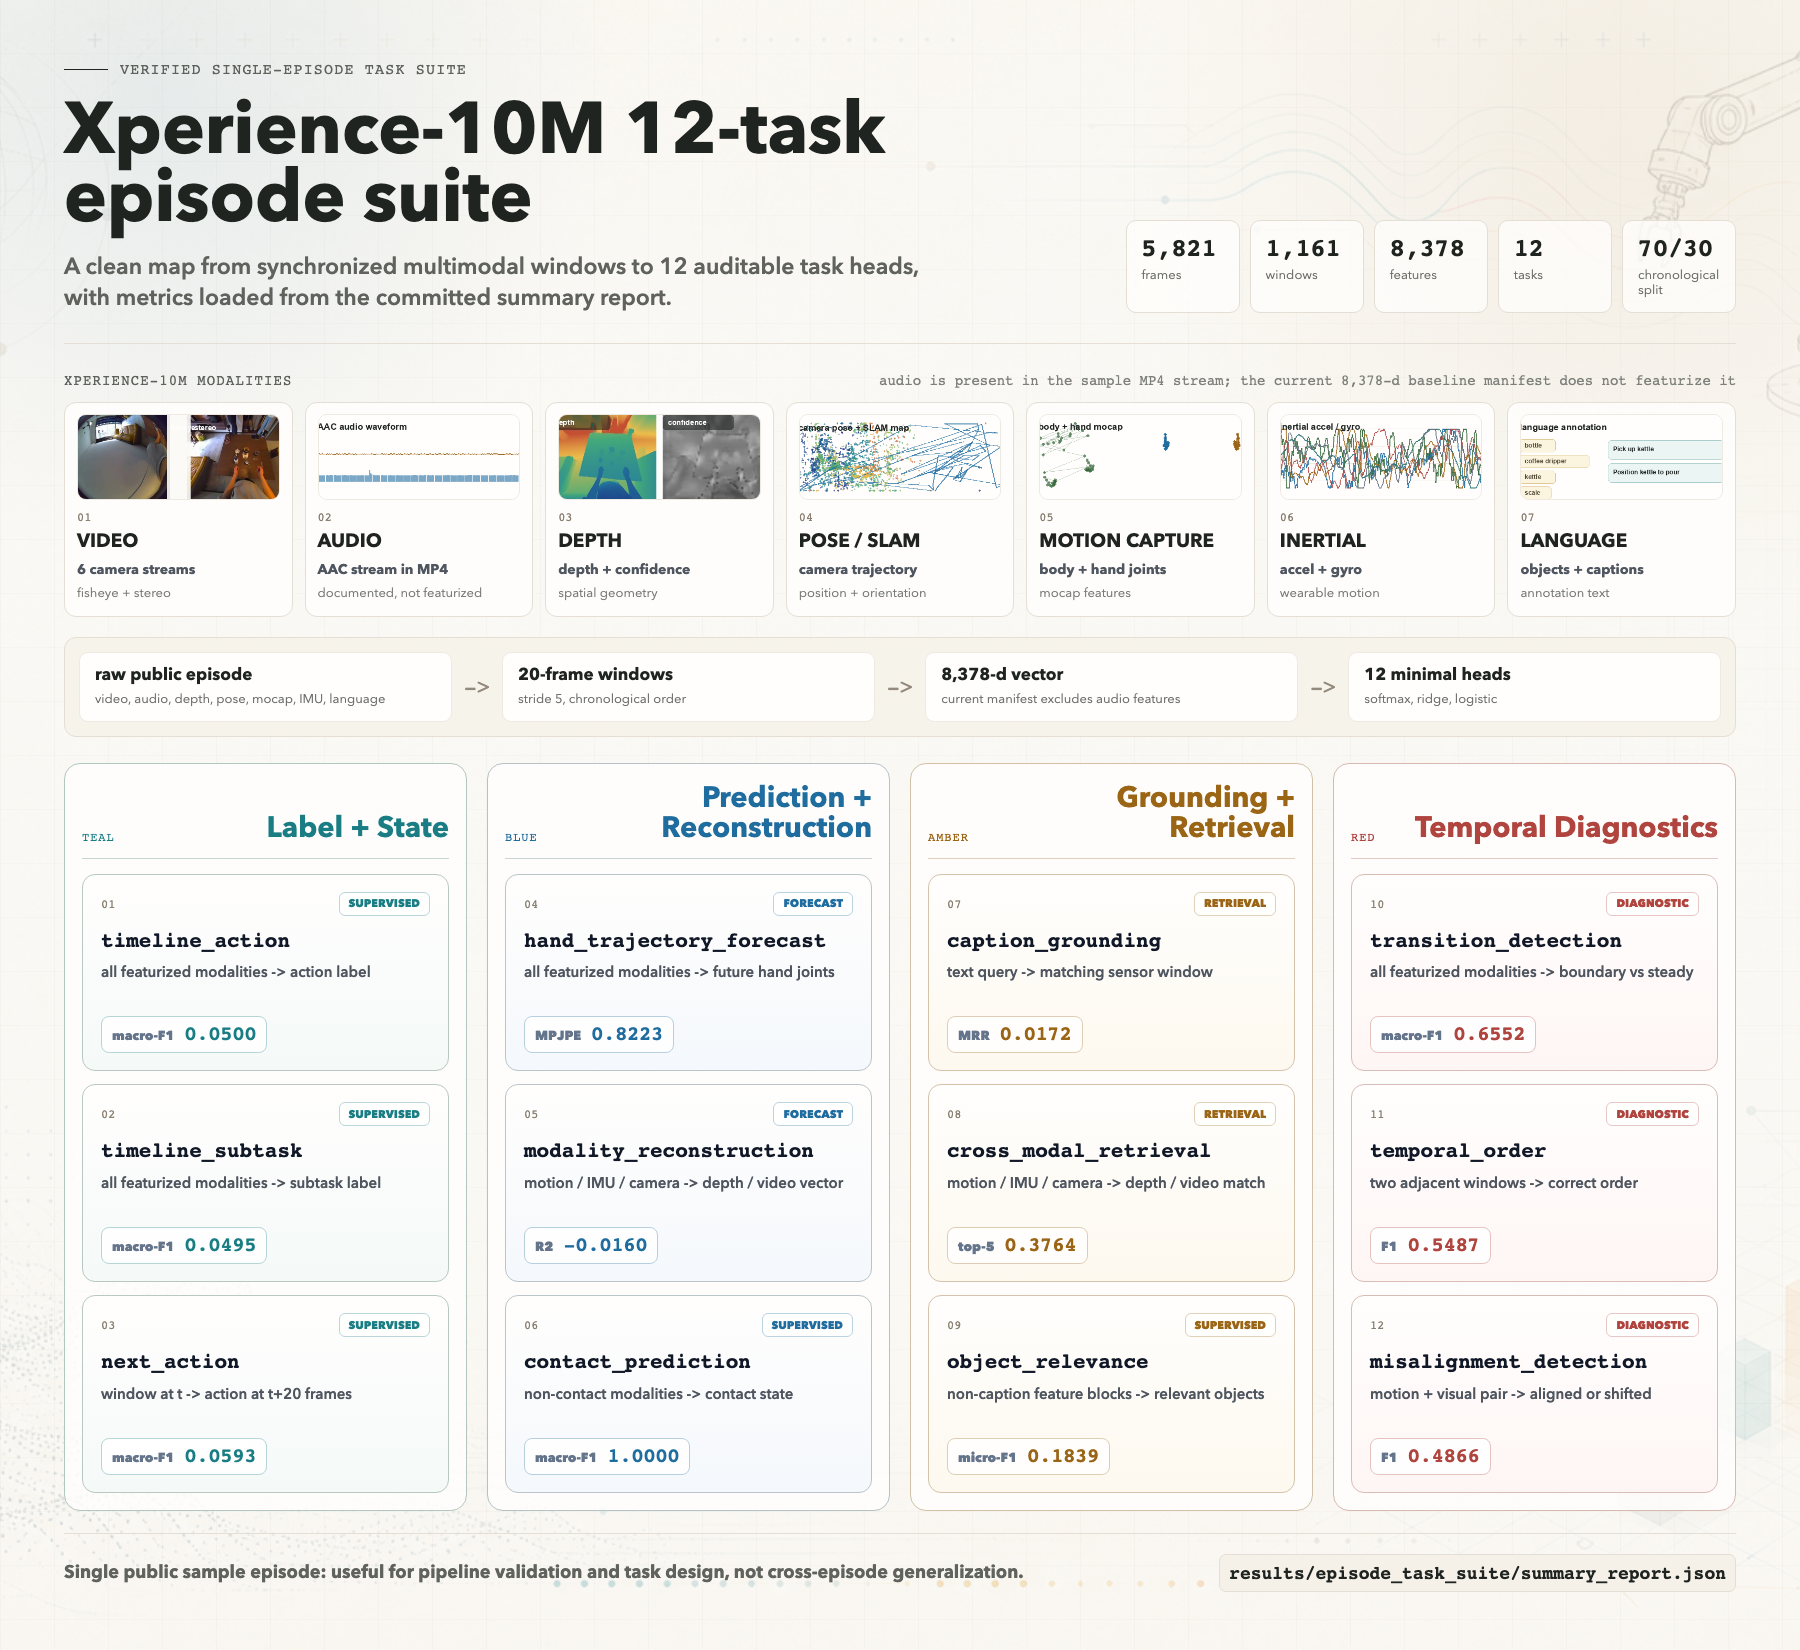
|
Git LFS Details
|
docs/index.html
CHANGED
|
@@ -3,9 +3,9 @@
|
|
| 3 |
<head>
|
| 4 |
<meta charset="utf-8">
|
| 5 |
<meta name="viewport" content="width=device-width, initial-scale=1">
|
| 6 |
-
<title>
|
| 7 |
-
<meta name="description" content="A transparent multimodal task suite for one public
|
| 8 |
-
<meta property="og:title" content="
|
| 9 |
<meta property="og:description" content="One public embodied-AI episode, converted into reproducible multimodal tasks, baselines, metrics, and diagrams.">
|
| 10 |
<meta property="og:image" content="assets/task_suite_infographic.png?v=bb2beb9">
|
| 11 |
<style>
|
|
@@ -487,9 +487,9 @@
|
|
| 487 |
<a class="skip-link" href="#main">Skip to content</a>
|
| 488 |
<nav class="site-nav">
|
| 489 |
<div class="wrap nav-inner">
|
| 490 |
-
<a class="brand" href="#top" aria-label="
|
| 491 |
-
<span class="mark" aria-hidden="true">
|
| 492 |
-
<span>
|
| 493 |
</a>
|
| 494 |
<div class="nav-links" aria-label="Page navigation">
|
| 495 |
<a href="#suite">Suite</a>
|
|
@@ -509,9 +509,9 @@
|
|
| 509 |
<div class="wrap hero-inner">
|
| 510 |
<div>
|
| 511 |
<div class="eyebrow">single public episode / verified artifacts</div>
|
| 512 |
-
<h1>One
|
| 513 |
<p class="hero-copy">
|
| 514 |
-
A compact research lab for the public
|
| 515 |
video, audio, depth, pose, motion capture, inertial sensing, and language annotation,
|
| 516 |
with an explicit record of which modalities enter the current minimal feature vector.
|
| 517 |
</p>
|
|
@@ -547,10 +547,10 @@
|
|
| 547 |
<section id="suite">
|
| 548 |
<div class="wrap">
|
| 549 |
<div class="section-head">
|
| 550 |
-
<h2>
|
| 551 |
<p>The top-level map shows the Xperience-10M sample modalities and the verified 12-task results. Audio is present in the sample MP4 stream, but the current 8,378-d baseline manifest does not featurize it.</p>
|
| 552 |
</div>
|
| 553 |
-
<img class="task-suite-image" src="assets/task_suite_infographic.png?v=
|
| 554 |
</div>
|
| 555 |
</section>
|
| 556 |
|
|
@@ -560,11 +560,11 @@
|
|
| 560 |
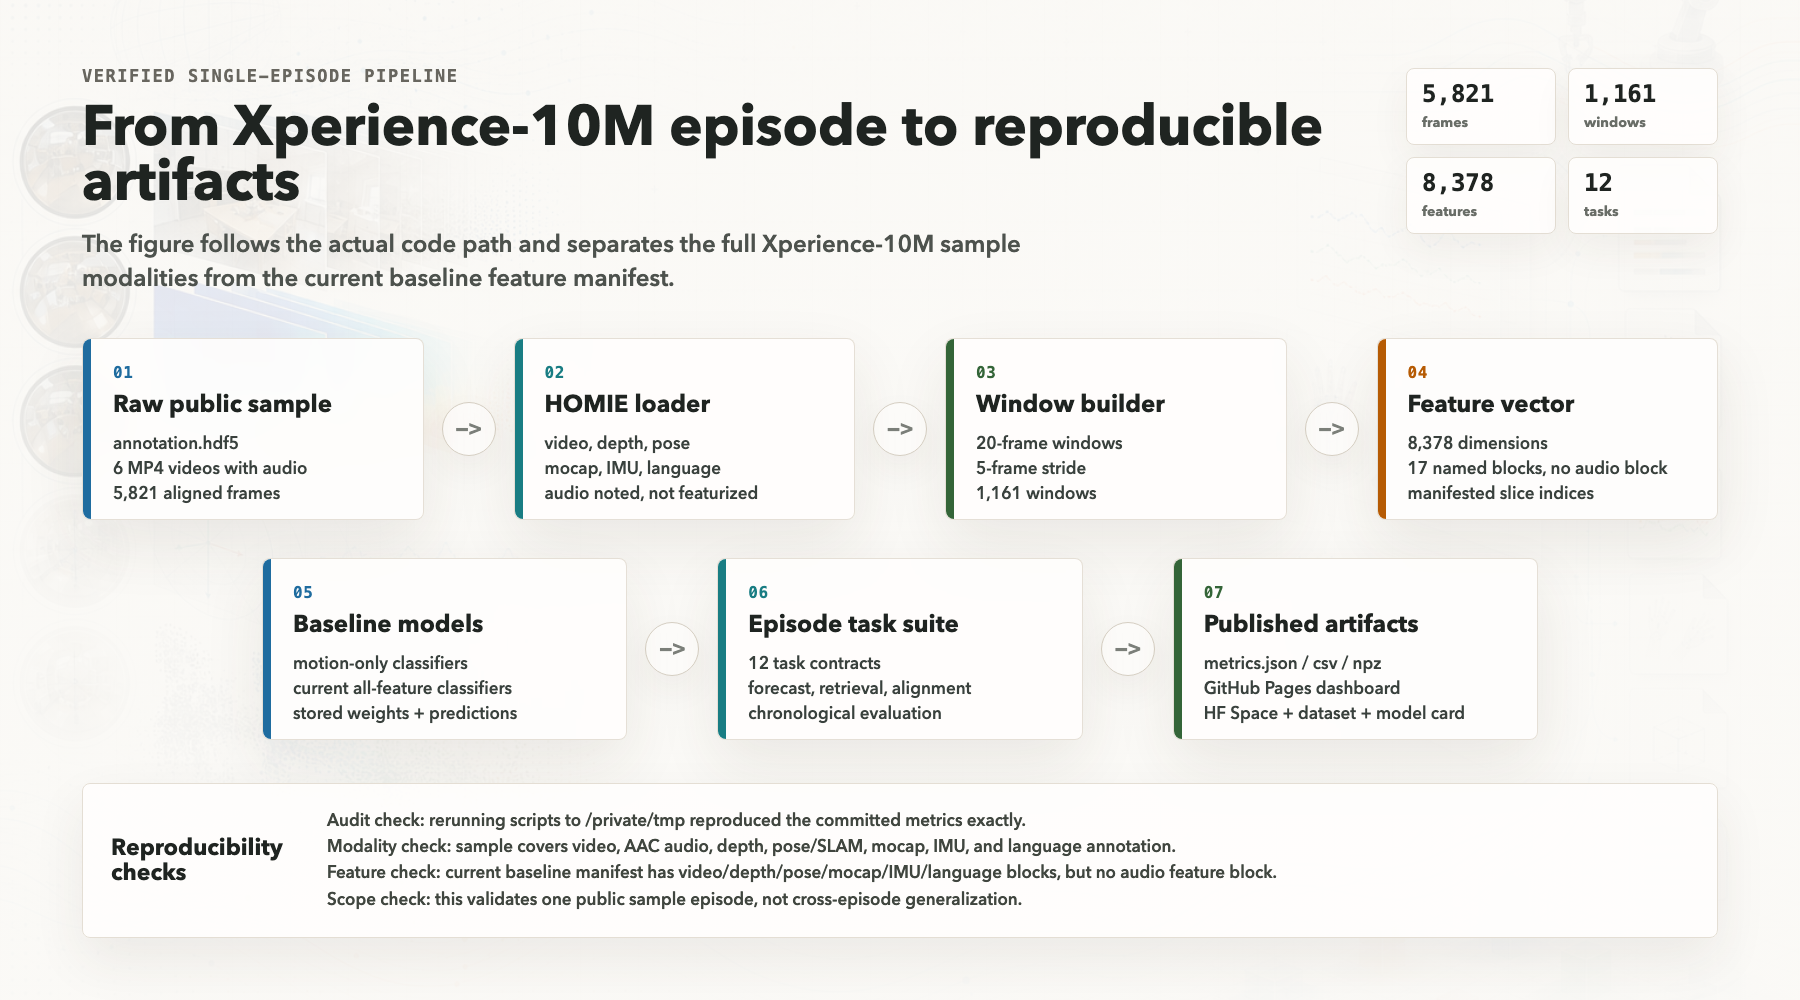
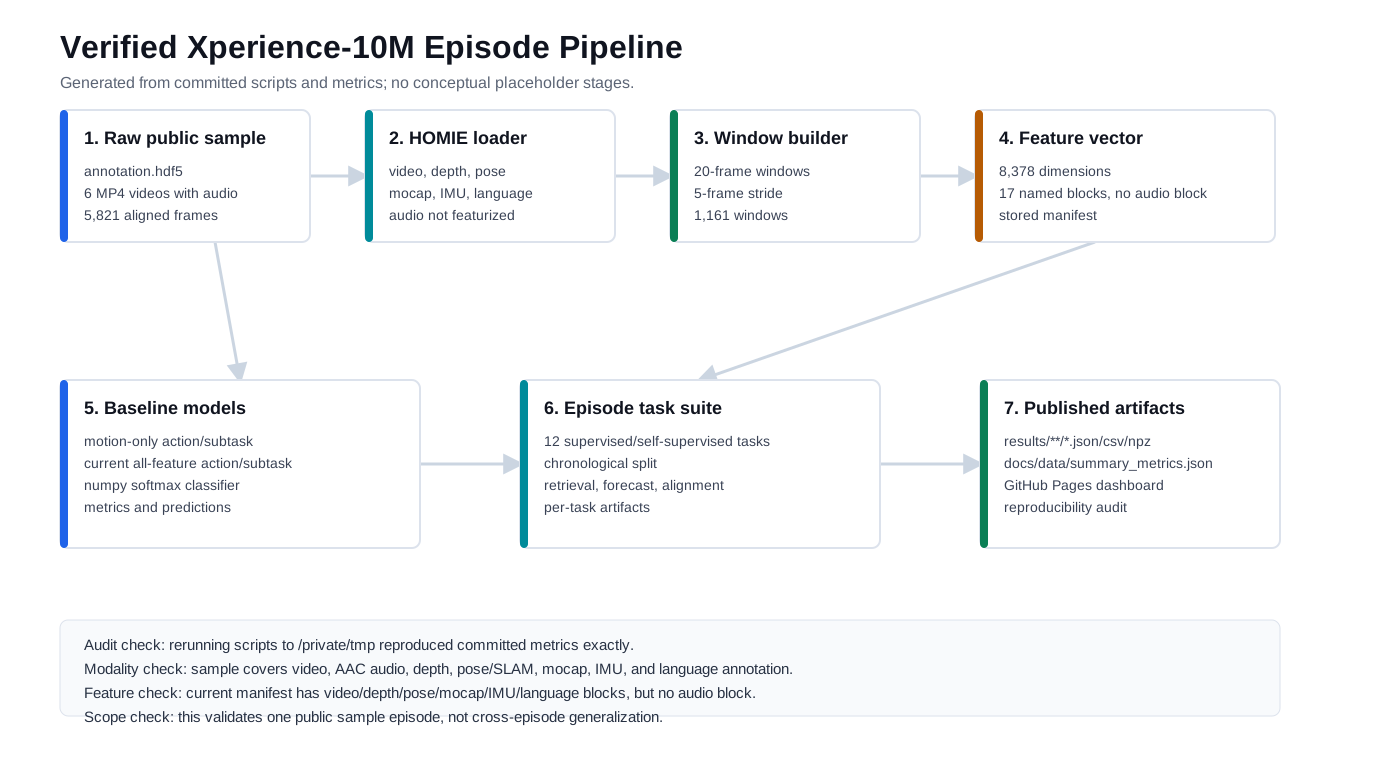
<h2>From raw episode to checked artifacts.</h2>
|
| 561 |
<p>Every script works from one data contract: aligned multimodal windows, explicit labels, cached feature extraction, and a manifest that makes omitted modalities visible.</p>
|
| 562 |
</div>
|
| 563 |
-
<img class="pipeline-image" src="assets/pipeline_diagram.png?v=
|
| 564 |
<div class="callout-row">
|
| 565 |
<div class="callout">
|
| 566 |
<h3>What this project proves</h3>
|
| 567 |
-
<p>It proves the full engineering loop: reading
|
| 568 |
</div>
|
| 569 |
<div class="callout">
|
| 570 |
<h3>What it does not prove</h3>
|
|
@@ -596,7 +596,7 @@
|
|
| 596 |
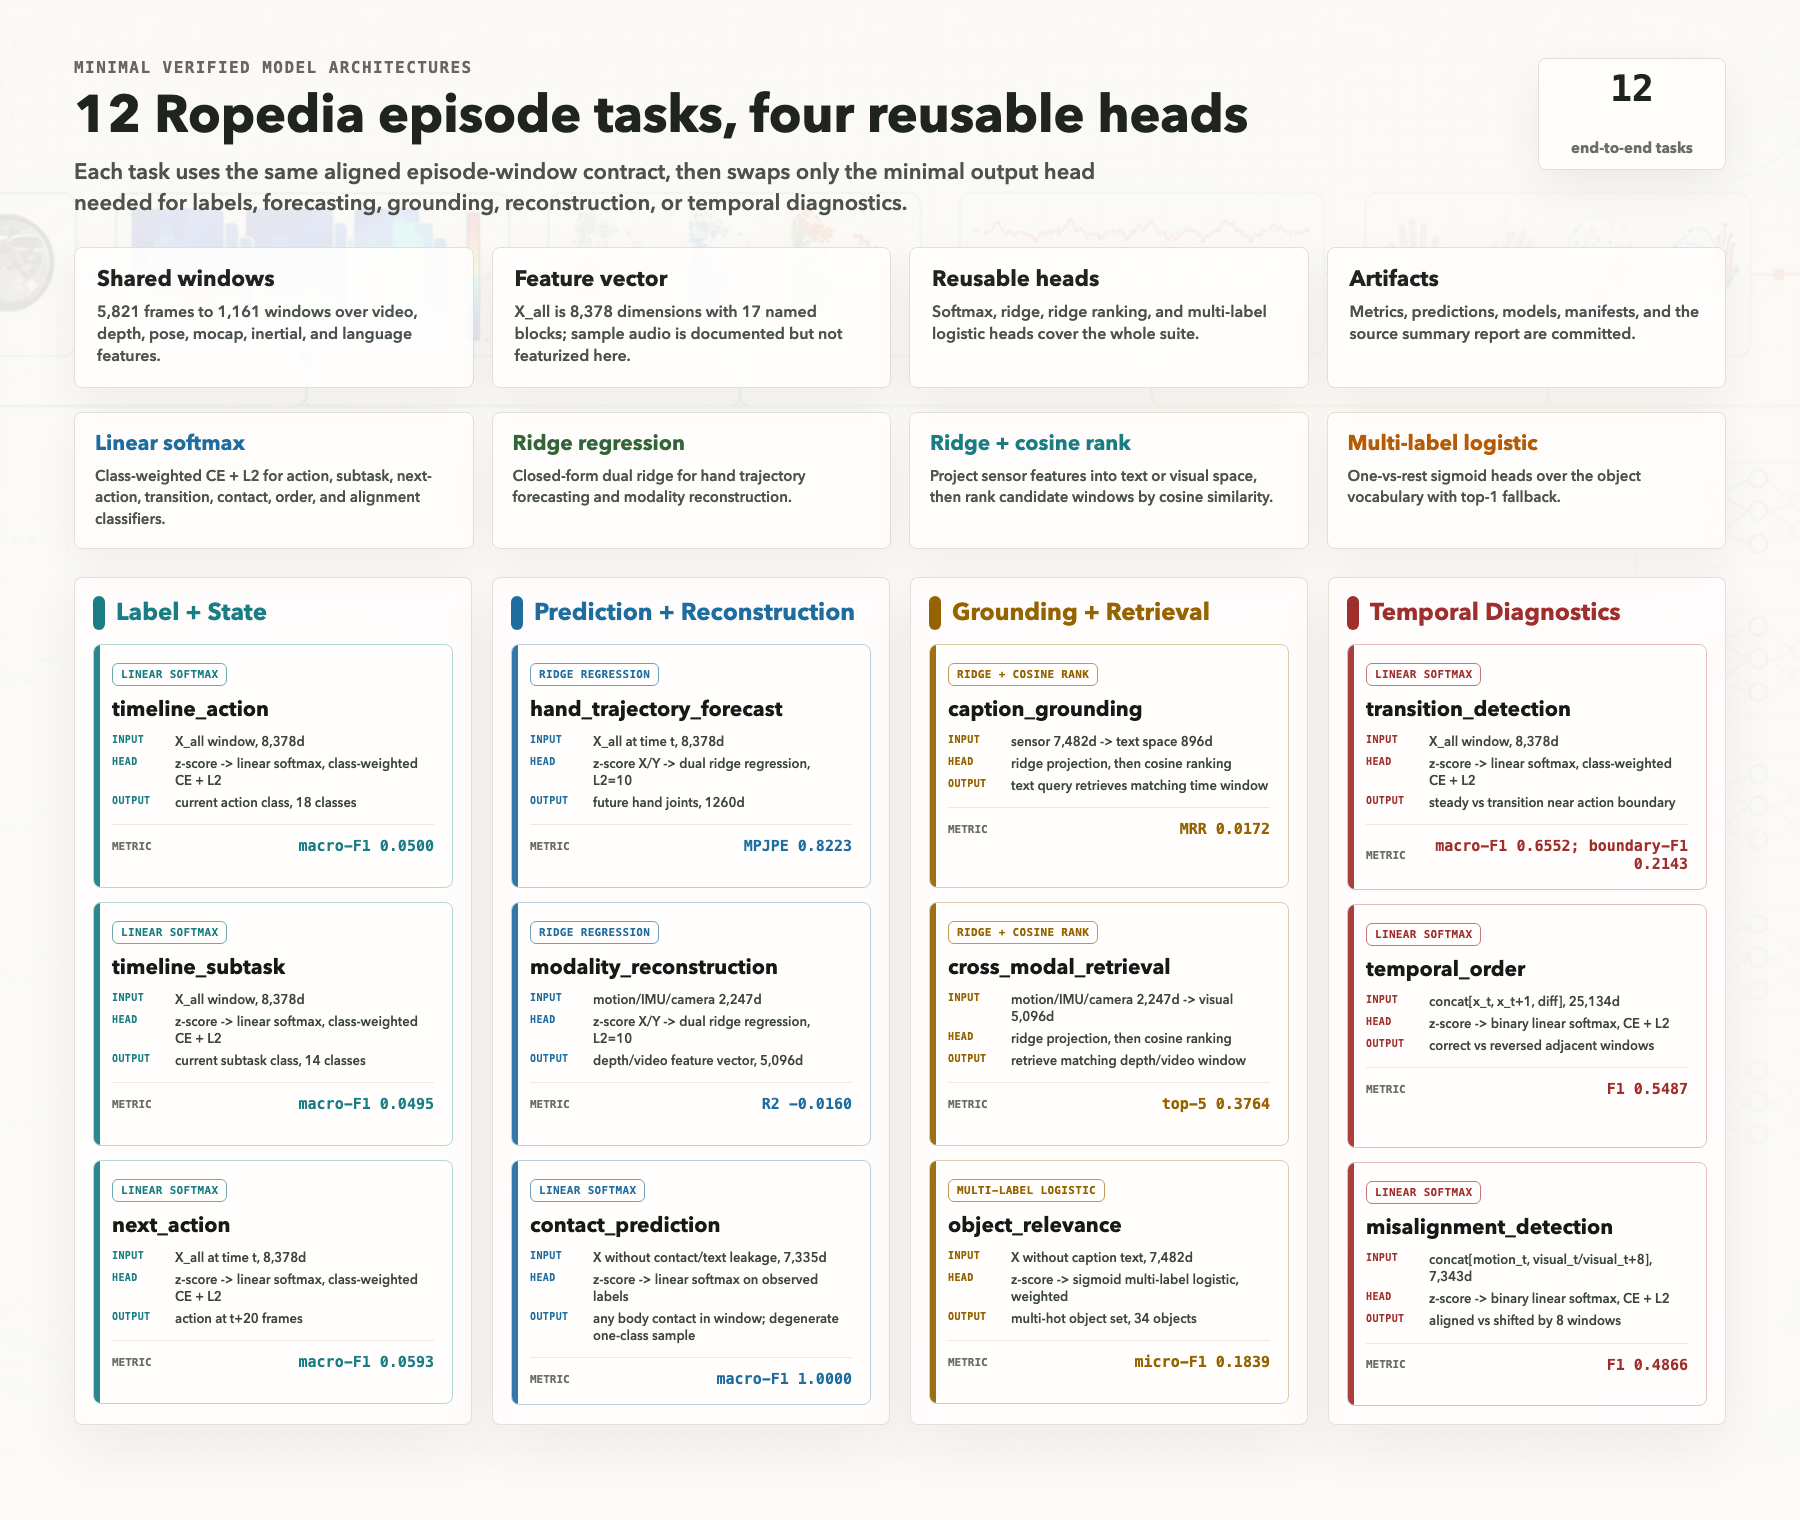
<h2>The 12 tasks share four head families.</h2>
|
| 597 |
<p>The diagram separates the shared episode-window feature pipeline from the task-specific heads, and notes that audio remains dataset context rather than a current baseline feature block.</p>
|
| 598 |
</div>
|
| 599 |
-
<img class="architecture-image" src="assets/task_architectures.png?v=
|
| 600 |
</div>
|
| 601 |
</section>
|
| 602 |
|
|
@@ -667,7 +667,7 @@
|
|
| 667 |
<article class="artifact"><h3>Windows table</h3><p>Window start/end frames and aligned action/subtask labels.</p><a href="https://github.com/ChaoYue0307/ropedia-episode-task-suite/blob/main/results/episode_task_suite/windows.csv">windows.csv</a></article>
|
| 668 |
<article class="artifact"><h3>Reproduction scripts</h3><p>Three training scripts plus the dashboard generator.</p><a href="https://github.com/ChaoYue0307/ropedia-episode-task-suite/tree/main/scripts">scripts/</a></article>
|
| 669 |
<article class="artifact"><h3>Hugging Face Space</h3><p>The same dashboard packaged as a public static Space.</p><a href="https://huggingface.co/spaces/cy0307/ropedia-episode-task-suite">cy0307/ropedia-episode-task-suite</a></article>
|
| 670 |
-
<article class="artifact"><h3>Derived HF artifacts</h3><p>Metrics, predictions, docs, and lightweight derived files without raw
|
| 671 |
<article class="artifact"><h3>HF baseline models</h3><p>Minimal NumPy softmax and ridge baseline weights with model card and architecture diagrams.</p><a href="https://huggingface.co/cy0307/ropedia-minimal-task-baselines">model repo</a></article>
|
| 672 |
<article class="artifact"><h3>HF collection</h3><p>Space, artifacts, and model baselines grouped into one public project collection.</p><a href="https://huggingface.co/collections/cy0307/ropedia-episode-task-suite">collection</a></article>
|
| 673 |
</div>
|
|
@@ -678,7 +678,7 @@
|
|
| 678 |
<div class="wrap">
|
| 679 |
<div class="section-head">
|
| 680 |
<h2>Reproduce the suite.</h2>
|
| 681 |
-
<p>Raw
|
| 682 |
</div>
|
| 683 |
<pre class="code-panel"><button type="button" data-copy="setup">Copy</button><code id="setup">git clone https://github.com/Ropedia/HOMIE-toolkit.git
|
| 684 |
python3.12 -m venv .venv
|
|
|
|
| 3 |
<head>
|
| 4 |
<meta charset="utf-8">
|
| 5 |
<meta name="viewport" content="width=device-width, initial-scale=1">
|
| 6 |
+
<title>Xperience-10M Episode Task Suite</title>
|
| 7 |
+
<meta name="description" content="A transparent multimodal task suite for one public Xperience-10M sample episode released by Ropedia.">
|
| 8 |
+
<meta property="og:title" content="Xperience-10M Episode Task Suite">
|
| 9 |
<meta property="og:description" content="One public embodied-AI episode, converted into reproducible multimodal tasks, baselines, metrics, and diagrams.">
|
| 10 |
<meta property="og:image" content="assets/task_suite_infographic.png?v=bb2beb9">
|
| 11 |
<style>
|
|
|
|
| 487 |
<a class="skip-link" href="#main">Skip to content</a>
|
| 488 |
<nav class="site-nav">
|
| 489 |
<div class="wrap nav-inner">
|
| 490 |
+
<a class="brand" href="#top" aria-label="Xperience-10M Episode Task Suite home">
|
| 491 |
+
<span class="mark" aria-hidden="true">X</span>
|
| 492 |
+
<span>Xperience-10M Episode Task Suite</span>
|
| 493 |
</a>
|
| 494 |
<div class="nav-links" aria-label="Page navigation">
|
| 495 |
<a href="#suite">Suite</a>
|
|
|
|
| 509 |
<div class="wrap hero-inner">
|
| 510 |
<div>
|
| 511 |
<div class="eyebrow">single public episode / verified artifacts</div>
|
| 512 |
+
<h1>One Xperience-10M episode, made auditable.</h1>
|
| 513 |
<p class="hero-copy">
|
| 514 |
+
A compact research lab for the public Xperience-10M sample from Ropedia:
|
| 515 |
video, audio, depth, pose, motion capture, inertial sensing, and language annotation,
|
| 516 |
with an explicit record of which modalities enter the current minimal feature vector.
|
| 517 |
</p>
|
|
|
|
| 547 |
<section id="suite">
|
| 548 |
<div class="wrap">
|
| 549 |
<div class="section-head">
|
| 550 |
+
<h2>Xperience-10M 12-task suite, first.</h2>
|
| 551 |
<p>The top-level map shows the Xperience-10M sample modalities and the verified 12-task results. Audio is present in the sample MP4 stream, but the current 8,378-d baseline manifest does not featurize it.</p>
|
| 552 |
</div>
|
| 553 |
+
<img class="task-suite-image" src="assets/task_suite_infographic.png?v=xperience10m" alt="ChatGPT-image-backed infographic showing all 12 Xperience-10M episode tasks">
|
| 554 |
</div>
|
| 555 |
</section>
|
| 556 |
|
|
|
|
| 560 |
<h2>From raw episode to checked artifacts.</h2>
|
| 561 |
<p>Every script works from one data contract: aligned multimodal windows, explicit labels, cached feature extraction, and a manifest that makes omitted modalities visible.</p>
|
| 562 |
</div>
|
| 563 |
+
<img class="pipeline-image" src="assets/pipeline_diagram.png?v=xperience10m" alt="Verified Xperience-10M multimodal pipeline diagram">
|
| 564 |
<div class="callout-row">
|
| 565 |
<div class="callout">
|
| 566 |
<h3>What this project proves</h3>
|
| 567 |
+
<p>It proves the full engineering loop: reading Xperience-10M sample data, aligning modalities, converting them into model-ready windows, defining meaningful tasks, producing metrics, and packaging every artifact for review.</p>
|
| 568 |
</div>
|
| 569 |
<div class="callout">
|
| 570 |
<h3>What it does not prove</h3>
|
|
|
|
| 596 |
<h2>The 12 tasks share four head families.</h2>
|
| 597 |
<p>The diagram separates the shared episode-window feature pipeline from the task-specific heads, and notes that audio remains dataset context rather than a current baseline feature block.</p>
|
| 598 |
</div>
|
| 599 |
+
<img class="architecture-image" src="assets/task_architectures.png?v=xperience10m" alt="Verified minimal architecture diagram for all 12 Xperience-10M episode tasks">
|
| 600 |
</div>
|
| 601 |
</section>
|
| 602 |
|
|
|
|
| 667 |
<article class="artifact"><h3>Windows table</h3><p>Window start/end frames and aligned action/subtask labels.</p><a href="https://github.com/ChaoYue0307/ropedia-episode-task-suite/blob/main/results/episode_task_suite/windows.csv">windows.csv</a></article>
|
| 668 |
<article class="artifact"><h3>Reproduction scripts</h3><p>Three training scripts plus the dashboard generator.</p><a href="https://github.com/ChaoYue0307/ropedia-episode-task-suite/tree/main/scripts">scripts/</a></article>
|
| 669 |
<article class="artifact"><h3>Hugging Face Space</h3><p>The same dashboard packaged as a public static Space.</p><a href="https://huggingface.co/spaces/cy0307/ropedia-episode-task-suite">cy0307/ropedia-episode-task-suite</a></article>
|
| 670 |
+
<article class="artifact"><h3>Derived HF artifacts</h3><p>Metrics, predictions, docs, and lightweight derived files without raw Xperience-10M video/data redistribution.</p><a href="https://huggingface.co/datasets/cy0307/ropedia-episode-task-suite-artifacts">dataset repo</a></article>
|
| 671 |
<article class="artifact"><h3>HF baseline models</h3><p>Minimal NumPy softmax and ridge baseline weights with model card and architecture diagrams.</p><a href="https://huggingface.co/cy0307/ropedia-minimal-task-baselines">model repo</a></article>
|
| 672 |
<article class="artifact"><h3>HF collection</h3><p>Space, artifacts, and model baselines grouped into one public project collection.</p><a href="https://huggingface.co/collections/cy0307/ropedia-episode-task-suite">collection</a></article>
|
| 673 |
</div>
|
|
|
|
| 678 |
<div class="wrap">
|
| 679 |
<div class="section-head">
|
| 680 |
<h2>Reproduce the suite.</h2>
|
| 681 |
+
<p>Raw Xperience-10M data is not redistributed here. Download the public sample separately, then run the same scripts.</p>
|
| 682 |
</div>
|
| 683 |
<pre class="code-panel"><button type="button" data-copy="setup">Copy</button><code id="setup">git clone https://github.com/Ropedia/HOMIE-toolkit.git
|
| 684 |
python3.12 -m venv .venv
|
notes/episode_task_suite.md
CHANGED
|
@@ -6,7 +6,7 @@ Script:
|
|
| 6 |
scripts/episode_task_suite.py
|
| 7 |
```
|
| 8 |
|
| 9 |
-
This script turns the single public
|
| 10 |
|
| 11 |
Run:
|
| 12 |
|
|
|
|
| 6 |
scripts/episode_task_suite.py
|
| 7 |
```
|
| 8 |
|
| 9 |
+
This script turns the single public Xperience-10M sample episode into many end-to-end tasks. It is designed for learning, debugging, and task design. It is **not** a generalization benchmark because the data is still one episode.
|
| 10 |
|
| 11 |
Run:
|
| 12 |
|
notes/min_action_model.md
CHANGED
|
@@ -1,6 +1,6 @@
|
|
| 1 |
# Minimal Action Model
|
| 2 |
|
| 3 |
-
This is the first modeling baseline for the
|
| 4 |
|
| 5 |
The script is:
|
| 6 |
|
|
|
|
| 1 |
# Minimal Action Model
|
| 2 |
|
| 3 |
+
This is the first modeling baseline for the public Xperience-10M sample released by Ropedia.
|
| 4 |
|
| 5 |
The script is:
|
| 6 |
|
notes/reproducibility_audit.md
CHANGED
|
@@ -2,7 +2,7 @@
|
|
| 2 |
|
| 3 |
Audit date: 2026-05-30 Asia/Singapore.
|
| 4 |
|
| 5 |
-
Purpose: verify that the committed
|
| 6 |
real outputs from the scripts, not placeholder or fabricated metrics.
|
| 7 |
|
| 8 |
## Raw Inputs Checked
|
|
|
|
| 2 |
|
| 3 |
Audit date: 2026-05-30 Asia/Singapore.
|
| 4 |
|
| 5 |
+
Purpose: verify that the committed Xperience-10M Episode Task Suite artifacts are
|
| 6 |
real outputs from the scripts, not placeholder or fabricated metrics.
|
| 7 |
|
| 8 |
## Raw Inputs Checked
|
results/omni_exploration/modelscope_manifest.json
ADDED
|
@@ -0,0 +1,66 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"summary": {
|
| 3 |
+
"num_episodes": 1,
|
| 4 |
+
"total_bytes": 2021338279,
|
| 5 |
+
"train_minimal_bytes": 2021338279,
|
| 6 |
+
"notes": [
|
| 7 |
+
"train_minimal_bytes excludes visualization.rrd because model training does not need it.",
|
| 8 |
+
"This file is metadata-only; it does not copy or download raw data."
|
| 9 |
+
]
|
| 10 |
+
},
|
| 11 |
+
"episodes": [
|
| 12 |
+
{
|
| 13 |
+
"episode_id": "xperience-10m-sample",
|
| 14 |
+
"path": "/home/cy/Ropedia/modelscope_data/xperience-10m-sample",
|
| 15 |
+
"annotation": "/home/cy/Ropedia/modelscope_data/xperience-10m-sample/annotation.hdf5",
|
| 16 |
+
"files": [
|
| 17 |
+
{
|
| 18 |
+
"name": "annotation.hdf5",
|
| 19 |
+
"bytes": 1931496028,
|
| 20 |
+
"exists": true
|
| 21 |
+
},
|
| 22 |
+
{
|
| 23 |
+
"name": "fisheye_cam0.mp4",
|
| 24 |
+
"bytes": 89842251,
|
| 25 |
+
"exists": true
|
| 26 |
+
},
|
| 27 |
+
{
|
| 28 |
+
"name": "fisheye_cam1.mp4",
|
| 29 |
+
"bytes": 0,
|
| 30 |
+
"exists": false
|
| 31 |
+
},
|
| 32 |
+
{
|
| 33 |
+
"name": "fisheye_cam2.mp4",
|
| 34 |
+
"bytes": 0,
|
| 35 |
+
"exists": false
|
| 36 |
+
},
|
| 37 |
+
{
|
| 38 |
+
"name": "fisheye_cam3.mp4",
|
| 39 |
+
"bytes": 0,
|
| 40 |
+
"exists": false
|
| 41 |
+
},
|
| 42 |
+
{
|
| 43 |
+
"name": "stereo_left.mp4",
|
| 44 |
+
"bytes": 0,
|
| 45 |
+
"exists": false
|
| 46 |
+
},
|
| 47 |
+
{
|
| 48 |
+
"name": "stereo_right.mp4",
|
| 49 |
+
"bytes": 0,
|
| 50 |
+
"exists": false
|
| 51 |
+
},
|
| 52 |
+
{
|
| 53 |
+
"name": "visualization.rrd",
|
| 54 |
+
"bytes": 0,
|
| 55 |
+
"exists": false
|
| 56 |
+
}
|
| 57 |
+
],
|
| 58 |
+
"total_bytes": 2021338279,
|
| 59 |
+
"train_minimal_bytes": 2021338279,
|
| 60 |
+
"has_annotation": true,
|
| 61 |
+
"has_any_video": true,
|
| 62 |
+
"has_all_videos": false,
|
| 63 |
+
"has_rrd": false
|
| 64 |
+
}
|
| 65 |
+
]
|
| 66 |
+
}
|
results/omni_exploration/qwen3_adapter_smoke/RUN_REPORT.md
ADDED
|
@@ -0,0 +1,15 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Qwen3-Omni Adapter Smoke Test
|
| 2 |
+
|
| 3 |
+
- Base model target: `Qwen/Qwen3-Omni-30B-A3B-Thinking`
|
| 4 |
+
- Qwen3-Omni weights loaded: `false`
|
| 5 |
+
- Episodes: `1`
|
| 6 |
+
- Windows: `59` total, `41` train, `18` test
|
| 7 |
+
- Split: `single_episode_chronological`
|
| 8 |
+
- Feature dimension: `4262`
|
| 9 |
+
- Adapter soft-token blocks: `11`
|
| 10 |
+
- Accuracy: `0.0000`
|
| 11 |
+
- Macro-F1: `0.0000`
|
| 12 |
+
|
| 13 |
+
## Why this is the minimum real test
|
| 14 |
+
|
| 15 |
+
This run uses real Ropedia annotation/video-derived feature blocks. It tests the sensor-adapter side that depth, pose, mocap, contacts, and IMU need before those tokens are attached to Qwen3-Omni. It deliberately avoids downloading the 30B Qwen3-Omni weights until the data path, labels, splits, and storage plan are confirmed.
|
results/omni_exploration/qwen3_adapter_smoke/adapter_blocks.json
ADDED
|
@@ -0,0 +1,68 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
[
|
| 2 |
+
{
|
| 3 |
+
"name": "hand_left_joints",
|
| 4 |
+
"start": 0,
|
| 5 |
+
"end": 441,
|
| 6 |
+
"dim": 441
|
| 7 |
+
},
|
| 8 |
+
{
|
| 9 |
+
"name": "hand_right_joints",
|
| 10 |
+
"start": 441,
|
| 11 |
+
"end": 882,
|
| 12 |
+
"dim": 441
|
| 13 |
+
},
|
| 14 |
+
{
|
| 15 |
+
"name": "body_joints",
|
| 16 |
+
"start": 882,
|
| 17 |
+
"end": 1974,
|
| 18 |
+
"dim": 1092
|
| 19 |
+
},
|
| 20 |
+
{
|
| 21 |
+
"name": "body_contacts",
|
| 22 |
+
"start": 1974,
|
| 23 |
+
"end": 2121,
|
| 24 |
+
"dim": 147
|
| 25 |
+
},
|
| 26 |
+
{
|
| 27 |
+
"name": "camera_translation",
|
| 28 |
+
"start": 2121,
|
| 29 |
+
"end": 2142,
|
| 30 |
+
"dim": 21
|
| 31 |
+
},
|
| 32 |
+
{
|
| 33 |
+
"name": "camera_rotation_matrix",
|
| 34 |
+
"start": 2142,
|
| 35 |
+
"end": 2205,
|
| 36 |
+
"dim": 63
|
| 37 |
+
},
|
| 38 |
+
{
|
| 39 |
+
"name": "imu_accel_gyro",
|
| 40 |
+
"start": 2205,
|
| 41 |
+
"end": 2247,
|
| 42 |
+
"dim": 42
|
| 43 |
+
},
|
| 44 |
+
{
|
| 45 |
+
"name": "depth_confidence",
|
| 46 |
+
"start": 2247,
|
| 47 |
+
"end": 3227,
|
| 48 |
+
"dim": 980
|
| 49 |
+
},
|
| 50 |
+
{
|
| 51 |
+
"name": "caption_objects_interaction_text",
|
| 52 |
+
"start": 3227,
|
| 53 |
+
"end": 4123,
|
| 54 |
+
"dim": 896
|
| 55 |
+
},
|
| 56 |
+
{
|
| 57 |
+
"name": "slam_point_cloud",
|
| 58 |
+
"start": 4123,
|
| 59 |
+
"end": 4145,
|
| 60 |
+
"dim": 22
|
| 61 |
+
},
|
| 62 |
+
{
|
| 63 |
+
"name": "calibration",
|
| 64 |
+
"start": 4145,
|
| 65 |
+
"end": 4262,
|
| 66 |
+
"dim": 117
|
| 67 |
+
}
|
| 68 |
+
]
|
results/omni_exploration/qwen3_adapter_smoke/available_modalities.json
ADDED
|
@@ -0,0 +1,34 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
[
|
| 2 |
+
{
|
| 3 |
+
"episode_id": "xperience-10m-sample",
|
| 4 |
+
"modalities": [
|
| 5 |
+
{
|
| 6 |
+
"modality": "depth_confidence",
|
| 7 |
+
"shape": [
|
| 8 |
+
5821,
|
| 9 |
+
140
|
| 10 |
+
]
|
| 11 |
+
},
|
| 12 |
+
{
|
| 13 |
+
"modality": "caption_text",
|
| 14 |
+
"shape": [
|
| 15 |
+
5821,
|
| 16 |
+
128
|
| 17 |
+
],
|
| 18 |
+
"fields": "objects,interaction"
|
| 19 |
+
},
|
| 20 |
+
{
|
| 21 |
+
"modality": "slam_point_cloud_static",
|
| 22 |
+
"shape": [
|
| 23 |
+
22
|
| 24 |
+
]
|
| 25 |
+
},
|
| 26 |
+
{
|
| 27 |
+
"modality": "calibration_static",
|
| 28 |
+
"shape": [
|
| 29 |
+
117
|
| 30 |
+
]
|
| 31 |
+
}
|
| 32 |
+
]
|
| 33 |
+
}
|
| 34 |
+
]
|
results/omni_exploration/qwen3_adapter_smoke/confusion_matrix.csv
ADDED
|
@@ -0,0 +1,19 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
true\pred,Pick up kettle,Position kettle to pour,Move kettle,Hold coffee carafe,Grasp coffee scoop,Transfer coffee to dripper,Hold gooseneck kettle,Grasp gooseneck kettle,Lift gooseneck kettle,Move kettle away,Place kettle on table,Pick up white bottle,Pour liquid from white bottle,Close bottle cap,Place item on table,Wait/Prepare for pouring,Pour coffee,Pour milk into coffee
|
| 2 |
+
Pick up kettle,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0
|
| 3 |
+
Position kettle to pour,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0
|
| 4 |
+
Move kettle,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0
|
| 5 |
+
Hold coffee carafe,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0
|
| 6 |
+
Grasp coffee scoop,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0
|
| 7 |
+
Transfer coffee to dripper,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0
|
| 8 |
+
Hold gooseneck kettle,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0
|
| 9 |
+
Grasp gooseneck kettle,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0
|
| 10 |
+
Lift gooseneck kettle,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0
|
| 11 |
+
Move kettle away,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0
|
| 12 |
+
Place kettle on table,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0
|
| 13 |
+
Pick up white bottle,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0
|
| 14 |
+
Pour liquid from white bottle,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,0
|
| 15 |
+
Close bottle cap,0,0,0,0,0,0,1,1,0,0,0,0,1,0,0,0,0,0
|
| 16 |
+
Place item on table,1,0,0,0,0,0,0,1,0,0,0,0,0,0,0,0,0,0
|
| 17 |
+
Wait/Prepare for pouring,2,0,0,0,0,0,2,0,0,0,0,0,0,0,0,0,0,0
|
| 18 |
+
Pour coffee,0,0,0,0,5,0,0,0,0,0,0,0,1,2,0,0,0,0
|
| 19 |
+
Pour milk into coffee,0,0,0,0,1,0,0,0,0,0,0,0,0,0,0,0,0,0
|
results/omni_exploration/qwen3_adapter_smoke/feature_manifest.json
ADDED
|
@@ -0,0 +1,68 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
[
|
| 2 |
+
{
|
| 3 |
+
"name": "hand_left_joints",
|
| 4 |
+
"start": 0,
|
| 5 |
+
"end": 441,
|
| 6 |
+
"dim": 441
|
| 7 |
+
},
|
| 8 |
+
{
|
| 9 |
+
"name": "hand_right_joints",
|
| 10 |
+
"start": 441,
|
| 11 |
+
"end": 882,
|
| 12 |
+
"dim": 441
|
| 13 |
+
},
|
| 14 |
+
{
|
| 15 |
+
"name": "body_joints",
|
| 16 |
+
"start": 882,
|
| 17 |
+
"end": 1974,
|
| 18 |
+
"dim": 1092
|
| 19 |
+
},
|
| 20 |
+
{
|
| 21 |
+
"name": "body_contacts",
|
| 22 |
+
"start": 1974,
|
| 23 |
+
"end": 2121,
|
| 24 |
+
"dim": 147
|
| 25 |
+
},
|
| 26 |
+
{
|
| 27 |
+
"name": "camera_translation",
|
| 28 |
+
"start": 2121,
|
| 29 |
+
"end": 2142,
|
| 30 |
+
"dim": 21
|
| 31 |
+
},
|
| 32 |
+
{
|
| 33 |
+
"name": "camera_rotation_matrix",
|
| 34 |
+
"start": 2142,
|
| 35 |
+
"end": 2205,
|
| 36 |
+
"dim": 63
|
| 37 |
+
},
|
| 38 |
+
{
|
| 39 |
+
"name": "imu_accel_gyro",
|
| 40 |
+
"start": 2205,
|
| 41 |
+
"end": 2247,
|
| 42 |
+
"dim": 42
|
| 43 |
+
},
|
| 44 |
+
{
|
| 45 |
+
"name": "depth_confidence",
|
| 46 |
+
"start": 2247,
|
| 47 |
+
"end": 3227,
|
| 48 |
+
"dim": 980
|
| 49 |
+
},
|
| 50 |
+
{
|
| 51 |
+
"name": "caption_objects_interaction_text",
|
| 52 |
+
"start": 3227,
|
| 53 |
+
"end": 4123,
|
| 54 |
+
"dim": 896
|
| 55 |
+
},
|
| 56 |
+
{
|
| 57 |
+
"name": "slam_point_cloud",
|
| 58 |
+
"start": 4123,
|
| 59 |
+
"end": 4145,
|
| 60 |
+
"dim": 22
|
| 61 |
+
},
|
| 62 |
+
{
|
| 63 |
+
"name": "calibration",
|
| 64 |
+
"start": 4145,
|
| 65 |
+
"end": 4262,
|
| 66 |
+
"dim": 117
|
| 67 |
+
}
|
| 68 |
+
]
|
results/omni_exploration/qwen3_adapter_smoke/metrics.json
ADDED
|
@@ -0,0 +1,30 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"task": "qwen3_omni_sensor_adapter_smoke_action",
|
| 3 |
+
"base_model_target": "Qwen/Qwen3-Omni-30B-A3B-Thinking",
|
| 4 |
+
"qwen3_loaded": false,
|
| 5 |
+
"qwen3_note": "This run validates Xperience-10M sensor-adapter tokens and task heads before loading or LoRA-tuning Qwen3-Omni.",
|
| 6 |
+
"split": "single_episode_chronological",
|
| 7 |
+
"num_episodes": 1,
|
| 8 |
+
"num_windows": 59,
|
| 9 |
+
"num_train_windows": 41,
|
| 10 |
+
"num_test_windows": 18,
|
| 11 |
+
"num_classes": 18,
|
| 12 |
+
"feature_dim": 4262,
|
| 13 |
+
"num_adapter_tokens": 11,
|
| 14 |
+
"accuracy": 0.0,
|
| 15 |
+
"macro_f1": 0.0,
|
| 16 |
+
"train_final_loss": 1.4479121318677577,
|
| 17 |
+
"train_final_accuracy": 0.6829268292682927,
|
| 18 |
+
"direct_qwen3_inputs": [
|
| 19 |
+
"rgb/fisheye video",
|
| 20 |
+
"embedded mp4 audio",
|
| 21 |
+
"language annotation prompt"
|
| 22 |
+
],
|
| 23 |
+
"adapter_required_inputs": [
|
| 24 |
+
"depth/confidence",
|
| 25 |
+
"pose/SLAM camera trajectory",
|
| 26 |
+
"motion capture hand/body joints",
|
| 27 |
+
"IMU accel/gyro",
|
| 28 |
+
"contacts/object state features"
|
| 29 |
+
]
|
| 30 |
+
}
|
results/omni_exploration/qwen3_adapter_smoke/per_class_metrics.csv
ADDED
|
@@ -0,0 +1,19 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
class_id,class_name,support,predicted,precision,recall,f1
|
| 2 |
+
0,Pick up kettle,0,3,0.0,0.0,0.0
|
| 3 |
+
1,Position kettle to pour,0,0,0.0,0.0,0.0
|
| 4 |
+
2,Move kettle,0,0,0.0,0.0,0.0
|
| 5 |
+
3,Hold coffee carafe,0,0,0.0,0.0,0.0
|
| 6 |
+
4,Grasp coffee scoop,0,6,0.0,0.0,0.0
|
| 7 |
+
5,Transfer coffee to dripper,0,0,0.0,0.0,0.0
|
| 8 |
+
6,Hold gooseneck kettle,0,3,0.0,0.0,0.0
|
| 9 |
+
7,Grasp gooseneck kettle,0,2,0.0,0.0,0.0
|
| 10 |
+
8,Lift gooseneck kettle,0,0,0.0,0.0,0.0
|
| 11 |
+
9,Move kettle away,0,0,0.0,0.0,0.0
|
| 12 |
+
10,Place kettle on table,0,0,0.0,0.0,0.0
|
| 13 |
+
11,Pick up white bottle,0,0,0.0,0.0,0.0
|
| 14 |
+
12,Pour liquid from white bottle,0,2,0.0,0.0,0.0
|
| 15 |
+
13,Close bottle cap,3,2,0.0,0.0,0.0
|
| 16 |
+
14,Place item on table,2,0,0.0,0.0,0.0
|
| 17 |
+
15,Wait/Prepare for pouring,4,0,0.0,0.0,0.0
|
| 18 |
+
16,Pour coffee,8,0,0.0,0.0,0.0
|
| 19 |
+
17,Pour milk into coffee,1,0,0.0,0.0,0.0
|
results/omni_exploration/qwen3_adapter_smoke/predictions.csv
ADDED
|
@@ -0,0 +1,19 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
sample_index,episode_id,window_id,true_label,predicted_label,correct
|
| 2 |
+
41,xperience-10m-sample,41,Close bottle cap,Pour liquid from white bottle,0
|
| 3 |
+
42,xperience-10m-sample,42,Close bottle cap,Grasp gooseneck kettle,0
|
| 4 |
+
43,xperience-10m-sample,43,Close bottle cap,Hold gooseneck kettle,0
|
| 5 |
+
44,xperience-10m-sample,44,Place item on table,Grasp gooseneck kettle,0
|
| 6 |
+
45,xperience-10m-sample,45,Place item on table,Pick up kettle,0
|
| 7 |
+
46,xperience-10m-sample,46,Wait/Prepare for pouring,Hold gooseneck kettle,0
|
| 8 |
+
47,xperience-10m-sample,47,Wait/Prepare for pouring,Pick up kettle,0
|
| 9 |
+
48,xperience-10m-sample,48,Wait/Prepare for pouring,Hold gooseneck kettle,0
|
| 10 |
+
49,xperience-10m-sample,49,Wait/Prepare for pouring,Pick up kettle,0
|
| 11 |
+
50,xperience-10m-sample,50,Pour coffee,Grasp coffee scoop,0
|
| 12 |
+
51,xperience-10m-sample,51,Pour coffee,Close bottle cap,0
|
| 13 |
+
52,xperience-10m-sample,52,Pour coffee,Pour liquid from white bottle,0
|
| 14 |
+
53,xperience-10m-sample,53,Pour coffee,Close bottle cap,0
|
| 15 |
+
54,xperience-10m-sample,54,Pour coffee,Grasp coffee scoop,0
|
| 16 |
+
55,xperience-10m-sample,55,Pour coffee,Grasp coffee scoop,0
|
| 17 |
+
56,xperience-10m-sample,56,Pour coffee,Grasp coffee scoop,0
|
| 18 |
+
57,xperience-10m-sample,57,Pour coffee,Grasp coffee scoop,0
|
| 19 |
+
58,xperience-10m-sample,58,Pour milk into coffee,Grasp coffee scoop,0
|
scripts/episode_task_suite.py
CHANGED
|
@@ -1,6 +1,6 @@
|
|
| 1 |
#!/usr/bin/env python3
|
| 2 |
"""
|
| 3 |
-
End-to-end task suite for one
|
| 4 |
|
| 5 |
The purpose is not to prove generalization from one sample episode. It is to
|
| 6 |
turn the episode into multiple meaningful supervised/self-supervised learning
|
|
@@ -56,7 +56,7 @@ TASKS = [
|
|
| 56 |
def parse_args() -> argparse.Namespace:
|
| 57 |
workspace_default = Path(__file__).resolve().parents[1]
|
| 58 |
annotation_default = workspace_default / "data/sample/xperience-10m-sample/annotation.hdf5"
|
| 59 |
-
parser = argparse.ArgumentParser(description="Run an end-to-end task suite on one
|
| 60 |
parser.add_argument("--workspace", type=Path, default=workspace_default)
|
| 61 |
parser.add_argument("--annotation", type=Path, default=annotation_default)
|
| 62 |
parser.add_argument("--output-dir", type=Path, default=workspace_default / "outputs/episode_task_suite")
|
|
|
|
| 1 |
#!/usr/bin/env python3
|
| 2 |
"""
|
| 3 |
+
End-to-end task suite for one Xperience-10M episode released by Ropedia.
|
| 4 |
|
| 5 |
The purpose is not to prove generalization from one sample episode. It is to
|
| 6 |
turn the episode into multiple meaningful supervised/self-supervised learning
|
|
|
|
| 56 |
def parse_args() -> argparse.Namespace:
|
| 57 |
workspace_default = Path(__file__).resolve().parents[1]
|
| 58 |
annotation_default = workspace_default / "data/sample/xperience-10m-sample/annotation.hdf5"
|
| 59 |
+
parser = argparse.ArgumentParser(description="Run an end-to-end task suite on one Xperience-10M episode.")
|
| 60 |
parser.add_argument("--workspace", type=Path, default=workspace_default)
|
| 61 |
parser.add_argument("--annotation", type=Path, default=annotation_default)
|
| 62 |
parser.add_argument("--output-dir", type=Path, default=workspace_default / "outputs/episode_task_suite")
|
scripts/generate_visualizations.py
CHANGED
|
@@ -1,6 +1,6 @@
|
|
| 1 |
#!/usr/bin/env python3
|
| 2 |
"""
|
| 3 |
-
Generate static SVG visualizations and website data for the
|
| 4 |
|
| 5 |
No plotting dependencies are required; this uses only the Python standard
|
| 6 |
library so the repo stays easy to run.
|
|
@@ -117,7 +117,7 @@ def svg_pipeline_diagram(path: Path, summary: dict) -> None:
|
|
| 117 |
f'<svg xmlns="http://www.w3.org/2000/svg" width="{width}" height="{height}" viewBox="0 0 {width} {height}">',
|
| 118 |
'<rect width="100%" height="100%" fill="#ffffff"/>',
|
| 119 |
'<rect x="0" y="0" width="1400" height="760" fill="#ffffff"/>',
|
| 120 |
-
'<text x="60" y="58" font-family="Arial, sans-serif" font-size="32" font-weight="700" fill="#10141f">Verified
|
| 121 |
'<text x="60" y="88" font-family="Arial, sans-serif" font-size="16" fill="#5b6475">Generated from committed scripts and metrics; no conceptual placeholder stages.</text>',
|
| 122 |
]
|
| 123 |
arrows = [
|
|
@@ -324,7 +324,7 @@ def svg_task_architectures(path: Path, summary: dict) -> None:
|
|
| 324 |
f'<svg xmlns="http://www.w3.org/2000/svg" width="{width}" height="{height}" viewBox="0 0 {width} {height}">',
|
| 325 |
'<defs><marker id="arrow2" viewBox="0 0 10 10" refX="8" refY="5" markerWidth="7" markerHeight="7" orient="auto-start-reverse"><path d="M 0 0 L 10 5 L 0 10 z" fill="#cbd5e1"/></marker></defs>',
|
| 326 |
'<rect width="100%" height="100%" fill="#ffffff"/>',
|
| 327 |
-
'<text x="60" y="56" font-family="Arial, sans-serif" font-size="34" font-weight="700" fill="#10141f">Minimal Architectures for the 12
|
| 328 |
'<text x="60" y="88" font-family="Arial, sans-serif" font-size="16" fill="#5b6475">Generated from scripts/episode_task_suite.py semantics and committed summary metrics. These are minimal baselines, not deep foundation models.</text>',
|
| 329 |
]
|
| 330 |
|
|
|
|
| 1 |
#!/usr/bin/env python3
|
| 2 |
"""
|
| 3 |
+
Generate static SVG visualizations and website data for the Xperience-10M task suite.
|
| 4 |
|
| 5 |
No plotting dependencies are required; this uses only the Python standard
|
| 6 |
library so the repo stays easy to run.
|
|
|
|
| 117 |
f'<svg xmlns="http://www.w3.org/2000/svg" width="{width}" height="{height}" viewBox="0 0 {width} {height}">',
|
| 118 |
'<rect width="100%" height="100%" fill="#ffffff"/>',
|
| 119 |
'<rect x="0" y="0" width="1400" height="760" fill="#ffffff"/>',
|
| 120 |
+
'<text x="60" y="58" font-family="Arial, sans-serif" font-size="32" font-weight="700" fill="#10141f">Verified Xperience-10M Episode Pipeline</text>',
|
| 121 |
'<text x="60" y="88" font-family="Arial, sans-serif" font-size="16" fill="#5b6475">Generated from committed scripts and metrics; no conceptual placeholder stages.</text>',
|
| 122 |
]
|
| 123 |
arrows = [
|
|
|
|
| 324 |
f'<svg xmlns="http://www.w3.org/2000/svg" width="{width}" height="{height}" viewBox="0 0 {width} {height}">',
|
| 325 |
'<defs><marker id="arrow2" viewBox="0 0 10 10" refX="8" refY="5" markerWidth="7" markerHeight="7" orient="auto-start-reverse"><path d="M 0 0 L 10 5 L 0 10 z" fill="#cbd5e1"/></marker></defs>',
|
| 326 |
'<rect width="100%" height="100%" fill="#ffffff"/>',
|
| 327 |
+
'<text x="60" y="56" font-family="Arial, sans-serif" font-size="34" font-weight="700" fill="#10141f">Minimal Architectures for the 12 Xperience-10M Episode Tasks</text>',
|
| 328 |
'<text x="60" y="88" font-family="Arial, sans-serif" font-size="16" fill="#5b6475">Generated from scripts/episode_task_suite.py semantics and committed summary metrics. These are minimal baselines, not deep foundation models.</text>',
|
| 329 |
]
|
| 330 |
|
scripts/omni/build_episode_manifest.py
ADDED
|
@@ -0,0 +1,101 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
#!/usr/bin/env python3
|
| 2 |
+
"""Build a lightweight manifest for local Xperience-10M episode folders.
|
| 3 |
+
|
| 4 |
+
The manifest is intentionally metadata-only. It lets us decide how many
|
| 5 |
+
episodes fit on the H20 server before downloading or copying large media.
|
| 6 |
+
"""
|
| 7 |
+
|
| 8 |
+
from __future__ import annotations
|
| 9 |
+
|
| 10 |
+
import argparse
|
| 11 |
+
import json
|
| 12 |
+
from pathlib import Path
|
| 13 |
+
|
| 14 |
+
|
| 15 |
+
VIDEO_NAMES = [
|
| 16 |
+
"fisheye_cam0.mp4",
|
| 17 |
+
"fisheye_cam1.mp4",
|
| 18 |
+
"fisheye_cam2.mp4",
|
| 19 |
+
"fisheye_cam3.mp4",
|
| 20 |
+
"stereo_left.mp4",
|
| 21 |
+
"stereo_right.mp4",
|
| 22 |
+
]
|
| 23 |
+
|
| 24 |
+
|
| 25 |
+
def parse_args() -> argparse.Namespace:
|
| 26 |
+
parser = argparse.ArgumentParser(description="Scan Xperience-10M episode folders.")
|
| 27 |
+
parser.add_argument(
|
| 28 |
+
"--data-root",
|
| 29 |
+
type=Path,
|
| 30 |
+
action="append",
|
| 31 |
+
required=True,
|
| 32 |
+
help="Root to scan. May be passed multiple times.",
|
| 33 |
+
)
|
| 34 |
+
parser.add_argument(
|
| 35 |
+
"--output",
|
| 36 |
+
type=Path,
|
| 37 |
+
default=Path("outputs/omni_exploration/episode_manifest.json"),
|
| 38 |
+
)
|
| 39 |
+
parser.add_argument("--max-episodes", type=int, default=0, help="0 means no cap.")
|
| 40 |
+
return parser.parse_args()
|
| 41 |
+
|
| 42 |
+
|
| 43 |
+
def size_or_zero(path: Path) -> int:
|
| 44 |
+
try:
|
| 45 |
+
return path.stat().st_size
|
| 46 |
+
except FileNotFoundError:
|
| 47 |
+
return 0
|
| 48 |
+
|
| 49 |
+
|
| 50 |
+
def inspect_episode(annotation: Path) -> dict:
|
| 51 |
+
episode_dir = annotation.parent
|
| 52 |
+
files = [{"name": "annotation.hdf5", "bytes": size_or_zero(annotation), "exists": annotation.exists()}]
|
| 53 |
+
for name in VIDEO_NAMES:
|
| 54 |
+
path = episode_dir / name
|
| 55 |
+
files.append({"name": name, "bytes": size_or_zero(path), "exists": path.exists()})
|
| 56 |
+
rrd = episode_dir / "visualization.rrd"
|
| 57 |
+
files.append({"name": "visualization.rrd", "bytes": size_or_zero(rrd), "exists": rrd.exists()})
|
| 58 |
+
total_bytes = sum(item["bytes"] for item in files)
|
| 59 |
+
train_bytes = sum(item["bytes"] for item in files if item["name"] != "visualization.rrd")
|
| 60 |
+
return {
|
| 61 |
+
"episode_id": episode_dir.name,
|
| 62 |
+
"path": str(episode_dir),
|
| 63 |
+
"annotation": str(annotation),
|
| 64 |
+
"files": files,
|
| 65 |
+
"total_bytes": total_bytes,
|
| 66 |
+
"train_minimal_bytes": train_bytes,
|
| 67 |
+
"has_annotation": annotation.exists(),
|
| 68 |
+
"has_any_video": any((episode_dir / name).exists() for name in VIDEO_NAMES),
|
| 69 |
+
"has_all_videos": all((episode_dir / name).exists() for name in VIDEO_NAMES),
|
| 70 |
+
"has_rrd": rrd.exists(),
|
| 71 |
+
}
|
| 72 |
+
|
| 73 |
+
|
| 74 |
+
def main() -> int:
|
| 75 |
+
args = parse_args()
|
| 76 |
+
annotations: list[Path] = []
|
| 77 |
+
for root in args.data_root:
|
| 78 |
+
annotations.extend(sorted(root.expanduser().resolve().rglob("annotation.hdf5")))
|
| 79 |
+
if args.max_episodes > 0:
|
| 80 |
+
annotations = annotations[: args.max_episodes]
|
| 81 |
+
|
| 82 |
+
episodes = [inspect_episode(path) for path in annotations]
|
| 83 |
+
summary = {
|
| 84 |
+
"num_episodes": len(episodes),
|
| 85 |
+
"total_bytes": sum(ep["total_bytes"] for ep in episodes),
|
| 86 |
+
"train_minimal_bytes": sum(ep["train_minimal_bytes"] for ep in episodes),
|
| 87 |
+
"notes": [
|
| 88 |
+
"train_minimal_bytes excludes visualization.rrd because model training does not need it.",
|
| 89 |
+
"This file is metadata-only; it does not copy or download raw data.",
|
| 90 |
+
],
|
| 91 |
+
}
|
| 92 |
+
payload = {"summary": summary, "episodes": episodes}
|
| 93 |
+
args.output.parent.mkdir(parents=True, exist_ok=True)
|
| 94 |
+
args.output.write_text(json.dumps(payload, indent=2), encoding="utf-8")
|
| 95 |
+
print(json.dumps(summary, indent=2))
|
| 96 |
+
print(f"Wrote {args.output}")
|
| 97 |
+
return 0
|
| 98 |
+
|
| 99 |
+
|
| 100 |
+
if __name__ == "__main__":
|
| 101 |
+
raise SystemExit(main())
|
scripts/omni/download_sample_modelscope.py
ADDED
|
@@ -0,0 +1,78 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
#!/usr/bin/env python3
|
| 2 |
+
"""Download the public Xperience-10M sample from ModelScope.
|
| 3 |
+
|
| 4 |
+
This is the preferred path for servers inside mainland China. It downloads
|
| 5 |
+
only model-training files by default and skips visualization.rrd.
|
| 6 |
+
"""
|
| 7 |
+
|
| 8 |
+
from __future__ import annotations
|
| 9 |
+
|
| 10 |
+
import argparse
|
| 11 |
+
import json
|
| 12 |
+
from pathlib import Path
|
| 13 |
+
|
| 14 |
+
|
| 15 |
+
DEFAULT_PATTERNS = [
|
| 16 |
+
"README.md",
|
| 17 |
+
"annotation.hdf5",
|
| 18 |
+
"fisheye_cam0.mp4",
|
| 19 |
+
]
|
| 20 |
+
|
| 21 |
+
ALL_TRAINING_PATTERNS = [
|
| 22 |
+
"README.md",
|
| 23 |
+
"annotation.hdf5",
|
| 24 |
+
"fisheye_cam0.mp4",
|
| 25 |
+
"fisheye_cam1.mp4",
|
| 26 |
+
"fisheye_cam2.mp4",
|
| 27 |
+
"fisheye_cam3.mp4",
|
| 28 |
+
"stereo_left.mp4",
|
| 29 |
+
"stereo_right.mp4",
|
| 30 |
+
]
|
| 31 |
+
|
| 32 |
+
|
| 33 |
+
def parse_args() -> argparse.Namespace:
|
| 34 |
+
parser = argparse.ArgumentParser(description="Download Xperience-10M sample data from ModelScope.")
|
| 35 |
+
parser.add_argument("--repo-id", default="ropedia-ai/xperience-10m-sample")
|
| 36 |
+
parser.add_argument("--output-dir", type=Path, default=Path("data/sample/xperience-10m-sample"))
|
| 37 |
+
parser.add_argument(
|
| 38 |
+
"--mode",
|
| 39 |
+
choices=["minimal", "all-training", "all"],
|
| 40 |
+
default="minimal",
|
| 41 |
+
help="minimal downloads annotation + one video; all-training adds all MP4s; all also allows visualization.rrd.",
|
| 42 |
+
)
|
| 43 |
+
parser.add_argument("--max-workers", type=int, default=2)
|
| 44 |
+
return parser.parse_args()
|
| 45 |
+
|
| 46 |
+
|
| 47 |
+
def main() -> int:
|
| 48 |
+
args = parse_args()
|
| 49 |
+
from modelscope.hub.snapshot_download import snapshot_download
|
| 50 |
+
|
| 51 |
+
if args.mode == "minimal":
|
| 52 |
+
allow_patterns = DEFAULT_PATTERNS
|
| 53 |
+
elif args.mode == "all-training":
|
| 54 |
+
allow_patterns = ALL_TRAINING_PATTERNS
|
| 55 |
+
else:
|
| 56 |
+
allow_patterns = None
|
| 57 |
+
|
| 58 |
+
args.output_dir.mkdir(parents=True, exist_ok=True)
|
| 59 |
+
path = snapshot_download(
|
| 60 |
+
repo_id=args.repo_id,
|
| 61 |
+
repo_type="dataset",
|
| 62 |
+
local_dir=str(args.output_dir),
|
| 63 |
+
allow_patterns=allow_patterns,
|
| 64 |
+
max_workers=args.max_workers,
|
| 65 |
+
)
|
| 66 |
+
summary = {
|
| 67 |
+
"repo_id": args.repo_id,
|
| 68 |
+
"output_dir": str(args.output_dir),
|
| 69 |
+
"mode": args.mode,
|
| 70 |
+
"allow_patterns": allow_patterns,
|
| 71 |
+
"download_path": path,
|
| 72 |
+
}
|
| 73 |
+
print(json.dumps(summary, indent=2))
|
| 74 |
+
return 0
|
| 75 |
+
|
| 76 |
+
|
| 77 |
+
if __name__ == "__main__":
|
| 78 |
+
raise SystemExit(main())
|
scripts/omni/plan_finetune_sample_budget.py
ADDED
|
@@ -0,0 +1,147 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
#!/usr/bin/env python3
|
| 2 |
+
"""Plan Xperience-10M episode counts for an H20 fine-tuning run.
|
| 3 |
+
|
| 4 |
+
This is a storage and evaluation-design helper. It does not train a model and
|
| 5 |
+
does not invent results. Use it before downloading many episodes.
|
| 6 |
+
"""
|
| 7 |
+
|
| 8 |
+
from __future__ import annotations
|
| 9 |
+
|
| 10 |
+
import argparse
|
| 11 |
+
import json
|
| 12 |
+
import math
|
| 13 |
+
import shutil
|
| 14 |
+
from pathlib import Path
|
| 15 |
+
|
| 16 |
+
|
| 17 |
+
GB = 1024 ** 3
|
| 18 |
+
|
| 19 |
+
|
| 20 |
+
def parse_args() -> argparse.Namespace:
|
| 21 |
+
parser = argparse.ArgumentParser(description="Estimate feasible Xperience-10M fine-tuning sample counts.")
|
| 22 |
+
parser.add_argument("--storage-root", type=Path, default=Path("/home/cy"), help="Disk root to inspect.")
|
| 23 |
+
parser.add_argument("--free-gb", type=float, default=None, help="Override measured free space in GiB.")
|
| 24 |
+
parser.add_argument("--target-free-after-download-gb", type=float, default=800.0)
|
| 25 |
+
parser.add_argument("--model-cache-gb", type=float, default=250.0)
|
| 26 |
+
parser.add_argument("--checkpoint-cache-gb", type=float, default=200.0)
|
| 27 |
+
parser.add_argument("--log-cache-gb", type=float, default=50.0)
|
| 28 |
+
parser.add_argument("--minimal-per-episode-gb", type=float, default=2.02)
|
| 29 |
+
parser.add_argument("--all-training-per-episode-gb", type=float, default=2.40)
|
| 30 |
+
parser.add_argument("--full-preview-per-episode-gb", type=float, default=5.10)
|
| 31 |
+
parser.add_argument("--windows-per-episode", type=int, default=1161)
|
| 32 |
+
parser.add_argument("--test-fraction", type=float, default=0.20)
|
| 33 |
+
parser.add_argument("--output", type=Path, default=Path("outputs/omni_exploration/finetune_sample_budget.json"))
|
| 34 |
+
return parser.parse_args()
|
| 35 |
+
|
| 36 |
+
|
| 37 |
+
def measured_free_gb(storage_root: Path, override: float | None) -> float:
|
| 38 |
+
if override is not None:
|
| 39 |
+
return float(override)
|
| 40 |
+
if not storage_root.exists():
|
| 41 |
+
raise FileNotFoundError(f"storage root does not exist: {storage_root}")
|
| 42 |
+
return shutil.disk_usage(storage_root).free / GB
|
| 43 |
+
|
| 44 |
+
|
| 45 |
+
def max_episodes_for_budget(available_data_gb: float, per_episode_gb: float) -> int:
|
| 46 |
+
if available_data_gb <= 0 or per_episode_gb <= 0:
|
| 47 |
+
return 0
|
| 48 |
+
return max(0, int(math.floor(available_data_gb / per_episode_gb)))
|
| 49 |
+
|
| 50 |
+
|
| 51 |
+
def split_windows(episodes: int, windows_per_episode: int, test_fraction: float) -> dict:
|
| 52 |
+
if episodes <= 0:
|
| 53 |
+
return {"train_episodes": 0, "test_episodes": 0, "train_windows": 0, "test_windows": 0}
|
| 54 |
+
test_episodes = max(1, int(round(episodes * test_fraction))) if episodes > 1 else 1
|
| 55 |
+
train_episodes = max(0, episodes - test_episodes)
|
| 56 |
+
return {
|
| 57 |
+
"train_episodes": train_episodes,
|
| 58 |
+
"test_episodes": test_episodes,
|
| 59 |
+
"train_windows": train_episodes * windows_per_episode,
|
| 60 |
+
"test_windows": test_episodes * windows_per_episode,
|
| 61 |
+
}
|
| 62 |
+
|
| 63 |
+
|
| 64 |
+
def phase_rows(max_all_training: int, windows_per_episode: int, test_fraction: float) -> list[dict]:
|
| 65 |
+
phase_specs = [
|
| 66 |
+
("smoke", 1, "Verify loaders, alignment, and heads."),
|
| 67 |
+
("smoke_plus", 3, "Catch obvious multi-episode path issues."),
|
| 68 |
+
("pilot", 16, "First held-out-episode evaluation."),
|
| 69 |
+
("recommended_next", 32, "Default next run if download layout is clean."),
|
| 70 |
+
("useful_lora_small", 64, "Train sensor adapters plus selected LoRA layers."),
|
| 71 |
+
("useful_lora_medium", 128, "More useful LoRA run after pilot is stable."),
|
| 72 |
+
("storage_heavy", 256, "Only after checkpoint size and data layout are stable."),
|
| 73 |
+
]
|
| 74 |
+
rows = []
|
| 75 |
+
for name, episodes, purpose in phase_specs:
|
| 76 |
+
split = split_windows(episodes, windows_per_episode, test_fraction)
|
| 77 |
+
rows.append({
|
| 78 |
+
"phase": name,
|
| 79 |
+
"episodes": episodes,
|
| 80 |
+
"feasible_under_all_training_budget": episodes <= max_all_training,
|
| 81 |
+
"approx_windows": episodes * windows_per_episode,
|
| 82 |
+
**split,
|
| 83 |
+
"purpose": purpose,
|
| 84 |
+
})
|
| 85 |
+
return rows
|
| 86 |
+
|
| 87 |
+
|
| 88 |
+
def choose_recommendation(max_all_training: int) -> int:
|
| 89 |
+
for candidate in (32, 16, 8, 3, 1):
|
| 90 |
+
if max_all_training >= candidate:
|
| 91 |
+
return candidate
|
| 92 |
+
return 0
|
| 93 |
+
|
| 94 |
+
|
| 95 |
+
def main() -> int:
|
| 96 |
+
args = parse_args()
|
| 97 |
+
free_gb = measured_free_gb(args.storage_root.expanduser(), args.free_gb)
|
| 98 |
+
reserved_gb = args.target_free_after_download_gb + args.model_cache_gb + args.checkpoint_cache_gb + args.log_cache_gb
|
| 99 |
+
available_data_gb = max(0.0, free_gb - reserved_gb)
|
| 100 |
+
|
| 101 |
+
modes = {
|
| 102 |
+
"minimal_annotation_plus_one_video": args.minimal_per_episode_gb,
|
| 103 |
+
"all_training_files_no_rrd": args.all_training_per_episode_gb,
|
| 104 |
+
"full_preview_including_rrd": args.full_preview_per_episode_gb,
|
| 105 |
+
}
|
| 106 |
+
mode_summary = {
|
| 107 |
+
name: {
|
| 108 |
+
"per_episode_gb": per_episode_gb,
|
| 109 |
+
"max_episodes": max_episodes_for_budget(available_data_gb, per_episode_gb),
|
| 110 |
+
}
|
| 111 |
+
for name, per_episode_gb in modes.items()
|
| 112 |
+
}
|
| 113 |
+
max_all_training = mode_summary["all_training_files_no_rrd"]["max_episodes"]
|
| 114 |
+
recommended = choose_recommendation(max_all_training)
|
| 115 |
+
|
| 116 |
+
payload = {
|
| 117 |
+
"assumptions": {
|
| 118 |
+
"storage_root": str(args.storage_root),
|
| 119 |
+
"measured_or_overridden_free_gb": round(free_gb, 3),
|
| 120 |
+
"target_free_after_download_gb": args.target_free_after_download_gb,
|
| 121 |
+
"reserved_model_cache_gb": args.model_cache_gb,
|
| 122 |
+
"reserved_checkpoint_cache_gb": args.checkpoint_cache_gb,
|
| 123 |
+
"reserved_log_cache_gb": args.log_cache_gb,
|
| 124 |
+
"available_for_episode_data_gb": round(available_data_gb, 3),
|
| 125 |
+
"windows_per_episode": args.windows_per_episode,
|
| 126 |
+
"test_fraction": args.test_fraction,
|
| 127 |
+
"note": "Episode sizes are estimates until build_episode_manifest.py scans the actual downloaded folders.",
|
| 128 |
+
},
|
| 129 |
+
"modes": mode_summary,
|
| 130 |
+
"recommended_next_episodes": recommended,
|
| 131 |
+
"recommended_next_reason": (
|
| 132 |
+
"Use 32 episodes first when feasible; otherwise use the largest smaller phase. "
|
| 133 |
+
"Scale to 64 or 128 only after the pilot download and held-out-episode evaluation are stable."
|
| 134 |
+
),
|
| 135 |
+
"phases": phase_rows(max_all_training, args.windows_per_episode, args.test_fraction),
|
| 136 |
+
}
|
| 137 |
+
|
| 138 |
+
args.output.parent.mkdir(parents=True, exist_ok=True)
|
| 139 |
+
args.output.write_text(json.dumps(payload, indent=2), encoding="utf-8")
|
| 140 |
+
print(json.dumps(payload["assumptions"], indent=2))
|
| 141 |
+
print(json.dumps({"recommended_next_episodes": recommended, "modes": mode_summary}, indent=2))
|
| 142 |
+
print(f"Wrote {args.output}")
|
| 143 |
+
return 0
|
| 144 |
+
|
| 145 |
+
|
| 146 |
+
if __name__ == "__main__":
|
| 147 |
+
raise SystemExit(main())
|
scripts/omni/qwen3_omni_adapter_smoke.py
ADDED
|
@@ -0,0 +1,493 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
#!/usr/bin/env python3
|
| 2 |
+
"""Minimum real-data adapter smoke test for an Xperience-10M -> Qwen3-Omni path.
|
| 3 |
+
|
| 4 |
+
This script does not pretend to fine-tune Qwen3-Omni itself. It validates the
|
| 5 |
+
part that Xperience-10M sensor modalities need before they can be attached
|
| 6 |
+
to an omni backbone: windowing real episodes, turning sensor blocks into
|
| 7 |
+
adapter tokens, and training/evaluating a small task head on real labels.
|
| 8 |
+
"""
|
| 9 |
+
|
| 10 |
+
from __future__ import annotations
|
| 11 |
+
|
| 12 |
+
import argparse
|
| 13 |
+
import csv
|
| 14 |
+
import json
|
| 15 |
+
import math
|
| 16 |
+
import sys
|
| 17 |
+
from collections import Counter, OrderedDict
|
| 18 |
+
from dataclasses import dataclass
|
| 19 |
+
from pathlib import Path
|
| 20 |
+
|
| 21 |
+
import numpy as np
|
| 22 |
+
|
| 23 |
+
|
| 24 |
+
DIRECT_QWEN3_INPUTS = [
|
| 25 |
+
"rgb/fisheye video",
|
| 26 |
+
"embedded mp4 audio",
|
| 27 |
+
"language annotation prompt",
|
| 28 |
+
]
|
| 29 |
+
|
| 30 |
+
ADAPTER_INPUTS = [
|
| 31 |
+
"depth/confidence",
|
| 32 |
+
"pose/SLAM camera trajectory",
|
| 33 |
+
"motion capture hand/body joints",
|
| 34 |
+
"IMU accel/gyro",
|
| 35 |
+
"contacts/object state features",
|
| 36 |
+
]
|
| 37 |
+
|
| 38 |
+
|
| 39 |
+
def parse_args() -> argparse.Namespace:
|
| 40 |
+
workspace_default = Path(__file__).resolve().parents[2]
|
| 41 |
+
parser = argparse.ArgumentParser(description="Run a real-data Xperience-10M sensor-adapter smoke test.")
|
| 42 |
+
parser.add_argument("--workspace", type=Path, default=workspace_default)
|
| 43 |
+
parser.add_argument(
|
| 44 |
+
"--episode-root",
|
| 45 |
+
type=Path,
|
| 46 |
+
action="append",
|
| 47 |
+
help="Episode folder containing annotation.hdf5. May be passed multiple times.",
|
| 48 |
+
)
|
| 49 |
+
parser.add_argument(
|
| 50 |
+
"--manifest",
|
| 51 |
+
type=Path,
|
| 52 |
+
help="Manifest produced by build_episode_manifest.py. Episodes from this file are appended.",
|
| 53 |
+
)
|
| 54 |
+
parser.add_argument("--target", choices=["action", "subtask"], default="action")
|
| 55 |
+
parser.add_argument("--output-dir", type=Path, default=workspace_default / "outputs/omni_exploration/qwen3_adapter_smoke")
|
| 56 |
+
parser.add_argument("--cache-dir", type=Path, default=workspace_default / "outputs/omni_exploration/feature_cache")
|
| 57 |
+
parser.add_argument("--base-model-id", default="Qwen/Qwen3-Omni-30B-A3B-Thinking")
|
| 58 |
+
parser.add_argument("--window-frames", type=int, default=20)
|
| 59 |
+
parser.add_argument("--stride-frames", type=int, default=20)
|
| 60 |
+
parser.add_argument("--min-label-fraction", type=float, default=0.6)
|
| 61 |
+
parser.add_argument("--max-windows-per-episode", type=int, default=128)
|
| 62 |
+
parser.add_argument("--test-fraction", type=float, default=0.30)
|
| 63 |
+
parser.add_argument("--epochs", type=int, default=3)
|
| 64 |
+
parser.add_argument("--batch-size", type=int, default=32)
|
| 65 |
+
parser.add_argument("--hidden-dim", type=int, default=192)
|
| 66 |
+
parser.add_argument("--transformer-layers", type=int, default=1)
|
| 67 |
+
parser.add_argument("--learning-rate", type=float, default=2e-3)
|
| 68 |
+
parser.add_argument("--weight-decay", type=float, default=1e-3)
|
| 69 |
+
parser.add_argument("--seed", type=int, default=7)
|
| 70 |
+
parser.add_argument("--device", default="cuda", choices=["cuda", "cpu", "auto"])
|
| 71 |
+
parser.add_argument("--force-rebuild-cache", action="store_true")
|
| 72 |
+
parser.add_argument("--video-image-size", type=int, default=32)
|
| 73 |
+
parser.add_argument("--video-grid-size", type=int, default=8)
|
| 74 |
+
parser.add_argument("--video-hist-bins", type=int, default=8)
|
| 75 |
+
parser.add_argument("--depth-grid-size", type=int, default=8)
|
| 76 |
+
parser.add_argument("--text-hash-dim", type=int, default=128)
|
| 77 |
+
parser.add_argument("--include-label-text", action="store_true")
|
| 78 |
+
parser.add_argument(
|
| 79 |
+
"--skip-video-features",
|
| 80 |
+
action="store_true",
|
| 81 |
+
help="Do not decode MP4s for handcrafted visual features. The direct Qwen3 path is still recorded.",
|
| 82 |
+
)
|
| 83 |
+
return parser.parse_args()
|
| 84 |
+
|
| 85 |
+
|
| 86 |
+
def add_repo_imports(workspace: Path) -> None:
|
| 87 |
+
scripts = workspace / "scripts"
|
| 88 |
+
if str(scripts) not in sys.path:
|
| 89 |
+
sys.path.insert(0, str(scripts))
|
| 90 |
+
|
| 91 |
+
|
| 92 |
+
def add_toolkit_to_path(workspace: Path) -> None:
|
| 93 |
+
toolkit = workspace / "HOMIE-toolkit"
|
| 94 |
+
if not toolkit.exists():
|
| 95 |
+
raise FileNotFoundError(f"HOMIE-toolkit not found: {toolkit}")
|
| 96 |
+
if str(toolkit) not in sys.path:
|
| 97 |
+
sys.path.insert(0, str(toolkit))
|
| 98 |
+
|
| 99 |
+
|
| 100 |
+
def episode_dirs_from_args(args: argparse.Namespace) -> list[Path]:
|
| 101 |
+
episode_dirs: list[Path] = []
|
| 102 |
+
if args.episode_root:
|
| 103 |
+
episode_dirs.extend(path.expanduser().resolve() for path in args.episode_root)
|
| 104 |
+
if args.manifest:
|
| 105 |
+
payload = json.loads(args.manifest.read_text(encoding="utf-8"))
|
| 106 |
+
for ep in payload.get("episodes", []):
|
| 107 |
+
path = Path(ep["path"]).expanduser().resolve()
|
| 108 |
+
if path not in episode_dirs:
|
| 109 |
+
episode_dirs.append(path)
|
| 110 |
+
if not episode_dirs:
|
| 111 |
+
default = args.workspace / "data/sample/xperience-10m-sample"
|
| 112 |
+
episode_dirs.append(default.resolve())
|
| 113 |
+
return episode_dirs
|
| 114 |
+
|
| 115 |
+
|
| 116 |
+
@dataclass
|
| 117 |
+
class EpisodeDataset:
|
| 118 |
+
episode_id: str
|
| 119 |
+
X: np.ndarray
|
| 120 |
+
labels: np.ndarray
|
| 121 |
+
starts: np.ndarray
|
| 122 |
+
ends: np.ndarray
|
| 123 |
+
feature_manifest: list[dict]
|
| 124 |
+
available_modalities: list[dict]
|
| 125 |
+
|
| 126 |
+
|
| 127 |
+
def load_episode(args: argparse.Namespace, episode_dir: Path) -> EpisodeDataset:
|
| 128 |
+
from data_loader import load_from_annotation_hdf5
|
| 129 |
+
from train_all_modalities_model import build_feature_dataset, prepare_modalities, VIDEO_FILES
|
| 130 |
+
|
| 131 |
+
annotation = episode_dir / "annotation.hdf5"
|
| 132 |
+
if not annotation.exists():
|
| 133 |
+
raise FileNotFoundError(f"Missing annotation.hdf5: {annotation}")
|
| 134 |
+
|
| 135 |
+
ann = load_from_annotation_hdf5(annotation, 0, None, load_slam_point_cloud=True)
|
| 136 |
+
local_args = argparse.Namespace(**vars(args))
|
| 137 |
+
local_args.annotation = annotation
|
| 138 |
+
local_args.cache_dir = args.cache_dir / episode_dir.name
|
| 139 |
+
|
| 140 |
+
if args.skip_video_features:
|
| 141 |
+
original_video_files = VIDEO_FILES.copy()
|
| 142 |
+
VIDEO_FILES.clear()
|
| 143 |
+
try:
|
| 144 |
+
extras, available_modalities = prepare_modalities(local_args, ann)
|
| 145 |
+
finally:
|
| 146 |
+
VIDEO_FILES.clear()
|
| 147 |
+
VIDEO_FILES.update(original_video_files)
|
| 148 |
+
else:
|
| 149 |
+
extras, available_modalities = prepare_modalities(local_args, ann)
|
| 150 |
+
|
| 151 |
+
X, labels, starts, ends, _label_fracs, feature_manifest = build_feature_dataset(
|
| 152 |
+
ann,
|
| 153 |
+
extras,
|
| 154 |
+
target=args.target,
|
| 155 |
+
window_frames=args.window_frames,
|
| 156 |
+
stride_frames=args.stride_frames,
|
| 157 |
+
min_label_fraction=args.min_label_fraction,
|
| 158 |
+
)
|
| 159 |
+
if args.max_windows_per_episode > 0 and len(labels) > args.max_windows_per_episode:
|
| 160 |
+
keep = np.linspace(0, len(labels) - 1, args.max_windows_per_episode, dtype=np.int64)
|
| 161 |
+
X = X[keep]
|
| 162 |
+
labels = labels[keep]
|
| 163 |
+
starts = starts[keep]
|
| 164 |
+
ends = ends[keep]
|
| 165 |
+
return EpisodeDataset(
|
| 166 |
+
episode_id=episode_dir.name,
|
| 167 |
+
X=X.astype(np.float32),
|
| 168 |
+
labels=labels,
|
| 169 |
+
starts=starts,
|
| 170 |
+
ends=ends,
|
| 171 |
+
feature_manifest=feature_manifest,
|
| 172 |
+
available_modalities=available_modalities,
|
| 173 |
+
)
|
| 174 |
+
|
| 175 |
+
|
| 176 |
+
def align_feature_dims(episodes: list[EpisodeDataset]) -> tuple[np.ndarray, np.ndarray, np.ndarray, np.ndarray, list[dict]]:
|
| 177 |
+
max_dim = max(ep.X.shape[1] for ep in episodes)
|
| 178 |
+
Xs, labels, episode_ids, window_ids = [], [], [], []
|
| 179 |
+
for ep in episodes:
|
| 180 |
+
X = ep.X
|
| 181 |
+
if X.shape[1] < max_dim:
|
| 182 |
+
padded = np.zeros((X.shape[0], max_dim), dtype=np.float32)
|
| 183 |
+
padded[:, : X.shape[1]] = X
|
| 184 |
+
X = padded
|
| 185 |
+
Xs.append(X)
|
| 186 |
+
labels.extend([str(x) for x in ep.labels])
|
| 187 |
+
episode_ids.extend([ep.episode_id] * len(ep.labels))
|
| 188 |
+
window_ids.extend(range(len(ep.labels)))
|
| 189 |
+
manifest = max(episodes, key=lambda ep: ep.X.shape[1]).feature_manifest
|
| 190 |
+
return (
|
| 191 |
+
np.concatenate(Xs, axis=0).astype(np.float32),
|
| 192 |
+
np.asarray(labels, dtype=object),
|
| 193 |
+
np.asarray(episode_ids, dtype=object),
|
| 194 |
+
np.asarray(window_ids, dtype=np.int64),
|
| 195 |
+
manifest,
|
| 196 |
+
)
|
| 197 |
+
|
| 198 |
+
|
| 199 |
+
def encode_labels(labels: np.ndarray) -> tuple[np.ndarray, list[str]]:
|
| 200 |
+
seen = OrderedDict()
|
| 201 |
+
for label in labels:
|
| 202 |
+
if label not in seen:
|
| 203 |
+
seen[label] = len(seen)
|
| 204 |
+
return np.asarray([seen[label] for label in labels], dtype=np.int64), list(seen.keys())
|
| 205 |
+
|
| 206 |
+
|
| 207 |
+
def split_indices(episode_ids: np.ndarray, labels: np.ndarray, test_fraction: float, seed: int) -> tuple[np.ndarray, np.ndarray, str]:
|
| 208 |
+
unique_episodes = np.unique(episode_ids)
|
| 209 |
+
if len(unique_episodes) >= 2:
|
| 210 |
+
n_test = max(1, int(round(len(unique_episodes) * test_fraction)))
|
| 211 |
+
heldout = set(unique_episodes[-n_test:].tolist())
|
| 212 |
+
test = np.asarray([i for i, ep in enumerate(episode_ids) if ep in heldout], dtype=np.int64)
|
| 213 |
+
train = np.asarray([i for i, ep in enumerate(episode_ids) if ep not in heldout], dtype=np.int64)
|
| 214 |
+
return train, test, "held_out_episode"
|
| 215 |
+
|
| 216 |
+
# Single-episode smoke: use a chronological split, not shuffled windows.
|
| 217 |
+
n = len(labels)
|
| 218 |
+
cut = max(1, min(n - 1, int(round(n * (1.0 - test_fraction)))))
|
| 219 |
+
return np.arange(cut, dtype=np.int64), np.arange(cut, n, dtype=np.int64), "single_episode_chronological"
|
| 220 |
+
|
| 221 |
+
|
| 222 |
+
def block_slices(feature_manifest: list[dict], input_dim: int) -> list[tuple[str, int, int]]:
|
| 223 |
+
slices = []
|
| 224 |
+
for block in feature_manifest:
|
| 225 |
+
start = int(block["start"])
|
| 226 |
+
end = min(int(block["end"]), input_dim)
|
| 227 |
+
if start < end:
|
| 228 |
+
slices.append((str(block["name"]), start, end))
|
| 229 |
+
if not slices:
|
| 230 |
+
slices.append(("all_features", 0, input_dim))
|
| 231 |
+
return slices
|
| 232 |
+
|
| 233 |
+
|
| 234 |
+
def macro_f1(y_true: np.ndarray, y_pred: np.ndarray, n_classes: int) -> tuple[float, list[dict], np.ndarray]:
|
| 235 |
+
cm = np.zeros((n_classes, n_classes), dtype=np.int64)
|
| 236 |
+
for t, p in zip(y_true, y_pred):
|
| 237 |
+
cm[int(t), int(p)] += 1
|
| 238 |
+
rows = []
|
| 239 |
+
f1s = []
|
| 240 |
+
for idx in range(n_classes):
|
| 241 |
+
tp = float(cm[idx, idx])
|
| 242 |
+
fp = float(cm[:, idx].sum() - cm[idx, idx])
|
| 243 |
+
fn = float(cm[idx, :].sum() - cm[idx, idx])
|
| 244 |
+
precision = tp / (tp + fp) if tp + fp else 0.0
|
| 245 |
+
recall = tp / (tp + fn) if tp + fn else 0.0
|
| 246 |
+
f1 = 2.0 * precision * recall / (precision + recall) if precision + recall else 0.0
|
| 247 |
+
f1s.append(f1)
|
| 248 |
+
rows.append({
|
| 249 |
+
"class_id": idx,
|
| 250 |
+
"support": int(cm[idx, :].sum()),
|
| 251 |
+
"predicted": int(cm[:, idx].sum()),
|
| 252 |
+
"precision": precision,
|
| 253 |
+
"recall": recall,
|
| 254 |
+
"f1": f1,
|
| 255 |
+
})
|
| 256 |
+
return float(np.mean(f1s)) if f1s else 0.0, rows, cm
|
| 257 |
+
|
| 258 |
+
|
| 259 |
+
def write_csv(path: Path, rows: list[dict], fieldnames: list[str]) -> None:
|
| 260 |
+
path.parent.mkdir(parents=True, exist_ok=True)
|
| 261 |
+
with path.open("w", newline="", encoding="utf-8") as fp:
|
| 262 |
+
writer = csv.DictWriter(fp, fieldnames=fieldnames)
|
| 263 |
+
writer.writeheader()
|
| 264 |
+
writer.writerows(rows)
|
| 265 |
+
|
| 266 |
+
|
| 267 |
+
def train_adapter_model(
|
| 268 |
+
X: np.ndarray,
|
| 269 |
+
y: np.ndarray,
|
| 270 |
+
train_idx: np.ndarray,
|
| 271 |
+
test_idx: np.ndarray,
|
| 272 |
+
blocks: list[tuple[str, int, int]],
|
| 273 |
+
args: argparse.Namespace,
|
| 274 |
+
) -> tuple[dict, np.ndarray, list[dict]]:
|
| 275 |
+
import torch
|
| 276 |
+
import torch.nn as nn
|
| 277 |
+
import torch.nn.functional as F
|
| 278 |
+
|
| 279 |
+
class SensorAdapterClassifier(nn.Module):
|
| 280 |
+
def __init__(self, block_specs: list[tuple[str, int, int]], hidden_dim: int, n_classes: int, n_layers: int):
|
| 281 |
+
super().__init__()
|
| 282 |
+
self.block_specs = block_specs
|
| 283 |
+
self.adapters = nn.ModuleList([
|
| 284 |
+
nn.Sequential(
|
| 285 |
+
nn.LayerNorm(end - start),
|
| 286 |
+
nn.Linear(end - start, hidden_dim),
|
| 287 |
+
nn.GELU(),
|
| 288 |
+
nn.Linear(hidden_dim, hidden_dim),
|
| 289 |
+
)
|
| 290 |
+
for _name, start, end in block_specs
|
| 291 |
+
])
|
| 292 |
+
self.type_embedding = nn.Parameter(torch.randn(len(block_specs), hidden_dim) * 0.02)
|
| 293 |
+
layer = nn.TransformerEncoderLayer(
|
| 294 |
+
d_model=hidden_dim,
|
| 295 |
+
nhead=max(1, min(8, hidden_dim // 32)),
|
| 296 |
+
dim_feedforward=hidden_dim * 4,
|
| 297 |
+
dropout=0.10,
|
| 298 |
+
batch_first=True,
|
| 299 |
+
activation="gelu",
|
| 300 |
+
norm_first=True,
|
| 301 |
+
)
|
| 302 |
+
self.fusion = nn.TransformerEncoder(layer, num_layers=n_layers)
|
| 303 |
+
self.head = nn.Sequential(nn.LayerNorm(hidden_dim), nn.Linear(hidden_dim, n_classes))
|
| 304 |
+
|
| 305 |
+
def forward(self, features: torch.Tensor) -> torch.Tensor:
|
| 306 |
+
tokens = []
|
| 307 |
+
for adapter, (_name, start, end) in zip(self.adapters, self.block_specs):
|
| 308 |
+
tokens.append(adapter(features[:, start:end]))
|
| 309 |
+
x = torch.stack(tokens, dim=1) + self.type_embedding.unsqueeze(0)
|
| 310 |
+
x = self.fusion(x)
|
| 311 |
+
pooled = x.mean(dim=1)
|
| 312 |
+
return self.head(pooled)
|
| 313 |
+
|
| 314 |
+
if args.device == "auto":
|
| 315 |
+
device = torch.device("cuda" if torch.cuda.is_available() else "cpu")
|
| 316 |
+
elif args.device == "cuda" and not torch.cuda.is_available():
|
| 317 |
+
device = torch.device("cpu")
|
| 318 |
+
else:
|
| 319 |
+
device = torch.device(args.device)
|
| 320 |
+
|
| 321 |
+
torch.manual_seed(args.seed)
|
| 322 |
+
X_mean = X[train_idx].mean(axis=0, keepdims=True)
|
| 323 |
+
X_std = X[train_idx].std(axis=0, keepdims=True)
|
| 324 |
+
X_std[X_std < 1e-6] = 1.0
|
| 325 |
+
Xs = (X - X_mean) / X_std
|
| 326 |
+
|
| 327 |
+
x_tensor = torch.from_numpy(Xs.astype(np.float32))
|
| 328 |
+
y_tensor = torch.from_numpy(y.astype(np.int64))
|
| 329 |
+
train_tensor = torch.from_numpy(train_idx.astype(np.int64))
|
| 330 |
+
test_tensor = torch.from_numpy(test_idx.astype(np.int64))
|
| 331 |
+
|
| 332 |
+
n_classes = int(y.max()) + 1
|
| 333 |
+
model = SensorAdapterClassifier(blocks, args.hidden_dim, n_classes, args.transformer_layers).to(device)
|
| 334 |
+
counts = np.bincount(y[train_idx], minlength=n_classes).astype(np.float32)
|
| 335 |
+
weights = counts.sum() / np.maximum(counts, 1.0)
|
| 336 |
+
weights = weights / weights.mean()
|
| 337 |
+
class_weights = torch.from_numpy(weights.astype(np.float32)).to(device)
|
| 338 |
+
opt = torch.optim.AdamW(model.parameters(), lr=args.learning_rate, weight_decay=args.weight_decay)
|
| 339 |
+
|
| 340 |
+
history = []
|
| 341 |
+
gen = torch.Generator()
|
| 342 |
+
gen.manual_seed(args.seed)
|
| 343 |
+
for epoch in range(1, args.epochs + 1):
|
| 344 |
+
perm = train_tensor[torch.randperm(len(train_tensor), generator=gen)]
|
| 345 |
+
total_loss = 0.0
|
| 346 |
+
correct = 0
|
| 347 |
+
seen = 0
|
| 348 |
+
model.train()
|
| 349 |
+
for start in range(0, len(perm), args.batch_size):
|
| 350 |
+
idx = perm[start : start + args.batch_size]
|
| 351 |
+
xb = x_tensor[idx].to(device)
|
| 352 |
+
yb = y_tensor[idx].to(device)
|
| 353 |
+
logits = model(xb)
|
| 354 |
+
loss = F.cross_entropy(logits, yb, weight=class_weights)
|
| 355 |
+
opt.zero_grad(set_to_none=True)
|
| 356 |
+
loss.backward()
|
| 357 |
+
opt.step()
|
| 358 |
+
total_loss += float(loss.detach().cpu()) * len(idx)
|
| 359 |
+
pred = logits.argmax(dim=1)
|
| 360 |
+
correct += int((pred == yb).sum().detach().cpu())
|
| 361 |
+
seen += len(idx)
|
| 362 |
+
history.append({"epoch": epoch, "loss": total_loss / max(seen, 1), "train_accuracy": correct / max(seen, 1)})
|
| 363 |
+
|
| 364 |
+
model.eval()
|
| 365 |
+
with torch.no_grad():
|
| 366 |
+
logits = []
|
| 367 |
+
for start in range(0, len(test_tensor), args.batch_size):
|
| 368 |
+
idx = test_tensor[start : start + args.batch_size]
|
| 369 |
+
logits.append(model(x_tensor[idx].to(device)).detach().cpu())
|
| 370 |
+
test_logits = torch.cat(logits, dim=0)
|
| 371 |
+
probs = torch.softmax(test_logits, dim=1).numpy()
|
| 372 |
+
pred = probs.argmax(axis=1).astype(np.int64)
|
| 373 |
+
|
| 374 |
+
artifact = {
|
| 375 |
+
"model_state": model.state_dict(),
|
| 376 |
+
"feature_mean": X_mean.astype(np.float32),
|
| 377 |
+
"feature_std": X_std.astype(np.float32),
|
| 378 |
+
"blocks": blocks,
|
| 379 |
+
"history": history,
|
| 380 |
+
}
|
| 381 |
+
return artifact, pred, history
|
| 382 |
+
|
| 383 |
+
|
| 384 |
+
def main() -> int:
|
| 385 |
+
args = parse_args()
|
| 386 |
+
args.workspace = args.workspace.expanduser().resolve()
|
| 387 |
+
args.output_dir.mkdir(parents=True, exist_ok=True)
|
| 388 |
+
args.cache_dir.mkdir(parents=True, exist_ok=True)
|
| 389 |
+
add_repo_imports(args.workspace)
|
| 390 |
+
add_toolkit_to_path(args.workspace)
|
| 391 |
+
|
| 392 |
+
episode_dirs = episode_dirs_from_args(args)
|
| 393 |
+
episodes = [load_episode(args, path) for path in episode_dirs]
|
| 394 |
+
X, labels, episode_ids, window_ids, feature_manifest = align_feature_dims(episodes)
|
| 395 |
+
y, class_names = encode_labels(labels)
|
| 396 |
+
train_idx, test_idx, split_name = split_indices(episode_ids, labels, args.test_fraction, args.seed)
|
| 397 |
+
if len(train_idx) == 0 or len(test_idx) == 0:
|
| 398 |
+
raise ValueError("Need non-empty train and test splits.")
|
| 399 |
+
blocks = block_slices(feature_manifest, X.shape[1])
|
| 400 |
+
|
| 401 |
+
artifact, pred, history = train_adapter_model(X, y, train_idx, test_idx, blocks, args)
|
| 402 |
+
y_test = y[test_idx]
|
| 403 |
+
accuracy = float(np.mean(pred == y_test))
|
| 404 |
+
macro, per_class, cm = macro_f1(y_test, pred, len(class_names))
|
| 405 |
+
for row in per_class:
|
| 406 |
+
row["class_name"] = class_names[int(row["class_id"])]
|
| 407 |
+
|
| 408 |
+
import torch
|
| 409 |
+
|
| 410 |
+
model_path = args.output_dir / "sensor_adapter_model.pt"
|
| 411 |
+
torch.save(artifact, model_path)
|
| 412 |
+
|
| 413 |
+
prediction_rows = []
|
| 414 |
+
for local_pos, pred_id in enumerate(pred):
|
| 415 |
+
absolute_idx = int(test_idx[local_pos])
|
| 416 |
+
true_id = int(y[absolute_idx])
|
| 417 |
+
prediction_rows.append({
|
| 418 |
+
"sample_index": absolute_idx,
|
| 419 |
+
"episode_id": str(episode_ids[absolute_idx]),
|
| 420 |
+
"window_id": int(window_ids[absolute_idx]),
|
| 421 |
+
"true_label": class_names[true_id],
|
| 422 |
+
"predicted_label": class_names[int(pred_id)],
|
| 423 |
+
"correct": int(true_id == int(pred_id)),
|
| 424 |
+
})
|
| 425 |
+
|
| 426 |
+
metrics = {
|
| 427 |
+
"task": f"qwen3_omni_sensor_adapter_smoke_{args.target}",
|
| 428 |
+
"base_model_target": args.base_model_id,
|
| 429 |
+
"qwen3_loaded": False,
|
| 430 |
+
"qwen3_note": "This run validates Xperience-10M sensor-adapter tokens and task heads before loading or LoRA-tuning Qwen3-Omni.",
|
| 431 |
+
"split": split_name,
|
| 432 |
+
"num_episodes": len(episodes),
|
| 433 |
+
"num_windows": int(len(labels)),
|
| 434 |
+
"num_train_windows": int(len(train_idx)),
|
| 435 |
+
"num_test_windows": int(len(test_idx)),
|
| 436 |
+
"num_classes": int(len(class_names)),
|
| 437 |
+
"feature_dim": int(X.shape[1]),
|
| 438 |
+
"num_adapter_tokens": int(len(blocks)),
|
| 439 |
+
"accuracy": accuracy,
|
| 440 |
+
"macro_f1": macro,
|
| 441 |
+
"train_final_loss": float(history[-1]["loss"]),
|
| 442 |
+
"train_final_accuracy": float(history[-1]["train_accuracy"]),
|
| 443 |
+
"direct_qwen3_inputs": DIRECT_QWEN3_INPUTS,
|
| 444 |
+
"adapter_required_inputs": ADAPTER_INPUTS,
|
| 445 |
+
}
|
| 446 |
+
|
| 447 |
+
(args.output_dir / "metrics.json").write_text(json.dumps(metrics, indent=2), encoding="utf-8")
|
| 448 |
+
(args.output_dir / "feature_manifest.json").write_text(json.dumps(feature_manifest, indent=2), encoding="utf-8")
|
| 449 |
+
(args.output_dir / "adapter_blocks.json").write_text(
|
| 450 |
+
json.dumps([{"name": name, "start": start, "end": end, "dim": end - start} for name, start, end in blocks], indent=2),
|
| 451 |
+
encoding="utf-8",
|
| 452 |
+
)
|
| 453 |
+
(args.output_dir / "available_modalities.json").write_text(
|
| 454 |
+
json.dumps([{"episode_id": ep.episode_id, "modalities": ep.available_modalities} for ep in episodes], indent=2),
|
| 455 |
+
encoding="utf-8",
|
| 456 |
+
)
|
| 457 |
+
write_csv(args.output_dir / "predictions.csv", prediction_rows, ["sample_index", "episode_id", "window_id", "true_label", "predicted_label", "correct"])
|
| 458 |
+
write_csv(
|
| 459 |
+
args.output_dir / "per_class_metrics.csv",
|
| 460 |
+
per_class,
|
| 461 |
+
["class_id", "class_name", "support", "predicted", "precision", "recall", "f1"],
|
| 462 |
+
)
|
| 463 |
+
with (args.output_dir / "confusion_matrix.csv").open("w", newline="", encoding="utf-8") as fp:
|
| 464 |
+
writer = csv.writer(fp)
|
| 465 |
+
writer.writerow(["true\\pred"] + class_names)
|
| 466 |
+
for i, name in enumerate(class_names):
|
| 467 |
+
writer.writerow([name] + [int(x) for x in cm[i]])
|
| 468 |
+
|
| 469 |
+
report = [
|
| 470 |
+
"# Qwen3-Omni Adapter Smoke Test",
|
| 471 |
+
"",
|
| 472 |
+
f"- Base model target: `{args.base_model_id}`",
|
| 473 |
+
"- Qwen3-Omni weights loaded: `false`",
|
| 474 |
+
f"- Episodes: `{len(episodes)}`",
|
| 475 |
+
f"- Windows: `{len(labels)}` total, `{len(train_idx)}` train, `{len(test_idx)}` test",
|
| 476 |
+
f"- Split: `{split_name}`",
|
| 477 |
+
f"- Feature dimension: `{X.shape[1]}`",
|
| 478 |
+
f"- Adapter soft-token blocks: `{len(blocks)}`",
|
| 479 |
+
f"- Accuracy: `{accuracy:.4f}`",
|
| 480 |
+
f"- Macro-F1: `{macro:.4f}`",
|
| 481 |
+
"",
|
| 482 |
+
"## Why this is the minimum real test",
|
| 483 |
+
"",
|
| 484 |
+
"This run uses real Ropedia annotation/video-derived feature blocks. It tests the sensor-adapter side that depth, pose, mocap, contacts, and IMU need before those tokens are attached to Qwen3-Omni. It deliberately avoids downloading the 30B Qwen3-Omni weights until the data path, labels, splits, and storage plan are confirmed.",
|
| 485 |
+
]
|
| 486 |
+
(args.output_dir / "RUN_REPORT.md").write_text("\n".join(report) + "\n", encoding="utf-8")
|
| 487 |
+
print(json.dumps(metrics, indent=2))
|
| 488 |
+
print(f"Wrote {args.output_dir}")
|
| 489 |
+
return 0
|
| 490 |
+
|
| 491 |
+
|
| 492 |
+
if __name__ == "__main__":
|
| 493 |
+
raise SystemExit(main())
|
scripts/omni/qwen3_omni_next_steps.md
ADDED
|
@@ -0,0 +1,20 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Qwen3-Omni Exploration Notes
|
| 2 |
+
|
| 3 |
+
This directory separates the concrete Qwen3-Omni plan into two layers.
|
| 4 |
+
|
| 5 |
+
1. Native Qwen3-Omni inputs: RGB/fisheye video, embedded audio, and text prompts.
|
| 6 |
+
2. Xperience-10M sensor adapter inputs: depth, pose/SLAM, mocap, contacts, and IMU.
|
| 7 |
+
|
| 8 |
+
`qwen3_omni_adapter_smoke.py` validates the second layer first using real
|
| 9 |
+
episode windows and real labels. It does not fabricate Qwen outputs and does not
|
| 10 |
+
claim Qwen3-Omni was fine-tuned. Once multiple episodes are available and the
|
| 11 |
+
storage budget is clear, the next step is to attach the saved adapter tokens to
|
| 12 |
+
Qwen3-Omni through LoRA or a cross-attention memory bridge.
|
| 13 |
+
|
| 14 |
+
Suggested progression:
|
| 15 |
+
|
| 16 |
+
1. Run the adapter smoke test on one public sample episode.
|
| 17 |
+
2. Add a small manifest of additional episodes, capped by storage.
|
| 18 |
+
3. Hold out whole episodes for evaluation.
|
| 19 |
+
4. Load Qwen3-Omni processor/model on H20 only after data flow is verified.
|
| 20 |
+
5. Train sensor adapters first, then LoRA selected Qwen3-Omni layers.
|
scripts/render_overview_figures.py
CHANGED
|
@@ -356,7 +356,7 @@ def build_pipeline_html(summary: dict, base_path: Path) -> str:
|
|
| 356 |
<header>
|
| 357 |
<div>
|
| 358 |
<div class="kicker">verified single-episode pipeline</div>
|
| 359 |
-
<h1>From
|
| 360 |
<p class="subtitle">The figure follows the actual code path and separates the full Xperience-10M sample modalities from the current baseline feature manifest.</p>
|
| 361 |
</div>
|
| 362 |
<div class="metrics">
|
|
@@ -694,7 +694,7 @@ def build_architecture_html(summary: dict, base_path: Path) -> str:
|
|
| 694 |
<header>
|
| 695 |
<div>
|
| 696 |
<div class="kicker">minimal verified model architectures</div>
|
| 697 |
-
<h1>12
|
| 698 |
<p class="subtitle">Each task uses the same aligned episode-window contract, then swaps only the minimal output head needed for labels, forecasting, grounding, reconstruction, or temporal diagnostics.</p>
|
| 699 |
</div>
|
| 700 |
<div class="summary-pill"><strong>{len(suite['tasks'])}</strong><span>end-to-end tasks</span></div>
|
|
|
|
| 356 |
<header>
|
| 357 |
<div>
|
| 358 |
<div class="kicker">verified single-episode pipeline</div>
|
| 359 |
+
<h1>From Xperience-10M episode to reproducible artifacts</h1>
|
| 360 |
<p class="subtitle">The figure follows the actual code path and separates the full Xperience-10M sample modalities from the current baseline feature manifest.</p>
|
| 361 |
</div>
|
| 362 |
<div class="metrics">
|
|
|
|
| 694 |
<header>
|
| 695 |
<div>
|
| 696 |
<div class="kicker">minimal verified model architectures</div>
|
| 697 |
+
<h1>12 Xperience-10M episode tasks, four reusable heads</h1>
|
| 698 |
<p class="subtitle">Each task uses the same aligned episode-window contract, then swaps only the minimal output head needed for labels, forecasting, grounding, reconstruction, or temporal diagnostics.</p>
|
| 699 |
</div>
|
| 700 |
<div class="summary-pill"><strong>{len(suite['tasks'])}</strong><span>end-to-end tasks</span></div>
|
scripts/render_task_suite_infographic.py
CHANGED
|
@@ -1,6 +1,6 @@
|
|
| 1 |
#!/usr/bin/env python3
|
| 2 |
"""
|
| 3 |
-
Render a polished 12-task
|
| 4 |
|
| 5 |
The task names, inputs, and metrics are read from
|
| 6 |
results/episode_task_suite/summary_report.json. The output is a deterministic
|
|
@@ -550,7 +550,7 @@ def build_html(summary: dict, base_image: Path | None, sample_dir: Path | None)
|
|
| 550 |
<head>
|
| 551 |
<meta charset="utf-8">
|
| 552 |
<meta name="viewport" content="width={CANVAS_WIDTH}, initial-scale=1">
|
| 553 |
-
<title>
|
| 554 |
<style>
|
| 555 |
* {{ box-sizing: border-box; }}
|
| 556 |
html,
|
|
@@ -897,13 +897,13 @@ def build_html(summary: dict, base_image: Path | None, sample_dir: Path | None)
|
|
| 897 |
</style>
|
| 898 |
</head>
|
| 899 |
<body>
|
| 900 |
-
<main class="canvas" aria-label="
|
| 901 |
{base_layer}
|
| 902 |
<div class="content">
|
| 903 |
<header class="header">
|
| 904 |
<div>
|
| 905 |
<div class="kicker">verified single-episode task suite</div>
|
| 906 |
-
<h1>
|
| 907 |
<p class="subtitle">A clean map from synchronized multimodal windows to 12 auditable task heads, with metrics loaded from the committed summary report.</p>
|
| 908 |
</div>
|
| 909 |
<div class="stats">{stats_html}</div>
|
|
|
|
| 1 |
#!/usr/bin/env python3
|
| 2 |
"""
|
| 3 |
+
Render a polished 12-task Xperience-10M episode-suite infographic.
|
| 4 |
|
| 5 |
The task names, inputs, and metrics are read from
|
| 6 |
results/episode_task_suite/summary_report.json. The output is a deterministic
|
|
|
|
| 550 |
<head>
|
| 551 |
<meta charset="utf-8">
|
| 552 |
<meta name="viewport" content="width={CANVAS_WIDTH}, initial-scale=1">
|
| 553 |
+
<title>Xperience-10M 12-Task Episode Suite Infographic</title>
|
| 554 |
<style>
|
| 555 |
* {{ box-sizing: border-box; }}
|
| 556 |
html,
|
|
|
|
| 897 |
</style>
|
| 898 |
</head>
|
| 899 |
<body>
|
| 900 |
+
<main class="canvas" aria-label="Xperience-10M 12-task episode suite infographic">
|
| 901 |
{base_layer}
|
| 902 |
<div class="content">
|
| 903 |
<header class="header">
|
| 904 |
<div>
|
| 905 |
<div class="kicker">verified single-episode task suite</div>
|
| 906 |
+
<h1>Xperience-10M 12-task episode suite</h1>
|
| 907 |
<p class="subtitle">A clean map from synchronized multimodal windows to 12 auditable task heads, with metrics loaded from the committed summary report.</p>
|
| 908 |
</div>
|
| 909 |
<div class="stats">{stats_html}</div>
|
scripts/train_all_modalities_model.py
CHANGED
|
@@ -1,6 +1,6 @@
|
|
| 1 |
#!/usr/bin/env python3
|
| 2 |
"""
|
| 3 |
-
All-modality lightweight baseline for
|
| 4 |
|
| 5 |
This intentionally stays small enough for a MacBook:
|
| 6 |
- no deep video training
|
|
|
|
| 1 |
#!/usr/bin/env python3
|
| 2 |
"""
|
| 3 |
+
All-modality lightweight baseline for an Xperience-10M episode.
|
| 4 |
|
| 5 |
This intentionally stays small enough for a MacBook:
|
| 6 |
- no deep video training
|
scripts/train_min_action_model.py
CHANGED
|
@@ -1,6 +1,6 @@
|
|
| 1 |
#!/usr/bin/env python3
|
| 2 |
"""
|
| 3 |
-
Minimal end-to-end action-recognition pipeline for
|
| 4 |
|
| 5 |
Input:
|
| 6 |
annotation.hdf5
|
|
|
|
| 1 |
#!/usr/bin/env python3
|
| 2 |
"""
|
| 3 |
+
Minimal end-to-end action-recognition pipeline for an Xperience-10M episode.
|
| 4 |
|
| 5 |
Input:
|
| 6 |
annotation.hdf5
|