
Datasets:

Polish the dataset card, declare the six splits, and license under MIT
Browse filesDeclare train/val/test_id/test_app/test_theme/test_resolution (WebDataset) as the default config, add a transitions config, keep the preview. MIT license. Remove host, path and personal details from the docs and provenance.
- LICENSE +17 -14
- README.md +145 -125
- docs/known_issues.md +10 -11
- release_provenance.json +2 -4
LICENSE
CHANGED
|
@@ -1,18 +1,21 @@
|
|
| 1 |
-
|
| 2 |
-
=========================================
|
| 3 |
|
| 4 |
-
|
| 5 |
-
redistribution.
|
| 6 |
|
| 7 |
-
|
| 8 |
-
|
| 9 |
-
|
| 10 |
-
|
| 11 |
-
|
|
|
|
| 12 |
|
| 13 |
-
|
| 14 |
-
|
| 15 |
|
| 16 |
-
|
| 17 |
-
|
| 18 |
-
|
|
|
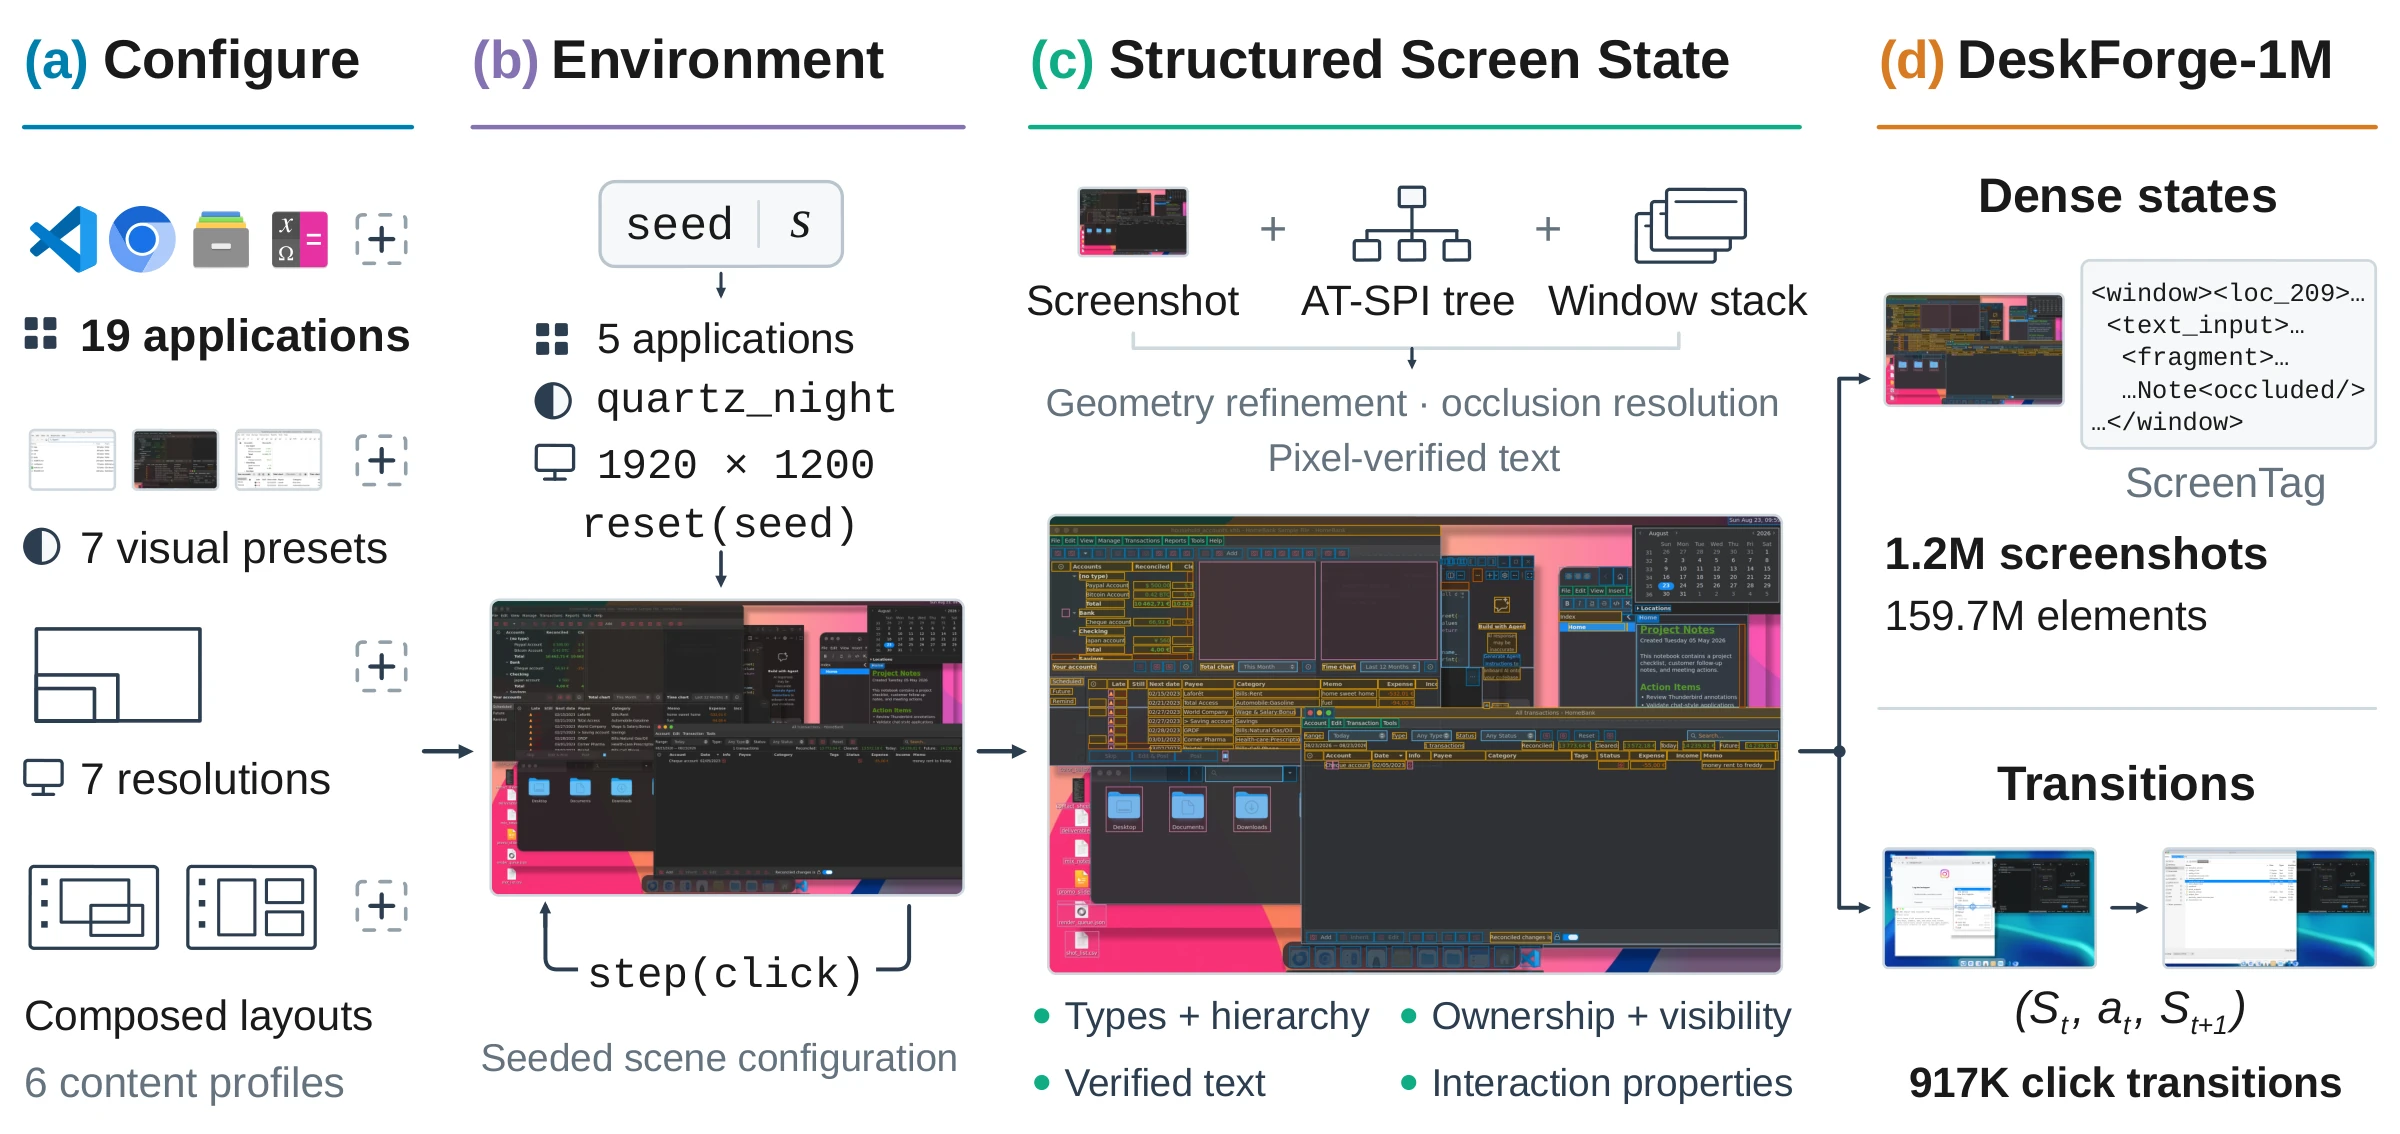
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
MIT License
|
|
|
|
| 2 |
|
| 3 |
+
Copyright (c) 2026 The DeskForge authors
|
|
|
|
| 4 |
|
| 5 |
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
| 6 |
+
of this software and associated documentation files (the "Software"), to deal
|
| 7 |
+
in the Software without restriction, including without limitation the rights
|
| 8 |
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
| 9 |
+
copies of the Software, and to permit persons to whom the Software is
|
| 10 |
+
furnished to do so, subject to the following conditions:
|
| 11 |
|
| 12 |
+
The above copyright notice and this permission notice shall be included in all
|
| 13 |
+
copies or substantial portions of the Software.
|
| 14 |
|
| 15 |
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
| 16 |
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
| 17 |
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
| 18 |
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
| 19 |
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
| 20 |
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
| 21 |
+
SOFTWARE.
|
README.md
CHANGED
|
@@ -1,7 +1,6 @@
|
|
| 1 |
---
|
| 2 |
pretty_name: DeskForge-1M
|
| 3 |
-
license:
|
| 4 |
-
license_name: license-pending-review
|
| 5 |
task_categories:
|
| 6 |
- image-to-text
|
| 7 |
- object-detection
|
|
@@ -9,13 +8,44 @@ language:
|
|
| 9 |
- en
|
| 10 |
tags:
|
| 11 |
- gui
|
| 12 |
-
-
|
|
|
|
| 13 |
- computer-use
|
|
|
|
| 14 |
- accessibility
|
| 15 |
- webdataset
|
| 16 |
size_categories:
|
| 17 |
- 1M<n<10M
|
| 18 |
configs:
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 19 |
- config_name: preview
|
| 20 |
data_files:
|
| 21 |
- split: preview
|
|
@@ -24,153 +54,143 @@ configs:
|
|
| 24 |
|
| 25 |
# DeskForge-1M
|
| 26 |
|
| 27 |
-
**1
|
| 28 |
-
|
| 29 |
-
|
| 30 |
-
|
| 31 |
-
|
| 32 |
-
|
| 33 |
-
|
| 34 |
-
|
| 35 |
-
|
| 36 |
-
|
| 37 |
-
|
| 38 |
-
|
| 39 |
-
|
| 40 |
-
|
| 41 |
-
|
| 42 |
-
|
| 43 |
-
|
| 44 |
-
|
| 45 |
-
|
| 46 |
-
|
| 47 |
-
|
| 48 |
-
|
| 49 |
-
|
| 50 |
-
|
| 51 |
-
|
| 52 |
-
|
| 53 |
-
|
| 54 |
-
|
| 55 |
-
|
| 56 |
-
|
| 57 |
-
|
| 58 |
-
|
| 59 |
-
##
|
| 60 |
-
|
| 61 |
-
|
| 62 |
-
|
| 63 |
-
|
| 64 |
-
|
| 65 |
-
|
|
| 66 |
-
| --- | --- | --- |
|
| 67 |
-
| `
|
| 68 |
-
|
|
| 69 |
-
| `
|
| 70 |
-
| `
|
| 71 |
-
|
| 72 |
-
|
| 73 |
-
|
| 74 |
-
|
| 75 |
-
|
| 76 |
-
|
| 77 |
-
|
| 78 |
-
|
| 79 |
-
|
| 80 |
-
|
| 81 |
-
|
| 82 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 83 |
|
| 84 |
## Loading
|
| 85 |
|
| 86 |
-
Payload is WebDataset; the indexes are Parquet. No custom loader script.
|
| 87 |
-
|
| 88 |
```python
|
| 89 |
-
|
| 90 |
-
url = "data/train/part-{00000..00903}.tar"
|
| 91 |
-
ds = (wds.WebDataset(url, shardshuffle=True)
|
| 92 |
-
.decode("pil")
|
| 93 |
-
.to_tuple("png", "leaf.json", "screentag.txt", "record.json"))
|
| 94 |
-
```
|
| 95 |
|
| 96 |
-
|
|
|
|
|
|
|
|
|
|
| 97 |
|
| 98 |
-
|
| 99 |
-
|
| 100 |
-
<key>.leaf.json every visible element
|
| 101 |
-
<key>.screentag.txt the serialized markup a model is trained to emit
|
| 102 |
-
<key>.record.json sanitized metadata, and the action that produced this state
|
| 103 |
```
|
| 104 |
|
| 105 |
-
|
| 106 |
-
|
| 107 |
-
|
| 108 |
-
transitions, and random access by key. `demo/preview.parquet` is a stratified
|
| 109 |
-
sample with images inline for the Dataset Viewer. Its images are **downscaled to
|
| 110 |
-
1024 px on the long edge** so the viewer stays responsive - the canonical
|
| 111 |
-
full-resolution PNGs are in `data/`. ScreenTag coordinates are on a 0-500 grid
|
| 112 |
-
normalized to the viewport, so they still describe the resized image, and each
|
| 113 |
-
row keeps the original `width` and `height`.
|
| 114 |
-
|
| 115 |
-
Filter before you stream, with Parquet:
|
| 116 |
|
| 117 |
```python
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 118 |
import pyarrow.parquet as pq
|
| 119 |
obs = pq.read_table("index/observations/test_id.parquet")
|
| 120 |
-
|
| 121 |
```
|
| 122 |
|
| 123 |
-
|
| 124 |
-
|
| 125 |
-
Xvfb + xfwm4 on Linux, real GTK applications driven headlessly. Annotations come
|
| 126 |
-
from the AT-SPI2 accessibility tree, then are resolved against the window stack
|
| 127 |
-
so a box describes what is *visible*, not what the tree claims. Generation is
|
| 128 |
-
deterministic from a seed; the generating commit and the SHA-256 of both source
|
| 129 |
-
manifests are in `release_provenance.json`, and `checksums/sha256sums.txt`
|
| 130 |
-
covers every published file.
|
| 131 |
-
|
| 132 |
-
Labels are **automatic**, not human. Quality is enforced by automated audits —
|
| 133 |
-
element coverage against rendered pixels, blank-widget suppression, leaf/window
|
| 134 |
-
ownership, fragment containment — and 59,103 observations that failed them are
|
| 135 |
-
not in this release.
|
| 136 |
|
| 137 |
-
|
|
|
|
|
|
|
|
|
|
| 138 |
|
| 139 |
-
|
| 140 |
-
demonstrations, not goal-conditioned trajectories, and carry no task
|
| 141 |
-
instruction, reward or success label. The action space is **click only**.
|
| 142 |
|
| 143 |
-
|
| 144 |
-
|
| 145 |
-
|
| 146 |
-
|
|
|
|
| 147 |
|
| 148 |
## Limitations
|
| 149 |
|
| 150 |
-
|
| 151 |
-
|
| 152 |
-
|
| 153 |
-
|
| 154 |
-
|
| 155 |
-
|
| 156 |
-
`docs/known_issues.md`. No host path appears in any constructed metadata
|
| 157 |
-
record; that is enforced at pack time. Some scenes load live web pages, so a browser window
|
| 158 |
-
shows whatever that site served on the capture date; the domain is recorded.
|
| 159 |
-
Read `docs/known_issues.md` before using this for anything load-bearing.
|
| 160 |
|
| 161 |
-
##
|
| 162 |
|
| 163 |
-
|
| 164 |
-
|
| 165 |
-
|
| 166 |
|
| 167 |
## Citation
|
| 168 |
|
| 169 |
```bibtex
|
| 170 |
-
@
|
| 171 |
-
title
|
| 172 |
-
|
| 173 |
-
|
| 174 |
-
|
|
|
|
|
|
|
| 175 |
}
|
| 176 |
```
|
|
|
|
| 1 |
---
|
| 2 |
pretty_name: DeskForge-1M
|
| 3 |
+
license: mit
|
|
|
|
| 4 |
task_categories:
|
| 5 |
- image-to-text
|
| 6 |
- object-detection
|
|
|
|
| 8 |
- en
|
| 9 |
tags:
|
| 10 |
- gui
|
| 11 |
+
- gui-grounding
|
| 12 |
+
- screen-parsing
|
| 13 |
- computer-use
|
| 14 |
+
- desktop
|
| 15 |
- accessibility
|
| 16 |
- webdataset
|
| 17 |
size_categories:
|
| 18 |
- 1M<n<10M
|
| 19 |
configs:
|
| 20 |
+
- config_name: default
|
| 21 |
+
default: true
|
| 22 |
+
data_files:
|
| 23 |
+
- split: train
|
| 24 |
+
path: data/train/*.tar
|
| 25 |
+
- split: val
|
| 26 |
+
path: data/val/*.tar
|
| 27 |
+
- split: test_id
|
| 28 |
+
path: data/test_id/*.tar
|
| 29 |
+
- split: test_app
|
| 30 |
+
path: data/test_app/*.tar
|
| 31 |
+
- split: test_theme
|
| 32 |
+
path: data/test_theme/*.tar
|
| 33 |
+
- split: test_resolution
|
| 34 |
+
path: data/test_resolution/*.tar
|
| 35 |
+
- config_name: transitions
|
| 36 |
+
data_files:
|
| 37 |
+
- split: train
|
| 38 |
+
path: index/transitions/train.parquet
|
| 39 |
+
- split: val
|
| 40 |
+
path: index/transitions/val.parquet
|
| 41 |
+
- split: test_id
|
| 42 |
+
path: index/transitions/test_id.parquet
|
| 43 |
+
- split: test_app
|
| 44 |
+
path: index/transitions/test_app.parquet
|
| 45 |
+
- split: test_theme
|
| 46 |
+
path: index/transitions/test_theme.parquet
|
| 47 |
+
- split: test_resolution
|
| 48 |
+
path: index/transitions/test_resolution.parquet
|
| 49 |
- config_name: preview
|
| 50 |
data_files:
|
| 51 |
- split: preview
|
|
|
|
| 54 |
|
| 55 |
# DeskForge-1M
|
| 56 |
|
| 57 |
+
**DeskForge-1M** is a corpus of **1.21M annotated desktop screenshots** with
|
| 58 |
+
**159.7M element instances** and **917K recorded click transitions**, generated
|
| 59 |
+
with [DeskForge](https://github.com/Saidgurbuz/deskforge), a controllable
|
| 60 |
+
desktop environment that composes and explores real applications.
|
| 61 |
+
|
| 62 |
+
[**Project page**](https://saidgurbuz.github.io/deskforge/) ·
|
| 63 |
+
[**Code**](https://github.com/Saidgurbuz/deskforge) · **Paper** (coming soon)
|
| 64 |
+
|
| 65 |
+
A. Said Gurbuz · Ahmed Nassar · Sunghwan Hong · Marc Pollefeys · Peter W. J. Staar
|
| 66 |
+
<br>ETH Zurich · IBM Research Zurich · Microsoft
|
| 67 |
+
|
| 68 |
+
|
| 69 |
+
|
| 70 |
+
Every screenshot is annotated densely: not one target, but **every visible
|
| 71 |
+
element**, with its type, text, geometry, interaction properties, hierarchy and
|
| 72 |
+
owning window. Overlapping windows are resolved, so each element records both
|
| 73 |
+
its full extent and the fragments that are actually visible. Scenes combine
|
| 74 |
+
several real applications with varied content, window layouts, appearance
|
| 75 |
+
presets and display resolutions, and short click explorations link each action
|
| 76 |
+
to the screen before and after it.
|
| 77 |
+
|
| 78 |
+
## At a glance
|
| 79 |
+
|
| 80 |
+
| | |
|
| 81 |
+
| --- | --- |
|
| 82 |
+
| Observations | 1,207,368 screenshots in 323,731 scenes |
|
| 83 |
+
| Element instances | 159.7M (132 per screen on average) |
|
| 84 |
+
| Click transitions | 917,211, from 135,731 exploration episodes |
|
| 85 |
+
| Applications | 19 real Linux desktop applications, several per screen |
|
| 86 |
+
| Appearance | 7 presets, from classic Linux to Windows- and macOS-inspired styles |
|
| 87 |
+
| Resolutions | 7, from 1366×768 to 3840×2160 |
|
| 88 |
+
|
| 89 |
+
## Splits
|
| 90 |
+
|
| 91 |
+
Splits are made per **scene**, so all frames of a scene stay together. Three test
|
| 92 |
+
splits hold an attribute out of training **entirely**, which measures
|
| 93 |
+
generalization to desktop configurations never seen in training.
|
| 94 |
+
|
| 95 |
+
| split | held out | observations | transitions |
|
| 96 |
+
| --- | --- | ---: | ---: |
|
| 97 |
+
| `train` | | 999,494 | 760,850 |
|
| 98 |
+
| `val` | | 11,279 | 8,667 |
|
| 99 |
+
| `test_id` | new scenes with seen attributes | 22,550 | 17,383 |
|
| 100 |
+
| `test_app` | GNOME System Monitor, Pluma, Xarchiver | 43,206 | 32,848 |
|
| 101 |
+
| `test_theme` | the Quartz Night Nord preset | 51,627 | 38,671 |
|
| 102 |
+
| `test_resolution` | 2880×1800 | 79,212 | 58,792 |
|
| 103 |
+
|
| 104 |
+
A held-out application is excluded from every scene that contains it, in any
|
| 105 |
+
frame. See [`docs/splits.md`](docs/splits.md) for how each axis was chosen.
|
| 106 |
+
|
| 107 |
+
## What a sample contains
|
| 108 |
+
|
| 109 |
+
The default configuration streams the observations as WebDataset shards. Each
|
| 110 |
+
observation is four members sharing one key:
|
| 111 |
+
|
| 112 |
+
| member | content |
|
| 113 |
+
| --- | --- |
|
| 114 |
+
| `png` | the screenshot |
|
| 115 |
+
| `leaf.json` | every visible element: type, role, name and visible text, `rect` and `visible_fragments`, interaction state, parent and reading order, owning application and window |
|
| 116 |
+
| `screentag.txt` | the screen serialized as [ScreenTag](https://github.com/Saidgurbuz/screenparse) markup, on a 0–500 grid normalized to the screenshot |
|
| 117 |
+
| `record.json` | scene metadata (applications, preset, resolution, window stack), eligibility flags, and the action that produced this state |
|
| 118 |
+
|
| 119 |
+
Two further configurations are available: `transitions` lists every recorded
|
| 120 |
+
click with its before and after observation keys, target element and effect,
|
| 121 |
+
and `preview` is a small stratified sample with images inline (downscaled to
|
| 122 |
+
1024 px) for quick browsing. The field reference is in
|
| 123 |
+
[`docs/schema.md`](docs/schema.md).
|
| 124 |
|
| 125 |
## Loading
|
| 126 |
|
|
|
|
|
|
|
| 127 |
```python
|
| 128 |
+
from datasets import load_dataset
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 129 |
|
| 130 |
+
# Stream observations from any split.
|
| 131 |
+
ds = load_dataset("docling-project/DeskForge-1M", split="test_app", streaming=True)
|
| 132 |
+
sample = next(iter(ds))
|
| 133 |
+
sample["png"], sample["leaf.json"], sample["screentag.txt"], sample["record.json"]
|
| 134 |
|
| 135 |
+
# Transitions: before/after keys, the clicked target and what changed.
|
| 136 |
+
transitions = load_dataset("docling-project/DeskForge-1M", "transitions", split="val")
|
|
|
|
|
|
|
|
|
|
| 137 |
```
|
| 138 |
|
| 139 |
+
For full passes, read the shards with [`webdataset`](https://github.com/webdataset/webdataset);
|
| 140 |
+
the Parquet indexes select subsets before streaming, and give the byte offset of
|
| 141 |
+
every member for random access:
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 142 |
|
| 143 |
```python
|
| 144 |
+
import webdataset as wds
|
| 145 |
+
ds = (wds.WebDataset("data/train/part-{00000..00903}.tar", shardshuffle=True)
|
| 146 |
+
.decode("pil")
|
| 147 |
+
.to_tuple("png", "leaf.json", "screentag.txt", "record.json"))
|
| 148 |
+
|
| 149 |
import pyarrow.parquet as pq
|
| 150 |
obs = pq.read_table("index/observations/test_id.parquet")
|
| 151 |
+
heavily_occluded = obs.filter(obs["occluded_ratio"] > 0.5)
|
| 152 |
```
|
| 153 |
|
| 154 |
+
[`examples/`](examples) contains runnable scripts for streaming states, pairing
|
| 155 |
+
transitions and fetching a single observation by key.
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 156 |
|
| 157 |
+
**Recommended filters.** `state_train_eligible` selects the still-image view
|
| 158 |
+
(excluding near-duplicate scenes and frames where a click changed nothing), and
|
| 159 |
+
`transition_train_eligible` selects the action view, which keeps no-op clicks as
|
| 160 |
+
supervision.
|
| 161 |
|
| 162 |
+
## Annotation quality
|
|
|
|
|
|
|
| 163 |
|
| 164 |
+
Annotations are generated automatically from the accessibility tree and
|
| 165 |
+
reconciled with the screenshot and the window stack. Captures that fail the
|
| 166 |
+
automated audits (element coverage against rendered pixels, blank-widget
|
| 167 |
+
suppression, window ownership and fragment containment) are not included. A
|
| 168 |
+
human audit finds **99.8%** of sampled element annotations correct.
|
| 169 |
|
| 170 |
## Limitations
|
| 171 |
|
| 172 |
+
All screenshots come from one Linux backend (Xfce): the Windows- and
|
| 173 |
+
macOS-inspired presets reproduce the look of those systems rather than run them.
|
| 174 |
+
Actions are clicks from undirected exploration, not goal-directed
|
| 175 |
+
demonstrations. Because annotations transcribe what is on screen, text drawn by
|
| 176 |
+
applications (for example session paths or live web content in browser scenes)
|
| 177 |
+
is part of the data. Details are in [`docs/known_issues.md`](docs/known_issues.md).
|
|
|
|
|
|
|
|
|
|
|
|
|
| 178 |
|
| 179 |
+
## License
|
| 180 |
|
| 181 |
+
The dataset is released under the [MIT License](LICENSE). Application
|
| 182 |
+
interfaces, themes, icons, wallpapers and web content visible in the screenshots
|
| 183 |
+
remain the property of their respective owners.
|
| 184 |
|
| 185 |
## Citation
|
| 186 |
|
| 187 |
```bibtex
|
| 188 |
+
@article{gurbuz2026deskforge,
|
| 189 |
+
title = {DeskForge: Dense Supervision from Desktop Environments
|
| 190 |
+
for Computer-Use Agents},
|
| 191 |
+
author = {Gurbuz, A. Said and Nassar, Ahmed and Hong, Sunghwan and
|
| 192 |
+
Pollefeys, Marc and Staar, Peter W. J.},
|
| 193 |
+
journal = {arXiv preprint},
|
| 194 |
+
year = {2026}
|
| 195 |
}
|
| 196 |
```
|
docs/known_issues.md
CHANGED
|
@@ -14,17 +14,16 @@ rewriting them would make the annotation disagree with its own image.
|
|
| 14 |
| --- | --- | --- |
|
| 15 |
| `/tmp/session-<random>/` | 32.8% of captures | the ephemeral session root of the generating job, in file-chooser paths and window titles |
|
| 16 |
| synthetic persona homes, e.g. `/Users/anika/`, `/home/kwame/` | 32.5% | **generated** persona names, not real people |
|
| 17 |
-
|
|
| 18 |
-
| the generating machine's
|
| 19 |
-
| the dataset author's
|
| 20 |
|
| 21 |
-
The first three were measured over 600 random captures; the author's
|
| 22 |
constructed `record.json` files** — that is checked for every record at pack
|
| 23 |
time and refused. **No real home directory and no third party's personal data
|
| 24 |
-
appears anywhere.** The
|
| 25 |
-
printed it on screen and the annotation faithfully transcribed it. The author's own
|
| 26 |
-
|
| 27 |
-
disclosed here rather than removed because it is in the pixels.
|
| 28 |
|
| 29 |
Downstream filtering on these strings is straightforward: they are exact and
|
| 30 |
they are in the text members, not only the images.
|
|
@@ -34,13 +33,13 @@ they are in the text members, not only the images.
|
|
| 34 |
Some scenes drive a real Chromium against a real URL, so a browser window shows
|
| 35 |
whatever that site served on the capture date. The domain is recorded, the page
|
| 36 |
content is not curated, and it may include news text, advertising or images
|
| 37 |
-
belonging to third parties.
|
| 38 |
|
| 39 |
## Annotation
|
| 40 |
|
| 41 |
* **Labels are automatic.** They come from the AT-SPI2 accessibility tree and
|
| 42 |
-
automated refinement
|
| 43 |
-
reports its own tree badly is annotated badly.
|
| 44 |
* **Toggle state is invisible on this stack.** AT-SPI 2.40.3 does not expose
|
| 45 |
`checkable`/`checked` for menu items here, so a checked menu item is not
|
| 46 |
distinguishable from an unchecked one in the annotation.
|
|
|
|
| 14 |
| --- | --- | --- |
|
| 15 |
| `/tmp/session-<random>/` | 32.8% of captures | the ephemeral session root of the generating job, in file-chooser paths and window titles |
|
| 16 |
| synthetic persona homes, e.g. `/Users/anika/`, `/home/kwame/` | 32.5% | **generated** persona names, not real people |
|
| 17 |
+
| the generating machine's host name | 9.8% | surfaced as an AT-SPI label in file managers |
|
| 18 |
+
| the generating machine's checkout path | 153 captures (0.01%), 71 shards | printed by VS Code itself — a terminal showing its own command line, or a docs entry resolving the `code` binary |
|
| 19 |
+
| the dataset author's own account details | **830 captures (0.07%)**, 266 scenes | the account name field of the generating user, captured into a document fixture and therefore painted into those screenshots |
|
| 20 |
|
| 21 |
+
The first three were measured over 600 random captures; the author's account string was counted exactly, across all 1,266,471 source captures. **No host path appears in any of the 1,207,368
|
| 22 |
constructed `record.json` files** — that is checked for every record at pack
|
| 23 |
time and refused. **No real home directory and no third party's personal data
|
| 24 |
+
appears anywhere.** The checkout path above appears only where an application
|
| 25 |
+
printed it on screen and the annotation faithfully transcribed it. The author's own account string
|
| 26 |
+
belongs to the dataset's author and is disclosed here rather than removed because it is in the pixels.
|
|
|
|
| 27 |
|
| 28 |
Downstream filtering on these strings is straightforward: they are exact and
|
| 29 |
they are in the text members, not only the images.
|
|
|
|
| 33 |
Some scenes drive a real Chromium against a real URL, so a browser window shows
|
| 34 |
whatever that site served on the capture date. The domain is recorded, the page
|
| 35 |
content is not curated, and it may include news text, advertising or images
|
| 36 |
+
belonging to third parties.
|
| 37 |
|
| 38 |
## Annotation
|
| 39 |
|
| 40 |
* **Labels are automatic.** They come from the AT-SPI2 accessibility tree and
|
| 41 |
+
automated refinement; a human audit of sampled elements finds 99.8% of them
|
| 42 |
+
correct. An application that reports its own tree badly is annotated badly.
|
| 43 |
* **Toggle state is invisible on this stack.** AT-SPI 2.40.3 does not expose
|
| 44 |
`checkable`/`checked` for menu items here, so a checked menu item is not
|
| 45 |
distinguishable from an unchecked one in the annotation.
|
release_provenance.json
CHANGED
|
@@ -2,7 +2,6 @@
|
|
| 2 |
"dataset_name": "DeskForge-1M",
|
| 3 |
"dataset_version": "1.0.0",
|
| 4 |
"created_utc": "2026-08-25T15:15:50Z",
|
| 5 |
-
"corpus_root": "/proj/docling-vision/users/said/deskshot_corpus/v1",
|
| 6 |
"source_manifests": {
|
| 7 |
"plan/manifest.jsonl": {
|
| 8 |
"sha256": "f50f6a7c87cc6d2a05bb04a820b20e3a634c2cb60ea9ed1afa51325f69c6dc8c",
|
|
@@ -14,9 +13,8 @@
|
|
| 14 |
}
|
| 15 |
},
|
| 16 |
"code": {
|
| 17 |
-
"
|
| 18 |
-
"
|
| 19 |
-
"dirty": false
|
| 20 |
},
|
| 21 |
"key_scheme": {
|
| 22 |
"observation_key": "<shard>__<stem>",
|
|
|
|
| 2 |
"dataset_name": "DeskForge-1M",
|
| 3 |
"dataset_version": "1.0.0",
|
| 4 |
"created_utc": "2026-08-25T15:15:50Z",
|
|
|
|
| 5 |
"source_manifests": {
|
| 6 |
"plan/manifest.jsonl": {
|
| 7 |
"sha256": "f50f6a7c87cc6d2a05bb04a820b20e3a634c2cb60ea9ed1afa51325f69c6dc8c",
|
|
|
|
| 13 |
}
|
| 14 |
},
|
| 15 |
"code": {
|
| 16 |
+
"repository": "https://github.com/Saidgurbuz/deskforge",
|
| 17 |
+
"release": "v1.0.0"
|
|
|
|
| 18 |
},
|
| 19 |
"key_scheme": {
|
| 20 |
"observation_key": "<shard>__<stem>",
|