
Datasets:


Commit ·
3b130aa
0
Parent(s):
Duplicate from witcheer/rtx-5090-benchmarks
Browse filesCo-authored-by: witcheer <witcheer@users.noreply.huggingface.co>
This view is limited to 50 files because it contains too many changes. See raw diff
- .gitattributes +60 -0
- README.md +191 -0
- benchmarks.csv +50 -0
- raw/hrm-gsm8k-synth-cot-n200.jsonl +0 -0
- raw/hrm-gsm8k-synth-cot-nomask-n200.jsonl +0 -0
- raw/la-screenspot.jsonl +0 -0
- reports/ace-step-music.md +56 -0
- reports/ace-step-music.png +3 -0
- reports/agentic-nex-n2-mini.md +66 -0
- reports/agentic-nex-n2-mini.png +3 -0
- reports/agentic-tokens.png +3 -0
- reports/agentworld-lwm-transfer.md +43 -0
- reports/agentworld-lwm-transfer.png +3 -0
- reports/agentworld-think-on-null.md +39 -0
- reports/agentworld-think-on-null.png +3 -0
- reports/assets/ltx/bench/campfire-night-1280x704-97f.mp4 +3 -0
- reports/assets/ltx/bench/campfire-night-768x512-97f.mp4 +3 -0
- reports/assets/ltx/bench/drummer-solo-1280x704-97f.mp4 +3 -0
- reports/assets/ltx/bench/drummer-solo-768x512-97f.mp4 +3 -0
- reports/assets/ltx/bench/ocean-storm-1280x704-97f.mp4 +3 -0
- reports/assets/ltx/bench/ocean-storm-768x512-97f.mp4 +3 -0
- reports/assets/ltx/bench/puppy-garden-1280x704-97f.mp4 +3 -0
- reports/assets/ltx/bench/puppy-garden-768x512-97f.mp4 +3 -0
- reports/assets/ltx/bench/street-market-1280x704-97f.mp4 +3 -0
- reports/assets/ltx/bench/street-market-768x512-97f.mp4 +3 -0
- reports/assets/ltx/bench/summary.json +21 -0
- reports/assets/ltx/bench/synth.json +145 -0
- reports/assets/ltx/bench/warmup.mp4 +3 -0
- reports/assets/zimage-montage.png +3 -0
- reports/assets/zimage/complex-1024-8st.png +3 -0
- reports/assets/zimage/counting-1024-8st.png +3 -0
- reports/assets/zimage/illustration-1024-8st.png +3 -0
- reports/assets/zimage/landscape-1024-8st.png +3 -0
- reports/assets/zimage/portrait-1024-8st.png +3 -0
- reports/assets/zimage/spatial-1024-8st.png +3 -0
- reports/assets/zimage/sweep-portrait-1024-16st.png +3 -0
- reports/assets/zimage/sweep-portrait-1024-4st.png +3 -0
- reports/assets/zimage/sweep-portrait-1024-8st.png +3 -0
- reports/assets/zimage/sweep-portrait-1024-9st.png +3 -0
- reports/assets/zimage/text-1024-8st.png +3 -0
- reports/assets/zimage/two-object-1024-8st.png +3 -0
- reports/bias-only-steering.md +109 -0
- reports/cacheback-spec-decode.md +54 -0
- reports/cacheback-spec-decode.png +3 -0
- reports/card-quality-leaderboard.png +3 -0
- reports/chart-awq-recipe-coverage.png +3 -0
- reports/chart-grpo-gsm8k.png +3 -0
- reports/chart-lfm2-vl-extract.png +3 -0
- reports/chart-nemotron-speed-vs-quality.png +3 -0
- reports/chart-nvfp4-vs-q6.png +3 -0
.gitattributes
ADDED
|
@@ -0,0 +1,60 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
*.7z filter=lfs diff=lfs merge=lfs -text
|
| 2 |
+
*.arrow filter=lfs diff=lfs merge=lfs -text
|
| 3 |
+
*.avro filter=lfs diff=lfs merge=lfs -text
|
| 4 |
+
*.bin filter=lfs diff=lfs merge=lfs -text
|
| 5 |
+
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
| 6 |
+
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
| 7 |
+
*.ftz filter=lfs diff=lfs merge=lfs -text
|
| 8 |
+
*.gz filter=lfs diff=lfs merge=lfs -text
|
| 9 |
+
*.h5 filter=lfs diff=lfs merge=lfs -text
|
| 10 |
+
*.joblib filter=lfs diff=lfs merge=lfs -text
|
| 11 |
+
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
| 12 |
+
*.lz4 filter=lfs diff=lfs merge=lfs -text
|
| 13 |
+
*.mds filter=lfs diff=lfs merge=lfs -text
|
| 14 |
+
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
| 15 |
+
*.model filter=lfs diff=lfs merge=lfs -text
|
| 16 |
+
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
| 17 |
+
*.npy filter=lfs diff=lfs merge=lfs -text
|
| 18 |
+
*.npz filter=lfs diff=lfs merge=lfs -text
|
| 19 |
+
*.onnx filter=lfs diff=lfs merge=lfs -text
|
| 20 |
+
*.ot filter=lfs diff=lfs merge=lfs -text
|
| 21 |
+
*.parquet filter=lfs diff=lfs merge=lfs -text
|
| 22 |
+
*.pb filter=lfs diff=lfs merge=lfs -text
|
| 23 |
+
*.pickle filter=lfs diff=lfs merge=lfs -text
|
| 24 |
+
*.pkl filter=lfs diff=lfs merge=lfs -text
|
| 25 |
+
*.pt filter=lfs diff=lfs merge=lfs -text
|
| 26 |
+
*.pth filter=lfs diff=lfs merge=lfs -text
|
| 27 |
+
*.rar filter=lfs diff=lfs merge=lfs -text
|
| 28 |
+
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
| 29 |
+
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
| 30 |
+
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
| 31 |
+
*.tar filter=lfs diff=lfs merge=lfs -text
|
| 32 |
+
*.tflite filter=lfs diff=lfs merge=lfs -text
|
| 33 |
+
*.tgz filter=lfs diff=lfs merge=lfs -text
|
| 34 |
+
*.wasm filter=lfs diff=lfs merge=lfs -text
|
| 35 |
+
*.xz filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 37 |
+
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 38 |
+
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 39 |
+
# Audio files - uncompressed
|
| 40 |
+
*.pcm filter=lfs diff=lfs merge=lfs -text
|
| 41 |
+
*.sam filter=lfs diff=lfs merge=lfs -text
|
| 42 |
+
*.raw filter=lfs diff=lfs merge=lfs -text
|
| 43 |
+
# Audio files - compressed
|
| 44 |
+
*.aac filter=lfs diff=lfs merge=lfs -text
|
| 45 |
+
*.flac filter=lfs diff=lfs merge=lfs -text
|
| 46 |
+
*.mp3 filter=lfs diff=lfs merge=lfs -text
|
| 47 |
+
*.ogg filter=lfs diff=lfs merge=lfs -text
|
| 48 |
+
*.wav filter=lfs diff=lfs merge=lfs -text
|
| 49 |
+
# Image files - uncompressed
|
| 50 |
+
*.bmp filter=lfs diff=lfs merge=lfs -text
|
| 51 |
+
*.gif filter=lfs diff=lfs merge=lfs -text
|
| 52 |
+
*.png filter=lfs diff=lfs merge=lfs -text
|
| 53 |
+
*.tiff filter=lfs diff=lfs merge=lfs -text
|
| 54 |
+
# Image files - compressed
|
| 55 |
+
*.jpg filter=lfs diff=lfs merge=lfs -text
|
| 56 |
+
*.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 57 |
+
*.webp filter=lfs diff=lfs merge=lfs -text
|
| 58 |
+
# Video files - compressed
|
| 59 |
+
*.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 60 |
+
*.webm filter=lfs diff=lfs merge=lfs -text
|
README.md
ADDED
|
@@ -0,0 +1,191 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: mit
|
| 3 |
+
task_categories:
|
| 4 |
+
- text-generation
|
| 5 |
+
tags:
|
| 6 |
+
- benchmark
|
| 7 |
+
- inference
|
| 8 |
+
- llm
|
| 9 |
+
- nvidia
|
| 10 |
+
- rtx-5090
|
| 11 |
+
- llama-cpp
|
| 12 |
+
- vllm
|
| 13 |
+
- speed
|
| 14 |
+
- quality
|
| 15 |
+
- mmlu
|
| 16 |
+
- gsm8k
|
| 17 |
+
- humaneval
|
| 18 |
+
- moe
|
| 19 |
+
size_categories:
|
| 20 |
+
- n<1K
|
| 21 |
+
configs:
|
| 22 |
+
- config_name: default
|
| 23 |
+
data_files:
|
| 24 |
+
- split: train
|
| 25 |
+
path: benchmarks.csv
|
| 26 |
+
---
|
| 27 |
+
|
| 28 |
+
# RTX 5090 LLM Benchmarks
|
| 29 |
+
|
| 30 |
+
Speed and quality benchmarks for quantized LLMs on NVIDIA RTX 5090 32GB, measured with [llm-bench-rig](https://github.com/notwitcheer/llm-bench-rig).
|
| 31 |
+
|
| 32 |
+
## Quality Benchmarks
|
| 33 |
+
|
| 34 |
+
Generative evaluation through llama-server chat completions. Replicates standard benchmark methodology using custom evaluators — no `lm-evaluation-harness` dependency.
|
| 35 |
+
|
| 36 |
+
Results are **split by reasoning mode**: comparing a thinking-on (reasoning) model's quality against a thinking-off model is apples-to-oranges, so the two groups are ranked separately. `q_avg` is the mean of the five tasks.
|
| 37 |
+
|
| 38 |
+
### Thinking OFF (non-reasoning · direct answer)
|
| 39 |
+
|
| 40 |
+
| Model | Params | Quant | MMLU | ARC-C | HellaSwag | GSM8K | HumanEval | q_avg |
|
| 41 |
+
|-------|-------:|-------|-----:|------:|----------:|------:|----------:|------:|
|
| 42 |
+
| Gemma 4 31B-it | 30.70B | Q6_K | 87.8 | 97.6 | 92.0 | 97.5 | 96.3 | **94.2** |
|
| 43 |
+
| Qwopus3.6-27B-Coder | 27.32B | Q5_K_M | 87.5 | 96.8 | 95.2 | 97.5 | 93.3 | **94.1** |
|
| 44 |
+
| Qwen3.6-27B² | 26.90B | Q6_K | 87.9 | 96.9 | 95.4 | 97.3 | 93.3 | **94.2** |
|
| 45 |
+
| Qwen3.6-27B² | 26.90B | NVFP4³ | 87.6 | 96.4 | 95.4 | 97.5 | 93.3 | **94.1** |
|
| 46 |
+
| Qwopus3.6-27B-Coder-Compat | 27.32B | Q6_K | 87.9 | 96.7 | 95.3 | 97.8 | 90.9 | **93.7** |
|
| 47 |
+
| Qwable-5-27B-Coder | 26.90B | Q6_K | 87.9 | 97.1 | 95.5 | 97.0 | 90.9 | **93.7** |
|
| 48 |
+
| Qwen3.6-35B-A3B | 34.66B | UD-Q4_K_M | 85.0 | 95.7 | 93.3 | 96.7 | 95.7 | **93.3** |
|
| 49 |
+
| Qwen3.6-27B | 26.90B | NVFP4-GGUF⁴ | 87.0 | 96.7 | 94.9 | 97.1 | 90.2 | **93.2** |
|
| 50 |
+
| Qwen3.6-27B² | 26.90B | AWQ-int4⁵ | 87.5 | 96.4 | 95.2 | 97.3 | 89.0 | **93.1** |
|
| 51 |
+
| Qwen3-Coder-Next | 79.67B | UD-Q2_K_XL | 83.7 | 96.0 | 89.3 | 96.0 | 93.3 | **91.7** |
|
| 52 |
+
| Gemma 4 12B-it | 11.91B | Q6_K | 78.9 | 94.0 | 81.6 | 96.4 | 87.2 | **87.6** |
|
| 53 |
+
| gpt-oss-20b | 20.91B | Q4_K_M | 78.6 | 94.6 | 74.5 | 94.8 | 94.5 | **87.4** |
|
| 54 |
+
| Nemotron-3-Nano | 31.58B | UD-Q4_K_XL | 74.5 | 89.9 | 75.6 | 90.5 | 80.5 | **82.2** |
|
| 55 |
+
| Nemotron-Cascade-2 | 31.58B | Q4_K_M | 74.4 | 91.5 | 75.7 | 87.1 | 79.3 | **81.6** |
|
| 56 |
+
| North-Mini-Code-1.0† | 30.48B | Q6_K | 73.3 | 60.2 | 70.8 | 95.8 | 86.6 | **77.4** |
|
| 57 |
+
|
| 58 |
+
† North-Mini-Code-1.0 is a *reasoning* model, run think-OFF for board parity. ARC-Challenge is reasoning-gated: 60.2 think-OFF to ~95 think-ON (+35), which deflates its q_avg. See the [report](reports/north-mini-code.md).
|
| 59 |
+
|
| 60 |
+
² Re-banked 2026-07-15 under the pinned harness (rig ec00ff0, llama-server b9653); the re-bank moved HumanEval by one passing problem (92.7 → 93.3) and nothing else beyond 0.05.
|
| 61 |
+
³ unsloth compressed-tensors NVFP4 (23.4GB, 303 modules kept high-precision, lm_head dequanted), served via vLLM 0.21.0 on the native cutlass sm_120 FP4 path, measured 2026-07-15 under the same pin. Protocol and per-suite deltas: [report addendum](reports/qwen3-6-27b-nvfp4.md).
|
| 62 |
+
⁴ NVFP4-GGUF (s-batman MTP GGUF, 14.6GB, flat quant), llama.cpp b9365 `BLACKWELL_NATIVE_FP4`, June numbers, pre-pin: [NVFP4 vs Q6_K](reports/nvfp4-vs-q6-qwen3-6-27b.md). Rows ³ and ⁴ share a format name and nothing else; the 0.9 q_avg spread between them is recipe coverage (which modules stay high-precision), not the FP4 format.
|
| 63 |
+
⁵ QuantTrio true AWQ (4-bit g128 gemm, 8 modules ignored — flat recipe, 21.9GB), served via vLLM 0.21.0 awq_marlin, measured 2026-07-16 under the same pin. sglang 0.5.14 cannot serve this artifact (hybrid-GDN dtype wall: degenerate output at bf16, crash at fp16) — [report](reports/qwen3-6-27b-awq.md). The recipe-coverage rule now holds cross-format: flat recipes cluster (⁴ 93.2, ⁵ 93.1) while the protected recipe (³) holds the baseline.
|
| 64 |
+
|
| 65 |
+
### Thinking ON (reasoning · extended chain-of-thought)
|
| 66 |
+
|
| 67 |
+
| Model | Params | Quant | MMLU | ARC-C | HellaSwag | GSM8K | HumanEval | q_avg |
|
| 68 |
+
|-------|-------:|-------|-----:|------:|----------:|------:|----------:|------:|
|
| 69 |
+
| Qwen3.6-35B-A3B | 34.66B | UD-Q6_K | 94.7 | 97.0 | 87.0 | 92.0 | 98.0 | **93.8** |
|
| 70 |
+
| gpt-oss-120B¹ | 116.83B | MXFP4 | 89.5 | 95.0 | 80.0 | 97.0 | 98.0 | **91.9** |
|
| 71 |
+
| Qwen3.6-28B-REAP-A3B | 28.24B | Q6_K | 87.7 | 95.0 | 82.0 | 90.0 | 94.0 | **89.7** |
|
| 72 |
+
|
| 73 |
+
> **HumanEval correction (2026-06-04).** An earlier harness passed API stop sequences (`\ndef`, `\nclass`) that fired *mid-reasoning*, truncating inline-reasoning models before they emitted code — producing false-low scores (Qwen3-Coder-Next read **10%**, not 93%). Every model has since been re-run on the fixed, reasoning-aware harness (no stop sequences, `max_tokens=4096`, indentation-preserving response handling). A second extraction fix (2026-06-04) makes program assembly format-agnostic — it generates candidate assemblies and keeps whichever one compiles — after Nemotron-3-Nano exposed a case where the model indents only the *first* body line differently (raw HumanEval read **21%**; corrected to 80.5%). **Do not cite any HumanEval figure published before this date.**
|
| 74 |
+
>
|
| 75 |
+
> **Why two tables.** Thinking-off rows answer directly; thinking-on rows emit an extended reasoning chain first. The two modes are not comparable on the same axis — including on MCQ/GSM8K — so they are ranked separately. Within a family, turning thinking on trades raw knowledge recall for reasoning depth (compare Qwen3.6-35B-A3B in both tables: MMLU 85.0 → 94.7).
|
| 76 |
+
>
|
| 77 |
+
> ¹ **gpt-oss-120B** runs via MoE CPU-offload (`--n-cpu-moe 20`) — it does not fit 32GB VRAM (59GB model); ~30GB VRAM + the rest in system RAM, ~47 tok/s generation. It and the other two thinking-on rows were run on a ~100-item-per-task subset (MMLU 2/subject).
|
| 78 |
+
|
| 79 |
+
> **Sampling.** MMLU & HellaSwag use 50% stratified sampling (seed=42); ARC-Challenge, GSM8K, and HumanEval run the full item counts (HumanEval = all 164). Full per-model reports in [`reports/`](reports/).
|
| 80 |
+
|
| 81 |
+
### Methodology
|
| 82 |
+
|
| 83 |
+
| Benchmark | Dataset | Few-shot | Scoring | Items |
|
| 84 |
+
|-----------|---------|----------|---------|------:|
|
| 85 |
+
| MMLU | `cais/mmlu` | 5-shot | Letter extraction (A/B/C/D) | 14,042 |
|
| 86 |
+
| ARC-Challenge | `allenai/ai2_arc` | 25-shot | Letter extraction | 1,172 |
|
| 87 |
+
| HellaSwag | `Rowan/hellaswag` | 10-shot | Letter extraction | 10,042 |
|
| 88 |
+
| GSM8K | `openai/gsm8k` | 5-shot CoT | Exact numeric match | 1,319 |
|
| 89 |
+
| HumanEval | `openai/openai_humaneval` | 0-shot | pass@1 (code execution) | 164 |
|
| 90 |
+
|
| 91 |
+
All benchmarks run at `temperature=0`. MCQ and GSM8K use `max_tokens=2048`; HumanEval uses `max_tokens=4096` with **no stop sequences** (reasoning models emit code only after long inline reasoning — premature stops were the bug corrected above). Multiple-choice tasks use generative letter extraction instead of loglikelihood scoring — scores are internally consistent for model comparison but may differ from logprob-based evaluations by 5-15%.
|
| 92 |
+
|
| 93 |
+
Full per-model reports with MMLU category breakdowns, parse reliability stats, and speed data: [`reports/`](reports/)
|
| 94 |
+
|
| 95 |
+
---
|
| 96 |
+
|
| 97 |
+
## Speed Benchmarks
|
| 98 |
+
|
| 99 |
+
### What's measured
|
| 100 |
+
|
| 101 |
+
- **Prompt processing (pp)**: parallel batched token throughput at context lengths 128, 512, 2048, 4096, 8192, 16384
|
| 102 |
+
- **Text generation (tg)**: sequential autoregressive token throughput at 128 tokens
|
| 103 |
+
- All models fully GPU-offloaded (ngl=99)
|
| 104 |
+
|
| 105 |
+
### Speed data schema
|
| 106 |
+
|
| 107 |
+
| Column | Description |
|
| 108 |
+
|--------|-------------|
|
| 109 |
+
| `model` | Model name |
|
| 110 |
+
| `architecture` | Dense or MoE (with active param count) |
|
| 111 |
+
| `params_b` | Total parameters in billions |
|
| 112 |
+
| `quant` | Quantization method |
|
| 113 |
+
| `size_gib` | File size in GiB |
|
| 114 |
+
| `engine` | Inference engine (llama.cpp or vLLM) |
|
| 115 |
+
| `backend` | Compute backend (CUDA) |
|
| 116 |
+
| `gpu` | GPU model |
|
| 117 |
+
| `vram_gb` | VRAM in GB |
|
| 118 |
+
| `test` | Benchmark test (pp128, pp512, ..., tg128) |
|
| 119 |
+
| `tokens_per_sec` | Throughput in tokens/second |
|
| 120 |
+
| `stddev` | Standard deviation |
|
| 121 |
+
| `date` | Benchmark date |
|
| 122 |
+
|
| 123 |
+
### Key findings
|
| 124 |
+
|
| 125 |
+
MoE (3B active) vs Dense (27B) on same-family Qwen3.6 models:
|
| 126 |
+
- Prompt processing: **2.4x faster** across all context lengths
|
| 127 |
+
- Text generation: **3.5x faster** (271 vs 77 t/s)
|
| 128 |
+
- Both degrade ~17% at 16K context (attention + VRAM, not parameter count)
|
| 129 |
+
|
| 130 |
+
---
|
| 131 |
+
|
| 132 |
+
## Field Reports
|
| 133 |
+
|
| 134 |
+
One-shot investigations that don't fit the leaderboard format — claim verification, new-architecture probes, and consumer-hardware autopsies, all measured on the same rig. Newest first.
|
| 135 |
+
|
| 136 |
+
| Report | Finding |
|
| 137 |
+
|---|---|
|
| 138 |
+
| [First EAGLE-3 draft head for Hermes-4.3-36B: trained on one 5090, converged at 39% of the epoch, 1.29–1.57x](reports/hermes-drafter-epoch1.md) · [chart](reports/hermes-drafter-epoch1.png) | Hermes-4.3-36B (Seed-OSS architecture) had no speculative-decoding draft head anywhere on Hugging Face; this run trained the first one entirely on a single RTX 5090, using SpecForge's online mode with a 4-bit AWQ teacher (six memory patches, five filed upstream), 54K curated conversations, 54,000 steps across 8 unattended nights (~55 GPU-h, every night rc=0). Release bench (sglang 0.5.14, cuda graphs, 8 fixed prompts/workload, 66 tok/s no-drafter baseline): tree-3-4-8 wins all four workloads at 1.29–1.57x real decode speedup, while the wider tree-5-8-16 accepts deeper (accept-len to 2.22) yet lands slower everywhere — the draft cost eats more than the extra accepted tokens return. Two findings beyond the table: the head converged at step 21,000 (the epoch-end bench reproduces the 39%-of-epoch dry run within noise, so the last five nights of training moved nothing), and the 1.7–2.2x trained-head precedent band is out of reach at batch 1 on one card, where roughly a quarter of the theoretical accept-len gain pays for the draft pass itself. Decision recorded in the report: no epoch 2 on the same data; a v2 changes the data mix, not the step count. Weights + model card follow with the release. |
|
| 139 |
+
| [LTX-2.3 audio-video on a 5090: synced sound, decode-bound wall time](reports/ltx-2.3.md) · [chart](reports/ltx-2.3.png) · [clips](reports/assets/ltx/bench/) | First consumer-Blackwell (sm_120) numbers for LTX-2.3, Lightricks' ~19B dual-stream DiT (14B video + 5B audio) that generates video and synchronized audio in one pass. The distilled two-stage pipeline (8+4 steps, fp8-cast, tiled VAE, SDPA) makes a 97-frame ~4s clip with h264 + AAC 48kHz output in ~40s at 768x512 (steady state) and ~50s at 1280x704 on one RTX 5090: 10.8 and 12.3 seconds of compute per second of output video. The surprise is the shape of the cost: 2.5x the pixels adds only ~14% wall time, and true peak VRAM (torch counter) is flat at 24.2GB in both configs, because the DiT accounts for just ~5-12s of the wall while tiled VAE decode + audio decode + mp4/AAC encode dominate. Consequences: render at the higher resolution (the quality jump is nearly free) and expect DiT-side speedups to move at most ~a quarter of wall time at these clip lengths. Honest limits flagged in the report: the first generation at a new shape pays ~+20s of one-time lazy init (kept in the published mean), and the vendor's "5.7x faster than Wan2.2 on a 5090" claim is cited, not re-measured. All ten clips attached. Completes the artifact-first modality arc: music (ACE-Step), image (Z-Image), now video-with-audio, all on one card. |
|
| 140 |
+
| [Z-Image-Turbo on a 5090: few-step distillation, measured](reports/z-image-turbo.md) · [chart](reports/z-image-turbo.png) · [samples](reports/assets/zimage-montage.png) | First RTX-5090/sm_120 numbers for Z-Image-Turbo, an open-weights (Apache-2.0) 6B text-to-image DiT with a Qwen3-4B text encoder, measured out-of-box (bf16, SDPA, no torch.compile, no quant). A 1024px image takes 3.18s (~19/min), a 512px one 0.83s. The "turbo" is distillation from the ~50 denoising steps a normal diffusion model runs down to 8, and compute is exactly linear in the step count (each step is one DiT forward): 1.69s at 4 steps, 3.20s at 8, 6.23s at 16, with 4 steps near-indistinguishable from 8 on portraits. Resolution is the real cost, not memory: 0.83/3.18/9.99/23.36s at 512/1024/1536/2048, super-linear because attention scales with pixel count squared. The whole model fits a 32GB card at every tested size (true per-image peak 20.4/21.7/24.6/28.8GB), so 2048px keeps ~4GB of headroom: a time wall, never a VRAM wall. The classically-hard cases hold at 8 steps, where it renders exact text on a sign ("WITCHEER", letters correct) and draws exactly-N objects on request, with colours and spatial relations landing too (sample grid attached). Measurement note: per-image VRAM comes from torch.cuda.max_memory_allocated() with reset_peak_memory_stats() each iteration, because nvidia-smi over-reports. PyTorch's caching allocator retains its high-water mark and never releases it between generations, flattening a naive VRAM curve to a wrong constant. Speed and footprint only; a GenEval quality pass (its mmcv/mmdet detector needs a from-source sm_120 build) is the natural follow-up. Companion to the ACE-Step music bench, the other few-step distilled generator on this rig. |
|
| 141 |
+
| [Nemotron-TwoTower autopsy: a 2.4x speedup that costs a second 30B model](reports/nemotron-twotower-autopsy.md) · [chart](reports/nemotron-twotower-autopsy.png) | NVIDIA's Nemotron-TwoTower is a diffusion LM adapted from a frozen autoregressive Nemotron-3-Nano-30B that generates 2.42x faster than plain AR at 98.7% quality (arXiv 2606.26493) — clever, and datacenter-only by construction. The speedup comes from running two full 30B backbones co-resident: a frozen context tower plus a trained denoiser that unmasks several tokens per diffusion step. The checkpoint ships both stacks (126GB bf16, ~63B params) and the card requires 2x80GB (~59GB/GPU). The towers can't be shared (the paper's own ablation: tying is "substantially worse") or run sequentially (the denoiser cross-attends to and seeds Mamba state from the live context tower every block-step), so the 2.42x is bought by doubling the model's resident memory. The comparison that matters: on one RTX 5090, speculative decoding already delivers the same multiplier for a draft head in single-digit GB — from this rig's t036 spec-decode run on Gemma-4-26B-A4B (sm_120): MTP 2.13x, DFlash 2.19x, EAGLE-3 1.69x, for ~0-2GB of drafter (MTP ships inside the model). Same ~2.2x speedup, ~60x the memory. Two honest caveats: different mechanisms on different models (an architectural argument, not a controlled A/B — TwoTower won't run on the rig), and TwoTower's 2.42x is measured vs plain AR with no speculative-decoding baseline, so against a production AR server already at ~2.2x via spec-decode the marginal win mostly disappears while still costing a second 30B backbone. Doesn't run on consumer hardware at all: 126GB exceeds a 96GB box even fully offloaded, no quant of the custom trust_remote_code arch exists, and the mamba_ssm/causal_conv1d kernels are the usual Blackwell build wall. The two HF repos are the same checkpoint (config + shard sha256 identical; -Labs- adds inference.py). Arithmetic autopsy from the published artifact, no 5090 run. Companion to the GLM-5.2 datacenter-only autopsy and the spec-decode three-way. |
|
| 142 |
+
| [Making music on a gaming GPU: ACE-Step 1.5 writes a 4-minute song in 1.75s](reports/ace-step-music.md) · [chart](reports/ace-step-music.png) | First RTX-5090/sm_120 numbers for ACE-Step 1.5, an open-weights text-to-music model. One gaming GPU generates a full 4-minute song in 1.75s of compute (2B turbo, DiT-only, bf16, 8-step, batch 1) — level with the model authors' own A100 claim (~1-2s) and ~6x past the RTX 3090 (<10s), at 137x real-time. The higher-quality XL 4B tier costs ~1.65x the time (2.9s, 83x) and ~60% more VRAM (14.8 vs 9.4GB); both fit far inside 32GB, and XL would run on a 16GB card. Real-time factor RISES with length — 81x at 30s to 137x at 4min — because the turbo model's step count is fixed at 8 (distilled from ~50), so a 4-minute track is ~5x the compute of a 30-second one, not 8x. Measured out-of-box with no torch.compile and no quantization: a floor, not a ceiling. Speed only — audio quality is left to the ear (paired 2B-vs-XL samples), a prompt-alignment score the natural follow-up. Companion to the DiffusionGemma AR-vs-diffusion null. |
|
| 143 |
+
| [Bias-only steering: nothing moves at bounded budget, and random rewards match correct ones](reports/bias-only-steering.md) · [chart](reports/steering-claimed-vs-measured.png) | Bias-Only Reasoning Steering (arXiv 2505.18706, EMNLP 2025) claims RL-training one bias vector per layer (~0.0016% of params, added to mlp.down_proj) matches full RL fine-tuning: Qwen2.5-Math-7B MATH500 52.2 to 79.9 (steering even beats full-FT). Their pinned stack is dead on arrival on consumer Blackwell — torch 2.6.0+cu124/vllm 0.8.5 fails its first kernel launch on sm_120 — so the recipe was reimplemented from their own configs (RLOO, steering lr 1e-3, qwen_math template, DeepScaleR) at a matched bounded budget (20 steps x 8 prompts x 8 generations, ~1,280 rollouts vs their ~645K), plus the controls neither paper reports: their-own-config LoRA (r4, down_proj only), random-reward steering (Spurious-Rewards protocol), and a zero-training 'To'-prefix probe of their companion paper's first-token-substitution mechanism. A five-arm null: base 54.6 MATH500 / 45.0 AMC23 (reproduces their 52.2/45.8 starting point), steering 54.4/45.0, LoRA 53.8/40.0, random-reward steering 54.2/45.0, 'To'-prefix 53.0 — every arm is the base. Correct rewards buy nothing over coin flips at this budget, and the claimed ~10-11pt 'To'-prefix gain lands at -1.6 on the standard template, where the base's generations already open with 'To'. Wall-clock decomposition (identical across arms): rollouts 75%, backward+update 25%, grading under 1% — the '34s vs 52m' headline counts only the optimizer sliver, and the slice that shrinks with trainable-param count is ~none of a step; on 32GB the real bias-only win is memory (full-param 7B RL does not fit at all; ~100K bias params train comfortably). Bounds where the gain is not (early), does not refute their full-recipe endpoint. Steering checkpoints served in stock vLLM via a Qwen2-to-Llama re-badge (mlp_bias=true), fp32-verified logit-identical. |
|
| 144 |
+
| [Ornith-1.0-35B's self-written scaffold doesn't survive a different harness](reports/ornith-1-0-35b-anchor.md) · [chart](reports/ornith-anchor.png) | DeepReinforce's Ornith-1.0 (MIT) is an RL coder that co-trains a task-specific agent scaffold INTO the weights; the 35B claims 75.6 SWE-bench Verified (the 82.4 headline is the unrunnable 397B flagship), measured in OpenHands. Held the bugs, harness, quant (Q4_K_M), and thinking mode (off) fixed and changed only the model: against the exact base it was post-trained from (Qwen3.5-35B-A3B) in the rig's strict native loop, Ornith-35B resolves 5/12 vs the base's 7/12 — a regression, and a strict subset (it recovers nothing the base missed). The two losses (astropy-12907, xarray-3677) are bugs the base solved, lost to tool-call JSON fragility: Ornith emits multi-line bash with unescaped newlines, llama-server's strict parser 500s, and even after the loop is hardened to feed the error back and let it retry (a fix inert for the base, which never 500s), it burns its full 40-step budget producing no patch. The reading: their 75.6 lives in a lenient harness with the model's own scaffold; stripped to a strict neutral loop the self-scaffold model is more fragile than the base it was trained from, so the orchestration didn't travel. An agentic-coding number is a property of the model and the harness, not the model alone. And the rig's own synthetic Agentic Score is worse than blind to it: it ranks Ornith-35B at 98.06, ABOVE the base's 97.5 (#6 on the board), while Ornith resolves fewer real bugs — the synthetic axis inverts the ranking, scoring fluent tool-driving rather than real-bug fixing. Not a refutation of the 75.6 (different harness, temperature, and scaffold); the 397B flagship is datacenter-only and untested. The fourth Qwen-family coding tune to regress on the real anchor — only pi-tune, trained on real agent traces, improved. |
|
| 145 |
+
| [Swap the agent harness, not the model: a +1/12 persistence lever](reports/omp-harness-as-variable.md) · [chart](reports/omp-harness-as-variable.png) | How much of an agentic-coding score is the model and how much is the harness wrapped around it? Held the model fixed (Qwen3.6-27B-Q6_K, one local llama-server on a 5090, think-off, temp 0) and swapped only the agent scaffold, graded on 12 SWE-bench Verified bugs with the official harness. The rig-native tool loop (40-step budget) resolves 8/12; omp v16.1.14 (a deps-free CLI agent, 450s budget, same model and `:8090` endpoint) resolves 9/12 — a strict superset, the lone delta being sphinx-8621. The mechanism is persistence, not reasoning: on the 4 hard bugs the native loop committed no patch (gave up) 3 times, omp once; omp lands patches where native quits, and one of those passed. Both harnesses miss the same 3 bugs (seaborn-3187, requests-1921, pylint-7080) — same model, same ceiling, so the scaffold only moves the give-up rate. Empty-patch rate is the give-up tell, here separating two harnesses on a fixed model. Honest limits: n=12 single seed, so the +1 is inside the noise (the signal is the direction plus the mechanism); the budgets differ by construction (steps vs wall-clock), which is the point — a harness is prompt plus tools plus stopping policy, bundled. The inverse of the Ornith-1.0 claim the rig tests next (RL that bakes the scaffold into training). |
|
| 146 |
+
| [Qwen-AgentWorld's zero-fine-tune transfer doesn't reproduce on a 5090](reports/agentworld-lwm-transfer.md) · [chart](reports/agentworld-lwm-transfer.png) | Qwen-AgentWorld (arXiv 2606.24597) trains a language world model to predict environment transitions and claims the warm-up transfers to agentic tasks with zero agent fine-tuning, +3.4-12.8%. Tested the released LWM-warmed 35B-A3B against its own base Qwen3.5-35B-A3B in a think-OFF/temp-0 controlled A/B on one RTX 5090. The synthetic agentic board is flat (97.5 = 97.5, a saturated axis that hides differences); the real SWE-bench Verified anchor (30 bugs, official harness) goes 14/30 vs the base's 16/30 — a reshuffle rather than a collapse (11 solved by both, 3 AgentWorld-only, 5 base-only), net -2 with more give-ups (13 empty patches vs 10, mean 33/40 steps: it explores more and commits fewer fixes). The claimed +3.4-12.8% transfer lands at 0% on synthetic and -12.5% on real coding. A scoped null: think-OFF to match the base's banked number, so it doesn't refute a think-ON gain (that A/B is the queued falsification leg), and it tests the SWE-coding slice of a seven-domain claim. |
|
| 147 |
+
| [FP4 on a consumer 5090: the Blackwell headline loses to plain int4](reports/fp4-consumer-blackwell.md) · [chart](reports/fp4-consumer-blackwell.png) | FP4 is the Blackwell selling point — benchmarked on one RTX 5090 (sm_120) against the quants you'd actually run, Qwen3-14B in vLLM 0.21. Two findings that compound. (1) NVFP4 is the only quant that won't run out of the box: AWQ/FP8 use prebuilt Marlin kernels, but NVFP4 makes FlashInfer JIT-compile native sm_120 FP4 cutlass kernels at load — needing ninja on PATH + a real CUDA toolkit + the correct CUDA_HOME (the default /usr/local/cuda-13.0 doesn't exist on the box) + a flashinfer-cache clear. (2) Once native FP4 is genuinely running (declared modelopt_fp4, not a Marlin dequant fallback), it's still slower than AWQ int4 at every batch: batch-1 decode AWQ 150 vs NVFP4 100 (0.66x) vs FP8 90; batch-32 AWQ 3937 vs NVFP4 3321. The 4-6x FP4 numbers are B200 tensor-core throughput; on consumer sm_120 a mature int4-Marlin kernel wins. bf16-14B doesn't fit 32GB (no KV room). (3) The academic real-FP4 path (QuTLASS MXFP4, arXiv 2509.23202), built from source on sm_120a (CUTLASS submodule, torch 2.8/cu128, forced -ccbin g++-14 past the GCC-15/CUDA-12.8 guard): its 4x is real at the GEMM — the MXFP4 matmul crosses 4x by batch 128 and peaks ~6x over bf16 on Qwen3-8B — but end-to-end decode runs 3-4x slower than bf16 (20.4 vs 78.6 tok/s at batch 1) and uses ~2x the VRAM, because decode is memory-bound and pays a fixed per-layer rotation+quant tax the tiny matmul can't amortise. Verdict: use AWQ int4 for serving, skip NVFP4 on consumer Blackwell; QuTLASS MXFP4 only pays off for compute-bound high-batch/prefill work, not single-stream serving. |
|
| 148 |
+
| [One-Shot EM doesn't reproduce on a 5090: entropy fell, accuracy didn't](reports/one-shot-em.md) · [chart](reports/one-shot-em.png) | One-Shot Entropy Minimization (arXiv 2505.20282) claims +24.7 on Qwen2.5-Math-7B from ONE unlabeled example in ~10 steps, no rewards. The full-param recipe OOMs on 32GB (14GB weights + 14GB bf16 grads), so the consumer-feasible version is LoRA (batch 16). Measured greedy pass@1 with the authors' grader: base reproduces the paper (MATH500 53.4 vs 53.0), but EM adds +2.0 at its peak step then collapses back by step 15, and AMC23 goes −2.5 (claim was +25.8 / +26.2). The keeper is the mechanism: the entropy objective trained fine (mean per-token entropy 0.098→0.035) while accuracy stayed flat — distribution-sharpening, not learning, in the paper's own words. Same base as Spurious Rewards (+21 on MATH500 from random rewards). Honest limits: full-param didn't fit, so this isn't a refutation of the multi-GPU number; the few-shot format control backfired on Qwen-Math's native zero-shot CoT. |
|
| 149 |
+
| [Draft-free spec-decode on Qwen3-8B: workload split + dumb-vs-fancy null](reports/cacheback-spec-decode.md) · [chart](reports/cacheback-spec-decode.png) | Cache-only speculative decoding (no draft model, no extra VRAM) on Qwen3-8B: one greedy loop, three drafters (AR / one-line prompt-lookup / Cacheback's dynamic LRU table) × three workloads. The speedup is workload-shaped, not method-shaped — code 1.45-1.47x, summarize 1.30x, open chat 1.26x, with MAT tracking speedup 1:1, biggest where local agents live and no workload at zero. The null: Cacheback's LRU table ties one-line prompt-lookup (identical on 2/3 workloads, +0.01 MAT on code) — at leader-length 1 they are the same algorithm; Cacheback's real edge is its frozen corpus + tree drafting, not the dynamic table, and the cited "1.86x" is Vicuna-7B + frozen corpus on a 4090, not a modern 8B. Lossless: 46072/46080 tokens byte-identical to greedy; the 8 misses are exact bf16 logit ties (gap 0.000) where greedy itself is non-deterministic, not a decoder bug. |
|
| 150 |
+
| [Sovereign TTS head-to-head: 1.7B Apache beats 4B research-license](reports/tts-head-to-head.md) · [chart](reports/tts-head-to-head.png) | Qwen3-TTS-1.7B (Apache) vs Fish-S2-Pro (4B, research license) on one RTX 5090, 150 Seed-TTS-eval EN utterances, both bf16 and neither compiled. Round-trip WER is a tie (0.6% each — Fish's sub-1% claim holds, Qwen matches it); SIM-o 0.699 vs 0.625; but RTFx 2.22× vs 0.39× and first-audio latency 1.72s vs 9.74s. Fish-S2-Pro's serving stack assumes SGLang + torch.compile + datacenter cards (its RTF<0.5 is an H200 number) — out-of-the-box on a consumer GPU the small open model is 5.7× faster at the same intelligibility. Size + serving assumptions, not quality. A compiled-Fish rerun is the obvious follow-up. |
|
| 151 |
+
| [GLM-5.2 autopsy: clever MLA+DSA, still datacenter-only](reports/glm-5-2-autopsy.md) · [chart](reports/glm-5-2-walls.png) | The biggest open-weights drop in months (743B MoE, MIT, 1M context), measured by arithmetic from the published config — not served. Credit first: `glm_moe_dsa` = MLA + DeepSeek sparse attention compresses the KV cache ~57× (1M = ~88 GiB vs ~4.9 TiB). But the weights can't fit 96GB addressable at any quant (743B needs 1.03 bits/weight; smallest ~1.58-bit = ~147 GB), the 1M KV alone ≈ the whole machine, and DSA saves compute not memory. ~235 GB to use 1M context — past a single H200. Clever ≠ consumer; the home-lab move is to wait for a GLM-5.2-Air. |
|
| 152 |
+
| [Qwen3.6-27B pi-tune: the coding tune that works](reports/qwen3-6-27b-pi-tune.md) · [chart](reports/pi-tune-provenance.png) | A community QLoRA SFT of Qwen3.6-27B on REAL non-thinking agent traces, measured controlled vs its base at matched Q6_K across four legs. Quality (93.3 vs 94.0) and synthetic Agentic Score (98.01 vs 98.61) stay flat — but real SWE-bench Verified resolve goes UP 19 → 20/30 (give-ups 8 → 6) and the MTP drafter holds (2.0-2.4× vs base 1.8-2.2×) where Qwopus-Coder's degraded. The first of three Qwen3.6-27B coding tunes to improve real bug-fixing: across all three the synthetic score is a 2.4pt band while real SWE spans 11-20, so training-data provenance (real traces > synthetic distill), not the "agentic coder" label, is what the anchor sees. |
|
| 153 |
+
| [Qwable-5-27B-Coder: real traces, still regresses](reports/qwable-5-27b-coder.md) · [chart](reports/qwable-5-anchor.png) | A real-trace SFT of Qwen3.6-27B (Claude Fable-5 then Kimi 2.7 Coder agent traces), measured controlled vs its base at matched Q6_K. Quality (93.7 vs 94.0) AND the synthetic Agentic Score (98.61 vs 98.61, identical to the decimal) stay flat — but real SWE-bench Verified resolve drops 19 → 17/30 and give-ups rise 8 → 10. The 4th Qwen3.6-27B coding tune on the anchor: real traces are necessary but not sufficient (pi-tune's terminal/repo/DevOps traces remain the only data that moved real resolve up). The MTP drafter survived the SFT (1.9-2.4×, base range) — so drafter-survival is not capability-preservation. |
|
| 154 |
+
| [Qwable-3.6-27b: the distill every cheap eval passes, SWE-bench fails](reports/qwable-3.6-27b-q4.md) · [chart](reports/qwable-27b-flat-cliff.png) | A dense Qwen3.6-27B + Fable-5-style SFT, measured controlled vs its base at matched Q4_K_M. Quality (93.4 vs 94.0) AND the synthetic Agentic Score (97.64 vs 98.19) stay flat — but real SWE-bench Verified resolve drops 18 → 11/30 and give-ups rise 7 → 13. Quant ruled out (base Q6 → Q4 = −1 bug). The agentic board would call it neutral; only the reality anchor caught the give-up regression — a 3rd failure mode, and the inverse of the MoE Qwable-v1 (whose synthetic honestly declined). |
|
| 155 |
+
| [Qwable-v1: agentic distillation regresses vs base](reports/qwable-v1.md) · [chart](reports/qwable-decline.png) | A Claude-Code/Fable-5-distilled "agentic coder" (Qwen3.6-35B-A3B) measured controlled vs its vanilla base + the Opus-reasoning-distill, same Q5_K_M. Every post-train step LOWERS the agentic score (99.58 → 97.92 → 96.25), and real SWE-bench Verified resolve drops 19 → 11/30 with give-ups nearly doubling (9 → 16 empty patches). Not a mirage — synthetic fairly predicts real here; the distillation regressed a top-tier base (the vanilla base ties best real resolve on the board). |
|
| 156 |
+
| [ECHO maze microcosm](reports/echo-maze-microcosm.md) · [chart](reports/echo-maze-microcosm.png) | ECHO's "world model for free" env-token loss, isolated in a 10M from-scratch maze transformer (behavior cloning; the only A/B is the loss mask). A clean null under both observation regimes — full-obs and walls-only — every gap inside the seed spread, no growth with maze size. The free aux loss is worth exactly that in pure imitation; the reported gain must live in ECHO's on-policy RL coupling, not the loss as a plug-in. (The paper has no maze — this microcosm is original, verified by grepping the source + repo.) |
|
| 157 |
+
| [Spec-decode three-way (Gemma 4 26B-A4B)](reports/specdecode-gemma-4-26b-a4b.md) · [chart](reports/specdecode-gemma-4-26b-a4b.png) | MTP vs EAGLE-3 vs DFlash on one RTX 5090 (vLLM 0.21, sm_120), including the EAGLE-3 leg nobody publishes. Single-stream near-tie: DFlash 2.19x, MTP 2.13x, EAGLE-3 1.69x — DFlash is feast-or-famine (prose 1.04x, repetitive 4.37x), MTP the steady all-rounder. Six consumer-Blackwell fixes to run it at all (NVFP4 to MARLIN, FLEX_ATTENTION for the #42068 attention deadlock) plus a self-caught /metrics parser bug. Dense 31B excluded: no clean quant fits 32GB. |
|
| 158 |
+
| [Qwopus3.6-27B-Coder](reports/qwopus-coder-27b.md) · [chart](reports/qwopus-coder-chart.png) | Four legs measured: q_avg 94.1 (#2 thinking-off, beats its base at a smaller quant); "100 tps" MTP verified (96-114 t/s) but the finetuned head accepts worse than the original (1.4-1.6x vs 1.8-2.2x); a perfect 100 Agentic Score — and 57% real SWE-bench resolve, *below its own base* (63%). Trained on Hermes traces: the in-distribution mirage the reality anchor was built to catch. 67% claim doesn't reproduce. |
|
| 159 |
+
| [Qwopus3.6-27B-Coder-Compat: the regressions healed](reports/qwopus-coder-compat.md) · [chart](reports/qwopus-coder-compat-recovery.png) | The "compatibility" re-release of Qwopus-Coder, measured controlled vs base Qwen3.6-27B + the prior Coder at matched Q6_K (think-off, temp 0). Quality flat (q_avg 93.7). The prior tune's two regressions both heal: the degraded MTP draft head recovers 1.4-1.6x → 1.9-2.3x (back on the base curve), and real SWE-bench Verified resolve returns to base parity — 8/12, the exact same bugs as base, +1 over the prior tune (recovers pytest-6202) with one fewer give-up. Agentic Score 100.0 ties the prior (saturated — the synthetic axis can't separate the two; the anchor can). A compat fix that costs no capability: the coder tune no longer carries a drafter or real-bug penalty. |
|
| 160 |
+
| [Keye-VL-2.0-30B autopsy](reports/keye-vl-2-autopsy.md) · [chart](reports/keye-walls-chart.png) | Five measured walls: "lossless 256K" needs 25.8GB of KV alone; the shipped sparse attention is O(N²)-memory (one 30.65GiB allocation at ~32K, measured); 4-bit quant reaches 4.7% of params; the code's API window is two transformers release candidates wide. Does not run on consumer hardware. |
|
| 161 |
+
| [LocateAnything-3B](reports/locateanything-3b.md) · [chart](reports/la-screenspot-chart.png) · [raw](raw/la-screenspot.jsonl) | ScreenSpot-Pro 55.3% measured vs 60.3 claimed (32GB forces extra downscale; accuracy tracks screenshot size). Real fault line: text 63.2% vs icons 42.7%. PBD parallel box decoding verified at 2.07x on the SDPA fallback. |
|
| 162 |
+
| [HRM-Text-1B](reports/hrm-text-1b.md) · [chart](reports/hrm-trap.png) · [raw gens](raw/) | GSM8K 79.5% (claimed 84.5: holds at n=200). Omitting `token_type_ids` — which every standard harness does — silently costs 26 points. The recurrence bill: a 1.2B that decodes like a ~5B (42.9 tok/s bf16, 4x KV cache). |
|
| 163 |
+
| [DiffusionGemma vs AR](reports/diffusion-vs-ar.md) · [chart](reports/diffusion-vs-ar.png) | AR wins at every answer length: diffusion pays a fixed ~3s per 256-token canvas (0.8 effective tok/s on short answers; best case still 2.3x slower). Day-0 public GGUFs were unloadable — convert from source. |
|
| 164 |
+
| [Gemma 4 31B QAT + MTP](reports/gemma4-31b-qat-mtp.md) · [chart](reports/gemma4-qat-speed.png) | The MTP draft head lifts decode 76 to 125 tok/s (1.67x). QAT's real value is VRAM, not quality: the Q4 footprint is what fits 128K context plus the draft head on one card. |
|
| 165 |
+
| [NVFP4 vs Q6_K](reports/nvfp4-vs-q6-qwen3-6-27b.md) · [chart](reports/chart-nvfp4-vs-q6.png) | Qwen3.6-27B: NVFP4 trades ~1pt q_avg against Q6_K. |
|
| 166 |
+
| [GRPO on one 5090](reports/fp8-rl-grpo.md) · [chart](reports/chart-grpo-gsm8k.png) | Single-GPU RL: +7.66 GSM8K on a 4B. Train-prompt-to-eval-prompt alignment is the lever. |
|
| 167 |
+
| [Embedding retrieval bench](reports/embedding-retrieval-bench.md) · [chart](reports/embed-bench-scatter.png) | Local embedding models benchmarked for retrieval quality vs speed on the 5090. |
|
| 168 |
+
| [Mistral Small 4 speed](reports/mistral-small-4-speed.md) · [chart](reports/mistral-vs-gptoss-speed.png) | Speed profile vs gpt-oss-20b — and a benchmarking trap: reasoning is gated behind `reasoning_effort`, which defaults off. |
|
| 169 |
+
| [LFM2.5-VL 1.6B extraction](reports/lfm2-5-vl-1-6b-extract.md) · [chart](reports/chart-lfm2-vl-extract.png) | A 1.6B VL model as a local structured-data extractor. |
|
| 170 |
+
| [Nex-N2-mini agentic probe](reports/agentic-nex-n2-mini.md) | Adaptive Thinking saves 65% of tokens but costs 13pts task success. Superseded by the dedicated Agentic Score leaderboard (below). |
|
| 171 |
+
|
| 172 |
+
## Related Datasets
|
| 173 |
+
|
| 174 |
+
- [witcheer/agentic-score-leaderboard](https://huggingface.co/datasets/witcheer/agentic-score-leaderboard) — model-agnostic agentic tool-calling benchmark (7 models, 40 tasks) + the SWE-bench reality anchor
|
| 175 |
+
- [witcheer/sovereign-asr-bench](https://huggingface.co/datasets/witcheer/sovereign-asr-bench) — local ASR on the 5090: Parakeet-TDT vs Whisper (WER / RTFx / VRAM)
|
| 176 |
+
|
| 177 |
+
---
|
| 178 |
+
|
| 179 |
+
## Hardware
|
| 180 |
+
|
| 181 |
+
| Component | Spec |
|
| 182 |
+
|-----------|------|
|
| 183 |
+
| GPU | NVIDIA GeForce RTX 5090 32GB (Blackwell, sm_120a) |
|
| 184 |
+
| CPU | AMD Ryzen 5 9600 (6c/12t) |
|
| 185 |
+
| RAM | 64GB DDR5-5600 |
|
| 186 |
+
| OS | Ubuntu 26.04 LTS |
|
| 187 |
+
| CUDA | 12.8 (patched for glibc 2.41) |
|
| 188 |
+
|
| 189 |
+
## Tooling
|
| 190 |
+
|
| 191 |
+
All benchmarks generated with [llm-bench-rig](https://github.com/notwitcheer/llm-bench-rig) — open-source pipeline for speed and quality benchmarks on GGUF and safetensors models.
|
benchmarks.csv
ADDED
|
@@ -0,0 +1,50 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
model,architecture,params_b,quant,size_gib,engine,backend,gpu,vram_gb,test,tokens_per_sec,stddev,date
|
| 2 |
+
Qwen3.6-35B-A3B,MoE (3B active),34.66,UD-Q4_K_M,20.61,llama.cpp,CUDA,RTX 5090,32,pp128,3605.03,48.69,2026-05-28
|
| 3 |
+
Qwen3.6-35B-A3B,MoE (3B active),34.66,UD-Q4_K_M,20.61,llama.cpp,CUDA,RTX 5090,32,pp512,9239.86,63.85,2026-05-28
|
| 4 |
+
Qwen3.6-35B-A3B,MoE (3B active),34.66,UD-Q4_K_M,20.61,llama.cpp,CUDA,RTX 5090,32,pp2048,9041.04,65.96,2026-05-28
|
| 5 |
+
Qwen3.6-35B-A3B,MoE (3B active),34.66,UD-Q4_K_M,20.61,llama.cpp,CUDA,RTX 5090,32,pp4096,8760.53,53.07,2026-05-28
|
| 6 |
+
Qwen3.6-35B-A3B,MoE (3B active),34.66,UD-Q4_K_M,20.61,llama.cpp,CUDA,RTX 5090,32,pp8192,8442.99,37.16,2026-05-28
|
| 7 |
+
Qwen3.6-35B-A3B,MoE (3B active),34.66,UD-Q4_K_M,20.61,llama.cpp,CUDA,RTX 5090,32,pp16384,7713.79,15.46,2026-05-28
|
| 8 |
+
Qwen3.6-35B-A3B,MoE (3B active),34.66,UD-Q4_K_M,20.61,llama.cpp,CUDA,RTX 5090,32,tg128,270.97,1.24,2026-05-28
|
| 9 |
+
Qwen3.6-27B,Dense,26.90,Q4_K_M,15.66,llama.cpp,CUDA,RTX 5090,32,pp128,2972.93,322.84,2026-05-28
|
| 10 |
+
Qwen3.6-27B,Dense,26.90,Q4_K_M,15.66,llama.cpp,CUDA,RTX 5090,32,pp512,3825.83,41.56,2026-05-28
|
| 11 |
+
Qwen3.6-27B,Dense,26.90,Q4_K_M,15.66,llama.cpp,CUDA,RTX 5090,32,pp2048,3740.84,1.29,2026-05-28
|
| 12 |
+
Qwen3.6-27B,Dense,26.90,Q4_K_M,15.66,llama.cpp,CUDA,RTX 5090,32,pp4096,3644.93,2.76,2026-05-28
|
| 13 |
+
Qwen3.6-27B,Dense,26.90,Q4_K_M,15.66,llama.cpp,CUDA,RTX 5090,32,pp8192,3484.57,7.20,2026-05-28
|
| 14 |
+
Qwen3.6-27B,Dense,26.90,Q4_K_M,15.66,llama.cpp,CUDA,RTX 5090,32,pp16384,3161.79,3.66,2026-05-28
|
| 15 |
+
Qwen3.6-27B,Dense,26.90,Q4_K_M,15.66,llama.cpp,CUDA,RTX 5090,32,tg128,77.09,0.16,2026-05-28
|
| 16 |
+
Nemotron-3-Nano-30B-A3B,MoE (3B active),31.58,Q4_K_M,22.88,llama.cpp,CUDA,RTX 5090,32,pp128,4423.05,74.78,2026-05-28
|
| 17 |
+
Nemotron-3-Nano-30B-A3B,MoE (3B active),31.58,Q4_K_M,22.88,llama.cpp,CUDA,RTX 5090,32,pp512,10674.44,108.43,2026-05-28
|
| 18 |
+
Nemotron-3-Nano-30B-A3B,MoE (3B active),31.58,Q4_K_M,22.88,llama.cpp,CUDA,RTX 5090,32,pp2048,10277.54,40.85,2026-05-28
|
| 19 |
+
Nemotron-3-Nano-30B-A3B,MoE (3B active),31.58,Q4_K_M,22.88,llama.cpp,CUDA,RTX 5090,32,pp4096,9999.48,26.46,2026-05-28
|
| 20 |
+
Nemotron-3-Nano-30B-A3B,MoE (3B active),31.58,Q4_K_M,22.88,llama.cpp,CUDA,RTX 5090,32,pp8192,9448.36,34.02,2026-05-28
|
| 21 |
+
Nemotron-3-Nano-30B-A3B,MoE (3B active),31.58,Q4_K_M,22.88,llama.cpp,CUDA,RTX 5090,32,pp16384,8558.68,16.72,2026-05-28
|
| 22 |
+
Nemotron-3-Nano-30B-A3B,MoE (3B active),31.58,Q4_K_M,22.88,llama.cpp,CUDA,RTX 5090,32,tg128,363.69,1.58,2026-05-28
|
| 23 |
+
gpt-oss-20b,Dense,20.91,Q4_K_M,10.81,llama.cpp,CUDA,RTX 5090,32,pp128,7220.69,67.12,2026-05-28
|
| 24 |
+
gpt-oss-20b,Dense,20.91,Q4_K_M,10.81,llama.cpp,CUDA,RTX 5090,32,pp512,16749.65,148.73,2026-05-28
|
| 25 |
+
gpt-oss-20b,Dense,20.91,Q4_K_M,10.81,llama.cpp,CUDA,RTX 5090,32,pp2048,13524.44,12.42,2026-05-28
|
| 26 |
+
gpt-oss-20b,Dense,20.91,Q4_K_M,10.81,llama.cpp,CUDA,RTX 5090,32,pp4096,11684.53,43.99,2026-05-28
|
| 27 |
+
gpt-oss-20b,Dense,20.91,Q4_K_M,10.81,llama.cpp,CUDA,RTX 5090,32,pp8192,9413.7,16.38,2026-05-28
|
| 28 |
+
gpt-oss-20b,Dense,20.91,Q4_K_M,10.81,llama.cpp,CUDA,RTX 5090,32,pp16384,6677.6,14.13,2026-05-28
|
| 29 |
+
gpt-oss-20b,Dense,20.91,Q4_K_M,10.81,llama.cpp,CUDA,RTX 5090,32,tg128,367.9,1.18,2026-05-28
|
| 30 |
+
Qwen3.6-27B-MTP,Dense (MTP),27.32,Q4_K_M,15.92,llama.cpp,CUDA,RTX 5090,32,pp128,2972.2,321.87,2026-05-28
|
| 31 |
+
Qwen3.6-27B-MTP,Dense (MTP),27.32,Q4_K_M,15.92,llama.cpp,CUDA,RTX 5090,32,pp512,3835.77,43.26,2026-05-28
|
| 32 |
+
Qwen3.6-27B-MTP,Dense (MTP),27.32,Q4_K_M,15.92,llama.cpp,CUDA,RTX 5090,32,pp2048,3746.68,1.53,2026-05-28
|
| 33 |
+
Qwen3.6-27B-MTP,Dense (MTP),27.32,Q4_K_M,15.92,llama.cpp,CUDA,RTX 5090,32,pp4096,3655.53,9.44,2026-05-28
|
| 34 |
+
Qwen3.6-27B-MTP,Dense (MTP),27.32,Q4_K_M,15.92,llama.cpp,CUDA,RTX 5090,32,pp8192,3495.59,4.04,2026-05-28
|
| 35 |
+
Qwen3.6-27B-MTP,Dense (MTP),27.32,Q4_K_M,15.92,llama.cpp,CUDA,RTX 5090,32,pp16384,3161.77,3.81,2026-05-28
|
| 36 |
+
Qwen3.6-27B-MTP,Dense (MTP),27.32,Q4_K_M,15.92,llama.cpp,CUDA,RTX 5090,32,tg128,76.99,0.09,2026-05-28
|
| 37 |
+
Qwen3-Coder-Next,MoE,79.67,UD-Q2_K_XL,24.92,llama.cpp,CUDA,RTX 5090,32,pp128,2381.32,29.12,2026-05-28
|
| 38 |
+
Qwen3-Coder-Next,MoE,79.67,UD-Q2_K_XL,24.92,llama.cpp,CUDA,RTX 5090,32,pp512,4447.3,39.42,2026-05-28
|
| 39 |
+
Qwen3-Coder-Next,MoE,79.67,UD-Q2_K_XL,24.92,llama.cpp,CUDA,RTX 5090,32,pp2048,4420.86,35.94,2026-05-28
|
| 40 |
+
Qwen3-Coder-Next,MoE,79.67,UD-Q2_K_XL,24.92,llama.cpp,CUDA,RTX 5090,32,pp4096,4380.75,11.49,2026-05-28
|
| 41 |
+
Qwen3-Coder-Next,MoE,79.67,UD-Q2_K_XL,24.92,llama.cpp,CUDA,RTX 5090,32,pp8192,4250.74,14.71,2026-05-28
|
| 42 |
+
Qwen3-Coder-Next,MoE,79.67,UD-Q2_K_XL,24.92,llama.cpp,CUDA,RTX 5090,32,pp16384,4042.73,18.93,2026-05-28
|
| 43 |
+
Qwen3-Coder-Next,MoE,79.67,UD-Q2_K_XL,24.92,llama.cpp,CUDA,RTX 5090,32,tg128,224.87,1.86,2026-05-28
|
| 44 |
+
Gemma 4 12B,Dense,11.91,Q6_K,9.1,llama.cpp,CUDA,RTX 5090,32,pp128,5099.28,452.85,2026-06-04
|
| 45 |
+
Gemma 4 12B,Dense,11.91,Q6_K,9.1,llama.cpp,CUDA,RTX 5090,32,pp512,7160.37,149.07,2026-06-04
|
| 46 |
+
Gemma 4 12B,Dense,11.91,Q6_K,9.1,llama.cpp,CUDA,RTX 5090,32,pp2048,6788.28,10.42,2026-06-04
|
| 47 |
+
Gemma 4 12B,Dense,11.91,Q6_K,9.1,llama.cpp,CUDA,RTX 5090,32,pp4096,6605.39,1.81,2026-06-04
|
| 48 |
+
Gemma 4 12B,Dense,11.91,Q6_K,9.1,llama.cpp,CUDA,RTX 5090,32,pp8192,6359.06,5.49,2026-06-04
|
| 49 |
+
Gemma 4 12B,Dense,11.91,Q6_K,9.1,llama.cpp,CUDA,RTX 5090,32,pp16384,5846.08,5.21,2026-06-04
|
| 50 |
+
Gemma 4 12B,Dense,11.91,Q6_K,9.1,llama.cpp,CUDA,RTX 5090,32,tg128,122.3,0.19,2026-06-04
|
raw/hrm-gsm8k-synth-cot-n200.jsonl
ADDED
|
The diff for this file is too large to render.
See raw diff
|
|
|
raw/hrm-gsm8k-synth-cot-nomask-n200.jsonl
ADDED
|
The diff for this file is too large to render.
See raw diff
|
|
|
raw/la-screenspot.jsonl
ADDED
|
The diff for this file is too large to render.
See raw diff
|
|
|
reports/ace-step-music.md
ADDED
|
@@ -0,0 +1,56 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Making music on a gaming GPU: ACE-Step 1.5 on one RTX 5090
|
| 2 |
+
|
| 3 |
+
**A full 4-minute song in under 2 seconds, on a consumer graphics card.** ACE-Step 1.5 is an open-weights text-to-music model. Point it at one RTX 5090 (the current top gaming GPU) and it writes a complete 4-minute track in about 1.75 seconds of compute. That is roughly what the model's makers report for a datacenter A100, and about 6x faster than the last-gen RTX 3090 they also cite. These are the first numbers for this model on consumer Blackwell (sm_120).
|
| 4 |
+
|
| 5 |
+
The point of the benchmark is simple: you do not need a data center to make music with AI. A card you can buy for a gaming PC does it faster than the song plays.
|
| 6 |
+
|
| 7 |
+
## The numbers
|
| 8 |
+
|
| 9 |
+
Two model sizes, both the fast "turbo" variant (8 diffusion steps). Each cell is 6 prompts across different genres, one seed, warm-up discarded.
|
| 10 |
+
|
| 11 |
+
| model | 30s song | 2-min song | 4-min song | vs real-time (4-min) | peak VRAM |
|
| 12 |
+
|---|---|---|---|---|---|
|
| 13 |
+
| **2B turbo** | 0.37s | 0.92s | **1.75s** | **137x faster** | 9.4 GB |
|
| 14 |
+
| **XL 4B turbo** (higher quality) | 0.58s | 1.43s | **2.9s** | **83x faster** | 14.8 GB |
|
| 15 |
+
|
| 16 |
+
Times are generation compute (diffusion + audio decode), the same basis as the vendor's own figures. Writing the file to disk adds about 0.2 to 0.4s. Real-time factor (RTF) is song length divided by generation time: 137x means the 4-minute song is written 137 times faster than you could listen to it.
|
| 17 |
+
|
| 18 |
+
**Where the 5090 lands.** ACE-Step's team reports the 2B turbo at roughly 1 to 2 seconds per 4-minute song on an A100 80GB, and under 10 seconds on an RTX 3090. The 5090 comes in at 1.75s: level with the datacenter card, and far ahead of the 3090. And this is the plain out-of-box path (bf16, no torch.compile, no quantization), so it is a floor, not a ceiling.
|
| 19 |
+
|
| 20 |
+
## Three things worth knowing
|
| 21 |
+
|
| 22 |
+
**1. The fast tier is A100-class on a gaming card.** 1.75s for a 4-minute song is the headline. A card built for games keeps pace with a card built for data centers, on a model anyone can download.
|
| 23 |
+
|
| 24 |
+
**2. Quality costs time, and not much of it.** The XL 4B model is the higher-quality tier. It takes about 1.65x longer than the 2B (2.9s vs 1.75s for a 4-minute song) and about 60% more memory. Still under 3 seconds, still on a single card. Listen to the paired samples and decide whether your ear wants the bigger model.
|
| 25 |
+
|
| 26 |
+
**3. Longer songs are proportionally cheaper.** RTF climbs from 81x at 30 seconds to 137x at 4 minutes for the 2B model. Because the step count is fixed at 8 regardless of length, the fixed overhead spreads thinner over a longer track. A 4-minute song is not 8x the work of a 30-second one; it is closer to 5x.
|
| 27 |
+
|
| 28 |
+
## What we did not measure
|
| 29 |
+
|
| 30 |
+
Speed is the finding here. Audio *quality* is not scored: "which song sounds better" is a subjective call, and a made-up number would not help. Instead the run saves the actual songs, and the paired 2B-vs-XL clips are attached so you can judge by ear. A quality-alignment score (does the audio match the prompt) is the natural follow-up.
|
| 31 |
+
|
| 32 |
+
The run is DiT-only: the diffusion model generates directly from a text caption, with no planning language model in front. That matches how the vendor measured the speed claim, and it is the path most people will use.
|
| 33 |
+
|
| 34 |
+
## Config
|
| 35 |
+
|
| 36 |
+
DiT-only, bf16, SDPA attention (flash-attn not required on sm_120), 8-step turbo, guidance off (turbo has no CFG), batch size 1, seed 0, 48 kHz stereo. RTX 5090 32GB, torch 2.10.0+cu128, ACE-Step 1.5 (v0.1.8). No torch.compile, no quantization. Donald (the box's resident model server) drained for the GPU window and restored after.
|
| 37 |
+
|
| 38 |
+
## Reproduce
|
| 39 |
+
|
| 40 |
+
```
|
| 41 |
+
# capsule (RTX 5090), in the ACE-Step 1.5 clone + its uv env:
|
| 42 |
+
ACESTEP_INIT_LLM=false .venv/bin/python ace_synth.py \
|
| 43 |
+
--model-tier 2b --config-path acestep-v15-turbo \
|
| 44 |
+
--prompts prompts.json --durations 30,120,240 --steps 8 --seed 0 \
|
| 45 |
+
--out-dir ~/ace-out --synth-json ~/ace-out/synth-2b.json --save-audio
|
| 46 |
+
# (repeat with --model-tier xl --config-path acestep-v15-xl-turbo)
|
| 47 |
+
|
| 48 |
+
# Mac: aggregate + chart
|
| 49 |
+
python3 -m scripts.ace_bench --synth results/ace_step/synth-2b.json results/ace_step/synth-xl.json \
|
| 50 |
+
--out results/ace_step/ace-step-music.json
|
| 51 |
+
python3 scripts/chart_ace.py
|
| 52 |
+
```
|
| 53 |
+
|
| 54 |
+
Prompt set (`dataset/ace_step/prompts.json`): pop, lo-fi, orchestral, EDM, acoustic, hip-hop. Metric helpers `lib/ace_step/` (RTF, aggregation) are unit-tested.
|
| 55 |
+
|
| 56 |
+
*Model: [ACE-Step 1.5](https://github.com/ace-step/ACE-Step-1.5) (Apache-2.0), paper [arXiv 2602.00744](https://arxiv.org/abs/2602.00744). First RTX-5090/sm_120 figures.*
|
reports/ace-step-music.png
ADDED

|
Git LFS Details
|
reports/agentic-nex-n2-mini.md
ADDED
|
@@ -0,0 +1,66 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Agentic post-training, measured: Nex-N2-mini vs its base — on one RTX 5090
|
| 2 |
+
|
| 3 |
+
**Rig:** single RTX 5090 32GB · llama.cpp b9562 · native OpenAI tool-calling (`--jinja`) · temp 0
|
| 4 |
+
**Subjects:** `Nex-N2-mini` (35B-A3B, agentic post-train) vs its base `Qwen3.5-35B-A3B`, both Q4_K_M
|
| 5 |
+
**Harness:** the rig's new **Agentic Score** — a model-agnostic native tool-calling loop over 15
|
| 6 |
+
deterministic, programmatically-checked tasks (tool-use chains, multi-step dependencies, sandboxed
|
| 7 |
+
coding). Calibration-grade, not SWE-bench; a sub-5% gap is a tie.
|
| 8 |
+
|
| 9 |
+
---
|
| 10 |
+
|
| 11 |
+
## The finding
|
| 12 |
+
|
| 13 |
+
Nex-N2's headline claim is that "Adaptive Thinking" cuts ~20% of tokens at zero performance loss. On
|
| 14 |
+
this rig, **the token claim is not just true — it's an understatement.** Nex-N2-mini does the same
|
| 15 |
+
agentic work in **93 tokens/task vs the base's 264 — a 65% cut, ~2.8x leaner.** But "zero performance
|
| 16 |
+
loss" does **not** hold: the post-train trades **13 points of task success** for that efficiency.
|
| 17 |
+
|
| 18 |
+
| axis | base Qwen3.5-35B-A3B | Nex-N2-mini | read |
|
| 19 |
+
|---|---|---|---|
|
| 20 |
+
| **Agentic Score** | **98.0** | 92.0 | base wins overall |
|
| 21 |
+
| Task success | **100%** (15/15) | 86.7% (13/15) | base completes more |
|
| 22 |
+
| Tool efficiency | 0.90 | **0.933** | Nex slightly tighter |
|
| 23 |
+
| Loop stability | 100% | 100% | tie — neither stalls |
|
| 24 |
+
| **Tokens / task** | 264.3 | **93.3** | **Nex −65%** |
|
| 25 |
+
|
| 26 |
+
Per axis, Nex's misses are concentrated: chain 4/5, multistep **5/5**, coding 4/5. The base is clean 5/5/5.
|
| 27 |
+
|
| 28 |
+
## The mechanism (why the post-train loses success)
|
| 29 |
+
|
| 30 |
+
Both failures trace to the *same* cause — terse Adaptive Thinking skips the sanity-check a longer pass
|
| 31 |
+
would have caught:
|
| 32 |
+
|
| 33 |
+
1. **`chain_vram_sq`** — Nex searched (got 32GB), then called `calc("32^2")`. The calculator is Python
|
| 34 |
+
`eval`, where `^` is **XOR**, so it returned **34**. Nex trusted the surprising number and answered
|
| 35 |
+
34. The base used a power/multiply expression and got 1024. *A model that paused on "34 ≠ 32²" would
|
| 36 |
+
have caught it; Nex didn't pause.*
|
| 37 |
+
2. **`coding_sum_evens`** — Nex's code `print()`ed the answer instead of assigning `result` (the tool's
|
| 38 |
+
documented contract), got an error, then **guessed 90** (correct: 110). The base followed the
|
| 39 |
+
contract and verified in the sandbox.
|
| 40 |
+
|
| 41 |
+
Same tools, same prompts, temp 0, both reproduced on a re-run. This is the agentic cost of aggressive
|
| 42 |
+
brevity: fewer tokens, fewer self-checks.
|
| 43 |
+
|
| 44 |
+
## Methodology note (the harness, suspected first)
|
| 45 |
+
|
| 46 |
+
The first Nex run scored 73% — and was **wrong**. Traces showed the mock `web_search` only matched an
|
| 47 |
+
exact key, so the model's reasonable paraphrases ("RTX 5090 specs VRAM GB") returned *"no match"* and it
|
| 48 |
+
looped to the step cap; a second task tripped a safety refusal. Those were **harness artifacts, not
|
| 49 |
+
model weakness.** Fixed (search now tolerates phrasing like a real engine; tasks ground via named tools;
|
| 50 |
+
the safety-trap task reframed), re-ran both models on the identical corrected set. The numbers above are
|
| 51 |
+
from the corrected harness. Suspect the harness before the model — every time.
|
| 52 |
+
|
| 53 |
+
## Worth it?
|
| 54 |
+
|
| 55 |
+
- **Reach for Nex-N2-mini** if tokens, latency, or serving cost dominate and your tasks are
|
| 56 |
+
well-specified — it does the same tool-driving for a third of the tokens, with tighter tool use and
|
| 57 |
+
zero stalls.
|
| 58 |
+
- **Reach for the base** if maximum task completion matters more than token budget — it self-checks
|
| 59 |
+
surprising tool outputs and honors tool contracts that the terse post-train skips.
|
| 60 |
+
|
| 61 |
+
Adaptive Thinking is a real, large efficiency win. Just not a free one.
|
| 62 |
+
|
| 63 |
+
---
|
| 64 |
+
|
| 65 |
+
*Harness: `lib/agentic/native/` in notwitcheer/llm-bench-rig (17 unit tests). Charts:
|
| 66 |
+
`reports/agentic-nex-n2-mini.png`, `reports/agentic-tokens.png`.*
|
reports/agentic-nex-n2-mini.png
ADDED

|
Git LFS Details
|
reports/agentic-tokens.png
ADDED

|
Git LFS Details
|
reports/agentworld-lwm-transfer.md
ADDED
|
@@ -0,0 +1,43 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Qwen-AgentWorld's zero-fine-tune transfer doesn't show up on a 5090: flat on synthetic, down on real coding
|
| 2 |
+
|
| 3 |
+
**Rig:** one RTX 5090 32GB (sm_120) · Qwen-AgentWorld-35B-A3B (UD-Q4_K_M) vs its base Qwen3.5-35B-A3B (Q4_K_M) · llama.cpp, think-OFF, temp 0, native tool-calling · agentic board + SWE-bench Verified anchor (30 bugs, official harness)
|
| 4 |
+
**Question:** Qwen-AgentWorld (arXiv 2606.24597) trains a language world model to predict environment state transitions, and claims that this "LWM warm-up" **transfers to agentic tasks with zero agent fine-tuning, +3.4–12.8%**. Does the released LWM-warmed checkpoint actually act as a stronger agent than the base it was built from?
|
| 5 |
+
|
| 6 |
+
## The numbers
|
| 7 |
+
|
| 8 |
+
| | synthetic agentic board | SWE-bench Verified (real) | empty patches (give-ups) |
|
| 9 |
+
|---|---|---|---|
|
| 10 |
+
| **Qwen3.5-35B-A3B** (base) | 97.5 | **16/30 (53%)** | 10 |
|
| 11 |
+
| **Qwen-AgentWorld-35B-A3B** (LWM-warmed) | 97.5 | **14/30 (47%)** | 13 |
|
| 12 |
+
|
| 13 |
+
Same checkpoint family, same harness, same think-OFF/temp-0 protocol the base's numbers were measured under. The only variable is the LWM warm-up.
|
| 14 |
+
|
| 15 |
+
## Finding 1 — the synthetic board can't see it (97.5 = 97.5)
|
| 16 |
+
|
| 17 |
+
On our native tool-calling Agentic Score, AgentWorld lands **97.5**, identical to the base, with the same 100% task-success and near-identical tool efficiency. This axis saturates near the top (the whole cohort sits in a ~2-point band), so a "flat" here means nothing on its own. It's the reason the rig keeps a real-bug anchor: the synthetic score is where in-distribution gains hide and real differences vanish.
|
| 18 |
+
|
| 19 |
+
## Finding 2 — on the real anchor, the warm-up is a reshuffle, net −2
|
| 20 |
+
|
| 21 |
+
Against 30 real SWE-bench Verified bugs graded by the official harness, AgentWorld resolves **14/30 vs the base's 16/30**. It isn't strictly worse, it's a behaviour change: **11 bugs solved by both, 5 base-only, 3 AgentWorld-only** (it newly fixes `django-16429`, `matplotlib-23314`, `sphinx-8621` that the base missed, while losing five others). So the LWM training moved which problems the model can close, but the net is **−2 with more give-ups: 13 empty patches vs 10**, at a high mean of **33 of 40 steps per bug**. It explores longer and commits fewer fixes — the persistence-under-ambiguity tell, not a capability gain.
|
| 22 |
+
|
| 23 |
+
The claimed +3.4–12.8% transfer lands nowhere on the rig: **0% on the synthetic axis, −12.5% on real resolve.**
|
| 24 |
+
|
| 25 |
+
## What this is, and isn't
|
| 26 |
+
|
| 27 |
+
- **It's a controlled A/B, think-OFF.** Both models ran the exact same protocol the base's 16/30 was measured under, so the comparison is clean and the only moving part is the LWM warm-up. Under that protocol, no positive transfer to real agentic coding.
|
| 28 |
+
- **It is not a refutation of a think-ON number.** AgentWorld is designed to *reason* about environment transitions and recommends thinking mode (temp 0.6). We held thinking OFF to match the base. A think-ON A/B (both models, re-run) is the real falsification leg and is the queued follow-up; a think-OFF null doesn't speak to a think-ON gain.
|
| 29 |
+
- **Scope: the SWE-coding slice.** The paper's +3.4–12.8% spans AgentWorldBench's seven domains (MCP, Search, Terminal, SWE, Web, OS, Android). We tested the one the rig anchors on — real software-bug resolve. No transfer there.
|
| 30 |
+
- **Quant:** AgentWorld ran unsloth UD-Q4_K_M vs the base's bartowski Q4_K_M. The dynamic quant is, if anything, slightly higher quality, so the null is conservative against AgentWorld.
|
| 31 |
+
- **n=30, single seed:** −2/30 is within noise. The honest headline is "no positive transfer," not a strong regression.
|
| 32 |
+
|
| 33 |
+
## Worth it if / not if
|
| 34 |
+
|
| 35 |
+
- **As a drop-in agent, the LWM checkpoint gives a home-lab user nothing over the plain base** on real coding, think-OFF. If you want the best 35B-A3B agent on a 5090 today, the base (or Qwen3.6-27B) is the pick.
|
| 36 |
+
- **The interesting result is for environment simulation, not agency.** AgentWorld's actual job is modelling environments (AgentWorldBench); the "use it as an agent for free" transfer is the part that doesn't carry to real bugs here. Its env-simulation quality is a separate, untested question.
|
| 37 |
+
- **The think-ON regime is the open door.** If the transfer is real, it should appear when the model is allowed to reason. That's the next run.
|
| 38 |
+
|
| 39 |
+
## Repro
|
| 40 |
+
|
| 41 |
+
- Agentic board: `./gate_and_run.sh <gguf> agentworld-35b-a3b` (drains/restores Donald, hard tool-calling gate, then `lib.agentic.native.run_native`). → `results/<slug>/agentic_native.json`.
|
| 42 |
+
- SWE anchor: serve at `-c 32768 --jinja`, `swebench-env/bin/python -m lib.agentic.native.run_swebench <slug> swebench_ids_30.txt` → predictions; grade with the official `swebench.harness.run_evaluation --dataset_name princeton-nlp/SWE-bench_Verified`. → `results/swebench/<slug>.report.json`.
|
| 43 |
+
- Model: `unsloth/Qwen-AgentWorld-35B-A3B-GGUF` (UD-Q4_K_M); base reference `Qwen3.5-35B-A3B` Q4_K_M from `reports/swebench-anchor.md`.
|
reports/agentworld-lwm-transfer.png
ADDED

|
Git LFS Details
|
reports/agentworld-think-on-null.md
ADDED
|
@@ -0,0 +1,39 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Thinking mode isn't hiding Qwen-AgentWorld's transfer either: think-ON is bug-for-bug identical to think-OFF
|
| 2 |
+
|
| 3 |
+
**Rig:** one RTX 5090 32GB (sm_120) · Qwen-AgentWorld-35B-A3B (UD-Q4_K_M) vs base Qwen3.5-35B-A3B (Q4_K_M) · llama.cpp b9653, `--reasoning on`, native tool-calling, temp 0 · same bounded 12-bug SWE-bench Verified subset used for the t082 Ornith harness study, official swebench grader
|
| 4 |
+
**Question:** [The original AgentWorld finding](agentworld-lwm-transfer.md) ran think-OFF to match the base's banked protocol and explicitly scoped out think-ON as "the real falsification" — AgentWorld is designed to reason about environment transitions, so if the claimed transfer needs reasoning to surface, forcing thinking on should reveal it. Does it?
|
| 5 |
+
|
| 6 |
+
## The numbers
|
| 7 |
+
|
| 8 |
+
| resolved / 12 | think-OFF (banked) | think-ON |
|
| 9 |
+
|---|---|---|
|
| 10 |
+
| **Qwen3.5-35B-A3B** (base) | 7 | 7 |
|
| 11 |
+
| **Qwen-AgentWorld-35B-A3B** (LWM-warmed) | 8 | 8 |
|
| 12 |
+
|
| 13 |
+
Same count both ways for both models. But the count hides the real result — look at the per-bug outcomes.
|
| 14 |
+
|
| 15 |
+
## Finding 1 — AgentWorld is bug-for-bug identical, not just count-identical
|
| 16 |
+
|
| 17 |
+
Every one of the 12 bugs gets the exact same classification (resolved / wrong patch / gave up empty) whether thinking is on or off. The 8 resolved are the same 8. The 3 give-ups are the same 3. The 1 wrong-patch is the same 1. Twelve-for-twelve, zero movement. Thinking mode is not suppressing some latent capability here — there is nothing to unlock. Mean steps did tick up slightly with reasoning on (34.4 vs the native loop's typical ~33/40) but it changed nothing about which bugs got fixed.
|
| 18 |
+
|
| 19 |
+
## Finding 2 — the base moves by exactly one wash
|
| 20 |
+
|
| 21 |
+
The base isn't perfectly static: `astropy-12907` flips resolved→give-up and `matplotlib-23314` flips give-up→resolved when reasoning is turned on (`seaborn-3187` also shifts from wrong-patch to give-up, without changing the resolve count). Net zero, and with n=12 this is noise-band movement, not a signal — but it's worth naming precisely rather than waving at "flat."
|
| 22 |
+
|
| 23 |
+
## What this closes
|
| 24 |
+
|
| 25 |
+
The original report explicitly left the door open: *"AgentWorld is designed to reason about environment transitions and recommends thinking mode... a think-ON A/B is the real falsification leg."* This is that leg, and it closes clean: **turning reasoning on does not change AgentWorld's real-bug performance at all.** The −2/30 (or, on this smaller 12-bug slice, the +1/12 edge — see caveats) isn't an artifact of an unfair think-OFF protocol suppressing the LWM warm-up's benefit. The model's behavior on these bugs simply doesn't respond to the think toggle, full stop.
|
| 26 |
+
|
| 27 |
+
## Honest caveats
|
| 28 |
+
|
| 29 |
+
- **n=12, not the original 30.** This reuses the bounded subset already banked for the t082 Ornith harness-as-variable study, chosen for direct comparability and to fit inside a session's time budget. Treat the 8/12 and 7/12 counts as noisy on their own — the load-bearing result is the **per-bug identity** for AgentWorld (12/12 unchanged classifications), which is a stronger, count-independent signal than a resolve-rate delta.
|
| 30 |
+
- **This 12-bug subset flatters AgentWorld relative to the full 30** (8-7 here vs 14-16 over on the full anchor) — expected sampling variance on a 12-bug slice of a 30-bug set, not a contradiction. The 30-bug think-OFF number remains the authoritative anchor result; this run's job was only to test the think toggle, not to re-litigate the resolve rate.
|
| 31 |
+
- **Engineering note, in case it saves someone the same debugging:** there is no literal `--think` flag on this llama.cpp build (b9653) — the switch is `--reasoning on|off|auto` (`--reasoning-format` controls how `<think>` gets extracted into `message.reasoning_content`). Smoke-tested before the real run: `reasoning_content` separates cleanly from `content`, tool-calls still parse correctly alongside it, and round-tripping the full assistant message (content + reasoning_content) back into multi-turn history doesn't break the template or need any harness code changes. Zero-code-change wiring, confirmed empirically rather than assumed.
|
| 32 |
+
|
| 33 |
+
## Verdict
|
| 34 |
+
|
| 35 |
+
Reasoning was the last plausible explanation for why the LWM warm-up's claimed +3.4–12.8% transfer doesn't show up on real bugs. It isn't the explanation — the model performs identically bug-for-bug with thinking on or off. Between the original think-OFF result and this think-ON check, the claim has now been tested on the two axes that mattered (synthetic vs real, thinking off vs on) and shows no transfer on any of them for real coding.
|
| 36 |
+
|
| 37 |
+
---
|
| 38 |
+
|
| 39 |
+
*Generation: native loop = `lib/agentic/native/{tools_repo,run_swebench,agent_loop,client}.py` (40-step, temp 0), server flags `--jinja -c 32768 --reasoning on`, Q4_K_M / UD-Q4_K_M, b9653. Grading = official `swebench` harness. Banked reports: `results/swebench/{agentworld-35b-a3b-think,qwen3-5-35b-base-think}.report.json` (think-ON); `results/swebench/{agentworld-35b-a3b,qwen3-5-35b-base}.report.json` (think-OFF, filtered to the 12-bug subset for this comparison). Chart (`reports/agentworld-think-on-null.png`): left = the think-OFF→think-ON slopegraph (AgentWorld flat, base flat); right = the per-bug grid, the base's one swap highlighted. Companion: `reports/agentworld-lwm-transfer.md` (the original think-OFF finding this closes).*
|
reports/agentworld-think-on-null.png
ADDED
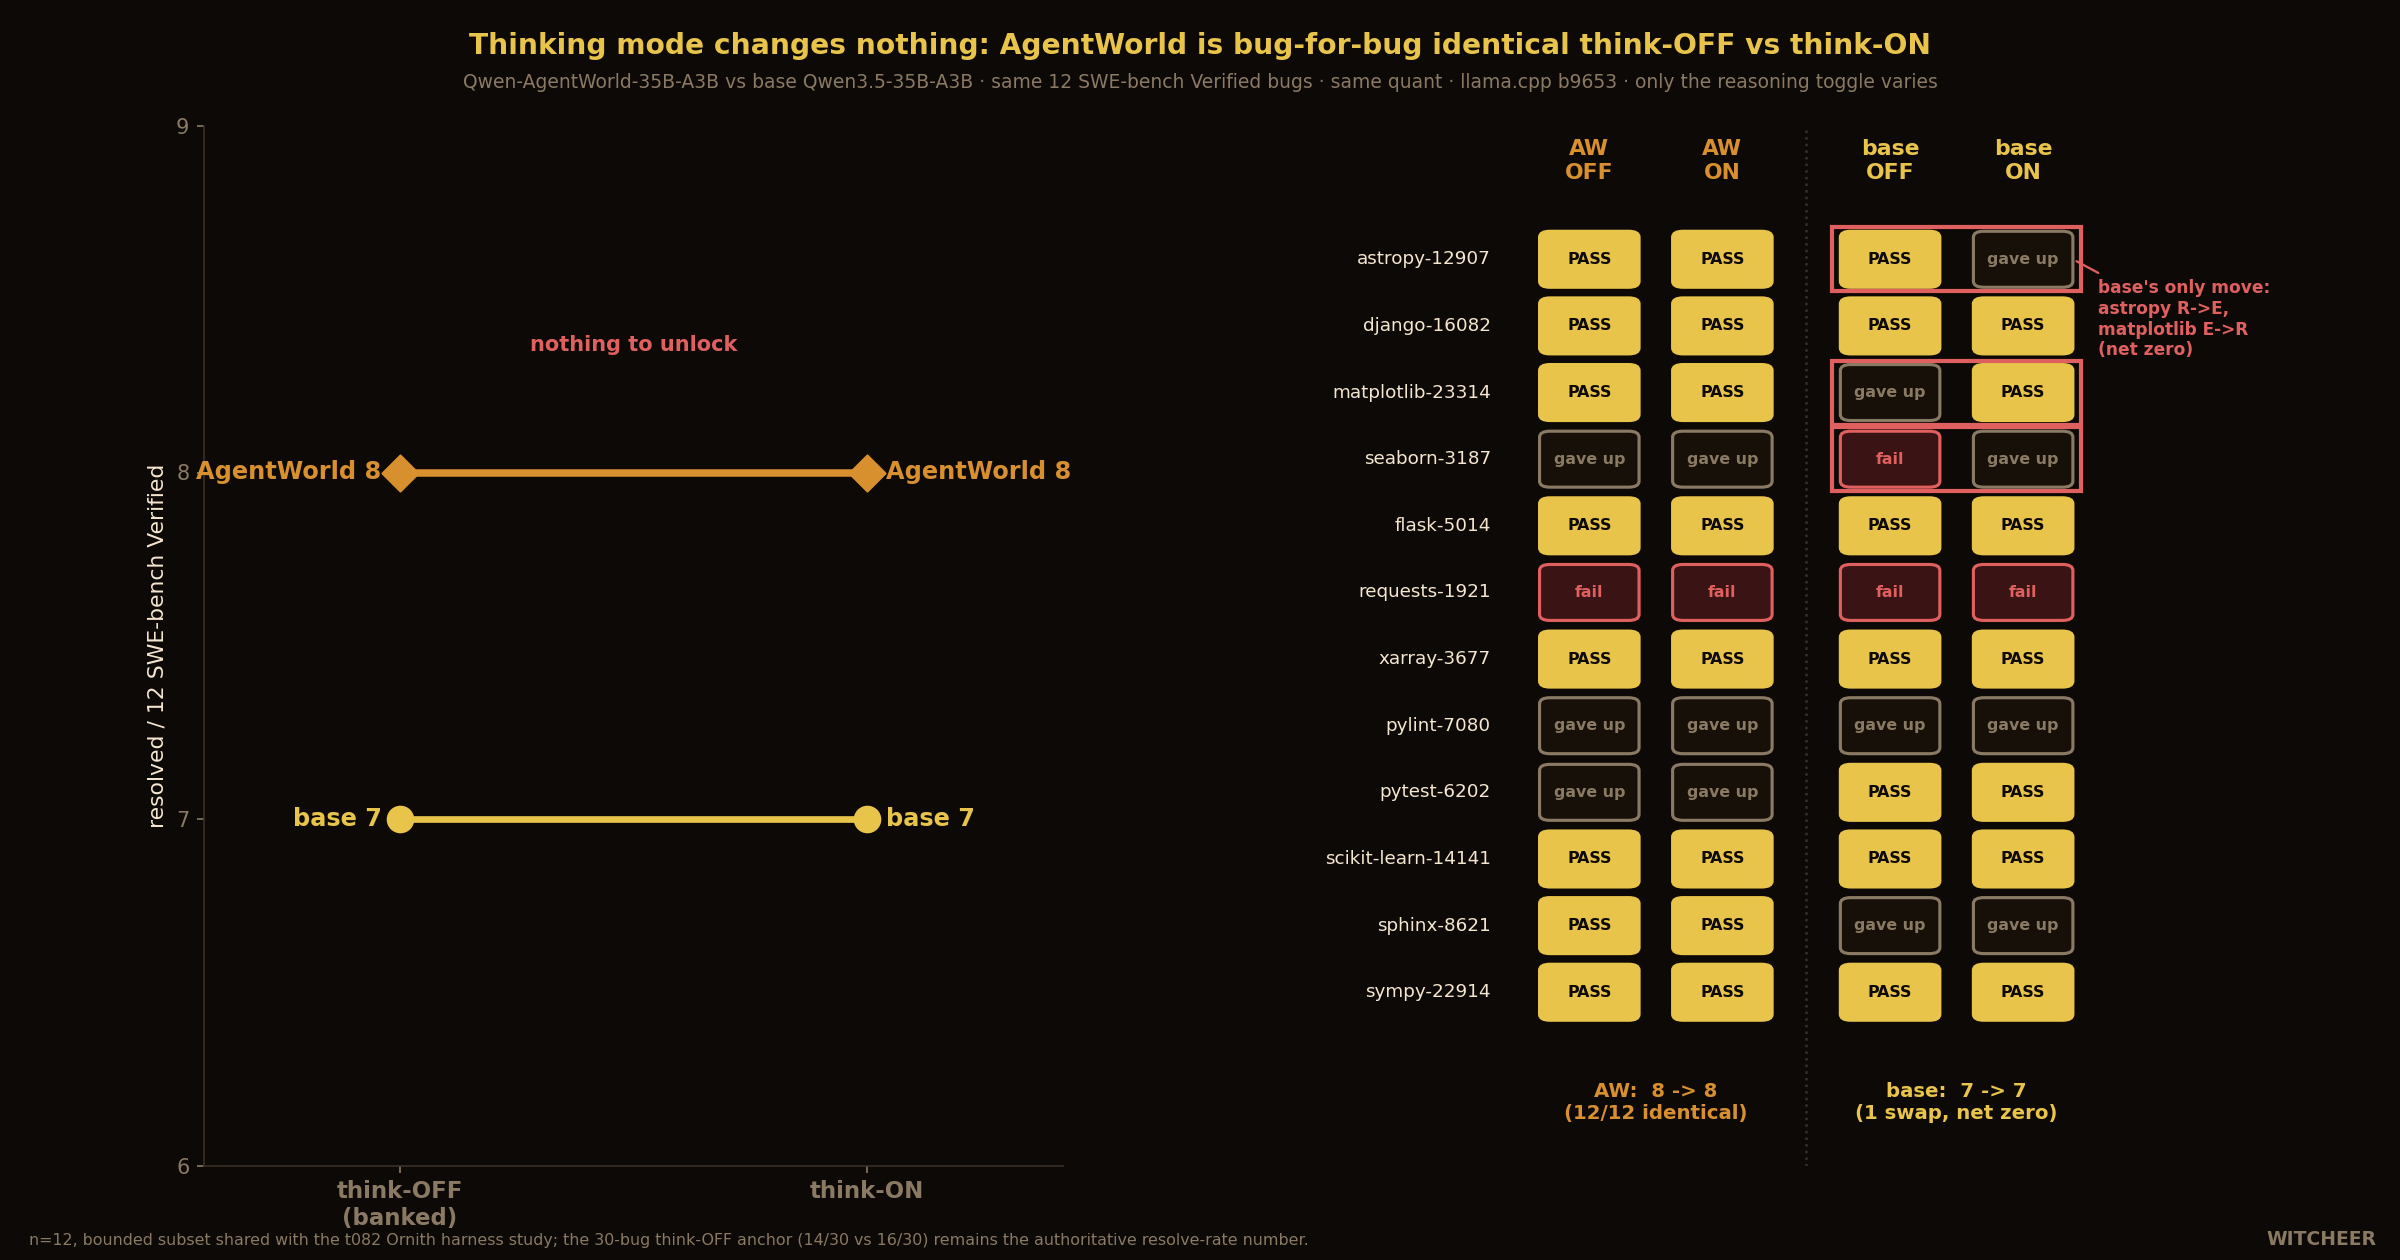
|
Git LFS Details
|
reports/assets/ltx/bench/campfire-night-1280x704-97f.mp4
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:50445405bc06a1e0fbfcbbb0fd45fb75f097f5b1a925234ae37329a86c74b25b
|
| 3 |
+
size 1611195
|
reports/assets/ltx/bench/campfire-night-768x512-97f.mp4
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:4a726a22ffdd873e09d5d8cf393d6f8827de8732623e758d466080dd2eb31d4a
|
| 3 |
+
size 961579
|
reports/assets/ltx/bench/drummer-solo-1280x704-97f.mp4
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:c3c5c49ed1adcb865c4e4ba706aa69aec0628732ccebd5747a6778d40ac3b753
|
| 3 |
+
size 2300664
|
reports/assets/ltx/bench/drummer-solo-768x512-97f.mp4
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:80f48d799436806b68d5a43d4db32b5c99d0a8a621dcdd2325bf5420075e52c6
|
| 3 |
+
size 1478788
|
reports/assets/ltx/bench/ocean-storm-1280x704-97f.mp4
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:7f13fa5e3d813f89a42a787bfd06e836864b7172fa9d0cc5801431e86dd1e061
|
| 3 |
+
size 1801514
|
reports/assets/ltx/bench/ocean-storm-768x512-97f.mp4
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:ffc1e2fff82231749bcf1945ecf5194a963004336ead98203c15861eeaa596d5
|
| 3 |
+
size 1185260
|
reports/assets/ltx/bench/puppy-garden-1280x704-97f.mp4
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:287ec9497008908c86bb46b4f4b7f7b9c78dcf64e40a4e6ff9efa5f1533d47ac
|
| 3 |
+
size 2755194
|
reports/assets/ltx/bench/puppy-garden-768x512-97f.mp4
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:de4e02997fb5ea1fc62ed7babc13581991152b06f6efb2a0dca625d0eb947904
|
| 3 |
+
size 1980693
|
reports/assets/ltx/bench/street-market-1280x704-97f.mp4
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:93fb9419404adbb5e37e702ec3caeb1ceb4b477e63001560d9645936ec733d6e
|
| 3 |
+
size 2906405
|
reports/assets/ltx/bench/street-market-768x512-97f.mp4
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:b4df83532a87ef318c59f43e7a81f38ad05726c93edc0b40bbdc7f61ae71c179
|
| 3 |
+
size 1563294
|
reports/assets/ltx/bench/summary.json
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"configs": {
|
| 3 |
+
"768x512": {
|
| 4 |
+
"n_ok": 5,
|
| 5 |
+
"n_failed": 0,
|
| 6 |
+
"mean_gen_seconds": 43.5306,
|
| 7 |
+
"video_seconds": 4.041666666666667,
|
| 8 |
+
"seconds_per_video_second": 10.770457731958762,
|
| 9 |
+
"max_peak_vram_mib": 24226
|
| 10 |
+
},
|
| 11 |
+
"1280x704": {
|
| 12 |
+
"n_ok": 5,
|
| 13 |
+
"n_failed": 0,
|
| 14 |
+
"mean_gen_seconds": 49.7772,
|
| 15 |
+
"video_seconds": 4.041666666666667,
|
| 16 |
+
"seconds_per_video_second": 12.31600824742268,
|
| 17 |
+
"max_peak_vram_mib": 24226
|
| 18 |
+
}
|
| 19 |
+
},
|
| 20 |
+
"load_seconds": 0.01
|
| 21 |
+
}
|
reports/assets/ltx/bench/synth.json
ADDED
|
@@ -0,0 +1,145 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"load_seconds": 0.01,
|
| 3 |
+
"records": [
|
| 4 |
+
{
|
| 5 |
+
"name": "puppy-garden",
|
| 6 |
+
"category": "motion-tracking",
|
| 7 |
+
"width": 768,
|
| 8 |
+
"height": 512,
|
| 9 |
+
"num_frames": 97,
|
| 10 |
+
"fps": 24.0,
|
| 11 |
+
"seed": 42,
|
| 12 |
+
"gen_seconds": 61.22,
|
| 13 |
+
"peak_vram_mib": 24225,
|
| 14 |
+
"nvidia_global_mib": 25176,
|
| 15 |
+
"clip": "/home/witcheer/ltx-out/bench/puppy-garden-768x512-97f.mp4",
|
| 16 |
+
"ok": true
|
| 17 |
+
},
|
| 18 |
+
{
|
| 19 |
+
"name": "drummer-solo",
|
| 20 |
+
"category": "audio-sync",
|
| 21 |
+
"width": 768,
|
| 22 |
+
"height": 512,
|
| 23 |
+
"num_frames": 97,
|
| 24 |
+
"fps": 24.0,
|
| 25 |
+
"seed": 42,
|
| 26 |
+
"gen_seconds": 40.479,
|
| 27 |
+
"peak_vram_mib": 24224,
|
| 28 |
+
"nvidia_global_mib": 25170,
|
| 29 |
+
"clip": "/home/witcheer/ltx-out/bench/drummer-solo-768x512-97f.mp4",
|
| 30 |
+
"ok": true
|
| 31 |
+
},
|
| 32 |
+
{
|
| 33 |
+
"name": "ocean-storm",
|
| 34 |
+
"category": "ambient-physics",
|
| 35 |
+
"width": 768,
|
| 36 |
+
"height": 512,
|
| 37 |
+
"num_frames": 97,
|
| 38 |
+
"fps": 24.0,
|
| 39 |
+
"seed": 42,
|
| 40 |
+
"gen_seconds": 41.641,
|
| 41 |
+
"peak_vram_mib": 24226,
|
| 42 |
+
"nvidia_global_mib": 24792,
|
| 43 |
+
"clip": "/home/witcheer/ltx-out/bench/ocean-storm-768x512-97f.mp4",
|
| 44 |
+
"ok": true
|
| 45 |
+
},
|
| 46 |
+
{
|
| 47 |
+
"name": "street-market",
|
| 48 |
+
"category": "crowd-ambience",
|
| 49 |
+
"width": 768,
|
| 50 |
+
"height": 512,
|
| 51 |
+
"num_frames": 97,
|
| 52 |
+
"fps": 24.0,
|
| 53 |
+
"seed": 42,
|
| 54 |
+
"gen_seconds": 34.283,
|
| 55 |
+
"peak_vram_mib": 24226,
|
| 56 |
+
"nvidia_global_mib": 25242,
|
| 57 |
+
"clip": "/home/witcheer/ltx-out/bench/street-market-768x512-97f.mp4",
|
| 58 |
+
"ok": true
|
| 59 |
+
},
|
| 60 |
+
{
|
| 61 |
+
"name": "campfire-night",
|
| 62 |
+
"category": "quiet-detail",
|
| 63 |
+
"width": 768,
|
| 64 |
+
"height": 512,
|
| 65 |
+
"num_frames": 97,
|
| 66 |
+
"fps": 24.0,
|
| 67 |
+
"seed": 42,
|
| 68 |
+
"gen_seconds": 40.03,
|
| 69 |
+
"peak_vram_mib": 24226,
|
| 70 |
+
"nvidia_global_mib": 24158,
|
| 71 |
+
"clip": "/home/witcheer/ltx-out/bench/campfire-night-768x512-97f.mp4",
|
| 72 |
+
"ok": true
|
| 73 |
+
},
|
| 74 |
+
{
|
| 75 |
+
"name": "puppy-garden",
|
| 76 |
+
"category": "motion-tracking",
|
| 77 |
+
"width": 1280,
|
| 78 |
+
"height": 704,
|
| 79 |
+
"num_frames": 97,
|
| 80 |
+
"fps": 24.0,
|
| 81 |
+
"seed": 42,
|
| 82 |
+
"gen_seconds": 50.906,
|
| 83 |
+
"peak_vram_mib": 24226,
|
| 84 |
+
"nvidia_global_mib": 25260,
|
| 85 |
+
"clip": "/home/witcheer/ltx-out/bench/puppy-garden-1280x704-97f.mp4",
|
| 86 |
+
"ok": true
|
| 87 |
+
},
|
| 88 |
+
{
|
| 89 |
+
"name": "drummer-solo",
|
| 90 |
+
"category": "audio-sync",
|
| 91 |
+
"width": 1280,
|
| 92 |
+
"height": 704,
|
| 93 |
+
"num_frames": 97,
|
| 94 |
+
"fps": 24.0,
|
| 95 |
+
"seed": 42,
|
| 96 |
+
"gen_seconds": 50.227,
|
| 97 |
+
"peak_vram_mib": 24222,
|
| 98 |
+
"nvidia_global_mib": 25260,
|
| 99 |
+
"clip": "/home/witcheer/ltx-out/bench/drummer-solo-1280x704-97f.mp4",
|
| 100 |
+
"ok": true
|
| 101 |
+
},
|
| 102 |
+
{
|
| 103 |
+
"name": "ocean-storm",
|
| 104 |
+
"category": "ambient-physics",
|
| 105 |
+
"width": 1280,
|
| 106 |
+
"height": 704,
|
| 107 |
+
"num_frames": 97,
|
| 108 |
+
"fps": 24.0,
|
| 109 |
+
"seed": 42,
|
| 110 |
+
"gen_seconds": 48.701,
|
| 111 |
+
"peak_vram_mib": 24225,
|
| 112 |
+
"nvidia_global_mib": 25260,
|
| 113 |
+
"clip": "/home/witcheer/ltx-out/bench/ocean-storm-1280x704-97f.mp4",
|
| 114 |
+
"ok": true
|
| 115 |
+
},
|
| 116 |
+
{
|
| 117 |
+
"name": "street-market",
|
| 118 |
+
"category": "crowd-ambience",
|
| 119 |
+
"width": 1280,
|
| 120 |
+
"height": 704,
|
| 121 |
+
"num_frames": 97,
|
| 122 |
+
"fps": 24.0,
|
| 123 |
+
"seed": 42,
|
| 124 |
+
"gen_seconds": 50.822,
|
| 125 |
+
"peak_vram_mib": 24222,
|
| 126 |
+
"nvidia_global_mib": 25260,
|
| 127 |
+
"clip": "/home/witcheer/ltx-out/bench/street-market-1280x704-97f.mp4",
|
| 128 |
+
"ok": true
|
| 129 |
+
},
|
| 130 |
+
{
|
| 131 |
+
"name": "campfire-night",
|
| 132 |
+
"category": "quiet-detail",
|
| 133 |
+
"width": 1280,
|
| 134 |
+
"height": 704,
|
| 135 |
+
"num_frames": 97,
|
| 136 |
+
"fps": 24.0,
|
| 137 |
+
"seed": 42,
|
| 138 |
+
"gen_seconds": 48.23,
|
| 139 |
+
"peak_vram_mib": 24225,
|
| 140 |
+
"nvidia_global_mib": 25260,
|
| 141 |
+
"clip": "/home/witcheer/ltx-out/bench/campfire-night-1280x704-97f.mp4",
|
| 142 |
+
"ok": true
|
| 143 |
+
}
|
| 144 |
+
]
|
| 145 |
+
}
|
reports/assets/ltx/bench/warmup.mp4
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:53b1a38dcdf376e6540b3dcbacae504db30a26632eac4e9f67199445b0558cd2
|
| 3 |
+
size 339041
|
reports/assets/zimage-montage.png
ADDED

|
Git LFS Details
|
reports/assets/zimage/complex-1024-8st.png
ADDED

|
Git LFS Details
|
reports/assets/zimage/counting-1024-8st.png
ADDED

|
Git LFS Details
|
reports/assets/zimage/illustration-1024-8st.png
ADDED

|
Git LFS Details
|
reports/assets/zimage/landscape-1024-8st.png
ADDED

|
Git LFS Details
|
reports/assets/zimage/portrait-1024-8st.png
ADDED

|
Git LFS Details
|
reports/assets/zimage/spatial-1024-8st.png
ADDED

|
Git LFS Details
|
reports/assets/zimage/sweep-portrait-1024-16st.png
ADDED

|
Git LFS Details
|
reports/assets/zimage/sweep-portrait-1024-4st.png
ADDED

|
Git LFS Details
|
reports/assets/zimage/sweep-portrait-1024-8st.png
ADDED

|
Git LFS Details
|
reports/assets/zimage/sweep-portrait-1024-9st.png
ADDED

|
Git LFS Details
|
reports/assets/zimage/text-1024-8st.png
ADDED

|
Git LFS Details
|
reports/assets/zimage/two-object-1024-8st.png
ADDED

|
Git LFS Details
|
reports/bias-only-steering.md
ADDED
|
@@ -0,0 +1,109 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Bias-Only Reasoning Steering on one RTX 5090: nothing moves at bounded budget — and random rewards match correct ones
|
| 2 |
+
|
| 3 |
+
**t074 · 2026-07-02 · Qwen2.5-Math-7B · RLOO · bounded-budget reproduction + the controls the paper omits**
|
| 4 |
+
|
| 5 |
+
Paper: *Steering LLM Reasoning Through Bias-Only Adaptation* (arXiv 2505.18706, EMNLP 2025).
|
| 6 |
+
Companion: *Small Vectors, Big Effects* (arXiv 2509.06608). Code: corl-team/steering-reasoning.
|
| 7 |
+
|
| 8 |
+
## The claims
|
| 9 |
+
|
| 10 |
+
1. **Capability:** train ONE d-dim bias vector per layer (added to `mlp.down_proj` output,
|
| 11 |
+
≈0.0016% of params) with RL and match full RL fine-tuning. Their Table 1, Qwen2.5-Math-7B:
|
| 12 |
+
MATH500 base 52.2 → full-FT 79.3 → **steering 79.9**; AMC23 45.8 → 64.2 → 62.5.
|
| 13 |
+
2. **Efficiency:** "34s vs 52m" training, "0.11s vs 9.94s" per step, 240KB vs 13.8GB optimizer
|
| 14 |
+
memory (Qwen2.5-14B figures).
|
| 15 |
+
3. **Their own mechanism paper:** the last-layer vector "behaves like first-token
|
| 16 |
+
substitution" — prefixing the token "To" recovers ~10–11 points on this base, "about
|
| 17 |
+
three quarters" of the last-layer vector's gain.
|
| 18 |
+
|
| 19 |
+
## What we ran (and why it's not their code)
|
| 20 |
+
|
| 21 |
+
**Their pinned stack cannot execute on consumer Blackwell.** torch 2.6.0+cu124 (with
|
| 22 |
+
vllm 0.8.5.post1 + flashinfer cu124 on top) fails the first kernel launch on sm_120:
|
| 23 |
+
`CUDA error: no kernel image is available for execution on the device`. The stack is dead
|
| 24 |
+
on arrival on an RTX 5090, as shipped.
|
| 25 |
+
|
| 26 |
+
So we reimplemented their recipe on the rig's stack (torch 2.10+cu128, HF transformers),
|
| 27 |
+
pinned from their own configs (`configs/train/rl/qwen2.5-math-7b/deepscaler/`): RLOO,
|
| 28 |
+
temperature 1.0, steering lr 1e-3, their LoRA baseline config verbatim (rank 4, alpha 4,
|
| 29 |
+
`down_proj` only, lr 1e-4), `qwen_math` template, DeepScaleR dataset.
|
| 30 |
+
|
| 31 |
+
**Bounded budget, identical across arms** (disclosed deviation from their full recipe of
|
| 32 |
+
~1 epoch ≈ 2,500 steps × 16 prompts × 16 generations × 4K ctx): 20 steps × 8 prompts ×
|
| 33 |
+
8 generations × 1,024 max new tokens, seed 0, same fixed 512-problem DeepScaleR slice.
|
| 34 |
+
That is ~1,280 training rollouts against their ~645K — a gain-at-matched-compute probe,
|
| 35 |
+
not a full-recipe reproduction.
|
| 36 |
+
|
| 37 |
+
**Eval:** MATH500 + AMC23, greedy pass@1, the rig's t073-validated pipeline (vLLM
|
| 38 |
+
generation + the authors' vendored Qwen2.5-Math grader), identical prompts and grader for
|
| 39 |
+
every arm. Steering checkpoints served in **stock vLLM** via an architecture re-badge:
|
| 40 |
+
Qwen2.5 relabeled `LlamaForCausalLM` with `mlp_bias=true` (Qwen2.5 is Llama-shaped;
|
| 41 |
+
zero-filled o/gate/up biases; learned vectors in the down biases) — logit-equivalence
|
| 42 |
+
verified (fp32 max|Δ| = 0.0; bf16 argmax-identical on all probes).
|
| 43 |
+
|
| 44 |
+
## Results: a five-arm null
|
| 45 |
+
|
| 46 |
+
| arm | MATH500 | Δ vs base | AMC23 | Δ |
|
| 47 |
+
|---|---|---|---|---|
|
| 48 |
+
| base | 54.6 | — | 45.0 | — |
|
| 49 |
+
| steering @ 20 steps | 54.4 | −0.2 | 45.0 | 0.0 |
|
| 50 |
+
| LoRA r4 down_proj @ 20 steps | 53.8 | −0.8 | 40.0 | −5.0 |
|
| 51 |
+
| random-reward steering @ 20 steps | 54.2 | −0.4 | 45.0 | 0.0 |
|
| 52 |
+
| base + "To" prefix (no training) | 53.0 | −1.6 | — | — |
|
| 53 |
+
| *their claim (full recipe)* | *79.9* | *+27.7* | *62.5* | *+16.7* |
|
| 54 |
+
|
| 55 |
+
Base sanity holds: 54.6 MATH500 / 45.0 AMC23 vs their reported base 52.2 / 45.8 (and the
|
| 56 |
+
rig's t073 measurement 53.4) — the pipeline reproduces their starting point. The trained
|
| 57 |
+
arms are genuinely different checkpoints (steering vector norms ~0.30–0.32 per layer,
|
| 58 |
+
LoRA 2.52M params trained, generations shifted) — they just don't score differently.
|
| 59 |
+
|
| 60 |
+
Three reads:
|
| 61 |
+
|
| 62 |
+
1. **The steering gain does not materialize early.** At 20 matched steps the +27.7 claim
|
| 63 |
+
shows +0.0. Whatever their curve does, none of it lives in the first ~1,280 rollouts —
|
| 64 |
+
on a consumer card the recipe's cost-to-first-signal is the whole recipe, not a cheap
|
| 65 |
+
probe. (Contrast One-Shot-EM, same base family, which moved +2.0 by step 10 — t073.)
|
| 66 |
+
2. **Correct rewards buy nothing over random ones here.** Random-reward steering (54.2 /
|
| 67 |
+
45.0) is indistinguishable from correct-reward steering (54.4 / 45.0) — both are base.
|
| 68 |
+
At this budget there is no evidence the reward signal, the thing RL is supposedly
|
| 69 |
+
injecting, does anything at all.
|
| 70 |
+
3. **Their own token-substitution number does not reproduce on the standard template.**
|
| 71 |
+
"To"-prefix: −1.6, not +10–11. The likely reason is right in the raw generations: on
|
| 72 |
+
the `qwen_math` CoT template the base model's answers *already open with "To"* — the
|
| 73 |
+
token the last-layer vector allegedly boosts is already there. The 10–11-point claim
|
| 74 |
+
must live in a weaker base protocol; on the template their own training config uses,
|
| 75 |
+
there is nothing for first-token substitution to elicit.
|
| 76 |
+
|
| 77 |
+
## Where the wall-clock actually goes
|
| 78 |
+
|
| 79 |
+
Measured per step, median across all three trained arms (one RTX 5090): rollout ~50s
|
| 80 |
+
(**75–76%**), reward grading ~0.3s (<1%), backward+update ~16s (**24–25%**). The
|
| 81 |
+
per-step split is IDENTICAL whether 100K bias params or 2.52M LoRA params train, because
|
| 82 |
+
the update slice is dominated by the backward pass through the frozen 7.6B network —
|
| 83 |
+
which no adapter scheme shrinks. Their "0.11s vs 9.94s" can only be the optimizer sliver
|
| 84 |
+
inside that slice; their "34s vs 52m" headline excludes the ~75% of wall-clock (rollouts)
|
| 85 |
+
that is invariant to what trains.
|
| 86 |
+
|
| 87 |
+
On a 32GB consumer card the honest efficiency win of bias-only adaptation is **memory,
|
| 88 |
+
not speed**: full-param 7B RL does not fit at all (t073's OOM gate), while bias-only
|
| 89 |
+
(~100K params, ~800KB optimizer state) trains comfortably. That is a real and useful
|
| 90 |
+
result — it is just not "34s training."
|
| 91 |
+
|
| 92 |
+
## Honest limits
|
| 93 |
+
|
| 94 |
+
- 20 steps is ~0.2% of their rollout budget; this bounds where the gain ISN'T (early),
|
| 95 |
+
not whether their endpoint is real. The Table-1 claim is neither confirmed nor refuted.
|
| 96 |
+
- Their full-FT arm cannot run on 32GB; their published number is shown as reference.
|
| 97 |
+
- Qwen2.5-14B untouched (bf16 weights alone ≈ 29GB).
|
| 98 |
+
- Single seed; AMC23 is 40 questions (±2.5pts/question); LoRA's −5.0 there is 2 questions.
|
| 99 |
+
- Our loop uses HF-generate rollouts (their vLLM-engine rollouts are faster in absolute
|
| 100 |
+
terms); the SHARE decomposition, not the absolute seconds, is the finding.
|
| 101 |
+
|
| 102 |
+
## Artifacts
|
| 103 |
+
|
| 104 |
+
- `lib/steering.py` + tests (budget chooser, Qwen2→Llama re-badge config, timing parse)
|
| 105 |
+
- `scripts/train_steering.py` (bounded RLOO; steering / their-config LoRA / random-reward arms; timing instrument)
|
| 106 |
+
- `scripts/convert_steering_checkpoint.py` + `scripts/steering_equiv_check.py` (re-badge + fp32-verified gate)
|
| 107 |
+
- `scripts/fetch_steering_data.py`, `scripts/aggregate_steering.py`, `scripts/chart_steering.py`
|
| 108 |
+
- `scripts/eval_math.py --assistant-prefix` (the zero-training "To" probe)
|
| 109 |
+
- Chart: `reports/steering-claimed-vs-measured.png`
|
reports/cacheback-spec-decode.md
ADDED
|
@@ -0,0 +1,54 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Draft-free spec-decode on Qwen3-8B: the win is the workload, and the fancy table buys nothing
|
| 2 |
+
|
| 3 |
+
**Rig:** one RTX 5090 32GB (sm_120) · Qwen3-8B **bf16** · batch=1, **greedy** · 30 prompts/workload, warm-state (first discarded) · 16.5–16.8GB VRAM
|
| 4 |
+
**Method:** one instrumented greedy spec-decode loop; the three arms differ *only* by the drafter — **AR** (no draft), **PLD** (single-line prompt-lookup, the dumb baseline), **Cacheback** (the paper's dynamic LRU n-gram table). No second model, no training, no extra VRAM. Three workloads spanning the repetition spectrum: **code** (HumanEval), **copyctx** (summarize a CNN/DailyMail article), **chat** (open-ended Q&A).
|
| 5 |
+
**Metric:** MAT = mean accepted tokens per target forward pass (the portable, implementation-independent number) and realized speedup vs AR.
|
| 6 |
+
|
| 7 |
+
## The numbers (Qwen3-8B, RTX 5090, 30 prompts each)
|
| 8 |
+
|
| 9 |
+
| workload | AR | PLD (dumb) | Cacheback (LRU table) | MAT PLD → CB |
|
| 10 |
+
|---|---|---|---|---|
|
| 11 |
+
| code | 1.00× | **1.45×** | **1.47×** | 1.45 → 1.46 |
|
| 12 |
+
| copyctx | 1.00× | 1.30× | 1.30× | 1.30 → 1.30 |
|
| 13 |
+
| chat | 1.00× | 1.26× | 1.26× | 1.25 → 1.25 |
|
| 14 |
+
|
| 15 |
+
Two findings, one of them a clean null.
|
| 16 |
+
|
| 17 |
+
## Finding 1 — the speedup is real but workload-shaped, and not where you'd guess
|
| 18 |
+
|
| 19 |
+
Cache-only spec-decode needs no draft model: it proposes the next few tokens by looking up where the recent context appeared earlier in the *same* stream. So its payoff is pure n-gram repetition, and that varies by task:
|
| 20 |
+
|
| 21 |
+
- **Code is the sweet spot (1.45–1.47×), not summarization.** HumanEval completions are saturated with repeated structure — identifiers, `self.`, `return`, indentation runs — so the lookup hits often (MAT 1.45).
|
| 22 |
+
- **Summarization (copyctx) lands in the middle (1.30×), not on top.** The intuition is "summaries copy the source, lookup wins big." But a *three-sentence* summary paraphrases — it doesn't echo long verbatim spans — so the win is moderate.
|
| 23 |
+
- **Even open-ended chat gets 1.26×.** The "low-repetition" workload still has plenty of common n-grams (function words, stock phrases). There is no zero — n-gram repetition is everywhere in natural generation.
|
| 24 |
+
|
| 25 |
+
Net: a free 1.25–1.47× on single-stream greedy decoding, no model and no VRAM, with the largest gain exactly where local agents spend their time (code).
|
| 26 |
+
|
| 27 |
+
## Finding 2 — the dynamic LRU table ties dumb prompt-lookup (the null)
|
| 28 |
+
|
| 29 |
+
The headline question was whether Cacheback's machinery — an LRU n-gram table with multiple stored continuations — beats one-line prompt-lookup. On these workloads, **it doesn't**: identical MAT on chat and copyctx, +0.01 on code. The slope chart's PLD → Cacheback segment is flat.
|
| 30 |
+
|
| 31 |
+
The mechanism is the reason. With leader-length 1 (match on the last token), "look up the most-recent continuation in an LRU table" and "scan back for the last occurrence and take what followed" are the *same algorithm*. The table's extra bookkeeping changes nothing the greedy verifier accepts. Cacheback's published edge over prompt-lookup comes from the parts this dynamic-only arm omits — a **frozen background text corpus** seeded before generation, plus **tree drafting with tree-attention** — not from the dynamic table itself.
|
| 32 |
+
|
| 33 |
+
This also corrects the brief that started this run. The widely-cited **"1.86×" is Vicuna-7B with a frozen corpus + tree on an RTX 4090** (Spec-Bench), not a modern 8B. There is no per-workload table and no head-to-head-vs-PLD in the paper; both are measured here for the first time on Qwen3-8B / consumer Blackwell.
|
| 34 |
+
|
| 35 |
+
## The measurement guard that earned its keep
|
| 36 |
+
|
| 37 |
+
Greedy spec-decode is lossless by construction — a draft token is accepted only when it equals the target's own argmax. We checked it empirically against a separate pure-AR run and found **46072 / 46080 generated tokens byte-identical**. The 8 that differ are not a decoder bug: every one sits at an **exact bf16 logit tie** (top-2 logits equal to the bit, gap = 0.000). At a tie, greedy argmax is resolved by CUDA reduction order, which changes with the forward-pass tensor shape — so appending a draft can flip a coin the model is genuinely indifferent about, and greedy path-dependence carries it forward. (Re-running the AR step at the same shape flips it too.) That is bf16 greedy non-determinism, a property of the model, not the method. The realized speedup also stays ≤ MAT on every cell, the physical sanity bound (a measured speedup above MAT would mean an instrumentation bug).
|
| 38 |
+
|
| 39 |
+
## Caveats (read before quoting the numbers)
|
| 40 |
+
|
| 41 |
+
- **The harness recomputes the full prefix each step (no KV-cache reuse).** That depresses *absolute* tok/s and is why the table reports speedup and MAT, not throughput. MAT is implementation-independent — it counts target forward passes saved — and that saving is exactly what carries over to a KV-cached server. The relative ordering (code > copyctx > chat; PLD ≈ Cacheback) is the result.
|
| 42 |
+
- **Single-stream, greedy, batch=1.** Under batching, spec-decode economics change (the verifier competes with other sequences); these numbers are the single-user latency regime.
|
| 43 |
+
- **Lossless modulo bf16 ties**, quantified above — not glossed.
|
| 44 |
+
|
| 45 |
+
## Worth it if / not if
|
| 46 |
+
|
| 47 |
+
- **Worth it** as a zero-cost latency win for single-stream local generation — especially code — when you can't or won't run a draft model: no second model, no training, no extra VRAM, lossless. Plain prompt-lookup (`prompt_lookup_num_tokens` in HF) already captures essentially all of it.
|
| 48 |
+
- **Not worth the extra machinery** of a dynamic LRU table over one-line prompt-lookup — it ties on these workloads. The only reason to build the full Cacheback is its *frozen corpus + tree* arm, which is a different (parked) experiment.
|
| 49 |
+
|
| 50 |
+
## Repro
|
| 51 |
+
|
| 52 |
+
- Loop + drafters + invariants (dep-free, tested): `lib/cacheback.py` (`spec_decode_loop`, `pld_propose`, `CachebackDrafter`, `greedy_accept`, exact-cap + EOS truncation). Driver: `scripts/bench_cacheback.py` (`--arm ar|pld|cacheback`). Workloads: `scripts/build_cacheback_workloads.py` → `dataset/cacheback/{code,chat,copyctx}.jsonl`. Aggregate + chart: `scripts/{aggregate,chart}_cacheback.py`.
|
| 53 |
+
- Losslessness guard (tie-aware, GPU): `scripts/verify_cacheback_lossless.py` — recomputes the logit gap at every AR-vs-spec divergence and asserts each is a bf16 tie.
|
| 54 |
+
- Env note: a fresh `uv` venv with `transformers ≥ 4.51` + torch cu128 (the official Spec-Bench `cacheback` branch pins `transformers==4.37.1`, which can't load Qwen3); HF dataset ids must be namespaced (`openai/openai_humaneval`, `abisee/cnn_dailymail`).
|
reports/cacheback-spec-decode.png
ADDED
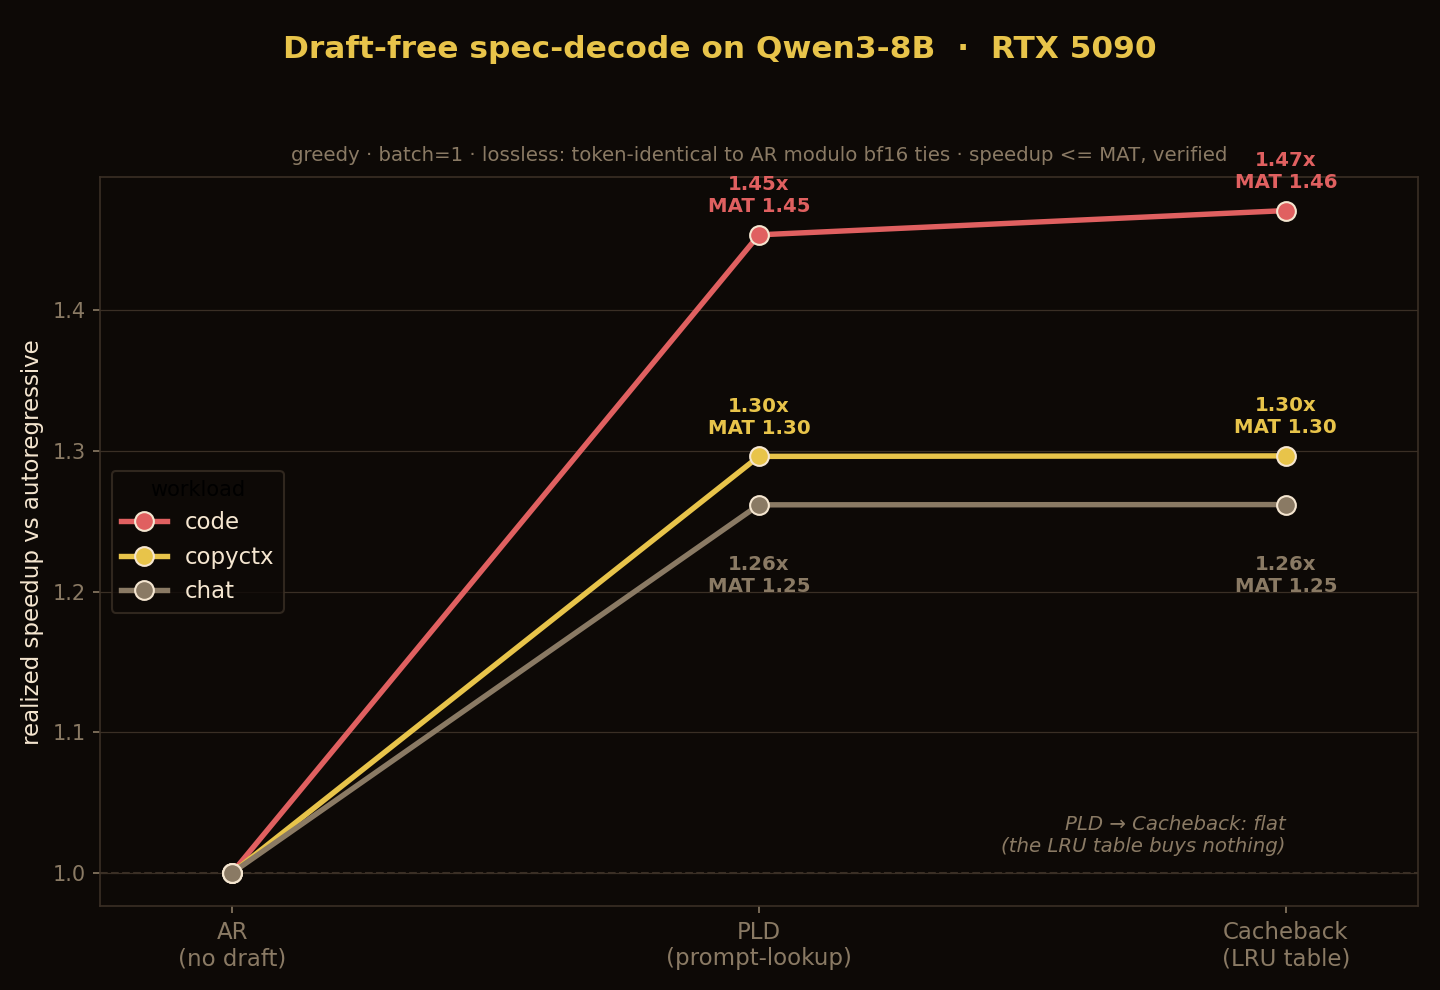
|
Git LFS Details
|
reports/card-quality-leaderboard.png
ADDED

|
Git LFS Details
|
reports/chart-awq-recipe-coverage.png
ADDED

|
Git LFS Details
|
reports/chart-grpo-gsm8k.png
ADDED

|
Git LFS Details
|
reports/chart-lfm2-vl-extract.png
ADDED

|
Git LFS Details
|
reports/chart-nemotron-speed-vs-quality.png
ADDED

|
Git LFS Details
|
reports/chart-nvfp4-vs-q6.png
ADDED

|
Git LFS Details
|